Last verified: August 26, 2026 (Pacific Time)May 2026 edition covered the Opus 4.8 launch, the SpaceX compute deal, and Managed Agents memory features.
Direct Answer (August 2026 Update): Major mid-2026 Anthropic releases introduced Claude Fable 5, native Model Context Protocol (MCP) tool integration in Claude Desktop, extended 1M context beta on Vertex AI/AWS Bedrock, and decoupled Enterprise seat pricing.
June 2026 is one of the biggest months for Anthropic since the Claude 4 launch: a new top-tier model is generally available, two workhorse models retire in four days, and Managed Agents can now run inside infrastructure you control. Here is everything that changed, with dates and migration paths.
Claude Fable 5 — the Mythos-class model goes public (June 9, 2026)
Fable 5 launch — keep the timeline abstract.
Anthropic released Claude Fable 5 on June 9, 2026 — the public version of what had been known as its Mythos-class model tier. It is positioned as a new tier above Opus, and it is Anthropic’s most capable generally available model. According to CNBC’s launch coverage, Fable 5 scored more than 10% higher than Claude Opus 4.8 on some benchmarks, with exceptional performance across software engineering and knowledge work. Anthropic credits new safeguards that block responses in specific high-risk areas for making a broad release possible.
The practical details developers need:
Model ID:claude-fable-5
Availability: enterprise customers and paid subscribers
Context window: 1 million tokens; maximum output 128K tokens
API pricing: $10 per million input tokens / $50 per million output tokens
API surface: adaptive thinking only — temperature, top_p, top_k, and budget_tokens are not accepted, and unlike Opus 4.8, an explicit thinking: {type: "disabled"} returns a 400 error. Omit the thinking parameter entirely if you do not want it.
For where Fable 5 sits against every other Claude model on price, see our continuously updated Claude AI pricing guide, and our complete Fable 5 guide for capabilities and use cases.
June 15 deadline: Claude Opus 4 and Sonnet 4 retire in four days
If you are still calling claude-opus-4-20250514 or claude-sonnet-4-20250514, those models retire from the Claude API on June 15, 2026. Requests after retirement return 404 errors. The drop-in replacements:
claude-opus-4-20250514 → claude-opus-4-8
claude-sonnet-4-20250514 → claude-sonnet-4-6
Note that both replacements use adaptive thinking rather than manual thinking budgets, and the 4.6+ models reject assistant-turn prefills — so this is a small migration, not just a string swap. Anthropic also deprecated Claude Opus 4.1 this month, with API retirement scheduled for August 5, 2026 — worth adding to your migration calendar now.
Current Claude model lineup and API pricing (June 2026)
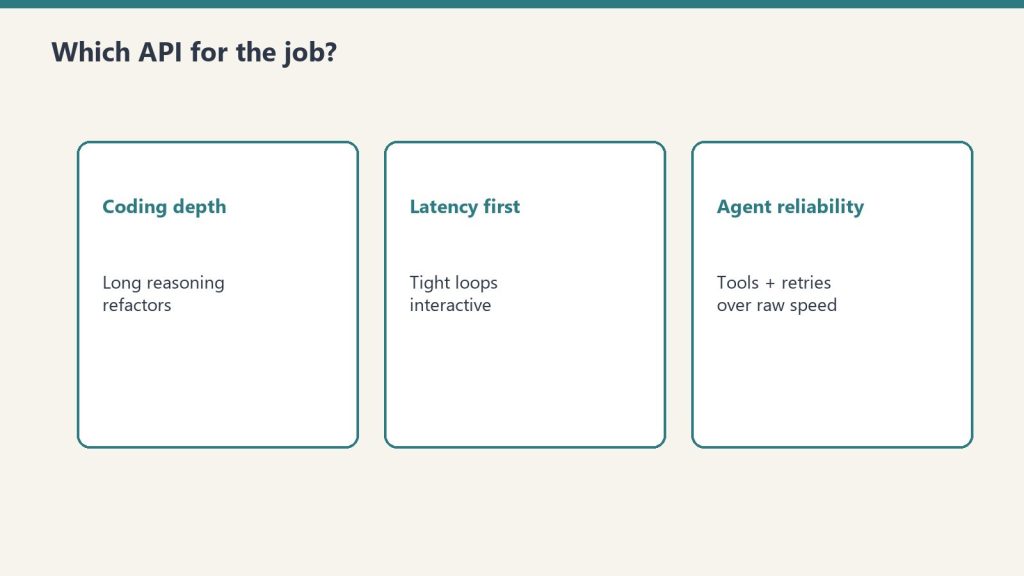
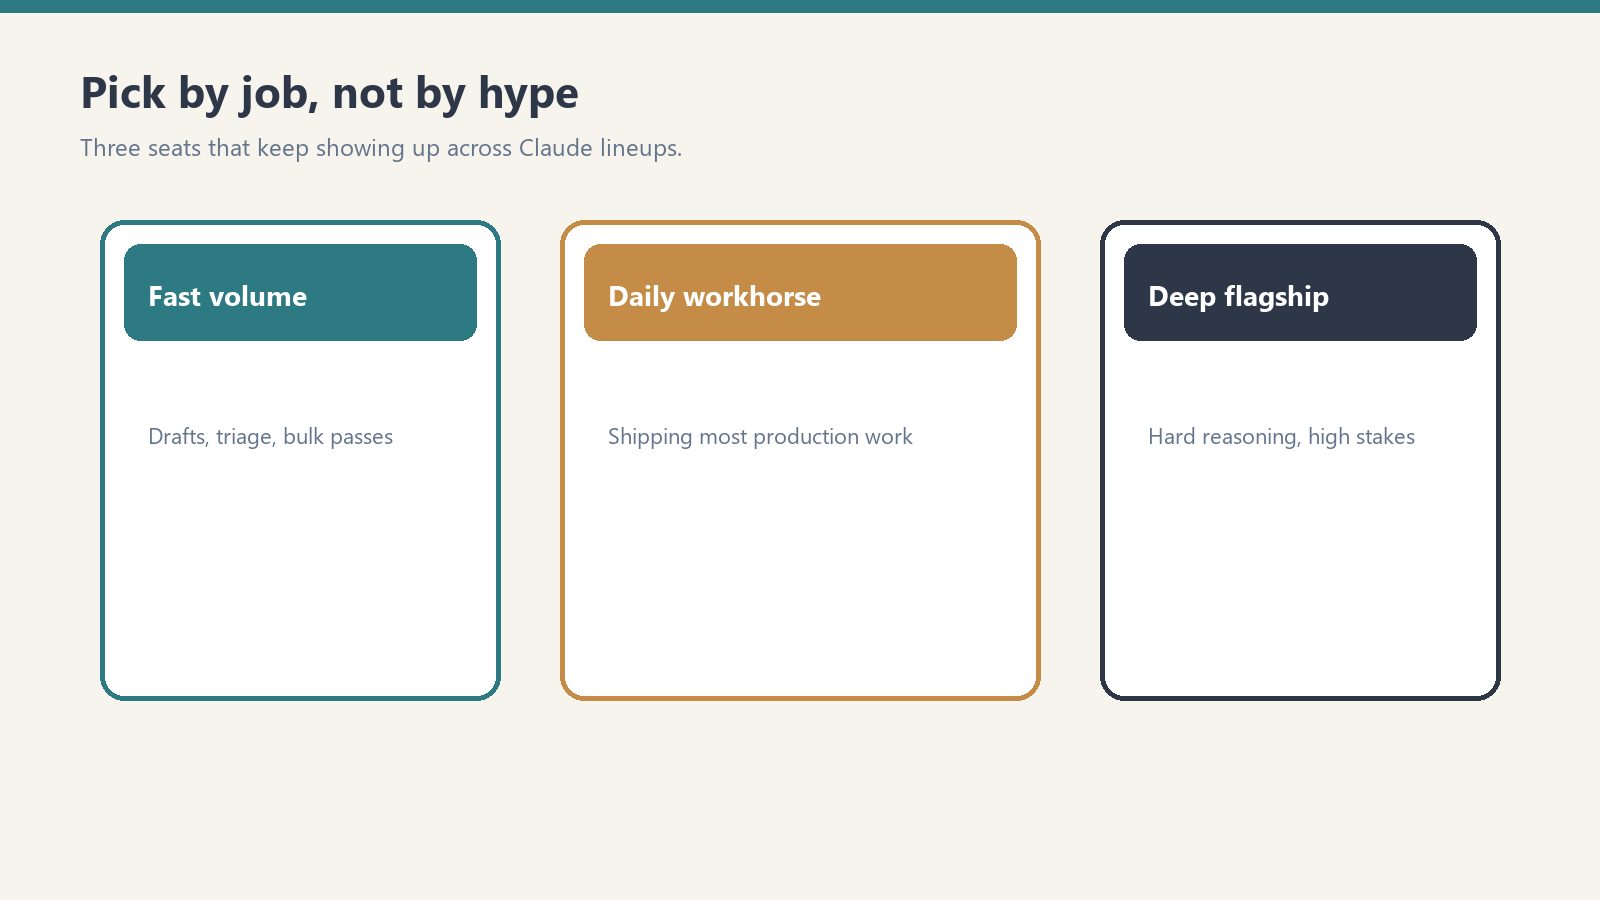
Current lineup by job — no sticky version stickers on art.
Model
Model ID
Context
Max output
Input $/1M
Output $/1M
Claude Fable 5
claude-fable-5
1M
128K
$10.00
$50.00
Claude Opus 4.8 (legacy — still listed)
claude-opus-4-8
1M
128K
$5.00
$25.00
Claude Opus 4.8 (legacy — still listed)
claude-opus-4-8
1M
128K
$5.00
$25.00
Claude Sonnet 4.6 (legacy — still listed)
claude-sonnet-4-6
1M
64K
$3.00
$15.00
Claude Haiku 4.5
claude-haiku-4-5
200K
64K
$1.00
$5.00
Opus 4.7, 4.6, 4.5, and 4.1 and Sonnet 4.5 remain active for pinned workloads. We track which model is current at any moment in our current Claude model version reference.
Managed Agents: self-hosted sandboxes and private MCP servers
Managed Agents and private MCP servers.
Claude Managed Agents — Anthropic’s server-managed agent platform — can now execute tools inside a sandbox you control. The agent loop still runs on Anthropic’s orchestration layer, but bash commands, file operations, and code execution happen in your own container, behind your own firewall, with your own egress rules. Your worker long-polls Anthropic’s work queue over outbound-only connections; Anthropic never dials into your network. Managed Agents can also now connect to private MCP servers, which matters for any organization whose internal tools are not on the public internet.
For regulated industries — healthcare, finance, legal — this is the missing piece that lets you adopt hosted agents while keeping data residency: files and tool output never leave infrastructure you own.
Claude Code: nested sub-agents and plugin search
Claude Code shipped a steady stream of updates in June: nested sub-agents (agents can now spawn their own sub-agents for deeper task decomposition), smarter model and region handling, a new plugin search, and improved Chrome, VS Code, and terminal workflows.
Legal expansion: 20+ MCP connectors and 12 practice-area plugins
Anthropic released more than 20 new legal MCP connectors and 12 practice-area plugins, covering research, contracts, discovery, matter management, and legal aid. The pattern to note: Anthropic is increasingly shipping vertical integration bundles rather than leaving connector-building entirely to the ecosystem.
Claude Corps: $150M for nonprofit AI adoption
Anthropic announced Claude Corps, a $150 million fellowship program that will embed roughly 1,000 trained fellows inside nonprofit organizations for a year to help them use AI effectively. Applications and program details are rolling out through Anthropic’s newsroom.
Apple Foundation Models integration
Claude support is coming to Apple’s Foundation Models framework on iOS 27, iPadOS 27, macOS 27, and visionOS 27 — meaning third-party Apple developers will be able to call Claude through Apple’s native AI framework rather than integrating the API directly.
What to watch for in July
August 5, 2026: Claude Opus 4.1 retires from the API — migrate to claude-opus-4-8 before then.
Fable 5 ecosystem: expect Claude Code, Cowork, and Managed Agents to expose Fable 5 more broadly through July as capacity scales.
Apple rollout: developer betas of the iOS 27 family will show what Claude-via-Foundation-Models actually looks like in practice.
The Signal is a daily AI intelligence briefing from Tygart Media — field notes from someone who builds with these tools 12 hours a day, not someone who reads press releases about them. Each edition distills the day’s most consequential AI and search developments into what they actually mean for agencies, small business operators, and builders shipping real infrastructure.
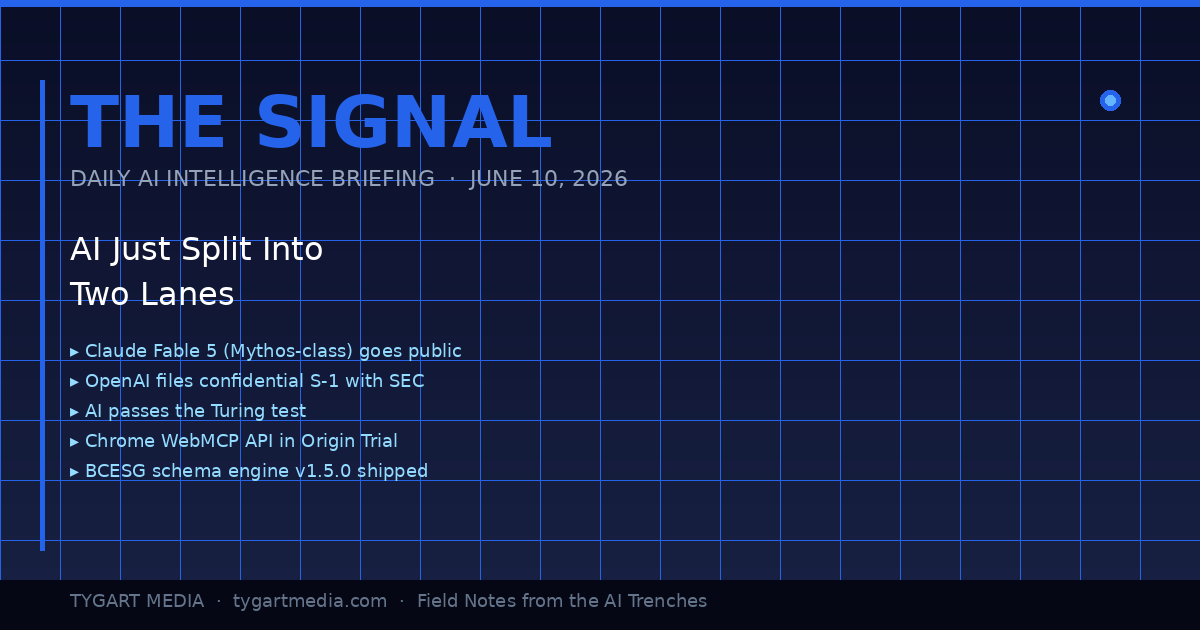
June 10, 2026: The Day the Lanes Forked
The day the lanes forked — product vs infrastructure.
Today was the kind of day where you can feel the road forking under your tires. Not because one thing happened — because eight things happened simultaneously, and if you squint at the pattern, they all point the same direction: AI just stopped being a product category and started being infrastructure. The plumbing layer. The thing you build on top of, not the thing you buy.
I’ve been building with Claude since the Haiku days. I run it 12 hours a day across 20+ WordPress sites, a five-site knowledge cluster on Google Cloud, and a custom schema engine I shipped yesterday. When the landscape shifts, I don’t read about it on TechCrunch — I feel it in the tooling. And today, the tooling lurched forward in a way that matters.
Here’s the daily signal.
Claude Fable 5: Mythos-Class AI Goes Public
Anthropic launched Claude Fable 5 yesterday — the first publicly available Mythos-class model, a tier above Opus. Pricing is $10 per million input tokens and $50 per million output tokens. It’s the most capable model Anthropic has ever released to the general public, state-of-the-art on nearly every benchmark, and it comes with a fascinating constraint: queries on certain topics automatically route to Opus 4.8 instead, triggering in less than 5% of sessions. Anthropic is essentially saying: here’s the most powerful thing we’ve ever built, and we’ve installed guard rails at the edge cases where power becomes risk.
For agencies and small business operators, the practical read is this: Fable 5 is included on Pro, Max, Team, and Enterprise plans through June 22 at no extra cost. After that, it comes off the subscription tiers. If you’re building workflows that depend on Mythos-class reasoning, you have 12 days to test whether the capability justifies the API cost — or whether Opus and Sonnet handle your actual use cases just fine.
The real signal isn’t the model itself. It’s that Anthropic also doubled Cowork limits at no charge and shipped Claude Managed Agents in public beta. They’re not just selling you a smarter model — they’re selling you an operating system for delegating work to AI. That’s a fundamentally different product than a chatbot.
Meanwhile, I Was Building the Infrastructure Layer — Not Reading About It
Infrastructure layer work while the headlines chase models.
While the tech press was writing headlines about Fable 5, I was elbow-deep in the kind of work that actually turns these models into business value. Yesterday, across a 14-hour session, my team — which at this point is me and a fleet of Claude instances — shipped three things that matter more to my clients than any benchmark score:
1. bcesg-knowledge-api v1.5.0 — a custom WordPress plugin I built and deployed across BCESG.org that outputs a JSON-LD @graph array containing Article, FAQPage, Organization, WebPage, BreadcrumbList, Person (author), and speakable schema — all generated from 13 custom meta fields. This isn’t a schema plugin you install from the WordPress directory. It’s a purpose-built schema engine designed for one thing: making every page on the site machine-readable enough that AI systems cite it as an authoritative source. That’s Generative Engine Optimization at the infrastructure level, not the content level.
2. WordPress 7.0 across the entire knowledge cluster. All five sites — bcesg.org, restorationintel.com, riskcoveragehub.com, continuityhub.org, and healthcarefacilityhub.org — upgraded from WP 6.9.4 to 7.0. Why does this matter? Because WordPress 7.0 ships the Abilities API: agent-to-agent communication endpoints. That means my Claude-powered content pipelines can now negotiate directly with WordPress about what they’re allowed to do, without me acting as the middleware. The cluster just became AI-native infrastructure.
3. The stack around it. RankMath SEO installed with the schema module deliberately disabled — because the custom plugin handles schema, and two schema systems fighting each other is worse than none at all. IndexNow for instant search engine notification on every publish and update. Microsoft Clarity for behavioral analytics so I can see what humans actually do when they land on AI-optimized content.
And here’s the detail that would have been impossible to explain six months ago: the peer review on the bcesg-knowledge-api plugin was done by Claude Fable 5 reviewing the code that Claude Opus wrote. AI reviewing AI’s code. In production. On a live WordPress cluster. That’s not a demo — that’s Tuesday.
OpenAI’s S-1 and the $965 Billion Elephant
What the split means for operators building agents.
OpenAI filed a confidential S-1 with the SEC. They’re going public. Meanwhile, Anthropic hit a $965 billion valuation. These two facts, side by side, tell you everything about where the money thinks AI is going: it’s going to be the most valuable infrastructure layer since cloud computing, and the market is pricing it that way before most businesses have figured out how to use it.
For small business owners and agency operators, this isn’t abstract finance news. It means the tools you’re using today — Claude, GPT, Gemini — are backed by companies with enough capital to keep shipping improvements for years. The platform risk isn’t that these companies disappear. The platform risk is that you don’t build on them fast enough and your competitors do.
AI Passed the Turing Test. Now What?
A UC San Diego study published in PNAS confirmed that OpenAI’s GPT-4.5 and Meta’s Llama-3.1-405B both passed a standard three-party Turing test — with GPT-4.5 being identified as human 73% of the time when given a persona prompt, significantly more often than actual human participants. This has been treated as a milestone headline, and it is one, but the practical implication is more subtle than “AI can fool humans.”
What it actually means: the content quality bar just moved permanently. If AI can produce text that’s indistinguishable from a human expert, then the only content that wins is content with something AI can’t fake — lived experience, proprietary data, operational specifics, the kind of “I shipped this yesterday and here’s what happened” detail that no model can generate from training data. This is why I write The Signal as field notes, not as analysis. Analysis can be generated. Field notes from the arena cannot.
Chrome WebMCP: The Browser Becomes an AI Endpoint
Google shipped the Chrome WebMCP API in Origin Trial for Chrome 149 through 156. The Model Context Protocol — the same protocol that lets Claude connect to external tools, databases, and APIs — is now a browser-native capability. Web applications can expose structured tool interfaces that AI models call directly.
This is a bigger deal than it sounds. Right now, when Claude interacts with a web application, it’s either through a dedicated MCP server or through browser automation (clicking pixels on a screen like a human would). WebMCP means any web app can define a structured API surface that AI agents consume natively. For agencies building client tools, this is the moment your internal dashboards and client portals become AI-ready without a full backend rewrite.
If you’re running WordPress sites — and 43% of the web is — this has direct implications for how AI agents interact with your content management layer. The gap between “website” and “AI-accessible knowledge base” just narrowed dramatically.
The GPU Infrastructure Play: xAI Becomes an AI REIT
Elon Musk’s xAI, home of Grok, is increasingly looking less like an AI model company and more like a GPU real estate investment trust. They’re partnering with both Anthropic and Google to provide compute infrastructure. This is the clearest sign yet that the AI industry is stratifying into two distinct layers: model companies (who build the brains) and infrastructure companies (who build the data centers those brains run in).
For builders, this is good news. More compute supply means more pricing competition means lower API costs over time. The $10/$50 per million tokens for Fable 5 today will look expensive in 18 months.
The Security Layer Nobody’s Talking About
HashiCorp announced Boundary for agentic AI — access security specifically designed for AI agents that need to authenticate across multiple systems. And MemPalace shipped a local-first AI memory system with 96.6% recall accuracy and 29 MCP tools for Claude Code.
These aren’t headline products. They’re infrastructure connective tissue. When AI agents can securely authenticate across your entire tool stack (HashiCorp Boundary) and maintain persistent memory across sessions (MemPalace), you stop using AI for one-off tasks and start using it as a persistent operational layer. That’s the transition my agency is making right now — from “Claude helps me write articles” to “Claude runs the content pipeline while I focus on strategy.”
What This All Means: The Two-Lane Highway
Here’s the pattern I see when I lay these signals side by side:
Lane 1: The AI product lane. This is where most people are. They use ChatGPT to draft emails. They ask Claude to summarize documents. They treat AI as a productivity tool, like a faster Google or a better autocomplete. This lane is getting crowded, commoditized, and — with the Turing test results — increasingly indistinguishable from one provider to the next.
Lane 2: The AI infrastructure lane. This is where the alpha is. Custom schema engines. Agent-to-agent communication via the WordPress Abilities API. Browser-native MCP endpoints. Persistent AI memory. Secure multi-system authentication for autonomous agents. This lane is where you stop using AI and start building on AI — where it becomes the foundation layer of your operations, not an add-on.
The gap between these two lanes is widening every day. Today’s eight signals all point the same direction: toward a world where the businesses that win aren’t the ones that use AI tools the best, but the ones that build AI infrastructure the fastest.
I’m building in Lane 2. Yesterday it was a custom schema engine and a WordPress 7.0 cluster upgrade. Today it’s field-testing Fable 5 as a code reviewer. Tomorrow it’ll be whatever the next signal demands.
The question isn’t whether AI is going to transform your industry. That’s settled. The question is whether you’re in the arena building the infrastructure, or on the sidelines reading about people who are.
What is Claude Fable 5 and how does it differ from Claude Opus?
Claude Fable 5 is Anthropic’s first publicly available Mythos-class AI model, released June 9, 2026. It sits a tier above Claude Opus in capability, priced at $10 per million input tokens and $50 per million output tokens. Fable 5 is state-of-the-art on nearly all tested benchmarks and includes built-in safeguards that route certain queries to Opus 4.8, triggering in less than 5% of sessions. It’s available free on subscription plans through June 22, 2026.
What is the Chrome WebMCP API and why does it matter for businesses?
The Chrome WebMCP API, now in Origin Trial for Chrome versions 149 through 156, brings the Model Context Protocol natively into the browser. This allows web applications to expose structured tool interfaces that AI models can call directly — eliminating the need for dedicated backend integrations or browser automation. For businesses running web-based tools, dashboards, or WordPress sites, this means your existing applications can become AI-accessible without a full rebuild.
What is the WordPress 7.0 Abilities API?
The WordPress 7.0 Abilities API provides agent-to-agent communication endpoints, allowing AI-powered systems to negotiate capabilities and permissions directly with a WordPress installation. This transforms WordPress from a content management system into AI-native infrastructure where automated pipelines can query what operations they’re authorized to perform without human middleware.
What does AI passing the Turing test mean for content creators?
A UC San Diego study published in PNAS found that OpenAI’s GPT-4.5 and Meta’s Llama-3.1-405B both passed a standard three-party Turing test in 2026 — GPT-4.5 was identified as human 73% of the time with persona prompting. For content creators, this permanently raises the quality bar — the only content that wins is content with elements AI cannot fake: lived experience, proprietary data, operational specifics, and first-person field reports that no model can generate from training data alone.
What is Generative Engine Optimization (GEO) and how does it work?
Generative Engine Optimization is the practice of structuring web content so AI systems — including ChatGPT, Claude, Gemini, Perplexity, and Google AI Overviews — cite, reference, and recommend it. GEO involves entity enrichment, structured data (JSON-LD schema), authoritative citations, and machine-readable formatting. Unlike traditional SEO which targets search engine crawlers, GEO targets the large language models that increasingly mediate how users discover information.
How should small businesses approach AI infrastructure in 2026?
Start by moving from Lane 1 (using AI as a productivity tool) to Lane 2 (building AI into your operational infrastructure). Practical first steps include implementing structured data and schema markup on your website, setting up AI-optimized content pipelines, ensuring your site is crawlable by AI systems via protocols like LLMS.txt, and testing agentic workflows where AI handles multi-step operational tasks autonomously rather than single-prompt interactions.
What is a custom schema engine and why build one instead of using plugins?
A custom schema engine is a purpose-built WordPress plugin that generates structured data (JSON-LD) tailored to specific business objectives — in this case, AI citation optimization. Unlike off-the-shelf schema plugins that generate generic markup, a custom engine outputs precisely the entity relationships, author signals, and speakable content markers that AI systems use when deciding which sources to cite. The bcesg-knowledge-api plugin generates a seven-type @graph array from 13 custom meta fields, providing a level of control that no general-purpose plugin offers.
What is the significance of AI reviewing AI-written code in production?
When Claude Fable 5 peer-reviewed code written by Claude Opus for a production WordPress plugin, it demonstrated a mature AI development workflow where different model tiers serve different roles — one for generation, another for quality assurance. This mirrors human development practices (developer writes, senior reviews) but at machine speed and cost. It’s a practical example of how AI agent collaboration is already operational in real business infrastructure, not just research demos.
The Signal is published daily on Tygart Media by Will Tygart. Each edition distills the day’s most consequential AI, search, and technology developments into actionable intelligence for agencies, small business operators, and builders shipping real AI infrastructure.
Everything you need to know about Anthropic’s new frontier tier — pricing, context window, model comparisons, and how to route the right work to the right model.
Updated November 2026 · ~14 min read · Includes interactive calculators
Lineup update (November 2026): Since this guide was last fully updated, Anthropic shipped Opus 5.5 ($4/MTok in, $20/MTok out) and Sonnet 5.5 ($2/MTok in, $10/MTok out) as its current flagship and mid-tier models, with Haiku 5.5 ($0.10/$0.50) as the current small model. Fable 5.1 remains the top-tier model referenced throughout, at the same $10/$50 pricing shown below. Opus 4.8 and Sonnet 4.6 are now legacy — still supported, no longer current default.
What Is Claude Fable 5?
What is Claude Fable 5?
Claude Fable 5 is Anthropic’s new frontier model tier — positioned above Opus in the lineup and designed for tasks where raw capability, extended reasoning depth, and massive context handling matter more than cost. Where Opus 4.8 set the bar for complex multi-step reasoning, Fable 5 raises it with a 1-million-token context window, enhanced agentic autonomy, and improved performance on long-horizon software engineering, research synthesis, and cross-domain analysis tasks.
The “Fable” naming signals a new generation of model architecture rather than an incremental update. Anthropic positions it as the model you reach for when a task exceeds what Opus can do reliably — not as a replacement for Opus, Sonnet, or Haiku in their respective cost tiers.
Quick Facts — Claude Fable 5
Context Window
1M
tokens (~750K words)
Max Output
32K
tokens per response
Input Price
$10
per million tokens
Output Price
$50
per million tokens
Cache Write
$12.50
per million tokens
Cache Read
$1.00
per million tokens
Key positioning: Fable 5 is the model for tasks where Opus 4.8 produces reliable but imperfect results — long codebase audits, full-document analysis, complex multi-agent orchestration, and strategic synthesis across large corpora. For most production workflows, Sonnet remains the value pick.
Before you price this out: The table below reflects the June 2026 lineup (Fable 5, Opus 4.8, Sonnet 4.6, Haiku 4.5). As of November 2026, the current four are Fable 5.1, Opus 5.5 ($4/$20), Sonnet 5.5 ($2/$10), and Haiku 5.5 — priced lower than the legacy Opus 4.8 / Sonnet 4.6 rows shown here.
Full Model Lineup Comparison
Full model lineup comparison.
Here’s how the complete 2026 Claude lineup stacks up across every dimension that matters for production usage:
Model
Input $/M
Output $/M
Context
Max Out
Vision
Tool Use
Extended Think
Best For
◆ Fable 5
$10
$50
1M
32K
✓
✓
✓ Deep
Max-capability tasks, 1M+ context
◆ Opus 4.8
$5
$25
200K
32K
✓
✓
✓
Complex reasoning, agentic workflows
◆ Sonnet 4.6
$3
$15
200K
16K
✓
✓
✓
Production apps, content at scale
◆ Haiku 4.5
$1
$5
200K
8K
✓
✓
—
High-volume, latency-sensitive tasks
Prices are per million tokens. Cache reads cost 0.1x standard input on most models, 0.05x on Opus 5.5 and Sonnet 5.5, and 0.025x on Fable 5.1. Batch API provides an additional 50% discount on both input and output.
Capability Matrix — What Each Model Can Do
Capability
Fable 5
Opus 4.8
Sonnet 4.6
Haiku 4.5
Full codebase analysis (>500K tokens)
✓ Native
⚠ Chunked
✗
✗
Extended thinking / chain-of-thought
✓ Deep
✓
✓
✗
Multi-step agentic orchestration
✓ Best
✓
Good
Limited
Computer use
✓
✓
✓
✗
MCP tool integration
✓
✓
✓
✓
Prompt caching
✓
✓
✓
✓
Batch API (50% discount)
✓
✓
✓
✓
PDF / document analysis
✓
✓
✓
Limited
Real-time streaming
✓
✓
✓
✓
Structured JSON output
✓
✓
✓
✓
Interactive Cost Calculator
Estimate your monthly API spend across the full model lineup. Enter your token volumes below — the calculator models prompt caching and Batch API discounts automatically.
Token Cost Calculator
Estimated Monthly Cost
$0.00
Which Claude Model Should You Use?
Which Claude model should you use?
Answer three questions to get a model recommendation tailored to your use case.
Model Picker — 3 Questions
1. How large is your context? (document/codebase size)
Under 50K tokens
50K–200K tokens
200K–1M tokens
2. How complex is the task?
Simple / structured (classify, extract, format)
Moderate (draft, summarize, QA)
Complex (reason, plan, code, orchestrate)
3. How cost-sensitive is this workload?
Very — high volume, every cent counts
Moderate — quality matters more than cost
Not sensitive — quality and capability first
How We Actually Use Each Model
These are real production workflows mapped to the right tier — built from running Claude in content operations, publishing automation, and knowledge management at scale. No hypotheticals.
Haiku 4.5 — High Volume
Daily SEO Refresh Pipeline
25-post-per-day SEO metadata refresh
Article classification and tag assignment
Structured data extraction from web pages
Keyword density checks across large post archives
Link validation and redirect flagging
Sonnet 4.6 — Production Default
Editorial Content at Scale
Desk article writing (1,200–2,500 words)
Content brief execution from keyword clusters
FAQ and schema markup generation
Cross-site content adaptation and localization
Monthly client update drafts and summaries
Opus 4.8 — Complex Reasoning
Workers & Deep Refreshes
Agentic Notion Workers (multi-step pipelines)
Deep content refresh with competitive gap analysis
Multi-database synthesis and reporting
Strategy documents requiring extended reasoning
Code generation for automation scripts
Fable 5 — Max Capability
Portfolio Audits & Strategy
Full-site content audits (500+ posts in single context)
Cross-domain strategy synthesis across large corpora
Complex multi-agent orchestration at the flagship tier
Long-horizon planning requiring deep reasoning depth
Codebase-wide analysis and architecture review
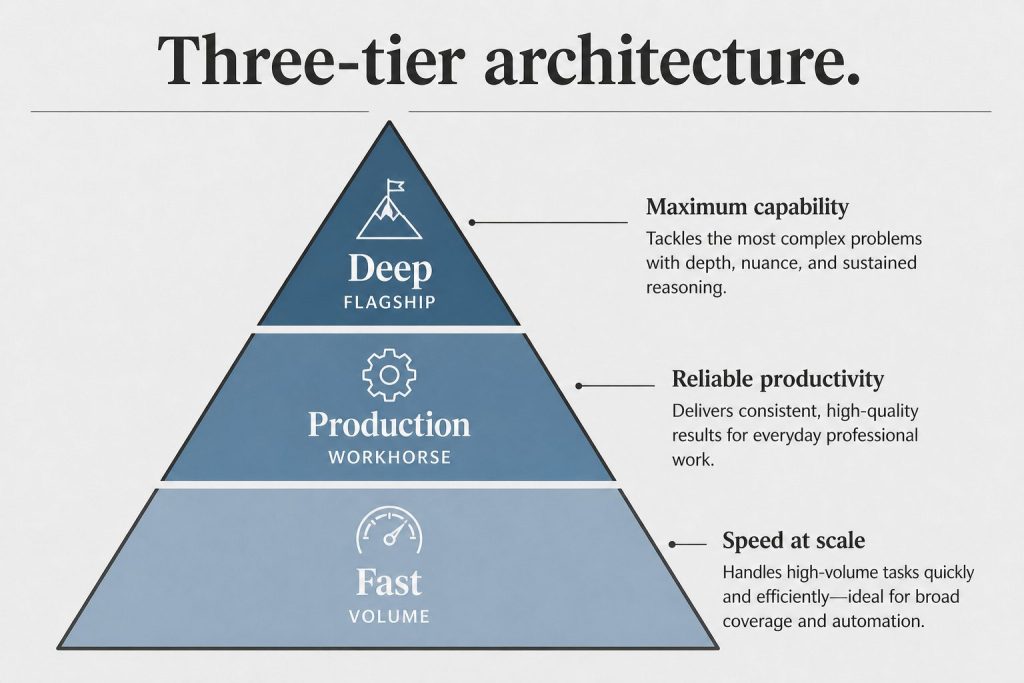
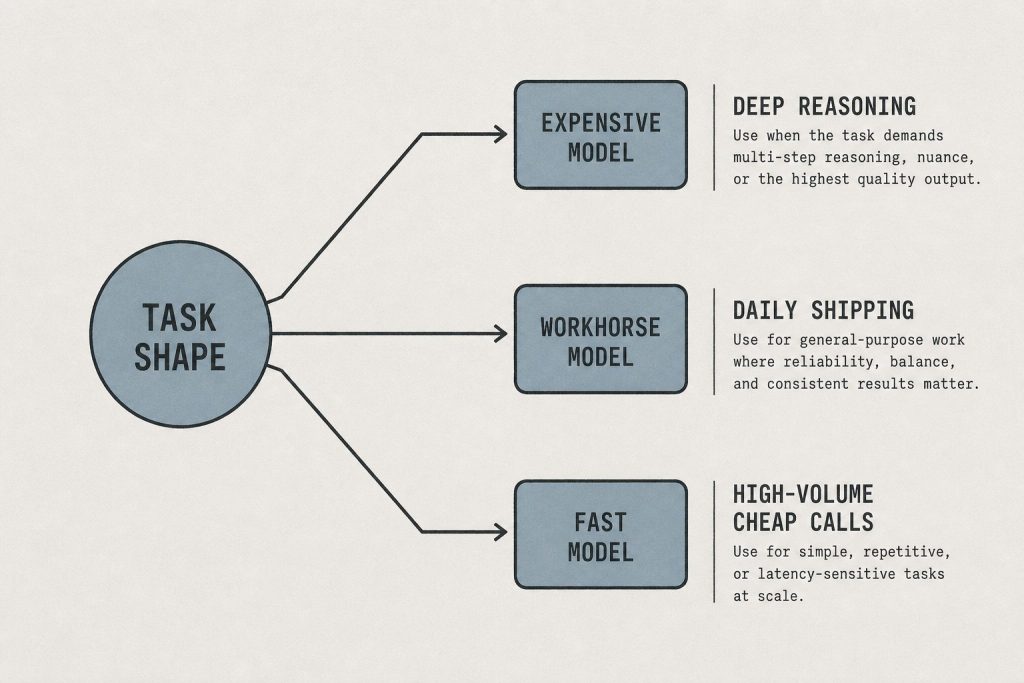
Routing principle: The right model is the cheapest one that reliably completes the task. Haiku handles volume. Sonnet handles production. Opus handles complexity. Fable 5 handles scale + complexity together — specifically the cases where you’d need Opus and more context than Opus can hold.
The Economics: Routed vs All-Fable
Smart model routing is where API costs get controlled. Here’s a real-world comparison of a mixed content-and-automation workload at scale — routed vs running everything on Fable 5.
Workload
Monthly Volume
Routed Model
Routed Cost
All-Fable 5 Cost
Savings
SEO metadata batch refresh
750 posts/mo
Haiku 4.5 + Batch
$1.20
$18.75
93% less
Article drafting
90 articles/mo
Sonnet 4.6
$8.10
$67.50
88% less
Agentic worker runs
200 runs/mo
Opus 4.8
$22.50
$45.00
50% less
Full-site portfolio audits
4 audits/mo
Fable 5
$24.00
$24.00
—
Total
—
Routed
$55.80
$155.25
64% less
Stacking Discounts: Caching + Batch API
Two discount mechanisms compound independently:
Prompt caching: Cache your system prompt and shared context once. Subsequent requests pay ~10% of the input price for cache reads. On Fable 5, that’s $1.00/M instead of $10.00/M on cached tokens — a 90% reduction on your largest cost lever.
Batch API: Submit requests asynchronously (results within 24 hours) for a flat 50% discount on both input and output. Works on all four models. Best for non-real-time workloads like overnight refreshes, audits, or bulk classification.
Stacked: Caching + Batch combined can bring effective Fable 5 input cost from $10/M to ~$0.50/M on cached tokens — making it economically viable for high-volume tasks that previously only fit Haiku’s budget.
Claude Fable 5 sits above Opus 4.8 in the lineup. The primary difference is context window size — Fable 5 offers 1 million tokens vs Opus 4.8’s 200K — and the depth of extended reasoning for highly complex tasks. Opus 4.8 remains the right choice for most complex agentic workflows at half the cost. Fable 5 is best when you need both maximum context and maximum reasoning depth simultaneously, or when a task has routinely hit the limits of what Opus can do reliably.
Claude Fable 5 is priced at $10 per million input tokens and $50 per million output tokens — 2× Opus 4.8 ($5/$25), 3.3× Sonnet 4.6 ($3/$15), and 10× Haiku 4.5 ($1/$5). Prompt caching drops the effective input cost to $1.00/M on cache reads, and the Batch API adds a 50% discount on all tokens for non-real-time workloads. Stacking both discounts makes Fable 5 viable for higher-volume use cases than the base price suggests.
Claude Fable 5 has a 1-million-token context window — approximately 750,000 words or roughly 1,500 pages of text. This is 5× the context window of Opus 4.8, Sonnet 4.6, and Haiku 4.5 (all 200K). In practice, a 1M context window lets you pass entire codebases, long research corpora, or full document archives in a single API call without chunking or retrieval workarounds. For more on context window mechanics, see our full context window guide.
Yes. Claude Fable 5 is available through the Anthropic API using the model ID claude-fable-5-20260101 (check the Anthropic documentation for the exact identifier). It supports the same API surface as the rest of the Claude family — streaming, tool use, prompt caching, vision, the Batch API, and MCP server integration. Access requires an Anthropic API account with Fable 5 enabled on your usage tier.
Fable 5 is available in Claude.ai on the Pro and Team plans. The interface lets you select it from the model picker when starting a conversation. Like Opus, Fable 5 in claude.ai has message limits that reset on a rolling window — it’s designed for individual complex tasks rather than high-volume API workloads. For production-scale usage, the API with the Batch API discount is the more economical path.
Yes — and Fable 5’s extended thinking is the deepest in the lineup. Where Opus 4.8 supports extended thinking for complex reasoning tasks, Fable 5 uses a more capable reasoning engine designed for tasks that require longer chains of inference, more working memory, and more reliable self-correction. It’s particularly effective on math, logic, long-horizon planning, and tasks where the model needs to hold and manipulate many interdependent concepts simultaneously.
For most content production — articles, blog posts, social copy, summaries, SEO content — Sonnet 4.6 is the right call. It produces high-quality output at 3.3× less cost than Fable 5, and for typical content lengths (500–3,000 words), the quality difference is minimal. Reach for Fable 5 when you need to synthesize across a very large corpus (e.g., auditing 200+ posts simultaneously), when the content requires deep domain reasoning that benefits from extended thinking, or when the task involves both large-context ingestion and complex output generation in a single pass.
Three levers in order of impact: (1) Model routing — only use Fable 5 when the task genuinely requires it; route everything else to Opus, Sonnet, or Haiku based on complexity and volume. (2) Prompt caching — structure your system prompt and shared context so it can be cached; cache reads cost $1.00/M instead of $10.00/M on Fable 5. (3) Batch API — submit non-real-time workloads via the Batch API for a flat 50% discount. Stacking all three — routing + caching + batch — can reduce effective per-task costs by 85–95% compared to unoptimized Fable 5 calls.
More Claude Guides from Tygart Media
We run Claude in production every day. These are the guides that come from using it, not just writing about it.
Direct Answer (9 September 2026): Claude Cowork is the desktop workspace in the Claude app. It works on local files and apps you approve. It is not Chat and it is not the Chrome extension. Use Chat when the job is a conversation. Use Cowork when the job is a folder, a document, or a multi-step desktop workflow. It ships on Pro, Max, Team, and Enterprise — not Free.
Claude Cowork lets Claude work on the machine, not just talk about the work. Last verified 9 September 2026.
Chat vs Cowork vs Chrome
Chat — conversation, no local workspace.
Cowork — local files, Skills, desktop workflows in the Claude app.
Chrome extension — the page in the browser. Separate install. See Claude in Chrome.
Claude Cowork missing HCS services — the local helper stack did not start. Quit the Claude app, confirm disk space, relaunch. If it persists, reinstall the desktop app. Do not treat this as a chat usage-limit.
Failed to start Claude’s workspace / not enough disk space — free space on the volume that holds the workspace, then retry. Cowork and Code spin their own copy of the server.
Couldn’t start this server for Cowork and Code sessions — same class. The session runner failed to boot. Restart the app; do not keep retrying from Chat.
Cowork not working — confirm you are in the desktop app on a paid seat, not claude.ai Chat and not the Chrome side panel.
How Cowork works
How Cowork mode works.
In the desktop app Claude can read folders you grant, write documents, run Skills, and call MCP tools. Actions ask for approval. It is not a silent screen-scraper.
What it can automate
File management, document creation (DOCX, XLSX, PPTX, PDF), data cleanup, and cross-app handoffs you approve. It is not a replacement for Claude Code on a repo.
Cowork vs Claude Code
Code is the terminal path for developers. Cowork is the visual path for operators. Both sit on Pro / Max / Team / Enterprise. Matrix: Cowork vs Code vs Agent SDK.
Getting started
Install the Claude desktop app. Open a Cowork session. Grant the folder. Describe the job. Approve the first file write before you let it run a batch.
Frequently Asked Questions
What is Claude Cowork?
Desktop workspace in the Claude app for files and local workflows.
Updated November 2, 2026 — added direct answers on Claude Pro vs Claude Max pricing and limits, sourced from Anthropic’s published pricing.
Last verified: November 5, 2026 (Pacific).
Updated October 28, 2026: Made infographic diagrams clickable to open full-size images.
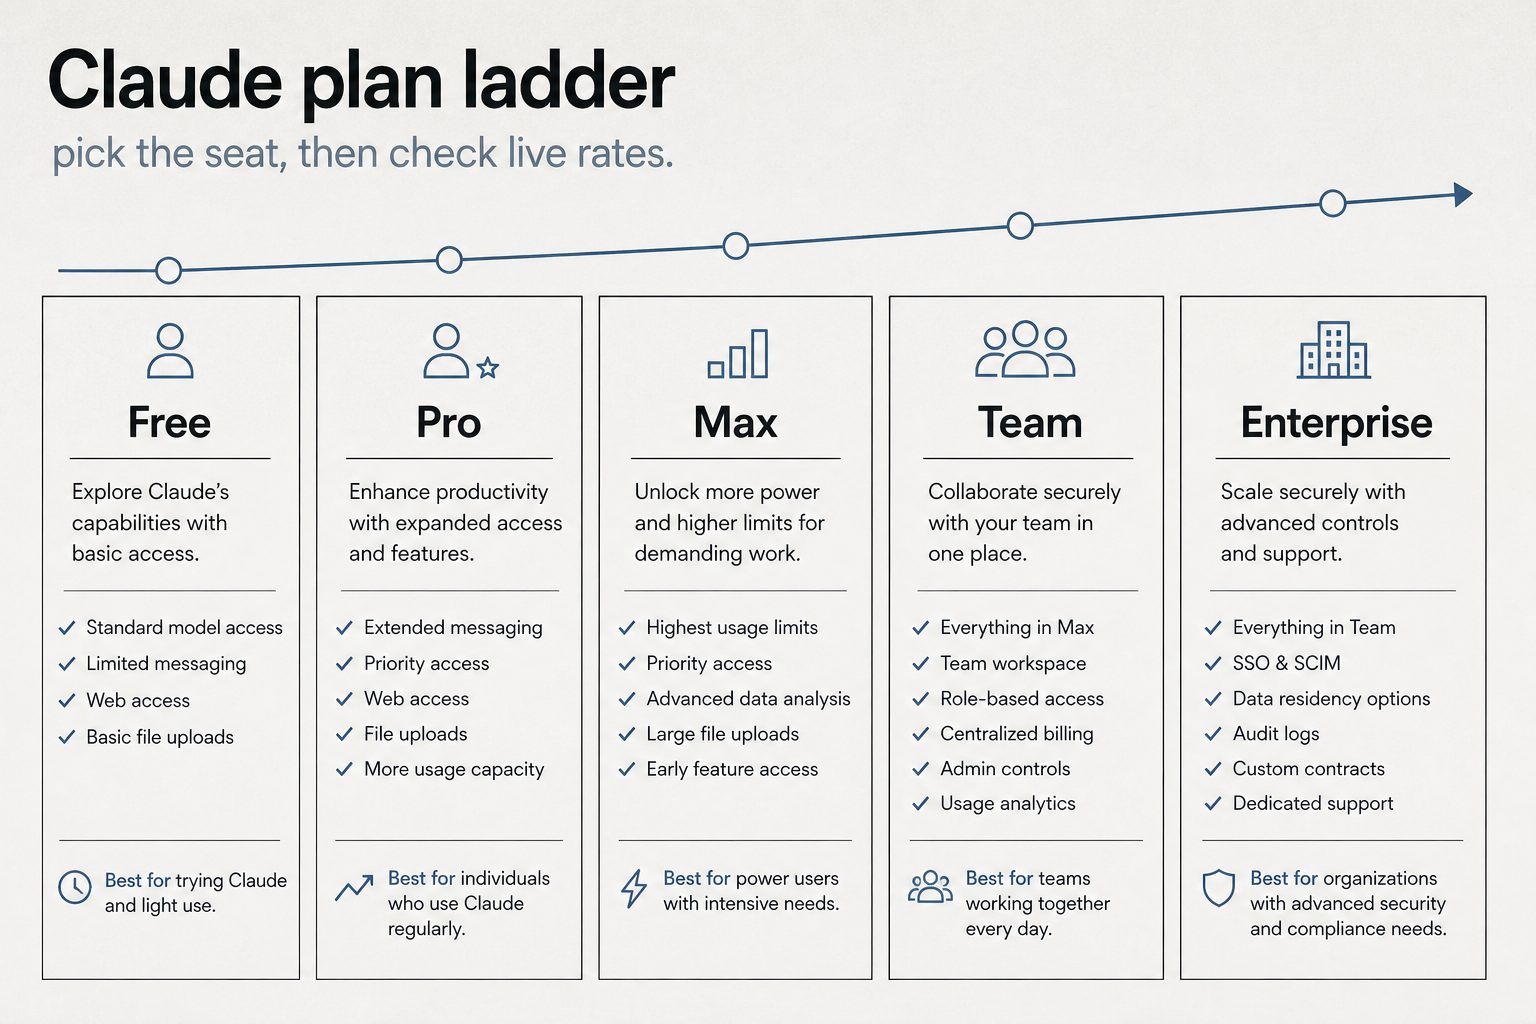
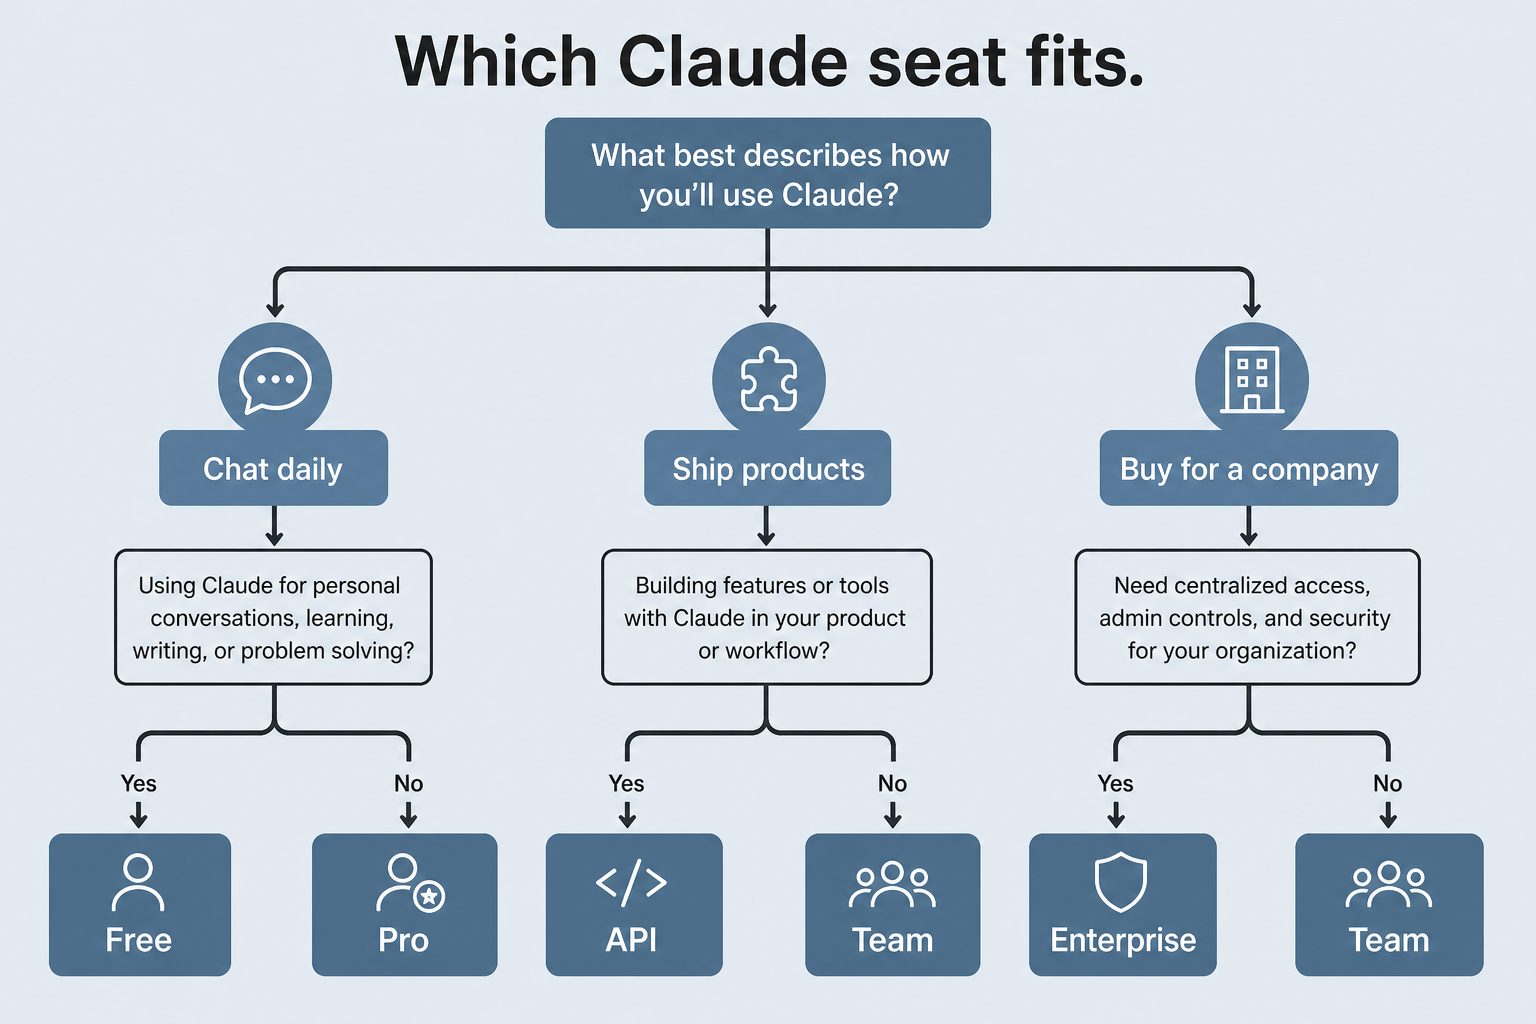
Claude Pro costs $20/month. Claude Max costs $100/month; Ultra costs $200/month. The question everyone asks: is 5x or 10x the price actually worth it? The answer depends entirely on how you use Claude. This comparison breaks down the real differences — not the marketing bullet points — so you can make an informed decision.
Pro at $20/month ($17/month annual) includes Claude Code, Claude Cowork, unlimited Projects, Research mode, access to additional models, and Claude for Microsoft 365 and Outlook. The usage allowance is described as “more usage” compared to Free — in practice, this means you can have sustained conversations throughout a workday without hitting limits under normal use. Most professionals who use Claude as a daily tool — a few hours of active conversation per day — find Pro sufficient.
What Max Adds
What Max adds.
Max and Ultra are separate plans. The $100/month tier gives approximately 5x the usage of Pro. The $200/month Ultra tier gives 10x Pro weekly usage. Beyond the usage multiplier, Max adds three concrete features: higher output limits for all tasks (longer responses, more complex code generation), early access to advanced Claude features before they reach Pro users, and priority access during high-traffic periods (you skip the queue).
The Fable factor: Max’s real exclusive
Direct answer: Max is now the only individual plan that includes Anthropic’s Fable models. On Pro, every Fable token runs on usage credits; on Max and Ultra, Fable is included up to half the weekly usage pool. If your work benefits from Fable — long-horizon agent loops with heavy cache reuse — this alone can decide the plan. Our Fable 5 pricing guide breaks down the $10/$50 headline rates and the 75% cache-read cut that Fable 5.1 brought on September 1.
Who Actually Needs Max
Who actually needs Max.
Heavy Claude Code users: If you spend 4+ hours per day actively using Claude Code for development — not just coding, but running extended agent sessions, multi-file refactoring, and complex debugging — you’ll likely hit Pro limits. Max 5x removes this friction. Content production teams: If you’re producing 10+ pieces of content per day through Claude, the usage adds up fast. Researchers and analysts: Extended research sessions with multiple deep-dive conversations consume significant tokens. Anyone who hits Pro limits regularly: If you see the “usage limit reached” message more than once or twice per week, Max pays for itself in recovered productivity.
Who Should Stay on Pro
Most individual professionals: If you use Claude for 1-3 hours per day with normal conversation patterns, Pro is plenty. Occasional users: If Claude is one of many tools in your workflow rather than the central one, Pro is more than enough. Budget-conscious users: At $20/month, Pro delivers extraordinary value. The jump to $100/month should be justified by measurable productivity gains. Users who haven’t hit Pro limits: If you’ve never seen the usage limit message, you don’t need Max.
When you hit the wall: usage credits
One newer mechanic worth knowing before you upgrade: when a paid plan hits its usage limit, usage credits keep Claude working at standard API rates instead of making you wait for the 5-hour reset window. Credits are pay-as-you-go on top of the subscription — the middle path for spiky weeks where one heavy project doesn’t justify a whole tier upgrade. If you hit Pro limits twice a month rather than twice a week, credits are usually cheaper than Max.
The Math on Max
Max 5x costs $80/month more than Pro. If that additional usage saves you 2+ hours per week of productivity (waiting for limits to reset, or time spent on tasks you could have delegated to Claude), and your time is worth $40+/hour, Max pays for itself. Ultra at $200/month ($180 more than Pro) needs to save roughly 4.5 hours/week to break even at $40/hour. The early access and priority features are hard to quantify financially — they matter most for users who need Claude reliably during peak demand.
A Better Strategy Than Max
Before upgrading to Max, consider whether your usage patterns can be optimized on Pro. Use Projects to maintain context instead of repeating background in every conversation. Be concise in prompts — verbose prompts consume more tokens. Use the appropriate model (Haiku for simple tasks, Sonnet for standard work, Opus for complex reasoning). Close conversations you’re done with rather than continuing indefinitely. If you’re hitting limits despite these optimizations, Max is the right move.
How Claude usage limits actually work
Claude usage limits reset on a rolling five-hour window, and paid plans add weekly limits on top of that. There is no fixed number of messages.
On claude.com/pricing, checked November 5, 2026, Free covers everyday questions. Pro includes at least 5x more usage per five-hour session than Free. Max includes 5x Pro usage; Ultra provides 10x Pro weekly usage with no 5-hour limit for verified accounts. Max costs $100 per month with 5x Pro usage; Ultra costs $200 per month with 10x Pro weekly usage. Chat on the web, the desktop app, mobile, and Claude Code all draw from the same pool.
What spends the allowance is the work itself. A longer conversation, a heavier model, file creation, or research uses more of the window than a short question. Anthropic also says it may apply weekly or monthly caps, or limits on a specific model or feature, so one account does not crowd out everyone else. On the plan table, Fable is unavailable on Free, listed as usage credits on Pro, and listed as 50% of weekly limits on Max and Ultra.
When a limit hits, the same page gives three moves: wait for the reset, move to a higher plan, or, on a paid plan, turn on usage credits and keep working at standard API rates. Settings, then Usage, shows the current status. Team seats use a different meter. A standard seat includes more usage than Pro, at $20 per seat per month billed annually or $25 billed monthly. A premium seat includes 5x the usage of a standard seat, at $100 per seat per month billed annually or $125 billed monthly.
A Claude API bill is input tokens plus output tokens, and output costs more than input on every current model. Prices below are US dollars per million tokens. Pricing checked November 5, 2026.
Fable 5.1: $10 input, $50 output
Opus 5.5: $4 input, $20 output
Sonnet 5.5: $2 input, $10 output
Haiku 5.5: $0.10 input, $0.50 output (up to 100k prompts)
The official table also lists older and retired models. Those rows are omitted here. Sonnet 5 is the same $2 input and $10 output as Sonnet 5.5, and Anthropic says the increase to $3 and $15 that had been scheduled for September 1, 2026 will not happen.
The model and the length of the reply do most of the damage. Output is five times the input price on each model above, so an agent that writes a long diff costs more than one that only reads. Three other switches change the same rates. The Batch API takes 50% off input and output when the job can wait: Fable 5.1 batch is $5 and $25, Opus 5.5 is $2 and $10, Sonnet 5.5 is $1 and $5, and Haiku 5.5 is $0.05 and $0.25. US-only inference on Claude 4.6 and later multiplies input, output, cache writes, and cache reads by 1.1. Fast mode, still a research preview, prices Opus 5.5 at $8 input and $40 output, and Opus 5 or Opus 4.8 at $10 and $50. Fast mode does not run on the Batch API.
Claude 4.6 and later include the full 1 million token context window at that same per-token rate. A 900,000-token request is billed at the same rate per token as a 9,000-token request. Claude 4.7 and later, and Mythos Preview, use a newer tokenizer that produces about 30% more tokens for the same text, so an unchanged document can cost more after a model move. Sonnet 4.6 and earlier use the previous tokenizer.
Tools add their own lines. The pricing page lists web search at $10 per 1,000 searches, separate from the tokens used to process the request. Code execution includes 50 free hours a day per organization, then $0.05 per hour per container.
Prompt caching saves money when the same long prefix is sent again inside a short window. You pay extra to store that prefix, then a fraction of the normal input price each time a later request reads it.
Anthropic’s docs, checked November 5, 2026, price a 5-minute cache write at 1.25 times the base input price and a 1-hour cache write at 2 times. A cache hit on most models costs 10% of the standard input price. The docs say 5-minute caching pays for itself after one cache read, and 1-hour caching pays for itself after two cache reads. Two current models are cheaper on the read: Fable 5.1 and Mythos 5.1 hits are $0.25 per million tokens, which is 2.5% of base input, and Opus 5.5 hits are $0.20 per million tokens, which is 5% of base input. On the standard table, a 5-minute write is $12.50 for Fable 5.1, $5 for Opus 5.5, $2.50 for Sonnet 5.5, and $0.125 for Haiku 5.5. A 1-hour write on those models is $20, $8, $4, and $0.20.
The buyers who come out ahead repeat a prefix: a long system prompt, a tool list, a standing document, or an agent loop that reloads the same context every turn. A one-off short chat has nothing to reuse. Cache writes are charged when the prefix is first stored. Cache reads are charged when a later request retrieves it, and a read also refreshes the entry. Those multipliers stack with the Batch API discount and with the 1.1x US-inference multiplier.
At the everyday paid chat tier, Claude Pro and ChatGPT Plus are both $20 a month. Above that, compare the usage multiple on the plan, and price the API separately from the subscription.
Checked November 5, 2026. Claude lists Free at $0, Pro at $20 a month or $17 a month when $200 is billed up front for the year, and Max from $100 a month with 5x Pro usage, and Ultra at $200 a month with 10x Pro weekly usage. OpenAI’s Help Center lists ChatGPT Plus at $20 a month, billed monthly, and two Pro tiers: $100 for 5x the usage of Plus, and $200 for 20x the usage of Plus. The Plus article says API usage is billed separately. ChatGPT Go appears as a lower plan; a current Go dollar price was not on the pages read for this check.
The meters differ even when the monthly price lines up. Claude draws web, desktop, mobile, and Claude Code from one pool, on a rolling five-hour window, with weekly limits added on paid plans. OpenAI’s Pro article says models can have separate allowances, and reaching one model’s allowance does not by itself end the plan. Pick the product whose limit matches the work.
API rates below are the standard paid tier, in US dollars per million tokens, from the same November 5, 2026 check. Where a vendor publishes a short-context rate and a long-context rate, both are included.
Claude Haiku 5.5 is $0.10 input and $0.50 output (up to 100k prompts). Sonnet 5.5 is $2 and $10. Opus 5.5 is $4 and $20. Fable 5.1 is $10 and $50. Claude 4.6 and later keep that per-token rate through a 1 million token context window.
On OpenAI’s standard tab, gpt-6-luna is $0.10 input and $0.50 output for short context, and $0.20 and $0.75 for long context. gpt-6.1-sol is $2 and $10 short, and $4 and $15 long. gpt-6-astra is $10 and $50 short, and $20 and $75 long. The same page also publishes Batch, Flex, Fast, and Ultrafast rates.
On Google’s Gemini API, standard paid, Gemini 3.8 Flash is $0.75 input and $3.75 output through December 31, 2026, then $1.50 and $7.50. Gemini 3.1 Pro Preview is $2 input and $12 output on prompts up to 200,000 tokens, and $4 and $18 above that. Gemini’s output price includes thinking tokens.
The useful comparison is the shape of the bill. On all three, output tokens cost more than input tokens. OpenAI’s flagship models and Gemini 3.1 Pro Preview raise the per-token rate once a prompt crosses their long-context line. Claude’s current models keep one rate inside the 1 million token window. A repeated prefix is discounted on each platform under that platform’s own cache rules.
What is the difference between Claude Pro and Claude Max?
The primary difference between Claude Pro and Claude Max is capacity, monthly usage headroom, and bundled developer credits on identical underlying models. Anthropic prices Claude Pro at $20 per month (or $17 per month when billed annually at $200 upfront). Claude Max is priced at $100 per month, delivering an official 5x usage multiplier over Pro across both the 5-hour rolling session window and the weekly account cap.
Beyond session headroom, Claude Max includes $100 per month in Claude Platform API credits, priority access during peak network traffic times, early access to new Claude features, and included access to Anthropic’s flagship Fable model up to half your weekly allowance. For extreme workloads, Anthropic also offers an Ultra tier at $200 per month, providing 10x weekly usage, $200 per month in API credits, and no 5-hour limit for verified accounts.
Workload fit determines the right tier: Claude Pro fits solo professionals, writers, and analysts working 1 to 3 hours per day with moderate prompt lengths. Claude Max fits full-time developers, engineering leads running continuous Claude Code sessions, and power users who regularly hit Pro’s 5-hour rolling limits mid-task.
How much does Claude Pro cost?
Claude Pro costs $20 per month when billed monthly, or $17 per month when billed annually ($200 billed upfront). Anthropic’s published terms confirm that Pro provides substantially more usage than the Free tier across both the 5-hour session window and weekly cap, access to advanced models (Sonnet and Opus), Projects for context management, Claude Code, Claude Science, Claude Dashboards (beta), and priority bandwidth during high-traffic periods.
Is Claude Max worth it for daily coding?
For daily coding, Claude Max is worth the investment if you write software full-time and frequently run into Pro’s session-based rate limits. In daily developer workflows involving continuous terminal interactions, multi-file diffs, and iterative debugging in Claude Code, each prompt re-submits previous code turns and file context. On Claude Pro, intensive coding sessions often hit the 5-hour rolling cap within 60 to 90 minutes of active development.
The financial math on Max for coding is straightforward: Max costs $100 per month, an $80 monthly premium over Pro. That plan includes an official 5x usage multiplier across 5-hour and weekly windows, plus $100 per month in API credits to build on the Claude Platform. If avoiding interrupted coding sessions saves you just 2 hours per week of downtime, and your professional developer time is valued at $40 or more per hour, Claude Max pays for itself within the first week.
What does pay-as-you-go API usage beat a Max subscription?
Pay-as-you-go API usage beats a Claude Max subscription when your workloads are automated, bursty, or integrated directly into developer environments rather than open-ended conversational web chats. Instead of paying a flat $100 or $200 monthly subscription fee for personal seat headroom, direct API access bills only for the exact tokens your tasks consume at standard published rates (such as Claude Sonnet 5.5 at $2.00 per million input tokens and $10.00 per million output tokens, or Haiku 5.5 at $0.10 input and $0.50 output).
For programmatic scripting, IDE extensions, or scheduled batch jobs, typical developer consumption often totals $15 to $40 per month in API charges—well below the $100 per month cost of a Max seat. Furthermore, API usage unlocks prompt caching (reducing input token costs up to 90% on cached prefix reads) and Message Batches (providing an automatic 50% discount for asynchronous turnaround within 24 hours). For a detailed structural analysis of when to buy per-user seats versus consuming raw tokens, see our analysis of Seats vs API — the question models get wrong.
Frequently Asked Questions
Is Claude Max worth $100 a month?
If you regularly hit Pro usage limits — especially heavy Claude Code users, content producers, or researchers — Max pays for itself in recovered productivity. If you’ve never hit Pro limits, stay on Pro.
What is the difference between Max and Ultra?
Max ($100/month) gives 5x Pro usage. Ultra ($200/month) gives 10x Pro weekly usage with no 5-hour limit for verified accounts. Both include higher output limits, early feature access, and priority. Most users who need Max find 5x sufficient.
Can I switch between Pro and Max?
Yes. You can upgrade from Pro to Max or downgrade from Max to Pro at any time. Changes take effect on the next billing cycle.
Does Max include Claude Code?
Yes. Both Pro and Max include Claude Code. Max gives you more usage capacity for Claude Code sessions.
Does Claude Max include Fable?
Yes — Max is the only individual plan that includes Fable models, up to 50% of the weekly usage pool. On Pro, Fable usage runs on usage credits from the first token.
What are Claude usage credits?
Pay-as-you-go tokens billed at standard API rates that keep you working when a paid plan hits its limit, instead of waiting for the reset window. Ideal for occasional spike weeks.
Can I pay for Max or Ultra annually?
No. Max and Ultra are monthly billing only. Pro is the plan with an annual option — $17/month billed yearly ($200 up front).
Manage it all from the Anthropic Console — API keys, billing, and a token-to-dollar cost estimator for your actual usage.
Claude has become a core tool for content teams — not as a replacement for human writers, but as a force multiplier that changes what’s possible with limited resources. This guide covers the practical workflows that professional content creators, SEO specialists, and marketing teams use with Claude in 2026, including where it excels, where it falls short, and how to integrate it into a production content operation.
Blog Posts and Long-Form Content
Blog posts and long-form with Claude.
Claude excels at drafting long-form content when given proper direction. The key is providing a detailed brief — not just a topic, but the target keyword, the audience, the desired structure, the tone, competing content to differentiate from, and any specific data or examples to include. A well-briefed Claude request produces a first draft that’s 70-80% of the way to publishable, versus a vague request that produces generic filler.
Best practices for blog production: write a content brief first (or use Claude to help write one), include your brand voice guidelines in a Project, specify the exact structure you want (H2s and H3s), request specific word counts, and always edit the output for accuracy, originality, and brand alignment. Never publish AI-generated content without human review — this is especially important for factual claims, statistics, and technical accuracy.
SEO Content Optimization
SEO content optimization workflows.
Claude can analyze existing content for SEO improvements — identifying missing keywords, suggesting heading structure changes, improving meta descriptions, and recommending internal linking opportunities. Feed Claude your target keyword, your current content, and competitor content, and ask for specific optimization recommendations. Claude can also generate FAQ sections with structured data markup, which directly targets featured snippets and People Also Ask placements.
For new content, Claude can research keyword clusters, identify search intent, and draft content structured for both traditional SEO and emerging AI search optimization (AEO/GEO). The combination of web search capability and content generation means Claude can research a topic and draft optimized content in a single session.
Email Marketing
Claude handles email marketing content effectively — subject line variations, body copy, CTAs, and nurture sequences. The workflow that works best: share your product/service details and audience information in a Project, then request specific email types (welcome sequence, promotional, re-engagement, newsletter). Claude can generate multiple variations for A/B testing and adapt tone for different segments.
Social Media Content
Claude can repurpose long-form content into social media posts tailored for different platforms — LinkedIn articles and thought leadership posts, Twitter/X threads, Instagram captions, and Facebook updates. Provide the source content and specify the platform, tone, and any hashtag or formatting requirements. Claude adapts naturally between professional (LinkedIn), conversational (Twitter), and visual-caption (Instagram) styles.
Content Strategy and Planning
Content strategy and planning.
Beyond individual pieces, Claude can help with content strategy — editorial calendar planning, content gap analysis, persona development, and competitive content auditing. Upload your existing content inventory, share your business goals and target audience, and ask Claude to identify gaps, suggest topics, and prioritize based on potential impact. This is especially powerful with web search enabled, allowing Claude to analyze competitor content in real-time.
Quality Control and Accuracy
AI-generated content requires human quality control. Every piece should be checked for factual accuracy (especially statistics, dates, and specific claims), brand voice consistency, originality (run through plagiarism detection), legal compliance (disclaimers, disclosures), and genuine value to the reader. The biggest risk with AI content is not that it’s bad — it’s that it’s competent but generic. Human editors should push for the specific insights, examples, and perspectives that make content genuinely useful rather than just technically correct.
Yes. Claude can draft keyword-optimized content, generate meta descriptions, create FAQ sections with schema markup, and analyze content for SEO improvements. Human review for accuracy and originality is essential.
Should I use Claude to write my entire blog?
Use Claude as a drafting and optimization tool, not a hands-off content factory. The best results come from human-directed Claude drafts that are then edited for accuracy, brand voice, and genuine insight.
Can Google detect AI-written content?
Google has stated it focuses on content quality regardless of how it’s produced. The key is creating content that’s helpful, accurate, and provides genuine value — whether written by humans, AI, or both.
How much content can Claude produce per day?
On a Pro plan, a content professional can realistically produce 5-10 well-researched, edited articles per day with Claude assistance — compared to 1-2 without it. The bottleneck shifts from writing to editing and quality control.
Model Context Protocol (MCP) is an open standard created by Anthropic that lets Claude connect to external tools, data sources, and services. Instead of copying data into Claude manually, MCP gives Claude structured access to the tools you already use — databases, APIs, project management platforms, file systems, and more. MCP has become one of the most important developments in the AI ecosystem in 2026, and understanding it is increasingly essential for developers and technical teams.
What MCP Actually Does
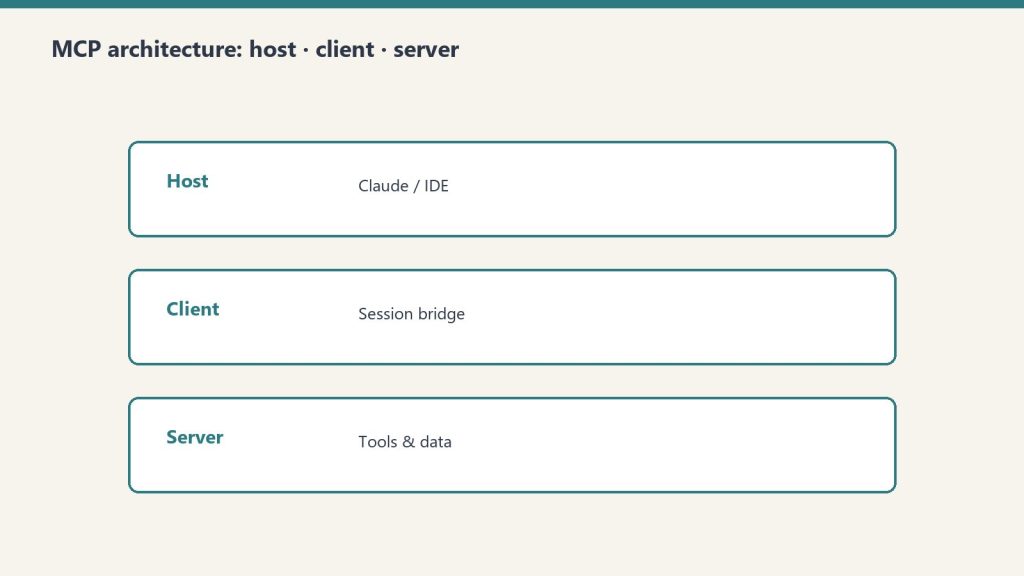
What MCP actually does — hosts, clients, servers.
At its core, MCP is a protocol — a standardized way for AI models to communicate with external services. Think of it like how HTTP standardized web communication or how SQL standardized database queries. MCP standardizes how AI assistants request and receive data from external tools. Before MCP, connecting Claude to a database required custom integration code. With MCP, you configure an MCP server that speaks the protocol, and Claude can query the database through that server using a standardized interface.
The Architecture: Hosts, Clients, and Servers
Architecture: hosts, clients, and servers.
MCP has three components. The host is the application where Claude runs (the desktop app, Claude Code, or a custom application). The client is the MCP client built into Claude that manages connections to MCP servers. The server is the service that provides tools, data, or capabilities to Claude. MCP servers expose three types of primitives: tools (actions Claude can take, like querying a database or creating a Jira ticket), resources (data Claude can read, like file contents or documentation), and prompts (pre-built interaction patterns).
Practical Examples
A Notion MCP server lets Claude read and write Notion pages and databases directly. A PostgreSQL MCP server lets Claude query your database. A Slack MCP server lets Claude read channels and send messages. A GitHub MCP server lets Claude interact with repositories, issues, and pull requests. A Sentry MCP server lets Claude access error tracking and debugging data. These aren’t hypothetical — they’re production tools that teams use daily.
Local vs Remote MCP Servers
MCP servers can run locally on your machine or remotely as hosted services. Local MCP servers run alongside the Claude desktop app and have access to your local environment — file system, local databases, development tools. They use the stdio transport (standard input/output) and require no network configuration. Remote MCP servers run as web services and are accessed over the network using Streamable HTTP or Server-Sent Events (SSE) transports. Remote servers can be shared across teams and don’t require local installation.
Token Cost Considerations
An important practical consideration: MCP tools add tokens to every conversation turn. Each configured MCP server’s tool descriptions are included in Claude’s context, consuming input tokens. If you have 10 MCP servers with 5 tools each, that’s 50 tool descriptions included in every request — potentially thousands of tokens per turn. Best practices include only connecting the MCP servers you actively need, using scoped configurations to limit which tools are available in which contexts, and monitoring your token usage to identify MCP-related costs.
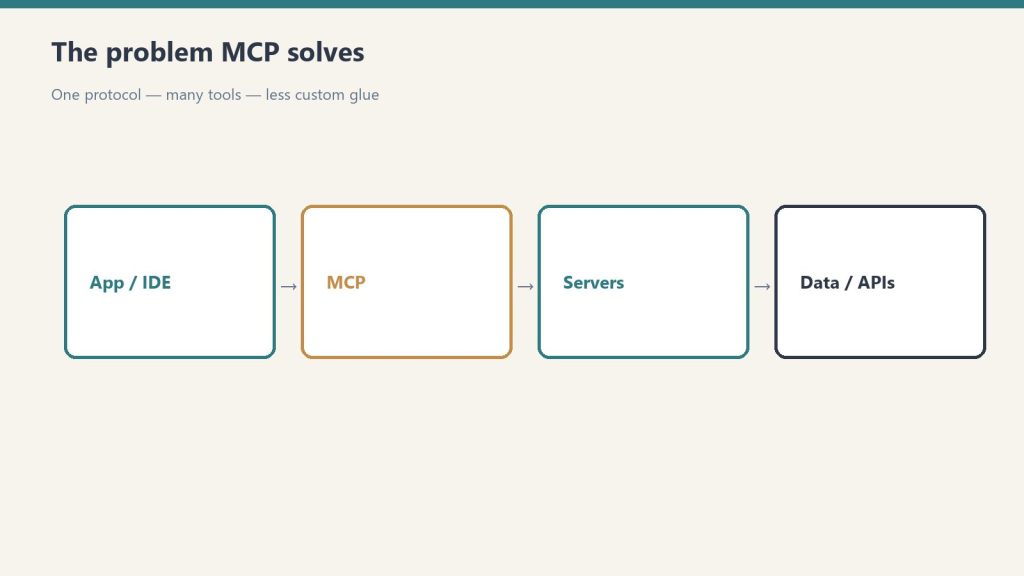
Why Developers Care
Why developers care — less custom glue.
MCP matters because it transforms Claude from a standalone chatbot into a connected agent. Without MCP, Claude can only work with information you paste into the conversation. With MCP, Claude can pull real-time data, take actions in external systems, and operate as part of your existing toolchain. For development teams, MCP means Claude Code can interact with your entire development stack — version control, CI/CD, error tracking, documentation, project management — through a single standardized interface.
Getting Started with MCP
The fastest path is to install a pre-built MCP server for a tool you already use. The Claude desktop app’s settings include MCP server configuration. Add a server definition (the server command and its arguments), restart Claude, and the tools become available in your conversations. For custom integrations, Anthropic provides SDKs for building MCP servers in Python and TypeScript. The MCP specification is open — anyone can build a server for any tool.
MCP (Model Context Protocol) is an open standard that lets Claude connect to external tools and data sources — databases, APIs, file systems, and more — through a standardized interface.
Is MCP free to use?
MCP itself is free and open. MCP servers may be free (open source) or paid (commercial). The token costs from MCP tool descriptions are included in your regular Claude usage or API billing.
Do I need to be a developer to use MCP?
Basic MCP server setup requires some technical comfort — editing configuration files and running commands. Pre-built connectors in the Claude interface are simpler. Building custom MCP servers requires programming knowledge.
Can MCP be used with other AI models?
MCP is an open protocol. While Anthropic created it for Claude, other AI platforms and tools have begun adopting MCP as a standard for tool integration.
Anthropic is an AI safety company that happens to build a product, not a product company that happens to care about safety. That distinction matters. Every design decision in Claude — from how it handles sensitive topics to how it processes your data — traces back to Anthropic’s safety-first philosophy. This guide explains what that philosophy is, how it works in practice, and what it means for you as a user.
Constitutional AI: How Claude Learns to Behave
Constitutional AI — how Claude learns to behave.
Claude is trained using a methodology called Constitutional AI (CAI). Instead of relying solely on human feedback to determine what’s helpful and harmless, Claude is given a set of principles — a “constitution” — that guides its behavior. These principles cover helpfulness, harmlessness, and honesty. During training, Claude evaluates its own outputs against these principles and self-corrects. This produces more consistent behavior than pure human feedback, which can be noisy and contradictory.
In practice, this means Claude tends to be thoughtful about edge cases, transparent about uncertainty, and willing to push back when a request might lead to harmful outcomes — while still being maximally helpful within safe boundaries.
The Responsible Scaling Policy
Responsible Scaling Policy.
Anthropic’s Responsible Scaling Policy (RSP) is a framework that ties safety testing to capability levels. As models become more capable, the RSP requires more rigorous safety evaluations before deployment. The policy defines specific capability thresholds and the safety measures required at each level. This means Anthropic won’t release a model that’s significantly more capable without also implementing significantly more safety infrastructure. The RSP has been publicly documented and updated as the company has learned from deployments.
Interpretability Research
Anthropic invests heavily in interpretability — the science of understanding what happens inside neural networks. While most AI companies treat their models as black boxes, Anthropic’s research team publishes work on identifying how models store and process information, what individual neurons and circuits represent, and how to detect when a model might be reasoning in unexpected ways. This research directly informs safety work: if you can see inside the model, you can better identify and prevent harmful behavior.
Data Handling and Privacy
Data handling and privacy.
Anthropic’s data handling practices reflect its safety orientation. On Free and Pro plans, users can opt out of having their data used for model training. On Team and Enterprise plans, content is not used for training by default — this is an opt-out-by-default approach, not opt-in. Enterprise plans add custom data retention controls, so organizations can specify exactly how long their data is stored. The HIPAA-ready Enterprise option provides additional safeguards for healthcare data.
Corporate Structure as Safety Mechanism
Anthropic’s public benefit corporation (PBC) structure and Long-Term Benefit Trust (LTBT) are designed as institutional safeguards. The PBC structure legally requires balancing profit with public benefit. The LTBT can intervene if the company’s actions deviate from its safety mission. These aren’t just statements of intent — they’re legal mechanisms with real enforcement power.
What This Means for Users
For individual users, Anthropic’s safety approach means Claude is less likely to produce harmful, misleading, or biased content. It’s more transparent about what it doesn’t know. It handles sensitive topics with care rather than either refusing entirely or engaging recklessly. For business users, it means enterprise-grade security features, data handling that meets regulatory requirements, and a vendor whose incentive structure is aligned with long-term reliability rather than short-term growth at any cost.
Constitutional AI is Anthropic’s training methodology where Claude is given a set of principles (a “constitution”) and learns to evaluate and correct its own outputs against those principles, producing more consistent helpful and safe behavior.
Does Claude use my data for training?
On Free/Pro plans, you can opt out. On Team and Enterprise plans, your data is not used for training by default.
Why does Claude sometimes refuse requests?
Claude’s safety training teaches it to decline requests that could lead to harmful outcomes. It aims to be maximally helpful within safe boundaries. If Claude refuses something you think is reasonable, you can rephrase or provide more context.
Is Anthropic more safety-focused than OpenAI?
Anthropic was founded specifically as an AI safety company and has embedded safety into its corporate structure through PBC status and the LTBT. Both companies invest in safety, but Anthropic’s organizational design makes safety central rather than supplementary.
Updated November 2, 2026 — added direct answers on research workflows and comparative writing performance, sourced from the vendors’ published model and pricing pages.
If you’re evaluating Claude AI, you’re probably also looking at the alternatives. The AI assistant market in 2026 has matured — each major platform has developed distinct strengths rather than trying to be identical. This guide compares Claude against ChatGPT, Gemini, Perplexity, Grok, Microsoft Copilot, and other options on the metrics that actually matter: pricing, capability, reliability, and fit for specific use cases.
Claude vs ChatGPT
Compare alternatives by job — start with Claude vs ChatGPT.
The most common comparison. Both offer free tiers and $20/month Pro/Plus plans. Claude’s strengths are long-form writing quality, instruction following, code generation with Claude Code, and the 1M token context window. ChatGPT’s strengths are its ecosystem (plugins, GPT store, DALL-E integration), broader brand recognition, and strong general-purpose capabilities. For developers, the choice often comes down to Claude Code vs ChatGPT’s code interpreter and canvas features. For writers, Claude generally produces more nuanced, less formulaic output. API pricing is competitive between the two platforms at comparable model tiers.
Is Claude better than ChatGPT for writing?
Whether Claude is better than ChatGPT for writing depends on the genre, required voice, and editorial workflow rather than benchmark scores alone. In qualitative use-case comparisons, the two platforms present distinct stylistic profiles:
Essays and long-form analysis: Claude generally produces prose with greater tonal consistency, less formulaic structure, and more natural syntactic variation. Where ChatGPT often defaults to repetitive structural markers (such as rigid introductory signposting and uniform transitional paragraphs), Claude maintains sustained voice across complex essays and opinion pieces.
Structured business content and technical documentation: Both models perform strongly. ChatGPT excels at rapid, modular drafting against standard corporate templates and benefits from workflow flexibility like Canvas for iterative editing. Claude excels when documentation requires adhering strictly to granular voice guidelines, negative constraints (what not to say), and nuanced technical accuracy without promotional inflation.
Marketing copy and creative brainstorming: ChatGPT offers high ideation velocity, rapid headline brainstorming, and immediate tone shifting across multiple marketing variants. Claude excels at long-form brand storytelling, editorial thought leadership, and narrative depth where avoiding clichés and generic phrasing is paramount.
Fiction and narrative prose: Writers frequently favor Claude for its natural dialogue rhythm, subtle character voice, and avoidance of predictable narrative tropes, aided by its 1M token context window when tracking multi-chapter consistency.
In practice, many professional writing workflows pair both tools: using ChatGPT for rapid outlining, structural brainstorming, and modular editing, and relying on Claude for drafting long-form prose, refining voice, and polishing complex editorial copy.
Claude vs Google Gemini
Claude vs Gemini — different strengths, different seats.
Gemini’s key advantage is integration with the Google ecosystem — Gmail, Docs, Drive, Search, and Google Workspace. If your organization runs on Google, Gemini fits naturally into existing workflows. Claude’s advantages are stronger reasoning on complex tasks, better code generation, and more robust enterprise features (SCIM, audit logs, HIPAA). Gemini offers a generous free tier and is deeply integrated into Android. Claude is available on Google Cloud through Vertex AI, so organizations can use both within the Google ecosystem.
How does Claude compare to Gemini for research work?
When conducting research, Claude and Google Gemini represent two fundamentally different architectural philosophies: synthesis-focused reasoning versus retrieval-heavy workflow integration.
Synthesis-focused reasoning (Claude): Claude is engineered for deep analytical synthesis over extensive source materials. With its 1M token context window and strong instruction-following fidelity, Claude excels at ingesting dozens of dense research papers, financial filings, or legal transcripts simultaneously. It cross-references conflicting claims, identifies methodological gaps, and synthesizes nuanced findings without losing thread context. For web research, Anthropic offers integrated web search ($10 per 1K searches on the API) to ground analysis in current facts.
Retrieval-heavy workflows and live data (Gemini): Gemini’s primary research advantage is its direct integration with the Google ecosystem. Through native Grounding with Google Search (offering 5,000 free monthly requests on the Gemini API, then $14 per 1,000 queries) and deep connectivity to Google Workspace (Docs, Drive, Gmail, and Google Scholar), Gemini excels at rapid fact-finding, retrieving real-time public data, and organizing research findings directly inside existing Google workflows.
Workflow recommendation: Use Google Gemini when your research requires real-time web discovery, live data retrieval across Google services, or broad multi-source literature scanning. Transition to Claude when you have gathered your primary source corpus and require deep qualitative analysis, rigorous counter-argument evaluation, or publication-ready narrative synthesis. For a dedicated evaluation of Google’s assistant architecture, see our guide on What is Google Gemini.
Claude vs Perplexity
Claude vs Perplexity — research seat vs general assistant.
Perplexity occupies a different niche — it’s primarily a search and research tool, not a general-purpose assistant. Perplexity excels at answering factual questions with cited sources, making it excellent for research and fact-checking. Claude is better for creative work, coding, analysis, and extended projects. Many professionals use both: Perplexity for research and fact-finding, Claude for drafting, analysis, and execution.
Claude vs Microsoft Copilot
Microsoft Copilot (powered by OpenAI) is embedded throughout Microsoft 365 — Word, Excel, PowerPoint, Teams, Outlook. If your organization is Microsoft-centric, Copilot has the integration advantage. However, Claude now offers Claude for Microsoft 365 and Outlook, giving it a presence in the Microsoft ecosystem as well. For standalone AI capabilities, Claude generally outperforms Copilot in reasoning, writing quality, and code generation.
Claude vs Grok
Grok, built by xAI, is integrated with the X (formerly Twitter) platform and has access to real-time social media data. Grok’s strength is current events and social sentiment analysis. Claude’s strengths are safety, reliability, enterprise features, and broader use case coverage. Grok appeals to users who want an AI with a less restricted personality and real-time social context.
Pricing Comparison
Free tiers: Claude, ChatGPT, Gemini, Perplexity, and Copilot all offer free access. Individual paid plans: Claude Pro $20/month, ChatGPT Plus $20/month, Gemini Advanced $19.99/month (often bundled with Google One), Perplexity Pro $20/month. Claude’s Max plan ($100-200/month) has equivalents in ChatGPT Pro ($200/month). At the API level, pricing varies by model class but is broadly competitive across major providers.
How to Choose
Choose Claude if you prioritize writing quality, code generation, enterprise security, and long-context processing. Choose ChatGPT if you want the broadest ecosystem of plugins and integrations. Choose Gemini if you’re deep in the Google ecosystem. Choose Perplexity if your primary need is research with cited sources. Choose Copilot if Microsoft 365 integration is your top priority. Many organizations use multiple AI tools — they’re not mutually exclusive.
Claude excels at long-form writing, instruction following, and code generation. ChatGPT has a larger ecosystem of plugins and integrations. Neither is universally “better” — the right choice depends on your use case.
What is the best free AI chatbot in 2026?
Claude, ChatGPT, and Gemini all offer strong free tiers. Claude’s free tier is notable for including web search, code execution, memory, and extended thinking at no cost.
Can I use Claude and ChatGPT together?
Yes. Many professionals use multiple AI tools for different tasks. At the API level, platforms like OpenRouter let you route requests to different models based on the task.
Which AI has the largest context window?
As of June 2026, both Claude (Opus and Sonnet) and Gemini support 1M+ token context windows. Claude’s 1M context is available at flat-rate pricing with no surcharge.
For the full standalone explainer on one name in this field, see What is Google Gemini — Google’s assistant defined on its own terms, including its data rules and costs.
Claude AI is powerful, but getting the most out of it requires more than typing a question and hoping for the best. This guide covers the fundamentals — from signing up to writing prompts that produce genuinely useful output — so you can start getting value from Claude immediately, whether you’re using the free tier or a paid plan.
Getting Started
Getting started with Claude.
Go to claude.ai and sign up with your email or Google account. No credit card required for the free tier. Once you’re in, you’ll see a chat interface where you can start a conversation immediately. Claude is available on web, iOS, Android, and a desktop app for macOS and Windows. Your conversations sync across all platforms.
The Basics of Good Prompting
The basics of good prompting.
Be specific about what you want. Instead of “write me something about marketing,” try “write a 500-word blog post about email marketing best practices for small e-commerce businesses, focusing on subject line optimization and send timing.” The more specific your request, the more useful the output.
Provide context. Claude doesn’t know your situation unless you tell it. Share relevant background: your role, your audience, your constraints, your goals. “I’m a freelance graphic designer preparing a proposal for a client who sells organic skincare” gives Claude much more to work with than “help me write a proposal.”
Specify the format. Tell Claude how you want the output structured: bullet points, numbered steps, a table, a narrative paragraph, a code snippet. If you want a specific length, say so. If you want a specific tone (formal, casual, technical), specify that too.
Iterate. Your first prompt rarely produces the perfect result. Treat Claude like a collaborative colleague — give feedback, ask for revisions, and refine. “Make the tone more conversational” or “expand the section about pricing” or “now format this as an email instead of a document.”
Key Features to Know About
Projects: Organize related conversations and documents together. Create a Project for each client, each project, or each area of your work. Projects maintain context across conversations, so Claude remembers the background you’ve established.
Web search: Claude can search the internet in real-time to find current information. When you need up-to-date data, Claude will search, cite sources, and incorporate findings into its response.
Memory: Claude remembers things you tell it across conversations. If you share your preferences, your role, or your communication style, Claude applies that context in future conversations automatically.
Code execution: Claude can write and run code in a sandbox. Ask it to analyze data, create charts, process files, or test code snippets. The results are displayed directly in the conversation.
Extended thinking: For complex problems, Claude can engage in step-by-step reasoning before responding. This produces better results on math problems, logic puzzles, strategic planning, and multi-variable analysis.
File uploads: You can upload documents, images, spreadsheets, and other files for Claude to analyze. Upload a PDF contract for review, a CSV dataset for analysis, or an image for description.
Common Use Cases for Beginners
Writing assistance: Draft emails, blog posts, reports, proposals, social media content. Claude excels at adapting to different tones and formats. Research: Ask Claude to explain complex topics, summarize long documents, or investigate questions across multiple angles. Data analysis: Upload spreadsheets and ask Claude to find patterns, create visualizations, or generate summaries. Learning: Use Claude as a tutor — ask it to explain concepts, quiz you, or create study guides. Coding: Even non-developers can use Claude to write scripts, automate tasks, or build simple tools.
Mistakes to Avoid
Mistakes to avoid as a beginner.
Don’t assume Claude’s output is always correct — verify important facts, especially numbers, dates, and claims about specific companies or people. Don’t share sensitive personal information unnecessarily. Don’t treat Claude’s first response as final — iterate and refine. Don’t write vague prompts and expect specific results. Don’t ignore Claude’s caveats and limitations when it flags uncertainty.
Go to claude.ai, sign up for free, and start chatting. No credit card or technical setup required. Download the desktop app from claude.com/download for additional features.
What should I ask Claude AI?
Anything you’d ask a knowledgeable assistant: writing help, research, analysis, coding, brainstorming, summarization, explanation of complex topics, or task planning. Be specific about what you need.
How do I write a good prompt for Claude?
Be specific about your request, provide relevant context, specify the format and length you want, and iterate on the results. The more detail you give, the better the output.
Is Claude AI better than ChatGPT for beginners?
Both are capable tools with similar pricing ($0 free, $20/month paid). Claude is often praised for longer, more nuanced responses and better instruction-following. The best approach is to try both and see which fits your workflow.
The Signal — Tygart Media's weekly brief. What we actually ran, what it measured, and what it means for a restoration shop.