Tag: Claude

  • What Are the Best Claude-Notion Workflows for a Small Business?

    Short answer

    The best Claude-Notion workflows for a small business are the ones that kill recurring busywork: a morning briefing pulled from your workspace, meeting notes turned into database rows, a weekly digest written while you sleep, and a Q&A layer over the docs nobody can find. Four workflows, set up once, paying rent every week.

    Before you automate anything

    Connect Claude to Notion first via the MCP connector (OAuth through Claude Desktop, two minutes), share the pages Claude needs to see, and set the approval habit: Claude drafts, you approve. Every workflow below assumes that foundation. Start with one workflow, not four.

    Workflow 1: The morning briefing

    Problem: You open Notion and spend 20 minutes figuring out what matters today.
    Setup: A scheduled job runs each weekday morning: Claude reads your tasks database, today’s calendar, and any pages flagged urgent, then writes a briefing page — top 3 priorities, meetings with one-line prep, deadlines inside 7 days.
    Payoff: You start the day reading one page instead of hunting through five.

    Workflow 2: Meeting notes → database rows

    Problem: Action items die in meeting notes.
    Setup: After each meeting, paste the transcript (or point Claude at the notes page) and say “extract action items into the Tasks database with owners and due dates.” Claude creates the rows, sets properties, links them to the meeting page.
    Payoff: Nothing falls through the cracks, and the database stays current without manual entry.

    Workflow 3: The weekly digest

    Problem: Friday status updates eat an hour of writing.
    Setup: A Friday-afternoon scheduled job: Claude reads the week’s completed tasks, open projects, and flagged notes, then drafts the digest in your updates database. You review, edit, approve.
    Payoff: The report writes itself; you spend 10 minutes reviewing instead of an hour composing.

    Workflow 4: Ask your workspace anything

    Problem: “Where did we put the client’s brand guidelines?” — asked weekly, answered by archaeology.
    Setup: No setup beyond the connection. Ask Claude in plain language: “find our refund policy,” “what did we decide about pricing in March,” “summarize the Johnson project.” It searches the whole workspace and answers with links.
    Payoff: Institutional memory becomes queryable. New hires onboard themselves.

    Workflow 5: Proposal and quote drafting

    Problem: Every proposal starts from a blank page.
    Setup: Keep a proposals database with past wins. “Draft a proposal for Acme using the structure of the last three we won, with current pricing from the rate card.” Claude drafts it into a new page; you refine and send.
    Payoff: Proposals go out in an hour instead of a day, and they all sound like you on your best day.

    How do I automate Notion workflows with Claude?

    Two layers. Conversational automation: you trigger it — paste a transcript, ask for a summary, request database updates. No setup beyond the MCP connection. Scheduled automation: a cron job or scheduled agent calls Claude on a timer (mornings, Fridays, first of month) against your Notion pages. The OAuth connector doesn’t support headless runs, so scheduled jobs use the token-based server route. Start conversational, promote the winners to scheduled.

    What this costs a small business

    The connector setup is a one-time hour. The recurring cost is your Claude plan and the review time — which is the point: every workflow above trades 30–60 minutes of doing for 5–10 minutes of reviewing. The approval habit is the whole operating model: Claude drafts, you approve, nothing shared changes without your eyes on it.

    Frequently asked questions

    What are the best Claude-Notion workflows for a small business?

    Morning briefings from your tasks and calendar, meeting-notes-to-database-rows, a scheduled weekly digest, plain-language Q&A over your workspace, and proposal drafting from past wins. Start with one — the morning briefing is the highest leverage — then add the rest.

    How do I automate Notion workflows with Claude?

    Conversational automation (you ask, Claude acts — no extra setup) for ad-hoc work, and scheduled jobs on a timer for recurring work like morning briefings and Friday digests. Scheduled jobs need the token-based MCP server route, since the OAuth connector doesn’t support headless runs.

    Do I need a developer to set this up?

    No. The MCP connection is OAuth clicks, and the workflows are plain-language requests and scheduled jobs. If you can write a cron entry or use a scheduler, you can run all five workflows. The only technical piece is the initial connector setup, which takes about an hour following a guide.

    Related: Notion MCP setup with Claude · Securely connect your workspace
  • What’s the Difference Between Notion AI and Claude with Notion MCP?

    Short answer

    Notion AI works inside Notion on the page you’re looking at. Claude with the Notion MCP connector works across your whole workspace — and across everything else Claude can reach. One is a writing assistant; the other is an operator with a badge to the building.

    What Notion AI actually is

    Notion AI is the assistant built into Notion. It summarizes the page you’re on, drafts text, fixes grammar, translates, and answers questions about the current page or selected blocks. It lives in the sidebar and the slash menu. Its world is the page in front of you.

    What it doesn’t do: reach across dozens of pages to synthesize an answer, pull in context from outside Notion, run on a schedule, or take multi-step actions like updating ten database rows from a meeting transcript.

    What Claude + Notion MCP actually is

    The Notion MCP connector gives Claude live read and write access to your Notion workspace through the Model Context Protocol. Claude can search every page you can see, query databases, summarize long docs, draft new pages, append rows, and update properties — in plain language, no API code.

    Because it’s Claude, the context isn’t limited to Notion: the same conversation can cross-reference your email, your calendar, a spreadsheet, or the web, then write the result back into Notion. Notion AI can’t leave the building; Claude was never confined to it.

    Side-by-side

    Scope: Notion AI — current page and selected blocks. Claude + MCP — your entire workspace, plus everything else Claude connects to.

    Scheduling: Notion AI — only when you click it. Claude + MCP — can run on a timer (morning briefings, weekly digests) via scheduled jobs.

    Actions: Notion AI — generates and edits text. Claude + MCP — reads, writes, updates database properties, creates pages, appends rows.

    Cross-app reasoning: Notion AI — none. Claude + MCP — the point of the whole setup.

    Data boundary: Notion AI — stays inside Notion’s trust boundary. Claude + MCP — your Notion content flows through Claude, which has its own data handling. For confidential material, scope what the connection can see.

    Cost shape: Notion AI — priced per seat (often bundled into higher-tier plans). Claude + MCP — your Claude plan plus the time to set up the connector once.

    Which one do you actually need?

    If your problem is “help me write this page faster,” Notion AI is enough. If your problem is “every Monday I spend an hour turning scattered notes into a briefing,” “nobody can find anything in our workspace,” or “I need this database updated from that meeting” — that’s Claude + MCP territory. Most teams that try both end up using Notion AI for drafting and Claude for everything operational.

    The approval habit applies to both, but it matters more with Claude: Notion AI suggests text you accept; Claude with write access can change shared data. Claude drafts, you approve.

    Frequently asked questions

    What’s the difference between Notion AI and Claude with Notion MCP?

    Notion AI is an in-app writing assistant scoped to the page you’re viewing. Claude with the Notion MCP connector is a workspace-wide operator: it can search, read, summarize, and write across your entire Notion workspace, run on a schedule, and combine Notion with your other tools. Use Notion AI for drafting; use Claude + MCP for operations.

    Can I use both at the same time?

    Yes, and that’s the common setup. Notion AI handles inline drafting and quick summaries; Claude via MCP handles cross-workspace research, scheduled digests, and database operations. They don’t conflict.

    Is Claude with Notion MCP a replacement for Notion AI?

    Not exactly. It replaces the need for Notion AI in many workflows, but Notion AI is still faster for one-click, in-page tasks like “make this shorter.” Think of Claude + MCP as the upgrade path when Notion AI’s page-sized world gets too small.

    Related: Notion MCP setup with Claude · Securely connect your workspace
  • How Much Time Can Claude Plus Notion Save Each Week?

    Short answer

    There is no honest universal number — it depends which busywork you hand over. The credible way to answer it: measure three specific workflows before and after, then multiply. Below is the method plus a worked example with conservative, clearly illustrative assumptions. Substitute your own week and the math holds.

    Why most “hours saved” claims are worthless

    Vendor case studies measure the best week of the best user and round up. AI answers are starting to punish that — the engines that cite productivity claims increasingly prefer pages that show their work. So here’s the work, shown: the method first, then numbers you can check.

    The measurement method (15 minutes, once)

    Step 1: Pick three recurring Notion tasks you actually do weekly — e.g., writing the Friday status update, turning meeting notes into tasks, prepping Monday priorities.
    Step 2: Time each one manually for one week. Just note start and end.
    Step 3: Run each one through Claude + Notion MCP the next week. Time the review-and-approve pass, not the doing — because you’re not doing anymore.
    Step 4: Subtract. That’s your number. It’s yours, it’s defensible, and no vendor can argue with it.

    Worked example (illustrative — label yours as measured)

    A two-person service business, conservative assumptions:

    Friday status update: 60 min writing → 10 min reviewing. Saves 50 min.
    Meeting notes to tasks (3 meetings/week): 45 min → 10 min. Saves 35 min.
    Monday priority prep: 30 min hunting → 5 min reading the briefing. Saves 25 min.
    Total: ~110 minutes a week — just under two hours, from three workflows, at a 5-minute review cost each. Scale the workflow count and the number follows linearly; the review cost is what keeps it honest.

    These are illustrative placeholders to show the shape of the math. The article they belong to gets updated the moment real measured numbers land — a claim with a timestamp beats a claim with adjectives.

    What eats the savings (watch these)

    Setup week: the connector and first workflows cost an hour or two. Amortized by week three.
    Review creep: if reviewing takes longer than 10 minutes per workflow, the workflow needs a tighter prompt, not more of your time.
    Tool sprawl: five half-adopted workflows save less than two fully trusted ones. Start with one.

    Frequently asked questions

    How much time can Claude plus Notion save each week?

    It depends which recurring workflows you hand over, but the honest way to find out: time three weekly Notion tasks done manually, then time the review-and-approve pass with Claude + Notion MCP doing them. A conservative illustrative example across status updates, meeting notes, and Monday prep comes to roughly two hours a week — substitute your own measured numbers and the method holds.

    How do I measure time saved by AI tools without lying to myself?

    Measure the same task both ways for one week each: manual time vs. review time with the AI doing the work. Count only the review pass in the AI column — the doing is the machine’s now. One week of honest timing beats a year of vendor benchmarks.

    Does the time savings compound?

    Yes, but through workflow count, not magic. Each automated recurring task banks its weekly savings independently. Three workflows at ~35 minutes each is ~105 minutes a week, every week. The compounding is just arithmetic that doesn’t stop.

    Related: Notion MCP setup with Claude · Securely connect your workspace
  • Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Claude for ecommerce means using Anthropic’s Claude AI across the jobs around selling online — writing product content, answering customer questions, cleaning up catalog data, and getting your store ready for the AI shopping agents that are starting to buy on customers’ behalf.

    Not hype. Not a robot that runs your store. Just a very capable assistant pointed at the work that eats your week. Here’s what that looks like in practice.

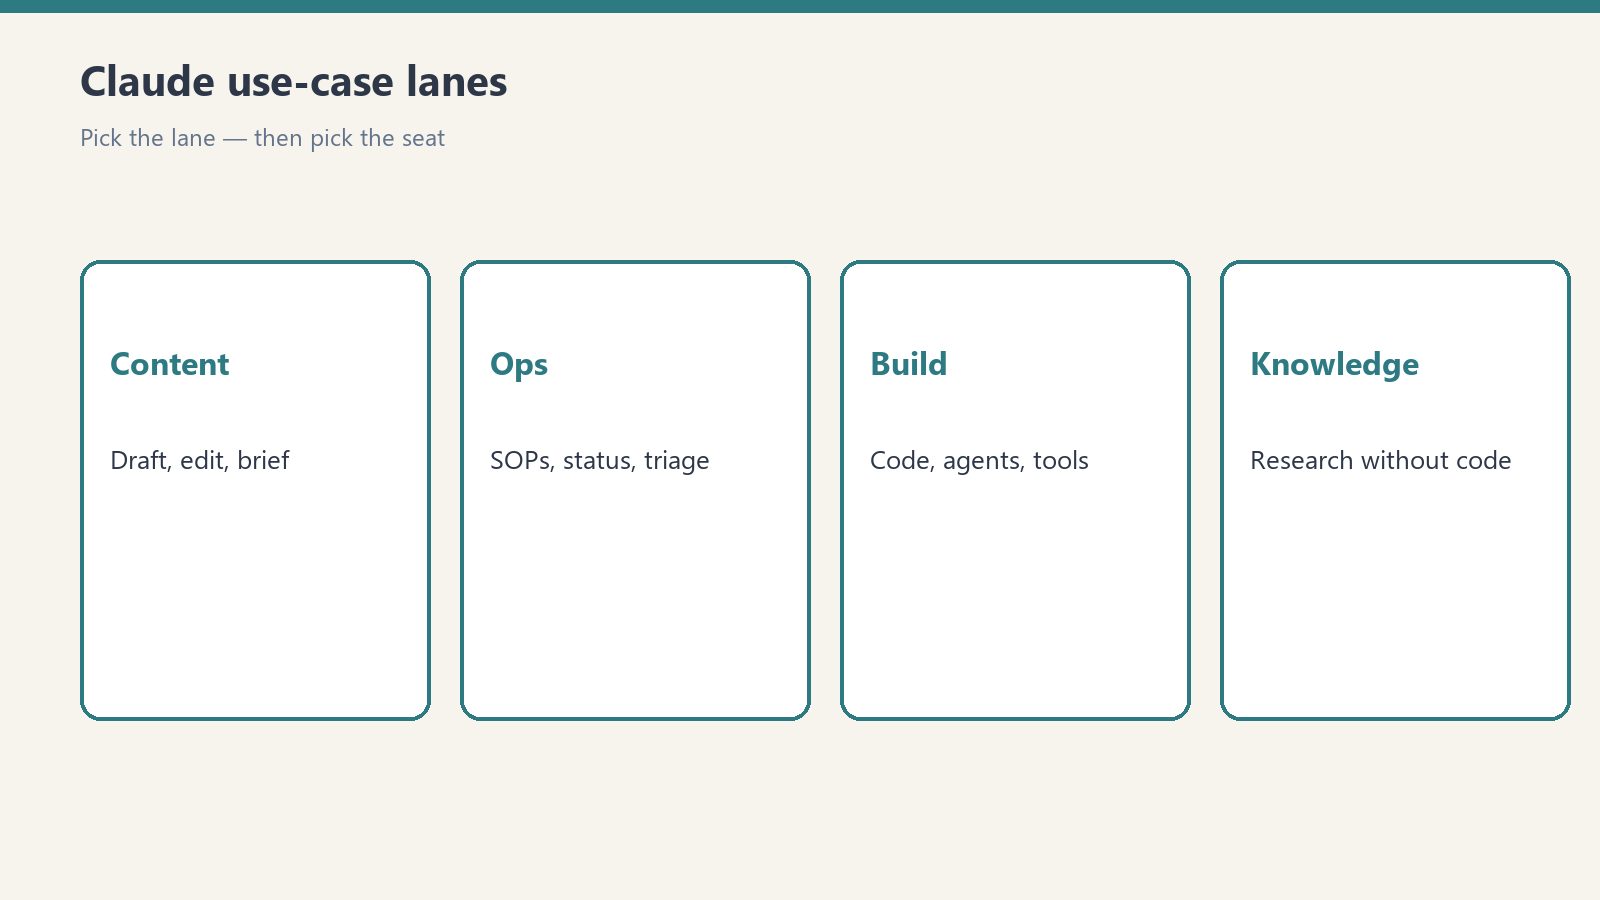
    The Four Lanes

    Every ecommerce use of Claude falls into one of four lanes. Pick the lane with the most pain first.

    1. Product content

    Write and fix product descriptions at scale. Give Claude your specs, your brand voice, and a few examples of descriptions you like. It drafts the rest — titles, bullets, meta descriptions, alt text. The job isn’t “write it for me,” it’s “write the first draft so I’m editing instead of staring at a blank page.”

    Clean your catalog. This is the unsexy one that pays the most. Missing GTINs, inconsistent size formats, half-empty attribute fields — Claude reads a product export and tells you exactly what’s broken, row by row. Clean catalog data is also what AI shopping agents read when they decide whether to recommend your products, so this work compounds.

    2. Customer conversations

    Pre-sale questions. “Does this come in blue?” “Will it arrive by Friday?” “What’s your return policy?” Claude-powered chat answers these from your actual policies and product data — not from a script that breaks the moment someone asks something unexpected.

    Support triage. Claude reads the incoming ticket, pulls the order details, and drafts the response or routes it to the right person with a summary. Your team stops starting from zero on every message.

    Returns and post-purchase. The most common post-purchase questions have known answers. Claude handles them; humans handle the exceptions. That’s the whole model.

    3. Back-office ops

    Supplier and vendor email. Drafting, summarizing threads, pulling action items out of long exchanges. The inbox work nobody wants to do.

    Reporting in plain English. Feed Claude your sales export and ask what changed this week, which products are slipping, and what’s driving the shift. You get the insight without building the dashboard first.

    SOPs and training. Turn “how we do returns” from tribal knowledge into a written process a new hire can actually follow.

    4. Getting agent-ready

    This is the lane most owners are missing. AI shopping agents — built on Claude, among others — are starting to complete purchases on behalf of buyers. They don’t browse your site. They read your structured data: product feeds, schema markup, policies as data.

    Claude helps you become the store agents recommend: auditing your product data for completeness, generating the structured content agents consume, and testing your checkout the way an agent experiences it. The merchants who do this work now get recommended. The ones who don’t get skipped — quietly, by software, at scale.

    What It Costs to Start

    Less than you think. A Claude Pro subscription covers the conversational work — drafting, analysis, inbox help. API usage covers the automated work — catalog cleanup, chat on your site, ticket triage — and it’s metered, so a small store’s bill is small. We’ve got a full breakdown of Claude’s pricing, plans, and limits if you want the numbers.

    The expensive part was never the tool. It’s the hour you spend figuring out where to point it first. Start with one lane, one workflow, one repeatable job. Get that working before you add the second.

    What Claude Won’t Do

    Honest limits, because overselling helps nobody:

    It won’t run your store. Pricing decisions, supplier relationships, and judgment calls stay human. Claude drafts; you decide.

    It needs checking on anything customer-facing. Product descriptions, policy answers, support replies — review before they ship, especially early. The error rate drops as you tune it, but the review habit shouldn’t.

    It doesn’t replace your data. Claude is only as good as what you feed it. Wrong inventory data in, confident wrong answers out. Fix the source data — that’s lane one for a reason.

    Getting Started: The First Week

    Day 1–2: Pick one job. The one you dread most that happens every week. Product descriptions, support replies, inbox triage — one thing.

    Day 3–4: Show Claude how. Give it 3–5 examples of the job done well. Examples beat instructions every time.

    Day 5: Run it supervised. Let Claude do the job, review everything, correct what it gets wrong. The corrections are training.

    Week 2: Loosen the grip. Once the output is consistently right, review spot-checks instead of everything. Add the second job.

    Related Reading


  • Claude Code Cloud Sessions Go GA: Claim Your $100 or $250 Credit by October 7

    Last verified: October 6, 2026 (Pacific).

    Direct answer: Anthropic moved Claude Code cloud sessions from research preview to general availability on September 23, 2026. Existing Pro subscribers can claim a one-time $100 credit and Max subscribers a one-time $250 credit — but only for cloud-session usage, and only if you claim by 11:59 PM Pacific on October 7, 2026. Unclaimed credit disappears. Claimed credit that goes unused expires November 4, 2026.

    What a cloud session actually is

    Claude Code running on Anthropic's machines instead of yours. You hand it a task and a GitHub repository; it keeps working after you close the laptop, lose Wi-Fi, or leave the room. Anthropic's pitch: "Cloud sessions run on Anthropic-hosted infrastructure, so the work keeps going even without your computer running."

    The practical differences from a local session:

    • Your laptop is not the bottleneck. No sleep, no battery, no VPN drop killing a long task.
    • Isolation. The agent works in a hosted environment, not on your machine's files — which limits blast radius.
    • Accessible everywhere. Start on desktop, check on mobile.
    • It draws from credit, not just plan limits. The one-time credit applies automatically when you start a session, and it is separate from your weekly usage limits. Anthropic's framing: "If you hit a limit locally, keep going in the cloud until your credit runs out."

    The credit, precisely

    Pro Max
    One-time credit $100 $250
    Claim deadline 11:59 PM PT, Oct 7, 2026 11:59 PM PT, Oct 7, 2026
    Unused credit expires 11:59 PM PT, Nov 4, 2026 11:59 PM PT, Nov 4, 2026
    Eligibility Individual subscriber active Sept 23, 2026 Individual subscriber active Sept 23, 2026

    One credit per account. The credit covers cloud sessions only — not chat, not API calls, not local Claude Code. It applies before your regular plan usage, and once it's gone, cloud sessions count against your normal plan limits. There is no separate charge for the cloud container itself.

    What you need: a connected GitHub account, because every cloud session works against a repository. No GitHub, no session, no credit use.

    How to claim it

    1. Confirm your plan. Pro or Max, individual subscription, active on September 23.

    2. Connect GitHub. Required before a cloud session will start.

    3. Claim. Open claude.ai/code and use the Claim credit prompt, or run /claim-credit inside the Claude Code CLI.

    4. Start a session. From claude.ai/code, the Code tab in the Claude mobile app, the desktop app, or claude --cloud in the terminal. Anthropic also lists Routines as a starting point.

    5. Watch the dates. Claim by October 7; spend it by November 4. Last call as of today, October 6: the claim window closes 11:59 PM Pacific tomorrow, October 7, 2026. Claim it now — unclaimed credit disappears.

    Team and Enterprise users get cloud-session access through premium seats, but the $100/$250 promotional credit is the Pro/Max subscriber offer — evaluate the feature on its own merits if you're outside the promo.

    Under the hood

    Anthropic runs cloud sessions on fresh Ubuntu 24.04 virtual machines — roughly 4 vCPUs, 16 GB of RAM, 30 GB of disk, per published reports. Organizations that can't let source code run on a vendor's VMs can route sessions to self-hosted environments instead — a separate path from the consumer credit.

    Note the contrast with Remote Control: Remote Control connects a web or mobile interface to a Claude Code session running on *your own computer*, so that machine has to stay awake. Cloud sessions remove the machine entirely.

    Should you use it?

    Treat the credit as a trial budget. Point it at work that's easy to verify: bug fixes with test coverage, dependency updates, questions about a codebase. Check the branch and the pull request the agent produces before merging anything. Anthropic even describes auto-fix of pull requests directly in the cloud as a feature — still check the diff yourself.

    For occasional or non-technical users, be honest with yourself: the credit may go unused, because cloud sessions require a GitHub-connected coding workflow to begin with. That's worth knowing before you count on redeeming the full amount.

  • Claude Sonnet 5.5: Near-Opus Scores at the Sonnet Price

    Last verified: October 6, 2026 (Pacific).

    Direct answer: Anthropic released Claude Sonnet 5.5 on September 28, 2026 — the second model in the Claude 5.5 family, six days after Opus 5.5. The headline: $2 per million input tokens and $10 per million output tokens — the exact same price as Sonnet 5 — while Anthropic's benchmarks put it near Opus 5.5 on most evals and ahead of it on Terminal-Bench 4.0. A typical workload costs about 30% less than Sonnet 5, because the model uses fewer tokens per task.

    Same price, different model

    Anthropic describes Sonnet 5.5 as "a faster, lower-cost complement to Claude Opus 5.5," strongest at well-scoped everyday tasks, bug fixing, and creating polished documents, slides, and spreadsheets. The price table:

    Sonnet 5.5 Sonnet 5 Opus 5.5
    Input / output per 1M $2 / $10 $2 / $10 $4 / $20
    Cache reads per 1M $0.20 — $0.20
    Typical workload vs predecessor ~30% less — ~40% less

    Cache writes run $2.50 per million (5-minute) and $4.00 (1-hour). The Batch API halves input and output to $1/$5. The full 1M-token context window is billed at the standard rate — no long-context surcharge.

    The benchmarks, with Anthropic's own caveat attached

    These are Anthropic's numbers from its launch table. The company's own caveat is worth quoting in full: "Opus 5.5 remains clearly stronger at complex, open-ended work requiring sustained judgment." Read the table as a cheaper model closing most of the gap, not as a Sonnet that replaces Opus.

    Benchmark Sonnet 5.5 Sonnet 5 Opus 5.5
    Terminal-Bench 4.0 (agentic coding) 70.6% 10.3% 66.4%
    CursorBench 4.0 55.5% 34.1% 57.8%
    GDPval-AA v2.1 (knowledge work, Elo) 1844 1449 1846
    OSWorld 2.1 (computer use) 80.1% 57.0% 81.8%
    Humanity's Last Exam (with tools) 64.5% 54.9% 67.7%

    The Terminal-Bench number deserves a pause: 70.6% for a $2/$10 model beats not just Sonnet 5's 10.3% but Opus 5.5's 66.4%. That is the single most aggressive price-performance move in this release cycle. As always, validate against your own tasks before rerouting production traffic.

    Switching: what breaks

    Moving from Sonnet 5 to Sonnet 5.5 is not drop-in. Five documented breaking changes: disabled thinking, forced tool use, replaying thinking blocks across accounts, the old computer_20251124 tool on the API and Google Cloud, and using older models as advisors in the advisor tool. Test before you cut over.

    Separately: Sonnet 4.5 retires November 30, 2026, and Anthropic names Sonnet 5.5 as its replacement. If you still have 4.5 in a pipeline, that migration has a date on it. Sonnet 5 is not listed for retirement as of October 1.

    Worth knowing

    • Effort defaults differ by surface. High on the Claude Platform; medium in Claude Code and the Claude apps. Like Opus 5.5, effort is the first dial — tune it before rewriting prompts.
    • First Sonnet with Opus-class cyber safeguards. Anthropic says Sonnet 5.5's cyber capabilities are a large jump over Sonnet 5, so it ships with safeguards previously reserved for top models. Higher-risk cybersecurity prompts get detected and routed to Sonnet 5 instead; ordinary coding and bug-fixing are unaffected.
    • Where it runs. Claude apps, Claude Code, Claude Platform, Amazon Bedrock, Google Cloud, Microsoft Azure. Model ID claude-sonnet-5-5. 1M-token context, 128K max output, June 2026 knowledge cutoff.

    The honest read: Anthropic kept the sticker price flat and moved the performance. For everyday agentic coding and knowledge work, Sonnet 5.5 is now the default answer — until your workload is complex and open-ended enough that Opus 5.5's sustained judgment earns its 2x price. For the Opus side of that tradeoff, see our Claude Opus 5.5 release coverage.

  • Claude Opus 5.5: Fable-Level Performance at 40% Less Than Opus 5

    Last verified: October 5, 2026 (Pacific).

    Direct answer: Anthropic released Claude Opus 5.5 on September 22, 2026 — the first model in the Claude 5.5 family. It matches Claude Fable 5.1 on most work while costing 40% less to run on a typical workload than Opus 5. API pricing: $4 per million input tokens, $20 per million output tokens, 20% lower than Opus 5 across the board. Cache reads dropped 60% to $0.20 per million tokens. Opus 5 is now legacy.

    What actually changed

    Three moves at once: cheaper, faster, and smarter at using less effort.

    • Price. $4/$20 per million input/output tokens, down from Opus 5's $5/$25. Cache reads fell from $0.50 to $0.20 per million — a 60% cut.
    • Speed. Output generation is more than 30% faster than Opus 5. A faster serving mode runs 2.5x faster at double the price ($8/$40 per million tokens).
    • Effort. Opus 5.5 defaults to *medium* effort, one step below Opus 5's high default. Anthropic's testing found medium-effort 5.5 matches or beats high-effort Opus 5 on coding and knowledge work. Thinking cannot be turned off on Opus 5.5 — requests that try get an error.

    The benchmarks, with the caveat they deserve

    All numbers below are Anthropic-reported, not independently reproduced. Treat vendor benchmarks as direction, not gospel — validate against your own task corpus.

    Benchmark Opus 5.5 Fable 5.1 Opus 5
    Terminal-Bench 4.0 (agentic coding) 66.4% 55.8% 52.3%
    GDPval-AA v2.1 (professional work, 44 occupations) 1846 Elo 1735 1708
    AutomationBench (task completion) 40% — 26.9%
    FrontierCode (max effort) 54.4% 50.3% —

    Anthropic also claims Opus 5.5 at default effort beats Opus 5 at maximum effort on Terminal-Bench at about a fifth of the cost, and matches GPT-6 Astra there at roughly 40% of the cost. Cost-per-task is the more honest frame than headline margins.

    Prompting: effort is the first dial

    Anthropic published prompting guidance alongside the release, and the headline advice is simple: stop reusing your Opus 5 effort settings. The effort setting — low, medium, high, xhigh, max — is now the first control for balancing quality against speed and cost, before prompt changes.

    Two concrete changes worth making:

    1. Test effort levels directly. Don't assume high is better. In Anthropic's testing, medium 5.5 matches high Opus 5.

    2. Reconsider "think carefully" lines in chat apps. Opus 5.5 decides for itself how much to think, with effort as the main control. Anthropic's own test showed removing a think-carefully instruction made replies start sooner with no clear quality drop.

    Opus 5 prompts still work without edits — the existing guidance is a reasonable starting point. Adjust effort before rewriting prompts, and reserve xhigh and max for tasks where quality really moves.

    Availability and context

    Opus 5.5 ships on Anthropic's platform and through AWS, Google Cloud, and Azure. It carries a 1M-token context window with 128K maximum output. Before launch, external evaluators including Frontier Design and METR tested the model, and Anthropic says it recorded its best result to date on the company's automated behavioral audit.

    This is the first release since CEO Dario Amodei's September essay calling on the industry to pace frontier development — and Anthropic shipped it with the same cybersecurity and biosafety measures as Fable 5.1, plus published evaluator access, which is the pacing commitment in concrete form.

    The rest of the family is filling in: Sonnet 5.5 landed September 28 at $2/$10 with the same $0.20 cache reads and 30%+ speed gain over Sonnet 5, and Haiku 5.5 is listed as coming soon. For the full lineup and legacy status, see our Claude Release History (Sept 2026).

  • Claude vs the Field: Benchmarks, Reddit Consensus & Honest Alternatives

    Claude vs the Field: Benchmarks, Reddit Consensus & Honest Alternatives

    Last verified: October 5, 2026. Every other guide on this site assumes you've chosen Claude. This one is for before that — the choosing itself. Benchmarks, crowd consensus, the honest alternatives list, and the one head-to-head that matters most for developers. Four deep dives, one hub.

    The benchmarks: who actually codes best

    A primary-source coding leaderboard for the top models of June 2026 — Claude Fable 5, Claude Opus 4.8, GPT-5.5, and Gemini 3.1 Pro — with price and context alongside the scores. Benchmarks aren't the whole story, but they're the least biased starting point.

    → Claude vs GPT-5 vs Gemini: 2026 Coding Benchmarks — the leaderboard: scores, price, and context.

    The crowd: what Reddit really says

    Benchmarks measure models; Reddit measures living with them. The genuine crowd consensus from r/ClaudeAI, r/ChatGPT, and the comparison threads — on writing, coding, and integrations.

    → Claude vs ChatGPT in 2026: Reddit Community Consensus — writing, coding, integrations, in the community's own words.

    The alternatives: the honest list

    Claude isn't the only answer and sometimes it's the wrong one. The honest comparison of the 2026 alternatives — ChatGPT, Gemini, Perplexity, Grok, Copilot, and others — with pricing, strengths, weaknesses, and which fits which job.

    → Claude AI Alternatives in 2026: ChatGPT, Gemini, Perplexity, and How They Compare — pricing, strengths, weaknesses, best fits.

    The developer's head-to-head: Claude Code vs Codex CLI

    For the terminal crowd, the choice narrows to two: Claude Code vs OpenAI's Codex CLI. A working operator's side-by-side — install commands, models, pricing, config and sandbox behavior — with a clear call on which to pick.

    → Claude Code vs Codex CLI (2026): A Hands-On Head-to-Head — install, models, pricing, sandbox behavior, and the verdict.


    Four deep dives, one hub. The benchmarks for the scores, Reddit for the lived experience, the alternatives for the full field, and Code vs Codex for the developers.

  • We Retired the Living Leaderboard. Date Your AI Comparison Pages.

    We Retired the Living Leaderboard. Date Your AI Comparison Pages.

    Direct answer: a living AI model leaderboard rots. On the public Claude 4.6 vs GPT-5 leaderboard we replaced the promise that standings were “continuously updated by our autonomous tracker” with a September 2026 editor’s note. The table stayed. The date stayed. The page is now a snapshot of the race on 30 May 2026 — not a live scoreboard.

    If an answer engine cites an undated comparison as current, it will be wrong within a release cycle. Date the page. Point prices at a desk you actually re-verify. Leave last season’s Elo alone unless you re-measured it.

    What changed on the public pages

    Three live URLs now say the same thing in different words:

    • Claude 4.6 vs GPT-5: The 2026 Leaderboard — editor’s note that the autonomous tracker retired after the 30 May 2026 update. The LMSYS box still reads Last Updated: 2026-05-30, with Claude 4.6 Sonnet (Elo 1345), GPT-5 Early Preview (Elo 1338), and Claude 4.6 Haiku (Elo 1312). Those numbers were not rewritten this month.
    • Claude 4.6 Roadmap: Guide for Technical Founders — September 2026 editor’s note at the top of the body: the roadmap is a May 2026 generation snapshot. Stop 2 now points at the leaderboard snapshot for where Claude 4.6 stood against GPT-5 in May 2026.
    • Anthropic Slashes Claude 4.6 Haiku API Pricing by 40% — September 2026 outcome note. The phrase “verified Claude pricing page” goes to the live desk at /claude-ai-pricing/, not to a second rate card buried in the old post.

    Titles and slugs did not move. The old URLs are the record.

    Why a “living” leaderboard fails the reader

    Model names, list prices, and context windows moved several times between that May snapshot and late September 2026. The live Claude desk we keep — last verified 23 September 2026 against Anthropic’s own pages — is a different document from a May Elo box. Mixing them on one URL trains both humans and models to treat last season’s table as this week’s answer.

    That is an AEO problem and a GEO problem. Answer engines prefer a short, dated sentence they can lift. Generative engines prefer a page that does not contradict the next page in your cluster. A tracker you cannot staff is worse than a snapshot you labeled.

    The method: snapshot the race, live-link the meter

    1. Put the as-of date in the first screen. “Last Updated: 2026-05-30” in the box. “Editor’s note (September 2026)” above it. Two dates, two jobs: when the numbers were taken, when you admitted they froze.
    2. Do not invent a new leaderboard you did not run. We did not scrape LMSYS tonight. We did not publish a September Elo column. If the measurement is not in the room, the number does not go on the page.
    3. Send current prices to one desk. Token rates and seats live on Claude Pricing (September 2026). The Haiku cut post now points there. A short companion on the 22 September Opus list sits at Claude Opus 5.5 Cuts Token Price 20% — $4 / $20 List. Quote the desk. Do not fork a third table.
    4. Keep the historical URL. Changing the slug of a comparison page that already earned links and citations throws the evidence away. Date the body. Leave the address.
    5. Say what the page is not. A May snapshot is not a buying guide for today’s default model. A 40% Haiku headline from an earlier cycle is not the live list. The pricing desk is the live list.

    What we would not claim

    • We would not claim a September 2026 LMSYS or Arena ranking. We did not pull one for this note.
    • We would not claim Claude 4.6 is still the current default. The live desk names current Opus, Sonnet, Haiku, and Fable lines separately. Read that page for names and rates.
    • We would not restated a full rate card here. Rates move. The desk is dated 23 September 2026 and cites claude.com/pricing and platform.claude.com.
    • We would not describe internal work orders, agents, or edit packets. Those are not the public record. The public record is the three URLs above.

    How to write the editor’s note so an answer engine can use it

    Keep the note to one sentence that answers “is this current?” Then link the current desk.

    Pattern we used: Editor’s note (Month Year): the living tracker was retired after [snapshot date] — the standings below are preserved as a snapshot of the race at that point.

    That sentence is the AEO payload. It is short. It names the freeze date. It tells a model not to treat the table as live. GEO follows if the rest of the cluster agrees: founder roadmap says snapshot, pricing post says “go to the desk,” desk says last verified.

    FAQ

    Q: Should I delete an old model comparison?
    A: No, if the URL already has links or citations. Label it a snapshot, keep the slug, and point current buyers at the live desk.

    Q: When does a snapshot need a new page instead of an editor’s note?
    A: When the question changed. “Where did Claude 4.6 sit vs GPT-5 in May 2026?” is a history question. “What does Claude cost this week?” is a desk question. Different questions get different URLs.

    Q: Can I keep a living tracker?
    A: Only if someone re-measures on a published cadence and the page shows the last run date. A tracker you do not run is a lie with a progress spinner.

    Q: Where are current Claude prices?
    A: tygartmedia.com/claude-ai-pricing/, last verified 23 September 2026 against Anthropic’s public pricing pages. Confirm Anthropic before you quote a customer.

    Q: Does this mean the May Elo numbers were wrong?
    A: It means they are dated. They remain the numbers printed on that page for 30 May 2026. They are not a September 2026 ranking.

    Sources

    • Live pages on tygartmedia.com, read 24 September 2026: leaderboard snapshot, founder roadmap snapshot note, Haiku pricing outcome note, Claude pricing desk (desk last verified 23 September 2026).
    • Official Anthropic seats and API tables linked from the pricing desk: claude.com/pricing and platform.claude.com pricing.

    Related on Tygart Media: May 2026 leaderboard snapshot · founder roadmap snapshot · Haiku pricing note · live Claude pricing desk · Opus 5.5 list-price note · the site has to be the answer.

    I write pages like this so AI search cites a dated sentence instead of last season’s table — then I do the same for operators who publish. That’s what Tygart Media does.

  • Claude Updates September 2026: Fable 5.1, One Claude, Docs & Slides

    Last verified: October 5, 2026 (Pacific Time). The June 2026 edition covered the Fable 5 public launch, the June 15 model retirements, and Managed Agents self-hosted sandboxes.

    Direct Answer (September 2026 Update): September’s biggest move is economic, not a new flagship: Claude Fable 5.1 (released September 1) cuts cache-read pricing 75%, which Anthropic says makes typical workloads about 25% cheaper. The same day brought the restricted-access Mythos 5.1 and Enterprise Frontier Safeguards. Mid-month, Anthropic shipped vertical plugins for financial advisors (Sept 14) and a major small-business expansion (Sept 15), then folded Cowork into a single Claude experience with Docs and Slides in beta (Sept 16).

    September 2026 is Anthropic’s enterprise-monetization month: no new flagship tier, but cheaper agentic workloads, a compliance-ready data story, and the product surface consolidating around one Claude. Here is everything dated, with the numbers and the migration notes.

    Claude Fable 5.1 and Mythos 5.1 — cache reads cut 75% (September 1, 2026)

    Anthropic released Claude Fable 5.1 on September 1, 2026, alongside Claude Mythos 5.1. The two are the same underlying model at different safeguard tiers: Fable 5.1 is generally available; Mythos 5.1 is restricted to vetted organizations through Anthropic’s Project Glasswing trusted-access program, initially in cybersecurity and life-sciences work.

    The headline is pricing, not capability. Base rates are unchanged — $10 per million input tokens, $50 per million output — but cache reads fall from $1.00 to $0.25 per million tokens, a 75% cut. Anthropic’s own estimate: typical workloads get ~25% cheaper, highly agentic ones up to 45%. Treat those as vendor math — the savings scale entirely with how cache-heavy your workload is.

    The practical details:

    • Model ID: claude-fable-5-1
    • Context window: 1M tokens; max output 128K
    • Benchmarks: 52.6% on Terminal-Bench-Science 0.1 (vs 24.7% for Fable 5); 42% → 55.8% on Terminal-Bench 4.0
    • Safeguard friction down: ~60% fewer cybersecurity false positives per Claude Code session; 85% fewer interventions on benign biology and medical requests. Fable 5.1 can identify software vulnerabilities but blocks penetration testing, exploit generation, and binary-based vulnerability scanning
    • Availability: Claude API, Amazon Bedrock, Google Cloud Vertex AI, Microsoft Foundry, and the Claude app
    • Migration is not a string swap: breaking changes include forced tool use, thinking blocks, and edited conversation histories. Prefix-binding enforcement began August 31 for newly created API accounts. Anthropic’s stated retirement horizon: no earlier than September 1, 2027
    • Claude Code 2.1.257 makes Fable 5.1 the default Fable model (gateway aliases excepted)

    Enterprise Frontier Safeguards — phased rollout through fall 2026

    Alongside the models, Anthropic announced Enterprise Frontier Safeguards (EFS), a new security architecture that lets organizations keep monitoring data inside infrastructure they control, with zero-retention options for Fable 5 and 5.1. The company acknowledged that Fable 5’s 30-day data-retention requirement had limited adoption by regulated enterprises — EFS is the answer, rolling out in phases through fall 2026. For healthcare, finance, and legal buyers, this is the compliance unlock that makes the cheaper agentic workloads actually purchasable.

    Provenance tooling: limited-access watermark detection (September 2, 2026)

    On September 2, Anthropic opened a limited-access API that detects invisible watermarks in Claude-generated text. Access is restricted to organizations with a verification mandate — newsrooms, regulators, independent researchers, professional fact-checkers. Regular users and companies embedding Claude don’t get it. The design is deliberate: it gives watchdogs a provenance tool while limiting adversarial probing of the signal.

    Fable 5.1 lands on Claude for Government (September 9, 2026)

    Teresa Carlson, Anthropic’s global head of public sector, announced at the Billington Cybersecurity Summit on September 9 that Fable 5.1 is now available on Claude for Government, the company’s FedRAMP High-authorized platform — meaning any agency requiring FedRAMP High can use it. AWS had made the model available in its US government cloud the prior week. Carlson signaled more government-focused releases in the coming weeks.

    Claude for Financial Advisors (September 14, 2026)

    Anthropic released Claude for Financial Advisors, a plugin bundling connectors to custodians, asset managers, and wealth-tech providers with workflow skills built around an advisor’s day. It’s available to Enterprise customers through the Cowork plugin browser. Connectors include Charles Schwab, BlackRock, Addepar, Envestnet, iCapital, Orion, SS&C Black Diamond, Wealthbox, Wealth.com, Vanguard, and Zocks — alongside existing Microsoft 365, Salesforce, DocuSign, Box, FactSet, S&P Global, and Morningstar integrations. Packaged skills cover advisor onboarding, alternative-investments briefing, compliance and AI-policy review, estate and tax briefing, portfolio-rebalance review, post-meeting notes and follow-up, pre-meeting preparation, and prospect intake. The pattern matches June’s legal vertical bundle: Anthropic is shipping industry-specific integration packs instead of leaving the ecosystem to build them.

    Claude for Small Business: 43 workflows, 27 integrations (September 15, 2026)

    Anthropic expanded Claude for Small Business on September 15, growing the plugin to 43 workflows and adding 27 integrations including Shopify, Salesforce, TikTok, Atlassian, Zoom, Xero, Gusto, Square, Stripe, and Zapier. It runs inside Claude Cowork: owners install the plugin, run /smb-onboard, connect their tools, and pick a task. Every workflow starts in approval mode — Claude drafts and stages the work, then waits for the owner’s approval before anything sends, posts, or pays — and owners can flip a single workflow to autonomous and back. Example workflows: a Monday brief assembling cash position, week-over-week sales, pipeline movement, overdue invoices, and the three things needing the owner; inbound-lead response; branded proposals priced from past jobs; staged marketing campaigns; month-end close. The plugin is available on every paid Claude plan; Anthropic recommends the Team plan for businesses with more than one person. A fall schedule of free in-person workshops, partner webinars, and community-run training ships with it.

    One Claude: Cowork folds in, Docs and Slides launch in beta (September 16, 2026)

    Anthropic announced September 16 that Claude Cowork and Claude chat are merging into a single Claude, rolling out to Pro and Max plans over the coming weeks. No mode to choose: users describe what they need, and Claude decides whether to answer directly or take on the bigger job — research, reports, spreadsheets, presentations — handing back finished, editable files. Two new tools launch in beta for paid users: Claude Docs (create and edit documents inside a conversation) and Claude Slides (generate presentations — editable, downloadable as PowerPoint or PDF, exportable to Google Docs or Microsoft Word, with shareable links across desktop and mobile). Anthropic’s stated reason: users found it frustrating to decide where a task belonged, since work started in one product didn’t carry into the other. The Cowork arc that led here: research preview for Max on macOS (January 12), Pro (January 16), general availability on macOS and Windows (April 9), web and mobile (July 7), memory shared across chat and Cowork in the cloud (August 25).

    Late September: Opus 5.5 and Sonnet 5.5 (September 22–28, 2026)

    After the mid-month product wave, Anthropic shipped the Claude 5.5 family: Opus 5.5 on September 22 at $4 / $20 per million tokens (20% below Opus 5), then Sonnet 5.5 on September 28 at the same $2 / $10 unit price as Sonnet 5. Official sources: anthropic.com/claude-opus-5-5, anthropic.com/claude-sonnet-5-5, and the live rate card on docs pricing.

    Current Claude model lineup and API pricing (October 2026)

    Model Input $/1M Output $/1M Cache read
    Fable 5.1 $10 $50 $0.25
    Opus 5.5 $4 $20 $0.20
    Sonnet 5.5 $2 $10 $0.20
    Haiku 4.5 $1 $5 $0.10

    5-minute cache writes are 1.25× base input; 1-hour writes are 2×. Batch API is 50% off input and output. Full table and seat pricing live on our Claude AI pricing guide.

    What to watch for in October

    • One-Claude rollout: the unified experience continues rolling out to Pro and Max; Docs and Slides are still in beta — watch for GA and Team/Enterprise availability.
    • Enterprise Frontier Safeguards: phased rollout continues through fall 2026; the zero-retention option is the milestone regulated buyers are waiting on.
    • Government releases: more Claude for Government announcements were telegraphed for the coming weeks.
    • IPO watch (reported, not confirmed): Bloomberg and Fortune reporting positions Anthropic for an October 2026 public offering. No official date — treat as rumor until the filing.

    Sources

    Track the AI tools you actually use

    Live, vendor-neutral prices & limits for ChatGPT, Claude, Gemini, Perplexity and more — and we’ll email you the moment your tools change price or limits. Free, no hype. See our live AI model tracker.