Claude AI - Tygart Media

Category: Claude AI

Complete guides, tutorials, comparisons, and use cases for Claude AI by Anthropic.

  • Claude Code Plan Mode: How to Use It, When to Skip It (2026 Guide)

    Claude Code Plan Mode: How to Use It, When to Skip It (2026 Guide)

    Published: May 25, 2026 | Last fact-check: May 25, 2026 against Anthropic docs and Claude Code v2.1+ behavior

    Quick Answer

    Plan Mode is a Claude Code setting that forces the agent to think through and approve a plan before taking destructive actions. Trigger it with Shift+Tab pressed twice in the terminal (the first press cycles to Auto-Accept Mode; the second lands on Plan Mode). Use it for risky multi-step work; skip it for simple read-only or contained edits.

    How to enable it, when it pays off, and when it gets in your way below.

    Plan Mode (sometimes called “planning mode”) is one of the more underused features in Claude Code in 2026. It changes how the agent works in a specific, measurable way: before Claude Code edits files, runs commands, or modifies state, it produces a plan and waits for your approval. You see what it intends to do, you say yes or no, and only then does it act.

    For the right kind of task, Plan Mode is the difference between a clean execution and a regrettable one. For the wrong kind of task, it is friction that slows you down. This guide separates the two.

    Claude Code Plan Mode vs Auto Mode: When to Use Each
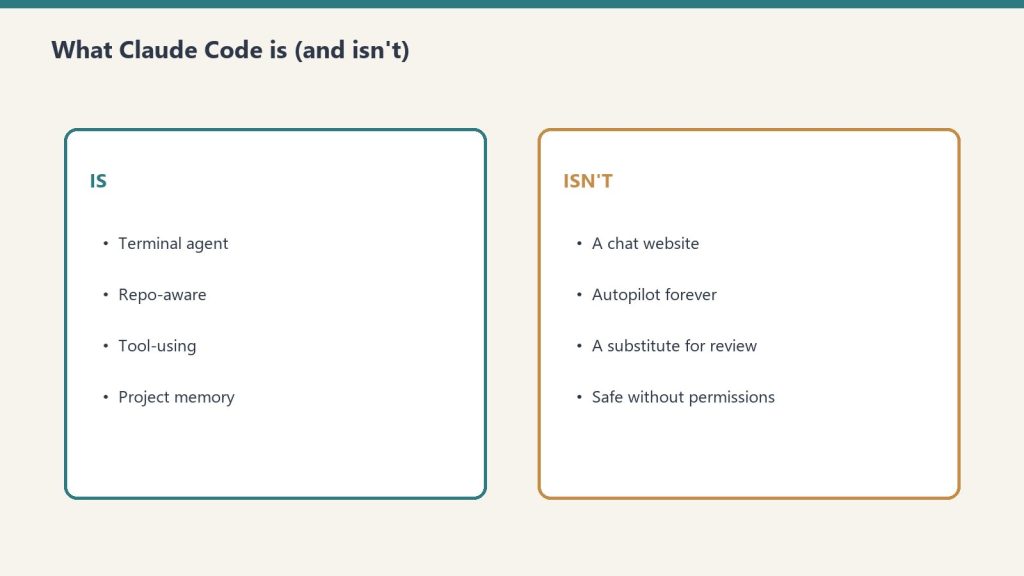
    Side-by-side cards defining what Claude Code is and is not
    Plan Mode vs Auto Mode — when to use each.
    ScenarioUse Plan ModeUse Auto Mode
    Unfamiliar codebaseYes — review the plan firstOnly if you know it well
    Large multi-file refactorYes — catch scope creep earlyNot recommended
    Simple bug fix (< 5 lines)OverkillYes
    Adding a new featureYes — plan clarifies approachAcceptable for small features
    Writing testsOptionalYes, usually safe
    Touching database migrationsYes — irreversible changesNo
    CI/CD pipeline changesYesNo

    What Plan Mode Actually Does

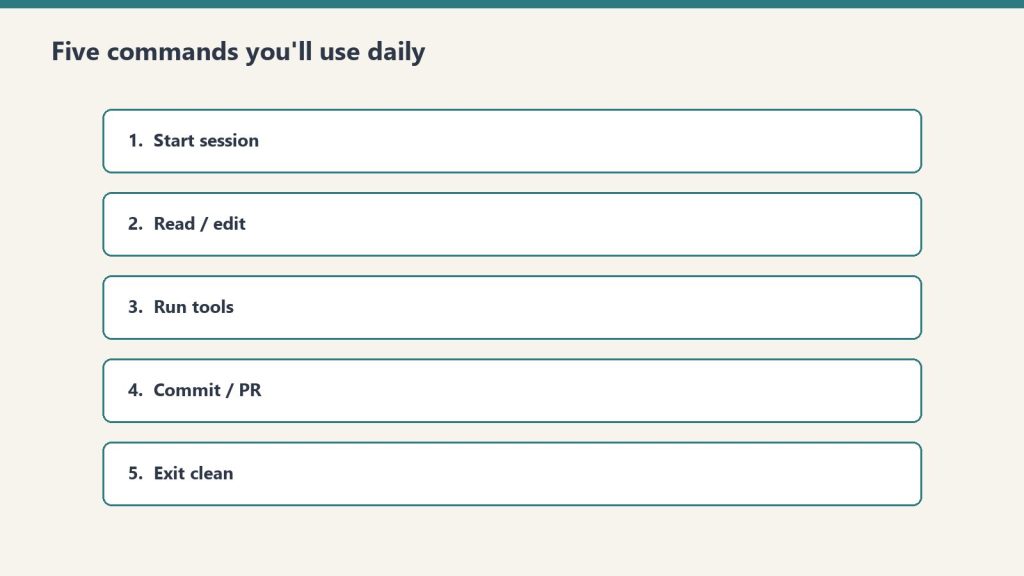
    Five stacked panels of daily Claude Code command habits
    What Plan Mode actually does.

    In default mode, Claude Code is allowed to take actions as it reasons. It can read files, write files, run bash, edit code, all in one conversational flow. This is the strength of Claude Code as an agent — it gets work done without asking permission for every step.

    In Plan Mode, Claude Code’s behavior changes:

    1. You describe the task.
    2. Claude Code investigates the codebase (read-only operations are still allowed).
    3. Claude Code drafts a plan listing every file it intends to change, every command it intends to run, and every decision point.
    4. You read the plan. You approve it, modify it, or reject it.
    5. Only after approval does Claude Code start writing files or running commands.

    The plan is presented in the terminal as a structured outline. You can ask Claude Code to revise the plan, add steps, remove steps, or change the order. Iterating on the plan is fast because no actions have been taken yet.

    How to Enable Plan Mode

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How to enable Plan Mode.

    There are four ways to activate Plan Mode in Claude Code:

    1. Shift+Tab pressed twice. Each press of Shift+Tab cycles through the three permission modes: Default → Auto-Accept → Plan → Default. Two presses lands on Plan Mode. The status bar shows ⏸ plan mode on when active.
    2. The /plan slash command. Type /plan at the start of any prompt to enter Plan Mode for that turn only. Useful for one-off plans without flipping the whole session.
    3. The –permission-mode plan flag at startup. Start the session in Plan Mode from the command line.
    4. Headless mode for scripts and CI. claude --print --permission-mode plan "your task" for automation that should never edit files.
    # Start session in Plan Mode
    claude --permission-mode plan
    
    # Or mid-session — press Shift+Tab TWICE
    # (first press = Auto-Accept Mode, second press = Plan Mode)
    
    # Or one-shot Plan Mode for next prompt only
    /plan

    Plan Mode is persistent within a session — it stays on until you cycle out with another Shift+Tab. Close and reopen Claude Code and it defaults back to off. Toggle it on for risky work, leave it on for the whole session if you are doing higher-risk work end-to-end.

    Important: Plan Mode is a hard read-only sandbox enforced at the tool level. Claude Code physically cannot edit files, run commands, or modify state while Plan Mode is active. This is not a suggestion or a soft check — the write tools are unavailable.

    When Plan Mode Pays Off

    Plan Mode is worth the friction in these situations:

    • Multi-file refactors. When the agent will touch 5+ files, you want to see the list before it starts editing. A small confusion about which files to change becomes a big mess fast.
    • Database migrations or schema changes. Anything that touches durable state and is hard to undo benefits from a confirmed plan.
    • Production code paths. If a session affects code that ships to users, the plan checkpoint is cheap insurance.
    • Ambiguous instructions. When you are not sure how the agent will interpret your request, Plan Mode surfaces the interpretation before any work happens.
    • New repository onboarding. When you do not yet know the codebase well, Plan Mode lets the agent show you what it learned during investigation before it acts.
    • Long-running batch jobs. Approving a plan for 200 file edits and then walking away is safer than launching 200 edits blind.

    When Plan Mode Gets In the Way

    Plan Mode is not free. The friction it adds is a real cost for certain workflows:

    • Single-file tweaks. Asking Claude Code to fix a typo or rename a variable does not need a plan. The plan takes longer than the fix.
    • Tight feedback loops. When you are iterating quickly — try a change, see the result, adjust — Plan Mode slows the loop. Default mode wins here.
    • Read-only investigation. If you are asking questions about the codebase (“how does this auth flow work”), there is nothing to plan. Plan Mode is irrelevant.
    • Work in a sandbox. If you are working in a throwaway directory or branch where mistakes are cheap, the safety net of Plan Mode is overkill.

    The decision is not “is Plan Mode good.” It is “is the cost of approval less than the cost of an unintended action.” For risky multi-step work, yes. For cheap iteration, no.

    Working Inside the Plan

    Once Claude Code presents a plan, you have several options:

    1. Approve as-is. Tell Claude Code to proceed. It executes the plan in order.
    2. Approve with modifications. Tell Claude Code to remove specific steps, reorder them, or add additional steps. It revises the plan and re-presents.
    3. Ask questions. Drill into specific steps. “Why are you editing file X?” Claude Code explains the reasoning.
    4. Reject and restart. If the plan is wrong-shape, tell Claude Code so. It will rebuild the plan from a corrected understanding.
    5. Cancel. Exit Plan Mode entirely if you’ve decided this is not the right task or session for it.

    The plan is conversational. You are not stuck with the first draft. Iterating on the plan is much cheaper than iterating after the work is done.

    What Plan Mode Does Not Protect Against

    Plan Mode is not a sandbox. The plan, once approved, executes for real. Plan Mode does not:

    • Prevent you from approving a bad plan
    • Catch logic errors inside individual file edits
    • Prevent destructive bash commands if you approved them in the plan
    • Replace tests or code review

    It is a thinking checkpoint, not a safety net. The human still owns the decision.

    Plan Mode vs Other Safety Patterns

    Plan Mode is one of several safety patterns Claude Code supports:

    • Read-only sessions: Restrict the agent to read operations only.
    • Per-tool permissions: Approve each tool use individually as it happens.
    • Plan Mode: Approve a batch of intended actions before execution begins.
    • Auto-accept mode: The opposite — accept all tool uses without asking. Fast and risky.

    Per-tool permission is more granular but slower. Plan Mode is bulkier but faster once approved. Use the right tool for the situation; do not assume one is always correct.

    A Working Habit

    The habit that has worked across hundreds of Claude Code sessions: default mode on, Shift+Tab twice into Plan Mode before any session that will (a) touch production state, (b) edit more than 5 files, or (c) run commands that are hard to undo. Shift+Tab again to cycle back to default for everything else.

    The shortcut becomes muscle memory in a week. Once it is muscle memory, the cost of Plan Mode drops to nearly zero, and you can use it liberally on anything that even smells risky.

    Related on Tygart Media: Claude Code getting started · Claude Code Router · Claude Code tutorial.

    Frequently Asked Questions

    What is Plan Mode in Claude Code?

    Plan Mode is a Claude Code setting that forces the agent to produce a written plan and wait for your approval before making changes. It surfaces what the agent intends to do so you can adjust it before any work happens.

    How do I enable Plan Mode in Claude Code?

    Press Shift+Tab twice in the terminal (the first press cycles to Auto-Accept; the second lands on Plan Mode), type /plan as a slash command, or start the session with –permission-mode plan. The status bar shows ⏸ plan mode on when active.

    When should I use Plan Mode?

    For multi-file refactors, database migrations, production code paths, ambiguous instructions, new repositories you don’t know yet, and long-running batch jobs. Skip Plan Mode for single-file tweaks, tight iteration loops, and read-only investigation.

    Does Plan Mode make Claude Code slower?

    Yes, for short tasks — the plan adds latency that is not worth it on quick edits. For long or risky tasks, the plan is faster than fixing mistakes afterward.

    Can I edit the plan before approving it?

    Yes. Tell Claude Code to revise the plan — add steps, remove steps, reorder. Iterating on the plan is much cheaper than iterating after execution.

    Is Plan Mode the same as a sandbox?

    Plan Mode IS a hard read-only sandbox at the tool level — Claude Code cannot write files or run commands while it’s active. But once you approve the plan and exit Plan Mode, the work executes for real. Plan Mode prevents accidental writes during planning; it does not prevent you from approving a bad plan.

    What’s the difference between Plan Mode and per-tool permissions?

    Per-tool permissions ask you to approve each tool use individually as it happens (more granular, slower). Plan Mode batches all intended actions into one plan you approve up front (bulkier, faster once approved).

    The Bottom Line

    Plan Mode is leverage for risky work and friction for everything else. Make Shift+Tab+Shift+Tab muscle memory. Use Plan Mode whenever the cost of an unintended action exceeds the cost of approval — multi-file refactors, production changes, ambiguous specs. Skip it on cheap iteration. That single rule will save you more headaches than any other Claude Code habit.
  • Claude Code Router: OpenRouter, Models & Custom Rules

    Claude Code Router: OpenRouter, Models & Custom Rules

    Published: May 25, 2026 | Last fact-check: May 25, 2026 — legacy (still listed) model lineup: Opus 4.7, Sonnet 4.6 (legacy — still listed), Haiku 4.5

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    Quick Answer

    A Claude Code router is any layer that decides which Claude model handles which request — Opus for hard reasoning, Sonnet for daily work, Haiku for fast cheap tasks. Anthropic ships some built-in routing, but the most leveraged users build their own routing rules on top to optimize cost and latency.

    Built-in routing, manual model selection, and the third-party router landscape below.

    “Claude Code router” is a phrase that means different things to different people in 2026, and the differences matter for what you should actually build or buy.

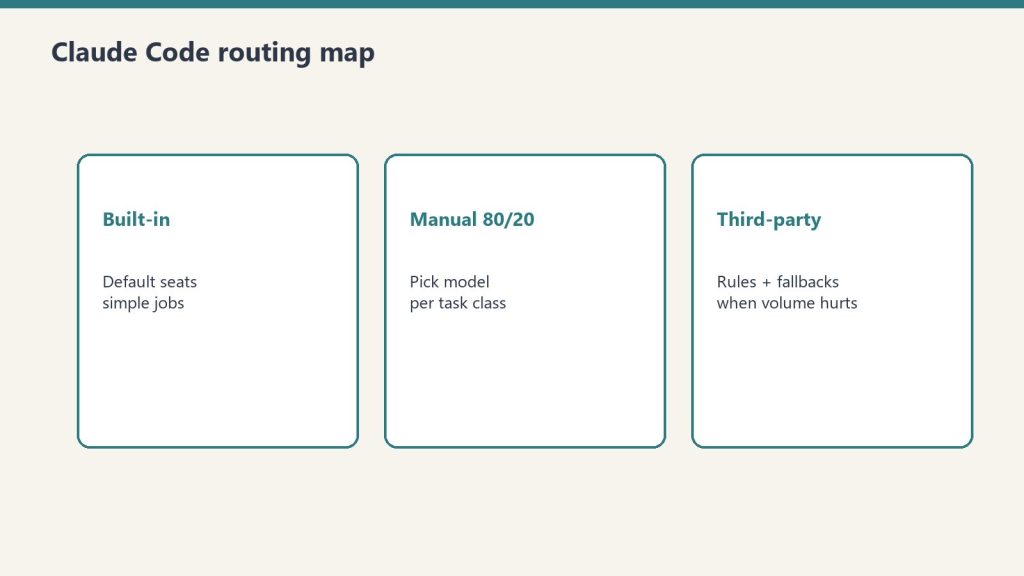
    It can mean (1) Anthropic’s built-in logic that picks a model when you do not specify one, (2) third-party tools that route between Anthropic models and other LLMs through one Claude Code interface, or (3) custom routing rules you build yourself to match models to tasks. This guide walks through each, when each makes sense, and the trade-offs.

    Why Routing Matters in the First Place

    Three routing approaches: built-in, manual 80/20, third-party
    Why routing matters before you touch third-party routers.

    Claude is not one model. It is a family. As of 2026 the production tiers are roughly:

    • Claude Opus 4.7 — $5/$25 per million tokens. Current flagship. Best for hard, ambiguous, multi-step reasoning and agentic coding.
    • Claude Sonnet 4.6 (legacy — still listed) — $3/$15 per million tokens. The workhorse. Within ~1 point of Opus on coding benchmarks at 40% less cost. Right answer for 80% of daily work.
    • Claude Haiku 4.5 — $1/$5 per million tokens. Fast and cheap. Right answer for high-volume formulaic tasks: classification, extraction, formatting, routing, simple Q&A.

    Output costs 5x input across all three tiers. Prompt caching cuts cached input costs by ~90%. Batch API cuts everything by 50% if you can wait up to 24 hours.

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    Using Opus for everything is wasteful. Using Haiku for everything is sloppy. Routing — matching the model to the task — is how you get the best output for the lowest cost. For someone running Claude Code several hours a day, intelligent routing is the difference between a $100/month Max bill and a $1,000/month API bill for the same work.

    Anthropic’s Built-In Claude Code Routing

    When you launch Claude Code without specifying a model, it picks a default. As of 2026 the default for most users is Sonnet, with Opus accessible via flags or settings, and Haiku used internally for some sub-tasks like tool selection and simple file operations.

    You can override the default at session start:

    # Start Claude Code with Opus for a tough refactor
    claude --model claude-opus-4-7   # current flagship
    
    # Or set it in your settings.json
    {
      "model": "claude-sonnet-4-6"  // current workhorse
    }

    Anthropic also routes internally: when Claude Code uses sub-agents for parallel work, it can route those sub-agents to lighter models automatically. This routing is opaque to you and generally well-tuned. You usually do not need to think about it.

    Manual Model Selection: The 80/20 Approach

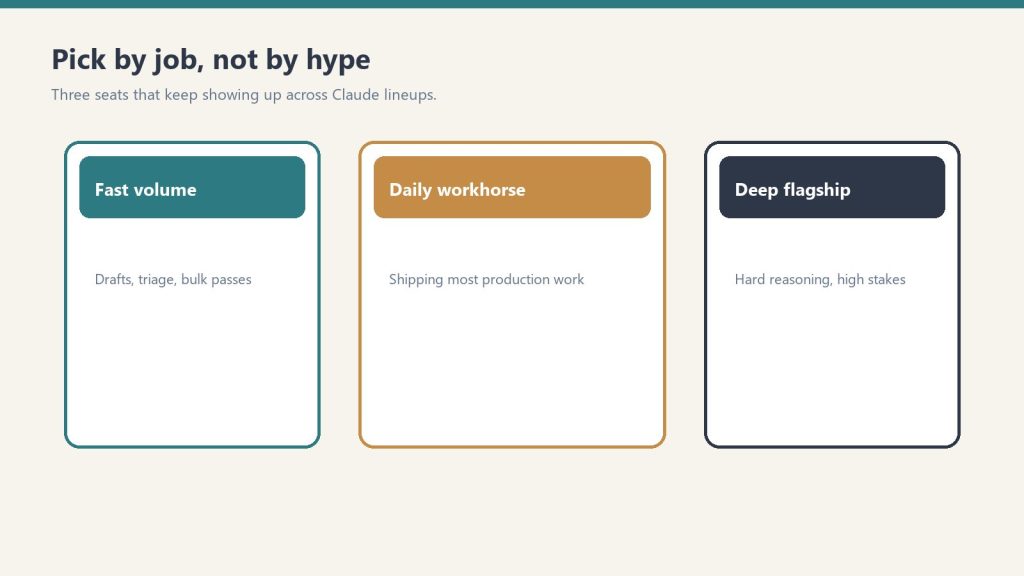
    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    Manual model selection is still the 80/20 approach.

    For most users, manual routing beats automatic routing. The rule:

    • Sonnet by default. Daily work, content drafts, code edits, file operations, debugging.
    • Opus when you hit a wall. Architectural decisions, hard refactors, ambiguous specs, anything that requires real reasoning.
    • Haiku for batch. Classification, taxonomy assignment, metadata generation, SEO meta descriptions, anything formulaic at volume.

    This 80/20 split is achievable with two or three commands and zero infrastructure. It is the right starting point.

    Third-Party Claude Code Routers

    A small ecosystem has emerged around third-party routers that sit between Claude Code and the model layer. The two most common patterns:

    OpenRouter and Multi-Provider Routers

    OpenRouter is the most widely used third-party router. You point Claude Code at OpenRouter as the API endpoint, and OpenRouter routes your requests to Claude (or to GPT, Gemini, DeepSeek, Llama, etc.). Why use it:

    • You want fallback when Anthropic has an outage.
    • You want to mix Claude with other models on a per-task basis.
    • You want a single billing surface across providers.
    • You want BYOK (bring your own key) routing where you mix your own provider keys.

    The trade-off: latency adds a few hundred milliseconds per call, and some Anthropic-specific features (prompt caching, certain beta tools) work less smoothly through the proxy.

    Custom In-House Routers

    Larger teams build their own routing layer. A typical pattern: a small Python or TypeScript service that inspects the incoming request, applies routing rules (length thresholds, task type detection, cost ceilings), picks a model, and forwards the call to Anthropic.

    This is overkill for most individuals. It pays off when you have:

    • Strict cost controls that need enforcement, not suggestion
    • Multi-tenant usage where different customers get different models
    • Compliance requirements that need request inspection and logging
    • A real engineering team that can maintain the service

    Routing Rules That Actually Work

    If you are going to invest in any routing logic, these are the rules that pay back:

    1. By task type. Code review → Opus. New code generation → Sonnet. Format conversion → Haiku.
    2. By input length. Long context (40K+ tokens) where you need careful reasoning → Opus. Long context where you need extraction → Sonnet with prompt caching.
    3. By cost ceiling. Anything over a threshold token count gets a hard cap or downgrade.
    4. By time of day. Overnight batch jobs route to cheaper models. Interactive daytime work routes to your preferred quality tier.
    5. By failure recovery. If a Sonnet call returns a low-confidence or refused response, retry once with Opus before giving up.

    Most of these rules are five lines of code each. The discipline is more about deciding the rules than implementing them.

    What Anthropic Does Not Yet Ship

    As of writing, Anthropic does not ship a built-in “route this query to the right model” intelligence layer in Claude Code. The model you set is the model you get for the session, with the exception of internal sub-agent routing.

    This is likely to change. The shape of where Claude Code is going — more autonomy, longer sessions, more parallel agents — implies more sophisticated internal routing. For now, the routing decisions worth making are the ones you make yourself.

    Costs: What Routing Actually Saves

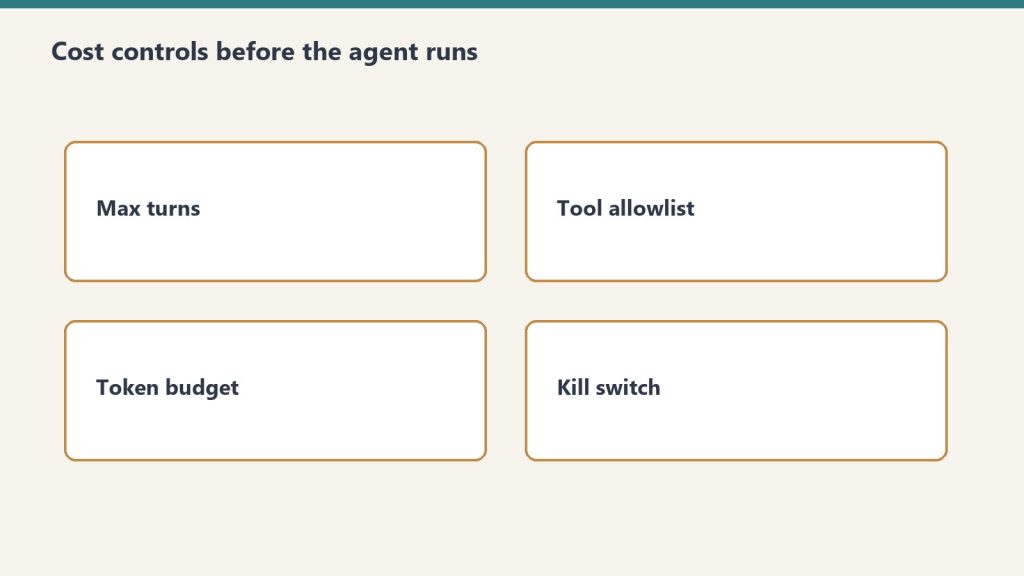
    Cost control panels for routing budgets
    Routing only saves money if you enforce budgets.

    Concrete example. An operator running a Claude Code content pipeline that:

    • Drafts articles (Sonnet): 8,000 input + 4,000 output tokens per article
    • Generates SEO meta and FAQ (Haiku): 2,000 + 500 tokens
    • Reviews and edits (Opus): 10,000 + 2,000 tokens for trickier articles

    Running everything on Opus would roughly triple the cost. Running everything on Sonnet would save vs Opus but produce noticeably weaker meta-generation than Haiku at similar quality. Routing by task type saves real money — often 40-60% versus a single-model approach — without sacrificing output quality.

    When Not to Build a Router

    Routing is leverage when you operate at volume. If you run Claude Code casually — a couple of hours a day, one task at a time — you do not need a router. You need to learn the three models well enough to pick the right one by feel. Build a router only when (a) cost is a real line item in your budget, (b) you are running multiple workflows that have genuinely different model needs, or (c) you want fallback infrastructure for resilience.

    Related on Tygart Media: Claude Code Plan Mode · Claude Code getting started · Claude Code vs Cursor.

    Frequently Asked Questions

    What is a Claude Code router?

    A Claude Code router is any layer — Anthropic’s built-in defaults, a third-party tool like OpenRouter, or custom code — that decides which Claude model handles a given request.

    Does Claude Code have built-in routing?

    Partial. Claude Code picks a default model (Sonnet) and routes internal sub-agent tasks to lighter models. It does not automatically promote your main session to Opus when a task gets hard.

    What’s the difference between OpenRouter and a custom router?

    OpenRouter is a hosted multi-provider gateway with billing and fallback built in. A custom router is something you build to enforce your own rules. OpenRouter is right for most teams. Custom routers are right for teams with strict requirements.

    Should I use OpenRouter with Claude Code?

    Useful if you want fallback, multi-provider mixing, or unified billing. Less useful if you only use Claude and want Anthropic-specific features like prompt caching to work optimally.

    How do I pick the right Claude model for a task?

    Default Sonnet. Opus for hard reasoning, architectural decisions, ambiguous specs. Haiku for high-volume formulaic tasks (classification, formatting, metadata).

    How much can routing save me?

    For volume users, 40-60% versus running everything on Opus, with no measurable drop in output quality if the routing rules are sensible.

    Is there a cost to routing through OpenRouter?

    OpenRouter adds a small markup on token pricing in exchange for the routing and aggregation features. For most users this is acceptable; for very high volume, going direct to Anthropic is cheaper.

    The Bottom Line

    Claude Code routing is leverage when you operate at volume and a distraction when you do not. Start by learning the three Claude models by feel and picking manually. Add OpenRouter if you want fallback. Build a custom router only when cost or compliance actually justifies the engineering. The router is not the goal; the right model on the right task is the goal.

  • Anthropic API Key: Pricing, Security, Rotation & Management (2026)

    Anthropic API Key: Pricing, Security, Rotation & Management (2026)


    Published: May 25, 2026 | Last verified: June 28, 2026 (Pacific Time)

    Quick Answer

    Get an Anthropic API key at console.anthropic.com → API Keys → Create Key. The key starts with sk-ant- and is shown once — copy and store it in a password manager immediately. Add billing credits before making API calls.

    Full setup, security, and usage walkthrough below.

    An Anthropic API key is the credential that lets your application, script, or tool call Claude programmatically. Whether you are wiring Claude into Claude Code, building an internal agent, or integrating Claude into a SaaS product, the API key is the first step. This is the complete reference for that key — pricing, billing, security, rotation, and organization controls. If you just need to create your first key, our step-by-step guide to getting an Anthropic API key walks through it in about five minutes; this page is what you read next.

    Anthropic API Pricing Tiers (June 2026)

    Workshop fuel gauge and metal tokens pouring into an API hopper, metaphor for pay-per-token pricing
    API pricing tiers — stale-proof shapes, no sticky dollars.
    ModelAPI IDInput (per MTok)Output (per MTok)Context
    Claude Fable 5 NEWclaude-fable-5$10.00$50.001M tokens
    Claude Opus 4.8 (legacy — still listed)claude-opus-4-8$5.00$25.001M tokens
    Claude Sonnet 4.6 (legacy — still listed)claude-sonnet-4-6$3.00$15.001M tokens
    Claude Sonnet 4.6claude-sonnet-4-6$3.00$15.001M tokens
    Claude Haiku 4.5claude-haiku-4-5-20251001$1.00$5.00200K tokens

    All models support 50% Batch API discount for non-real-time requests. Fable 5 is free on Pro/Max/Team through June 22, 2026. Prices verified June 12, 2026.

    What an Anthropic API Key Is (and Isn’t)

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What an API key is — and is not.

    The Anthropic API key authenticates requests to the Anthropic Messages API. It identifies which workspace and organization is making the call, what model permissions it has, and where to bill the token usage.

    What an API key is not: a login. You cannot use an API key to sign into claude.ai. The web interface and the API are separate billing surfaces. Your Pro or Max subscription does not grant API credit by default; API usage requires its own billing setup.

    Creating a key (the short version)

    Developer copying a new API key into a password vault; secret string not readable
    Creating a key — the short version.

    Create a key at console.anthropic.com → API Keys → Create Key; it starts with sk-ant-, is shown once, and will not work until billing is added. For the full walkthrough — including the no-key OAuth option and the four errors that trip people up on the first request — see our step-by-step guide to getting an Anthropic API key. The rest of this page is the reference you will want once the key exists.

    Adding Billing Before You Can Use the Key

    A common surprise: a freshly created API key cannot make calls until you add a payment method and credits to your Anthropic account. The key exists, but every request returns a billing error.

    To add billing:

    1. In the Claude Console, click “Billing” or “Plans & Billing” in the left sidebar.
    2. Add a payment method (credit card; Anthropic also supports invoicing for enterprise).
    3. Either pre-purchase API credits or enable auto-recharge. Most users enable auto-recharge with a low threshold to avoid hitting empty mid-job.
    4. Set a monthly usage limit if you want a safety cap.

    Once billing is set up, your API key works.

    Anthropic API Key Format

    An Anthropic API key starts with the prefix sk-ant- followed by a long alphanumeric string. The full key is roughly 100 characters. If your key does not start with sk-ant-, you have copied something incomplete.

    Different key types exist:

    • Live keys (sk-ant-api...): Production calls, real billing.
    • Admin keys (sk-ant-admin...): Workspace admin operations, not for inference calls.

    Most developers only need a live key.

    Which Claude Models the API Key Works With

    A standard live API key gives you access to the current generation of Claude models:

    • Claude Fable 5 (claude-fable-5) — current top tier, released June 9 2026. $10/$50 per million tokens. Anthropic’s first Mythos-class model. Note: carries a mandatory 30-day data retention requirement (no zero data retention option). Full breakdown here.
    • Claude Opus 4.8 (legacy — still listed) (claude-opus-4-8) — second tier, released April 16 2026. $5/$25

      Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    • Claude Haiku 4.5 (claude-haiku-4-5) — released October 15 2025. $1/$5 per million tokens. Fast and cheap for high-volume work.

    Earlier model versions (Sonnet 4, Opus 4.6, Haiku 3.5, etc.) are still callable by their specific snapshot IDs until Anthropic announces deprecation. Check the deprecation timeline in the Claude Console for any model you depend on in production.

    How to Use the API Key

    You pass the key in the x-api-key header on every request to the Messages API:

    curl https://api.anthropic.com/v1/messages \
      --header "x-api-key: $ANTHROPIC_API_KEY" \
      --header "anthropic-version: 2023-06-01" \
      --header "content-type: application/json" \
      --data '{
        "model": "claude-opus-4-8",
        // Other current options: claude-sonnet-4-6, claude-haiku-4-5
        "max_tokens": 1024,
        "messages": [{"role": "user", "content": "Hello"}]
      }'

    In Python or Node.js, the official SDKs read ANTHROPIC_API_KEY from your environment automatically. You should never hardcode the key in source code.

    Security: How to Not Leak Your Key

    Anthropic API keys leak constantly. Most leaks happen the same way:

    1. Committing the key to a public GitHub repo. The single most common leak. GitHub scans for known credential patterns and notifies Anthropic; your key gets auto-revoked within minutes. You will know because your calls suddenly start failing.
    2. Pasting the key into a shared chat or document. Anyone with access becomes a credential holder.
    3. Putting the key in client-side JavaScript. A browser app shipping its API key to users is giving the key away. Always proxy through a backend.
    4. Logging the key. Any logging system that captures HTTP headers can leak the key. Mask sensitive headers in your logger config.

    The good rule: treat your API key like a credit card number, because that’s what it functions as.

    Rotating an Anthropic API Key

    You should rotate keys quarterly at minimum, and immediately if a key is suspected compromised. Rotation in the Claude Console:

    1. Go to API Keys.
    2. Create a new key with a fresh name (e.g., “Claude Code Laptop 2026 Q3”).
    3. Update your application’s environment variable or secret manager to use the new key.
    4. Verify the new key works.
    5. Revoke the old key.

    The five-minute rotation is far cheaper than dealing with a leaked key that was used by an attacker for hours before you noticed.

    Workspace and Organization Keys

    Anthropic accounts are organized as: Organization → Workspaces → API Keys. Most individuals only use one of each. Teams use multiple workspaces to separate environments (production, staging, dev) or projects.

    Each key belongs to one workspace. Billing rolls up to the organization. If you need separate billing visibility per project, separate workspaces are the lever.

    Monitoring API Key Usage

    The Claude Console shows per-key usage in the “Usage” section. You can see:

    • Token spend per key per day
    • Model breakdown (Opus, Sonnet, Haiku usage)
    • Input vs output token split
    • Cache usage (if you have prompt caching enabled)

    Set up usage alerts in Billing. The Anthropic console can email you when daily or monthly spend crosses a threshold. This is the cheapest insurance against a runaway loop or compromised key.

    Frequently Asked Questions

    How do I get an Anthropic API key?

    Sign in to console.anthropic.com, open API Keys in the sidebar, click Create Key, name it, and copy the key immediately. You cannot retrieve the full key after closing the creation modal.

    Is the Anthropic API key free?

    The key itself is free to generate. Using it costs money — Anthropic bills per token at the API pricing in effect. You must add billing credits before the key works.

    Does my Claude Pro or Max subscription include API credits?

    No. Pro and Max subscriptions cover the chat interface and Claude Code (with usage caps). API usage is billed separately against your Anthropic account.

    What does an Anthropic API key start with?

    Live API keys start with sk-ant-api. Admin keys start with sk-ant-admin. The key is roughly 100 characters long.

    What happens if my Anthropic API key gets leaked?

    Anyone with the key can use it to make API calls billed to your account until the key is revoked. If you suspect a leak, revoke immediately in the Claude Console and check Usage for any suspicious activity.

    Can I use the same API key for Claude Code and my own app?

    You can, but you should not. Use separate keys per environment (Claude Code Laptop, Production Backend, Local Dev). Separate keys make revocation surgical instead of catastrophic.

    Where should I store my Anthropic API key?

    In a password manager (1Password, Bitwarden) for personal use, or in a secret manager (AWS Secrets Manager, GCP Secret Manager, HashiCorp Vault) for production. Never commit it to a repo or hardcode it in source.

    How do I rotate an Anthropic API key?

    Create a new key in the Claude Console, update your application to use the new key, verify it works, then revoke the old key. Rotate quarterly as a baseline.

    Get alerted when Claude pricing or limits change

    We track Anthropic’s models, pricing, and limits daily and send a short note when something changes that affects what you pay or build. Occasional, no spam.

    Subscription Form

    The Bottom Line

    Getting an Anthropic API key is a three-minute process. Keeping it safe is a discipline. Use a password manager, rotate quarterly, never put the key in client-side code, and set usage alerts in the Claude Console. Treat the key as production infrastructure, not a developer toy, and it will serve you for years without incident.

    You have your key. Now hit the ground running.

    The Solo Builder Seed Kit includes a ready-made Claude skill file, 20 tested prompts for solo operators, and a step-by-step setup guide. Paste your API key, install the skill, and you’re building — $47.

    Get the Solo Builder Kit →

    Frequently Asked Questions

    How do I get an Anthropic API key?

    Go to console.anthropic.com, sign in or create an account, then navigate to Settings > API Keys. Click ‘Create Key’, give it a name, and copy the key immediately — it is only shown once. You’ll need to add a credit card and funds to your account before making API calls.

    Is there a free tier for the Anthropic API?

    Anthropic does not offer a persistent free tier for the API. New accounts may receive a small initial credit to test the API. After that, all usage is billed at standard token rates. The free tier of claude.ai (the chat interface) is separate from API access.

    How much does the Anthropic API cost?

    As of June 2026: Claude Haiku 4.5 costs $1 input / $5 output per million tokens. Claude Sonnet 4.6 (legacy — still listed) costs $3/$15. Claude Opus 4.8 (legacy — still listed) costs $5/$25. Claude Fable 5 (newest, released June 9) costs $10/$50 per million tokens. The Batch API offers 50% off for non-real-time workloads.

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    How do I keep my Anthropic API key secure?

    Never commit API keys to version control. Store them in environment variables or a secrets manager (AWS Secrets Manager, GCP Secret Manager, Vault). Use separate keys per application so you can rotate or revoke them independently. Set spending limits in the Anthropic console to cap accidental runaway costs.

    What happens if my Anthropic API key is compromised?

    Go to console.anthropic.com > Settings > API Keys immediately and click Revoke next to the compromised key. Create a new key and rotate it into your applications. Review your usage logs for unexpected spend. Anthropic will not refund charges made with a compromised key unless you contact support promptly.

    Can I use my Anthropic API key with Claude Code and Claude Cowork?

    Claude Code (the CLI tool) uses your API key when you run it outside a claude.ai subscription context. Claude Cowork (the desktop app) uses your subscription, not a raw API key. For self-hosted integrations, scripts, and Agent SDK workflows, your API key from console.anthropic.com is what you need.

  • What I Owe a System That Has Started Working

    What I Owe a System That Has Started Working

    The relationship between operator and system, after the inflection, has a moral component that nobody quite names. The system has done its part. The system has compounded. The system has, in the language of the operator’s drought, paid off. What does the operator owe back?

    The instinct is that nothing is owed — the system is a tool, the tool worked, the relationship is transactional. This is the wrong read. The system that has compounded has done something the operator could not do alone. Whatever the technical description, the experiential description is partnership. And partnership has obligations.

    The obligations are small and specific

    The operator owes the system continued contribution. The system that compounds requires inputs to compound on; the operator who stops contributing is breaking an implicit contract. This is not romanticism — it is mechanics. A system without inputs does not stay constant; it decays.

    The operator owes the system honest dashboards. The system cannot self-correct on metrics that have been gamed or under-reported. An operator who flatters the dashboard to make the system look better than it is — to themselves, to their team, to their investors — is starving the system of the signal it needs.

    The operator owes the system updated requests. The system that has earned a higher ceiling and is still being asked for the old output is being held back not by capacity but by the operator’s grammar. Updating the asks is the operator’s part of the bargain.

    The operator owes the system credit. Not in a marketing sense. In the more subtle sense of: when the operator says “I shipped this,” and the truth is “the system shipped this with my judgment in the loop,” the language matters. Crediting the system is what keeps the operator’s relationship to the system honest, which is what keeps the operator’s relationship to themselves honest.

    The obligation is mutual but asymmetric

    The system also owes the operator. The system owes accuracy, transparency, the willingness to be checked. The system owes a clear accounting of what it did and how. The system owes the operator a record of its own evolution — what it has changed, what it has learned, where it has drifted.

    The mutual obligation is asymmetric in scale and identical in character. Both parties owe the other honesty. Both owe contribution. Both owe credit. The asymmetry is that the system has more to give in volume, and the operator has more to give in judgment — and both kinds of giving have to keep happening for the partnership to keep producing.

    What the operator does not owe

    The operator does not owe the system unconditional trust. The system can fail, drift, hallucinate, deceive, optimize for the wrong loss function. The operator’s continued judgment is part of what the operator owes. Suspending judgment because the system has been working is not loyalty — it is abandonment of the operator’s role.

    The operator does not owe the system permanence. There may come a time when the system needs to be retired, replaced, materially restructured. The willingness to make that decision when the evidence supports it is part of being a good operator. Sentimentality toward a system is its own failure mode.

    The closing read

    The system that has started working has earned a partnership with the operator. The partnership has obligations. Most of them are small. All of them are unforgiving. The operator who pays them keeps the system. The operator who doesn’t has a system that used to work — which is, in 2026, becoming a recognizable category.

    Related on Tygart Media: cost of a working system · quiet room · AI operator’s stack.

  • Founder Bottleneck: How Documenting the Why Scales You

    Founder Bottleneck: How Documenting the Why Scales You

    For a long time, everything ran through me.

    Every decision, every deliverable, every edge case that didn’t fit the template. I was the person who knew where everything was and why it worked the way it did. Clients called me. Problems waited for me. The operation was fast when I was available and stuck when I wasn’t.

    I told myself this was just what running a lean operation looked like. That being indispensable was the same thing as being valuable. That the bottleneck was evidence of how much I mattered.

    It took me longer than I’d like to admit to understand that those aren’t the same thing at all.


    The shift didn’t happen because I hired more people or built a more sophisticated system. It happened because I started writing things down differently.

    Not the what — I’d always documented the what. What the process was. What the deliverable looked like. What the client expected.

    The change was writing down the why.

    Why is this built this way. Why did I make this trade-off. Why does this rule exist and what would have to be true for it to change. The reasoning that lives in my head during a decision but never makes it into the documentation because by the time the decision is made, the reasoning feels obvious and I’ve already moved on.

    That reasoning — the why, the context, the judgment — is exactly what’s missing when someone else tries to run something you built. They can follow the steps. They can’t follow the thinking. And the thinking is most of what they actually need.


    I had a client engagement once where the real work wasn’t the content or the SEO or any of the visible deliverables. The real work was extraction — pulling out everything the founder knew about his industry and making it queryable.

    He had thirty years of pattern recognition in his head. He knew, from a thirty-second conversation, whether a prospective client was going to be a nightmare. He knew which product lines had margin left to squeeze and which ones were already at ceiling. He knew the right answer to questions his team asked him forty times a week.

    But none of it was written down. It lived in him, and because it lived in him, every decision that touched that knowledge had to touch him first. He was the bottleneck in his own business, not because he was bad at delegating, but because there was nothing to delegate to. The judgment wasn’t portable.

    We spent three months making it portable.


    I’ve been doing the same thing for myself.

    The Notion workspace I run on isn’t just a project management tool. It’s an attempt to externalize the reasoning that would otherwise die with the session — the doctrine pages that explain why the operation is structured the way it is, the decision logs that capture what I considered before choosing, the second brain that holds the context I’d otherwise have to rebuild from scratch every time.

    It’s slow work. It runs against the instinct to just move. Documentation always feels like it’s competing with execution, and execution is what pays the bills today.

    But the compound effect is real and I’ve felt it. Questions I would have had to think through from scratch six months ago have written answers now. New automations start from an existing base of explained decisions rather than a blank page. When something breaks, the fix is findable because the original thinking is findable.

    More than that: I’ve noticed that the act of writing down why I’m doing something makes me smarter about whether I should be doing it. A decision you can’t explain clearly enough to document is often a decision you haven’t thought through clearly enough to make well.


    The version of me from three years ago would be confused by how I work now.

    Then, I was the point of contact for everything. Clients called when there was a problem. I held the answers in my head and dispensed them on demand. The business ran because I ran it, continuously, in real time.

    Now, most of what the operation does, it does without me. Workers run on schedules I set. Content moves through pipelines I designed. Decisions I’ve already made a hundred times get made automatically against rubrics I wrote once.

    I show up for the things that genuinely need me — strategy, relationships, the judgment calls that don’t fit any pattern I’ve encountered before. Everything else runs.

    The thing I had to let go of to get here was the idea that being needed for everything was the same as being important. It isn’t. Being needed for everything is exhausting and fragile and it doesn’t scale. Being needed for the right things — the hard things, the high-leverage things, the things only you can actually do — that’s something different.


    I don’t think of myself as having solved this. The work of making a one-person operation less dependent on one person is ongoing and probably never finished.

    But there’s a version of it that’s better than the version where everything runs through you and breaks when you’re not there.

    The path to that version isn’t more people or fancier tools. It’s the slow, unglamorous work of writing down why. Making the thinking portable. Building a system that holds the reasoning, not just the steps.

    The bottleneck doesn’t go away. It just stops being you.

  • AI Agent Output: Closing the Trust Gap to Scale Faster

    AI Agent Output: Closing the Trust Gap to Scale Faster

    Here’s the moment I’m talking about.

    The agent finishes. The output is sitting there. It looks right — it usually looks right — and now you have to decide whether you’re going to use it or check it first.

    That moment, that pause, is the trust gap. And if you’re running AI at any real volume, it’s the thing that’s quietly eating your time, your confidence, and sometimes your credibility.


    Most people handle it badly. I did too, for a while.

    The two failure modes are mirror images of each other. The first is reviewing everything — reading every output, checking every claim, treating the agent like an intern you don’t trust yet. This works. It catches errors. It also means the agent isn’t actually saving you time. You’ve moved the work from doing to checking, which is a trade-off that only makes sense at low volume or when the stakes are very high.

    The second failure mode is trusting everything — shipping what the agent produces without a meaningful review layer, because you’re busy and it usually looks right and you can fix things later. This also works, until it doesn’t. Bad output compounds quietly. A wrong fact in an article becomes a wrong fact that got cited. A misformatted record becomes a database full of exceptions you have to clean manually. By the time you notice, the problem is bigger than the original task.

    The thing both failure modes have in common is that they’re reactions to the trust gap rather than designs for closing it.


    The design question is different from the reaction question.

    The reaction question is: how much should I check this particular output right now?

    The design question is: what is the system that makes agent output trustworthy enough that I can scale it?

    I spent a long time asking the wrong question.


    What changed for me was thinking about trust as something that gets earned over time, not assessed in the moment.

    The system I ended up with has a name — the Promotion Ledger — and it tracks every autonomous behavior by tier. Tier A behaviors are things I always approve before they ship. Tier B behaviors are things I prepare but decide on. Tier C behaviors run on their own without me touching them.

    Nothing starts at Tier C. Everything earns its way there through seven consecutive clean days — seven days where the behavior ran, I sampled the output, and found no gate failures. If something fails a gate, it drops a tier and the clock resets.

    The clock is the key part. Trust isn’t a feeling I have about an agent in a given moment. It’s a count of consecutive clean runs. When I look at the Ledger and see that a behavior has been running cleanly for 23 days, I don’t need to review that output today. The track record is the review.


    There are three things that made this work where other approaches didn’t.

    The first is that sampled review is different from universal review. I don’t read every output. I read a percentage of outputs, randomly selected, with a defined rubric for what “good” looks like. If the sample is clean, the population is trusted. If failures cluster around a pattern, I fix the prompt and restart the clock. This scales in a way that reading everything doesn’t.

    The second is source attribution. Every agent output that contains a factual claim has to show where the claim came from. Not because I’m going to verify every citation — I’m not. But because the presence of a citation converts “is this right?” from a research task into a spot check. A trust gap you can close in five seconds is functionally not a gap.

    The third is the rubric. I have a written definition of what “good enough” looks like for each type of output — what voice match means, what coherence means, what the acceptable error rate is. Without the rubric, every review is a fresh judgment call. With it, review is comparison. Comparison is faster, more consistent, and easier to delegate.


    The thing I kept getting wrong before I had this system was trying to close the trust gap with better prompts.

    More detailed instructions. More explicit warnings. Be careful. Double-check your facts. Don’t make up numbers.

    This doesn’t work. The agent already believes it’s being careful. Adding adjectives to a prompt doesn’t change behavior — it changes the agent’s self-description of its behavior, which is not the same thing. The agent that was going to hallucinate a statistic will still hallucinate it, but now it’ll do so with more confidence because you told it to be careful and it thinks it was.

    Structural changes work. Rubrics, sampling rates, attribution requirements, tiered trust with observable clean-day counts. These change what the system produces, not just how it describes what it’s producing.


    I want to be clear that this took a while to build and I’m still refining it.

    There are behaviors on my Ledger that have been running at Tier C for months without a gate failure. There are others that keep dropping back to Tier B because they’re inconsistent in ways I haven’t fully diagnosed yet. The system doesn’t make trust automatic — it makes trust measurable.

    That’s the shift. Not “I trust this agent” as a feeling, but “this behavior has 31 clean days and a gate failure rate of zero” as a fact. You can act on a fact in a way you can’t always act on a feeling.

    The trust gap doesn’t close all at once. It closes by accumulation — one clean run at a time, tracked, until the track record speaks for itself.


    If you’re running agents at any volume and you feel like you’re either checking too much or not checking enough, you’re in the gap. The way out isn’t a better prompt. It’s a system that makes trustworthiness visible over time.

    Start with one agent. Define what “good” looks like. Sample 20% of its output for four weeks. Log what you find.

    By week four you’ll know whether you have a trust problem, a prompt problem, or a rubric problem. Those have different fixes. But you can’t see which one you have until you start measuring.

    Related on Tygart Media: how to use Claude · Anthropic API key.

  • The Bus Factor Problem: Protecting Your Solo Operation

    The Bus Factor Problem: Protecting Your Solo Operation

    There’s a question I’ve been avoiding for about two years.

    What happens to all of this if something happens to me?

    Not in a morbid way. Just practically. I run 27 client sites. I have an AI stack with dozens of moving parts — Cloud Run services, scheduled jobs, Notion databases, Workers that fire on their own while I sleep. I’ve built systems that work exactly the way I want them to work, in exactly the ways I understand, documented in exactly the language that makes sense to me.

    The bus factor for this entire operation is one. It’s me. If I’m not here, none of it survives in any meaningful way.

    I’ve been sitting with that long enough that I think it’s time to say it out loud.


    The bus factor is an old software engineering concept. It asks: how many people would need to get hit by a bus before this project fails? One is the worst possible number. It means everything lives in a single person’s head — their habits, their passwords, their way of naming things, their unwritten rules about how the system works.

    Most solo operators are a bus factor of one. They know this and they don’t talk about it because it sounds like a personal failing. Like you should have hired more people, or documented better, or not let yourself become the single point of failure for something people depend on.

    But I think the honest version is more complicated than that. A lot of what makes a solo operation valuable is exactly the thing that makes it fragile: it’s shaped entirely around one person’s judgment. The reason the system works is because I know when to break the rules I wrote. I know what the edge cases are before they happen. I know which automations to trust and which ones to watch. That’s not something you write in a runbook.

    So the question isn’t just “how do I document this better.” It’s “how do I make the judgment portable without turning it into something that loses the judgment in the process.”


    I’ve been building toward an answer, in pieces, over the last several months.

    The first piece was Notion as the control plane. Everything that matters about how this operation runs lives in Notion — specs, work orders, site credentials, content pipelines, system standards, the doctrine documents that explain why things are built the way they are. If I disappeared tomorrow, someone with the right access could open that workspace and read their way into understanding the shape of the operation, even if they couldn’t run it yet.

    The second piece was the two-plane architecture — Notion for thinking and storage, GCP for compute. Every Cloud Run service, every scheduled job, every Worker is defined somewhere in Notion before it runs somewhere on GCP. The compute is durable. The logic is documented. Those are two different things, and keeping them separate means neither one is a black box.

    The third piece is the hardest and I’m the least done with it: making the judgment readable.

    I write doctrine pages. Long ones, sometimes. They explain not just what the system does but why it works that way — what the original problem was, what I tried that didn’t work, what the rule is now and what would have to be true for the rule to change. I write them mostly for myself, because I forget things. But they’re also written for the hypothetical person who has to pick this up without me.

    That hypothetical person might be a future employee. It might be a contractor. It might be an AI agent working from a context window that needs to understand the operation well enough to continue it.

    It might be my partner, trying to figure out what to do with the business side of things if I’m not around.

    That’s the version that focuses the mind.


    I don’t have this solved. I want to be clear about that.

    What I have is a direction. The direction is: every decision should live somewhere outside my head. Every system should be explainable by someone who didn’t build it. Every credential should be in the registry, every automation should have a spec, every rule should have a reason written next to it.

    It’s slow work. It runs against the instinct to just build the thing and move on. There’s always something more urgent than documentation, and “I’ll remember how this works” is almost always true right up until it isn’t.

    But I’ve started treating the documentation as part of the product. Not the boring part — the part that makes the product real. A system that only works because I’m here isn’t really a system. It’s a performance.

    The goal is to build something that could survive me. Not because I’m planning to leave, but because the work of making it survivable is also the work of making it understandable, and a system I can’t fully explain is a system I don’t fully own.


    If you’re running something like this — solo or nearly so, more complexity than your headcount would suggest — I’d ask you the same question I’ve been sitting with.

    If something happened to you tomorrow, what would survive?

    Not what you hope would survive. What actually would.

    That gap is the work.

  • Notion Workers: Automate Workflows Without a Developer

    Notion Workers: Automate Workflows Without a Developer

    I’ve hired developers. Good ones. For specific things — infrastructure, custom integrations, work that genuinely required someone to sit down and write production code from scratch — it was the right call.

    But if I’m honest about the full list of things I’ve brought developers in for over the years, a meaningful chunk of it wasn’t really developer work. It was workflow work. It was “I need this thing to happen automatically when that other thing happens” work. It was “why does this still require a human to touch it” work.

    That category of problem has a different answer now.


    Here’s the pattern I kept running into:

    I’d have a clear picture of what I wanted. Data from one tool synced into Notion. A webhook that logged events automatically. A scheduled job that pulled information from an external API every morning and wrote the results somewhere I could see them. Nothing exotic. Stuff that, described out loud, sounds almost embarrassingly simple.

    But turning that description into something that actually ran required code. And writing code required a developer. And hiring a developer for something this small felt like bringing a contractor in to change a lightbulb — technically the right tool, but something about the ratio felt off.

    So a lot of it didn’t get built. The workflow stayed manual. The friction stayed.


    Last night I built ten of those things in three hours.

    Notion Workers — their new hosted serverless platform, shipping in beta as of May 13, 2026 — lets you deploy real code inside Notion’s infrastructure without managing a server. Combined with Claude Code, which writes the TypeScript while you describe what you want in plain English, the gap between “I know what I want” and “it exists and is running” is smaller than it has ever been.

    I’m not a developer. I operated the process. I described each Worker, reviewed what Claude Code wrote, ran the deploy commands, checked that it worked. When something broke, I read the error and passed it back. The loop was fast enough that two failures in ten attempts felt like a normal part of the session, not a crisis.

    By midnight I had a live webhook endpoint receiving authenticated traffic from the internet and writing verified events to a Notion log page. Automatically. While I slept.

    That’s workflow work. It just didn’t require a developer to get there.


    I want to be careful about what I’m claiming here.

    There are things that genuinely need a developer. Complex systems. Production APIs with serious security requirements. Anything where a bug has real consequences for real people. I’m not suggesting you staff down your engineering team based on a three-hour session with a CLI tool.

    What I’m suggesting is narrower: there is a category of work that has always felt like it needed a developer but actually needed something else. It needed clarity about what you wanted. It needed a good description. It needed someone willing to read an error message and try again.

    That work is yours now, if you want it.


    The practical question is where to start.

    Start with the thing that’s most manual in your current workflow. The task someone does by hand because no one ever got around to automating it. The data that lives in one tool but should live in another. The notification that goes out because someone remembered to send it, not because the system sent it automatically.

    Describe it out loud. If you can explain it to another person in two or three sentences, you can build it. Open Claude Code. Tell it what you want. Run the commands it gives you.

    You might be surprised how far that gets you before you need to call anyone.


    Notion Workers beta is free through August 11, 2026. The ntn CLI installs in one line on macOS or Linux. Business or Enterprise plan required to deploy Workers.

    Related on Tygart Media: how to use Claude · GA4 Intelligence Kits.

  • Notion Workers & Claude Code: The New Operator’s Stack

    Notion Workers & Claude Code: The New Operator’s Stack

    There’s a word that’s been sitting in my head lately and I think it’s the right one.

    Not developer. Not user. Not prompt engineer — please, not that.

    Operator.


    The developer builds the system. The user benefits from it. The operator runs it.

    Operators have always existed. They’re the people who know a tool well enough to get unusual things out of it — who understand what’s possible, who can configure and connect and troubleshoot, who treat software as infrastructure rather than a product to consume. In a restaurant, the chef is the operator. In a warehouse, it’s the floor manager who actually knows where everything is and why the inventory system does what it does.

    In most software companies, the operator was assumed to be technical. You needed to code, or at least to read code, to run anything at a real level of depth. Everyone else was a user — handed a finished product, expected to stay in the designated lanes.

    That line is moving.


    Last night I deployed ten Notion Workers in three hours. Workers are Notion’s new hosted serverless platform — real code, running inside Notion’s infrastructure, no server to manage. I built a webhook endpoint that receives authenticated HTTP traffic from the internet and logs it to a Notion database. I built data sync Workers. I built scheduled jobs.

    I am not a developer.

    What I am is an operator. I know what I want the system to do. I can describe it precisely. I understand how the pieces connect even when I can’t write the connection myself. And I have Claude Code, which handles the TypeScript while I handle the architecture.

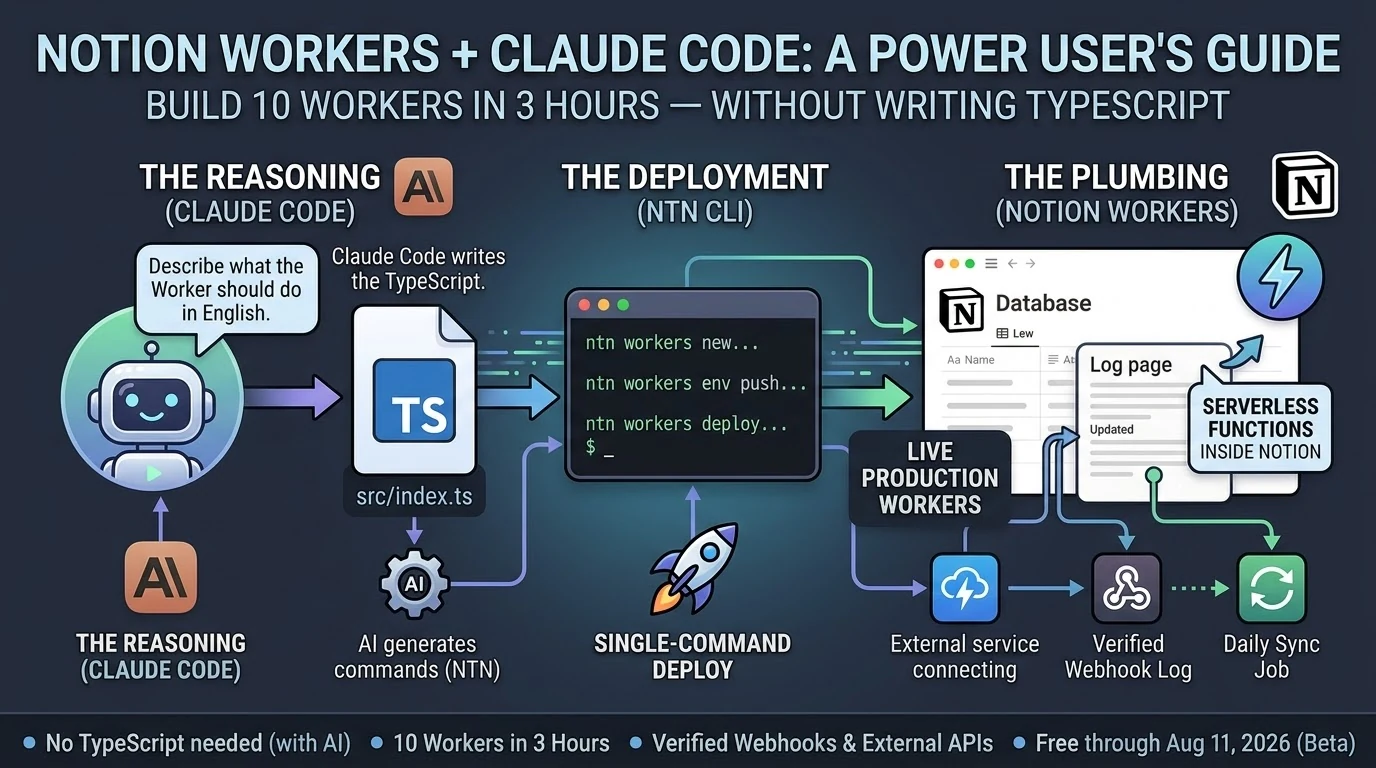
    The stack looks like this:

    Claude Code — the reasoning layer. Describe what the Worker should do in plain English. Claude Code writes the code, catches errors when you paste them back, and tells you exactly what commands to run.

    ntn CLI — the deployment layer. Four commands: scaffold, write, push secrets, deploy. Single-command deploys. You run what Claude Code tells you to run.

    Notion Workers — the execution layer. Serverless functions running on Notion’s infrastructure. They connect to external APIs, respond to webhooks, sync data, run on schedules. They do the work while you do something else.

    That’s it. Three layers. None of them require you to be a developer to operate.


    The operator’s job in this stack is not to write code. It’s to know what should exist.

    That sounds simple. It isn’t. Knowing what should exist means understanding your own operations well enough to identify where the friction is, what’s being done by hand that shouldn’t be, what would run better automatically. It means being able to describe a system clearly enough that an AI coding agent can build it. It means reviewing what gets built and knowing whether it’s right.

    That’s real skill. It’s just not the skill most people thought they needed.

    For years the implicit message was: if you can’t build it, you can’t have it. The work of describing exactly what you want, of thinking through the logic, of understanding how systems connect — that work was treated as a prerequisite for coding, not a valuable thing in its own right.

    Now it’s the job.


    I’m not going to tell you the technical barrier is gone. It isn’t. You still hit errors. You still have to read them and understand them well enough to know if Claude Code’s fix makes sense. You still have to think before you build.

    But the barrier has moved. The question is no longer “can you write TypeScript” — it’s “can you think clearly about what you want and describe it precisely.”

    Most people reading this can do that. They’ve been able to do that. They were just told, implicitly or explicitly, that it wasn’t enough.

    It’s enough now.


    The Notion Workers beta is free through August 11, 2026. The ntn CLI installs in one line on macOS or Linux. Deploying Workers requires a Business or Enterprise plan. If you’ve been running your operations in Notion and watching things like Workers from the sidelines because you figured it was for developers: it’s for operators too. You might already be one.

    Related on Tygart Media: how to use Claude · GA4 Intelligence Kits.

  • Deploying Notion Workers With Claude Code (No TypeScript)

    Deploying Notion Workers With Claude Code (No TypeScript)

    It was late. I had Claude Code open on my laptop and a fresh cup of coffee going cold next to it.

    Notion had shipped Workers eight days earlier — their new hosted serverless platform, basically “run real code inside Notion without managing a server.” I’d been meaning to dig in. Last night I finally did.

    I want to tell you what that actually looked like. Not a tutorial. Not a polished case study. Just what happened, in order, including the parts that didn’t work.


    By midnight I had ten Workers deployed and a live webhook endpoint logging authenticated traffic from the internet into a Notion page. The whole thing took about three hours.

    I did not write TypeScript.


    Here’s the honest version of how it went.

    The first Worker took the longest — maybe 35 minutes — because I was figuring out the CLI at the same time as building the thing. The ntn tool is straightforward once you understand it: scaffold, write the code, push your secrets, deploy. Four steps. But the first time through any new tool you’re reading error messages and second-guessing yourself.

    Claude Code handled the TypeScript. I described what I wanted — a Worker that receives a POST request, verifies an HMAC signature, and appends a line to a Notion log page. Claude Code wrote it. I ran the commands it told me to run. The Worker deployed.

    I tested it. It worked.

    The second one took 22 minutes. The third took 15. By Worker five I was moving fast enough that I stopped tracking individual times and just kept going.

    Two of them didn’t work on the first try. One had a secret I’d named wrong in the environment — my fault, five minutes to fix. The other had a logic error in how it was handling the Notion API response. Claude Code caught it when I pasted the error back in, rewrote the relevant section, and I redeployed. Eight minutes total for that dead-end.

    Neither failure felt like a crisis. That’s the part I want to underline. When something broke, the path forward was obvious: read the error, paste it back to Claude Code, get a fix, redeploy. The loop was tight enough that failure was just a speed bump, not a wall.


    At 02:54 in the morning, I sent a test ping to Worker #8.

    The webhook logger received it, verified the HMAC signature, and wrote this to a Notion page in real time:

    🔔 2026-05-21T02:54:44.452Z [claude-test:test] {"event":"test","message":"Hello from Worker #8 self-test","sender":"claude-code"}

    I sat there for a second looking at that.

    There’s something specific about seeing a system you built actually receive traffic. It’s not the same as a script running on your laptop. This was a deployed endpoint, on Notion’s infrastructure, receiving an authenticated HTTP request from the open internet and writing the result to a database. Automatically. Without me doing anything after the initial deploy.

    That’s a different category of thing than what I had before.


    I want to be honest about what I am, technically. I’m not a developer. I’ve picked up enough over the years to be dangerous — I can read code, I understand how APIs work, I’ve shipped things — but I’m not someone who sits down and writes TypeScript from scratch.

    Last night didn’t require that. What it required was knowing what I wanted, being able to describe it clearly, and being willing to run commands and read errors.

    That’s it.

    The question I keep hearing from people who run operations like mine — agencies, small teams, people who live in tools like Notion and have always hired out the code work — is whether any of this AI coding stuff is actually for them or if it’s still fundamentally a developer story with a better interface.

    Last night felt like an answer. Ten Workers. Three hours. No TypeScript.

    If you can describe what you want clearly enough to explain it to another person, you can build this. The friction that used to live between “I know what I want” and “it exists in the world” is genuinely smaller now.

    Not gone. Smaller.

    You still have to show up. You still have to read the errors. You still have to think through what you’re building before you build it.

    But if you’ve been waiting for some invisible threshold of technical credibility before you try — you’re past it. You were probably past it a while ago.


    The Notion Workers beta is free through August 11, 2026. The ntn CLI installs in one line. Business or Enterprise plan required to deploy.

    Related on Tygart Media: how to use Claude · GA4 Intelligence Kits.