Updated July 6, 2026
Official links:Try the models (claude.ai) · Official model docs · API console
Comparison note: the tier-by-tier comparisons below remain valid. As of July 6, 2026, Anthropic’s lineup is Claude Fable 5.1 (top tier above Opus; $10 in / $50 out per MTok; Mythos 5 is the limited-availability sibling), Claude Opus 5 ($5/$25), Claude Sonnet 5 (released June 30, 2026; now the default for Free and Pro; $2/$10 per MTok standard pricing, made permanent August 11, 2026), and Claude Haiku 4.5 ($1/$5). Opus 4.7 and Sonnet 4.6 are now legacy. Full details: the Claude Fable 5 Complete Guide.
Last refreshed: June 9, 2026
Model Accuracy Note — Updated September 14, 2026
Lineup currency (Sept 2026, verified): Sonnet 5 ($2/$10), Opus 5.5 ($4/$20), Haiku 4.5 ($1/$5), Fable 5.1 ($10/$50). Legacy (still listed): Opus 4.8 ($5/$25), Sonnet 4.6 ($3/$15). Prior note (superseded): Prior flagship claim: Claude Fable 5.1. Prior models claim: Fable 5.1 · Opus 5 · Sonnet 5 · Haiku 4.5. Claude Opus 5 is the current Opus-tier model as of September 2026. The overall flagship is Claude Fable 5.1, which launched June 9, 2026 and sits above Opus in capability and price. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →
Direct Answer (September 2026): Claude models are divided into three performance classes: Haiku ($1/$5 MTok) for instantaneous responses and lightweight routing, Sonnet ($2/$10 MTok) for optimal balance of speed and intelligence across 90% of business tasks, and Opus ($5/$25 MTok) for deep code refactoring, mathematics, and intricate technical architecture.
Anthropic’s model lineup is organized around three tiers — Haiku 4.5, Sonnet 5, and Opus 5 — each representing a different point on the speed-versus-intelligence spectrum. Understanding which model to use, and which API string to call it with, saves both time and money. This is the complete June 2026 reference.
Where Sonnet Wins

Sonnet is not a compromise — it’s the right tool for the majority of professional tasks. Writing, research, summarization, drafting, analysis, code generation, SEO work, email, strategy — Sonnet handles all of it at a level that’s indistinguishable from Opus for most outputs. The difference shows up at the edges: highly ambiguous problems, tasks requiring multiple competing constraints to be held simultaneously, or situations where the consequences of a slightly wrong answer are significant.
For production API workloads, Sonnet’s cost advantage is substantial. Running high-volume content or data pipelines on Opus instead of Sonnet multiplies costs without proportional quality gains on most tasks.
Where Opus Wins
Opus earns its premium on genuinely hard problems. Complex multi-step reasoning where the chain of logic matters. Legal or technical documents where precision at every sentence is required. Strategic analysis where you need the model to hold and weigh competing frameworks simultaneously. Code debugging on complex, unfamiliar systems where Sonnet gives you the obvious answer and Opus finds the non-obvious one.
I use Opus specifically for: client strategy documents where I’m synthesizing months of context, complex GCP architecture decisions, and any task where I’ve tried Sonnet and felt the output was a notch below what the problem deserved. That’s a smaller subset of work than most people assume.
The Practical Routing Rule

Use Sonnet when: the task is well-defined, the output type is familiar, and quality at the 90th percentile is sufficient. That’s most professional work.
Use Opus when: the task is genuinely novel, involves high-stakes judgment, requires deep multi-step reasoning, or you’ve already run it on Sonnet and the output wasn’t quite right.
Use Haiku when: you need the same operation at scale, latency matters more than depth, or cost is the primary constraint.
The Decision Framework
Use Haiku when: same operation at high volume, output is constrained/structured, cost and speed matter, real-time latency required.
Use Sonnet when: any standard professional task — writing, coding, analysis, research. This should be your default 90% of the time.
Use Opus when: the task is genuinely hard, involves novel reasoning, Sonnet’s output wasn’t quite right, or quality is the only variable that matters regardless of cost.
For full pricing details, see Anthropic API Pricing. For a Haiku deep-dive, see Claude Haiku 4.5: Pricing, Use Cases, and API String. For the Opus vs Sonnet head-to-head, see Claude Opus 4.8 vs Sonnet.
The Three-Tier Model Architecture
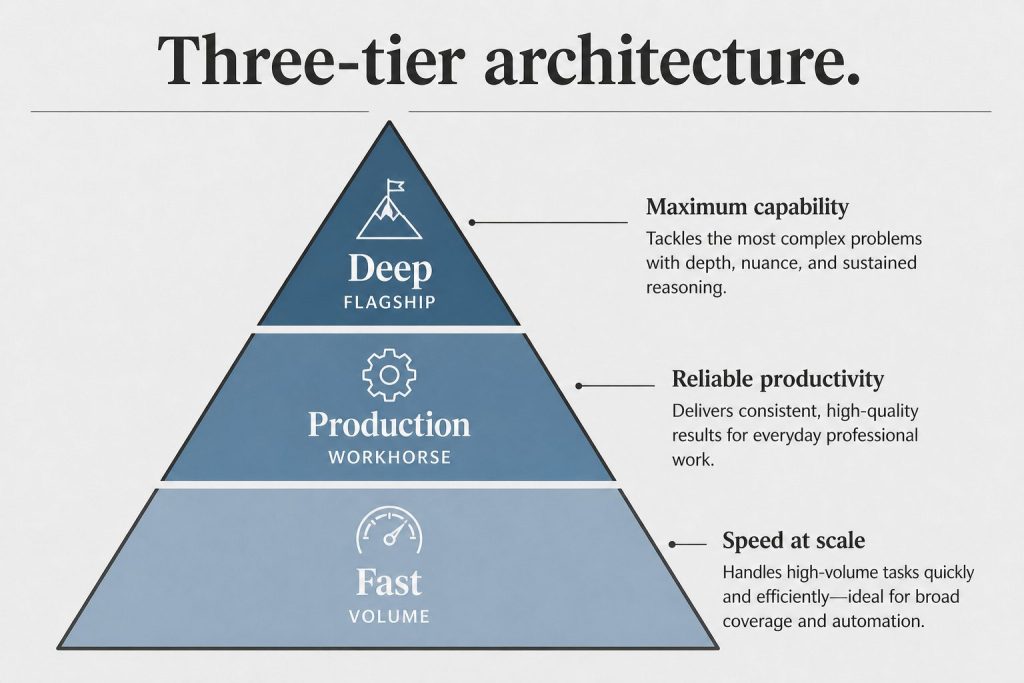
Full Claude model lineup — June 2026
| Model | Tier | Best for | Input $/MTok | Output $/MTok | Context |
|---|---|---|---|---|---|
| Claude Fable 5.1 | New flagship | Most demanding reasoning & agentic work | $10 | $50 | 1M tokens |
| Claude Opus 5 | High capability | Complex reasoning, long-horizon agentic coding | $5 | $25 | 1M tokens |
| Claude Sonnet 5 | Balanced | Production apps — best speed/intelligence ratio | $2 | $10 | 1M tokens |
| Claude Haiku 4.5 | Fast/efficient | High-volume, latency-sensitive, cost-sensitive | $1 | $5 | 200k tokens |
Pricing from platform.claude.com as of June 9, 2026. Claude Fable 5 launched June 9, 2026 as the new most capable widely-released model. Claude Mythos 5 is available only through Project Glasswing (invitation-only) and is not listed for general comparison.
Claude vs competitors — June 2026
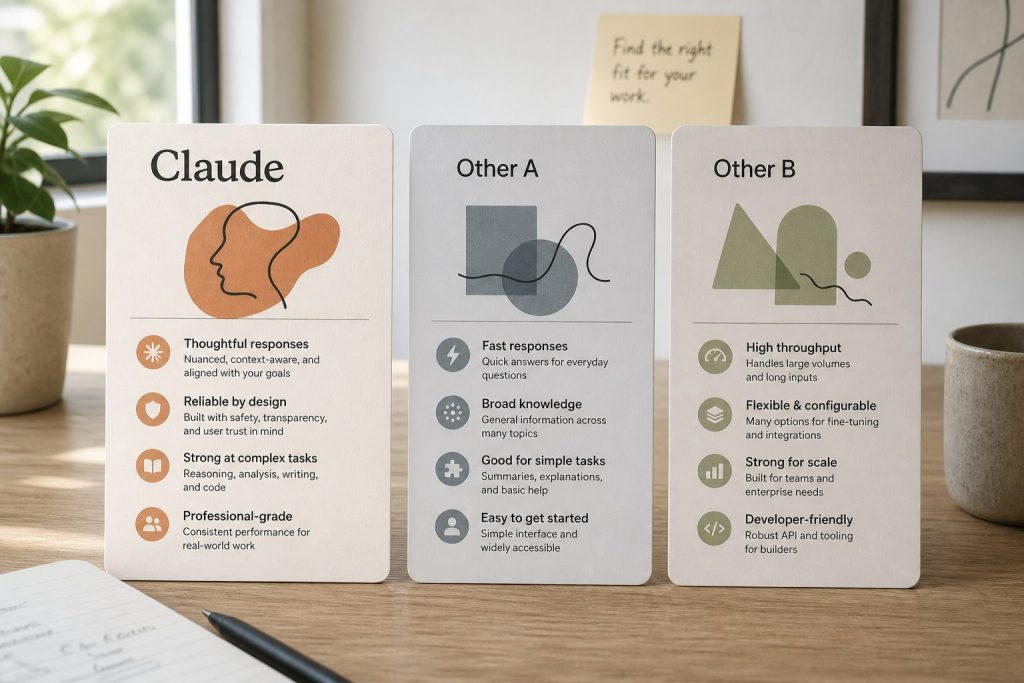
| Platform | Flagship model | Key strength | Input $/MTok |
|---|---|---|---|
| Anthropic | Claude Fable 5 | Reasoning, agentic coding, 1M context | $10 |
| OpenAI | GPT-5.5 | Agentic tasks, coding, cross-tool workflows | Contact OpenAI |
| Gemini 3.5 Flash (GA June 9) / Gemini 2.5 Pro (stable) | Multimodal, Google ecosystem integration | See ai.google |
Competitor data sourced from openai.com and deepmind.google/models/gemini as of June 9, 2026.
Anthropic structures its models around a consistent naming pattern: a Greek letter indicating capability tier (Haiku → Sonnet → Opus, low to high) and a version number indicating the generation. The current generation is the 5.x series.
| Model | API String | Context Window | Best for |
|---|---|---|---|
| Claude Haiku 4.5 | claude-haiku-4-5-20251001 | 200K tokens | Classification, tagging, high-volume pipelines |
| Claude Sonnet 5 | see platform.claude.com/docs | 200K tokens | Most production work, writing, analysis, coding |
| Claude Opus 5 | see platform.claude.com/docs | 1M tokens | Complex reasoning, research, quality-critical |
Claude Haiku 4.5: Speed and Cost Efficiency
Haiku is Anthropic’s fastest and least expensive model. It’s built for tasks where throughput and cost matter more than maximum reasoning depth — think classification pipelines, metadata generation, content tagging, simple Q&A at volume, or any workload where you’re making thousands of API calls and can’t afford Sonnet pricing at scale.
Don’t mistake “cheapest” for “bad.” Haiku handles everyday language tasks competently. What it can’t do as well as Sonnet or Opus is maintain coherence across very long context, handle subtle nuance in complex instructions, or produce writing that reads like a human crafted it. For structured outputs and clear-cut tasks, it’s excellent.
When to use Haiku: batch content generation, automated tagging and classification, chatbot applications where responses are short and structured, high-volume data processing, anywhere you’re cost-sensitive at scale.
Claude Sonnet 4.6: The Production Workhorse
Sonnet is the model most developers and knowledge workers should default to. It sits at the sweet spot of the capability-cost curve — significantly more capable than Haiku at complex tasks, significantly cheaper than Opus, and fast enough for interactive use cases.
Sonnet handles long-document analysis well, produces writing that requires minimal editing, follows complex multi-part instructions without drift, and codes competently across most languages and frameworks. For the overwhelming majority of real-world tasks, Sonnet is the right choice.
When to use Sonnet: article writing, code generation and review, document analysis, customer-facing AI features, research summarization, agentic workflows that need a balance of quality and cost.
Claude Opus 4.8: Maximum Capability
Opus is Anthropic’s most powerful model — and its most expensive. It’s built for tasks where you need maximum reasoning depth: complex strategic analysis, intricate multi-step problem solving, long-horizon planning, nuanced evaluation work, or any scenario where you’d rather pay more per call than accept a lower-quality output.
Opus is not the right default. The cost premium is real and meaningful at scale. The right question to ask before routing to Opus is: “Will a human reviewer actually tell the difference between Sonnet and Opus output on this task?” If the answer is no, use Sonnet.
When to use Opus: high-stakes strategic documents, complex legal or financial analysis, research that requires synthesizing across many sources with genuine insight, tasks where the output gets published or presented to executives without further editing.
Claude Opus 4.8 vs Sonnet: The Practical Decision
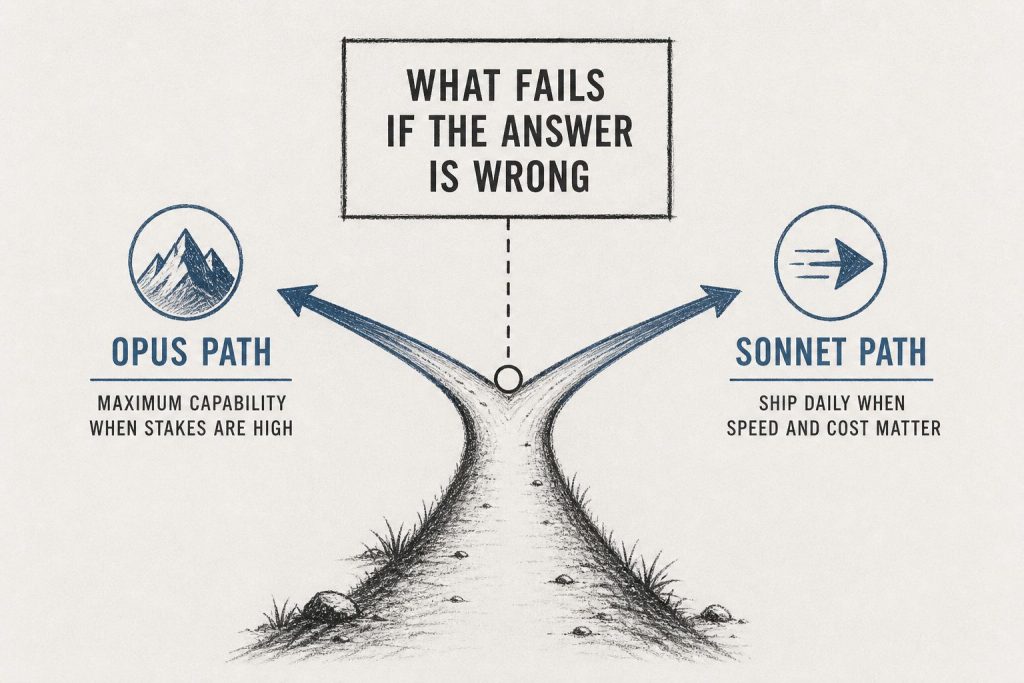
| Task Type | Use Sonnet | Use Opus |
|---|---|---|
| Article writing | ✅ Usually | Long-form flagship only |
| Code generation | ✅ Most tasks | Complex architecture |
| Document analysis | ✅ Standard docs | High-stakes, nuanced |
| Strategic planning | Good enough | ✅ When stakes are high |
| High-volume pipelines | ✅ Or Haiku | ❌ Too expensive |
| Interactive chat | ✅ Best fit | Overkill for most |
Claude Sonnet 5: What’s Coming
Anthropic follows a consistent release cadence — major model generations are announced publicly and the naming convention stays stable. The current top-tier model is Claude Fable 5.1. Claude Sonnet 5 shipped June 30, 2026 and is now the production default, replacing Sonnet 4.6; Claude Opus 5 shipped July 24, 2026, replacing Opus 4.8 (legacy — still listed). As of September 2026, the current models are Claude Fable 5.1 (top tier), Claude Opus 5.5, Claude Sonnet 5, and Claude Haiku 4.5. Sonnet 4.6, Opus 4.7, and Opus 4.6 are legacy versions and should not be used for new integrations.
When new models release, Anthropic typically maintains the previous generation in the API for a transition period. Production applications should always pin to a specific model version string rather than using a generic alias, so new model releases don’t silently change your application’s behavior.
How to Use Model Names in the API
Always use the full versioned model string in API calls. Generic strings like claude-sonnet without a version may resolve to different models over time as Anthropic updates defaults.
# Current production model strings (September 2026)
claude-haiku-4-5-20251001 # Fast, cheap
# Sonnet 5 / Opus 5: pin the full versioned strings published at
# platform.claude.com/docs — never rely on unversioned aliases in production.
Frequently Asked Questions
What is the best Claude model?
Claude Opus 5 is our most capable model, but Claude Sonnet 5 is the best choice for most use cases — it offers the best balance of capability, speed, and cost. Use Opus only when the task genuinely requires maximum reasoning depth. Use Haiku for high-volume, cost-sensitive workloads.
What is the difference between Claude Sonnet 5 and Claude Opus 5?
Sonnet is the balanced mid-tier model — faster, cheaper, and suitable for most production tasks. Opus is the highest-capability model, significantly more expensive, and best reserved for complex reasoning tasks where quality is the primary consideration. For most writing, coding, and analysis tasks, Sonnet’s output is indistinguishable from Opus at a fraction of the cost.
What are the current Claude model API strings?
As of September 2026: claude-haiku-4-5-20251001 (Haiku 4.5); for Sonnet 5 and Opus 5, pin the full versioned strings published at platform.claude.com/docs. Always use the full versioned string in production code to avoid silent behavior changes when Anthropic updates model defaults.
Is Claude Sonnet 5 available?
Yes. Claude Sonnet 5 was released June 30, 2026 and is now the production-default Sonnet, replacing Sonnet 4.6 (legacy — still listed). It runs at standard pricing of $2 input / $10 output per MTok, made permanent on August 11, 2026 (the planned rise to $3/$15 was cancelled). The current top tier is Claude Fable 5.1, with Claude Opus 5.5 as the current Opus.
Leave a Reply