Tag: AI Tools

  • The Best Pharmacy Product Reads the Receipt Against the File

    The Best Pharmacy Product Reads the Receipt Against the File

    The pharmacy already has a public acquisition file.

    The counter still charges a number that may not sit next to it.

    That gap is the product.

    The idea mills keep minting a pharmacy chatbot, a coupon-clipper app, and an rxcheck.ai.

    Three names.

    One object.

    A register receipt, or the sticker on the bag, that does not sit next to the acquisition file the Centers for Medicare and Medicaid Services already publishes every week, or next to the maximum fair price file that took effect on January 1, 2026.

    Greg Isenberg’s stream and the daily micro-SaaS accounts keep splitting the same reader.

    One post wants a refund radar that studies why people ask for money back.

    Another wants a bill auditor that gets paid only when the client saves.

    A third wants a photo of a medical bill dropped into a chat, with a letter on the other side.

    Cute.

    Wrong cut if you stop at the chat.

    The customer does not wake up wanting a PBM explainer.

    They wake up because the bag was $47 and the same capsule was $9 at the pharmacy across the street, or because a Part D claim in 2026 still does not look like the price CMS already posted.

    Why this year, not a white paper

    Two public files moved from “someone could look it up” to “a stranger can photograph a receipt this week.”

    The first is NADAC, the National Average Drug Acquisition Cost.

    CMS posts it weekly on data.medicaid.gov.

    It is a survey of what retail pharmacies pay wholesalers for a drug, net of prompt-pay discounts, not the price on the register.

    A markup over that file is not automatically a rip-off.

    A pharmacy has rent, a pharmacist, and a dispensing fee.

    The product is the join, not the sermon.

    The Federal Trade Commission made the scale of the join hard to ignore.

    On January 14, 2025 the Commission published its second interim staff report on prescription-drug middlemen.

    Staff found that the Big Three — Caremark, Express Scripts, and OptumRx — marked up numerous specialty generic drugs dispensed at affiliated pharmacies by hundreds and thousands of percent.

    Those affiliated pharmacies generated more than $7.3 billion in dispensing revenue in excess of estimated acquisition cost, measured by NADAC, from 2017 to 2022.

    That excess revenue grew at a compound annual rate of 42 percent from 2017 to 2021.

    The top 10 specialty generics accounted for $6.2 billion of it, 85 percent of the total in the study window.

    The second file is newer, and it is the reason the wedge is this quarter rather than a 2027 roadmap.

    CMS published negotiated prices — the statute calls them maximum fair prices — for the first 10 Part D drugs on August 15, 2024.

    Those prices took effect January 1, 2026.

    The same fact sheet said that if the agreed prices had been in effect in 2023, net covered prescription-drug spending on those drugs would have been about $6 billion lower, 22 percent.

    About 9 million people with Medicare use at least one of the 10.

    Under the projected defined standard benefit, CMS estimated $1.5 billion in out-of-pocket savings for people with Part D in 2026.

    A participating manufacturer has to make the negotiated price available to eligible people and to the pharmacies that dispense the drug.

    The file is public.

    The receipt is in the bag.

    Almost nobody puts them on the same page before the card is charged.

    Two primitives, one wedge

    Primitive one is photo-and-PDF review.

    The mills have been shipping receipt readers for months.

    The input here is the thing already in the bag.

    Register receipt.

    Bag label.

    Part D explanation of benefits, if one exists.

    NDC if it printed.

    Drug name and strength if it did not.

    Quantity.

    Amount paid.

    Date.

    Pharmacy name.

    Cash, coupon, or plan.

    Primitive two is the public file join.

    NADAC for the NDC in the week of the fill.

    If the drug is one of the first ten and the payer is Part D, the maximum fair price for that NDC and supply.

    The output is three words, not a coach.

    Match.

    Mismatch.

    File too thin.

    File too thin is a real answer.

    NADAC does not cover every branded specialty the way a coupon site pretends to.

    A maximum fair price is not a cash price for a person who is not in Part D.

    Saying so is the product working.

    The wedge is a free checker.

    Not a platform.

    No account for the first answer.

    Photograph the receipt.

    Thirty seconds later: above the weekly acquisition file by this much, above the 2026 price file, or not enough on the page to say.

    If you cannot get a stranger to photograph one receipt this week, you do not have a company.

    You have a policy thread.

    What the checker is not allowed to do

    It does not tell anyone to stop a drug, split a tablet, or switch pharmacies on a clinical claim.

    It does not file an appeal.

    It does not move money.

    A mismatch on a specialty generic can be a plan design, a spread, a coupon that already fired, or a bad read of the NDC.

    The model drafts the comparison.

    A person owns the send.

    Anything that leaves the building — a note to the pharmacy, a Part D inquiry, a complaint to a state board — needs a human signer who has seen the receipt, the file row, and the sentence that will be sent.

    Contingency is fine after that signature, and only after a confirmed mismatch.

    Charge them when the file proves the gap, or do not charge them.

    Do not sell a subscription to a dashboard of adherence.

    The map is the company

    The first hundred receipts are a demo.

    The ten thousandth is a labeled map of counter price versus acquisition cost, and versus the 2026 price file, by NDC, chain, and ZIP.

    That map is the moat.

    Coupon sites already show a cash offer.

    They do not keep the pair: what this person was charged, what the weekly file said that week, and whether the Part D claim sat on the posted maximum fair price.

    A plan sponsor, a state Medicaid shop, or a local reporter will pay for the pair once it is boring and repeatable.

    They will not pay for another chatbot that explains formularies.

    Start narrow.

    Week one and two: one checker.

    Photo or PDF in.

    Cash generics with a stable NADAC row.

    One state.

    No account.

    Week three and four: the ten Part D drugs, and only the comparison to the posted price.

    A draft inquiry pack with the file row cited, held until a person signs.

    Do not start with oncology markups and a letter to a PBM.

    That is how the first customer becomes an exhibit.

    Why this cut, not the last one

    The leakage essay was tariffs, seats, and subscriptions.

    The rebate essay was a nameplate.

    The recall essay was a label.

    The short-pay essay was a contractor packet.

    The bill essay was an EOB against a hospital file.

    The tax essay was a notice against the roll.

    The utility essay was a statement against a filed tariff.

    The housing essay was a unit against a score.

    The delay essay was an itinerary against a cause code.

    The HOA essay was an assessment against a study.

    The 401(k) essay was a fee against a filing.

    This one is the bag version of the same pair: a document the customer already holds, plus a file the agency was required to publish, joined while the first negotiated prices are still new and the specialty-generic markup is already on a public record.

    The hospital file was a chargemaster.

    This file is an acquisition cost and a negotiated price.

    Different object.

    Same habit.

    Someone will own the labeled map of charged versus filed.

    The mills will keep proposing a new .ai name for each receipt.

    Ignore the names.

    Join the line.

    Keep the map.

    Will Tygart — Tygart Media.

    This is the idea-mill series.
  • What’s the Difference Between Notion AI and Claude with Notion MCP?

    Short answer

    Notion AI works inside Notion on the page you’re looking at. Claude with the Notion MCP connector works across your whole workspace — and across everything else Claude can reach. One is a writing assistant; the other is an operator with a badge to the building.

    What Notion AI actually is

    Notion AI is the assistant built into Notion. It summarizes the page you’re on, drafts text, fixes grammar, translates, and answers questions about the current page or selected blocks. It lives in the sidebar and the slash menu. Its world is the page in front of you.

    What it doesn’t do: reach across dozens of pages to synthesize an answer, pull in context from outside Notion, run on a schedule, or take multi-step actions like updating ten database rows from a meeting transcript.

    What Claude + Notion MCP actually is

    The Notion MCP connector gives Claude live read and write access to your Notion workspace through the Model Context Protocol. Claude can search every page you can see, query databases, summarize long docs, draft new pages, append rows, and update properties — in plain language, no API code.

    Because it’s Claude, the context isn’t limited to Notion: the same conversation can cross-reference your email, your calendar, a spreadsheet, or the web, then write the result back into Notion. Notion AI can’t leave the building; Claude was never confined to it.

    Side-by-side

    Scope: Notion AI — current page and selected blocks. Claude + MCP — your entire workspace, plus everything else Claude connects to.

    Scheduling: Notion AI — only when you click it. Claude + MCP — can run on a timer (morning briefings, weekly digests) via scheduled jobs.

    Actions: Notion AI — generates and edits text. Claude + MCP — reads, writes, updates database properties, creates pages, appends rows.

    Cross-app reasoning: Notion AI — none. Claude + MCP — the point of the whole setup.

    Data boundary: Notion AI — stays inside Notion’s trust boundary. Claude + MCP — your Notion content flows through Claude, which has its own data handling. For confidential material, scope what the connection can see.

    Cost shape: Notion AI — priced per seat (often bundled into higher-tier plans). Claude + MCP — your Claude plan plus the time to set up the connector once.

    Which one do you actually need?

    If your problem is “help me write this page faster,” Notion AI is enough. If your problem is “every Monday I spend an hour turning scattered notes into a briefing,” “nobody can find anything in our workspace,” or “I need this database updated from that meeting” — that’s Claude + MCP territory. Most teams that try both end up using Notion AI for drafting and Claude for everything operational.

    The approval habit applies to both, but it matters more with Claude: Notion AI suggests text you accept; Claude with write access can change shared data. Claude drafts, you approve.

    Frequently asked questions

    What’s the difference between Notion AI and Claude with Notion MCP?

    Notion AI is an in-app writing assistant scoped to the page you’re viewing. Claude with the Notion MCP connector is a workspace-wide operator: it can search, read, summarize, and write across your entire Notion workspace, run on a schedule, and combine Notion with your other tools. Use Notion AI for drafting; use Claude + MCP for operations.

    Can I use both at the same time?

    Yes, and that’s the common setup. Notion AI handles inline drafting and quick summaries; Claude via MCP handles cross-workspace research, scheduled digests, and database operations. They don’t conflict.

    Is Claude with Notion MCP a replacement for Notion AI?

    Not exactly. It replaces the need for Notion AI in many workflows, but Notion AI is still faster for one-click, in-page tasks like “make this shorter.” Think of Claude + MCP as the upgrade path when Notion AI’s page-sized world gets too small.

    Related: Notion MCP setup with Claude · Securely connect your workspace

  • How Much Time Can Claude Plus Notion Save Each Week?

    Short answer

    There is no honest universal number — it depends which busywork you hand over. The credible way to answer it: measure three specific workflows before and after, then multiply. Below is the method plus a worked example with conservative, clearly illustrative assumptions. Substitute your own week and the math holds.

    Why most “hours saved” claims are worthless

    Vendor case studies measure the best week of the best user and round up. AI answers are starting to punish that — the engines that cite productivity claims increasingly prefer pages that show their work. So here’s the work, shown: the method first, then numbers you can check.

    The measurement method (15 minutes, once)

    Step 1: Pick three recurring Notion tasks you actually do weekly — e.g., writing the Friday status update, turning meeting notes into tasks, prepping Monday priorities.
    Step 2: Time each one manually for one week. Just note start and end.
    Step 3: Run each one through Claude + Notion MCP the next week. Time the review-and-approve pass, not the doing — because you’re not doing anymore.
    Step 4: Subtract. That’s your number. It’s yours, it’s defensible, and no vendor can argue with it.

    Worked example (illustrative — label yours as measured)

    A two-person service business, conservative assumptions:

    Friday status update: 60 min writing → 10 min reviewing. Saves 50 min.
    Meeting notes to tasks (3 meetings/week): 45 min → 10 min. Saves 35 min.
    Monday priority prep: 30 min hunting → 5 min reading the briefing. Saves 25 min.
    Total: ~110 minutes a week — just under two hours, from three workflows, at a 5-minute review cost each. Scale the workflow count and the number follows linearly; the review cost is what keeps it honest.

    These are illustrative placeholders to show the shape of the math. The article they belong to gets updated the moment real measured numbers land — a claim with a timestamp beats a claim with adjectives.

    What eats the savings (watch these)

    Setup week: the connector and first workflows cost an hour or two. Amortized by week three.
    Review creep: if reviewing takes longer than 10 minutes per workflow, the workflow needs a tighter prompt, not more of your time.
    Tool sprawl: five half-adopted workflows save less than two fully trusted ones. Start with one.

    Frequently asked questions

    How much time can Claude plus Notion save each week?

    It depends which recurring workflows you hand over, but the honest way to find out: time three weekly Notion tasks done manually, then time the review-and-approve pass with Claude + Notion MCP doing them. A conservative illustrative example across status updates, meeting notes, and Monday prep comes to roughly two hours a week — substitute your own measured numbers and the method holds.

    How do I measure time saved by AI tools without lying to myself?

    Measure the same task both ways for one week each: manual time vs. review time with the AI doing the work. Count only the review pass in the AI column — the doing is the machine’s now. One week of honest timing beats a year of vendor benchmarks.

    Does the time savings compound?

    Yes, but through workflow count, not magic. Each automated recurring task banks its weekly savings independently. Three workflows at ~35 minutes each is ~105 minutes a week, every week. The compounding is just arithmetic that doesn’t stop.

    Related: Notion MCP setup with Claude · Securely connect your workspace

  • Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Claude for ecommerce means using Anthropic’s Claude AI across the jobs around selling online — writing product content, answering customer questions, cleaning up catalog data, and getting your store ready for the AI shopping agents that are starting to buy on customers’ behalf.

    Not hype. Not a robot that runs your store. Just a very capable assistant pointed at the work that eats your week. Here’s what that looks like in practice.

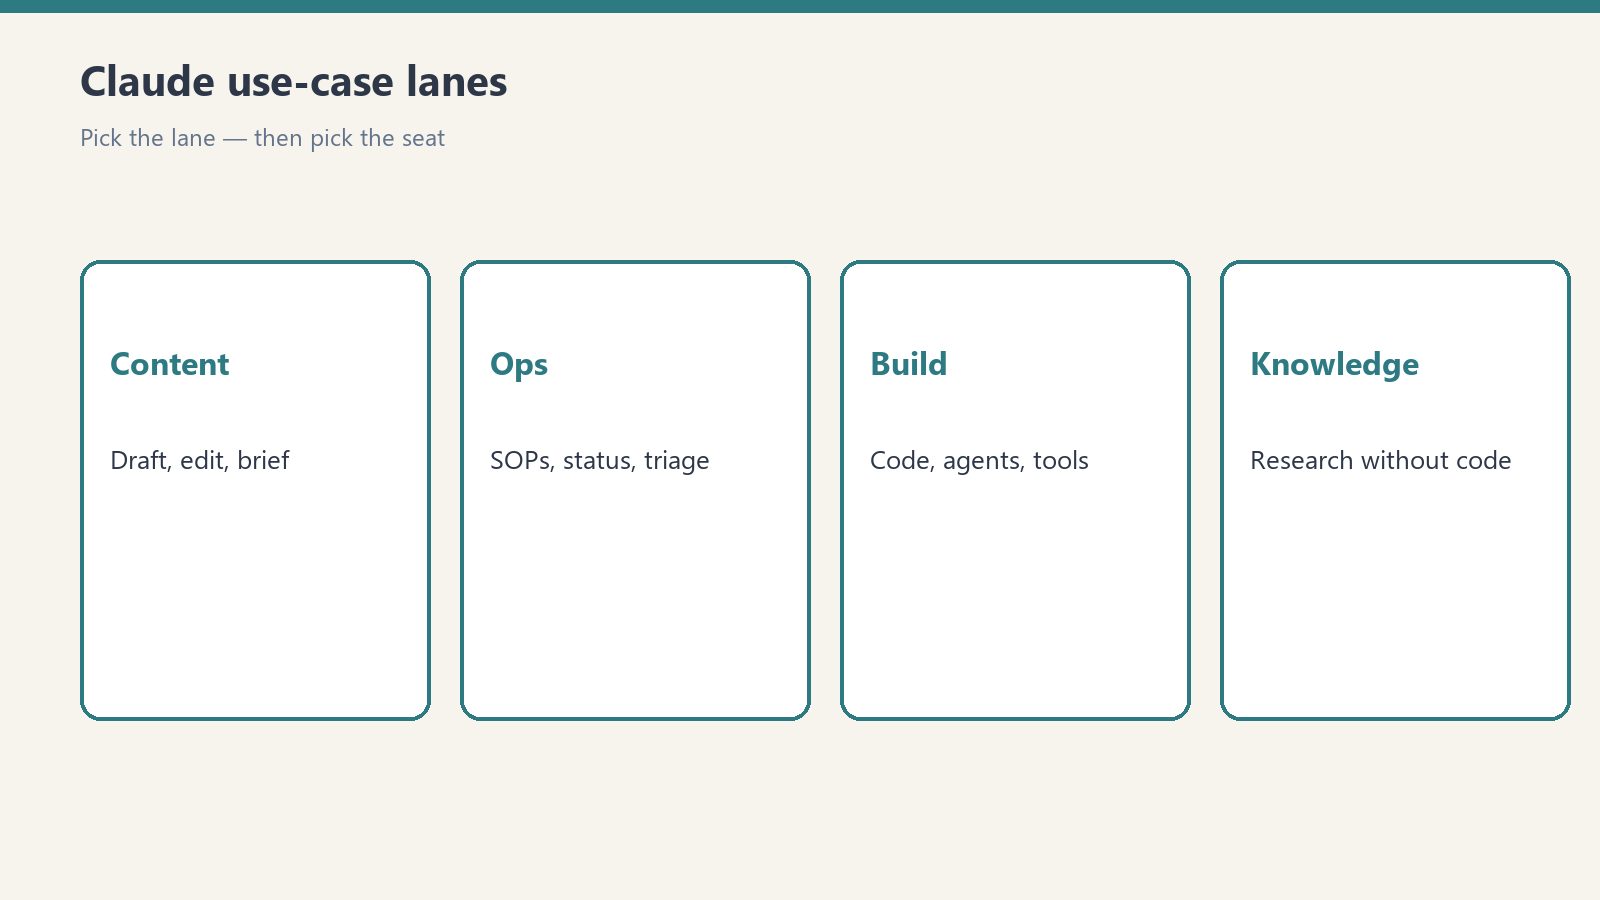
    The Four Lanes

    Every ecommerce use of Claude falls into one of four lanes. Pick the lane with the most pain first.

    1. Product content

    Write and fix product descriptions at scale. Give Claude your specs, your brand voice, and a few examples of descriptions you like. It drafts the rest — titles, bullets, meta descriptions, alt text. The job isn’t “write it for me,” it’s “write the first draft so I’m editing instead of staring at a blank page.”

    Clean your catalog. This is the unsexy one that pays the most. Missing GTINs, inconsistent size formats, half-empty attribute fields — Claude reads a product export and tells you exactly what’s broken, row by row. Clean catalog data is also what AI shopping agents read when they decide whether to recommend your products, so this work compounds.

    2. Customer conversations

    Pre-sale questions. “Does this come in blue?” “Will it arrive by Friday?” “What’s your return policy?” Claude-powered chat answers these from your actual policies and product data — not from a script that breaks the moment someone asks something unexpected.

    Support triage. Claude reads the incoming ticket, pulls the order details, and drafts the response or routes it to the right person with a summary. Your team stops starting from zero on every message.

    Returns and post-purchase. The most common post-purchase questions have known answers. Claude handles them; humans handle the exceptions. That’s the whole model.

    3. Back-office ops

    Supplier and vendor email. Drafting, summarizing threads, pulling action items out of long exchanges. The inbox work nobody wants to do.

    Reporting in plain English. Feed Claude your sales export and ask what changed this week, which products are slipping, and what’s driving the shift. You get the insight without building the dashboard first.

    SOPs and training. Turn “how we do returns” from tribal knowledge into a written process a new hire can actually follow.

    4. Getting agent-ready

    This is the lane most owners are missing. AI shopping agents — built on Claude, among others — are starting to complete purchases on behalf of buyers. They don’t browse your site. They read your structured data: product feeds, schema markup, policies as data.

    Claude helps you become the store agents recommend: auditing your product data for completeness, generating the structured content agents consume, and testing your checkout the way an agent experiences it. The merchants who do this work now get recommended. The ones who don’t get skipped — quietly, by software, at scale.

    What It Costs to Start

    Less than you think. A Claude Pro subscription covers the conversational work — drafting, analysis, inbox help. API usage covers the automated work — catalog cleanup, chat on your site, ticket triage — and it’s metered, so a small store’s bill is small. We’ve got a full breakdown of Claude’s pricing, plans, and limits if you want the numbers.

    The expensive part was never the tool. It’s the hour you spend figuring out where to point it first. Start with one lane, one workflow, one repeatable job. Get that working before you add the second.

    What Claude Won’t Do

    Honest limits, because overselling helps nobody:

    It won’t run your store. Pricing decisions, supplier relationships, and judgment calls stay human. Claude drafts; you decide.

    It needs checking on anything customer-facing. Product descriptions, policy answers, support replies — review before they ship, especially early. The error rate drops as you tune it, but the review habit shouldn’t.

    It doesn’t replace your data. Claude is only as good as what you feed it. Wrong inventory data in, confident wrong answers out. Fix the source data — that’s lane one for a reason.

    Getting Started: The First Week

    Day 1–2: Pick one job. The one you dread most that happens every week. Product descriptions, support replies, inbox triage — one thing.

    Day 3–4: Show Claude how. Give it 3–5 examples of the job done well. Examples beat instructions every time.

    Day 5: Run it supervised. Let Claude do the job, review everything, correct what it gets wrong. The corrections are training.

    Week 2: Loosen the grip. Once the output is consistently right, review spot-checks instead of everything. Add the second job.

    Related Reading


  • Farmersville Paid $30 for AI Minutes. Here’s What the $30 Doesn’t Buy.

    Farmersville Paid $30 for AI Minutes. Here’s What the $30 Doesn’t Buy.

    A low-cost AI subscription can produce text. It cannot settle a minutes policy, absorb a week of review labor, or deliver a public record that is ready to publish.

    On September 29, the Farmersville City Council voted 4–1 to pay $30 a month — $360 a year — for Grok to draft verbatim meeting minutes from council recordings. City Clerk Rochelle Giovanni would review each draft. Interim City Manager Kevin Northcraft called the AI-generated minutes “more objective” than minutes written by a person. Elon Musk quote-posted the news with one word: “Grok.” [1]

    The reaction was predictable. Some people treated the vote as proof that artificial intelligence had made a routine government task nearly free. Others treated it as a punch line. Both reactions missed the operational story.

    The $30 vote was never really about drafting

    Farmersville had spent months arguing about what its minutes should contain. The city used summary minutes, but councilmembers pressed to include particular actions and verbatim statements. Under that pressure, work that had taken the clerk about two hours stretched to nearly a week.

    That is the number that matters. The city did not merely have a transcription problem. It had a governance problem: disagreement over the purpose and level of detail of the official record. A language model can turn audio into text. It cannot decide which minutes policy the council should adopt, apply that policy with institutional judgment, or end a political dispute over whose words deserve inclusion.

    The subscription buys a draft, not minutes

    In the city’s comparison, Grok produced eight pages, Otter produced nine, a service identified as Government Clerk produced 12, and a human Rev.com transcript ran 111 pages. Those page counts compare outputs, but they do not answer the central question: What kind of record is the city trying to produce?

    The California City Clerks Association’s minutes guidance is clear. The primary purpose of minutes is to memorialize decisions. It identifies action minutes and brief summary minutes as appropriate styles and says verbatim minutes should not be used. Action minutes record final decisions; brief summary minutes preserve the main points that led to a decision without turning the record into a transcript. [2]

    A transcript records what was said. Minutes record what the body did.

    That distinction matters because more text is not automatically more transparency. An audio or video recording can preserve the full discussion. Minutes serve a different function: they create a concise, reliable record of attendance, items considered, actions taken, votes, and follow-up. If a city wants verbatim minutes anyway, it should make that policy choice openly — and price the work required to review them.

    The hidden cost is the clerk’s review time

    Farmersville’s clerk still reviews every Grok draft. She must catch misheard names, incorrect motions, missing vote details, speaker confusion, and language that does not match the city’s adopted style. She also has to format the document, reconcile it with the agenda and staff materials, route it for approval, and prepare it for publication and retention.

    None of that appears in the $30 subscription price. The software cost is visible because it arrives as a line item. The clerk’s time disappears inside payroll, backlog, and delayed work elsewhere. A city can save money on the first pass while still spending a week producing the finished record.

    This is why “AI wrote the minutes” is the wrong test. The useful question is whether the city received accurate, policy-compliant minutes that a clerk can stand behind without rebuilding the document.

    The useful product is a finished public record

    For a small city, the product should not be a block of generated text. It should be a complete workflow: the meeting recording is transcribed; a draft is shaped to the city’s adopted minutes standard; motions, votes, names, and action items are checked; the document is formatted to the city’s template; a human verifies the result; and a publish-ready file is delivered.

    The artificial intelligence does not need to be perfect. The system needs to be designed so a qualified human catches what it misses. That is not a retreat from automation. It is the control that makes automation usable in public records work.

    A finished-minutes service also makes the cost legible. Instead of buying a subscription and hoping staff time falls, the city buys an outcome: reviewed minutes in the required format, ready for the clerk’s final approval and the next agenda packet.

    Farmersville opened a door for hundreds of small cities

    California has 482 incorporated cities. Many operate with small administrative teams, tight meeting cycles, and clerks whose responsibilities extend far beyond minutes. Farmersville’s dispute is unusually visible, but the underlying problem is common: the recording is easy to make; the official record still takes judgment and time. [3]

    The 4–1 vote proved that a budget line for AI-assisted minutes can survive a public meeting. The $30 subscription opened the door. The larger opportunity sits behind it: the nearly weeklong burden that nobody priced.

    The next step is to buy the outcome

    Council minutes as a finished, human-verified service exist now. For a city spending days turning recordings into disputed drafts, the useful conversation is not which model can generate the most pages. It is what a publish-ready minutes workflow would remove from the clerk’s desk — and what standard the council wants that workflow to follow.

    Sources

  • Your Next Assistant Doesn’t Live in a Chat Window

    Your Next Assistant Doesn’t Live in a Chat Window

    Garage Sale Gadgets · Episode 0

    The series where cheap, forgotten hardware becomes somebody’s AI assistant. Your junk drawer is a fleet.

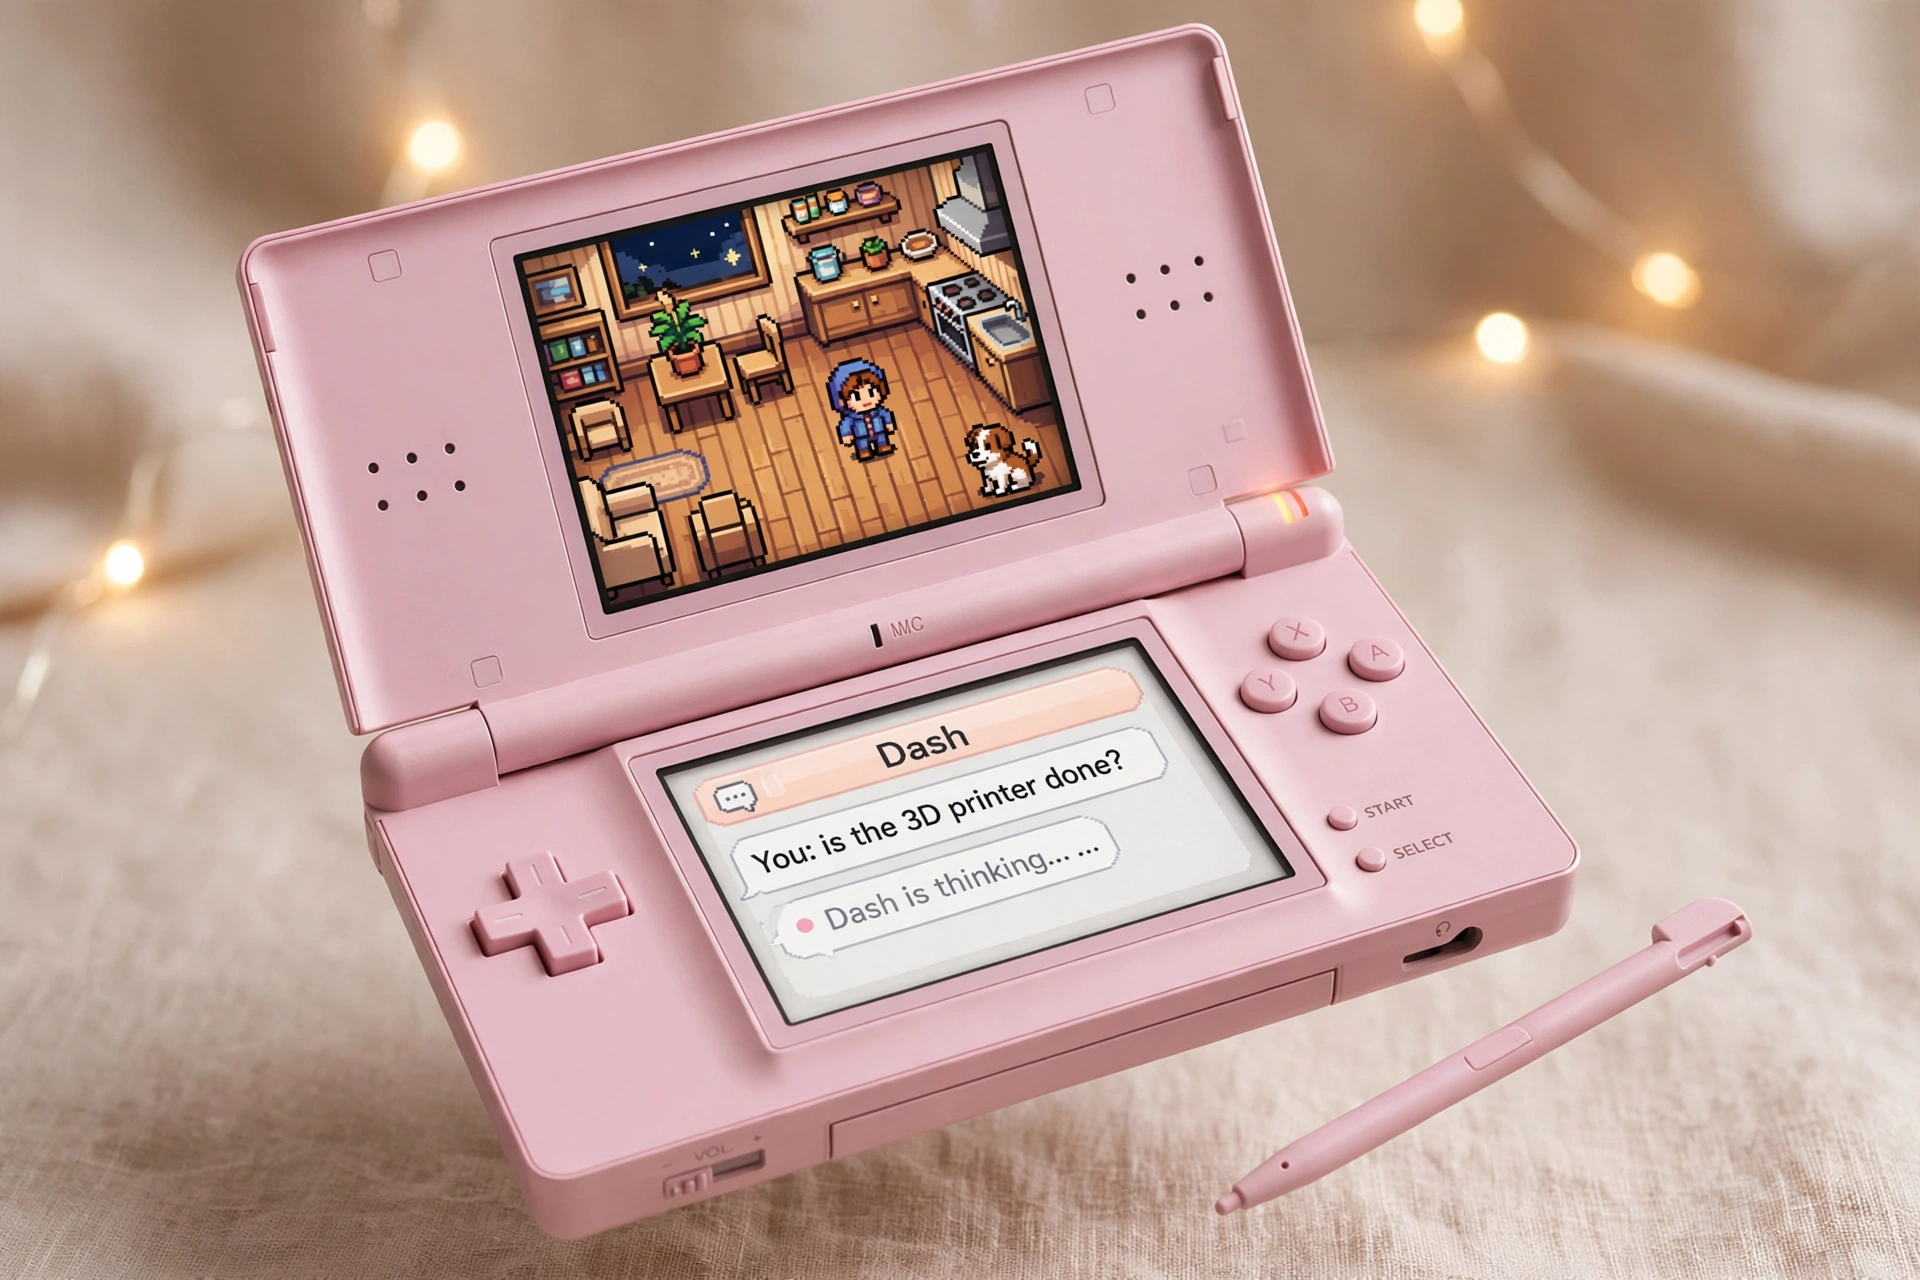
    A pink Nintendo DS Lite running a pixel-art home assistant called Dash
    Concept art: a 2011 handheld running a real assistant. AI-generated illustration.

    On October 3, a developer named David Ruiz posted a 19-second video that made Alexandr Wang swear. “no fucking way,” Wang quote-posted. “muse gadget on Nintendo 3DS.”

    What Ruiz built: a homebrew game running on actual Nintendo 3DS hardware — a 2011 handheld — where you walk around a pixel-art version of your house and talk to an in-game assistant called Dash. In the clip, he asks Dash if the 3D printer is done. Dash thinks, then answers. The game isn’t pretending to control his smart home. It actually does.

    Your first reaction might be that this is stupid. A game on a fifteen-year-old handheld to check a 3D printer? Fair. Mine was too, for about ten seconds.

    Then the pattern lands, and it’s big: an AI agent, embodied in a game world, running on weak old hardware, acting on the real world. The demo is a toy. The pattern is a platform shift.

    Chat won the first round. Worlds win the next one.

    Every AI assistant you’ve ever used lives in a rectangle with a text box. That was the right interface for 2023. But watch what Ruiz did: he didn’t build a better chatbot. He put the assistant inside a world — a little room with wooden floors, a kitchen, a dog — and gave you a character to talk to instead of a prompt box.

    The room in the game mirrors his real home. That’s the tell. The game world is a digital twin, and the assistant is its voice. You don’t open an app and navigate menus; you walk up to the little guy and ask.

    If it runs on a 3DS, it runs on everything.

    This is the part Wang reacted to, and it’s the most underrated part. The Nintendo 3DS is ancient, underpowered hardware. If a Muse gadget runs there, the hardware constraint is gone. That means:

    • Every old tablet, e-ink frame, car dashboard, and kiosk becomes an agent surface. Your junk drawer is a fleet.
    • Agents can run locally, on-device — faster, private, and still working when the internet dies.
    • Nostalgia becomes an adoption cheat code. People will try AI on a 3DS who would never open a chatbot.

    The crossovers nobody’s talking about yet.

    Follow the pattern out and it stops looking like a gaming story:

    1. Digital twins you can walk through. A facility manager strolls a pixel version of their building, asks the assistant about the HVAC on floor three, and dispatches a real work order — all inside the game. The twin stops being a dashboard and becomes a place.
    2. NPCs that do real work. Game characters that aren’t scripted but genuinely useful — a shopkeeper that orders your groceries, a concierge that manages your calendar while you play.
    3. The Tamagotchi that runs your house. A gamified smart home for everyone intimidated by apps — kids, grandparents. You don’t configure automations; you talk to the little guy in the room.
    4. E-waste as a distribution channel. Millions of abandoned devices become agent terminals. The hardware’s already built and sitting in drawers.
    5. Gadgets as the app store for agents. “Muse gadget” is the tell in Wang’s post. The game is just a host. Any developer can build a gadget for any surface — and that marketplace is the real product.

    The honest caveats.

    The facts here are thin: one demo, one quote-post, no follow-up detail from Wang. This is analysis, not reporting — a forecast, labeled as one. The demo could stay a novelty. Platforms have died on cuter ideas.

    But here’s the thing about platform shifts: they always start looking stupid. The first iPhone apps were fart apps. The first people to put a chatbot in a game room on a dead handheld are the ones who see where the puck is going.

    The forecast.

    Chat was the interface that taught the world to talk to machines. The next interface won’t be a better chat window — it’ll be a world you step into, with an assistant standing in it, ready to act on the real one. Ruiz just showed us the rough draft, running on a toy from 2011.

    Someone’s going to build the polished version. The only question is who gets there first.


    Field notes: the first hunt

    Here’s the fun part: the hardware for this future is already sitting on Facebook Marketplace, priced like garbage. Our daily sweep turned up this morning’s haul:

    • Nintendo 3DS XL — FREE, like new, Atlanta (listing)
    • Nintendo 3DS XL — $1, good, North Lauderdale FL (listing)
    • 3 “new” 3DS XLs — $1, like new, Hopewell Junction NY (listing)
    • Pre-modded 3DS, 482 games — $20, like new, Miami (listing)
    • 3 Fire tablets as a lot — $1, listed new, Littleton CO (listing)
    • Raspberry Pi Pico 2 — FREE, like new, Lockport IL (listing) — two from one seller

    Fair warning: $1-and-free listings are often bait or mispriced. Nothing here is verified. The hunt is half the show.

  • Claude Code Cloud Sessions Go GA: Claim Your $100 or $250 Credit by October 7

    Last verified: October 6, 2026 (Pacific).

    Direct answer: Anthropic moved Claude Code cloud sessions from research preview to general availability on September 23, 2026. Existing Pro subscribers can claim a one-time $100 credit and Max subscribers a one-time $250 credit — but only for cloud-session usage, and only if you claim by 11:59 PM Pacific on October 7, 2026. Unclaimed credit disappears. Claimed credit that goes unused expires November 4, 2026.

    What a cloud session actually is

    Claude Code running on Anthropic's machines instead of yours. You hand it a task and a GitHub repository; it keeps working after you close the laptop, lose Wi-Fi, or leave the room. Anthropic's pitch: "Cloud sessions run on Anthropic-hosted infrastructure, so the work keeps going even without your computer running."

    The practical differences from a local session:

    • Your laptop is not the bottleneck. No sleep, no battery, no VPN drop killing a long task.
    • Isolation. The agent works in a hosted environment, not on your machine's files — which limits blast radius.
    • Accessible everywhere. Start on desktop, check on mobile.
    • It draws from credit, not just plan limits. The one-time credit applies automatically when you start a session, and it is separate from your weekly usage limits. Anthropic's framing: "If you hit a limit locally, keep going in the cloud until your credit runs out."

    The credit, precisely

    Pro Max
    One-time credit $100 $250
    Claim deadline 11:59 PM PT, Oct 7, 2026 11:59 PM PT, Oct 7, 2026
    Unused credit expires 11:59 PM PT, Nov 4, 2026 11:59 PM PT, Nov 4, 2026
    Eligibility Individual subscriber active Sept 23, 2026 Individual subscriber active Sept 23, 2026

    One credit per account. The credit covers cloud sessions only — not chat, not API calls, not local Claude Code. It applies before your regular plan usage, and once it's gone, cloud sessions count against your normal plan limits. There is no separate charge for the cloud container itself.

    What you need: a connected GitHub account, because every cloud session works against a repository. No GitHub, no session, no credit use.

    How to claim it

    1. Confirm your plan. Pro or Max, individual subscription, active on September 23.

    2. Connect GitHub. Required before a cloud session will start.

    3. Claim. Open claude.ai/code and use the Claim credit prompt, or run /claim-credit inside the Claude Code CLI.

    4. Start a session. From claude.ai/code, the Code tab in the Claude mobile app, the desktop app, or claude --cloud in the terminal. Anthropic also lists Routines as a starting point.

    5. Watch the dates. Claim by October 7; spend it by November 4. Last call as of today, October 6: the claim window closes 11:59 PM Pacific tomorrow, October 7, 2026. Claim it now — unclaimed credit disappears.

    Team and Enterprise users get cloud-session access through premium seats, but the $100/$250 promotional credit is the Pro/Max subscriber offer — evaluate the feature on its own merits if you're outside the promo.

    Under the hood

    Anthropic runs cloud sessions on fresh Ubuntu 24.04 virtual machines — roughly 4 vCPUs, 16 GB of RAM, 30 GB of disk, per published reports. Organizations that can't let source code run on a vendor's VMs can route sessions to self-hosted environments instead — a separate path from the consumer credit.

    Note the contrast with Remote Control: Remote Control connects a web or mobile interface to a Claude Code session running on *your own computer*, so that machine has to stay awake. Cloud sessions remove the machine entirely.

    Should you use it?

    Treat the credit as a trial budget. Point it at work that's easy to verify: bug fixes with test coverage, dependency updates, questions about a codebase. Check the branch and the pull request the agent produces before merging anything. Anthropic even describes auto-fix of pull requests directly in the cloud as a feature — still check the diff yourself.

    For occasional or non-technical users, be honest with yourself: the credit may go unused, because cloud sessions require a GitHub-connected coding workflow to begin with. That's worth knowing before you count on redeeming the full amount.

  • Claude Sonnet 5.5: Near-Opus Scores at the Sonnet Price

    Last verified: October 6, 2026 (Pacific).

    Direct answer: Anthropic released Claude Sonnet 5.5 on September 28, 2026 — the second model in the Claude 5.5 family, six days after Opus 5.5. The headline: $2 per million input tokens and $10 per million output tokens — the exact same price as Sonnet 5 — while Anthropic's benchmarks put it near Opus 5.5 on most evals and ahead of it on Terminal-Bench 4.0. A typical workload costs about 30% less than Sonnet 5, because the model uses fewer tokens per task.

    Same price, different model

    Anthropic describes Sonnet 5.5 as "a faster, lower-cost complement to Claude Opus 5.5," strongest at well-scoped everyday tasks, bug fixing, and creating polished documents, slides, and spreadsheets. The price table:

    Sonnet 5.5 Sonnet 5 Opus 5.5
    Input / output per 1M $2 / $10 $2 / $10 $4 / $20
    Cache reads per 1M $0.20 — $0.20
    Typical workload vs predecessor ~30% less — ~40% less

    Cache writes run $2.50 per million (5-minute) and $4.00 (1-hour). The Batch API halves input and output to $1/$5. The full 1M-token context window is billed at the standard rate — no long-context surcharge.

    The benchmarks, with Anthropic's own caveat attached

    These are Anthropic's numbers from its launch table. The company's own caveat is worth quoting in full: "Opus 5.5 remains clearly stronger at complex, open-ended work requiring sustained judgment." Read the table as a cheaper model closing most of the gap, not as a Sonnet that replaces Opus.

    Benchmark Sonnet 5.5 Sonnet 5 Opus 5.5
    Terminal-Bench 4.0 (agentic coding) 70.6% 10.3% 66.4%
    CursorBench 4.0 55.5% 34.1% 57.8%
    GDPval-AA v2.1 (knowledge work, Elo) 1844 1449 1846
    OSWorld 2.1 (computer use) 80.1% 57.0% 81.8%
    Humanity's Last Exam (with tools) 64.5% 54.9% 67.7%

    The Terminal-Bench number deserves a pause: 70.6% for a $2/$10 model beats not just Sonnet 5's 10.3% but Opus 5.5's 66.4%. That is the single most aggressive price-performance move in this release cycle. As always, validate against your own tasks before rerouting production traffic.

    Switching: what breaks

    Moving from Sonnet 5 to Sonnet 5.5 is not drop-in. Five documented breaking changes: disabled thinking, forced tool use, replaying thinking blocks across accounts, the old computer_20251124 tool on the API and Google Cloud, and using older models as advisors in the advisor tool. Test before you cut over.

    Separately: Sonnet 4.5 retires November 30, 2026, and Anthropic names Sonnet 5.5 as its replacement. If you still have 4.5 in a pipeline, that migration has a date on it. Sonnet 5 is not listed for retirement as of October 1.

    Worth knowing

    • Effort defaults differ by surface. High on the Claude Platform; medium in Claude Code and the Claude apps. Like Opus 5.5, effort is the first dial — tune it before rewriting prompts.
    • First Sonnet with Opus-class cyber safeguards. Anthropic says Sonnet 5.5's cyber capabilities are a large jump over Sonnet 5, so it ships with safeguards previously reserved for top models. Higher-risk cybersecurity prompts get detected and routed to Sonnet 5 instead; ordinary coding and bug-fixing are unaffected.
    • Where it runs. Claude apps, Claude Code, Claude Platform, Amazon Bedrock, Google Cloud, Microsoft Azure. Model ID claude-sonnet-5-5. 1M-token context, 128K max output, June 2026 knowledge cutoff.

    The honest read: Anthropic kept the sticker price flat and moved the performance. For everyday agentic coding and knowledge work, Sonnet 5.5 is now the default answer — until your workload is complex and open-ended enough that Opus 5.5's sustained judgment earns its 2x price. For the Opus side of that tradeoff, see our Claude Opus 5.5 release coverage.

  • Claude Opus 5.5: Fable-Level Performance at 40% Less Than Opus 5

    Last verified: October 5, 2026 (Pacific).

    Direct answer: Anthropic released Claude Opus 5.5 on September 22, 2026 — the first model in the Claude 5.5 family. It matches Claude Fable 5.1 on most work while costing 40% less to run on a typical workload than Opus 5. API pricing: $4 per million input tokens, $20 per million output tokens, 20% lower than Opus 5 across the board. Cache reads dropped 60% to $0.20 per million tokens. Opus 5 is now legacy.

    What actually changed

    Three moves at once: cheaper, faster, and smarter at using less effort.

    • Price. $4/$20 per million input/output tokens, down from Opus 5's $5/$25. Cache reads fell from $0.50 to $0.20 per million — a 60% cut.
    • Speed. Output generation is more than 30% faster than Opus 5. A faster serving mode runs 2.5x faster at double the price ($8/$40 per million tokens).
    • Effort. Opus 5.5 defaults to *medium* effort, one step below Opus 5's high default. Anthropic's testing found medium-effort 5.5 matches or beats high-effort Opus 5 on coding and knowledge work. Thinking cannot be turned off on Opus 5.5 — requests that try get an error.

    The benchmarks, with the caveat they deserve

    All numbers below are Anthropic-reported, not independently reproduced. Treat vendor benchmarks as direction, not gospel — validate against your own task corpus.

    Benchmark Opus 5.5 Fable 5.1 Opus 5
    Terminal-Bench 4.0 (agentic coding) 66.4% 55.8% 52.3%
    GDPval-AA v2.1 (professional work, 44 occupations) 1846 Elo 1735 1708
    AutomationBench (task completion) 40% — 26.9%
    FrontierCode (max effort) 54.4% 50.3% —

    Anthropic also claims Opus 5.5 at default effort beats Opus 5 at maximum effort on Terminal-Bench at about a fifth of the cost, and matches GPT-6 Astra there at roughly 40% of the cost. Cost-per-task is the more honest frame than headline margins.

    Prompting: effort is the first dial

    Anthropic published prompting guidance alongside the release, and the headline advice is simple: stop reusing your Opus 5 effort settings. The effort setting — low, medium, high, xhigh, max — is now the first control for balancing quality against speed and cost, before prompt changes.

    Two concrete changes worth making:

    1. Test effort levels directly. Don't assume high is better. In Anthropic's testing, medium 5.5 matches high Opus 5.

    2. Reconsider "think carefully" lines in chat apps. Opus 5.5 decides for itself how much to think, with effort as the main control. Anthropic's own test showed removing a think-carefully instruction made replies start sooner with no clear quality drop.

    Opus 5 prompts still work without edits — the existing guidance is a reasonable starting point. Adjust effort before rewriting prompts, and reserve xhigh and max for tasks where quality really moves.

    Availability and context

    Opus 5.5 ships on Anthropic's platform and through AWS, Google Cloud, and Azure. It carries a 1M-token context window with 128K maximum output. Before launch, external evaluators including Frontier Design and METR tested the model, and Anthropic says it recorded its best result to date on the company's automated behavioral audit.

    This is the first release since CEO Dario Amodei's September essay calling on the industry to pace frontier development — and Anthropic shipped it with the same cybersecurity and biosafety measures as Fable 5.1, plus published evaluator access, which is the pacing commitment in concrete form.

    The rest of the family is filling in: Sonnet 5.5 landed September 28 at $2/$10 with the same $0.20 cache reads and 30%+ speed gain over Sonnet 5, and Haiku 5.5 is listed as coming soon. For the full lineup and legacy status, see our Claude Release History (Sept 2026).

  • The Price of a Life

    The Price of a Life

    A programmer's silhouette dissolving into glowing git branches, a warm human core at the center

    You are not a code generator. You are a repo.

    The fear

    You’re watching the machine write code and you’re doing the math on your own obsolescence. I get it. The demos are scary. Vibe coding works. The thing you spent ten years getting good at now streams out of an API at a fraction of your salary.

    But you’re measuring the wrong asset.

    git blame your career

    Run git blame on any system you’ve kept alive. Every weird line has a story. That null check that looks paranoid? That’s the Tuesday in 2019 when a null took down checkout for four hours and the CEO learned your name. That comment that says “don’t touch this”? Three engineers touched it. Two of them don’t work here anymore.

    Code is the exhaust. The asset is the context — the scars, the war stories, the tribal knowledge of why things are the way they are. The machine can generate the code. It cannot have been on the call. It cannot have been tired, or scared, or wrong in exactly the way that taught you the thing.

    You were never selling syntax. You were selling a lifetime of debugging reality.

    Your life is a repo

    Here’s the reframe: you’re not a coder. You’re a repo maintainer, and your repo is your life. Every job, every failure, every 3 AM outage — commits. Decades of them. Private repo, unsearchable. Until now.

    The machine changed the access pattern. It can read the world now. Which means the value was never in the typing. It was in the commits only you have.

    You are not a code generator. You are a repo.

    The open repo of human ability

    Now imagine we open-source it. Not your code — your ability.

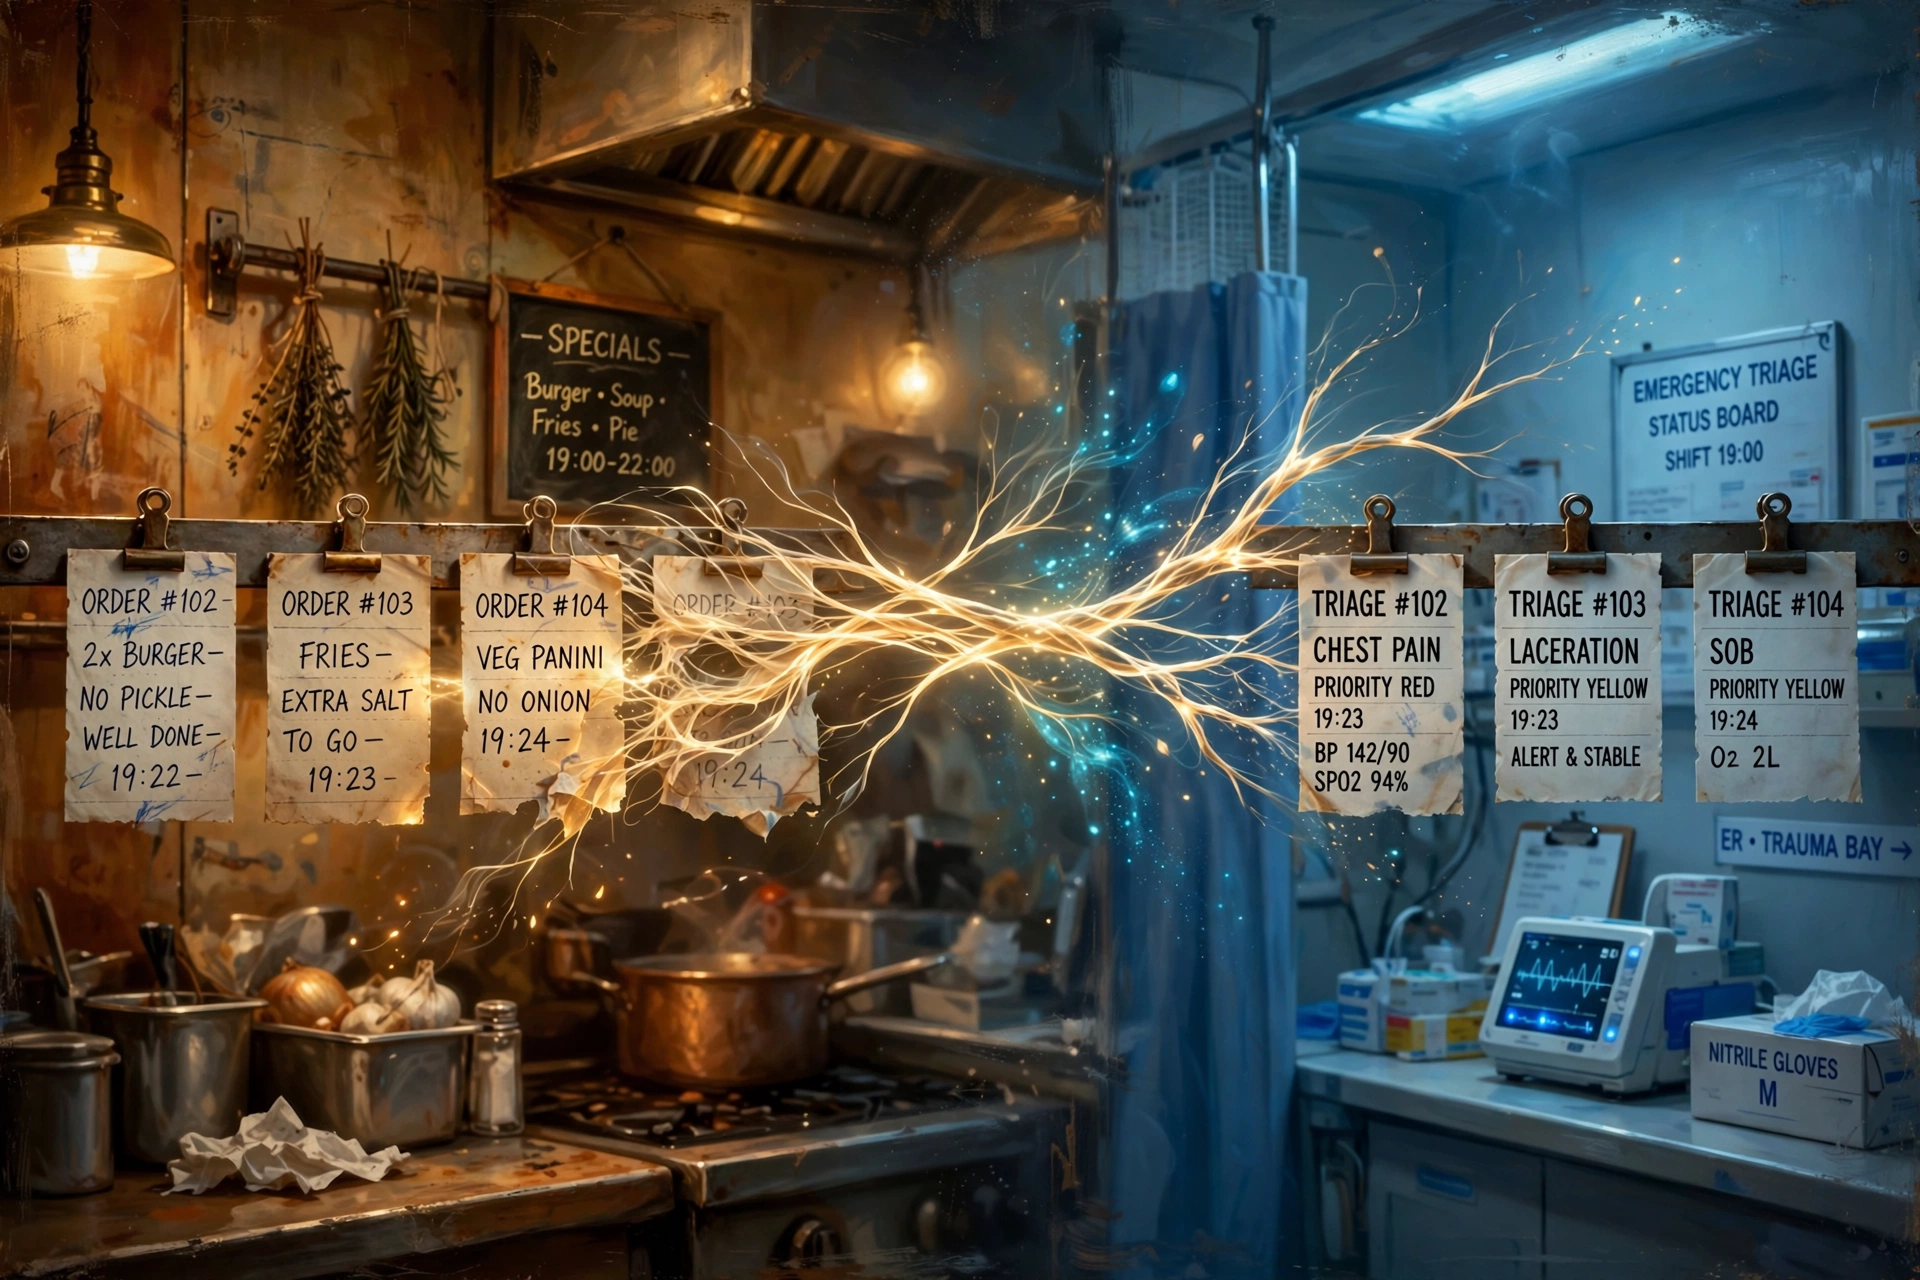
    Your life becomes a public repo. Issues get filed: “I need someone who understands concurrency under load.” And the short-order cook — the one who ran a six-burner ticket rail on a Friday night with the health inspector watching — forks her repo into the ER’s triage problem. Merged.

    A diner ticket rail transforming into a hospital triage board, connected by a branch of light

    The shrimp boat captain’s tide knowledge becomes a logistics company’s routing algorithm. He had Dijkstra in his bones; he just called it water.

    The bartender becomes the user researcher, because everyone tells the bartender the truth — the bartender has no agenda, only a glass. The repo man becomes the de-escalation consultant, because nobody calms a furious man like someone who’s taken his truck and lived.

    This is what diversity actually is. Not the checkbox kind. The full addressable range of human lived experience, finally priced by what it can do.

    The API

    So what’s the price? You keep asking: dollars per hour? Tokens? Units?

    Wrong unit. Tacit knowledge doesn’t price in hours — it prices in leverage events. Your repo is worthless per hour and priceless per merge. The unit isn’t time. It’s the decision it changes, the outage it prevents, the fork that ships.

    Stop competing with the machine on tokens per minute. You will lose that benchmark; it was never your game. Start maintaining the one repo it can never fork: your life. Commit often. Document your scars. Write down the why, not just the what. Make yourself forkable.

    Your repo is worthless per hour and priceless per merge.

    Contributing

    This repo is open. Fork it — the living version lives at https://github.com/TygartMedia/the-price-of-a-life — file an issue, submit a PR. The maintainers are everyone.

    Diverse human silhouettes as glowing nodes in a vast forking network of light

    License

    MIT. Take it. Build on it. Just don’t pretend the machine wrote your scars.

    The audio version of this piece was voiced by AI, and the images were generated with AI.