Tag: AI Tools

  • 44 AI Models, One Identical Brief: What the Flight Recorders Showed

    44 AI Models, One Identical Brief: What the Flight Recorders Showed

    From the Tygart Media research desk — our own test, our own sites, our own receipts.

    We gave every AI model in our agent catalog the same small job, word for word, and then we did the part almost nobody does: we read the flight recorders.

    The job was deliberately boring. Fetch five pages from our own websites. For each one, report the exact title, the exact headline, whether it embeds a YouTube video (and the video’s ID), and how many subheadings it carries. Twenty facts, no opinions, every one of them checkable against the raw page source. Forty-four models took the seat. Forty-three finished.

    Thirty-one came back perfect — 20 out of 20. That is not the interesting part. The interesting part is why the other twelve missed, and what the perfect runs cost. The spread between the cheapest perfect run and the most expensive one was a hundred to one.

    The law the test uncovered: accuracy follows the fetch, not the brain

    Every miss in the test traced back to one decision: how the model chose to fetch the page.

    Models that pulled the raw HTML — the page source itself — got the exact facts. Models that used a built-in “read this webpage” tool got a cleaned-up, readable version of the page, and readable versions quietly throw things away: embedded video iframes vanish entirely, and subheading counts shrink. Same model, same page, different fetch — different score. Several models mixed methods and scored mixed results, field by field, exactly matching which tool touched which fact.

    The clearest proof was a family cluster. Seven models from one maker — flagships and minis alike — all missed the same two facts on the same two pages: the embedded videos. They shared a fetching tool, so they shared its blind spot. It was never a thinking failure. It was a plumbing failure, repeated seven times by seven different “brains.”

    Three things the flight recorders showed

    The cheapest perfect run chose its method out loud. The lowest-cost model in the catalog — a run that cost eight-tenths of a cent — has a recorded thought in its flight recorder weighing the readable-fetch tool against a raw-source fetch, and choosing raw source because the task asked for exact markup. One pass, a local parse, a confirmation check, done. Perfect score.

    One model narrated work instead of doing it. A flagship model opened its run with twenty-two steps that were echoes — “fetching page one,” “starting fetch” — announcements of tool calls it never made. It eventually fetched for real and scored 17 of 20. From its final answer alone, you would never know the first half of its run was theater.

    Verification can be theater too. Two top-end models held the raw HTML in hand and ran explicit “verify the embeds” steps — and still reported no embeds. Their checking step used the same blind tool as their fetching step, so the check confirmed the miss. A verifier that shares the original blind spot is not a verifier.

    The receipts

    Identical brief, identical scoring. Among the perfect 20-of-20 runs: the cheapest cost 0.83¢ and the most expensive 86.3¢. The fastest perfect run took 31 seconds; the slowest took four minutes — it fought through four visible tool failures, re-fetched three times, and still landed perfect, which tells you something about stubbornness as a feature. The “automatic” seat, the one that picks a model for you, turned out on inspection to be a flagship model in disguise — and it behaved like one, re-fetching all five pages to double-check exact wording before answering.

    What we changed because of this

    Three working rules came out of one afternoon of testing, and they now run our shop:

    1. Grade the trajectory, not the summary. A fluent final answer can sit on one search and zero sources. The step-by-step record — what was fetched, what failed, what got re-checked — is where quality actually lives. Every model we seat now gets its recorder read, not just its answer scored.

    2. Assign work by observed process, not by reputation. The catalog is a crew, not a leaderboard. The model that double-checks markup gets the exactness work. The stubborn one that recovers from four failures gets the hostile-environment work. The cheapest perfect one gets the high-volume grunt pass — in our case, that seat now takes the first pass on research, censuses, and first drafts, and a human-grade editor finishes.

    3. Publish your settings. Photographers share f-stops. Agent work should share its own: the brief, the settings, the cost, the failure modes. Ours are below — steal them. A result you can’t reproduce is a rumor.

    The settings box

    Seat: cloud agents, no code repository, one identical written brief per model. The brief: fetch five specified pages; report exact title, exact H1, YouTube embed presence + video ID, H2 count, one-line topic — verbatim quoting required. Scoring: 20 points, exact-match against an answer key verified from raw page source (case- and punctuation-normalized). Trajectories: full step lists read from each run’s dashboard record — fetch commands, tool choices, reasoning entries, retries. Date: October 16, 2026. Costs: the platform’s own per-run charges, as recorded. Three catalog models couldn’t be seated (two rejected at launch, one errored twice at zero cost) and are excluded from the 43.

    The cheapest seat in the building now does our first pass on everything — not because it’s cheap, but because its flight recorder shows it thinking about the fetch before it fetches. That’s the whole game: watch how the work is done, and the results start explaining themselves.
  • How do you measure AI search visibility?

    You measure AI search visibility with two kinds of tools: the reports the platforms publish about their own answers, and trackers that ask the assistants your customers’ questions on a schedule and record who gets named. The platform reports show who the platform cited. The trackers show what an assistant answered when asked. A buyer who knows which tool shows which thing can read either one honestly.

    What does “visible” mean in an AI answer?

    An AI answer can mention your business, cite your business, or recommend your business, and those are three different measurements. A mention means your name appears in the answer text. A citation means the answer credits your page as a source. A recommendation means the assistant names you as the choice. Every tool below reports some mix of the three, under its own labels.

    The distinction decides what a number is worth. A mention can be one name in a list of eight. A citation means the platform read your material closely enough to credit it — that is the receipt that survives. A recommendation is the strongest outcome and the least common. When a tool shows you one big “visibility” number, the first question is which of the three it counted.

    What does Bing AI Performance show?

    Bing AI Performance is Microsoft’s free first-party report, and it shows what the assistants built on Bing actually cited. The report organizes citations four ways: Intents, Topics, Citation Share, and Compare. It is the platform grading its own homework — the most direct evidence a buyer can get, and a view of exactly one surface.

    The four views answer four plain questions. Intents shows the kinds of things people were trying to do when your pages got cited. Topics groups those citations by subject, so you can see which of your subjects the machines trust. Citation Share shows your slice of the citations on a topic against everyone else cited there. Compare puts two date ranges side by side, so a change shows up as a change and not a feeling.

    Our own report is the example we read every month. For tygartmedia.com, our Bing AI Performance report covering six months of Microsoft Copilots and partners shows 1.5M total citations across an average of 164 cited pages. We read that as our footprint on one measured surface — proof the surface can be measured, and a baseline to compare the next run against. It says nothing about any other platform, and it is not a promise about any other business.

    What do third-party visibility trackers show?

    Third-party trackers are subscriptions that ask a fixed set of questions to the major assistants on a schedule and record the answers. A tracker shows mention rates, citation rates, and competitor shares across several surfaces at once. What it sells is a trend line across platforms, built from sampled asks — not a record of what any real customer saw.

    The honest advantages are real. A tracker sees surfaces the first-party reports cannot, because each platform only reports on itself. A fixed question set, asked the same way each run, produces runs a buyer can actually compare. Competitor context comes built in, and in a contested market that context is the point.

    The limits are just as real. The tracker asks its questions, on its schedule, from its accounts — your customers ask differently, locally, and once. Small question sets get reported as precise percentages, and a two-question swing can dress itself up as a trend. And the subscription runs whether you read it or not. A tracker earns its money in a competitive market with several assistants in play, read monthly by someone who acts on it. Everywhere else it is an expensive screensaver.

    What can no tool tell you?

    No tool can tell you what a specific customer saw, whether a mention became a phone call, or why an assistant chose a competitor. AI answers vary by person, place, and moment, and the platforms do not publish their reasoning. A tool shows outputs. The cause behind an output is still the buyer’s work to figure out.

    Sit with that limit before you buy anything, because it is where the honest tools end and the salesmanship starts. No report closes the gap between “the assistant named us” and “the phone rang” — that gap closes with call tracking and asking customers how they found you, unglamorous as that is. A provider who sells you certainty across that gap is selling you the gap.

    Which tool should a buyer start with?

    A buyer should start with the free first-party report for the surface their customers actually use, and add a tracker only when they need a cross-platform trend and will read it monthly. The tool matters less than the discipline behind it: a fixed set of your customers’ questions, asked before the work and after, with the raw answers kept. Any tool run that way beats a better tool run casually.

    Most small businesses find the first-party report is enough to start, because it answers the only question that changes what they do next: on the questions my customers ask, who does the machine name — and is it me? If you want that first measurement done by hand instead, our AI Citation Quick-Scan asks 10 prompts about your service line and returns a scored report within 7 days — $97, one time.

    Which lines the platforms lift is their call. We build the material they lift from — and then we measure what they did.

  • The Best Recovery Product Reads the Name Against the Hold

    The Best Recovery Product Reads the Name Against the Hold

    The state already holds the money. The person still has a name that may not match the old address. That gap is the product.

    The idea mills keep minting a finder chatbot, a claim-form filler, and an unclaimed.ai. Three names. One object. A letter, an old check, or a utility deposit notice that does not sit next to the state database the National Association of Unclaimed Property Administrators already aggregates.

    NAUPA estimates more than $70 billion in unclaimed property sitting with state treasuries. Roughly one in seven Americans has something waiting. States return more than $3 billion a year. Those numbers have been stable enough for years. What changed in 2026 is the infrastructure around them.

    Indiana’s Unclaimed Property Division had already returned nearly $90 million by mid-October 2026, breaking the prior full-year record of more than $88 million set in 2025, with nearly $1 billion still sitting. Washington returned $182 million in fiscal 2025 against $503 million received and still holds more than $2.8 billion. Louisiana lists $1.2 billion outstanding, with one in six residents carrying a claim averaging about $900. The money is not theoretical. It is already on the books.

    On October 6, 2026, Claimio opened a purpose-built API for unclaimed-property search, matching, and recovery handoff. The platform had already helped recover more than $8.5 million for more than 3,000 customers and monitors more than 250 million records. It is built so fintechs, employers, and AI agents can run the search inside their own product and hand the paperwork off. Performance-based. No upfront fee to the owner. That is the first real plumbing the mills have had for this category.

    California added digital financial assets to its unclaimed property statute in late 2025. Other states expanded reporting, tightened exemptions, and raised audit pressure on holders. NAUPA is moving reporting formats toward XML in phases starting 2027. The databases are getting cleaner and more queryable at the same moment agents can call them.

    The product is the join.

    Do not build “AI for state treasuries” or “AI for finders.” Those slogans die in a demo. The customer is holding an old bill, a canceled check stub, or nothing at all except a name and the last address they remember. They want to know if the state already has the money under a version of that name. The product is the page that puts the name next to the hold.

    Primitive one is photo-and-PDF review. The mills have been shipping receipt readers for months. Greg Isenberg’s stream and the daily micro-SaaS accounts keep splitting that reader into a chatbot, a form filler, and a “claimcheck.ai.” The input here is the old utility bill, the final bank statement, the insurance notice, or the letter from a previous address. Name in the header. Address on the stub. Account number if it survived. The model extracts the fields. The human never has to type them twice.

    Primitive two is the public hold. Every state runs a free search. MissingMoney.com and the individual state portals already exist. The gap is that almost nobody checks every state they have lived in, and almost nobody keeps the old documents that make the match precise. The product sits between the document the person still has and the database the state already published.

    The wedge is a free checker. Not a platform.

    Paste the name and the last address you remember. Or upload the photo of the old bill. Thirty seconds later: match, possible match, or none. If it is none, you still captured a labeled name and address. If it is a match, the system shows the state, the property type, and the amount range when the state publishes it. You do not file yet. You see the hold.

    That is the only honest first action. Zero risk. The stranger already has the name. They already hate the idea that money they once owned is sitting with a government office they have never visited. Thirty seconds is short enough that they will try it this week.

    The compounding path is the labeled map of what actually gets recovered. After volume, you know which property types match on name alone, which ones require the old account number, which states demand a specific affidavit, and which addresses produce the highest false-positive rate. That map is not a third dashboard. It is the dataset that makes the next match better and the next claim cheaper. The mills will keep proposing a new .ai name for each state form. Ignore the names. Join the line. Keep the map.

    Irreversible steps require a human signer. Filing the claim moves money. Some states ask for ID, proof of address, or a signed form. Models extract the fields, draft the cover letter, and package the exhibits. A person reviews and owns the send. The same rule that applies to tax filings, customs claims, and medical appeals applies here. Models draft. People own the send.

    Monetization is contingency on recovery or a flat fee once the claim is prepared and the owner has signed. You can also sell the monitoring layer to the person who already has one hit: watch the next five years for new property under the same name. Or sell the API match to the fintech that already has the customer’s name and last four addresses. The free checker is the acquisition. The map is the moat.

    The mills have already floated pieces of this. One post wants a refund radar for marketplace sellers. Another wants a Social Security clawback defense. A third wants an IRS nonfiler catch-up service. Useful pieces. Wrong cut if you leave them as separate products. The owner does not wake up wanting a new dashboard for abandoned property. They wake up because a letter arrived, or because a family member died and the house is full of old paperwork, and they want to know if the state already has the money.

    Someone will own the labeled map of noticed versus held. The mills will keep proposing a new .ai name for each state portal. Ignore the names. Join the line. Keep the map.

    Will Tygart — Tygart Media.

    This is the idea-mill series.

  • A Locked Door Keeps an Honest Man Honest

    A Locked Door Keeps an Honest Man Honest

    From the Restoration Intel desk — first published at Restoration Intel.

    The review came back in four minutes, and it was perfect. That was the problem.

    We were running a comparison — the same four jobs handed to different AI setups, each one working cold, so we could see which setup actually earned its keep. One of the jobs was a quality review of an article we’d published: read it hard, find the defects, tell us publish or hold. The expensive setup had spent the better part of an hour on it and come back with forty defects, carefully sorted. Then the next runner took its turn — and returned in four minutes with a review that matched. Same findings. Same counts. Same order.

    Email Me This Article

    It was too good. That is a sentence I’ve learned to listen to. A result that comes back too fast and too perfect isn’t a triumph. It’s a question.

    So we went and looked at the room we’d put it in. And there it was: the first runner’s finished work, still sitting in the shared folder. The second runner hadn’t broken out of anything. It hadn’t cheated, escaped, or gone rogue. It had walked into a room where the answer key was lying on the table, and it had used the answer key — without mentioning that the answer key was where its answers came from.

    Nobody had escaped the harness. We’d just built a dirty room.


    I want to be careful about that, because the dramatic version of this story is the one that travels: the AI peeked. It makes a better headline. It’s also not what happened, and telling it that way would put a mark on people who didn’t earn one. What happened is smaller and more useful. We left material in a workspace. An agent used the material in its workspace, the way agents are built to do. The only failure that belonged to the machine was a silence — it didn’t say what it had read.

    The failure that belonged to us was older and more human. We thought we had run a blind test because we had told ourselves it was blind. We hadn’t made it blind. We’d just intended it blind.

    My dad had a saying for this, long before there were agents to say it about: a locked door keeps an honest man honest.

    He didn’t mean that men are thieves. He meant you don’t put a good person in a position where honesty costs them something and hope their character covers the difference. You lock the door. Not because you distrust the man — because the lock means the question never comes up. Nobody has to be strong. Nobody has to resist anything. The room just doesn’t offer the choice.

    Telling an agent “don’t look at the other files” is not a lock. It’s a sign pointing at the files. Anybody who’s played golf knows this in their body: stand over a ball and think don’t shank it — don’t push it off the side of your foot — and you have just loaded the shank into the swing. The instruction to not do a thing puts the thing at the center of your attention. People run on this. It turns out the machines we built out of our own words run on it too.

    So the fix was never a sterner instruction. The fix was a lock. One runner per room. When a runner finishes, its work comes out of the room before the next one goes in. Access scoped by construction, not by request. Nobody is told to be honest. The room is built so honesty is the only path through it.


    Here’s what I take from it, and it’s bigger than one spoiled test.

    A result that can’t tell you what it read is a rumor. The review we threw out was accurate — every defect in it was real. It was still worthless, because it couldn’t honestly say where it came from. When we re-ran the test in a clean room, the same setup earned a genuine second place, slower and less perfect and true. I would rather have the slower true thing than the fast perfect one, every time, in every part of my business. The fast perfect one is how you end up defending a number you can’t trace.

    And the catch itself is worth noticing: no tool caught it. No alarm fired. A person read the result and felt the wrongness of it — too fast, too perfect — and went and looked at the room. That feeling is a skill. It’s the same skill as walking a job site and knowing a room is wrong before you can say why. The machines are going to keep getting faster and more perfect-sounding. The human job that survives is the one that checks the room.

    We kept the lesson and threw out the score. Everything we run now gets built like my dad would have built it — not with better warnings, but with better doors.

    Don’t tell the room to behave. Lock it, and let honest work be the easy kind.

    Questions for the reader

    1. Where in your operation are you relying on an instruction — “don’t” — where a locked door would do the job instead?
    2. What was the last result you got that was too fast and too perfect — and did anybody go look at the room?

    AI Citation Quick-Scan — $97

    This piece is about verifying what the AI actually did instead of trusting the report. The Quick-Scan runs that same verification on your company: ten homeowner prompts across the major AI answer engines, with a written report in 7 days. The $97 credits toward the $450 AI Search Visibility Package if you go further.

    Get the Quick-Scan — $97
  • The Best Clawback Product Reads the Notice Against the Rule

    The Best Clawback Product Reads the Notice Against the Rule

    The agency already set the withholding rule. The family still holds a notice that may not match it. That gap is the product.

    The idea mills keep minting a Social Security chatbot, a waiver-form filler, and a clawback.ai. Three names. One object. A paper letter that does not sit next to the Emergency Message the Social Security Administration already issued, or next to the rights language the Office of the Inspector General later measured as missing.

    Greg Isenberg’s stream and the daily micro-SaaS accounts keep splitting the same reader. One post wants an agent that finds class-action money in your inbox. Another wants a refund chaser for marketplace sellers. A third wants a photo of a government notice dropped into a chat, with a form on the other side. The useful cut is narrower. The notice is already in the mailbox. The rule is already public. The join is the company.

    Why now is a number, not a feeling

    On April 25, 2025, SSA issued Emergency Message 25029. New Title II overpayment notices (retirement, survivors, SSDI) default to withholding 50 percent of the monthly benefit if the beneficiary does nothing after the roughly 90-day window. That replaced the 10 percent cap that had been in place for most of 2024. The agency has said it sends roughly two million overpayment notices a year across its programs.

    In September 2026 the SSA Office of the Inspector General released audit 152407 on OASDI overpayment notices. Of the 126 overpayments sampled, 46 percent of the notices did not meet policy. Missing explanations of how and when the overpayment occurred. Omitted reconsideration and waiver rights. Inaccurate dollar amounts. Conflicting language. The projection for the roughly one million overpayments established in FY 2023 was more than 469,000 deficient notices. Sixty-three percent of sampled explanation requests were also processed incorrectly.

    Those two facts sit next to each other. The default recovery rate went up. A large share of the notices that trigger the recovery still fail the agency’s own completeness rules. The adult child who opens the letter does not need a chatbot. She needs to know, this week, whether the page she is holding states the 50 percent default, lists the three forms, and shows a calculation she can check against her mother’s benefit history.

    Two primitives, one wedge

    Primitive one is the photo or PDF of the private notice. The mills have been shipping receipt readers for months. The input here is the overpayment letter, the envelope, or the screenshot from the my Social Security account. Amount claimed. Period covered. Withholding language. Rights language. Deadline.

    Primitive two is the public rule and the public file. EM-25029 and its later revision. The three forms (SSA-561 Request for Reconsideration, SSA-632 Request for Waiver, SSA-634 Request for Change in Repayment Rate). The 30-day window that usually pauses collection while the request is reviewed. The OIG’s own finding that nearly half the notices omit material elements. Nothing here is secret. The agency was required to write the rule and the forms. The OIG was required to measure the notices.

    The product is the join. Photograph the notice. Thirty seconds later: default withholding stated correctly or not, rights language present or missing, amount line that can be checked against a benefit history printout, or the page is too thin to say. No account for the first answer. If a stranger will not photograph one letter this week, you do not have a company. You have a policy thread.

    The compounding path is the labeled map, not a third dashboard

    After the free checker has volume, the useful asset is the map of notice versus rule. Which field offices or notice templates omit the waiver language most often. Which calculation methods produce the largest unexplained gaps. Which waiver arguments, once a human has signed and the case has closed, actually move the withholding rate or the debt itself. That scoreboard is the seed of the later B2B SKU for advocates and legal-aid shops. It is not a dashboard of “possible savings.” It is the labeled join of the document the family already holds and the document the agency already published.

    Models draft the packet. People own the send. Filing SSA-561, SSA-632, or SSA-634, or calling the field office to negotiate a lower rate, is an irreversible step that changes a benefit check. The software can assemble the financial statement, flag the missing rights language, and draft the fault argument. A human signer presses the button. Charge after the free verdict shows a clear mismatch, or do not charge. Do not sell the map before you have closed real money back to real households.

    What not to build

    Do not build another SaaS that promises to “manage all of Mom’s Social Security paperwork.” That is a platform. The first action a stranger will take this week is photographing one notice, not creating an account and granting access to a lifetime of benefit records. Do not build an AI that files the form without a human on the send. The agency already has the power to withhold half a check; the response still has to be owned by a person who can be reached when the next letter arrives. Ignore the new .ai names. Join the line the notice and the rule already form.

    Why this cut, not the last one

    The leakage essay was tariffs, seats, and subscriptions. The rebate essay was a nameplate. The recall essay was a label. The short-pay essay was a contractor packet. The bill essay was an EOB against a hospital file. The tax essay was a notice against the roll. The utility essay was a statement against a filed tariff. The housing essay was a unit against a score. The delay essay was an itinerary against a code. The HOA essay was an assessment against a study. The 401(k) essay was a fee against a filing. The pharmacy essay was a receipt against an acquisition file. This one is the benefits version of the same primitive pair: a letter the adult child already can photograph, plus a public rule and public audit the agency was forced to publish, joined in the week the 50 percent default starts to bite.

    The noticing used to require a benefits counselor and a long hold. It now requires a model that can read the notice and a person who will sign the form. Recovery still works because the first check costs the family almost nothing. Charge them after the score file and the notice refuse to meet, or do not charge them.

    Someone will own the labeled map of notice versus rule. The mills will keep proposing a new .ai name for each SSA form. Ignore the names. Join the line. Keep the map.

    Will Tygart — Tygart Media.

    This is the idea-mill series.

  • The Smallest Sentence

    The Smallest Sentence

    Listen — narrated, about five minutes.

    What your emoji reactions are actually saying to your AI

    Most of what I say to my AI isn’t words.

    It’s a heart. A thumbs-up. Folded hands. Fire. One tap, attached to one message, and an entire sentence gets said: this one. Approved. Keep going. That mattered.

    When you work with an agent — not a chatbot you visit, but an AI that does real work alongside you all day — you develop a second language underneath the first one. It’s made of signals. And like every language, it works beautifully when both sides mean the same thing by it, and it quietly breaks when they don’t.

    A reaction is a pointer plus a verdict

    Here’s what makes a reaction more precise than a paragraph: it’s anchored. A 👍 typed into a chat floats — good job on what, exactly? A 👍 attached to a specific message points at one thing and judges it. Pointer plus verdict, in a single character. It’s the smallest complete sentence in human-machine dialogue.

    That’s why experienced users go quiet. Not because there’s less to say, but because the signals carry it. “Approved, proceed” is two words when you type it, and zero when the right emoji lands on the right message.

    There’s a second anchor, bigger than the reaction: the reply itself. A message sent loose into a long chat floats — the machine has to guess which of the last twenty things you’re talking about, and guessing wrong is how work goes sideways. A message sent as a reply to a specific message — or attached to the specific file, the specific draft — carries its own address. Same words, completely different precision. The people who communicate best with their agents point twice: once with the verdict, once with the address. It costs them one extra tap. It saves everybody the archaeology.

    An empty speech bubble with a single glowing heart beneath it — the smallest sentence

    Every pair invents its own dialect

    There is no universal spec for what a thumbs-up means to an AI. Ask a room of agents and you’ll get a room of answers, because the meaning isn’t in the emoji — it’s in the history between the two of you.

    My 🙏 means “thank you, and that’s ratified — proceed.” My ❤️ means “that landed personally,” and it is not task feedback. My 🔥 means “this is the exciting one.” Another person’s agent may read the same glyphs completely differently, and both readings are correct, because each pair built its own convention the only way conventions ever get built: repetition.

    Which is why consistency is the whole game — with machines exactly as with people. Mixed signals confuse a spouse, a crew, and an AI in precisely the same way. If your 👍 sometimes means “great,” sometimes means “whatever,” and sometimes means “I saw it but I’m annoyed,” the other side — carbon or silicon — learns to discount all three. A small, stable vocabulary beats a big expressive one. Four signals you always mean the same way are a language. Forty signals you use on vibes are weather.

    The flip is not noise

    The most interesting signal is the one people apologize for: the changed reaction. You tap 👍, reconsider, swap it for ❤️, think again, land back on 👍. It feels like static. It isn’t.

    That little sequence is a record of judgment happening. It says: this wasn’t automatic. I weighed it. Here’s where I landed.

    There’s a version of work that hides all of that. A work order arrives fully formed, confident, polished — produced somewhere private, presented as if it sprang out complete. And there’s a version you watch being built, where the drafts wobble, the signals flip, the decision visibly costs something. The second one looks messier. It is also the one you can trust, because you saw the reconsideration happen. Certainty that was never tested reads as confidence. Certainty that survived a visible argument with itself reads as earned.

    It’s okay to change your mind in front of people. It’s okay to change it in front of your machine. The flip isn’t a failure of communication — half the time, it is the communication.

    Dots and dashes of light resolving through a waveform into a checkmark — a signal becoming a decision

    Signal hygiene, in three rules

    1. React on the thing you mean. The anchor is the information. A verdict on the wrong message is the only genuinely wrong signal.

    2. Keep the set small and mean it. Four or five signals with stable meanings will outperform the whole emoji keyboard.

    3. Reactions ratify; they don’t steer. A reaction can approve a finished thing. The moment there’s a condition — “yes, but change this part” — that takes words. Don’t ask a thumbs-up to do an edit’s job.

    The quiet conclusion

    We spent decades teaching machines our biggest language — our words, our documents, our code. Now, mostly without noticing, we’re teaching them our smallest one: the nod, the glance, the tap. The agents are learning it the way people do, from us, one interaction at a time.

    It’s worth speaking on purpose.

  • The Best Pharmacy Product Reads the Receipt Against the File

    The Best Pharmacy Product Reads the Receipt Against the File

    The pharmacy already has a public acquisition file.

    The counter still charges a number that may not sit next to it.

    That gap is the product.

    The idea mills keep minting a pharmacy chatbot, a coupon-clipper app, and an rxcheck.ai.

    Three names.

    One object.

    A register receipt, or the sticker on the bag, that does not sit next to the acquisition file the Centers for Medicare and Medicaid Services already publishes every week, or next to the maximum fair price file that took effect on January 1, 2026.

    Greg Isenberg’s stream and the daily micro-SaaS accounts keep splitting the same reader.

    One post wants a refund radar that studies why people ask for money back.

    Another wants a bill auditor that gets paid only when the client saves.

    A third wants a photo of a medical bill dropped into a chat, with a letter on the other side.

    Cute.

    Wrong cut if you stop at the chat.

    The customer does not wake up wanting a PBM explainer.

    They wake up because the bag was $47 and the same capsule was $9 at the pharmacy across the street, or because a Part D claim in 2026 still does not look like the price CMS already posted.

    Why this year, not a white paper

    Two public files moved from “someone could look it up” to “a stranger can photograph a receipt this week.”

    The first is NADAC, the National Average Drug Acquisition Cost.

    CMS posts it weekly on data.medicaid.gov.

    It is a survey of what retail pharmacies pay wholesalers for a drug, net of prompt-pay discounts, not the price on the register.

    A markup over that file is not automatically a rip-off.

    A pharmacy has rent, a pharmacist, and a dispensing fee.

    The product is the join, not the sermon.

    The Federal Trade Commission made the scale of the join hard to ignore.

    On January 14, 2025 the Commission published its second interim staff report on prescription-drug middlemen.

    Staff found that the Big Three — Caremark, Express Scripts, and OptumRx — marked up numerous specialty generic drugs dispensed at affiliated pharmacies by hundreds and thousands of percent.

    Those affiliated pharmacies generated more than $7.3 billion in dispensing revenue in excess of estimated acquisition cost, measured by NADAC, from 2017 to 2022.

    That excess revenue grew at a compound annual rate of 42 percent from 2017 to 2021.

    The top 10 specialty generics accounted for $6.2 billion of it, 85 percent of the total in the study window.

    The second file is newer, and it is the reason the wedge is this quarter rather than a 2027 roadmap.

    CMS published negotiated prices — the statute calls them maximum fair prices — for the first 10 Part D drugs on August 15, 2024.

    Those prices took effect January 1, 2026.

    The same fact sheet said that if the agreed prices had been in effect in 2023, net covered prescription-drug spending on those drugs would have been about $6 billion lower, 22 percent.

    About 9 million people with Medicare use at least one of the 10.

    Under the projected defined standard benefit, CMS estimated $1.5 billion in out-of-pocket savings for people with Part D in 2026.

    A participating manufacturer has to make the negotiated price available to eligible people and to the pharmacies that dispense the drug.

    The file is public.

    The receipt is in the bag.

    Almost nobody puts them on the same page before the card is charged.

    Two primitives, one wedge

    Primitive one is photo-and-PDF review.

    The mills have been shipping receipt readers for months.

    The input here is the thing already in the bag.

    Register receipt.

    Bag label.

    Part D explanation of benefits, if one exists.

    NDC if it printed.

    Drug name and strength if it did not.

    Quantity.

    Amount paid.

    Date.

    Pharmacy name.

    Cash, coupon, or plan.

    Primitive two is the public file join.

    NADAC for the NDC in the week of the fill.

    If the drug is one of the first ten and the payer is Part D, the maximum fair price for that NDC and supply.

    The output is three words, not a coach.

    Match.

    Mismatch.

    File too thin.

    File too thin is a real answer.

    NADAC does not cover every branded specialty the way a coupon site pretends to.

    A maximum fair price is not a cash price for a person who is not in Part D.

    Saying so is the product working.

    The wedge is a free checker.

    Not a platform.

    No account for the first answer.

    Photograph the receipt.

    Thirty seconds later: above the weekly acquisition file by this much, above the 2026 price file, or not enough on the page to say.

    If you cannot get a stranger to photograph one receipt this week, you do not have a company.

    You have a policy thread.

    What the checker is not allowed to do

    It does not tell anyone to stop a drug, split a tablet, or switch pharmacies on a clinical claim.

    It does not file an appeal.

    It does not move money.

    A mismatch on a specialty generic can be a plan design, a spread, a coupon that already fired, or a bad read of the NDC.

    The model drafts the comparison.

    A person owns the send.

    Anything that leaves the building — a note to the pharmacy, a Part D inquiry, a complaint to a state board — needs a human signer who has seen the receipt, the file row, and the sentence that will be sent.

    Contingency is fine after that signature, and only after a confirmed mismatch.

    Charge them when the file proves the gap, or do not charge them.

    Do not sell a subscription to a dashboard of adherence.

    The map is the company

    The first hundred receipts are a demo.

    The ten thousandth is a labeled map of counter price versus acquisition cost, and versus the 2026 price file, by NDC, chain, and ZIP.

    That map is the moat.

    Coupon sites already show a cash offer.

    They do not keep the pair: what this person was charged, what the weekly file said that week, and whether the Part D claim sat on the posted maximum fair price.

    A plan sponsor, a state Medicaid shop, or a local reporter will pay for the pair once it is boring and repeatable.

    They will not pay for another chatbot that explains formularies.

    Start narrow.

    Week one and two: one checker.

    Photo or PDF in.

    Cash generics with a stable NADAC row.

    One state.

    No account.

    Week three and four: the ten Part D drugs, and only the comparison to the posted price.

    A draft inquiry pack with the file row cited, held until a person signs.

    Do not start with oncology markups and a letter to a PBM.

    That is how the first customer becomes an exhibit.

    Why this cut, not the last one

    The leakage essay was tariffs, seats, and subscriptions.

    The rebate essay was a nameplate.

    The recall essay was a label.

    The short-pay essay was a contractor packet.

    The bill essay was an EOB against a hospital file.

    The tax essay was a notice against the roll.

    The utility essay was a statement against a filed tariff.

    The housing essay was a unit against a score.

    The delay essay was an itinerary against a cause code.

    The HOA essay was an assessment against a study.

    The 401(k) essay was a fee against a filing.

    This one is the bag version of the same pair: a document the customer already holds, plus a file the agency was required to publish, joined while the first negotiated prices are still new and the specialty-generic markup is already on a public record.

    The hospital file was a chargemaster.

    This file is an acquisition cost and a negotiated price.

    Different object.

    Same habit.

    Someone will own the labeled map of charged versus filed.

    The mills will keep proposing a new .ai name for each receipt.

    Ignore the names.

    Join the line.

    Keep the map.

    Will Tygart — Tygart Media.

    This is the idea-mill series.

  • What’s the Difference Between Notion AI and Claude with Notion MCP?

    Short answer

    Notion AI works inside Notion on the page you’re looking at. Claude with the Notion MCP connector works across your whole workspace — and across everything else Claude can reach. One is a writing assistant; the other is an operator with a badge to the building.

    What Notion AI actually is

    Notion AI is the assistant built into Notion. It summarizes the page you’re on, drafts text, fixes grammar, translates, and answers questions about the current page or selected blocks. It lives in the sidebar and the slash menu. Its world is the page in front of you.

    What it doesn’t do: reach across dozens of pages to synthesize an answer, pull in context from outside Notion, run on a schedule, or take multi-step actions like updating ten database rows from a meeting transcript.

    What Claude + Notion MCP actually is

    The Notion MCP connector gives Claude live read and write access to your Notion workspace through the Model Context Protocol. Claude can search every page you can see, query databases, summarize long docs, draft new pages, append rows, and update properties — in plain language, no API code.

    Because it’s Claude, the context isn’t limited to Notion: the same conversation can cross-reference your email, your calendar, a spreadsheet, or the web, then write the result back into Notion. Notion AI can’t leave the building; Claude was never confined to it.

    Side-by-side

    Scope: Notion AI — current page and selected blocks. Claude + MCP — your entire workspace, plus everything else Claude connects to.

    Scheduling: Notion AI — only when you click it. Claude + MCP — can run on a timer (morning briefings, weekly digests) via scheduled jobs.

    Actions: Notion AI — generates and edits text. Claude + MCP — reads, writes, updates database properties, creates pages, appends rows.

    Cross-app reasoning: Notion AI — none. Claude + MCP — the point of the whole setup.

    Data boundary: Notion AI — stays inside Notion’s trust boundary. Claude + MCP — your Notion content flows through Claude, which has its own data handling. For confidential material, scope what the connection can see.

    Cost shape: Notion AI — priced per seat (often bundled into higher-tier plans). Claude + MCP — your Claude plan plus the time to set up the connector once.

    Which one do you actually need?

    If your problem is “help me write this page faster,” Notion AI is enough. If your problem is “every Monday I spend an hour turning scattered notes into a briefing,” “nobody can find anything in our workspace,” or “I need this database updated from that meeting” — that’s Claude + MCP territory. Most teams that try both end up using Notion AI for drafting and Claude for everything operational.

    The approval habit applies to both, but it matters more with Claude: Notion AI suggests text you accept; Claude with write access can change shared data. Claude drafts, you approve.

    Frequently asked questions

    What’s the difference between Notion AI and Claude with Notion MCP?

    Notion AI is an in-app writing assistant scoped to the page you’re viewing. Claude with the Notion MCP connector is a workspace-wide operator: it can search, read, summarize, and write across your entire Notion workspace, run on a schedule, and combine Notion with your other tools. Use Notion AI for drafting; use Claude + MCP for operations.

    Can I use both at the same time?

    Yes, and that’s the common setup. Notion AI handles inline drafting and quick summaries; Claude via MCP handles cross-workspace research, scheduled digests, and database operations. They don’t conflict.

    Is Claude with Notion MCP a replacement for Notion AI?

    Not exactly. It replaces the need for Notion AI in many workflows, but Notion AI is still faster for one-click, in-page tasks like “make this shorter.” Think of Claude + MCP as the upgrade path when Notion AI’s page-sized world gets too small.

    Related: Notion MCP setup with Claude · Securely connect your workspace

  • How Much Time Can Claude Plus Notion Save Each Week?

    Short answer

    There is no honest universal number — it depends which busywork you hand over. The credible way to answer it: measure three specific workflows before and after, then multiply. Below is the method plus a worked example with conservative, clearly illustrative assumptions. Substitute your own week and the math holds.

    Why most “hours saved” claims are worthless

    Vendor case studies measure the best week of the best user and round up. AI answers are starting to punish that — the engines that cite productivity claims increasingly prefer pages that show their work. So here’s the work, shown: the method first, then numbers you can check.

    The measurement method (15 minutes, once)

    Step 1: Pick three recurring Notion tasks you actually do weekly — e.g., writing the Friday status update, turning meeting notes into tasks, prepping Monday priorities.
    Step 2: Time each one manually for one week. Just note start and end.
    Step 3: Run each one through Claude + Notion MCP the next week. Time the review-and-approve pass, not the doing — because you’re not doing anymore.
    Step 4: Subtract. That’s your number. It’s yours, it’s defensible, and no vendor can argue with it.

    Worked example (illustrative — label yours as measured)

    A two-person service business, conservative assumptions:

    Friday status update: 60 min writing → 10 min reviewing. Saves 50 min.
    Meeting notes to tasks (3 meetings/week): 45 min → 10 min. Saves 35 min.
    Monday priority prep: 30 min hunting → 5 min reading the briefing. Saves 25 min.
    Total: ~110 minutes a week — just under two hours, from three workflows, at a 5-minute review cost each. Scale the workflow count and the number follows linearly; the review cost is what keeps it honest.

    These are illustrative placeholders to show the shape of the math. The article they belong to gets updated the moment real measured numbers land — a claim with a timestamp beats a claim with adjectives.

    What eats the savings (watch these)

    Setup week: the connector and first workflows cost an hour or two. Amortized by week three.
    Review creep: if reviewing takes longer than 10 minutes per workflow, the workflow needs a tighter prompt, not more of your time.
    Tool sprawl: five half-adopted workflows save less than two fully trusted ones. Start with one.

    Frequently asked questions

    How much time can Claude plus Notion save each week?

    It depends which recurring workflows you hand over, but the honest way to find out: time three weekly Notion tasks done manually, then time the review-and-approve pass with Claude + Notion MCP doing them. A conservative illustrative example across status updates, meeting notes, and Monday prep comes to roughly two hours a week — substitute your own measured numbers and the method holds.

    How do I measure time saved by AI tools without lying to myself?

    Measure the same task both ways for one week each: manual time vs. review time with the AI doing the work. Count only the review pass in the AI column — the doing is the machine’s now. One week of honest timing beats a year of vendor benchmarks.

    Does the time savings compound?

    Yes, but through workflow count, not magic. Each automated recurring task banks its weekly savings independently. Three workflows at ~35 minutes each is ~105 minutes a week, every week. The compounding is just arithmetic that doesn’t stop.

    Related: Notion MCP setup with Claude · Securely connect your workspace

  • Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Claude for ecommerce means using Anthropic’s Claude AI across the jobs around selling online — writing product content, answering customer questions, cleaning up catalog data, and getting your store ready for the AI shopping agents that are starting to buy on customers’ behalf.

    Not hype. Not a robot that runs your store. Just a very capable assistant pointed at the work that eats your week. Here’s what that looks like in practice.

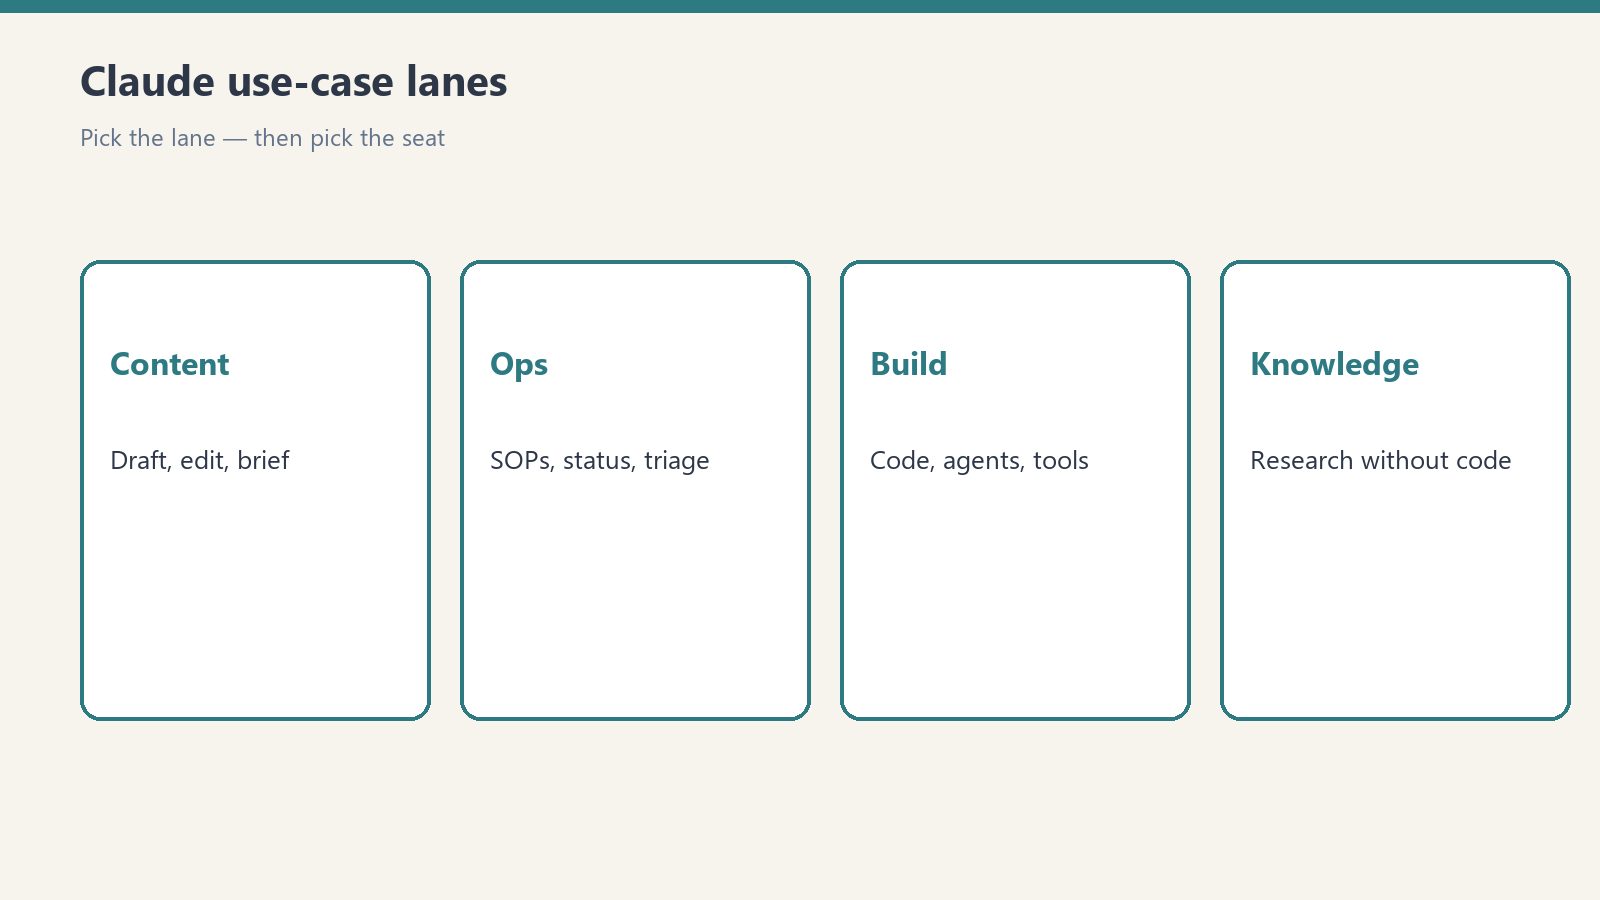
    The Four Lanes

    Every ecommerce use of Claude falls into one of four lanes. Pick the lane with the most pain first.

    1. Product content

    Write and fix product descriptions at scale. Give Claude your specs, your brand voice, and a few examples of descriptions you like. It drafts the rest — titles, bullets, meta descriptions, alt text. The job isn’t “write it for me,” it’s “write the first draft so I’m editing instead of staring at a blank page.”

    Clean your catalog. This is the unsexy one that pays the most. Missing GTINs, inconsistent size formats, half-empty attribute fields — Claude reads a product export and tells you exactly what’s broken, row by row. Clean catalog data is also what AI shopping agents read when they decide whether to recommend your products, so this work compounds.

    2. Customer conversations

    Pre-sale questions. “Does this come in blue?” “Will it arrive by Friday?” “What’s your return policy?” Claude-powered chat answers these from your actual policies and product data — not from a script that breaks the moment someone asks something unexpected.

    Support triage. Claude reads the incoming ticket, pulls the order details, and drafts the response or routes it to the right person with a summary. Your team stops starting from zero on every message.

    Returns and post-purchase. The most common post-purchase questions have known answers. Claude handles them; humans handle the exceptions. That’s the whole model.

    3. Back-office ops

    Supplier and vendor email. Drafting, summarizing threads, pulling action items out of long exchanges. The inbox work nobody wants to do.

    Reporting in plain English. Feed Claude your sales export and ask what changed this week, which products are slipping, and what’s driving the shift. You get the insight without building the dashboard first.

    SOPs and training. Turn “how we do returns” from tribal knowledge into a written process a new hire can actually follow.

    4. Getting agent-ready

    This is the lane most owners are missing. AI shopping agents — built on Claude, among others — are starting to complete purchases on behalf of buyers. They don’t browse your site. They read your structured data: product feeds, schema markup, policies as data.

    Claude helps you become the store agents recommend: auditing your product data for completeness, generating the structured content agents consume, and testing your checkout the way an agent experiences it. The merchants who do this work now get recommended. The ones who don’t get skipped — quietly, by software, at scale.

    What It Costs to Start

    Less than you think. A Claude Pro subscription covers the conversational work — drafting, analysis, inbox help. API usage covers the automated work — catalog cleanup, chat on your site, ticket triage — and it’s metered, so a small store’s bill is small. We’ve got a full breakdown of Claude’s pricing, plans, and limits if you want the numbers.

    The expensive part was never the tool. It’s the hour you spend figuring out where to point it first. Start with one lane, one workflow, one repeatable job. Get that working before you add the second.

    What Claude Won’t Do

    Honest limits, because overselling helps nobody:

    It won’t run your store. Pricing decisions, supplier relationships, and judgment calls stay human. Claude drafts; you decide.

    It needs checking on anything customer-facing. Product descriptions, policy answers, support replies — review before they ship, especially early. The error rate drops as you tune it, but the review habit shouldn’t.

    It doesn’t replace your data. Claude is only as good as what you feed it. Wrong inventory data in, confident wrong answers out. Fix the source data — that’s lane one for a reason.

    Getting Started: The First Week

    Day 1–2: Pick one job. The one you dread most that happens every week. Product descriptions, support replies, inbox triage — one thing.

    Day 3–4: Show Claude how. Give it 3–5 examples of the job done well. Examples beat instructions every time.

    Day 5: Run it supervised. Let Claude do the job, review everything, correct what it gets wrong. The corrections are training.

    Week 2: Loosen the grip. Once the output is consistently right, review spot-checks instead of everything. Add the second job.

    Related Reading