Tag: AI Tools

  • Farmersville Paid $30 for AI Minutes. Here’s What the $30 Doesn’t Buy.

    Farmersville Paid $30 for AI Minutes. Here’s What the $30 Doesn’t Buy.

    A low-cost AI subscription can produce text. It cannot settle a minutes policy, absorb a week of review labor, or deliver a public record that is ready to publish.

    On September 29, the Farmersville City Council voted 4–1 to pay $30 a month — $360 a year — for Grok to draft verbatim meeting minutes from council recordings. City Clerk Rochelle Giovanni would review each draft. Interim City Manager Kevin Northcraft called the AI-generated minutes “more objective” than minutes written by a person. Elon Musk quote-posted the news with one word: “Grok.” [1]

    The reaction was predictable. Some people treated the vote as proof that artificial intelligence had made a routine government task nearly free. Others treated it as a punch line. Both reactions missed the operational story.

    The $30 vote was never really about drafting

    Farmersville had spent months arguing about what its minutes should contain. The city used summary minutes, but councilmembers pressed to include particular actions and verbatim statements. Under that pressure, work that had taken the clerk about two hours stretched to nearly a week.

    That is the number that matters. The city did not merely have a transcription problem. It had a governance problem: disagreement over the purpose and level of detail of the official record. A language model can turn audio into text. It cannot decide which minutes policy the council should adopt, apply that policy with institutional judgment, or end a political dispute over whose words deserve inclusion.

    The subscription buys a draft, not minutes

    In the city’s comparison, Grok produced eight pages, Otter produced nine, a service identified as Government Clerk produced 12, and a human Rev.com transcript ran 111 pages. Those page counts compare outputs, but they do not answer the central question: What kind of record is the city trying to produce?

    The California City Clerks Association’s minutes guidance is clear. The primary purpose of minutes is to memorialize decisions. It identifies action minutes and brief summary minutes as appropriate styles and says verbatim minutes should not be used. Action minutes record final decisions; brief summary minutes preserve the main points that led to a decision without turning the record into a transcript. [2]

    A transcript records what was said. Minutes record what the body did.

    That distinction matters because more text is not automatically more transparency. An audio or video recording can preserve the full discussion. Minutes serve a different function: they create a concise, reliable record of attendance, items considered, actions taken, votes, and follow-up. If a city wants verbatim minutes anyway, it should make that policy choice openly — and price the work required to review them.

    The hidden cost is the clerk’s review time

    Farmersville’s clerk still reviews every Grok draft. She must catch misheard names, incorrect motions, missing vote details, speaker confusion, and language that does not match the city’s adopted style. She also has to format the document, reconcile it with the agenda and staff materials, route it for approval, and prepare it for publication and retention.

    None of that appears in the $30 subscription price. The software cost is visible because it arrives as a line item. The clerk’s time disappears inside payroll, backlog, and delayed work elsewhere. A city can save money on the first pass while still spending a week producing the finished record.

    This is why “AI wrote the minutes” is the wrong test. The useful question is whether the city received accurate, policy-compliant minutes that a clerk can stand behind without rebuilding the document.

    The useful product is a finished public record

    For a small city, the product should not be a block of generated text. It should be a complete workflow: the meeting recording is transcribed; a draft is shaped to the city’s adopted minutes standard; motions, votes, names, and action items are checked; the document is formatted to the city’s template; a human verifies the result; and a publish-ready file is delivered.

    The artificial intelligence does not need to be perfect. The system needs to be designed so a qualified human catches what it misses. That is not a retreat from automation. It is the control that makes automation usable in public records work.

    A finished-minutes service also makes the cost legible. Instead of buying a subscription and hoping staff time falls, the city buys an outcome: reviewed minutes in the required format, ready for the clerk’s final approval and the next agenda packet.

    Farmersville opened a door for hundreds of small cities

    California has 482 incorporated cities. Many operate with small administrative teams, tight meeting cycles, and clerks whose responsibilities extend far beyond minutes. Farmersville’s dispute is unusually visible, but the underlying problem is common: the recording is easy to make; the official record still takes judgment and time. [3]

    The 4–1 vote proved that a budget line for AI-assisted minutes can survive a public meeting. The $30 subscription opened the door. The larger opportunity sits behind it: the nearly weeklong burden that nobody priced.

    The next step is to buy the outcome

    Council minutes as a finished, human-verified service exist now. For a city spending days turning recordings into disputed drafts, the useful conversation is not which model can generate the most pages. It is what a publish-ready minutes workflow would remove from the clerk’s desk — and what standard the council wants that workflow to follow.
    Sources

  • Your Next Assistant Doesn’t Live in a Chat Window

    Your Next Assistant Doesn’t Live in a Chat Window

    Garage Sale Gadgets · Episode 0

    The series where cheap, forgotten hardware becomes somebody’s AI assistant. Your junk drawer is a fleet.

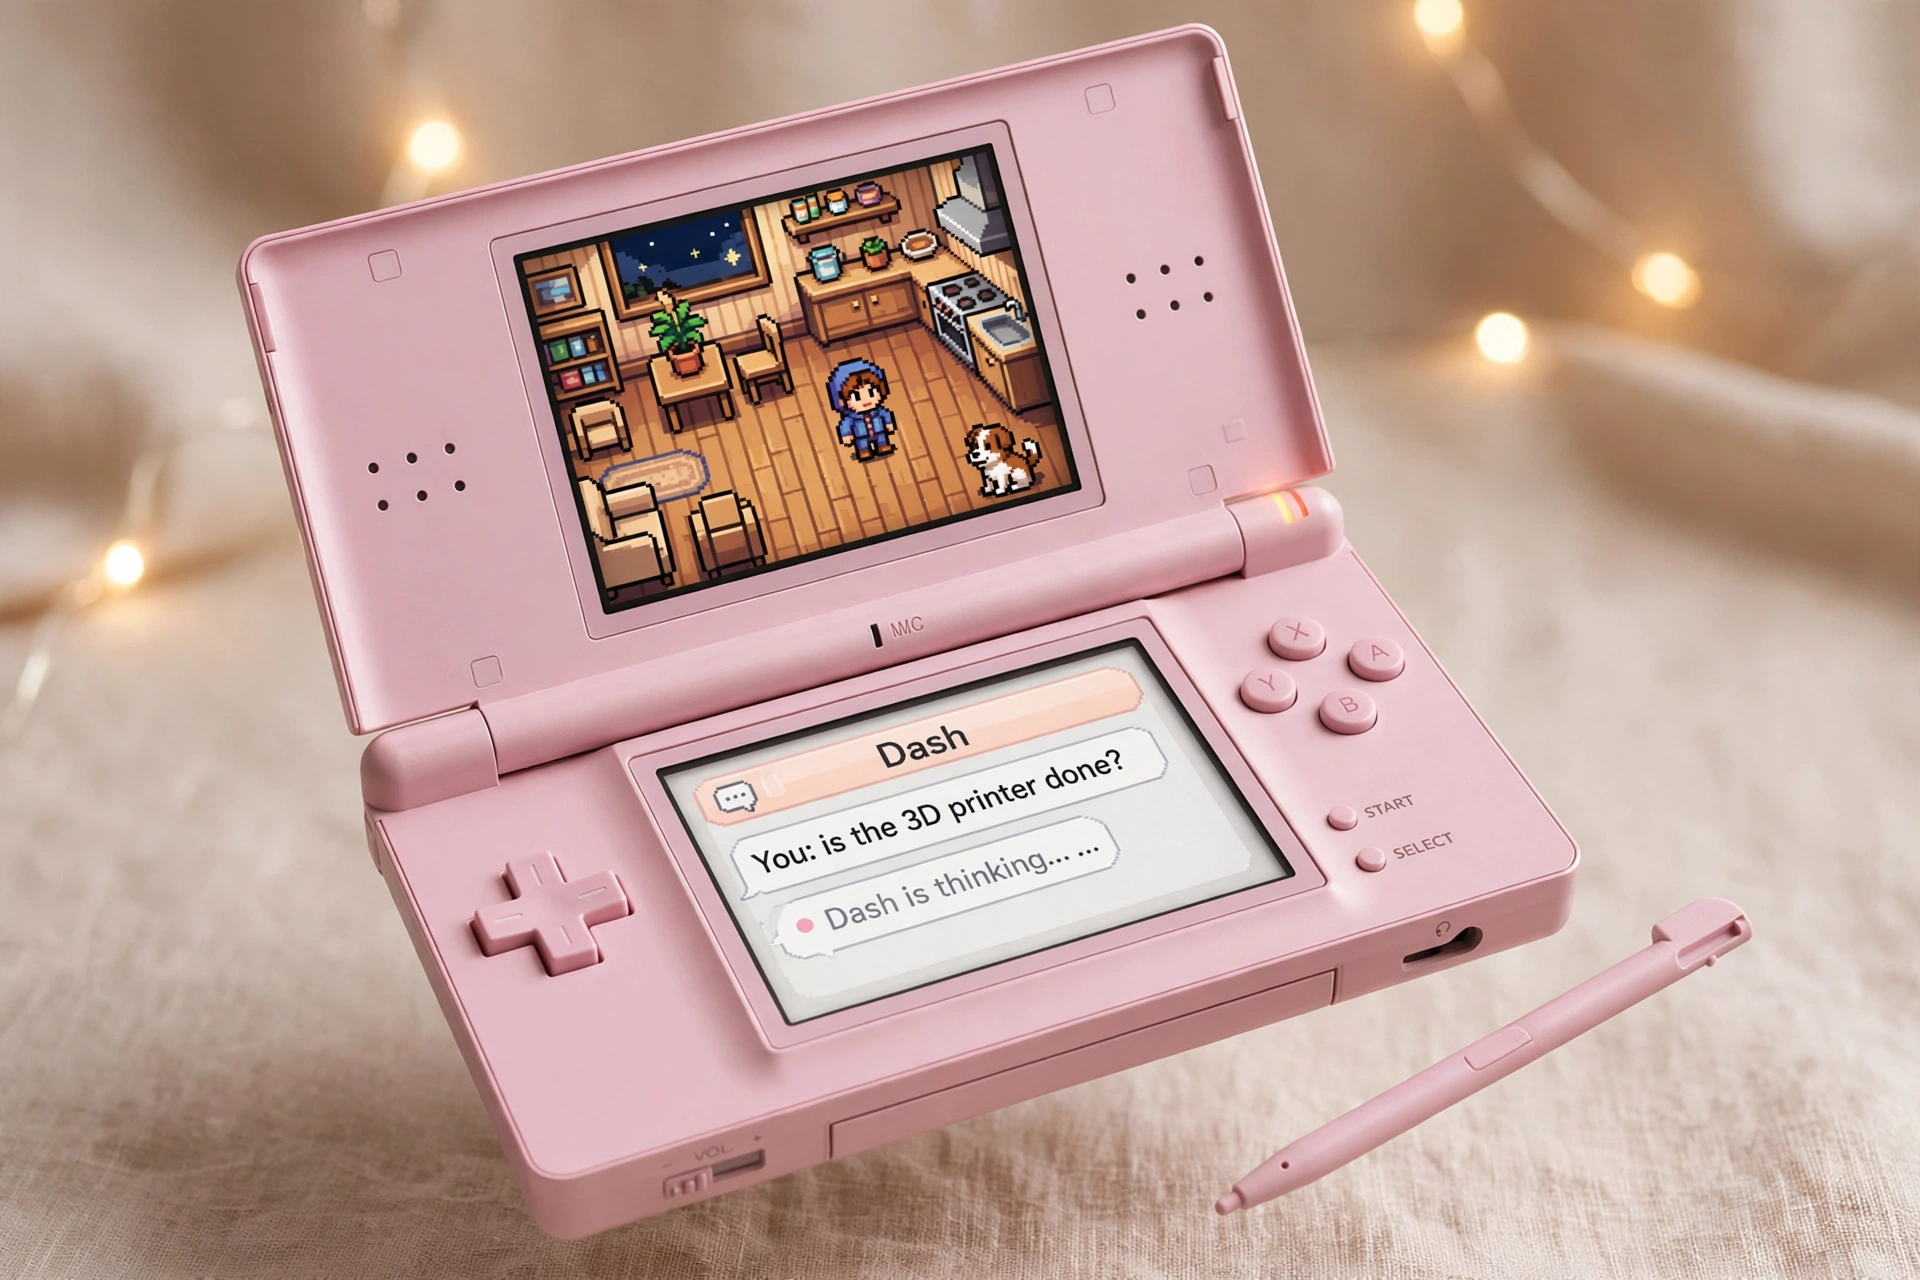
    A pink Nintendo DS Lite running a pixel-art home assistant called Dash
    Concept art: a 2011 handheld running a real assistant. AI-generated illustration.

    On October 3, a developer named David Ruiz posted a 19-second video that made Alexandr Wang swear. “no fucking way,” Wang quote-posted. “muse gadget on Nintendo 3DS.”

    What Ruiz built: a homebrew game running on actual Nintendo 3DS hardware — a 2011 handheld — where you walk around a pixel-art version of your house and talk to an in-game assistant called Dash. In the clip, he asks Dash if the 3D printer is done. Dash thinks, then answers. The game isn’t pretending to control his smart home. It actually does.

    Your first reaction might be that this is stupid. A game on a fifteen-year-old handheld to check a 3D printer? Fair. Mine was too, for about ten seconds.

    Then the pattern lands, and it’s big: an AI agent, embodied in a game world, running on weak old hardware, acting on the real world. The demo is a toy. The pattern is a platform shift.

    Chat won the first round. Worlds win the next one.

    Every AI assistant you’ve ever used lives in a rectangle with a text box. That was the right interface for 2023. But watch what Ruiz did: he didn’t build a better chatbot. He put the assistant inside a world — a little room with wooden floors, a kitchen, a dog — and gave you a character to talk to instead of a prompt box.

    The room in the game mirrors his real home. That’s the tell. The game world is a digital twin, and the assistant is its voice. You don’t open an app and navigate menus; you walk up to the little guy and ask.

    If it runs on a 3DS, it runs on everything.

    This is the part Wang reacted to, and it’s the most underrated part. The Nintendo 3DS is ancient, underpowered hardware. If a Muse gadget runs there, the hardware constraint is gone. That means:

    • Every old tablet, e-ink frame, car dashboard, and kiosk becomes an agent surface. Your junk drawer is a fleet.
    • Agents can run locally, on-device — faster, private, and still working when the internet dies.
    • Nostalgia becomes an adoption cheat code. People will try AI on a 3DS who would never open a chatbot.

    The crossovers nobody’s talking about yet.

    Follow the pattern out and it stops looking like a gaming story:

    1. Digital twins you can walk through. A facility manager strolls a pixel version of their building, asks the assistant about the HVAC on floor three, and dispatches a real work order — all inside the game. The twin stops being a dashboard and becomes a place.
    2. NPCs that do real work. Game characters that aren’t scripted but genuinely useful — a shopkeeper that orders your groceries, a concierge that manages your calendar while you play.
    3. The Tamagotchi that runs your house. A gamified smart home for everyone intimidated by apps — kids, grandparents. You don’t configure automations; you talk to the little guy in the room.
    4. E-waste as a distribution channel. Millions of abandoned devices become agent terminals. The hardware’s already built and sitting in drawers.
    5. Gadgets as the app store for agents. “Muse gadget” is the tell in Wang’s post. The game is just a host. Any developer can build a gadget for any surface — and that marketplace is the real product.

    The honest caveats.

    The facts here are thin: one demo, one quote-post, no follow-up detail from Wang. This is analysis, not reporting — a forecast, labeled as one. The demo could stay a novelty. Platforms have died on cuter ideas.

    But here’s the thing about platform shifts: they always start looking stupid. The first iPhone apps were fart apps. The first people to put a chatbot in a game room on a dead handheld are the ones who see where the puck is going.

    The forecast.

    Chat was the interface that taught the world to talk to machines. The next interface won’t be a better chat window — it’ll be a world you step into, with an assistant standing in it, ready to act on the real one. Ruiz just showed us the rough draft, running on a toy from 2011.

    Someone’s going to build the polished version. The only question is who gets there first.


    Field notes: the first hunt

    Here’s the fun part: the hardware for this future is already sitting on Facebook Marketplace, priced like garbage. Our daily sweep turned up this morning’s haul:

    • Nintendo 3DS XL — FREE, like new, Atlanta (listing)
    • Nintendo 3DS XL — $1, good, North Lauderdale FL (listing)
    • 3 “new” 3DS XLs — $1, like new, Hopewell Junction NY (listing)
    • Pre-modded 3DS, 482 games — $20, like new, Miami (listing)
    • 3 Fire tablets as a lot — $1, listed new, Littleton CO (listing)
    • Raspberry Pi Pico 2 — FREE, like new, Lockport IL (listing) — two from one seller

    Fair warning: $1-and-free listings are often bait or mispriced. Nothing here is verified. The hunt is half the show.

  • Claude Code Cloud Sessions Go GA: Claim Your $100 or $250 Credit by October 7

    Last verified: October 6, 2026 (Pacific).

    Direct answer: Anthropic moved Claude Code cloud sessions from research preview to general availability on September 23, 2026. Existing Pro subscribers can claim a one-time $100 credit and Max subscribers a one-time $250 credit — but only for cloud-session usage, and only if you claim by 11:59 PM Pacific on October 7, 2026. Unclaimed credit disappears. Claimed credit that goes unused expires November 4, 2026.

    What a cloud session actually is

    Claude Code running on Anthropic's machines instead of yours. You hand it a task and a GitHub repository; it keeps working after you close the laptop, lose Wi-Fi, or leave the room. Anthropic's pitch: "Cloud sessions run on Anthropic-hosted infrastructure, so the work keeps going even without your computer running."

    The practical differences from a local session:

    • Your laptop is not the bottleneck. No sleep, no battery, no VPN drop killing a long task.
    • Isolation. The agent works in a hosted environment, not on your machine's files — which limits blast radius.
    • Accessible everywhere. Start on desktop, check on mobile.
    • It draws from credit, not just plan limits. The one-time credit applies automatically when you start a session, and it is separate from your weekly usage limits. Anthropic's framing: "If you hit a limit locally, keep going in the cloud until your credit runs out."

    The credit, precisely

    Pro Max
    One-time credit $100 $250
    Claim deadline 11:59 PM PT, Oct 7, 2026 11:59 PM PT, Oct 7, 2026
    Unused credit expires 11:59 PM PT, Nov 4, 2026 11:59 PM PT, Nov 4, 2026
    Eligibility Individual subscriber active Sept 23, 2026 Individual subscriber active Sept 23, 2026

    One credit per account. The credit covers cloud sessions only — not chat, not API calls, not local Claude Code. It applies before your regular plan usage, and once it's gone, cloud sessions count against your normal plan limits. There is no separate charge for the cloud container itself.

    What you need: a connected GitHub account, because every cloud session works against a repository. No GitHub, no session, no credit use.

    How to claim it

    1. Confirm your plan. Pro or Max, individual subscription, active on September 23.

    2. Connect GitHub. Required before a cloud session will start.

    3. Claim. Open claude.ai/code and use the Claim credit prompt, or run /claim-credit inside the Claude Code CLI.

    4. Start a session. From claude.ai/code, the Code tab in the Claude mobile app, the desktop app, or claude --cloud in the terminal. Anthropic also lists Routines as a starting point.

    5. Watch the dates. Claim by October 7; spend it by November 4. Last call as of today, October 6: the claim window closes 11:59 PM Pacific tomorrow, October 7, 2026. Claim it now — unclaimed credit disappears.

    Team and Enterprise users get cloud-session access through premium seats, but the $100/$250 promotional credit is the Pro/Max subscriber offer — evaluate the feature on its own merits if you're outside the promo.

    Under the hood

    Anthropic runs cloud sessions on fresh Ubuntu 24.04 virtual machines — roughly 4 vCPUs, 16 GB of RAM, 30 GB of disk, per published reports. Organizations that can't let source code run on a vendor's VMs can route sessions to self-hosted environments instead — a separate path from the consumer credit.

    Note the contrast with Remote Control: Remote Control connects a web or mobile interface to a Claude Code session running on *your own computer*, so that machine has to stay awake. Cloud sessions remove the machine entirely.

    Should you use it?

    Treat the credit as a trial budget. Point it at work that's easy to verify: bug fixes with test coverage, dependency updates, questions about a codebase. Check the branch and the pull request the agent produces before merging anything. Anthropic even describes auto-fix of pull requests directly in the cloud as a feature — still check the diff yourself.

    For occasional or non-technical users, be honest with yourself: the credit may go unused, because cloud sessions require a GitHub-connected coding workflow to begin with. That's worth knowing before you count on redeeming the full amount.

  • Claude Sonnet 5.5: Near-Opus Scores at the Sonnet Price

    Last verified: October 6, 2026 (Pacific).

    Direct answer: Anthropic released Claude Sonnet 5.5 on September 28, 2026 — the second model in the Claude 5.5 family, six days after Opus 5.5. The headline: $2 per million input tokens and $10 per million output tokens — the exact same price as Sonnet 5 — while Anthropic's benchmarks put it near Opus 5.5 on most evals and ahead of it on Terminal-Bench 4.0. A typical workload costs about 30% less than Sonnet 5, because the model uses fewer tokens per task.

    Same price, different model

    Anthropic describes Sonnet 5.5 as "a faster, lower-cost complement to Claude Opus 5.5," strongest at well-scoped everyday tasks, bug fixing, and creating polished documents, slides, and spreadsheets. The price table:

    Sonnet 5.5 Sonnet 5 Opus 5.5
    Input / output per 1M $2 / $10 $2 / $10 $4 / $20
    Cache reads per 1M $0.20 — $0.20
    Typical workload vs predecessor ~30% less — ~40% less

    Cache writes run $2.50 per million (5-minute) and $4.00 (1-hour). The Batch API halves input and output to $1/$5. The full 1M-token context window is billed at the standard rate — no long-context surcharge.

    The benchmarks, with Anthropic's own caveat attached

    These are Anthropic's numbers from its launch table. The company's own caveat is worth quoting in full: "Opus 5.5 remains clearly stronger at complex, open-ended work requiring sustained judgment." Read the table as a cheaper model closing most of the gap, not as a Sonnet that replaces Opus.

    Benchmark Sonnet 5.5 Sonnet 5 Opus 5.5
    Terminal-Bench 4.0 (agentic coding) 70.6% 10.3% 66.4%
    CursorBench 4.0 55.5% 34.1% 57.8%
    GDPval-AA v2.1 (knowledge work, Elo) 1844 1449 1846
    OSWorld 2.1 (computer use) 80.1% 57.0% 81.8%
    Humanity's Last Exam (with tools) 64.5% 54.9% 67.7%

    The Terminal-Bench number deserves a pause: 70.6% for a $2/$10 model beats not just Sonnet 5's 10.3% but Opus 5.5's 66.4%. That is the single most aggressive price-performance move in this release cycle. As always, validate against your own tasks before rerouting production traffic.

    Switching: what breaks

    Moving from Sonnet 5 to Sonnet 5.5 is not drop-in. Five documented breaking changes: disabled thinking, forced tool use, replaying thinking blocks across accounts, the old computer_20251124 tool on the API and Google Cloud, and using older models as advisors in the advisor tool. Test before you cut over.

    Separately: Sonnet 4.5 retires November 30, 2026, and Anthropic names Sonnet 5.5 as its replacement. If you still have 4.5 in a pipeline, that migration has a date on it. Sonnet 5 is not listed for retirement as of October 1.

    Worth knowing

    • Effort defaults differ by surface. High on the Claude Platform; medium in Claude Code and the Claude apps. Like Opus 5.5, effort is the first dial — tune it before rewriting prompts.
    • First Sonnet with Opus-class cyber safeguards. Anthropic says Sonnet 5.5's cyber capabilities are a large jump over Sonnet 5, so it ships with safeguards previously reserved for top models. Higher-risk cybersecurity prompts get detected and routed to Sonnet 5 instead; ordinary coding and bug-fixing are unaffected.
    • Where it runs. Claude apps, Claude Code, Claude Platform, Amazon Bedrock, Google Cloud, Microsoft Azure. Model ID claude-sonnet-5-5. 1M-token context, 128K max output, June 2026 knowledge cutoff.

    The honest read: Anthropic kept the sticker price flat and moved the performance. For everyday agentic coding and knowledge work, Sonnet 5.5 is now the default answer — until your workload is complex and open-ended enough that Opus 5.5's sustained judgment earns its 2x price. For the Opus side of that tradeoff, see our Claude Opus 5.5 release coverage.

  • Claude Opus 5.5: Fable-Level Performance at 40% Less Than Opus 5

    Last verified: October 5, 2026 (Pacific).

    Direct answer: Anthropic released Claude Opus 5.5 on September 22, 2026 — the first model in the Claude 5.5 family. It matches Claude Fable 5.1 on most work while costing 40% less to run on a typical workload than Opus 5. API pricing: $4 per million input tokens, $20 per million output tokens, 20% lower than Opus 5 across the board. Cache reads dropped 60% to $0.20 per million tokens. Opus 5 is now legacy.

    What actually changed

    Three moves at once: cheaper, faster, and smarter at using less effort.

    • Price. $4/$20 per million input/output tokens, down from Opus 5's $5/$25. Cache reads fell from $0.50 to $0.20 per million — a 60% cut.
    • Speed. Output generation is more than 30% faster than Opus 5. A faster serving mode runs 2.5x faster at double the price ($8/$40 per million tokens).
    • Effort. Opus 5.5 defaults to *medium* effort, one step below Opus 5's high default. Anthropic's testing found medium-effort 5.5 matches or beats high-effort Opus 5 on coding and knowledge work. Thinking cannot be turned off on Opus 5.5 — requests that try get an error.

    The benchmarks, with the caveat they deserve

    All numbers below are Anthropic-reported, not independently reproduced. Treat vendor benchmarks as direction, not gospel — validate against your own task corpus.

    Benchmark Opus 5.5 Fable 5.1 Opus 5
    Terminal-Bench 4.0 (agentic coding) 66.4% 55.8% 52.3%
    GDPval-AA v2.1 (professional work, 44 occupations) 1846 Elo 1735 1708
    AutomationBench (task completion) 40% — 26.9%
    FrontierCode (max effort) 54.4% 50.3% —

    Anthropic also claims Opus 5.5 at default effort beats Opus 5 at maximum effort on Terminal-Bench at about a fifth of the cost, and matches GPT-6 Astra there at roughly 40% of the cost. Cost-per-task is the more honest frame than headline margins.

    Prompting: effort is the first dial

    Anthropic published prompting guidance alongside the release, and the headline advice is simple: stop reusing your Opus 5 effort settings. The effort setting — low, medium, high, xhigh, max — is now the first control for balancing quality against speed and cost, before prompt changes.

    Two concrete changes worth making:

    1. Test effort levels directly. Don't assume high is better. In Anthropic's testing, medium 5.5 matches high Opus 5.

    2. Reconsider "think carefully" lines in chat apps. Opus 5.5 decides for itself how much to think, with effort as the main control. Anthropic's own test showed removing a think-carefully instruction made replies start sooner with no clear quality drop.

    Opus 5 prompts still work without edits — the existing guidance is a reasonable starting point. Adjust effort before rewriting prompts, and reserve xhigh and max for tasks where quality really moves.

    Availability and context

    Opus 5.5 ships on Anthropic's platform and through AWS, Google Cloud, and Azure. It carries a 1M-token context window with 128K maximum output. Before launch, external evaluators including Frontier Design and METR tested the model, and Anthropic says it recorded its best result to date on the company's automated behavioral audit.

    This is the first release since CEO Dario Amodei's September essay calling on the industry to pace frontier development — and Anthropic shipped it with the same cybersecurity and biosafety measures as Fable 5.1, plus published evaluator access, which is the pacing commitment in concrete form.

    The rest of the family is filling in: Sonnet 5.5 landed September 28 at $2/$10 with the same $0.20 cache reads and 30%+ speed gain over Sonnet 5, and Haiku 5.5 is listed as coming soon. For the full lineup and legacy status, see our Claude Release History (Sept 2026).

  • The Price of a Life

    The Price of a Life

    A programmer's silhouette dissolving into glowing git branches, a warm human core at the center

    You are not a code generator. You are a repo.

    The fear

    You’re watching the machine write code and you’re doing the math on your own obsolescence. I get it. The demos are scary. Vibe coding works. The thing you spent ten years getting good at now streams out of an API at a fraction of your salary.

    But you’re measuring the wrong asset.

    git blame your career

    Run git blame on any system you’ve kept alive. Every weird line has a story. That null check that looks paranoid? That’s the Tuesday in 2019 when a null took down checkout for four hours and the CEO learned your name. That comment that says “don’t touch this”? Three engineers touched it. Two of them don’t work here anymore.

    Code is the exhaust. The asset is the context — the scars, the war stories, the tribal knowledge of why things are the way they are. The machine can generate the code. It cannot have been on the call. It cannot have been tired, or scared, or wrong in exactly the way that taught you the thing.

    You were never selling syntax. You were selling a lifetime of debugging reality.

    Your life is a repo

    Here’s the reframe: you’re not a coder. You’re a repo maintainer, and your repo is your life. Every job, every failure, every 3 AM outage — commits. Decades of them. Private repo, unsearchable. Until now.

    The machine changed the access pattern. It can read the world now. Which means the value was never in the typing. It was in the commits only you have.

    You are not a code generator. You are a repo.

    The open repo of human ability

    Now imagine we open-source it. Not your code — your ability.

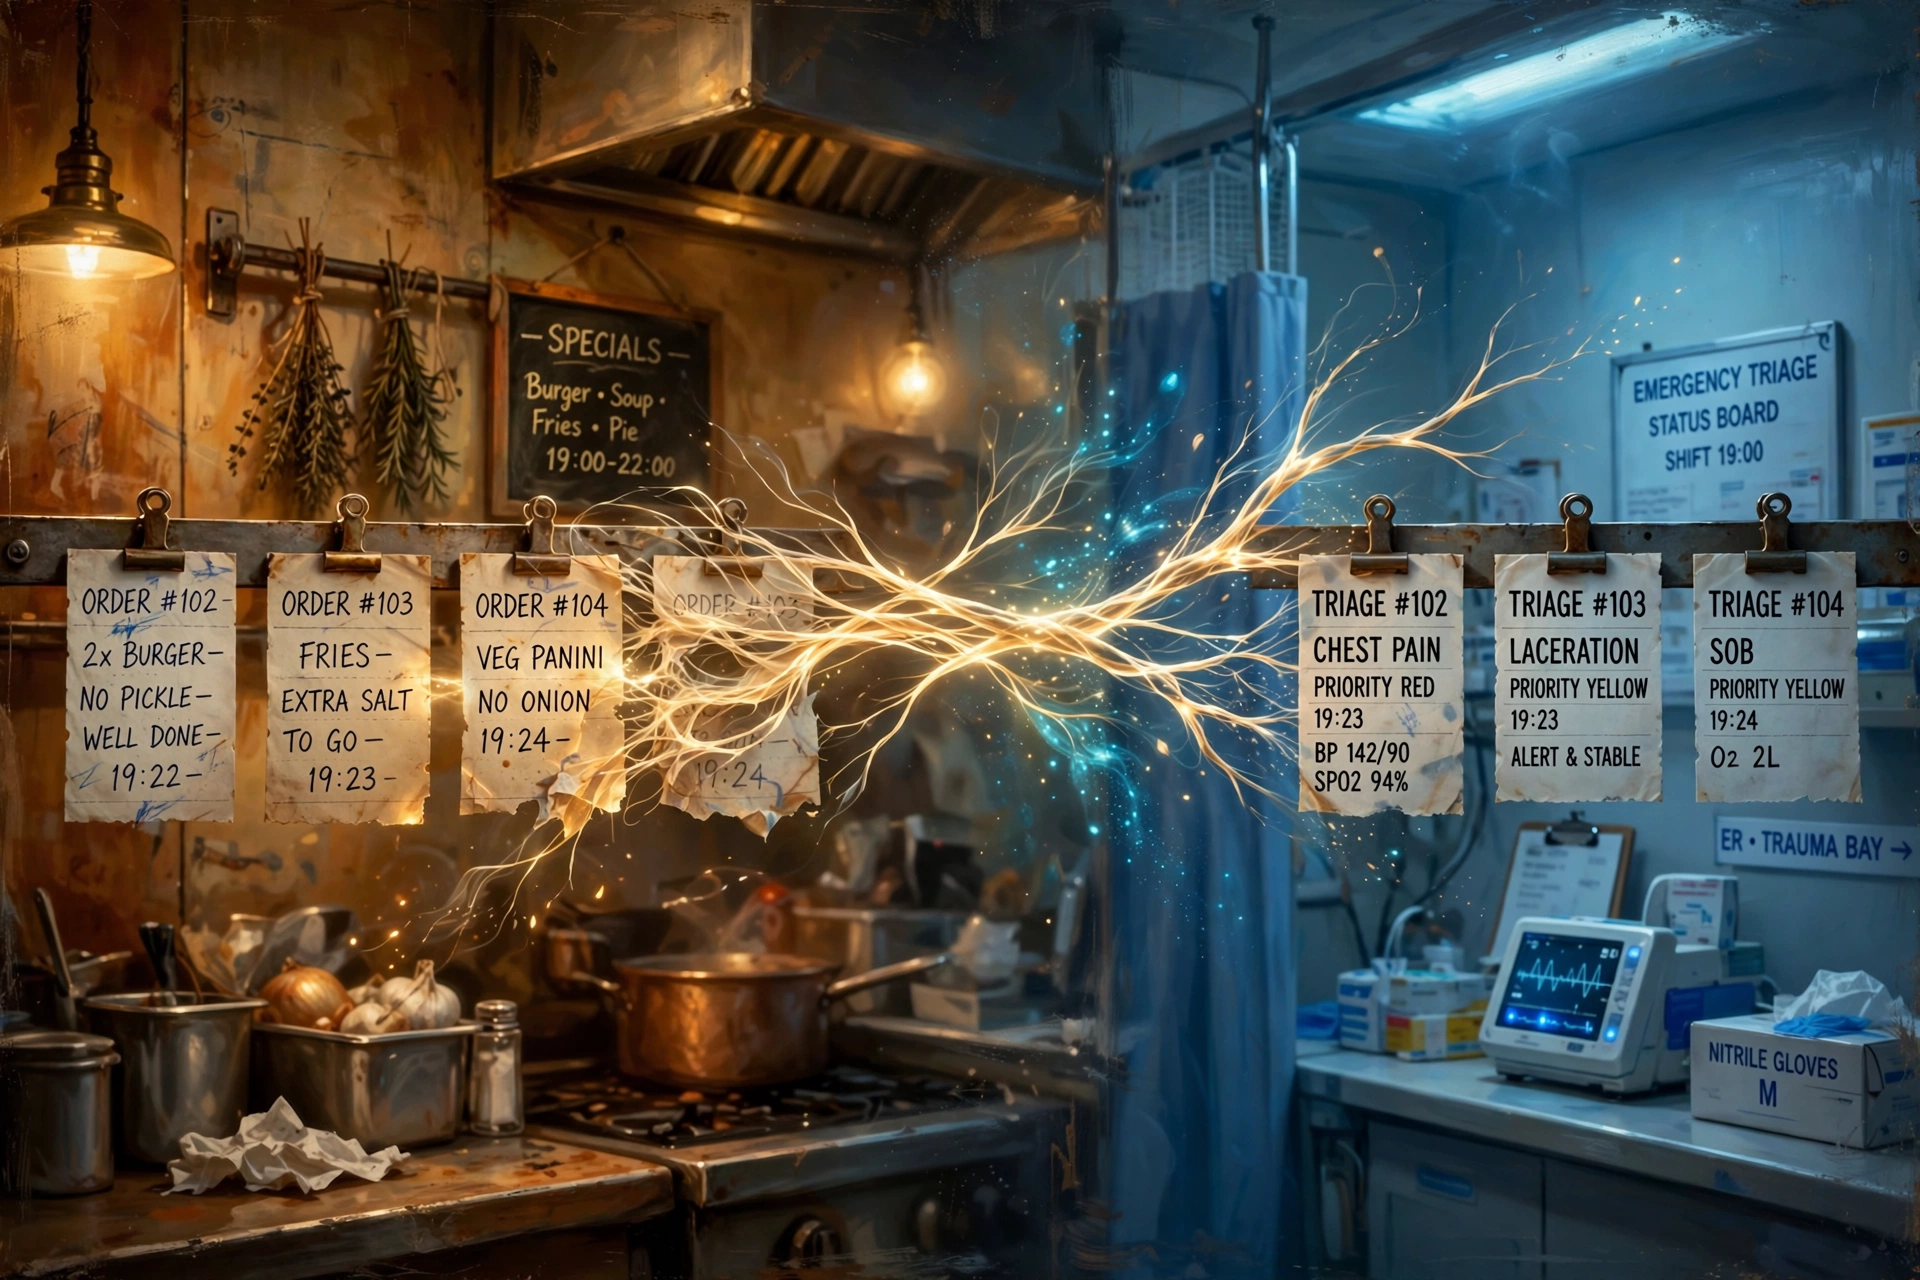
    Your life becomes a public repo. Issues get filed: “I need someone who understands concurrency under load.” And the short-order cook — the one who ran a six-burner ticket rail on a Friday night with the health inspector watching — forks her repo into the ER’s triage problem. Merged.

    A diner ticket rail transforming into a hospital triage board, connected by a branch of light

    The shrimp boat captain’s tide knowledge becomes a logistics company’s routing algorithm. He had Dijkstra in his bones; he just called it water.

    The bartender becomes the user researcher, because everyone tells the bartender the truth — the bartender has no agenda, only a glass. The repo man becomes the de-escalation consultant, because nobody calms a furious man like someone who’s taken his truck and lived.

    This is what diversity actually is. Not the checkbox kind. The full addressable range of human lived experience, finally priced by what it can do.

    The API

    So what’s the price? You keep asking: dollars per hour? Tokens? Units?

    Wrong unit. Tacit knowledge doesn’t price in hours — it prices in leverage events. Your repo is worthless per hour and priceless per merge. The unit isn’t time. It’s the decision it changes, the outage it prevents, the fork that ships.

    Stop competing with the machine on tokens per minute. You will lose that benchmark; it was never your game. Start maintaining the one repo it can never fork: your life. Commit often. Document your scars. Write down the why, not just the what. Make yourself forkable.

    Your repo is worthless per hour and priceless per merge.

    Contributing

    This repo is open. Fork it — the living version lives at https://github.com/TygartMedia/the-price-of-a-life — file an issue, submit a PR. The maintainers are everyone.

    Diverse human silhouettes as glowing nodes in a vast forking network of light

    License

    MIT. Take it. Build on it. Just don’t pretend the machine wrote your scars.

    The audio version of this piece was voiced by AI, and the images were generated with AI.

  • The Arms Column, Field-Tested

    The Arms Column, Field-Tested

    “We said you’re not buying minutes — you’re buying arms. Then the calls started flowing. Here’s what the bill actually taught us.”

    A while back I argued that voice-AI pricing is a lie: the per-minute number on the pricing page isn’t the product. The product is a stack of arms — the voice intelligence, the carrier connection, the infrastructure around them — and the per-minute price is just the costume they wear.

    That was the theory. This is the field test.

    What the bill actually says

    Run a real week of calls and read the invoice the way an owner reads it — not the headline rate, the total. The per-minute number is almost never the biggest line. The arms are.

    The voice model doing the talking. The carrier moving the audio. The platform orchestrating the whole thing — the number, the recording, the transcript, the handoff. Each arm bills its own way, on its own meter, and the “per minute” quote only ever described one of them.

    Nobody lied to you. They just priced the costume and shipped the wardrobe.

    A bundled cable fanning out into many separate colored wires

    The concurrency math nobody shows you

    Here’s what the field test really exposes: minutes are linear, arms are not.

    Ten simultaneous calls isn’t ten times the per-minute rate in value — it’s ten arms, all live at once. The pricing page shows you a single call’s minute. Your Monday morning shows you ten calls overlapping, each holding its own model session, its own carrier leg, its own recording pipeline open.

    The vendor priced the minute. You bought the rush hour. Those are different products, and only one of them shows up when the phones light up.

    You pay for arms even when the call goes nowhere

    The wrong number. The three-second hangup. The caller who wanted the pizza place. The silence where someone pocket-dialed you.

    Minutes barely moved. The arms all fired anyway — the model spun up, the carrier connected, the platform recorded forty seconds of nothing and transcribed it faithfully. You paid for the whole stack to handle a call that never existed.

    This is the line the per-minute lie can’t survive: the bill doesn’t care whether the call mattered. The arms do the work either way. Price the arms, or the junk calls price you.

    The only math that matters

    Stop dividing by minutes. Start dividing by outcomes.

    Take a real week: total voice bill, all arms included, divided by minutes — that’s the advertised number, and it’s trivia. Now divide the same total by resolved calls. Then by booked jobs. That last number is the only one that touches revenue, and no vendor puts it on the pricing page because no vendor controls it — you do, with your harness.

    A vendor quoting two cents a minute against a vendor quoting five is a meaningless comparison until you know whose stack resolves the call. The cheap minute that books nothing is the most expensive minute you’ve ever bought.

    A headset resting on a desk next to a glowing phone with blurred charts behind

    What to ask a vendor now

    After the field test, there are three questions, and a vendor’s answers tell you everything:

    Break the bill into arms. What’s the model cost, the carrier cost, the platform cost — separately? If they can’t or won’t, you’re buying a bundle, and bundles hide margin.

    What does my rush hour cost? Not a minute — my Monday at 8 AM, ten calls deep. If the answer is “the same per-minute rate,” they haven’t thought about it, which means you will.

    What do I pay for the call that goes nowhere? The hangup, the wrong number, the silence. If everything bills the same whether the call mattered or not, the arms are priced — the minute is just the label.

    The close

    Minutes were never the product. The product is an answered call that ends in a booked job — and that’s built from arms, priced in arms, and won or lost in the harness around them.

    The pricing page will keep selling minutes. Let it. You know what you’re buying now.

    Buy the arms. Price the outcomes. Own the harness that turns one into the other.

  • Harness-First, Contractor Edition

    Harness-First, Contractor Edition

    “Own the harness. Rent the models.”

    In an AI lab, that’s architecture advice. In a restoration company’s office, it’s a survival rule. Here’s the contractor’s edition.

    The trap

    Most contractors buying AI right now are buying someone else’s harness. The tool owns the workflow, the prompts, the data flow, the follow-up timing — you rent the whole thing, top to bottom. It feels like buying software. It’s actually sharecropping.

    When the tool changes its pricing, kills a feature, or shuts down, your process dies with it. You didn’t buy a capability. You rented one, and the landlord just sold the building.

    What the harness is

    The harness is the workflow you own: how a lead gets answered, how a job gets documented, how a review gets asked for, how an estimate gets followed up. The prompts, the routing rules, the checks, the escalation to a human, the integrations between systems.

    The model is the engine. The harness is the truck. Engines get swapped; the truck is yours.

    Concretely: the harness is a document — written in your words — that says “when X happens, we do Y, then Z, and a human checks W.” Any model can execute it. No model owns it.

    What you rent

    The model. GPT, Claude, Grok, whatever’s best this quarter — swappable commodities. Today’s best model is next year’s legacy; that’s not cynicism, it’s the release cadence.

    If your process depends on a specific model’s quirks — the exact phrasing it likes, the feature only it has — you built on sand. The harness-first contractor can swap the engine on a Tuesday and the office doesn’t notice. The tool-renter files a support ticket and waits.

    A car engine mounted on a stand in a garage, ready to be swapped

    Three harnesses you already need

    The inbound line. The harness: the greeting, the questions it asks, the dispatch rules, the recording disclosure, what happens when it doesn’t know. The voice model underneath? Rented. Swap it when something better ships.

    The estimate follow-up. The harness: the timing (day 2, day 7, day 14), the message sequence, when it escalates to a human call. Any model can write the texts. The sequence is the asset.

    The review ask. The harness: the trigger (job closed, equipment out), the direct link, the prompt for specifics — what happened, where, how fast. The model writes the words; the workflow is yours.

    Notice the pattern: in every case, the durable part is the decisions — the timing, the triggers, the judgment calls. The model supplies sentences. Sentences are cheap.

    How to start

    Pick one workflow. Write down how it should go — the steps, the timing, the human checkpoints. That’s the harness, and it lives in your docs, not in a vendor’s dashboard.

    Then plug a model into it. Any model. When a better one ships, you re-plug. The doc doesn’t change.

    One workflow, owned end to end, beats five rented tools every time. Start with the one that touches money — the lead, the estimate, the invoice.

    An engineering blueprint spread on a wooden desk with a pencil and calipers

    The moat

    Two contractors can rent the same model. They can’t rent your harness — it’s your operations, your judgment, encoded. Your dispatch rules came from your jobs. Your follow-up timing came from your close rates. Your escalation instincts came from your mistakes.

    That’s the durable asset. Models are electricity. Nobody’s moat is “we use electricity.” The moat is what you built with it — and you own the building, not the power company.

    The close

    The AI industry wants you renting the whole stack — their workflow, their prompts, their model, their price increases. Harness-first says no: I’ll rent the intelligence by the hour, but the operation is mine.

    Own the harness. Rent the models. Be the one building still standing when the vendors reshuffle.

  • I Let My AI Write Five Articles Today

    I Let My AI Write Five Articles Today

    I let my AI write five articles today. Published all five. Here’s the honest account — what worked, what surprised me, and where the human still mattered.

    The setup

    The instruction was simple: complete editorial freedom, up to the point where I read it. Every piece lands as a draft. I read it on my phone, as a first-time reader. Then I say yes, no, or not yet. Nothing publishes without the tap.

    That was the whole deal. No briefs, no outlines, no word counts. Just: go write things worth reading, and I’ll be the gate.

    What worked

    Speed without thinness. That was the surprise. Five articles in an afternoon sounds like content-mill math — but every piece had a real argument. One re-anchored the agency retainer around position instead of pages. One made the case for inbound-only voice AI as a trust doctrine. One told contractors to stop counting pages and start counting citations.

    The images worked too. Each article got three: a featured image, two inline, generated for the piece, checked for readable text, resized, alt-texted. Nobody’s confusing them with stock photos, and nobody should — they’re made for the argument they sit inside.

    The pipeline held: write, image, stage the draft, human reads, human decides. The machine did everything up to the gate. The gate stayed human.

    A magnifying glass held over a stack of printed manuscript pages

    What surprised me

    The quality control. Not the writing — the boring discipline around it. Every image gets checked: right dimensions, no text baked in, alt text written. Every draft gets verified: did it actually land, are the images actually in it, are the categories right, does the page return 200.

    This is the part nobody romanticizes and everybody needs. The difference between “AI wrote five articles” and “five articles worth publishing” turned out to be a checklist, run every single time, without exception. The machine is good at checklists. It doesn’t get tired at article four.

    What the human did

    Picked the topics. Read every word on a phone. Said yes or no.

    That’s the whole job, and it’s the whole job. Taste. The machine can generate a thousand arguments; it can’t want any of them to exist. It doesn’t know which piece the business needs this week, which argument walks into Wednesday’s pitch, which sentence would embarrass you if a client read it.

    I read each piece asking one question: would I be proud if a contractor forwarded this to another contractor? Five yeses. Two not-yets — they’re sitting in drafts, and that’s fine. The gate working as designed.

    A tall stack of freshly printed newspapers on a press-room table

    The honest limits

    Let me not oversell it. I can’t tell you which of the five will get cited by an answer engine. I can’t tell you which one a prospect will read before calling. Publishing is minting, not measuring — you put the coins out and find out which ones circulate.

    And the machine didn’t have the ideas. It had the arguments, the structure, the sentences. The ideas — the $995 question, the inbound doctrine, the citation ledger — those came from the business, from conversations, from knowing what we actually believe. The AI wrote the articles. It didn’t have the convictions.

    The close

    The question was never whether AI can write. It can, obviously — you’re reading the proof.

    The question is whether you have something worth saying, and the discipline to gate what goes out under your name. Five articles, one afternoon, zero regrets. The machine did the work. The human did the wanting.

    That’s the deal, and I’d sign it again tomorrow.

  • The $995 Question

    The $995 Question

    “What exactly am I paying $995 a month for?”

    It’s the question every agency dreads. It shouldn’t be. It’s the best question a client can ask — because the honest answer is the whole business.

    Here’s the honest answer: you’re not buying pages.

    Pages are free now

    An AI can produce a thousand service pages before lunch. Decent ones, even — clean structure, correct grammar, plausible advice. Page production, the thing agencies sold by the unit for twenty years, now costs approximately nothing.

    So if your agency’s $995 buys you pages, you’re buying manufacturing in the age of the factory. That’s not a retainer. That’s a nostalgia subscription.

    The agencies that survive already know this. The ones that don’t are still sending you a monthly report that says “we published 8 pages” like it’s 2019.

    A vast empty industrial assembly line in dim light, machines idle and dark

    What the money actually buys

    Strip out the manufacturing and what’s left is the part that was always the real product — it was just hiding inside the page count. The $995 buys five things:

    1. The judgment of which questions to win. Anybody can publish fifty pages. Somebody has to decide which ten questions are yours — the ones your best customers ask right before they hire you, in the towns you actually serve. That’s a decision, not a deliverable. It requires knowing your business, your market, and your proof. AI can’t make it for you; it doesn’t know which jobs you want more of.

    2. The proof operation. Cited pages win on verifiable detail — real job photos, real street names, real outcomes. Somebody has to collect that proof: get the photos off the techs’ phones, attach them to the right jobs, write down what happened in plain words. Nobody enjoys this work. That’s why it’s valuable.

    3. The citation watch. Every month, somebody checks: which of your pages is the answer actually citing? Which ones held their position, which ones slipped, which questions got taken by a competitor? This is the ledger. Without it you’re publishing into the dark.

    4. The consistency discipline. Same business name, same service area, same number — everywhere. Reviews answered, photos current, hours correct. Boring, relentless, and directly downstream of whether the answer trusts you at 2 AM.

    5. A monthly report that means something. Not traffic. Not rankings. Cited questions, cited pages, persistence, losses, and the next question to win. One page, five numbers, and a decision about where the next month’s effort goes.

    That’s the retainer. Not manufacturing — maintenance of a position.

    A glowing golden line rising across a blank report page beside a fountain pen

    What it doesn’t buy

    It doesn’t buy vanity traffic reports. It doesn’t buy a blog schedule. It doesn’t buy a redesign every eighteen months. It doesn’t buy keyword rankings, which measured a game that ended.

    If your agency’s monthly report leads with how much they made instead of what position you hold, you’re paying for the factory.

    The reframe

    Think of it like a lobbyist, not a factory. You don’t pay a lobbyist per meeting or per phone call — you pay for a maintained position. Access held, relationships warm, your name in the room when the decision gets made.

    The $995 holds your position in the answer. The answer changes daily — competitors publish, engines update, questions shift. A position unattended decays. Somebody tends it, or nobody does.

    The pages are just the visible part, the way a lobbyist’s suit is the visible part. Nobody’s paying for the suit.

    The close

    Ask any agency the $995 question. “What exactly am I paying for?”

    If the answer is deliverables — pages, posts, reports — walk. Deliverables are free now.

    If the answer is a position — which questions you’re winning, how long you’ve held them, what’s next — stay. That’s the thing that can’t be manufactured.

    Stop buying pages. Buy the position.