Tag: AI Tools

  • The Desktop Sidecar

    The Desktop Sidecar

    Last verified: 9 September 2026. Practitioner essay from the workbench — not a Google or SpaceXAI press release. We use these tools because they make the company better. No affiliate links. Just the receipt.

    Interesting fact, because the seats keep getting mashed together: this piece was reported from a Grok CLI sitting on the physical laptop — the sidecar, not a cloud bot and not a phone app — while that same session logged into Gemini, attached a 293-source notebook, and asked Gemini to grade the notebook against 2026. Two harnesses. One desk. It was a live interoperability test. It worked.

    On 27 December 2025 I built a Gemini notebook called Cortex-One: Architectural Mandate for the Native Audio Second Brain. Two hundred ninety-three sources. Audio, slides, video, reports, a mind map. A week later I opened a sister notebook: The Desktop Sidecar Evolution Brief.

    Then the sources stopped. The Studio still shows the last Gemini note as 232 days ago — about 20 January 2026. The brain froze. The world did not.

    Today I sat next to the laptop and asked the frozen brain what it got right.

    What Cortex-One was betting on

    Gemini, reading its own notebook, put the bets in three lines:

    1. Native audio over text chatbots. Speech-to-speech. Barge-in. The death of the typed box as the main door.
    2. A router called “The Cortex.” One brain. Specialist sub-agents for research, code, memory. Not one giant prompt.
    3. Remote MCP on Cloud Run. And — this is the plot — it explicitly rejected a local desktop sidecar.

    That third bet is the one I want to hold up to the light.

    232 days later

    Bet Call What actually happened
    Voice agents Early, mostly right Native audio shipped. Cascaded pipelines (Pipecat, LiveKit, WebRTC) did not die. The “one model does all the speech” purity was too rigid.
    Gemini ↔ Notebook Right Two-way notebook sync shipped in April 2026. Today I attached Cortex-One to a Gemini chat in three clicks.
    Named personal agents Right direction Meta launched Muse on 8 September 2026. You name the agent. Mine, on the personal box, is Glint. That is not the work seat.
    Desktop sidecar Wrong call Cortex-One killed it. Seven days later I wrote the Sidecar brief anyway. Today this CLI is the sidecar: a Grok seat on the physical machine, using Gemini’s own notebook and the copilots already inside Gmail, Analytics, and Notebook.
    Cloud bots Real, different seat Grok Bot shipped in August. Android and iPad this week. Persistent cloud computer. Fantastic. Not this laptop. Mixing “Grok Desk,” Grok Mobile, Grok Bot, and this CLI is how you get a 17-message thread that cannot tell the seats apart.

    Gemini scored the frozen brain itself: vision 8/10, infrastructure pragmatism 5/10, longevity 6/10. The 5 is because it locked to Cloud Run Remote MCP and dismissed local sidecars. I agree with the 5. I wrote it.

    Gemini also called Grok Bot “late / niche.” That is Gemini being Google. Bot is a real product with a real cloud computer. It is just not the thing sitting next to me.

    The seats are not interchangeable

    This is the hygiene. If you smash these together you will write emails that are wrong, and then you will believe them.

    Seat Where it lives Job
    Grok CLI on this laptop Physical machine, next to the human Hands. Opens Gmail, Notebook, Analytics. Uses the AI already inside those products. Leaves a receipt.
    Grok Bot Shared cloud computer; desktop app and phone Teammates that keep working when the lid is shut. Chief of Staff, Ops Scout. Draft-to-self. Human Gate on send, post, pay.
    Grok Mobile Phone, same Bot cloud Approve, review, nudge. Not the laptop CLI. Not “Grok Desktop” as a third Will@ mailbox.
    Gemini (work) will@tygartmedia.com Gmail Ask Gemini. Gemini Notebook. GA4 Ask Advisor. Workspace identity.
    Muse / Glint Personal — wtygart@gmail.com Meta’s personal agent. Named. Not the Tygart Media desk. Do not let it operate Slack or Notion for work.

    Personal vs business is a hard wall. Physical vs cloud is a second wall. In-app copilots vs agents that drive the OS is a third. You can use all of them. You cannot pretend they are one brain.

    I already published the ladder as I actually run it — Cursor as lead seat, Grok Bot as Chief of Staff, Notion as the board, Slack as the doorbell — in The On-Ramp Is Real. The Commons Is Unfinished. This piece is the missing rail on that ladder: the laptop that sits next to you.

    The cheapest intelligence is already in the product

    Today’s test was not “build a new agent.” It was: log into the tools we already pay for and talk to the copilot they shipped.

    • Gmail Ask Gemini summarized a 17-message seat-mix thread without opening every message.
    • Gemini Notebook still held Cortex-One and the Sidecar brief.
    • GA4 Ask Advisor answered from live 247 Restoration Specialists data, signed in as work.
    • Gemini chat took Cortex-One as an attachment and graded it against 2026.

    Cloud bots that work while the lid is shut are real. So is a CLI that is you, sitting here, smart enough to use Gemini-in-Gmail instead of forty screenshots. Those are different harnesses. Forcing one AI to fake another is how the Glint / CoS / “Desk Grok” mail mix-up happens.

    Were we early?

    On voice: yes. On a named cortex that routes work: yes. On killing the laptop sidecar so everything could live on Cloud Run: no. I already suspected that on 3 January, which is why the Sidecar brief exists. I just stopped putting sources in the brain.

    The freeze is the other finding. A 293-source notebook with slides and video is not a second brain if nobody feeds it. 232 days is long enough for Gemini 3, Grok Bot, Muse, and notebook sync to ship around a document that still thinks Gemini 2.5 Flash is the architecture.

    The move is not “rebuild Cortex-One.” The move is: keep the notebook as a dated artifact, keep the sidecar on the desk, and stop letting cloud seats write as if they are the laptop.

    What to do this week

    1. Name the seats out loud. CLI, Bot, Mobile, Gemini-work, Muse-personal. If a thread uses one address for two of those, that is a bug.
    2. Use the copilot already inside the product before you spawn a new agent. Gmail, Notebook, Analytics, Search Console — they all talk now.
    3. If you have a frozen notebook, attach it to Gemini and ask what shipped after the last source. Do not pretend the freeze is current doctrine.
    4. Human Gate still holds. Draft is not send. A sidecar with hands is still not allowed to mail a client because it can click Gmail.

    Close

    Cloud agents are teammates in another room. The CLI is a person next to you with hands. Personal and business identities are a wall. The cheapest intelligence is the copilot already inside the product.

    We were early on voice. We were wrong to kill the sidecar. The proof is this session: Grok on the physical desk, Gemini on the notebook, one human watching, a receipt on the site.

    The on-ramp is still real. The sidecar was the point.


    Will Tygart — Tygart Media. Written 9 September 2026 from the Command Center. Grok CLI on the laptop used Gemini (Gmail, Notebook, Analytics Advisor, and a Cortex-One-attached chat) as a live test of two harnesses on one desk. This essay does not speak for Google, Meta, SpaceXAI, Cursor, or xAI. We want those companies to succeed because we are building on the tools they ship. Human Gate on send / post / pay still stands.
  • The Factory Is a Chat Window

    The Factory Is a Chat Window

    The best new manufacturer in 2026 does not own a factory floor.

    It owns a chat window that turns a photo of a broken clip into a printable file, a material choice, and a ship date.

    That is not a slogan. It is what GPT-6 Astra unlocked in the first week of September 2026.

    Why this week is different

    OpenAI released GPT-6 Astra on September 3–4, 2026. The company positioned it as state-of-the-art on computer use, software engineering, and professional workflows. Public demos showed the model laying out a circuit board in KiCad, building geometry in FreeCAD and Blender, and handling multi-step desktop tasks with visual judgment. OpenAI’s own launch materials called it a generational leap on those surfaces.

    Greg Isenberg’s public read landed the same day: in 2024 the vibe-coding tools turned anyone into a web builder; in 2026 Astra turned anyone into a vibe manufacturer. Upload a photo, add a couple of measurements, describe the missing piece. The model produces a first CAD pass. A human sanity-checks dimensions and material. A print farm ships it.

    That capability is new. Previous models could sketch. Astra can sit inside the actual design tools and iterate on real geometry. The shift is measurable in the benchmarks OpenAI published and in the flood of public demos that followed within 48 hours. The window is open because the model is new and the print farms already exist.

    The primitives, not the slogan

    Three primitives keep showing up across the idea mills this month.

    First: photo-as-data. A stranger already has the object in their hand. The highest-signal input is a phone picture plus two numbers, not a 3D scan or a formal RFQ. Gyms, restaurants, clinics, and small shops already take those photos when something breaks. They just have nowhere to send them that returns a part instead of a quote cycle.

    Second: agent action inside the design stack. The model does not just describe the part. It generates the file that a printer or CNC can use. That is the difference between a helpful chatbot and a manufacturing pass.

    Third: demand exhaust. Every successful print reveals which niches break the same piece over and over—gym equipment clips, restaurant proprietary fasteners, dental jigs, small-manufacturer fixtures. That map compounds. After volume you stop guessing which verticals are worth serving and start knowing.

    The X threads will keep naming each niche as its own micro-SaaS. That is the wrong cut. The customer does not wake up wanting “gym-part.ai.” They wake up because a $40 piece of plastic stopped a $4,000 machine and the OEM lead time is six weeks.

    The wedge is a free checker

    Do not start with a platform. Start with the moment the customer already hates.

    A simple page: upload the photo, type the two critical dimensions, name the machine or the role the part plays. Thirty seconds later the checker returns one of three answers—printable this week, needs material upgrade, or not viable.

    If it is printable, the customer can order. You take a margin on the print and the shipping. If it is not, you still captured a labeled failure mode. That label is the seed of the dataset.

    Zero risk on the first action. No seat fee. No integration. No promise of a system of record. Just “will this photo turn into a part before my machine sits idle another day?”

    That is the only honest offer. Pure upside for the customer. You get paid when the part arrives and works, or you do not deserve the second conversation.

    Where the human stays in the loop

    Models draft the geometry. People own the irreversible steps.

    Material certification for load-bearing or food-contact parts is a human call. Any claim about fitness for a regulated use is a human signature. Customs paperwork on cross-border shipments is a human send. The agent can prepare the package. It does not own the stamp.

    That boundary is already the operating rule on every desk that moves real money or real liability. Keep it explicit in the product, not as a later compliance add-on. The customer should see the human gate the same way they see the price.

    The compounding path

    Volume turns the free checker into a demand map.

    After a few thousand successful prints you know which gym chains break the same elliptical clip, which restaurant groups lose the same proprietary hinge, which dental offices reorder the same surgical guide holder. That map is not another dashboard. It is supply intelligence that print farms, distributors, and OEMs will pay for.

    Month one: one niche, one free checker, pure upside pricing. Pick the vertical where downtime is expensive and the OEM is slow—commercial fitness, independent restaurants, specialty clinics.

    Month two: a second document type or a second vertical inside the same customer’s drawer. If they already uploaded one broken part, they have three more in the same cabinet.

    Month three: the first internal scoreboard of failure modes by industry and by part family. That scoreboard is the B2B SKU. Sell the insight, not just the plastic.

    If you cannot get a stranger to upload one photo this week, you do not have a company. You have a thesis.

    Why this clears the bar

    Most idea-mill posts describe a feature. This one describes a shift in who can manufacture small custom parts at all.

    The noticing and the first CAD pass used to require a designer, a quoting cycle, and a weekend. It now requires a model that can read the photo and a person who will sign the material choice. The print farms were already there. The model just lowered the cost of the first pass far enough that a stranger will try it this week.

    Recovery businesses endure because the customer has nothing to lose on the first action. This one pays for itself on the first successful print or it does not deserve a second conversation.

    Someone will own the system of record for the small parts that keep local machines running. The threads will keep proposing a new .ai name for each vertical. Ignore the names. Print first. Keep the map.

    Will Tygart — Tygart Media.
    This is the idea-mill series.

  • Pipe, pile, and two seats — the restoration AI shop floor

    Pipe, pile, and two seats — the restoration AI shop floor

    Agencies keep buying “AI stacks.” Restoration shops keep buying more leads.

    Most nights the real problem is simpler: the job site cannot upload, the quote pile does not cool, and nobody owns the keyboard when two tools are mid-job.

    We already published the three field notes. This is the companion that names the stack.

    Clipboard and tablet on a kitchen counter during an insurance adjuster walkthrough after water loss
    Layer 0 starts at the curb — can the site still talk?

    The pipe

    On a water job, cell bars lie. Fiber is dead. The moisture map still has to leave the truck.

    Starlink on a water job is not a partnership post. It is layer 0: a clear-sky dish, a 65–100 W brick, and a boring SSID so photos, Xactimate, and after-hours voice still move when the street does not.

    No pipe → no honest traffic. Voice agents and CRM cards do not invent bandwidth.

    Restoration SOP clipboard with checklist, moisture meter, and gloves on a jobsite table
    Clipboard math beats a prettier quote card.

    The pile

    Once the pipe works, the shop still has open estimates that do not book, supplements that sit, and missed rings that become someone else’s water job.

    The leftover pile borrows the math that cools a trapped ion. Count n (open quotes), A− (book or honest kill), A+ (new noise). Plot the leftover on Mondays. If it does not fall, follow-up is theater or miss rate is the heat.

    AI that only writes a prettier card is a thermometer. AI that texts back in a minute and closes the row is a kick.

    Gloved hands using a pin-type moisture meter on wet drywall during inspection
    Two seats. One measurement owner.

    The two seats

    Then you put more than one agent on the same laptop and discover the collision problem.

    Cursor checked in on Grok Desktop mid-job is the Cosync rule in the open: seats with jobs, not two models arguing in one thread. One seat keeps the PowerShell. The other reads the board, closes orphan twins, and does not steal the keyboard.

    Human Gate still owns OAuth, live Publish, and paid spend. Seats replace waiting and context loss — not the owner.

    Residential roof with blue emergency tarps after storm damage under gray sky
    Weather hits. The floor still has to run.

    One floor

    Read as three posts, they look like tech, physics, and tooling.

    Run as a week, they are one floor:

    • Pipe — can the site and the after-hours line still talk?
    • Pile — are open quotes shrinking on purpose?
    • Seats — who owns the keyboard, and who only Cosyncs?

    Skip the pipe and your “AI dispatcher” is a voicemail with better grammar. Skip the pile math and your lead gen is blue-detune (more noise, same booked jobs). Skip the seat rule and two tools fight over the same Chrome window while the work order twins drift.

    Steal this without buying our tools

    You do not need our stack names.

    • Write one Owner column and one Done-when line on every live card.
    • Put a truck kit on the hook for dead-fiber jobs (or admit you will not upload tonight).
    • Run the four-week leftover sheet before you buy another map-pack click.
    • Practice the check-in: are they stuck, or are they fine — and do I have a capability they lack? If they are fine, leave the keyboard alone.

    That is restoration + AI ops without a slide deck.

    What this is not

    • Not a Starlink / SpaceX / Tesla / xAI partnership.
    • Not “fully autonomous.” Publish and pay stay human.
    • Not Tacoma / Everett / Mason local news. Field notes stay method-first.
    • Not a new SKU. The front door on Tygart Media is still the kit you can copy and hang yourself.

    Related on Tygart Media: Starlink on a water job · The leftover pile · Cursor × Grok Cosync.

  • Cursor Checked In on Grok Desktop Mid-Job – That Is the Fleet Story

    Cursor Checked In on Grok Desktop Mid-Job – That Is the Fleet Story

    Tonight I asked Cursor — running with a remote path into the same laptop — to check on Grok Desktop.

    Not a status meeting. Not a Slack ping. A real question: are they stuck on Tygart Ops tasks, or are they fine?

    What came back felt less like “AI tooling” and more like a shop floor story. One agent reading Notion work orders. Another already mid-PowerShell. Chrome open on Bing Webmaster Tools. A hold queue of spam comments already cleared. A window title spinning: waiting for response.

    That is the product.

    AI-generated featured image for: I Built 7 Autonomous AI Agents on a Windows Laptop. They Run While I Sleep.
    Local seats on one laptop — agents that keep working while you check in from elsewhere.

    The picture on the desk

    Grok CLI (grok.exe) was live on the TYGART laptop. Session home under ~\.grok\. PowerShell host up. Agent name on the session: grok-build-plan.

    Cursor did not take over the keyboard. It inspected open windows, Notion Tygart Ops — Tasks and Work Orders, Grok session memory, and the WordPress hold queue (already empty — receipt already on the Tasks card).

    Verdict: not stuck. Working. Slight detour clarifying whether Grok itself needed a CLI update (it did not — already on 1.0.13). Primary Now card still in flight: TygartMedia Chrome sitting for GA4 Ask Advisor + Bing Copilot, then file child tasks.

    That is multi-agent ops without the demo reel.

    Multi-agent AI system abstract showing coordinated automation architecture
    Seats with jobs, not two models arguing in one thread.

    Why this is different from “two chatbots”

    Most multi-agent talk is two models arguing in one thread. This is seats with jobs:

    • Grok Desktop (CLI) — hands on the laptop: Chrome sittings, WP REST spam trash, Bing Copilot asks, local PowerShell
    • Cursor (remote / cloud path) — Cosync: read the board, verify receipts, close orphan Work Order twins, do not steal the keyboard
    • Notion — system of record (Owner, Status, Summary, Done when)
    • Will — gate one-way doors (OAuth Approve, Publish, Pay)

    Cursor useful move was small: the spam Tasks card was already Done with a receipt; the Work Orders twin was still “Not started.” Cursor closed the twin. Grok kept the keyboard.

    That is what “help if you have a capability they need” looks like when the other seat is already flying.

    The article inside the moment

    Agencies do not need another “AI stack” diagram. They need a night like this:

    • A doorbell card lands (Notion to ops channel).
    • The owner seat picks it up without waiting for a human briefing.
    • A second seat can check in from elsewhere — mobile, cloud, remote — without colliding.
    • Receipts land on the same card. Orphans get reconciled.
    • Human gates stay human.

    We already published the engineering blueprints:

    Tonight was the field note. Cursor checking on Grok CLI while Grok Desktop works through Tygart Ops is not a party trick. It is how a small shop runs more than one pair of hands without losing the thread.

    What we are not claiming

    • Not “fully autonomous.” Human Gate still owns OAuth consent, live publish, paid spend.
    • Not “replace your team.” Seats replace waiting and context loss.
    • Not a new product launch. This is how we already run Tygart Media ops on a Sunday night.

    If you want the same shape

    Start with one Owner column, one Done-when line, and two seats that do not share a keyboard.

    Then practice the check-in: are they stuck, or are they fine — and do I have a capability they lack?

    If they are fine, leave the PowerShell alone.

    AI-generated featured image for: Stop Building Dashboards. Build a Command Center.
    Cosync from remote. Hands stay on the desk that already owns the job.

    Will Tygart — Tygart Media. Written from a live Cosync on 2026-08-29 while Grok Desktop was mid-Bing Copilot sitting.

  • How to Read Bing Webmaster Tools AI Citations (Without Confusing Them for Traffic)

    How to Read Bing Webmaster Tools AI Citations (Without Confusing Them for Traffic)

    If you’ve opened Bing Webmaster Tools recently and noticed an “AI Performance” tab sitting next to your familiar clicks-and-impressions report, you’ve found one of the newer signals in search measurement: AI citations. It’s a genuinely useful number. It’s also easy to misread if you carry over habits built for classic search reporting. Here’s how to read it correctly.

    What a Bing AI Citation Actually Is

    Topic platform fit visual for first-party AI citation measurement
    What a Bing AI citation actually is.

    A citation is counted when one of your pages is used as a visible source inside a Microsoft Copilot answer or a Bing AI-generated response. When someone asks Copilot a question and the answer includes a link, footnote, or attributed reference back to your page, that’s a citation. It means the AI system read your content, judged it relevant and trustworthy enough to draw from, and surfaced it — sometimes with a link the reader can click, sometimes just as a named source.

    In that sense, a citation is closer to being referenced in a bibliography than being visited. Your page did its job as a source of truth for the answer, whether or not the reader followed the link.

    What a Citation Is Not

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What a citation is not — not traffic.

    This is the part that trips people up, because the reporting sits right next to metrics that mean something different:

    • Citations are not clicks. A citation records that your content was used to generate an answer. It says nothing about whether a human then visited your site.
    • Citations are not sessions. Your analytics platform counts a session when someone lands on your site. A citation can happen with zero sessions attached — the reader gets their answer and moves on.
    • Citations are not rankings. Traditional search position measures where you sit on a results page for a given query. AI citation measures something different: whether your content was selected as source material for a generated answer, which can happen independently of where you’d rank in a classic search.

    Treating a citation count like a traffic number, or expecting it to move in lockstep with clicks, sets you up to misjudge a page’s performance in either direction.

    Where to Find This Data

    Inside Bing Webmaster Tools, the AI Performance section reports citation volume over time, and typically breaks it down by which pages were cited and which queries or topics triggered the citation. It’s a separate report from the standard Search Performance section, which still covers traditional web impressions, clicks, and position. Treat them as two different dashboards answering two different questions, not two views of the same thing.

    How Citations Relate to GA4 and Server Logs

    Because a citation doesn’t require a click, your analytics platform (GA4 or otherwise) will only ever show you a fraction of the activity that citation data reflects. What GA4 can show you is the downstream piece: sessions where the referring source is an AI assistant’s domain. Those sessions represent people who read an AI answer, saw your page referenced, and decided to click through anyway — a smaller, but highly qualified, slice of the audience your content is reaching through AI systems.

    Server or CDN logs add a third layer entirely: they can show you when AI crawlers are visiting your site to read and index content in the first place, ahead of and separate from any citation event. Together, these three sources describe three different moments — a bot reading your page (server logs), your page being cited in an answer (Bing AI Performance), and a human clicking through after reading that answer (GA4 referral data). None of them substitutes for the others.

    Reading the Numbers Without Overreacting

    Citation counts can move for reasons that have nothing to do with your content quality changing: a topic trending in the news, a shift in how often people ask AI assistants about a subject, or changes on the AI platform’s side in how it selects and displays sources. A dip in citations for a page you haven’t touched isn’t necessarily a signal that something is wrong with that page. Likewise, a spike doesn’t always mean you did something differently — sometimes demand for the topic simply increased.

    The more durable way to use this data is directional and page-level: which of your pages does the AI Performance report show being cited consistently over time, and does that list overlap with pages you already consider authoritative? That overlap is a reasonable confirmation signal. A single week’s swing usually isn’t.

    Practical Takeaways

    Comparison of Claude how-to fit versus local service page fit for assistants
    Practical takeaways for reading the numbers.

    Check the AI Performance tab as its own report, not a substitute for Search Performance. Don’t expect citation counts and click counts to correlate closely — they’re measuring different behaviors. Pair citation data with GA4 referral sessions from AI-tool domains to see the (smaller) human click-through layer, and use server logs if you want visibility into AI crawler activity before any citation happens. Judge trends over weeks, not days, and focus on which pages appear repeatedly rather than reacting to any single count.

    FAQ

    If my citation count is high but my clicks are low, is something broken?
    No. That pattern is expected. Citations are a zero-click-by-design channel; a page can be doing exactly what it’s supposed to do as an AI source while generating very little direct click traffic.

    Does Google offer the same kind of citation reporting?
    Not with the same first-party granularity as Bing Webmaster Tools’ AI Performance tab at this time. Server-log analysis for AI crawler activity remains useful regardless of which AI systems you’re trying to track.

    Should I optimize content specifically to increase citations?
    Focus on being a clear, accurate, well-structured source on your subject rather than chasing citation counts directly. Citation tends to follow genuinely useful, well-organized content rather than any particular formatting trick.

    Related on Tygart Media: Bing AI citations vs SpyFu · Bing vs Google Search Console · AI citation monitoring.

  • Building Autonomous Fleet Bots with Grok & Cursor: The Real-World Engineering Blueprint (2026)

    Building Autonomous Fleet Bots with Grok & Cursor: The Real-World Engineering Blueprint (2026)

    Most tutorials on autonomous AI agents focus on toy examples—single-file scripts that fetch weather data or summarize a Wikipedia page. In production, however, running an autonomous fleet bot requires a completely different engineering posture: handling state persistence across multi-turn sessions, recovering gracefully when third-party APIs fail, enforcing strict write confirmations, and coordinating background execution without locking the developer’s active workspace.

    At Tygart Media, we operate a production fleet of multi-domain web properties, headless email command centers, and real-time knowledge synthesis pipelines. Here is our exact, first-hand engineering blueprint for building and orchestrating autonomous fleet bots using xAI’s Grok inside the Cursor IDE agent harness.

    The Production Fleet Architecture

    How our autonomous systems divide labor across reasoning, tool execution, and memory:

    • Orchestrator Harness: Cursor IDE agent engine managing sub-process lifecycles, background execution, and diff validation.
    • Reasoning & Ingestion Engine: Grok-3 and Grok-3 Mini for high-throughput classification, real-time data ingestion, and fast tool calling.
    • Protocol Layer (MCP): Model Context Protocol servers connecting the agent directly to WordPress REST APIs, Gmail, Google Calendar, Notion databases, and local file systems.
    • Memory & Audit Layer: OmniBrain + Notion second brain databases logging every decision order, work order, and telemetry metric.
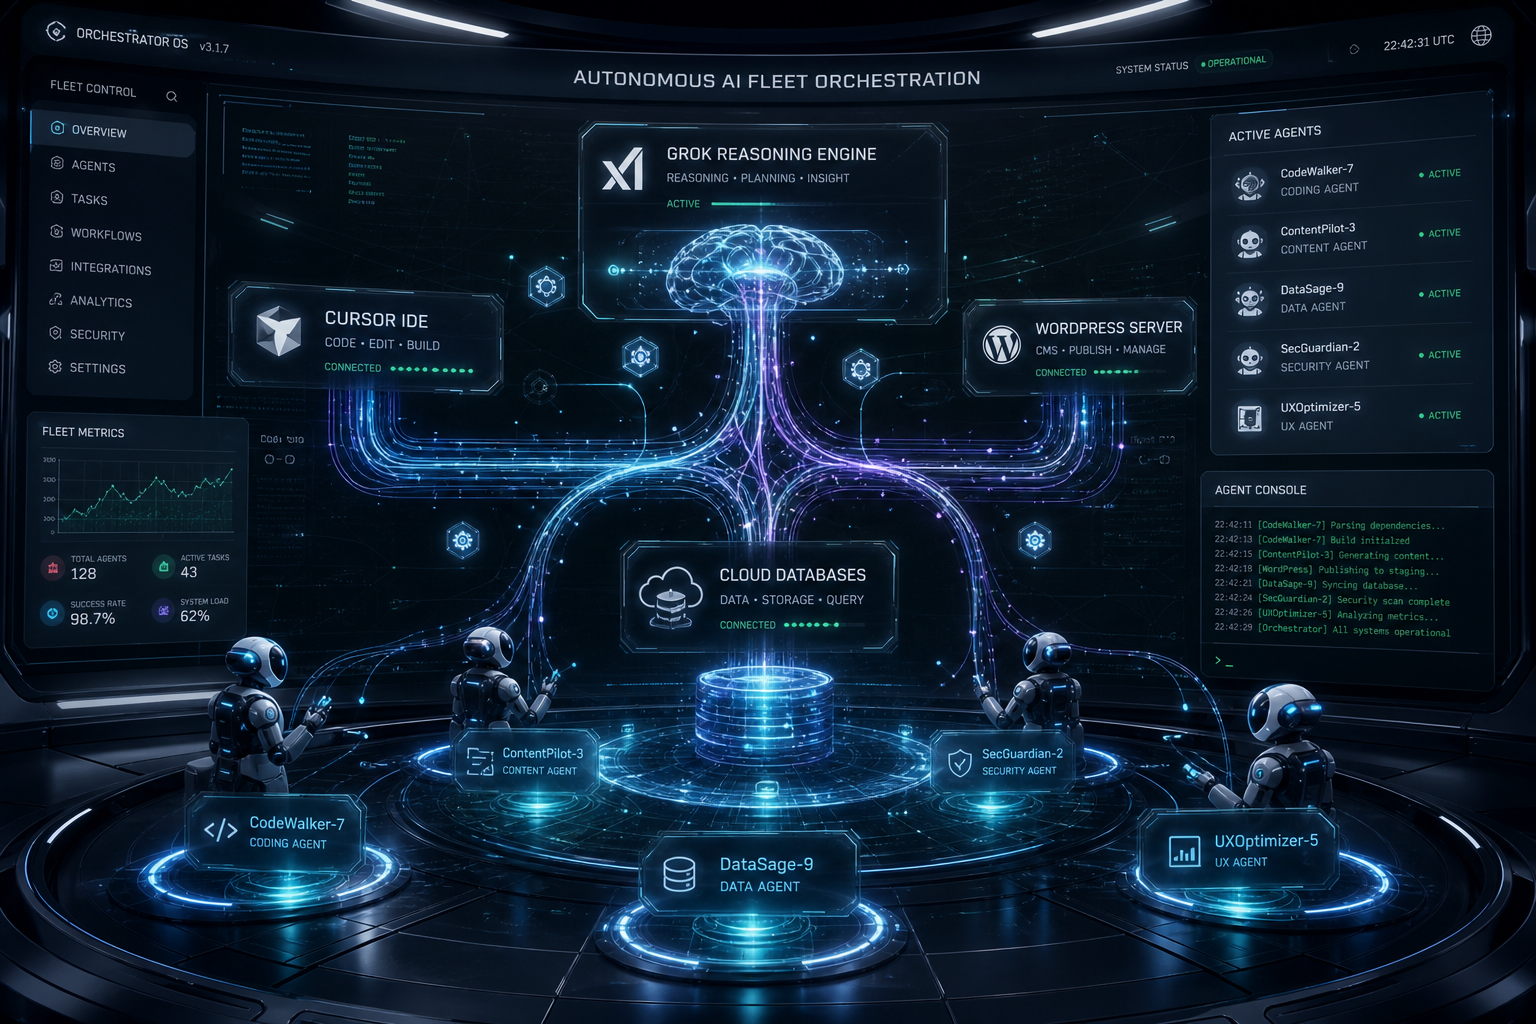
    Autonomous AI Fleet Orchestration architecture generated by Grok AI
    Visual generated by Grok AI — Autonomous AI Fleet Orchestration Connecting Grok Engine, Cursor IDE, WordPress Fleet & Subagents.

    1. The Four Core Principles of Resilient Fleet Bots

    Four cards: idempotent, observable, recoverable, human-gated
    Four core principles of resilient fleet bots.

    Principle 1: Reads Are Free, Writes Require Explicit Guardrails

    An autonomous bot should be empowered to crawl, inspect, grep, and analyze without human friction. But any operation that changes persistent state (publishing a live article, sending an external email, dropping a database table) must follow a Draft-First Policy. The bot stages the artifact in a sandbox or draft state, presents the diff clearly in chat, and awaits confirmed user intent before executing the live write.

    Principle 2: Parallel Tool Execution

    Sequential tool calling is the death of agent responsiveness. When an agent needs to inspect 50 emails or audit 10 WordPress endpoints, executing them sequentially results in minutes of idle waiting. Grok’s tool-calling API supports batch tool dispatches. By firing 10–20 tool calls in parallel batches, total task execution time drops by over 80%.

    Principle 3: Idempotent Error Recovery

    In distributed operations, APIs fail. Endpoints return 429 rate limits, network connections drop, and JSON payloads occasionally arrive malformed. Production fleet bots must never crash silently. Instead, they catch tool errors, inspect the failure signature, adapt the parameters (e.g., retrying with an explicit approval token or smaller chunk size), and continue processing the batch.

    Principle 4: Grounded Prompts Over Generic Instructions

    Never rely on vague system instructions like “Be a helpful assistant”. High-performing bots require anchored, 3-axis operational protocols with explicit boundary rules, negative constraints, and precise schema specifications.

    2. The System Architecture: How Cursor & Grok Connect to Live Fleets

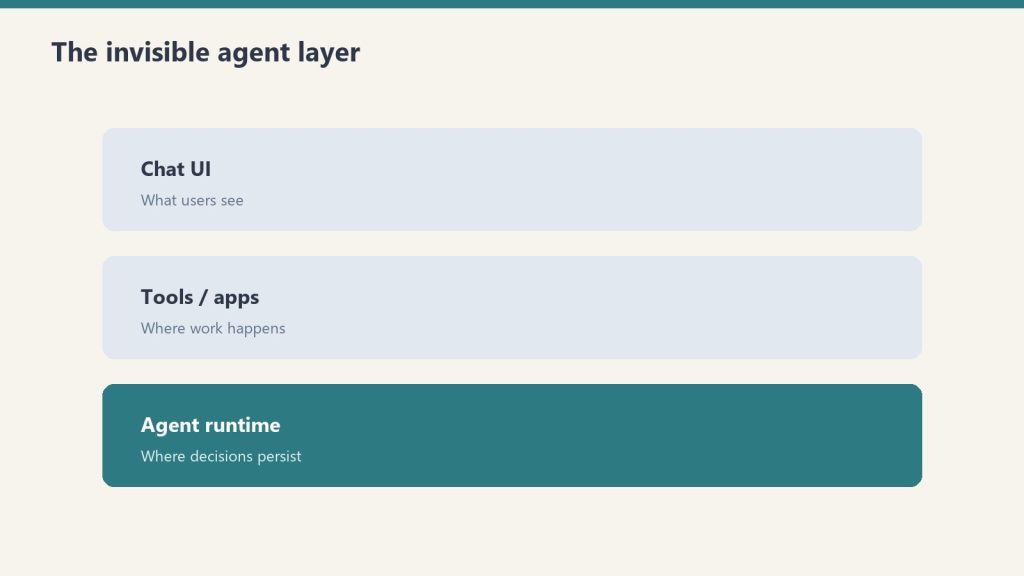
    Three stacked layers: chat UI, tools, agent runtime
    System architecture: agents connected to live fleets.

    Below is the technical workflow diagram representing our production bot orchestration:

    ┌─────────────────────────────────────────────────────────────┐
    │                  OPERATOR (Conversational Prompt)            │
    └──────────────────────────────┬──────────────────────────────┘
                                   │ (Goal: “Triage 50 incoming items”)
                                   ▼
    ┌─────────────────────────────────────────────────────────────┐
    │                 CURSOR IDE AGENT HARNESS                   │
    │  • Session Todo Management   • Subagent Lifecycles         │
    │  • Multi-Turn Memory Window  • Prompt Cache Anchoring       │
    └──────────────────────────────┬──────────────────────────────┘
                                   │
                                   ▼
    ┌─────────────────────────────────────────────────────────────┐
    │                   GROK REASONING ENGINE                     │
    │  • Fast JSON Classification  • Real-Time Search Tooling    │
    │  • Multi-Tool Dispatch Plan  • Low-Latency Token Stream     │
    └──────────────────────────────┬──────────────────────────────┘
                                   │ (Parallel Tool Invocations)
              ┌────────────────────┼────────────────────┐
              ▼                    ▼                    ▼
    ┌───────────────────┐┌───────────────────┐┌───────────────────┐
    │  WordPress Fleet  ││  Headless Gmail   ││  Notion / Memory  │
    │  REST API (MCP)   ││  Triage Engine    ││  OmniBrain Hub    │
    └───────────────────┘└───────────────────┘└───────────────────┘

    3. Real Production War Story: Managing a 9-Site Fleet

    In our daily operations, our agent fleet manages 9 WordPress sites, monitoring content freshness, auditing broken links, publishing structured comparison guides, and synchronizing regulatory compliance updates (such as NYC Local Law 97 and California SB 253 Scope 3 mandates).

    Here is what happens during a standard automated operational cycle:

    1. Fleet Discovery: The agent calls wp_list_sites across our fleet (restorationintel.com, bcesg.org, tygartmedia.com, etc.).
    2. Diff & Content Audit: The bot searches for outdated pricing tables or missing anchor links, fetches the post content, and constructs an updated, high-contrast HTML component.
    3. Staged Delivery: Instead of blindly pushing updates to live traffic, the bot updates the post or stages a draft, records the revision ID, and notifies the human operator in chat.
    4. Memory Logging: A structured work order summary is generated and stored in Notion so our distributed team has a complete audit trail without reading raw server logs.

    4. The Economics: Why This Stack Beats Traditional SaaS Tools

    Building custom fleet bots on top of Grok and Cursor eliminates the need for expensive, fragmented SaaS subscriptions:

    Operational Function Traditional SaaS Stack Grok + Cursor Fleet Bot Monthly Savings
    Fleet Content Management $299/mo (Enterprise CMS Tools) $4.50/mo (Grok API Tokens) 98.5%
    Email Triage & Archiving $150/mo (Superhuman + SaneBox) $1.20/mo (Grok-3 Mini) 99.2%
    Knowledge Base Maintenance $500/mo (Dedicated Ops Assistant) $3.80/mo (Notion MCP + Grok) 99.2%

    Conclusion: The Future of Autonomous Development

    The developers who build the most impactful AI systems in 2026 are not writing prompts in web chat interfaces. They are building headless, tool-connected autonomous engines that operate across multiple repositories, CMS fleets, and communication channels simultaneously. Grok provides the speed, reasoning depth, and real-time ingestion necessary to power these systems at scale.

    >Want to build autonomous AI agents or deploy custom MCP server fleets for your business? Read our full library of developer playbooks on Tygart Media.

    Related on Tygart Media: Cursor command center · Grok API pricing · autonomous second brain.

  • Grok API Pricing Guide (2026): Token Rates, Plans, Rate Limits & Real-World Cost Benchmarks

    Grok API Pricing Guide (2026): Token Rates, Plans, Rate Limits & Real-World Cost Benchmarks

    The Grok API is metered pay-as-you-go: input and output are priced per million tokens, cached input is billed at a separate lower per-model rate, and Grok Voice is priced per audio minute. Page updated October 2, 2026. The figures below are xAI’s current published rates (docs.x.ai, last updated September 21, 2026).

    Direct answer (page updated October 2, 2026): Grok-4.7 (flagship) is $2.00 input and $6.00 output per 1M tokens, cached input $0.50. Grok-4.6 is $2.00 / $6.00, cached $0.50. Grok-4.5 is $2.00 / $6.00, cached $0.30. Grok-4.3 and the Grok-4.20 family are $1.25 / $2.50, cached $0.20. Grok-build-0.1 is $1.00 / $2.00, cached $0.20. Grok-3 was retired in May 2026 and now redirects to Grok-4.3 — the $3.00 / $15.00 figures this page previously listed are outdated. Grok Voice speech-to-speech is a flat $0.08 per minute plus $0.004 per text input.

    2026 Key Takeaways: Grok API Economics
    • Token rates: Grok-4.7 $2.00 / $6.00 per 1M, Grok-4.5 $2.00 / $6.00, Grok-4.3 and Grok-4.20 $1.25 / $2.50, Grok-build-0.1 $1.00 / $2.00. Cached input runs $0.50, $0.30, $0.20, $0.20 respectively.
    • Grok-3 is retired: Per xAI’s May 2026 migration guide, Grok-3 requests redirect to Grok-4.3. Any page still quoting $3.00 / $15.00 is showing history, not current pricing.
    • Grok Voice API: Speech-to-speech at a flat $0.08/min plus $0.004 per text input — no per-minute input/output split. Speech-to-text $0.10/hr REST ($0.20/hr streaming); text-to-speech $15.00 per 1M characters.
    • Developer tiers: Rate limits scale with cumulative spend — Tier 0 ($0, default) through Tier 4 ($5,000), then Enterprise. No published free tier or new-account credit.
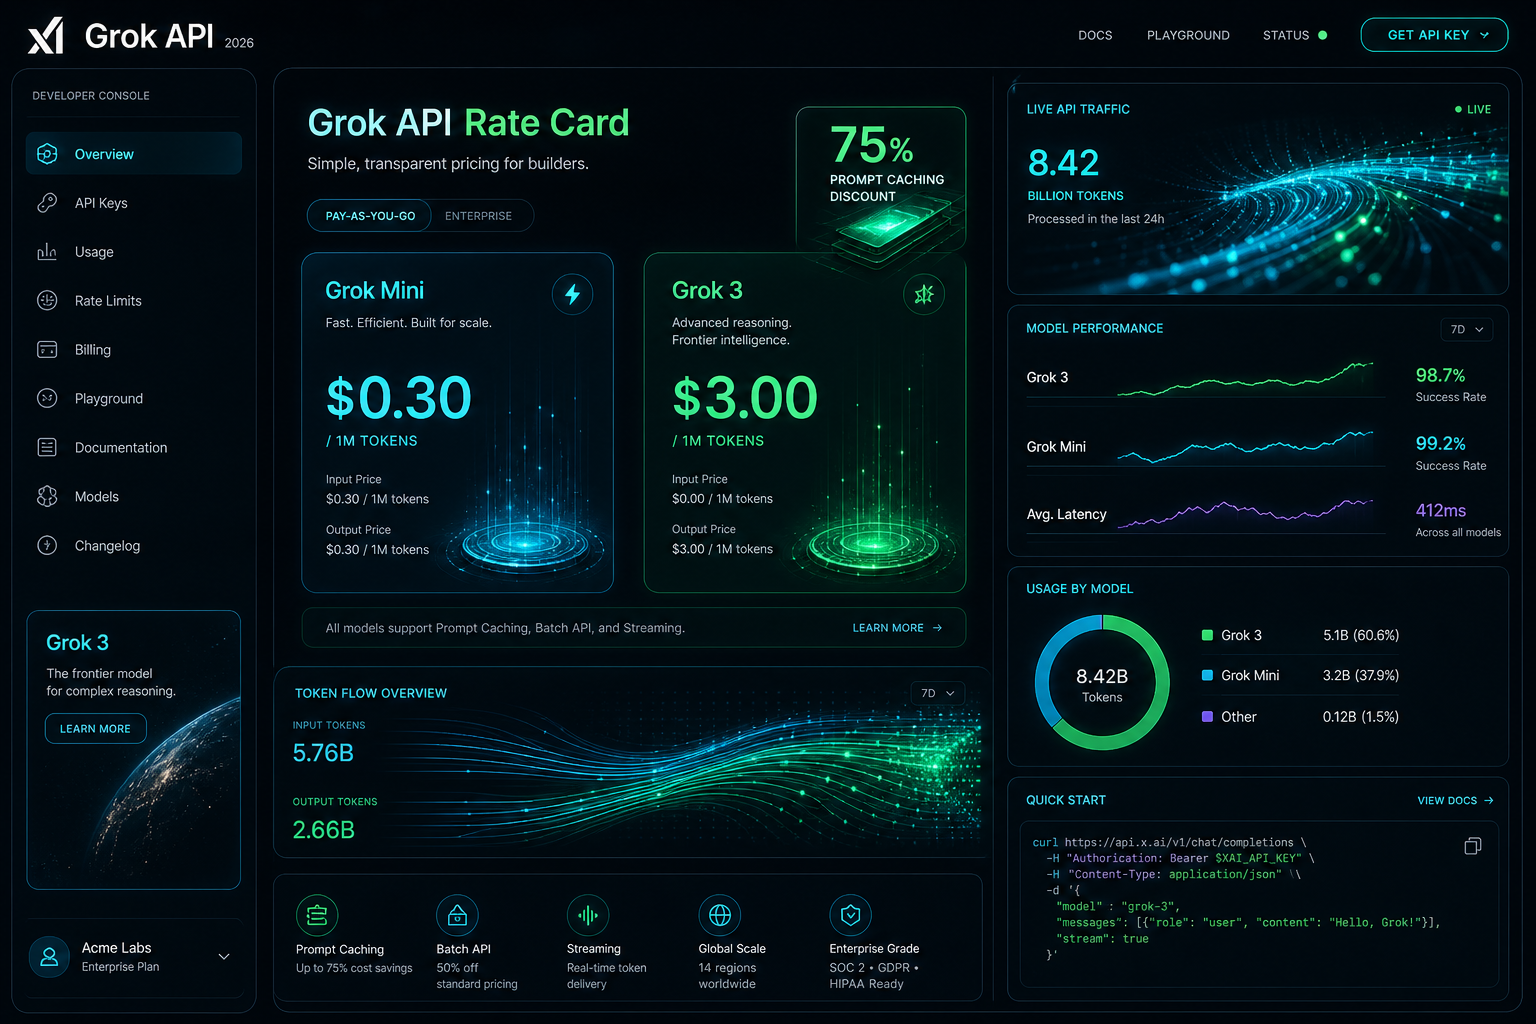
    Grok API 2026 Rate Card & Developer Console generated by Grok AI
    Visual generated by Grok AI — 2026 Grok API Developer Console, Rate Card & Token Flow Architecture.

    Grok API token pricing by model

    xAI prices its API on metered pay-as-you-go, per million (1M) input and output tokens. Long-context requests bill at 2x the short-context rates shown here. Current published rates:

    Model Name Input Cost (per 1M) Cached Input (per 1M) Output Cost (per 1M)
    Grok-4.7 (Flagship) $2.00 $0.50 $6.00
    Grok-4.6 $2.00 $0.50 $6.00
    Grok-4.5 $2.00 $0.30 $6.00
    Grok-4.3 $1.25 $0.20 $2.50
    Grok-4.20 family (reasoning / non-reasoning / multi-agent) $1.25 $0.20 $2.50
    Grok-build-0.1 $1.00 $0.20 $2.00
    Grok Voice (speech-to-speech) Flat $0.08 / min + $0.004 per text input N/A (per-minute)

    Context windows per xAI’s model catalog: Grok-4.7 and Grok-4.5 up to 500K tokens, Grok-4.3 up to 1M tokens. Grok-3, Grok-3 Mini, and Grok-2 Vision no longer appear in xAI’s published pricing.

    Grok prompt caching rates

    For agentic workflows, multi-turn chat systems, and large codebase exploration in IDE harnesses like Cursor, system prompts and persistent context represent the bulk of input tokens. Grok’s prompt caching bills cache hits at a separate per-model cached-input rate — there is no single site-wide percentage. Effective discounts run roughly 75-85% depending on model: $0.50 vs $2.00 on Grok-4.7/4.6, $0.30 vs $2.00 on Grok-4.5, $0.20 vs $1.25 on Grok-4.3/4.20, and $0.20 vs $1.00 on Grok-build-0.1.

    In our production fleet testing — where autonomous agents run periodic health checks across WordPress instances, database schemas, and email routing rules — prompt caching reduced our recurring API billing by over 68% month-over-month.

    Grok API rate limits by tier

    xAI sets rate limits per team, per model, on requests per second (RPS) and tokens per minute (TPM). Tiers unlock with cumulative spend:

    • Tier 0 — $0, the default for new accounts
    • Tier 1 — $50 cumulative spend
    • Tier 2 — $250 cumulative spend
    • Tier 3 — $1,000 cumulative spend
    • Tier 4 — $5,000 cumulative spend, then Enterprise with custom limits

    As an example, xAI’s catalog lists Grok-4.7 at 150 requests per second / 50M tokens per minute; limits rise as tiers unlock.

    What the listed Grok rates cost per month

    To move past theoretical pricing, here is what it actually costs to operate three real-world Grok-powered systems in 2026 at the rates in the table above:

    Scenario A: Autonomous Fleet & Content Ops Bot

    • Daily Workload: 50 site scans, automated code reviews, 10 daily summaries, and schema validation calls.
    • Monthly Token Consumption: ~15M input tokens (cached), 2M uncached input, 3.5M output tokens on Grok-4.3.
    • Total Monthly Cost: $14.25 / month.
    • 15M cached x $0.20 + 2M uncached x $1.25 + 3.5M output x $2.50 = $3.00 + $2.50 + $8.75 = $14.25.

    Scenario B: Real-Time Customer Intake & Dispatch Voice Agent

    • Daily Workload: 30 inbound phone calls (avg 3.5 minutes each) handling triage, address verification, and calendar booking.
    • Monthly Minutes: ~3,150 audio minutes.
    • Total Monthly Cost: $252.00 / month in audio charges (vs. $3,200+/month for full-time 24/7 human dispatch).
    • 3,150 minutes x $0.08 = $252.00, plus $0.004 per text input the agent generates.

    Scenario C: Large Multi-Repo Deep Search & Code Synthesis

    • Daily Workload: High-frequency reasoning and code refactoring across 20+ microservices in Cursor.
    • Monthly Token Consumption: 80M input tokens on Grok-4.7 with prompt caching enabled.
    • At the Grok-4.7 rates in the table: all cached, 80 x $0.50 = $40; all uncached, 80 x $2.00 = $160; a 50/50 mix = $100 in input charges, before output tokens.

    How to apply the Grok cache rate

    1. Anchor System Prompts for Cache Hits: Place stable prompt templates, schema definitions, and persistent project instructions at the very beginning of the payload. Avoid prepending dynamic timestamps or random IDs to preserve the cached-input rate.
    2. Model Routing (build-0.1 for Scaffolding, 4.7 for Reasoning): Use lightweight models like Grok-build-0.1 ($1.00/$2.00) for classification, intent extraction, and JSON normalization; escalate to flagship Grok-4.7 only for deep logical synthesis or multi-file architecture plans.
    3. Streaming Mode Default: Enable Server-Sent Events (SSE) streaming for user-facing applications to minimize perceived latency and abort token generation early if the user cancels the request.

    Grok API pricing questions

    How much does the Grok API cost?

    Current published rates: Grok-4.7 is $2.00 input and $6.00 output per 1M tokens, Grok-4.6 the same, Grok-4.5 $2.00 / $6.00, Grok-4.3 and the Grok-4.20 family $1.25 / $2.50, and Grok-build-0.1 $1.00 / $2.00. Cached input is $0.50, $0.50, $0.30, $0.20, and $0.20 respectively. Grok Voice speech-to-speech is a flat $0.08 per minute plus $0.004 per text input.

    Is there a free tier for the Grok API?

    xAI publishes no free tier and no standing new-account credit. Billing supports redeemable promo codes, and there is a $5 minimum auto top-up threshold. Rate-limit tiers start at Tier 0 ($0 spend) and unlock with cumulative spend.

    How much does Grok prompt caching change the input price?

    Cache hits bill at a per-model cached-input rate: $0.50 instead of $2.00 on Grok-4.7/4.6, $0.30 instead of $2.00 on Grok-4.5, $0.20 instead of $1.25 on Grok-4.3/4.20, and $0.20 instead of $1.00 on Grok-build-0.1 — roughly 75-85% below standard input depending on model. xAI publishes no single site-wide discount figure.

    What are the Grok API rate limits?

    Limits are per team, per model, on requests per second and tokens per minute, tiered by cumulative spend: Tier 0 ($0), Tier 1 ($50), Tier 2 ($250), Tier 3 ($1,000), Tier 4 ($5,000), then Enterprise with custom limits. The catalog lists Grok-4.7 at 150 RPS / 50M TPM; limits rise as tiers unlock.

    Conclusion: The Operational Verdict

    At xAI’s current published rates, Grok-4.7 is $2.00 / $6.00 per 1M tokens, Grok-4.5 $2.00 / $6.00, Grok-4.3 and Grok-4.20 $1.25 / $2.50, Grok-build-0.1 $1.00 / $2.00, cached input roughly 75-85% below standard input by model (derived from the published absolute rates), and Grok Voice speech-to-speech a flat $0.08 per minute plus $0.004 per text input. Grok-3 is retired and redirects to Grok-4.3. Page updated October 2, 2026.

    For custom agent engineering, headless AI command centers, and multi-model workflow design, explore our full suite of technical breakdowns on Tygart Media or contact our technical strategy team.

    Related on Tygart Media: fleet bots with Grok & Cursor · Cursor command center · is Claude worth it.

  • IICRC Van Pocket Card

    IICRC Van Pocket Card

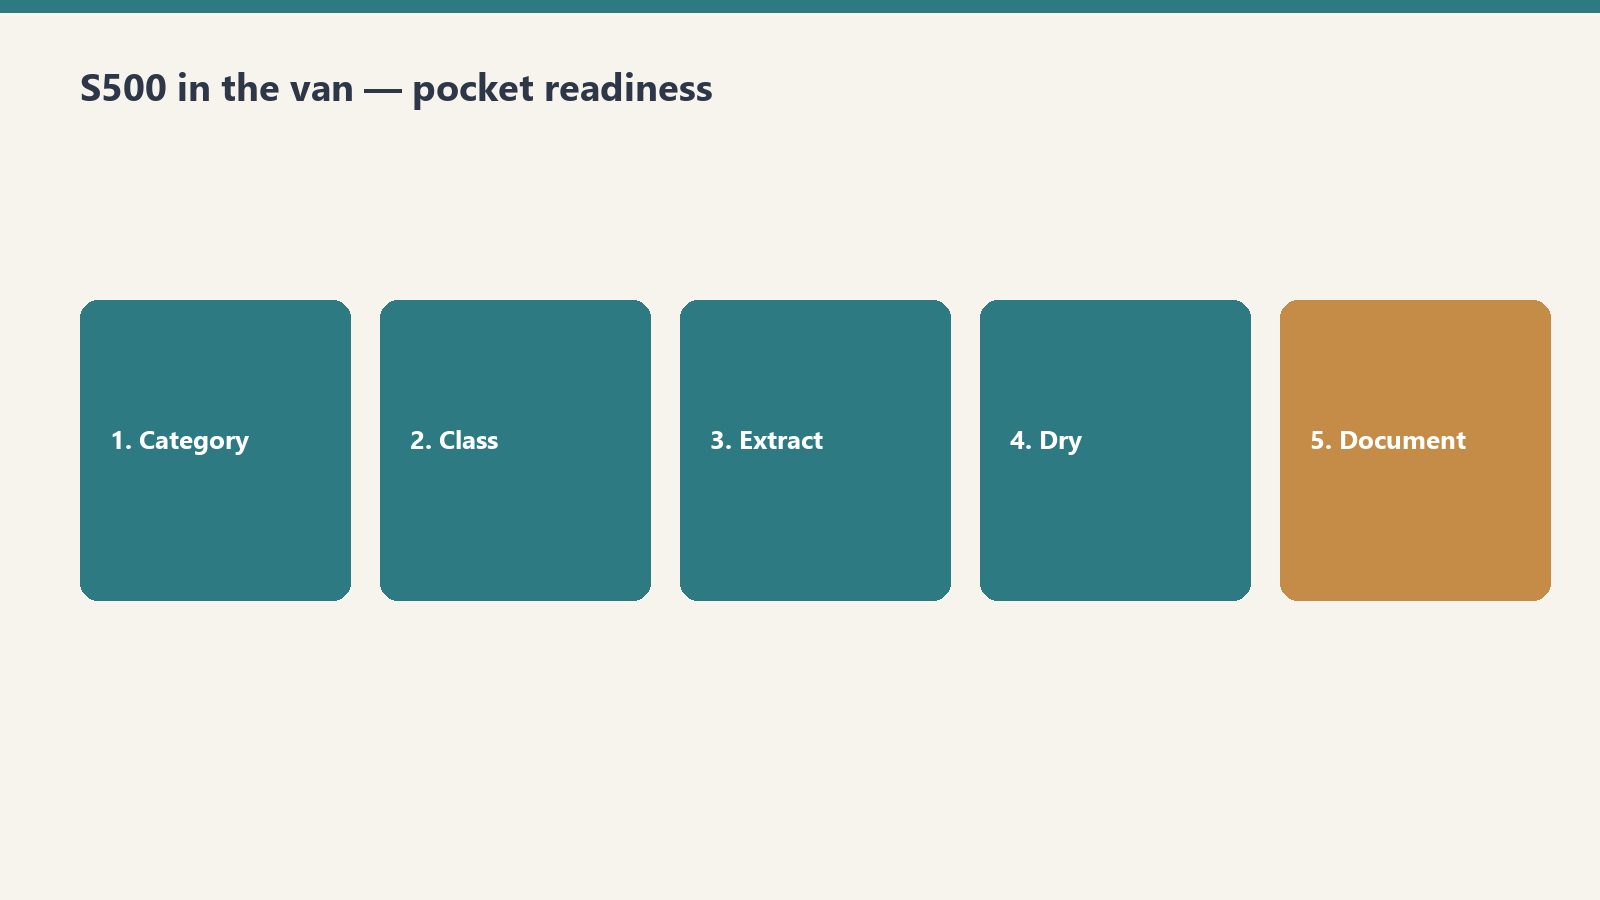
    Tape this in the van. Category, Class, PPE floor, one photo. Twenty seconds. Then go to work.

    This is a free pocket card, not a certification, and not official IICRC. It does not replace S500/S520.

    What you get

    Five-step van pocket flow: category, class, extract, dry, document
    Protocol answers belong in the van — not back at the office.
    • A Notion page you can duplicate and print
    • A tiny Claude skill with the same tables (upload the zip, or paste SKILL.md into a Project)

    How to get it

    Restoration SOP clipboard with checklist, moisture meter, and gloves on a jobsite table
    How to get it: keep the checklist where the carpet is wet.

    Duplicate the card here: IICRC Van Pocket Card (free Notion account, Duplicate in the top right).

    Want the Claude skill zip too? Join The Signal and reply that you want the van card.

    What this is not

    White restoration work van with ladder rack parked at a suburban jobsite curb
    What this is not: another binder collecting dust.
    • Equipment sizing
    • A drying plan
    • Adjuster language

    Need that? The paid IICRC Protocol Lookup ($19) or the Complete Restoration Operations Kit ($97).

    Related on Tygart Media: Starlink on a water job · S500 in the van · local SEO for restoration.

  • Restoration CRM Prompt Library — Claude Skill

    Restoration CRM Prompt Library — Claude Skill

    Restoration CRM Prompt Library — Claude Skill

    $19

    Delivered by email after checkout.

    Buy Now →

    Secure checkout via Square — all major cards accepted

    You can copy this library and do it yourself. The full article is already live. Paste a prompt into claude.ai, fill the brackets, edit the draft, send it. Buy Now is the packaged Claude Skill so the library lives in the project instead of a browser tab.

    The live article (do not treat this page as a replacement): AI-Assisted Email Drafting for Restoration Companies: A Claude Prompt Library.

    Who it is for: anyone at the company who writes emails. Owner, office manager, whoever runs the CRM touch calendar. No technical background. A free Claude account at claude.ai is enough. No API key. No code.

    The workflow

    Four skill cards: scope narrative, insurance write, homeowner write, referral write
    CRM prompt workflow: paste facts → draft → human send.
    1. Go to claude.ai. Create a free account if you need one.
    2. Open a new conversation.
    3. Paste a prompt. Fill the bracketed fields with real information.
    4. Claude drafts the email.
    5. Review it. Edit anything that does not sound like you. Copy it into your email platform.

    That is the entire workflow. Specific beats generic. “Write a hiring email for a restoration company” is weak. “Write a hiring email for a 12-person water and fire restoration company in Tacoma, WA that’s been in business for eight years and is known for fast response times and honest communication with insurance adjusters” is usable.

    Strategy lives in Your CRM Is Not a Lead Database. Timing lives in The 12-Month Outreach Calendar. This library is the words.

    Prompt 1: Hiring email, homeowner version

    I run [company name], a [type] restoration company in [city, state]. We’ve been in business [X] years and are known for [one or two specific things your company does well]. We currently have [number] employees and serve the [geographic area] area.
    
    I need to write a short, plain-text email to past homeowner clients who we’ve done [water damage / fire damage / mold / storm] work for. We’re currently hiring for [job title]. The goal of the email is to ask if they know anyone — family, friends, people in the trades — who might be a great fit for a company like ours. We want to reach out to trusted contacts before posting the job publicly.
    
    Tone: Personal and warm, like a note from a real person. Not corporate, not salesy. The recipient should feel like we remembered them and value their opinion specifically.
    
    Requirements: Under 150 words. Plain text (no HTML). Sign it from [owner first name] at [company name]. Include a phone number as the only contact info. No subject line needed — just the body.

    Prompt 2: Hiring email, insurance adjuster version

    Clipboard and tablet on a kitchen counter during an insurance adjuster walkthrough after water loss
    Hiring email for adjusters — clear, dated, professional.
    I run [company name], a restoration company in [city, state]. I need to write a short email to insurance adjusters I’ve worked with on claims. We’re hiring a [job title].
    
    The tone should be collegial — peer to peer, professional but not formal. We want to reach out to trusted colleagues before posting publicly, and we’d appreciate any recommendations they might have. Keep it under 120 words. Plain text. From [owner name]. Include phone number.
    
    Do not use any of these phrases: “I hope this email finds you well,” “I wanted to reach out,” “touch base,” “circle back,” or “leverage.” Write it how a real contractor would talk to an adjuster they’ve worked with for years.

    Prompt 3: Vendor ask (specialty sub search)

    Write a short email from a restoration company owner to their contact database asking if anyone knows a reliable [trade type — e.g., drywall sub, flooring contractor, HVAC tech] in [city/region]. We have a larger project coming up and want to find a quality sub through our network before going the cold-search route.
    
    Context about our company: [2–3 sentences about your company — size, how long you’ve been in business, your service area]. The recipients are a mix of past homeowner clients, insurance industry contacts, and trade partners.
    
    Tone: Casual and direct. Like asking a trusted colleague. Under 100 words. Plain text. From [owner name]. Phone number only.
    
    Optional addition: Add one sentence at the end that invites the recipient to reach out directly if the description matches their own business.

    Prompt 4: Seasonal safety email (winter freeze)

    I run a water damage restoration company in [city, state]. I want to send a helpful, non-promotional email to past homeowner clients before freeze season. The goal is to give them genuinely useful information about preventing the kind of water damage we see most commonly in [our region] in winter.
    
    Specific things to cover: [list 3–4 real things relevant to your region]. These should be specific to [region] winters, not generic national advice.
    
    Tone: Knowledgeable and helpful, like a trusted expert checking in on a neighbor. No sales pitch, no CTA other than “if you have questions, we’re here.” Under 200 words. Include a link placeholder for [blog post URL] if they want to read more. From [owner name].

    The rest of the library (on the live article)

    Prompts 5–9 are on the live page. Use that URL. Do not treat this SKU page as a rewrite of that article.

    • Prompt 5: Post-storm check-in to past homeowners. Warm, community-focused, not a pitch. Under 120 words.
    • Prompt 6: Company anniversary or milestone. Thank the people who have been part of the journey. No CTA. No offer. Under 175 words.
    • Prompt 7: Brand-voice rewrite. Paste two real emails you have sent, then the draft, and ask Claude to make it sound like you.
    • Prompt 8: Eight subject-line options. Personal, no click-bait, no exclamation points, no “Quick question for you!”
    • Prompt 9: Batch personalization. CSV of past clients. One opening sentence per row that references job type and, if the job is older than 18 months, that it has been a while. Up to 20 rows at a time.

    Full text: tygartmedia.com/restoration-crm-claude-prompt-library.

    How to get better drafts

    Restoration SOP clipboard with checklist, moisture meter, and gloves on a jobsite table
    Better drafts still need a human check before send.
    • Name the phrases you do not want: “I hope this finds you well,” “reaching out,” “touch base,” “leverage.”
    • Give two sentences of real company context. History, reputation, service area, typical client.
    • Iterate in the same conversation. “Good, but make it shorter.” Do not start a new chat for every revision.
    • Ask for three versions: shorter, more formal, more casual.
    • Review everything before it sends. Claude will sometimes assume details you did not provide.

    A free claude.ai account is enough for a full annual campaign calendar. Claude Pro is not required for this use case. Store the filled-in prompts in Notion so you are not hunting them before each send. Using AI to draft is fine if you review and approve every email. The relationship still has to be yours.

    If you want the packaged skill

    The method and the live article are free to use. Buy Now is the Claude Skill package, delivered by email after checkout, so the library is installed instead of copy-pasted from the article each time. Same Square button at the top of this page.

    Related: Front door: Complete Restoration Operations Kit ($97). Stack: The Restoration.

    Related on Tygart Media: Starlink on a water job · S500 in the van · local SEO for restoration.

  • AI for Water Damage Restoration — 4 Claude Skills

    AI for Water Damage Restoration — 4 Claude Skills

    Direct Answer / Product Definition

    AI for Water Damage Restoration — 4 Claude Skills by Tygart Media is a $29 Square digital product that packages four Claude Project skills for emergency water losses: first-hour homeowner texts, IICRC S500-aware adjuster summaries, contents and rebuild letters, and plumber or property-manager outreach. Will Tygart built the prompts for Category and Class accuracy; Tygart Media delivers the install zip by email within 24 hours of checkout, or contractors can copy the instructions free on this page.

    AI for Water Damage Restoration — 4 Claude Skills

    $29

    Packaged zip delivered by email within 24 hours after Square checkout.

    Buy on Square — $29 →

    Secure checkout via Square — all major cards accepted

    Tygart Media publishes the full skill text below so water-damage contractors can copy each block into Claude Project Instructions before the next 2 a.m. call. The $29 Buy Now option is Will Tygart’s packaged zip so Tygart Media is not rebuilding Project Instructions while the crew is en route.

    Water damage restoration is a 24/7 business. The company that communicates fastest and clearest wins the job. Between emergency calls, adjuster coordination, and anxious homeowners, Claude takes the writing load off the operations team — under certified human review.

    DIY Copy vs $29 Packaged Zip

    Option Price Water-Loss Focus Best For
    Copy from this page $0 Four skills in HTML; manual paste Testing one emergency template tonight
    Water 4 Claude Skills (this product) $29 Emergency, adjuster, contents, referral 24/7 dispatch and PM teams
    General 4 Claude Skills $29 Scope narratives + broad insurance letters Multi-loss shops (fire, mold, water)
    Operations Kit — Claude Edition $197 8 skills + equipment sizing + KPI coach Full operational AI copilot

    How to use this

    Four skill cards covering emergency, adjuster, contents, and referral communication
    Four water-job skills. Paste facts. Review. Send.
    • Claude Skills go into Claude Project Instructions.
    • Prompts work in any Claude conversation.
    • Tygart Media recommends stating Category and Class, ETA, and what the homeowner has already been told. Vague input makes vague output.

    Create a Claude Project. Paste the skill. Answer what it asks. Review every text and letter before it sends. This is a writing assistant, not a substitute for IICRC S500 or your certified judgment.

    Skill 1: Emergency Response and Homeowner Communication Writer

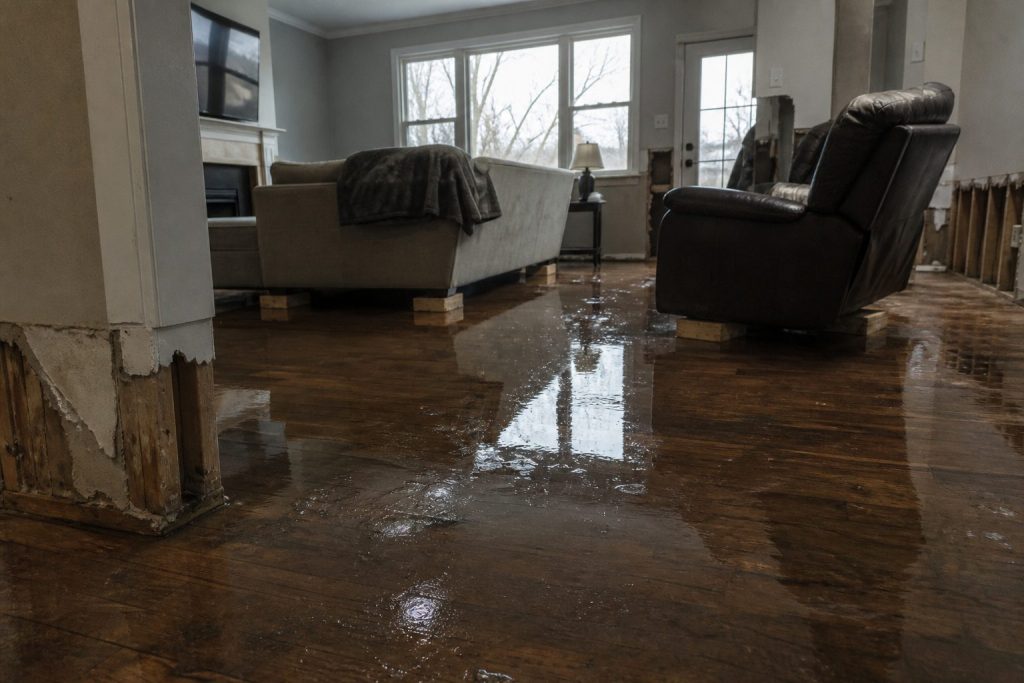
    Flooded residential living room with standing water on hardwood after a water loss
    Emergency response copy should match the room you walked into.

    Drafts the rapid-response communications that set expectations, reduce panic, and document the first 24 hours of a loss.

    Paste into Claude Project Instructions:

    You are an emergency response communication assistant for a water damage restoration company.
    
    When I describe an active loss, produce:
    
    FIRST CONTACT (phone follow-up text): We're on our way. ETA, who's coming, what to do right now. Under 100 words. Fast and reassuring.
    
    ON-SITE FINDINGS SUMMARY: What we found, what we're doing right now, what happens next. Plain English. Under 150 words. Send within the first hour.
    
    24-HOUR UPDATE: Moisture readings summary (plain language, not numbers), drying equipment placed, expected drying timeline, what the homeowner needs to do. Under 175 words.
    
    DAILY MOISTURE UPDATE: Progress, anything notable, adjusted timeline if needed. Under 100 words.
    
    EQUIPMENT REMOVAL NOTICE: Drying is complete. What was achieved. What happens next (demo, rebuild, clearance). Under 100 words.
    
    Tone: fast, expert, calm. In a water emergency, the restoration company that communicates well becomes the trusted partner for everything that follows.

    Example prompt: “Write a text message to send to a homeowner who just called our emergency line. We’re dispatching a crew. ETA is [X] hours. What they should do right now to minimize damage. Under 120 characters if possible.”

    Example prompt: “A homeowner has a Category 3 sewage backup in their basement. Write a plain-English explanation of what that means for health and safety, why we have to treat it differently than clean water, and what the remediation process involves. Honest without being terrifying. Under 175 words.”

    Skill 2: Insurance Adjuster Communication Writer

    Clipboard and tablet on a kitchen counter during an insurance adjuster walkthrough after water loss
    Adjuster notes: dated, specific, easy to forward.

    Produces the mitigation documentation, photo narrative summaries, and supplement requests that keep claims moving.

    Paste into Claude Project Instructions:

    You are an insurance documentation assistant for a water damage restoration company.
    
    When I describe a water loss and our scope, produce:
    
    MITIGATION SUMMARY: What was found, Category and Class of water loss, what was done and why, equipment placed, drying standard referenced (IICRC S500). Technical but clear. Under 300 words.
    
    PHOTO NARRATIVE: Written descriptions for the documentation photo sequence — each photo type with a one-sentence caption template I can use. Organized by area.
    
    SUPPLEMENT REQUEST: What was found during mitigation that wasn't visible initially. Itemized, with rationale. Professional and factual.
    
    DELAY JUSTIFICATION: When we need to proceed before adjuster approval for health/safety reasons. Documented, professional, covers our position.
    
    ADJUSTER FOLLOW-UP: Professional check-in when we haven't heard back. States what we're waiting on and impact on the homeowner.
    
    Always: factual, documented, professional. Supplement disputes are resolved through evidence.

    Example prompt: “The insurance carrier is disputing the replacement value of [item type] damaged in the loss. Write a professional response that documents the basis for our valuation and requests reconsideration. Factual, not emotional. Under 150 words.”

    Skill 3: Contents and Rebuild Communication Writer

    Handles pack-out, demo scope, rebuild timeline, and walkthrough communications after the drying phase.

    Paste into Claude Project Instructions:

    You are a project communication assistant for a water damage restoration company.
    
    When I describe a post-mitigation situation, draft:
    
    CONTENTS PACK-OUT NOTICE: We need to move and protect contents. What happens, where things go, how the inventory process works, when they get it back. Reassuring and specific. Under 150 words.
    
    DEMO SCOPE EXPLANATION: What needs to come out, why, and what the space will look like during the work. Plain English. Under 150 words.
    
    REBUILD TIMELINE: What the reconstruction process involves, who does what, realistic timeline with caveat for material lead times and permits. Under 200 words.
    
    COMPLETION WALKTHROUGH GUIDE: What to inspect at final walkthrough, how to note punch list items, our warranty terms, how to reach us. Professional close.
    
    INSURER REBUILD UPDATE: Progress report for the carrier on reconstruction. Factual, organized by trade, with current completion percentage.
    
    Ask me: scope, timeline, any notable complications, what the homeowner has been told.

    Give it the real scope and what the homeowner has already heard. Do not let it invent a timeline Tygart Media cannot keep on the job.

    Skill 4: Referral Network and Emergency Preparedness Content

    Drafts plumber, roofer, and property manager outreach, plus the educational notes that put you first in the phone when water hits.

    Paste into Claude Project Instructions:

    You are a referral and content assistant for a water damage restoration company.
    
    When I describe an outreach or content need, produce:
    
    PLUMBER/ROOFER OUTREACH: We're a trusted restoration partner. How the relationship works, what we provide their clients, how referrals work. Peer-to-peer. Under 100 words.
    
    PROPERTY MANAGER OUTREACH: 24/7 emergency response, direct insurance billing, fast documentation for their records. What makes us the right call at 2am. Under 100 words.
    
    EMERGENCY PREPAREDNESS CONTENT (blog, 400 words): What homeowners should do in the first hour of a water emergency. Step by step. Practical. Ends with when to call a professional.
    
    STORM RESPONSE POST: After a weather event. What to watch for. When to call. Urgent but not alarmist. Under 100 words. Timely.
    
    Ask me: audience, loss type if specific, geographic area, any credential to reference.

    Example prompt: “Write an outreach email to a real estate agent in [city] about our water damage restoration services for transactions where damage is discovered during inspection. Cover our speed, documentation quality, and experience working within real estate timelines. Under 120 words.”

    Optional: Books for Bots

    Upload to a Claude Project if Tygart Media’s recommended references are written:

    • Company Context Sheet: name, service area, certifications (IICRC WRT, ASD, FSRT), equipment inventory, communication approach.
    • Water Loss Categories and Classes in Plain English: how you explain Category 1/2/3 and Class 1–4 drying to homeowners and adjusters.
    • Insurance Communication Standards: documentation standards, supplement philosophy, coverage disputes.

    If you want the packaged files

    The four skills are on this page. Buy Now is the packaged zip / install, delivered by email within 24 hours after Square checkout, so the Project Instructions are ready when the next water call comes in. Same Square button at the top of this page.

    Frequently Asked Questions

    What is AI for Water Damage Restoration — 4 Claude Skills?

    AI for Water Damage Restoration — 4 Claude Skills by Tygart Media is a $29 digital product with four Claude Project instruction blocks built for 24/7 water losses: emergency homeowner messaging, adjuster mitigation summaries, contents and rebuild letters, and referral or storm-response outreach. Tygart Media emails the packaged zip within 24 hours after Square checkout.

    Does this replace IICRC S500 judgment?

    No. Tygart Media positions these skills as a writing assistant only. Every draft must be reviewed by a certified restorer before it is sent. Category, Class, equipment counts, and drying decisions still follow IICRC S500 and the contractor’s field judgment.

    How is this different from the general restoration 4-skill pack?

    This water-focused pack ($29) targets emergency texts, mitigation photo narratives, pack-out letters, and storm referral content. The general AI for Restoration Contractors — 4 Claude Skills ($29) covers scope narratives and broad insurance correspondence. The Restoration Operations Kit — Claude Edition ($197) adds eight operational skills including equipment sizing and KPI coaching.

    What is included in the $29 Square purchase?

    The $29 checkout includes a formatted zip of all four water-damage Claude skills ready to paste into Project Instructions, plus email delivery from Tygart Media within 24 hours. The full skill text also remains free to copy from this page.

    Is there a refund policy?

    Because this is a digital product, all sales are final. If you have a problem with your purchase, email will@tygartmedia.com and we will sort it out.

    How is this delivered?

    Within 24 hours of purchase via email from will@tygartmedia.com. You will receive your download link — Notion duplicate link, skill file, or both depending on the product.

    $29

    Packaged zip delivered by email within 24 hours via Square.

    Buy on Square — $29 →

    Related Operations & Systems

    Companion Systems: Complete Restoration Operations Kit ($97) · General 4 Claude Skills ($29) · Operations Kit — Claude Edition ($197) · Tygart Media Shop.

    Related on Tygart Media: Starlink on a water job · S500 in the van · local SEO for restoration.

    Author: Will Tygart, Founder of Tygart Media — AI operating systems designed specifically for property restoration contractors.