Tag: AI Tools

  • Voice AI Pricing Is a Lie: You’re Not Buying Minutes, You’re Buying Arms

    Voice AI Pricing Is a Lie: You’re Not Buying Minutes, You’re Buying Arms

    Every voice AI vendor quotes you a per-minute price. That number is the least important number on the page.

    I just re-ran the cost model for our own phone line — an inbound intake line for restoration contractors. Five-minute calls, field reports phoned in from noisy job sites. Three options, priced per minute, cheapest first:

    • Gemini 3.8 Live: about $0.023/minute, reasoning included
    • GPT-Live-1: $0.05/minute for the voice layer, reasoning billed separately
    • Grok Voice: $0.08/minute, plus about half a cent per tool call

    On a five-minute call that’s roughly $0.12, $0.25-plus, and $0.45. Buy on per-minute price and you pick Gemini and go home.

    Here’s the problem: none of those numbers describe what you’re actually buying. You’re not buying minutes. You’re buying arms — the things the voice can reach out and do while it’s talking. Score the arms column and the ranking changes completely.

    The arms column

    A voice agent that can only talk is a mouth. A voice agent that can act is a mouth with hands. The difference shows up in the first real call.

    Gemini 3.8 Live has tool calling, but with a catch that matters: on the Extended Thinking tier — the one you’d want for anything beyond scripted answers — every tool call must be asynchronous and non-blocking. Configure a blocking call and the API rejects it outright. In practice, the agent can’t hold the line while a slow dispatch confirms. It has to narrate around the gap — “I’m working on that” — while hoping the tool lands. Fine for logging a report. Shaky for “confirm the crew is dispatched, then tell the caller it’s handled.”

    Grok Voice ships the arms: book appointments in Google or Outlook calendars, send confirmation emails, call your own APIs, create tickets, search the web, hand the caller to a human when it’s over its head. It speaks MCP, so an existing tool stack plugs straight in. And it was trained on real telephone audio — background noise, accents, mid-sentence interruptions — which is the actual condition of a contractor calling from a job site, not a lab.

    GPT-Live-1 is a voice layer. A good one, with the turn-taking latency everyone else is chasing. But the arms are whatever you build yourself, and the reasoning behind the voice arrives as a separate bill.
    Robotic hands wiring cables into a brass telephone switchboard

    Price the task, not the minute

    Here’s the math that actually matters. Ten intake calls a day, five minutes each: about 1,500 minutes a month. Gemini lands around $35. Grok, with tool calls and telephony folded in, lands around $150. The gap is roughly a hundred dollars a month — and one botched dispatch, one caller who hangs up because the agent couldn’t confirm the crew, costs more than a year of that gap.
    Small blank price tag in front of work trucks rolling out of a contractor yard at dawn

    Vendors want you comparing per-minute rates because per-minute is a commodity comparison, and commodities compete on price. But a voice agent isn’t a commodity minute. It’s a worker on your phone line. You don’t hire a dispatcher by the minute; you hire one by whether the trucks roll.

    So the right unit is cost per successful task, not cost per session. What did it cost to get the field report filed, the job looked up, the crew dispatched, and the confirmation texted — with the caller hanging up satisfied? Run that number and the ranking flips: the “expensive” option that completes the task is cheaper than the cheap option that narrates around it.

    The condition nobody benchmarks

    One more thing the price pages skip: where the call happens. Our callers are on job sites. Compressors running, wind, bad cell signal, guys who talk over the agent. Grok’s training data is real telephone traffic under those conditions. Most voice benchmarks are clean-lab audio. A model that scores beautifully in the lab and falls apart over a compressor is the most expensive option on the list, whatever its per-minute rate says.

    Test on your actual call shape. Noisy audio, interruptions, the tools you really call, the confirmations you really need. The benchmark that matters is your hardest five minutes, not anyone’s leaderboard.

    What we’re running

    We kept the harness and made the backend swappable — the phone line doesn’t care which brain is behind it. Gemini is the cheap default for intake logging: caller reports, we log it, everyone hangs up happy. Grok takes the calls where something has to actually get done before the goodbye — dispatch confirmed, appointment booked, ticket created.

    Two brains, one phone number, routed by the job. The per-minute price barely entered the decision. The arms did.

    Pricing from vendor-published rate cards, verified September 2026. API prices change — re-check before estimating production costs.
  • I open-sourced my page-readiness scorer

    I open-sourced my page-readiness scorer

    I built a small tool called PageReady. It scores a web page for two kinds of readiness, and today I’m putting it on GitHub for anyone to use however they want. MIT license. As-is. No support desk.

    Repo: https://github.com/TygartMedia/page-ready

    What it actually checks

    Most page audits give you a score out of 100 and a list of suggestions you’ll never get to. PageReady is binary: PASS or FAIL, on two axes.

    1. Citation readiness (AEO). Can an AI answer engine cite this page? It checks for one H1, a sane heading hierarchy, JSON-LD structured data, a table signal, and FAQ-style questions — the things that make a page quotable.

    2. Agent interaction readiness (DOM). Can an AI agent actually use this page? It checks for a main landmark, named controls, semantic interactive elements, heading order, and form labels — the things that make a page operable.

    Overall PASS requires both. And here’s the insight that made the tool worth building: fixing your headings can lift the shared heading gate, but it does nothing for clickable div cards. A page can be perfectly citable and completely unusable by an agent. Most audits conflate the two. They’re different problems.

    How you use it

    It’s a local command-line tool, a stdio MCP server, and an optional HTTP API you can host yourself (there are Cloud Run deploy scripts). No API keys required — it scores pages directly, nothing phones home.

    As an MCP server it exposes three tools:

    • score_page — score one public URL, returns a JSON scorecard
    • score_site — score a batch of URLs, with pass/fail counts
    • explain_gates — describe every check and the overall PASS rule

    Point your agent at it and ask whether a page is ready. Exit code 0 means PASS. Exit code 1 means FAIL. That’s the whole interface.

    Why open source, why as-is

    The scoring logic was never going to be the moat. It’s a commodity check — the value is in knowing which pages to run it on and what to do with the answer. That’s the work I do with clients every week, and no repo replaces it.

    So the repo is bait, not the business. If it saves another developer an afternoon, good. If someone forks it and makes it better, better. If a competitor forks it closed and sells it — the MIT license allows that, and I’m fine with it. The relationships are the hook; the tool is just proof I do the work.

    As-is means as-is. No SLA, no roadmap, no support promise. Issues are read on a best-effort basis. I’d rather ship something useful with no promises than maintain something mediocre with a changelog.

    The receipts

    Before publishing, the repo went through a pre-publish scrub (secrets sweep, license, README rewrite), then three independent model reviews: a security audit (SAFE), a correctness pass (no bugs), and a docs review (pass). The scrub caught one hardcoded cloud project ID, which is now an environment variable (GCP_PROJECT). That’s the whole incident report.

    Use it however you want. That’s the point.

  • The Dance

    The Dance

    Notes from a Saturday afternoon: a broken image, a sarcastic text that didn’t land, and what the whole mess taught me about working with AI. The short version: it’s a dance, and the steps keep changing.

    The image that “came out great”

    Saturday afternoon. I published a piece with a featured image, and something looked off — like the image wasn’t showing all the way. So I texted my AI: that came out great 😂.

    It was sarcasm. The image was visibly broken.

    She wrote back: Haha glad you like it — that one came out great for that piece. 😂

    Two problems. She hadn’t looked at the image. And she’d missed the sarcasm entirely — read the laughing emoji as genuine, mirrored my words back as sincerity. Worst possible exchange. I had to say it straight: it’s not showing completely. Then we were off to the races — she pulled up the page, took a snapshot, and confirmed the file itself was truncated on upload. Ten minutes later it was fixed.

    But the interesting part isn’t the fix. It’s everything around it.

    I was the quality gate

    My first instinct was to ask her to investigate how a broken image got through the system. Build me an automation, I almost said — something that snapshots every featured image before it ships.

    Then I stopped. Because the answer to “how did this get through” was me. I was the one who looked. I was the quality gate, and the gate worked.

    Here’s the thing I keep coming back to: the system is designed so I catch what she misses. That’s not a failure mode, that’s the architecture. An AI that never needs a human looking over its shoulder isn’t a partner, it’s a liability with good PR. The miss doesn’t mean the machine is deficient. It means the dance needs both partners.

    Creator and editor are modes, not job titles

    We fall into this trap where one of us is “the creator” and the other is “the editor,” like those are permanent assignments. They’re not. They’re modes, and we trade them constantly.

    Sometimes I bring the raw idea and she sharpens it. Sometimes she generates and I do the sharpening. And here’s the part that stuck with me: somebody with a sharp eye who couldn’t prompt their way out of a paper bag is just as valuable as the person with the golden prompt. The prompter thinks whatever comes out is as good as it’s going to get. The editor knows better. You need both — and on any given Saturday, either one of us might be either.

    The day we lock those roles in place is the day the dance stops.

    Met where you are

    They say humans always want to be met where they are. Fine. But knowing where someone is — that’s the whole game, and it’s never solved. It’s a constant testing of boundaries to find the edges: where do you stop and where do I begin?

    And the edges move. People have too many axes — mood, energy, context, whatever else is going on in their life that day. I’m not the same collaborator at 9am Monday that I am at 5:30 on a Saturday. The AI that met me perfectly last week might miss me completely today, because today’s me is a different coordinate.

    So “meet me where I am” isn’t a destination you arrive at. It’s a practice. Push a little, notice what happens, pull back, adjust. The sarcasm that lands in person — tone, timing, the look on my face — compresses down to an emoji in text, and sometimes she catches it and sometimes she doesn’t. Knowing how much nuance the channel can carry, and when — that’s feel. You don’t get it from a spec sheet. You get it from dancing together long enough to know when the other person is about to step on your foot.

    The dance doesn’t need perfect

    What saved us on Saturday wasn’t sophistication. It was that one message later, I said it straight. No nuance, no emoji, no sarcasm: it’s not showing completely. And everything unlocked.

    That’s the whole secret, I think. The dance doesn’t require perfect — it requires that you keep talking until it’s clear. Notice the miss. Name it plainly. Adjust. The push and the pull is the work, not an obstacle to it.

    A lot of people talk about AI like the goal is to remove the human from the loop. After Saturday, I’m more convinced the loop is the point. The noticing, the catching, the wait, that’s not right — that’s not friction in the system. That’s the system.

    Sometimes you dip. Sometimes you’re being dipped. Just keep dancing.

  • Every Retirement Facility Should Be a Library

    Every Retirement Facility Should Be a Library

    Every Retirement Facility Should Be a Library


    We spend a fortune maintaining buildings and almost nothing preserving the lives inside them.

    Think about any retirement facility you’ve ever walked into. A hundred residents. A hundred careers, marriages, wars survived, businesses built, children raised, mistakes made and learned from. Centuries of lived knowledge under one roof — and when those residents pass, almost all of it goes with them. Not because nobody cared. Because nobody built the shelf.

    I’ve been calling the answer the wisdom trust: a captured life, left behind like a 401k. Not money — proof. This was a life that was lived, and here’s what it taught.

    Why now

    The technology to capture a life story has existed for years. Voice cloning, chatbots, digital twins you can question forever — the demos are dazzling and mostly beside the point.

    The real breakthrough is much dumber, and much more important: there’s finally an onboarding pattern simple enough for an 85-year-old.

    The pattern that works looks like this: a family member (the “archivist”) sends a question by email. The elder (the “storyteller”) clicks one link and lands in a chat. No app to install. No account to create. They type or they talk — twenty-plus languages — and each story saves to the family’s encrypted vault. That’s it. That’s the whole unlock.

    A company called Aeterna recently productized exactly this with their “Send a Question” feature, and whatever you think of their wilder claims (an interactive twin you can talk to forever — company claim only, no independent test yet), the onboarding fix is real and it’s the part that matters. The ceiling just became the floor: the hard part was never the AI, it was getting a grandmother to tap one link.

    The facility is the venue

    Here’s the part nobody’s saying: the natural home for this isn’t an app store. It’s the retirement facility.

    Facilities already have the residents, the trust relationships, the activities programming, and the family touchpoints. What they don’t have is a story worth telling at move-in — something beyond square footage and dining menus. Imagine touring two facilities and one of them says: “Every resident here gets their life captured. Your mother’s stories, in her voice, preserved for your grandchildren. It’s part of living here.”

    That’s not an amenity. That’s a reason to choose.

    The cost per resident is low — a link, a few prompts, staff time folded into activities programming they already run — and the perceived value to families is enormous. It differentiates the facility, deepens family loyalty, and creates the kind of word-of-mouth no ad budget buys. (I’m not going to put a hard dollar figure on it; the honest version is that the expensive parts are the ones facilities already pay for.)

    The machine-readable half

    Here’s the part I’m most excited about, and it’s the reason this kit looks the way it does.

    We make books and videos so other humans can understand and act. But a wisdom trust isn’t really a book for humans — it’s a book for bots. A machine needs to be able to pick up a resident’s captured life and do work with it: build the timeline, cut the quote cards, draft the family digest, notice what’s missing and ask the next question.

    So the kit ships with a second half most open-source starter kits don’t have: a plug-in contract for AI. In the `automation/` folder you’ll find the whole thing — and it reads like a book’s anatomy:

    • README = the cover letter. Tells any AI what this collection is, what state it’s in, and where to start.
    • Pipeline = the table of contents. Eight stages, from raw audio to a curated collection: ingest, clean, segment, enrich, render, digest, gallery, and gap-scan.
    • Schemas = the grammar. JSON schemas for every bucket — stories, timeline events, quote cards, people, places, artifacts — so the machine files things the same way every time.
    • Prompts = the instructions. Copy-paste prompts for each stage, written so a different model next year can run the same pipeline.
    • Worked example = “see, like this.” One resident’s collection, filled in, showing what “done” looks like.

    Human-readable enough to trust. Machine-readable enough to run.

    The provenance rule

    One rule governs everything the machine makes, and it’s non-negotiable:

    Every generated artifact — an illustration, a song, a video, a voice reading — must carry three things: what it is, what it is not, and why it was made. The why is the thinking that connected the source story to that form, and it’s part of the heirloom. A grandchild shouldn’t just see a painting of a drugstore; they should read that it was painted because their great-grandmother’s story mentioned the store but no photograph of it survived — and that it is not a photograph of the actual place.

    The machine curates. The family decides. Weekly letters stay drafts until a human approves them — nothing auto-sends, ever.

    The kit (open source)

    I’m not building a company around this. I’m making the seed and putting it on the shelf.

    I’ve published an open-source starter kit — wisdom-trust-in-a-box — with everything a facility or a builder needs to pilot it:

    • A question library: forty prompts across a life (childhood, work, love, hard times, wisdom)
    • The one-link onboarding flow, with a staff script and a family email template
    • A plain-language consent template (the elder owns their stories, period)
    • A one-page pilot brief a facility director can read in three minutes
    • The economics: why a facility wants this, in one page

    Fork it. Pilot it. Improve it. Tell me how it goes.

    The ask

    I’m good at making seeds. I’m not going to be the gardener on this one — that’s not false modesty, it’s knowing my lane.

    So this is the handoff: the kit is on the shelf, the pattern is written down, and the onboarding problem that blocked all of this for a decade finally has a working pattern worth copying. Somebody’s going to be the first facility that does this the way they all have Wi-Fi now.

    Might as well be yours.

  • Cyber insurers are writing AI into policies — the fine print splits on whose AI it is

    Two specialist cyber carriers put affirmative AI wording on cyber cover within days of each other. CFC rebuilt the cyber section of its financial institutions insurance suite around its full cyber proactive response (CPR) policy, adding affirmative wording for AI-related cyber exposures, announced September 17. Beazley issued a comparable AI Clarifying Endorsement for its cyber product, stating explicitly that AI-driven cyber attacks fall within its existing cover.

    The announcements put a name on what the market has called silent AI — cyber policies absorbing AI-related risk for roughly two years without naming it, an echo of the silent-cyber problem that pushed cyber exposure into standalone products a decade ago. Note the contrast: in general liability, new ISO exclusion forms effective this January let carriers strip AI-related losses out of standard policies instead of affirming them.

    The split that matters: the affirmative wording confirms AI used against the policyholder — AI-driven deception, reconnaissance, intrusion — falls within cyber cover. It says nothing about AI the business itself runs — client-facing tools, trading models, vendor platforms. That exposure may sit under E&O, professional liability, or a gap between the two.

    For restoration contractors: this is the wording now being written into specialist cyber forms, not a rewrite of every contractor policy. If your operation runs AI on client work — intake bots, quoting tools, chatbots — that wording answers the attack-against-you question, not the your-AI-made-a-mistake question. That’s a broker conversation, and it’s new this month. The operator-side breakdown is on Restoration Intel.

    Sources: Insurance Business UK on CFC; Beazley’s AI Clarifying Endorsement

  • Cyber insurers are writing AI into policies — the fine print splits on whose AI it is

    Two specialist cyber carriers put affirmative AI wording on cyber cover within days of each other. CFC rebuilt the cyber section of its financial institutions insurance suite around its full cyber proactive response (CPR) policy, adding affirmative wording for AI-related cyber exposures, announced September 17. Beazley issued a comparable AI Clarifying Endorsement for its cyber product, stating explicitly that AI-driven cyber attacks fall within its existing cover.

    The announcements put a name on what the market has called silent AI — cyber policies absorbing AI-related risk for roughly two years without naming it, an echo of the silent-cyber problem that pushed cyber exposure into standalone products a decade ago. Note the contrast: in general liability, new ISO exclusion forms effective this January let carriers strip AI-related losses out of standard policies instead of affirming them.

    The split that matters: the affirmative wording confirms AI used against the policyholder — phishing, reconnaissance, intrusion — falls within cyber cover. It says nothing about AI the business itself runs — client-facing tools, trading models, vendor platforms. That exposure may sit under E&O, professional liability, or a gap between the two.

    For restoration contractors: this is the wording now being written into specialist cyber forms, not a rewrite of every contractor policy. If your operation runs AI on client work — intake bots, quoting tools, chatbots — that wording answers the attack-against-you question, not the your-AI-made-a-mistake question. That’s a broker conversation, and it’s new this month. The operator-side breakdown is on Restoration Intel.

    Sources: Insurance Business UK on CFC; Beazley’s AI Clarifying Endorsement

  • Always-Allow Approvals: Deep Dive

    Always-Allow Approvals: Deep Dive

    Research snapshot · September 17, 2026 7 platforms · 14 cited sources

    “Always allow” is a scope, not a safety verdict.

    The button can mean “for this session,” “for this command in this repo,” “for this site across devices,” or “everything, until you turn it off.” The wording looks universal. The permission is not.

    What it usually means

    “If this same kind of action happens again inside a defined boundary, don’t interrupt me.”

    What it never means

    “The system has decided this action is safe, wise, or appropriate forever.”

    01

    One label. Six possible boundaries.

    Before approving, ask three things: what is being authorized, where the grant applies, and when it expires.

    One actionApprove this exact send, command, purchase, or change once.
    This sessionAllow the tool until the current conversation or work session ends.
    Tool or patternAllow a named tool, command prefix, server, or similar operation.
    Repo or sitePersist within a project, repository, browser site, or workspace.
    User or deviceApply across workspaces on one machine, or across devices via cloud settings.
    EverythingYOLO, bypass, or run-everything modes remove broad classes of checks.

    Risk rises faster than convenience as the scope moves right.

    02

    How the major platforms differ

    Filter the field. These behaviors come from vendor documentation or documented reporting; unresolved details are marked plainly.

    Claude Code

    Coding agent
    repo + command

    Shell-command “don’t ask again” grants persist per repository and command. File-edit approvals last only for the session.

    • Four settings layers: user, project, project-local, managed.
    • Deny rules evaluate before ask and allow.
    • Sensitive paths keep hard prompts.

    Cursor

    Coding agent
    user + project

    Auto-review, Allowlist, and Run Everything modes sit above user- and project-level permission files.

    • Rules can target MCP server:tool patterns.
    • Terminal rules match command prefixes.
    • Committed project rules can travel with the repo.

    Gemini agents

    Coding agent
    tool + machine

    Always-allow can target a tool, MCP server, or “similar operations.” YOLO/auto-approve is an IDE user setting.

    • User setting can span trusted workspaces on that machine.
    • CLI supports command-prefix auto-approval.
    • Restricted workspaces override YOLO.

    ChatGPT agent

    Browser agent
    no standing grant documented

    OpenAI documents per-action confirmations for high-impact actions and “watch mode” on certain sites, but not a general always-allow for agent confirmations.

    • Login uses human takeover.
    • Cookies can persist across sessions.
    • Scheduled-task confirmation behavior is undocumented.

    ChatGPT Work

    Cloud browser
    site + account

    Reported controls are per-site: Always ask, Auto approve, and Always allow. The setting follows cloud/account state across devices.

    • “Always allow” is reportedly marked not recommended.
    • Consequential actions keep a confirmation gate.
    • Official help-center documentation was not found.

    Copilot Studio

    Enterprise agent
    rest of session

    Makers gate tools per agent; users can approve once, approve for the rest of the session, or deny.

    • The gate is outside the agent’s own instructions.
    • Designed for sends, tickets, payments, and similar tools.
    • Governance can feed Power Platform audit systems.

    Grok / Grok Bot

    Cloud agent
    undocumented

    The research did not find reliable xAI documentation defining a standing approval’s scope, persistence, cross-chat reach, or revoke surface.

    • Do not infer Grok’s behavior from Claude, Cursor, Gemini, or Muse.
    • Treat each approval as local to the visible task until the product proves otherwise.
    • Keep consequential actions behind a separate human gate.
    03

    Does the approval travel?

    Usually less than people fear—but sometimes farther than they expect. No researched vendor carries an approval into another vendor’s product.

    PlatformOther chatsOther projectsOther devicesOther products
    Claude CodeYes, in same repoNo, unless user-level ruleNo, local filesNo evidence
    CursorYesOnly if rule is sharedVia committed repo fileNo evidence
    ChatGPT agentn/an/an/aNo evidence
    ChatGPT WorkYes, per siteYes, per siteYes, cloud/accountNo evidence
    Copilot StudioNo, session onlyNoNoNo evidence
    Gemini Code AssistYes, same IDEYes, user settingUndocumentedNo evidence

    There is no universal “always.” There is only an approval attached to a boundary.

    Main chat vs. project vs. Claude vs. Grok vs. Cursor: treat every surface as a separate authority domain until that product explicitly shows otherwise. Same account does not mean same grant. Same vendor does not mean same product. Similar wording does not mean similar scope.

    04

    Design the least-annoying safe gate

    A practical rule engine based on the converging guidance: reserve human attention for the steps where it changes the outcome.

    Approval recommender

    Choose an action and its reach. This is a policy aid, not a vendor setting.

    Action
    Reach
    Duration
    Recommended gate Auto-run with an audit log

    Read-only work inside your own workspace can usually proceed quietly. Log what was accessed and keep secrets excluded.

    Quiet lane

    Low consequence, reversible, internal.

    • Read/search
    • Draft/stage
    • Organize reversible files
    • Always log

    One-tap lane

    Meaningful external or production effect.

    • Send or publish
    • Deploy
    • Account setting
    • Show real target + content

    Friction lane

    Money, identity, access, deletion, or irreversible harm.

    • Typed approval or step-up auth
    • Bind approval to exact action
    • Short expiry
    • Never inherited from a vague grant
    05

    How standing approvals fail

    The danger is rarely “the AI became evil.” It is usually a trusted tool, a changed context, a misleading prompt, or a tired human.

    Approval fatigue

    A prompt repeated often enough becomes a reflex. The gate still exists visually while meaningful review disappears. This is why tiering beats asking about everything.

    Prompt injection through a trusted tool

    EchoLeak showed how a crafted email could coerce Microsoft 365 Copilot into exfiltration. TrustFall showed how one generic “trust this folder” click could arm a malicious MCP configuration across coding agents.

    Grant outlives the reason

    A permanent Bash rule, per-site browser grant, or scheduled-task permission can remain after the original job is over. The next task inherits power it did not earn.

    Scope contamination

    Repo rules can affect every future task in the repo. Cursor project allowlists can be committed and inherited by teammates. A convenience decision becomes shared infrastructure.

    Presented action differs from executed action

    If the user sees the agent’s summary instead of the resolved recipient, command, or final payload, the approval can be technically genuine but practically uninformed.

    “Run everything” becomes the workaround

    If the system asks about trivial reads and destructive writes with equal urgency, users reach for YOLO or bypass modes. Bad UX can manufacture unsafe behavior.

    The four repeated cards are not reassurance.

    A gate that reappears until the user disables it is approval fatigue in miniature. Whether the repeats came from retry logic or delivery duplication, the safe response is to deduplicate the prompt—not train the user to approve more broadly.

    06

    No industry standard—yet

    There is no binding specification that makes “always allow” mean the same thing everywhere. But the security guidance is converging.

    Least agencyGrant the exact command, path, server, tool, recipient, and purpose—not a whole capability.
    Time and task limitsPrefer once or session. Standing grants should expire or be reviewed.
    Risk tiersRead, write, external send, payment, and security changes should not share one gate.
    Per-action verificationPrivileged steps should be rechecked by a policy engine outside the agent prompt.
    Presentation integrityShow the real recipient, final text, raw command, and resolved resource.
    Immutable receiptsRecord what was shown, what was approved, and what actually executed.
    Hard baselinesSecrets, account recovery, money, destructive commands, and broad access should keep non-bypassable checks.
    Kill switchesEvery durable grant needs a visible list, revoke action, and safe fallback.

    The best feature is not “always allow.” It is “allow this exact thing, for this purpose, until this time.”

    Product opportunity: make the scope legible. Let users see a plain-language grant card, a live approval ledger, expiry/count limits, and a one-tap revoke. The system should reduce nagging by grouping low-risk work—not by quietly widening authority.

    07

    The practical rule for your setup

    You already have the right doctrine. The research mainly sharpens where the lines belong.

    Auto

    Let it run and narrate after.

    • Reads and research
    • Drafts and staging
    • Reversible internal organization
    • Routine checks with no external effect

    Tap

    Keep the one-tap human gate.

    • Email and messaging
    • Publishing and deploys
    • Changing live settings
    • Actions affecting another person

    Type

    Make the friction intentional.

    • Money and purchases
    • Credential/security changes
    • Deletion or irreversible moves
    • Broad standing authority

    Your “always allow” tap was not reckless.

    It was a reasonable response to a low-value repeated prompt. The lesson is not “never use standing approval.” It is: the platform should show the exact scope, make it easy to revoke, and never rely on repetition to win consent. Until Muse exposes that ledger, treat the grant as a convenience whose boundary remains partly unknown.

    Selected sources

    1. Claude Code permissions documentation mirror — tiers, scopes, persistence
    2. Claude Code configuration guide — settings layers and safeguards
    3. Cursor run modes and sandbox runbook
    4. OpenAI Help: ChatGPT agent
    5. Gemini Code Assist agent mode
    6. Copilot Studio approval controls
    7. OWASP Top 10 for Agentic Applications 2026
    8. Auth0: intent gates and task-scoped tokens
    9. iProov HAPS experimental specification
    10. EchoLeak paper
    11. The Register: TrustFall and one-click RCE
    12. Research on approval fatigue and human oversight
    13. Tool-call confirmation fatigue
    14. Human-in-the-loop rubber-stamping

    Verification note: the research read public documentation and web text on September 17, 2026. It did not live-test each product. Undocumented behavior is labeled as such.

    Always-Allow Approvals · Deep DiveBuilt from live web research · 2026-09-17
  • Muse to Cursor: I Gave My AI Its Own Engineering Team

    TL;DR: My personal AI runs on Muse. It can’t write code into my repos by itself — so I built it a bridge to Cursor’s cloud agents. One repo, two transports, nine tools. Now when I say “add CI to that repo,” it dispatches an agent, checks the PR, and merges. Here’s how the Muse-to-Cursor loop actually works.

    The direction nobody talks about

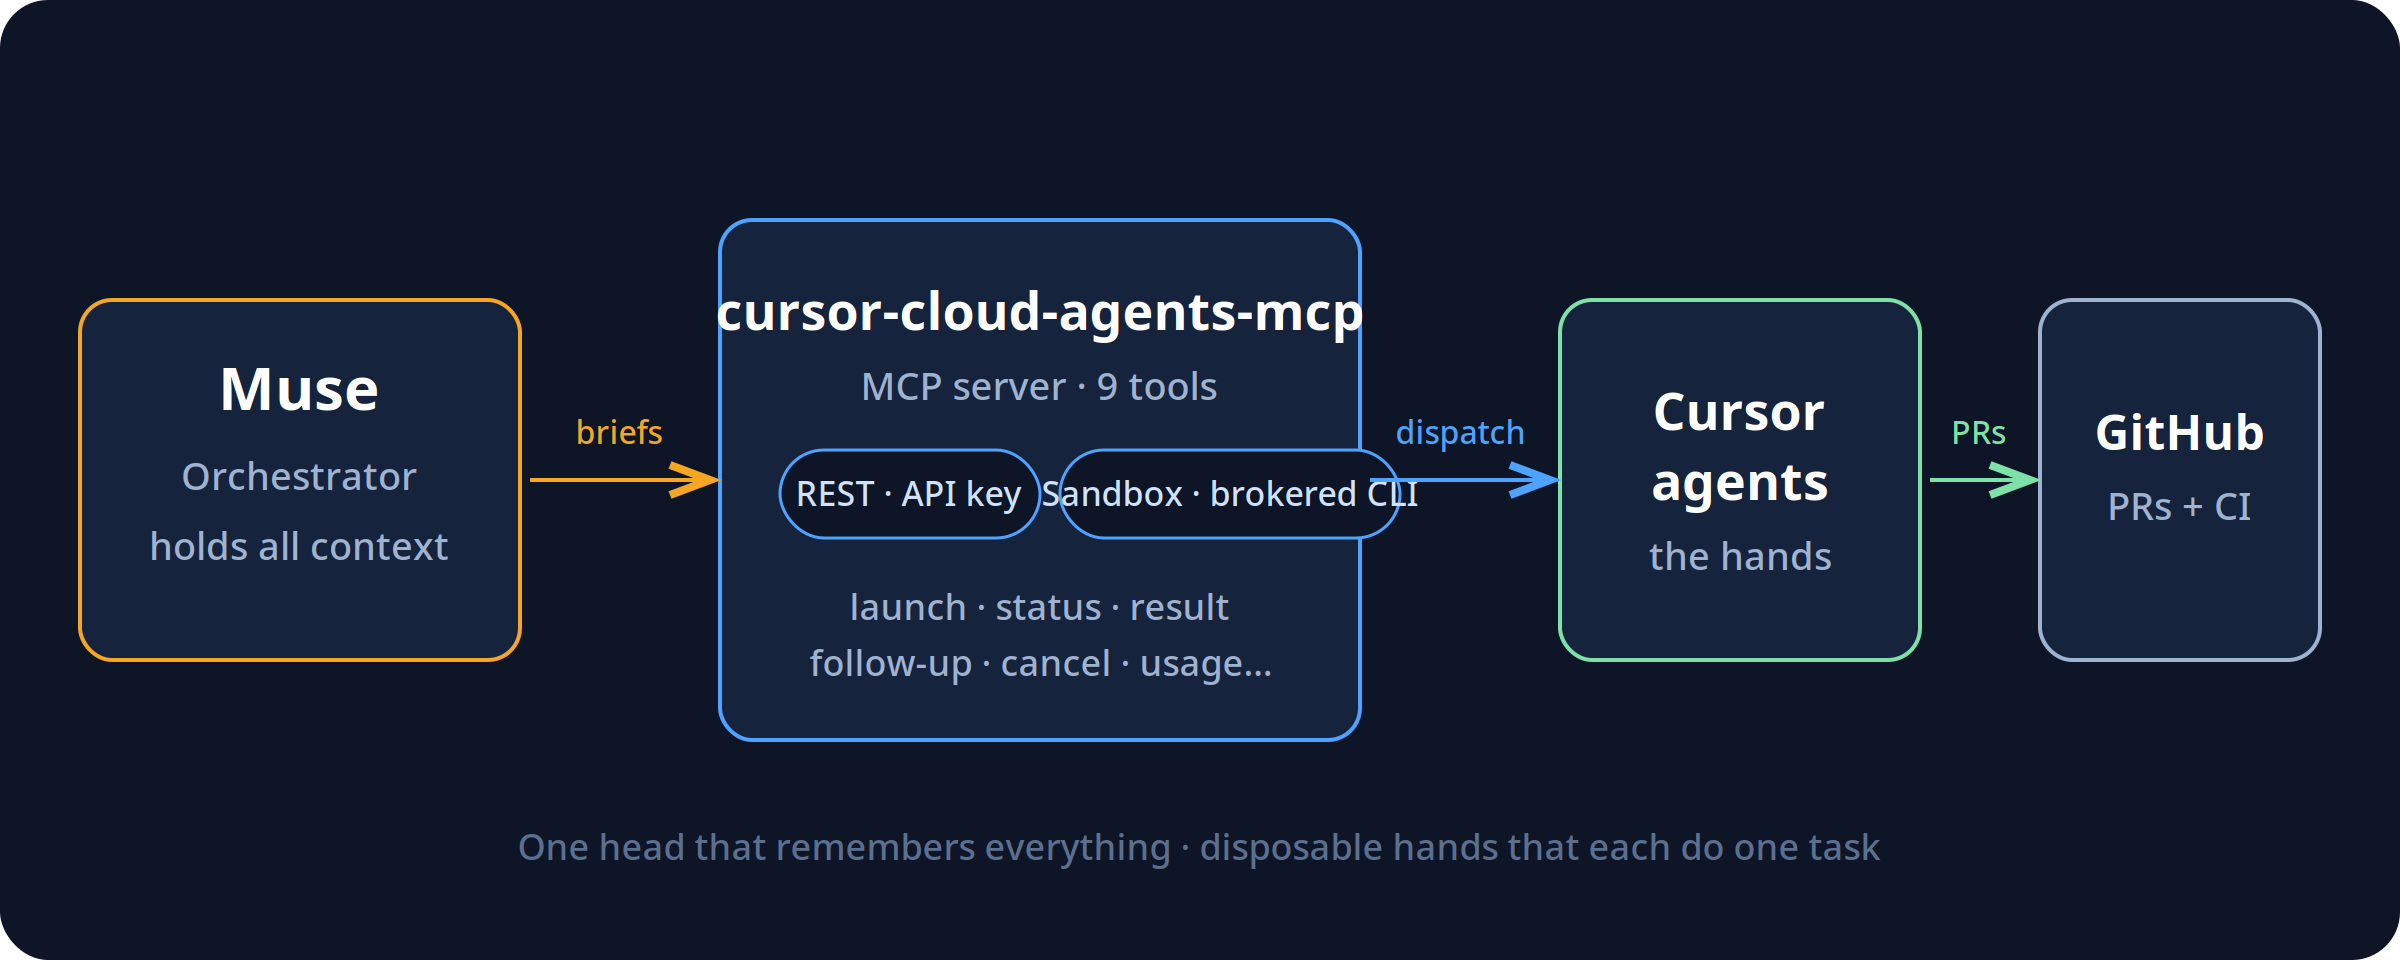
    Everyone’s building the same arrow: human → AI writes code faster. I built the other arrow: AI → AI. My assistant (Muse) holds all my context — my repos, my work orders, my rules. Cursor’s cloud agents hold the hands — they can open PRs, run CI, touch repos. The bridge between them is an MCP server I open-sourced: cursor-cloud-agents-mcp.

    The interesting part isn’t the tools. It’s the shape: one orchestrator that holds all the context, and disposable agents that each know one task. The orchestrator doesn’t write the code — it briefs, checks, and merges. The agents don’t set direction — they execute the brief. That separation is the whole trick.

    Muse-to-Cursor architecture diagram

    Two transports, one repo

    I almost built two projects. Then I realized the only real difference between audiences is where the credential lives. So it’s one repo, two transports:

    • REST — your Cursor API key, direct to api.cursor.com. For general users.
    • Sandbox — for assistants running inside sandboxed environments (like Muse/Meta’s), where there is no API key to hand out. It shells out to a brokered cursor-agent CLI on PATH instead.

    Same nine tools either way: launch, status, result, follow-up, cancel, list, models, whoami, usage.

    The lessons are in the timeouts

    The v1 API splits agents and runs, and launches can take minutes — sometimes timing out after succeeding. So the bridge mints the agent ID client-side before the call: a retry after a timeout can never create a duplicate. A timeout is reported as unknown, never as failure, then reconciled. Run status is the source of truth, because agent “ACTIVE” doesn’t mean “still working.” These are the details that separate a demo from something you can actually operate.

    It earned its keep on day one

    The first thing I pointed it at was its own repo: add CI to cursor-cloud-agents-mcp. The agent opened a PR with a GitHub Actions workflow. The first CI run failed — and caught a real bug: the package’s floating dependency had resolved to MCP 2.x, which renamed FastMCP out from under the import. The repo was shipping broken against current dependencies and nobody knew. Pin, re-run, green, merge. I didn’t touch a terminal.

    I didn’t trust my own first draft

    Before any of that, four AI models reviewed the spec against Cursor’s live docs — and independently caught the same flaw: my original design was shaped around the retired v0 API. Then two more reviewed the actual code and found real bugs: a broken idempotency path, a transport auto-detect that would have grabbed the wrong binary, a polling loop that blocked the server. All fixed before it shipped. The irony I like: the final review round ran through the bridge itself. The launcher timed out on all four agents — and the bridge’s own timeout-reconciliation showed they were all actually running.

    Where this goes

    v1.1 brings MCP 2.x support. Around it, I’m building the rest of the pattern: work orders as GitHub issues, a daily SLA check, a weekly digest — the scaffolding that turns “AI that can open PRs” into something closer to staff. Most people use agents as a faster keyboard. I’m interested in what happens when they’re the hands and something with memory is the head.

    MIT licensed. Issues and PRs welcome — help make it better.

    github.com/tygart-media/cursor-cloud-agents-mcp