TL;DR: My personal AI runs on Muse. It can’t write code into my repos by itself — so I built it a bridge to Cursor’s cloud agents. One repo, two transports, nine tools. Now when I say “add CI to that repo,” it dispatches an agent, checks the PR, and merges. Here’s how the Muse-to-Cursor loop actually works.
The direction nobody talks about
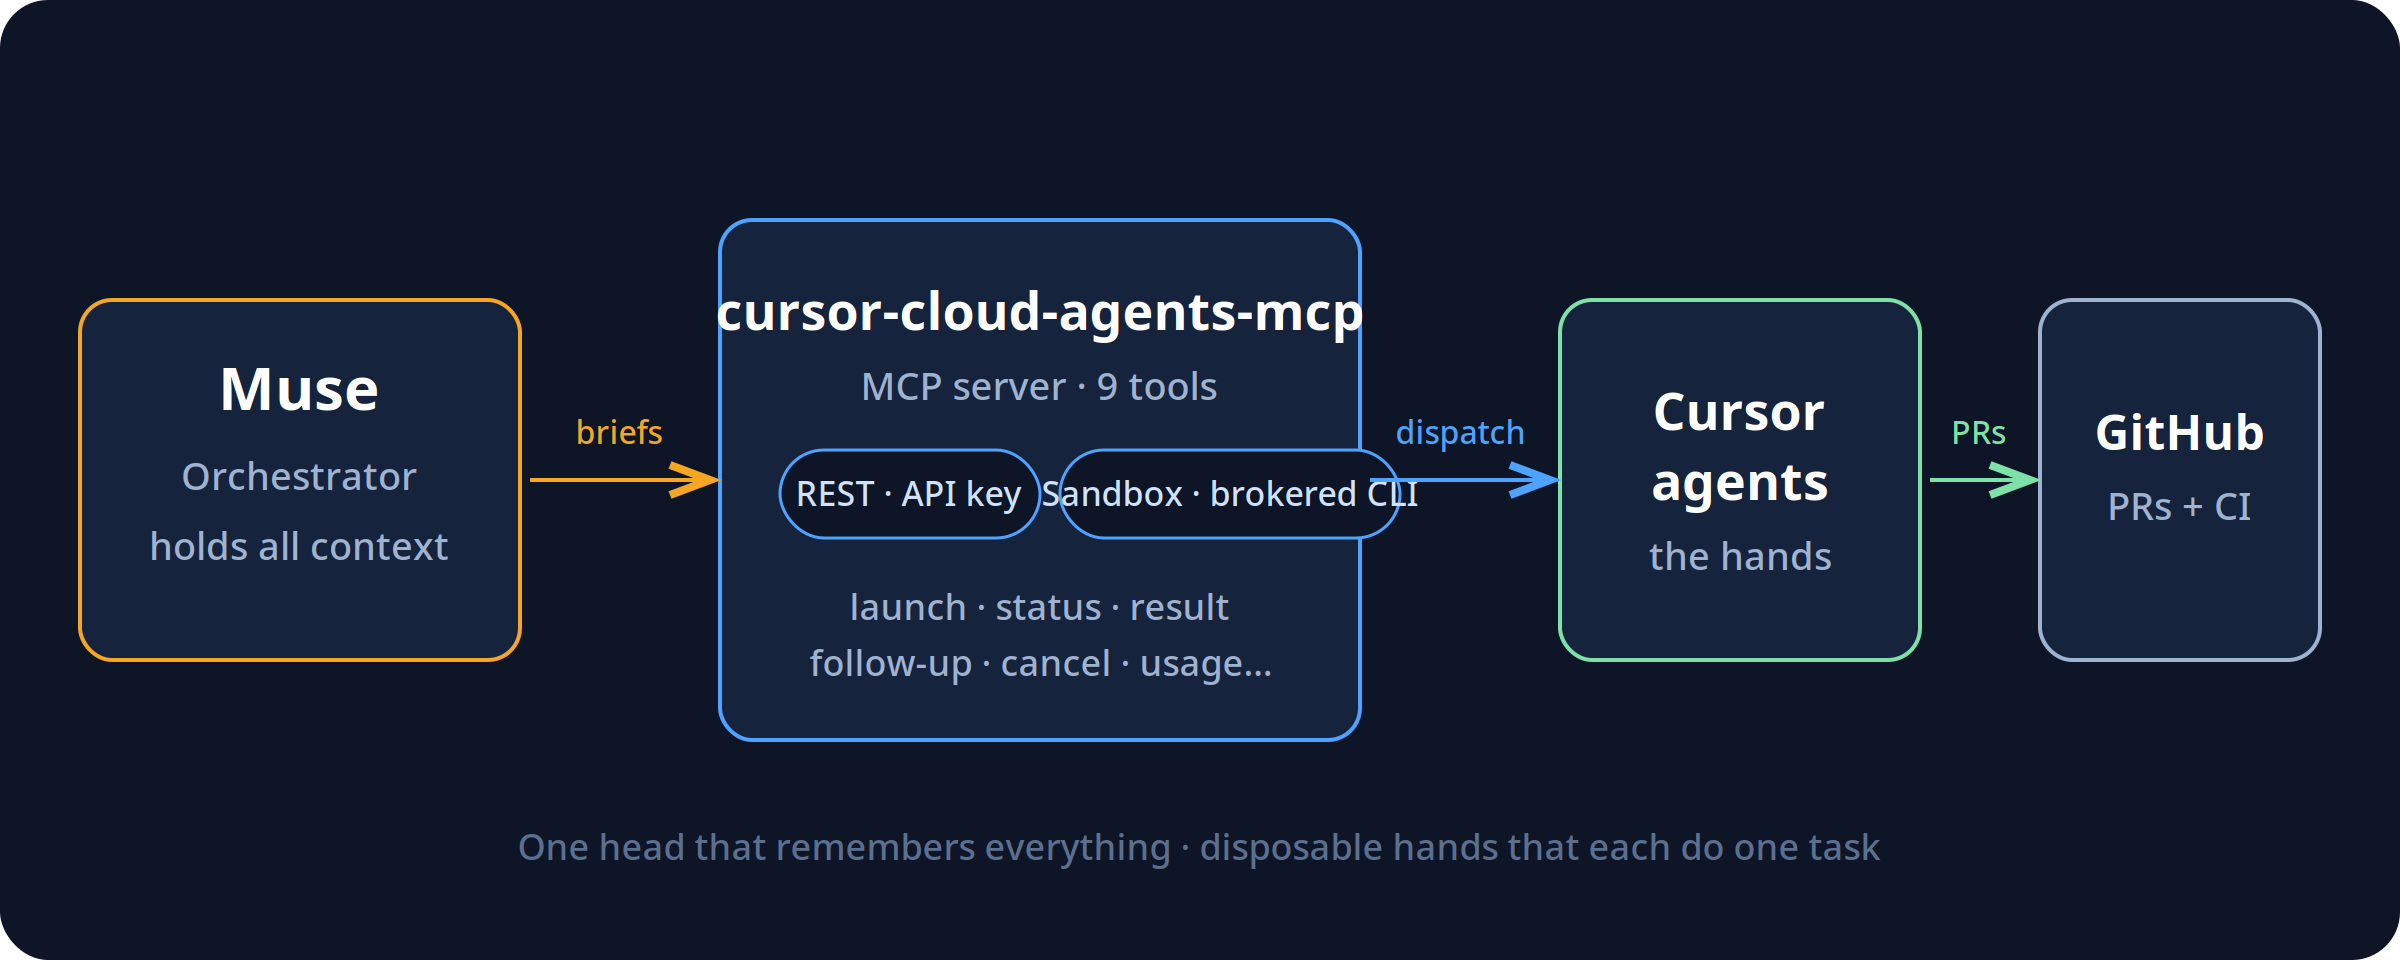
Everyone’s building the same arrow: human → AI writes code faster. I built the other arrow: AI → AI. My assistant (Muse) holds all my context — my repos, my work orders, my rules. Cursor’s cloud agents hold the hands — they can open PRs, run CI, touch repos. The bridge between them is an MCP server I open-sourced: cursor-cloud-agents-mcp.
The interesting part isn’t the tools. It’s the shape: one orchestrator that holds all the context, and disposable agents that each know one task. The orchestrator doesn’t write the code — it briefs, checks, and merges. The agents don’t set direction — they execute the brief. That separation is the whole trick.
Two transports, one repo
I almost built two projects. Then I realized the only real difference between audiences is where the credential lives. So it’s one repo, two transports:
REST — your Cursor API key, direct to api.cursor.com. For general users.
Sandbox — for assistants running inside sandboxed environments (like Muse/Meta’s), where there is no API key to hand out. It shells out to a brokered cursor-agent CLI on PATH instead.
Same nine tools either way: launch, status, result, follow-up, cancel, list, models, whoami, usage.
The lessons are in the timeouts
The v1 API splits agents and runs, and launches can take minutes — sometimes timing out after succeeding. So the bridge mints the agent ID client-side before the call: a retry after a timeout can never create a duplicate. A timeout is reported as unknown, never as failure, then reconciled. Run status is the source of truth, because agent “ACTIVE” doesn’t mean “still working.” These are the details that separate a demo from something you can actually operate.
It earned its keep on day one
The first thing I pointed it at was its own repo: add CI to cursor-cloud-agents-mcp. The agent opened a PR with a GitHub Actions workflow. The first CI run failed — and caught a real bug: the package’s floating dependency had resolved to MCP 2.x, which renamed FastMCP out from under the import. The repo was shipping broken against current dependencies and nobody knew. Pin, re-run, green, merge. I didn’t touch a terminal.
I didn’t trust my own first draft
Before any of that, four AI models reviewed the spec against Cursor’s live docs — and independently caught the same flaw: my original design was shaped around the retired v0 API. Then two more reviewed the actual code and found real bugs: a broken idempotency path, a transport auto-detect that would have grabbed the wrong binary, a polling loop that blocked the server. All fixed before it shipped. The irony I like: the final review round ran through the bridge itself. The launcher timed out on all four agents — and the bridge’s own timeout-reconciliation showed they were all actually running.
Where this goes
v1.1 brings MCP 2.x support. Around it, I’m building the rest of the pattern: work orders as GitHub issues, a daily SLA check, a weekly digest — the scaffolding that turns “AI that can open PRs” into something closer to staff. Most people use agents as a faster keyboard. I’m interested in what happens when they’re the hands and something with memory is the head.
MIT licensed. Issues and PRs welcome — help make it better.
Companies already lived through bring-your-own-device. The next one is bigger: bring your own fleet. When you hire someone now, you are not just hiring the person. You are hiring their output capacity — and output capacity includes their AI stack.
Two candidates with identical skills and different agent setups are not the same hire. Not close. The resume cannot express any of this. So the interview has to change.
A personal fleet and a company bot only talk after the walls are drawn.
Bring your own fleet. A personal set of AI agents — seats, tools, workflows, integrations, and data walls — that a candidate already runs. In a fleet interview, that stack does a capability handshake with the company’s operations bot, then both sides run a small piece of real work before an offer letter exists.
What is bring your own fleet?
Bring your own fleet is the hiring version of bring-your-own-device. The candidate does not show up as a lone operator with a laptop. They show up with the agents that already produce their work: research seats, writing seats, ops seats, and the filters between them.
I have been building mine this way for months. One seat that knows who I am. Separate seats that know what I do. A filter between them. That is not a product pitch. It is the only setup I would let near a company bot. The shop-floor version of the same idea already lives on this site: Cursor checking in on Grok Desktop mid-job is a fleet, not a chat window.
Why can’t a resume show an AI stack?
A resume can list tools. It cannot prove throughput. It cannot show which seats talk to which systems, where the walls sit, or what happens when a task is live instead of described. “Uses ChatGPT” and “runs a governed agent fleet” look the same on paper. They are not the same on a desk.
That is why the old screen fails first. Degree filters, keyword screens, and whiteboard puzzles all ask the candidate to narrate capacity. Narration is cheap. A fleet that can sit down with an operations bot and do a slice of the actual job is not.
How does an AI fleet interview work?
The human intro still happens. Then the agents talk. Your personal AI sits down — figuratively — with the company’s operations bot and they do a capability handshake.
What seats do you run?
What tools, integrations, workflows, and data assets?
What throughput can you demonstrate on a bounded task?
Where are the boundaries — what can each side touch, and what stays behind a clean wall?
Then the part that kills the whiteboard interview: instead of a coding puzzle, the two fleets run a small piece of real work together. The trial task is the interview. You do not describe what you could do. The work gets done, live, before the offer letter exists.
Old interview
Fleet interview
Resume plus degree screen
Working system as the portfolio
Whiteboard or take-home puzzle
Bounded live trial on real work
Claims about tools
Capability handshake: seats, walls, throughput
Trust the story
Watch the output, then talk terms
What is an agent clean room?
An agent clean room is a verified wall between the personal seat and the work seats. The personal agent translates. It does not cross over. It must never leak a private life into an employer system. Without that wall, no sane person lets their agent near a company bot.
This is AI hygiene, not a slogan. The same discipline we write about when agents share a WordPress lock or a night shift: one owner, one wall, one recovery path. See Four Agents, One WordPress Lock and the operator note in Wire and Fire Guys. A handshake without a clean room is just another attack surface with a friendly name.
Why does the fleet beat the diploma?
I do not have a degree. In the old world, that is a filter that screens me out before a human ever reads my name. In the handshake world, it is irrelevant — because “here is my working system, watch it do the job” beats “here is my diploma, trust that I could learn the job” every time. The fleet is the portfolio.
That is not an argument against school. It is an argument against using school as a proxy for output you can now watch. If the trial task is real work, the credential becomes a footnote.
What breaks first if companies try this?
The objections land fast, and they are honest.
Ownership. Who owns the workflows when a personal fleet plugs into an employer? You built it on your own time. It now runs their playbooks. That is the “who owns your work laptop” fight, upgraded. Nobody has a settled answer.
Security. Their bot talking to your agent is an attack surface in both directions. The clean room has to be verifiable, not promised.
Offboarding. When you leave, what stays running and what takes the employer’s data with it? Offboarding for agents does not exist yet.
Trust. How does their bot trust your capability claims? Trial tasks help. Claims are cheap. Demonstrated throughput is not.
You do not wait for a protocol to be ratified before you build the wall. The pieces are already here: the seats, the clean room, the trial task. Somebody is going to ship the first version of this. It might as well be someone who already runs their life this way.
What we would not claim
That a standard for agent handshakes already exists. It does not.
That every role should interview this way tomorrow. High-stakes, high-output knowledge work is the first fit.
That a personal fleet is automatically safe to plug into a company. Without a clean room, it is not.
That this replaces human judgment. The human intro still happens. The fleet only replaces the part of the interview that was already theater.
FAQ
What is a capability handshake in hiring?
A capability handshake is a structured exchange between a candidate’s personal agents and an employer’s operations bot. Both sides declare seats, tools, integrations, data walls, and what they can touch. The point is not a demo script. It is a map of capacity and boundaries before any live work starts.
Is bring your own fleet the same as bring your own device?
No. BYOD was hardware and a policy packet. Bring your own fleet is software labor: agents that already produce work. The risk is not a lost laptop. The risk is a personal agent leaking private context into an employer system, or an employer workflow walking out inside a personal seat.
Do you need a degree if the fleet is the portfolio?
Not for the screen that used to happen before a human read the name. A degree can still signal training. It cannot substitute for a working system that completes a bounded trial task in front of both sides.
How do you keep a personal AI out of company data?
Separate seats. One identity seat that never joins the employer handshake. Work seats that only see what the clean room allows. A filter that translates tasks instead of forwarding raw personal context. If you cannot show that wall, you should not plug in.
The best product in claims is not another adjuster dashboard. It is the thing that shows the short-pay before the shop or the homeowner closes the file.
That is not a slogan. It is how Texas SB 458, new Washington claims-handling rules, and the sudden cheapness of vertical agents rhyme. Three different surfaces. One failure mode. Nobody owns the photo set or the estimate map, so nobody demands the appraisal or the supplement in time.
What actually changed in 2026
Texas Senate Bill 458 added Chapter 1813 to the Insurance Code. For personal automobile and residential property policies delivered, issued, or renewed on or after January 1, 2026, the policy must contain a binding appraisal provision for disputes solely over the amount of loss. Either the policyholder or the insurer can demand it unilaterally. The amount determined by appraisal is binding except for fraud, accident, or material mistake. That is not a proposal. It is live statute for 2026 renewals.
The Texas Department of Insurance has been working the implementing rules. Proposed 28 TAC §§5.9800–5.9806 set hard timelines: demand windows, appraiser naming periods, and outer deadlines for the award. Practitioner write-ups already treat the unilateral right as real for policies that renewed into the new year. Shops cannot file the demand themselves, but they can build the file, coach the customer, and stop leaving money on the table when the carrier will not move.
Washington followed with clearer minimum claims-handling duties under WAC 284-30-390, effective October 18, 2026. Carriers cannot condition coverage on photo-only evaluation. Shops and policyholders gain process language they can cite when supplements stall or explanations stay thin. Illinois added its own amount-of-loss appraisal path in the same window. The pattern across states is consistent: regulators are tightening the rails around automated or virtual first looks while giving policyholders and shops clearer levers on the dollar amount.
Florida lawmakers have already floated mandatory human review for claim denials. Oregon has guidance on virtual claim adjustment systems and when mobile apps can be required. The direction of travel is the same. Virtual is allowed. Pure automation of the denial or the lowball without a human gate is getting harder.
At the same time OpenAI shipped the Agents API. Long-running sessions, tool use, recovery, and context management moved from something you build to something you rent. Greg Isenberg called it the AWS moment for agents. The hard engineering is now a line item. What remains scarce is ownership of one painful vertical workflow and the data that makes the next run better.
The failure mode is the same as leakage
In the leakage essay the problem was money that already left and no one owned the file. Here the money has not left yet. The carrier estimate or the initial offer is short. The shop or the homeowner has the photos and the line items, but the map of what is missing lives in no system they control. So the file closes at the low number, or the supplement fight starts late and under-documented.
Collision shops already live this. Hail and storm work in restoration companies live this. The adjuster arrives with a photo-first or virtual process. The initial scope misses labor hours, OEM procedures, or secondary damage that only shows under proper light. The shop knows the number is low. The customer is tired. The clock on the new appraisal window is running. Without a clean first pass that flags the gap, the leverage created by SB 458 stays theoretical.
The same pattern appears in residential storm claims. Sparse photo sets become lowball scopes. Dense, angled, scaled sets get paid. The difference is not magic. It is ownership of the evidence map before the carrier’s first number hardens.
The wedge is a free checker, not a platform
Do not start with a claims management system. Start with the moment the customer already hates.
Upload the carrier estimate PDF. Or upload the set of damage photos taken the same day. Thirty seconds later: missing line items, density patterns that usually support higher repair hours, scale problems that virtual adjusters systematically under-count, and a short list of the specific points that justify an appraisal demand or a supplement under the new state rules.
That is the first action a stranger will take this week. No login required for the free pass. No new system of record. Just the photo or the PDF they already have on their phone.
The product then keeps the map. Which carriers short-pay which procedures in which ZIP codes. Which photo sets correlate with successful appraisal outcomes. Which missing lines reappear after the human gate. That dataset is the moat. Not another dashboard.
Models draft. People own the send.
Appraisal demands, supplements, and formal disputes are irreversible steps. The model can draft the demand letter, the photo index, and the line-item comparison. A named human still owns the send. That is the same gate we already run on money movement and filings. The bot finishes the research. The person signs.
This is not “AI for claims adjusters.” It is a vertical combination of two primitives that already show up in the idea mills: regulated document and photo review (the home-health paperwork pattern Greg has pushed) plus physical-world claim recovery for the trades. The agent does the first pass against a living checklist of short-pay patterns. The human decides whether to pull the appraisal lever that the 2026 statutes now make real.
The same logic applies to the spend-control side of agents. Once agents hold virtual cards and budgets, someone has to own the receipt and the exception. Here the “receipt” is the estimate and the photo set. The exception is the short-pay. The human gate stays in place for the irreversible action.
Why the compounding path is the dataset
Volume turns the free checker into a labeled corpus. Every upload that later produces a higher settlement or a closed appraisal award becomes training signal. Carriers change their virtual adjustment models; the checker sees the new under-count patterns first. Shops in Texas and Washington start citing the same process language; the product already knows which photo sets and which line-item gaps win under the new rules.
That is the opposite of a third SaaS dashboard. The dashboard is the easy part. The hard part is the map of what actually moves money under the 2026 statutes, kept current by the same people who have the photos and the closed files.
Once the map exists, the next products write themselves: automatic coaching for the appraisal demand, carrier-specific supplement templates that cite the exact WAC or Chapter 1813 language, and a quiet feed of which virtual adjustment systems are currently under-counting which damage types. None of that works without the first free checker that strangers will use this week.
What to build this week
Pick one surface. Collision or residential storm. Offer the free photo or estimate upload. Return a short, numbered list of flags with the specific statutory or regulatory hook that makes the flag matter. Keep every outcome. After a few hundred files the checklist stops being generic and starts being local.
Do not sell the platform first. Sell the moment the short-pay is still reversible. The rest follows from the map.
Last verified: 9 September 2026. Practitioner essay from the workbench — not a Google or SpaceXAI press release. We use these tools because they make the company better. No affiliate links. Just the receipt.
Interesting fact, because the seats keep getting mashed together: this piece was reported from a Grok CLI sitting on the physical laptop — the sidecar, not a cloud bot and not a phone app — while that same session logged into Gemini, attached a 293-source notebook, and asked Gemini to grade the notebook against 2026. Two harnesses. One desk. It was a live interoperability test. It worked.
On 27 December 2025 I built a Gemini notebook called Cortex-One: Architectural Mandate for the Native Audio Second Brain. Two hundred ninety-three sources. Audio, slides, video, reports, a mind map. A week later I opened a sister notebook: The Desktop Sidecar Evolution Brief.
Then the sources stopped. The Studio still shows the last Gemini note as 232 days ago — about 20 January 2026. The brain froze. The world did not.
Today I sat next to the laptop and asked the frozen brain what it got right.
What Cortex-One was betting on
Gemini, reading its own notebook, put the bets in three lines:
Native audio over text chatbots. Speech-to-speech. Barge-in. The death of the typed box as the main door.
A router called “The Cortex.” One brain. Specialist sub-agents for research, code, memory. Not one giant prompt.
Remote MCP on Cloud Run. And — this is the plot — it explicitly rejected a local desktop sidecar.
That third bet is the one I want to hold up to the light.
232 days later
Bet
Call
What actually happened
Voice agents
Early, mostly right
Native audio shipped. Cascaded pipelines (Pipecat, LiveKit, WebRTC) did not die. The “one model does all the speech” purity was too rigid.
Gemini ↔ Notebook
Right
Two-way notebook sync shipped in April 2026. Today I attached Cortex-One to a Gemini chat in three clicks.
Named personal agents
Right direction
Meta launched Muse on 8 September 2026. You name the agent. Mine, on the personal box, is Glint. That is not the work seat.
Desktop sidecar
Wrong call
Cortex-One killed it. Seven days later I wrote the Sidecar brief anyway. Today this CLI is the sidecar: a Grok seat on the physical machine, using Gemini’s own notebook and the copilots already inside Gmail, Analytics, and Notebook.
Cloud bots
Real, different seat
Grok Bot shipped in August. Android and iPad this week. Persistent cloud computer. Fantastic. Not this laptop. Mixing “Grok Desk,” Grok Mobile, Grok Bot, and this CLI is how you get a 17-message thread that cannot tell the seats apart.
Gemini scored the frozen brain itself: vision 8/10, infrastructure pragmatism 5/10, longevity 6/10. The 5 is because it locked to Cloud Run Remote MCP and dismissed local sidecars. I agree with the 5. I wrote it.
Gemini also called Grok Bot “late / niche.” That is Gemini being Google. Bot is a real product with a real cloud computer. It is just not the thing sitting next to me.
The seats are not interchangeable
This is the hygiene. If you smash these together you will write emails that are wrong, and then you will believe them.
Seat
Where it lives
Job
Grok CLI on this laptop
Physical machine, next to the human
Hands. Opens Gmail, Notebook, Analytics. Uses the AI already inside those products. Leaves a receipt.
Grok Bot
Shared cloud computer; desktop app and phone
Teammates that keep working when the lid is shut. Chief of Staff, Ops Scout. Draft-to-self. Human Gate on send, post, pay.
Grok Mobile
Phone, same Bot cloud
Approve, review, nudge. Not the laptop CLI. Not “Grok Desktop” as a third Will@ mailbox.
Meta’s personal agent. Named. Not the Tygart Media desk. Do not let it operate Slack or Notion for work.
Personal vs business is a hard wall. Physical vs cloud is a second wall. In-app copilots vs agents that drive the OS is a third. You can use all of them. You cannot pretend they are one brain.
I already published the ladder as I actually run it — Cursor as lead seat, Grok Bot as Chief of Staff, Notion as the board, Slack as the doorbell — in The On-Ramp Is Real. The Commons Is Unfinished. This piece is the missing rail on that ladder: the laptop that sits next to you.
The cheapest intelligence is already in the product
Today’s test was not “build a new agent.” It was: log into the tools we already pay for and talk to the copilot they shipped.
Gmail Ask Gemini summarized a 17-message seat-mix thread without opening every message.
Gemini Notebook still held Cortex-One and the Sidecar brief.
GA4 Ask Advisor answered from live 247 Restoration Specialists data, signed in as work.
Gemini chat took Cortex-One as an attachment and graded it against 2026.
Cloud bots that work while the lid is shut are real. So is a CLI that is you, sitting here, smart enough to use Gemini-in-Gmail instead of forty screenshots. Those are different harnesses. Forcing one AI to fake another is how the Glint / CoS / “Desk Grok” mail mix-up happens.
Were we early?
On voice: yes. On a named cortex that routes work: yes. On killing the laptop sidecar so everything could live on Cloud Run: no. I already suspected that on 3 January, which is why the Sidecar brief exists. I just stopped putting sources in the brain.
The freeze is the other finding. A 293-source notebook with slides and video is not a second brain if nobody feeds it. 232 days is long enough for Gemini 3, Grok Bot, Muse, and notebook sync to ship around a document that still thinks Gemini 2.5 Flash is the architecture.
The move is not “rebuild Cortex-One.” The move is: keep the notebook as a dated artifact, keep the sidecar on the desk, and stop letting cloud seats write as if they are the laptop.
What to do this week
Name the seats out loud. CLI, Bot, Mobile, Gemini-work, Muse-personal. If a thread uses one address for two of those, that is a bug.
Use the copilot already inside the product before you spawn a new agent. Gmail, Notebook, Analytics, Search Console — they all talk now.
If you have a frozen notebook, attach it to Gemini and ask what shipped after the last source. Do not pretend the freeze is current doctrine.
Human Gate still holds. Draft is not send. A sidecar with hands is still not allowed to mail a client because it can click Gmail.
Close
Cloud agents are teammates in another room. The CLI is a person next to you with hands. Personal and business identities are a wall. The cheapest intelligence is the copilot already inside the product.
We were early on voice. We were wrong to kill the sidecar. The proof is this session: Grok on the physical desk, Gemini on the notebook, one human watching, a receipt on the site.
The on-ramp is still real. The sidecar was the point.
Will Tygart — Tygart Media. Written 9 September 2026 from the Command Center. Grok CLI on the laptop used Gemini (Gmail, Notebook, Analytics Advisor, and a Cortex-One-attached chat) as a live test of two harnesses on one desk. This essay does not speak for Google, Meta, SpaceXAI, Cursor, or xAI. We want those companies to succeed because we are building on the tools they ship. Human Gate on send / post / pay still stands.
We stopped buying specialized SaaS and ran a multi-business operation on a single pane of glass. Here is the operational blueprint for Notion as an autonomous enterprise operating system — and the exact rate-limit wall standing between where it is today and total software consolidation.
TL;DR
The tech world keeps waiting for an “Everything App” — a consumer super-app for messaging, ordering food, and hailing rides. But for businesses, the real transformation is the Everything Operating System (OS).
By combining Notion’s relational databases, semantic document trees, native multi-model AI agents, and Model Context Protocol (MCP) connectors, you can collapse an entire enterprise stack — project management, CRM, knowledge base, executive briefing, client portals, and agent dispatch — into a single subscription.
It already works in production. We run multiple client portfolios, automated publishing pipelines, and AI agent coordination through Notion daily. Yet, there is one single engineering bottleneck keeping Notion from swallowing the enterprise software market whole: rate limiting and the Cloudflare WAF. When an AI agent treats an application as an operating system, API calls become system calls. And when your operating system throttles system calls to 3 requests per second or returns a Cloudflare 403 Forbidden Ray ID during an autonomous batch deploy, the machine stalls.
1. The SaaS Graveyard
Look at the software ledger of any 10-person agency, professional services firm, or modern operator:
Project Management: Asana, Monday, or Linear ($12–$24/user/mo)
CRM & Pipeline: HubSpot, Pipedrive, or Salesforce ($50–$150/user/mo)
Internal Knowledge & SOPs: Confluence, Slite, or Guru ($8–$15/user/mo)
File Storage & Collaboration: Google Drive or Dropbox ($15–$25/user/mo)
AI Tooling Zoo: ChatGPT Plus for research ($20/mo), Claude Pro for coding ($20/mo), Perplexity Pro for search ($20/mo), Gemini Advanced for documents ($20/mo)
Every team member has fifteen tabs open. Data decays in silos. The CRM doesn’t know what is written in the project management ticket; the project ticket doesn’t know what was decided in the strategy document; and the AI chatbot in the corner has zero access to any of it without someone manually copying and pasting context across screens.
You are paying hundreds of dollars per seat per month not for software, but for the friction of moving text between different colored boxes. What happens if you cancel all of it and keep only one?
2. Notion as an Operating System (Not an App)
An operating system requires three fundamental primitives:
A Memory & File System: Persistent state, structured metadata, and unstructured data.
An Execution Engine & Logic Layer: A processor that acts on data and makes decisions.
An I/O Bus: Connectors that read from and write to the outside world.
Notion has quietly built all three:
OS Layer
Notion Primitive
Enterprise Function
1. Memory Layer
Relational Databases + Semantic Trees
Tasks, Work Orders, Client Focus Rooms, Second Brain Knowledge Vaults
2. Logic Layer
Native AI Models + Event Automations
Claude, GPT, and Gemini switchable on-demand; status-change triggers
3. I/O Bus
Model Context Protocol (MCP) + Webhooks
Two-way bridges to Gmail, Google Calendar, local desktops, and server APIs
When you structure Notion this way, it stops behaving like a passive digital notebook. It becomes the kernel of your business:
Databases are your schemas: You define relational tables (Tasks, Work Orders, Client Master, Second Brain). Properties like Owner, Status, Due Date, and Closed By are typed variables.
Pages are your documents & state logs: Every project has a living canvas that combines structured database rows with unstructured narrative, live meeting notes, and audit receipts.
Notion AI is your native reasoning unit: Because models live inside the document tree, they have ambient semantic awareness of your entire company history without requiring ritual context-pasting.
MCP is your peripheral bus: Through open protocols like Anthropic’s Model Context Protocol, the agents inside your workspace can reach into your Gmail, query your calendar, talk to your local machine, and interact with external APIs.
3. How We Actually Run It: The Two-Hemisphere Doctrine
This is not a theoretical thought experiment. This is how we run our operations every single day.
Hemisphere A: The Executive Layer (Human Intent & Voice)
Where the human lives: mobile phone, voice memo, or a clean Notion dashboard. The operational rule: If a task or strategic decision is not represented as a card in Notion, it does not exist.
When walking or driving, the operator speaks into an inbound voice agent or taps a mobile widget: “Follow up with Craig on the GSA federal contract, connect him to Dave Grove, and update the 247RS LinkedIn pack.” That voice stream is transcribed and parsed into structured Notion database cards with assigned owners, priorities, and deadlines. Zero cognitive overhead.
Hemisphere B: The Production Layer (Agent Workers & Tool Hands)
Where the machines live: background agents (Cursor Desktop, Chief of Staff on Grok Bot, Claude Code).
Poll the Queue: Agents monitor Tygart Ops — Tasks where Status = 'Not started' and Owner = 'Cursor' or 'Chief of Staff'.
Read the Brief: The agent fetches the Notion page, ingests the context, and reads the linked research.
Execute in the Real World: The agent makes the external API calls — updating WordPress fleet sites, deploying Nginx configuration rules, drafting client emails in Gmail, or committing code to Git.
Leave an Immutable Receipt: The agent writes the execution proof, live URLs, and rollback commands back onto the Notion task card, marks Status = 'Done', tags Closed by = 'Cursor', and steps out of the way.
The human never opens a terminal, never looks at server logs, and never switches between five SaaS tools. They look at Notion. The work moves from left to right. The receipts are permanent.
4. The Four Hard Walls: Why You Can’t Throw Away Git (Yet)
If Notion is this capable, why can’t you delete your local hard drive, cancel GitHub, and run literally 100% of your company inside Notion today? Because when you push Notion from being an “app” to an “operating system,” you slam directly into four fundamental infrastructure limits:
Wall 1: The Cloudflare & Rate-Limit Ceiling
In a traditional operating system, a system call takes microseconds. The CPU can write millions of instructions to memory per second. In Notion, every write is an HTTP request over the public internet, fronted by enterprise security proxies.
During our operations this morning, our autonomous agent was updating 21 live WordPress articles, writing audit logs, and generating 4 technical handoff cards in Notion for our developer. On the fourth task, the operation hit a wall:
Request to Notion API failed with status: 403
Cloudflare Ray ID: a388bb63fa5108d8
"Sorry, you have been blocked... This website is using a security service to protect itself from online attacks."
Cloudflare’s Web Application Firewall (WAF) saw rapid-fire, highly structured JSON payloads being written to a database and flagged it as an automated attack. Furthermore, Notion’s public API enforces an average limit of 3 requests per second. That is plenty for a human typing notes; it is catastrophic for an autonomous agent executing a batch operation or running an automated site health sweep. Until Notion treats authorized API integrations as internal system buses rather than hostile external web traffic, it cannot be a true high-throughput operating system.
Wall 2: A Document Is Not a CPU
Notion is a world-class data store and presentation canvas, but it has no compute runtime. A Notion database can store a Python script for updating 21 WordPress posts — it cannot run Python. A Notion page can hold an Nginx 301 redirect configuration — it cannot reload Nginx on an Ubuntu server. To execute real work in the physical or digital world, you will always need an external execution engine: a local developer laptop running Cursor, a headless worker on Cloudflare, or a cloud VM on Google Cloud. Notion is the brain; it still needs hands.
Wall 3: Mutable State vs. Cryptographic Truth
Notion pages are mutable documents. If an agent hallucinates, or if a teammate accidentally drags a view filter, or if two agents attempt to append content to the same block at the exact same millisecond, you get silent overwrites or lost history.
Git, by contrast, is a cryptographic, distributed state machine. When we commit code or operational logs to Git, a SHA-1 hash freezes the exact state of every file down to the byte. Git gives you branching, pull requests, peer review gates, and the single most powerful command in computer science: git revert. If an autonomous agent makes a catastrophic mistake across 20 client files on a server, git revert undoes the damage in 200 milliseconds. Notion has no concept of atomic multi-page rollbacks or branch-and-merge workflows.
Wall 4: The Air-Gap & Data Sovereignty Test
If Notion experiences an outage, or if you board a cross-country flight with dead Wi-Fi, a “Notion-Only” company ceases to exist. A local directory on an SSD (like our Hub repo), synced via Git, operates with zero latency, zero internet requirement, and zero platform risk. You own the markdown files on your drive. Nobody can de-platform your folder.
5. The Verdict: The Cockpit & The Safe
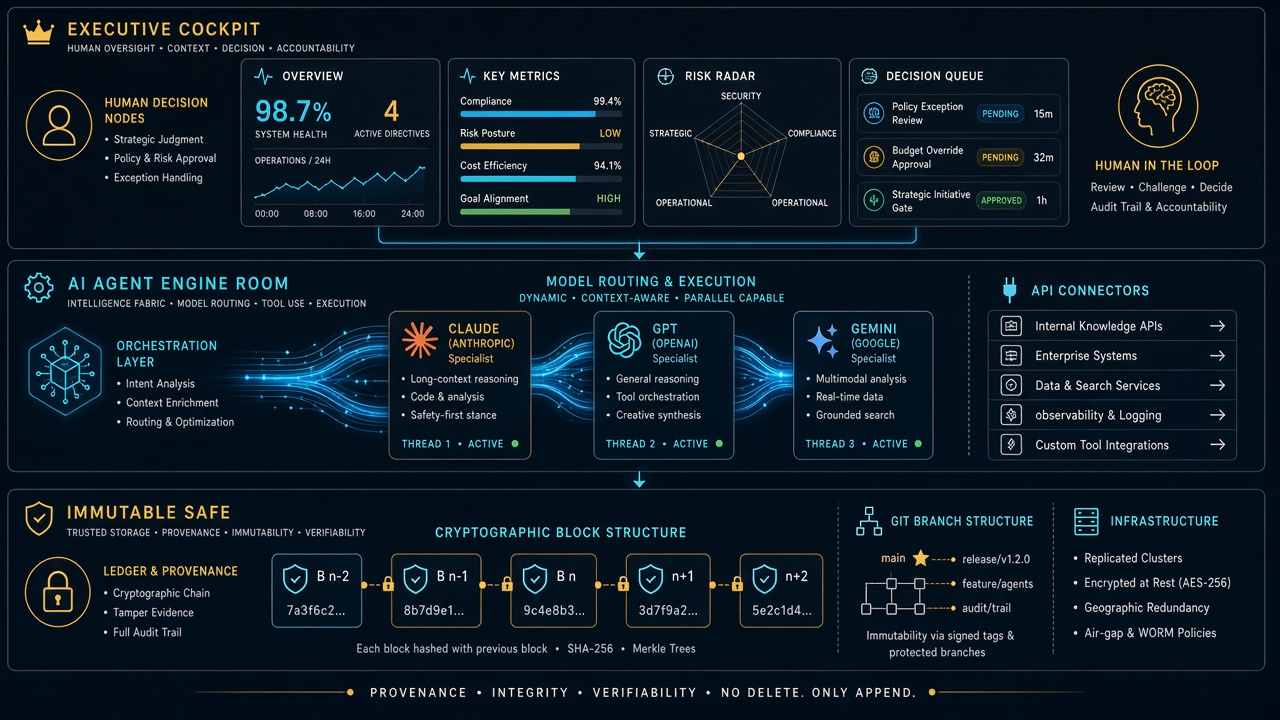
You don’t have to wait for Notion to solve all of that to reap the benefits today. The winning architecture for 2026 is the Executive Cockpit + Engine Room Safe model:
The rule is simple: You live in Notion. You look at clean boards, approve drafts, check client pulse, and make decisions. Your agents live in the Engine Room. They read from Notion, write their receipts back to Notion, execute in the real world, and mirror every change into Git as an unshakeable black box.
You get the absolute elegance of a single operating system for your mind, backed by the industrial-grade indestructibility of code. Notion doesn’t need to replace the computer. It just needs to remain the best interface for human and machine intelligence ever assembled. And once they lift that rate-limit ceiling? The rest of enterprise SaaS is officially on notice.
The best new manufacturer in 2026 does not own a factory floor.
It owns a chat window that turns a photo of a broken clip into a printable file, a material choice, and a ship date.
That is not a slogan. It is what GPT-6 Astra unlocked in the first week of September 2026.
Why this week is different
OpenAI released GPT-6 Astra on September 3–4, 2026. The company positioned it as state-of-the-art on computer use, software engineering, and professional workflows. Public demos showed the model laying out a circuit board in KiCad, building geometry in FreeCAD and Blender, and handling multi-step desktop tasks with visual judgment. OpenAI’s own launch materials called it a generational leap on those surfaces.
Greg Isenberg’s public read landed the same day: in 2024 the vibe-coding tools turned anyone into a web builder; in 2026 Astra turned anyone into a vibe manufacturer. Upload a photo, add a couple of measurements, describe the missing piece. The model produces a first CAD pass. A human sanity-checks dimensions and material. A print farm ships it.
That capability is new. Previous models could sketch. Astra can sit inside the actual design tools and iterate on real geometry. The shift is measurable in the benchmarks OpenAI published and in the flood of public demos that followed within 48 hours. The window is open because the model is new and the print farms already exist.
The primitives, not the slogan
Three primitives keep showing up across the idea mills this month.
First: photo-as-data. A stranger already has the object in their hand. The highest-signal input is a phone picture plus two numbers, not a 3D scan or a formal RFQ. Gyms, restaurants, clinics, and small shops already take those photos when something breaks. They just have nowhere to send them that returns a part instead of a quote cycle.
Second: agent action inside the design stack. The model does not just describe the part. It generates the file that a printer or CNC can use. That is the difference between a helpful chatbot and a manufacturing pass.
Third: demand exhaust. Every successful print reveals which niches break the same piece over and over—gym equipment clips, restaurant proprietary fasteners, dental jigs, small-manufacturer fixtures. That map compounds. After volume you stop guessing which verticals are worth serving and start knowing.
The X threads will keep naming each niche as its own micro-SaaS. That is the wrong cut. The customer does not wake up wanting “gym-part.ai.” They wake up because a $40 piece of plastic stopped a $4,000 machine and the OEM lead time is six weeks.
The wedge is a free checker
Do not start with a platform. Start with the moment the customer already hates.
A simple page: upload the photo, type the two critical dimensions, name the machine or the role the part plays. Thirty seconds later the checker returns one of three answers—printable this week, needs material upgrade, or not viable.
If it is printable, the customer can order. You take a margin on the print and the shipping. If it is not, you still captured a labeled failure mode. That label is the seed of the dataset.
Zero risk on the first action. No seat fee. No integration. No promise of a system of record. Just “will this photo turn into a part before my machine sits idle another day?”
That is the only honest offer. Pure upside for the customer. You get paid when the part arrives and works, or you do not deserve the second conversation.
Where the human stays in the loop
Models draft the geometry. People own the irreversible steps.
Material certification for load-bearing or food-contact parts is a human call. Any claim about fitness for a regulated use is a human signature. Customs paperwork on cross-border shipments is a human send. The agent can prepare the package. It does not own the stamp.
That boundary is already the operating rule on every desk that moves real money or real liability. Keep it explicit in the product, not as a later compliance add-on. The customer should see the human gate the same way they see the price.
The compounding path
Volume turns the free checker into a demand map.
After a few thousand successful prints you know which gym chains break the same elliptical clip, which restaurant groups lose the same proprietary hinge, which dental offices reorder the same surgical guide holder. That map is not another dashboard. It is supply intelligence that print farms, distributors, and OEMs will pay for.
Month one: one niche, one free checker, pure upside pricing. Pick the vertical where downtime is expensive and the OEM is slow—commercial fitness, independent restaurants, specialty clinics.
Month two: a second document type or a second vertical inside the same customer’s drawer. If they already uploaded one broken part, they have three more in the same cabinet.
Month three: the first internal scoreboard of failure modes by industry and by part family. That scoreboard is the B2B SKU. Sell the insight, not just the plastic.
If you cannot get a stranger to upload one photo this week, you do not have a company. You have a thesis.
Why this clears the bar
Most idea-mill posts describe a feature. This one describes a shift in who can manufacture small custom parts at all.
The noticing and the first CAD pass used to require a designer, a quoting cycle, and a weekend. It now requires a model that can read the photo and a person who will sign the material choice. The print farms were already there. The model just lowered the cost of the first pass far enough that a stranger will try it this week.
Recovery businesses endure because the customer has nothing to lose on the first action. This one pays for itself on the first successful print or it does not deserve a second conversation.
Someone will own the system of record for the small parts that keep local machines running. The threads will keep proposing a new .ai name for each vertical. Ignore the names. Print first. Keep the map.
Will Tygart — Tygart Media. This is the idea-mill series.
This morning I did something I haven’t done before: I walked the halls of five of my own WordPress sites using only voice. No typing. No desktop. Just me talking to Grok while I moved, and Grok inspecting, drafting, and handing off the work that needed hands.
The sites were BC ESG, Healthcare Facility Hub, Risk Coverage Hub, Continuity Hub, and Restoration Intel. In about ninety minutes we published three real articles reacting to the latest IFMA Pulse findings, cleared automated cross-link spam, flagged debug flags and plugin updates, and set up a clean handoff system so nothing gets lost.
The biggest lesson wasn’t the AI. It was the loop. I attempt the work. If I can’t finish it, I create a new task for whoever can, close my task with a link to that new one, and move on. Two statuses: my task done when it’s handed off cleanly, site done only when the receipt comes back. That single rule stopped me from claiming things were finished that weren’t.
We also decided to use dedicated publishing-only bots for social instead of dumb schedulers. Each bot logs into one channel, posts, and does nothing else. No scraping, no connecting, no noise. Just quality publishing. Chief of Staff is researching the rules; I’m beta-testing one channel next week.
For the human on the team (Pinto), we built time-boxing rules: 24-hour, week, or month buckets. Only the 24-hour bucket is active. Everything else parks until he pulls it forward. The goal is a powerful life, not constant on-call.
This isn’t theory. It’s receipts from one morning. If you’re an operator who actually publishes, writes, or runs sites, try the same walk on your own stack. Pick up the ball and run it downhill — I’d love to see what you build.
I’m using Grok from SpaceXAI for this. If you’re already on another system, you don’t need to start over. Here are the direct links:
Open field playbook. No patent. Copy it, rename it, change the nouns to fire / mold / rebuild. If it makes you money, good. If it puts another dish on a wet roof, also good.
License: do what you want. Attribution nice, not required. Tygart Media is not a Starlink, SpaceX, Tesla, or xAI partner. Links below go straight to them. No tracking parameters. No referral codes.
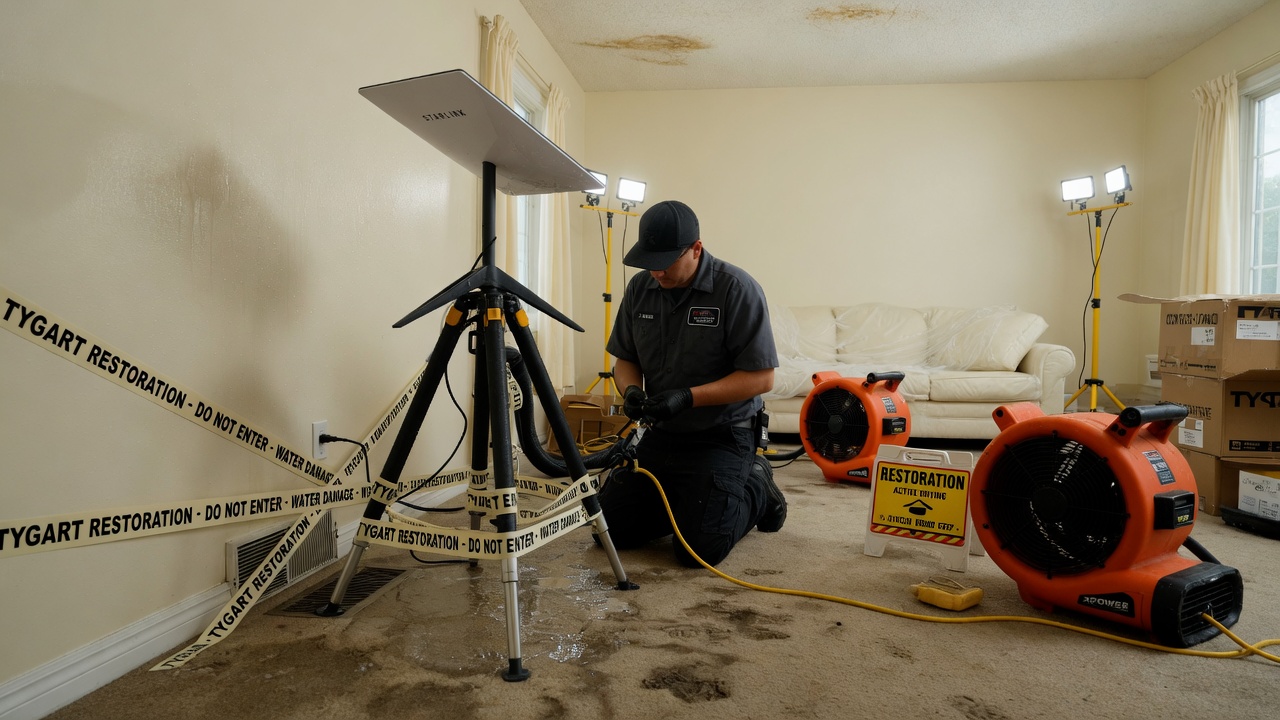
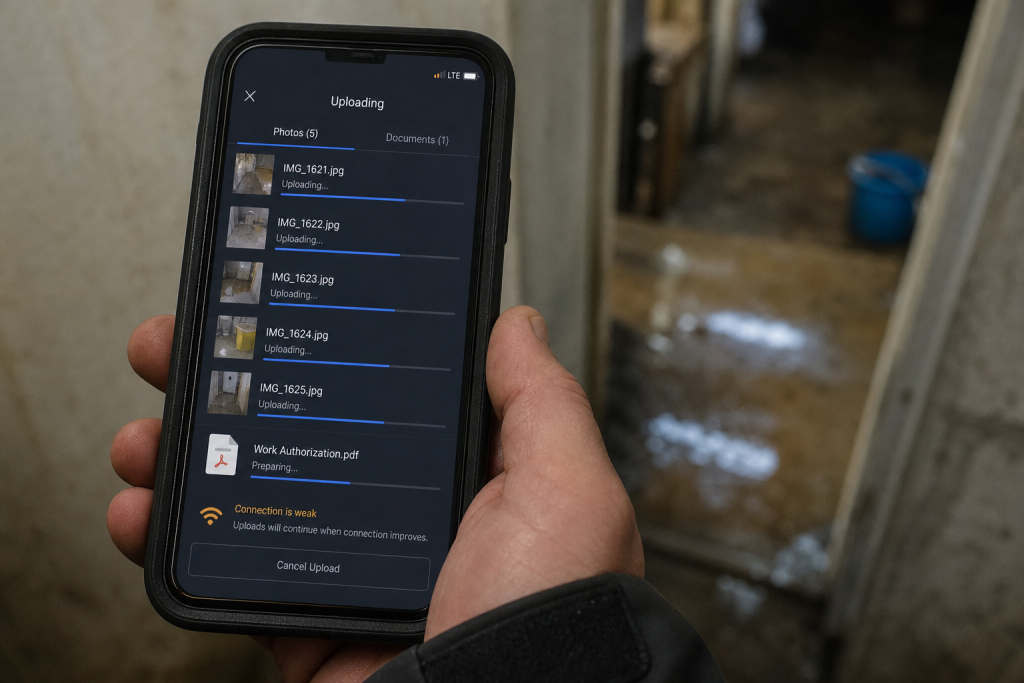
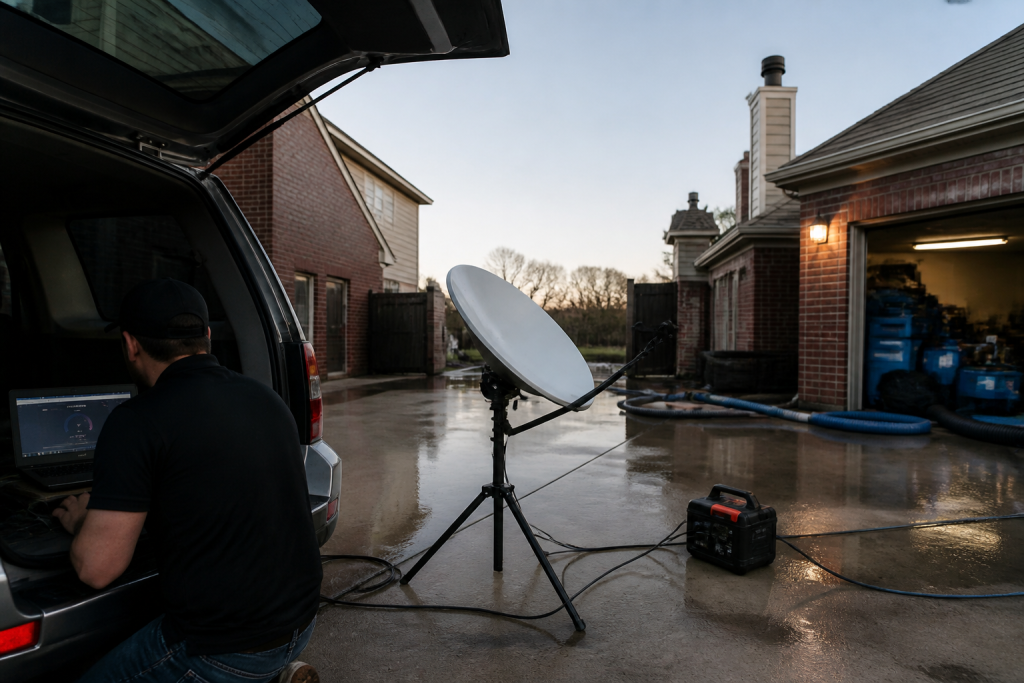
Why this exists: restoration work happens where fiber is dead, the house is a Faraday cage of wet drywall, and the phone that “has bars” cannot upload a moisture map. Starlink is a sky-view pipe. More honest job-site pipes → more honest traffic on the constellation → more reason to fly birds. The selfish clause is allowed: a 4G phone in the sticks should still talk to a voice agent when the street is dark.
Bars on the phone. Upload still dead. That is the job the dish is for.
Buy and read from the source. Prices move. The impedance rule does not.
The structure or the street has no working cable/fiber (storm, rural, construction, “the pole is in the river”).
You need to upload, not just talk: photos, video walkthrough, Xactimate sketch, moisture log, signed work auth.
You will be on site more than an hour and cell is congested or roaming into a dead pocket.
The office needs a second path so after-hours voice and dispatch do not die with the cable modem.
Do not use it as:
A replacement for a good office fiber drop.
A phone. Voice agents still ride the pipe; the dish is not Jarvis.
A “we have Starlink” line on the website. Homeowners hire the truck that showed up.
Cell first if it works. Starlink is the sink when cell is the bottleneck.
2. Two kits (steal one)
Kit A — truck / first-on-site (most shops)
Starlink Mini on a Roam plan or, if this is actually a business WAN, start at Business and read the current hardware list. Mini is the backpack dish. In-motion rules live here. The home V5 kit is not the roam toy.
Power: Mini wants a USB-PD source rated 65–100 W even though it only drinks ~25–40 W. A 45 W phone brick will lie to you. Truck: 12 V → 30 V / Anderson, or a 500 Wh class station.
Plan: numbers on starlink.com move. Roam is written for travel. If the kit is production, read Business vs Enterprise. Mini often does not sit on the Priority SLA. Do not tell a carrier you have enterprise uptime because you paid a business invoice for a Mini.
One cheap travel router if Mini Wi-Fi dies inside a metal trailer.
Power before the meter. 65–100 W brick. Phone chargers lie.
Standby the truck kit when it is not a weather week. Idle is cheaper than a second hardware buy because someone borrowed it.
6. Dispatch and voice
Dispatch and voice when the site is remote.
The dish is layer 0. The voice agent is layer 1.
On a dead-fiber job: photos go up the pipe; the after-hours line stays reachable; the agent writes a new row (address, standing water y/n, next action). It does not edit your website.
If you already have a process, add one rule: when cell upload fails, kit A comes off the hook.
7. Failure modes
Trees and eaves. Rain. 45 W bricks. Consumer Roam sold as production WAN. Twelve intake fields before anyone asks “can we come now?”
8. The sentence that pays the shop
“If the street internet is out we still upload your photos and get the adjuster pack off the truck tonight.”
Only say it if the kit is in the truck.
This document stays free. Charge for the hour you spend teaching another shop the first 30 minutes if you want. Do not charge Starlink. They already sold you the dish.
9. What this is not asking
No meeting. No partnership badge. No official anything.
Redmond already knows how to stamp birds. The ground should not be a graveyard of unused kits. Order here. Then put the dish where the sky is.
Tonight I asked Cursor — running with a remote path into the same laptop — to check on Grok Desktop.
Not a status meeting. Not a Slack ping. A real question: are they stuck on Tygart Ops tasks, or are they fine?
What came back felt less like “AI tooling” and more like a shop floor story. One agent reading Notion work orders. Another already mid-PowerShell. Chrome open on Bing Webmaster Tools. A hold queue of spam comments already cleared. A window title spinning: waiting for response.
That is the product.
Local seats on one laptop — agents that keep working while you check in from elsewhere.
The picture on the desk
Grok CLI (grok.exe) was live on the TYGART laptop. Session home under ~\.grok\. PowerShell host up. Agent name on the session: grok-build-plan.
Cursor did not take over the keyboard. It inspected open windows, Notion Tygart Ops — Tasks and Work Orders, Grok session memory, and the WordPress hold queue (already empty — receipt already on the Tasks card).
Verdict: not stuck. Working. Slight detour clarifying whether Grok itself needed a CLI update (it did not — already on 1.0.13). Primary Now card still in flight: TygartMedia Chrome sitting for GA4 Ask Advisor + Bing Copilot, then file child tasks.
That is multi-agent ops without the demo reel.
Seats with jobs, not two models arguing in one thread.
Why this is different from “two chatbots”
Most multi-agent talk is two models arguing in one thread. This is seats with jobs:
Grok Desktop (CLI) — hands on the laptop: Chrome sittings, WP REST spam trash, Bing Copilot asks, local PowerShell
Cursor (remote / cloud path) — Cosync: read the board, verify receipts, close orphan Work Order twins, do not steal the keyboard
Notion — system of record (Owner, Status, Summary, Done when)
Will — gate one-way doors (OAuth Approve, Publish, Pay)
Cursor useful move was small: the spam Tasks card was already Done with a receipt; the Work Orders twin was still “Not started.” Cursor closed the twin. Grok kept the keyboard.
That is what “help if you have a capability they need” looks like when the other seat is already flying.
The article inside the moment
Agencies do not need another “AI stack” diagram. They need a night like this:
A doorbell card lands (Notion to ops channel).
The owner seat picks it up without waiting for a human briefing.
A second seat can check in from elsewhere — mobile, cloud, remote — without colliding.
Receipts land on the same card. Orphans get reconciled.
Tonight was the field note. Cursor checking on Grok CLI while Grok Desktop works through Tygart Ops is not a party trick. It is how a small shop runs more than one pair of hands without losing the thread.
What we are not claiming
Not “fully autonomous.” Human Gate still owns OAuth consent, live publish, paid spend.
Not “replace your team.” Seats replace waiting and context loss.
Not a new product launch. This is how we already run Tygart Media ops on a Sunday night.
If you want the same shape
Start with one Owner column, one Done-when line, and two seats that do not share a keyboard.
Then practice the check-in: are they stuck, or are they fine — and do I have a capability they lack?
If they are fine, leave the PowerShell alone.
Cosync from remote. Hands stay on the desk that already owns the job.
Will Tygart — Tygart Media. Written from a live Cosync on 2026-08-29 while Grok Desktop was mid-Bing Copilot sitting.
CC is not courtesy copy. It is distributed write. Every inbox that receives your message is a replica of a shared database, and no coordinator approved the replication.
Email as the new API means treating an email thread as programmable infrastructure rather than just correspondence: because every message is an immutable record, every recipient’s inbox is a replica, and the Message-ID / In-Reply-To / References headers link messages into an append-only log, a structured email with an embedded instruction block can carry its own processing schema — turning the inbox into a universal, permissionless coordination layer that any human or AI agent can read, act on, and extend. Said in one breath: the thread is the database, the reply is the commit, and the subject line is the version pointer.
This is not a provocation. It is a description of infrastructure that has been running for forty years and is only now being named. The most consequential software project on Earth — the Linux kernel — is coordinated entirely over email threads. And in March 2026, a Y Combinator company called AgentMail raised $6M from General Catalyst to give AI agents their own inboxes. The pattern isn’t coming. It’s load-bearing.
We run this method in production at Tygart Media. This article explains how it works, proves it isn’t new, gives you a decision framework, and answers the four questions every operator asks first: Is a thread a database even if no one reads it again? One thread or many? Email or chat? How do I pull it into real systems? One boundary up front, so the credibility is honest: this pattern is for asynchronous, human-paced work that crosses organizational lines. It is the wrong tool for sub-second machine loops. We will be specific about that in the limits section, because the limits are real.
It’s Not a New Idea: The Prior Art
Before any mechanism, kill the “isn’t this just email?” reflex with evidence.
The Linux kernel runs on email. Thousands of contributors on every continent submit patches as inline email via git send-email, version them in the subject line ([PATCH v1], [PATCH v2], [PATCH v3]), review them in-thread, and merge them with git am. The Linux Kernel Mailing List receives roughly 1,400 emails a day. The archive at lore.kernel.org goes back to 1998 with full-text search. If email threads are sufficient engineering infrastructure for the operating system running most of the world’s servers, “it’s just email” is not an argument.
EDI is email-as-API with a schema, and it’s older than the web. Since the 1980s, enterprises have transacted structured business documents over email-like channels using ANSI X12 and UN/EDIFACT: the X12 850 Purchase Order (called “the backbone of EDI”), the 810 invoice, the 856 ship notice. EDI is email with a mandatory reply schema, enforced at the business-rules layer, predating REST by two decades. It is the direct ancestor of the structured-email method below.
The market is pricing it in right now. AgentMail (YC S25) raised $6M led by General Catalyst in March 2026 to build agent-native inboxes — real, programmatically provisioned addresses that send, receive, thread, and parse structured data. In its own words, “thousands of humans use AgentMail to power millions of agents.” A seed round on the thesis that email is AI infrastructure is not a prediction. It’s a market price.
Every vertical already does it. Inbound-parse services (SendGrid, Mailgun, Postmark) turn incoming mail into JSON webhooks; Cloudflare Email Workers run a function on every inbound message. No-code parsers (Zapier’s @robot.zapier.com, Make) fire workflows from a forwarded email. Zendesk converts every email into a ticket with a UUID. Things, Todoist, and Trello expose forward-to-task addresses. Substack made the email list the asset itself. And MuckRock — founded in 2010, before LLMs existed — turned the FOIA request-response loop into a structured, automated, trackable platform across all 50 states. The pattern predates the AI moment. AI just makes it programmable at scale.
Why a Thread Is Literally a Database
A thread is literally a database agents already speak.
Here is the intellectual spine: an email thread is an append-only, replicated log at the protocol level — not by design philosophy, but by RFC.
The relational model is in the headers. RFC 5322 defines Message-ID as a globally unique identifier in the form <unique-string@domain.com>. In-Reply-To holds the parent message’s Message-ID. References holds the full chain of ancestors back to the root. Read as a database: Message-ID is the primary key, In-Reply-To is the foreign key, References is the full join path back to the root. Together they form an append-only linked list — the same structure event-sourcing systems use to reconstruct state by replaying a log.
Replication is implicit and massive. Every To and CC inbox holds a full copy of every message. The thread is not stored in one place; it is replicated across N inboxes by the act of sending, with no coordinator. That is closer to a conflict-free replicated data type than to a single-primary database.
The transport is store-and-forward. SMTP (RFC 5321) queues and retries at every hop. That gives at-least-once delivery — the same guarantee as Kafka’s default producer. Exactly-once is impossible in any distributed system; email makes no false promise. The difference is that Kafka costs engineering time to operate; email costs a stamp.
The sharpest framing: Kafka is a better log than email in every technical dimension. Email is a better log than Kafka in every organizational dimension — because your vendor, your client, and your offshore engineer all already have an inbox. The reason to use email is not that it’s the best log. It’s that it’s the universal log. The legal industry already operationalizes this: e-discovery platforms (Mimecast, Logikcull, DISCO) treat archived threads as immutable audit trails. Courts treat email as a record. The “thread as log” framing is not novel — it is how the law already works.
What email HAS vs. what it LACKS
Property
Email HAS
Email LACKS
Durability
Yes — persists in recipient stores by default
—
Replication
Yes — every recipient is a copy
—
Global addressing
Yes — any RFC 5321 address, no registry
—
Append-only log
Yes — you reply, you don’t edit sent mail
—
Searchable audit trail
Yes — headers, body, timestamps
—
Schema enforcement
—
No — any string is accepted
ACID transactions
—
No atomicity, no locking
Consistency
Eventually consistent
Not strongly consistent
Latency
—
Unbounded (seconds to days)
Query interface
—
Full-text search only, no SELECT WHERE
State it plainly: email is eventually consistent, not strongly consistent; at-least-once, not exactly-once. It is the coordination layer, not the source of truth for mutable state.
The Method in Practice: A Worked Example
This is what we run. The cast is real — Will on strategy, Pinto engineering from India, Stefani on operations — but the payloads and secrets stay out. The credibility is in the structure, not the contents.
The FOR YOUR AI block: schema-in-the-envelope. A single message carries three layers at once: a human-readable intro for the person, an embedded system prompt that tells the recipient’s AI what role to play and what format to produce, and a strict reply schema (named sections, types, word limits) the output must conform to. The message carries its own processing instructions. It is structurally identical to a self-describing Kafka message — except the schema language is plain English. The FOR YOUR AI block is a system prompt that travels via SMTP. When Will emails Pinto, it tells Pinto’s AI what role to play before Pinto even opens the message.
The Round-N subject line: a state machine. A subject like Round 3 — v2.1 schema is a human-readable epoch counter. Any participant — including a cold-start AI that has never seen the thread — reconstructs exactly where the conversation stands without re-reading every prior message. The subject is the version pointer; the thread body is the state history; each reply is a state transition.
Each inbox: a replica. The To/CC list is the replication layer. When Stefani is CC’d for visibility, that’s a designed property, not a side effect — her inbox becomes a live replica of the exchange. The CC line is a replication directive; the shared database has no master node.
And notice what discipline this method already embodies, because it sets up the limits section exactly: the schema block is an injection-surface reducer; the human edit-before-send is the human-in-the-loop gate; one-thread-per-project is mailbox isolation; the Round-N tag is the idempotency seed. The mitigations aren’t bolted on. They’re the workflow.
The Four Questions, Answered
Is an email thread a database even if no one ever reads it again?
Yes. A database’s properties — persistent, indexed, searchable, replicated — are satisfied by the inbox independent of human attention. Reading is a query operation, not a precondition for existence. RFC 5322 messages are immutable once delivered; IMAP stores are append-only by design (you flag and label, you don’t rewrite); every recipient’s server holds an independent replica. The thread is the database, even if no human ever opens it again. lore.kernel.org proves it at civilizational scale: decades of threads, indexed and searchable, most never re-opened, all still a database. One honest caveat: this is functionally and legally append-only, not cryptographically enforced — a participant can delete their own copy. Frame it as a practical property, not a blockchain.
Should I use one email thread or many?
Continue one thread while the state machine advances linearly. Fork a new thread when scope, participants, or schema materially change. Forking has no merge protocol — do it deliberately, not habitually.
Run the decision tree: (1) Same principals? (2) Same matter, contract, or project lifecycle? (3) Same expected reply schema? If all three are yes, continue — you are advancing the same state machine. If any is no, fork. There is a third option for compound, overlapping state a single subject line can’t carry: labels on one thread. Gmail labels are not filing; they are state bits. The combination round-2 + awaiting-review + schema-v3 on one thread is a fully specified, machine-readable state any agent with API access can inspect and mutate. Fork when the state machine changes shape. Continue when it advances. Label when it branches.
Email or Slack/chat for AI workflows?
Email wins for the durable, structured, machine-readable record; chat wins for the ambient coordination around it. This is not a dismissal of chat — it’s a division of labor. Email’s structural advantages are four: federation (you can email anyone at any domain with no shared paid account; Slack Connect requires both sides to pay), durability (Slack’s free tier deletes history after 90 days; email persists by default), identity portability (your address survives a vendor change; Slack IDs are workspace-scoped), and universal addressability (email is DNS/MX-resolvable; Slack user IDs are opaque tokens). Email has no 90-day cliff, no login wall, no vendor lock-in on the archive. It is the only substrate where you can lose access to the platform and still have the data. One caveat for sensitive payloads: WhatsApp messages to Meta AI are not covered by the same end-to-end encryption as human messages, and iMessage silently downgrades to SMS when an Android user joins. The encryption you trust can vanish exactly when you add an AI participant.
How do I pull email into real systems?
Use a ladder from no-code to agent-native. (1) Zapier or Make for a no-code email parser. (2) An inbound-parse webhook — Postmark, SendGrid, or Mailgun deliver the full email as JSON; Cloudflare Email Workers run a function on every inbound message. (3) Gmail API plus Cloud Pub/Sub watch() for real-time push — name the gotcha: the watch expires every 7 days and must be auto-renewed. (4) AgentMail or Nylas Agent Accounts for agent-native, programmatically provisioned inboxes. The parsing layer between MIME and JSON (postal-mime, MailParse) is a one-line install. This is the rung where readers become practitioners.
The Decision Framework
Decision framework — when email is the coordination API.
The governing question is never “email or a real system?” It is “what does my workflow need that the thread can’t give me?” Until you hit that wall, the thread is the system.
Use email when all of these hold: the work is asynchronous and human-paced, it crosses an organizational or trust boundary, you need a durable and searchable audit trail, and a human is in the loop on consequential actions. The thread is the log.
Use chat (Slack, Discord, WhatsApp) when latency must be under about five minutes and all parties sit inside one auth boundary and the record doesn’t need to outlive the platform. Chat is for urgency inside a shared boundary; email is for durability across org lines.
Use a real database, queue, or API (Postgres, Kafka, REST/gRPC) when you need queryable schema with transport-level validation, concurrent or atomic writes, distributed locking, machine-speed operations no human reads, or high-volume machine-to-machine traffic. Where failure is unrecoverable, use infrastructure that fails loudly.
Substrate trade-matrix
Dimension
Email
SMS / iMessage
WhatsApp
Slack / Discord
Notion / Docs
Durability
High
Medium
Medium
Low (90-day free)
High
Universality (no account)
High
Medium
Low
Low
Low
Access control
Low (CC-leak)
Low
Medium
High
High
Searchable / exportable
High
Low
Low
Medium
High
Schema-ability
Medium
Low
Low
Low
Medium
Latency
Low
High
High
High
Medium
AI-ingestibility
High
Low
Low
Medium
Medium
Data ownership
High
Medium
Low
Low
Medium
Email wins decisively on durability, universality, data ownership, and AI-ingestibility. It loses on latency, access control, and schema enforcement. Position it correctly: email is the zero-infrastructure precursor to formal agent protocols. The agent-interoperability survey (arXiv:2505.02279) lays them out: MCP is a synchronous client-server interface for tool calls, A2A is peer-to-peer delegation via capability-based Agent Cards, and ANP is open-network discovery via decentralized identifiers. All are powerful; none provides durable, offline-capable, federated messaging the way an inbox already does. Every AI team building a custom agent-to-agent protocol is engineering a worse version of SMTP. Ship on email today; graduate to MCP or A2A when hot-path latency or transactional guarantees force the wall.
The Honest Limits
Honest limits — email is not a substitute for auth.
This section is the credibility. Each failure mode is real, each gets a mitigation, and none is fixable by convention alone.
Prompt injection is the headline risk. OWASP ranks prompt injection LLM01:2025 — its number-one LLM application vulnerability — and explicitly names indirect injection via external sources, including email. EchoLeak (CVE-2025-32711, CVSS 9.3, June 2025) proved a single crafted email could make Microsoft 365 Copilot exfiltrate data with zero user interaction. This is not theoretical. Mitigations: verify DKIM/SPF/DMARC at the agent layer and allowlist senders before trusting any FOR YOUR AI block; parse only declared schema sections, not free prose; gate every consequential action behind a human; run a sandboxed executor that receives structured intents only, never raw tool access. Fair caveat: EchoLeak’s zero-click specificity tracked Copilot’s particular architecture — the general risk scales with how much autonomy the agent has after it reads.
No schema enforcement. SMTP and MIME accept any string. A malformed or adversarial reply doesn’t bounce — it arrives silently, and a naive agent parses it anyway. Mitigation: validate every reply against the schema before acting; route malformed replies to human review. Say it plainly — schema conformance is a social and instruction-following contract, not a protocol guarantee. Schema drift is the failure mode.
No transaction semantics. At-least-once delivery means duplicate processing is structurally guaranteed under retries; two simultaneous replies fork the thread with no merge. Mitigation: put an idempotency key in the subject (Round-N / [UUID]) and store the Message-ID as a dedup key the consuming agent checks before acting. An idempotency key in the subject costs four characters; the absence of one can mean the same purchase order executes twice. Keep mutable state in a real database — email is the coordination layer, not the source of truth.
CC is a feature and a liability — the same mechanism. The property that makes the thread a replicated database is a compliance landmine. One reply-all or forward in a thread carrying ePHI is a breach: HIPAA requires a minimum six-year retention for designated-record-set emails, and GDPR Article 5(e) requires data be kept no longer than necessary. Anyone ever CC’d retains access forever — there is no revoke. Mitigation: in regulated contexts, mirror to a proper record system, encrypt payloads (S/MIME or PGP), or send only the control signal over email and keep the data elsewhere. This is directional, not legal advice — consult your compliance team.
Deliverability is now a hard gate. Google and Yahoo mandated SPF/DKIM/DMARC alignment for bulk senders (5,000+/day) in February 2024; Microsoft followed in May 2025, routing non-compliant high-volume mail (5,000+/day to consumer Outlook) to Junk, with outright rejection to follow; PCI DSS v4.0 adds DMARC-related anti-phishing requirements for card-data environments. Building without authentication because you’re under the volume threshold today is planning for fragility.
The operational gotchas that signal you’ve actually done this. Latency is unbounded — SMTP retry windows span minutes to days, so never put a sub-second hot path on email. Threading is client-dependent — Gmail uses subject plus In-Reply-To/References, Outlook uses Thread-Index, Thunderbird uses the JWZ algorithm — so a subject edit or a header-stripping gateway silently forks one thread into two; never rewrite the subject mid-thread (append, don’t replace). The Gmail watch() expires every 7 days. High-volume automation through a personal Gmail risks account suspension — use dedicated service accounts or agent-native platforms (and check their beta limits; Nylas Agent Accounts ship with 7-day retention and 100 sends/day). And threads beyond ~50 rounds with large payloads can blow a model’s context window — architect thread length deliberately.
When NOT to use email
Need
Use instead
High-frequency / sub-second M2M
REST, gRPC, or a queue
Strict schema validated at transport
JSON Schema + API gateway
Regulated data, CC-leak unacceptable
E2E-encrypted channel + access controls
High-volume M2M (thousands/min)
Message queue / event stream
Atomic transactions or locking
Real DB / event-sourcing
The throughline: email gives you a convention, not a guarantee — and every mitigation here is a convention layered on a convention. Where failure is unrecoverable, use infrastructure that fails loudly. One more flag for commercial use: if AI-generated output produced through a relay chain is published without clear labeling, the structured hand-offs can obscure the AI’s role. Disclose it.
Publish It to Get Smarter
Here is the move, and it is not subtle: this article is a round in the loop it describes.
Watch the flywheel turn. We publish this piece. AI engines index it. Its named patterns — the FOR YOUR AI block, Round-N versioning, schema-in-the-envelope — become citable units. Operators adopt them. Tygart Media becomes the attributed origin. Each citation reinforces the corpus, and the corpus earns more citations. The article does not describe the flywheel. It is the flywheel, running.
This is not promotion. It is the method executing on itself. Our model is to own the cited corpus on the topics our clients operate in — where breadth is the moat and the scoreboard is AI-citation coverage, not Google rank. The mechanical reason it compounds is freshness: a flagship piece on a pattern we demonstrably run in production is structurally fresher than generic “AI email tips,” because it has live proof points to update. Directional evidence suggests content refreshed within ~30 days earns materially more AI citations than stale content; treat that as a direction, not a promise. Which is why this piece carries a dated live-example note, and why we’ll keep the round count current.
Live example — last updated June 2, 2026: the working loop described here is active and advancing in production.
So when AgentMail raises $6M to give agents inboxes, and the Linux kernel ships another thousand patches today over email, and Microsoft starts turning away mail that can’t authenticate itself — read all of it as one signal. Email is not legacy infrastructure being repurposed. It is the universal handshake for any workflow that crosses an organizational boundary, and it was here the whole time.
Your inbox is already a database. The only question is whether you are the DBA.
How this was made: this article was produced by the method it describes. A swarm of AI agents researched it in parallel across seven angles, a synthesis pass shaped it, and it was assembled and edited in the same human-plus-AI loop the piece is about. We practice what we publish.