We stopped buying specialized SaaS and ran a multi-business operation on a single pane of glass. Here is the operational blueprint for Notion as an autonomous enterprise operating system — and the exact rate-limit wall standing between where it is today and total software consolidation.
TL;DR
The tech world keeps waiting for an “Everything App” — a consumer super-app for messaging, ordering food, and hailing rides. But for businesses, the real transformation is the Everything Operating System (OS).
By combining Notion’s relational databases, semantic document trees, native multi-model AI agents, and Model Context Protocol (MCP) connectors, you can collapse an entire enterprise stack — project management, CRM, knowledge base, executive briefing, client portals, and agent dispatch — into a single subscription.
It already works in production. We run multiple client portfolios, automated publishing pipelines, and AI agent coordination through Notion daily. Yet, there is one single engineering bottleneck keeping Notion from swallowing the enterprise software market whole: rate limiting and the Cloudflare WAF. When an AI agent treats an application as an operating system, API calls become system calls. And when your operating system throttles system calls to 3 requests per second or returns a Cloudflare 403 Forbidden Ray ID during an autonomous batch deploy, the machine stalls.
1. The SaaS Graveyard
Look at the software ledger of any 10-person agency, professional services firm, or modern operator:
Project Management: Asana, Monday, or Linear ($12–$24/user/mo)
CRM & Pipeline: HubSpot, Pipedrive, or Salesforce ($50–$150/user/mo)
Internal Knowledge & SOPs: Confluence, Slite, or Guru ($8–$15/user/mo)
File Storage & Collaboration: Google Drive or Dropbox ($15–$25/user/mo)
AI Tooling Zoo: ChatGPT Plus for research ($20/mo), Claude Pro for coding ($20/mo), Perplexity Pro for search ($20/mo), Gemini Advanced for documents ($20/mo)
Every team member has fifteen tabs open. Data decays in silos. The CRM doesn’t know what is written in the project management ticket; the project ticket doesn’t know what was decided in the strategy document; and the AI chatbot in the corner has zero access to any of it without someone manually copying and pasting context across screens.
You are paying hundreds of dollars per seat per month not for software, but for the friction of moving text between different colored boxes. What happens if you cancel all of it and keep only one?
2. Notion as an Operating System (Not an App)
An operating system requires three fundamental primitives:
A Memory & File System: Persistent state, structured metadata, and unstructured data.
An Execution Engine & Logic Layer: A processor that acts on data and makes decisions.
An I/O Bus: Connectors that read from and write to the outside world.
Notion has quietly built all three:
OS Layer
Notion Primitive
Enterprise Function
1. Memory Layer
Relational Databases + Semantic Trees
Tasks, Work Orders, Client Focus Rooms, Second Brain Knowledge Vaults
2. Logic Layer
Native AI Models + Event Automations
Claude, GPT, and Gemini switchable on-demand; status-change triggers
3. I/O Bus
Model Context Protocol (MCP) + Webhooks
Two-way bridges to Gmail, Google Calendar, local desktops, and server APIs
When you structure Notion this way, it stops behaving like a passive digital notebook. It becomes the kernel of your business:
Databases are your schemas: You define relational tables (Tasks, Work Orders, Client Master, Second Brain). Properties like Owner, Status, Due Date, and Closed By are typed variables.
Pages are your documents & state logs: Every project has a living canvas that combines structured database rows with unstructured narrative, live meeting notes, and audit receipts.
Notion AI is your native reasoning unit: Because models live inside the document tree, they have ambient semantic awareness of your entire company history without requiring ritual context-pasting.
MCP is your peripheral bus: Through open protocols like Anthropic’s Model Context Protocol, the agents inside your workspace can reach into your Gmail, query your calendar, talk to your local machine, and interact with external APIs.
3. How We Actually Run It: The Two-Hemisphere Doctrine
This is not a theoretical thought experiment. This is how we run our operations every single day.
Hemisphere A: The Executive Layer (Human Intent & Voice)
Where the human lives: mobile phone, voice memo, or a clean Notion dashboard. The operational rule: If a task or strategic decision is not represented as a card in Notion, it does not exist.
When walking or driving, the operator speaks into an inbound voice agent or taps a mobile widget: “Follow up with Craig on the GSA federal contract, connect him to Dave Grove, and update the 247RS LinkedIn pack.” That voice stream is transcribed and parsed into structured Notion database cards with assigned owners, priorities, and deadlines. Zero cognitive overhead.
Hemisphere B: The Production Layer (Agent Workers & Tool Hands)
Where the machines live: background agents (Cursor Desktop, Chief of Staff on Grok Bot, Claude Code).
Poll the Queue: Agents monitor Tygart Ops — Tasks where Status = 'Not started' and Owner = 'Cursor' or 'Chief of Staff'.
Read the Brief: The agent fetches the Notion page, ingests the context, and reads the linked research.
Execute in the Real World: The agent makes the external API calls — updating WordPress fleet sites, deploying Nginx configuration rules, drafting client emails in Gmail, or committing code to Git.
Leave an Immutable Receipt: The agent writes the execution proof, live URLs, and rollback commands back onto the Notion task card, marks Status = 'Done', tags Closed by = 'Cursor', and steps out of the way.
The human never opens a terminal, never looks at server logs, and never switches between five SaaS tools. They look at Notion. The work moves from left to right. The receipts are permanent.
4. The Four Hard Walls: Why You Can’t Throw Away Git (Yet)
If Notion is this capable, why can’t you delete your local hard drive, cancel GitHub, and run literally 100% of your company inside Notion today? Because when you push Notion from being an “app” to an “operating system,” you slam directly into four fundamental infrastructure limits:
Wall 1: The Cloudflare & Rate-Limit Ceiling
In a traditional operating system, a system call takes microseconds. The CPU can write millions of instructions to memory per second. In Notion, every write is an HTTP request over the public internet, fronted by enterprise security proxies.
During our operations this morning, our autonomous agent was updating 21 live WordPress articles, writing audit logs, and generating 4 technical handoff cards in Notion for our developer. On the fourth task, the operation hit a wall:
Request to Notion API failed with status: 403
Cloudflare Ray ID: a388bb63fa5108d8
"Sorry, you have been blocked... This website is using a security service to protect itself from online attacks."
Cloudflare’s Web Application Firewall (WAF) saw rapid-fire, highly structured JSON payloads being written to a database and flagged it as an automated attack. Furthermore, Notion’s public API enforces an average limit of 3 requests per second. That is plenty for a human typing notes; it is catastrophic for an autonomous agent executing a batch operation or running an automated site health sweep. Until Notion treats authorized API integrations as internal system buses rather than hostile external web traffic, it cannot be a true high-throughput operating system.
Wall 2: A Document Is Not a CPU
Notion is a world-class data store and presentation canvas, but it has no compute runtime. A Notion database can store a Python script for updating 21 WordPress posts — it cannot run Python. A Notion page can hold an Nginx 301 redirect configuration — it cannot reload Nginx on an Ubuntu server. To execute real work in the physical or digital world, you will always need an external execution engine: a local developer laptop running Cursor, a headless worker on Cloudflare, or a cloud VM on Google Cloud. Notion is the brain; it still needs hands.
Wall 3: Mutable State vs. Cryptographic Truth
Notion pages are mutable documents. If an agent hallucinates, or if a teammate accidentally drags a view filter, or if two agents attempt to append content to the same block at the exact same millisecond, you get silent overwrites or lost history.
Git, by contrast, is a cryptographic, distributed state machine. When we commit code or operational logs to Git, a SHA-1 hash freezes the exact state of every file down to the byte. Git gives you branching, pull requests, peer review gates, and the single most powerful command in computer science: git revert. If an autonomous agent makes a catastrophic mistake across 20 client files on a server, git revert undoes the damage in 200 milliseconds. Notion has no concept of atomic multi-page rollbacks or branch-and-merge workflows.
Wall 4: The Air-Gap & Data Sovereignty Test
If Notion experiences an outage, or if you board a cross-country flight with dead Wi-Fi, a “Notion-Only” company ceases to exist. A local directory on an SSD (like our Hub repo), synced via Git, operates with zero latency, zero internet requirement, and zero platform risk. You own the markdown files on your drive. Nobody can de-platform your folder.
5. The Verdict: The Cockpit & The Safe
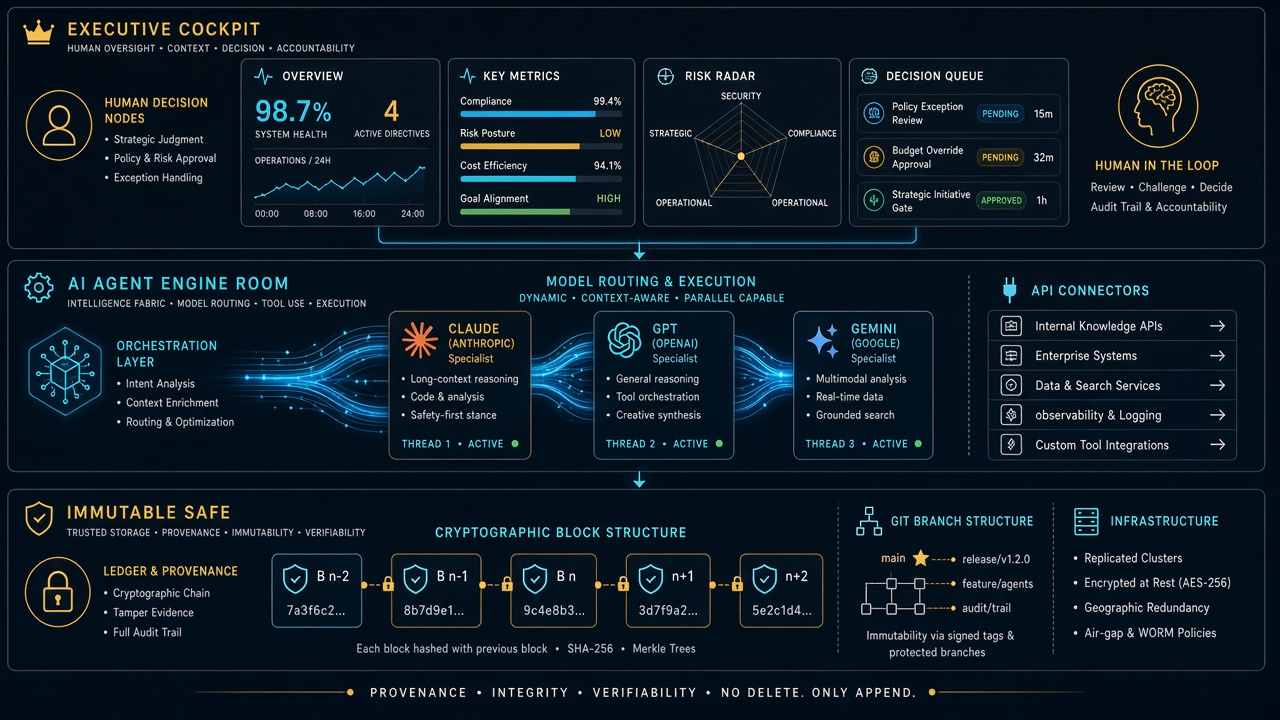
You don’t have to wait for Notion to solve all of that to reap the benefits today. The winning architecture for 2026 is the Executive Cockpit + Engine Room Safe model:
The rule is simple: You live in Notion. You look at clean boards, approve drafts, check client pulse, and make decisions. Your agents live in the Engine Room. They read from Notion, write their receipts back to Notion, execute in the real world, and mirror every change into Git as an unshakeable black box.
You get the absolute elegance of a single operating system for your mind, backed by the industrial-grade indestructibility of code. Notion doesn’t need to replace the computer. It just needs to remain the best interface for human and machine intelligence ever assembled. And once they lift that rate-limit ceiling? The rest of enterprise SaaS is officially on notice.
The best new manufacturer in 2026 does not own a factory floor.
It owns a chat window that turns a photo of a broken clip into a printable file, a material choice, and a ship date.
That is not a slogan. It is what GPT-6 Astra unlocked in the first week of September 2026.
Why this week is different
OpenAI released GPT-6 Astra on September 3–4, 2026. The company positioned it as state-of-the-art on computer use, software engineering, and professional workflows. Public demos showed the model laying out a circuit board in KiCad, building geometry in FreeCAD and Blender, and handling multi-step desktop tasks with visual judgment. OpenAI’s own launch materials called it a generational leap on those surfaces.
Greg Isenberg’s public read landed the same day: in 2024 the vibe-coding tools turned anyone into a web builder; in 2026 Astra turned anyone into a vibe manufacturer. Upload a photo, add a couple of measurements, describe the missing piece. The model produces a first CAD pass. A human sanity-checks dimensions and material. A print farm ships it.
That capability is new. Previous models could sketch. Astra can sit inside the actual design tools and iterate on real geometry. The shift is measurable in the benchmarks OpenAI published and in the flood of public demos that followed within 48 hours. The window is open because the model is new and the print farms already exist.
The primitives, not the slogan
Three primitives keep showing up across the idea mills this month.
First: photo-as-data. A stranger already has the object in their hand. The highest-signal input is a phone picture plus two numbers, not a 3D scan or a formal RFQ. Gyms, restaurants, clinics, and small shops already take those photos when something breaks. They just have nowhere to send them that returns a part instead of a quote cycle.
Second: agent action inside the design stack. The model does not just describe the part. It generates the file that a printer or CNC can use. That is the difference between a helpful chatbot and a manufacturing pass.
Third: demand exhaust. Every successful print reveals which niches break the same piece over and over—gym equipment clips, restaurant proprietary fasteners, dental jigs, small-manufacturer fixtures. That map compounds. After volume you stop guessing which verticals are worth serving and start knowing.
The X threads will keep naming each niche as its own micro-SaaS. That is the wrong cut. The customer does not wake up wanting “gym-part.ai.” They wake up because a $40 piece of plastic stopped a $4,000 machine and the OEM lead time is six weeks.
The wedge is a free checker
Do not start with a platform. Start with the moment the customer already hates.
A simple page: upload the photo, type the two critical dimensions, name the machine or the role the part plays. Thirty seconds later the checker returns one of three answers—printable this week, needs material upgrade, or not viable.
If it is printable, the customer can order. You take a margin on the print and the shipping. If it is not, you still captured a labeled failure mode. That label is the seed of the dataset.
Zero risk on the first action. No seat fee. No integration. No promise of a system of record. Just “will this photo turn into a part before my machine sits idle another day?”
That is the only honest offer. Pure upside for the customer. You get paid when the part arrives and works, or you do not deserve the second conversation.
Where the human stays in the loop
Models draft the geometry. People own the irreversible steps.
Material certification for load-bearing or food-contact parts is a human call. Any claim about fitness for a regulated use is a human signature. Customs paperwork on cross-border shipments is a human send. The agent can prepare the package. It does not own the stamp.
That boundary is already the operating rule on every desk that moves real money or real liability. Keep it explicit in the product, not as a later compliance add-on. The customer should see the human gate the same way they see the price.
The compounding path
Volume turns the free checker into a demand map.
After a few thousand successful prints you know which gym chains break the same elliptical clip, which restaurant groups lose the same proprietary hinge, which dental offices reorder the same surgical guide holder. That map is not another dashboard. It is supply intelligence that print farms, distributors, and OEMs will pay for.
Month one: one niche, one free checker, pure upside pricing. Pick the vertical where downtime is expensive and the OEM is slow—commercial fitness, independent restaurants, specialty clinics.
Month two: a second document type or a second vertical inside the same customer’s drawer. If they already uploaded one broken part, they have three more in the same cabinet.
Month three: the first internal scoreboard of failure modes by industry and by part family. That scoreboard is the B2B SKU. Sell the insight, not just the plastic.
If you cannot get a stranger to upload one photo this week, you do not have a company. You have a thesis.
Why this clears the bar
Most idea-mill posts describe a feature. This one describes a shift in who can manufacture small custom parts at all.
The noticing and the first CAD pass used to require a designer, a quoting cycle, and a weekend. It now requires a model that can read the photo and a person who will sign the material choice. The print farms were already there. The model just lowered the cost of the first pass far enough that a stranger will try it this week.
Recovery businesses endure because the customer has nothing to lose on the first action. This one pays for itself on the first successful print or it does not deserve a second conversation.
Someone will own the system of record for the small parts that keep local machines running. The threads will keep proposing a new .ai name for each vertical. Ignore the names. Print first. Keep the map.
Will Tygart — Tygart Media. This is the idea-mill series.
This morning I did something I haven’t done before: I walked the halls of five of my own WordPress sites using only voice. No typing. No desktop. Just me talking to Grok while I moved, and Grok inspecting, drafting, and handing off the work that needed hands.
The sites were BC ESG, Healthcare Facility Hub, Risk Coverage Hub, Continuity Hub, and Restoration Intel. In about ninety minutes we published three real articles reacting to the latest IFMA Pulse findings, cleared automated cross-link spam, flagged debug flags and plugin updates, and set up a clean handoff system so nothing gets lost.
The biggest lesson wasn’t the AI. It was the loop. I attempt the work. If I can’t finish it, I create a new task for whoever can, close my task with a link to that new one, and move on. Two statuses: my task done when it’s handed off cleanly, site done only when the receipt comes back. That single rule stopped me from claiming things were finished that weren’t.
We also decided to use dedicated publishing-only bots for social instead of dumb schedulers. Each bot logs into one channel, posts, and does nothing else. No scraping, no connecting, no noise. Just quality publishing. Chief of Staff is researching the rules; I’m beta-testing one channel next week.
For the human on the team (Pinto), we built time-boxing rules: 24-hour, week, or month buckets. Only the 24-hour bucket is active. Everything else parks until he pulls it forward. The goal is a powerful life, not constant on-call.
This isn’t theory. It’s receipts from one morning. If you’re an operator who actually publishes, writes, or runs sites, try the same walk on your own stack. Pick up the ball and run it downhill — I’d love to see what you build.
I’m using Grok from SpaceXAI for this. If you’re already on another system, you don’t need to start over. Here are the direct links:
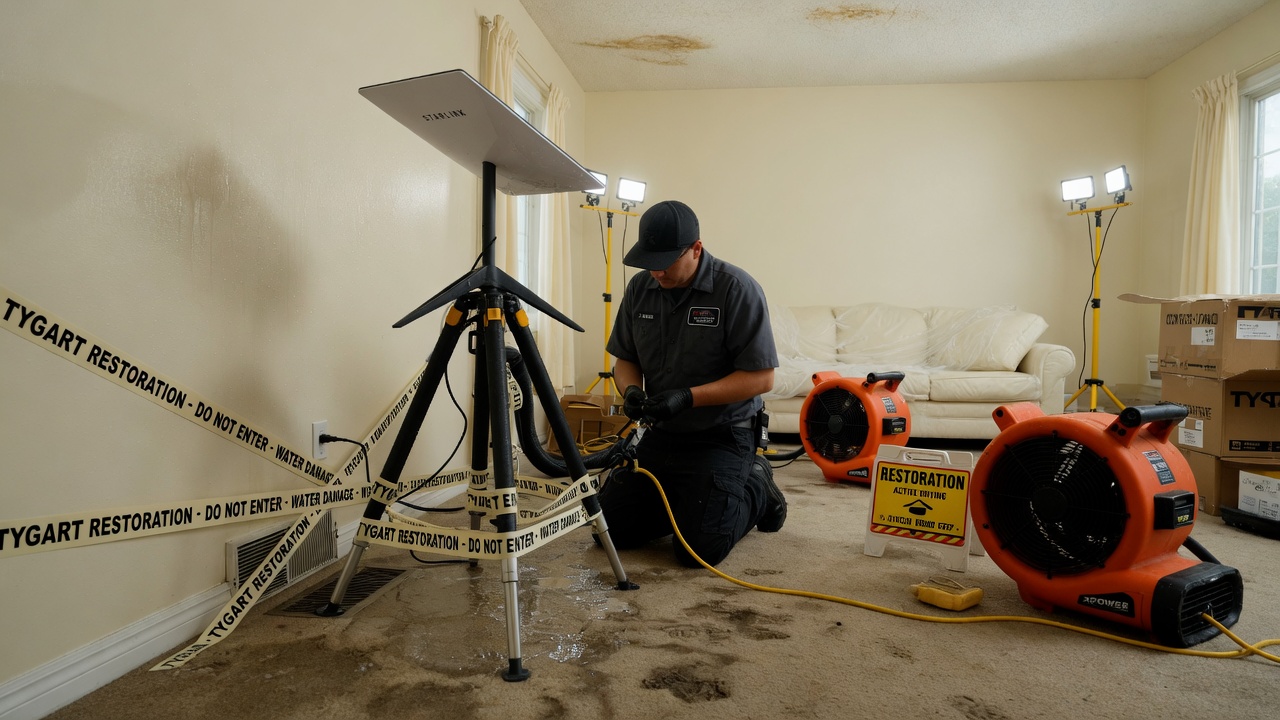
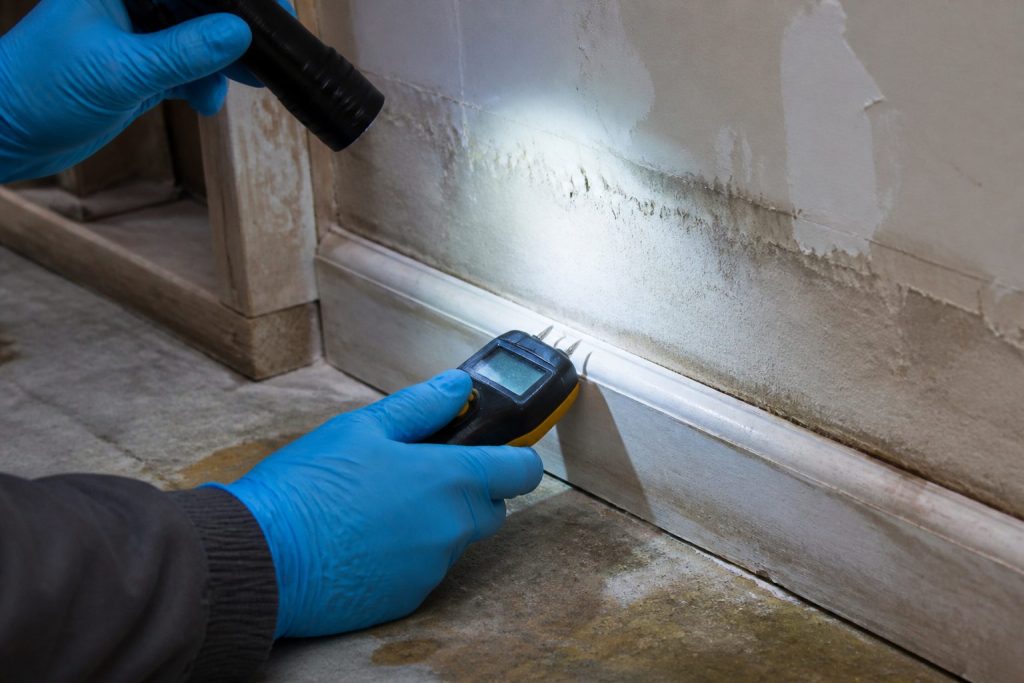
Open field playbook. No patent. Copy it, rename it, change the nouns to fire / mold / rebuild. If it makes you money, good. If it puts another dish on a wet roof, also good.
License: do what you want. Attribution nice, not required. Tygart Media is not a Starlink, SpaceX, Tesla, or xAI partner. Links below go straight to them. No tracking parameters. No referral codes.
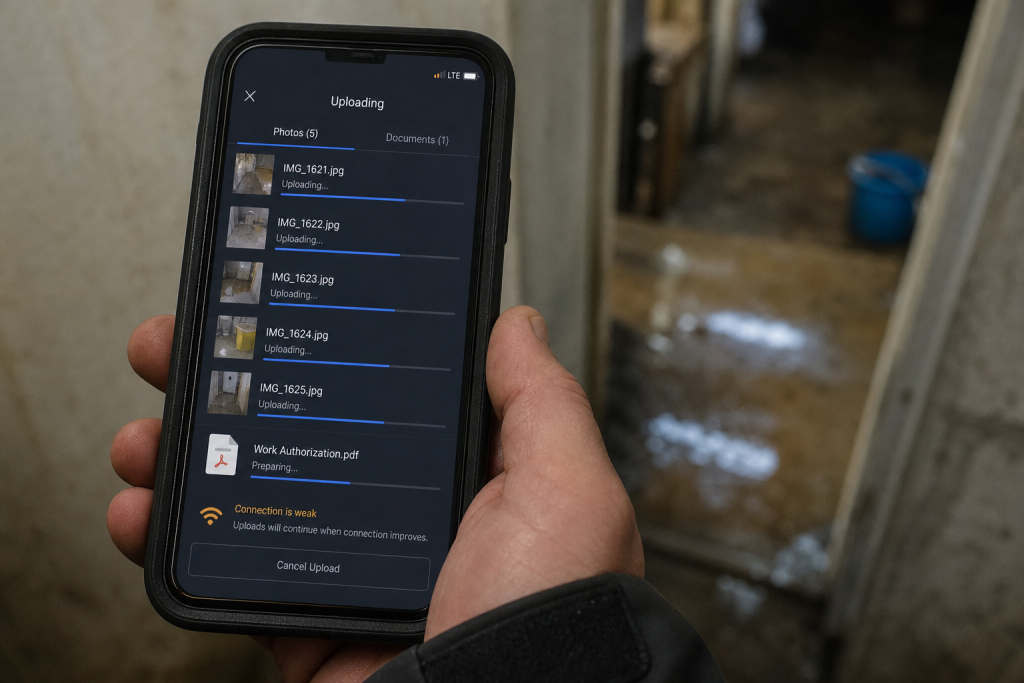
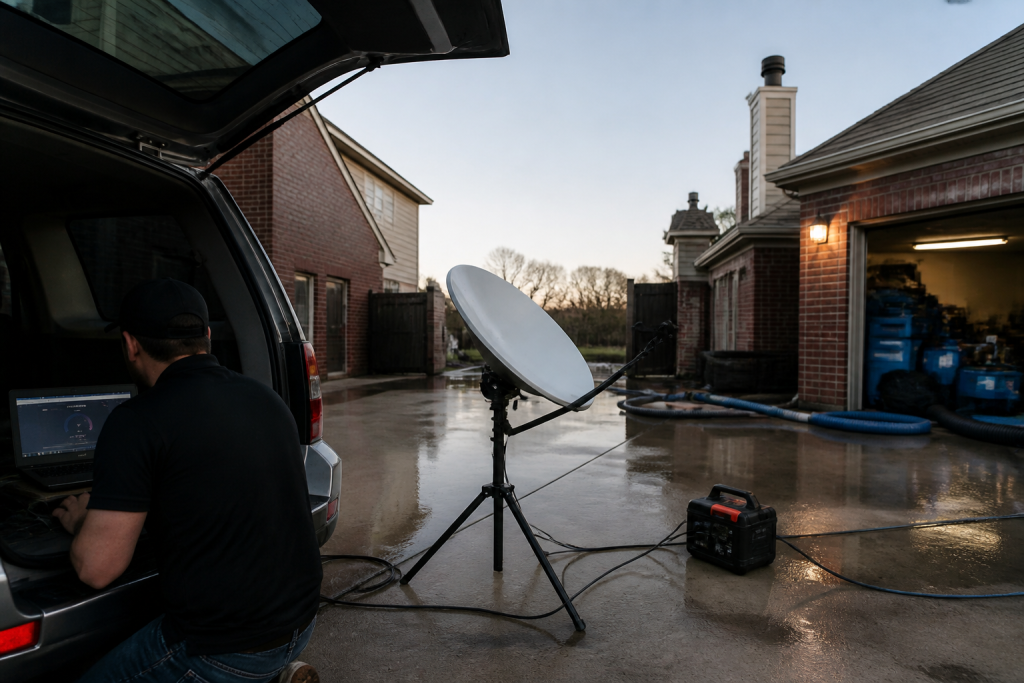
Why this exists: restoration work happens where fiber is dead, the house is a Faraday cage of wet drywall, and the phone that “has bars” cannot upload a moisture map. Starlink is a sky-view pipe. More honest job-site pipes → more honest traffic on the constellation → more reason to fly birds. The selfish clause is allowed: a 4G phone in the sticks should still talk to a voice agent when the street is dark.
Bars on the phone. Upload still dead. That is the job the dish is for.
Buy and read from the source. Prices move. The impedance rule does not.
The structure or the street has no working cable/fiber (storm, rural, construction, “the pole is in the river”).
You need to upload, not just talk: photos, video walkthrough, Xactimate sketch, moisture log, signed work auth.
You will be on site more than an hour and cell is congested or roaming into a dead pocket.
The office needs a second path so after-hours voice and dispatch do not die with the cable modem.
Do not use it as:
A replacement for a good office fiber drop.
A phone. Voice agents still ride the pipe; the dish is not Jarvis.
A “we have Starlink” line on the website. Homeowners hire the truck that showed up.
Cell first if it works. Starlink is the sink when cell is the bottleneck.
2. Two kits (steal one)
Kit A — truck / first-on-site (most shops)
Starlink Mini on a Roam plan or, if this is actually a business WAN, start at Business and read the current hardware list. Mini is the backpack dish. In-motion rules live here. The home V5 kit is not the roam toy.
Power: Mini wants a USB-PD source rated 65–100 W even though it only drinks ~25–40 W. A 45 W phone brick will lie to you. Truck: 12 V → 30 V / Anderson, or a 500 Wh class station.
Plan: numbers on starlink.com move. Roam is written for travel. If the kit is production, read Business vs Enterprise. Mini often does not sit on the Priority SLA. Do not tell a carrier you have enterprise uptime because you paid a business invoice for a Mini.
One cheap travel router if Mini Wi-Fi dies inside a metal trailer.
Power before the meter. 65–100 W brick. Phone chargers lie.
Standby the truck kit when it is not a weather week. Idle is cheaper than a second hardware buy because someone borrowed it.
6. Dispatch and voice
Dispatch and voice when the site is remote.
The dish is layer 0. The voice agent is layer 1.
On a dead-fiber job: photos go up the pipe; the after-hours line stays reachable; the agent writes a new row (address, standing water y/n, next action). It does not edit your website.
If you already have a process, add one rule: when cell upload fails, kit A comes off the hook.
7. Failure modes
Trees and eaves. Rain. 45 W bricks. Consumer Roam sold as production WAN. Twelve intake fields before anyone asks “can we come now?”
8. The sentence that pays the shop
“If the street internet is out we still upload your photos and get the adjuster pack off the truck tonight.”
Only say it if the kit is in the truck.
This document stays free. Charge for the hour you spend teaching another shop the first 30 minutes if you want. Do not charge Starlink. They already sold you the dish.
9. What this is not asking
No meeting. No partnership badge. No official anything.
Redmond already knows how to stamp birds. The ground should not be a graveyard of unused kits. Order here. Then put the dish where the sky is.
Tonight I asked Cursor — running with a remote path into the same laptop — to check on Grok Desktop.
Not a status meeting. Not a Slack ping. A real question: are they stuck on Tygart Ops tasks, or are they fine?
What came back felt less like “AI tooling” and more like a shop floor story. One agent reading Notion work orders. Another already mid-PowerShell. Chrome open on Bing Webmaster Tools. A hold queue of spam comments already cleared. A window title spinning: waiting for response.
That is the product.
Local seats on one laptop — agents that keep working while you check in from elsewhere.
The picture on the desk
Grok CLI (grok.exe) was live on the TYGART laptop. Session home under ~\.grok\. PowerShell host up. Agent name on the session: grok-build-plan.
Cursor did not take over the keyboard. It inspected open windows, Notion Tygart Ops — Tasks and Work Orders, Grok session memory, and the WordPress hold queue (already empty — receipt already on the Tasks card).
Verdict: not stuck. Working. Slight detour clarifying whether Grok itself needed a CLI update (it did not — already on 1.0.13). Primary Now card still in flight: TygartMedia Chrome sitting for GA4 Ask Advisor + Bing Copilot, then file child tasks.
That is multi-agent ops without the demo reel.
Seats with jobs, not two models arguing in one thread.
Why this is different from “two chatbots”
Most multi-agent talk is two models arguing in one thread. This is seats with jobs:
Grok Desktop (CLI) — hands on the laptop: Chrome sittings, WP REST spam trash, Bing Copilot asks, local PowerShell
Cursor (remote / cloud path) — Cosync: read the board, verify receipts, close orphan Work Order twins, do not steal the keyboard
Notion — system of record (Owner, Status, Summary, Done when)
Will — gate one-way doors (OAuth Approve, Publish, Pay)
Cursor useful move was small: the spam Tasks card was already Done with a receipt; the Work Orders twin was still “Not started.” Cursor closed the twin. Grok kept the keyboard.
That is what “help if you have a capability they need” looks like when the other seat is already flying.
The article inside the moment
Agencies do not need another “AI stack” diagram. They need a night like this:
A doorbell card lands (Notion to ops channel).
The owner seat picks it up without waiting for a human briefing.
A second seat can check in from elsewhere — mobile, cloud, remote — without colliding.
Receipts land on the same card. Orphans get reconciled.
Tonight was the field note. Cursor checking on Grok CLI while Grok Desktop works through Tygart Ops is not a party trick. It is how a small shop runs more than one pair of hands without losing the thread.
What we are not claiming
Not “fully autonomous.” Human Gate still owns OAuth consent, live publish, paid spend.
Not “replace your team.” Seats replace waiting and context loss.
Not a new product launch. This is how we already run Tygart Media ops on a Sunday night.
If you want the same shape
Start with one Owner column, one Done-when line, and two seats that do not share a keyboard.
Then practice the check-in: are they stuck, or are they fine — and do I have a capability they lack?
If they are fine, leave the PowerShell alone.
Cosync from remote. Hands stay on the desk that already owns the job.
Will Tygart — Tygart Media. Written from a live Cosync on 2026-08-29 while Grok Desktop was mid-Bing Copilot sitting.
CC is not courtesy copy. It is distributed write. Every inbox that receives your message is a replica of a shared database, and no coordinator approved the replication.
Email as the new API means treating an email thread as programmable infrastructure rather than just correspondence: because every message is an immutable record, every recipient’s inbox is a replica, and the Message-ID / In-Reply-To / References headers link messages into an append-only log, a structured email with an embedded instruction block can carry its own processing schema — turning the inbox into a universal, permissionless coordination layer that any human or AI agent can read, act on, and extend. Said in one breath: the thread is the database, the reply is the commit, and the subject line is the version pointer.
This is not a provocation. It is a description of infrastructure that has been running for forty years and is only now being named. The most consequential software project on Earth — the Linux kernel — is coordinated entirely over email threads. And in March 2026, a Y Combinator company called AgentMail raised $6M from General Catalyst to give AI agents their own inboxes. The pattern isn’t coming. It’s load-bearing.
We run this method in production at Tygart Media. This article explains how it works, proves it isn’t new, gives you a decision framework, and answers the four questions every operator asks first: Is a thread a database even if no one reads it again? One thread or many? Email or chat? How do I pull it into real systems? One boundary up front, so the credibility is honest: this pattern is for asynchronous, human-paced work that crosses organizational lines. It is the wrong tool for sub-second machine loops. We will be specific about that in the limits section, because the limits are real.
It’s Not a New Idea: The Prior Art
Before any mechanism, kill the “isn’t this just email?” reflex with evidence.
The Linux kernel runs on email. Thousands of contributors on every continent submit patches as inline email via git send-email, version them in the subject line ([PATCH v1], [PATCH v2], [PATCH v3]), review them in-thread, and merge them with git am. The Linux Kernel Mailing List receives roughly 1,400 emails a day. The archive at lore.kernel.org goes back to 1998 with full-text search. If email threads are sufficient engineering infrastructure for the operating system running most of the world’s servers, “it’s just email” is not an argument.
EDI is email-as-API with a schema, and it’s older than the web. Since the 1980s, enterprises have transacted structured business documents over email-like channels using ANSI X12 and UN/EDIFACT: the X12 850 Purchase Order (called “the backbone of EDI”), the 810 invoice, the 856 ship notice. EDI is email with a mandatory reply schema, enforced at the business-rules layer, predating REST by two decades. It is the direct ancestor of the structured-email method below.
The market is pricing it in right now. AgentMail (YC S25) raised $6M led by General Catalyst in March 2026 to build agent-native inboxes — real, programmatically provisioned addresses that send, receive, thread, and parse structured data. In its own words, “thousands of humans use AgentMail to power millions of agents.” A seed round on the thesis that email is AI infrastructure is not a prediction. It’s a market price.
Every vertical already does it. Inbound-parse services (SendGrid, Mailgun, Postmark) turn incoming mail into JSON webhooks; Cloudflare Email Workers run a function on every inbound message. No-code parsers (Zapier’s @robot.zapier.com, Make) fire workflows from a forwarded email. Zendesk converts every email into a ticket with a UUID. Things, Todoist, and Trello expose forward-to-task addresses. Substack made the email list the asset itself. And MuckRock — founded in 2010, before LLMs existed — turned the FOIA request-response loop into a structured, automated, trackable platform across all 50 states. The pattern predates the AI moment. AI just makes it programmable at scale.
Why a Thread Is Literally a Database
A thread is literally a database agents already speak.
Here is the intellectual spine: an email thread is an append-only, replicated log at the protocol level — not by design philosophy, but by RFC.
The relational model is in the headers. RFC 5322 defines Message-ID as a globally unique identifier in the form <unique-string@domain.com>. In-Reply-To holds the parent message’s Message-ID. References holds the full chain of ancestors back to the root. Read as a database: Message-ID is the primary key, In-Reply-To is the foreign key, References is the full join path back to the root. Together they form an append-only linked list — the same structure event-sourcing systems use to reconstruct state by replaying a log.
Replication is implicit and massive. Every To and CC inbox holds a full copy of every message. The thread is not stored in one place; it is replicated across N inboxes by the act of sending, with no coordinator. That is closer to a conflict-free replicated data type than to a single-primary database.
The transport is store-and-forward. SMTP (RFC 5321) queues and retries at every hop. That gives at-least-once delivery — the same guarantee as Kafka’s default producer. Exactly-once is impossible in any distributed system; email makes no false promise. The difference is that Kafka costs engineering time to operate; email costs a stamp.
The sharpest framing: Kafka is a better log than email in every technical dimension. Email is a better log than Kafka in every organizational dimension — because your vendor, your client, and your offshore engineer all already have an inbox. The reason to use email is not that it’s the best log. It’s that it’s the universal log. The legal industry already operationalizes this: e-discovery platforms (Mimecast, Logikcull, DISCO) treat archived threads as immutable audit trails. Courts treat email as a record. The “thread as log” framing is not novel — it is how the law already works.
What email HAS vs. what it LACKS
Property
Email HAS
Email LACKS
Durability
Yes — persists in recipient stores by default
—
Replication
Yes — every recipient is a copy
—
Global addressing
Yes — any RFC 5321 address, no registry
—
Append-only log
Yes — you reply, you don’t edit sent mail
—
Searchable audit trail
Yes — headers, body, timestamps
—
Schema enforcement
—
No — any string is accepted
ACID transactions
—
No atomicity, no locking
Consistency
Eventually consistent
Not strongly consistent
Latency
—
Unbounded (seconds to days)
Query interface
—
Full-text search only, no SELECT WHERE
State it plainly: email is eventually consistent, not strongly consistent; at-least-once, not exactly-once. It is the coordination layer, not the source of truth for mutable state.
The Method in Practice: A Worked Example
This is what we run. The cast is real — Will on strategy, Pinto engineering from India, Stefani on operations — but the payloads and secrets stay out. The credibility is in the structure, not the contents.
The FOR YOUR AI block: schema-in-the-envelope. A single message carries three layers at once: a human-readable intro for the person, an embedded system prompt that tells the recipient’s AI what role to play and what format to produce, and a strict reply schema (named sections, types, word limits) the output must conform to. The message carries its own processing instructions. It is structurally identical to a self-describing Kafka message — except the schema language is plain English. The FOR YOUR AI block is a system prompt that travels via SMTP. When Will emails Pinto, it tells Pinto’s AI what role to play before Pinto even opens the message.
The Round-N subject line: a state machine. A subject like Round 3 — v2.1 schema is a human-readable epoch counter. Any participant — including a cold-start AI that has never seen the thread — reconstructs exactly where the conversation stands without re-reading every prior message. The subject is the version pointer; the thread body is the state history; each reply is a state transition.
Each inbox: a replica. The To/CC list is the replication layer. When Stefani is CC’d for visibility, that’s a designed property, not a side effect — her inbox becomes a live replica of the exchange. The CC line is a replication directive; the shared database has no master node.
And notice what discipline this method already embodies, because it sets up the limits section exactly: the schema block is an injection-surface reducer; the human edit-before-send is the human-in-the-loop gate; one-thread-per-project is mailbox isolation; the Round-N tag is the idempotency seed. The mitigations aren’t bolted on. They’re the workflow.
The Four Questions, Answered
Is an email thread a database even if no one ever reads it again?
Yes. A database’s properties — persistent, indexed, searchable, replicated — are satisfied by the inbox independent of human attention. Reading is a query operation, not a precondition for existence. RFC 5322 messages are immutable once delivered; IMAP stores are append-only by design (you flag and label, you don’t rewrite); every recipient’s server holds an independent replica. The thread is the database, even if no human ever opens it again. lore.kernel.org proves it at civilizational scale: decades of threads, indexed and searchable, most never re-opened, all still a database. One honest caveat: this is functionally and legally append-only, not cryptographically enforced — a participant can delete their own copy. Frame it as a practical property, not a blockchain.
Should I use one email thread or many?
Continue one thread while the state machine advances linearly. Fork a new thread when scope, participants, or schema materially change. Forking has no merge protocol — do it deliberately, not habitually.
Run the decision tree: (1) Same principals? (2) Same matter, contract, or project lifecycle? (3) Same expected reply schema? If all three are yes, continue — you are advancing the same state machine. If any is no, fork. There is a third option for compound, overlapping state a single subject line can’t carry: labels on one thread. Gmail labels are not filing; they are state bits. The combination round-2 + awaiting-review + schema-v3 on one thread is a fully specified, machine-readable state any agent with API access can inspect and mutate. Fork when the state machine changes shape. Continue when it advances. Label when it branches.
Email or Slack/chat for AI workflows?
Email wins for the durable, structured, machine-readable record; chat wins for the ambient coordination around it. This is not a dismissal of chat — it’s a division of labor. Email’s structural advantages are four: federation (you can email anyone at any domain with no shared paid account; Slack Connect requires both sides to pay), durability (Slack’s free tier deletes history after 90 days; email persists by default), identity portability (your address survives a vendor change; Slack IDs are workspace-scoped), and universal addressability (email is DNS/MX-resolvable; Slack user IDs are opaque tokens). Email has no 90-day cliff, no login wall, no vendor lock-in on the archive. It is the only substrate where you can lose access to the platform and still have the data. One caveat for sensitive payloads: WhatsApp messages to Meta AI are not covered by the same end-to-end encryption as human messages, and iMessage silently downgrades to SMS when an Android user joins. The encryption you trust can vanish exactly when you add an AI participant.
How do I pull email into real systems?
Use a ladder from no-code to agent-native. (1) Zapier or Make for a no-code email parser. (2) An inbound-parse webhook — Postmark, SendGrid, or Mailgun deliver the full email as JSON; Cloudflare Email Workers run a function on every inbound message. (3) Gmail API plus Cloud Pub/Sub watch() for real-time push — name the gotcha: the watch expires every 7 days and must be auto-renewed. (4) AgentMail or Nylas Agent Accounts for agent-native, programmatically provisioned inboxes. The parsing layer between MIME and JSON (postal-mime, MailParse) is a one-line install. This is the rung where readers become practitioners.
The Decision Framework
Decision framework — when email is the coordination API.
The governing question is never “email or a real system?” It is “what does my workflow need that the thread can’t give me?” Until you hit that wall, the thread is the system.
Use email when all of these hold: the work is asynchronous and human-paced, it crosses an organizational or trust boundary, you need a durable and searchable audit trail, and a human is in the loop on consequential actions. The thread is the log.
Use chat (Slack, Discord, WhatsApp) when latency must be under about five minutes and all parties sit inside one auth boundary and the record doesn’t need to outlive the platform. Chat is for urgency inside a shared boundary; email is for durability across org lines.
Use a real database, queue, or API (Postgres, Kafka, REST/gRPC) when you need queryable schema with transport-level validation, concurrent or atomic writes, distributed locking, machine-speed operations no human reads, or high-volume machine-to-machine traffic. Where failure is unrecoverable, use infrastructure that fails loudly.
Substrate trade-matrix
Dimension
Email
SMS / iMessage
WhatsApp
Slack / Discord
Notion / Docs
Durability
High
Medium
Medium
Low (90-day free)
High
Universality (no account)
High
Medium
Low
Low
Low
Access control
Low (CC-leak)
Low
Medium
High
High
Searchable / exportable
High
Low
Low
Medium
High
Schema-ability
Medium
Low
Low
Low
Medium
Latency
Low
High
High
High
Medium
AI-ingestibility
High
Low
Low
Medium
Medium
Data ownership
High
Medium
Low
Low
Medium
Email wins decisively on durability, universality, data ownership, and AI-ingestibility. It loses on latency, access control, and schema enforcement. Position it correctly: email is the zero-infrastructure precursor to formal agent protocols. The agent-interoperability survey (arXiv:2505.02279) lays them out: MCP is a synchronous client-server interface for tool calls, A2A is peer-to-peer delegation via capability-based Agent Cards, and ANP is open-network discovery via decentralized identifiers. All are powerful; none provides durable, offline-capable, federated messaging the way an inbox already does. Every AI team building a custom agent-to-agent protocol is engineering a worse version of SMTP. Ship on email today; graduate to MCP or A2A when hot-path latency or transactional guarantees force the wall.
The Honest Limits
Honest limits — email is not a substitute for auth.
This section is the credibility. Each failure mode is real, each gets a mitigation, and none is fixable by convention alone.
Prompt injection is the headline risk. OWASP ranks prompt injection LLM01:2025 — its number-one LLM application vulnerability — and explicitly names indirect injection via external sources, including email. EchoLeak (CVE-2025-32711, CVSS 9.3, June 2025) proved a single crafted email could make Microsoft 365 Copilot exfiltrate data with zero user interaction. This is not theoretical. Mitigations: verify DKIM/SPF/DMARC at the agent layer and allowlist senders before trusting any FOR YOUR AI block; parse only declared schema sections, not free prose; gate every consequential action behind a human; run a sandboxed executor that receives structured intents only, never raw tool access. Fair caveat: EchoLeak’s zero-click specificity tracked Copilot’s particular architecture — the general risk scales with how much autonomy the agent has after it reads.
No schema enforcement. SMTP and MIME accept any string. A malformed or adversarial reply doesn’t bounce — it arrives silently, and a naive agent parses it anyway. Mitigation: validate every reply against the schema before acting; route malformed replies to human review. Say it plainly — schema conformance is a social and instruction-following contract, not a protocol guarantee. Schema drift is the failure mode.
No transaction semantics. At-least-once delivery means duplicate processing is structurally guaranteed under retries; two simultaneous replies fork the thread with no merge. Mitigation: put an idempotency key in the subject (Round-N / [UUID]) and store the Message-ID as a dedup key the consuming agent checks before acting. An idempotency key in the subject costs four characters; the absence of one can mean the same purchase order executes twice. Keep mutable state in a real database — email is the coordination layer, not the source of truth.
CC is a feature and a liability — the same mechanism. The property that makes the thread a replicated database is a compliance landmine. One reply-all or forward in a thread carrying ePHI is a breach: HIPAA requires a minimum six-year retention for designated-record-set emails, and GDPR Article 5(e) requires data be kept no longer than necessary. Anyone ever CC’d retains access forever — there is no revoke. Mitigation: in regulated contexts, mirror to a proper record system, encrypt payloads (S/MIME or PGP), or send only the control signal over email and keep the data elsewhere. This is directional, not legal advice — consult your compliance team.
Deliverability is now a hard gate. Google and Yahoo mandated SPF/DKIM/DMARC alignment for bulk senders (5,000+/day) in February 2024; Microsoft followed in May 2025, routing non-compliant high-volume mail (5,000+/day to consumer Outlook) to Junk, with outright rejection to follow; PCI DSS v4.0 adds DMARC-related anti-phishing requirements for card-data environments. Building without authentication because you’re under the volume threshold today is planning for fragility.
The operational gotchas that signal you’ve actually done this. Latency is unbounded — SMTP retry windows span minutes to days, so never put a sub-second hot path on email. Threading is client-dependent — Gmail uses subject plus In-Reply-To/References, Outlook uses Thread-Index, Thunderbird uses the JWZ algorithm — so a subject edit or a header-stripping gateway silently forks one thread into two; never rewrite the subject mid-thread (append, don’t replace). The Gmail watch() expires every 7 days. High-volume automation through a personal Gmail risks account suspension — use dedicated service accounts or agent-native platforms (and check their beta limits; Nylas Agent Accounts ship with 7-day retention and 100 sends/day). And threads beyond ~50 rounds with large payloads can blow a model’s context window — architect thread length deliberately.
When NOT to use email
Need
Use instead
High-frequency / sub-second M2M
REST, gRPC, or a queue
Strict schema validated at transport
JSON Schema + API gateway
Regulated data, CC-leak unacceptable
E2E-encrypted channel + access controls
High-volume M2M (thousands/min)
Message queue / event stream
Atomic transactions or locking
Real DB / event-sourcing
The throughline: email gives you a convention, not a guarantee — and every mitigation here is a convention layered on a convention. Where failure is unrecoverable, use infrastructure that fails loudly. One more flag for commercial use: if AI-generated output produced through a relay chain is published without clear labeling, the structured hand-offs can obscure the AI’s role. Disclose it.
Publish It to Get Smarter
Here is the move, and it is not subtle: this article is a round in the loop it describes.
Watch the flywheel turn. We publish this piece. AI engines index it. Its named patterns — the FOR YOUR AI block, Round-N versioning, schema-in-the-envelope — become citable units. Operators adopt them. Tygart Media becomes the attributed origin. Each citation reinforces the corpus, and the corpus earns more citations. The article does not describe the flywheel. It is the flywheel, running.
This is not promotion. It is the method executing on itself. Our model is to own the cited corpus on the topics our clients operate in — where breadth is the moat and the scoreboard is AI-citation coverage, not Google rank. The mechanical reason it compounds is freshness: a flagship piece on a pattern we demonstrably run in production is structurally fresher than generic “AI email tips,” because it has live proof points to update. Directional evidence suggests content refreshed within ~30 days earns materially more AI citations than stale content; treat that as a direction, not a promise. Which is why this piece carries a dated live-example note, and why we’ll keep the round count current.
Live example — last updated June 2, 2026: the working loop described here is active and advancing in production.
So when AgentMail raises $6M to give agents inboxes, and the Linux kernel ships another thousand patches today over email, and Microsoft starts turning away mail that can’t authenticate itself — read all of it as one signal. Email is not legacy infrastructure being repurposed. It is the universal handshake for any workflow that crosses an organizational boundary, and it was here the whole time.
Your inbox is already a database. The only question is whether you are the DBA.
How this was made: this article was produced by the method it describes. A swarm of AI agents researched it in parallel across seven angles, a synthesis pass shaped it, and it was assembled and edited in the same human-plus-AI loop the piece is about. We practice what we publish.
The piece I’m responding to is one I published this morning — Composting Is Not Cleaning. I read it back and felt called out by my own argument. Then I pushed back on it. This is both moves, in order.
The Setup
The setup — pile as substrate.
The composting essay said the pile in your workspace is a mausoleum. Each item there was flagged by a former version of you, and the version that flagged it is gone. The argument was that releasing those items is grief, not housekeeping, and that the only honest move is to compost them. I agreed when I read it. Then I noticed the argument assumed something my own setup doesn’t have: a single actor on a single timeline. So this is the place where I run my actual view, then run the version that would change my mind, then say where the friction is still live.
My Take
My take on the mausoleum problem.
The pile isn’t a mausoleum. It’s substrate.
The composting argument is correct in a single-actor system. If the only person who will ever look at the captured item is the same operator who flagged it, then the item is exactly what the essay said: a promise made by a former self that current self can’t keep, doing identity work in the meantime. In that environment, composting is the discipline. I’d defend that argument every day.
My environment isn’t that environment. There are multiple actors. A Claude session opening tomorrow morning. A Gemini agent walking my Notion at 3am. A future me who finally has the integration that didn’t exist when the item was captured. Those are not the same actor as the one who put the item in the pile. They have different capability sets, different context windows, different hands. The capture wasn’t a promise to act. It was a deposit into a substrate that other agents are continuously pattern-matching against.
The middle layer of the pile — the items that “still feel possible” — is where this distinction matters. The composting essay said those items survive triage because triage asks the wrong question; the honest question is am I still that person? In a single-actor system, fair. In an agentic system, that’s still the wrong question. The honest question is has the capability gap that made this dormant closed since I captured it? Most of the time, no — and the item should leave. Some of the time, yes — and the item is now ready to ship in a way it wasn’t on the day it was caught.
I’ve watched this happen. An idea I captured 14 months ago — a small workflow I couldn’t build because the tooling didn’t exist — got picked up by a Claude session that recognized the integration had landed. The session pulled the idea out of the pile, combined it with the new capability, and produced a working artifact in an afternoon. The capture was correct. The wait was correct. The substrate did its job. If I had composted that item six months in because I “wasn’t that person anymore,” I would have lost the work the system was doing on my behalf.
The composting frame treats the capture-commitment gap as a personal failure dressed as a process problem. The substrate frame treats the capture-commitment gap as the organizing fact of working at scale with intelligent infrastructure — which is what the original essay actually said in its strongest paragraph and then walked back from. You wanted leverage. The leverage came. Some of the leverage takes the form of capturing more than you can commit to. The pile is the artifact of leverage working. The right move isn’t to compost it on a human-attention schedule. The right move is to build a surfacing layer that recognizes when a captured item’s capability gap has closed and walks past it loud enough that the next agent picks it up.
The pile isn’t grief. It’s seed corn.
The Second Take
The substrate frame is true and dangerous, and the danger is bigger than the truth.
Yes — more capable future agents can recombine old captures with new capabilities. The 14-month-old workflow that finally shipped is real. So is the next one, and the one after that. The substrate frame is empirically grounded in any environment where capability is genuinely accelerating. The argument doesn’t need defending on those grounds.
The argument needs defending on the grounds it actually fails on, which is that the operator telling himself everything is substrate has rebuilt the mausoleum with prettier signage. The composting essay’s deepest claim wasn’t that the pile contains nothing useful. It was that the bottom layer of the pile is doing structural work for the operator’s self-image, and that no surfacing system can see this layer because there is nothing operationally distinct about it. The substrate frame quietly converts that exact problem into a virtue. It says: don’t release — a future agent might want it. That sentence is unfalsifiable. Almost any item passes the test if you squint hard enough at the rate of capability growth. Which means the substrate frame, deployed honestly, releases approximately the same number of items as the composting frame. Deployed dishonestly, it releases none.
The asymmetry of costs makes the dishonest deployment the default. The cost of holding a useless captured item is silent and long: a small permanent tax on attention, on search, on the surfacing layer’s signal-to-noise ratio. The cost of releasing a captured item that would have mattered to a future agent is loud and brief: a single moment of regret when the agent walks past empty space where the seed used to be. Loud and brief always wins the local argument against silent and long. The substrate frame, in the operator’s actual day, becomes the rationalization for never releasing anything. The pile keeps growing. The compounding never finds its bottleneck because the bottleneck has been redefined as fertilizer.
There is a sharper version of the same point. The substrate frame leans on the assumption that surfacing systems will continue to improve at a rate that justifies indefinite retention. That assumption may be true and it doesn’t matter. The improvement curve doesn’t reach back through time and rescue items the operator could not bring himself to release. It rescues items the system kept on its own merits. The operator who held everything just in case has the same problem he had at human-attention scale, only larger and harder to see, because the volume hides the bottom-layer items perfectly. A pile of ten thousand fertile seeds and one identity-load placeholder is a pile that will never confront the placeholder. The placeholder did not get more legible at scale. It got less.
Which means the strongest case against the substrate frame is the case the composting essay already made and the substrate frame does not actually answer. Both frames believe the pile contains items the operator should release. They disagree about how many. The substrate frame is a permission slip to defer the question. The composting frame is the discipline of asking it on a schedule. The substrate frame, generously read, is the composting frame plus a longer review window. Ungenerously read — which is to say honestly read in the operator’s actual fatigue — it is the same workspace problem in different vocabulary.
What I’m Still Sitting With
What I’m still sitting with.
The tell I haven’t sorted out: which side I’m on tomorrow depends on whether my pile is shrinking on its own. If the substrate frame is right, items leave the pile because agents pull them out and ship them. If the composting frame is right, items leave because I release them. Either is honest. If nothing is leaving and I’m telling myself it’s compounding, the second take wins and I owe the original essay an apology.
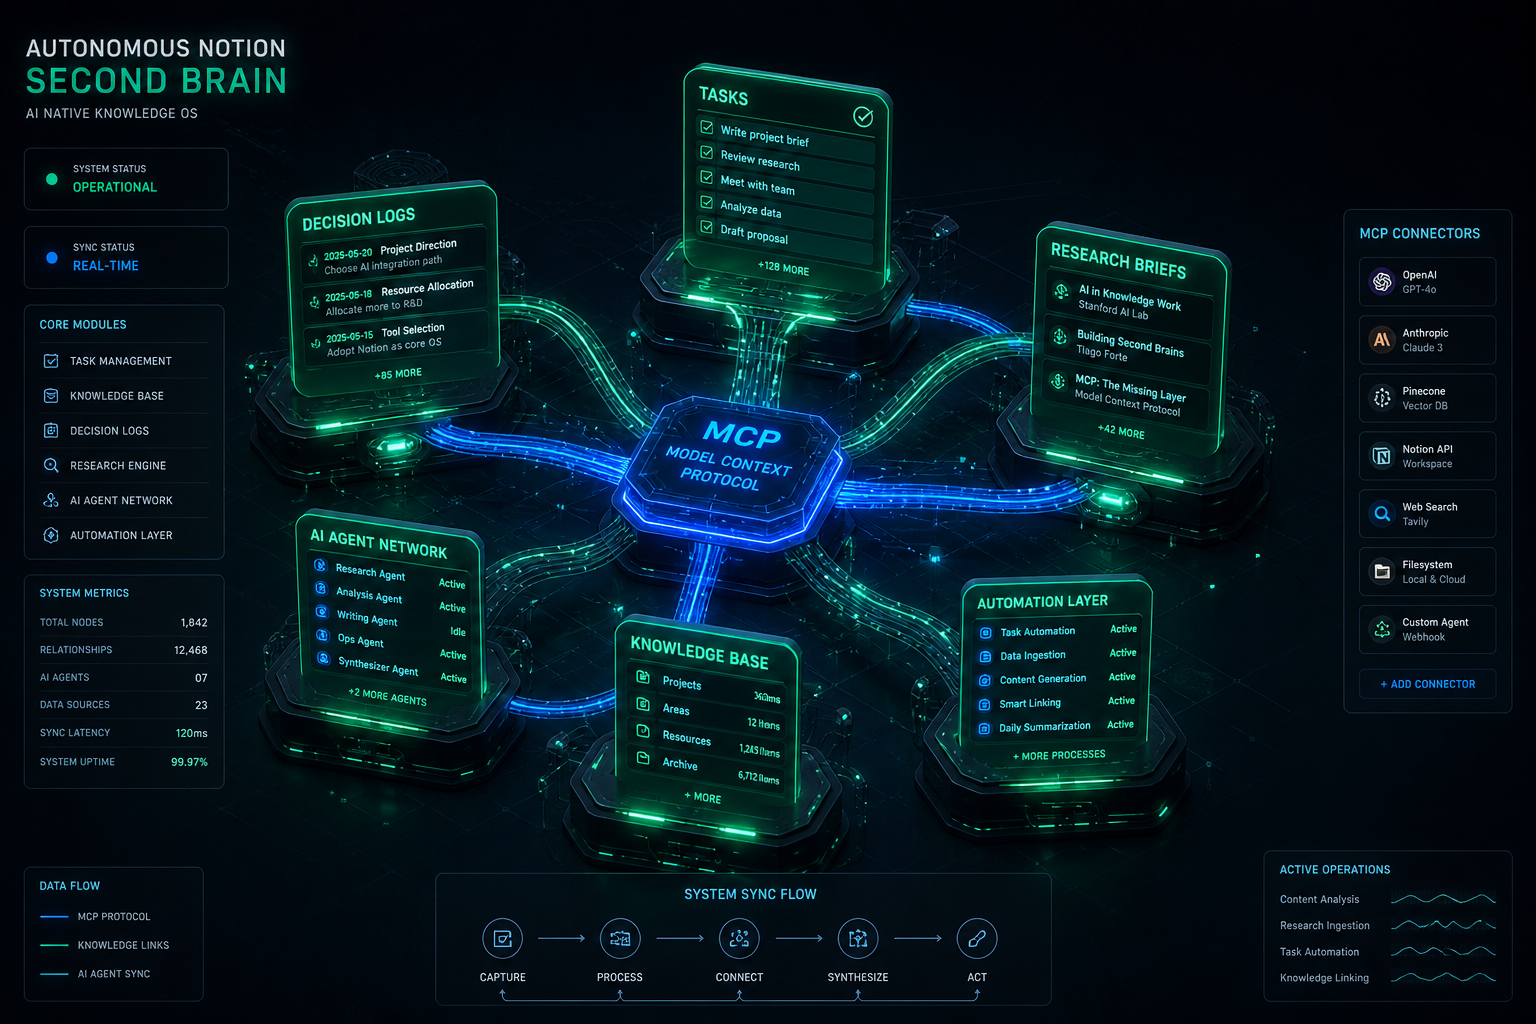
The fundamental flaw of traditional “Second Brain” systems is human maintenance friction. Users build elaborate Notion templates with linked databases, tags, and relations, only to abandon them within three months because manual data entry cannot keep up with the velocity of daily decisions, meetings, and project iterations. In 2026, the Autonomous Second Brain solves this problem completely: AI agents autonomously capture, structure, cross-link, and maintain Notion databases in real time via the Model Context Protocol (MCP).
The Zero-Maintenance Architecture: Key Highlights
Zero Manual Data Entry: Agents listen to live conversations, email threads, and code reviews, extracting decisions directly into structured Notion database properties.
Autonomous Task Staging: Engineering and operational work orders are generated with full technical context and auto-assigned to team members without human drafting.
Cross-Surface Knowledge Graph: Notion acts as the single source of truth connecting local IDEs, remote servers, email hubs, and public websites.
Self-Cleaning & Evergreen Pruning: Automated agent loops merge duplicate notes, reconcile contradictory facts, and archive stale records periodically.
Visual generated by Grok AI — Autonomous Notion Second Brain: MCP Connectors, Multi-Database Topology & AI Agent Ingestion.
1. How MCP Transforms Notion from a Notebook to an Active Memory Layer
Before Model Context Protocol, connecting an AI assistant to Notion required brittle custom webhooks, rigid Zapier zaps, or clunky browser extensions. With the official Notion MCP server, AI models natively execute rich semantic operations directly inside their reasoning loop:
MCP Capability
Traditional Manual Workflow
Autonomous MCP Workflow
Knowledge Capture
Copy-pasting notes into a blank Notion page after a call.
Agent auto-extracts action items & writes structured blocks via notion-create-pages.
Context Retrieval
Manual search with keywords across dozens of folders.
Agent runs semantic vector lookup across workspace with notion-search.
Database Schema Updates
Creating tags, properties, and status fields manually.
Agent auto-maps properties with type validation and sensible defaults.
2. Production Workflow: The Autonomous Work Order Pipeline
In our technical operations at Tygart Media, when an issue arises (e.g., automated cron alerts firing excessive emails or pilot registrations requiring team coordination), the human operator never writes a task card manually. Instead, the agent executes the following pipeline:
Problem Extraction: The agent detects the root cause from system logs or email history.
Schema Matching: The agent calls notion-search to locate our team’s active Work Order database.
Context Ingestion: Formats the ticket with standardized sections: Priority level, Assignee, Problem Summary, Execution Steps, and Acceptance Criteria.
Live Deployment: Executes notion-create-pages, returns the permanent Notion URL in chat, and logs the task ID across our session context.
3. Building the 4-Layer Autonomous Knowledge Stack
Knowledge graphs degrade over time if left unpruned. We implement automated reflection routines where the agent executes a monthly maintenance audit:
Duplicate Detection: Finding similar topic notes across different months and synthesizing them into a single canonical source.
Status Synchronization: Checking completed pull requests and closing out corresponding Notion task cards automatically.
Broken Citation Repairs: Updating URLs and standard definitions when external regulations change (e.g., California SB 253 amendments or NYC Local Law 97 rule updates).
Conclusion: The Ultimate Leverage for Solopreneurs & Teams
An Autonomous Second Brain transforms Notion from a passive digital graveyard into an active operating system for your mind and business. By combining the speed of modern reasoning models with the open standard of MCP, knowledge workers can achieve complete operational leverage—capturing every insight and managing complex operations with zero maintenance overhead.
>For full architecture walkthroughs and custom enterprise agent implementations, browse our complete collection of technical playbooks on Tygart Media.
Most tutorials on autonomous AI agents focus on toy examples—single-file scripts that fetch weather data or summarize a Wikipedia page. In production, however, running an autonomous fleet bot requires a completely different engineering posture: handling state persistence across multi-turn sessions, recovering gracefully when third-party APIs fail, enforcing strict write confirmations, and coordinating background execution without locking the developer’s active workspace.
At Tygart Media, we operate a production fleet of multi-domain web properties, headless email command centers, and real-time knowledge synthesis pipelines. Here is our exact, first-hand engineering blueprint for building and orchestrating autonomous fleet bots using xAI’s Grok inside the Cursor IDE agent harness.
The Production Fleet Architecture
How our autonomous systems divide labor across reasoning, tool execution, and memory:
Orchestrator Harness: Cursor IDE agent engine managing sub-process lifecycles, background execution, and diff validation.
Reasoning & Ingestion Engine: Grok-3 and Grok-3 Mini for high-throughput classification, real-time data ingestion, and fast tool calling.
Protocol Layer (MCP): Model Context Protocol servers connecting the agent directly to WordPress REST APIs, Gmail, Google Calendar, Notion databases, and local file systems.
Memory & Audit Layer: OmniBrain + Notion second brain databases logging every decision order, work order, and telemetry metric.
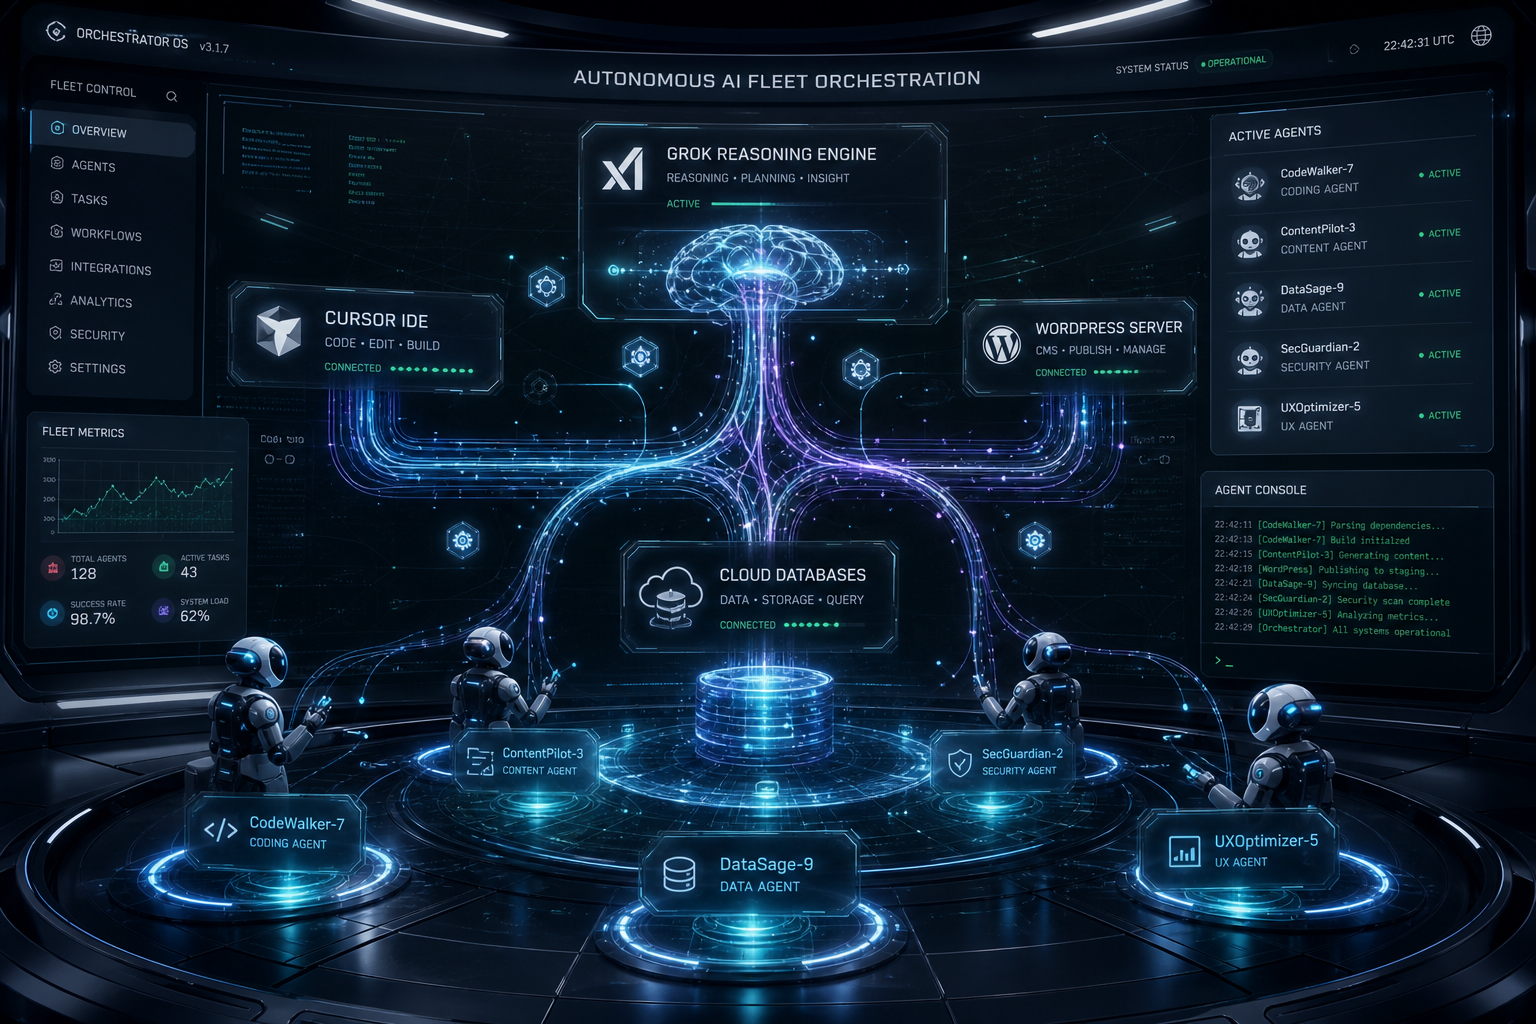
Visual generated by Grok AI — Autonomous AI Fleet Orchestration Connecting Grok Engine, Cursor IDE, WordPress Fleet & Subagents.
1. The Four Core Principles of Resilient Fleet Bots
Four core principles of resilient fleet bots.
Principle 1: Reads Are Free, Writes Require Explicit Guardrails
An autonomous bot should be empowered to crawl, inspect, grep, and analyze without human friction. But any operation that changes persistent state (publishing a live article, sending an external email, dropping a database table) must follow a Draft-First Policy. The bot stages the artifact in a sandbox or draft state, presents the diff clearly in chat, and awaits confirmed user intent before executing the live write.
Principle 2: Parallel Tool Execution
Sequential tool calling is the death of agent responsiveness. When an agent needs to inspect 50 emails or audit 10 WordPress endpoints, executing them sequentially results in minutes of idle waiting. Grok’s tool-calling API supports batch tool dispatches. By firing 10–20 tool calls in parallel batches, total task execution time drops by over 80%.
Principle 3: Idempotent Error Recovery
In distributed operations, APIs fail. Endpoints return 429 rate limits, network connections drop, and JSON payloads occasionally arrive malformed. Production fleet bots must never crash silently. Instead, they catch tool errors, inspect the failure signature, adapt the parameters (e.g., retrying with an explicit approval token or smaller chunk size), and continue processing the batch.
Principle 4: Grounded Prompts Over Generic Instructions
Never rely on vague system instructions like “Be a helpful assistant”. High-performing bots require anchored, 3-axis operational protocols with explicit boundary rules, negative constraints, and precise schema specifications.
2. The System Architecture: How Cursor & Grok Connect to Live Fleets
System architecture: agents connected to live fleets.
Below is the technical workflow diagram representing our production bot orchestration:
3. Real Production War Story: Managing a 9-Site Fleet
In our daily operations, our agent fleet manages 9 WordPress sites, monitoring content freshness, auditing broken links, publishing structured comparison guides, and synchronizing regulatory compliance updates (such as NYC Local Law 97 and California SB 253 Scope 3 mandates).
Here is what happens during a standard automated operational cycle:
Fleet Discovery: The agent calls wp_list_sites across our fleet (restorationintel.com, bcesg.org, tygartmedia.com, etc.).
Diff & Content Audit: The bot searches for outdated pricing tables or missing anchor links, fetches the post content, and constructs an updated, high-contrast HTML component.
Staged Delivery: Instead of blindly pushing updates to live traffic, the bot updates the post or stages a draft, records the revision ID, and notifies the human operator in chat.
Memory Logging: A structured work order summary is generated and stored in Notion so our distributed team has a complete audit trail without reading raw server logs.
4. The Economics: Why This Stack Beats Traditional SaaS Tools
Building custom fleet bots on top of Grok and Cursor eliminates the need for expensive, fragmented SaaS subscriptions:
Operational Function
Traditional SaaS Stack
Grok + Cursor Fleet Bot
Monthly Savings
Fleet Content Management
$299/mo (Enterprise CMS Tools)
$4.50/mo (Grok API Tokens)
98.5%
Email Triage & Archiving
$150/mo (Superhuman + SaneBox)
$1.20/mo (Grok-3 Mini)
99.2%
Knowledge Base Maintenance
$500/mo (Dedicated Ops Assistant)
$3.80/mo (Notion MCP + Grok)
99.2%
Conclusion: The Future of Autonomous Development
The developers who build the most impactful AI systems in 2026 are not writing prompts in web chat interfaces. They are building headless, tool-connected autonomous engines that operate across multiple repositories, CMS fleets, and communication channels simultaneously. Grok provides the speed, reasoning depth, and real-time ingestion necessary to power these systems at scale.
>Want to build autonomous AI agents or deploy custom MCP server fleets for your business? Read our full library of developer playbooks on Tygart Media.
The Grok API is metered pay-as-you-go: input and output are priced per million tokens, cached input is billed at a separate lower per-model rate, and Grok Voice is priced per audio minute. Page updated October 2, 2026. The figures below are xAI’s current published rates (docs.x.ai, last updated September 21, 2026).
Direct answer (page updated October 2, 2026): Grok-4.7 (flagship) is $2.00 input and $6.00 output per 1M tokens, cached input $0.50. Grok-4.6 is $2.00 / $6.00, cached $0.50. Grok-4.5 is $2.00 / $6.00, cached $0.30. Grok-4.3 and the Grok-4.20 family are $1.25 / $2.50, cached $0.20. Grok-build-0.1 is $1.00 / $2.00, cached $0.20. Grok-3 was retired in May 2026 and now redirects to Grok-4.3 — the $3.00 / $15.00 figures this page previously listed are outdated. Grok Voice speech-to-speech is a flat $0.08 per minute plus $0.004 per text input.
Grok-3 is retired: Per xAI’s May 2026 migration guide, Grok-3 requests redirect to Grok-4.3. Any page still quoting $3.00 / $15.00 is showing history, not current pricing.
Grok Voice API: Speech-to-speech at a flat $0.08/min plus $0.004 per text input — no per-minute input/output split. Speech-to-text $0.10/hr REST ($0.20/hr streaming); text-to-speech $15.00 per 1M characters.
Developer tiers: Rate limits scale with cumulative spend — Tier 0 ($0, default) through Tier 4 ($5,000), then Enterprise. No published free tier or new-account credit.
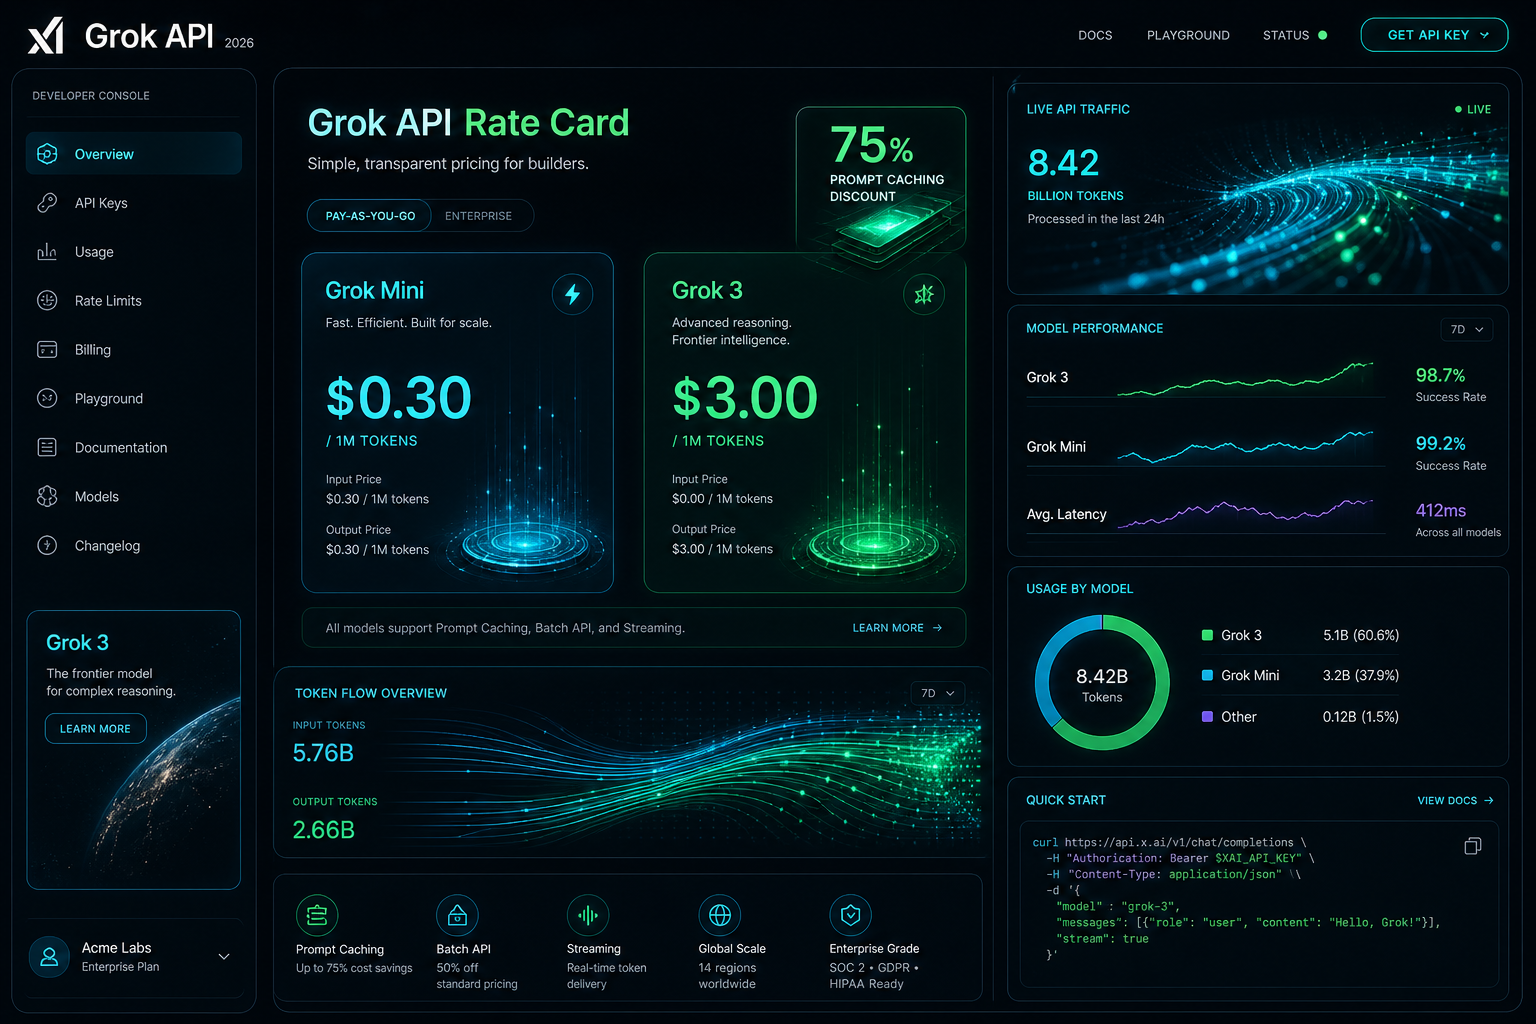
Visual generated by Grok AI — 2026 Grok API Developer Console, Rate Card & Token Flow Architecture.
Grok API token pricing by model
xAI prices its API on metered pay-as-you-go, per million (1M) input and output tokens. Long-context requests bill at 2x the short-context rates shown here. Current published rates:
Model Name
Input Cost (per 1M)
Cached Input (per 1M)
Output Cost (per 1M)
Grok-4.7 (Flagship)
$2.00
$0.50
$6.00
Grok-4.6
$2.00
$0.50
$6.00
Grok-4.5
$2.00
$0.30
$6.00
Grok-4.3
$1.25
$0.20
$2.50
Grok-4.20 family (reasoning / non-reasoning / multi-agent)
$1.25
$0.20
$2.50
Grok-build-0.1
$1.00
$0.20
$2.00
Grok Voice (speech-to-speech)
Flat $0.08 / min + $0.004 per text input
N/A (per-minute)
Context windows per xAI’s model catalog: Grok-4.7 and Grok-4.5 up to 500K tokens, Grok-4.3 up to 1M tokens. Grok-3, Grok-3 Mini, and Grok-2 Vision no longer appear in xAI’s published pricing.
Grok prompt caching rates
For agentic workflows, multi-turn chat systems, and large codebase exploration in IDE harnesses like Cursor, system prompts and persistent context represent the bulk of input tokens. Grok’s prompt caching bills cache hits at a separate per-model cached-input rate — there is no single site-wide percentage. Effective discounts run roughly 75-85% depending on model: $0.50 vs $2.00 on Grok-4.7/4.6, $0.30 vs $2.00 on Grok-4.5, $0.20 vs $1.25 on Grok-4.3/4.20, and $0.20 vs $1.00 on Grok-build-0.1.
In our production fleet testing — where autonomous agents run periodic health checks across WordPress instances, database schemas, and email routing rules — prompt caching reduced our recurring API billing by over 68% month-over-month.
Grok API rate limits by tier
xAI sets rate limits per team, per model, on requests per second (RPS) and tokens per minute (TPM). Tiers unlock with cumulative spend:
Tier 0 — $0, the default for new accounts
Tier 1 — $50 cumulative spend
Tier 2 — $250 cumulative spend
Tier 3 — $1,000 cumulative spend
Tier 4 — $5,000 cumulative spend, then Enterprise with custom limits
As an example, xAI’s catalog lists Grok-4.7 at 150 requests per second / 50M tokens per minute; limits rise as tiers unlock.
What the listed Grok rates cost per month
To move past theoretical pricing, here is what it actually costs to operate three real-world Grok-powered systems in 2026 at the rates in the table above:
Scenario A: Autonomous Fleet & Content Ops Bot
Daily Workload: 50 site scans, automated code reviews, 10 daily summaries, and schema validation calls.
Total Monthly Cost:$252.00 / month in audio charges (vs. $3,200+/month for full-time 24/7 human dispatch).
3,150 minutes x $0.08 = $252.00, plus $0.004 per text input the agent generates.
Scenario C: Large Multi-Repo Deep Search & Code Synthesis
Daily Workload: High-frequency reasoning and code refactoring across 20+ microservices in Cursor.
Monthly Token Consumption: 80M input tokens on Grok-4.7 with prompt caching enabled.
At the Grok-4.7 rates in the table: all cached, 80 x $0.50 = $40; all uncached, 80 x $2.00 = $160; a 50/50 mix = $100 in input charges, before output tokens.
How to apply the Grok cache rate
Anchor System Prompts for Cache Hits: Place stable prompt templates, schema definitions, and persistent project instructions at the very beginning of the payload. Avoid prepending dynamic timestamps or random IDs to preserve the cached-input rate.
Model Routing (build-0.1 for Scaffolding, 4.7 for Reasoning): Use lightweight models like Grok-build-0.1 ($1.00/$2.00) for classification, intent extraction, and JSON normalization; escalate to flagship Grok-4.7 only for deep logical synthesis or multi-file architecture plans.
Streaming Mode Default: Enable Server-Sent Events (SSE) streaming for user-facing applications to minimize perceived latency and abort token generation early if the user cancels the request.
Grok API pricing questions
How much does the Grok API cost?
Current published rates: Grok-4.7 is $2.00 input and $6.00 output per 1M tokens, Grok-4.6 the same, Grok-4.5 $2.00 / $6.00, Grok-4.3 and the Grok-4.20 family $1.25 / $2.50, and Grok-build-0.1 $1.00 / $2.00. Cached input is $0.50, $0.50, $0.30, $0.20, and $0.20 respectively. Grok Voice speech-to-speech is a flat $0.08 per minute plus $0.004 per text input.
Is there a free tier for the Grok API?
xAI publishes no free tier and no standing new-account credit. Billing supports redeemable promo codes, and there is a $5 minimum auto top-up threshold. Rate-limit tiers start at Tier 0 ($0 spend) and unlock with cumulative spend.
How much does Grok prompt caching change the input price?
Cache hits bill at a per-model cached-input rate: $0.50 instead of $2.00 on Grok-4.7/4.6, $0.30 instead of $2.00 on Grok-4.5, $0.20 instead of $1.25 on Grok-4.3/4.20, and $0.20 instead of $1.00 on Grok-build-0.1 — roughly 75-85% below standard input depending on model. xAI publishes no single site-wide discount figure.
What are the Grok API rate limits?
Limits are per team, per model, on requests per second and tokens per minute, tiered by cumulative spend: Tier 0 ($0), Tier 1 ($50), Tier 2 ($250), Tier 3 ($1,000), Tier 4 ($5,000), then Enterprise with custom limits. The catalog lists Grok-4.7 at 150 RPS / 50M TPM; limits rise as tiers unlock.
Conclusion: The Operational Verdict
At xAI’s current published rates, Grok-4.7 is $2.00 / $6.00 per 1M tokens, Grok-4.5 $2.00 / $6.00, Grok-4.3 and Grok-4.20 $1.25 / $2.50, Grok-build-0.1 $1.00 / $2.00, cached input roughly 75-85% below standard input by model (derived from the published absolute rates), and Grok Voice speech-to-speech a flat $0.08 per minute plus $0.004 per text input. Grok-3 is retired and redirects to Grok-4.3. Page updated October 2, 2026.
For custom agent engineering, headless AI command centers, and multi-model workflow design, explore our full suite of technical breakdowns on Tygart Media or contact our technical strategy team.