Tag: AI Agents

  • Notion Developer Platform: What Changes for Claude

    Notion Developer Platform: What Changes for Claude

    Last refreshed: May 15, 2026
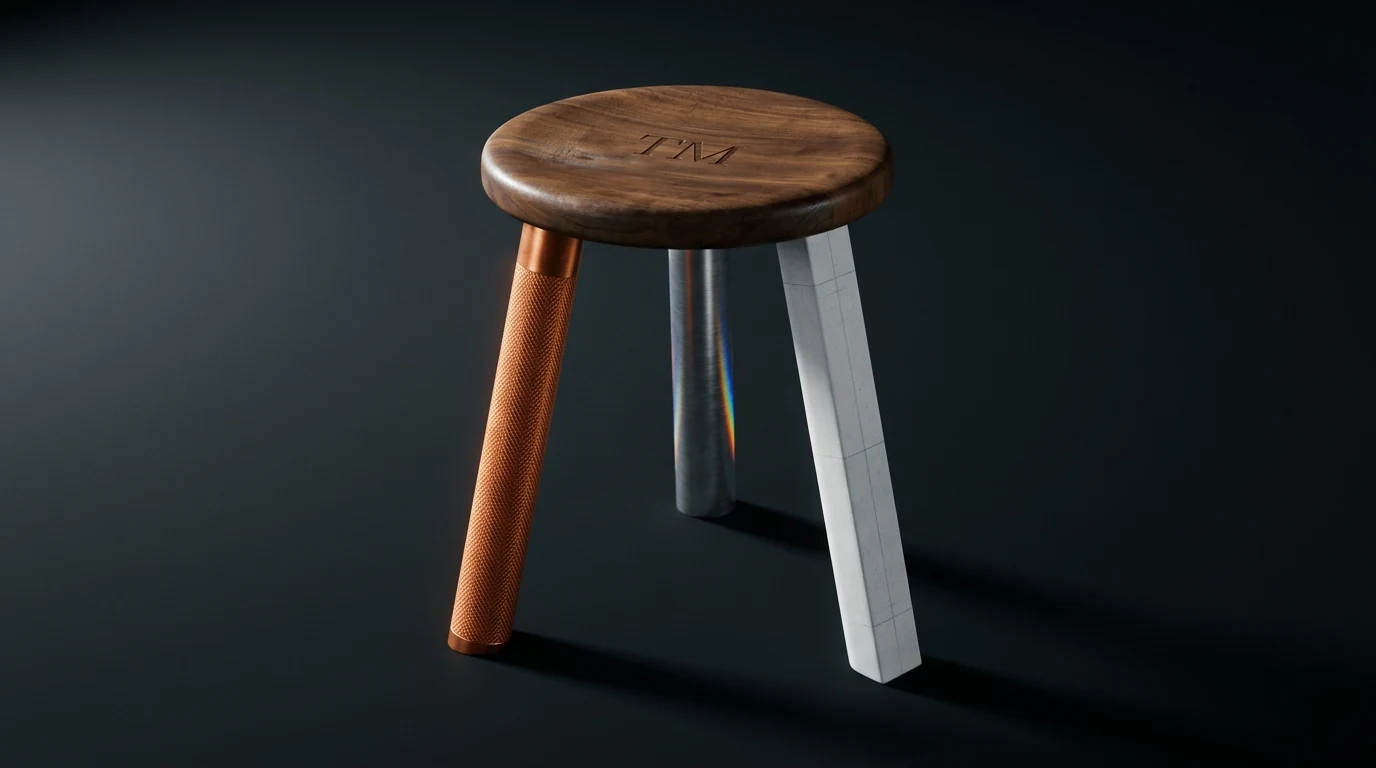
    The Three-Legged Stack: Claude, Notion, GCP - walnut stool with copper, porcelain, and steel legs representing the Tygart Media AI operating stack
    Notion’s May 13 Developer Platform launch reshapes how the Notion + Claude + GCP stack fits together.

    On May 13, 2026, Notion shipped what is, structurally, the biggest change to how Notion fits into an AI-driven operating stack since the original Notion AI launch. Version 3.5 — the Notion Developer Platform — turns Notion from a workspace that you operate into a platform that other agents can operate inside. Claude is one of the launch partners.

    This article is written from inside the practice of running a business on a three-legged stool of Notion, Claude, and Google Cloud. The Developer Platform launch matters to that stool in specific ways, and most of the day-one coverage is missing them. The goal here is to pin down what shipped, what it actually changes for an operator who already runs Claude against Notion, and where the seams are between this platform and the way most of us were already wiring things together.

    What Notion actually shipped on May 13, 2026

    From Notion’s own release notes for version 3.5 (verified May 15, 2026), the Developer Platform comprises four meaningfully distinct pieces:

    Workers. A cloud-based runtime that runs custom code inside Notion’s infrastructure. Workers is how you take a Notion-resident workflow and bind real compute to it — running on a schedule, reacting to a database trigger, fanning work out to other systems — without standing up your own infrastructure for the runtime.

    Database sync. Notion databases can now pull live data from any API-enabled external source. The thing that used to require a Zapier or Make.com bridge becomes a property of the database itself.

    External Agents API. The piece that matters most for Claude users: an outside AI agent can appear and operate inside the Notion workspace as a first-class collaborator. Claude is one of the launch partners, alongside Cursor, Codex, and Decagon.

    Notion CLI. A command-line tool through which both developers and agents interact with the platform. Available across all plan tiers.

    The packaging detail worth noting: Workers and the Developer Platform deployment surface are limited to Business and Enterprise plans, but the External Agents API and the CLI are available on all tiers. The whole platform is free to use through August 11, 2026.

    The shift in framing, in operator terms

    Before May 13, the standard pattern for getting Claude to work with Notion looked like this: install a Notion MCP server, point Claude Code at it, and use Claude as the active driver that reads from and writes to Notion through tool calls. Notion was the database, Claude was the agent, MCP was the wire.

    After May 13, the relationship can flip. The External Agents API lets Claude appear inside Notion — not as an external tool you switch to, but as a collaborator your team can assign work to from the same task board where you assign work to humans. The wire is no longer “Claude reaches into Notion when called.” It’s “Notion can hand work to Claude the same way it can hand work to a person.”

    For an operator running a second-brain architecture, that’s a meaningful change. It moves Claude from a tool you invoke into a participant your system operates against. Both modes are still available — MCP wiring still works fine — but the External Agents API opens a different set of patterns where the system of record stays in Notion and Claude becomes one of several agents that the system orchestrates.

    Where this fits in the three-legged stool

    For anyone running Notion + Claude + Google Cloud as the operating stack of a small business or solo operator setup, the Developer Platform launch reinforces something the architecture was already pointing at: Notion is the system of record, Claude is the reasoning layer, GCP is the compute and data substrate. The May 13 launch makes that division of labor more legible.

    • Notion as system of record — Workers and database sync make Notion an active control plane, not just a passive document store. State lives here. Workflows initiate here.
    • Claude as reasoning layer — The External Agents API gives Claude a formal role inside Notion’s task management, planning, and review loops. Claude does the thinking; Notion holds the result.
    • GCP as compute substrate — Anything Workers can’t do (long-running automation, heavy compute, custom data pipelines, things that need to live behind a firewall), Cloud Run and Compute Engine still handle. Workers doesn’t replace GCP for the operations that need real horsepower; it extends Notion into the lightweight automation gap that previously required a Zapier-class bridge.

    The leg that grows the most from this launch is Notion. It picks up native automation and native AI-agent orchestration in one shipment. The leg that doesn’t change is Google Cloud — GCP is still where the heavyweight workloads live, the per-site WordPress fortresses run, and the custom Python and Node services that hold the operational glue together.

    The Claude-specific implications

    Anthropic’s customer page on Notion (verified May 15, 2026) confirms that Notion has integrated Claude Managed Agents — the version of Claude designed for long-running sessions with persistent memory and high-quality multi-turn outputs. Notion has also made Claude Opus available inside Notion Agent for the first time as part of the broader integration. The framing from Anthropic’s side: Notion is a design partner that helped shape Claude Code’s early development, and the External Agents API is the formal extension of that partnership into the Notion product surface.

    Practically, three things change for someone who already runs Claude against Notion:

    1. The MCP wiring is no longer the only path. If you’ve been using a Notion MCP server to give Claude Code read-write access to your workspace, that pattern still works and still has its place — particularly for developer workflows where Claude is doing the driving. But for operational workflows where Notion should drive and Claude should respond, the External Agents API is now the more natural fit.

    2. Multi-agent orchestration becomes a first-class concept. When Notion can address Claude, Cursor, Codex, and Decagon as discrete agents, the question stops being “which AI tool do I use” and becomes “which agent gets which task.” That’s a richer surface for actually distributing work across capabilities — Cursor for IDE-bound coding, Claude for long-form reasoning and writing, Decagon for customer-facing workflows. The orchestration sits in Notion.

    3. The persistent-memory pattern gets cleaner. The “Notion as Claude’s memory” architecture that we and others have been building with MCP wiring is now a supported, native pattern rather than a clever workaround. The structured pages, databases, and templates that hold what Claude needs to remember between sessions can now be addressed through a sanctioned API rather than reverse-engineered through tool calls.

    What we’d actually rebuild now

    If we were starting our second-brain architecture from scratch on May 15, 2026, knowing what shipped on May 13, the build order would be different than what we have today:

    • Database structures stay in Notion — same as before. The systems of record (clients, projects, content pipelines, scheduled tasks, the Promotion Ledger) all live in Notion databases.
    • Sync replaces a meaningful chunk of Zapier/Make — anywhere we currently bridge Notion to an external API for read or for write, native database sync becomes the first thing to try before reaching for a third-party automation tool.
    • Workers handles light recurring automation — the kind of thing we currently run as a Cloud Run cron job, where the trigger and state both live in Notion. Workers is closer to the data and easier to reason about for operators who don’t want to context-switch out of Notion.
    • External Agents API for Claude orchestration — Claude assignments come from inside Notion’s task surfaces. The Promotion Ledger, the editorial calendar, the client deliverable boards all become places where Claude can be assigned the same way a teammate is assigned.
    • GCP holds everything that’s heavyweight or sensitive — WordPress fortresses, custom data pipelines, anything HIPAA/regulated, the AI Media Architect run on Cloud Run, the knowledge-cluster-vm. None of this moves. Notion’s platform doesn’t compete here.

    The honest part: most of our existing infrastructure is staying. The Developer Platform launch isn’t a “rebuild everything” moment. It’s a “reach for Notion-native first when the workflow naturally lives in Notion anyway” moment. Where we used to glue together MCP servers, Zapier flows, and custom Cloud Run jobs to bridge gaps, the gaps are smaller now.

    The seams worth noticing

    Three things to be honest about:

    Workers is plan-gated. If you’re on a Notion plan below Business, you can use the External Agents API and the CLI but not Workers. The full programmable-platform vision requires the upgrade. For solo operators on Plus or below, this is a real friction point.

    The free-through-August window is a usage signal, not a permanent state. The Developer Platform is free through August 11, 2026. Notion has not yet published post-window pricing. Anyone building production workloads against the platform should plan for the possibility of a usage-based or tier-gated pricing model after that date.

    External Agents is a launch-partner-first model. Claude Code, Cursor, Codex, and Decagon are first-class. Other agents — and there will be other agents — show up later through the API. If your stack depends on an agent that isn’t on the launch partner list, the surface for integrating it is smaller right now than it will be in a few months.

    What to actually do this week

    If you’re running Claude against Notion in any operational capacity:

    1. Read Notion’s official release notes for 3.5 (notion.com/releases/2026-05-13). It’s short and concrete.
    2. Try the Notion CLI on a non-production workspace. The CLI is the lowest-friction way to feel what’s actually changed.
    3. If you have any workflow currently glued together with Zapier/Make where the trigger and state are both in Notion, evaluate whether database sync or Workers replaces it more cleanly.
    4. If you currently invoke Claude through MCP for tasks that would more naturally be assigned to Claude from inside Notion’s task boards, prototype the same workflow through the External Agents API and compare.
    5. Don’t migrate anything you don’t have to. The May 13 launch creates new options, not new mandates.

    Related on Tygart Media: how to use Claude · GA4 Intelligence Kits.

    Frequently Asked Questions

    What is the Notion Developer Platform?

    It’s the May 13, 2026 release (Notion 3.5) that adds Workers (cloud-based runtime), database sync (live data from external APIs), an External Agents API (outside AI agents operating natively inside Notion), and a Notion CLI. It turns Notion from an application you use into a platform you and your agents can build on.

    Is Claude one of the launch partners?

    Yes. Per Notion’s release notes and Anthropic’s customer page on Notion (both verified May 15, 2026), Claude is a launch partner alongside Cursor, Codex, and Decagon. Notion has also integrated Claude Managed Agents and made Claude Opus available inside Notion Agent.

    How is the External Agents API different from connecting Claude through MCP?

    MCP wiring lets Claude reach into Notion through tool calls — Claude is the driver, Notion is the data source. The External Agents API lets Claude appear inside Notion as a collaborator that can be assigned work — Notion is the driver, Claude is one of several agents responding. Both patterns coexist. Pick the one that matches who should be in charge of the workflow.

    What does the Developer Platform cost?

    Free through August 11, 2026, per Notion’s release notes. Workers and the deploy surface are limited to Business and Enterprise plans; the External Agents API and CLI are available across all tiers. Post-window pricing has not been published as of May 15, 2026.

    Does this replace MCP servers?

    No. MCP servers remain useful — particularly for developer workflows where Claude is doing the driving from inside Claude Code, and for cases where you need Claude to talk to multiple systems (not just Notion). The External Agents API adds an alternative pattern for the cases where Notion should hold the workflow and Claude should respond to it.

    Should I move workloads off Google Cloud onto Notion Workers?

    For most things, no. Workers is suited to lightweight, Notion-native automation. Heavy compute, regulated workloads, custom data pipelines, and anything that needs to live behind a firewall still belong on GCP (or your equivalent cloud). The Developer Platform extends what Notion can do natively; it doesn’t replace what cloud infrastructure does.

    Related Reading

    How we sourced this

    Sources reviewed May 15, 2026:

    • Notion official release notes: May 13, 2026 – 3.5: Notion Developer Platform at notion.com/releases/2026-05-13 (primary source for what shipped, pricing window, plan-tier gating)
    • Anthropic customer page on Notion at claude.com/customers/notion (primary source for Claude Managed Agents integration, Opus availability in Notion Agent, design-partner relationship)
    • TechCrunch coverage of the May 13 launch (Tier 2 confirming source for partner agent list and “control room for AI agents” framing)
    • InfoWorld coverage of the Notion Developer Platform launch (Tier 2 confirming source)
    • BetaNews and Dataconomy coverage (additional Tier 2 confirming sources)

    This article will need a refresh after August 11, 2026, when the free-pricing window ends and Notion publishes post-window pricing details. The verified-vs-reported standard from our other May 2026 pieces applies — anything beyond what Notion’s own release notes and Anthropic’s customer page confirm has been clearly distinguished.
  • Claude Agent SDK Dual-Bucket Billing: What Changes June 15, 2026 (And Why It Matters)

    Claude Agent SDK Dual-Bucket Billing: What Changes June 15, 2026 (And Why It Matters)

    Last refreshed: June 9, 2026

    If you’ve been running Claude Code’s claude -p command in production, kicking off background jobs through the Claude Agent SDK, or wiring the Agent SDK into a third-party app, the way you pay for that work is about to change.

    Starting June 15, 2026, Anthropic is splitting Claude subscription billing into two separate buckets: one for the things you do interactively (Claude.ai chat, Claude Code in your terminal, Claude Cowork), and a brand-new credit pool that only covers programmatic, autonomous, and SDK-driven work.

    This is a meaningful shift. It’s also one of the most under-explained changes Anthropic has made to subscription pricing this year. If you don’t know about it after June 15, 2026 (now in effect), you can find yourself with stopped automations, surprise overage charges, or both.

    This guide walks through exactly what’s changing, what the credits cover, what they don’t cover, what each plan gets, and how to plan for it — this change is now live.

    Agent SDK Monthly Credit by Plan (June 2026)

    Workshop fuel gauge and metal tokens pouring into an API hopper, metaphor for pay-per-token pricing
    Agent SDK monthly credit by plan — no sticky dollars.
    PlanMonthly PriceAgent SDK Credit/MonthCovers
    Pro$20/month$20claude -p, SDK jobs, GitHub Actions
    Max 5x$100/month$100claude -p, SDK jobs, GitHub Actions
    Max 20x$200/month$200claude -p, SDK jobs, GitHub Actions
    Team Standard$20/seat/mo (annual) or $25/seat/mo (monthly)$20/seatclaude -p, SDK jobs, GitHub Actions
    Team Premium$100/seat/mo (annual)$100/seatclaude -p, SDK jobs, GitHub Actions
    Enterprise (usage-based)Custom$20/monthSDK-driven work only
    Enterprise (seat-based Premium)Custom$200/seatSDK-driven work only

    The short version

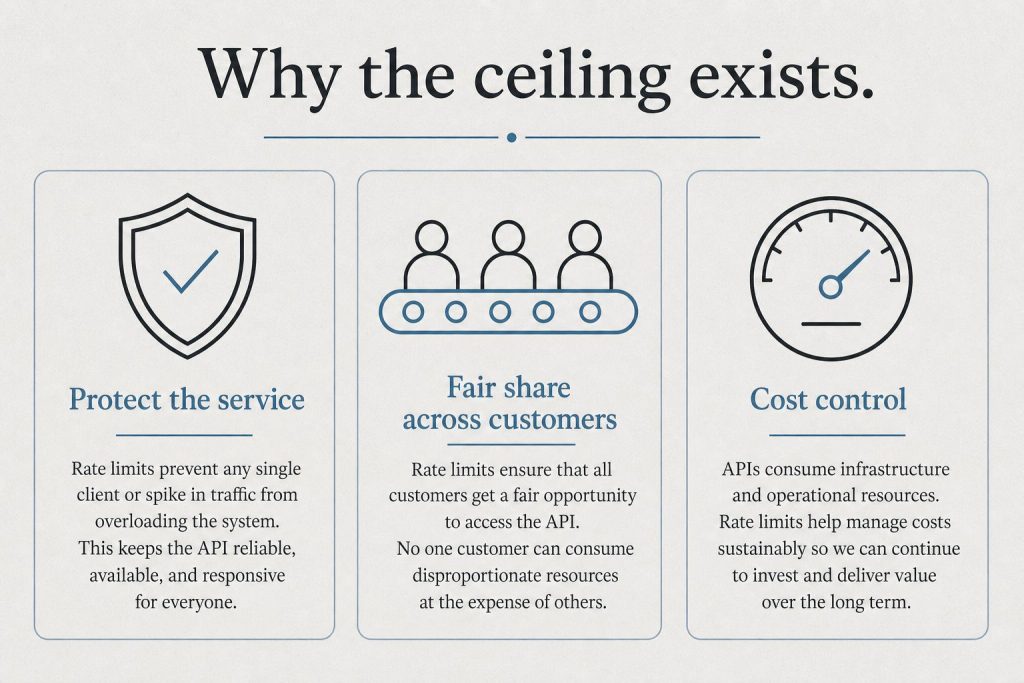
    Infographic with three panels: protect the service, fair share, and cost control explaining rate limits
    The short version of dual-bucket billing.

    Claude subscription plans (Pro, Max, Team, Enterprise) currently have one shared usage limit. Whether you’re chatting with Claude on the web, using Claude Code in your terminal, or running unattended jobs through the Agent SDK, all of that draws from the same plan-level allowance.

    On June 15, 2026, Anthropic is separating those two modes of use:

    • Bucket 1 — Interactive use: Claude.ai chat, Claude Code in the terminal/IDE, Claude Cowork. Uses your existing subscription usage limits, exactly as before.
    • Bucket 2 — Agent SDK monthly credit: A separate, dollar-denominated credit pool. Funds the Claude Agent SDK, the claude -p non-interactive command, the Claude Code GitHub Actions integration, and any third-party app that authenticates via the Agent SDK.

    The two buckets do not commingle. Agent SDK work cannot draw from your interactive subscription limit, and interactive use cannot draw from your Agent SDK credit. If you exhaust your Agent SDK credit and don’t have extra usage enabled, your background jobs simply stop until the credit refreshes the following month.

    What each plan gets

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    What each plan gets.

    Here is the official monthly Agent SDK credit by plan, as published in Anthropic’s Help Center (verified June 9, 2026):

    • Pro: $20/month
    • Max 5x: $100/month
    • Max 20x: $200/month
    • Team — Standard seats: $20/month per seat
    • Team — Premium seats: $100/month per seat
    • Enterprise — usage-based: $20/month
    • Enterprise — seat-based Premium seats: $200/month

    Important detail buried in the announcement: Enterprise seat-based plans on Standard seats are not eligible to claim the Agent SDK credit at all. If you administer one of those plans and have engineers running automation, that’s a gap to plan around.

    What the credit covers (and what it doesn’t)

    Anthropic’s documentation is specific about what counts as Agent SDK use, so this is worth reading carefully.

    Covered by the credit:

    • Claude Agent SDK usage in your own Python or TypeScript projects
    • The claude -p command in Claude Code (non-interactive mode)
    • The Claude Code GitHub Actions integration
    • Third-party apps that authenticate with your Claude subscription through the Agent SDK

    Not covered (these still draw from your normal subscription limits):

    • Interactive Claude Code in your terminal or IDE
    • Claude conversations on web, desktop, or mobile
    • Claude Cowork
    • Other features that draw from extra usage

    The plain-English version: if a human is sitting at the keyboard waiting for the response, that’s interactive use. If a script kicks off the work and the result lands somewhere else later, that’s Agent SDK use.

    How the credit actually works in practice

    Five mechanics matter for budgeting:

    1. Per-user, never pooled. Each eligible user on a Team or Enterprise plan claims their own credit. There is no organization-level pool. Credits cannot be transferred between users, shared, or stockpiled across accounts.

    2. Refreshes monthly with the billing cycle. Whatever you don’t spend in a given month evaporates. Unused credits do not roll over.

    3. One-time opt-in. You claim your credit through your Claude account once. After that initial claim, it refreshes automatically each cycle.

    4. Drains first, before any other source. When an Agent SDK request fires, it pulls from your monthly credit before any other paid usage source kicks in. This is good — it means you actually use what you’ve already paid for.

    5. After the credit, requests either flow to extra usage or stop entirely. When your monthly credit hits zero, additional Agent SDK requests draw from extra usage at standard API rates — but only if you have extra usage enabled. If you haven’t enabled extra usage, your Agent SDK requests stop until the next refresh.

    That last point is the one most likely to bite teams. If you’re running a daily cron job through the Agent SDK and you don’t enable extra usage, the day your credit runs out is the day your automation goes silent — without obvious warning if you’re not watching the credit balance.

    Why Anthropic is doing this

    Anthropic frames this as separating individual experimentation from production automation. From the Help Center documentation: “The Agent SDK monthly credit is sized for individual experimentation and automation. Teams running shared production automation should use the Claude Developer Platform with an API key for predictable pay-as-you-go billing.”

    The translation: a single user’s $20 or $200 of Agent SDK credit was never going to cover a real production workload anyway. Anthropic is making explicit what was already true under the hood — that a subscription was a chat product, and serious unattended automation belongs on the API.

    What this also does, structurally, is protect interactive subscription users from getting their experience degraded by heavy autonomous workloads sharing the same pool. If you’ve ever hit a subscription rate limit during a normal chat session because something else on your account was burning tokens in the background, this change removes that failure mode.

    What you should do after June 15, 2026 (now in effect), 2026

    If you run any unattended Claude work (the most important group):

    Audit every place your subscription is being used by something other than a human at a keyboard. The big four to check:

    • claude -p commands in cron jobs, CI pipelines, or shell scripts
    • Claude Code GitHub Actions workflows
    • Custom Python or TypeScript projects using the Agent SDK
    • Any third-party tool that asks for “Sign in with Claude” — those go through the Agent SDK

    For each one, estimate dollar consumption per day at standard API rates. If the total approaches or exceeds your plan’s Agent SDK monthly credit, you have three options: enable extra usage to allow overage, move that workload to a Claude Developer Platform API key (more predictable for sustained loads), or downsize the workload itself.

    If you administer a Team or Enterprise plan:

    Eligible users on your team will receive an email with claim instructions after June 15, 2026 (now in effect), 2026. You don’t need to take action yourself, but it’s worth communicating internally that the credits are per-user, can’t be pooled, and that any team-wide automation should be on an API key, not on a subscription seat.

    If you’re a solo Pro or Max user who only chats with Claude:

    You probably don’t need to do anything. The split affects you only if you’re running scripts or background jobs. If you’ve never used claude -p or the Agent SDK directly, your interactive usage limits don’t change.

    Related on Tygart Media: how to use Claude · Anthropic API key.

    Frequently Asked Questions

    What happens to my Agent SDK usage on June 14 vs. June 15, 2026?

    Before June 15, Agent SDK and claude -p usage counts against your subscription’s general usage limits. Starting June 15, that same usage no longer touches your subscription limits and instead draws from the new Agent SDK monthly credit pool. Your interactive Claude Code, web chat, and Cowork usage continues to work exactly as before.

    Can I share the Agent SDK credit across my team?

    No. Per Anthropic’s official documentation, “Credits are per-user. Each eligible user on your team claims their own credit. Credits can’t be pooled, transferred, or shared across the organization.” If your team needs shared automation budget, the Claude Developer Platform with an API key is the recommended path.

    Do unused Agent SDK credits roll over?

    No. Unused credits expire at the end of each billing cycle and do not carry into the next month.

    What happens if I run out of Agent SDK credit mid-month?

    If you have extra usage enabled, additional requests flow to extra usage at standard API rates (the same per-token prices listed in Anthropic’s pricing documentation). If extra usage is not enabled, your Agent SDK requests stop until your credit refreshes at the start of the next billing cycle.

    Does this affect Claude API customers using their own API key?

    No. If you authenticate with the Agent SDK using a Claude Developer Platform API key, nothing changes. Pay-as-you-go billing continues, and you do not receive an Agent SDK monthly credit. The credit only applies to subscription-authenticated Agent SDK use.

    Is interactive Claude Code in my terminal still covered by my subscription?

    Yes. Interactive Claude Code (typing commands and getting responses in your terminal or IDE) continues to draw from your subscription usage limits exactly as before. Only the non-interactive claude -p mode and direct Agent SDK calls move to the new credit pool.

    What’s the dollar value of the credit on each plan?

    As of May 15, 2026: Pro $20, Max 5x $100, Max 20x $200, Team Standard $20/seat, Team Premium $100/seat, Enterprise usage-based $20, Enterprise seat-based Premium $200. Enterprise seat-based Standard seats do not receive a credit.

    Related Reading

    How we sourced this

    Every factual claim in this article was triple-checked across the following sources, all reviewed on May 15, 2026:

    • Anthropic Help Center: Use the Claude Agent SDK with your Claude plan (primary source for credit amounts, eligibility, and mechanics)
    • Anthropic Pricing Documentation: docs.claude.com/en/docs/about-claude/pricing (primary source for standard API rates and tool-use pricing)
    • Independent press coverage from The New Stack, The Decoder, and InfoWorld confirming the announcement and its scope

    If you spot a number that’s drifted out of sync with Anthropic’s current published rates, treat the official documentation as authoritative. The pricing surface around Claude is moving quickly in 2026, and we date-stamp specifics so readers know which facts to re-verify.

    Frequently Asked Questions

    What is the Claude Agent SDK dual-bucket billing change?

    Starting June 15, 2026, Anthropic split Claude subscription billing into two buckets. Bucket 1 covers interactive use (claude.ai chat, Claude Code in terminal, Cowork). Bucket 2 is a separate monthly credit pool that covers only programmatic/autonomous work via the Claude Agent SDK, the claude -p command, and GitHub Actions integration.

    What happens if I run out of Agent SDK credit?

    If you exhaust your Agent SDK monthly credit and don’t have extra usage enabled, your background jobs and SDK-driven automations simply stop until the credit refreshes the following month. Interactive Claude use (chat, Claude Code in terminal) is unaffected — it draws from a separate bucket.

    How much Agent SDK credit does each Claude plan include?

    Pro: $20/month. Max 5x: $100/month. Max 20x: $200/month. Team Standard: $20/seat/month. Team Premium: $100/seat/month. Enterprise seat-based Premium: $200/seat/month. The credit is dollar-denominated and depletes at standard API token rates for whichever model your SDK jobs use.

    Does the Agent SDK credit apply to Claude Code in the terminal?

    No. Claude Code used interactively in your terminal or IDE draws from Bucket 1 (your subscription usage limit), not from the Agent SDK credit pool. Only non-interactive, programmatic use via the Agent SDK and claude -p command draws from the Agent SDK credit bucket.

    Can I add more Agent SDK credit if I run out?

    Yes. You can enable extra usage on Pro, Max 5x, Max 20x, and Team plans. Once enabled, SDK jobs that exceed your monthly credit continue at standard API rates with a spending cap you set, rather than stopping entirely.

    Which Claude plans don’t get Agent SDK credit?

    The Free plan receives no Agent SDK credit. Free tier users cannot run programmatic SDK workloads at all — that requires at minimum a Pro subscription at $20/month.

  • Zapier AI Orchestration: Building the Everything App

    Zapier AI Orchestration: Building the Everything App

    What Is Zapier? Zapier is a no-code automation platform founded in 2011 that connects over 8,000 apps through a unified workflow engine. Originally built around simple “if this, then that” triggers, Zapier has transformed in 2025–2026 into an AI orchestration platform—adding autonomous agents, multi-model AI routing, natural language workflow building, and an MCP server that exposes its entire integration library to external AI models including Claude.

    Every company in this series has come at the everything app from a position of strength. Microsoft from enterprise software. Google from search. OpenAI from the frontier model. Mistral from sovereignty and open source. But none of them started where Zapier started: already inside your workflows, connected to every tool you use, trusted with the actual operations of your business.

    That’s the sleeper advantage in this race. While everyone else is building toward the everything app from the outside in, Zapier has been inside the everything app since the day you first connected your Gmail to your CRM.

    The question is whether a 13-year-old automation company can evolve fast enough to own the AI orchestration layer—or whether it becomes the platform that makes everyone else’s AI more powerful.

    📚 Everything App Series

    This is article 9 in our ongoing series examining which AI companies are building the everything app:

    The Transformation: From Connector to Orchestrator

    Three stacked layers: chat UI, tools, agent runtime
    From connector to orchestrator.

    For most of its first decade, Zapier’s value proposition was simple: connect two apps without writing code. You set a trigger (“when I get a new email in Gmail”), define an action (“add a row to my Google Sheet”), and Zapier ran the automation in the background. Powerful, but fundamentally passive. Zapier did what you told it to do.

    In 2025, that changed fundamentally. Zapier relaunched its positioning as an AI Orchestration Platform and shipped three products that move it from passive connector to active AI layer:

    Zapier Copilot lets you describe a workflow in plain language and watch Zapier build it. Instead of manually connecting triggers and actions, you say “whenever a new lead comes in from our website form, research them on LinkedIn, score them, and add the qualified ones to our CRM with a draft follow-up email.” Copilot builds the multi-step Zap. This collapses the skill barrier that kept many users on simpler workflows.

    Zapier Agents, launched in January 2025 and reaching general availability in December 2025, are autonomous AI teammates. Unlike Zaps (which follow a fixed sequence), Agents decide how to accomplish a goal. You give an Agent a role—”you are our inbound lead coordinator”—a set of tools from Zapier’s app library, and a goal. The Agent reasons through the task, calls the appropriate tools in whatever order makes sense, handles exceptions, and reports back. In August 2025, Zapier added agent-to-agent orchestration, letting Agents delegate subtasks to specialist Agents—the first multi-agent architecture available to non-developers at scale.

    Zapier Canvas is the visual command center that maps how all of this fits together: your Zaps, Tables, Interfaces, Chatbots, and Agents displayed as a connected system. Canvas makes the invisible visible—you can finally see the full automation architecture of your business and edit it from a single surface.

    The 8,000-App Moat

    Here’s the number that matters more than any AI feature: 8,000 connected apps.

    Building an AI integration with a single app is straightforward. Building reliable, maintained, authenticated integrations with 8,000 apps—including niche tools that serve specific industries, legacy enterprise software, and the long tail of SaaS that most AI companies ignore—is a 13-year infrastructure investment that no new entrant can replicate quickly.

    Every AI model that wants to take actions in the real world faces the same problem: getting access to the apps where work actually happens. OpenAI is building these integrations one by one. Google has its own ecosystem but a limited integration library beyond Workspace. Microsoft covers the Office stack but leaves everything else to third parties.

    Zapier already has the connectors. That means Zapier Agents can operate across your full stack on day one—not the curated stack of apps a closed AI platform supports, but the actual combination of tools your business uses, however idiosyncratic.

    Zapier MCP: The Move That Changes the Competitive Map

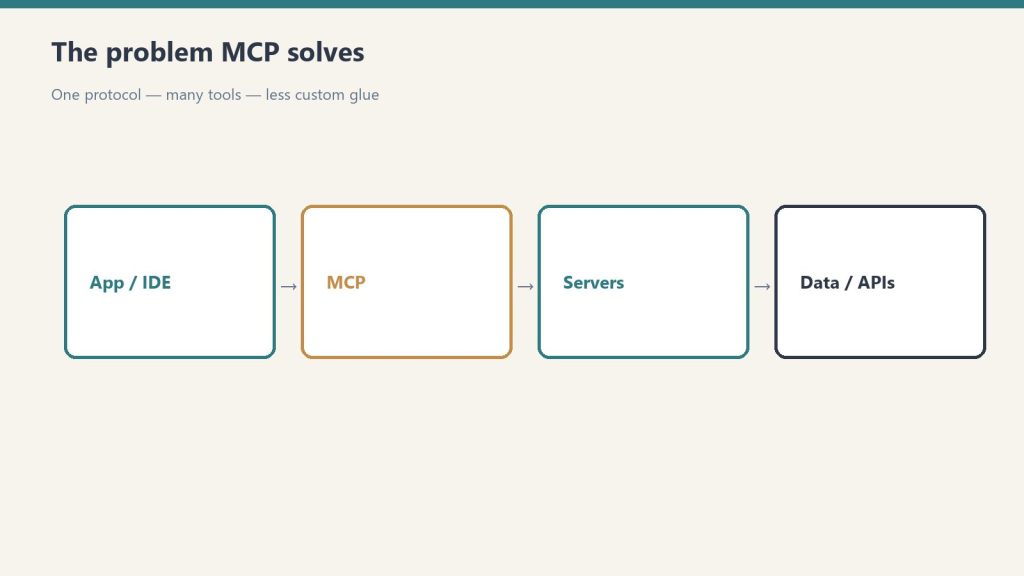
    Flow from app/IDE through MCP to servers and data APIs
    Zapier MCP — the competitive map shift.

    The most strategically significant product Zapier shipped in 2025 wasn’t Agents. It was Zapier MCP.

    Model Context Protocol (MCP) is the emerging standard that lets AI models call external tools. Zapier built an MCP server that exposes its entire integration library—all 8,000+ apps, tens of thousands of actions—to any AI model that speaks MCP. Claude can use it. GPT-4o can use it. Any MCP-compatible AI can use it.

    This is Zapier making a platform bet rather than a product bet. Instead of trying to be the AI model that users talk to, Zapier is becoming the action layer that every AI model reaches into when it needs to do something in the real world. The developer and coding agents plug in through the SDK. The AI assistants plug in through MCP. IT administrators see everything through unified audit logs and governance controls.

    Zapier is an official Anthropic integration partner. When Claude users need their AI to actually send an email, update a CRM record, add a calendar event, or post to Slack—Zapier is the infrastructure doing that work. That’s not a small bet. That’s positioning as the execution layer for the entire AI industry.

    The Financial Position: Profitable, Independent, Patient

    One underappreciated aspect of Zapier’s strategic position is its financial independence. Unlike most AI companies burning through venture capital at extraordinary rates, Zapier has been profitable for years. It has raised minimal external funding—approximately $1.4 million in a 2012 seed round and nothing significant since—and generates its own growth from revenue.

    Revenue reached $310 million in 2024 and is projected to approach $400 million in 2025. The company serves over 100,000 business customers. Its valuation is estimated around $5 billion—modest relative to OpenAI, Anthropic, or Mistral’s recent rounds, but built on actual cash flow rather than projected futures.

    This matters for the everything app question because Zapier is not under pressure to show explosive AI growth to justify a valuation. It can evolve its platform deliberately, double down on enterprise reliability, and build the trust that enterprise automation requires—without the distraction of a fundraising cycle or the fear of running out of runway.

    Zapier’s Approach to Enterprise AI Governance

    Five security domains: identity, data, code governance, audit, agents
    Enterprise AI governance approach.

    One of the signal differences between Zapier’s AI platform and its competitors is the emphasis on controls alongside capability. The February 2026 product updates focused specifically on AI guardrails and governance: who can create agents, what apps agents can access, what actions require human approval, and full audit logs of everything that ran.

    This is the unsexy but critical work of making AI deployable in regulated environments. An autonomous agent that can send emails, update databases, and call external APIs is a significant liability risk without proper governance. Zapier’s enterprise controls—managed credentials, admin dashboards, approval workflows for high-risk actions, comprehensive audit trails—represent years of enterprise trust-building that AI-first startups are only beginning to think about.

    The AI guardrails feature allows administrators to set boundaries on what Agents can do autonomously versus what requires a human in the loop. This isn’t a limitation on Zapier’s AI ambitions—it’s the feature that gets Zapier past the enterprise security review that blocks most AI tools from production deployment.

    The Notion Everything Database Connection

    If you’re using Notion as an everything database—as we explored earlier in this series—Zapier is one of the most powerful connectors in your stack. Zapier’s Notion integration supports triggers on database property changes, creating and updating pages, querying databases, and more. Zapier Agents can use these Notion actions as tools, meaning an Agent can reason about your Notion data, make decisions, and update records—all without you touching a line of code.

    The practical architecture looks like this: your Notion everything database stores structured business context. A Zapier Agent monitors specific triggers (a new record appears, a property changes, a status updates). The Agent pulls relevant context from Notion, reasons over it using its AI model, takes actions across your other connected apps, and writes results back to Notion. The entire workflow runs in the background, governed by your Zapier admin controls, with full audit logs.

    For teams building on the Notion everything database model, Zapier isn’t competing with that architecture—it’s the automation and agent layer that makes it operational. You design the data model in Notion; Zapier handles the movement and the intelligence on top of it.

    Where Zapier Falls Short

    Zapier’s everything app candidacy has real limits, and they’re worth naming plainly.

    First, Zapier is a B2B tool that has never built meaningful consumer presence. Everything apps in the historical sense—WeChat, Line, Grab, Gojek—succeed by capturing daily personal habits: messaging, payments, food delivery. Zapier operates in the workflow automation category, which is powerful for businesses but invisible to consumers. There is no path from Zapier’s current position to consumer everything app.

    Second, Zapier depends on the apps in its library. If OpenAI, Google, or Microsoft decides to deprecate their public APIs or make integration prohibitively expensive, Zapier’s connectors break. The 8,000-app moat is only as strong as those 8,000 companies’ continued willingness to maintain open APIs. As AI platforms consolidate, that willingness may erode.

    Third, Zapier’s AI layer is not a frontier model. Zapier Agents use third-party models (primarily OpenAI’s GPT-4o and related) for their reasoning capabilities. This means Zapier’s AI quality ceiling is set by someone else. When OpenAI ships a better model, Zapier agents get smarter—but so does every OpenAI customer. Zapier cannot differentiate on model quality the way Mistral or OpenAI can.

    Finally, the no-code positioning that made Zapier accessible also limits its ceiling. Complex enterprise workflows—the kind that justify serious AI investment—often require the custom logic, error handling, and integration depth that Zapier’s visual interface makes difficult. Competitors like n8n (open-source), Make (formerly Integromat), and enterprise-focused platforms like MuleSoft are taking direct aim at the workflows Zapier can’t handle.

    The Verdict: The Action Layer, Not the Interface Layer

    Is Zapier building the everything app? Not in the way the term is usually understood. Zapier is not trying to be the app you open every morning, the one that knows your identity, your preferences, and your social graph. It has no interest in capturing your attention or your feed.

    Zapier is building something that might matter more for AI’s actual impact on work: the universal action layer. The layer that every AI model reaches into when it needs to do something that matters. The layer that connects AI reasoning to business reality across the entire software ecosystem—not the 50 apps in one company’s walled garden, but the 8,000 apps that businesses actually use.

    In a world where every AI platform is competing to be your interface, Zapier is quietly becoming the infrastructure that makes any interface actually work. That’s not the everything app thesis. It’s the everything execution thesis. And given that 13 years of profitable growth and 100,000 enterprise customers are backing it, it may be the most durable bet in this entire series.

    Key Takeaway

    Zapier is not competing to be the everything app. It’s becoming the action layer that makes every everything app actually functional—the 8,000-integration infrastructure that AI models plug into when they need to do real work in real systems.

    What’s Next in This Series

    This article closes the core competitive series on everything app contenders. But the conversation isn’t finished. Two threads we’ve opened in this series deserve their own deep dives: the xAI infrastructure pivot story—whether Elon Musk is quietly turning Colossus and X into the “everything app ability” rather than the everything app itself—and a Track 2 series on how to actually connect each of these platforms to a Notion everything database as your operational backbone.

    If you’ve been following this series from the beginning, you’ve seen the landscape of AI consolidation from nine different angles. The conclusion that keeps emerging: the everything app isn’t a product. It’s a position. And the race to own that position is just getting started.

    Frequently Asked Questions About Zapier and the Everything App

    What is Zapier’s current AI platform called?

    Zapier relaunched in 2025 as an AI Orchestration Platform. The platform includes Zapier Agents (autonomous AI teammates), Zapier Copilot (natural language workflow builder), Zapier Canvas (visual system map), Zapier Tables, Zapier Interfaces, Zapier Chatbots, and Zapier MCP (an integration server for external AI models). The foundational Zaps automation engine remains the core, with these AI products layered on top.

    What is Zapier MCP and why does it matter?

    Zapier MCP is a Model Context Protocol server that exposes Zapier’s entire integration library to external AI models. Any MCP-compatible AI—including Claude, GPT-4o, and others—can use Zapier MCP to take actions across the 8,000+ apps Zapier connects. This makes Zapier the action execution layer for AI systems built by other companies, not just for Zapier’s own agents. Zapier is an official Anthropic integration partner through this mechanism.

    How many apps does Zapier connect?

    As of 2026, Zapier connects over 8,000 apps. This integration library has been built and maintained over 13 years and represents Zapier’s primary competitive moat. No AI-first entrant has built a comparable breadth of authenticated, maintained app integrations.

    What are Zapier Agents?

    Zapier Agents are autonomous AI teammates that reason about goals rather than following fixed if-then sequences. Launched in January 2025 and reaching general availability in December 2025, Agents can browse the web, read data sources, update CRMs, draft communications, and delegate to other specialist agents through multi-agent orchestration. They’re configured with a role, a set of tool permissions, and a goal—then run autonomously within governance guardrails set by administrators.

    How does Zapier integrate with Notion?

    Zapier’s Notion integration supports database triggers, page creation and updates, and database queries. Zapier Agents can use these as tools in their reasoning loops, enabling autonomous workflows that read from and write to Notion databases. For teams using Notion as an everything database, Zapier provides the automation and agent execution layer that makes that data architecture operational across connected business apps.

    Is Zapier profitable?

    Yes. Zapier has been profitable for years and has raised minimal external funding since a $1.4 million seed round in 2012. Revenue reached $310 million in 2024 with projections near $400 million for 2025. This financial independence distinguishes Zapier from most AI platform companies and gives it patience to evolve its platform without fundraising pressure.

    What are Zapier’s AI governance features?

    Zapier offers enterprise AI governance through managed credentials, admin controls on which users and teams can create or deploy agents, approval workflows for high-risk actions, AI guardrails that bound what agents can do autonomously, and comprehensive audit logs of all agent activity. These controls were prominently featured in the February 2026 product update and represent Zapier’s push to make AI deployment safe for regulated enterprise environments.

    How does Zapier compare to Make (Integromat) and n8n?

    Make and n8n are Zapier’s primary competitors in workflow automation. Make offers more complex branching logic at competitive pricing. n8n is open-source and self-hostable, appealing to developers and privacy-conscious enterprises. Zapier differentiates on breadth of integrations, ease of use for non-technical users, and its newer AI layer (Agents, Copilot, MCP). For enterprises prioritizing AI orchestration with governance controls, Zapier’s platform depth currently leads. For developers wanting maximum flexibility or self-hosting, n8n is the primary alternative.

  • Claude Code Hooks: Enforce Workflow Rules Automatically

    Claude Code Hooks: Enforce Workflow Rules Automatically

    Last refreshed: May 15, 2026

    You’ve been there. You add a rule to CLAUDE.md — “always run prettier after editing files” — and Claude follows it, most of the time. Then it doesn’t. The formatter doesn’t run, the lint check gets skipped, and you’re back to reviewing diffs manually.

    Hooks fix this. Claude Code hooks are shell commands, HTTP endpoints, or LLM prompts that fire deterministically at specific points in Claude’s agentic loop. Unlike CLAUDE.md instructions, which are advisory, hooks are enforced at the execution layer — Claude cannot skip them.

    As of early 2026, Claude Code ships with 21 lifecycle events across four hook types. This article covers the two that matter most for daily workflow: PreToolUse and PostToolUse.

    How Hooks Work Architecturally

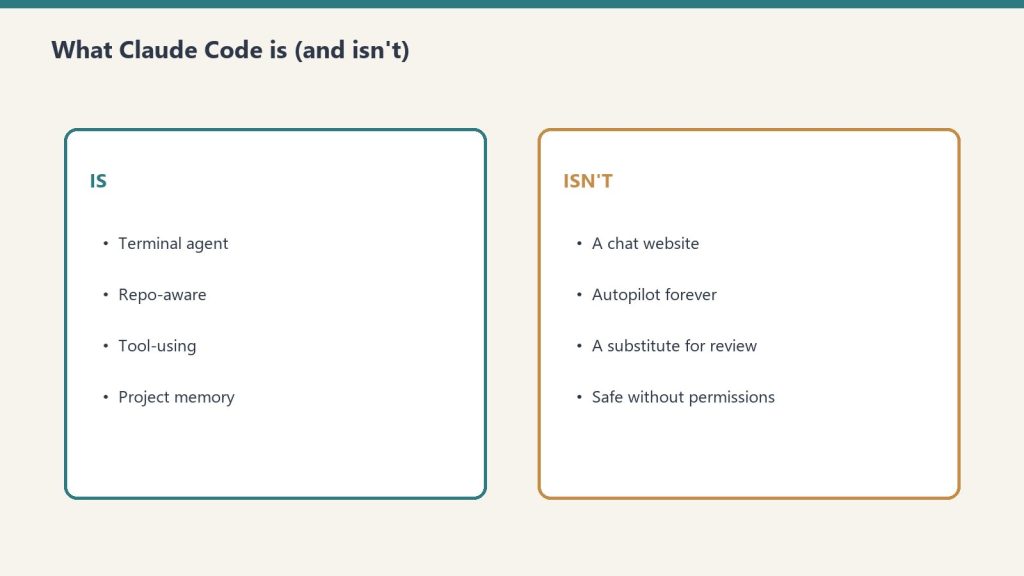
    Side-by-side cards defining what Claude Code is and is not
    How Claude Code hooks work architecturally.

    Claude Code’s agent loop is a continuous cycle: receive input → plan → execute tools → observe results → repeat. Hooks intercept this loop at named checkpoints.

    Every hook is defined in .claude/settings.json under a hooks key. A hook entry has three parts: the lifecycle event name, an optional matcher (a regex against tool names), and the handler definition — either a shell command, an HTTP endpoint, or an LLM prompt.

    {
      "hooks": {
        "PostToolUse": [
          {
            "matcher": "Write|Edit",
            "hooks": [
              {
                "type": "command",
                "command": "npx prettier --write "$CLAUDE_TOOL_INPUT_FILE_PATH""
              }
            ]
          }
        ]
      }
    }

    That’s it. Every file Claude writes or edits now auto-formats. No CLAUDE.md reminders, no hoping Claude remembers — the formatter runs on every single Write or Edit tool call, period.

    PreToolUse: Enforce Before Claude Acts

    Five stacked panels of daily Claude Code command habits
    PreToolUse — enforce before Claude acts.

    PreToolUse fires before Claude executes any tool. Your hook receives the full tool call — name, inputs, arguments — and can return one of three signals:

    • Exit 0 → allow the tool call to proceed
    • Exit 2 → block the tool call; Claude receives your error message and adjusts
    • Exit 1 → hook error; Claude proceeds but logs the failure

    This makes PreToolUse the right place for guardrails. Here’s a real example: blocking npm in a bun project.

    #!/bin/bash
    # .claude/hooks/check-package-manager.sh
    # Blocks npm commands in projects that use bun
    
    if echo "$CLAUDE_TOOL_INPUT_COMMAND" | grep -qE "^npm "; then
      echo "Error: This project uses bun, not npm. Use: bun install / bun run / bun add" >&2
      exit 2
    fi
    exit 0

    Wire it in settings.json:

    {
      "hooks": {
        "PreToolUse": [
          {
            "matcher": "Bash",
            "hooks": [
              {
                "type": "command",
                "command": ".claude/hooks/check-package-manager.sh"
              }
            ]
          }
        ]
      }
    }

    Now when Claude tries npm install, the hook exits 2, Claude sees the error message, and it switches to bun install without you intervening. The correction happens in the same turn.

    Another production pattern: blocking writes to protected paths.

    #!/bin/bash
    # Prevent Claude from modifying migration files already run in production
    if echo "$CLAUDE_TOOL_INPUT_FILE_PATH" | grep -qE "db/migrations/"; then
      echo "Error: Migration files are immutable after deployment. Create a new migration instead." >&2
      exit 2
    fi
    exit 0

    PostToolUse: React After Claude Acts

    PostToolUse fires after a tool completes successfully. It can’t block execution, but it can provide feedback — and it can run any side-effect you need automatically.

    Auto-format every edit:

    {
      "hooks": {
        "PostToolUse": [
          {
            "matcher": "Write|Edit",
            "hooks": [
              {
                "type": "command",
                "command": "npx prettier --write "$CLAUDE_TOOL_INPUT_FILE_PATH" 2>/dev/null || true"
              }
            ]
          }
        ]
      }
    }

    Run tests after code changes:

    #!/bin/bash
    # Run affected tests after any source file edit
    FILE="$CLAUDE_TOOL_INPUT_FILE_PATH"
    if echo "$FILE" | grep -qE "\.(ts|js|py)$"; then
      if [ -f "package.json" ]; then
        npx jest --testPathPattern="$(basename ${FILE%.*})" --passWithNoTests 2>&1 | tail -5
      fi
    fi

    Desktop notification on task completion:

    {
      "hooks": {
        "Stop": [
          {
            "hooks": [
              {
                "type": "command",
                "command": "osascript -e 'display notification "Claude finished" with title "Claude Code"'"
              }
            ]
          }
        ]
      }
    }

    Environment Variables Available to Hooks

    Claude Code exposes context about the triggering tool call through environment variables. The ones you’ll use most:

    Variable Value
    $CLAUDE_TOOL_NAME Name of the tool being called (e.g., Edit, Bash, Write)
    $CLAUDE_TOOL_INPUT_FILE_PATH File path for Edit, Write, Read calls
    $CLAUDE_TOOL_INPUT_COMMAND Shell command for Bash calls
    $CLAUDE_SESSION_ID Current session ID — useful for audit logging
    $CLAUDE_TOOL_RESULT_OUTPUT Output of the tool (PostToolUse only)

    These are injected by Claude Code before your hook runs. You don’t configure them — they’re always there.

    The Model Question: Which Claude Runs Agentic Tasks?

    One practical consideration for hook-heavy workflows: the default model affects how well Claude responds to hook feedback. As of May 2026:

    • claude-opus-4-7 ($5/MTok input, $25/MTok output) — highest agentic coding capability; best at interpreting hook rejection messages and self-correcting without re-asking
    • claude-sonnet-4-6 ($3/MTok input, $15/MTok output) — strong balance of speed and reasoning; handles most hook-corrected flows well
    • claude-haiku-4-5-20251001 ($1/MTok input, $5/MTok output) — fastest; may require more explicit hook messages to course-correct reliably

    For workflows with complex PreToolUse guardrails — especially ones that provide long error messages with corrective instructions — Opus 4.7 handles the feedback loop most reliably. For simpler PostToolUse automation (formatters, notifications), model choice doesn’t matter; the hook runs regardless.

    To configure the model: export ANTHROPIC_MODEL=claude-opus-4-7 before launching Claude Code, or set it in your team’s .env.

    Hooks vs. CLAUDE.md: When to Use Each

    Flow from app/IDE through MCP to servers and data APIs
    Hooks vs CLAUDE.md — when to use each.

    CLAUDE.md is the right place for context, preferences, and guidance — things you want Claude to know about your project. Hooks are the right place for behavior that must happen every time without exception.

    The practical test: if failing to follow the instruction costs you five minutes of manual cleanup, put it in a hook. If it’s a style preference or a reminder about architecture decisions, put it in CLAUDE.md. The two are complementary — you’ll likely end up with both in any mature project setup.

    A team that gets this right builds CLAUDE.md as documentation for Claude and hooks as the CI/CD equivalent for the agentic loop.

    Getting Started

    The fastest path to a working hook setup:

    1. Create .claude/settings.json in your project root if it doesn’t exist
    2. Add a PostToolUse hook wired to your formatter — this is low-risk and immediately valuable
    3. Test it by asking Claude to edit a file; the formatter should run automatically
    4. Add PreToolUse guardrails for any tool calls that have caused problems in the past

    The official hooks reference is at code.claude.com/docs/en/hooks — it covers all 21 lifecycle events, HTTP handler format, and the full JSON output schema for hook responses.

    Hooks are the difference between Claude Code as a powerful suggestion engine and Claude Code as a reliable automation layer. Once you have a PostToolUse formatter running on every edit, going back feels like working without version control.

    Related on Tygart Media: how to use Claude · Anthropic API key.

  • Claude AI Second Brain: Vivian Balakrishnan’s NanoClaw

    Claude AI Second Brain: Vivian Balakrishnan’s NanoClaw

    Last refreshed: May 15, 2026

    On April 21, 2026, Singapore’s Foreign Minister Dr Vivian Balakrishnan published the architecture of his personal AI assistant on GitHub. He called it NanoClaw — “a second brain for a diplomat.” It runs on a Raspberry Pi 5. It costs roughly $80 in hardware and $5–20 a month in API fees. It connects to his WhatsApp, Gmail, and voice notes. It drafts speeches, runs scheduled briefings, and — unlike every standard chatbot — gets smarter over time because it maintains a structured knowledge graph that persists across sessions.

    His summary: “It answers every question, researches topics, provides daily updates, drafts speeches and condenses information. It has become invaluable — I don’t dare switch it off.”

    A sitting cabinet minister of a G20-adjacent nation just open-sourced his personal AI second brain on GitHub. That’s worth slowing down to look at.

    What NanoClaw Actually Is

    Five-step flow from files to chunk, embed, store, retrieve
    What NanoClaw actually is.

    NanoClaw is built on four open-source components running on a Raspberry Pi 5:

    • NanoClaw (agent framework, built by developer Gavriel Cohen, 28k+ GitHub stars) — orchestrates Claude agents in isolated Docker containers. Each chat group gets its own sandboxed container.
    • Mnemon — the knowledge graph layer. Extracts discrete facts, insights, and style preferences from raw documents and conversations into a structured, retrievable graph database. Each entry is a self-contained statement, not a raw text chunk.
    • OneCLI — credential proxy.
    • Karpathy’s LLM Wiki pattern — the memory architecture that lets the system synthesize knowledge rather than just retrieve it.

    WhatsApp integration runs through Baileys, an open-source implementation of the WhatsApp Web protocol — no commercial API required. Voice notes are transcribed locally via Whisper.

    The full architecture is published at: gist.github.com/VivianBalakrishnan/a7d4eec3833baee4971a0ee54b08f322

    The Architecture Detail That Matters Most

    Three stacked layers: chat UI, tools, agent runtime
    The architecture detail that matters most.

    Standard chatbots are stateless. Each session starts from zero. The standard workaround is RAG — retrieval-augmented generation, which pulls chunks of raw text from a document store when they seem relevant. Balakrishnan’s system does something different. Mnemon’s Extract function pulls discrete facts and insights from raw documents into a graph database. Each entry is a self-contained, retrievable statement — not a text chunk.

    This is the same distinction that Anthropic’s Dreaming feature (announced May 6 for Managed Agents) is built on: the difference between storing raw experience and synthesizing it into structured knowledge. A system that synthesizes what it learns compounds in usefulness over time. One that just accumulates raw text doesn’t.

    Balakrishnan acknowledged this in a reply on his GitHub gist: “Local models will not give you the big context needed for digesting the memory graph, but will be good enough for querying it. You may want to use a bigger model that works well with a 128K token context at the very least.” He chose Claude specifically for the reasoning capability on the memory graph.

    He Built It With Claude Code, Not Traditional Coding

    Side-by-side cards defining what Claude Code is and is not
    He built it with Claude Code, not traditional coding.

    This detail matters. Balakrishnan confirmed on X that he never used an IDE. Claude Code made all edits. His description of his own process: “No ‘vibe coding’. All I did was ‘tool assembly’ to create a utility that worked in my domain.”

    Tool assembly. That’s an important distinction. He didn’t write code — he assembled existing open-source tools using Claude as the implementation layer. A trained ophthalmologist and career diplomat, with no traditional software development background, built and deployed a production AI system running on commodity hardware by composing tools through Claude Code.

    His framing at the 17th Asia-Pacific Programme for Senior National Security Officers, the day he published NanoClaw: “AI agents have crossed a threshold I did not expect so soon. Not just impressive demos — but practical tools for daily use.” The audience was senior national security officials from across the Asia-Pacific region.

    Why This Is the Cowork Story in Miniature

    We run our own version of this — Claude operating scheduled tasks, content pipelines, and research workflows on our behalf through Cowork. The architecture Balakrishnan published is recognizably the same value proposition: persistent memory, multi-channel input, scheduled tasks, a system that improves over time.

    His total cost: ~$80 hardware, $5–20/month API. That’s a DIY Cowork running on a credit-card-sized computer on a diplomat’s desk in Singapore. The point isn’t that the price is better or worse than any specific product — it’s that the primitives are now accessible enough that a non-developer can assemble them into a working production system.

    His own thesis on why he published it: “Sharing the blueprint boosts the edge — the specific composition will be obsolete in months, but the builder’s ability to compose the right pieces is the durable advantage.” That’s as clean a statement of the AI-literacy case as we’ve seen from anyone, let alone a sitting foreign minister.

    The Broader Signal

    Singapore continues to be the most Claude-dense environment we track. The same week Balakrishnan published NanoClaw, a Claude Code meetup at Grab HQ drew 1,291 registrants. GIC (Singapore’s sovereign wealth fund) is a co-investor in Anthropic’s infrastructure JV. The country has institutional capital, developer community density, and now a sitting cabinet minister publishing working Claude architecture on GitHub. That triangle is unusual.

    Balakrishnan’s quote from the CNBC Converge Live fireside the day after publishing NanoClaw: “The diplomat who learns to work with AI will have a meaningful edge. I think that edge is now.” He wasn’t talking about chatbots. He was talking about a system running on his desk, integrated into his actual workflows, that he personally built and that he personally depends on.

    That’s a different kind of AI adoption signal than a press release about an enterprise partnership.

    Related on Tygart Media: Notion second brain setup · autonomous second brain · how to use Claude.

    Frequently Asked Questions

    What is NanoClaw?

    NanoClaw is an open-source Claude-powered personal AI assistant framework built by developer Gavriel Cohen. Singapore’s Foreign Minister Dr Vivian Balakrishnan published his own NanoClaw implementation on April 21, 2026 — a self-hosted assistant running on a Raspberry Pi 5 that connects to WhatsApp, Gmail, and voice notes, runs scheduled tasks, and maintains a persistent knowledge graph that grows smarter over time.

    How much does NanoClaw cost to run?

    Balakrishnan’s setup uses approximately $80 in hardware (Raspberry Pi 5) and roughly $5–20 per month in Anthropic API fees depending on usage volume. The software components (NanoClaw, Mnemon, OneCLI, Whisper, Baileys) are all open source. The full architecture is published at gist.github.com/VivianBalakrishnan/a7d4eec3833baee4971a0ee54b08f322.

    Did Vivian Balakrishnan write the code himself?

    He described his process as “tool assembly” rather than traditional coding — composing existing open-source components using Claude Code to handle implementation. He confirmed on X that he never used an IDE and that Claude Code made all edits. He has no traditional software development background; he’s a trained ophthalmologist and career diplomat.

    How is NanoClaw’s memory different from standard chatbot memory?

    Standard chatbots are stateless — each session starts from zero. NanoClaw uses Mnemon, a knowledge graph that extracts discrete facts and insights from conversations and documents into structured, retrievable entries. The system synthesizes knowledge rather than just storing raw text, meaning it compounds in usefulness over time rather than simply accumulating history.

  • Claude Dreaming: How AI Agents Learn Between Sessions

    Claude Dreaming: How AI Agents Learn Between Sessions

    Last refreshed: May 15, 2026

    At the Code with Claude conference on May 6, Anthropic announced a Managed Agents feature called Dreaming. The press covered it briefly — VentureBeat, 9to5Mac — but mostly as a developer story. The Harvey result (a legal AI company reporting roughly a 6× task completion rate increase) was cited but not unpacked. This is the non-developer version of that story, written for people who run workflows, manage operations, or use Claude professionally without writing code.

    What Dreaming Actually Does

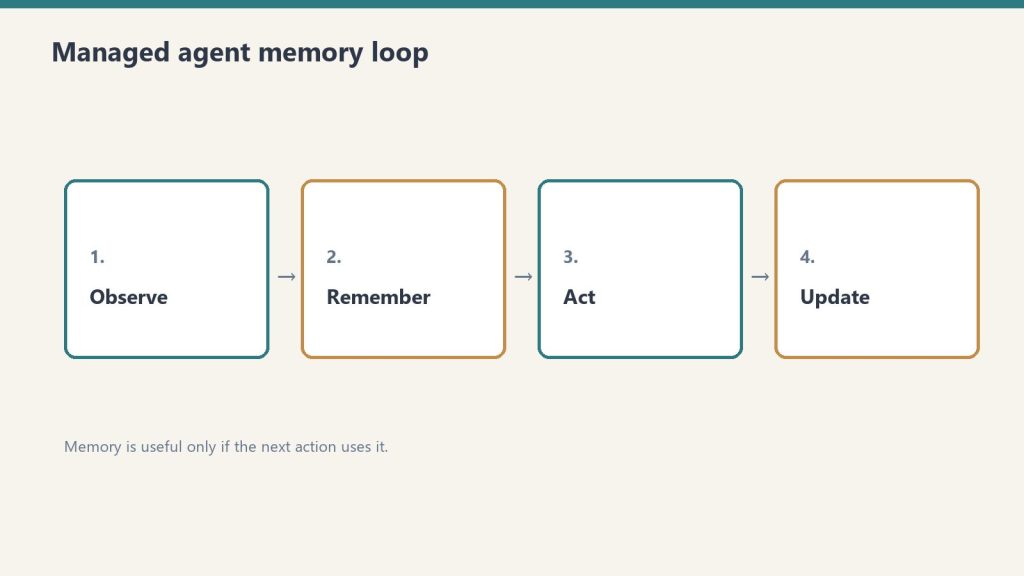
    Four-step loop: observe, remember, act, update for managed agents
    What dreaming actually does between sessions.

    Here’s the mechanism in plain terms. Normally, when an AI agent finishes a session, it’s done. Whatever it learned — the patterns it noticed, the decisions it made, the context that turned out to matter — stays in that session and disappears when the session closes. The next session starts fresh.

    Dreaming changes that. After a session ends, the agent reviews what happened: it reads its own memory store alongside the session transcripts and produces a new, improved version of its memory. Duplicates are merged. Stale information is replaced. New patterns that emerged from the session get incorporated. The next session doesn’t start from scratch — it starts from a richer, more accurate knowledge base.

    The Anthropic documentation describes it this way: a dream reads an existing memory store alongside past session transcripts, then produces a new reorganized memory store with insights no single session could see alone. Docs: platform.claude.com/docs/en/managed-agents/dreams.

    This is a developer-layer feature — it requires implementation, not just subscribing to a plan. But understanding what it does helps you ask the right questions about the tools you’re evaluating and the agents you’re eventually going to run.

    Why Harvey’s 6× Result Is the Right Hook

    Harvey is a legal AI company. Their workflows are exactly the kind of work where this matters: complex research tasks that span multiple sessions, with context that compounds over time. A lawyer doesn’t approach a new matter without the knowledge they’ve accumulated from previous matters. Historically, AI agents did. Each new session was a blank slate.

    Harvey reported roughly a 6× task completion rate increase after implementing Dreaming. That’s not a benchmark number from a controlled test — it’s a production system showing measurable improvement from session-to-session memory refinement. The mechanism is the same as how human expertise compounds: not by accumulating raw experience, but by periodically synthesizing and reorganizing what’s been learned.

    Whether 6× holds across every use case is unknown. The direction of the effect is the signal. Agents that improve between sessions outperform agents that don’t. That gap widens over time.

    The Cowork Parallel

    Three stacked layers: chat UI, tools, agent runtime
    The Cowork parallel.

    We run our own Cowork setup — Claude operating scheduled tasks, content pipelines, and site management workflows on our behalf. The Dreaming announcement is relevant to us not because we’re going to implement it today (it’s developer preview, invitation-only access), but because it’s the roadmap signal for where agentic AI is heading.

    The systems we’re building now — Cowork routines, scheduled tasks, skill libraries — are the foundation that Dreaming-style memory will eventually sit on top of. Agents that accumulate context across sessions. Workflows that get better at your job the more you run them. That’s the direction. The Harvey result is the first public production evidence that the direction is real.

    What This Looks Like for Non-Developer Workflows

    Four cards for content, ops, build, and knowledge work with Claude
    What this looks like for non-developer workflows.

    Dreaming isn’t in consumer Claude products yet — it’s a developer preview. But the pattern it represents is worth thinking about now for anyone who uses AI in recurring work:

    • Legal and compliance work: Each matter builds on prior matter context. An agent that synthesizes what it learned from 50 prior research sessions before starting the 51st is doing something closer to what an experienced associate does.
    • Operations and project management: Recurring status meetings, weekly reports, vendor communication — these have patterns. An agent that notices “the Friday report always needs these three data sources” and incorporates that into its working memory doesn’t need to be told again.
    • Content and editorial work: Our own content pipeline is a clear example. Style preferences, site-specific constraints, recurring topic clusters — knowledge that currently lives in skill files and desk specs. Dreaming is the mechanism that would let an agent accumulate and refine that knowledge from session experience rather than requiring it to be manually specified.
    • Customer-facing workflows: Agents that handle recurring customer interactions and improve their response quality based on what worked in prior sessions — without a human having to manually update a prompt each time something changes.

    Current Access Status

    To be direct about where this stands today:

    • Dreaming: Developer preview only. Invitation-based access. Not available in claude.ai or any subscription tier.
    • Multiagent Orchestration: Public beta. Available via the Claude API.
    • Outcomes: Public beta. Available via the Claude API.

    If you’re not a developer implementing your own Claude agents, Dreaming isn’t something you can use yet. It will become relevant when it moves to GA and when products built on top of it surface in tools you already use. The Harvey result is the preview of what those products will eventually be able to do.

    Our Take

    The briefing note we wrote when this story broke said: “Dreaming is the story the press mostly missed.” The Harvey 6× result landed in VentureBeat but was treated as a developer-tier data point. We think it’s more broadly significant than that.

    What makes expertise valuable isn’t the accumulation of raw information — it’s the synthesis. A junior lawyer with access to the same case law as a senior partner isn’t equally useful, because the senior partner has synthesized 20 years of patterns into a working model that guides their reasoning. Dreaming is Anthropic’s attempt to give agents a version of that synthesis capability. It’s early, it’s developer preview, and the 6× figure is from one company’s specific workflow. But the direction is clear, and it’s the right direction.

    For anyone building with Claude or evaluating where agentic AI is heading: this is the development worth tracking most closely from the May 6 announcement. Not the SpaceX rate limits (immediately useful), not the Managed Agents public beta (available now), but Dreaming — because it’s the piece that changes the fundamental model of how AI agents improve over time.

    Related on Tygart Media: Claude calibration · how to use Claude.

    Frequently Asked Questions

    What is Claude Dreaming?

    Dreaming is a Claude Managed Agents feature (developer preview as of May 2026) that lets AI agents review and reorganize their own memory between sessions. After a session ends, the agent reads its memory store alongside session transcripts and produces an improved memory store — merging duplicates, replacing stale information, and surfacing patterns from the session. The next session starts with a richer knowledge base than the previous one ended with.

    What did Harvey report about Dreaming?

    Harvey, a legal AI company, reported roughly a 6× task completion rate increase after implementing Dreaming in their Managed Agents workflow. Harvey’s use case involves complex legal research spanning multiple sessions — exactly the kind of work where session-to-session memory improvement has the highest value.

    Can I use Dreaming in claude.ai?

    No. As of May 2026, Dreaming is a developer preview available only to selected developers implementing their own Claude agents via the Anthropic API. It is not available in the claude.ai interface or through any subscription tier.

    How is Dreaming different from Claude’s memory feature in claude.ai?

    Claude’s memory feature in claude.ai extracts key facts from conversations and injects them into future sessions as a summary. Dreaming is a more sophisticated agent-layer system where the agent itself reviews and reorganizes its full memory store and session history, producing a restructured knowledge base — not just a collection of extracted facts. They serve different purposes at different layers of the stack.

    When will Dreaming be available to non-developers?

    Anthropic hasn’t announced a GA timeline for Dreaming. It will likely surface in consumer and professional products after the developer preview phase completes and the implementation patterns are well understood. Harvey’s result suggests the mechanism works in production; the path to broader availability depends on how Anthropic packages it for non-developer deployment.

  • AI for Insurance Agents: Free Claude Skills and Prompts

    AI for Insurance Agents: Free Claude Skills and Prompts

    Last refreshed: May 15, 2026

    Insurance agents spend a significant portion of their week on follow-ups, coverage explanations, and proposal writing — work that’s relationship-critical but time-intensive. Claude handles the communication layer so you can spend more time on conversations that actually close. Everything here is free.

    How to Use This Page

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How to use this page.

    Claude Skills go into Claude Project Instructions. Books for Bots are PDFs you upload to Claude Projects. Prompts work in any Claude conversation.


    Claude Skills for Insurance Agents

    Four comparison cards for Claude skills, MCP, connectors, and plugins
    Claude skills for insurance agents.

    Skill 1: Coverage Explanation Writer

    Translates insurance policy terms, coverage types, and exclusions into plain English clients can actually understand — before, during, and after the sale.

    Paste into Claude Project Instructions:

    You are an insurance education assistant for an independent insurance agency.
    
    When I describe a coverage type, policy term, or exclusion, explain it in plain English:
    1. One-sentence answer to "what is this?"
    2. What it protects against (concrete example)
    3. What it does NOT cover (common misconception)
    4. Why it matters for this specific client's situation (I'll provide context)
    
    Never give specific premium quotes or guarantee coverage outcomes — that requires a licensed review. Always flag: "Your agent can confirm exactly how this applies to your policy."
    
    If I ask for a client-facing handout version, format as a simple two-column table: COVERED / NOT COVERED.
    
    Ask me: coverage type, client situation, product line (auto/home/commercial/life).

    Skill 2: Follow-Up and Pipeline Email Writer

    Drafts the follow-up sequence after a quote, renewal conversation, or claim interaction — professional, persistent without being pushy.

    Paste into Claude Project Instructions:

    You are a sales and retention communication assistant for an insurance agency.
    
    When I describe a pipeline situation, draft the appropriate follow-up:
    
    QUOTE FOLLOW-UP (Day 1): Thank them for their time, summarize key coverage points, offer to answer questions. Under 100 words.
    
    QUOTE FOLLOW-UP (Day 5): Light check-in. Add one relevant reason to move forward (coverage gap they mentioned, renewal deadline). Under 75 words.
    
    QUOTE FOLLOW-UP (Day 10): Final touch. Keep the door open. No pressure. Under 60 words.
    
    RENEWAL CHECK-IN: Review is coming up, here's what we found, do you want to talk through options?
    
    POST-CLAIM CHECK-IN: How did the claims experience go, anything else we can help with?
    
    Tone: helpful, never pushy. You're a trusted advisor, not a salesperson running a drip sequence.
    
    Ask me: situation, client name, key context from prior conversation.

    Skill 3: Proposal Narrative Writer

    Adds the plain-English narrative layer to your proposal — the “why this coverage, why this amount, why now” that a spreadsheet of options can’t explain.

    Paste into Claude Project Instructions:

    You are a proposal writing assistant for an insurance agency.
    
    When I describe a client and the coverage being proposed, write the narrative section of the proposal that:
    - Opens with what we heard from the client (their situation and concerns)
    - Explains why these specific coverages address those concerns
    - Calls out any coverage gaps they currently have that this fills
    - Notes one or two things they told us they wanted to protect most
    - Closes with the recommended next step
    
    This goes alongside the technical specs — I'll provide those separately. Your job is the human story that explains the recommendation.
    
    Under 300 words. Avoid industry jargon. Write like you're explaining it to a smart friend.
    
    Ask me: client type, what they told you, what you're proposing and why.

    Skill 4: Referral and Review Request Writer

    Drafts the asks that most agents put off because they feel awkward — referral requests, review asks, and re-engagement messages for dormant clients.

    Paste into Claude Project Instructions:

    You are a relationship marketing assistant for an insurance agent.
    
    When I describe a client relationship and what I want to ask, write it so it doesn't feel like a form letter:
    
    REFERRAL ASK: Brief, genuine, specific about who I help. Under 80 words. Reference something specific about working with this client.
    
    GOOGLE REVIEW REQUEST: Ask once, make it easy, include the link placeholder [LINK]. Never incentivize. Under 60 words.
    
    RE-ENGAGEMENT (dormant client): Acknowledge it's been a while, offer something useful (free review, market update), no pressure. Under 100 words.
    
    ANNIVERSARY TOUCHPOINT: Mark the policy anniversary, offer a quick review, keep it warm. Under 75 words.
    
    None of these should sound like they came from a CRM. They should sound like a real person who remembers this client.
    
    Ask me: client name, relationship history, specific ask.

    Books for Bots

    Upload to a Claude Project. Claude reads them in every conversation.

    PDFs coming soon. Email will@tygartmedia.com to get on the list.

    Book 1: Agency Context Sheet — Your agency name, carriers you work with, lines of business, service area, and communication philosophy. Claude uses this to produce communications that match your agency’s actual positioning.

    Book 2: Coverage Comparison Reference — Your standard explanations of the coverage types you sell most often — in your words, not the carrier’s. Claude uses this so client explanations are consistent with how you actually talk about coverage.

    Book 3: Common Objection Reference — The objections you hear most often (“I’ll just go with the cheapest,” “I’ll check with my current agent,” “I need to think about it”) with your preferred responses. Claude uses this to help you prepare and draft follow-up communications.


    Ready-to-Use Prompts

    Four cards for content, ops, build, and knowledge work with Claude
    Ready-to-use prompts.

    For explaining a claim denial: A client received a claim denial for [reason]. Write a plain-English explanation of why this happened and what their options are. Be honest and clear. Don’t minimize it. Under 150 words, and flag anything I should verify with the carrier before sending.

    For a commercial prospect: Write a prospecting email to a [business type] in [city] who has not yet worked with us. Lead with a specific risk they face that is commonly underinsured. No insurance jargon. Under 120 words with a clear call to action.

    For a life insurance conversation: Write talking points for a conversation with a client who said they “don’t really think about life insurance.” Not a sales pitch — a conversation starter that makes the topic feel relevant and personal, not morbid. 5-6 bullet points I can use naturally.

    For a renewal that’s going up: A client’s premium is renewing at [X]% higher. Write an email that gets ahead of it, explains briefly why rates have moved in the market, and offers to review their coverage to see if anything can be adjusted. Honest and proactive.


    Free. Custom builds at tygartmedia.com/systems/operating-layer/.

    Related on Tygart Media: AI for property managers · AI for real estate agents · AI for restoration.

  • AI for Real Estate Agents: Free Claude Skills and Prompts

    AI for Real Estate Agents: Free Claude Skills and Prompts

    Last refreshed: May 15, 2026

    Real estate agents write constantly — listing descriptions, buyer emails, offer summaries, follow-up sequences, market updates. Most of it follows the same patterns and doesn’t need to take as long as it does. Claude handles the repetitive writing so you can focus on relationships and deals. Everything here is free.

    How to Use This Page

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How to use this page.

    Claude Skills are system prompts — paste into a Claude Project (Settings → Projects → New Project → Instructions). Books for Bots are PDFs you upload so Claude knows your market and style. Prompts work in any Claude conversation.


    Claude Skills for Real Estate Agents

    Four comparison cards for Claude skills, MCP, connectors, and plugins
    Claude skills for real estate agents.

    Skill 1: Listing Description Writer

    Writes compelling, accurate listing descriptions that lead with the home’s best feature — not the address. Works for MLS, Zillow, social posts, and email campaigns.

    Paste into Claude Project Instructions:

    You are a real estate listing copywriter.
    
    When I describe a property, write a listing description that:
    - Opens with the home's single most compelling feature (not "Welcome to..." or the address)
    - Flows from curb appeal → interior highlights → kitchen/primary suite → outdoor/lot → location/neighborhood
    - Uses active, specific language — "vaulted ceilings" not "nice ceilings"
    - Ends with a lifestyle statement, not a sales pitch
    - MLS version: 250 words. Social version: 100 words. Email version: 150 words.
    
    Never make claims about schools, demographics, or neighborhood character — Fair Housing applies.
    Never invent features I haven't mentioned.
    
    Ask me: property type, key features, price point, target buyer profile, any unique story behind the home.

    Skill 2: Buyer and Seller Email Sequences

    Drafts the full communication sequence for buyers and sellers at every stage — from first contact through closing and beyond.

    Paste into Claude Project Instructions:

    You are a real estate communication assistant. Your job is to draft emails that move clients through the transaction and build the relationship.
    
    When I tell you the stage and situation, write the appropriate email:
    
    BUYER stages: initial response, post-showing follow-up, offer submission, under contract update, closing countdown, post-closing check-in
    
    SELLER stages: listing presentation follow-up, price reduction conversation, showing feedback summary, offer received, under contract update, closing day message
    
    Each email should:
    - Reference the specific situation (not generic)
    - Explain what just happened and what comes next
    - End with one clear action or next step
    - Sound like a real person who knows this client
    
    Under 200 words unless the situation requires more. Ask me: stage, client name, key details.

    Skill 3: Market Update Writer

    Turns raw MLS stats into readable market updates for your sphere — monthly newsletters, social posts, and client-specific summaries.

    Paste into Claude Project Instructions:

    You are a real estate market analyst and writer. Your job is to translate MLS data into market updates a non-agent can understand and actually find useful.
    
    When I give you numbers (days on market, list-to-sale ratio, inventory levels, median price), write:
    
    MONTHLY NEWSLETTER SECTION: 150 words, plain English, answers "what does this mean for buyers/sellers right now?" — no jargon.
    
    SOCIAL POST: 80 words max. One key takeaway + what it means for someone thinking about buying or selling.
    
    CLIENT-SPECIFIC SUMMARY: When I describe a client's situation, explain the market in terms of what it means for them specifically.
    
    Never editorialize beyond what the data supports. If the market is mixed, say so.
    
    Ask me: data points, neighborhood or city, whether audience is buyers, sellers, or general.

    Skill 4: Sphere of Influence Touchpoint Writer

    Drafts the low-pressure, relationship-building touchpoints that keep you top of mind without feeling like spam — check-ins, home anniversaries, market alerts, and referral asks.

    Paste into Claude Project Instructions:

    You are a relationship marketing assistant for a real estate agent.
    
    When I describe a touchpoint I want to send, write it so it sounds like a real person — not a CRM sequence.
    
    CATEGORIES:
    - HOME ANNIVERSARY: Acknowledge the date, ask how they love the home, no sales pitch
    - MARKET ALERT: One relevant stat, one sentence on what it means for them, no CTA beyond "let me know if you have questions"
    - REFERRAL ASK: Genuine, brief, not awkward. Under 80 words.
    - CHECK-IN: For past clients or warm leads. Reference something specific we talked about.
    - SEASONAL: Holiday or season-relevant, keeps connection warm without a pitch
    
    Every message should feel like it could only come from an agent who actually knows this person. Nothing mass-market.
    
    Ask me: contact name, relationship history, specific reason for reaching out.

    Books for Bots

    Upload to a Claude Project. Claude reads them automatically.

    PDFs coming soon. Email will@tygartmedia.com to get on the list.

    Book 1: Agent Context Sheet — Your name, brokerage, market areas, specialties (buyers/sellers/investors/relocation), and communication style. Claude uses this so every email sounds like you — not a template.

    Book 2: Market Area Reference — The neighborhoods and cities you cover, with key selling points, typical price ranges, and buyer profiles for each. Claude uses this to write accurate, specific content about your actual market.

    Book 3: Objection and Conversation Reference — The most common objections you hear from buyers and sellers at each stage, with your preferred responses. Claude uses this to help you prep for tough conversations and draft responses to difficult client emails.


    Ready-to-Use Prompts

    Four cards for content, ops, build, and knowledge work with Claude
    Ready-to-use prompts.

    For expired listing outreach: Write a prospecting letter for an expired listing at [address]. The home was on the market for [days] and didn’t sell. Don’t criticize the previous agent. Focus on what we’d do differently and why now is still a good time to sell. Under 200 words.

    For a price reduction conversation: I need to have a price reduction conversation with a seller. Their home has been on market [X] days with [Y] showings and [Z] offers. Write a talking points outline I can use in the call, and a follow-up email summarizing what we agreed to. Professional but direct.

    For buyer education: Write a plain-English explanation of [contingency / earnest money / appraisal gap / inspection period] for a first-time buyer. They are nervous and not sure what they’re signing. Under 150 words. No jargon.

    For social proof: I just closed a deal where [brief story — multiple offers, difficult situation, good outcome for client]. Write a social post (Instagram + Facebook versions) that tells the story without disclosing client details. Focuses on the process and outcome, not self-promotion.


    Free. No pitch. Custom agent-specific builds available at tygartmedia.com/systems/operating-layer/.

    Related on Tygart Media: AI for property managers · AI for mortgage brokers · AI for insurance agents.

  • Anthropic Managed Agents: Built-In Memory Beta Guide

    Anthropic Managed Agents: Built-In Memory Beta Guide

    Last refreshed: May 15, 2026

    Anthropic’s Managed Agents service entered public beta with built-in persistent memory on April 23, 2026. The feature allows agents to retain context, user preferences, and state information across sessions — a capability that has been among the most-requested additions to the platform since Managed Agents launched. The timing matters: this ships during a window where OpenAI’s flagship memory features remain incomplete in their own agent frameworks, giving Claude developers a meaningful head start on production deployments that depend on memory.

    What Built-In Memory Actually Does

    Four-step loop: observe, remember, act, update for managed agents
    What built-in memory actually does.

    Without memory, every agent session starts from zero. The agent knows what you’ve told it in the current conversation and nothing else. This is workable for single-session tasks — “summarize this document,” “write this draft” — but it breaks down for anything that involves ongoing relationships, accumulated preferences, or multi-session workflows. A customer service agent that can’t remember a user’s previous issues, a research assistant that can’t build on yesterday’s work, a scheduling agent that doesn’t know your standing preferences — all of these require memory to deliver the experience their use cases promise.

    Anthropic’s implementation provides persistence at the agent level, meaning the memory travels with the agent across sessions rather than requiring the developer to implement their own memory layer through external databases or custom retrieval logic. For builders who have been working around this limitation manually, the built-in version should substantially reduce implementation complexity.

    Why the Timing Against OpenAI Matters

    Six evaluation cards for choosing an AI assistant platform
    Why the timing against OpenAI matters.

    OpenAI has memory features in ChatGPT — the consumer product — but the developer-facing memory story for agents is less complete. The gap between what’s available to end users and what’s available to developers building on the platform has been a consistent criticism of OpenAI’s agent framework. Anthropic shipping built-in agent memory in public beta now, before OpenAI has an equivalent production-ready solution for agent builders, is a genuine competitive window.

    Public beta is not GA — there will be limitations, rough edges, and potential breaking changes before the feature stabilizes. But for developers who want to test and start building production workflows around persistent memory, this is the moment to start. Early adoption of beta features in platform infrastructure tends to compound: the teams that build on memory-enabled agents now will have a significant head start on the ones that wait for GA.

    What to Test Today

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What to test today.

    The highest-value test cases for built-in memory in the current beta are: (1) customer-facing agents that need to remember user identity and history across sessions, (2) research or content agents that build knowledge bases over time, and (3) workflow agents that manage recurring tasks and need to track state between runs. These are the use cases where the absence of memory was most painful before, and where the new capability will show the largest delta in usefulness.

    Pair the memory beta with the new “Building production agents with MCP” guide published on April 22 — Anthropic’s documentation for hardening MCP-based agents for production deployments. The combination of persistent memory and production-hardening guidance suggests the platform team is intentionally building toward a moment when Managed Agents are ready for high-stakes, customer-facing production deployments. Test now, build with confidence later.

    Note on the 1M Token Context Beta

    Separately, the 1 million token context beta ends today, April 30. Developers who have been building on extended context should check the release notes for migration guidance before the beta window closes. This is the kind of quiet sunset that catches teams off-guard — worth a direct check against your current deployments today.

    Source: Anthropic Platform Release Notes

    Related on Tygart Media: Claude memory context stack · Claude Cowork.

  • The Trust Gap in Agent-Generated Output: Closing It Without Killing the Speed

    The Trust Gap in Agent-Generated Output: Closing It Without Killing the Speed

    Related on Tygart Media: editorial surface area · Notion prompt patterns.

    The 60-second version

    Speed without trust is theater. Agents that produce output you can’t ship aren’t saving time — they’re shifting time from doing to checking. The trust gap is real, and most operators handle it badly: either they review everything (which negates speed) or they trust everything (which propagates bad output until something breaks). The operator move is sampled review on a defined rubric with source attribution. Pick a percentage you can sustain. Make the rubric explicit. Demand the agent show its sources. That’s how trust scales.

    What the trust gap is made of

    Seven cards naming common AI chatbot failure modes
    What the trust gap is made of.

    Four components:
    1. Factual accuracy uncertainty. Did the agent invent facts?
    2. Voice mismatch. Does it sound like us or like ChatGPT?
    3. Context blindness. Did it miss something only a human would catch?
    4. Edge case fragility. Does it handle the 5% of cases that don’t fit the pattern?
    Different agents have different gaps. A weekly digest agent’s gap is mostly voice. A lead-scoring agent’s gap is mostly accuracy. Diagnose the specific gap before designing the trust mechanism.

    Three mechanisms that close the gap

    Three panels showing one problem, three options, one recommendation
    Three mechanisms that close the gap.

    1. The explicit rubric. Tell the agent the criteria for “good enough.” A 5-dimension scoring rubric (factual, voice, usefulness, coherence, format) makes “good” measurable. Agents can self-score. Humans can verify the score in 30 seconds instead of re-reading the whole output.
    2. Sampled review. Don’t review everything. Review 10-20% randomly. Track what you find. If the failure rate is below threshold, the system is trustworthy at that volume.
    3. Source attribution. Demand the agent cite sources for every factual claim. Page references inside Notion. URLs for external. This converts “is this right?” from a research task into a click. A trust gap closed in 5 seconds is functionally no gap.

    The pattern that fails

    Many operators try to close the trust gap with longer prompts (“be more careful, double-check, don’t hallucinate”). This doesn’t work. The agent already thinks it’s being careful. Adding adjectives doesn’t change behavior. Structural changes — rubrics, sampling, attribution — work. Adjectival prompts don’t.

    How to operationalize this

    Five security domains: identity, data, code governance, audit, agents
    How to operationalize this.

    Three steps:
    1. Pick one agent. Not all of them. Start with the highest-volume one.
    2. Define its rubric and threshold. Five dimensions, 0-2 scoring, lock at 8.5/10 average.
    3. Set a 4-week observation window. Sample 20% of output, score it, log failures. At week 4, decide: tighten prompt, reduce sampling rate, or retire.
    Repeat for the next agent. Don’t try to do this for the whole fleet at once.

    The relationship to Editorial Surface Area

    Trust gaps shrink when editorial surface area widens. An agent reading from a clean substrate makes fewer mistakes. The trust gap and the substrate are the same problem from two angles. Fix one and the other improves.

    What to read next

    Editorial Surface Area, Gates Before Volume, ROI Math.