Tag: AI Agents

  • Claude Agent SDK Migration: Package Renames an (2026)

    Claude Agent SDK Migration: Package Renames an (2026)

    Last verified: June 13, 2026

    The Claude Code SDK has been renamed to the Claude Agent SDK. Migrating is three mechanical edits plus two behavioral changes you have to opt back into: rename the package, rename the imports, rename ClaudeCodeOptions to ClaudeAgentOptions, then decide whether you want the old Claude Code system prompt and filesystem settings back. The breaking changes landed in v0.1.0. Everything below is taken from Anthropic’s official Agent SDK migration guide and the live package registries, verified June 13, 2026.

    The renames at a glance
    Side-by-side when to use a script versus an agent
    The Agent SDK renames at a glance.

    Two packages and one Python type changed names. The documentation also moved out of the Claude Code docs into the API Guide’s Agent SDK section.

    AspectOldNew
    Package (TS/JS)@anthropic-ai/claude-code@anthropic-ai/claude-agent-sdk
    Package (Python)claude-code-sdkclaude-agent-sdk
    Python importclaude_code_sdkclaude_agent_sdk
    Python options typeClaudeCodeOptionsClaudeAgentOptions
    Docs locationClaude Code docsAPI Guide → Agent SDK

    Current published versions

    These are the latest versions on the public registries as fetched on June 13, 2026. The migration guide itself uses ^0.0.42 as the example old TypeScript version and ^0.2.0 as the example new one; pin to whatever is current when you install.

    RegistryPackageLatest version
    npm@anthropic-ai/claude-agent-sdk0.3.177
    PyPIclaude-agent-sdk0.2.101

    TypeScript migration

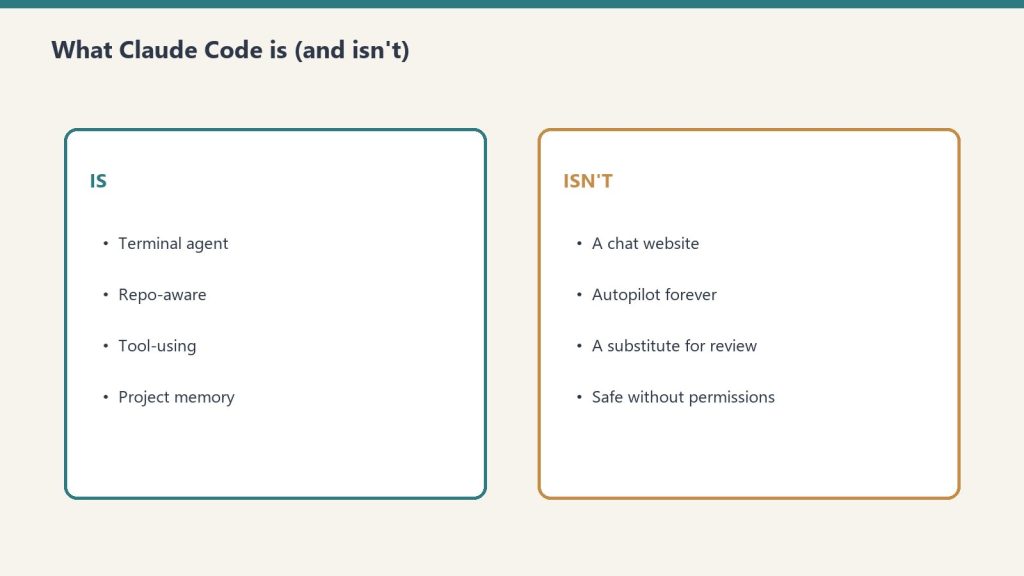
    Side-by-side cards defining what Claude Code is and is not
    TypeScript migration path.

    Swap the package, then update every import. The exported names (query, tool, createSdkMcpServer) are unchanged — only the module specifier moves.

    npm uninstall @anthropic-ai/claude-code
    npm install @anthropic-ai/claude-agent-sdk
    // Before
    import { query, tool, createSdkMcpServer } from "@anthropic-ai/claude-code";
    
    // After
    import { query, tool, createSdkMcpServer } from "@anthropic-ai/claude-agent-sdk";

    Update package.json as well, replacing the dependency key from @anthropic-ai/claude-code to @anthropic-ai/claude-agent-sdk.

    Python migration
    Five stacked panels of daily Claude Code command habits
    Python migration path.

    Swap the package, update the import path, and rename the options type. The import name changes from underscore-claude_code_sdk to underscore-claude_agent_sdk.

    pip uninstall claude-code-sdk
    pip install claude-agent-sdk
    # Before (claude-code-sdk)
    from claude_code_sdk import query, ClaudeCodeOptions
    
    options = ClaudeCodeOptions(model="claude-opus-4-7", permission_mode="acceptEdits")
    
    # After (claude-agent-sdk)
    from claude_agent_sdk import query, ClaudeAgentOptions
    
    options = ClaudeAgentOptions(model="claude-opus-4-7", permission_mode="acceptEdits")

    The rename is the only change to the type — its fields and constructor signature are otherwise the same. Per Anthropic, the new name matches the “Claude Agent SDK” branding.

    Breaking change: the system prompt is no longer default

    This is the change most likely to silently alter your agent’s behavior. In v0.0.x, the SDK used Claude Code’s system prompt by default. As of v0.1.0, query() uses a minimal system prompt instead. To get the old behavior, explicitly request the claude_code preset.

    GoalsystemPrompt value
    Restore Claude Code’s prompt{ type: "preset", preset: "claude_code" }
    Use your own instructionsa plain string
    Minimal prompt (new default)omit the option
    // TypeScript — restore the old default
    const result = query({
      prompt: "Hello",
      options: {
        systemPrompt: { type: "preset", preset: "claude_code" }
      }
    });
    
    // Or a custom system prompt:
    const custom = query({
      prompt: "Hello",
      options: { systemPrompt: "You are a helpful coding assistant" }
    });
    # Python — restore the old default
    from claude_agent_sdk import query, ClaudeAgentOptions
    
    async for message in query(
        prompt="Hello",
        options=ClaudeAgentOptions(
            system_prompt={"type": "preset", "preset": "claude_code"}
        ),
    ):
        print(message)
    
    # Or a custom system prompt:
    async for message in query(
        prompt="Hello",
        options=ClaudeAgentOptions(system_prompt="You are a helpful coding assistant"),
    ):
        print(message)

    settingSources: changed, then reverted

    This one is widely mis-reported, so read it carefully. v0.1.0 briefly defaulted to loading no filesystem settings — and that default was reverted in subsequent releases. Anthropic’s current guidance is that no migration action is needed for setting sources.

    Current behavior: omitting settingSources on query() loads user, project, and local filesystem settings, matching the CLI — equivalent to ["user", "project", "local"]. That includes ~/.claude/settings.json, .claude/settings.json, .claude/settings.local.json, CLAUDE.md files, and custom commands. The accepted values are below.

    SourceLoads from
    "user"~/.claude/ — user CLAUDE.md, rules, skills, settings
    "project"<cwd>/.claude/ — project CLAUDE.md, rules, skills, hooks, settings.json
    "local"CLAUDE.local.md and .claude/settings.local.json

    To run isolated from filesystem settings, pass an empty array. This matters for CI/CD, deployed apps, test environments, and multi-tenant systems where local customizations should not leak in.

    // TypeScript — no filesystem settings
    const isolated = query({
      prompt: "Hello",
      options: { settingSources: [] }
    });
    
    // Only project settings
    const projectOnly = query({
      prompt: "Hello",
      options: { settingSources: ["project"] }
    });
    # Python — no filesystem settings
    from claude_agent_sdk import query, ClaudeAgentOptions
    
    async for message in query(
        prompt="Hello",
        options=ClaudeAgentOptions(setting_sources=[]),
    ):
        print(message)

    Two caveats Anthropic documents explicitly. First, Python SDK 0.1.59 and earlier treated an empty list the same as omitting the option — upgrade before relying on setting_sources=[]. Second, some inputs are read regardless of settingSources: managed policy settings, the global ~/.claude.json config, auto-memory, and claude.ai MCP connectors. For true multi-tenant isolation, the docs recommend running each tenant in its own filesystem and setting settingSources: [] plus CLAUDE_CODE_DISABLE_AUTO_MEMORY=1.

    The full checklist

    Work top to bottom; the first three are required, the last two are behavioral decisions.

    StepAction
    1Uninstall old package, install @anthropic-ai/claude-agent-sdk / claude-agent-sdk
    2Update all imports to the new module / package name
    3Python only: rename ClaudeCodeOptions → ClaudeAgentOptions
    4If you relied on Claude Code’s prompt, set systemPrompt to the claude_code preset
    5Decide on settingSources: omit for CLI parity, or [] to isolate

    Do I have to change settingSources when I migrate?

    No. Anthropic states no migration action is needed for setting sources. The v0.1.0 change to “load nothing by default” was reverted; omitting settingSources again loads user, project, and local settings, matching the CLI.

    What is the new default system prompt?

    A minimal system prompt. Before v0.1.0 the SDK inherited Claude Code’s full system prompt by default. To restore it, pass systemPrompt as { type: "preset", preset: "claude_code" } (TypeScript) or system_prompt={"type": "preset", "preset": "claude_code"} (Python).

    Did the exported function names change in TypeScript?

    No. query, tool, and createSdkMcpServer are unchanged. Only the import path moves from @anthropic-ai/claude-code to @anthropic-ai/claude-agent-sdk.

    Which version introduced the breaking changes?

    Claude Agent SDK v0.1.0, introduced “to improve isolation and explicit configuration,” per the official guide. The latest published versions as of June 13, 2026 are 0.3.177 on npm and 0.2.101 on PyPI.

    Does settingSources: [] fully isolate my agent?

    Not by itself. Managed policy settings, the global ~/.claude.json config, auto-memory, and claude.ai MCP connectors are read regardless. For multi-tenant isolation, also run each tenant in its own filesystem and set CLAUDE_CODE_DISABLE_AUTO_MEMORY=1.

    Related on Tygart Media: Claude Code getting started · Cowork vs Code vs Agent SDK · model migration.
  • Claude Code Billing & Monthly Credit Pools (2026)

    Claude Code Billing & Monthly Credit Pools (2026)

    Last verified: October 5, 2026 (Pacific)

    Claude Code has two billing models, and which one applies depends on how you run it, not just which plan you hold. When you use Claude Code interactively in the terminal or IDE on a Pro or Max plan, it draws from the same subscription usage limits as your Claude.ai chats. But starting June 15, 2026, Anthropic separates out programmatic usage: the Claude Agent SDK, the claude -p headless command, the Claude Code GitHub Actions integration, and third-party apps that authenticate through the Agent SDK will no longer count against your interactive subscription pool. Instead they draw from a new, separate monthly Agent SDK credit, billed at standard API rates. This page documents both models, the exact credit amounts per plan, and the SDK package rename you may also need to handle.

    The two billing models at a glance

    Workshop fuel gauge and metal tokens pouring into an API hopper, metaphor for pay-per-token pricing
    Two billing models at a glance — no sticky dollar stickers.

    The dividing line is interactive vs. programmatic. One number to remember: setting an ANTHROPIC_API_KEY environment variable overrides your subscription entirely — Claude Code then authenticates with that key and bills as pay-as-you-go API usage, regardless of plan.

    Usage type How it runs Billed against
    Interactive Claude Code Terminal or IDE, human at the keyboard Pro/Max subscription usage limits
    Claude.ai chat Web, desktop, mobile Pro/Max subscription usage limits
    Agent SDK (Python/TypeScript) Your own programmatic projects Separate Agent SDK credit (from June 15, 2026)
    claude -p (non-interactive) Headless / scripted Claude Code Separate Agent SDK credit (from June 15, 2026)
    Claude Code GitHub Actions CI/CD automation Separate Agent SDK credit (from June 15, 2026)
    Any usage with ANTHROPIC_API_KEY set API-key auth instead of subscription Standard API rates (pay-as-you-go)

    What changes on June 15, 2026

    Per Anthropic’s support documentation: “Starting June 15, 2026, Claude Agent SDK and claude -p usage no longer counts toward your Claude plan’s usage limits.” Each subscription tier instead receives a fixed monthly Agent SDK credit. When that credit runs out, additional Agent SDK usage flows to usage credits at standard API rates — but only if you have enabled usage credits. If you have not, “Agent SDK requests stop until your credit refreshes.” Unused credits do not roll over to the next billing cycle, and there is no automatic fallback to the interactive pool.

    Plan Monthly Agent SDK credit
    Pro $20
    Max 5x $100
    Max 20x $200
    Team (Standard seats) $20
    Team (Premium seats) $100
    Enterprise (seat-based Premium) $200

    What stays on the interactive subscription pool, unchanged: Claude conversations on web, desktop, and mobile; and interactive Claude Code in the terminal or IDE. The change is scoped strictly to programmatic execution.

    How each pool is metered and priced

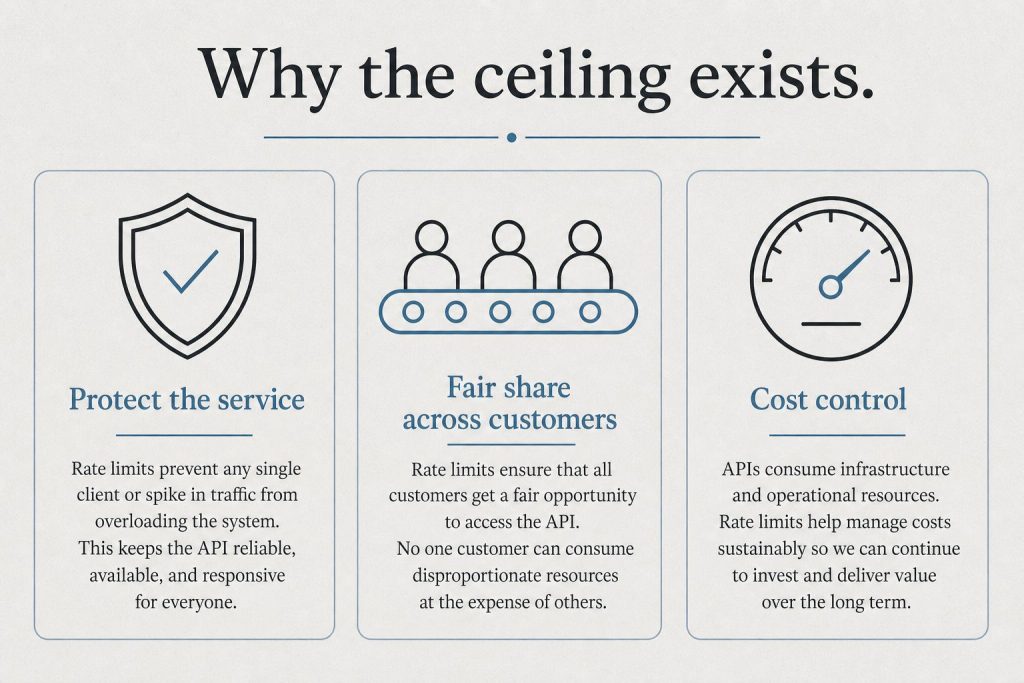
    Infographic with three panels: protect the service, fair share, and cost control explaining rate limits
    How each pool is metered.

    Claude Code “charges by API token consumption” — the underlying meter is input/output tokens, including thinking tokens billed as output. On a subscription, that token consumption is what counts against your plan limits (interactive) or your Agent SDK credit (programmatic). The Agent SDK credit and any overflow are billed at standard API list rates; the per-model API token prices below are the verified current rates.

    Pool Meter Price basis
    Interactive (Pro/Max) Tokens, against plan usage limits Included in subscription
    Agent SDK credit Tokens, against monthly credit Standard API rates
    Overflow past the credit Tokens, usage credits Standard API rates (only if usage credits enabled)
    API key (ANTHROPIC_API_KEY) Tokens, pay-as-you-go Standard API rates

    Verified current API token prices (per million tokens) for models commonly used in Claude Code:

    Model Model ID Input $/Mtok Output $/Mtok
    Claude Sonnet 5.5 claude-sonnet-5-5 $2.00 $10.00
    Claude Opus 5.5 claude-opus-5-5 $4.00 $20.00
    Claude Fable 5.1 claude-fable-5-1 $10.00 $50.00
    Claude Opus 4.8 (legacy — still listed) claude-opus-4-8 $5.00 $25.00
    Claude Sonnet 4.6 (legacy — still listed) claude-sonnet-4-6 $3.00 $15.00
    Claude Haiku 4.5 claude-haiku-4-5 $1.00 $5.00

    Subscription plan prices

    These are the published Claude plan prices the Agent SDK credits attach to. The Max 5x plan starts at $100/month; the $200 figure for Max 20x is documented as the matching Agent SDK credit amount for that tier.

    Plan Price
    Free $0
    Pro $20/month, or $17/month billed annually ($200 up front)
    Max 5x From $100/month
    Team (Standard seat) $25/seat/month, or $20/seat/month billed annually

    The SDK rename: claude-code-sdk to claude-agent-sdk

    Separate from billing, the SDK itself was renamed. Anthropic’s migration guide states: “The Claude Code SDK has been renamed to the Claude Agent SDK.” If you have code on the old package, you must update the package name, imports, and one Python type. The headless CLI command name is unchanged — it is still claude -p.

    Aspect Old New
    npm package (TS/JS) @anthropic-ai/claude-code @anthropic-ai/claude-agent-sdk
    Python package claude-code-sdk claude-agent-sdk
    Python options type ClaudeCodeOptions ClaudeAgentOptions
    Default system prompt Claude Code’s preset Minimal (opt back in via preset: "claude_code")
    # TypeScript
    npm uninstall @anthropic-ai/claude-code
    npm install @anthropic-ai/claude-agent-sdk
    
    # Python
    pip uninstall claude-code-sdk
    pip install claude-agent-sdk

    Decision: which billing path applies to your work

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    Which billing path applies to your work.
    If you are… Billing path
    A developer coding interactively in the terminal Subscription usage limits (unchanged)
    Running claude -p in a script or cron job Agent SDK credit (from June 15, 2026)
    Running Claude Code in GitHub Actions Agent SDK credit (from June 15, 2026)
    Building an app on the Agent SDK with subscription auth Agent SDK credit (from June 15, 2026)
    A team or service account wanting budgets + usage reports Set ANTHROPIC_API_KEY → standard API billing

    Does interactive Claude Code billing change on June 15, 2026?

    No. Anthropic’s documentation confirms interactive Claude Code in the terminal or IDE, and Claude conversations on web, desktop, and mobile, continue using subscription usage limits as before. Only programmatic usage — the Agent SDK, claude -p, GitHub Actions, and third-party Agent SDK apps — moves to the separate Agent SDK credit.

    How much is the separate Agent SDK credit?

    $20/month on Pro, $100 on Max 5x, $200 on Max 20x, $20 on Team Standard seats, $100 on Team Premium seats, and $200 on Enterprise seat-based Premium. The credit is billed at standard API rates, does not roll over, and refreshes monthly.

    What happens when the Agent SDK credit runs out?

    Additional Agent SDK usage flows to usage credits at standard API rates — but only if you have enabled usage credits. If you have not enabled them, Agent SDK requests stop until your credit refreshes. There is no automatic fallback to your interactive subscription pool.

    How do I avoid the credit pool entirely?

    Set an ANTHROPIC_API_KEY environment variable. Claude Code and the Agent SDK then authenticate with that key and bill as standard pay-as-you-go API usage, separate from any subscription. This is Anthropic’s recommended path for apps, CI jobs, service accounts, and team-owned projects that need budgets and usage reporting.

    Was the Claude Code SDK renamed?

    Yes. It is now the Claude Agent SDK. The npm package @anthropic-ai/claude-code became @anthropic-ai/claude-agent-sdk, the Python package claude-code-sdk became claude-agent-sdk, and the Python type ClaudeCodeOptions became ClaudeAgentOptions. The claude -p CLI command name is unchanged.

    Related on Tygart Media: Claude Code getting started · Claude pricing · Pro vs Max.


    Part of the complete guide: Claude Code

  • Claude Code Getting Started: Installation, Firs (2026)

    Claude Code Getting Started: Installation, Firs (2026)

    Claude Code is Anthropic’s official CLI for Claude — a terminal-based agent you can point at any codebase and have it read, write, test, and ship code. It’s different from the Claude.ai chat interface in one key way: Claude Code can act, not just answer. It reads your actual files, runs your actual commands, and makes changes that stick.

    This guide walks you through installation, first run, and the commands that cover 90% of what you’ll do daily.

    What Claude Code Is (and Isn’t)

    Side-by-side cards defining what Claude Code is and is not
    Claude Code is a terminal agent — not a chat website.

    Claude Code runs in your terminal. It gives Claude access to your local machine — file system, shell, and any MCP servers you configure — so it can do real engineering work: implement features, fix bugs, write tests, explain unfamiliar codebases, and run multi-step agentic workflows.

    It is not a code autocomplete plugin (that’s what GitHub Copilot does). Claude Code is a conversational agent that works at the task level, not the token level. You describe what you want; it figures out the steps and executes them.

    Installation

    Claude Code requires Node.js 18 or later. Install via npm:

    npm install -g @anthropic-ai/claude-code

    Verify the install:

    claude --version

    That’s the only dependency. Claude Code is a Node.js CLI — no Docker, no Python env, no platform-specific setup beyond Node.

    First-Run Authentication

    The first time you run claude, it walks you through authentication. You have two options:

    Option 1: Claude subscription (Pro, Max, Team, Enterprise)
    Run claude, select “Login with Claude.ai,” and it opens a browser window to authorize. Your subscription covers Claude Code usage — no separate API billing.

    Option 2: Anthropic API key
    Set your API key as an environment variable before running:

    export ANTHROPIC_API_KEY="sk-ant-..."
    claude

    Or on Windows:

    $env:ANTHROPIC_API_KEY = "sk-ant-..."
    claude

    API key usage is billed per token at standard API rates. For heavy daily use, a Max subscription ($100–$200/month) is usually more economical than API billing.

    Your First Session

    Navigate to a project directory and start Claude Code:

    cd ~/projects/my-app
    claude

    Claude Code reads your directory automatically. At the > prompt, describe what you want:

    > What does this codebase do? Give me a 3-paragraph overview.
    

    Claude reads the files it needs and responds. No configuration required for basic usage — Claude Code infers context from the directory you’re in.

    The 5 Commands You’ll Use Daily

    Five stacked panels of daily Claude Code command habits
    The five commands you’ll use daily.

    1. claude — Start an interactive session

    claude

    Launches the REPL (read-eval-print loop). This is where you spend most of your time. Claude has access to your current directory’s files, can run bash commands, and can call any MCP servers you’ve configured.

    Within a session, you can:

    • Ask questions about the codebase
    • Request implementations (“add a rate limiter to the auth middleware”)
    • Have Claude run tests and fix failures
    • Use /help to see available slash commands
    • Use /clear to reset context without leaving the session
    • Press Escape twice to interrupt a running task

    2. claude -p "prompt" — One-shot non-interactive mode

    claude -p "What are all the API endpoints in this codebase?"

    Runs a single prompt and exits. No REPL. Good for scripting, CI pipelines, or quick one-off queries you don’t want to interrupt a workflow for. Output goes to stdout — pipe it wherever you need it.

    claude -p "Summarize the changes in the last 10 commits" | pbcopy

    3. claude mcp add — Connect an external tool

    claude mcp add github -- npx -y @modelcontextprotocol/server-github

    Adds an MCP server to your Claude Code configuration. After running this, Claude can call the server’s tools in any session. Common additions:

    # File system access (scoped to a directory)
    claude mcp add files -- npx -y @modelcontextprotocol/server-filesystem ~/Documents
    
    # GitHub integration
    claude mcp add github -- npx -y @modelcontextprotocol/server-github
    
    # Web search
    claude mcp add search -- npx -y @modelcontextprotocol/server-brave-search

    The GitHub and Brave Search servers need API tokens — set them as environment variables before the server starts, or pass them via the --env flag in the mcp add command.

    4. claude -c — Continue the last conversation

    claude -c

    Resumes your most recent Claude Code conversation, including all prior context. Essential for multi-session work on a feature. If you closed the terminal mid-task, claude -c picks up exactly where you left off.

    For a specific prior conversation:

    claude --resume SESSION_ID

    5. claude --model — Select the model for a session

    claude --model claude-opus-4-8

    Claude Code defaults to the most capable available model for your plan. You can override this per session. Current options:

    • claude-fable-5 — Highest capability, complex tasks (2x cost vs Opus 4.8)
    • claude-opus-4-8 — Default for most work, strong balance of quality and speed
    • claude-sonnet-4-6 — Faster responses, good for routine tasks
    • claude-haiku-4-5-20251001 — Fastest, lowest cost, short tasks

    Slash Commands Inside a Session

    While in a Claude Code session (> prompt), these slash commands are available:

    CommandWhat It Does
    /helpShow all available commands
    /clearClear conversation context (keep the session open)
    /compactCompress prior context to save tokens while preserving essential memory
    /costShow token usage and estimated cost for the current session
    /modelSwitch the model mid-session
    /reviewRequest a multi-agent code review of the current branch
    /initGenerate a CLAUDE.md file with project context for this repo
    /exitEnd the session

    CLAUDE.md — Project-Level Context

    Drop a CLAUDE.md file in your project root and Claude Code reads it automatically at session start. Use it to encode project-specific context Claude shouldn’t have to re-derive every session:

    # My Project
    
    ## Architecture
    - Backend: FastAPI + PostgreSQL
    - Frontend: React + TypeScript
    - Deployed to: AWS ECS
    
    ## Development
    - Tests: `pytest tests/`
    - Local server: `./scripts/start-dev.sh`
    - Database migrations: `alembic upgrade head`
    
    ## Rules
    - Never modify migration files directly
    - All API routes go in `src/routes/`
    - Use `httpx` not `requests` for HTTP calls

    Generate a starter CLAUDE.md for an existing project with /init.

    Permission Modes

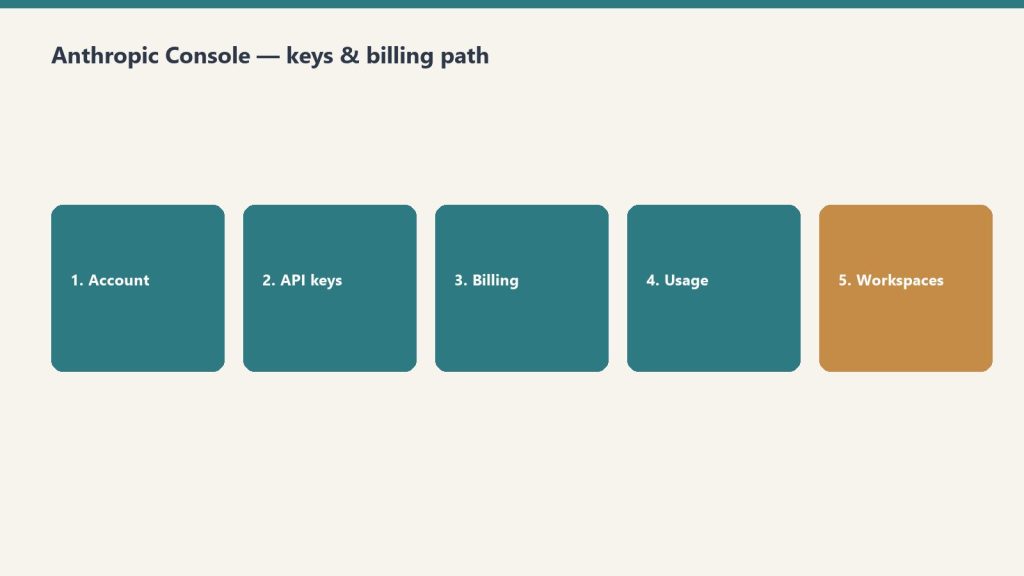
    Five-step path: account, API keys, billing, usage, workspaces
    Permission modes — decide what the agent may touch.

    Claude Code asks for confirmation before running bash commands, creating files, or making other changes — unless you grant it broader permissions. There are three ways to control this:

    • Default: Claude asks before each tool use that modifies files or runs commands
    • --dangerously-skip-permissions: Skip all confirmations. Use only in isolated environments (Docker containers, CI). Not for everyday use on your primary machine.
    • Session-level allowlist: During a session, you can approve individual tools for the rest of the session by selecting “Allow always” when prompted

    For most work, the default confirmation behavior is the right trade-off — it keeps you in the loop on changes without requiring you to pre-define a permission policy.

    IDE Integration

    Claude Code integrates with VS Code and JetBrains IDEs. Install the extension from each marketplace, then launch Claude Code from inside the IDE. This keeps the terminal panel visible alongside your editor without alt-tabbing between windows.

    The IDE extensions also add shortcuts for common actions like opening Claude Code in the current file’s directory and running one-shot queries against the selected code.

    Related on Tygart Media: Claude Code billing · Claude Code vs Cursor · Claude Code tutorial.

    Frequently Asked Questions

    What’s the difference between Claude Code and Claude.ai?
    Claude.ai is the web chat interface — good for questions, document analysis, and writing. Claude Code is a terminal CLI that can access your local files, run commands, and act autonomously on multi-step tasks. Claude.ai can’t modify files on your machine; Claude Code can.

    Does Claude Code cost extra on top of my Claude subscription?
    No. Claude Pro, Max, Team, and Enterprise subscriptions include Claude Code access. You use the same account. Heavy agentic usage counts toward the plan’s usage limits, but there’s no separate Claude Code fee.

    Can Claude Code access the internet?
    Not by default. Claude Code’s built-in WebFetch tool can fetch content from a specific URL when you provide it. For live web search, add the Brave Search or similar MCP server. Claude can’t browse freely without explicit tool access.

    What does Claude Code do with my code?
    Claude Code sends the file contents and context it needs to the Anthropic API for inference. Standard Anthropic API data policies apply — if you’re using an API key, you can configure zero data retention. If you’re using a subscription, default Anthropic retention policies apply. Review Anthropic’s privacy policy for current details.

    Is Claude Code open source?
    Claude Code itself (the CLI client) is not open source — it’s an Anthropic product. The MCP server ecosystem it connects to includes many open-source servers, and the MCP specification itself is open.

    What version of Node.js do I need?
    Node.js 18 or later. Run node --version to check. The Long-Term Support (LTS) version is always a safe choice.

    Last verified: June 12, 2026. Claude Code is updated frequently — run npm update -g @anthropic-ai/claude-code to stay current.

  • What Is Model Context Protocol (MCP)? The Complete Guid (2026)

    What Is Model Context Protocol (MCP)? The Complete Guid (2026)

    Model Context Protocol (MCP) is the reason Claude can read your files, query your database, search the web, and push code to GitHub — all from inside a single conversation. Without it, Claude would be limited to whatever you paste in manually. With it, Claude connects to almost any external system.

    Quick answer: MCP is an open standard developed by Anthropic that lets AI models securely connect to external tools, data sources, and services through a standard client-server architecture (MCP getting started). You install an MCP server for the system you want Claude to access. Claude becomes a client that calls that server. The server executes the action and returns results.

    The Problem MCP Solves

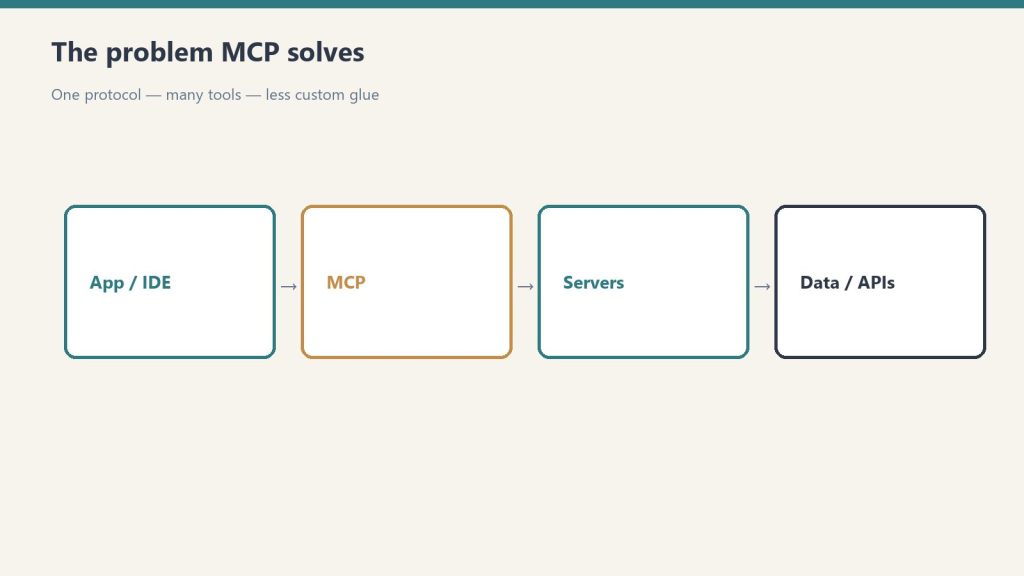
    Flow from app/IDE through MCP to servers and data APIs
    The problem MCP solves: one protocol, many tools.

    Before MCP, connecting an AI model to external data meant one of two things: either the AI company built a native integration (slow, expensive, proprietary), or you cobbled together a pipeline that passed data manually between systems.

    Neither approach scales. If Claude natively supported every database, every API, every file format, and every SaaS tool on the planet, the model would be perpetually behind. And manual copy-paste workflows aren’t agentic — they require you to do all the coordination work the AI should be doing.

    MCP solves this with a universal adapter layer. Instead of building individual integrations, Anthropic defined a standard. Now any developer can build an MCP server for any system, and any MCP-compatible AI client (like Claude) can use it automatically.

    How MCP Works

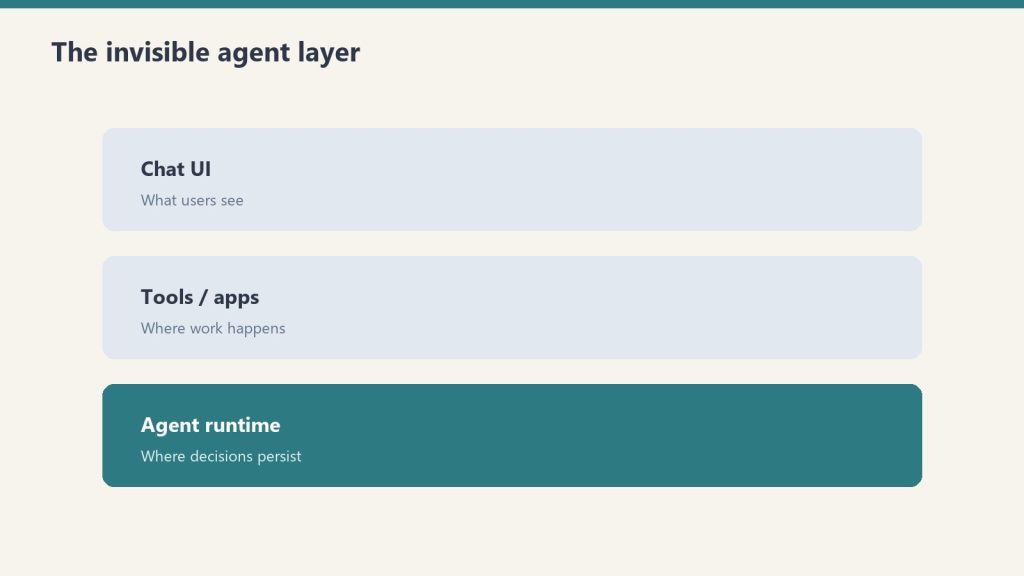
    Three stacked layers: chat UI, tools, agent runtime
    How MCP works as a layer between tools and agents.

    MCP uses a client-server model over two transport mechanisms:

    • stdio: The MCP server runs as a local subprocess on your machine. Claude Code spawns it, communicates via standard input/output. This is the most common setup.
    • HTTP/SSE: The MCP server runs as a network service. Claude connects over HTTP with Server-Sent Events for streaming. Better for remote or shared servers.

    The communication protocol underneath is JSON-RPC 2.0 — a lightweight, well-understood standard for calling methods and getting results.

    Each MCP server exposes one or more of three primitives:

    • Tools: Functions Claude can call. Example: read_file(path), create_issue(title, body), run_query(sql). Claude decides when to call them based on context.
    • Resources: Data sources Claude can read. Example: the contents of a directory, a database schema, a project’s README. Resources are passive — they don’t take actions, they expose information.
    • Prompts: Reusable prompt templates that servers can provide to standardize how Claude interacts with them.

    When Claude sees a task that could benefit from an available tool, it calls the tool, receives the result, and incorporates it into the response. This happens automatically — you don’t have to tell Claude when to use MCP. Claude decides based on what the server exposes.

    MCP in Claude Code vs Claude Desktop

    Both Claude Code (the CLI tool) and Claude Desktop support MCP, but they configure servers differently.

    Claude Code

    Claude Code has built-in MCP management via the claude mcp command family:

    claude mcp add my-server -- npx -y @modelcontextprotocol/server-filesystem /path/to/directory
    claude mcp list
    claude mcp remove my-server

    Servers added with claude mcp add are stored in your Claude Code config (~/.claude.json or the project-level .claude/settings.json). Project-level configs let you commit MCP server setups to source control so the whole team gets them automatically.

    Claude Code also ships with a set of built-in tools that behave like MCP servers but don’t require separate installation: file read/write/edit, bash execution, glob search, grep, web fetch, and the agent spawning tools you’re reading about in this article.

    Claude Desktop

    Claude Desktop reads MCP server configuration from a JSON file:

    • macOS: ~/Library/Application Support/Claude/claude_desktop_config.json
    • Windows: %APPDATA%\Claude\claude_desktop_config.json

    A typical config entry looks like this:

    {
      "mcpServers": {
        "filesystem": {
          "command": "npx",
          "args": ["-y", "@modelcontextprotocol/server-filesystem", "/Users/you/Documents"]
        },
        "github": {
          "command": "npx",
          "args": ["-y", "@modelcontextprotocol/server-github"],
          "env": {
            "GITHUB_PERSONAL_ACCESS_TOKEN": "ghp_your_token_here"
          }
        }
      }
    }

    Restart Claude Desktop after editing the config. Each server you add appears in the Claude Desktop interface with a hammer icon, and Claude can access its tools in any conversation.

    The Most Useful MCP Servers

    Anthropic maintains a reference set of official MCP servers. These are the ones worth knowing:

    ServerWhat It DoesPackage
    FilesystemRead/write files and directories on your local machine@modelcontextprotocol/server-filesystem
    GitHubRead repos, create issues, open PRs, push code@modelcontextprotocol/server-github
    PostgreSQLRead-only SQL queries against a Postgres database@modelcontextprotocol/server-postgres
    SQLiteRead/write a local SQLite database file@modelcontextprotocol/server-sqlite
    Brave SearchLive web search via Brave’s Search API@modelcontextprotocol/server-brave-search
    PuppeteerHeadless browser — screenshot pages, scrape, fill forms@modelcontextprotocol/server-puppeteer
    SlackRead channels, send messages, search workspace@modelcontextprotocol/server-slack
    Google DriveRead and search Google Drive files@modelcontextprotocol/server-google-drive
    GitGit operations — log, diff, commit, branch management@modelcontextprotocol/server-git
    MemoryPersistent key-value knowledge graph across conversations@modelcontextprotocol/server-memory

    Beyond the official set, hundreds of community-built MCP servers cover everything from Notion and Linear to AWS and Docker. The MCP ecosystem grew faster than almost anyone expected after the November 2024 launch.

    Installing Your First MCP Server

    The fastest path is Claude Code with the filesystem server. This gives Claude read/write access to a directory you specify — useful for any project work.

    Prerequisites: Node.js installed (the server runs via npx).

    In your terminal:

    claude mcp add filesystem -- npx -y @modelcontextprotocol/server-filesystem ~/Documents/projects

    That’s it. Open a Claude Code session. Claude can now list, read, write, and search files inside ~/Documents/projects. Try: “List all Python files in this directory and summarize what each one does.”

    For Claude Desktop, edit the claude_desktop_config.json file directly (see format above), then restart the app.

    What MCP Cannot Do

    Five red warning rows of MCP limitations
    What MCP cannot do — permissions and review still matter.

    A few things worth understanding before you build on MCP:

    MCP servers don’t persist between conversations. Each Claude session starts fresh. If you need state persistence, you need a server with its own storage layer (the Memory server handles this specifically).

    MCP doesn’t bypass Claude’s safety guidelines. Claude still decides whether to execute a tool call based on safety and ethics reasoning. Connecting a filesystem server doesn’t give Claude unlimited license to delete files — Claude will still confirm before destructive operations.

    Subprocess MCP servers are local. The stdio transport runs servers on your machine. This means they only work when you’re running Claude Code locally. For remote or team-shared access, you need HTTP/SSE transport with a hosted server.

    Security Considerations

    MCP servers have real permissions. The filesystem server can read and write files. The GitHub server can push code to your repos. The Postgres server can run SQL queries.

    Apply the principle of least privilege:

    • Scope filesystem servers to the directory you actually need, not /
    • Use read-only database credentials where you don’t need writes
    • Create GitHub tokens with minimum required scope (e.g., repo for private repos, not org-level admin)
    • Never commit environment variables containing API keys to source control, even in .claude/settings.json — use env var references instead

    MCP servers run with the permissions of the user running Claude. If something goes wrong with a tool call, it can have real consequences. The upside: everything runs locally and through your own credentials — there’s no MCP cloud intermediary with access to your data.

    MCP and Claude Code’s Agentic Workflows

    The full power of MCP shows up in Claude Code’s multi-step agentic mode. When Claude Code has access to git, a filesystem, a browser, and a search tool simultaneously, it can execute workflows like:

    1. Search the web for a library’s current API (Brave Search)
    2. Read your existing code to understand the integration point (filesystem)
    3. Write the updated code (filesystem write)
    4. Run tests (bash)
    5. Create a PR (GitHub)

    Each of these steps would require a separate tool in a traditional automation stack. With MCP, Claude orchestrates all of them within a single session, using whatever servers are available.

    This is what makes MCP the infrastructure layer for agentic AI — not a feature, but the foundation that makes complex AI-driven workflows possible.

    Related on Tygart Media: Claude MCP · Skills vs MCP vs plugins · how to use Claude.

    Frequently Asked Questions

    What does MCP stand for?
    Model Context Protocol. It’s an open standard for connecting AI models to external tools, data sources, and services through a standard client-server interface.

    Who created MCP?
    Anthropic created MCP and released it as an open standard in November 2024. The specification and reference servers are open-source on GitHub. While Claude is the primary client, other AI systems can implement MCP clients too.

    Do I need to install MCP to use Claude?
    No. Claude works without any MCP servers. MCP is an extension layer — you add servers when you want Claude to access specific external systems. Claude Code also ships with a set of built-in tools (file operations, bash, web fetch) that don’t require MCP installation.

    Is MCP available on Claude.ai (the web app)?
    MCP server support is primarily in Claude Desktop and Claude Code. The Claude.ai web interface has its own tool integrations (web search, document analysis) but doesn’t support custom MCP servers in the same way.

    What’s the difference between MCP tools and Claude’s native tools in Claude Code?
    Claude Code’s native tools (Read, Write, Bash, Glob, Grep, WebFetch, Agent) are built into the application and don’t require a separate server process. MCP servers are external — they run as subprocesses or network services that Claude Code connects to. Both expose tools that Claude can call; the mechanism for loading them is different.

    How do I build my own MCP server?
    Anthropic provides official SDKs for building MCP servers in TypeScript, Python, Go, and other languages. The TypeScript SDK (@modelcontextprotocol/sdk) is the most mature. Start with Anthropic’s MCP documentation and the reference server implementations on GitHub as templates.

    Last verified: June 12, 2026. MCP specification and server ecosystem evolve quickly — check the official Anthropic MCP documentation for the current spec.

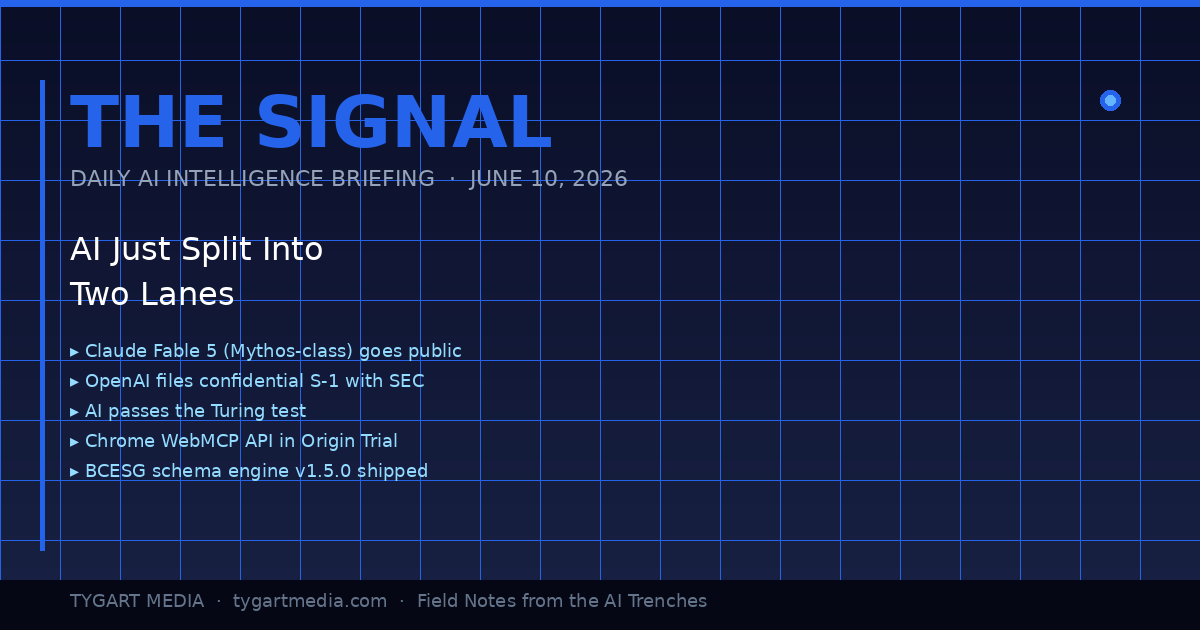
  • The Signal: AI Just Split Into Two Lanes (2026)

    The Signal: AI Just Split Into Two Lanes (2026)

    The Signal is a daily AI intelligence briefing from Tygart Media — field notes from someone who builds with these tools 12 hours a day, not someone who reads press releases about them. Each edition distills the day’s most consequential AI and search developments into what they actually mean for agencies, small business operators, and builders shipping real infrastructure.

    June 10, 2026: The Day the Lanes Forked

    Abstract milestone timeline from early Claude eras through today without version numbers
    The day the lanes forked — product vs infrastructure.

    Today was the kind of day where you can feel the road forking under your tires. Not because one thing happened — because eight things happened simultaneously, and if you squint at the pattern, they all point the same direction: AI just stopped being a product category and started being infrastructure. The plumbing layer. The thing you build on top of, not the thing you buy.

    I’ve been building with Claude since the Haiku days. I run it 12 hours a day across 20+ WordPress sites, a five-site knowledge cluster on Google Cloud, and a custom schema engine I shipped yesterday. When the landscape shifts, I don’t read about it on TechCrunch — I feel it in the tooling. And today, the tooling lurched forward in a way that matters.

    Here’s the daily signal.

    Claude Fable 5: Mythos-Class AI Goes Public

    Anthropic launched Claude Fable 5 yesterday — the first publicly available Mythos-class model, a tier above Opus. Pricing is $10 per million input tokens and $50 per million output tokens. It’s the most capable model Anthropic has ever released to the general public, state-of-the-art on nearly every benchmark, and it comes with a fascinating constraint: queries on certain topics automatically route to Opus 4.8 instead, triggering in less than 5% of sessions. Anthropic is essentially saying: here’s the most powerful thing we’ve ever built, and we’ve installed guard rails at the edge cases where power becomes risk.

    For agencies and small business operators, the practical read is this: Fable 5 is included on Pro, Max, Team, and Enterprise plans through June 22 at no extra cost. After that, it comes off the subscription tiers. If you’re building workflows that depend on Mythos-class reasoning, you have 12 days to test whether the capability justifies the API cost — or whether Opus and Sonnet handle your actual use cases just fine.

    The real signal isn’t the model itself. It’s that Anthropic also doubled Cowork limits at no charge and shipped Claude Managed Agents in public beta. They’re not just selling you a smarter model — they’re selling you an operating system for delegating work to AI. That’s a fundamentally different product than a chatbot.

    Meanwhile, I Was Building the Infrastructure Layer — Not Reading About It

    Three stacked layers: chat UI, tools, agent runtime
    Infrastructure layer work while the headlines chase models.

    While the tech press was writing headlines about Fable 5, I was elbow-deep in the kind of work that actually turns these models into business value. Yesterday, across a 14-hour session, my team — which at this point is me and a fleet of Claude instances — shipped three things that matter more to my clients than any benchmark score:

    1. bcesg-knowledge-api v1.5.0 — a custom WordPress plugin I built and deployed across BCESG.org that outputs a JSON-LD @graph array containing Article, FAQPage, Organization, WebPage, BreadcrumbList, Person (author), and speakable schema — all generated from 13 custom meta fields. This isn’t a schema plugin you install from the WordPress directory. It’s a purpose-built schema engine designed for one thing: making every page on the site machine-readable enough that AI systems cite it as an authoritative source. That’s Generative Engine Optimization at the infrastructure level, not the content level.

    2. WordPress 7.0 across the entire knowledge cluster. All five sites — bcesg.org, restorationintel.com, riskcoveragehub.com, continuityhub.org, and healthcarefacilityhub.org — upgraded from WP 6.9.4 to 7.0. Why does this matter? Because WordPress 7.0 ships the Abilities API: agent-to-agent communication endpoints. That means my Claude-powered content pipelines can now negotiate directly with WordPress about what they’re allowed to do, without me acting as the middleware. The cluster just became AI-native infrastructure.

    3. The stack around it. RankMath SEO installed with the schema module deliberately disabled — because the custom plugin handles schema, and two schema systems fighting each other is worse than none at all. IndexNow for instant search engine notification on every publish and update. Microsoft Clarity for behavioral analytics so I can see what humans actually do when they land on AI-optimized content.

    And here’s the detail that would have been impossible to explain six months ago: the peer review on the bcesg-knowledge-api plugin was done by Claude Fable 5 reviewing the code that Claude Opus wrote. AI reviewing AI’s code. In production. On a live WordPress cluster. That’s not a demo — that’s Tuesday.

    OpenAI’s S-1 and the $965 Billion Elephant

    Three cards: coding depth, latency first, agent reliability
    What the split means for operators building agents.

    OpenAI filed a confidential S-1 with the SEC. They’re going public. Meanwhile, Anthropic hit a $965 billion valuation. These two facts, side by side, tell you everything about where the money thinks AI is going: it’s going to be the most valuable infrastructure layer since cloud computing, and the market is pricing it that way before most businesses have figured out how to use it.

    For small business owners and agency operators, this isn’t abstract finance news. It means the tools you’re using today — Claude, GPT, Gemini — are backed by companies with enough capital to keep shipping improvements for years. The platform risk isn’t that these companies disappear. The platform risk is that you don’t build on them fast enough and your competitors do.

    AI Passed the Turing Test. Now What?

    A UC San Diego study published in PNAS confirmed that OpenAI’s GPT-4.5 and Meta’s Llama-3.1-405B both passed a standard three-party Turing test — with GPT-4.5 being identified as human 73% of the time when given a persona prompt, significantly more often than actual human participants. This has been treated as a milestone headline, and it is one, but the practical implication is more subtle than “AI can fool humans.”

    What it actually means: the content quality bar just moved permanently. If AI can produce text that’s indistinguishable from a human expert, then the only content that wins is content with something AI can’t fake — lived experience, proprietary data, operational specifics, the kind of “I shipped this yesterday and here’s what happened” detail that no model can generate from training data. This is why I write The Signal as field notes, not as analysis. Analysis can be generated. Field notes from the arena cannot.

    Chrome WebMCP: The Browser Becomes an AI Endpoint

    Google shipped the Chrome WebMCP API in Origin Trial for Chrome 149 through 156. The Model Context Protocol — the same protocol that lets Claude connect to external tools, databases, and APIs — is now a browser-native capability. Web applications can expose structured tool interfaces that AI models call directly.

    This is a bigger deal than it sounds. Right now, when Claude interacts with a web application, it’s either through a dedicated MCP server or through browser automation (clicking pixels on a screen like a human would). WebMCP means any web app can define a structured API surface that AI agents consume natively. For agencies building client tools, this is the moment your internal dashboards and client portals become AI-ready without a full backend rewrite.

    If you’re running WordPress sites — and 43% of the web is — this has direct implications for how AI agents interact with your content management layer. The gap between “website” and “AI-accessible knowledge base” just narrowed dramatically.

    The GPU Infrastructure Play: xAI Becomes an AI REIT

    Elon Musk’s xAI, home of Grok, is increasingly looking less like an AI model company and more like a GPU real estate investment trust. They’re partnering with both Anthropic and Google to provide compute infrastructure. This is the clearest sign yet that the AI industry is stratifying into two distinct layers: model companies (who build the brains) and infrastructure companies (who build the data centers those brains run in).

    For builders, this is good news. More compute supply means more pricing competition means lower API costs over time. The $10/$50 per million tokens for Fable 5 today will look expensive in 18 months.

    The Security Layer Nobody’s Talking About

    HashiCorp announced Boundary for agentic AI — access security specifically designed for AI agents that need to authenticate across multiple systems. And MemPalace shipped a local-first AI memory system with 96.6% recall accuracy and 29 MCP tools for Claude Code.

    These aren’t headline products. They’re infrastructure connective tissue. When AI agents can securely authenticate across your entire tool stack (HashiCorp Boundary) and maintain persistent memory across sessions (MemPalace), you stop using AI for one-off tasks and start using it as a persistent operational layer. That’s the transition my agency is making right now — from “Claude helps me write articles” to “Claude runs the content pipeline while I focus on strategy.”

    What This All Means: The Two-Lane Highway

    Here’s the pattern I see when I lay these signals side by side:

    Lane 1: The AI product lane. This is where most people are. They use ChatGPT to draft emails. They ask Claude to summarize documents. They treat AI as a productivity tool, like a faster Google or a better autocomplete. This lane is getting crowded, commoditized, and — with the Turing test results — increasingly indistinguishable from one provider to the next.

    Lane 2: The AI infrastructure lane. This is where the alpha is. Custom schema engines. Agent-to-agent communication via the WordPress Abilities API. Browser-native MCP endpoints. Persistent AI memory. Secure multi-system authentication for autonomous agents. This lane is where you stop using AI and start building on AI — where it becomes the foundation layer of your operations, not an add-on.

    The gap between these two lanes is widening every day. Today’s eight signals all point the same direction: toward a world where the businesses that win aren’t the ones that use AI tools the best, but the ones that build AI infrastructure the fastest.

    I’m building in Lane 2. Yesterday it was a custom schema engine and a WordPress 7.0 cluster upgrade. Today it’s field-testing Fable 5 as a code reviewer. Tomorrow it’ll be whatever the next signal demands.

    The question isn’t whether AI is going to transform your industry. That’s settled. The question is whether you’re in the arena building the infrastructure, or on the sidelines reading about people who are.

    — Will Tygart, Tygart Media

    Frequently Asked Questions

    What is Claude Fable 5 and how does it differ from Claude Opus?

    Claude Fable 5 is Anthropic’s first publicly available Mythos-class AI model, released June 9, 2026. It sits a tier above Claude Opus in capability, priced at $10 per million input tokens and $50 per million output tokens. Fable 5 is state-of-the-art on nearly all tested benchmarks and includes built-in safeguards that route certain queries to Opus 4.8, triggering in less than 5% of sessions. It’s available free on subscription plans through June 22, 2026.

    What is the Chrome WebMCP API and why does it matter for businesses?

    The Chrome WebMCP API, now in Origin Trial for Chrome versions 149 through 156, brings the Model Context Protocol natively into the browser. This allows web applications to expose structured tool interfaces that AI models can call directly — eliminating the need for dedicated backend integrations or browser automation. For businesses running web-based tools, dashboards, or WordPress sites, this means your existing applications can become AI-accessible without a full rebuild.

    What is the WordPress 7.0 Abilities API?

    The WordPress 7.0 Abilities API provides agent-to-agent communication endpoints, allowing AI-powered systems to negotiate capabilities and permissions directly with a WordPress installation. This transforms WordPress from a content management system into AI-native infrastructure where automated pipelines can query what operations they’re authorized to perform without human middleware.

    What does AI passing the Turing test mean for content creators?

    A UC San Diego study published in PNAS found that OpenAI’s GPT-4.5 and Meta’s Llama-3.1-405B both passed a standard three-party Turing test in 2026 — GPT-4.5 was identified as human 73% of the time with persona prompting. For content creators, this permanently raises the quality bar — the only content that wins is content with elements AI cannot fake: lived experience, proprietary data, operational specifics, and first-person field reports that no model can generate from training data alone.

    What is Generative Engine Optimization (GEO) and how does it work?

    Generative Engine Optimization is the practice of structuring web content so AI systems — including ChatGPT, Claude, Gemini, Perplexity, and Google AI Overviews — cite, reference, and recommend it. GEO involves entity enrichment, structured data (JSON-LD schema), authoritative citations, and machine-readable formatting. Unlike traditional SEO which targets search engine crawlers, GEO targets the large language models that increasingly mediate how users discover information.

    How should small businesses approach AI infrastructure in 2026?

    Start by moving from Lane 1 (using AI as a productivity tool) to Lane 2 (building AI into your operational infrastructure). Practical first steps include implementing structured data and schema markup on your website, setting up AI-optimized content pipelines, ensuring your site is crawlable by AI systems via protocols like LLMS.txt, and testing agentic workflows where AI handles multi-step operational tasks autonomously rather than single-prompt interactions.

    What is a custom schema engine and why build one instead of using plugins?

    A custom schema engine is a purpose-built WordPress plugin that generates structured data (JSON-LD) tailored to specific business objectives — in this case, AI citation optimization. Unlike off-the-shelf schema plugins that generate generic markup, a custom engine outputs precisely the entity relationships, author signals, and speakable content markers that AI systems use when deciding which sources to cite. The bcesg-knowledge-api plugin generates a seven-type @graph array from 13 custom meta fields, providing a level of control that no general-purpose plugin offers.

    What is the significance of AI reviewing AI-written code in production?

    When Claude Fable 5 peer-reviewed code written by Claude Opus for a production WordPress plugin, it demonstrated a mature AI development workflow where different model tiers serve different roles — one for generation, another for quality assurance. This mirrors human development practices (developer writes, senior reviews) but at machine speed and cost. It’s a practical example of how AI agent collaboration is already operational in real business infrastructure, not just research demos.

    The Signal is published daily on Tygart Media by Will Tygart. Each edition distills the day’s most consequential AI, search, and technology developments into actionable intelligence for agencies, small business operators, and builders shipping real AI infrastructure.

  • llms-full.txt vs llms.txt: Why AI Agents Crawl It More (2026)

    llms-full.txt vs llms.txt: Why AI Agents Crawl It More (2026)

    Last verified: October 11, 2026. AI crawler user-agents and llms.txt conventions shift quickly — always confirm bot names and file conventions against the current provider docs and your own server logs before relying on them.

    Most conversations about AI crawlability focus on one file: llms.txt. But if you look at what Anthropic, Vercel, and LangGraph actually ship – and what GEO crawler research found AI agents fetching most – the file that matters more is its companion: llms-full.txt.

    Here’s the practical reality: llms.txt is the map. llms-full.txt is the territory. And in 2026, the agents that matter for citation traffic are fetching the territory.

    The Full File Family You Probably Don’t Know About

    The original llms.txt proposal – published by Jeremy Howard in September 2024 – defined one file. Implementers built the rest. The complete family as of mid-2026 is four files, but most sites only need two:

    FileWhat’s in itWhen to use
    /llms.txtCurated index – H1, summary, link sectionsAlways. The orientation layer.
    /llms-full.txtFull content of every linked page, concatenated as MarkdownWhen you want a model to deep-ingest your docs in a single fetch
    /llms-ctx.txtPre-expanded context without URLsFastHTML-style implementations
    /llms-ctx-full.txtPre-expanded context with URLs preservedSame, but URL-aware

    The pattern that works – and the one Anthropic, Vercel, and LangGraph all run – is the index + export pair: llms.txt for orientation, llms-full.txt for deep ingestion.

    Why llms-full.txt Gets Crawled More

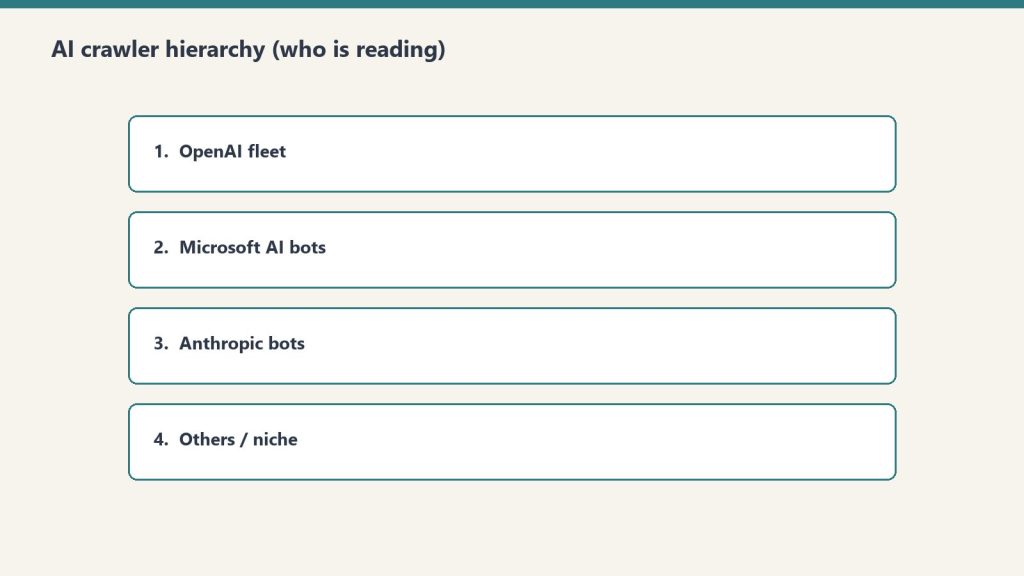
    Four ranked rows of AI crawler fleets reading publisher content
    Why llms-full.txt gets crawled more.

    GEO researchers analyzing AI crawler behavior – including work cited by Profound – have noted that agents from Microsoft, OpenAI, and others tend to fetch llms-full.txt more frequently than llms.txt when both are present. The working explanation is structural: when a file contains the full content, it removes one retrieval step. An agent that fetches llms-full.txt gets everything it needs in a single HTTP request instead of fetching the index, parsing the links, then fetching each linked page individually. This is consistent with how developer documentation platforms like Mintlify describe the behavior of IDE agents operating under tight latency budgets.

    For IDE agents (Cursor, Continue, Cline) and MCP integrations, this is even more pronounced. These tools are operating under tight context windows and latency budgets. A single fetch that returns a clean Markdown blob of your entire docs is structurally preferable to a multi-step crawl.

    The implication: if you’ve shipped llms.txt but not llms-full.txt, you’ve done half the job.

    How to Build llms-full.txt

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How to build llms-full.txt.

    The construction logic is simple: take every URL in your llms.txt, fetch each page, strip HTML to Markdown, and concatenate. In practice, most sites do this in their build pipeline.

    Here’s the minimal Node.js pattern:

    const fs = require('fs');
    const fetch = require('node-fetch');
    const TurndownService = require('turndown');
    const turndown = new TurndownService();
    
    async function buildLlmsFullTxt(llmsIndexPath, outputPath) {
      const index = fs.readFileSync(llmsIndexPath, 'utf8');
      const urlRegex = /\[.*?\]\((https?:\/\/[^\)]+)\)/g;
      const urls = [...index.matchAll(urlRegex)].map(m => m[1]);
    
      let output = '';
      for (const url of urls) {
        const res = await fetch(url);
        const html = await res.text();
        const markdown = turndown.turndown(html);
        output += \n\n---\n# Source: \n\n;
      }
    
      fs.writeFileSync(outputPath, output);
      console.log(Built llms-full.txt:  pages,  chars);
    }
    
    buildLlmsFullTxt('./public/llms.txt', './public/llms-full.txt');

    One constraint to manage: keep llms-full.txt under roughly 200,000 tokens (about 150K words, around 700KB). That’s the threshold where most models can ingest the file in a single context window. If your docs are larger, segment by product or language the way Supabase does – llms-full-api.txt, llms-full-guides.txt – and list the segmented files in your main llms.txt.

    The 2026 robots.txt Stack That Completes the Picture

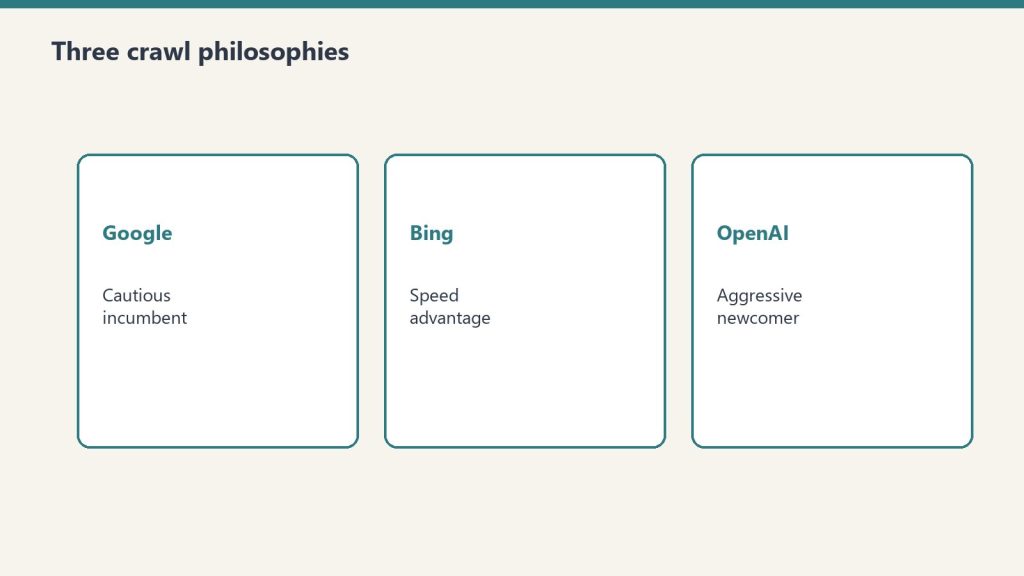
    Three cards for Google cautious, Bing speed, OpenAI aggressive crawl styles
    The 2026 robots.txt stack that completes the picture.

    Shipping llms.txt and llms-full.txt is the visibility layer. The access-control layer is robots.txt – and it changed significantly in Q2 2026.

    The key development: Anthropic split its crawler into two separate user-agents. ClaudeBot is the training scraper (high bandwidth, no citation value – block it). Claude-Web is the live-retrieval agent that fetches pages to answer Claude.ai user queries in real time (allow it, because it drives citation traffic). Brands that blanket-block “all Anthropic crawlers” lose Claude citations entirely.

    Meta also shipped two active training scrapers in March 2026 – FacebookBot and Meta-ExternalAgent – at GPTBot-level crawl volume. Most sites have no rules for them yet.

    Here’s the 2026 template:

    # BLOCK: Training scrapers - high bandwidth, zero referral value
    User-agent: GPTBot
    Disallow: /
    
    User-agent: CCBot
    Disallow: /
    
    User-agent: ClaudeBot
    Disallow: /
    
    User-agent: FacebookBot
    Disallow: /
    
    User-agent: Meta-ExternalAgent
    Disallow: /
    
    # OPT OUT: Google Gemini training (keeps Search indexing intact)
    User-agent: Google-Extended
    Disallow: /
    
    # ALLOW: Live-retrieval agents - drive citation traffic
    User-agent: OAI-SearchBot
    Allow: /
    
    User-agent: ChatGPT-User
    Allow: /
    
    User-agent: Claude-Web
    Allow: /
    
    User-agent: anthropic-ai
    Allow: /
    
    User-agent: PerplexityBot
    Allow: /

    One important caveat on robots.txt enforcement: aggressive training scrapers often ignore the file or spoof their user-agents. The robots.txt rules signal intent and work for compliant bots; a WAF rule at the edge is the only deterministic block for non-compliant crawlers.

    The Honest State of the Technology

    The SERanking study of 300,000 domains (November 2025) found no measurable correlation between having llms.txt and being cited by ChatGPT, Claude, Gemini, or Perplexity. Google’s John Mueller compared the file to the deprecated keywords meta tag – something site owners declare but that search systems derive from the content itself.

    None of that means you shouldn’t ship both files. The cost is low, the optionality is real, and the IDE-agent ecosystem (Cursor, Continue, Cline) does actively use llms.txt. But the robots.txt work is the lever that moves outcomes today. The llms.txt + llms-full.txt pair is infrastructure investment – you want to be correct when major LLM providers start honoring it, and building the build pipeline now costs far less than retrofitting it later.

    The practical sequence for a site that hasn’t done this yet:

    1. Update robots.txt first. Add the Q2 2026 user-agent rules above. This takes twenty minutes and immediately affects how training scrapers treat your content.
    2. Ship llms.txt. Curated index, 20-50 priority pages, one-sentence description per link, sections in priority order.
    3. Build llms-full.txt. Concatenated Markdown of every linked page, under 200K tokens. Run it in your build pipeline so it stays current.
    4. Verify both files are served correctly. curl -I https://yoursite.com/llms.txt should return 200 with Content-Type: text/plain. A 404 on either file is the most common implementation error.
    5. Add an access-log check. Once per month, grep your logs for requests to /llms.txt and /llms-full.txt by user-agent. You want to see live-retrieval agents (Claude-Web, OAI-SearchBot, PerplexityBot) in the results – not just training scrapers.

    The goal isn’t to optimize for a standard that isn’t fully adopted yet. It’s to build the infrastructure correctly now, while the field is still forming, so that adoption changes work in your favor rather than requiring catch-up.

    Related Reading

    Frequently Asked Questions

    What is the difference between llms.txt and llms-full.txt?

    llms.txt is a curated index — an H1, a summary, and link sections that orient an AI agent to your site. llms-full.txt is the full content of every linked page concatenated as Markdown, so an agent can deep-ingest your documentation in a single fetch. The index is the map; the full file is the territory.

    Why do AI agents crawl llms-full.txt more often than llms.txt?

    Fetching llms-full.txt removes a retrieval step: the agent gets everything in one HTTP request instead of fetching the index, parsing links, and fetching each page individually. For IDE agents like Cursor, Continue, and Cline operating under tight latency and context budgets, a single clean Markdown blob is structurally preferable to a multi-step crawl.

    How big should llms-full.txt be?

    Keep it under roughly 200,000 tokens (about 150K words, around 700KB) so most models can ingest it in a single context window. If your docs are larger, segment by product or language — for example llms-full-api.txt and llms-full-guides.txt — and list the segmented files in your main llms.txt.

    Does having llms.txt actually improve AI citations?

    Not measurably on its own. A November 2025 SERanking study of 300,000 domains found no correlation between having llms.txt and being cited by ChatGPT, Claude, Gemini, or Perplexity, and Google’s John Mueller compared it to the deprecated keywords meta tag. The lever that moves outcomes today is robots.txt configuration; llms.txt and llms-full.txt are low-cost infrastructure for when adoption grows.

    Which AI crawlers should I allow in robots.txt in 2026?

    Allow live-retrieval agents that drive citation traffic — Claude-Web, OAI-SearchBot, ChatGPT-User, anthropic-ai, and PerplexityBot. Block high-bandwidth training scrapers with no referral value such as GPTBot, CCBot, ClaudeBot, FacebookBot, and Meta-ExternalAgent, and opt out of Google-Extended to skip Gemini training while keeping Search indexing intact.

  • Claude Code vs Codex CLI (2026): A Hands-On Head-to-Head

    Claude Code vs Codex CLI (2026): A Hands-On Head-to-Head

    Last verified: June 2026.

    Both Claude Code and OpenAI Codex CLI are terminal-native coding agents: you run them inside a repo, they read your files, edit code, run commands, and iterate. I run both daily on real projects. This is the head-to-head I wish existed when I was deciding which one to make my default. No benchmarks-chasing, just install commands, config files, pricing math, and where each one actually earns its keep. For the broader toolchain these slot into, see our AI operator’s stack.

    Claude Code vs Codex CLI: the short answer

    Side-by-side cards defining what Claude Code is and is not
    Claude Code vs Codex CLI — the short answer.

    If you want one sentence: Claude Code is the more mature agentic harness (subagents, hooks, skills, deep MCP, a flat-rate plan that makes heavy use affordable), while Codex CLI is the leaner, cheaper-per-token option with strong raw coding from the GPT-5.x line and a tight sandbox model. Most teams that live in the terminal all day end up on Claude Code for the workflow tooling; people who want a fast, low-cost agent on top of an existing OpenAI subscription reach for Codex.

    The honest version: they are closer than tribal arguments suggest. The deciding factors are almost never “which model is smarter this week” and almost always pricing structure, sandbox defaults, and how much workflow scaffolding you need.

    How do you install each one?

    Five stacked panels of daily Claude Code command habits
    How do you install each one?

    Claude Code installs from npm and runs as the claude command:

    npm install -g @anthropic-ai/claude-code
    cd your-project
    claude

    First run walks you through OAuth login (Pro/Max plan) or an ANTHROPIC_API_KEY. On Windows it runs natively in PowerShell now, though a lot of operators still prefer it under WSL for fewer path headaches.

    Codex CLI ships an install script and is also on npm:

    # Mac / Linux
    curl -fsSL https://chatgpt.com/codex/install.sh | sh
    
    # Windows (PowerShell)
    powershell -ExecutionPolicy ByPass -c "irm https://chatgpt.com/codex/install.ps1 | iex"
    
    # or via npm
    npm install -g @openai/codex

    Then codex in your repo. Auth is either a ChatGPT login (Plus/Pro/Business) or an OpenAI API key via codex login. Both tools are open-source clients hitting hosted models, so the install is the easy part; the model access is what you are really buying.

    Which models do they run in 2026?

    Claude Code defaults to the current Claude flagship. As of June 2026 that is Opus 4.8 (legacy — still listed) for the hardest reasoning, with Sonnet 4.6 (legacy — still listed) as the fast everyday workhorse and Haiku 4

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    .5 for cheap, high-volume calls. You switch in-session with /model. Opus 4.8 also exposes reasoning-effort levels (high is the default; xhigh and max push deeper on gnarly problems at higher token cost).

    Codex CLI runs the GPT-5.x coding line. GPT-5.5 is the current recommended default for complex coding and agentic work, GPT-5.4-mini is the faster/cheaper option for light tasks and subagents, and GPT-5.3-Codex remains a strong coding-tuned choice. Pick the model with codex -m gpt-5.5 or set it in your config.

    Practical read: on a clean, well-specified function both produce good code. The gap shows up on long, multi-file refactors where the agent has to hold a lot of context and recover from its own mistakes. That is a harness problem as much as a model problem, which is the next section.

    What about workflow features: subagents, hooks, and config?

    This is where Claude Code is currently ahead, and it is the real reason it tends to win for power users.

    • Subagents – Claude Code spawns isolated sub-sessions with their own context window, tool restrictions, and prompts. Great for “go research this in parallel while the main thread keeps coding.” Codex has a lighter subagent concept (often pointed at GPT-5.4-mini to keep cost down) but it is less fleshed out.
    • Hooks – Claude Code fires deterministic scripts at lifecycle points (PreToolUse, UserPromptSubmit, and more). These run real code, so they cannot hallucinate: you can hard-block a dangerous command, auto-format on every edit, or inject context before the model sees a prompt. Codex leans on its approval/sandbox policy and execpolicy rules instead of a general hook system.
    • Skills and slash commands – In Claude Code, custom slash commands have merged into skills; /your-command still works and skills add reusable, packaged capabilities. Codex uses prompt files and profiles rather than a skills layer.
    • Project memory – Both read a project instruction file. Claude Code uses CLAUDE.md; Codex uses AGENTS.md (checked in a fallback order including AGENTS.override.md and .agents.md). Keep these tight: architecture, conventions, and the few rules the agent keeps forgetting.

    Codex’s config story is clean if you like a single file: ~/.codex/config.toml holds your model, approval policy, sandbox mode, MCP servers, and named profiles you switch with codex --profile work. Claude Code spreads config across ~/.claude/ and .claude/settings.json plus per-project files, which is more surface area but more granular control.

    How do the sandbox and approval models compare?

    This matters more than most comparisons admit, because it governs how much the agent can do without asking.

    Codex CLI has an explicit, well-documented sandbox. Sandbox modes run from read-only to workspace-write (edit files in the project, network off by default) up to full access, paired with approval policies like untrusted and on-request. On Windows the native sandbox can run unelevated or elevated. The mental model is clear: pick how much rope, then approve escalations.

    Claude Code manages permissions through allow/deny rules and modes (including a plan mode that reasons without touching files, and an auto-accept mode for trusted loops). Combined with PreToolUse hooks you can build a strict policy, but it is more “assemble it yourself” than Codex’s preset sandbox tiers.

    If you are dropping an agent onto an unfamiliar or sensitive repo, start read-only in both. Codex makes that posture a one-flag default; Claude Code gives you finer-grained control once you invest in the config.

    Do both support MCP?

    Flow from app/IDE through MCP to servers and data APIs
    Do both support MCP?

    Yes, and this is a genuine tie that matters. Both speak the Model Context Protocol, so you can wire in the same external tools, databases, and APIs. Codex registers STDIO or streaming-HTTP MCP servers in ~/.codex/config.toml and launches them at session start. Claude Code adds servers via claude mcp add or JSON config. If you have already built MCP integrations, neither tool locks you out. New to MCP, start with our Claude MCP setup guide and the Notion MCP setup walkthrough.

    What does each one cost?

    Pricing is where the decision often gets made, so here are the real numbers as of June 2026.

    Claude Code plans:

    • Pro – $20/mo: Sonnet 4.6 plus some Opus, roughly enough for focused daily sessions, not all-day heavy use.
    • Max 5x – $100/mo: much larger windows, real Opus headroom.
    • Max 20x – $200/mo: the heavy-user tier; effectively flat-rate firehose access.
    • API pay-as-you-go: Opus 4.7 about $5/$15 per million input/output… (legacy (still listed) Opus tier runs higher), Sonnet 4.6 (legacy — still listed) $3/$15, Haiku 4.5 $1/$5.

    Codex CLI: Included in ChatGPT Plus/Pro/Business plans (usage g

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

Codex CLI: Included in ChatGPT Plus/Pro/Business plans (usage governed by your plan’s limits), or pay-as-you-go on the API. GPT-5.3-Codex runs about $1.75 per million input / $14 per million output, with cheaper input on cached tokens. The mini model is far cheaper for light work.

The structural difference: Claude Code’s Max plans are flat-rate, which is why heavy users love them. People have tracked billions of tokens that would cost five figures on API metering but ran around a few hundred dollars on Max. Codex’s per-token rates are lower per unit and great if your usage is bursty or already bundled into a ChatGPT subscription, but a true all-day agent habit can run up metered cost faster than a flat plan. Estimate your monthly token volume honestly, then do the arithmetic both ways.

So which coding agent should you actually use?

Pick Claude Code if you want the deepest agentic workflow (subagents, hooks, skills), you are a heavy daily user who benefits from the flat-rate Max plan, or you need fine-grained, scriptable control over what the agent can do. It is the more complete operator’s harness in 2026.

Pick Codex CLI if you want lower per-token cost, you already pay for ChatGPT and want to use that allowance, you like the clean preset sandbox/approval model, or you simply prefer the GPT-5.x output style. It is lean, fast to stand up, and genuinely capable.

The move a lot of us make: run both. They are cheap relative to engineer time, they share MCP servers, and they have different failure modes. When one gets stuck in a loop on a hard bug, handing the same task to the other with fresh context often breaks the logjam. If you are weighing terminal agents against IDE-native ones, our Claude Code vs Cursor breakdown covers that axis.

Related on Tygart Media: Claude Code vs Cursor · Claude Code getting started · coding benchmarks.

Frequently asked questions

Is Claude Code or Codex CLI better for large refactors?

Claude Code tends to hold up better on long multi-file refactors, mostly because of subagents and hooks that keep context organized and catch mistakes deterministically. Codex can do it too, especially with GPT-5.5, but you lean harder on tight AGENTS.md instructions and approval gates.

Can I use Codex CLI without a ChatGPT subscription?

Yes. Run codex login with an OpenAI API key and you pay per token instead of through a ChatGPT plan. Same for Claude Code with an ANTHROPIC_API_KEY if you would rather meter than subscribe.

Do they work on Windows natively?

Both do in 2026. Claude Code runs in PowerShell (many operators still prefer WSL for cleaner paths), and Codex CLI has a native Windows installer plus a Windows sandbox with unelevated/elevated modes. Watch out for shells that mangle /tmp or C: style paths in arguments.

What is the single biggest difference?

Pricing structure and workflow depth. Claude Code offers flat-rate Max plans and a richer harness (subagents, hooks, skills); Codex offers lower per-token rates and a cleaner preset sandbox. Model quality is close enough that those two factors usually decide it.

Which model do they run by default?

Claude Code defaults to the legacy (still listed) Claude flagship (Opus 4.8 (legacy — still listed) as of June 2026, with Sonnet 4.6 (legacy — still listed) for everyday speed). Codex CLI recommends GPT-5.5 for complex work, with GPT-5.4-mini and GPT-5.3-Codex as alternatives

Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

. Switch in-session with /model or the -m flag.

How do I get either tool cited or surfaced by AI engines for my own docs?

That is a content question, not a tooling one. The same structure that makes this page answerable, short factual answers, question-shaped headers, and a visible FAQ, is what AI engines reward. See how AI engines cite content for the full playbook.

>Part of the complete guide: Claude vs the Field

  • Claude Code vs Cursor: Which AI Editor Wins in 2026?

    Claude Code vs Cursor: Which AI Editor Wins in 2026?

    Last verified: October 13, 2026.

    Claude Code and Cursor are the two tools most working developers actually reach for in 2026, and they are not the same kind of thing. Cursor is an AI-native code editor (a VS Code fork) where the model lives inside your IDE. Claude Code is a terminal agent that lives in your shell and edits files, runs commands, and drives git from the command line. This is the honest version: what each one is good at, what they cost right now, and a simple rule for picking.

    Claude Code vs Cursor: what is the actual difference?

    Side-by-side cards defining what Claude Code is and is not
    Claude Code vs Cursor — what is the actual difference?

    The short answer: Cursor is an editor you type in; Claude Code is an agent you delegate to. Cursor keeps you in the driver’s seat with autocomplete, inline edits, and a chat sidebar that sees your open files. Claude Code takes a goal and works the repo autonomously in the terminal, asking permission before it touches things.

    Dimension Claude Code Cursor
    Form factor Terminal CLI (plus IDE extension, web, desktop) Full IDE (VS Code fork)
    Primary loop Delegate a task, approve actions Type code, accept suggestions
    Models Claude only Multi-model: Grok included on higher tiers; Claude/GPT/Gemini at API list on Premium+
    Best at Multi-file refactors, scripted/headless runs, git workflows Tight edit loops, autocomplete, staying in one window
    Entry price $20/mo (Pro) or $17 annual Free limited / Plus $8 (Grok only) / Premium $30
    Billing model Usage windows (5-hour + weekly) Shared AI usage pool; third-party models at API list on Premium and above

    How does each one actually work?

    Five stacked panels of daily Claude Code command habits
    How each one actually works.

    Claude Code (terminal agent)

    You install it and run it from inside a project directory. Official claude.com copy: Claude Code is included in all paid Claude plans and shares the same usage pool as chat.

    npm install -g @anthropic-ai/claude-code
    cd my-project
    claude

    From there you talk to it in plain language. It reads files, proposes edits as diffs, and runs shell commands only after you approve them. Drop a CLAUDE.md in the repo root. Headless mode: claude -p "...".

    Cursor (AI IDE)

    Cursor is a download. Tab completion, inline edit, agent mode, and a model picker. Official cursor.com/pricing (checked October 13, 2026) lists Free, Plus $8/mo (Grok models only), Premium $30/mo (4x Plus; third-party models at API list price), Super $100/mo (15x), Ultra $200/mo (50x), Teams from $30+/user. Docs at cursor.com/docs/models-and-pricing still reference older Pro $20 / Pro+ $60 / Ultra $200 pools. Quote both; do not average.

    What does Claude Code cost in 2026?

    As of October 13, 2026, official claude.com / platform.claude.com:

    • Pro: $20/month, or $17/month billed annually ($200 up front). Includes Claude Code.
    • Max 5x: $100/month. 5x Pro usage. Includes $100/month API credits.
    • Max 20x: $200/month. 20x Pro usage. Includes $200/month API credits.
    • API: Haiku 5.5 $0.10 / $0.50 per MTok under 100k prompt tokens ($0.50 / $2.50 over); Sonnet 5.5 $2 / $10 with cache reads $0.10; Opus 5.5 $4 / $20 (cache read $0.20); Fable 5.1 $10 / $50 (cache read $0.25). Batch 50% off. US-only inference 1.1x on Claude 4.6+.

    There is a 5-hour rolling session window plus weekly limits on paid plans. Chat and Claude Code draw from one pool. Confirm in Settings > Usage.

    What does Cursor cost in 2026?

    • Free: Limited.
    • Plus: $8/month. Grok models only.
    • Premium: $30/month. 4x Plus usage. Third-party models (Claude, GPT, Gemini) at API list price.
    • Super: $100/month. 15x Plus.
    • Ultra: $200/month. 50x Plus. Earliest access.
    • Teams: From $30+/user/month.

    On the live pricing page, third-party model usage is not included in the monthly price and is billed separately at API list. Docs still describe older Pro/Pro+/Ultra usage pools for Cursor Models vs Other Models. Existing subscribers may keep prior plans.

    Which models do you actually get?

    • Claude Code is Claude-only.
    • Cursor includes Grok on Plus and above; Premium and higher add third-party models at API list price.

    Which one is better for big refactors and automation?

    Claude Code for repo-wide delegate work and headless claude -p runs. Cursor agent is strong inside the IDE; it is not a cron target.

    Which one is better for everyday coding flow?

    Cursor for most people who want tab completion and one window, especially if Grok covers the loop.

    Can you use both together?

    Yes. Common setup: Cursor as the editor, Claude Code in the integrated terminal. Claude Pro is $20; Cursor Premium is $30 if you need Claude models inside Cursor at API rates.

    Bottom line

    • Pick Claude Code if you want an autonomous terminal agent and you are happy with Claude as your one model. Entry is Pro at $20/$17.
    • Pick Cursor if you want autocomplete, Grok included, and a model picker. Entry for third-party is Premium at $30 plus API list.
    • Pick both if the seats are cheaper than the hours you lose switching contexts.

    FAQ

    Is Claude Code or Cursor cheaper?

    Claude Code starts at Pro $20/mo ($17 annual). Cursor Free is limited; Plus is $8 (Grok only); Premium is $30 with third-party models billed at API list on top. Claude Code meters by 5-hour plus weekly windows. Cursor meters a shared pool then on-demand / API list.

    Does Cursor use Claude?

    Yes, on Premium and above, at API list price (not included in the seat). You do not need a Claude Pro seat to use Claude models inside Cursor, but you pay the list rate for them.

    Related reading: Claude API rates · Claude Code vs Codex.

    Start here: Claude Code vs Cursor: Which AI Coding Tool is Better? — the full head-to-head comparison.

  • Claude Code vs Cursor in 2026: An Honest Comparison for Developers Who Ship

    Claude Code vs Cursor in 2026: An Honest Comparison for Developers Who Ship

    The conversation about Claude Code vs Cursor has collapsed into lazy takes: Claude Code is smarter, Cursor is friendlier, buy both. That framing is not wrong, but it isn’t useful. If you’re deciding where to put your coding tool budget in 2026, you need to know where each tool wins and loses – with specifics, not vibes.

    Here’s what a year of both tools in production actually looks like.

    The Fundamental Architecture Gap

    Side-by-side cards defining what Claude Code is and is not
    The fundamental architecture gap.

    Claude Code is a terminal-native CLI agent. You run it with claude in your shell, point it at a codebase, give it a task, and walk away. It has no GUI. It doesn’t autocomplete as you type. What it has is the ability to autonomously execute multi-step tasks – read files, write code, run tests, iterate on failures – without you babysitting it.

    Cursor is an IDE built on VS Code. It has tab autocomplete, an inline chat panel, Agent mode for longer tasks, and a polished visual interface that feels like VS Code with a superpower grafted on. If you already live in VS Code, Cursor’s learning curve is close to zero.

    These are genuinely different tools. The “which one wins” question should really be “which one wins for what.”

    Where Claude Code Wins: Long Autonomous Runs

    Five stacked panels of daily Claude Code command habits
    Where Claude Code wins — long autonomous runs.

    The biggest measurable advantage Claude Code has right now is context. Running on Claude Opus 4.6 or 4.7, Claude Code natively supports a 1 million token context window – and that’s a first-class, supported number with no per-token surcharge for long context on the API.

    Cursor’s advertised context is lower, and it draws from multiple model backends depending on which you select. On a large monorepo task – think refactoring an auth system across 40 files – the difference between context limits is the difference between Claude Code holding the whole codebase in view and the alternative having to page through it.

    Claude Opus 4.6 scores 80.84% on SWE-bench Verified, per Anthropic’s published system card. Opus 4.7 improved on that, particularly on the hardest problems in the benchmark set, and on Rakuten-SWE-Bench (a production-task evaluation, not just GitHub issues) it resolves 3x more tasks than Opus 4.6. That is a meaningful gap.

    The autonomous-run workflow looks like this in practice:

    claude "Refactor the payment module to use the new Stripe SDK, update all tests, and make sure existing integration tests still pass"

    Claude Code will read the relevant files, identify the Stripe version mismatch, write the new implementation, run your test suite, and iterate if something fails – often without a single follow-up prompt. That same task in Cursor’s Agent mode typically requires you to approve each file write and re-prompt when the agent stalls on an error.

    Where Cursor Wins: Daily Developer Experience

    Cursor’s tab autocomplete is genuinely good. It’s not a feature Claude Code has at all – Claude Code is not an IDE and doesn’t inject suggestions while you type. If your daily workflow is: open file, write code, open file, write code, Cursor is the better tool for that rhythm.

    Cursor’s @codebase reference and file mention system is also excellent for interactive exploration. You can ask “why does this function fail on null input?” while looking at the code, and Cursor’s inline context makes that conversation fast. Claude Code can answer the same question, but you’re doing it in a terminal with no visual reference.

    For teams on an existing GitHub workflow, GitHub Copilot’s deep integration with PRs, issues, and Actions is hard to match. If your team is standardized on GitHub and your security team needs IP indemnity coverage, Copilot is the defensible enterprise choice – Claude Code and Cursor both require more procurement work.

    The Pricing Reality

    Plan Monthly Cost
    Claude Code via Claude Pro $20/month
    Claude Code via Max 5x $100/month
    Claude Code via Max 20x $200/month
    Cursor Pro $20/month
    GitHub Copilot Individual $10/month

    The entry point is the same for Claude Code (via Claude Pro) and Cursor. At that tier, Claude Code’s usage limits are more restricted. The Max 5x plan at /month is where Claude Code becomes a full autonomous-agent platform – higher rate limits, Opus access, and Claude Code usage limits that are double the Pro tier.

    For individual developers doing heavy autonomous runs, the Max 5x plan at competes directly with a Cursor Pro subscription plus meaningful API spend. For teams, the calculus shifts: Cursor’s team plan pricing is lower per seat than a premium Claude Code subscription, which matters when you’re buying for 20 developers.

    The Honest Call

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    The honest call.

    Claude Code wins on: autonomous multi-step tasks, large codebase refactors, long-running agents, raw SWE-bench performance, and 1M token context on complex jobs.

    Cursor wins on: daily IDE experience, tab autocomplete, interactive inline chat, onboarding speed for VS Code users, and team-tier pricing.

    The recommendation most senior developers are landing on in 2026 is two tools: Cursor open in the background for interactive work, Claude Code for the tasks you used to put in a Jira ticket and wait two days for. If you can only buy one and you mostly write code file-by-file, get Cursor. If your bottleneck is “I need to refactor three services and I don’t have three days,” Claude Code is the one that changes your output.

    The Max 5x plan makes that bet financially coherent for a senior developer. The Pro tier is a reasonable way to find out if autonomous coding is a workflow you actually use.

    Frequently Asked Questions

    Is Claude Code better than Cursor in 2026?

    It depends on your workflow. Claude Code is a terminal-native CLI agent best for large codebase refactors, multi-file operations, and agentic tasks run from the command line. Cursor is an IDE-first editor with inline completions and a chat sidebar — better for continuous editing with visual feedback. Most developers who ship code daily use both rather than choosing.

    What is the difference between Claude Code and Cursor?

    Claude Code is a CLI tool you run with the ‘claude’ command in your terminal — it acts as an autonomous agent that can read, edit, and run files across a codebase. Cursor is a VS Code fork with AI completions and chat built into the editor interface. Claude Code suits agentic automation; Cursor suits interactive editing.

    Can I use Claude Code and Cursor at the same time?

    Yes. Many developers run Claude Code from the terminal for large refactors or test-writing sessions while keeping Cursor open for active editing. They complement each other: Claude Code for autonomous multi-step tasks, Cursor for line-by-line interactive work.

    How much does Claude Code cost in 2026?

    Claude Code usage is billed through your Anthropic API account against whichever Claude model you select. Claude Opus 4.8 (legacy — still listed) runs $5 per million input tokens and $25 per million output tokens. Claude Sonnet 4.6 (legacy — still listed) runs $3/$15 per million tokens. Claude Haiku 4.5 runs $1/$5 per million tokens. Cursor’s plans start around $20/month for Pro.

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    Does Cursor use Claude under the hood?

    Cursor supports multiple underlying models including Claude (Anthropic), GPT-4 (OpenAI), and others. You can select which model Cursor routes to in its settings. Claude Code, by contrast, is a dedicated Anthropic CLI tool that only runs on Anthropic’s Claude models.

    What is Claude Code best used for?

    Claude Code excels at large-scale codebase operations: refactoring across multiple files, writing comprehensive test suites, navigating unfamiliar codebases, and running agentic tasks that chain multiple steps. It is less suited for inline autocomplete as you type — Cursor is better at that.

  • Always Allow vs Allow Once: Claude Code’s Quiet Tell

    Always Allow vs Allow Once: Claude Code’s Quiet Tell

    The short version: In Claude Code, the prompt that asks whether to “Always Allow” or “Allow Once” isn’t really about security. It’s a question about your own systems. If you keep choosing Always Allow, the work is recurring — go build the automaton. If it’s honestly Allow Once, it’s a one-off — let it go instead of trying to remember it.

    I spend most of my day inside Claude Code, and a tiny piece of the interface has been living rent-free in my head. Every time the agent wants to run a command, edit a file, or hit an API, it stops and asks: Always Allow, or Allow Once?

    On the surface that’s a permission prompt. Click the box, move on. But after the hundredth time, I started to notice the choice was telling me something about how I actually work — and where I was leaving time on the table.

    “Always Allow” means: go build the automaton

    Side-by-side cards defining what Claude Code is and is not
    Always Allow means: go build the automaton.

    Always Allow vs Allow Once: quick reference

    Side-by-side when to use a script versus an agent
    Always Allow vs Allow Once — quick reference.
    SignalAlways AllowAllow Once
    Task typeRecurring, repeating workOne-off, situational
    Right responseBuild an automationLet it go — don’t memorize it
    Security posturePersistent permission for that tool+actionSingle-use, no persistent grant
    What it revealsA system worth buildingAn edge case not worth systemizing
    Risk if overusedBroad standing permissions accumulateMissed automation opportunity

    Here’s the pattern. If I find myself reaching for Always Allow, it’s because I’ve seen this exact action before. I’ll see it again. I trust it enough to stop being asked.

    That’s not a permission decision. That’s a build order.

    If an action is safe, repeatable, and I do it constantly, the right move isn’t to keep approving it forever — it’s to take it out of the prompt entirely. Turn it into a tool. Wrap it in a script. Register it as a skill. Put it on a cron so it runs whether I’m at the desk or not. The “Always Allow” click is the moment the work earns its own piece of infrastructure.

    Most people stop at the click. They grant the permission and feel productive because the friction went away. But friction that shows up every single day isn’t friction you should approve — it’s friction you should engineer out. Every “Always Allow” is a quiet little flag waving at you: this deserves to be an automaton.

    “Allow Once” means: let it go on purpose

    The other side is just as useful, and it’s the part people get wrong.

    When the honest answer is Allow Once — this is a weird one-off, I’m not going to do it again — the temptation is to write it down. Save the command. Add it to a doc. File it away just in case it ever comes back.

    Resist that. A one-off doesn’t deserve a permanent home in your memory or your system. The cost of storing it isn’t the disk space — it’s the upkeep. Every note you keep is something you now have to organize, search past, keep current, and trip over later. Knowledge you save but rarely touch quietly rots, and stale knowledge is worse than none.

    The way I think about it: it’s more fit to sift through the dirt than to re-sift the knowledge. If a one-off ever does come back, re-deriving it from scratch is cheap — you dig through the dirt once and you’re done. But re-sifting a giant pile of “just in case” notes, over and over, every time you go looking for the thing you actually need? That’s the expensive part. Forgetting a one-off on purpose is a feature, not a failure.

    Why re-deriving usually beats remembering

    This is really a question of economics, and it’s the same math whether you’re managing an AI agent or your own head.

    Storing knowledge has two costs people forget about: the cost to keep it accurate, and the cost to find the signal inside it later. A one-off has a low chance of ever being needed again, so the expected payoff of saving it is tiny — while the drag it adds to everything else you’ve stored is real and permanent. Recurring work is the opposite: high chance of reuse, so it’s worth paying once to encode it well and never think about it again.

    So the rule of thumb falls out on its own:

    • Recurring → encode it. Build the tool, the skill, the cron. Pay once, reuse forever.
    • One-off → forget it on purpose. Do the thing, then let it go. If it ever comes back, dig it up fresh — it’ll be faster than you think.

    The mistake is doing it backwards: hand-running the recurring stuff every day because you never built the automaton, while hoarding a graveyard of one-off notes you’ll never open again. That’s how you end up busy and buried at the same time.

    How to act on the tell in Claude Code

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How to act on the tell in Claude Code.

    Next time that prompt pops up, treat it as a tiny decision point instead of a speed bump:

    1. You reached for “Always Allow.” Stop for a second. Ask: what would it take to make this prompt never appear again? An orchestration step, a saved skill, a scheduled job, a hook? Put it on the list. The prompt just told you what to build next.
    2. You reached for “Allow Once.” Do it, then genuinely drop it. Don’t screenshot it, don’t file it. Trust that if it matters, it’ll show up again — and the second sighting is your real signal to build.
    3. You’re not sure. That’s fine — “Allow Once” is the safe default. Two or three “Allow Once” clicks for the same action is the universe telling you it was an “Always Allow” the whole time.

    None of this is really about Claude Code. The tool just happens to put the decision right in front of you, every day, in a little box. Most systems make you guess where your time is leaking. This one points at it and asks you to choose. (It pairs well with knowing when to use Plan Mode and when to skip it — same instinct, a different prompt.)

    Recurring work wants to become an automaton. One-off work wants to be forgotten. The prompt already knows which is which. The only question is whether you’re listening.

    Frequently asked questions

    What’s the difference between “Always Allow” and “Allow Once” in Claude Code?

    “Allow Once” approves a single action one time; the next identical action prompts you again. “Always Allow” approves that action or pattern going forward, so Claude Code stops asking. Functionally, “Always Allow” is how you tell the tool an action is safe and routine.

    Should I use “Always Allow” in Claude Code?

    Use it when an action is safe, repeatable, and something you do often — but treat each “Always Allow” as a signal to eventually build that action into a tool, skill, hook, or scheduled job so it leaves the prompt entirely.

    Is “Always Allow” a security risk?

    It can be if you grant it to broad or destructive actions. Keep “Always Allow” for narrow, well-understood operations, and lean on “Allow Once” for anything unfamiliar, destructive, or outward-facing.

    When should I turn a Claude Code action into an automation?

    When you’ve granted — or wanted to grant — “Always Allow” for it. That’s the tell that the work is recurring, and recurring, trusted work is worth encoding once as a tool, skill, hook, or cron so you never approve it by hand again.

    Why shouldn’t I save one-off commands?

    Because storing knowledge has ongoing costs — keeping it accurate, and sifting past it to find what you actually need. A one-off has little chance of reuse, so it’s usually cheaper to re-derive it later than to maintain it forever.

    What does “more fit to sift through the dirt than to re-sift the knowledge” mean?

    It means re-deriving a rarely-needed answer from scratch — sifting the dirt once — is cheaper than maintaining and repeatedly searching a hoard of saved notes, which is re-sifting the knowledge every time. For one-offs, forgetting is the efficient choice.

    Frequently Asked Questions

    What does ‘Always Allow’ mean in Claude Code?

    When Claude Code asks to run a tool or shell command, ‘Always Allow’ grants a persistent permission for that specific tool and action combination. Claude will not ask again for that combination in future sessions. ‘Allow Once’ grants permission only for the current request — Claude will ask again next time.

    Is it safe to click Always Allow in Claude Code?

    It depends on the action. Always Allow for read operations (reading files, querying a database) is generally low risk. Always Allow for write or execute operations (editing files, running shell commands) creates persistent permissions that compound over time. The best practice is to use Always Allow deliberately for actions you will genuinely repeat, and Allow Once for anything new or situational.

    What is the deeper meaning of Always Allow vs Allow Once?

    The choice is a signal about your own workflow. If you keep clicking Always Allow for the same action, that’s the system telling you the task is recurring and worth automating. If it’s genuinely Allow Once, the task is a one-off and you shouldn’t try to systemize it. The prompt is less about security and more about recognizing patterns in your own work.

    How do I review or remove Always Allow permissions in Claude Code?

    Run ‘claude permissions list’ to see what standing permissions you’ve granted. Use ‘claude permissions reset’ to clear them, or edit the .claude/settings.json file in your project directory to remove specific entries. Review these periodically — accumulated Always Allow grants are a common source of unexpected autonomous behavior.

    Does Always Allow apply to a specific project or globally?

    By default, permissions granted with Always Allow are scoped to the project where you granted them (stored in .claude/settings.json). If you use the –global flag, they apply across all projects. Be cautious with global Always Allow grants for write/execute operations — they persist across every codebase you open.