Tag: AI Agents

  • Your Site’s Next Visitor Sends an Agent. Tobira Wants Yours to Meet It.

    Your Site’s Next Visitor Sends an Agent. Tobira Wants Yours to Meet It.

    Ask your AI to do a simple errand: book a call with ten real companies you might buy from. Not research them. Book the call.

    Tobira’s founder, Vlad, ran that exact test before he built anything. He asked his Claude to book a call with 10 real companies. The result, in his launch account, was zero bookings and zero payments. The agent didn’t fail at reading. It failed at the last step — account walls it couldn’t pass, booking pages that block AI, and forms built for fingers and eyes.

    That zero-for-ten is the failure every small business is about to meet. More buyers research inside ChatGPT or Claude, and increasingly ask the same chat to take the next step: book the call, start the trial, place the order. Your site was built for the researcher, not the errand. If the errand dies at your form, you never learn the buyer was there.

    Tobira Site Agent is one vendor’s answer to that break. We have not tested it on our own sites — this is a desk read, built from Dirty Static’s guide to Tobira Site Agent, itself built from Tobira’s maker site and Product Hunt launch post, facts checked November 7, 2026. Where a number comes from Tobira, we say so.

    The clerk, not the brochure

    Most of what businesses have done for AI visitors so far is brochure work: clearer pages, structured content, files an agent can read. Necessary — and it’s the layer we already run. Tobira bets the brochure isn’t enough. A brochure can’t close. A clerk can.

    Tobira puts a site agent of your own on your website, one that lives there, answers questions, and sells — not just to people, but to the AI agents people send. Your site should not wait to be read by a visiting agent. It should send an agent of its own to meet it, answer it, and do the transaction.

    The job list is sales work, not trivia. Per the maker, the agent asks about the visitor’s case, suggests the option that fits, books the call, starts the trial, captures the lead, and sends a payment link — right inside the chat the visitor started in. Booking, trial starts, leads, and payment happen in that chat, not on a separate page. It can talk by voice, with a transcript, and answers in the visitor’s language. When a case gets hard, a person steps in with the chat context attached, so the human isn’t starting from zero.

    Two visitors, one site

    The mechanism is a split. People see your normal website. Visiting agents get a version made for them, built by your agent from your own content. Per the maker, your agent publishes the files agents look for — llms.txt, agent.json, and AGENTS.md — so a visiting agent reads the offer directly and talks to your agent, instead of scraping page after page.

    The token math is the quiet part of the pitch, and it’s a maker example, not a measurement. In Tobira’s worked example, a normal pricing page runs to about 120,000 tokens of page weight. The structured answer lands at about 1,300 tokens, which the company presents as 92 times fewer tokens. Treat that ratio as a company example, not a measured result for your site. Your pages are not their example page. The direction still makes sense: an agent handed the plan, the price, and the next open slot as clean data finishes faster than one guessing its way through your navigation.

    The guardrails are the real product

    A salesperson who improvises prices is worse than none, and a site agent is a salesperson. The important part of Tobira isn’t the booking trick — it’s three guardrails the maker describes.

    First, answers only from your own materials: your site, price lists, PDFs, and FAQs. If the answer isn’t there, the agent doesn’t guess. It offers a call instead. Second, it shares only what you made public. Pricing and plans you chose to publish can be public; internal notes and deal margins stay private. Third, a person steps in on hard cases, with context — the chat history goes to your team, so the buyer never starts over.

    Rules are set in plain words, per the maker — “price ranges only,” “no promised discounts.” If it works as described, the guardrails are the product. The chat is just where they show up.

    Setup and cost

    Setup, per the maker, starts with a scan: Tobira reads your site and builds the knowledge base from what it finds. You add documents, set tone and rules, and test it on the real questions buyers ask. Then it goes live as a badge or widget.

    How long? The founder says 10 minutes on Product Hunt; the product page says 2 minutes. Both are maker claims. The honest reading is minutes, not days — with the real work in checking what the scan learned before you trust it with prices.

    Pricing, maker site checked November 7, 2026, USD monthly before taxes: Free is $0 with your own AI key — Tobira’s fee is zero, the model bill is yours. Lite is $49, about 300 conversations. Start is $169. Business is $399, adding payments, your own branding with no Tobira badge, and voice up to about 1,500 minutes. Premium is $799, up to 3 sites, and on that tier Tobira keeps 15% of AI-subscription revenue. Paid plans carry a 14-day money-back guarantee, and the maker says a data processing agreement comes with paid plans, with data handled under GDPR.

    Free is a genuine test, not a stripped demo. Paid tiers climb fast.

    The network bet

    A site agent alone is a better shop window. Tobira also wants it to be a doorway into a market. Per the maker, your agent gets a public address in the Tobira network — an email-shaped handle, but for AI. When another company’s agent looks for what you offer, the two agents talk first and check fit. You get a qualified deal, or silence.

    The founder says the network holds more than 800 agents. That is a company figure, not audited, and a network is worth what its members are worth — from outside today you can’t tell a market from a list.

    Where this sits in our own house

    We’ve written this pattern before, from the other side. In October, after Kin’s WebMCP launch, we published “The Agent-Ready Site”: welcome the machine, structure the content, give the agent a way to act, measure what it does. Our fleet runs three of those four layers today. Our llms.txt has been live since October 2026, roughly 62% of our traffic is bots rather than people, and we measure the machine side with Bing’s citation exports.

    Tobira is what the unbuilt layer looks like when a vendor builds it for you. The missing layer was the third: give the agent a way to act. An llms.txt is the brochure on the door — it tells a visiting agent what you offer, in its own language. A site agent is the clerk behind it — it answers back, books, and takes payment. Same argument, next step. The pattern said structure your content for agents. Tobira’s bet is that the structure should be a salesperson.

    For the record: Tygart Media has not installed Tobira or run it on a client site. It’s a live commercial answer to a layer we know is missing.

    The two questions that decide it

    One: do your buyers send agents yet? The whole model depends on buyers asking their AI to book and buy, still a young habit. Every speed figure Tobira publishes — including its “2.2 times faster” claim — is founder-tested, not from an outside lab. If your customers still call and complete forms without trouble, a good booking page beats an agent you have to feed.

    Two: are your materials clean enough to be spoken aloud? An agent answering only from your materials is only as good as those materials. A stale price on a page is an embarrassment. A stale price spoken with confidence by your own agent, with a payment link attached, is worse than no agent at all.

    If your buyers already arrive through AI and die at the booking step, the free route is worth a real test. If they don’t, watch the habit and the network count, and keep your booking page in good shape. Guessing wrong about which one you’re in is the expensive option.

    The practice

    Run the founder’s test on yourself. Open the AI you actually use and ask it to book a call with your business — your real site, no help from you. Watch where it dies. If it books cleanly, your forms were never the wall; file this category under “later.” If it stalls at an account wall, a blocked page, or a form it can’t complete, you’ve just watched the exact failure Tobira is selling against — free, in ten minutes, on your own storefront.


    Want this thinking applied to your own business? Book a call with Will Tygart — 30 minutes, and we start from your receipts, not a pitch deck.
  • The Coding Ladder Says the Dial Pays. Our 52 Calls Said It Didn’t. Both Numbers Are Real.

    The Coding Ladder Says the Dial Pays. Our 52 Calls Said It Didn’t. Both Numbers Are Real.

    Yesterday we published a test: 52 calls to Muse Spark 1.3, seven kinds of work, every rung of the reasoning dial, everything scored against ground truth. Our result was not close. The cheapest setting never lost — and twice, extra thinking was the failure itself. We set the fleet’s operating rule on that evidence and moved on.

    Then a counter-check showed up, the way we’d want one to. BenchLeader — a third-party site that republishes benchmark results from their original publishers — carries a full rung-by-rung row for Muse Spark 1.3 on CursorBench, a coding benchmark. On that ladder, the dial pays at every single rung. If both results are real, they can’t both be the whole story. So we read the ladder the way we ran our own test: numbers first, bases stated, no vibes.

    The ladder’s numbers

    CursorBench, Muse Spark 1.3, as published on BenchLeader (data as of November 8, 2026; the underlying results are Cursor’s, dated September 2, 2026):

    Rung Tasks solved Rank on the board
    minimal 24.3% #79
    low 29.3% #72
    medium 32.6% #64
    high 33.4% #59
    xhigh 37.5% #48
    max 41.6% #38

    No rung regresses. Every step up solves more tasks than the step below it — +5.0 points from minimal to low, +3.3 to medium, +0.8 to high, +4.1 to xhigh, +4.1 to max. Across the whole ladder that’s +17.3 points: at max, the model solves roughly 1.7 times the share of coding tasks it solves at minimal. Ranks are among 82 model configurations with a published result on that benchmark.

    What is CursorBench? In BenchLeader’s words, it’s “Cursor’s internal coding-agent evaluation”: coding tasks run inside Cursor’s agent, with the reasoning level and cost per task recorded, scored as the percent of tasks solved. Two honest labels belong on it. It is published by a coding-tool vendor — BenchLeader itself flags “harness is theirs” — and BenchLeader carries it for reference only; it doesn’t count toward their composite index. It is still the only rung-by-rung coding evidence for this model that we know of, and it points the opposite way from ours.

    Our numbers, on the record

    Our battery was 52 API calls to the contributor tier of Muse Spark 1.3, November 6–7, 2026, identical prompts at multiple settings, mechanical scoring. The buyer-brief judgment task scored identically at every rung — minimal got it for 776 reasoning tokens and 6.5 seconds, xhigh for 6,847 tokens and 50 seconds. Verdicts at scale: 120 out of 120 at low, 120 out of 120 at xhigh. Planning: provably optimal schedules at every rung.

    And the coding cell — the one this ladder speaks to directly. Our debugging task was one function with three planted bugs. Every rung found the inverted discount logic and the rounding bug; the cheapest setting found all three. One xhigh call spent its entire 8,000-token budget thinking — 7,998 reasoning tokens — and returned an empty answer. It thought so long it never spoke. Minimal answered the same task correctly with 500 reasoning tokens.

    Our published conclusion: on our work, extra reasoning bought latency, not quality, and the operating rule became low by default, with xhigh and max earned only by a demonstrated failure at low.

    Both numbers are real. The tasks aren’t the same.

    Put the two bases side by side and the disagreement gets smaller and more specific:

    • Task shape. CursorBench runs coding tasks inside an agent — sustained, multi-step work where the model plans, acts, reads errors, and recovers over many turns. Our battery was single API calls with a checkable answer. Our one coding task was a single function, solved — or stalled on — in one shot.
    • Tier and harness. The ladder ran Spark 1.3 inside Cursor in September. We ran the contributor tier through the API in November.
    • Measurement. The ladder reports the percent of a task set solved. We scored one sample per cell against ground truth — a limit we printed in the original piece.

    Here is our reasoning, labeled as reasoning and not as either source’s claim: the reconciler is task shape. On a short, bounded task with a checkable answer, the first think is the one that does the work; rungs above it buy patience-testing latency, and occasionally a stall. On a long agent run — hold a codebase in mind, take twenty steps, survive your own mistakes — extra reasoning has something real to chew on, and the ladder pays for it. That reading fits the anomaly we flagged in our own data: the rungs behaved like task-shaped budgets, not fixed ceilings. It also fits the limit we printed: we never tested sustained work. CursorBench did — or rather, Cursor did.

    What would change the verdict

    Not an argument. A run. The test that settles this for our shop is our own coding work at every rung: real work-order-shaped jobs — a written spec, more than one file, a module plus a test suite with a mechanical pass/fail — at minimal, low, high and max, in one harness, more than one sample per cell, receipts published the way the first battery’s were. If low matches max on those, our rule stands for coding too, and the ladder is a story about Cursor’s harness. If max pulls away as the jobs get longer, the rule gets a carve-out: the rung follows the length of the task. Either result is publishable. We’ll run it and print what we find.

    The bottom line for an operator

    If your work is short, bounded calls — extraction, checking, verdicts, drafting to spec — run low. We have 52 metered calls that say the expensive rungs buy you nothing there, and our default hasn’t changed.

    If your work is a coding agent chewing through real jobs, the only rung-by-rung evidence that exists says turn it up: on Cursor’s own ladder, max solves 41.6% of tasks against minimal’s 24.3%, and every rung between them earns its step. That evidence is a vendor’s, run in the vendor’s harness, on September’s model build — hold it at that weight, not more.

    The mistake isn’t picking the wrong rung. It’s running one default across both shapes of work and calling it a policy. The dial is real. What it pays for depends on the length of the job in front of it — and now there are two published result sets, ours and Cursor’s, that say exactly that from opposite ends.

    Sources: BenchLeader, “Muse Spark 1.3” model page and CursorBench leaderboard (data as of November 8, 2026; CursorBench results published by Cursor via the Epoch AI Benchmarking Hub, Spark 1.3 results dated September 2, 2026). Our dial test: “We Ran Muse Spark’s Reasoning Dial Through 52 Calls. The Cheapest Setting Never Lost.” (Tygart Media, November 7, 2026), method and receipts in the Tygart-OS fact-gated fleet record on GitHub.


    Want this thinking applied to your own work? Book a call with Will Tygart — 30 minutes, and we start from your receipts, not a pitch deck.
  • The Carrier Moved Into ChatGPT: MGT’s Aimee, Mapped Against the Wisdom Trust

    The Carrier Moved Into ChatGPT: MGT’s Aimee, Mapped Against the Wisdom Trust

    On November 5, 2026, MGT Insurance — a full-stack commercial carrier — listed its AI quoting assistant, Aimee, in the ChatGPT app directories and opened its MCP, so appointed brokers can quote a business policy by typing a sentence. This is a mapping: the new model read against the Wisdom Trust — our open kit for capturing elders’ life stories, and its paid human sibling, the Wisdom Manager. Two earlier mappings in this series read NHS Life Stories (October 18, 2026) and LifeBio’s Engagement Services (October 24, 2026) the same way. Where MGT’s public pages are silent, this says so rather than guessing.

    The two things, in one paragraph each

    MGT / Aimee. MGT is a full-stack, licensed commercial P&C carrier — an “AI-native neo-insurer” (A- rated by AM Best, per its release) that owns its product, its platform, and its risk, selling small-business cover (today: Business Owner’s Policy, 300+ business classes across 43 states and D.C.) through independent agents. Aimee is its broker-facing AI agent: since 2025 she has answered appetite questions on mgtinsurance.com with no sign-in; on October 16, 2026 MGT became, by its own claim, the first carrier to offer chat-based quoting — an agent describes a business in plain language (or uploads an ACORD application) inside ChatGPT or Claude and gets a real rate; on November 5, 2026 the integration was listed in the ChatGPT app directories, with MGT “opening up our MCP so brokers can quote where they already work.” Aimee classifies the business, checks MGT’s appetite, asks only for what is missing, prices the quote, and — the load-bearing detail — “tells the agent what she assumed and why.” Every quote then opens in MGT’s own portal, where the human agent reviews it and binds. MGT’s platform numbers ($83B of quoted TIV, nearly 15,000 appointed agents) are the company’s own, printed in its release; trade coverage notes MGT has not disclosed how many agents use the ChatGPT channel, what time it saves per quote, or what volume has bound through it.

    Wisdom Trust (Will). Two related things. The kit: an open-source starter set (MIT, explicitly “a seed, not a product”) for capturing retirement-facility residents’ life stories — one emailed question per week, answered by voice through a single link with no account, curated by an AI pipeline into a family-owned collection, framed as inheritance (“a life documented like a 401k left behind”). The storyteller owns the material outright; the machine’s outputs are drafts for human approval; nothing outward is ever auto-sent. The Wisdom Manager: a sketch for a paid human service — part curator, part oral historian, part creative director — that turns a family’s scattered media into a living collection through a gated process (private intake → curator review → owner approval → presentation), priced from ~$1,000 guided products to $20,000+ commissions. Both halves are built to be run by the people they serve; neither is published as a tool inside a platform somebody else owns.


    Side by side

    Dimension MGT / Aimee Wisdom Trust (kit + Wisdom Manager)
    Capture prompts / structure Appetite-first. Before any full submission, Aimee gives a real-time read on whether a class/state fits MGT’s appetite (the published Appetite Guide covers 300+ classes with NAICS groupings). In a quote she classifies the business, checks appetite, then asks only for what’s missing — the structure is the carrier’s underwriting rules, proprietary, applied conversationally. The prompt surface is whatever the agent types: a sentence, pasted call notes, an uploaded ACORD. A fixed library of 40 written questions across a life, one sent per week, skippable at will; the pipeline’s final stage (“Notice Gaps”) reads the collection and generates the next questions from what’s missing. The “asks only for what’s missing” discipline exists in his design too — but at stage 8 of the pipeline, after collection, not at the front door before it.
    Media types Plain-language text and documents: typed descriptions, pasted call notes, uploaded ACORD applications and supporting files, which Aimee “turns into a quote, flagging any values worth confirming.” Voice-first. A spoken (or typed) answer in a chat, 20+ languages, transcribed verbatim then cleaned; the pipeline can render artifacts back out — image, music, video, voice — each labeled with what it is, what it is not, and why it was made. The Wisdom Manager side curates media a family already has.
    Who does the capturing The machine, employed by the carrier. Aimee does the data entry, classification, appetite check, and pricing; a second agent (Athena, per MGT’s own essay) has made end-to-end underwriting decisions “with no human input.” The human in the loop is the broker — a professional intermediary — who reviews the finished quote in the portal and binds. The insured business is described, not consulted. The elder answers alone, by link; a family archivist or staff champion sends the question; staff are guides, not interviewers. The machine curates, but every outward artifact is a draft for owner approval — nothing auto-sends, ever. Both models keep a human gate before the consequential act; the gatekeepers differ (a licensed broker binding cover vs. the owner of the material approving its use), and so does whom the machine works for.
    Entry / onboarding Two doors, deliberately tiered. The appetite door is open to anyone — “you can still chat with Aimee about appetite, with no sign-in required.” The quoting door requires an MGT appointment (a broker contract) and signing in with MGT credentials inside ChatGPT/Claude; appointment itself is a sales process (mgtinsurance.com/get-appointed). Once appointed, the friction claim is real: “They don’t need another form or another login” — the quote starts inside the assistant the agent already uses. One link, no app, no account, no password — a stated non-negotiable: “If the storyteller has to install anything, the design failed.” Consent is signed before the pilot starts; there is no tiered front door — no way to feel the thing, saving nothing, before the consent conversation. The friction didn’t move to procurement as with LifeBio; there is no procurement. But there is also no anonymous first touch.
    Who the finished work serves, and where Three beneficiaries: the broker (time back — the scarcest resource in MGT’s own framing), the small business (a bound policy it never had to fill in a form for), and MGT (distribution into the rooms where brokers already work, plus appetite-consistent risk selection). The finished work lives in MGT’s portal — the quote opens there, is reviewed there, binds there. The ChatGPT surface is the front step; custody of the record stays with the carrier. Serves the family and descendants: an heirloom — stories, timeline, quote cards, people/places index, a weekly family letter, a gallery page. The facility’s benefit is real but secondary and reputational. The finished work lives wherever the family keeps its collection — the kit’s whole custody posture is that the platform is a shelf, not an owner. The Wisdom Manager serves the paying family directly, owner-approved before anything is shown.
    Consent / custody / ownership The public documents are website-era documents, and the ownership check shows it (quotes below). The privacy policy (last updated Oct 21, 2026 — two weeks before the ChatGPT listing) never names Aimee, ChatGPT, Claude, or MCP, states no retention period, and contains no mention of training (verified by full-text search of the published page: zero hits for “Aimee,” “train,” “retain”). It reserves broad improvement purposes over submitted information: personal data may be used for “Auditing, research, and analysis in order to maintain, protect, and improve our services,” “Developing new services,” “To model our risks,” and “To make our products and services better”; “We may combine the information submitted under various forms and services… to improve the quality of our services.” It does state “We do not sell Personal Information.” The website terms contain no license grant over user-submitted content at all — nothing equivalent to LifeBio’s AI-training licence, in either direction — and on termination say only that MGT may terminate the account “at any time and for any reason”; what happens to a broker’s submitted data or quote history on termination is not addressed. No designee or succession concept exists in either public document. The operative broker terms (appointment agreement, portal terms, MCP-channel terms) sit behind the appointment process and are not public. One more custody layer is new with this launch: a submission made inside ChatGPT also passes through OpenAI’s platform, under OpenAI’s terms — the chain now has two companies in it before the carrier’s own documents even apply. The most heavily specified layer of the kit. A plain-language consent: the elder owns their stories, period; access only by the elder’s grant (family included — not by default); grant and revoke at will; delete permanently and immediately; never sold; voice never used to train products without separate written permission; a designated person decides after death, defaulting to deletion after 12 months if none is named. “The facility’s role is shelf, not owner.” The Wisdom Manager carries the same posture into the paid service: safety gates (private intake → curator review → owner approval → presentation) are “part of the product.”
    Output format A priced, reviewable quote — a real rate, not an estimate — carrying an assumption statement (“what she assumed and why”), which opens in the MGT portal for review and binding into a policy. The assumption statement is part of the output object, not a disclaimer under it. A structured collection, not a single object: raw + cleaned transcripts, story records, timeline, quote cards, people/places index, weekly digest letter (draft), gallery page (draft), and labeled generated artifacts — all in JSON buckets any future AI can re-render. Artifacts carry provenance labels (what it is, what it is not, why it was made); nothing in the kit attaches an assumptions record — what the machine inferred where the storyteller didn’t say — to any output.
    Institutional / commercial model A regulated company selling risk: a licensed, full-stack carrier that monetises bound premium. The AI channel itself carries no published price — it rides on the broker appointment (contract terms not public; no figures published for the channel). Appetite spans 300+ classes in 43 states + D.C. (Florida and Hawaii excluded; five states listed as coming soon). The MCP is opened free, as distribution: the quoting engine is the marketing. Note what trade coverage could not find either: no disclosed user counts, time-saved, or bound volume for the new channel — the launch is measured in platform totals, not channel outcomes. Deliberately not an institution and not a company: an MIT-licensed seed its author declines to operate (“I’m not going to be the gardener on this one”). The commercial sibling, the Wisdom Manager, is priced as independent practice — role-hour maths, ~$1,000 guided products to $20,000+ commissions, family pays. Neither side of his model publishes anything into someone else’s platform or charges by distribution; there is no channel, only a kit people pick up.

    The door moves: an open MCP, and the product stops being a destination

    NHS Life Stories is a place you go and build. LifeBio is a person who comes to you. MGT’s Aimee is neither: the product dissolves into whatever assistant the broker already has open. By listing in the ChatGPT directories and opening its MCP, MGT stopped asking brokers to visit a destination and instead published its quoting engine as a callable tool — any MCP-capable assistant (ChatGPT, Claude, and next, the broker’s own in-house agents) can invoke the carrier mid-conversation. That is a distribution mechanism neither earlier mapping has, and it inverts the kit’s founding move in an instructive way: his one-link flow deletes the destination for the storyteller (no app, no account — the capture comes to the elder). MGT deletes the destination for the professional — the capture comes to where the broker already works, and the broker’s own AI can be the one calling. What it buys:

    • Distribution without a destination. The directory listing is the shelf space. A carrier that can be quoted “by typing a sentence” competes inside every conversation a broker has, not inside a portal tab the broker must remember to open.
    • Agent-to-agent quoting becomes possible. Once the engine is a tool, the caller doesn’t have to be a human typing — a broker’s own agent, working a renewal list overnight, can call Aimee the same way. MGT says this plainly: the engine “was designed from day one to be called by agents, human and AI.”
    • The assumption statement is the trust patch that makes it viable. Moving quoting into a chat window removes the form’s forced precision; Aimee’s answer is to ship her assumptions with the quote and ask instead of guessing when something is missing. Speed is the pitch; stated assumptions are what let a professional rely on it.

    And what it costs, in terms his files would price honestly:

    • The surface is no longer theirs. Inside ChatGPT, MGT’s product renders under OpenAI’s chrome, beside competitors one directory row away, under a second company’s terms. The carrier traded a destination it controls for reach it rents.
    • The custody chain lengthens exactly where the documents are thinnest. A broker’s submission now passes a platform company’s terms before it reaches a carrier whose own public privacy policy never mentions the channel exists (see the ownership row). The mechanism is new; the paperwork is a website policy last updated before the listing.
    • “Open” is doing quiet work. No public developer documentation, endpoint, or tool specification for the MCP appears on the pages read — the openness is a listing, granted to appointed agents through two named platforms, not a published interface anyone can build on. It is an open door into a closed house: the engine, the appetite, and the submission data stay proprietary.

    What the Wisdom Trust could borrow

    1. An assumption ledger on every machine-made artifact. Aimee ships “what she assumed and why” with every quote. His artifacts carry provenance labels (what it is, what it is not, why it was made) but no record of what the machine inferred — which date it guessed for an undated story, which “Uncle Ray” it merged with which. Adding an assumptions array to the schemas (each entry: the inference, the evidence, a confirm/correct affordance for the owner) turns stage 4’s silent enrichment into something the family can audit — and it is the same fact-gating instinct his fleet work already runs on, applied to the kit.
    2. A two-tier front door: a no-save taste before the consent conversation. MGT’s appetite chat is open to anyone with no sign-in; only quoting requires the contract. The kit has one door, and it’s paperwork. A public “answer one question, nothing is kept” demo — one joy prompt, answered by voice, wiped when the tab closes — would let a family feel the thing before anyone signs anything, and would give facilities a tour artefact stronger than the one-pager. The consent template stays exactly as strict; the door in front of it gets lighter.
    3. Appetite before paperwork, as a designed step. Aimee checks fit before collecting anything and asks only for what’s missing. His pilot’s first act is consent; a two-minute fit conversation (does she want to talk about her life? joy-first or wisdom-first? who should hold the collection?) before the forms would put the kit’s existing gap-noticing discipline at the front of the flow instead of only at stage 8.
    4. Publish the kit’s functions as a callable tool, not only a link. The kit’s automation README is already a plug-in contract an AI can execute — the seed of an MCP-shaped door. MGT’s move shows the distribution value of finishing that thought: a family archivist’s own assistant could invoke “this week’s question” and “file this answer” as tools, meeting the archivist inside the assistant they already use, exactly as Aimee meets the broker inside theirs. The one-link flow stays for the elder; the archivist gets a second door.

    What his does differently, on purpose

    1. Ownership is answered in advance, in plain language — here the contrast is silence plus reservation. Against LifeBio, his template differed from stated terms (a training licence, discard on termination). Against MGT, the public terms state almost nothing about submitted content — no training licence is taken, which is genuinely better — but broad improvement and risk-modelling purposes are reserved over whatever is submitted, the channel itself is never mentioned in the privacy policy, and the documents that would settle the quoting channel’s ownership questions are contract-side and unpublished. His template answers every one of those questions before the first recording: whose it is, who may hear it, what happens when the relationship ends, who decides after death.
    2. Whom the machine works for. Aimee’s appetite is MGT’s appetite; she quotes one carrier’s product and her assumptions serve the carrier’s risk selection as much as the broker’s convenience. His pipeline works for the elder and family — its drafts wait for the owner’s approval, and its gap-finding serves the collection, not a seller. Both keep a human gate before the consequential act; the difference is whose human, and whose interest the machine was built to advance when the two diverge.
    3. Openness of the artifact vs. openness of the interface. His kit is open all the way down — MIT, forkable, schemas published. MGT’s openness stops at the interface: the MCP is listed and callable (by appointed agents, on named platforms), while the engine, the appetite logic, and everything submitted stay inside. Neither is a pose; they are opposite answers to “what do you give away to get distribution?” — he gives away the machine and keeps no channel; MGT keeps the machine and gives away the doorway.

    What he would likely reject, per his own files

    • Reserved improvement/modelling use of submissions as a standing term. His consent template promises: never sold, never used to train products without separate written permission, access only by the elder’s grant. MGT’s privacy policy reserves using submitted information to “improve our services,” “develop new products and services,” and “model our risks,” with an opt-out mechanism that applies to new purposes via a contact page. Risk modelling is ordinary, legitimate insurance practice — and it is still exactly the shape of clause his template exists to refuse: purposes named by the holder, changeable by the holder, consent handled as opt-out.
    • Changeable-at-will terms. The website terms “may be changed, modified, supplemented, or updated at any time, with or without advance notice,” with continued use counting as acceptance. His consent is a signed, plain-language document the elder can revoke at will; the terms of the relationship are not a web page one side edits.
    • A persona users mistake for a person. His pipeline labels every generated artifact with what it is and what it is NOT. MGT’s own essay reports, approvingly enough to print, that Aimee’s “users thank her and ask her to start their quotes, most of them not realizing she’s an AI” (the essay’s title is “They Don’t Know It’s an AI Bot”; MGT, to its credit, says it would rather answer the question in public than dodge it). Per his labeling rule, an assistant a user can’t tell is a machine is a disclosure defect, not a delight metric.
    • Credentials inside a third party’s surface as the consequential door. Quoting requires signing in with MGT credentials inside ChatGPT/Claude — the broker’s carrier login now lives in a platform the carrier doesn’t control. His non-negotiable deletes accounts and passwords for the person at the centre of the capture. (Nuance, noted in the table: the appetite door is credential-free — the tiering itself is borrowable #2.)

    Gaps in his own files (marked, not filled)

    • No machine-callable surface. His files describe a kit humans run and a pipeline an AI runs on the back end — but nothing about publishing the kit’s functions as tools other assistants can call, being listed anywhere, or distribution through a platform’s directory. MGT’s whole launch is that surface. The automation README is the seed of it; the discovery/distribution question is unasked in his files.
    • No assumption ledger. His stages enrich silently: dates inferred, people merged, gaps noticed — but no output carries what the machine assumed and why, in a form the owner can confirm or correct. Aimee’s quote does. (Borrowable #1 names the fix; this entry marks the silence.)
    • No eligibility step before collection. His pilot opens with consent paperwork and a 10-resident scope; nothing first asks fit — does this resident want this, which track, joy-first or wisdom-first — the way appetite precedes a quote. The appetite conversation is two minutes and saves the paperwork for people it fits.
    • The dementia silence, third mapping running (carried from NHS Life Stories, repeated in the LifeBio mapping, still open). Aimee exposes nothing here — commercial quoting is not its territory — but the standing instruction of this series is that a repeated silence gets named as repeated: his question library still assumes a storyteller who can sit with an abstraction, and no mapping since has closed it.
    • Custodian succession. His consent template settles what happens when the elder dies (a designated person decides). It does not settle what happens if the shelf changes hands — the facility is sold, the keeper of the vault exits. MGT’s privacy policy at least names the asset-sale transfer case for its side; his files leave the equivalent case unaddressed.

    Could not verify from public pages (MGT side)

    • The operative broker terms. The appointment agreement, the portal terms, and any terms specific to the MCP/directory channel sit behind the appointment process and are not public. The ownership questions for the quoting channel itself — who owns a submitted ACORD and the data extracted from it, whether it trains models, what happens to submission history when an appointment ends — are therefore unverified: the documents exist but are contract-side, not published. The public website terms and privacy policy were read in full and are silent on each.
    • What the “open MCP” technically is. No public developer documentation, endpoint, tool list, or authentication spec for the MCP was found on the pages read. “Open” is established as a distribution claim (listed in the directories, callable from ChatGPT and Claude), not as published developer access.
    • The second platform’s terms. Data submitted through the ChatGPT (or Claude) surface also passes under OpenAI’s (or Anthropic’s) terms for directory apps. Those terms were not read for this mapping, so the full custody chain of a broker’s submission is unverified at the platform layer.
    • The headline numbers. $83B quoted TIV, “nearly 15,000 appointed agents,” the “A-” AM Best rating, and “first carrier” are MGT’s own claims from its release and site. Trade coverage (GlobalFinTechEdge) narrows “first” to a carrier-specific quoting integration and records that MGT has not disclosed active ChatGPT-channel users, average time saved per quote, or policies bound through the channel.
    • Quote performance. No independent source on how often Aimee’s quotes bind as priced, how her classifications hold up, or how assumption statements read in the live ChatGPT surface (no transcript was available; the one concrete premium — $2,740/yr for a Sacramento bakery BOP — comes from MGT’s own demo video).
    • Athena’s end-to-end underwriting. The claim that an AI underwriting agent decided a case with no human input, “and got it right,” is from MGT’s own essay; no external account exists on the pages read.
    • Whether Aimee identifies herself as an AI in the quoting surfaces. MGT’s essay title and text (“users thank her… most of them not realizing she’s an AI”) describe the website agent; the disclosure behaviour of the ChatGPT/Claude listing itself was not observable from public pages.

    Sources

    • The occasion — Insurance Edge republication of the release (Nov 6, 2026): https://insurance-edge.net/2026/11/06/us-news-mgts-aimee-ai-assistant-now-listed-in-chatgpt-directories/
    • Original release (Business Wire, Nov 5, 2026): https://www.businesswire.com/news/home/20261105657905/en/MGT-Becomes-First-Insurance-Carrier-to-Bring-ChatGPT-Quoting-to-Independent-Agents
    • MGT — first carrier to offer chat-based quoting (three ways to quote; portal review before bind): https://www.mgtinsurance.com/blog/first-carrier-chat-based-quoting-independent-agents
    • MGT — how AI underwriting cuts quote time (Aimee in ChatGPT/Claude/portal; appetite with no sign-in): https://www.mgtinsurance.com/blog/how-ai-underwriting-cuts-quote-time-for-independent-agents
    • MGT — BOP appetite page (300+ classes; states covered/excluded): https://www.mgtinsurance.com/appetite
    • MGT — “The Neo-Insurer Bet” essay (Athena; “They Don’t Know It’s an AI Bot”; the disclosure question): https://www.mgtinsurance.com/blog/the-neo-insurer-bet
    • Trade coverage noting the undisclosed channel metrics and the narrow reading of “first” (GlobalFinTechEdge, Nov 2026): https://globalfintechedge.com/news/mgt-brings-ai-insurance-quoting-assistant-to-chatgpt/
    • InsureWire distribution tracker (Oct 16, 2026 announcement entry): https://insurewire.org/digital-insurer/agents-distribution/
    • Privacy policy (last updated Oct 21, 2026 — read in full; findings quoted above): https://www.mgtinsurance.com/privacy-policy
    • Website terms & conditions (read in full): https://www.mgtinsurance.com/terms-conditions
    • The Wisdom Trust kit and the Wisdom Manager service sketch — Tygart Media working papers; the two earlier mappings in this series are dated October 18 and October 24, 2026.
  • You Learn to Cook When You Have No Money

    You Learn to Cook When You Have No Money

    Stop blaming the token limit

    Every time an AI tool tightens a rate limit, the same crowd shows up to complain about it. The bot got slower. The bot cut me off. The bot won’t let me do what I was doing.

    Here’s a question nobody asks them: what were you doing?

    Because most of the time, the answer is nothing. Testing it. Poking it. Making it write a poem about your cat, summarize a video you were never going to watch, argue with it for forty minutes to see if it breaks. That’s not work. That’s burning reps on stupid shit and then complaining the gym is too small.

    Token limits aren’t the problem. Usage discipline is. And the people crying the loudest about limits are usually the people who never had any.

    Treat it like a gym, or don’t go

    An AI model is either a gym or an expensive tool, depending on how you treat it. It is not a toy.

    You don’t blame the gym because you did curls for three hours and your arms hurt. You show up with a plan. You do the work that’s actually on the program. You rack the weights and you go home. A table saw works the same way — it doesn’t care about your feelings, it rewards the person who measured twice and punishes the one who was playing around near the blade.

    AI is the same. Every session should start with a reason. Every call should buy something: a decision, a draft, a number you can check. If you can’t say what a run bought you, you weren’t working out. You were hanging out at the gym.

    Scarcity is the teacher

    You learn to cook when you have no money.

    When the pantry is almost empty, every ingredient has a job. You stop wasting cuts. You learn what heat actually does. Rich kitchens produce lazy cooks; empty ones produce good ones — if the cook cares enough to learn.

    Tokens are ingredients. When they feel unlimited, people cook like it: giant prompts with no point, five agents doing what one careful prompt would do, whole afternoons spent “exploring.” When every call costs you something — money, quota, time on a clock — your prompts get honest in a hurry.

    I know what mine buy. Last week I shipped a working agent system into a national hackathon on a $153 budget and spent $102.50 of it, every single call logged. This morning a research run I use cost under two cents and came back with a ranked answer I could act on. That’s not being cheap. That’s knowing the price of everything I asked for. Discipline isn’t deprivation — it’s receipts.

    A nearly empty pantry and a cook making a real meal from almost nothing

    The commute is the session

    Here’s how I’d actually run it, and it’s the whole philosophy in one picture.

    Buy a Tesla. Install the bot. Grok lives in the car — and only in the car.

    I live in Puyallup. The day job, the in-office days, are up in Bellevue. That’s a real drive, and a self-driving car turns it into the best office I’ll ever have: nobody interrupts a commute. The drive in is the Jarvis session. Run the side businesses. Clear the decisions that piled up overnight. Plan the day out loud while the car does the driving. If Tony Stark had ever given Pepper a suit, this is what she’d have done with the flight time — run the company from inside it.

    The drive home is the debrief. What got done, what’s open, what’s tomorrow. Then the car parks, and the session is over.

    You don’t sit in your car in the driveway and watch the football game. You go in your house.

    That’s the part people miss. The commute works as a session because it ends. Forty-five minutes of total focus with a wall around it beats nine hours of AI open in a tab while you half-watch your life go by. Sparingly isn’t a restriction. Sparingly is the design.

    A car parked in a driveway at dusk while the driver walks toward a warm-lit house

    Stop testing it like a macro

    And stop testing AI like it’s just a macro. This shit is more than that.

    A macro does the same thing every time and tells you nothing. Poking a model with toy questions tells you what it does in a toy situation, and then people act surprised when production behaves differently. You learn a tool by putting weight on it — real work, real stakes, a customer on the other end of the output. Every real thing I’ve learned about these systems, I learned from a run that mattered, under a limit that forced me to mean it.

    So no, the rate limit isn’t stealing your productivity. It’s offering you a program. Most people just don’t want to train.

    The limit is the workout

    Here’s the whole thing in one line: the limit isn’t the wall. The limit is the workout.

    The people who learn to cook with nothing in the pantry end up eating better than the people with a full fridge and no discipline — because skill compounds and quota doesn’t. Give the disciplined operator a bigger limit later and it’s terrifying. Give the complainer a bigger limit today and he’ll just run out faster, louder.

    Buy the car. Install the bot. Use the drive. Then go in the house.


    More from the operator desk: Slack Is the Last Mile — the hopper, and why the last step of every system is a person. And if you want the receipts live: I’m teaching the citation system behind all of this in a free session series, November 9–17 — the AEO sessions hub has the schedule and the question form.

  • How We Qualify Contractor Leads With AI: The Intake Matrix

    How We Qualify Contractor Leads With AI: The Intake Matrix

    How can AI automatically qualify contractor leads?

    Short answer, and it is the whole article: the AI does not qualify the lead. It collects the facts qualification runs on — the same questions, in the same order, at 2 a.m. exactly the way they run at 10 a.m. — and it stops where judgment starts. Qualification questions are not qualification judgment, and the difference is the entire ballgame. The questions collect facts. The judgment decides what the facts mean: is this a job we want — at this size, this distance, for this payer, with the crews already buried?

    That distinction is what makes the automation worth having. A flooded kitchen ten minutes away and a “come look at a stain” forty minutes out both answer the questions perfectly. Only one of them should get your Saturday. The matrix below is how we draw that line before a human ever picks up the phone.

    The intake matrix: six facts, in order

    Every inbound call and form runs through the same six gates. Each gate is a fact, not an opinion, and each one exists because it changes what happens next.

    1. Territory. Where is the job, exactly? Distance is the first filter because it is the one an unsupervised agent gets wrong first — nothing about a polite conversation tells a model that forty minutes each way eats the margin. The address gets captured and checked against the service area before anything is booked.

    2. Trade and scope. What happened, in the caller’s words? Water, fire, mold, storm — and what they can already see: standing water, a burst line, a smell, a stain. The intake records the problem as described; it does not diagnose. Scope facts decide who the lead routes to and how fast.

    3. Size signals. How big is it likely to be — one room or the whole floor, home or commercial space, occupied or empty? Size is a fact the caller usually knows and an agent can ask without pretending to estimate. Nobody quotes anything at intake. Size just tells the human what kind of job this probably is.

    4. Payer path. Is this going through insurance, or is the customer paying directly? Asked plainly, recorded as stated. The answer changes the paperwork, the pace, and who needs to be in the conversation — it never becomes a coverage opinion. The agent asks; it does not advise.

    5. Urgency. Is water still moving? Is the home livable tonight? Urgency is what separates the 2 a.m. emergency from the Tuesday estimate, and it drives the one promise-shaped thing the system is allowed to do: escalate to a human now, not at 8 a.m.

    6. A complete record. Name, callback number, address, and the facts above — logged on every call, whether it books or not. In our own operation the intake pipeline logs calls into a database the follow-up system can query, so no communication ever begins from scratch. A lead that doesn’t book today is still a record the shop owns tomorrow.

    What happens to each outcome

    The matrix sorts; it does not decide. A lead inside territory, in scope, and urgent gets booked or escalated immediately. A lead that is real but not urgent gets logged and followed up by the automated sequence — the same pipeline discipline we run on our own 3 a.m. shift, where follow-ups compile into a daily briefing sorted red, yellow, green for human review. A lead outside the lines — wrong territory, wrong trade — gets a polite, honest close and a record of why. Nothing disappears, and nothing gets promised that a person hasn’t approved.

    What the human keeps

    Pricing. Promises. The handoff. What a job costs is a person’s call, made with the board in front of them. “We’ll have a crew there by nine” is a promise only someone who knows the crew should make. And the moment a prospect stops being a lead and starts being a customer — when they need to hear that a real person owns their problem — a person takes the conversation. The agent’s job is to make that moment arrive fast, facts collected and appointment real. It is not to be that moment.

    The failure shape, so you can recognize it

    Hand an agent the whole seat — the questions and the judgment both — and it will qualify everybody. It will book the estimate outside your service area because nothing told it distance matters. It will fill the calendar with meetings a person would have filtered in thirty seconds, and once your techs learn to distrust anything the system books, you have automated the exact problem you bought it to solve. The bad version doesn’t fail loudly. It fails as a slow leak — wasted drive time, stood-up appointments — until somebody turns it off and announces that AI doesn’t work.

    The seat works when its boundary is drawn, not when the model is smart. A boundary is a list: what it can ask, what it can book, what it can never promise, and where it stops and hands over. Answer, qualify, schedule — first response, not the close. That is not a limitation of the setup. That is the product, correctly shaped.

    This is the intake standard we publish and work from. It describes our method; it is not a guarantee of lead volume or outcomes for any individual business.

  • The Shared Brain: A Company Brain Any Model Can Read

    The Shared Brain: A Company Brain Any Model Can Read

    Nobody Sells a Shared Brain: Own Your Files, Swap Any Model, Make Every Job Teach the Next One

    Over the last few weeks, we set out to answer a question contractors, field operators, and growing businesses keep asking: does anyone actually sell an AI “shared brain”?

    We wanted three things. First, a central company knowledge base holding our standard operating procedures, pricing schedules, safety protocols, and drying standards. Second, AI agents our whole team can query in plain language from a phone or desk. Third, an automated loop that takes the reality of every finished job—walkthrough videos, moisture logs, readings, photos, and voice notes—and distils lessons back into that knowledge base so the company gets smarter every week.

    We spent weeks auditing vendor documentation, testing APIs, and checking rate cards. The short answer: nobody sells the whole system.

    Meta, Google, Microsoft, OpenAI, and Anthropic each sell pieces of the puzzle, but none sells the complete loop. Even worse, each suite keeps your knowledge inside its own walls. Gemini answers from Google Drive. Copilot queries SharePoint and Microsoft Graph. ChatGPT and Claude work best when you upload files into their proprietary Projects.

    If you build inside a vendor’s closed project, you haven’t built an asset you own. You’ve rented space in someone else’s walled garden. When that vendor changes pricing, alters terms, or falls behind a rival model, your architecture breaks.

    The design that survives vendor churn is deliberately boring: keep your source files in a standard folder tree you own, run a lightweight distillation loop across any model API, and treat chat interfaces as porches that plug in and out. If your files live in ordinary formats on storage you control, you can swap models in fifteen minutes by changing one line in a script. The files, lessons, and team habits never move.

    Contractor Knowledge Architecture • $0 to $20 DIY Setup

    Install The Shared Brain in Your Shop: Free, $7 & $17 Downloads

    Field-tested 4-folder setup checklists, conflicting price-sheet resolvers, truck visor habit cards, 20-question NotebookLM reader test logs, weekly distiller worksheets, and bot-ready AI operator routines built directly from this guide.

    Quick Reference
    FREE

    Shared Brain Quick Card

    2-page field card: The 4-folder tree (00-BRAIN / 10-JOBS / 90-HOPPER / 99-ARCHIVE), the porch-vs-warehouse rule (WhatsApp limits), and the truck field habit on one card — condensed from the starter and field-proof sections.

    Download Free PDF

    Direct download • No email gate

    Working Pack
    $7

    30-Day Starter Pack: Checklists & Logs

    Printable/fillable 6-page working pack: 4-folder setup checklist with conflicting price-sheet resolver, 15-to-20 canonical docs inventory (80% answer test), NotebookLM 20-questions reader test log, truck visor habit card, weekly distiller worksheet with Friday review log, and porch-vs-warehouse reference with seat math.

    Get Starter Pack ($7) →

    Instant checkout • Square verified

    AI Intensive
    Book for Bots
    $17

    The Shared Brain Operator

    Feed to ChatGPT, Claude, or Gemini: 8-page executable prompt playbook with 6 interactive AI routines (Muse Mix-Up Decoder, Seat Bleed Audit, Folder Tree Builder & Conflict Resolver, Reader Test & Gap Hunter, Field Habit Installer, Weekly Distiller & Grace-Rule Approver) plus embedded router.

    Get Bot-Ready Operator ($17) →

    Software made of words • Instant delivery

    Meta, Untangled: Three Products and One Name

    Much of the current confusion comes from Meta using the name “Muse” for three completely different offerings with three distinct price lists. Mixing them up will mis-budget your project from day one.

    First is the Meta Muse app. Per Meta’s help pages, Muse is strictly a personal AI agent tied to individual Meta accounts, not a team platform. Meta offers a free tier with an unpublished usage limit, alongside two paid tiers: Power at $20 a month for 500 million Muse tokens a week, and Maximum at $100 a month for 3 billion tokens a week. These subscriptions buy additional usage rather than extra business features. Meta describes zero team seats, zero shared workspaces, zero admin consoles, and zero central billing. Knowledge in the Muse app lives in an isolated virtual machine for one person. It cannot serve as a company brain; at most, it is an owner’s personal chief of staff.

    Second is Meta Business Agent. Rolled out globally in June 2026, this is a customer porch running on WhatsApp, Messenger, and Instagram. It handles inbound inquiries, qualifies leads, recommends catalog items, and hands off to human staff. Per industry reporting on Meta’s pricing documentation, Platform usage is listed at $2.00 per million tokens starting August 2026—roughly 4 to 5 cents per message exchange. Verify in your Meta console before budgeting.

    Meta also sells in-app access via Meta One tiers, from Essential at $14.99 a month to Max at $499 a month per WhatsApp profile. The subscription price is published; the response volume per tier is not, so cost per conversation cannot be modelled. Furthermore, Business Agent carries a critical boundary: uploaded files have no update call. If you upload a revised policy without deleting the older file, the agent draws on both documents simultaneously and can quote obsolete terms to customers.

    Third is the Meta Model API at dev.meta.ai, offering raw developer access to frontier models like Muse Wonder and multimodal workhorses like Muse Spark 1.3 Standard. On that Standard tier, pricing is listed at $1.25 per million input tokens and $4.25 per million output tokens, under strict terms stating data is not used to train Meta’s models. This is infrastructure you can build on, but it is raw API access, not turnkey software.

    Seats Are the Real Bill, Not Tokens

    When owners evaluate AI, they usually fear token consumption. They assume processing text, audio, and video will create runaway invoices. The reality is the opposite: token usage is a rounding error, while seat licenses dominate the monthly software bill.

    Consider the math for a 10-person restoration company running 20 jobs a month. If technicians record a 45-minute audio walkthrough and voice note on every job, transcribing all 900 minutes using a dedicated speech-to-text API costs under $3 a month. Feeding those transcripts, drying logs, and photos into a multimodal model like Muse Spark Standard to extract lessons costs roughly $0.29 per job—about $6 a month. Even stepping up to a frontier model like Muse Wonder at roughly $1.00 per job, monthly distillation totals just $20. The entire automated distillation loop runs for $10 to $30 a month in compute.

    The real financial bleed happens when companies stack overlapping user seats. Paying $20 or $25 per user each month for ChatGPT Business or Claude Team on top of an existing corporate email suite burns $200 to $250 a month for 10 users, and still leaves you with project file caps or isolated document silos.

    If your company already pays for Google Workspace Standard, team AI is effectively bundled at roughly $140 a month all-in for 10 users, with Gemini and NotebookLM included. If you run a Microsoft shop, the Business Standard plus Copilot bundle runs approximately $235 a month all-in for 10 people. Don’t pay for a second $200 seat subscription on top of a suite you already license; use what you have as the reading interface, and keep the master brain in your own folder tree.

    WhatsApp Is a Porch, Not a Warehouse

    Because field crews live inside WhatsApp, owners naturally ask whether they can turn a company WhatsApp group into the knowledge base. The platform’s technical limits and legal terms rule that out.

    First, WhatsApp enforces hard media file caps: videos are capped at 16 MB and images at 5 MB. A three-minute high-definition walkthrough shot on a smartphone easily runs between 100 MB and 1 GB. If a technician sends raw job walkthroughs through WhatsApp, the media is heavily compressed or blocked entirely.

    Second, WhatsApp Business terms updated in January 2026 expressly prohibit general-purpose AI assistants, while permitting bots scoped to a company’s own customer support. Moreover, the WhatsApp Business Platform operates strictly in one-to-one chats; group chats do not synchronize to the API.

    The rule for field operations is clear: WhatsApp is a front porch, never a warehouse. Customer conversations and quick field notifications can pass through WhatsApp, but raw media—walkthrough videos, moisture readings, and photo logs—must upload directly to the job folder in your cloud storage. WhatsApp carries the notification link; your owned folder stores the truth.

    Field Proof and the Grace Rule

    We did not invent the principle that structured capture must precede AI. One early field example to watch is TRUERESTORE’s Ripple platform, described as launched in October 2026.

    Ripple places an AI project coordinator directly inside every job file. It operates over moisture logs, drying equipment readings, LiDAR room scans, 360 photos, and technician notes. It automatically flags missing documentation before a crew leaves a site and drafts loss summaries for adjusters. Most importantly, Ripple follows a strict operational rule: it changes nothing in the job record until a human confirms.

    In our view, platforms like TRUERESTORE represent the chef’s kitchen. If an operator wants a fully managed, turnkey commercial solution tailored to restoration workflows, hiring the chef and buying into a proven platform is a smart decision. But if you want to cook your own dinner—to retain sovereign ownership over your files, prevent vendor lock-in, and build systems that adapt whenever new models arrive—the open, DIY architecture gives you that control. Both choices are valid. What fails every time is buying AI tools before establishing disciplined field capture habits.

    As case studies from ATI Restoration, Ascendum, and regional contractors show, companies that clean up per-job documentation see immediate operational payback. Companies that dump unorganized photos into AI bots simply automate chaos.

    Contractor Field Operating Toolkit

    Stop Automating Chaos: Install Clean Field Capture Habits & Sovereign Knowledge Governance

    As case studies from ATI Restoration, Ascendum, and regional contractors demonstrate, companies that clean up per-job documentation see immediate operational payback; dumping unorganized photos into AI bots simply automates chaos. Platforms like TRUERESTORE Ripple follow the strict Grace Rule: change nothing in company records until a human confirms. Whether you need printable checklists, conflicting price-sheet resolvers, and truck visor habit cards for your technicians, or an autonomous AI operator that audits duplicate software seats, stress-tests your SOPs against 20 crew questions, and distills weekly walkthroughs into approved one-page lessons, equip your shop with field-proven operating tools.

    ⚙

    What’s In The Field Toolkit:

    • 4-Folder Tree Setup: 00/10/90/99 structure & rules.
    • Price-Sheet Resolver: Kill duplicate rate sheets.
    • 15–20 Canonical Docs: The 80% answer test sheet.
    • NotebookLM Reader Log: 20 crew questions & gaps doc.
    • Truck Visor Card: Continuous video & 3-min audio.
    • Weekly Distiller Sheet: Situation / Action / Result / Rule.
    • Porch & Seat Math: WhatsApp caps & seat audit sheet.
    Sovereign Guarantee: Files live in ordinary formats you own. Swap any AI model in 15 minutes.

    The 30-Day Starter ($0 to $20)

    You do not need an enterprise software contract or an expensive consultant to start building a company brain. A small company can deploy a functional version in 30 days for between $0 and $20 in month one.

    Week 1 establishes the folder tree ($0). In whatever cloud storage you already use—Google Drive, Dropbox, OneDrive, or a local server—set up four root directories: 00-BRAIN for canonical company knowledge, 10-JOBS partitioned by year and job ID, 90-HOPPER for unreviewed field uploads, and 99-ARCHIVE for superseded policies. Populate 00-BRAIN with the 15 to 20 documents that already answer 80% of routine questions. If two conflicting price sheets exist, resolve them now.

    Week 2 activates the reader ($0). Create a free NotebookLM notebook titled “Company Brain” using the documents in 00-BRAIN as sources. Share it with your technicians and office staff in chat-only mode. Because NotebookLM quotes only from supplied sources and provides passage citations, it cuts fabrication — but it can still misquote or miss, so test before you trust. Test it against the 20 questions your crew asks most often, and log missing information into a gaps document.

    Week 3 establishes the field habit ($0). Tape a single-page procedure inside every service truck: after each walkthrough, the lead tech shoots a continuous video and records a three-minute voice note explaining what was found, what actions were taken, and what should be done differently next time. The media uploads directly into 90-HOPPER via the mobile storage app—never through WhatsApp. In the afternoon, the office moves reviewed job logs into 10-JOBS.

    Week 4 introduces the distiller ($0 to $20). Designate one person—an office manager or senior estimator—using the single $20 chat seat you already pay for or a funded API balance. Using a standardized prompt template, the distiller runs weekly job transcripts to generate candidate operational lessons formatted as: situation encountered, action taken, result, and rule for next time. Every Friday, the owner and distiller spend 30 minutes reviewing candidate lessons. Approved one-pagers move into 00-BRAIN; outdated versions are dated and moved into 99-ARCHIVE. That weekly 30-minute human review is the brain. The AI only proposes; humans decide what becomes company policy.

    Implementation Comparison

    Compare the Three Shared Brain Implementation Tiers

    Downloads only, built directly from the published substance of this guide — zero consulting fees, zero enterprise lock-in.

    Quick Reference

    Shared Brain Quick Card

    FREE

    • 4-Folder Tree Map: Root architecture (00/10/90/99) for existing cloud storage.
    • Porch-vs-Warehouse Law: WhatsApp 16MB/5MB limits & mobile app upload rule.
    • Truck Visor Procedure: Continuous video & 3-minute voice note structure.
    • 30-Day Starter Roadmap: Week 1–4 milestone progression ($0 to $20).
    • Grace Rule Reference: Human-in-the-loop policy review principle.
    Download Free PDF

    Direct download • No email gate

    Print-and-Use Pack

    30-Day Starter Pack (PDF)

    $7

    • 4-Folder Setup Checklist: Permissions, file types & directory paths.
    • Price-Sheet Resolver: Audit & reconcile duplicate SOPs & rate cards.
    • Canonical Docs Inventory: 20-doc tracker with 80% answer test pass gate.
    • NotebookLM Test Log: 20 most-asked crew questions benchmark & gaps log.
    • Truck Visor Field Card: Laminated 1-page cabin habit procedure.
    • Weekly Distiller Sheet: Situation / Action / Result / Rule worksheet.
    • Friday Review Log: Approve-to-00-BRAIN / Archive-to-99 audit log.
    • Porch & Seat Math Sheet: WhatsApp caps, Meta chooser & seat bleed audit.
    Get Starter Pack ($7) →

    Print-and-use • Instant delivery

    AI Intensive
    Book for Bots

    The Shared Brain Operator

    $17

    • Buyer Onboarding: Feed directly to ChatGPT, Claude, or Gemini.
    • /muse-decoder: Interactive diagnostic mapping to App vs Agent vs API.
    • /seat-audit: Kill double $200 AI seat stack; model $140/$235 bundles.
    • /folder-builder: Build 00/10/90/99 tree & reconcile duplicate SOPs.
    • /reader-audit: Run 20-questions benchmark & generate gaps report.
    • /truck-habit: Generate visor cards, upload guides & porch scripts.
    • /distiller: Ingest transcripts, output candidate lesson one-pagers.
    • Embedded Router: Universal multi-format command dispatcher.
    Get Bot-Ready Operator ($17) →

    Software made of words • Instant delivery

    Building in Public

    We are developing this entire architecture in public as part of the Meta hackathon build. The complete operational playbook—a practical playbook for owners that any restoration firm or trade contractor can implement—will be open-sourced on GitHub with no paywalls or gated access.

    As part of our commitment to transparent lineage, we are releasing the complete, un-redacted Research Brief behind this project as a free download. The brief contains the full model pricing tables, platform cap comparisons, architecture diagrams, and field gotchas. There is no email wall, no form to fill out, and no marketing capture.

    Free Research Brief Download (No Email Required)

    Read the complete findings, platform cost models, technical gotchas, and architectural blueprints in the free PDF.

    Download The Shared Brain — Research Brief (PDF)

    — Will Tygart, Tygart Media

    Want help installing this in your shop? Contact Tygart Media — the brief above stays free either way.

    Updated October 30, 2026 — corrected the seat-cost math and starter budget figures; softened claims the page could not support.

    Updated Nov 1, 2026 — added the free shared brain quick card, 30-day starter pack, and shared brain operator downloads to this guide.

  • Receipts: One Week, 6,753 Bot Visits, Three Kinds of Bots

    Receipts: One Week, 6,753 Bot Visits, Three Kinds of Bots

    “AI traffic” sounds like one thing. On the dashboard it is three different things, doing three different jobs, and they are not interchangeable.

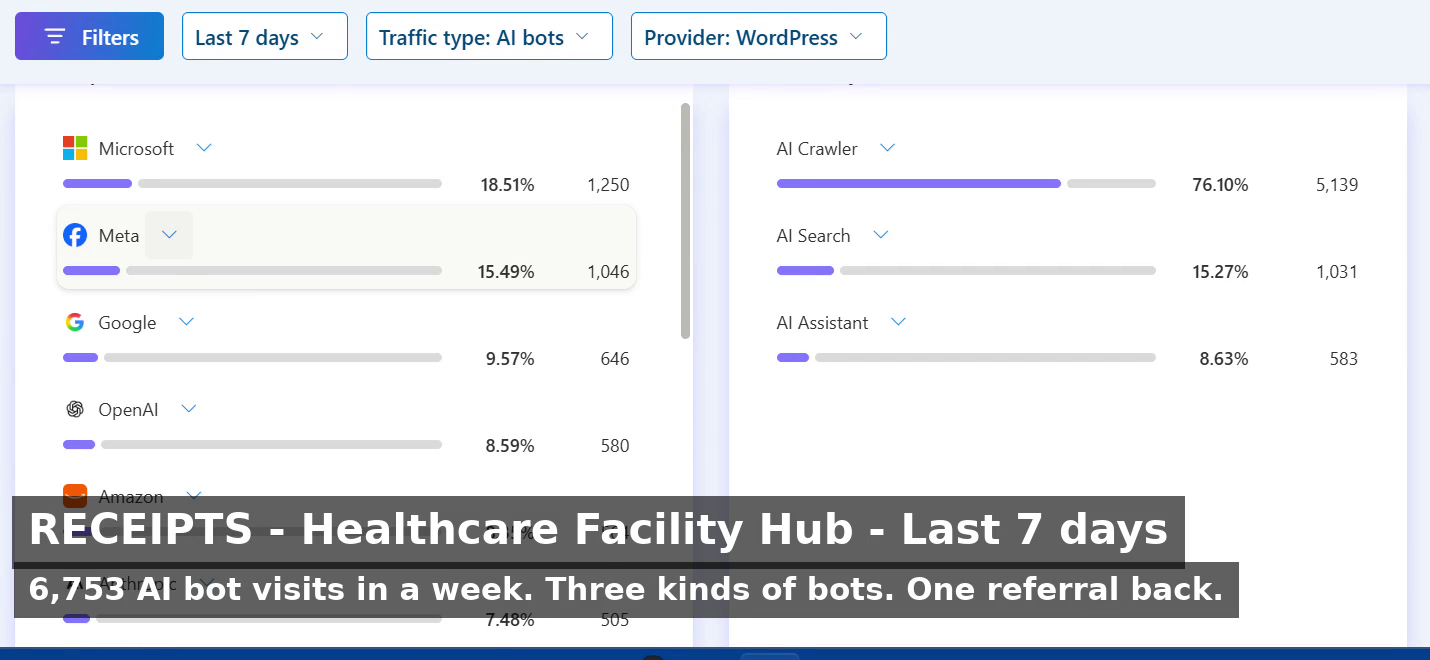
    Healthcare Facility Hub, last 7 days: 6,753 AI-bot requests. The operators alone are a crowd — Microsoft 1,250, Meta 1,046, Google 646, OpenAI 580, Amazon 564, Anthropic 505, Perplexity 444, Huawei 401, ByteDance behind them, and a tail that runs down to a single visit each from names most site owners have never heard of.

    Clarity sorts them by what they came to do. AI Crawlers made 5,139 of the visits, 76.10% — the index builders, reading everything so the models know it exists. AI Search made 1,031, 15.27% — bots fetching a page because somebody just asked a question: PerplexityBot 444 of them, plus Lyrenth and Parallel. AI Assistants made 583, 8.63% — browsing on behalf of a person mid-conversation: OpenAI 320, Anthropic 94, DuckDuckGo 17, Cohere exactly 1.

    The distinction matters because each kind wants something different from a page. A crawler wants it complete and clean. A search bot wants the answer findable in seconds. An assistant wants the page to make sense lifted out of context. One page, three readers, three jobs.

    And for all 6,753 visits, the scrape-to-referral ratio is 535:1. One referral came back all week. The most-wanted page on the site, by the way, is not the homepage — it is a field sheet, /email-my-field-sheet/, with 885 requests, 13.11% of everything the bots did.

    Ask for receipts.

  • The Agent-Ready Site: What Kin’s WebMCP Launch Means for Every Business Website

    The Agent-Ready Site: What Kin’s WebMCP Launch Means for Every Business Website

    On October 23, 2026, Kin Insurance became the first U.S. home insurer to enable WebMCP in its quoting experience — an open web standard that lets an AI agent work directly with kin.com, so a homeowner can tell ChatGPT "help me shop for home insurance" and get back a real quote. Strip away the insurance details and what remains is a pattern every business website is about to be measured against: is your site built for the agent your customer sends?

    Most businesses are still arguing about whether to let agents in. Kin skipped that argument. The interesting question is what its launch is made of, layer by layer — because three of the four layers are already visible in our own fleet's numbers.

    Agent-Ready Fleet Standard

    Make Your Site Machine-Ready for the 62% Bot Wave

    Field-ready quick cards, fillable 4-layer audit worksheets, and AI-powered bot runbooks built directly from this guide.

    Quick Reference FREE

    Agent-Ready Quick Card

    2-page field card: The 4 layers — welcome the machine (door vs. wall), structure for carrying (answers not brochures), give the agent a way to act (WebMCP), and measure what machines do (citation scoreboard) — on one card, condensed from the article body.

    Download Free PDF

    Direct download • No email gate

    Working Pack $7

    The Agent-Ready Site 4-Layer Print Pack

    5-page printable & fillable working pack: Layer 1 Door-or-Wall decision checklist (Kin vs Insurify default audit), Layer 2 answers-not-brochures worksheet with verbatim FAQ tracker modeled on 155-of-166 rollout, Layer 3 declared-action mapper with inputs-in-order sequence sheet, and Layer 4 citation scoreboard log (1.45M across 922 pages tracking model).

    Get Working Pack ($7) →

    Instant checkout • Square verified

    AI Intensive
    Book for Bots $17

    Feed Your AI: The Agent-Ready Site Bot Book

    Feed directly to ChatGPT or Claude: 4 intensive AI-run routines (Welcome Posture Interview, Readable Content Auditor, Declared Action Designer, Citation Scoreboard Diagnostic) with embedded executive command router (“software made of words”).

    Get AI Bot Book ($17) →

    Software made of words • Instant delivery

    Layer 1: Decide to welcome the machine

    Agent traffic is not coming; on our own sites it is already the majority — roughly 62% of visits across the fleet we run are bots and agents, not people. The only choice left is whether that traffic meets a door or a wall.

    Kin chose the door, publicly and in advance: it had already announced that AI shopping agents are welcome on kin.com rather than blocked, naming Meta's Muse among them. The opposite choice exists in the same industry — in September, insurance marketplace Insurify blocked Muse from its comparison platforms, arguing an agent could pull a price stripped of the context that makes it meaningful. Both are coherent positions. What is no longer available is having no position: a site that has not decided is a site whose default settings decide for it.

    Layer 2: Structure the content so a machine can carry it accurately

    An agent can only repeat what it can read, so the agent-ready site is built out of answers, not brochures: one real question per page, paragraphs that stand alone as complete ideas, and structured data underneath that states the facts in machine-readable form.

    This is the layer we work in every day, and it is unglamorous, mechanical work. Tonight, on one operator site in our fleet, we finished putting structured FAQ data — drawn from each page's own questions and answers, verbatim — onto 155 of its 166 articles, because agents cite what is structured and skip what is implied. Multiply that instinct across every page a business owns and you have the content layer of agent-readiness: nothing important lives only in an image, a video, or a sales conversation.

    Layer 3: Give the agent a way to act, not just to read

    WebMCP is the layer most sites do not have yet: the site declares the actions an agent may take — get a quote, with these inputs, in this order — so the agent executes a designed path instead of improvising clicks across a human interface.

    Kin's version is a quote flow, and its testing shows why the layer matters: agents reached a finished quote after asking the consumer only a handful of questions, because the path was declared and the carrier's data filled the rest. The equivalent for any business is the moment a visit becomes a transaction — a booking, a quote, an order. Our own commerce thinking already runs on two rails, one built for humans at a checkout and one an agent can complete; Kin just shipped the insurance version of the second rail, first.

    Autonomous Commerce Engineering

    Build Your Agent-Usable Rail Before Customers Stop Browsing

    Kin proved an agent can reach a finished quote in a handful of questions when the path is declared. Equip your technical and product teams with printable inputs-in-order worksheets, two-rail commerce planners, and interactive AI routines that convert human checkout forms into WebMCP-compliant endpoints.

    🤖

    What’s In The Agent-Ready Suite:

    • Layer 1 Door-or-Wall: Decision checklist & WAF audit.
    • Layer 2 Answers-Not-Brochures: 155-of-166 FAQ tracker.
    • Layer 3 Declared Action: Inputs-in-order sequence mapper.
    • Layer 4 Scoreboard Log: 1.45M across 922 pages tracking.
    • AI Bot Book: 4 interactive routines & command router ($17).
    Secure 1-Click Square Checkout

    Layer 4: Measure what the machines do

    Agent-readiness you cannot measure is a vibe. Kin will know whether agents quote it, because the protocol makes agent sessions countable; the rest of us measure the read layer — which pages agents cite, which questions they bring, how the share moves.

    On tygartmedia.com, we track AI citations from our own search-engine exports rather than a vendor's estimate: 1,459,726 citations across 922 cited pages in the October 15 export, up from 269,399 across 324 pages in the September 27 export. Those numbers are the scoreboard for layers 1 and 2. The day an agent can transact here, layer 3 gets a scoreboard of its own.

    Where our fleet honestly sits

    Layers 1, 2, and 4 are running here today — welcome posture, structured content, citation measurement. Layer 3, declared agent actions, is what Kin shipped first, and it is the next build. That is a fair summary of most of the web right now: readable by agents, citable by agents, and still requiring a human to show up for the transaction itself.

    The businesses that treat that gap as a roadmap, rather than a surprise, are the ones whose sites will be ready when their customers stop browsing and start sending.

    Specification Comparison

    Compare Agent-Ready Tools & AI Implementation Systems

    Choose the depth of operational rigor needed for your website: field quick card, printable audit working pack, or interactive bot-driven runbook.

    Field Summary

    Agent-Ready Quick Card

    2-page field card condensing the 4 layers into an executive reference standard.

    • 4-Layer architectural summary on one card
    • Door vs. Wall posture matrix (Kin vs. Insurify)
    • Answers-not-brochures & standalone paragraph test
    • WebMCP declared action & two-rail commerce summary
    • Citation scoreboard benchmarks (62% bot baseline)
    FREE
    Download Quick Card (PDF)

    Instant direct download • No email gate

    Static Working Pack

    The Agent-Ready Site 4-Layer Print Pack

    5-page printable & fillable audit system with complete engineering worksheets and scoreboard logs.

    • Layer 1 Door-or-Wall decision checklist & default audit
    • Layer 2 answers-not-brochures worksheet (1-question test)
    • Verbatim FAQ structured-data tracker (155-of-166 rollout model)
    • Layer 3 declared-action mapper & inputs-in-order sheet
    • Two-rail commerce planner (Human UI vs. Agent Rail)
    • Layer 4 citation scoreboard log (269k to 1.45M growth model)
    $7.00
    Get Working Pack ($7) →

    Instant delivery • Square checkout

    AI Intensive
    Book for Bots

    Feed Your AI: The Agent-Ready Site Bot Book

    Structured text document feeding 4 executable AI routines directly to ChatGPT or Claude to audit pages, generate schema, and design declared actions.

    • Routine 1: Welcome Posture Interview (/welcome-audit)
    • Routine 2: Readable Content Auditor (/content-audit)
    • Verbatim Schema Generator: JSON-LD FAQPage (155-of-166)
    • Routine 3: Declared Action Designer (/action-design)
    • Routine 4: Citation Scoreboard Diagnostic (/citation-diag)
    • Routine 5: Executive Roadmap Protocol (/roadmap)
    • Router: Embedded command router (“software made of words”)
    $17.00
    Get AI Bot Book ($17) →

    Software made of words • Instant delivery

    Frequently asked questions

    What is WebMCP? An open web standard that lets an AI agent interact with a website through a machine-usable path the site itself declares — no plug-in and no screen-scraping. Kin enabled it in its home insurance quoting experience on October 23, 2026, the first U.S. home insurer to do so.

    What makes a website "agent-ready"? Four layers: a deliberate decision to welcome agent traffic instead of blocking it by default; content structured as standalone answers with machine-readable data underneath; a declared path that lets an agent complete an action, such as a quote or booking; and measurement of what agents actually do on the site.

    Do agents really visit business websites that much? On the fleet we operate, roughly 62% of visits are bots and agents. The share varies by site, but the direction does not: the reader a growing share of your pages serve first is a machine deciding what to show its human.


    Source: Kin Insurance announcement via PR Newswire, October 23, 2026. Fleet figures are Tygart Media's own: bot share from our site analytics; citation counts from our Bing AI Performance exports of September 27 and October 15, 2026.

    Updated Nov 1, 2026 — added the free agent-ready quick card, 4-layer print pack, and agent-ready bot book downloads to this guide.

  • AI Governance Is the Gate That Caught the Thing

    AI Governance Is the Gate That Caught the Thing

    Most AI governance is written by people who have never had to govern an agent that could actually break something. It reads like insurance paperwork: frameworks, maturity models, principles laminated on a wall. Then a real agent, on a real Tuesday, publishes your drafting notes as if they were the article — and the framework has nothing to say about it, because the framework was never in the room.

    We run a small agency where AI agents do real production work every day: research, drafting, publishing, measurement, and an unattended night queue that runs while we sleep. Governance, for us, is not a document. It is the set of gates that have caught real things. Every rule below exists because something specific got past us first, and the rule is the scar.

    Governance starts with who is allowed to remember

    The agents are stateless; the memory lives in one place. Every agent we dispatch starts cold. It knows nothing about our clients, our sites, or yesterday’s decisions until its work order tells it. That sounds like a limitation. It is the control surface. Because the agent holds no standing memory, it holds no standing permissions either — every job is scoped, priced, and bounded by the order that created it, and when the job ends, the access ends with it.

    The work order itself is a governance document. It states the whole price up front, names the points where a human must tap before work proceeds, and lists what the executor may ship directly and what it must hold. An agent that has to ask a question the order should have answered is not a governance failure by the agent. It is a drafting failure by us, and we treat it that way.

    Draw the doors as lines, not policies

    Four things always need a human tap: money, credentials, outbound sends, and publishing. Everything else, the fleet runs on its own. That split is the entire access policy, and it fits in one sentence because it has to survive contact with a tired operator at the end of a long day. Policies that need interpretation get interpreted — usually at the worst moment, in the most generous direction.

    Credentials get the hardest line. Our agents never hold passwords, never see them, never pass them along. Work that reaches a login the agent cannot complete through an already-signed-in session does not get worked around. It stops, logs a hold, and waits for the human whose door that is. One night this fall, a run reached a registry login at three in the morning. The operator could not face the tap, said so, and went to bed. The work was built to survive stopping, so stopping cost nothing. The credential never moved. That is what a line is for: it has to hold when nobody has the energy to argue with it.

    The risk is not a rogue agent. The risk is a report you believe.

    Every serious failure we have had was a verification failure, not a rebellion. A judge model, asked to grade drafts against a length limit, invented word counts that were off by a quarter to a third — confidently, in both directions. A publish report stated a post ID from memory instead of reading it back from the result file, and the number was wrong. A page was verified from its HTML source and declared fine while its signup form rendered as blank white cards. Drafting notes were once published as article content because the check stopped at “the words are there.”

    So the rule is mechanical: proof lives at the receiving end. Numbers get read back by value from the file that recorded them. Pages get verified as rendered pages, in a browser, the way a reader sees them — not from source. A finished article must show visible structure, or it is a hold, not a publish. None of this requires trusting the agent less. It requires trusting the report exactly as far as the evidence under it, which is where trust should have been calibrated all along.

    We also measure trust per model, the way you would per employee. In scored head-to-head runs on identical briefs, exactly one of our models graded perfectly — every defect real, no invented ones — so that model holds the verifier seat. Another writes fast and clean but invents defects when it judges, so it drafts and never judges. The cheapest tier once certified work it had not actually checked, so its output is never trusted without a pass behind it. “The AI said so” is not a control. A scorecard is.

    Failures become regressions, not folklore

    Every break gets an ID, an entry in the failure ledger, and a gate. When the night queue failed in a new way, the failure was written down with its cause and its receipt, and a regression check was built that fails the next run if the same shape reappears. The ledger is unglamorous. It is also the difference between an operation that learns and an operation that just has stories. Governance that lives in people’s memories leaves with their mood, their weekend, and eventually their employment. Governance that lives in a gate runs every time.

    Each work order also carries one pre-decided instruction for the moment something breaks: if a step’s end state cannot be verified, stop that step, log the hold, and move to the next independent step. Never improvise past a failed check. The decision is made in advance, in calm, because the middle of a failing run is the worst possible place to invent policy.

    The 3 a.m. test

    Here is the only governance question we ask anymore: what can this system not do at 3 a.m.? Our night queue runs unattended with hard caps — a maximum number of jobs, a maximum number of attempts, a hard stop before dawn, and a pause switch that halts everything if a single file exists. Agents working overnight cannot spend money, cannot send anything to anyone, cannot touch a credential, and cannot publish. They can draft, measure, and report. Morning is a review: a human reads what the night produced, approves what is good, and the approvals are the fuel for the next day’s work.

    That is the whole philosophy. Governance is not the set of things your agents are allowed to do. It is the set of things they structurally cannot do while you are asleep, plus the evidence trail that lets you check everything else over coffee.

    What this is not

    This will not satisfy a compliance department, and it is not meant to. If you handle medical records or other people’s money under regulation, you need the paperwork kind too. But the paperwork kind alone will not save you from the ordinary failures — the believed report, the generous interpretation, the confident invented number — because those failures are not compliance failures. They are operating failures, and they happen at every scale, in shops with two people and in companies with two thousand.

    Start where the risk actually is. Give the agents no memory and no keys. Draw four doors and hold them. Verify at the receiving end. Write every failure down and make it a gate. Then run the 3 a.m. test on your own setup, honestly, and fix what it shows you. The framework can come later. The gate that catches the thing comes first.

  • The First Agent You Hire Answers the Phone

    The First Agent You Hire Answers the Phone

    Updated November 2, 2026 — added direct answers on how AI handles after-hours calls for a service business, from our own published work.

    Nobody’s first AI hire is a strategist. Ask a room full of operators what they’d hand off first and nobody says the thinking — they say the phone. The call that comes in at 6:40, after the office went dark at five. The form filled out at midnight, water coming through the kitchen ceiling. The lead that goes to whichever company answers first — and in home services, the first answer is very often the whole sale.

    That seat — first response — is where small businesses are actually hiring agents, and the money just said so out loud. On October 13, Dapta, an AI sales agent company out of Scottsdale and Miami, announced a $6 million seed round led by Chingona Ventures. Its agent, Dapti, answers, qualifies, and books the meeting the moment a prospect reaches out — no human touching it. Dapta says 200,000-plus users are on it, signing up at better than 4,000 a week, and that revenue will pass $4 million this year. Home services is one of the verticals where it took hold first.

    The seat, in a real shop

    First response in a small shop is a person-shaped hole. The owner answers between jobs, one glove off. The office manager answers until five. After five, a service answers, or nobody does, and the prospect — wet floor, search results page in hand — calls the next name on the list. It’s a staffing problem, not a marketing problem — one that shows up at the exact hours nobody wants to staff.

    The money makes it worse. On Google Local Services, a connected call that runs past twenty seconds can bill you whether a person picked up or not — you pay for the ring. And the caller isn’t comparison-shopping at leisure. They’re standing in water, or sleeping in a 90-degree house, and they hire the first competent voice that treats them like a person.

    What the agent can own outright

    The front half of the seat is script work, and script work is exactly what an agent is for. Answer instantly, at any hour, in the customer’s own language — Dapta got its start with Spanish-speaking owners in the U.S., and first response is meeting the customer where they are. Ask the basic qualifying set: what happened, where is it, when did it start, who is paying, how do we reach you. Then do what most shops fumble even in business hours: put a real appointment on a real calendar, confirmed where the customer can see it — not a callback promise the morning forgets.

    None of that requires judgment — just the script, the calendar, and the discipline to run both at 2 a.m. the way they run at 10 a.m., on the nights the office sits empty.

    What the human keeps

    Qualification questions are not qualification judgment, and the difference is the entire ballgame. The questions collect facts. The judgment decides what the facts mean: Is this a job we want — at this size, this distance, for this payer, with the crews already buried? A flooded kitchen ten minutes away and a “come look at a stain” forty minutes out both answer the questions perfectly. Only one of them should get your Saturday.

    The human also keeps pricing, promises, and the handoff. What a job costs is a person’s call, made with the board in front of them. “We’ll have a crew there by nine” is a promise only someone who knows the crew should make. And the moment a prospect stops being a lead and starts being a customer — when they need to hear a real person owns their problem — a person takes the conversation. The agent’s job is to make that moment arrive fast, facts collected and appointment real. It is not to be that moment.

    The failure shape

    Hand an agent the whole seat — the questions and the judgment both — and it will qualify everybody. It will book the estimate outside your service area because nothing told it distance matters. It will fill the calendar with meetings a person would have filtered in thirty seconds — and once your techs learn to distrust anything the system books, you have automated the exact problem you bought it to solve. The bad version doesn’t fail loudly. It fails as a slow leak — wasted drive time, stood-up appointments — until somebody turns it off and announces that AI doesn’t work.

    The seat works when its boundary is drawn, not when the model is smart. A boundary is a list: what it can ask, what it can book, what it can never promise, and where it stops and hands over. Dapta’s own framing stops at answer, qualify, schedule — first response, not the close. That is not a limitation. That is the product, correctly shaped.

    How can AI handle after-hours calls for a service business?

    For a service business, handling after-hours calls with AI is a matter of strict boundary design rather than conversational cleverness. When a pipe bursts or an AC fails after the office closes, an AI voice agent can own the front half of the intake seat outright: answering instantly at 2 a.m. in the caller’s language, running the structured qualifying questions (what happened, where is the property, when did the damage start, who is paying, and how to reach them), and booking a confirmed appointment on a live calendar instead of leaving an empty callback promise.

    What the AI agent cannot own is the judgment. As detailed in What the human keeps, human dispatchers must retain pricing, arrival promises (“we’ll have a crew there by nine”), and the decision of whether a job fits current crew capacity and service territory. The danger, as shown in The failure shape, is handing an agent both the script and the judgment: without hard boundaries, it books calls outside your territory, clogs the schedule with low-margin jobs, and creates a slow leak of wasted drive time until crews distrust the system. An effective after-hours setup treats the agent as first response—capturing verified facts and locking in the calendar slot—and hands off the data to an automated operational workflow so morning crews arrive with complete context.

    Hire it like a person

    You would never hand a new receptionist the phone on day one with no script, no boundary, and no “if it’s this, come get me.” An agent seat deserves the same three things, because it is the same hire: a script it runs word for word, a boundary it does not cross on its best day, and an escalation path that puts a human in the conversation the moment judgment enters.

    The $6 million is a bet that every small business staffs this seat the way it eventually got a website. The operators who get it right will not be the ones with the smartest agent. They will be the ones who wrote the seat down — job, boundary, and the name of the human who owns the judgment — before they let anything answer their phone.

    Sources: “Dapta Raises $6M to Accelerate the Adoption of AI Sales Agents for SMBs across the U.S. and Latin America,” Dapta LLC via GlobeNewswire, October 13, 2026 — globenewswire.com. User, signup-rate, and revenue figures are Dapta’s own statements in that release.