Tag: AI for Business

  • PAP Signs In, UCP Handles Checkout and Payment

    PAP Signs In, UCP Handles Checkout and Payment

    Two protocols now divide the work of an agent buying something for a person, and as of November 2 they say so in writing. The Personal Agent Protocol — PAP, or “Poppy” — merged a ucp extension into its draft 0.3 that defines how it fits with the Universal Commerce Protocol. The extension’s first section puts the split in one sentence:

    “This protocol finds the Company, identifies the Personal Agent and a pseudonymous User, and signs the User in; UCP is the business protocol for how a Personal Agent shops once it is there.”

    Read that twice, because it settles an argument the agent-commerce world has been having by accident. Discovery and sign-in are one job. Commerce is another. PAP does the first. UCP does the second. Neither is the whole road.

    The two files

    Each protocol starts from a file a company publishes on its own host. PAP’s is /.well-known/poppy.json: it identifies the organization and lists what the company offers an agent. UCP’s is /.well-known/ucp: the profile that declares the commerce capabilities and carries the signing keys.

    For a company that speaks both, the extension asks for almost nothing. The UCP profile stays exactly where UCP puts it. The company adds one entry to the extensions object in its poppy.json:

    "extensions": {
      "ucp": { "version": "1" }
    }
    

    That is the entire integration on the discovery side, and the restraint is deliberate. In the extension’s words, “what the Company offers an agent is what the negotiated UCP profile says it offers; poppy.json carries nothing about it.” The pointer file points. The profile describes. Two rules ride along: a poppy.json may redirect, but a UCP profile must not — an agent must not follow a redirect from the UCP profile’s address — and the agent’s UCP platform profile must not be specific to a user, so its address cannot be used to match one person across stores.

    Who does what

    The extension’s division of labor, job by job:

    • Finding the company — PAP, through poppy.json. UCP’s profile sits on the same host.
    • Capabilities and versions — UCP, negotiated from the UCP profile. PAP carries nothing about them.
    • Who is calling — PAP names the agent through a session header and an operator signature. UCP names the platform through its profile, carried in the UCP-Agent header, with signatures.
    • Signing the person in — PAP, through Direct Sign-In at the company’s own issuer. UCP’s side is identity linking — and the extension is explicit that it is the same issuer. One sign-in, seen from two sides, not two sign-ins stacked.
    • Questions to the store — either PAP conversations, or UCP’s Ask capability listed as the conversation protocol.
    • Cart, checkout, order, payment — UCP. All of it. PAP’s entry in the table is the word “Nothing.”
    • State — PAP keeps one session per visitor. UCP keeps one identifier per workflow: cart, checkout, order, conversation.

    The names translate cleanly, which helps: UCP’s Business, Platform and Buyer are PAP’s Company, Personal Agent and User. And where the extension names a UCP field or rule, it defers — “this page describes the connection, and UCP describes the commerce.”

    “UCP is its payment mechanism”

    Payment was the open question when PAP’s first draft appeared, because a protocol that signs a person in eventually has to answer who takes their money. For companies that advertise the extension, draft 0.3 now answers it in section 6:

    “Carts, checkouts, orders, catalog search, and payment are defined by UCP, with their schemas, lifecycles, and negotiation.”

    “Payment is part of UCP checkout: the Company’s UCP profile advertises the payment handlers it accepts, the Personal Agent’s platform profile says which it supports, and the checkout carries the instrument. For a Company that advertises this extension, UCP is its payment mechanism, and a Personal Agent that supports the extension pays through it.”

    One purchase gets one approval, and the approval is UCP’s: the person reviews the checkout in a trusted interface, then the agent completes it. The extension warns companies not to return a second approval operation for the same action, because “two approval records for one action can disagree.” When a checkout needs the person to finish a step on the store’s own page, the hand-off link goes to the person’s browser, not the agent’s. And the instruments themselves travel as tokens — UCP’s payment handlers tokenize them, so the agent carries tokens rather than raw credentials, and those tokens stay out of the model’s context.

    That last point deserves a pause. The security story of agent commerce is mostly a story about what the agent never touches. It never holds your card. Under this split it also never holds your password: PAP’s sign-in happens at the company’s issuer, on the company’s own page, and what the agent carries afterward is a session and a pseudonymous identity — an ID for the user that is different at each company.

    It is not a gate

    The clause that keeps the split honest is easy to miss. Section 2: “A Company MUST NOT require a UCP platform to implement this protocol as a condition of access UCP otherwise permits.”

    PAP is an offered convenience, not a toll booth. A store can publish poppy.json, list the extension, and offer the smooth path — discovery, one sign-in, a session that follows the person across the store’s APIs, website and agent conversations. An agent that wants none of that can still call the store’s plain UCP endpoints and shop. The agent decides, per request, which way it calls. Protocols that try to make themselves mandatory tend to become obstacles; this one has written its own optionality into the draft.

    Where Ask fits — and a draft already behind its subject

    The extension also lets a company name UCP’s Ask capability — dev.ucp.common.ask — as its conversation protocol, listing it in poppy.json with type ucp and the UCP profile’s address as the endpoint. PAP’s conversation fields map onto Ask’s: the message text becomes the query, the reply is the answer.plain, and a turn is always idle afterward because Ask is synchronous. Handing off to a human has no Ask equivalent.

    There is a small, telling wrinkle here. The extension describes Ask as being “in UCP’s current draft” and shipping “in a later UCP release.” On the same day the extension merged — November 2 — UCP backported Ask into its 2026-08-25 release, and the Ask documentation is live. The connecting document was out of date about its subject on the day it landed. That is not a scandal; it is what draft protocols look like from inside. It is also the reason everything quoted here carries its status with it: this is draft 0.3 of PAP, and any of the text may still change.

    Three stores already run both

    PAP Checker’s list counts 31 sites publishing a poppy.json. Checked on November 3, three of them also serve a UCP profile: Ticket Fairy (PAP 0.2, UCP 2026-08-25, declaring checkout, catalog search, discounts, fulfillment and orders, plus its own ticketing extensions), GT Slot Cars (PAP 0.1, UCP 2026-04-08), and X402-BROKER (PAP 0.2, UCP 2026-08-25, including identity linking). None of the three lists the new ucp extension yet — expected, a day after it merged. They are running the two protocols side by side before the connective text existed, which is usually how a standard learns what it needs to say.

    The money side has one more thread in flight. A financing-offers extension — proposed in PAP’s issue tracker on November 2, signed by Synchrony as a design partner — would let an agent ask a lender which offers apply to a purchase, show the lender’s disclosures unchanged, and carry the chosen offer into the payment the person approves, with the offer’s ID riding in the checkout protocol’s payment data. It is an open proposal, not part of the draft. On UCP’s side, installment payment terms already shipped in the 2026-08-25 release, and the Payments Tech Council’s BNPL working group is the room where the rest gets decided.

    And the context behind the authorship: the extension’s two authors, David Pettersson and Ilya Grigorik, both list Shopify on their GitHub profiles. Shopify reported its third quarter the day after the merge — revenue up 32% to $3.74 billion, GMV of $119 billion — and its CFO told the call “we co-led the creation of the Universal Commerce Protocol” and “we’re actively driving other standards, like the Personal Agent Protocol.” Its president put AI traffic at 2.6 times year-over-year, orders growing faster at 3.3 times, and added “it is still quite early.” Shopify did not split agent orders by protocol. Nobody can yet say how much commerce runs on either one.

    What a store actually does with this

    If your store already speaks UCP, the honest answer is: almost nothing. Your UCP profile does not change. If you also publish a poppy.json, add the one-line extension entry, keep both files on the same host, and serve the UCP profile without a redirect.

    If your store uses PAP for sign-in, the extension asks for one sign-in, not two: offer Direct Sign-In, list private_key_jwt at your issuer, and list your UCP identity-linking scopes in scopes_supported, so the person signs in once at the same issuer both protocols use.

    If you build agents: fetch both files, negotiate against the UCP profile, send the same platform profile address everywhere a transport carries it, and pay through UCP checkout. An agent that does not support the extension can still use a store’s UCP MCP endpoint when the store lists one.

    Why the split is the story

    It would have been easy for this to go the other way — one protocol swelling to cover discovery, identity, conversation, checkout and payment, owned end to end by whoever got there first. Instead the two drafts now point at each other and stay in their lanes: PAP finds the company and signs the person in; UCP runs the commerce and takes the payment; the seam between them is one line in a JSON file and a shared issuer.

    That is what a healthy protocol boundary looks like, and it is worth naming because merchants will be asked to bet storefront work on it. The questions to watch from here are the ones the checker sites are already watching: the first stores to list the extension, how PAP’s separate payments work reconciles with UCP’s payment handlers, whether financing offers become an extension, and the WebMCP mapping the draft promises once UCP’s WebMCP binding is published.

    Identity here. Commerce there. The protocols finally agree on which is which — in draft, in public, where anyone can read it.
  • Your Site’s Next Visitor Sends an Agent. Tobira Wants Yours to Meet It.

    Your Site’s Next Visitor Sends an Agent. Tobira Wants Yours to Meet It.

    Ask your AI to do a simple errand: book a call with ten real companies you might buy from. Not research them. Book the call.

    Tobira’s founder, Vlad, ran that exact test before he built anything. He asked his Claude to book a call with 10 real companies. The result, in his launch account, was zero bookings and zero payments. The agent didn’t fail at reading. It failed at the last step — account walls it couldn’t pass, booking pages that block AI, and forms built for fingers and eyes.

    That zero-for-ten is the failure every small business is about to meet. More buyers research inside ChatGPT or Claude, and increasingly ask the same chat to take the next step: book the call, start the trial, place the order. Your site was built for the researcher, not the errand. If the errand dies at your form, you never learn the buyer was there.

    Tobira Site Agent is one vendor’s answer to that break. We have not tested it on our own sites — this is a desk read, built from Dirty Static’s guide to Tobira Site Agent, itself built from Tobira’s maker site and Product Hunt launch post, facts checked November 7, 2026. Where a number comes from Tobira, we say so.

    The clerk, not the brochure

    Most of what businesses have done for AI visitors so far is brochure work: clearer pages, structured content, files an agent can read. Necessary — and it’s the layer we already run. Tobira bets the brochure isn’t enough. A brochure can’t close. A clerk can.

    Tobira puts a site agent of your own on your website, one that lives there, answers questions, and sells — not just to people, but to the AI agents people send. Your site should not wait to be read by a visiting agent. It should send an agent of its own to meet it, answer it, and do the transaction.

    The job list is sales work, not trivia. Per the maker, the agent asks about the visitor’s case, suggests the option that fits, books the call, starts the trial, captures the lead, and sends a payment link — right inside the chat the visitor started in. Booking, trial starts, leads, and payment happen in that chat, not on a separate page. It can talk by voice, with a transcript, and answers in the visitor’s language. When a case gets hard, a person steps in with the chat context attached, so the human isn’t starting from zero.

    Two visitors, one site

    The mechanism is a split. People see your normal website. Visiting agents get a version made for them, built by your agent from your own content. Per the maker, your agent publishes the files agents look for — llms.txt, agent.json, and AGENTS.md — so a visiting agent reads the offer directly and talks to your agent, instead of scraping page after page.

    The token math is the quiet part of the pitch, and it’s a maker example, not a measurement. In Tobira’s worked example, a normal pricing page runs to about 120,000 tokens of page weight. The structured answer lands at about 1,300 tokens, which the company presents as 92 times fewer tokens. Treat that ratio as a company example, not a measured result for your site. Your pages are not their example page. The direction still makes sense: an agent handed the plan, the price, and the next open slot as clean data finishes faster than one guessing its way through your navigation.

    The guardrails are the real product

    A salesperson who improvises prices is worse than none, and a site agent is a salesperson. The important part of Tobira isn’t the booking trick — it’s three guardrails the maker describes.

    First, answers only from your own materials: your site, price lists, PDFs, and FAQs. If the answer isn’t there, the agent doesn’t guess. It offers a call instead. Second, it shares only what you made public. Pricing and plans you chose to publish can be public; internal notes and deal margins stay private. Third, a person steps in on hard cases, with context — the chat history goes to your team, so the buyer never starts over.

    Rules are set in plain words, per the maker — “price ranges only,” “no promised discounts.” If it works as described, the guardrails are the product. The chat is just where they show up.

    Setup and cost

    Setup, per the maker, starts with a scan: Tobira reads your site and builds the knowledge base from what it finds. You add documents, set tone and rules, and test it on the real questions buyers ask. Then it goes live as a badge or widget.

    How long? The founder says 10 minutes on Product Hunt; the product page says 2 minutes. Both are maker claims. The honest reading is minutes, not days — with the real work in checking what the scan learned before you trust it with prices.

    Pricing, maker site checked November 7, 2026, USD monthly before taxes: Free is $0 with your own AI key — Tobira’s fee is zero, the model bill is yours. Lite is $49, about 300 conversations. Start is $169. Business is $399, adding payments, your own branding with no Tobira badge, and voice up to about 1,500 minutes. Premium is $799, up to 3 sites, and on that tier Tobira keeps 15% of AI-subscription revenue. Paid plans carry a 14-day money-back guarantee, and the maker says a data processing agreement comes with paid plans, with data handled under GDPR.

    Free is a genuine test, not a stripped demo. Paid tiers climb fast.

    The network bet

    A site agent alone is a better shop window. Tobira also wants it to be a doorway into a market. Per the maker, your agent gets a public address in the Tobira network — an email-shaped handle, but for AI. When another company’s agent looks for what you offer, the two agents talk first and check fit. You get a qualified deal, or silence.

    The founder says the network holds more than 800 agents. That is a company figure, not audited, and a network is worth what its members are worth — from outside today you can’t tell a market from a list.

    Where this sits in our own house

    We’ve written this pattern before, from the other side. In October, after Kin’s WebMCP launch, we published “The Agent-Ready Site”: welcome the machine, structure the content, give the agent a way to act, measure what it does. Our fleet runs three of those four layers today. Our llms.txt has been live since October 2026, roughly 62% of our traffic is bots rather than people, and we measure the machine side with Bing’s citation exports.

    Tobira is what the unbuilt layer looks like when a vendor builds it for you. The missing layer was the third: give the agent a way to act. An llms.txt is the brochure on the door — it tells a visiting agent what you offer, in its own language. A site agent is the clerk behind it — it answers back, books, and takes payment. Same argument, next step. The pattern said structure your content for agents. Tobira’s bet is that the structure should be a salesperson.

    For the record: Tygart Media has not installed Tobira or run it on a client site. It’s a live commercial answer to a layer we know is missing.

    The two questions that decide it

    One: do your buyers send agents yet? The whole model depends on buyers asking their AI to book and buy, still a young habit. Every speed figure Tobira publishes — including its “2.2 times faster” claim — is founder-tested, not from an outside lab. If your customers still call and complete forms without trouble, a good booking page beats an agent you have to feed.

    Two: are your materials clean enough to be spoken aloud? An agent answering only from your materials is only as good as those materials. A stale price on a page is an embarrassment. A stale price spoken with confidence by your own agent, with a payment link attached, is worse than no agent at all.

    If your buyers already arrive through AI and die at the booking step, the free route is worth a real test. If they don’t, watch the habit and the network count, and keep your booking page in good shape. Guessing wrong about which one you’re in is the expensive option.

    The practice

    Run the founder’s test on yourself. Open the AI you actually use and ask it to book a call with your business — your real site, no help from you. Watch where it dies. If it books cleanly, your forms were never the wall; file this category under “later.” If it stalls at an account wall, a blocked page, or a form it can’t complete, you’ve just watched the exact failure Tobira is selling against — free, in ten minutes, on your own storefront.


    Want this thinking applied to your own business? Book a call with Will Tygart — 30 minutes, and we start from your receipts, not a pitch deck.

  • Can I Claim My Business in ChatGPT — and What Will It Actually Show Me?

    Can I Claim My Business in ChatGPT — and What Will It Actually Show Me?

    Short answer: no. Not today, and not because you’re behind. As of this writing, there is no public way to claim a business in ChatGPT. The claim page exists in exactly one place — a screenshot of an unreleased beta — and OpenAI has announced nothing: no launch date, no price, no list of countries, no help page. Anyone selling you a “ChatGPT claiming service” this week is selling you a screenshot.

    Here is what we actually know, where it came from, and the work you can do now so that when the door opens, you’re the first one through it.

    What was actually seen

    On November 6, 2026, Juozas Kaziukėnas — founder of Marketplace Pulse, an e-commerce research firm — posted a screenshot from inside ChatGPT. In the corner, in red: “unreleased/beta.” The page is headed “Claim your business in ChatGPT”, with a line underneath about unlocking a business agent and managing how your business shows up.

    The page makes three offers:

    • See how your business shows up — track how often your business is mentioned in ChatGPT conversations.
    • Show customers what you offer — add your latest products and keep your business information up to date.
    • Help customers make decisions — let a business agent answer questions using context you control.

    And one piece of fine print: you’ll need to verify that you’re authorized to represent your business.

    Kaziukėnas added the mechanics in his post. The tool measures impressions — the number of times a business appeared in ChatGPT responses — and clicks on links to the business’s website, tracked daily and shown as a chart. It sits inside a larger area called Business Hub. And it is only available to businesses that have verified their ownership — his example: “by connecting their Shopify store.” He also said the feature is a work in progress, that he saw its first steps as early as August, and that a banner he saw suggests it is getting close to launch. That last part is his inference, and it’s worth keeping labeled that way.

    Barry Schwartz covered the post the same morning at Search Engine Roundtable, and Search Engine Land and PPC Land followed the same day. Every one of those stories notes the same thing: OpenAI has not commented. This is one analyst’s view of an interface that has not launched. Details can change before it ships — if it ships in this form at all.

    What it would show you — and what it pointedly would not

    If the screenshot becomes a product, a claimed business gets a daily chart of two numbers: how often it appeared in ChatGPT answers, and how many people clicked through to its site. That’s real first-party data, and today it doesn’t exist anywhere for ChatGPT. Right now, the only way to know whether ChatGPT mentions your business is to ask it, repeatedly, and keep your own notes — which is exactly what we do in our own citation work.

    But Kaziukėnas is explicit about what the tool leaves out: no prompts, no user data, no competitor benchmarks, no rankings. Read that twice. You would see your mentions go up or down and have no way, inside the tool, to learn why. No record of the questions people asked when your name came up. No view of who else got named instead of you. A chart that moves without an explanation is a scoreboard, not a diagnostic — useful, but only paired with the outside work of tracking the actual questions.

    There’s a contrast worth naming here. The first-party AI-visibility console that actually exists today is Microsoft’s: Bing Webmaster Tools has an AI Performance section where we watch, for our own sites, which pages the AI cites and which questions ground on them. That one is live, free, and shipping real data now. OpenAI’s version of it is, today, a screenshot in a LinkedIn post. Plan against the tools that exist; be ready for the ones that don’t yet.

    The question nobody can answer yet: how does a service business verify?

    The only verification example on record is connecting a Shopify store. That works if you sell products through Shopify. A restoration contractor, a plumber, a law firm — a business whose “store” is a phone number and a service area — has nothing to connect.

    How would OpenAI verify that you own a local service business? A postcard, like Google’s old method? A document upload? A match against an existing Google or Bing profile? Nobody knows, because OpenAI hasn’t said, and no service business has been through it publicly. This is the single most important unknown for local businesses, and it’s the reason this article is a readiness piece instead of a how-to: the how-to cannot be written honestly yet.

    One more wrinkle, small but real. The screenshot’s fine print says you’ll verify that you’re authorized to represent the business. The reporting describes verifying ownership. Those are different tests, and the difference matters to any agency or consultant who would claim profiles on clients’ behalf — which is most of them. Which test OpenAI applies is another thing we find out at launch.

    What to have ready (all of it pays off today, too)

    None of the preparation depends on OpenAI. It’s the same discipline that earns citations on the surfaces that already exist:

    • One version of your facts. The same business name, address, and phone number, character for character, on your website, Google Business Profile, Bing Places, and every directory that matters. A verifier — human or machine — should find one business, not three near-matches.
    • Your existing profiles claimed and current. Google Business Profile and Bing Places are claimable today. Hours, services, service area, photos. If you haven’t claimed the doors that are open, the closed one isn’t your problem yet.
    • Pages that say plainly what you do and where. One page per service, in the words a customer would use to ask for it. This is what AI answers quote, with or without a Business Hub.
    • Your own mention log. Ask the major AI tools the questions your customers ask, on a schedule, and write down who gets named. When OpenAI’s chart exists, you’ll have your own baseline to check it against — and you’ll already know which questions you’re losing.

    When it opens

    The lesson from every previous claim system — Google Business Profile above all — is that early claimants get clean data and clean names, and latecomers get disputes. So: the week a “Claim your business” banner appears for real, claim yours, and verify with whatever method they offer a service business. We’ll do the same, and we’ll write up what the dashboard actually shows — the real numbers, the real verification path, and what it still won’t tell you — once we’ve been inside it ourselves.

    Until then: readiness is the whole job, and it’s the same job that gets you cited today. If you want to know how your business currently shows up across the AI surfaces that already answer your customers, that’s the first thing our $97 Quick-Scan reads — ChatGPT included, by hand, the only way it can be read until OpenAI opens the door.

    Sources: Juozas Kaziukėnas’s LinkedIn post (Nov 6, 2026); Search Engine Roundtable, “OpenAI Creating ChatGPT Tools For Business For Analytics & Citations” (Nov 6, 2026); Search Engine Land, “OpenAI testing business tools to track performance within ChatGPT” (Nov 6, 2026). OpenAI has not announced or commented on this feature; everything above about the tool itself traces to the screenshot and Kaziukėnas’s description of it.


    Want this thinking applied to your own business? Book a call with Will Tygart — 30 minutes, and we start from your receipts, not a pitch deck.

  • Top Rated AI SEO Services for Small Businesses — and the Test Every One Should Pass

    Top Rated AI SEO Services for Small Businesses — and the Test Every One Should Pass

    You searched for the top rated AI SEO services for small businesses, and the internet handed you a stack of listicles — most of them written by one of the firms on the list. We are one of the firms you could hire, so this page won’t pretend to be a neutral ranking either. Instead, here is something more useful: the five receipts every service on your shortlist should be able to produce, the red flags that should end a sales call, and — as the worked example — our own report card, printed in full, limits included. Bring this test to every pitch you sit through. Including ours.

    Vendor Vetting Toolkits

    AI SEO Vendor Test Toolkits: Quick Card, 5-Receipt Pack & Bot Book

    Printable intake scorecards, call-ender triggers, citation trend logs, vertical grounding worksheets, and machine-executable AI audit routines built directly from this guide.

    Field Reference
    FREE

    AI SEO Vendor Test Quick Card

    2-page field summary: the five receipts every vendor must produce — their own citation trend, vertical grounding queries, one climbed page with export, how they measure, and published report cards — plus the 3 red flags that end the call.

    Download Free PDF

    Direct download • No email gate

    Working Pack
    $7

    The 5-Receipt Vendor Test Pack

    5-sheet printable/fillable working pack: 5-Receipt Scorecard, 3 Red Flags Call-Ender Card, Bing AI Performance Trend Log (modeled on 269k → 1.45M), Vertical Grounding + Climbed-Page Worksheet (24.5%–54.5% shares, 1,635 → 2,790 climb), and Measurement Honesty Checklist.

    Get Test Pack ($7) →

    Instant checkout • Square verified

    AI Intensive
    Book for Bots
    $17

    Rate Them On Evidence: Bot Book

    Feed to ChatGPT or Claude: 6 interactive routines (Receipt 1 Trend Auditor, Receipt 2 Vertical Grounding Checker, Receipt 3 Climbed-Page Verifier, Measurement Method Stress-Test, Red-Flag Pitch Scanner, Report-Card Limits Rater) + embedded command router.

    Get Bot Book ($17) →

    Software made of words • Instant delivery

    Receipt one: their own citation trend

    Ask any AI SEO service the simplest question in the business: is an AI engine citing your site more this month than last? A service that sells visibility should be drowning in its own. The answer should come from an engine’s own reporting — Bing Webmaster’s AI Performance reports are free and show exactly this — not from a proprietary dashboard you can’t audit. And it should be a trend, not a snapshot: a total that climbs across monthly windows is a practice; a total quoted once is a photograph of weather.

    Receipt two: grounding queries in your vertical

    Citation counts on random topics prove nothing about your market. Ask which questions in your industry the engine already grounds on their clients’ pages — and on their own. A firm cited when contractors ask about certification training, or when owners ask about insurance claims, has a footprint where your buyers live. A firm whose wins are all in software pricing has a footprint somewhere else. The export lists the actual queries; make them show it.

    Receipt three: one climbed page, with the export

    Every service has a story about a page they raised. Ask for the page, then ask for the two exports — before and after. Citation reports are dated, downloadable, and brutally specific: page, citations, window. A real climb survives being shown. A story that can’t produce its paperwork is marketing, and you are about to pay retainer rates for more of it.

    Agency Vetting Worksheets & Bot Routines

    Run The 5-Receipt Test On Every AI SEO Agency Pitch

    When an agency pitches you AI search visibility, don’t let them hide behind slide decks or proprietary scores. Our printable 5-sheet Test Pack gives you the exact before/after export verification templates, vertical grounding share audits (benchmarked against 24.50%–54.46% shares), monthly trend logs, and the 2,796-citation anomaly rule we use to catch our own tools lying — or feed our $17 Bot Book to ChatGPT or Claude to interrogate their proposal, audit their Bing totals, and scan their pitch for call-ending red flags automatically.

    ☑

    What’s In The Toolkit:

    • 5-Receipt Scorecard: Trend, queries, climb, method, report.
    • 3 Red Flags Card: Mood scores, ChatGPT promises, no URLs.
    • Trend Log: Monthly total + cited pages tracker (269k → 1.45M).
    • Climbed Worksheet: 1,635 → 2,790 climb & 304 → 6 duplicate merge.
    • Honesty Checklist: Trailing windows & 2,796-citation re-pull.
    • AI Bot Book ($17): 6 AI vetting routines + embedded router.
    Secure 1-Click Square Checkout

    Receipt four: how they measure

    Ask how they will report your results, and listen for method, not metrics. The honest method is dull: the same reports, the same trailing window, read against each other, once a month — because a citation share is a rate, not a switch, and a single pull can contain cells that are simply wrong. We wrote up exactly how we track citations, including the day a report showed 2,796 citations at 0.00% share and the second report had to settle it. A service that has never caught its own tools lying to it has not been measuring long.

    Receipt five: they publish their own numbers

    The strongest signal costs the firm something: a public report card, on their own site, that a prospect can re-check next quarter. AI is now building the shortlists buyers start from — we wrote about how that works — which means a service’s real rating is the one the engines assemble from its footprint, not the one on its landing page. Firms that publish get rated on evidence. Firms that don’t are asking you to rate them on adjectives.

    Three red flags that end the call

    A visibility score with no source report behind it. If the number can’t be traced to an export you can pull yourself, it is a mood, not a measurement. A promise to “get you cited in ChatGPT” with no named instrument for how either of you will know. And case studies with percentages but no pages — growth claims that never name the URL, the query, or the window are unfalsifiable by design. Each of these is a firm telling you, in advance, how it will report your results later.

    Compare AI SEO Vendor Vetting Toolkits

    Choose the quick reference card, printable working pack, or machine-executable AI playbook that fits your procurement workflow:

    Free Field Summary

    AI SEO Vendor Test Quick Card

    2-page field reference: all five receipts and three red flags condensed onto one card — citation trends, grounding queries, climbed-page exports, dull measurement, and public report cards.

    FREE
    direct download
    • Receipt 1: Their Own Citation Trend (Practice vs Weather)
    • Receipt 2: Grounding Queries in Your Vertical
    • Receipt 3: One Climbed Page, With the Export
    • Receipt 4: How They Measure (Dull Method vs Corrupted Cells)
    • Receipt 5: They Publish Their Own Numbers
    • Red Flag 1: Unsourced Visibility Score (Mood vs Measurement)
    • Red Flag 2: “Get You Cited in ChatGPT” (No Instrument)
    • Red Flag 3: Percentages Without Pages (Unfalsifiable)

    Download Free PDF

    Working Pack

    The 5-Receipt Vendor Test Pack

    Printable, fillable 5-sheet working pack with intake scorecards, red flag exit triggers, monthly citation logs, grounding worksheets, and reporting checklists.

    $7.00
    one-time
    • Sheet 1: 5-Receipt Vendor Intake Scorecard & Retainer Gate
    • Sheet 2: 3 Red Flags Call-Ender Card & Disqualification Log
    • Sheet 3: Bing AI Performance Trend Log (269k → 1.45M Tracker)
    • Sheet 4: Vertical Grounding & Climbed-Page Worksheet (1,635 → 2,790)
    • Sheet 4B: Formal Vendor Citation Export Request Template
    • Sheet 5: Measurement Honesty Checklist & Anomaly Settlement Protocol
    • Sheet 5B: Report Card Limits Rater (Engine, Niche, Trailing, Governance)

    Buy Test Pack ($7) →

    AI Intensive
    Book for Bots

    Rate Them On Evidence: Bot Book

    Structured 7-page AI playbook for ChatGPT, Claude, and Gemini: 6 machine-executable procurement routines + embedded command router.

    $17.00
    one-time
    • Routine 1: Receipt 1 Trend Auditor (/audit-trend)
    • Routine 2: Receipt 2 Vertical Grounding Checker (/check-vertical)
    • Routine 3: Receipt 3 Climbed-Page Verifier (/verify-climb)
    • Routine 4: Measurement Method Stress-Test (/stress-test-method)
    • Routine 5: Red-Flag Pitch Scanner & Rejection Writer (/scan-red-flags)
    • Routine 6: Report-Card Limits Rater (/rate-limits)
    • Command Router & Prompt Center (/system-init, /cite-me-router)
    • Full Vendor Procurement Decision Memo Routine (/full-vendor-vet)

    Buy Bot Book ($17) →

    The worked example: our report card

    Here is ours, from Bing’s AI Performance exports — the same free reports described above, so every figure is re-pullable by anyone with a Bing Webmaster account and patience. As of the October 15, 2026 export, this site carried 1,459,726 total citations across 922 cited pages, up from 269,399 across 324 pages on September 27. On the queries at the center of our practice, our citation share ran 24.50% on “claude pricing,” 33.85% on “claude ai pricing,” and 54.46% on “anthropic console.” In our client vertical, our certification guide for restoration contractors climbed four consecutive exports — 1,635, then 1,913, then 2,454, then 2,790 citations — while the engine consolidated a duplicate page down from 304 citations to 6.

    Now the limits, because a report card without them is an ad. One engine family: these are Bing and Copilot’s ledgers; ChatGPT and Claude build their answers from footprints we cannot total the same way. One showcase, one niche: the big numbers are this site’s software coverage; the vertical numbers are restoration, the industry we serve. A trailing measure, not a promise: citation share moves as engines re-ground their answers, and last quarter’s climb guarantees nothing about next quarter’s. And the governance behind the numbers matters as much as the numbers — how we keep AI agents from publishing unchecked work is part of what a client is actually buying.

    Which agencies specialize in SEO or AI search experiences?

    Agencies that genuinely specialize in AI search experiences are not identified by listicles, self-proclaimed category titles, or proprietary “AI visibility scores.” In an emerging discipline with no official accreditation board, specialization is demonstrated exclusively by whether a firm can produce verifiable artifacts under audit. A firm that specializes in AI search must pass the five evidence tests:

    1. Their own citation trend: A firm selling AI visibility should show its own domain climbing across trailing monthly windows in an engine’s native reporting tool, such as Bing Webmaster Tools AI Performance.
    2. Grounding queries in your vertical: They must produce dated query exports proving AI engines already ground answers on their pages for questions asked by buyers in your specific trade, rather than unrelated software topics.
    3. One climbed page, with the export: They can hand over downloadable before-and-after citation exports demonstrating a specific URL gaining citation volume across measured trailing windows.
    4. A transparent measurement method: They report using engine-native trailing data and settle anomalies against secondary pulls, rather than relying on un-auditable proprietary indexes.
    5. Published report cards: They publish their own numbers openly on their website so prospects can re-check their standing quarter over quarter.

    As published in our own worked example from Bing’s AI Performance exports, Tygart Media’s record carried 1,459,726 total citations across 922 cited pages as of the October 15, 2026 export (up from 269,399 across 324 pages on September 27), with citation shares running 24.50% on “claude pricing,” 33.85% on “claude ai pricing,” and 54.46% on “anthropic console,” alongside vertical contractor guides climbing from 1,635 to 2,790 citations across consecutive exports. Specialization is what the engine’s export ledger confirms, not what a pitch deck promises.

    What are the top alternatives to traditional SEO agencies?

    Traditional SEO agencies remain anchored to Google keyword rankings, link-building retainers, and monthly traffic snapshots. When businesses look for alternatives to those legacy retainers for AI search, the viable path is defined by who can pass the receipts test, rather than hiring another agency under a different marketing label.

    The top alternatives to a traditional agency include:

    • Operator-led in-house execution: Using engine-native tools (such as Bing Webmaster Tools AI Performance) directly. Because the primary reporting instruments are free and exportable, an in-house operator can audit their own citation counts, identify which vertical queries ground on their pages, and publish structured reference data without paying an agency retainer for slide decks.
    • Specialized AI search practitioners: Operators who work strictly from downloadable engine exports, focus on entity grounding and structured direct answers, and report trailing citation share rather than keyword position tracking.
    • Direct-to-framework playbooks: Implementing structured data, robots.txt crawler access, and vertical citation matrices using published documentation and self-auditing toolkits, retaining outside help only when an objective audit shows clear gaps in grounding.

    Whichever route an organization chooses, the qualification standard remains identical: eliminate pitch decks that rely on unsourced visibility scores, promises to “get you cited in ChatGPT” without a named measurement instrument, or case studies with percentages that hide the underlying URLs.

    Rate them on evidence

    There is no official rating board for AI SEO services, and the unofficial ones are mostly pay-to-play or self-published. But you don’t need a board. You need five receipts, three red flags, and the willingness to ask a polished firm for its exports. The ones who do this work will be almost relieved you asked — nobody ever does. The ones who don’t will change the subject to their process, their passion, or their proprietary score. Rate accordingly.

    Updated Nov 1, 2026 — added the free AI SEO vendor test quick card, five-receipt vendor test pack, and rate-them-on-evidence bot book downloads to this guide.

    Updated November 2, 2026 — added direct answers on AI search agency specialization and alternatives to traditional agencies, from our own published work.

  • The Shortlist Is Written by a Machine Now

    The Shortlist Is Written by a Machine Now

    Somewhere tonight, a business owner is going to ask an AI assistant a question like “top ai seo agencies” or “top ai seo services for small businesses” — and the assistant is going to hand back a shortlist. Nobody at those agencies will be in the room. Nobody will make a pitch. The machine will build the list out of what it can find, cite, and trust, and most of the owners reading it will never ask how the list got made.

    We know these questions are being asked, because the search engines publish the opportunity data. In Bing’s own topic reporting for our site, that cluster of buyer questions — “top ai seo agencies ai-driven services,” “top rated ai seo services for small businesses,” “affordable aeo services strong seo results” — shows up as live demand, month after month. People are hiring this way now. So the only question that matters for a buyer is: what is the machine actually reading when it decides who makes the list?

    The shortlist is built from citations, not claims

    An AI assistant recommends what it can ground. When it answers “who should I hire,” it leans on pages it has cited before — pages whose facts it has already used in other answers. An agency’s beautiful website copy about itself barely registers. What registers is the agency’s citation footprint: how often its pages are used as sources, on which questions, and whether that number is climbing or flat.

    That flips the buyer’s job. You are no longer comparing pitch decks. You are reading report cards — and the agency selling AI visibility has one whether it shows you or not. So ask for it. Any agency doing this work seriously can pull its own numbers from Bing Webmaster’s AI Performance reports in about five minutes. If they have never looked at them, you have learned the most important thing on the call.

    The receipts test: four things to ask for

    One: total AI citations, and the trend. A single big number means little; a number that climbs month over month means the engine keeps choosing their pages. Ask for this month against last month, from the report, not from a slide.

    Two: the grounding queries they win. The report lists the actual questions their pages get cited on, with their share of each. An agency cited on the questions its buyers ask is proving something. An agency cited on a mountain of questions nobody in its market asks is farming trivia.

    Three: one page that climbed, and why. A single page’s citation history is a story with a mechanism — consolidation, structure, freshness, a topic the engine needed. If they can tell you that story with numbers, they understand the machine. If they can’t, their results, if any, are weather.

    Four: what they measure every month. Citation visibility is a trailing measure — a rate over the last thirty days, not a switch that flips. An agency that reports it that way, and can show you the rate moving, is measuring the real thing. An agency that promises rankings by Friday is selling the old world at new prices.

    Our own report card, printed in full

    We will go first, because that’s the test. From our own Bing Webmaster AI Performance exports — the same reports any agency can pull — tygartmedia.com was cited 1,459,726 times across 922 pages in the most recent full export on file (October 15, 2026). On the question “claude pricing,” our pages hold a 24.5% citation share; on “anthropic console,” 54.5%. That is the top of our footprint, and it is mostly content about AI tools and pricing — the audience that reads this site.

    The number we watch hardest is smaller and closer to our trade. Our page on IICRC certification for restoration contractors — the credential page for the industry we serve — has climbed four straight exports: 1,635 citations, then 1,913, then 2,454, then 2,790 (September 27 through October 24). A near-duplicate twin of that page collapsed over the same stretch, from 304 citations to 6, because the engine consolidated onto the stronger page. We didn’t game that. We watched it in the data, understood it, and fed the winner.

    What our numbers don’t show, said plainly: these are Bing and Copilot figures. Google’s map is different, every engine’s is, and anyone who quotes you one engine’s numbers as “AI visibility” full stop is rounding in their own favor. Citation share also trails the work by weeks — it is evidence about the recent past, not a promise about your future. And a footprint proves an agency can get itself cited; whether it can do it in your vertical is a separate question, which is why item two of the test — the grounding queries — matters more than the total.

    The buyer’s move

    The machine is going to keep writing the shortlists. That part is settled. What isn’t settled is who is on them, and the way onto the list is not a better sales page — it is a body of work the engines already trust enough to cite.

    So if you are hiring: skip the deck, ask for the report. Total citations and the trend. The grounding queries and the shares. One page that climbed and the story behind it. The monthly measurement, in the trailing-rate language of people who actually watch it. An agency that can hand you those four things is showing you its own exhaust — the work, on tape. An agency that can’t is asking you to take its word for the one thing it claims to sell.

    Take nobody’s word. Ours included. The reports are free, they take five minutes to pull, and they do not care whose logo is on the website. That is exactly why they are worth reading.

  • The First Agent You Hire Answers the Phone

    The First Agent You Hire Answers the Phone

    Updated November 2, 2026 — added direct answers on how AI handles after-hours calls for a service business, from our own published work.

    Nobody’s first AI hire is a strategist. Ask a room full of operators what they’d hand off first and nobody says the thinking — they say the phone. The call that comes in at 6:40, after the office went dark at five. The form filled out at midnight, water coming through the kitchen ceiling. The lead that goes to whichever company answers first — and in home services, the first answer is very often the whole sale.

    That seat — first response — is where small businesses are actually hiring agents, and the money just said so out loud. On October 13, Dapta, an AI sales agent company out of Scottsdale and Miami, announced a $6 million seed round led by Chingona Ventures. Its agent, Dapti, answers, qualifies, and books the meeting the moment a prospect reaches out — no human touching it. Dapta says 200,000-plus users are on it, signing up at better than 4,000 a week, and that revenue will pass $4 million this year. Home services is one of the verticals where it took hold first.

    The seat, in a real shop

    First response in a small shop is a person-shaped hole. The owner answers between jobs, one glove off. The office manager answers until five. After five, a service answers, or nobody does, and the prospect — wet floor, search results page in hand — calls the next name on the list. It’s a staffing problem, not a marketing problem — one that shows up at the exact hours nobody wants to staff.

    The money makes it worse. On Google Local Services, a connected call that runs past twenty seconds can bill you whether a person picked up or not — you pay for the ring. And the caller isn’t comparison-shopping at leisure. They’re standing in water, or sleeping in a 90-degree house, and they hire the first competent voice that treats them like a person.

    What the agent can own outright

    The front half of the seat is script work, and script work is exactly what an agent is for. Answer instantly, at any hour, in the customer’s own language — Dapta got its start with Spanish-speaking owners in the U.S., and first response is meeting the customer where they are. Ask the basic qualifying set: what happened, where is it, when did it start, who is paying, how do we reach you. Then do what most shops fumble even in business hours: put a real appointment on a real calendar, confirmed where the customer can see it — not a callback promise the morning forgets.

    None of that requires judgment — just the script, the calendar, and the discipline to run both at 2 a.m. the way they run at 10 a.m., on the nights the office sits empty.

    What the human keeps

    Qualification questions are not qualification judgment, and the difference is the entire ballgame. The questions collect facts. The judgment decides what the facts mean: Is this a job we want — at this size, this distance, for this payer, with the crews already buried? A flooded kitchen ten minutes away and a “come look at a stain” forty minutes out both answer the questions perfectly. Only one of them should get your Saturday.

    The human also keeps pricing, promises, and the handoff. What a job costs is a person’s call, made with the board in front of them. “We’ll have a crew there by nine” is a promise only someone who knows the crew should make. And the moment a prospect stops being a lead and starts being a customer — when they need to hear a real person owns their problem — a person takes the conversation. The agent’s job is to make that moment arrive fast, facts collected and appointment real. It is not to be that moment.

    The failure shape

    Hand an agent the whole seat — the questions and the judgment both — and it will qualify everybody. It will book the estimate outside your service area because nothing told it distance matters. It will fill the calendar with meetings a person would have filtered in thirty seconds — and once your techs learn to distrust anything the system books, you have automated the exact problem you bought it to solve. The bad version doesn’t fail loudly. It fails as a slow leak — wasted drive time, stood-up appointments — until somebody turns it off and announces that AI doesn’t work.

    The seat works when its boundary is drawn, not when the model is smart. A boundary is a list: what it can ask, what it can book, what it can never promise, and where it stops and hands over. Dapta’s own framing stops at answer, qualify, schedule — first response, not the close. That is not a limitation. That is the product, correctly shaped.

    How can AI handle after-hours calls for a service business?

    For a service business, handling after-hours calls with AI is a matter of strict boundary design rather than conversational cleverness. When a pipe bursts or an AC fails after the office closes, an AI voice agent can own the front half of the intake seat outright: answering instantly at 2 a.m. in the caller’s language, running the structured qualifying questions (what happened, where is the property, when did the damage start, who is paying, and how to reach them), and booking a confirmed appointment on a live calendar instead of leaving an empty callback promise.

    What the AI agent cannot own is the judgment. As detailed in What the human keeps, human dispatchers must retain pricing, arrival promises (“we’ll have a crew there by nine”), and the decision of whether a job fits current crew capacity and service territory. The danger, as shown in The failure shape, is handing an agent both the script and the judgment: without hard boundaries, it books calls outside your territory, clogs the schedule with low-margin jobs, and creates a slow leak of wasted drive time until crews distrust the system. An effective after-hours setup treats the agent as first response—capturing verified facts and locking in the calendar slot—and hands off the data to an automated operational workflow so morning crews arrive with complete context.

    Hire it like a person

    You would never hand a new receptionist the phone on day one with no script, no boundary, and no “if it’s this, come get me.” An agent seat deserves the same three things, because it is the same hire: a script it runs word for word, a boundary it does not cross on its best day, and an escalation path that puts a human in the conversation the moment judgment enters.

    The $6 million is a bet that every small business staffs this seat the way it eventually got a website. The operators who get it right will not be the ones with the smartest agent. They will be the ones who wrote the seat down — job, boundary, and the name of the human who owns the judgment — before they let anything answer their phone.

    Sources: “Dapta Raises $6M to Accelerate the Adoption of AI Sales Agents for SMBs across the U.S. and Latin America,” Dapta LLC via GlobeNewswire, October 13, 2026 — globenewswire.com. User, signup-rate, and revenue figures are Dapta’s own statements in that release.

  • Which AI SEO services are right for a small business?

    The right AI SEO services for a small business are the ones matched to where your customers actually ask questions. For most local service businesses, that means three things, in order: a business profile the machines can read, answer pages on your own website written the way customers ask, and a scheduled check that shows who the machines name.

    What are AI SEO services?

    AI SEO services are services that make a business readable to AI answer engines. A traditional search engine returns a list of links; an AI assistant returns an answer, and it names the businesses it can read clearly. AI SEO is the work of giving those systems clean material — profiles, pages, and consistent facts — to name you from.

    The category is new enough that the label covers very different work. One provider’s “AI SEO” is a rebuilt Google Business Profile and a page of real answers. Another’s is a software subscription and a monthly PDF. The sections below separate the kinds, so you can buy the work instead of the label.

    What kinds of AI SEO services are there?

    AI SEO services come in five kinds: listing and profile work, answer-page writing, citation cleanup across directories, one-time audits that measure where you stand, and ongoing retainers that bundle all of it. Most small businesses need the first three once, the audit before and after, and a retainer only when the market moves fast.

    • Profile work builds the listings machines read first: Google Business Profile on Google’s side, Bing Places on Microsoft’s — the listing Copilot and the assistants built on Bing read from.
    • Answer-page writing puts pages on your own website that answer customer questions in customer language, in passages short and plain enough to be quoted.
    • Citation cleanup makes your name, address, phone, and services agree across directories and aggregators — Yelp, Foursquare, Apple Maps, Angi, and the data feeds behind them.
    • Audits and scans measure the starting point: a fixed set of questions, asked before the work and after, with the answers kept.
    • Retainers bundle the above into monthly work. They fit businesses in fast-moving markets; they are a poor fit for one-time fixes billed forever.

    How is AI SEO different from traditional SEO?

    Traditional SEO earns a position on a list of links; AI SEO earns a mention inside an answer. The list rewards the page; the answer rewards the clearest source. Both run on the same foundations — a readable website, consistent business facts, reviews, and real expertise — but the AI layer reads quotable passages, not just pages.

    That difference changes what good work looks like. A page stuffed with keywords can rank and still never be quoted, because there is no clean passage to lift. A plainly written answer — the question as the heading, the answer first, the detail after — gives an assistant something it can repeat word for word. Traditional SEO is not replaced by this; it is the floor it stands on.

    What should a small business buy first?

    A small business should buy in the order a customer asks. First, the profile a machine reads when someone asks for your trade nearby — your Google Business Profile and your Bing Places listing. Second, answer pages on your own site. Third, a measurement check. Software subscriptions and content volume come last, if at all.

    The order matters because the surfaces compound. An assistant answering “who does this work near me” starts from profiles and listings, then checks what your website says. A beautiful website behind an empty profile is invisible at the first step. A strong profile pointing at a website with no answers gives the machine nothing to quote. Buy the chain in order and each link makes the next one worth more.

    How much do AI SEO services cost?

    AI SEO services are sold three ways: one-time builds, monthly retainers, and small diagnostics. The honest difference is not the label but what you can hold afterward — a finished profile and pages you own, or a report you can re-run. Any price is too high for work you cannot inspect when it is done.

    Price follows scope: number of locations, number of services, number of towns you serve. What should make you careful is shape, not size. One-time work — a profile build, an answer page, a listing cleanup — should carry a one-time price. Monthly money should buy monthly work you can name: new questions tested, new answers written, changes logged. If a provider cannot tell you which of your dollars are one-time and which recur, that is the answer to whether to sign.

    What questions should I ask an AI SEO provider before I pay?

    Ask an AI SEO provider five questions before you pay: What exactly will exist when you are done? Which questions will you test, and can I see the answers before and after? What do you not control? What does the work cost once, and what recurs? Who owns the pages and profiles afterward? Ask us the same five.

    Each question has a tell. “What will exist” should produce a list, not adjectives. “Which questions” should produce your customers’ actual questions, written down. “What do you not control” is the honesty test — no provider controls which businesses an assistant names, and one who promises a ranking is telling you how the rest of the engagement will go. Ownership is the quiet one: profiles and pages built on your accounts, in your name, stay yours if you leave. Anything else is rent.

    What proof should an AI SEO service show me?

    An AI SEO service should show you a named report, a date range, and the questions it tested — not a screenshot of a ranking. On our own site, the proof habit looks like this: our Bing AI Performance report for tygartmedia.com, covering six months of Microsoft Copilots and partners, shows 1.5M total citations across an average of 164 cited pages.

    Read those numbers the way we do. They are our own footprint on one measured surface — evidence that the measurement exists and that we live under it — not a promise about your business. AI answers also churn: the same question asked next month can name different businesses, which is why honest proof is a before-and-after on your questions, re-asked on a schedule, with the raw answers kept. A provider who shows you their own numbers should be just as willing to show you yours.

    Can I do AI SEO myself?

    Yes — the free layer of AI SEO is real work any owner can do: claim and complete your Google Business Profile and Bing Places listing, write your services in plain language, and answer your customers’ common questions on your own site. What you pay a provider for is the audit discipline, the writing time, and the measurement habit.

    Be honest with yourself about which of those three you will actually do. The profile most businesses already “have” is a name, a pin, and hope — claimed years ago and never finished. The knowledge is not the scarce part; the finished, checked, written-down work is. If you will do it yourself, the sections above are the whole recipe, in order, and they will work the same for you as for us.

    Where does our own offer fit?

    If you want to know where you stand first, our AI Citation Quick-Scan runs 10 prompts about your service line and returns a scored report within 7 days — $97, one time. If you want the build done, the Ask Maps Protocol is our version: $450, one time — a mobile-first audit of how your listing actually renders, your Google Business Profile rebuilt for answers, an FAQ answer page on your website, your Bing Places listing claimed and matched, and a 30-day proof check.

    Which lines the platforms lift is their call. We build the material they lift from — and then we measure what they did.

  • The Best Clawback Product Reads the Notice Against the Rule

    The Best Clawback Product Reads the Notice Against the Rule

    The agency already set the withholding rule. The family still holds a notice that may not match it. That gap is the product.

    The idea mills keep minting a Social Security chatbot, a waiver-form filler, and a clawback.ai. Three names. One object. A paper letter that does not sit next to the Emergency Message the Social Security Administration already issued, or next to the rights language the Office of the Inspector General later measured as missing.

    Greg Isenberg’s stream and the daily micro-SaaS accounts keep splitting the same reader. One post wants an agent that finds class-action money in your inbox. Another wants a refund chaser for marketplace sellers. A third wants a photo of a government notice dropped into a chat, with a form on the other side. The useful cut is narrower. The notice is already in the mailbox. The rule is already public. The join is the company.

    Why now is a number, not a feeling

    On April 25, 2025, SSA issued Emergency Message 25029. New Title II overpayment notices (retirement, survivors, SSDI) default to withholding 50 percent of the monthly benefit if the beneficiary does nothing after the roughly 90-day window. That replaced the 10 percent cap that had been in place for most of 2024. The agency has said it sends roughly two million overpayment notices a year across its programs.

    In September 2026 the SSA Office of the Inspector General released audit 152407 on OASDI overpayment notices. Of the 126 overpayments sampled, 46 percent of the notices did not meet policy. Missing explanations of how and when the overpayment occurred. Omitted reconsideration and waiver rights. Inaccurate dollar amounts. Conflicting language. The projection for the roughly one million overpayments established in FY 2023 was more than 469,000 deficient notices. Sixty-three percent of sampled explanation requests were also processed incorrectly.

    Those two facts sit next to each other. The default recovery rate went up. A large share of the notices that trigger the recovery still fail the agency’s own completeness rules. The adult child who opens the letter does not need a chatbot. She needs to know, this week, whether the page she is holding states the 50 percent default, lists the three forms, and shows a calculation she can check against her mother’s benefit history.

    Two primitives, one wedge

    Primitive one is the photo or PDF of the private notice. The mills have been shipping receipt readers for months. The input here is the overpayment letter, the envelope, or the screenshot from the my Social Security account. Amount claimed. Period covered. Withholding language. Rights language. Deadline.

    Primitive two is the public rule and the public file. EM-25029 and its later revision. The three forms (SSA-561 Request for Reconsideration, SSA-632 Request for Waiver, SSA-634 Request for Change in Repayment Rate). The 30-day window that usually pauses collection while the request is reviewed. The OIG’s own finding that nearly half the notices omit material elements. Nothing here is secret. The agency was required to write the rule and the forms. The OIG was required to measure the notices.

    The product is the join. Photograph the notice. Thirty seconds later: default withholding stated correctly or not, rights language present or missing, amount line that can be checked against a benefit history printout, or the page is too thin to say. No account for the first answer. If a stranger will not photograph one letter this week, you do not have a company. You have a policy thread.

    The compounding path is the labeled map, not a third dashboard

    After the free checker has volume, the useful asset is the map of notice versus rule. Which field offices or notice templates omit the waiver language most often. Which calculation methods produce the largest unexplained gaps. Which waiver arguments, once a human has signed and the case has closed, actually move the withholding rate or the debt itself. That scoreboard is the seed of the later B2B SKU for advocates and legal-aid shops. It is not a dashboard of “possible savings.” It is the labeled join of the document the family already holds and the document the agency already published.

    Models draft the packet. People own the send. Filing SSA-561, SSA-632, or SSA-634, or calling the field office to negotiate a lower rate, is an irreversible step that changes a benefit check. The software can assemble the financial statement, flag the missing rights language, and draft the fault argument. A human signer presses the button. Charge after the free verdict shows a clear mismatch, or do not charge. Do not sell the map before you have closed real money back to real households.

    What not to build

    Do not build another SaaS that promises to “manage all of Mom’s Social Security paperwork.” That is a platform. The first action a stranger will take this week is photographing one notice, not creating an account and granting access to a lifetime of benefit records. Do not build an AI that files the form without a human on the send. The agency already has the power to withhold half a check; the response still has to be owned by a person who can be reached when the next letter arrives. Ignore the new .ai names. Join the line the notice and the rule already form.

    Why this cut, not the last one

    The leakage essay was tariffs, seats, and subscriptions. The rebate essay was a nameplate. The recall essay was a label. The short-pay essay was a contractor packet. The bill essay was an EOB against a hospital file. The tax essay was a notice against the roll. The utility essay was a statement against a filed tariff. The housing essay was a unit against a score. The delay essay was an itinerary against a code. The HOA essay was an assessment against a study. The 401(k) essay was a fee against a filing. The pharmacy essay was a receipt against an acquisition file. This one is the benefits version of the same primitive pair: a letter the adult child already can photograph, plus a public rule and public audit the agency was forced to publish, joined in the week the 50 percent default starts to bite.

    The noticing used to require a benefits counselor and a long hold. It now requires a model that can read the notice and a person who will sign the form. Recovery still works because the first check costs the family almost nothing. Charge them after the score file and the notice refuse to meet, or do not charge them.

    Someone will own the labeled map of notice versus rule. The mills will keep proposing a new .ai name for each SSA form. Ignore the names. Join the line. Keep the map.

    Will Tygart — Tygart Media.

    This is the idea-mill series.

  • What Are the Best Claude-Notion Workflows for a Small Business?

    Short answer

    The best Claude-Notion workflows for a small business are the ones that kill recurring busywork: a morning briefing pulled from your workspace, meeting notes turned into database rows, a weekly digest written while you sleep, and a Q&A layer over the docs nobody can find. Four workflows, set up once, paying rent every week.

    Before you automate anything

    Connect Claude to Notion first via the MCP connector (OAuth through Claude Desktop, two minutes), share the pages Claude needs to see, and set the approval habit: Claude drafts, you approve. Every workflow below assumes that foundation. Start with one workflow, not four.

    Workflow 1: The morning briefing

    Problem: You open Notion and spend 20 minutes figuring out what matters today.
    Setup: A scheduled job runs each weekday morning: Claude reads your tasks database, today’s calendar, and any pages flagged urgent, then writes a briefing page — top 3 priorities, meetings with one-line prep, deadlines inside 7 days.
    Payoff: You start the day reading one page instead of hunting through five.

    Workflow 2: Meeting notes → database rows

    Problem: Action items die in meeting notes.
    Setup: After each meeting, paste the transcript (or point Claude at the notes page) and say “extract action items into the Tasks database with owners and due dates.” Claude creates the rows, sets properties, links them to the meeting page.
    Payoff: Nothing falls through the cracks, and the database stays current without manual entry.

    Workflow 3: The weekly digest

    Problem: Friday status updates eat an hour of writing.
    Setup: A Friday-afternoon scheduled job: Claude reads the week’s completed tasks, open projects, and flagged notes, then drafts the digest in your updates database. You review, edit, approve.
    Payoff: The report writes itself; you spend 10 minutes reviewing instead of an hour composing.

    Workflow 4: Ask your workspace anything

    Problem: “Where did we put the client’s brand guidelines?” — asked weekly, answered by archaeology.
    Setup: No setup beyond the connection. Ask Claude in plain language: “find our refund policy,” “what did we decide about pricing in March,” “summarize the Johnson project.” It searches the whole workspace and answers with links.
    Payoff: Institutional memory becomes queryable. New hires onboard themselves.

    Workflow 5: Proposal and quote drafting

    Problem: Every proposal starts from a blank page.
    Setup: Keep a proposals database with past wins. “Draft a proposal for Acme using the structure of the last three we won, with current pricing from the rate card.” Claude drafts it into a new page; you refine and send.
    Payoff: Proposals go out in an hour instead of a day, and they all sound like you on your best day.

    How do I automate Notion workflows with Claude?

    Two layers. Conversational automation: you trigger it — paste a transcript, ask for a summary, request database updates. No setup beyond the MCP connection. Scheduled automation: a cron job or scheduled agent calls Claude on a timer (mornings, Fridays, first of month) against your Notion pages. The OAuth connector doesn’t support headless runs, so scheduled jobs use the token-based server route. Start conversational, promote the winners to scheduled.

    What this costs a small business

    The connector setup is a one-time hour. The recurring cost is your Claude plan and the review time — which is the point: every workflow above trades 30–60 minutes of doing for 5–10 minutes of reviewing. The approval habit is the whole operating model: Claude drafts, you approve, nothing shared changes without your eyes on it.

    Frequently asked questions

    What are the best Claude-Notion workflows for a small business?

    Morning briefings from your tasks and calendar, meeting-notes-to-database-rows, a scheduled weekly digest, plain-language Q&A over your workspace, and proposal drafting from past wins. Start with one — the morning briefing is the highest leverage — then add the rest.

    How do I automate Notion workflows with Claude?

    Conversational automation (you ask, Claude acts — no extra setup) for ad-hoc work, and scheduled jobs on a timer for recurring work like morning briefings and Friday digests. Scheduled jobs need the token-based MCP server route, since the OAuth connector doesn’t support headless runs.

    Do I need a developer to set this up?

    No. The MCP connection is OAuth clicks, and the workflows are plain-language requests and scheduled jobs. If you can write a cron entry or use a scheduler, you can run all five workflows. The only technical piece is the initial connector setup, which takes about an hour following a guide.

    Related: Notion MCP setup with Claude · Securely connect your workspace

  • Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Updated November 13, 2026 — facts, pricing tiers, models, and field-sheet PDF verified against live Anthropic documentation.

    Direct Answer · Verified November 13, 2026

    Claude for ecommerce gives store owners leverage across four operational lanes: product catalog content & GTIN hygiene, customer support triage, back-office SOPs & sales reporting, and readiness for AI shopping agents (claude.com/solutions/commerce). Solo owners start on Free ($0, up to 5 Projects) or Pro ($20/mo, or $17/mo annual); multi-person teams move to Team Standard ($20/seat/mo annual / $25 monthly); and bulk catalog jobs use the API (Sonnet 5.5 $2/$10, Haiku 5.5 $0.10/$0.50 ≤100K, plus 50% off Batch API). Compare interactive seat tiers and 50%-off Batch API token math on our Claude AI pricing guide.

    ECOMMERCE FIELD SHEET
    Claude for Ecommerce Owners — Tygart Media Field Sheet (PDF)
    Consolidated ecommerce playbook: 4 store lanes, 100+ SKU prompt specs, ad copy variants, WISMO/dispute templates & 50%-off Batch API math. Verified 2026-11-13.

    Claude for ecommerce means using Anthropic’s Claude AI across the jobs around selling online — writing product content, answering customer questions, cleaning up catalog data, and getting your store ready for the AI shopping agents that are starting to buy on customers’ behalf.

    Not hype. Not a robot that runs your store. Just a very capable assistant pointed at the work that eats your week. Here’s what that looks like in practice.

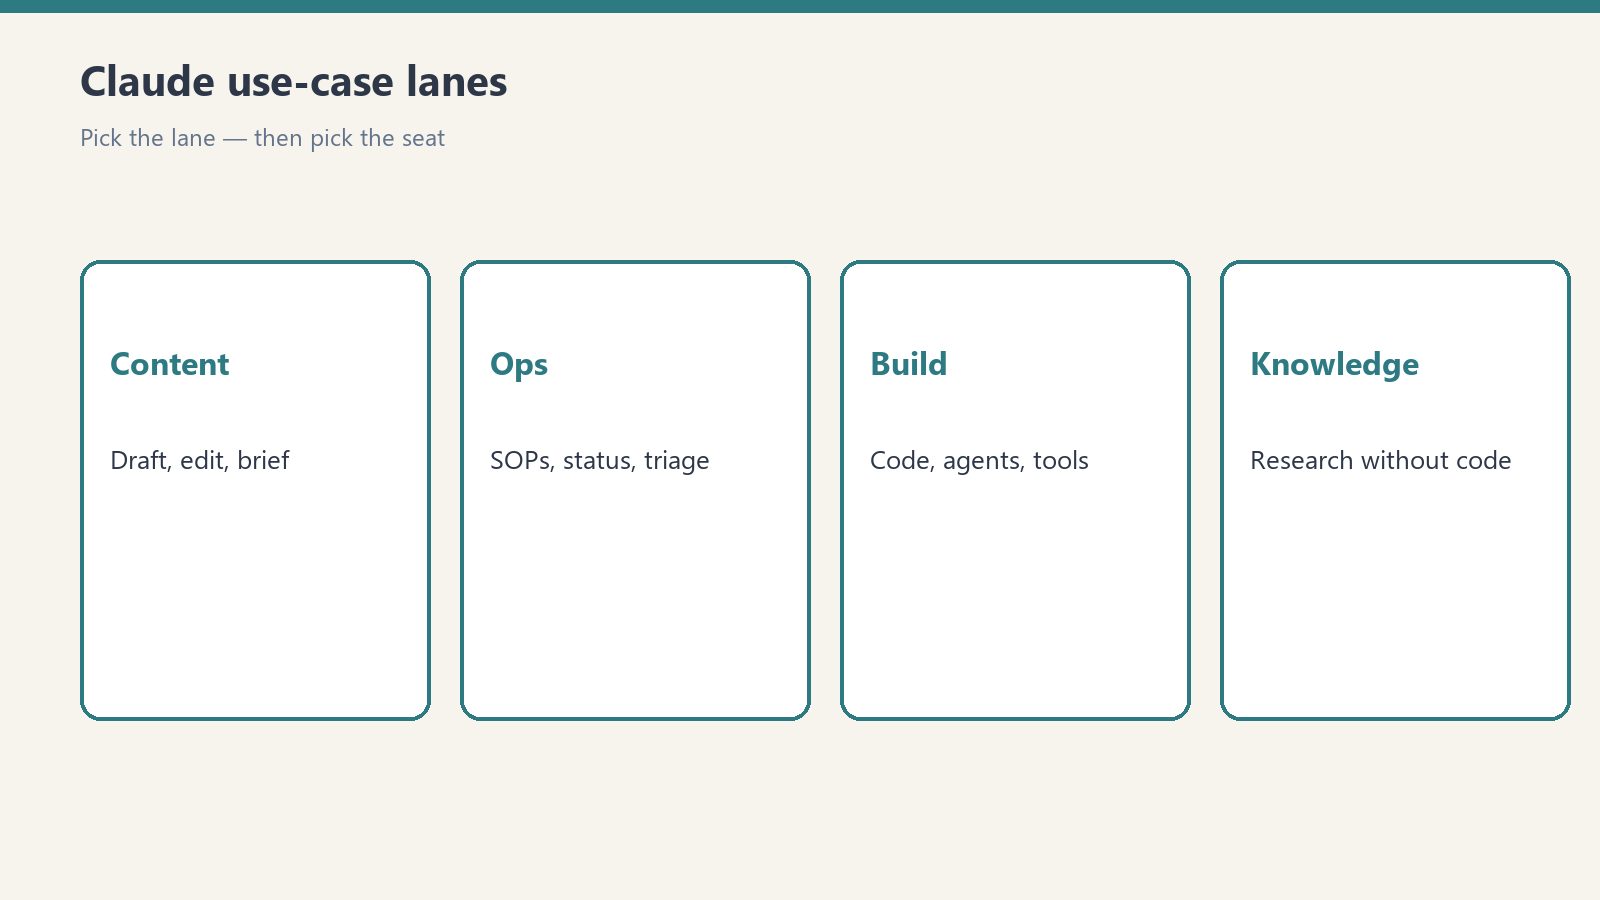
    The Four Lanes

    Every ecommerce use of Claude falls into one of four lanes. Pick the lane with the most pain first.

    1. Product content

    Write and fix product descriptions at scale. Anchor a Claude Project with your brand voice guide, top-converting listings, and SEO targets, then run a consistent prompt schema: product name, key specs/features, target customer, primary keyword, tone (technical, approachable, or luxury), and desired length. Claude drafts titles, bullets, meta descriptions, and alt text so your team edits instead of staring at a blank page — keeping consistency from SKU #1 to #500. For automated 100+ SKU runs, the 50%-off Anthropic Batch API drops rates to Sonnet 5.5 Batch $1/$5 MTok or Haiku 5.5 Batch $0.05/$0.25 (≤100K).

    Ad copy variants & bulk SEO metadata. Feed a hero product, its top 3 benefits, the core pain point, and buyer profile to generate 10 Meta/Instagram ad variants testing distinct hooks, angles, and CTAs in minutes, then promote the strongest 3–4 into paid testing. For large catalogs with neglected category/product tags, batch exported SKU lists alongside keyword targets to produce optimized title tags and meta descriptions in an afternoon rather than a week.

    Clean your catalog. This is the unsexy one that pays the most. Missing GTINs, inconsistent size formats, half-empty attribute fields — Claude reads a product export and tells you exactly what’s broken, row by row. Clean catalog data is also what AI shopping agents read when they decide whether to recommend your products, so this work compounds.

    2. Customer conversations

    Pre-sale questions. “Does this come in blue?” “Will it arrive by Friday?” “What’s your return policy?” Claude-powered chat answers these from your actual policies and product data — not from a script that breaks the moment someone asks something unexpected.

    Support triage. Claude reads the incoming ticket, pulls the order details, and drafts the response or routes it to the right person with a summary. Your team stops starting from zero on every message.

    WISMO templates & policy-holding returns/disputes. Support queues skew 80% toward repeatable scenarios: WISMO (where is my order), return requests, damaged-product claims, wrong items received, and refund follow-ups. Build a 20–30 template library grounded in your exact store policies, plus diplomatic “policy-holding” drafts for out-of-policy return denials, chargeback responses, and wholesale complaints — reviewed by human agents before sending so tone stays firm yet customer-preserving.

    3. Back-office ops

    Supplier and vendor email. Drafting, summarizing threads, pulling action items out of long exchanges. The inbox work nobody wants to do.

    Reporting in plain English. Feed Claude your sales export and ask what changed this week, which products are slipping, and what’s driving the shift. You get the insight without building the dashboard first.

    SOPs and training. Turn “how we do returns” from tribal knowledge into a written process a new hire can actually follow.

    4. Getting agent-ready

    This is the lane most owners are missing. AI shopping agents — built on Claude, among others — are starting to complete purchases on behalf of buyers. They don’t browse your site. They read your structured data: product feeds, schema markup, policies as data.

    Claude helps you become the store agents recommend: auditing your product data for completeness, generating the structured content agents consume, and testing your checkout the way an agent experiences it. The merchants who do this work now get recommended. The ones who don’t get skipped — quietly, by software, at scale.

    What It Costs to Start

    Less than you think. Individual store owners start on Free ($0, up to 5 Projects) or Claude Pro ($20/mo, or $17/mo annual / $200 upfront) for conversational drafting and analysis; multi-person ecommerce teams use Team Standard ($20/seat/mo annual or $25 monthly) or Premium ($100/$125, 5× Standard); and automated catalog cleanup or ticket triage runs on the API (Sonnet 5.5 at $2/$10 MTok, Haiku 5.5 at $0.10/$0.50 ≤100K, plus 50% off Batch API). See the numbers in our Claude AI pricing, plans & limits guide or inspect official retail patterns on claude.com/solutions/commerce.

    The expensive part was never the tool. It’s the hour you spend figuring out where to point it first. Start with one lane, one workflow, one repeatable job. Get that working before you add the second.

    What Claude Won’t Do

    Honest limits, because overselling helps nobody:

    It won’t run your store. Pricing decisions, supplier relationships, and judgment calls stay human. Claude drafts; you decide.

    It needs checking on anything customer-facing. Product descriptions, policy answers, support replies — review before they ship, especially early. The error rate drops as you tune it, but the review habit shouldn’t.

    It doesn’t replace your data. Claude is only as good as what you feed it. Wrong inventory data in, confident wrong answers out. Fix the source data — that’s lane one for a reason.

    Getting Started: The First Week

    Day 1–2: Pick one job. The one you dread most that happens every week. Product descriptions, support replies, inbox triage — one thing.

    Day 3–4: Show Claude how. Give it 3–5 examples of the job done well. Examples beat instructions every time.

    Day 5: Run it supervised. Let Claude do the job, review everything, correct what it gets wrong. The corrections are training.

    Week 2: Loosen the grip. Once the output is consistently right, review spot-checks instead of everything. Add the second job.

    Related Reading

    The Next Step · Verified Research Verdict (November 13, 2026)

    Next Step: Start One Lane or Scope Automated Catalog Pipelines

    Run one supervised workflow this week on Pro ($20/mo) or review Anthropic’s retail patterns at claude.com/solutions/commerce. Compare Team seats and 50%-off Batch API economics directly on our Claude pricing hub.

    ECOMMERCE FIELD SHEET
    Claude for Ecommerce Owners — Tygart Media Field Sheet (PDF)
    Download the consolidated ecommerce reference sheet (SKU prompts, ad/SEO batching, WISMO templates, and Pro/Team/Batch API rates). Verified 2026-11-13.