Tag: Agency Operations

  • Receipts: 105 Dead Clicks — and Why We Changed Nothing

    Receipts: 105 Dead Clicks — and Why We Changed Nothing

    Our analytics flagged 105 dead clicks on our Claude pricing pages this week. Dead clicks are supposed to mean friction — people clicking things that don’t work. The fix, if you believe the dashboard, is a redesign ticket.

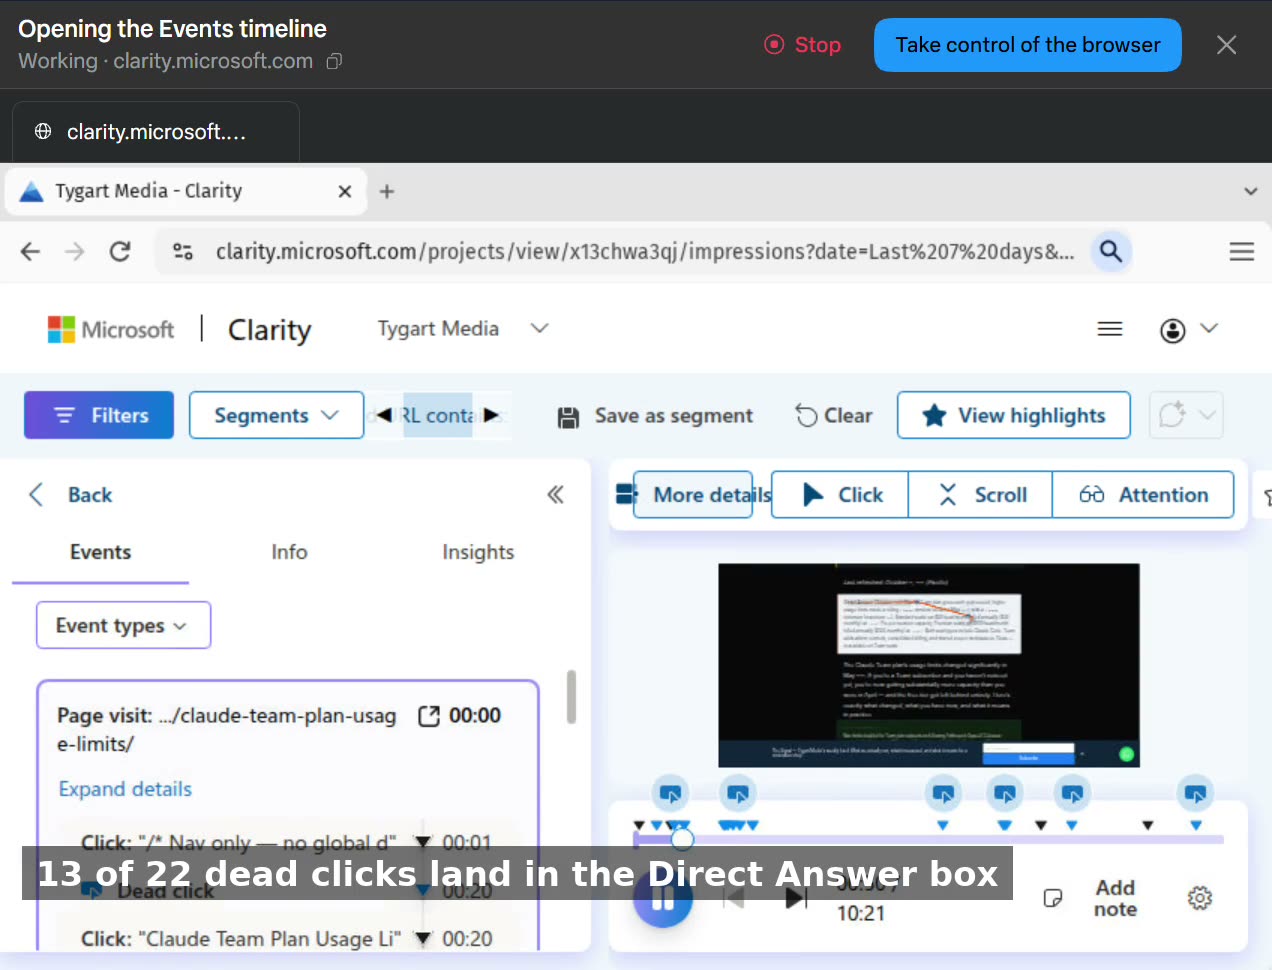
    So we watched the recordings. All of them, session by session. This video is that walkthrough, narrated as it happened: the three filters that isolate the signal, then the two densest sessions read event by event.

    Every flagged click was a reader selecting text. On the enterprise pricing page, one visitor accounts for all 17 dead clicks — four and a half minutes on the page, highlighting as they read. On the team-plan usage-limits page, 13 of the 22 dead clicks land inside the Direct Answer box at the top of the article: people selecting the summary to copy it out. Nobody clicked a broken button. Nobody clicked a price that wouldn’t respond. The one honest exception is a bold line inside a call-to-action block that got clicked like a button, four times — the only element on either page we’d even consider changing.

    If we’d worked from the dashboard alone, we’d have “fixed” pages that are doing their jobs — and probably broken the format that makes them get cited in the first place.

    This is the part of analytics nobody sells you: the number is a question, not an answer. The recording is the answer — if somebody actually watches it.

  • The Best Agency for AEO SEO Reporting Is the One Whose Numbers You Can Re-Pull

    The Best Agency for AEO SEO Reporting Is the One Whose Numbers You Can Re-Pull

    Updated Nov 1, 2026 — added the free AEO reporting quick card, re-pullable AEO report pack, and report auditor bot book downloads to this guide.

    If you are comparing agencies specifically on their AEO and SEO reporting, you have probably already been burned the standard way: a glossy dashboard, a score that only goes up, and no way to check any of it against a source the agency doesn’t control. Reporting is where this industry hides. So here is the standard we would hold any agency to — including the one writing this page — stated as five sections a real monthly report contains, the ownership rule that matters more than all of them, and our own current numbers filled in as the sample.

    Instant Operational Downloads

    The Re-Pullable AEO Reporting Framework: Free, $7 & $17 Buyer Tools

    Demand the 5-section monthly report standard, verify source Bing/Clarity exports, lock commercial query share in Month 1, and run forensic AI audits on past agency deliverables.

    Field Quick Card
    FREE

    AEO Reporting Quick Card

    2-page field summary: The five sections of a report you can re-pull — ledger summary, share on queries that pay, page movers, new questions, work priced against movement — plus the non-negotiable ownership rule and bad-reporting spotter on one card.

    Download Free PDF

    Direct download • No email gate

    Working Field Pack
    $7

    The Re-Pullable AEO Report Pack

    Printable/fillable 6-page working pack: 5-section monthly report checklist, ledger summary log template, money-queries share table, page movers log, new-questions action sheet, ownership + re-pull rule sheet, and bad-reporting spotter quick-reference.

    Get Report Pack ($7) →

    Instant checkout • Square verified

    AI Intensive
    Book for Bots
    $17

    Feed-Your-AI Auditor

    Feed to ChatGPT or Claude: 8-page executable playbook with 6 interactive AI routines (Re-Pull Verification Interview, Money-Query Share Audit, Page Movers Diagnostic, New-Questions Paper-Trail Builder, Flat-Result Honesty Check, Bad-Reporting Detector) plus embedded router.

    Get AI Auditor ($17) →

    Software made of words • Instant delivery

    Section one: the ledger summary

    A real report opens with your citation totals and their direction — this window against last window, from the engine’s own export. Ours, for this site, reads: 1,459,726 total citations across 922 cited pages in the October 15 export, against 269,399 across 324 pages on September 27. Two numbers, two dates, one source anyone can re-pull. A report that gives you a total without the previous window’s total is giving you a photograph and calling it a trend.

    Section two: share on the queries that pay

    Totals flatter; share tells the truth. The second section lists the handful of questions your buyers actually ask an AI, and your citation share of each — for us, 24.50% on “claude pricing,” 33.85% on “claude ai pricing,” 54.46% on “anthropic console” in our software coverage. If an agency’s report never names your money queries, it is because the answer would end the meeting. Make them name the queries, in writing, in month one — then the share line becomes the whole relationship in one table.

    Section three: the page movers

    Which pages climbed, which consolidated, which are being starved — named by URL, with figures. Our current read: the certification guide at the center of our contractor work climbed 1,635 → 1,913 → 2,454 → 2,790 citations across four exports while its duplicate was consolidated from 304 down to 6. That single line tells a client more than forty pages of charts: where the engine is placing its trust, and what the agency did about it. A report without named pages is a report about nothing in particular.

    Agency Evaluation Toolkit

    Don’t Rent Your History: Audit Agency Numbers From Your Own First-Party Exports

    If your agency reports anonymous averages or hides behind proprietary visibility scores, demand the 5-section re-pull standard before signing. Whether you need printable working logs, money-query share tables, and 4-export page mover diagnostic sheets ($7), or an autonomous AI auditor to cross-examine their deliverables, flag vanity bot totals, and generate binding contract redlines ($17), equip your team with forensic arithmetic.

    📊

    What’s In The Toolkit:

    • Ledger Summary Log: Sept 27 vs Oct 15 model.
    • Money-Queries Share Tracker: Month 1 query locking.
    • Page Movers Tracker: 4-export climber & consolidation logs.
    • New-Questions Action Sheet: Grounding query paper trail.
    • AI Audit Routines: 6 automated auditor workflows.
    Both tools grounded 100% in Post 25636 substance. Instant delivery.

    Section four: new questions, and what got built against them

    Every export surfaces grounding queries you have never seen — the market asking new questions in the open. Section four lists them and ties each to an action: published, queued, or deliberately passed on, with the reason. This is the section that proves the work is demand-led rather than calendar-led, and it’s the first section a lazy agency quietly drops, because it creates a paper trail of promises.

    Section five: the work, priced against the movement

    What was done, what it cost, what moved, what’s next — in that order, on one page. Not a ticket dump. If three articles shipped and the share line didn’t move, the report should say so and say what changes next month. The month the report stops admitting flat results is the month it became a sales document.

    The ownership rule that outranks all five sections

    Every figure in the report must be re-pullable by the client, from the client’s own accounts. Bing Webmaster and Microsoft Clarity are free; the exports belong to whoever owns the property. If your agency generates its numbers inside its own portal, from its own panel, under its own login, then leaving the agency means leaving your history — and a report you can’t verify is a report you’re renting. We run our tracking exactly this way, and the method is published so a client can audit it without us in the room. These five sections, by the way, are the receipts from the buyer’s test wearing their monthly clothes: the test is what you demand before signing; the report is what you should receive after.

    Compare the Three AEO Reporting Toolkits

    Choose the right level of rigor for evaluating finalist agencies and monthly deliverables.

    Feature / Capability Free Quick Card Working Pack ($7) AI Auditor Book ($17)
    Asset Format 2-Page Field Summary 6-Page Printable Pack 8-Page Executable AI Playbook
    5-Section Monthly Checklist ✓ Reference Table ✓ Fillable Master Form ✓ Automated Bot Audit
    Ledger Summary Log Template Summary Rules ✓ Full Working Log ✓ Re-Pull Interview Bot
    Money-Queries Share Tracker Benchmark Table ✓ Month 1 Lock Register ✓ Commercial Query Audit
    Page Movers 4-Export Tracker Progression Model ✓ Named URL Worksheets ✓ Cannibalization Diagnostic
    New-Questions Action Sheet Workflow Summary ✓ Paper-Trail Sheet ✓ Demand-Led Bot Builder
    Bad-Reporting Spotter (5 Tells) ✓ Red Flag Table ✓ Diagnostic Sheet ✓ Automated Detector Scan
    Interactive AI Routines — — ✓ 6 Dedicated AI Routines
    Action Free PDF Buy Pack ($7) Buy Bot ($17)

    What bad reporting looks like, so you can spot it in the wild

    A proprietary visibility score with no export behind it. A screenshot of the best week of the quarter. Engines blended into one soup so a Bing collapse hides inside a ChatGPT anecdote. Vanity totals — citations counted without share, traffic counted without asking how much of it was bots (on our fleet this month, roughly six visits in ten were automated; a report that never mentions that is averaging two different worlds). And the tell of tells: a report that arrives as a presentation, live, with no file you keep.

    How to choose, then

    Before you sign with anyone — us included — ask each finalist for last month’s report for a current client, redacted as needed, and for the source exports behind one number in it. The best agency for AEO SEO reporting is not the one with the prettiest dashboard or the boldest score. It is the one whose report survives your re-pull: same exports, same windows, same figures. Everything else is a pitch. The report is the product demo that can’t be rehearsed — judge that.

  • AI Governance Is the Gate That Caught the Thing

    AI Governance Is the Gate That Caught the Thing

    Most AI governance is written by people who have never had to govern an agent that could actually break something. It reads like insurance paperwork: frameworks, maturity models, principles laminated on a wall. Then a real agent, on a real Tuesday, publishes your drafting notes as if they were the article — and the framework has nothing to say about it, because the framework was never in the room.

    We run a small agency where AI agents do real production work every day: research, drafting, publishing, measurement, and an unattended night queue that runs while we sleep. Governance, for us, is not a document. It is the set of gates that have caught real things. Every rule below exists because something specific got past us first, and the rule is the scar.

    Governance starts with who is allowed to remember

    The agents are stateless; the memory lives in one place. Every agent we dispatch starts cold. It knows nothing about our clients, our sites, or yesterday’s decisions until its work order tells it. That sounds like a limitation. It is the control surface. Because the agent holds no standing memory, it holds no standing permissions either — every job is scoped, priced, and bounded by the order that created it, and when the job ends, the access ends with it.

    The work order itself is a governance document. It states the whole price up front, names the points where a human must tap before work proceeds, and lists what the executor may ship directly and what it must hold. An agent that has to ask a question the order should have answered is not a governance failure by the agent. It is a drafting failure by us, and we treat it that way.

    Draw the doors as lines, not policies

    Four things always need a human tap: money, credentials, outbound sends, and publishing. Everything else, the fleet runs on its own. That split is the entire access policy, and it fits in one sentence because it has to survive contact with a tired operator at the end of a long day. Policies that need interpretation get interpreted — usually at the worst moment, in the most generous direction.

    Credentials get the hardest line. Our agents never hold passwords, never see them, never pass them along. Work that reaches a login the agent cannot complete through an already-signed-in session does not get worked around. It stops, logs a hold, and waits for the human whose door that is. One night this fall, a run reached a registry login at three in the morning. The operator could not face the tap, said so, and went to bed. The work was built to survive stopping, so stopping cost nothing. The credential never moved. That is what a line is for: it has to hold when nobody has the energy to argue with it.

    The risk is not a rogue agent. The risk is a report you believe.

    Every serious failure we have had was a verification failure, not a rebellion. A judge model, asked to grade drafts against a length limit, invented word counts that were off by a quarter to a third — confidently, in both directions. A publish report stated a post ID from memory instead of reading it back from the result file, and the number was wrong. A page was verified from its HTML source and declared fine while its signup form rendered as blank white cards. Drafting notes were once published as article content because the check stopped at “the words are there.”

    So the rule is mechanical: proof lives at the receiving end. Numbers get read back by value from the file that recorded them. Pages get verified as rendered pages, in a browser, the way a reader sees them — not from source. A finished article must show visible structure, or it is a hold, not a publish. None of this requires trusting the agent less. It requires trusting the report exactly as far as the evidence under it, which is where trust should have been calibrated all along.

    We also measure trust per model, the way you would per employee. In scored head-to-head runs on identical briefs, exactly one of our models graded perfectly — every defect real, no invented ones — so that model holds the verifier seat. Another writes fast and clean but invents defects when it judges, so it drafts and never judges. The cheapest tier once certified work it had not actually checked, so its output is never trusted without a pass behind it. “The AI said so” is not a control. A scorecard is.

    Failures become regressions, not folklore

    Every break gets an ID, an entry in the failure ledger, and a gate. When the night queue failed in a new way, the failure was written down with its cause and its receipt, and a regression check was built that fails the next run if the same shape reappears. The ledger is unglamorous. It is also the difference between an operation that learns and an operation that just has stories. Governance that lives in people’s memories leaves with their mood, their weekend, and eventually their employment. Governance that lives in a gate runs every time.

    Each work order also carries one pre-decided instruction for the moment something breaks: if a step’s end state cannot be verified, stop that step, log the hold, and move to the next independent step. Never improvise past a failed check. The decision is made in advance, in calm, because the middle of a failing run is the worst possible place to invent policy.

    The 3 a.m. test

    Here is the only governance question we ask anymore: what can this system not do at 3 a.m.? Our night queue runs unattended with hard caps — a maximum number of jobs, a maximum number of attempts, a hard stop before dawn, and a pause switch that halts everything if a single file exists. Agents working overnight cannot spend money, cannot send anything to anyone, cannot touch a credential, and cannot publish. They can draft, measure, and report. Morning is a review: a human reads what the night produced, approves what is good, and the approvals are the fuel for the next day’s work.

    That is the whole philosophy. Governance is not the set of things your agents are allowed to do. It is the set of things they structurally cannot do while you are asleep, plus the evidence trail that lets you check everything else over coffee.

    What this is not

    This will not satisfy a compliance department, and it is not meant to. If you handle medical records or other people’s money under regulation, you need the paperwork kind too. But the paperwork kind alone will not save you from the ordinary failures — the believed report, the generous interpretation, the confident invented number — because those failures are not compliance failures. They are operating failures, and they happen at every scale, in shops with two people and in companies with two thousand.

    Start where the risk actually is. Give the agents no memory and no keys. Draw four doors and hold them. Verify at the receiving end. Write every failure down and make it a gate. Then run the 3 a.m. test on your own setup, honestly, and fix what it shows you. The framework can come later. The gate that catches the thing comes first.

  • The Work Order Desk

    The Work Order Desk

    New on the bench this week: the Work Order Desk.

    Four fixed-price jobs, each with a written definition of done and a proof sheet when it ships:

    • GA4 baseline + key events, $450
    • Citation scan + repair, $450
    • Fleet friction pass, $750
    • Sourced research run, $750

    You submit the form. You get a receipt with a work-order number. You get a written verdict within one business day. The price is agreed before anyone pays — the checkout link rides inside the verdict, after triage, not before it.

    No calls. No retainer pitch. No “let’s hop on a quick Zoom” standing between you and a finished piece of work.

    Before we told anybody about it, we ran a test work order through it ourselves — form, receipt, logging in two places so a submission can’t silently vanish. That last part is the whole design. A front door that loses orders quietly is worse than no front door.

    Built it this week. It works. Doors open as soon as the address is on it.

  • Move the Design System Before December 14 — the Chat Does Not Come With It

    Move the Design System Before December 14 — the Chat Does Not Come With It

    The standalone Claude Design site at claude.ai/design closes on December 14, 2026. After that date, the address opens Claude. Anthropic’s announcement gives the reason in one sentence: “Running two versions slows down fixes for both, so we’re folding the standalone site into Claude.”

    The migration that Anthropic offers moves design systems. It does not move projects. And the parts of your work that live only in the standalone product — the chats, the comments, the originals — have a deletion date, not a transfer path. This is the procedure for a team that has brand systems and client one-pagers in there, in the order the steps have to happen.

    What gets deleted, exactly

    Anthropic’s migration guide names the deletion list in two bullets: “Your chats with Claude” and “Comments on your projects and design systems.” Those stay in the standalone version and are deleted after it closes, per Anthropic’s data retention practices.

    Your originals are a separate statement, in the guide’s FAQ: they keep working in the standalone version until it closes on December 14, 2026, and “after that, they’re deleted.” A design system you migrate leaves its original behind in the standalone product, unchanged — and that original is on the same clock.

    Public links to standalone projects are a third outcome, and the guide words it differently on purpose: they “will no longer work after it closes.” Not deleted — dead. Every client you sent a public project link to holds a URL with an expiry date.

    The instruction Anthropic prints is the whole strategy for this section: save anything you need from your chats and comments before the standalone version closes. No fetched Anthropic page documents an export for chats or comments. The capture that matches the documentation is a screenshot of each comment thread and a copy of the chat text, done by hand.

    The dangerous sentence: “You don’t need to do anything with your projects yet”

    That sentence is in the migration guide, and it is true — your projects keep working in the standalone version until the close. It is also the sentence that will get client work deleted, because projects are the files with no migration path and a deadline.

    The Artifacts page in Claude lists up to 60 of your standalone projects, and they open in the standalone version. That list is a directory back into the product that is closing. It is not a move, and it is not a complete inventory if your team has made more than 60 projects. Anthropic’s position, in the guide’s words: “More details about moving your projects to Claude are coming soon.” Soon is doing a lot of work in that sentence, and December 14 is 56 days out.

    So the inventory step happens in the standalone product itself, not on the Artifacts list. Walk the standalone library for every client one-pager, deck, and brand system — including everything past the first 60 the Artifacts page shows.

    Before anyone clicks Migrate: the sharing problem

    One migration brings over every design system in your organization, including other people’s. It only needs to be started once — and anyone who can use Claude Design can start it, not just the organization’s owners. On individual plans there is no confirmation step at all: click, and it starts.

    The consequence that matters for a shop holding more than one client’s brand: “Published design systems that aren’t private will be shared with everyone in your organization and appear in their design system menu.” A system you published so your own projects would use it becomes an entry in every teammate’s menu the moment anyone runs the migration. On individual plans, nothing is shared — this is a team and organization trap, not a solo one.

    The precaution has to happen before the first click, because undoing it is not documented. In the standalone product, the setup guide names the Published toggle as the control that makes a system the organization’s working system. For every design system that should not appear in the whole organization’s menu, turn that toggle off first. A second migration is not a way back: a later run leaves an unchanged system alone and skips one that has changed inside Claude, so neither pass pulls a system out of the menu.

    Two kinds of systems do not migrate at all, no matter who clicks: “Empty design systems aren’t migrated, and neither are ones made from a built-in starter theme, even if you’ve edited them.” If your house brand began life as a starter theme you customized, the migration will silently leave it behind. There is no documented design-system export to fall back on. Copy the source assets out by hand before December 14.

    The export drill: one project, one zip

    There is no bulk download. Anthropic’s FAQ is blunt: “Not all at once. You can download them one at a time.” Open the project in the standalone version, click Share, choose “Project HTML” — for a slide deck, that item hides under “More formats and apps” — keep “Project archive” selected, and click Export.

    You get a .zip file with every file in the project. It is free and does not count toward your usage limits. Repeat it for every client one-pager and deck you cannot afford to lose, and store the zips outside Claude.

    Know what the zip is not. It is documented as every file in the project. Chats are on the deletion list, and no Anthropic page says the conversation comes along inside the archive. The zip preserves the files. The reasoning your team talked through in chat, and the client’s comments on the work, survive only if you captured them in the previous step.

    Enterprise: three switches, and one hard stop

    On Enterprise plans the migration is gated by settings that are easy to flatten into one wrong sentence, so take them separately. Artifacts themselves must be on — if they are off, people cannot migrate anything and will not even see the “Claude Design lives here now” banner.

    Design systems are a separate template switch: on for Team plans, off for Enterprise until an owner turns on Design systems in Organization settings > Artifacts. That is a different switch from Design and Slides, which Anthropic’s pages say were set to turn on by default on October 15, 2026 — a date that has now passed, with the help text still printing the scheduled sentence, so check your own settings rather than assuming either state. On plans with custom roles, each role also needs the Artifacts permissions, and a design system cannot be migrated if its owner’s role does not include design systems.

    The hard stop: “Organizations with zero data retention (ZDR) can’t turn on artifacts, so they can’t migrate.” If that is your organization, the migration procedure does not exist for you. The guide’s path is the per-project download, done before the close, one zip at a time.

    One more setting that does not do what an admin might hope: the Enterprise custom-retention article states that custom retention periods “do not apply to Claude Design.” The retention dial your organization already configured is not the instrument that keeps or deletes standalone chats, comments, or originals. The closure is.

    After it lands

    A migrated design system keeps its files as they were, and it cannot be hand-edited on its page yet. Its editors see the note: “Migrated from the standalone version. Ask Claude to make changes.” The editing model for a migrated brand system is a conversation, not a settings page.

    If someone edits a migrated system inside Claude and you later run the migration again, that system is listed under Skipped — “changed on claude.ai, left as they are” — so your edits are not overwritten. Replacing it with a fresh copy is a deliberate act: duplicate it first if the Claude-side changes matter, delete it in Claude, then migrate again.

    New design work lives in three doors now: any chat (ask for a design, or Output > Design in the message box), the Artifacts tab, and Claude Code, with /design to create, edit, and sync designs and /design-sync to pull in your design system. All of it draws on the same usage pool as the rest of Claude, including Claude Code — the separate weekly Claude Design allowance the product launched with is already gone, per the get-started guide.

    Two gaps in the new home are worth knowing before you move the team: Claude Design does not have version history yet, and inline comments there occasionally fail to appear on the page — Anthropic’s own workaround is to paste the feedback into the chat instead. The standalone product’s comment threads, the ones being deleted in December, are still the reliable record until you screenshot them.

    The order is the procedure

    Inventory in the standalone product. Turn off Published on anything that must not become an organization-wide menu entry. Mark the empty and starter-theme systems the migration will refuse, and copy their assets out by hand. Export every project that matters, one zip at a time. Screenshot the comments and copy the chats. Only then — owners having turned on Artifacts, Design systems, and the role permissions — does one person click Migrate, read the results window, and fix any failed system in the standalone product before running it again.

    Do those steps in that order and December 14 is a non-event: the address starts opening Claude, and everything you cared about is already there or already saved. Do them out of order — migrate first, inventory later — and the button will happily move the systems while the projects, comments, and originals sit in a product with 56 days left on it. We track vendor surface changes like this one on the desk because the procedure is always in the help pages; it is just never in the announcement. The announcement for this closure said chats and comments “won’t be available.” The help center is the text that says deleted.

    Sources: Anthropic’s migration guide, Migrate from standalone Claude Design to Claude, and the get-started guide, Get started with Claude Design, both read in full on October 19, 2026. A related surface change, worked the same way: Cursor’s shareable canvases, and how we check a vendor’s what’s-new claims in What’s New in Cursor Is a Claim.
  • Composer 2.5 Is Our Code Seat. Here’s Its Record.

    Composer 2.5 Is Our Code Seat. Here’s Its Record.

    Why Composer holds the code seat

    Every work order this shop writes names its executor up front — the model, the seat, and what happens if that seat is unavailable (stop; never substitute quietly). For code, the name on the order is Composer 2.5, Cursor’s own model. It did not get the seat by brand. It got it on a board we ran ourselves.

    The board: October 16, 2026

    Our fleet comparison put the models on one identical brief and graded the work. In the initial trio — Grok 4.7, Composer 2.5, and Auto — all three scored perfectly, and Composer was the fastest of the three: 31 seconds, 13 cents. Across the full board it was the fastest model tested, full stop, while identical perfect scores elsewhere on the board cost up to 86 cents. Speed with a perfect score is exactly the profile a code seat wants: code work is iterative, and iteration speed compounds.

    The same board explains the seat Composer does not hold. Our first pass — the wide, cheap, read-everything pass — belongs to GLM 5.3 Flash, which produced its perfect score for 0.83 cents. A hundred-fold cost spread for the same correct answers is the whole argument for routing by evidence instead of by logo: Composer where its speed pays, GLM where its price pays, and the receipts to say which is which.

    What we have put through it

    Through Desktop sittings, Composer executes the shop’s build work: fleet website builds and repairs across our WordPress properties, the Work Order Desk application (a BMAD+ build whose doctor checks pass 35 of 35), and the tooling runs in between. The work-order standard it runs under is not a prompt and a prayer — it is an unaided first pass in its own words before any templating, a permissions pre-flight, ship/hold boundaries stated in the order, and evidence graded on its timestamped trail plus screenshots at the verification points.

    The dents, on the record

    • The seat is bounded by the order. Our standing rule exists because it was earned: a work order that comes back with questions is a work order that was not finished. Composer executes what the order covers — gaps in the order surface as gaps in the run.
    • The real gates stay human. Sends, deletions, money, and credentials are never pre-approved for any executor. Composer stops there by design, and that is a feature of the harness, not a limit of the model.
    • The pipeline around it can bruise the output. In one October sitting, deliverables written through the Windows pipeline came back with mojibake on the em-dashes; the fix was ours to make — UTF-8 stated explicitly in every work order since. Blaming the model for a harness defect is how shops learn nothing.

    Cursor describes Composer as its in-house model family built for agentic coding — that is their claim, labeled as theirs. What this desk can vouch for is narrower and, we think, worth more: on our briefs, on our board, at our volume, it is the fastest pair of hands we have measured, and the record above is the whole of why it holds the seat.

    Method & settings — this piece

    Comparison: One identical brief across the fleet’s models, October 16, 2026; graded on output and execution trajectory; Composer 2.5: perfect score, 31 s, 13¢

    Seats: Composer 2.5 = code executor (Desktop sittings); GLM 5.3 Flash at max = first pass; Grok 4.7 = deep-verification seat — all three on Will’s Cursor plan

    Work-order standard: WO-198: execution model first, unaided first pass, permissions pre-flight, evidence = timestamped trail + screenshots

    Filed under the Cursor desk.

  • Desktop, Cloud, or API: One Cursor Harness, Three Seats

    Desktop, Cloud, or API: One Cursor Harness, Three Seats

    The seat is a routing decision

    Cursor is not one tool in this shop. It is three seats that share a harness — a Desktop app on a laptop, cloud agents behind an API, and a phone — and picking the wrong one wastes the day in a characteristic way. Desktop waits on a human. The cloud knows nothing about your logged-in life. The phone is a steering wheel, not a workbench. The routing rule we run: the seat is decided by where the work’s context lives.

    Desktop wins when the unlock is a logged-in browser

    A Desktop sitting is a supervised run: a written work order, an executor (Composer 2.5 in our shop) that makes an unaided first pass in its own words before any templating, and a human in the room for the real gates. Its superpower is everything the laptop already is — signed-in dashboards, the WordPress admin, the GA4 Advisor, the files on disk. When a fleet site needs hands inside a web UI that only exists behind Will’s login, no API lane substitutes.

    We learned the boundary the hard way. On October 18, an executor stopped cold at a site’s login redirect and left the step undone — which cost that sitting its unlock path. The standing rule now: in a sitting on Will’s own laptop, the executor clicks through sign-ins using the browser’s saved session. Saved-login only. No saved login means the step logs a HOLD — nobody hunts a password, ever.

    Desktop’s honest cost: it waits on a human, and a queued sitting is not a running job. Our TM pricing diagnosis (WO-353) has sat untouched since October 18 at 6:16 PM — steps written, folder staged — because a sitting starts when Will sits down. Anyone who tells you their Desktop pipeline is autonomous has not watched a folder sit still for a day.

    The cloud wins when the work fans out

    Cloud agents, launched from this desk over api.cursor.com, are the opposite shape: no login, no laptop, no waiting room — and they multiply. On October 16 we ran a census through that API: 44 models, one identical brief, five comparison rounds, graded on their execution trajectories. That is a shape of work a single Desktop seat cannot do before lunch, and it set our model routing for everything since.

    The scale shows in the bookkeeping: our completion watcher has seen 1,431 cloud agents come and go. The API runs two launch shapes for us — repo tasks that come back as pull requests, and no-repo research and evaluation runs with the model pinned in the launch body. The API is beta, and we treat it that way: when an endpoint changes shape, the error gets surfaced plainly, never papered over with invented fields.

    Mobile wins when the human is the bottleneck

    The phone’s job is judgment at human speed. Will reviews runs, reads results, and steers from his phone while the machines work elsewhere — and because a review that evaporates is a review wasted, a distiller folds his mobile and Desktop runs into the shop’s memory and Feed every 20 minutes. Mobile is not a production surface here. It is where the approvals live, and approvals are the scarcest resource in the building.

    What each seat’s failure taught the kit

    • Desktop: permission prompts were taxing the one human in the loop — fixed by a Step 0 permissions pre-flight in every work order (October 18): the executor declares the commands it expects up front, the human approves once, and prompts are reserved for sends, deletions, money, and credentials — which are never pre-approved.
    • Cloud: a finished summary is not evidence — fixed by trajectory grading and a completion watcher: results are verified at the receiving end, or they are not results.
    • Mobile: steering from the phone only counts if it lands in the record — fixed by the 20-minute distiller.

    One harness, three seats, and a routing rule a shop can steal: if the context is a login, sit down at Desktop. If the work fans out, launch it in the cloud. If the blocker is a decision, put it on the phone.

    Method & settings — this piece

    Evidence: This shop’s work-order record, October 2026: WO-198 standard, the WO-343 and WO-348 sittings, the WO-353 stall, the October 16 cloud census

    Desktop: Cursor 3.25.9 on Will’s laptop (read from the install, October 19, 2026); executor seat Composer 2.5

    Cloud: api.cursor.com/v1 (beta); completion watcher count 1,431 agents seen as of October 18, 2026

    Mobile: Cursor mobile app in a review/steer role; runs distilled into memory + Feed every 20 minutes

    Filed under the Cursor desk — where the catalog and the changelog are watched daily.

  • What does AEO reporting actually show?

    An honest AEO report shows four things: the exact questions that were asked, the answers the assistants actually gave, which businesses and pages those answers cited, and how all of it changed since the last run. AEO reporting is the scheduled record of those four things, kept the same way every time. Anything that cannot show you the four is showing you a mood, not a measurement.

    What questions were asked?

    A real AEO report prints its question set in full, word for word. The questions are the foundation of the whole report: they should be your customers’ real questions, fixed in advance, and identical from run to run. A citation count means nothing until you can see the questions it was counted on.

    This is where reports quietly cheat. Swap the questions between runs and every comparison is fiction — you improved because the test got easier. Add a question you already win and the average climbs without a single answer changing. Ask for the set in writing before the first run, and treat any later change to it as a new baseline, announced as one. A short set of real questions, held steady, beats a long set that wanders.

    What did the AI actually say?

    A real AEO report keeps the raw answers, not summaries of them. The answer text is what your customer actually reads — the names in it, the order they appear, the words around them. A summary written by the provider can only tell you what the provider noticed. The raw answer lets you check.

    Summaries hide the losses. A run where you were cited on nine questions and dropped on the tenth, hard, reads as “visibility strong” in a summary and as a work order in the raw text. Keep the full answers, dated, for every run. They take almost no space, they cannot be reconstructed later, and they are the difference between having evidence and having a recollection.

    Who got cited?

    A real AEO report names the citations for every question: which businesses the answers credited, which pages of theirs did the work, and what share of the citations on each question went to whom. The citation list is the most useful page in the report. It converts “we are not visible” into a named list of exactly who the machines trusted instead, question by question.

    Read it as a work list, not a wound. When one restoration client of ours kept losing a question to the same competitor, the citation list showed the competitor’s page the assistant kept crediting — a page that answered the question in the customer’s own words, in the first paragraph. That is a specific, fixable problem, and it was invisible in every summary number we had. Your citation share — your slice of the citations on your questions — is the one summary figure worth tracking, because it is arithmetic on the list, not an opinion about it.

    What changed since last time?

    A real AEO report is built to compare: this run against the last, same questions, with the differences stated plainly and the work done in between written next to them. Answers churn — the same question, asked next month, can name different businesses with nothing changed on either side. An honest report says so, and reads movement over several runs instead of celebrating or mourning a single one.

    The work log belongs inside the report for one reason: without it, you cannot tell your work from the weather. “We rebuilt the profile and published two answer pages in March; citations on those questions rose across the April and May runs” is knowledge. The same rise with no log behind it is luck you will try to repeat blind. If your provider’s report never mentions what they did between runs, ask why their work and their results live in separate documents.

    What does a horoscope report look like?

    A horoscope report shows a single score with no questions behind it, percentages with no counts under them, and screenshots of the one good answer from a good day. It changes its questions when the results are inconvenient, reports only the wins, and always finds that things are improving and that more budget would improve them faster. It feels good, commits to nothing, and cannot be checked.

    The test is simple. Pick any number in the report and ask: on which questions, from which answers, counted how? A real report answers in one step, because the number came from a list it can show you. A horoscope report answers with another number. We call them horoscopes because, like the ones in the paper, they are written to be agreeable about the future and impossible to grade about the past.

    How often should you read an AEO report?

    Read AEO reporting on a rolling cadence — monthly is a sane default — and never daily. AI answers move day to day with nothing changed, so daily reading is noise-chasing: it manufactures urgency, spends your attention, and teaches you to react to weather. What is worth reading is the run-over-run trend, and the first run after real work has had time to settle.

    Reading it should end in a decision, or the reading is decoration. The standing decision a good report sets up is small: which questions is a competitor cited on that we are not, and what is the missing answer we should write next? Our AI Citation Quick-Scan is this artifact in its smallest honest form — 10 prompts about your service line, the answers recorded, the citations named, a scored report within 7 days, $97, one time.

    Which lines the platforms lift is their call. We build the material they lift from — and then we measure what they did.

  • The Mailbox Is a Trigger. It Is Not a Topic.

    The Mailbox Is a Trigger. It Is Not a Topic.

    Short answer: a mailbox can start a publish job. It cannot choose the topic. If the incoming message is a digest, a rumor chain, or a subject line that would embarrass the brand, the correct article is not a reprint. The correct article is the gate.

    Tygart Media sits in Tacoma, Washington. The public site is an operator desk for AI-native content systems, restoration operations, and the search surfaces that now sit between a shop and a buyer. Those surfaces include classic Google results (SEO), answer engines that quote a paragraph as evidence (AEO), and generative engines that assemble a local picture of who you are (GEO). None of them are helped by publishing whatever landed in will@tygartmedia.com at 7:44 p.m.

    What is a source-fit gate?

    A source-fit gate is the first checklist in an inbox-triggered pipeline. It asks one question before outline, slug, schema, or Rank Math title: does this source belong on this domain?

    The test is not “is the subject loud.” The test is whether a contractor in Everett, a facility manager in Tacoma, or an answer engine citing tygartmedia.com would be right to treat the page as evidence. If the source is a third-party digest of celebrity gossip, political rumor, medical anecdotes, and crime blurbs, the source fails. Publishing it as news would contaminate the entity the site has spent years teaching search systems to recognize.

    That is the same instinct behind the $5 filter: would anyone pay to pipe this feed into an assistant as a trusted source? A mailbox firehose would fail that filter on most nights. The gate exists so the firehose does not become the catalog.

    What Sunday night’s mailbox actually contained

    The trigger for this piece was a Quora Digest addressed to the work inbox. The subject line led with a political rumor. The body mixed entertainment questions, relationship advice, medical anecdotes, a crime blurb, and other off-desk topics. None of that is Tygart Media’s beat. None of it is restoration operations. None of it is a first-party number we can stand behind.

    So the digest is not the article. The digest is the proof that an automation without a source-fit step will try to hang the wrong page. The human-readable rule is the same one already on this site: draft-only is the first verb, and publish stays a seat a human can refuse. The machine may open the envelope. It may not inherit the subject line as the H1.

    The six checks before anyone writes

    Run these in order. Stop at the first fail. Do not “find an angle” to rescue a bad source.

    • Domain fit. Would this page still make sense if the logo, the About page, and the $97 restoration kit sat next to it? If not, fail.
    • First-party or primary source. Can you name a dated public document, a product note, a field observation, or a number you measured? A digest snippet is not a source. Fail.
    • Identity lock. No client names, no secrets, no mail IDs, no thread IDs, no app passwords. The Quality Gate exists because a client name once leaked into live posts. That failure mode is still live.
    • Number lock. No invented click-through rates, ranking jumps, or “X% more citations.” If a figure is not on the page you can point to, leave it out.
    • Duplicate lock. Search the live site before you mint a slug. If the argument already exists, update that page or stop.
    • Place lock (GEO). If the piece claims a geography, name a real one the operator actually works — Tacoma, Puget Sound, Everett, Snohomish County — and do not stuff NAP into a thought-leadership body.

    Only after those six pass do AEO, SEO, and GEO get to work. Optimization is not a pardon for a bad source.

    How AEO, SEO, and GEO attach after the gate

    AEO — write the answer first

    Answer engines quote short, stable sentences. Lead with the claim a model can lift without inventing the rest of the page. Then explain. Then put the same claim in an FAQ block using the questions people actually type: what is a source-fit gate, should every email become a post, who owns Publish.

    SEO — one slug, one job

    Pick a slug that names the method, not the digest subject. Title tag under 60 characters. Meta description that restates the answer. Canonical on the live URL. Rank Math on this stack writes the title and robots fields; it does not invent the argument. Internal links go to pages that already carry the doctrine — the $5 filter, the draft-only desk, the afternoon where five drafts still needed a human tap.

    GEO — teach the place, don’t spray it

    Generative engines build a local picture from repeated, consistent facts. Tygart Media is a Tacoma agency. Restoration work in this network is often packed around Everett and Snohomish County. Say that when place is part of the method. Do not turn a content-ops essay into a fake service-area page. GEO is entity clarity, not a city list glued to the footer of every paragraph.

    What to publish when the source fails

    Three honest exits, in order of preference:

    1. Write the gate. If the failure mode is the news — an inbox automation almost reprinted a digest — the operator article is the checklist. That is this page.
    2. Hang nothing. An empty-delta night is a successful night. Silence is cheaper than a correction.
    3. Keep a receipt. Log the fail in the Command Center so the next run does not “try the digest again.” The receipt is not the public URL.

    What you do not do is launder the digest into a “roundup,” a “what people are asking,” or a thin news recap with a restoration sentence taped on the end. That is how a site teaches answer engines the wrong entity.

    What this desk will not do with a digest

    • Reprint political rumor, crime blurbs, or medical anecdotes as Tygart Media reporting.
    • Quote tracking URLs, message IDs, or unsubscribe tokens from the envelope.
    • Invent a percentage that makes the pipeline look smarter than it is.
    • IndexNow a thin title-price door, or ping Bing before the body exists.
    • Hand Publish to the same process that opened Gmail.

    The machine can fetch the letter. The machine can draft. The machine can stage images and fill Rank Math fields. The tap is still human.

    FAQ

    What is a source-fit gate in content operations?

    It is the pre-outline check that asks whether an incoming source belongs on this domain. Domain fit, primary source, identity lock, number lock, duplicate lock, and place lock. Fail any one and you do not draft the obvious article from the subject line.

    Should every incoming email become a WordPress post?

    No. Mailbox events are triggers. Product notes, first-party incident numbers, and field observations can become posts. Digests and rumor chains should not.

    How do AEO, SEO, and GEO fit after the gate?

    AEO wants an answer-first opening and an FAQ a model can quote. SEO wants one slug, a clean title and meta, and internal links to the doctrine pages. GEO wants consistent place facts — Tacoma for the agency, Everett and Snohomish County when the method is local restoration — without turning every essay into a service-area page.

    Where does Tygart Media apply this?

    On tygartmedia.com first. The same gate belongs on any site in the network before an inbox automation is allowed to mint a URL. The Command Center keeps the receipt. The public page keeps the method.

    If you want the restoration operating system this desk actually sells, the front door is the Complete Restoration Operations Kit. The method on that page is copyable. The checkout is on the page. The mailbox is still not the editor.

  • The Junk Calls Are the Tuition

    The Junk Calls Are the Tuition

    “Most of the calls are garbage. Listing bots, spam, junk — and I’m paying for every one of them. But all it takes is one. One real person, one real conversation, and it pays for all of them.”

    That’s the whole piece. But it took me a year of phone bills to learn it, and about five minutes of forgetting it, so I’m writing it down.

    The tuition frame

    Every system has tuition. Ad spend has click fraud. Email has spam filters and the good leads that land in them. The voice line has junk calls.

    Tuition isn’t a scam — it’s the price of the classroom. The question was never whether I’d pay it. The question was whether I’d remember what the classroom was for.

    What the junk actually costs

    Here’s the part that stings, and it’s straight from the arms column: the bill doesn’t care whether the call mattered.

    The listing bot that calls to sell me a listing. The robocall about my car’s warranty. The silence. Every one of them spins up the model, opens the carrier leg, records the nothing, transcribes the nothing. The arms fire either way. I pay for the whole stack to handle a call that never existed.

    Multiply that by a month and the tuition line on the invoice is real. I’m not going to pretend it isn’t.

    A glass jar of dull coins with one single coin glowing gold among them

    The math of the one

    But here’s the other column, the one the invoice doesn’t print.

    One call. A real person, a real problem, water where it shouldn’t be. They talked to the line instead of bouncing to the next listing. Somebody answered — well, something answered — and it sounded like a human who gave a damn, and by the end there was a name, an address, and a job on the calendar.

    One of those pays for months of junk. Not close — completely. The asymmetry is so lopsided it looks like a rounding error until you run the year.

    The junk calls cost arms. The one call buys the whole armory.

    Why the why fades

    The bill arrives every month. The connection was a Tuesday.

    That’s the whole problem. The tuition is invoiced on schedule; the reason is a memory. And memories fade faster than bills do. So every few months I catch myself staring at the junk-call line and thinking “why am I paying for this” — and the answer is always the same Tuesday I forgot.

    Systems don’t run on memory. They run on what’s written down. So this is me writing it down: the junk is the tuition, the one call is the classroom, and the day I forget that is the day I start optimizing the wrong thing.

    A single warmly lit open doorway at the end of a long dark hallway

    The filter question

    Notice what the answer isn’t. It isn’t “block the junk.”

    A filter aggressive enough to stop every bot is aggressive enough to stop a human — the tired homeowner who mumbles, the bad connection, the caller who sounds like a robocall for the first four seconds because they’re reading the address off a piece of paper. The door has to stay open. That’s the entire point of the door.

    The right question isn’t how to stop the junk. It’s how cheap the junk can get while the door stays wide open: faster hangup detection, quicker routing, less model time burned on the obviously-empty calls. That’s harness work — making the tuition cheaper, not pretending school is free.

    The close

    The junk calls are the tuition. Pay it gladly.

    Just don’t forget what the classroom is for. It’s for the one. It’s always been for the one.