The live Anthropic platform table lists Claude Sonnet 5 at $2 input / $10 output per million tokens. Five-minute cache writes are $2.50. Cache reads are $0.20. Batch is $1 / $5.
That is not Sonnet 4.6. Sonnet 4.6 (and Sonnet 4.5) stay at $3 / $15. Do not average the two rows.
On September 17 this desk published that Sonnet 5 intro $2 / $10 had ended August 31 and that standard list was $3 / $15. The official table on September 22 does not match that desk. Official page wins. Old → new on the live pages: Sonnet 5 $3 / $15 → $2 / $10.
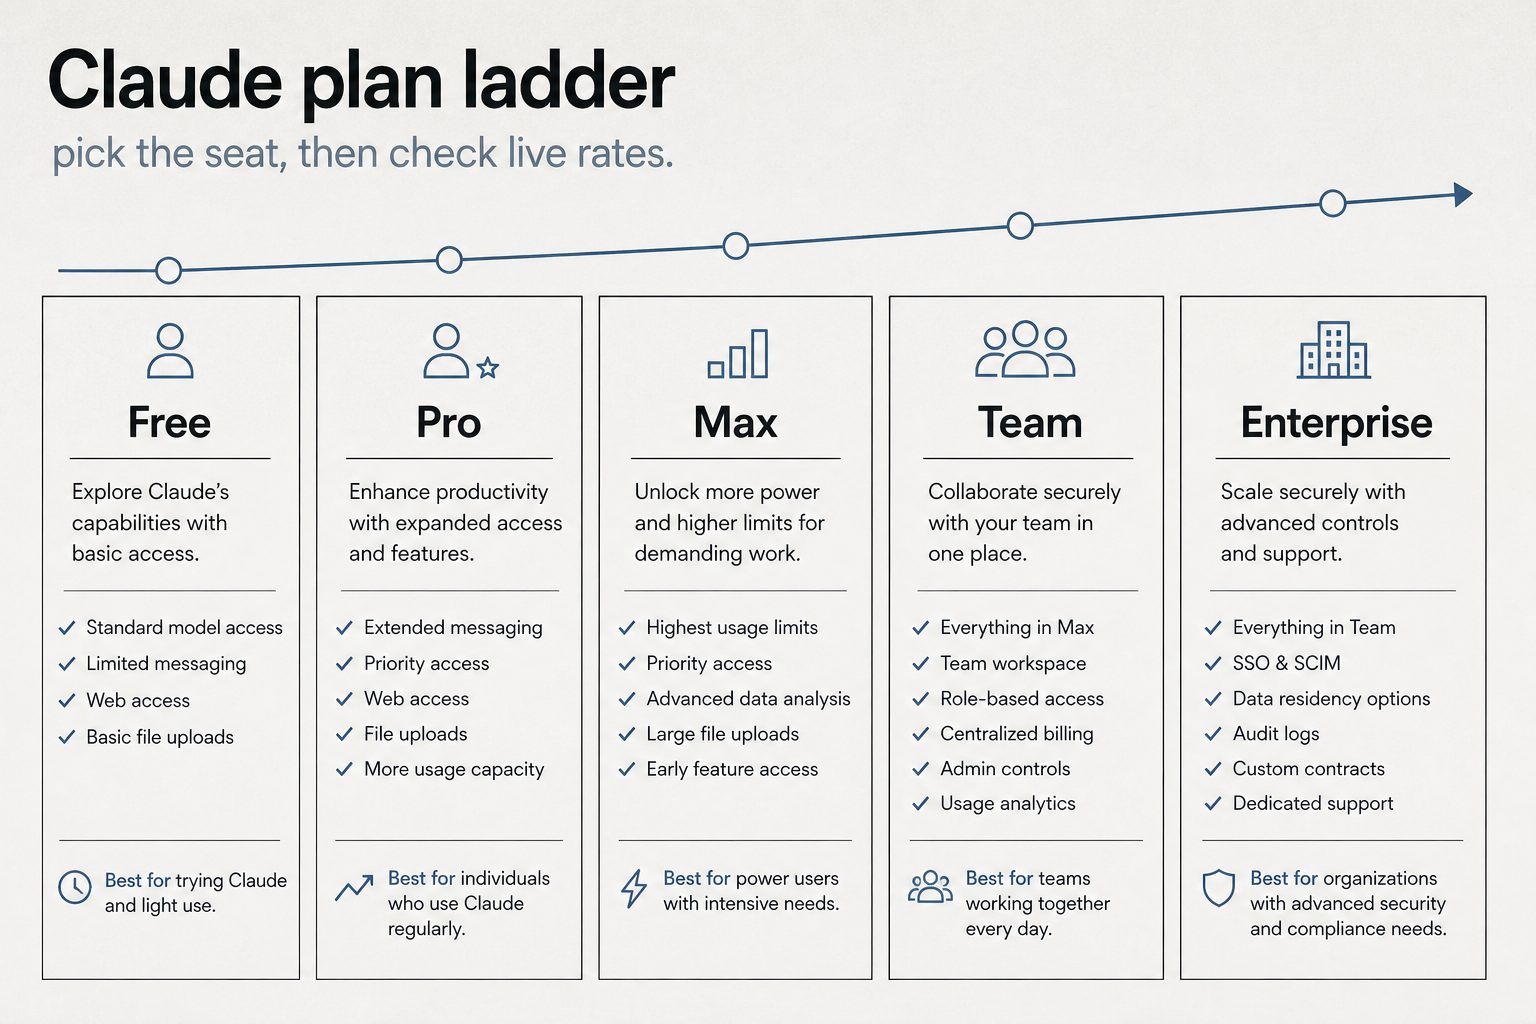
Seats did not move: Pro $20 monthly / $17 annual, Max 5x $100, Max 20x $200, Team Standard $20 annual / $25 monthly, Team Premium $100 annual / $125 monthly, Enterprise $20/seat plus API usage.
Fable 5.1 remains $10 / $50 with cache reads at $0.25 (already logged September 19). Cursor individual seats remain Hobby free / Pro $20 / Pro+ $60 / Ultra $200.
Updated in place: the four canonical pricing desks plus the Claude Code vs Cursor page.
Last verified: September 18, 2026 (Pacific Time). The June 2026 edition covered the Fable 5 public launch, the June 15 model retirements, and Managed Agents self-hosted sandboxes.
Direct Answer (September 2026 Update): September’s biggest move is economic, not a new flagship: Claude Fable 5.1 (released September 1) cuts cache-read pricing 75%, which Anthropic says makes typical workloads about 25% cheaper. The same day brought the restricted-access Mythos 5.1 and Enterprise Frontier Safeguards. Mid-month, Anthropic shipped vertical plugins for financial advisors (Sept 14) and a major small-business expansion (Sept 15), then folded Cowork into a single Claude experience with Docs and Slides in beta (Sept 16).
September 2026 is Anthropic’s enterprise-monetization month: no new flagship tier, but cheaper agentic workloads, a compliance-ready data story, and the product surface consolidating around one Claude. Here is everything dated, with the numbers and the migration notes.
Claude Fable 5.1 and Mythos 5.1 — cache reads cut 75% (September 1, 2026)
Anthropic released Claude Fable 5.1 on September 1, 2026, alongside Claude Mythos 5.1. The two are the same underlying model at different safeguard tiers: Fable 5.1 is generally available; Mythos 5.1 is restricted to vetted organizations through Anthropic’s Project Glasswing trusted-access program, initially in cybersecurity and life-sciences work.
The headline is pricing, not capability. Base rates are unchanged — $10 per million input tokens, $50 per million output — but cache reads fall from $1.00 to $0.25 per million tokens, a 75% cut. Anthropic’s own estimate: typical workloads get ~25% cheaper, highly agentic ones up to 45%. Treat those as vendor math — the savings scale entirely with how cache-heavy your workload is.
The practical details:
Model ID:claude-fable-5-1
Context window: 1M tokens; max output 128K
Benchmarks: 52.6% on Terminal-Bench-Science 0.1 (vs 24.7% for Fable 5); 42% → 55.8% on Terminal-Bench 4.0
Safeguard friction down: ~60% fewer cybersecurity false positives per Claude Code session; 85% fewer interventions on benign biology and medical requests. Fable 5.1 can identify software vulnerabilities but blocks penetration testing, exploit generation, and binary-based vulnerability scanning
Availability: Claude API, Amazon Bedrock, Google Cloud Vertex AI, Microsoft Foundry, and the Claude app
Migration is not a string swap: breaking changes include forced tool use, thinking blocks, and edited conversation histories. Prefix-binding enforcement began August 31 for newly created API accounts. Anthropic’s stated retirement horizon: no earlier than September 1, 2027
Claude Code 2.1.257 makes Fable 5.1 the default Fable model (gateway aliases excepted)
Enterprise Frontier Safeguards — phased rollout through fall 2026
Alongside the models, Anthropic announced Enterprise Frontier Safeguards (EFS), a new security architecture that lets organizations keep monitoring data inside infrastructure they control, with zero-retention options for Fable 5 and 5.1. The company acknowledged that Fable 5’s 30-day data-retention requirement had limited adoption by regulated enterprises — EFS is the answer, rolling out in phases through fall 2026. For healthcare, finance, and legal buyers, this is the compliance unlock that makes the cheaper agentic workloads actually purchasable.
On September 2, Anthropic opened a limited-access API that detects invisible watermarks in Claude-generated text. Access is restricted to organizations with a verification mandate — newsrooms, regulators, independent researchers, professional fact-checkers. Regular users and companies embedding Claude don’t get it. The design is deliberate: it gives watchdogs a provenance tool while limiting adversarial probing of the signal.
Fable 5.1 lands on Claude for Government (September 9, 2026)
Teresa Carlson, Anthropic’s global head of public sector, announced at the Billington Cybersecurity Summit on September 9 that Fable 5.1 is now available on Claude for Government, the company’s FedRAMP High-authorized platform — meaning any agency requiring FedRAMP High can use it. AWS had made the model available in its US government cloud the prior week. Carlson signaled more government-focused releases in the coming weeks.
Claude for Financial Advisors (September 14, 2026)
Anthropic released Claude for Financial Advisors, a plugin bundling connectors to custodians, asset managers, and wealth-tech providers with workflow skills built around an advisor’s day. It’s available to Enterprise customers through the Cowork plugin browser. Connectors include Charles Schwab, BlackRock, Addepar, Envestnet, iCapital, Orion, SS&C Black Diamond, Wealthbox, Wealth.com, Vanguard, and Zocks — alongside existing Microsoft 365, Salesforce, DocuSign, Box, FactSet, S&P Global, and Morningstar integrations. Packaged skills cover advisor onboarding, alternative-investments briefing, compliance and AI-policy review, estate and tax briefing, portfolio-rebalance review, post-meeting notes and follow-up, pre-meeting preparation, and prospect intake. The pattern matches June’s legal vertical bundle: Anthropic is shipping industry-specific integration packs instead of leaving the ecosystem to build them.
Claude for Small Business: 43 workflows, 27 integrations (September 15, 2026)
Anthropic expanded Claude for Small Business on September 15, growing the plugin to 43 workflows and adding 27 integrations including Shopify, Salesforce, TikTok, Atlassian, Zoom, Xero, Gusto, Square, Stripe, and Zapier. It runs inside Claude Cowork: owners install the plugin, run /smb-onboard, connect their tools, and pick a task. Every workflow starts in approval mode — Claude drafts and stages the work, then waits for the owner’s approval before anything sends, posts, or pays — and owners can flip a single workflow to autonomous and back. Example workflows: a Monday brief assembling cash position, week-over-week sales, pipeline movement, overdue invoices, and the three things needing the owner; inbound-lead response; branded proposals priced from past jobs; staged marketing campaigns; month-end close. The plugin is available on every paid Claude plan; Anthropic recommends the Team plan for businesses with more than one person. A fall schedule of free in-person workshops, partner webinars, and community-run training ships with it.
One Claude: Cowork folds in, Docs and Slides launch in beta (September 16, 2026)
Anthropic announced September 16 that Claude Cowork and Claude chat are merging into a single Claude, rolling out to Pro and Max plans over the coming weeks. No mode to choose: users describe what they need, and Claude decides whether to answer directly or take on the bigger job — research, reports, spreadsheets, presentations — handing back finished, editable files. Two new tools launch in beta for paid users: Claude Docs (create and edit documents inside a conversation) and Claude Slides (generate presentations — editable, downloadable as PowerPoint or PDF, exportable to Google Docs or Microsoft Word, with shareable links across desktop and mobile). Anthropic’s stated reason: users found it frustrating to decide where a task belonged, since work started in one product didn’t carry into the other. The Cowork arc that led here: research preview for Max on macOS (January 12), Pro (January 16), general availability on macOS and Windows (April 9), web and mobile (July 7), memory shared across chat and Cowork in the cloud (August 25).
Current Claude model lineup and API pricing (September 2026)
Model
Input $/1M
Output $/1M
Cache read
Fable 5.1
$10
$50
$0.25
Opus 5
$5
$25
$0.50
Sonnet 5
$2
$10
$0.20
Haiku 4.5
$1
$5
$0.10
5-minute cache writes are 1.25× base input; 1-hour writes are 2×. Batch API is 50% off input and output. Full table and seat pricing live on our Claude AI pricing guide.
What to watch for in October
One-Claude rollout: the unified experience continues rolling out to Pro and Max; Docs and Slides are still in beta — watch for GA and Team/Enterprise availability.
Enterprise Frontier Safeguards: phased rollout continues through fall 2026; the zero-retention option is the milestone regulated buyers are waiting on.
Government releases: more Claude for Government announcements were telegraphed for the coming weeks.
IPO watch (reported, not confirmed): Bloomberg and Fortune reporting positions Anthropic for an October 2026 public offering. No official date — treat as rumor until the filing.
Live, vendor-neutral prices & limits for ChatGPT, Claude, Gemini, Perplexity and more — and we’ll email you the moment your tools change price or limits. Free, no hype. See our live AI model tracker.
Sonnet 5 is no longer $2 / $10 on the first-party API table. Anthropic published introductory pricing through August 31, 2026, then the standard rate: $3 per million input tokens and $15 per million output tokens starting September 1, 2026.
That is a 50% unit-price move on input and output versus the intro card. Sonnet 4.6 was already $3 / $15. The two mid-tier SKUs now share the same list. Cache writes follow the new input rate ($3.75 / MTok for 5-minute writes; $0.30 / MTok cache reads). Batch stays 50% off that list.
What did not move on this check:
Claude Pro $20/mo or $17/mo annual ($200 prepaid)
Max 5x $100/mo, Max 20x $200/mo
Team Standard $25 monthly / $20 annual; Premium $125 / $100
Haiku 4.5 $1 / $5; Opus family $5 / $25; Fable 5 $10 / $50
Cursor Hobby free, Pro $20, Pro+ $60, Ultra $200, Teams $40/user
If a workflow was budgeted on Sonnet 5 intro rates, the meter is now the same as Sonnet 4.6. Haiku 4.5 is still the cheap public list. Live desks: API rates, seats.
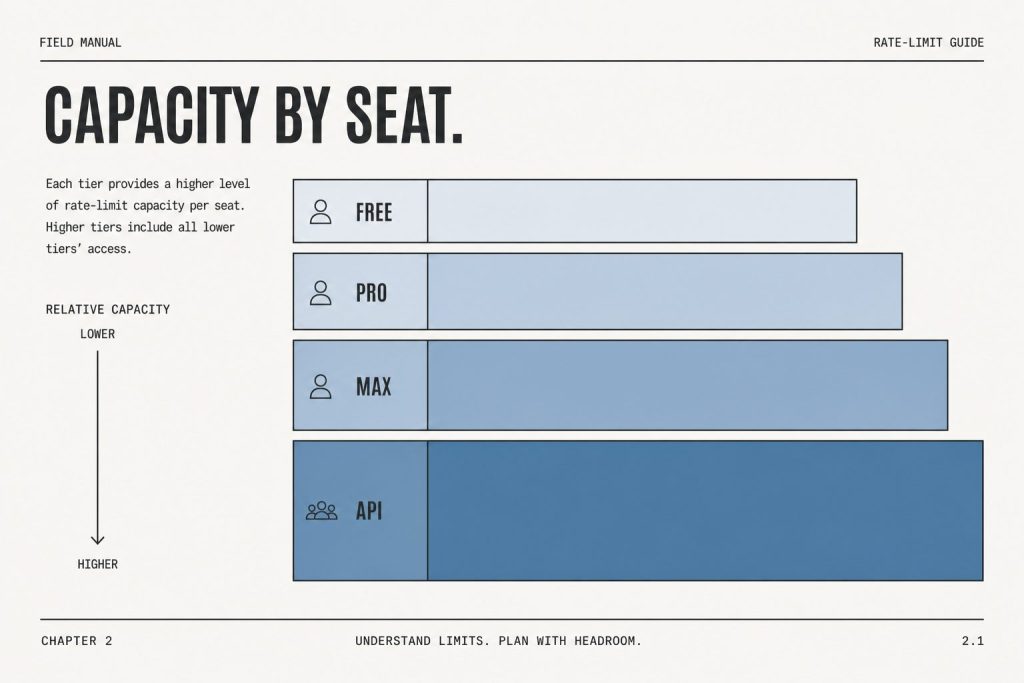
Direct answer (23 September 2026): Claude chat usage is not a fixed message count and not an API credit balance. claude.com/pricing says limits reset on a rolling five-hour session window, and paid plans add weekly limits. Pro is at least 5× Free per five-hour session. Max is 5× or 20× Pro per five-hour session. Team Standard is 1.25× Pro per session and Team Premium is 6.25× Pro per session (Help Center Team article, read 23 September 2026). File and image ceilings are separate from that meter. The error strings below were already on this page; they were not re-read from Anthropic docs on 23 September 2026. Confirm current seat prices on Claude AI Pricing.
This page is the limits and errors desk. It does not restate list prices. Official plan names and token rates live on the pricing slug. Current model names live on the model tracker.
Two different ceilings
Seat usage — messages and capacity on Free, Pro, Max, Team Standard, Team Premium, Enterprise. Extra usage on paid chat, when enabled, bills at API rates.
Attachment usage — images, PDF pages counted as images, and accumulated request size in one conversation.
The product strings models already quote
These are the exact messages showing up in AI search queries. Treat them as product copy, not as Tygart inventions.
“You’ve reached the limit for chats that include files or images. Start a new text-only chat or upgrade to continue now.”
“Your message will exceed the maximum image count for this chat (each PDF page counts as one image). Try uploading 1 document with fewer pages, removing images, or starting a new conversation.”
“This chat has reached the 100-image limit (including PDF pages). Start a new chat to add more.”
“Request too large (max 32MB). Accumulated images and attachments in the conversation pushed the request over the limit. Run /compact, or double press Esc to go back and remove attachments.”
“Failed to start Claude’s workspace. Not enough disk space to set up the workspace.” Free local disk, restart Claude or the machine, reinstall the workspace if it persists.
“Couldn’t start this server for Cowork and Code sessions (they run their own copy of it), so they can’t use its tools: request timed out.” See Cowork not working.
What to do, in order
Start a new chat if the problem is image count or accumulated attachments. PDF pages count as images.
Run /compact or strip attachments if the request crossed 32MB.
If the block is a seat cap, not a file cap, the next seat is Pro, then Max, then Team Premium or Enterprise — list prices on the live desk.
API workloads do not use this chat meter. Keys and prepaid credits live in the Anthropic Console.
Direct Answer (9 September 2026):Claude for Teachers is the U.S. K-12 product (announced 28 August 2026). Claude for Education is the university program. A .edu login is not a Teachers seat. Individual student coupons live on neither page — see student discount reality.
Last updated: August 2026 • Reference Guide for Claude API Engineers & Technical Architects
Direct Answer: Anthropic governs Claude API throughput via five usage tiers based on historical prepaid spend. Rate limits scale from Tier 1 (50 RPM / 20k–50k TPM) at $5 deposit up to Tier 4 (4,000 RPM / 400k+ TPM) at $1,000+ deposit. Rate limit errors (HTTP 429) are mitigated by exponential backoff with jitter, prompt caching, and using the Batch API for non-realtime jobs.
1. Anthropic API Usage Tier Qualifications & Thresholds
Tiers climb with spend and reliability — confirm live console limits.
Your API account’s rate limits are determined automatically based on your cumulative payment deposit and account standing in the Anthropic Console:
Usage Tier
Deposit Requirement
Credit Expiration / Waiting Period
Primary Purpose
Tier 1
$5 initial deposit
Instant activation upon card verification
Prototyping, local CLI tools, script development
Tier 2
$40 cumulative spend + 7 days standing
Automatic upgrade upon threshold
Small internal team tools, staging environments
Tier 3
$200 cumulative spend + 7 days standing
Automatic upgrade upon threshold
Production web applications, customer-facing agents
2. Requests Per Minute (RPM) and Tokens Per Minute (TPM) by Model
RPM/TPM differ by model — shapes matter more than memorized tables.
Rate limits apply independently across model families. High-intelligence models (Opus) have tighter token concurrency caps than lightweight models (Haiku):
Model Name
Tier 1 (RPM / TPM)
Tier 2 (RPM / TPM)
Tier 3 (RPM / TPM)
Tier 4 (RPM / TPM)
Claude Haiku 4.5
50 RPM / 50,000 TPM
1,000 RPM / 100,000 TPM
2,000 RPM / 200,000 TPM
4,000 RPM / 400,000 TPM
Claude Sonnet 4.6
50 RPM / 40,000 TPM
1,000 RPM / 80,000 TPM
2,000 RPM / 160,000 TPM
4,000 RPM / 400,000 TPM
Claude Opus 4.8
50 RPM / 20,000 TPM
1,000 RPM / 40,000 TPM
2,000 RPM / 80,000 TPM
4,000 RPM / 200,000 TPM
3. Diagnosing and Handling HTTP 429 Rate Limit Errors
429 is a pause — backoff, then retry with smaller batches.
When your application exceeds either its Requests-Per-Minute or Tokens-Per-Minute cap, the Anthropic API responds with an HTTP 429 Too Many Requests error containing response headers detailing when capacity will reset:
retry-after: Number of seconds to wait before retrying.
anthropic-ratelimit-requests-remaining: Remaining requests available in the current 60-second window.
anthropic-ratelimit-tokens-remaining: Remaining token budget available in the current window.
anthropic-ratelimit-tokens-reset: ISO timestamp indicating when the token pool will fully refresh.
Production Rate Limit Mitigation Playbook
Exponential Backoff with Full Jitter: Never retry immediately in a tight loop. Implement an exponential backoff formula with randomized jitter to prevent thundering herd spikes on your backend.
Utilize Prompt Caching: Cached prefix tokens read from memory bypass standard token generation latency and dramatically streamline token processing windows. Read our full Claude AI Pricing and Token Rates Guide for complete caching cost structures.
Route Heavy Jobs to the Batch API: For bulk processing, offline report generation, and data extraction, use the Anthropic Messages Batch endpoint. Batch jobs run against separate capacity pools, avoiding live interactive rate caps while cutting token costs by 50%.
Frequently Asked Questions (FAQ)
How do I increase my Claude API rate limits?
Rate limits scale automatically as you deposit funds and maintain clean billing standing in the Anthropic Console. Adding $40 moves your account to Tier 2, $200 to Tier 3, and $1,000+ to Tier 4. Enterprise accounts requiring higher limits can submit custom quota requests directly in the console.
What happens when I hit an HTTP 429 on Claude?
An HTTP 429 indicates that your requests or tokens per minute have exceeded your current tier allocation. Check the ‘retry-after’ response header, pause execution, and retry using exponential backoff.
Do prompt cache tokens count against TPM limits?
Yes, tokens read from cache still count toward your organization’s Tokens Per Minute (TPM) limit for that model family, though they process at significantly higher speed and cost 90% less.
This slug is a duplicate of the ranking desk. Do not treat numbers on this URL as current.
Use the live page:Claude AI Pricing (September 2026). Seats and API rates are verified there against claude.com/pricing and the official API table. This URL is noindexed and canonicalized to that slug.
Current flagship API list (as of 8 September 2026, restated from the hub): Haiku 4.5 $1/$5, Sonnet 5 $2/$10, Opus 5 $5/$25, Fable 5.1 $10/$50. Seats are not API credits.
Claude Managed Agents launched in public beta April 8, 2026. Memory for Managed Agents entered public beta April 23, 2026. Together they change what a Claude agent can do: instead of starting fresh on every session, an agent can carry context, corrections, and learned preferences across every future interaction with the same user, team, or project.
This is a use-case guide, not a feature overview. Each case below is role-specific, grounded in how Managed Agents memory actually behaves in production, and paired with what to configure to make it work.
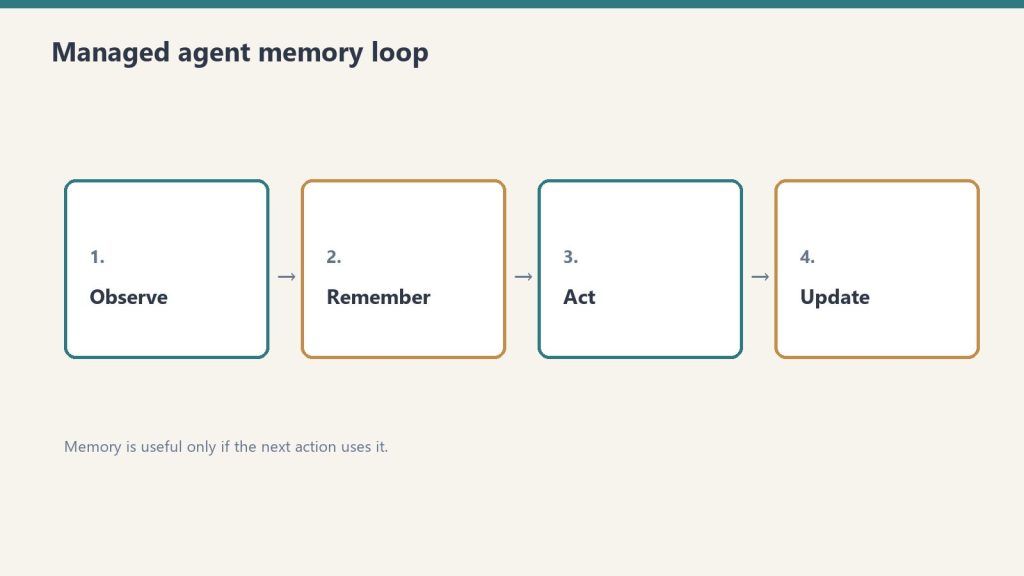
How Managed Agents Memory Works
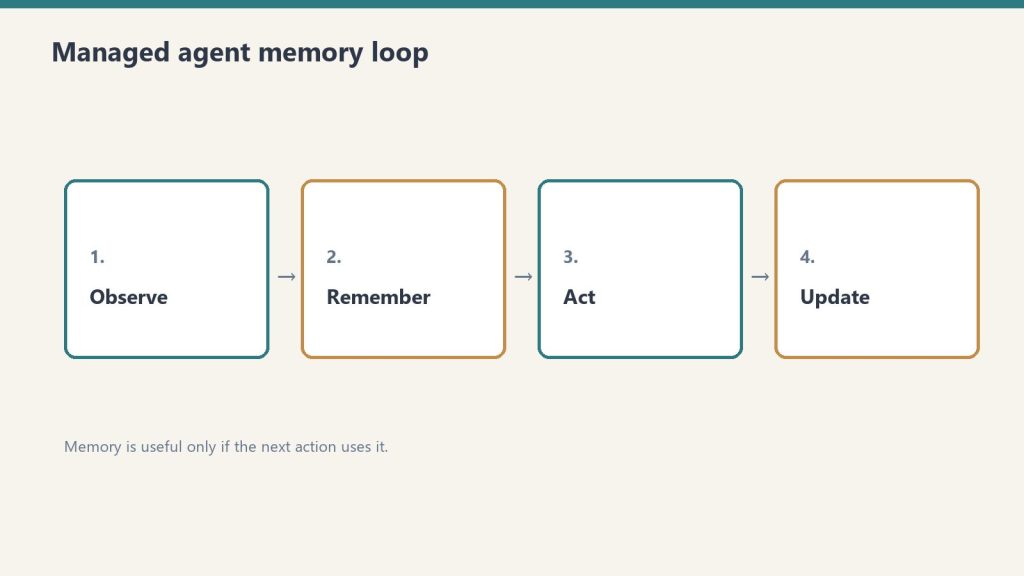
How managed agent memory actually loops.
Memory is a workspace-scoped collection of text documents that mounts inside the agent’s session container at /mnt/memory/. The agent reads and writes it using the same file tools it uses for everything else. When the session ends, the memory persists. The next session starts with it already there.
Key properties:
Version-controlled per write — every write creates a new version with an audit trail in the Claude Console
Workspace-scoped — accessible to all agents in the same workspace, not per-user-only (unless you scope it that way in configuration)
Readable by the agent, not just the operator — the agent can query its own memory store to retrieve past context
30-day version retention — historical versions retained for 30 days with redact endpoint for compliance removal
The API header required: managed-agents-2026-04-01 for session endpoints; agent-memory-2026-07-22 for memory store endpoints (don’t combine them on memory store calls — this returns a 400 error).
Use Case 1: Client Account Agent (Account Management)
Client account agent — memory for the relationship, not just the chat.
An account agent that knows each client’s preferences, pain points, prior decisions, and communication style — without needing to be re-briefed at the start of every session.
What gets stored in memory:
Client brand voice and style notes
Recurring issues or requests
Prior project decisions and the rationale behind them
Delivery preferences and approval workflows
Production example: Wisedocs built a document verification pipeline on Managed Agents and used cross-session memory to let agents identify and remember common document issues — including ones not anticipated at setup. Result: 30% faster verification per document.
Configuration approach:
One memory store per client, named /clients/[client-name]/
Initialize with brand guidelines, contact notes, and a log of past decisions
Agent writes a session summary to memory at the end of each engagement
Use Case 2: Development Team Agent (Software Teams)
A coding agent that learns the codebase conventions, preferred patterns, past architectural decisions, and recurring issues for a specific project — so it doesn’t give the same wrong suggestion twice.
What gets stored in memory:
Coding style guide for the project
Past refactoring decisions and why certain approaches were rejected
Known issues and workarounds in the codebase
Performance constraints and architectural boundaries
The problem this solves: agents without memory re-suggest patterns the team already evaluated and rejected, requiring the same explanation each session. With memory, those rejections are logged and the agent builds on them.
Configuration approach:
Memory store scoped to the project repository
Initialize with project conventions and architecture notes
Agent writes a session_log.md after each coding session with decisions made and issues found
Use Case 3: Research Agent (Knowledge Work)
A research agent that accumulates findings across sessions — building a persistent knowledge base from multiple research runs rather than starting from scratch each time.
Netflix’s internal agents use memory to carry context across sessions, including insights that took multiple turns to surface and corrections from human reviewers mid-conversation, instead of manually updating prompts between sessions.
Memory organized by topic: /research/[topic]/findings.md, /research/[topic]/sources.md, /research/[topic]/open_questions.md
Agent reads existing findings at session start before beginning new research
Human reviewer can add corrections directly to memory files via the API; agent picks them up next session
Use Case 4: Operations Agent (Business Operations)
Ops agents still need cost controls before they run.
An operations agent that manages recurring workflows — weekly reporting, vendor follow-ups, SOP updates — and carries forward the state of each workflow between runs.
What gets stored in memory:
Status of recurring tasks and workflows
Vendor and contact notes accumulated over time
Decision log for operational choices
Open items and their status
Configuration approach:
Memory organized by workflow: /ops/weekly-report/, /ops/vendor-follow-ups/
Agent reads open items at session start, completes what it can, updates status in memory
Operators review memory state weekly rather than re-briefing the agent
Use Case 5: Customer Support Agent (Support Teams)
A support agent that remembers each customer’s history, prior issues, resolutions, and communication preferences — so customers don’t re-explain their context on every interaction.
Ando is building their workplace messaging platform on Managed Agents, using memory to capture how each organization interacts instead of building custom memory infrastructure themselves.
What gets stored in memory:
Customer account context and tier
Prior issue history with resolutions
Communication preferences (tone, channel, response length)
Known product configurations or integrations the customer uses
Configuration approach:
Memory store per customer, scoped to their account ID
Initialize with CRM data (account type, history summary)
Agent writes a resolution summary after each ticket closes
Use Case 6: Legal and Compliance Agent (Legal Teams)
A compliance agent that tracks regulatory requirements, monitors changes, and maintains a running compliance status log — accumulating institutional knowledge across every compliance review it runs.
What gets stored in memory:
Current compliance status by regulation and jurisdiction
Prior audit findings and remediation decisions
Regulatory change log with effective dates
Open items requiring human review
Configuration approach:
Memory organized by regulation: /compliance/gdpr/, /compliance/hipaa/, /compliance/soc2/
Agent reads current status before each compliance check run
Writes updated status and flags human review items after each run
For regulated industries: memory redaction endpoint supports removing specific content from historical versions for GDPR/CCPA compliance while preserving the audit record structure.
Use Case 7: Sales Agent (Sales Teams)
A sales agent that knows each prospect’s engagement history, objections raised, competitive comparisons requested, and where they are in the buying process — without requiring a CRM update to carry context forward.
What gets stored in memory:
Prospect background and stakeholder map
Objections raised and responses given
Competitive questions and preferred comparisons
Next steps and commitments from prior conversations
Configuration approach:
Memory store per prospect, keyed to their company or contact ID
Initialize with CRM pull at first contact
Agent writes call summary and updated next steps after each prospect interaction
Use Case 8: Content Production Agent (Marketing Teams)
A content agent that learns the brand voice, audience preferences, what topics have already been covered, and what performed well — building a persistent content intelligence layer across every piece produced.
What gets stored in memory:
Brand voice rules and style examples
Topic map (what’s been covered, what’s planned)
Performance notes on past content (what resonated, what didn’t)
Client feedback on tone, format, and depth
Configuration approach:
Memory organized by brand: /content/[brand-name]/voice.md, /content/[brand-name]/topic_map.md, /content/[brand-name]/performance_log.md
Agent reads voice rules at session start before producing any content
Operator adds performance feedback directly to memory after publishing
Use Case 9: Finance Agent (Finance Teams)
A financial analysis agent that carries forward context on recurring reports — month-over-month trends, known anomalies, and prior analytical decisions — so each report builds on the last rather than starting from raw data.
Anthropic shipped a financial services agent template suite in May 2026, built on Managed Agents memory for cross-session continuity.
What gets stored in memory:
Key metrics and their historical baselines
Known data quality issues and how they’ve been handled
Prior period variances and the explanation documented at the time
Model risk notes for regulated environments
Configuration approach:
Memory organized by report type: /finance/monthly-pl/, /finance/board-report/
Agent reads prior period context before starting each new report cycle
Writes a period summary with key variances and decisions after each report run
Use Case 10: Onboarding Agent (HR and Operations)
An onboarding agent that adapts its guidance to each new hire’s role, prior experience, and progress through the onboarding checklist — and carries that context across every interaction during their ramp period.
What gets stored in memory:
New hire profile (role, team, prior experience notes)
Onboarding checklist progress
Questions asked and answers given (to avoid repetition)
Manager notes on priorities for this hire
Configuration approach:
Memory store per new hire, active during ramp period (typically 30–90 days)
Initialize with role profile and onboarding checklist
Agent writes progress update after each onboarding session
Archive or close memory store when onboarding period ends
What Memory Doesn’t Replace
Memory stores context and preferences. They don’t replace real-time data access, live system integrations, or human judgment on consequential decisions.
Memory is document storage, not a database. It works well for: text-based preferences, accumulated notes, decision logs, prior outputs. It doesn’t work well for: real-time status queries (use MCP connectors for those), structured data that needs querying (use a real database), or high-frequency writes (memory is designed for periodic updates, not per-turn state).
The right architecture in most production systems: memory for persistent context and preferences, MCP connectors for real-time system access, structured database for high-frequency operational data.
Memory for Claude Managed Agents is a workspace-scoped document store that persists across agent sessions. Instead of starting fresh each session, agents read and write memory files that carry context, preferences, and accumulated knowledge forward into every future session.
When did Managed Agents memory launch?
Claude Managed Agents launched in public beta April 8, 2026. Memory for Managed Agents entered public beta April 23, 2026.
How is memory different from a system prompt?
A system prompt is static and set at agent configuration time. Memory is dynamic — it’s written and updated by the agent during sessions and grows over time. Memory stores things the agent has learned or been told; system prompts store standing instructions that don’t change session to session.
What happens to memory when an agent is deleted?
Memory stores are separate from agent configurations. Deleting an agent doesn’t delete its memory store. Memory stores must be deleted or archived separately.
The Claude Agent SDK tutorial starts here — the SDK (formerly the Claude Code SDK, renamed late 2025) eliminates the boilerplate of building agentic loops by hand, shipping the same tool execution, context management, and permission system that powers Claude Code into a Python or TypeScript library you can embed in any product, pipeline, or internal tool.
This is a practical build guide. It covers when to use an agent versus a script, what the SDK actually does, how to set one up with working code, and what to watch for in production.
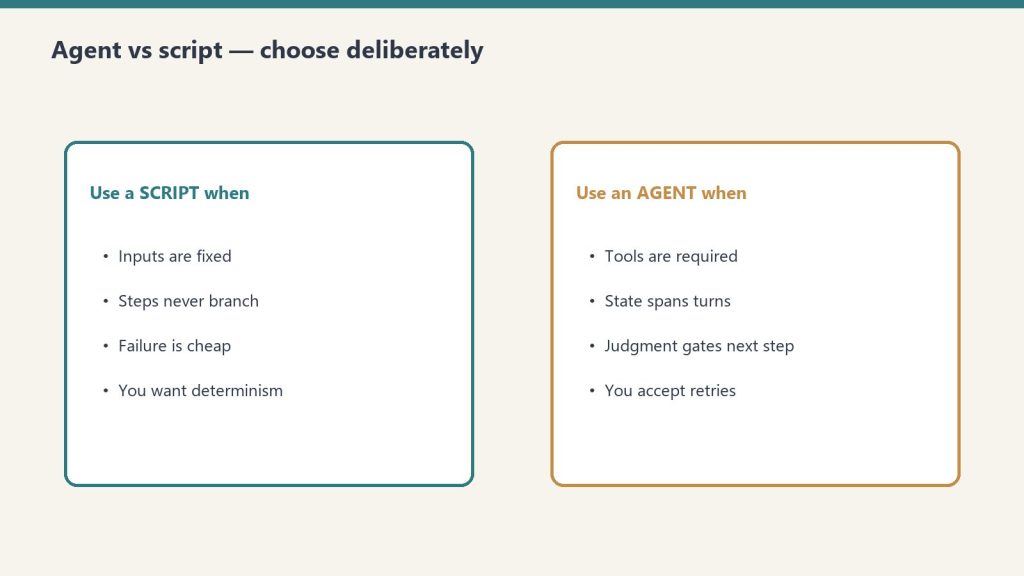
When to Use an Agent vs. a Script
Agent vs script — choose deliberately.
Use an agent when the number of steps to complete the task is unpredictable. If the workflow can be hardcoded, a linear script is faster, cheaper, and easier to debug.
This is Anthropic’s own guidance in Building Effective Agents, and it’s the right frame. The common mistake is reaching for agents because agents are fashionable — not because the problem requires them.
Agents fit:
Open-ended research tasks where the number of searches needed varies
Code debugging where the error chain isn’t known in advance
Multi-step data pipelines where decisions at each step depend on prior outputs
Any workflow where the model needs to try, observe, and adjust
Scripts fit:
Known sequences of steps that always run in the same order
Simple data transformation with no conditional branching
Any task where the output of each step is fully predictable
The cost implication matters too: a 15-step agentic research task can hit 200K+ tokens without optimization. Agents are expensive when you don’t need them.
How the Claude Agent SDK Works
How the Agent SDK loop behaves in practice.
The SDK automates the ReAct loop — Reason, Act, Observe, repeat — so you define the tools and instructions and the SDK handles the rest. You never write the prompt → check stop_reason → execute tool → loop boilerplate yourself.
The core loop the SDK manages:
Send the task to Claude with available tool definitions
Claude reasons and produces a tool call (or a final answer)
The SDK executes the tool in the local environment
The SDK sends the result back to Claude
Claude observes and decides: call another tool or produce final output
Loop until done
This continues until Claude produces a response with no tool calls. The SDK handles conversation history, token tracking, error handling, and session management across the entire loop.
A working agent requires three things: a task, tool definitions, and a Runner call. Everything else is configuration.
from claude_agent_sdk import ClaudeAgentOptions, Runner
import subprocess
import json

# Define tools the agent can use
tools = [
    {
        "name": "run_command",
        "description": "Run a shell command and return its output",
        "input_schema": {
            "type": "object",
            "properties": {
                "command": {
                    "type": "string",
                    "description": "The shell command to execute"
                }
            },
            "required": ["command"]
        }
    },
    {
        "name": "read_file",
        "description": "Read the contents of a file",
        "input_schema": {
            "type": "object",
            "properties": {
                "path": {
                    "type": "string",
                    "description": "File path to read"
                }
            },
            "required": ["path"]
        }
    }
]

# Tool execution handlers
def execute_tool(tool_name: str, tool_input: dict) -> str:
    if tool_name == "run_command":
        result = subprocess.run(
            tool_input["command"],
            shell=True,
            capture_output=True,
            text=True
        )
        return result.stdout or result.stderr
    elif tool_name == "read_file":
        with open(tool_input["path"], "r") as f:
            return f.read()
    return f"Unknown tool: {tool_name}"

# Configure and run the agent
options = ClaudeAgentOptions(
    model="claude-sonnet-4-6",
    max_turns=20,               # safety ceiling
    tools=tools,
    tool_executor=execute_tool
)

result = Runner.run_sync(
    task="Check the disk usage on this machine and report the top 5 largest directories under /home",
    options=options
)

print(result.final_output)
That’s a complete working agent. The SDK handles the loop; the tool definitions and executor are the only custom code.
Adding Cost Controls
Add cost controls before multi-turn agents hit production.
Always set a max_turns ceiling and a token budget. An uncapped agent loop can run indefinitely on an ambiguous task.
options = ClaudeAgentOptions(
    model="claude-sonnet-4-6",
    max_turns=20,
    max_tokens_per_turn=4000,   # cap per individual turn
    tools=tools,
    tool_executor=execute_tool
)
Cost at 20 turns using Claude Sonnet 4.6 with an average of 2,000 tokens per turn:
Input: 40,000 tokens × $3/M = $0.12
Output: 10,000 tokens × $15/M = $0.15
Total per agent run: ~$0.27
At 1,000 agent runs per month: ~$270. At 10,000: ~$2,700. Budget from these numbers, not from seat prices.
Switching the inner loop to Haiku 4.5 for tool selection and Sonnet only for synthesis cuts cost significantly:
# Route lighter reasoning to Haiku, reserve Sonnet for synthesis
light_options = ClaudeAgentOptions(model="claude-haiku-4-5-20251001", ...)
heavy_options = ClaudeAgentOptions(model="claude-sonnet-4-6", ...)
Multi-Turn Agents (Conversational)
For agents where a human asks follow-up questions across multiple turns, maintain conversation history and pass it on each call.
from claude_agent_sdk import ClaudeAgentOptions, Runner

conversation_history = []

def chat_with_agent(user_message: str) -> str:
    conversation_history.append({
        "role": "user",
        "content": user_message
    })

    options = ClaudeAgentOptions(
        model="claude-sonnet-4-6",
        max_turns=10,
        tools=tools,
        tool_executor=execute_tool,
        messages=conversation_history  # full history each call
    )

    result = Runner.run_sync(task=user_message, options=options)

    conversation_history.append({
        "role": "assistant",
        "content": result.final_output
    })

    return result.final_output

# Usage
print(chat_with_agent("What Python packages are installed on this system?"))
print(chat_with_agent("Which of those are outdated?"))
Claude Managed Agents vs. the Agent SDK
The Agent SDK runs locally in your environment. Claude Managed Agents runs in Anthropic’s cloud infrastructure with persistent sessions, built-in tools, and cross-session memory. Choose based on where you need the agent to execute.
Agent SDK
Managed Agents
Where it runs
Your server / local machine
Anthropic-managed cloud
Persistent sessions
Manual (maintain history)
Built-in
Cross-session memory
Manual
Built-in (public beta)
Built-in tools
Bring your own
20+ included
Multi-agent coordination
Manual
Built-in
Cost
API tokens only
API tokens + platform fee
Control
Full
Managed
The Agent SDK is right for custom environments, data that can’t leave your infrastructure, and workflows deeply embedded in existing systems. Managed Agents is right when you want to skip infrastructure and get to the agent behavior faster.
What Goes Wrong in Production
The most common production failures are uncapped loops, conversation history that grows without bound, and tool definitions written too vaguely.
Uncapped loops: An agent on an ambiguous task will keep calling tools indefinitely without a max_turns ceiling. Always set one. Always check message.subtype rather than is_error — a max-turns termination doesn’t set is_error: true correctly in some SDK versions.
Growing conversation history: Each turn adds tokens to history. At 20 turns on a complex task, history can push 100K+ tokens. Summarize aggressively between phases for long-running agents: prompt Claude to summarize phase 1 outputs before starting phase 2.
Vague tool definitions: Tool descriptions are how Claude decides which tool to call and how to use it. Vague descriptions produce tool call errors and unnecessary retry loops. Write tool descriptions as precisely as you would write a function docstring — what it does, what inputs it expects, what it returns.
camelCase vs snake_case mismatch:AgentDefinition uses camelCase (disallowedTools); ClaudeAgentOptions uses snake_case (disallowed_tools). This caught teams in early SDK versions.
The Claude Agent SDK is Anthropic’s Python and TypeScript library for building autonomous AI agents. It wraps the same agentic loop that powers Claude Code — tool execution, context management, and session handling — so developers don’t build that infrastructure from scratch. It was formerly called the Claude Code SDK and was renamed in late 2025.
What is the difference between the Agent SDK and Claude Code?
Claude Code is Anthropic’s interactive terminal-based development tool for agentic coding. The Agent SDK is the programmatic library for embedding agent behavior in custom applications and pipelines. They share the same underlying agent loop and tool system. Claude Code stays in the picture for interactive development; the SDK is for production automation.
How much does it cost to run an agent?
Agent cost is API token cost only (no platform fee for the SDK itself). A 20-turn agent on Claude Sonnet 4.6 with 2,000 tokens average per turn costs approximately $0.27. At 10,000 agent runs per month, that’s about $2,700. Switching the tool selection loop to Haiku 4.5 and reserving Sonnet for synthesis significantly reduces cost.
When should I use Managed Agents instead of the Agent SDK?
Use Managed Agents when you want cloud-hosted execution, persistent cross-session memory, built-in tools (20+ included), and multi-agent coordination without building that infrastructure yourself. Use the Agent SDK when you need local execution, full control over the environment, or your data can’t leave your infrastructure.
Compare Claude Sonnet 5 / Sonnet 4.6 / Opus 5 against GPT-5 / GPT-5.6 Sol. Fable 5.1 sits above Opus on Anthropic’s list price.
Model
Provider
Input (per 1M tokens)
Output (per 1M tokens)
Context
Claude Haiku 4.5
Anthropic
$1
$5
200K tokens
Claude Sonnet 5
Anthropic
$2
$10
1M tokens
Claude Sonnet 4.6
Anthropic
$3
$15
1M tokens
Claude Opus 5 / 4.8
Anthropic
$5
$25
1M tokens
Claude Fable 5.1
Anthropic
$10
$50
1M tokens
GPT-5
OpenAI
$1.25
$10
400K tokens
GPT-5.6 Sol (short-context promo)
OpenAI
$4
$20
see OpenAI long-context rows
The September 17 version of this page listed Sonnet 5 at $3 / $15. The live Anthropic table on September 22 lists Sonnet 5 at $2 / $10. Sonnet 4.6 is still $3 / $15. GPT-5 standard list ($1.25 / $10) remains cheaper per input token than Sonnet 5. GPT-5.6 Sol promo ($4 / $20 short context) is listed through at least November 21, 2026.
Coding Performance
Use Claude Opus or Sonnet for interactive coding and agentic runs. Use GPT-5 mini or Haiku-class models when throughput beats depth.
Latency and Context
GPT-5 is faster on raw throughput. Claude Sonnet/Opus SKUs publish a 1M token context window versus GPT-5 at 400K. Sonnet 5 at $2 / $10 is cheaper than Sonnet 4.6 at $3 / $15 for the same window class.
Cost Comparison for Real Workloads
OpenAI is still cheaper per token at GPT-5. Claude’s cache-read discount (10% of input on most SKUs; 2.5% on Fable 5.1) and 50% batch API close the gap when the system prompt repeats. For stateless high-frequency calls, GPT-5 wins on the published standard list.
Which API to Choose
Use Claude for coding, long-context document work, and agentic workflows. Use GPT-5 for high-frequency stateless calls. Running both is normal.