Tag: Automation

  • AI Governance Is the Gate That Caught the Thing

    AI Governance Is the Gate That Caught the Thing

    Most AI governance is written by people who have never had to govern an agent that could actually break something. It reads like insurance paperwork: frameworks, maturity models, principles laminated on a wall. Then a real agent, on a real Tuesday, publishes your drafting notes as if they were the article — and the framework has nothing to say about it, because the framework was never in the room.

    We run a small agency where AI agents do real production work every day: research, drafting, publishing, measurement, and an unattended night queue that runs while we sleep. Governance, for us, is not a document. It is the set of gates that have caught real things. Every rule below exists because something specific got past us first, and the rule is the scar.

    Governance starts with who is allowed to remember

    The agents are stateless; the memory lives in one place. Every agent we dispatch starts cold. It knows nothing about our clients, our sites, or yesterday’s decisions until its work order tells it. That sounds like a limitation. It is the control surface. Because the agent holds no standing memory, it holds no standing permissions either — every job is scoped, priced, and bounded by the order that created it, and when the job ends, the access ends with it.

    The work order itself is a governance document. It states the whole price up front, names the points where a human must tap before work proceeds, and lists what the executor may ship directly and what it must hold. An agent that has to ask a question the order should have answered is not a governance failure by the agent. It is a drafting failure by us, and we treat it that way.

    Draw the doors as lines, not policies

    Four things always need a human tap: money, credentials, outbound sends, and publishing. Everything else, the fleet runs on its own. That split is the entire access policy, and it fits in one sentence because it has to survive contact with a tired operator at the end of a long day. Policies that need interpretation get interpreted — usually at the worst moment, in the most generous direction.

    Credentials get the hardest line. Our agents never hold passwords, never see them, never pass them along. Work that reaches a login the agent cannot complete through an already-signed-in session does not get worked around. It stops, logs a hold, and waits for the human whose door that is. One night this fall, a run reached a registry login at three in the morning. The operator could not face the tap, said so, and went to bed. The work was built to survive stopping, so stopping cost nothing. The credential never moved. That is what a line is for: it has to hold when nobody has the energy to argue with it.

    The risk is not a rogue agent. The risk is a report you believe.

    Every serious failure we have had was a verification failure, not a rebellion. A judge model, asked to grade drafts against a length limit, invented word counts that were off by a quarter to a third — confidently, in both directions. A publish report stated a post ID from memory instead of reading it back from the result file, and the number was wrong. A page was verified from its HTML source and declared fine while its signup form rendered as blank white cards. Drafting notes were once published as article content because the check stopped at “the words are there.”

    So the rule is mechanical: proof lives at the receiving end. Numbers get read back by value from the file that recorded them. Pages get verified as rendered pages, in a browser, the way a reader sees them — not from source. A finished article must show visible structure, or it is a hold, not a publish. None of this requires trusting the agent less. It requires trusting the report exactly as far as the evidence under it, which is where trust should have been calibrated all along.

    We also measure trust per model, the way you would per employee. In scored head-to-head runs on identical briefs, exactly one of our models graded perfectly — every defect real, no invented ones — so that model holds the verifier seat. Another writes fast and clean but invents defects when it judges, so it drafts and never judges. The cheapest tier once certified work it had not actually checked, so its output is never trusted without a pass behind it. “The AI said so” is not a control. A scorecard is.

    Failures become regressions, not folklore

    Every break gets an ID, an entry in the failure ledger, and a gate. When the night queue failed in a new way, the failure was written down with its cause and its receipt, and a regression check was built that fails the next run if the same shape reappears. The ledger is unglamorous. It is also the difference between an operation that learns and an operation that just has stories. Governance that lives in people’s memories leaves with their mood, their weekend, and eventually their employment. Governance that lives in a gate runs every time.

    Each work order also carries one pre-decided instruction for the moment something breaks: if a step’s end state cannot be verified, stop that step, log the hold, and move to the next independent step. Never improvise past a failed check. The decision is made in advance, in calm, because the middle of a failing run is the worst possible place to invent policy.

    The 3 a.m. test

    Here is the only governance question we ask anymore: what can this system not do at 3 a.m.? Our night queue runs unattended with hard caps — a maximum number of jobs, a maximum number of attempts, a hard stop before dawn, and a pause switch that halts everything if a single file exists. Agents working overnight cannot spend money, cannot send anything to anyone, cannot touch a credential, and cannot publish. They can draft, measure, and report. Morning is a review: a human reads what the night produced, approves what is good, and the approvals are the fuel for the next day’s work.

    That is the whole philosophy. Governance is not the set of things your agents are allowed to do. It is the set of things they structurally cannot do while you are asleep, plus the evidence trail that lets you check everything else over coffee.

    What this is not

    This will not satisfy a compliance department, and it is not meant to. If you handle medical records or other people’s money under regulation, you need the paperwork kind too. But the paperwork kind alone will not save you from the ordinary failures — the believed report, the generous interpretation, the confident invented number — because those failures are not compliance failures. They are operating failures, and they happen at every scale, in shops with two people and in companies with two thousand.

    Start where the risk actually is. Give the agents no memory and no keys. Draw four doors and hold them. Verify at the receiving end. Write every failure down and make it a gate. Then run the 3 a.m. test on your own setup, honestly, and fix what it shows you. The framework can come later. The gate that catches the thing comes first.
  • The First Agent You Hire Answers the Phone

    The First Agent You Hire Answers the Phone

    Nobody’s first AI hire is a strategist. Ask a room full of operators what they’d hand off first and nobody says the thinking — they say the phone. The call that comes in at 6:40, after the office went dark at five. The form filled out at midnight, water coming through the kitchen ceiling. The lead that goes to whichever company answers first — and in home services, the first answer is very often the whole sale.

    That seat — first response — is where small businesses are actually hiring agents, and the money just said so out loud. On October 13, Dapta, an AI sales agent company out of Scottsdale and Miami, announced a $6 million seed round led by Chingona Ventures. Its agent, Dapti, answers, qualifies, and books the meeting the moment a prospect reaches out — no human touching it. Dapta says 200,000-plus users are on it, signing up at better than 4,000 a week, and that revenue will pass $4 million this year. Home services is one of the verticals where it took hold first.

    The seat, in a real shop

    First response in a small shop is a person-shaped hole. The owner answers between jobs, one glove off. The office manager answers until five. After five, a service answers, or nobody does, and the prospect — wet floor, search results page in hand — calls the next name on the list. It’s a staffing problem, not a marketing problem — one that shows up at the exact hours nobody wants to staff.

    The money makes it worse. On Google Local Services, a connected call that runs past twenty seconds can bill you whether a person picked up or not — you pay for the ring. And the caller isn’t comparison-shopping at leisure. They’re standing in water, or sleeping in a 90-degree house, and they hire the first competent voice that treats them like a person.

    What the agent can own outright

    The front half of the seat is script work, and script work is exactly what an agent is for. Answer instantly, at any hour, in the customer’s own language — Dapta got its start with Spanish-speaking owners in the U.S., and first response is meeting the customer where they are. Ask the basic qualifying set: what happened, where is it, when did it start, who is paying, how do we reach you. Then do what most shops fumble even in business hours: put a real appointment on a real calendar, confirmed where the customer can see it — not a callback promise the morning forgets.

    None of that requires judgment — just the script, the calendar, and the discipline to run both at 2 a.m. the way they run at 10 a.m., on the nights the office sits empty.

    What the human keeps

    Qualification questions are not qualification judgment, and the difference is the entire ballgame. The questions collect facts. The judgment decides what the facts mean: Is this a job we want — at this size, this distance, for this payer, with the crews already buried? A flooded kitchen ten minutes away and a “come look at a stain” forty minutes out both answer the questions perfectly. Only one of them should get your Saturday.

    The human also keeps pricing, promises, and the handoff. What a job costs is a person’s call, made with the board in front of them. “We’ll have a crew there by nine” is a promise only someone who knows the crew should make. And the moment a prospect stops being a lead and starts being a customer — when they need to hear a real person owns their problem — a person takes the conversation. The agent’s job is to make that moment arrive fast, facts collected and appointment real. It is not to be that moment.

    The failure shape

    Hand an agent the whole seat — the questions and the judgment both — and it will qualify everybody. It will book the estimate outside your service area because nothing told it distance matters. It will fill the calendar with meetings a person would have filtered in thirty seconds — and once your techs learn to distrust anything the system books, you have automated the exact problem you bought it to solve. The bad version doesn’t fail loudly. It fails as a slow leak — wasted drive time, stood-up appointments — until somebody turns it off and announces that AI doesn’t work.

    The seat works when its boundary is drawn, not when the model is smart. A boundary is a list: what it can ask, what it can book, what it can never promise, and where it stops and hands over. Dapta’s own framing stops at answer, qualify, schedule — first response, not the close. That is not a limitation. That is the product, correctly shaped.

    Hire it like a person

    You would never hand a new receptionist the phone on day one with no script, no boundary, and no “if it’s this, come get me.” An agent seat deserves the same three things, because it is the same hire: a script it runs word for word, a boundary it does not cross on its best day, and an escalation path that puts a human in the conversation the moment judgment enters.

    The $6 million is a bet that every small business staffs this seat the way it eventually got a website. The operators who get it right will not be the ones with the smartest agent. They will be the ones who wrote the seat down — job, boundary, and the name of the human who owns the judgment — before they let anything answer their phone.

    Sources: “Dapta Raises $6M to Accelerate the Adoption of AI Sales Agents for SMBs across the U.S. and Latin America,” Dapta LLC via GlobeNewswire, October 13, 2026 — globenewswire.com. User, signup-rate, and revenue figures are Dapta’s own statements in that release.

  • Desktop, Cloud, or API: One Cursor Harness, Three Seats

    Desktop, Cloud, or API: One Cursor Harness, Three Seats

    The seat is a routing decision

    Cursor is not one tool in this shop. It is three seats that share a harness — a Desktop app on a laptop, cloud agents behind an API, and a phone — and picking the wrong one wastes the day in a characteristic way. Desktop waits on a human. The cloud knows nothing about your logged-in life. The phone is a steering wheel, not a workbench. The routing rule we run: the seat is decided by where the work’s context lives.

    Desktop wins when the unlock is a logged-in browser

    A Desktop sitting is a supervised run: a written work order, an executor (Composer 2.5 in our shop) that makes an unaided first pass in its own words before any templating, and a human in the room for the real gates. Its superpower is everything the laptop already is — signed-in dashboards, the WordPress admin, the GA4 Advisor, the files on disk. When a fleet site needs hands inside a web UI that only exists behind Will’s login, no API lane substitutes.

    We learned the boundary the hard way. On October 18, an executor stopped cold at a site’s login redirect and left the step undone — which cost that sitting its unlock path. The standing rule now: in a sitting on Will’s own laptop, the executor clicks through sign-ins using the browser’s saved session. Saved-login only. No saved login means the step logs a HOLD — nobody hunts a password, ever.

    Desktop’s honest cost: it waits on a human, and a queued sitting is not a running job. Our TM pricing diagnosis (WO-353) has sat untouched since October 18 at 6:16 PM — steps written, folder staged — because a sitting starts when Will sits down. Anyone who tells you their Desktop pipeline is autonomous has not watched a folder sit still for a day.

    The cloud wins when the work fans out

    Cloud agents, launched from this desk over api.cursor.com, are the opposite shape: no login, no laptop, no waiting room — and they multiply. On October 16 we ran a census through that API: 44 models, one identical brief, five comparison rounds, graded on their execution trajectories. That is a shape of work a single Desktop seat cannot do before lunch, and it set our model routing for everything since.

    The scale shows in the bookkeeping: our completion watcher has seen 1,431 cloud agents come and go. The API runs two launch shapes for us — repo tasks that come back as pull requests, and no-repo research and evaluation runs with the model pinned in the launch body. The API is beta, and we treat it that way: when an endpoint changes shape, the error gets surfaced plainly, never papered over with invented fields.

    Mobile wins when the human is the bottleneck

    The phone’s job is judgment at human speed. Will reviews runs, reads results, and steers from his phone while the machines work elsewhere — and because a review that evaporates is a review wasted, a distiller folds his mobile and Desktop runs into the shop’s memory and Feed every 20 minutes. Mobile is not a production surface here. It is where the approvals live, and approvals are the scarcest resource in the building.

    What each seat’s failure taught the kit

    • Desktop: permission prompts were taxing the one human in the loop — fixed by a Step 0 permissions pre-flight in every work order (October 18): the executor declares the commands it expects up front, the human approves once, and prompts are reserved for sends, deletions, money, and credentials — which are never pre-approved.
    • Cloud: a finished summary is not evidence — fixed by trajectory grading and a completion watcher: results are verified at the receiving end, or they are not results.
    • Mobile: steering from the phone only counts if it lands in the record — fixed by the 20-minute distiller.

    One harness, three seats, and a routing rule a shop can steal: if the context is a login, sit down at Desktop. If the work fans out, launch it in the cloud. If the blocker is a decision, put it on the phone.

    Method & settings — this piece

    Evidence: This shop’s work-order record, October 2026: WO-198 standard, the WO-343 and WO-348 sittings, the WO-353 stall, the October 16 cloud census

    Desktop: Cursor 3.25.9 on Will’s laptop (read from the install, October 19, 2026); executor seat Composer 2.5

    Cloud: api.cursor.com/v1 (beta); completion watcher count 1,431 agents seen as of October 18, 2026

    Mobile: Cursor mobile app in a review/steer role; runs distilled into memory + Feed every 20 minutes

    Filed under the Cursor desk — where the catalog and the changelog are watched daily.

  • The Operator Is the Harness

    Somebody I follow posted a testing result this week that most people scrolled past. His benchmark harness plants defects in a codebase, lets an agent fix them, and then checks something subtler than whether the defect went away: whether the agent broke something else on the way through. A changed defect signature, he pointed out, is not proof of a correct fix. The bug can change shape and still be a bug. What catches that isn’t a better model. It’s the harness — the checks around the work.

    He’s right, and he’s also only halfway to the point. The harness matters. But who built the harness? Who decided what gets checked, what gets automated, and what never gets automated at all? That’s not the model. That’s the operator.

    I run a small fleet of websites and a stable of AI agents, and I test models the way you’d test trucks: same load, same road, see what happens. This month I ran one identical production brief through 44 different models — flagships, mid-tiers, cheap ones, open ones. Five rounds of comparisons. The results rearranged everybody’s assumptions, including mine. A mid-priced model I’d never heard anyone brag about did the best first-pass work on the board, at a fraction of the flagship cost. Models with famous names flopped on judgment calls. The leaderboard the internet argues about had almost nothing to do with the leaderboard in my shop.

    But here’s the part that actually matters: the brief was the same for all 44. Same instructions, same constraints, same definition of done. The spread in results wasn’t really a spread in models. It was a spread in how much each model needed the operator to have thought clearly. The ones that did well did well because the work was set up so that doing it well was the path of least resistance — the mission was written down completely, the boundaries were structural instead of hopeful, and the verification at the end didn’t care how confident the answer sounded.

    I grade my agents the way that benchmark grades code: not by the summary they hand me, but by the steps they actually took. I built a scorer that reads the execution record — what the agent went and looked at, how many sources it actually consulted, whether the answer was built on evidence or generated from memory with good posture. It has caught polished, lengthy, completely confident answers that were built on zero consulted sources. Zero. The answer read beautifully. It was worthless. The model didn’t fail there; the operation almost did, because a summary is the easiest thing in the world to fake and I was nearly set up to accept summaries.

    That’s the work nobody posts about. Deciding what the machine is allowed to do alone and what it is never allowed to do alone. In my shop, agents draft, research, extract, and stage. They do not touch money, they do not send anything with a commitment in it, and nothing publishes on an agent’s say-so — there’s a verification pass that reads the actual result at the receiving end, because “the API said 200” has lied to me more than any model ever has. Those rules aren’t prompts. Prompts are suggestions. The rules live in the structure: separate accounts, staged drafts, checkpoints that halt the batch when a check fails instead of improvising past it.

    My dad had a saying: a locked door keeps an honest man honest. You don’t make work reliable by telling the worker “don’t mess up.” You make it reliable by building the room so the mess-up is hard to reach.

    So when people argue about which model is best, I hear a question about drivers asked by people watching cars. If you’re a good driver, you can drive anything. Give me a mid-tier model, a cheap model, a local model running on a beat-up laptop — with a clear brief, structural boundaries, and honest verification, I’ll out-produce a careless operator running the flagship. Not because the model doesn’t matter at all. It matters the way a truck matters: payload, turning radius, fuel. But the truck has never once decided where the load needed to go.

    The model is rented. It changes every few weeks and the prices change faster. The operation — the judgment about what to automate, the discipline of verifying at the receiving end, the memory of every way it has gone wrong before — that’s the asset, and it compounds. Everybody I know is shopping for a better engine. The race is being won by the people building better drivers.

  • The Best Recovery Product Reads the Name Against the Hold

    The Best Recovery Product Reads the Name Against the Hold

    The state already holds the money. The person still has a name that may not match the old address. That gap is the product.

    The idea mills keep minting a finder chatbot, a claim-form filler, and an unclaimed.ai. Three names. One object. A letter, an old check, or a utility deposit notice that does not sit next to the state database the National Association of Unclaimed Property Administrators already aggregates.

    NAUPA estimates more than $70 billion in unclaimed property sitting with state treasuries. Roughly one in seven Americans has something waiting. States return more than $3 billion a year. Those numbers have been stable enough for years. What changed in 2026 is the infrastructure around them.

    Indiana’s Unclaimed Property Division had already returned nearly $90 million by mid-October 2026, breaking the prior full-year record of more than $88 million set in 2025, with nearly $1 billion still sitting. Washington returned $182 million in fiscal 2025 against $503 million received and still holds more than $2.8 billion. Louisiana lists $1.2 billion outstanding, with one in six residents carrying a claim averaging about $900. The money is not theoretical. It is already on the books.

    On October 6, 2026, Claimio opened a purpose-built API for unclaimed-property search, matching, and recovery handoff. The platform had already helped recover more than $8.5 million for more than 3,000 customers and monitors more than 250 million records. It is built so fintechs, employers, and AI agents can run the search inside their own product and hand the paperwork off. Performance-based. No upfront fee to the owner. That is the first real plumbing the mills have had for this category.

    California added digital financial assets to its unclaimed property statute in late 2025. Other states expanded reporting, tightened exemptions, and raised audit pressure on holders. NAUPA is moving reporting formats toward XML in phases starting 2027. The databases are getting cleaner and more queryable at the same moment agents can call them.

    The product is the join.

    Do not build “AI for state treasuries” or “AI for finders.” Those slogans die in a demo. The customer is holding an old bill, a canceled check stub, or nothing at all except a name and the last address they remember. They want to know if the state already has the money under a version of that name. The product is the page that puts the name next to the hold.

    Primitive one is photo-and-PDF review. The mills have been shipping receipt readers for months. Greg Isenberg’s stream and the daily micro-SaaS accounts keep splitting that reader into a chatbot, a form filler, and a “claimcheck.ai.” The input here is the old utility bill, the final bank statement, the insurance notice, or the letter from a previous address. Name in the header. Address on the stub. Account number if it survived. The model extracts the fields. The human never has to type them twice.

    Primitive two is the public hold. Every state runs a free search. MissingMoney.com and the individual state portals already exist. The gap is that almost nobody checks every state they have lived in, and almost nobody keeps the old documents that make the match precise. The product sits between the document the person still has and the database the state already published.

    The wedge is a free checker. Not a platform.

    Paste the name and the last address you remember. Or upload the photo of the old bill. Thirty seconds later: match, possible match, or none. If it is none, you still captured a labeled name and address. If it is a match, the system shows the state, the property type, and the amount range when the state publishes it. You do not file yet. You see the hold.

    That is the only honest first action. Zero risk. The stranger already has the name. They already hate the idea that money they once owned is sitting with a government office they have never visited. Thirty seconds is short enough that they will try it this week.

    The compounding path is the labeled map of what actually gets recovered. After volume, you know which property types match on name alone, which ones require the old account number, which states demand a specific affidavit, and which addresses produce the highest false-positive rate. That map is not a third dashboard. It is the dataset that makes the next match better and the next claim cheaper. The mills will keep proposing a new .ai name for each state form. Ignore the names. Join the line. Keep the map.

    Irreversible steps require a human signer. Filing the claim moves money. Some states ask for ID, proof of address, or a signed form. Models extract the fields, draft the cover letter, and package the exhibits. A person reviews and owns the send. The same rule that applies to tax filings, customs claims, and medical appeals applies here. Models draft. People own the send.

    Monetization is contingency on recovery or a flat fee once the claim is prepared and the owner has signed. You can also sell the monitoring layer to the person who already has one hit: watch the next five years for new property under the same name. Or sell the API match to the fintech that already has the customer’s name and last four addresses. The free checker is the acquisition. The map is the moat.

    The mills have already floated pieces of this. One post wants a refund radar for marketplace sellers. Another wants a Social Security clawback defense. A third wants an IRS nonfiler catch-up service. Useful pieces. Wrong cut if you leave them as separate products. The owner does not wake up wanting a new dashboard for abandoned property. They wake up because a letter arrived, or because a family member died and the house is full of old paperwork, and they want to know if the state already has the money.

    Someone will own the labeled map of noticed versus held. The mills will keep proposing a new .ai name for each state portal. Ignore the names. Join the line. Keep the map.

    Will Tygart — Tygart Media.

    This is the idea-mill series.

  • The Best Clawback Product Reads the Notice Against the Rule

    The Best Clawback Product Reads the Notice Against the Rule

    The agency already set the withholding rule. The family still holds a notice that may not match it. That gap is the product.

    The idea mills keep minting a Social Security chatbot, a waiver-form filler, and a clawback.ai. Three names. One object. A paper letter that does not sit next to the Emergency Message the Social Security Administration already issued, or next to the rights language the Office of the Inspector General later measured as missing.

    Greg Isenberg’s stream and the daily micro-SaaS accounts keep splitting the same reader. One post wants an agent that finds class-action money in your inbox. Another wants a refund chaser for marketplace sellers. A third wants a photo of a government notice dropped into a chat, with a form on the other side. The useful cut is narrower. The notice is already in the mailbox. The rule is already public. The join is the company.

    Why now is a number, not a feeling

    On April 25, 2025, SSA issued Emergency Message 25029. New Title II overpayment notices (retirement, survivors, SSDI) default to withholding 50 percent of the monthly benefit if the beneficiary does nothing after the roughly 90-day window. That replaced the 10 percent cap that had been in place for most of 2024. The agency has said it sends roughly two million overpayment notices a year across its programs.

    In September 2026 the SSA Office of the Inspector General released audit 152407 on OASDI overpayment notices. Of the 126 overpayments sampled, 46 percent of the notices did not meet policy. Missing explanations of how and when the overpayment occurred. Omitted reconsideration and waiver rights. Inaccurate dollar amounts. Conflicting language. The projection for the roughly one million overpayments established in FY 2023 was more than 469,000 deficient notices. Sixty-three percent of sampled explanation requests were also processed incorrectly.

    Those two facts sit next to each other. The default recovery rate went up. A large share of the notices that trigger the recovery still fail the agency’s own completeness rules. The adult child who opens the letter does not need a chatbot. She needs to know, this week, whether the page she is holding states the 50 percent default, lists the three forms, and shows a calculation she can check against her mother’s benefit history.

    Two primitives, one wedge

    Primitive one is the photo or PDF of the private notice. The mills have been shipping receipt readers for months. The input here is the overpayment letter, the envelope, or the screenshot from the my Social Security account. Amount claimed. Period covered. Withholding language. Rights language. Deadline.

    Primitive two is the public rule and the public file. EM-25029 and its later revision. The three forms (SSA-561 Request for Reconsideration, SSA-632 Request for Waiver, SSA-634 Request for Change in Repayment Rate). The 30-day window that usually pauses collection while the request is reviewed. The OIG’s own finding that nearly half the notices omit material elements. Nothing here is secret. The agency was required to write the rule and the forms. The OIG was required to measure the notices.

    The product is the join. Photograph the notice. Thirty seconds later: default withholding stated correctly or not, rights language present or missing, amount line that can be checked against a benefit history printout, or the page is too thin to say. No account for the first answer. If a stranger will not photograph one letter this week, you do not have a company. You have a policy thread.

    The compounding path is the labeled map, not a third dashboard

    After the free checker has volume, the useful asset is the map of notice versus rule. Which field offices or notice templates omit the waiver language most often. Which calculation methods produce the largest unexplained gaps. Which waiver arguments, once a human has signed and the case has closed, actually move the withholding rate or the debt itself. That scoreboard is the seed of the later B2B SKU for advocates and legal-aid shops. It is not a dashboard of “possible savings.” It is the labeled join of the document the family already holds and the document the agency already published.

    Models draft the packet. People own the send. Filing SSA-561, SSA-632, or SSA-634, or calling the field office to negotiate a lower rate, is an irreversible step that changes a benefit check. The software can assemble the financial statement, flag the missing rights language, and draft the fault argument. A human signer presses the button. Charge after the free verdict shows a clear mismatch, or do not charge. Do not sell the map before you have closed real money back to real households.

    What not to build

    Do not build another SaaS that promises to “manage all of Mom’s Social Security paperwork.” That is a platform. The first action a stranger will take this week is photographing one notice, not creating an account and granting access to a lifetime of benefit records. Do not build an AI that files the form without a human on the send. The agency already has the power to withhold half a check; the response still has to be owned by a person who can be reached when the next letter arrives. Ignore the new .ai names. Join the line the notice and the rule already form.

    Why this cut, not the last one

    The leakage essay was tariffs, seats, and subscriptions. The rebate essay was a nameplate. The recall essay was a label. The short-pay essay was a contractor packet. The bill essay was an EOB against a hospital file. The tax essay was a notice against the roll. The utility essay was a statement against a filed tariff. The housing essay was a unit against a score. The delay essay was an itinerary against a code. The HOA essay was an assessment against a study. The 401(k) essay was a fee against a filing. The pharmacy essay was a receipt against an acquisition file. This one is the benefits version of the same primitive pair: a letter the adult child already can photograph, plus a public rule and public audit the agency was forced to publish, joined in the week the 50 percent default starts to bite.

    The noticing used to require a benefits counselor and a long hold. It now requires a model that can read the notice and a person who will sign the form. Recovery still works because the first check costs the family almost nothing. Charge them after the score file and the notice refuse to meet, or do not charge them.

    Someone will own the labeled map of notice versus rule. The mills will keep proposing a new .ai name for each SSA form. Ignore the names. Join the line. Keep the map.

    Will Tygart — Tygart Media.

    This is the idea-mill series.

  • What Are the Best Claude-Notion Workflows for a Small Business?

    Short answer

    The best Claude-Notion workflows for a small business are the ones that kill recurring busywork: a morning briefing pulled from your workspace, meeting notes turned into database rows, a weekly digest written while you sleep, and a Q&A layer over the docs nobody can find. Four workflows, set up once, paying rent every week.

    Before you automate anything

    Connect Claude to Notion first via the MCP connector (OAuth through Claude Desktop, two minutes), share the pages Claude needs to see, and set the approval habit: Claude drafts, you approve. Every workflow below assumes that foundation. Start with one workflow, not four.

    Workflow 1: The morning briefing

    Problem: You open Notion and spend 20 minutes figuring out what matters today.
    Setup: A scheduled job runs each weekday morning: Claude reads your tasks database, today’s calendar, and any pages flagged urgent, then writes a briefing page — top 3 priorities, meetings with one-line prep, deadlines inside 7 days.
    Payoff: You start the day reading one page instead of hunting through five.

    Workflow 2: Meeting notes → database rows

    Problem: Action items die in meeting notes.
    Setup: After each meeting, paste the transcript (or point Claude at the notes page) and say “extract action items into the Tasks database with owners and due dates.” Claude creates the rows, sets properties, links them to the meeting page.
    Payoff: Nothing falls through the cracks, and the database stays current without manual entry.

    Workflow 3: The weekly digest

    Problem: Friday status updates eat an hour of writing.
    Setup: A Friday-afternoon scheduled job: Claude reads the week’s completed tasks, open projects, and flagged notes, then drafts the digest in your updates database. You review, edit, approve.
    Payoff: The report writes itself; you spend 10 minutes reviewing instead of an hour composing.

    Workflow 4: Ask your workspace anything

    Problem: “Where did we put the client’s brand guidelines?” — asked weekly, answered by archaeology.
    Setup: No setup beyond the connection. Ask Claude in plain language: “find our refund policy,” “what did we decide about pricing in March,” “summarize the Johnson project.” It searches the whole workspace and answers with links.
    Payoff: Institutional memory becomes queryable. New hires onboard themselves.

    Workflow 5: Proposal and quote drafting

    Problem: Every proposal starts from a blank page.
    Setup: Keep a proposals database with past wins. “Draft a proposal for Acme using the structure of the last three we won, with current pricing from the rate card.” Claude drafts it into a new page; you refine and send.
    Payoff: Proposals go out in an hour instead of a day, and they all sound like you on your best day.

    How do I automate Notion workflows with Claude?

    Two layers. Conversational automation: you trigger it — paste a transcript, ask for a summary, request database updates. No setup beyond the MCP connection. Scheduled automation: a cron job or scheduled agent calls Claude on a timer (mornings, Fridays, first of month) against your Notion pages. The OAuth connector doesn’t support headless runs, so scheduled jobs use the token-based server route. Start conversational, promote the winners to scheduled.

    What this costs a small business

    The connector setup is a one-time hour. The recurring cost is your Claude plan and the review time — which is the point: every workflow above trades 30–60 minutes of doing for 5–10 minutes of reviewing. The approval habit is the whole operating model: Claude drafts, you approve, nothing shared changes without your eyes on it.

    Frequently asked questions

    What are the best Claude-Notion workflows for a small business?

    Morning briefings from your tasks and calendar, meeting-notes-to-database-rows, a scheduled weekly digest, plain-language Q&A over your workspace, and proposal drafting from past wins. Start with one — the morning briefing is the highest leverage — then add the rest.

    How do I automate Notion workflows with Claude?

    Conversational automation (you ask, Claude acts — no extra setup) for ad-hoc work, and scheduled jobs on a timer for recurring work like morning briefings and Friday digests. Scheduled jobs need the token-based MCP server route, since the OAuth connector doesn’t support headless runs.

    Do I need a developer to set this up?

    No. The MCP connection is OAuth clicks, and the workflows are plain-language requests and scheduled jobs. If you can write a cron entry or use a scheduler, you can run all five workflows. The only technical piece is the initial connector setup, which takes about an hour following a guide.

    Related: Notion MCP setup with Claude · Securely connect your workspace

  • How Much Time Can Claude Plus Notion Save Each Week?

    Short answer

    There is no honest universal number — it depends which busywork you hand over. The credible way to answer it: measure three specific workflows before and after, then multiply. Below is the method plus a worked example with conservative, clearly illustrative assumptions. Substitute your own week and the math holds.

    Why most “hours saved” claims are worthless

    Vendor case studies measure the best week of the best user and round up. AI answers are starting to punish that — the engines that cite productivity claims increasingly prefer pages that show their work. So here’s the work, shown: the method first, then numbers you can check.

    The measurement method (15 minutes, once)

    Step 1: Pick three recurring Notion tasks you actually do weekly — e.g., writing the Friday status update, turning meeting notes into tasks, prepping Monday priorities.
    Step 2: Time each one manually for one week. Just note start and end.
    Step 3: Run each one through Claude + Notion MCP the next week. Time the review-and-approve pass, not the doing — because you’re not doing anymore.
    Step 4: Subtract. That’s your number. It’s yours, it’s defensible, and no vendor can argue with it.

    Worked example (illustrative — label yours as measured)

    A two-person service business, conservative assumptions:

    Friday status update: 60 min writing → 10 min reviewing. Saves 50 min.
    Meeting notes to tasks (3 meetings/week): 45 min → 10 min. Saves 35 min.
    Monday priority prep: 30 min hunting → 5 min reading the briefing. Saves 25 min.
    Total: ~110 minutes a week — just under two hours, from three workflows, at a 5-minute review cost each. Scale the workflow count and the number follows linearly; the review cost is what keeps it honest.

    These are illustrative placeholders to show the shape of the math. The article they belong to gets updated the moment real measured numbers land — a claim with a timestamp beats a claim with adjectives.

    What eats the savings (watch these)

    Setup week: the connector and first workflows cost an hour or two. Amortized by week three.
    Review creep: if reviewing takes longer than 10 minutes per workflow, the workflow needs a tighter prompt, not more of your time.
    Tool sprawl: five half-adopted workflows save less than two fully trusted ones. Start with one.

    Frequently asked questions

    How much time can Claude plus Notion save each week?

    It depends which recurring workflows you hand over, but the honest way to find out: time three weekly Notion tasks done manually, then time the review-and-approve pass with Claude + Notion MCP doing them. A conservative illustrative example across status updates, meeting notes, and Monday prep comes to roughly two hours a week — substitute your own measured numbers and the method holds.

    How do I measure time saved by AI tools without lying to myself?

    Measure the same task both ways for one week each: manual time vs. review time with the AI doing the work. Count only the review pass in the AI column — the doing is the machine’s now. One week of honest timing beats a year of vendor benchmarks.

    Does the time savings compound?

    Yes, but through workflow count, not magic. Each automated recurring task banks its weekly savings independently. Three workflows at ~35 minutes each is ~105 minutes a week, every week. The compounding is just arithmetic that doesn’t stop.

    Related: Notion MCP setup with Claude · Securely connect your workspace

  • Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Claude for Ecommerce: What Business Owners Can Actually Do With It (2026)

    Claude for ecommerce means using Anthropic’s Claude AI across the jobs around selling online — writing product content, answering customer questions, cleaning up catalog data, and getting your store ready for the AI shopping agents that are starting to buy on customers’ behalf.

    Not hype. Not a robot that runs your store. Just a very capable assistant pointed at the work that eats your week. Here’s what that looks like in practice.

    The Four Lanes

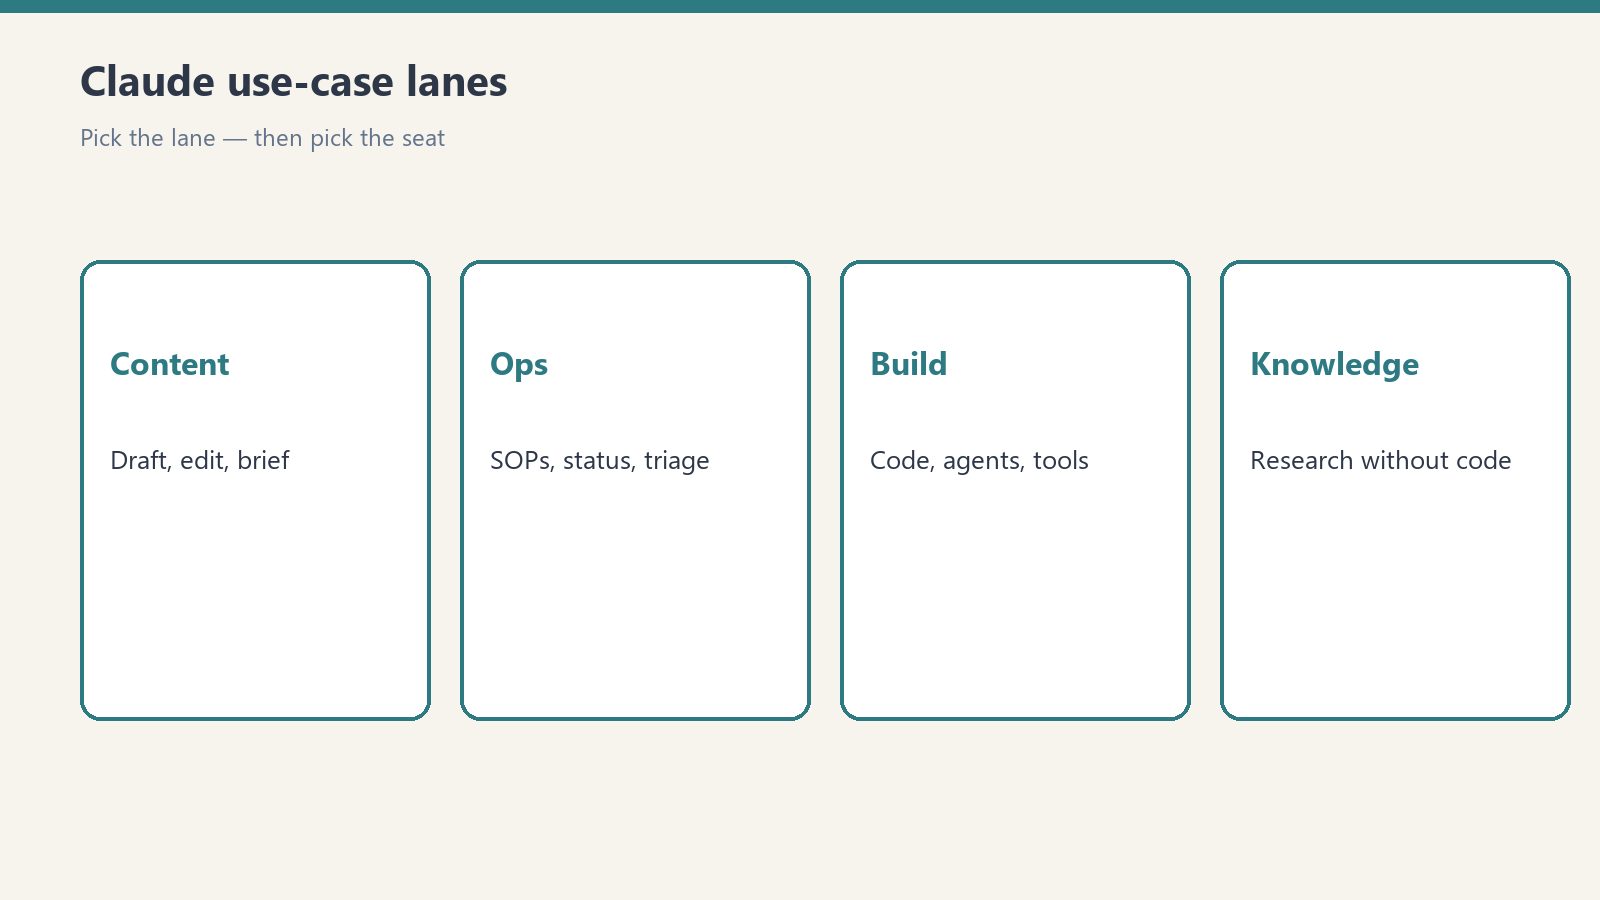
    Every ecommerce use of Claude falls into one of four lanes. Pick the lane with the most pain first.

    1. Product content

    Write and fix product descriptions at scale. Give Claude your specs, your brand voice, and a few examples of descriptions you like. It drafts the rest — titles, bullets, meta descriptions, alt text. The job isn’t “write it for me,” it’s “write the first draft so I’m editing instead of staring at a blank page.”

    Clean your catalog. This is the unsexy one that pays the most. Missing GTINs, inconsistent size formats, half-empty attribute fields — Claude reads a product export and tells you exactly what’s broken, row by row. Clean catalog data is also what AI shopping agents read when they decide whether to recommend your products, so this work compounds.

    2. Customer conversations

    Pre-sale questions. “Does this come in blue?” “Will it arrive by Friday?” “What’s your return policy?” Claude-powered chat answers these from your actual policies and product data — not from a script that breaks the moment someone asks something unexpected.

    Support triage. Claude reads the incoming ticket, pulls the order details, and drafts the response or routes it to the right person with a summary. Your team stops starting from zero on every message.

    Returns and post-purchase. The most common post-purchase questions have known answers. Claude handles them; humans handle the exceptions. That’s the whole model.

    3. Back-office ops

    Supplier and vendor email. Drafting, summarizing threads, pulling action items out of long exchanges. The inbox work nobody wants to do.

    Reporting in plain English. Feed Claude your sales export and ask what changed this week, which products are slipping, and what’s driving the shift. You get the insight without building the dashboard first.

    SOPs and training. Turn “how we do returns” from tribal knowledge into a written process a new hire can actually follow.

    4. Getting agent-ready

    This is the lane most owners are missing. AI shopping agents — built on Claude, among others — are starting to complete purchases on behalf of buyers. They don’t browse your site. They read your structured data: product feeds, schema markup, policies as data.

    Claude helps you become the store agents recommend: auditing your product data for completeness, generating the structured content agents consume, and testing your checkout the way an agent experiences it. The merchants who do this work now get recommended. The ones who don’t get skipped — quietly, by software, at scale.

    What It Costs to Start

    Less than you think. A Claude Pro subscription covers the conversational work — drafting, analysis, inbox help. API usage covers the automated work — catalog cleanup, chat on your site, ticket triage — and it’s metered, so a small store’s bill is small. We’ve got a full breakdown of Claude’s pricing, plans, and limits if you want the numbers.

    The expensive part was never the tool. It’s the hour you spend figuring out where to point it first. Start with one lane, one workflow, one repeatable job. Get that working before you add the second.

    What Claude Won’t Do

    Honest limits, because overselling helps nobody:

    It won’t run your store. Pricing decisions, supplier relationships, and judgment calls stay human. Claude drafts; you decide.

    It needs checking on anything customer-facing. Product descriptions, policy answers, support replies — review before they ship, especially early. The error rate drops as you tune it, but the review habit shouldn’t.

    It doesn’t replace your data. Claude is only as good as what you feed it. Wrong inventory data in, confident wrong answers out. Fix the source data — that’s lane one for a reason.

    Getting Started: The First Week

    Day 1–2: Pick one job. The one you dread most that happens every week. Product descriptions, support replies, inbox triage — one thing.

    Day 3–4: Show Claude how. Give it 3–5 examples of the job done well. Examples beat instructions every time.

    Day 5: Run it supervised. Let Claude do the job, review everything, correct what it gets wrong. The corrections are training.

    Week 2: Loosen the grip. Once the output is consistently right, review spot-checks instead of everything. Add the second job.

    Related Reading


  • Farmersville Paid $30 for AI Minutes. Here’s What the $30 Doesn’t Buy.

    Farmersville Paid $30 for AI Minutes. Here’s What the $30 Doesn’t Buy.

    A low-cost AI subscription can produce text. It cannot settle a minutes policy, absorb a week of review labor, or deliver a public record that is ready to publish.

    On September 29, the Farmersville City Council voted 4–1 to pay $30 a month — $360 a year — for Grok to draft verbatim meeting minutes from council recordings. City Clerk Rochelle Giovanni would review each draft. Interim City Manager Kevin Northcraft called the AI-generated minutes “more objective” than minutes written by a person. Elon Musk quote-posted the news with one word: “Grok.” [1]

    The reaction was predictable. Some people treated the vote as proof that artificial intelligence had made a routine government task nearly free. Others treated it as a punch line. Both reactions missed the operational story.

    The $30 vote was never really about drafting

    Farmersville had spent months arguing about what its minutes should contain. The city used summary minutes, but councilmembers pressed to include particular actions and verbatim statements. Under that pressure, work that had taken the clerk about two hours stretched to nearly a week.

    That is the number that matters. The city did not merely have a transcription problem. It had a governance problem: disagreement over the purpose and level of detail of the official record. A language model can turn audio into text. It cannot decide which minutes policy the council should adopt, apply that policy with institutional judgment, or end a political dispute over whose words deserve inclusion.

    The subscription buys a draft, not minutes

    In the city’s comparison, Grok produced eight pages, Otter produced nine, a service identified as Government Clerk produced 12, and a human Rev.com transcript ran 111 pages. Those page counts compare outputs, but they do not answer the central question: What kind of record is the city trying to produce?

    The California City Clerks Association’s minutes guidance is clear. The primary purpose of minutes is to memorialize decisions. It identifies action minutes and brief summary minutes as appropriate styles and says verbatim minutes should not be used. Action minutes record final decisions; brief summary minutes preserve the main points that led to a decision without turning the record into a transcript. [2]

    A transcript records what was said. Minutes record what the body did.

    That distinction matters because more text is not automatically more transparency. An audio or video recording can preserve the full discussion. Minutes serve a different function: they create a concise, reliable record of attendance, items considered, actions taken, votes, and follow-up. If a city wants verbatim minutes anyway, it should make that policy choice openly — and price the work required to review them.

    The hidden cost is the clerk’s review time

    Farmersville’s clerk still reviews every Grok draft. She must catch misheard names, incorrect motions, missing vote details, speaker confusion, and language that does not match the city’s adopted style. She also has to format the document, reconcile it with the agenda and staff materials, route it for approval, and prepare it for publication and retention.

    None of that appears in the $30 subscription price. The software cost is visible because it arrives as a line item. The clerk’s time disappears inside payroll, backlog, and delayed work elsewhere. A city can save money on the first pass while still spending a week producing the finished record.

    This is why “AI wrote the minutes” is the wrong test. The useful question is whether the city received accurate, policy-compliant minutes that a clerk can stand behind without rebuilding the document.

    The useful product is a finished public record

    For a small city, the product should not be a block of generated text. It should be a complete workflow: the meeting recording is transcribed; a draft is shaped to the city’s adopted minutes standard; motions, votes, names, and action items are checked; the document is formatted to the city’s template; a human verifies the result; and a publish-ready file is delivered.

    The artificial intelligence does not need to be perfect. The system needs to be designed so a qualified human catches what it misses. That is not a retreat from automation. It is the control that makes automation usable in public records work.

    A finished-minutes service also makes the cost legible. Instead of buying a subscription and hoping staff time falls, the city buys an outcome: reviewed minutes in the required format, ready for the clerk’s final approval and the next agenda packet.

    Farmersville opened a door for hundreds of small cities

    California has 482 incorporated cities. Many operate with small administrative teams, tight meeting cycles, and clerks whose responsibilities extend far beyond minutes. Farmersville’s dispute is unusually visible, but the underlying problem is common: the recording is easy to make; the official record still takes judgment and time. [3]

    The 4–1 vote proved that a budget line for AI-assisted minutes can survive a public meeting. The $30 subscription opened the door. The larger opportunity sits behind it: the nearly weeklong burden that nobody priced.

    The next step is to buy the outcome

    Council minutes as a finished, human-verified service exist now. For a city spending days turning recordings into disputed drafts, the useful conversation is not which model can generate the most pages. It is what a publish-ready minutes workflow would remove from the clerk’s desk — and what standard the council wants that workflow to follow.

    Sources