Agency Playbook - Tygart Media

Category: Agency Playbook

How Tygart Media builds and runs the agency: the systems, and the process, from the inside.

  • Industry vs Company Language: 2 Key Vocabulary Layers

    Industry vs Company Language: 2 Key Vocabulary Layers

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart · Practitioner-grade · From the workbench

    There are two distinct vocabulary layers that govern how people communicate inside any industry, and most content and communication work conflates them.

    Understanding the difference — and building both deliberately — is one of the highest-leverage things you can do to make your communication feel native rather than imported.

    Layer One: Universal Industry Language

    Universal industry language is the shared vocabulary that travels consistently across every company in a vertical. It’s the terminology that practitioners use without defining it, because everyone who works in that field already knows what it means.

    In healthcare: the “face sheet” is the document that summarizes a patient’s information at the top of a chart. Every hospital calls it that. You don’t explain it — you just use it.

    In property restoration: “Resto” and “Dehu” are shorthand for specific categories of work. In retail: MOD means manager on duty. In logistics: ETA, FTL, LTL are assumed knowledge.

    This layer is learnable. It lives in trade publications, certification materials, job descriptions, and any content written by and for industry practitioners. Build a glossary of universal industry terms before you write a word of content for a new vertical, and your work immediately reads as insider rather than outsider.

    Layer Two: Company Language

    Company language is the internal dialect that develops within a specific organization. It doesn’t transfer across companies, even within the same industry. It’s shaped by team culture, internal tools, historical decisions, and sometimes just the way one influential person at the company talked about something early on.

    This is the vocabulary that shows up in internal Slack channels, in how a team describes their own workflow, in the nicknames that get attached to products or processes or recurring situations. It often never makes it into any official documentation. You learn it by listening, by reading the company’s own content carefully, and sometimes by just asking.

    A prospect might refer to their CRM as “the system.” Their onboarding process might be internally called something that has nothing to do with what it’s officially named. Their main product line might have an internal nickname that their sales team uses but their marketing team doesn’t.

    When you use their language back at them, the effect is immediate. It signals that you paid attention. It creates a sense that you are already on their team, not pitching from outside it.

    Why Most Communication Work Stops at Layer One

    Layer one is the obvious layer. You can research it. You can build a glossary from public sources. It’s systematic and scalable.

    Layer two requires proximity. It requires listening before speaking. It requires time with the actual humans at the company, not just their external-facing content. Most content and outreach workflows don’t have a step for this — not because it isn’t valuable, but because it’s harder to systematize.

    The opportunity is there precisely because most people skip it.

    How to Build Both Layers Before You Write

    For layer one: read trade publications, certification materials, and forum conversations in the target vertical. Flag every term used without definition. Build a reference glossary before any content is written.

    For layer two: read the company’s blog posts, case studies, job postings, and leadership team’s LinkedIn content. Look for language that’s idiosyncratic — terms or framings that don’t appear in competitors’ content. If you have access to the prospect directly, listen carefully in early conversations for words they use consistently. Use those words back.

    Together, these two layers give you something most communicators don’t have: a vocabulary that feels native at both the industry level and the individual company level. That combination creates the feeling — even if the prospect can’t articulate why — that you understand them specifically, not just their category.

    What is universal industry language?

    Universal industry language is shared terminology that travels consistently across all companies in a vertical — terms every practitioner knows without needing a definition. Examples include “face sheet” in healthcare or “Reto” in restoration.

    What is company language?

    Company language is the internal dialect that develops within a specific organization — nicknames, shorthand, and internal framing that doesn’t transfer across companies, even in the same industry.

    Why does using a company’s own language matter?

    When you use a prospect’s or client’s specific language back at them, it signals that you listened before you spoke. It creates the feeling that you’re already on their team rather than pitching from outside it.

    How do you research company-specific language?

    Read their blog, case studies, job postings, and leadership team’s LinkedIn content. Look for terms that appear consistently but don’t show up in competitors’ content. In direct conversations, listen for words they use repeatedly and use those words back.

  • Communicating Complex Ideas: Mastering the Complexity Dial

    Communicating Complex Ideas: Mastering the Complexity Dial

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart · Practitioner-grade · From the workbench

    There’s a specific tension every expert faces when communicating their work. It’s not about whether you know enough. It’s about where you set the dial.

    Go too technical: the work isn’t approachable. The prospect can’t see themselves using it. The client feels like they need a translator just to follow the conversation. They disengage — not because they’re not smart, but because the cost of staying engaged is too high.

    Go too simple: the work doesn’t appear valuable. You’ve hidden the sophistication that earns the premium. The prospect sees a commodity. They wonder if they could just do this themselves.

    The complexity dial is real. And finding the right setting isn’t instinct — it’s a learnable skill.

    Why the Default Is Always Too Technical

    Experts default toward complexity for a reason that feels rational: you want people to understand what you built. You’ve invested in the architecture, the system, the methodology. You want credit for it.

    The problem is that credit for complexity doesn’t come from complexity itself. It comes from the outcome the complexity produces. And outcomes are most legible when they’re explained simply.

    When someone asks you what you do, they are not asking for the architecture. They are asking for the result. “I build AI-powered content systems that rank on Google” is more credible to a non-technical buyer than a description of the pipeline that produces it — even though the pipeline is impressive, and even though you should absolutely understand and be able to speak to it when the moment calls for it.

    How to Find the Right Setting

    The right complexity setting is not a fixed point. It moves based on who you’re talking to, what stage of the relationship you’re in, and what decision you’re trying to help them make.

    A useful calibration question: what is the one thing this person needs to understand to move forward?

    Not the ten things. Not everything you know. The one thing. That’s your anchor. Build your explanation from that point outward, adding complexity only as far as is necessary to make that one thing credible and actionable.

    Another useful signal: listen for when someone stops asking follow-up questions. In a live conversation, the questions stop either because they understand or because they’ve given up. Your job is to read which one it is. Silence after complexity is usually disengagement, not comprehension.

    The Two-Version Rule

    For anything you communicate regularly — your services, your process, your results — it’s worth building two versions deliberately:

    The technical version is for peers, for audits, for documentation, for conversations where the other person has signaled they want to go deep. It doesn’t simplify. It’s accurate and complete.

    The accessible version is for first conversations, for clients who are focused on outcomes, for anyone who hasn’t yet signaled they want the technical version. It doesn’t dumb things down. It leads with the result, earns the trust, and holds the technical detail in reserve.

    The mistake is using only one. The expert who only has the technical version loses approachable audiences. The expert who only has the accessible version never earns sophisticated ones.

    What This Looks Like in Real Work

    A client asks: “What do you actually do for SEO?”

    Technical version answer: “We run a full AEO/GEO content pipeline with schema injection, entity saturation, internal link graph optimization, and structured FAQ blocks targeting featured snippets and AI overview placement.”

    Accessible version answer: “We make sure that when someone searches for what you do, Google shows your site — and shows it in a way that answers their question directly, so they click.”

    Both are accurate. Only one is appropriate for the first conversation with a prospect who runs a restoration company and has never thought about AEO in their life. The technical version comes later — after the trust is built, after they’ve asked to understand more, after the relationship has earned it.

    What is the complexity dial in communication?

    The complexity dial refers to the register of technical depth you use when explaining your work. Too technical and you lose approachability. Too simple and you sacrifice perceived value. The right setting depends on who you’re talking to and what decision they need to make.

    Why do experts default to overly technical communication?

    Experts default toward complexity because they want credit for what they built. But credit comes from the outcome, not the architecture. Outcomes are most legible when explained simply.

    How do you find the right complexity level?

    Ask: what is the one thing this person needs to understand to move forward? Build your explanation from that anchor, adding complexity only as far as necessary to make it credible and actionable.

    Should you always simplify your communication?

    No. The goal is calibration, not permanent simplification. Build both a technical version and an accessible version of your key messages, and deploy each when the audience has signaled which one they need.

  • Prospect Vocabulary Research: Beyond Industry Personas

    Prospect Vocabulary Research: Beyond Industry Personas

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart · Practitioner-grade · From the workbench

    Most persona-driven content work stops at the industry layer. You research the CFO persona. You learn that CFOs care about ROI, risk, and efficiency. You write in that register. You feel good about it.

    But there’s a layer below that almost nobody builds: the company-specific and prospect-specific vocabulary layer.

    Why Industry Personas Are Only Half the Job

    Industry personas capture how a role thinks. They don’t capture how a specific company talks.

    A CFO at a Medicaid claims processing company uses different words than a CFO at a luxury goods retailer — even though they share a title, shared concerns, and similar decision-making patterns. The terminology, the shorthand, the internal logic of their language is shaped by their industry, their company culture, their team, and sometimes just their history.

    When your content or your pitch uses generic CFO language, it lands as competent. When it uses their language, it lands as trusted.

    Where Prospect Vocabulary Actually Lives

    You don’t have to guess. The vocabulary is findable. It’s in:

    • Job postings. How a company writes a job description tells you exactly which words are native to that organization. What do they call the role? What do they emphasize? What jargon appears without definition?
    • Industry forums and trade boards. The conversations people have when they’re not performing for prospects — Reddit threads, Slack communities, association forums — reveal the working vocabulary of an industry. This is where “Reto” for restoration or “face sheet” for hospitals lives. Informal, precise, insider.
    • LinkedIn comments and posts. Not company page posts. Personal posts from practitioners in the industry. What do they call their problems? How do they describe wins?
    • The prospect’s own content. Blog posts, press releases, case studies, even their About page. Every company has language patterns. Read enough of their content and the vocabulary starts to surface.

    Two Layers Worth Distinguishing

    There’s an important distinction between two vocabulary types that often get collapsed:

    Universal industry language is the shared terminology that travels across every company in a vertical. In healthcare, “face sheet” means the same thing at every hospital. In restoration, “Reto” and “D” refer to specific job codes. This language is consistent. Build a glossary and it applies broadly.

    Company-specific language is the internal dialect. The nickname they use for a process. The shorthand that evolved on their team. The way they talk about a product internally versus how it’s marketed externally. This doesn’t transfer across companies even in the same industry. It has to be researched per prospect.

    Most content work builds the first layer. The second layer is where genuine trust gets created.

    How to Build Prospect Vocabulary Research into Your Process

    For any significant prospect or client vertical, a lightweight vocabulary research pass should happen before content is written or a pitch is built. The process doesn’t need to be elaborate:

    1. Pull 3-5 job postings from the company and their closest competitors
    2. Find one active forum or community where practitioners in that vertical talk informally
    3. Read 10-15 recent LinkedIn posts from people with the target job title at similar companies
    4. Flag any terminology that appears without explanation — that’s the insider vocabulary
    5. Build a small glossary: their term → what it means → how to use it naturally

    This takes 30-45 minutes. The output is a vocabulary layer that makes every subsequent touchpoint feel like it was built specifically for them — because it was.

    The Competitive Advantage This Creates

    Most of your competitors are working from the same industry persona playbooks. They’re writing for the CFO archetype. They’re checking the same boxes.

    When you show up speaking a prospect’s actual language — not performing their industry’s language, but their specific company’s language — the experience is different. It signals that you listened before you spoke. It signals that you did the work. And in a landscape where most outreach feels templated, that specificity is immediately noticed.

    What is prospect-specific vocabulary research?

    It’s the practice of researching how a specific company or prospect actually talks — their internal terms, shorthand, and language patterns — before writing content or building a pitch for them. It goes deeper than standard industry persona work.

    Where do you find a prospect’s actual vocabulary?

    Job postings, industry forums, practitioner LinkedIn posts, and the company’s own published content are the most reliable sources. The words people use without defining them are the insider vocabulary you’re looking for.

    How is this different from building buyer personas?

    Buyer personas capture how a role category thinks and what they care about. Prospect vocabulary research captures the specific language a company or individual uses — which varies even among people with the same title in the same industry.

    How long does this research take?

    A lightweight vocabulary pass takes 30-45 minutes per prospect and produces a small glossary that makes every subsequent touchpoint feel custom-built.

  • Voice Mirroring: The Key to Better Client Communication

    Voice Mirroring: The Key to Better Client Communication

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart · Practitioner-grade · From the workbench

    There is a principle that separates consultants who get results from consultants who get ignored, and it has nothing to do with how smart you are or how deep your knowledge goes.

    It’s called voice mirroring. And it works like this: the depth you go is for you. The way you deliver it back is for them.

    What Voice Mirroring Actually Means

    Voice mirroring is the practice of returning information to someone in the same register, vocabulary, and complexity level they used when they asked for it.

    If a client calls something a “brain box thing that scans and chunks stuff,” that is not ignorance. That is their operating language. Your job is not to correct it. Your job is to meet it.

    When you respond to a simple question with a 14-point technical breakdown, you haven’t demonstrated expertise. You’ve created friction. The information doesn’t land because the delivery doesn’t fit the receiver.

    The Research Phase vs. the Delivery Phase

    Voice mirroring requires you to split your process into two distinct phases that should never bleed into each other.

    The research phase is where you go as deep as you need to. You build the full knowledge structure. You understand the technical landscape, the edge cases, the nuances. You go unrestricted. This phase is entirely internal.

    The delivery phase is where you filter. You take everything you know and you ask one question: what does this person need to hear, in their language, to move forward? You strip everything that doesn’t answer that question.

    Most people collapse these phases. They research and then output everything they found. That is not delivery. That is dumping.

    Why This Is Harder Than It Sounds

    The instinct for most experts is to demonstrate depth. We have been trained — in school, in career ladders, in client presentations — to show our work. The more we show, the more valuable we appear.

    But there is a tension at the center of this. Go too technical and you’re not approachable. Make it too simple and you don’t appear valuable. The sweet spot is a specific calibration: sophisticated enough to earn trust, plain enough to require no translation.

    Finding that calibration requires listening more than talking. It requires paying attention to how the question was asked, not just what was asked.

    What Voice Mirroring Looks Like in Practice

    A prospect emails you: “Hey, I just need to know if this thing is going to sit inside or outside my company, what it’s going to cost, and how much work it’s going to be for us.”

    They did not ask for a capabilities deck. They did not ask for a technical architecture diagram. They asked three direct questions in plain language.

    Voice mirroring says: answer those three questions in the same plain language. Then stop.

    Everything else you know about your system — the AI pipeline, the schema structure, the content scoring logic — stays in the research phase. It is not erased. It is reserved. You deploy it when and if the conversation earns it.

    Voice Mirroring as a Sales and Client Retention Tool

    The downstream effects of getting this right compound fast. Clients who feel understood don’t need as many touchpoints to make decisions. They trust faster. They refer more. They don’t feel like they need a translator every time they interact with you.

    Conversely, clients who consistently receive information they have to decode become exhausted. Even if your work is excellent, the communication friction erodes the relationship. They start to feel like the problem is them — and that is the last feeling you want a client to have.

    Voice mirroring is not a soft skill. It’s a retention mechanism.

    The Takeaway

    Go as deep as you need to go internally. Build the knowledge. Understand the complexity. Do not shortcut the research phase.

    Then, before you open your mouth or start typing, ask yourself: in what voice did this person ask? Return your answer in that voice. Everything else is noise.

    Frequently Asked Questions

    What is voice mirroring in client communication?

    Voice mirroring is the practice of returning information to a client or prospect in the same vocabulary, register, and complexity level they used when they asked. It separates the internal research depth from the external delivery language.

    Why do experts struggle with voice mirroring?

    Most experts are trained to demonstrate depth by showing their work. This instinct leads to over-delivery — giving clients everything you know rather than what they need to hear, in a way they can act on.

    Is voice mirroring just dumbing things down?

    No. The goal is calibration, not simplification. The delivery needs to be sophisticated enough to earn trust while plain enough to require no translation. That is a specific, practiced skill.

    How does voice mirroring affect client retention?

    Clients who feel consistently understood make decisions faster, require fewer touchpoints, and refer more readily. Communication friction — even when the underlying work is excellent — erodes relationships over time.

  • Your Jobs Are a Knowledge Base. You’re Just Not Using Them That Way.

    Your Jobs Are a Knowledge Base. You’re Just Not Using Them That Way.

    Related on Tygart Media: external knowledge API · S500 in the van.

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart
    · Practitioner-grade
    · From the workbench

    Every restoration job teaches something. Almost none of it ever gets written down.

    A crew shows up to a flooded basement at 2am. They make decisions — where to set the equipment, how to read the moisture map, which walls are worth opening and which aren’t, how to sequence the dry-down so the structure doesn’t get worse before it gets better. They’ve made these calls before. They know things that took years to learn. They finish the job, submit a field report, and move on.

    Then the experienced tech takes another job across town. Or retires. Or just gets too busy to train anyone. And that knowledge disappears.

    I want to talk about a different approach. One that captures that knowledge systematically — and turns it into something that works in two directions at once.

    Email Me This Article

    The Double-Purpose Content System

    Three cards for field SOPs, owner prompts, and KPI rhythm in an operations kit
    The double-purpose content system.

    The idea is straightforward: document your jobs as content. Scrub the client-specific details — no names, no addresses, no identifying information. But tell the real story. What was the scope? What made this job complicated? What decisions were made and why? What was the outcome?

    Published on your website, this does something conventional marketing content can’t: it demonstrates expertise through specificity. Not “we handle all types of water damage” — but a documented account of how your team handled a Category 3 intrusion in a commercial kitchen with active mold growth and a compressed timeline. That’s a different signal entirely.

    The reader — whether that’s a property manager searching for a qualified contractor or an insurance adjuster evaluating whether to refer you — isn’t reading a brochure. They’re reading a case record. They can see how your team thinks.

    But here’s the second direction, and it’s the one I find more interesting: that same documentation feeds back into the company as a knowledge base.

    The Internal Payoff

    Comparison of Claude how-to fit versus local service page fit for assistants
    The internal payoff.

    Restoration companies have a training problem that nobody talks about directly. The knowledge of how to do the job well is distributed unevenly across the team. The senior technicians have it. The new hires don’t. And the transfer mechanism is usually informal — ride-alongs, tribal knowledge, institutional memory held by people who may not stay forever.

    When you document jobs as structured content, you start to build something that actually scales. A new technician can search the knowledge base for jobs similar to what they’re walking into. They can see how a comparable loss was scoped, how the equipment was deployed, what complications arose and how they were handled. Before they’ve seen thirty jobs themselves, they can read about thirty jobs your company has already worked.

    An operations manager making a scheduling or resource decision can pull up historical jobs of a similar size and see what the typical crew requirements were. A project manager prepping a scope of work can see how similar scopes were structured and what line items were typically included.

    And when AI tools enter the workflow — which they will, if they haven’t already — that documented job history becomes training data your AI actually understands. Not generic restoration industry knowledge pulled from the web. Your company’s specific approach, your specific decisions, your specific standards. An AI assistant working from that foundation gives answers that sound like your company, because they’re drawn from your company’s real work.

    What Makes This Different From a Blog

    Most restoration company blogs are essentially SEO performance. Keywords stuffed into generic articles about what causes mold or how long drying takes. Useful, maybe. Differentiating, no.

    What I’m describing is a content system built on documented operational reality. The subject matter isn’t manufactured — it’s the actual work. Which means it has a quality that manufactured content can never replicate: it happened. The specificity is real because the job was real. The decisions were real. The outcome was real.

    Readers feel this, even when they can’t articulate why. They’re not evaluating whether your content sounds authoritative. They’re reading something that is authoritative, because it comes from direct experience rather than borrowed knowledge.

    And unlike a blog that requires a content team to invent topics every week, this system has an inventory problem that only gets easier over time. Every job adds to it. The longer you run the system, the richer the knowledge base becomes — for your website visitors and for your own team.

    The Setup

    Three panels showing one problem, three options, one recommendation
    The setup.

    The practical structure is simpler than it sounds. Each job entry captures a handful of consistent fields: loss type, scope classification, environmental conditions, key decision points, equipment deployed, timeline, outcome. The sensitive details — client, location, anything identifying — never make it into the published version.

    What gets published is the pattern. The structure of the problem and the response. Categorized, searchable, and useful to anyone trying to understand how your company operates — including your own people.

    This isn’t a new concept in medicine or law, where case documentation has always served both public communication and internal learning simultaneously. It’s just new in restoration, where the work is equally complex and the knowledge equally worth preserving.

    The companies that start building this now will have a meaningful advantage in three years. Not because their marketing was cleverer — because their institutional knowledge actually compounded instead of walking out the door every time someone left.


    Tygart Media builds content and knowledge systems for property damage restoration companies. If you’re interested in implementing a job documentation system for your operation, start here.

  • Experiential Knowledge Base: Writing Content You Can Trust

    Experiential Knowledge Base: Writing Content You Can Trust

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart
    · Practitioner-grade
    · From the workbench

    There are two kinds of knowledge bases a writer can work from.

    The first is built from reading. From research, from other people’s frameworks, from things you’ve studied and synthesized and stored. This is legitimate knowledge. It produces competent writing. It can be thorough, well-sourced, and useful.

    The second is built from doing. From the things that have actually happened, the decisions that were actually made, the results that actually came back. This knowledge has a different texture. A different authority. And when you write from it, something changes in the writing itself.

    I’ve been thinking about which kind of knowledge base I’m trusting when I write.

    The Anxiety of the Research-Based Writer

    When you write from research, there’s a persistent low-level anxiety underneath the work. You’re synthesizing things that happened to other people, in other contexts, under conditions you didn’t control. The knowledge is real but the application is theoretical. You’re always one degree away from direct experience.

    That distance shows up in the writing. You hedge more. You qualify more. You gesture toward possibilities rather than landing on conclusions. You write “this approach can work” instead of “this worked.” The careful reader feels it even when they can’t name it.

    And when AI enters the picture — when you’re using AI tools to generate content, to research topics, to pull frameworks — the research-based knowledge base gets even more diffuse. Now you’re synthesizing a synthesis. The AI has read everything, which means it’s essentially read nothing specifically. It knows the shape of the conversation without having been in any of the actual conversations.

    The Confidence of the Experience-Based Writer

    Writing from a knowledge base of what you’ve actually done is different in one specific way: you don’t have to wonder if it’s possible. It happened. The uncertainty is behind you.

    When I write about publishing content pipelines that run at scale across a dozen sites, I’m not theorizing about whether that’s achievable. I’ve done it. I know where the proxy errors happen, which hosting environments block which approaches, what the content looks like three months in versus three years in. The knowledge isn’t borrowed. It’s operational.

    That changes what I can say. It changes how directly I can say it. And it changes what the reader receives — because at some level, readers feel the difference between someone describing a map and someone describing a road they’ve driven.

    AI Makes This More Important, Not Less

    Here’s where it gets interesting. Most of the conversation about AI in content is about generation — what the AI can produce, how fast, at what quality. But the more important question is what the AI is drawing from when it helps you.

    An AI working from your experiential knowledge base — from your actual work logs, your real client results, your documented processes — produces something fundamentally different from an AI drawing from general web training data. The second one sounds credible. The first one is credible, because the source material is real events that actually occurred.

    This is the real leverage in treating your work history as a content source. Not just that it’s “authentic” in some vague brand-voice sense. But that it’s verified. You don’t have to fact-check your own experience. You don’t have to worry about whether the case studies hold up. They do, because you were there.

    When AI generates from that foundation — from things that have actually happened — it isn’t hallucinating plausible content. It’s articulating real content more clearly than you might have time to do yourself.

    The Trust Differential

    There’s a version of content marketing that’s essentially a confidence game. You project expertise through fluency. You write with authority about things you understand in theory. The reader can’t easily verify whether your knowledge is earned or performed, so the performance stands.

    This worked better before. It’s working less well now. Readers are more calibrated to the texture of generated, research-based content. They’re less impressed by confident-sounding frameworks they’ve seen assembled from the same sources everywhere. They’re more interested in specificity — in the detail that could only come from someone who was actually in the room when the thing happened.

    The experiential knowledge base is the moat. Not because it’s hidden, but because it can’t be replicated without the experience. Another writer can read everything I’ve read. They can’t have done what I’ve done. And when the writing comes from that layer, it has a specificity that research alone can’t produce.

    What This Means for How You Write

    The practical implication is this: the most valuable content you can create isn’t the content that synthesizes what others have said. It’s the content that documents what you’ve actually done — what worked, what didn’t, what the specific conditions were, what you’d do differently.

    This isn’t just a better content strategy. It’s a more honest one. You’re not performing expertise. You’re reporting it. And the writing that comes from that place has a quality that readers and, increasingly, AI systems are learning to recognize and prefer.

    Your knowledge base is only as trustworthy as its source. If it’s built from things that have happened, you can write from it without anxiety. The results are behind you. The uncertainty has been resolved. You’re not speculating about whether the approach works — you’re describing the approach that worked.

    That’s a different kind of writing. And I think it’s the kind that matters most right now.


    Will Tygart is a content strategist and founder of Tygart Media. He builds content operations for companies that want their actual knowledge — not borrowed knowledge — to do the work.

  • The claude_delta Standard: How We Built a Context Engineering System for a 27-Site AI Operation

    The claude_delta Standard: How We Built a Context Engineering System for a 27-Site AI Operation

    The Machine Room · Under the Hood

    What Is the claude_delta Standard?

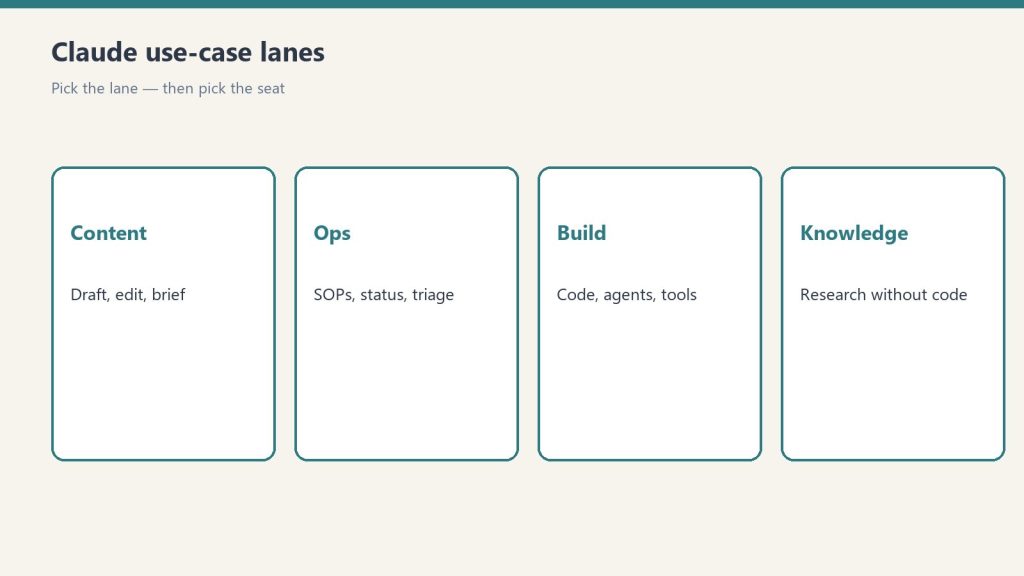
    Four cards for content, ops, build, and knowledge work with Claude
    What is the claude_delta standard?

    The claude_delta standard is a lightweight JSON metadata block injected at the top of every page in a Notion workspace. It gives an AI agent — specifically Claude — a machine-readable summary of that page’s current state, status, key data, and the first action to take when resuming work. Instead of fetching and reading a full page to understand what it contains, Claude reads the delta and often knows everything it needs in under 100 tokens.

    Think of it as a git commit message for your knowledge base — a structured, always-current summary that lives at the top of every page and tells any AI agent exactly where things stand.

    Why We Built It: The Context Engineering Problem

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    Why we built it — the context engineering problem.

    Running an AI-native content operation across 27+ WordPress sites means Claude needs to orient quickly at the start of every session. Without any memory scaffolding, the opening minutes of every session are spent on reconnaissance: fetch the project page, fetch the sub-pages, fetch the task log, cross-reference against other sites. Each Notion fetch adds 2–5 seconds and consumes a meaningful slice of the context window — the working memory that Claude has available for actual work.

    This is the core problem that context engineering exists to solve. The bottleneck in 2026 isn’t the model — it’s the quality of what you feed it.

    We were hitting this ceiling. Important project state was buried in long session logs. Status questions required 4–6 sequential fetches. Automated agents — the toggle scanner, the triage agent, the weekly synthesizer — were spending most of their token budget just finding their footing before doing any real work.

    The claude_delta standard was the solution we built to fix this from the ground up.

    How It Works

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How it works.

    Every Notion page in the workspace gets a JSON block injected at the very top — before any human content. The format looks like this:

    {
      "claude_delta": {
        "page_id": "uuid",
        "page_type": "task | knowledge | sop | briefing",
        "status": "not_started | in_progress | blocked | complete | evergreen",
        "summary": "One sentence describing current state",
        "entities": ["site or project names"],
        "resume_instruction": "First thing Claude should do",
        "key_data": {},
        "last_updated": "ISO timestamp"
      }
    }

    The standard pairs with a master registry — the Claude Context Index — a single Notion page that aggregates delta summaries from every page in the workspace. When Claude starts a session, fetching the Context Index (one API call) gives it orientation across the entire operation. Individual page fetches only happen when Claude needs to act on something, not just understand it.

    What We Did: The Rollout

    We executed the full rollout across the Notion workspace in a single extended session on April 8, 2026. The scope:

    • 70+ pages processed in one session, starting from a base of 79 and reaching 167 out of approximately 300 total workspace pages
    • All 22 website Focus Rooms received deltas with site-specific status and resume instructions
    • All 7 entity Focus Rooms received deltas linking to relevant strategy and blocker context
    • Session logs, build logs, desk logs, and content batch pages all injected with structured state
    • The Context Index updated three times during the session to reflect the running total

    The injection process for each page follows a read-then-write pattern: fetch the page content, synthesize a delta from what’s actually there (not from memory), inject at the top via Notion’s update_content API, and move on. Pages with active state get full deltas. Completed or evergreen pages get lightweight markers. Archived operational logs (stale work detector runs, etc.) get skipped entirely.

    The Validation Test

    After the rollout, we ran a structured A/B test to measure the real impact. Five questions that mimic real session-opening patterns — the kinds of things you’d actually say at the start of a workday.

    The results were clear:

    • 4 out of 5 questions answered correctly from deltas alone, with zero additional Notion fetches required
    • Each correct answer saved 2–4 fetches, or roughly 10–25 seconds of tool call time
    • One failure: a client checklist showed 0/6 complete in the delta when the live page showed 6/6 — a staleness issue, not a structural one
    • Exact numerical data (word counts, post IDs, link counts) matched the live pages to the digit on all verified tests

    The failure mode is worth understanding: a delta becomes stale when a page gets updated after its delta was written. The fix is simple — check last_updated before trusting a delta on any in_progress page older than 3 days. If it’s stale, a single verification fetch is cheaper than the 4–6 fetches that would have been needed without the delta at all.

    Why This Matters Beyond Our Operation

    2025 was the year of “retention without understanding.” Vendors rushed to add retention features — from persistent chat threads and long context windows to AI memory spaces and company knowledge base integrations. AI systems could recall facts, but still lacked understanding. They knew what happened, but not why it mattered, for whom, or how those facts relate to each other in context.

    The claude_delta standard is a lightweight answer to this problem at the individual operator level. It’s not a vector database. It’s not a RAG pipeline. Long-term memory lives outside the model, usually in vector databases for quick retrieval. Because it’s external, this memory can grow, update, and persist beyond the model’s context window. But vector databases are infrastructure — they require embedding pipelines, similarity search, and significant engineering overhead.

    What we built is something a single operator can deploy in an afternoon: a structured metadata convention that lives inside the tool you’re already using (Notion), updated by the AI itself, readable by any agent with Notion API access. No new infrastructure. No embeddings. No vector index to maintain.

    Context Engineering is a systematic methodology that focuses not just on the prompt itself, but on ensuring the model has all the context needed to complete a task at the moment of LLM inference — including the right knowledge, relevant history, appropriate tool descriptions, and structured instructions. If Prompt Engineering is “writing a good letter,” then Context Engineering is “building the entire postal system.”

    The claude_delta standard is a small piece of that postal system — the address label that tells the carrier exactly what’s in the package before they open it.

    The Staleness Problem and How We’re Solving It

    The one structural weakness in any delta-based system is staleness. A delta that was accurate yesterday may be wrong today if the underlying page was updated. We identified three mitigation strategies:

    1. Age check rule: For any in_progress page with a last_updated more than 3 days old, always verify with a live fetch before acting on the delta
    2. Agent-maintained freshness: The automated agents that update pages (toggle scanner, triage agent, content guardian) should also update the delta on the same API call
    3. Context Index timestamp: The master registry shows its own last-updated time, so you know how fresh the index itself is

    None of these require external tooling. They’re behavioral rules baked into how Claude operates on this workspace.

    What’s Next

    The rollout is at 167 of approximately 300 pages. The remaining ~130 pages include older session logs from March, a new client project sub-pages, the Technical Reference domain sub-pages, and a tail of Second Brain auto-entries. These will be processed in subsequent sessions using the same read-then-inject pattern.

    The longer-term evolution of this system points toward what the field is calling Agentic RAG — an architecture that upgrades the traditional “retrieve-generate” single-pass pipeline into an intelligent agent architecture with planning, reflection, and self-correction capabilities. The BigQuery operations_ledger on GCP is already designed for this: 925 knowledge chunks with embeddings via text-embedding-005, ready for semantic retrieval when the delta system alone isn’t enough to answer a complex cross-workspace query.

    For now, the delta standard is the right tool for the job — low overhead, human-readable, self-maintaining, and already demonstrably cutting session startup time by 60–80% on the questions we tested.

    Related on Tygart Media: managed agents memory · invisible agent layer · information density.

    Frequently Asked Questions

    What is the claude_delta standard?

    The claude_delta standard is a structured JSON metadata block injected at the top of Notion pages that gives AI agents a machine-readable summary of each page’s current status, key data, and next action — without requiring a full page fetch to understand context.

    How does claude_delta differ from RAG?

    RAG (Retrieval-Augmented Generation) uses vector embeddings and semantic search to retrieve relevant chunks from a knowledge base. Claude_delta is a simpler, deterministic approach: a structured summary at a known location in a known format. RAG scales to massive knowledge bases; claude_delta is designed for a single operator’s structured workspace where pages have clear ownership and status.

    How do you prevent delta summaries from going stale?

    The key_data field includes a last_updated timestamp. Any delta on an in_progress page older than 3 days triggers a verification fetch before Claude acts on it. Automated agents that modify pages are also expected to update the delta in the same API call.

    Can this approach work for other AI systems besides Claude?

    Yes. The JSON format is model-agnostic. Any agent with Notion API access can read and write claude_delta blocks. The standard was designed with Claude’s context window and tool-call economics in mind, but the pattern applies to any agent that needs to orient quickly across a large structured workspace.

    What is the Claude Context Index?

    The Claude Context Index is a master registry page in Notion that aggregates delta summaries from every processed page in the workspace. It’s the first page Claude fetches at the start of any session — a single API call that provides workspace-wide orientation across all active projects, tasks, and site operations.

  • Internal Link Mapping: A Complete Step-by-Step SEO Guide

    Internal Link Mapping: A Complete Step-by-Step SEO Guide

    The Machine Room · Under the Hood

    What is internal link mapping? Internal link mapping is the process of auditing, visualizing, and strategically planning the internal links between pages on a website. It creates a navigational architecture that helps both search engines and users move efficiently through your content — and directly influences how Google distributes PageRank across your site.

    Let me paint you a picture. Imagine Google’s crawler shows up to your website like a delivery driver in an unfamiliar city. No GPS. No street signs. Just vibes and whatever roads happen to be in front of them. That’s what your website looks like without a solid internal link map — a confusing maze where some pages get visited constantly and others quietly rot in a corner, never seen by anyone, including Google.

    Internal link mapping is the process of actually drawing the map. And once you see the map, you can’t unsee the problem.

    What Internal Link Mapping Actually Is (Not the Boring Version)

    Every page on your website is a node. Every internal link is a road between nodes. An internal link map is just the visualization of all those roads — which pages link to which, how many links each page receives, and crucially, which pages are orphaned (no roads in, no roads out).

    When Google crawls your site, it follows those roads. Pages that get linked to from many places get crawled more often, indexed faster, and treated as more authoritative. Pages buried three clicks deep with one lonely inbound link? Google eventually finds them — but it doesn’t think they matter much.

    Here’s the part that gets interesting: PageRank — Google’s foundational signal for evaluating page authority — flows through internal links. You have a fixed amount of it across your domain. Internal linking is how you choose to distribute it. A bad internal link structure is essentially leaving PageRank sitting in a bucket on your best pages while your ranking-ready content starves for authority.

    What Does an Internal Link Map Actually Look Like?

    A basic internal link map is a table or visual diagram showing:

    • Source page — the page that contains the link
    • Destination page — where the link goes
    • Anchor text — the clickable text used
    • Link depth — how many clicks from the homepage to reach that page
    • Inbound link count — how many pages link to this destination

    At scale, this becomes a graph. Tools like Screaming Frog or Sitebulb will generate a visual spider diagram of your entire site structure. For most sites under 500 pages, a simple spreadsheet works just fine. The goal isn’t to make art — it’s to see what’s actually connected to what.

    The ugly truth that usually surfaces: most sites have 20% of their pages receiving 80% of their internal links — usually the homepage and a few top-nav pages. Meanwhile, the blog posts you actually want to rank? Three inbound links between them. From 2019.

    How to Build an Internal Link Map (Step by Step)

    You don’t need expensive tools for a working internal link map. Here’s the straightforward version:

    1. Crawl your site. Use Screaming Frog (free up to 500 URLs), Sitebulb, or even Google Search Console’s coverage report. Export all internal links: source URL, destination URL, anchor text.
    2. Count inbound links per page. Sort the destination column and count how many times each URL appears. Pages with zero inbound links are orphans. Pages with one are nearly orphans. Flag both.
    3. Identify your high-priority targets. These are the pages you want to rank — your best content, service pages, money pages. How many inbound internal links do they have? If the answer is fewer than five, that’s your problem right there.
    4. Map topic clusters. Group your content by topic. Every topic cluster should have a pillar page that receives internal links from all related posts. Every related post should link back to the pillar. This creates a hub-and-spoke structure that Google reads as topical authority.
    5. Identify anchor text patterns. Are you using descriptive, keyword-rich anchor text? Or generic phrases like “click here” and “read more”? Anchor text is a ranking signal. “Internal link mapping guide” is better than “this article.”
    6. Fix and document. Create a link injection plan — a spreadsheet of which pages need new internal links added and what the anchor text should be. Execute it methodically.

    One pass through this process typically surfaces dozens of quick wins — pages that are one or two good internal links away from ranking significantly better.

    The Most Common Internal Link Mistakes (That Are Quietly Killing Your Rankings)

    Orphan pages. These are pages with no internal links pointing to them. They exist, technically, but Google either doesn’t know about them or doesn’t think anyone cares about them. Both outcomes are bad. Orphan pages account for a surprising percentage of most sites’ content — often 15-30%.

    Over-linking the homepage. Every page on your site already links to your homepage through the logo/nav. You don’t need additional contextual homepage links buried in body copy. That PageRank you’re wasting on the homepage? Redirect it to something that needs help ranking.

    Generic anchor text at scale. “Click here,” “learn more,” “read this post” — all wasted signal. Use the actual topic phrase as anchor text. It helps Google understand what the destination page is about, and it’s one of the easiest ranking signal improvements you can make without touching the page itself.

    Flat site architecture. Every page is three clicks or fewer from the homepage — that’s the goal. Deeper pages get crawled less frequently. If your blog archives push important posts six or seven levels deep, Google will find them eventually, but won’t prioritize them.

    Ignoring older content as a link source. Your highest-traffic pages — often older posts that have earned backlinks over time — are PageRank goldmines. Adding a single, contextual internal link from a high-traffic older post to a newer post you want to rank is one of the highest-ROI moves in SEO. Most people never do it.

    Tools for Internal Link Mapping

    Screaming Frog SEO Spider — The industry standard crawler. Free up to 500 URLs, paid license for larger sites. Exports a full internal link report and can generate site architecture visualizations. For most agencies and small businesses, this is the right starting point.

    Sitebulb — More visual than Screaming Frog, better for client presentations. Built-in link graph visualizations make it easier to spot cluster problems at a glance.

    Google Search Console — The Links report shows you both internal and external links Google has discovered. It won’t show you everything, but it’s free and gives you Google’s actual view of your link structure.

    Ahrefs or Semrush — Both have internal link audit tools built into their site audit modules. If you’re already paying for one of these platforms, use the built-in internal link analysis before adding another tool.

    A spreadsheet — Underrated. For sites under 100 pages, a manually maintained internal link spreadsheet is often the most actionable format. The point isn’t the tool — it’s having a documented plan you actually execute.

    How Internal Link Mapping Fits into a Broader SEO Strategy

    Internal link mapping doesn’t exist in isolation. It’s one layer of a three-part site architecture strategy:

    The topical authority layer — defined by your content clusters — tells Google what your site is about and what topics you cover with depth. The internal link layer communicates the relationships between those topics and the relative importance of each page. The technical layer — crawl depth, canonicalization, indexing rules — determines whether Google can even access what you’ve built.

    A site with great content and bad internal linking is like a library with excellent books and no card catalog. The information is there. Nobody can find it. Internal link mapping is how you build the card catalog.

    At Tygart Media, we build internal link maps as part of every site optimization engagement. The SEO Drift Detector we built for monitoring 18 client sites — which watches for ranking decay week over week — consistently flags internal link structure as one of the first places ranking drops originate. Fix the map, and the ranking often recovers on its own.

    Frequently Asked Questions About Internal Link Mapping

    What is the difference between internal links and external links?

    Internal links connect pages within the same website. External links (also called backlinks) point from one website to another. Internal links distribute authority you already have across your own site. External links bring new authority in from outside. Both matter for SEO, but internal links are entirely within your control.

    How many internal links should a page have?

    There’s no hard rule, but most SEO practitioners recommend 2-5 contextual internal links per 1,000 words of content. More important than quantity is relevance — each internal link should point to content that genuinely extends what the reader just learned. Stuffing 20 links into a 600-word post helps no one.

    How often should I audit my internal link structure?

    For active content sites, a full internal link audit every six months is reasonable. Smaller sites can often get away with an annual audit plus a quick check whenever new content is published. The higher your publishing frequency, the more often orphan pages accumulate. Set a calendar reminder — you’ll always find problems worth fixing.

    Can internal linking hurt my SEO?

    Over-optimized anchor text (every link using the exact same keyword phrase) can look manipulative to Google. Excessive linking on a single page (dozens of links in the body) dilutes the value of each individual link. Linking to low-quality or irrelevant pages from important pages can also be a mild negative signal. The goal is natural, useful internal linking — not engineered at every opportunity.

    What is a hub-and-spoke internal link structure?

    A hub-and-spoke structure groups content into topic clusters. The hub (or pillar page) covers a broad topic comprehensively and receives internal links from all related spoke pages. Each spoke page covers a subtopic in depth and links back to the hub. This architecture signals topical authority to Google and creates a clear navigational hierarchy for users.

    What is an orphan page in SEO?

    An orphan page is any page on your website that has no internal links pointing to it. Orphan pages are difficult for Google to discover and rarely accumulate authority. They’re a common byproduct of frequent publishing without a documented internal linking strategy. Finding and linking to orphan pages is one of the fastest low-effort SEO wins available on most established sites.

  • Bespoke AI Solutions: Why Tech Needs a Digital Tailor

    Bespoke AI Solutions: Why Tech Needs a Digital Tailor

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade

    There’s a moment in every fitting room that has nothing to do with fabric.

    The tailor doesn’t ask what color you want. Not yet. First, they ask where you’re going. Who will be in the room. Whether you’ll be standing all night or seated at a table. Whether this is the kind of event where people remember what you wore — or the kind where they remember what you said.

    The clothes come last. The understanding comes first.

    I’ve been building AI systems for businesses for the past two years, and I’ve started to realize that what I actually do has very little to do with technology. The job that’s emerging — the one that doesn’t have a name yet — looks a lot more like a Savile Row fitting than a software deployment.

    (more…)

  • Fast Pivot: How AI Compresses the Experience Curve

    Fast Pivot: How AI Compresses the Experience Curve

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart
    · Practitioner-grade
    · From the workbench

    Fifth in a series I did not plan and now apparently cannot stop. The previous four pieces walked through productizing the Tygart Media context layer, the dual-publish pattern, articles as infrastructure, and the naming question for the eventual product. This piece is about what happened when I read my own first article a few hours after publishing it and quietly killed the entire idea I had been planning to build.

    The Moment

    Two days ago I had an idea for a product. I had Claude help me think it through. We wrote a 3,000-word article about it, published it, and I felt good about it. The idea was real. The market analysis was solid. The recommended path was a clean-room knowledge base eventually packaged as a context-as-a-service API for other operators. I had a name for it. I had a phase plan. I was ready to start building.

    Then I went back and read my own article a few hours later. And I got to the section where Claude had laid out the existing competitors — Mem0 with its $24M Series A, Letta with its OS-inspired memory architecture, Zep with its temporal knowledge graphs, Hindsight with its open MIT license, SuperMemory with its generous free tier, LangMem for the LangGraph crowd. Six serious products. Some of them well-funded. All of them solving the technical layer of the thing I was about to spend months building from scratch.

    And the obvious thought arrived, the way obvious thoughts always arrive, late: why am I building this?

    The thing I cared about was the knowledge. The opinionated, accumulated, hard-won-from-running-27-client-sites operational wisdom. The stuff that makes my Claude work better than a fresh Claude. The stuff that — if you stripped it out of my Notion and exposed it via an API — would actually be valuable to other operators. That was the product. That was always the product.

    The infrastructure to serve that knowledge — vector storage, retrieval, embeddings, rate limiting, billing, SDKs, documentation, an API gateway — was not the product. That was just the delivery mechanism. And the delivery mechanism already existed, six different ways, built by teams with more engineers and more funding than I will ever have.

    I had been planning to build the entire stack. I should have been planning to bolt onto the existing stack. Pour my knowledge into Mem0 or Hindsight or whichever one fit best, configure it the way Tygart Media would configure it, and ship something in a week instead of a quarter. The product is the knowledge. The plumbing is somebody else’s problem and somebody else has already solved it.

    That is the pivot. It happened in about thirty seconds, in the middle of a chair, while reading my own article on my own website. The original idea died. A better one took its place.

    What Actually Happened in Those Thirty Seconds

    I want to slow this moment down because the mechanics of it are the actual point of this article. The pivot itself is mundane — operators pivot all the time. The interesting thing is how the pivot happened, and how fast, and what made it possible.

    Until very recently, the path from “I have an idea” to “I have decided to pivot off that idea” looked something like this. You have the idea. You sit with it for a few weeks. You sketch a business plan. You talk to a few people. You start building a prototype. You spend three months on the prototype. You discover the market is more crowded than you thought. You spend another month convincing yourself you can still differentiate. You spend a fourth month watching adoption fail to materialize. You finally admit the idea was wrong. You pivot — but now you have four months of sunk cost, an obsolete prototype, and a head full of bias toward the dead idea.

    That is the old shape of pivoting. It is expensive and slow and emotionally brutal because by the time you pivot, you have invested too much to think clearly about it.

    The new shape — the one that just happened to me — is different. Idea arrives. AI helps you model the entire business in a single evening. You publish the model as an article. A few hours later you re-read the article with fresh eyes, see what your past self missed, and pivot. Total elapsed time: less than 48 hours. Sunk cost: zero, except for some Claude tokens and a Notion page. Emotional attachment: minimal, because you haven’t invested enough to be attached.

    The thing AI did here was not “have the idea.” I had the idea. The thing AI did was compress the experience curve so violently that I got the wisdom of having explored the idea for months in the time it takes to write and read a long article. And the wisdom is what made the pivot possible.

    Compressed Experience Is the Actual Superpower

    This is the part that I think is genuinely new and worth taking seriously.

    For all of human business history, the only way to learn whether an idea was good was to do the idea. You had to actually build the thing, actually try to sell it, actually watch customers respond or fail to respond. Experience was something you could only acquire by spending time, money, and reputation. The cost of experience was the entire point of why most people never started anything — the price tag on finding out whether an idea worked was usually higher than they could afford to pay.

    What is happening now is that AI lets you simulate the experience curve cheaply enough that you can run an idea all the way to its likely outcome before you commit to building it. Not perfectly. Not completely. The simulation is missing things — you cannot simulate the actual conversations with actual customers, you cannot simulate the surprise that comes from a market doing something nobody predicted, you cannot simulate the slow grind of operations. But you can simulate enough to catch the obvious failures. You can simulate enough to notice that your idea has been built six times already by better-funded teams. You can simulate enough to realize that what you actually wanted was not the thing you were planning to build.

    The article I published two days ago was, functionally, a months-long thought experiment compressed into a single evening. It surveyed the market. It modeled the economics. It anticipated the scrubbing problem and the liability problem. It talked itself into a clean-room architecture and a phase plan. By the time I finished reading it, I had effectively done a quarter’s worth of strategic exploration in a few hours.

    And then — this is the part that matters — the simulation produced enough genuine insight that I could act on it. The pivot was not based on intuition. It was based on having actually thought through the idea in enough depth to see where it broke. The thinking-through was the experience. The experience was what made the pivot reasonable instead of flighty.

    This is not the same thing as actually having spent years running the business. There are things you only learn by running the business that no amount of simulation can produce. But the simulation is good enough to catch the largest and most embarrassing mistakes — the ones that would otherwise eat months of runway before you noticed them. And catching the largest mistakes early is most of what good entrepreneurial judgment actually is.

    The Accidental Customer Discovery

    Here is the second strange thing that happened in those thirty seconds. While I was sitting there realizing I should bolt onto an existing memory layer instead of building one, I also realized something else: I had just done customer discovery on myself.

    I had spent two days designing a product for a hypothetical other operator who wanted to plug a curated context layer into their AI workflow. I had thought carefully about what they would need, how they would use it, what would make them pay, what would make them churn. And then in the middle of all that thinking, I noticed that I was the customer. I was the person who needed a curated context layer plugged into my AI workflow. I had been describing my own needs the whole time and pretending they belonged to someone else.

    This is a pattern I think happens more often than people admit. You have a need. The need is not clearly visible to you because you have been working around it for so long that the workaround feels like just how things are. You start trying to design a product for somebody else, and the act of designing forces you to articulate the need clearly enough to recognize it — and then you realize the somebody-else was you the whole time. The product was a mirror. You were doing customer discovery on yourself by pretending to do it for a stranger.

    The pivot, then, is not just “buy instead of build.” It is “buy instead of build, because the customer for the bought thing is me, and the time saved by not building gets spent on the next-order thing I actually want to make.” The freed energy is the prize. The freed energy is what makes the pivot worth celebrating instead of mourning.

    What the Freed Energy Buys

    Every hour I do not spend building an API gateway and configuring a vector store and writing SDK documentation is an hour I can spend on the thing that actually matters: the knowledge layer itself, and the next idea sitting one step further out that I have not yet articulated.

    This is the part that most “build vs buy” discussions get wrong. The decision is usually framed as a tradeoff between control (build) and speed (buy). That framing misses the more important variable, which is what you do with the time you don’t spend building. If the time gets reabsorbed into operations or wasted on Twitter, then yes, build vs buy is just a control-vs-speed tradeoff. But if the time gets reinvested in something further up the value chain, then buy is not a compromise. Buy is leverage. Every hour saved on plumbing is an hour available for something nobody else can do.

    The knowledge that would have gone into “Will’s Second Brain as an API” can now go into a Mem0 instance configured in a specific way. That takes a week. The remaining eleven weeks of the original quarter are now available for whatever the next idea turns out to be. And the next idea will be better than the first one, because the first one already taught me something — through simulation, through writing, through reading my own writing back — that I could not have known before I tried to model it.

    The pivot is not retreat. It is acceleration. The original idea served its purpose by being thought through in enough detail to teach me what I actually needed. Now I get to use that lesson on a problem I could not have started with, because I would not have known the problem existed until I tried to solve a different one.

    The Counter-Argument I Should Make Honestly

    This whole framing has a failure mode and I want to name it before someone in the comments does.

    The failure mode is chronic pivoting. The same compression that lets you escape a bad idea fast also lets you escape a good idea fast, if you mistake the friction of doing real work for the friction of having picked the wrong thing. AI-assisted simulation is great at telling you when an idea is structurally broken. It is not great at telling you when an idea is structurally fine but is going to require a year of unglamorous grinding before it pays off. The two failure modes look similar from the inside. Both feel like “this is harder than I thought.” The difference is that one of them resolves itself if you keep going and the other one does not. And the simulation cannot reliably tell you which one you are in.

    If you get good at fast pivots, you can pivot yourself into oblivion. Every idea you start gets killed at the first sign of difficulty, because the cost of pivoting is now so low that pivoting becomes the path of least resistance. You end up with a graveyard of half-explored ideas and no shipped product.

    The defense against this is, awkwardly, commitment. You have to be willing to keep going on something even when the simulation says it might not work, because some ideas only work for people who refused to listen to the simulation. Most of the famous companies of the last twenty years were ideas that any reasonable simulation would have killed. AirBnB, strangers sleeping in strangers’ beds. Stripe, online payments in a market that already had PayPal. Notion, a productivity app in a category dominated by Microsoft. The simulations would have correctly identified those as “already done” or “structurally hard” and the founders would have correctly pivoted away if they trusted the simulations too much.

    So the right discipline is not “always trust the simulation.” It is “trust the simulation when it tells you the idea is redundant, but be skeptical when it tells you the idea is hard.” Redundancy is a real signal. Difficulty is just the price of doing anything worth doing.

    In my case, the simulation correctly identified redundancy. There are six funded teams already shipping the technical layer of the thing I was about to build. Pivoting off that is not chronic pivoting. It is reading the room. The test is whether the next idea I commit to gets the same fast-pivot treatment at the first sign of difficulty, or whether I commit to it long enough for the difficulty to actually mean something. Time will tell.

    The Larger Pattern

    If I zoom out from my specific situation, the pattern looks like this:

    Old entrepreneurship: Have an idea. Spend years building it. Discover during construction whether the idea was good. Most ideas turn out to be bad and most builders go down with their ideas because they cannot afford to have spent years on nothing.

    New entrepreneurship: Have an idea. Spend an evening modeling it in collaboration with AI. Read the model back. Either commit (rare) or pivot (common). The pivots are not failures because the cost of finding out was low enough that you can pivot ten times in a quarter and still have most of your runway. The commits are stronger because they survived a real model of the alternative.

    The result is not that fewer products get built. The result is that the products that get built are better, because the bad ones got killed during the modeling phase instead of during the construction phase. The kill rate is the same. The kill cost is different by orders of magnitude.

    And the secondary result, the one I am still digesting, is that the act of modeling the idea well enough to kill it is itself a form of compressed experience. You come out of the modeling phase having learned things you could not have learned without doing the modeling. Those lessons travel. The next idea is informed by the previous idea even though you never built the previous idea. The experience is real even though the experience is simulated.

    In thirty years of business writing, “fail fast” has been one of the most quoted and least practiced pieces of advice. The reason it was rarely practiced is that failing fast was never actually fast. It just meant failing in eighteen months instead of three years. AI is the first tool I have used that makes failing fast actually fast — fast enough that the failure does not hurt, fast enough that the lessons are still vivid when the next idea arrives, fast enough that pivoting feels like progress instead of defeat.

    That changes the math on starting things. It might even change the math on who gets to start things. The old math required either capital or stubbornness, because you needed enough of one to survive the slow failures. The new math requires neither. You need an idea, an evening, and the willingness to be honest with yourself about what your own writing is telling you when you read it back.

    The Practical Move

    I am going to bolt onto Mem0 or Hindsight or whichever existing memory layer best fits the shape of what Tygart Media needs. The decision between them is a half-day of testing, not a half-quarter of building. The freed energy goes into the actual knowledge layer — the patterns, the conventions, the operational wisdom — which is the part nobody else can replicate because nobody else has run my client roster.

    The “Where There’s a Will, There’s a Way” naming might still be the right name. Or it might be the wrong name now that the product is “Tygart Media’s accumulated wisdom layered on top of Mem0” instead of “Tygart Media’s accumulated wisdom served by a Tygart Media-built API.” That is a question for next week. The naming does not matter until the bolt-on is configured and tested.

    And the next idea — the one I have not yet articulated, the one that gets to use the freed twelve weeks — is the one I should actually be thinking about. The dead idea was the warm-up. The pivot is the real start.


    Knowledge Node Notes

    Structured residue for future retrieval.

    Core Claim

    AI compresses the experience curve so violently that you can simulate months of strategic exploration in a single evening. The simulation is good enough to catch the largest mistakes — including “this is already built six times by better-funded teams” — before you commit to building anything. The right response to that signal is to bolt onto the existing thing and redirect freed energy to the next-order idea, which will be better because the dead idea taught you something through simulation that you could not have known any other way.

    The Pivot Moment

    1. Two days ago: had an idea for a product (Will’s Second Brain as an API)
    2. Spent an evening modeling it with Claude → published as article
    3. Few hours later: re-read own article, hit the section listing Mem0/Letta/Zep/Hindsight/SuperMemory/LangMem
    4. Realized: the technical layer is already built six ways. I was about to rebuild what existed.
    5. Realized: the value is the knowledge, not the plumbing. Bolt onto existing memory layer, ship in a week instead of a quarter.
    6. Pivot took ~30 seconds. Sunk cost: a Notion page and some Claude tokens.

    The Old Shape vs The New Shape of Pivoting

    Old Pivot New Pivot
    Time from idea to pivot 4-12 months 24-48 hours
    Sunk cost at pivot point Prototype + opportunity cost Tokens + a Notion page
    Emotional attachment High (months invested) Low (no real investment)
    Quality of pivot decision Distorted by sunk cost bias Clean-eyed
    Lessons retained Buried in failure trauma Vivid and immediately applicable

    Compressed Experience Is the Actual Superpower

    The thing AI does is not “have the idea.” It is compress the experience curve. Months of strategic exploration get crammed into hours. The simulation is not perfect — it misses real customer surprise, real operational grind, real market weirdness — but it catches the largest and most embarrassing mistakes, which is most of what good entrepreneurial judgment actually is.

    This was impossible until very recently. For all of business history, learning whether an idea was good required doing the idea. The cost of experience was the entire reason most people never started anything. AI is the first tool that lets you simulate the experience cheaply enough that the simulation itself becomes a form of strategy.

    Accidental Customer Discovery

    Designed a product for a hypothetical other operator → realized halfway through that I AM the operator. Was doing customer discovery on myself by pretending to do it for a stranger.

    Pattern: needs that you have been working around for years are invisible to you. The act of designing a product for someone else forces you to articulate the need clearly enough to recognize it as your own. The product is a mirror. You are the customer.

    The Build vs Buy Reframing

    Standard framing: build = control, buy = speed. Tradeoff between two virtues.

    Better framing: the variable that matters is what you do with the time you don’t spend building. If the freed time gets reabsorbed into operations, build vs buy is just control vs speed. If the freed time gets reinvested further up the value chain, **buy is not a compromise — buy is leverage.** Every hour saved on plumbing is an hour available for something nobody else can do.

    The Failure Mode: Chronic Pivoting

    The same compression that lets you escape a bad idea fast also lets you escape a good idea fast, if you mistake “this is hard” for “this is wrong.” AI simulation is good at detecting redundancy. It is not good at detecting whether difficulty is the kind that resolves with grinding or the kind that doesn’t. Both feel the same from the inside.

    The discipline: trust the simulation when it tells you the idea is redundant. Be skeptical when it tells you the idea is hard. Difficulty is the price of doing anything worth doing. Most of the famous companies of the last 20 years would have been killed by a reasonable simulation (AirBnB, Stripe, Notion). The founders correctly ignored the simulation. The lesson is not “always pivot fast” — it is “pivot fast away from redundancy, commit hard through difficulty.”

    The Larger Pattern

    Old entrepreneurship: have idea → spend years building → discover during construction whether idea was good → most ideas were bad, most builders go down with them.

    New entrepreneurship: have idea → spend evening modeling with AI → read model back → commit (rare) or pivot (common) → freed energy goes to next idea, which is better because previous idea taught you something through simulation.

    Same kill rate as before. Different kill cost by orders of magnitude.

    “Fail fast” has been quoted for thirty years and rarely practiced because failing fast was never actually fast. AI makes failing fast actually fast.

    What This Means for Tygart Media’s Product Plan

    • Killed: Building a Tygart Media-owned context API from scratch
    • Adopted: Bolt onto Mem0 / Hindsight / whichever existing memory layer fits best after a half-day of testing
    • Saved: ~11 weeks of the original quarter that would have gone to plumbing
    • Reinvested into: The actual knowledge layer (patterns, conventions, operational wisdom) — the part nobody else can replicate
    • Open question: Does “Where There’s a Will, There’s a Way” still work as a name now that the product is “Tygart Media wisdom on top of Mem0” rather than “Tygart Media-built API”? Decide next week after the bolt-on is configured.
    • Bigger open question: What is the next idea — the one that gets the freed twelve weeks?

    Connection to the Series

    Article Question Answer (At Time of Writing)
    1. Second Brain as API Could we sell our context? Yes, with clean room + legal stack
    2. Dual Publish How does the context get built? Every article = deposit in two places
    3. Articles as Infrastructure What ARE the deposits? Infrastructure being minted
    4. Where There’s a Will What do we name the product? “The Way,” with a Phase 2 abstraction plan
    5. The Pivot (this one) Should we even build the product we just designed? No. Bolt onto an existing one. The freed energy buys the next idea.

    The series is itself an example of its own thesis. Article 5 only exists because Article 1 was written, published, and re-read. The dual-publish pattern (Article 2) made the re-reading possible. The infrastructure framing (Article 3) made the deposits durable enough to come back to. The naming question (Article 4) was the last gasp of the original plan. Article 5 is the pivot off all of it. The series is a five-act play in which the protagonist designs a product, slowly realizes the product is a mirror, and pivots in real time on the page.

    The Meta-Lesson

    The trilogy-turned-quintet itself is an artifact of the new shape of pivoting. Five articles, four days, total cost approaching zero, total value approaching “I know exactly what to do next and exactly what not to build.” This kind of compressed strategic exploration was not possible two years ago. It is possible now. It is going to be the default in two more years. The operators who learn to use it get to make ten honest attempts in the time it used to take to make one.

    Action Items

    • [ ] Test Mem0, Hindsight, and one other memory layer head-to-head on the same Tygart Media knowledge sample. Half-day max.
    • [ ] Pick one. Configure it. Load the clean-room version of the knowledge layer.
    • [ ] Decide if “the Way” still fits the bolted-on product or needs a different framing
    • [ ] Schedule a “what is the next idea” thinking session for next week — protect the freed twelve weeks from getting reabsorbed into operations
    • [ ] Watch for the chronic-pivoting failure mode. If the next idea also gets killed in 48 hours, the problem might be commitment, not idea quality.
    • [ ] Add a checklist to the Tygart Media SOP: “Before building anything, write the article about it. Read the article back the next day. If the article makes the case for buying instead of building, buy.”

    Tags

    compressed experience · pivot speed · build vs buy · accidental customer discovery · AI as simulation · fail fast actually fast · chronic pivoting · solo operator strategy · bolt-on products · Mem0 · Hindsight · second brain pivot · the Way · Tygart Media product plan · meta-series · series-as-pattern · entrepreneurship without capital · stubbornness vs reading the room · redundancy detection vs difficulty tolerance · freed energy reinvestment · article 5 of 5 · the pivot · simulation-driven strategy

    Last updated: April 2026.