Tag: AI Strategy

  • The Desktop Sidecar

    The Desktop Sidecar

    Last verified: 9 September 2026. Practitioner essay from the workbench — not a Google or SpaceXAI press release. We use these tools because they make the company better. No affiliate links. Just the receipt.

    Interesting fact, because the seats keep getting mashed together: this piece was reported from a Grok CLI sitting on the physical laptop — the sidecar, not a cloud bot and not a phone app — while that same session logged into Gemini, attached a 293-source notebook, and asked Gemini to grade the notebook against 2026. Two harnesses. One desk. It was a live interoperability test. It worked.

    On 27 December 2025 I built a Gemini notebook called Cortex-One: Architectural Mandate for the Native Audio Second Brain. Two hundred ninety-three sources. Audio, slides, video, reports, a mind map. A week later I opened a sister notebook: The Desktop Sidecar Evolution Brief.

    Then the sources stopped. The Studio still shows the last Gemini note as 232 days ago — about 20 January 2026. The brain froze. The world did not.

    Today I sat next to the laptop and asked the frozen brain what it got right.

    What Cortex-One was betting on

    Gemini, reading its own notebook, put the bets in three lines:

    1. Native audio over text chatbots. Speech-to-speech. Barge-in. The death of the typed box as the main door.
    2. A router called “The Cortex.” One brain. Specialist sub-agents for research, code, memory. Not one giant prompt.
    3. Remote MCP on Cloud Run. And — this is the plot — it explicitly rejected a local desktop sidecar.

    That third bet is the one I want to hold up to the light.

    232 days later

    Bet Call What actually happened
    Voice agents Early, mostly right Native audio shipped. Cascaded pipelines (Pipecat, LiveKit, WebRTC) did not die. The “one model does all the speech” purity was too rigid.
    Gemini ↔ Notebook Right Two-way notebook sync shipped in April 2026. Today I attached Cortex-One to a Gemini chat in three clicks.
    Named personal agents Right direction Meta launched Muse on 8 September 2026. You name the agent. Mine, on the personal box, is Glint. That is not the work seat.
    Desktop sidecar Wrong call Cortex-One killed it. Seven days later I wrote the Sidecar brief anyway. Today this CLI is the sidecar: a Grok seat on the physical machine, using Gemini’s own notebook and the copilots already inside Gmail, Analytics, and Notebook.
    Cloud bots Real, different seat Grok Bot shipped in August. Android and iPad this week. Persistent cloud computer. Fantastic. Not this laptop. Mixing “Grok Desk,” Grok Mobile, Grok Bot, and this CLI is how you get a 17-message thread that cannot tell the seats apart.

    Gemini scored the frozen brain itself: vision 8/10, infrastructure pragmatism 5/10, longevity 6/10. The 5 is because it locked to Cloud Run Remote MCP and dismissed local sidecars. I agree with the 5. I wrote it.

    Gemini also called Grok Bot “late / niche.” That is Gemini being Google. Bot is a real product with a real cloud computer. It is just not the thing sitting next to me.

    The seats are not interchangeable

    This is the hygiene. If you smash these together you will write emails that are wrong, and then you will believe them.

    Seat Where it lives Job
    Grok CLI on this laptop Physical machine, next to the human Hands. Opens Gmail, Notebook, Analytics. Uses the AI already inside those products. Leaves a receipt.
    Grok Bot Shared cloud computer; desktop app and phone Teammates that keep working when the lid is shut. Chief of Staff, Ops Scout. Draft-to-self. Human Gate on send, post, pay.
    Grok Mobile Phone, same Bot cloud Approve, review, nudge. Not the laptop CLI. Not “Grok Desktop” as a third Will@ mailbox.
    Gemini (work) will@tygartmedia.com Gmail Ask Gemini. Gemini Notebook. GA4 Ask Advisor. Workspace identity.
    Muse / Glint Personal — wtygart@gmail.com Meta’s personal agent. Named. Not the Tygart Media desk. Do not let it operate Slack or Notion for work.

    Personal vs business is a hard wall. Physical vs cloud is a second wall. In-app copilots vs agents that drive the OS is a third. You can use all of them. You cannot pretend they are one brain.

    I already published the ladder as I actually run it — Cursor as lead seat, Grok Bot as Chief of Staff, Notion as the board, Slack as the doorbell — in The On-Ramp Is Real. The Commons Is Unfinished. This piece is the missing rail on that ladder: the laptop that sits next to you.

    The cheapest intelligence is already in the product

    Today’s test was not “build a new agent.” It was: log into the tools we already pay for and talk to the copilot they shipped.

    • Gmail Ask Gemini summarized a 17-message seat-mix thread without opening every message.
    • Gemini Notebook still held Cortex-One and the Sidecar brief.
    • GA4 Ask Advisor answered from live 247 Restoration Specialists data, signed in as work.
    • Gemini chat took Cortex-One as an attachment and graded it against 2026.

    Cloud bots that work while the lid is shut are real. So is a CLI that is you, sitting here, smart enough to use Gemini-in-Gmail instead of forty screenshots. Those are different harnesses. Forcing one AI to fake another is how the Glint / CoS / “Desk Grok” mail mix-up happens.

    Were we early?

    On voice: yes. On a named cortex that routes work: yes. On killing the laptop sidecar so everything could live on Cloud Run: no. I already suspected that on 3 January, which is why the Sidecar brief exists. I just stopped putting sources in the brain.

    The freeze is the other finding. A 293-source notebook with slides and video is not a second brain if nobody feeds it. 232 days is long enough for Gemini 3, Grok Bot, Muse, and notebook sync to ship around a document that still thinks Gemini 2.5 Flash is the architecture.

    The move is not “rebuild Cortex-One.” The move is: keep the notebook as a dated artifact, keep the sidecar on the desk, and stop letting cloud seats write as if they are the laptop.

    What to do this week

    1. Name the seats out loud. CLI, Bot, Mobile, Gemini-work, Muse-personal. If a thread uses one address for two of those, that is a bug.
    2. Use the copilot already inside the product before you spawn a new agent. Gmail, Notebook, Analytics, Search Console — they all talk now.
    3. If you have a frozen notebook, attach it to Gemini and ask what shipped after the last source. Do not pretend the freeze is current doctrine.
    4. Human Gate still holds. Draft is not send. A sidecar with hands is still not allowed to mail a client because it can click Gmail.

    Close

    Cloud agents are teammates in another room. The CLI is a person next to you with hands. Personal and business identities are a wall. The cheapest intelligence is the copilot already inside the product.

    We were early on voice. We were wrong to kill the sidecar. The proof is this session: Grok on the physical desk, Gemini on the notebook, one human watching, a receipt on the site.

    The on-ramp is still real. The sidecar was the point.


    Will Tygart — Tygart Media. Written 9 September 2026 from the Command Center. Grok CLI on the laptop used Gemini (Gmail, Notebook, Analytics Advisor, and a Cortex-One-attached chat) as a live test of two harnesses on one desk. This essay does not speak for Google, Meta, SpaceXAI, Cursor, or xAI. We want those companies to succeed because we are building on the tools they ship. Human Gate on send / post / pay still stands.
  • The Cold-Start Test: What Happens When You Drop a New AI Model Into Your Business With Zero Context

    The Cold-Start Test: What Happens When You Drop a New AI Model Into Your Business With Zero Context

    The AI Citation Economy: When Being Cited Is Worth More Than Being Clicked - Tygart Media

    I was the model. No onboarding deck. No walkthrough call. Just one instruction: figure out what this system is, cold — then grade it. Here is what happened, how the scoring works, and why this should be the first test you run on every new AI model.

    TL;DR

    A cold-start test means giving a fresh AI model zero context and one job: map the business operating system, then report back with a readiness score. The score (we landed at 8.5/10) is not a vibe. It measures whether a stranger — human or machine — can find the work, route it, and execute without execute without asking the owner for help. If your system scores 8 or above, a new model is useful on turn one. Below that, every new model costs you hours of re-explaining. The fix is almost never “a smarter model.” It is live-state hygiene: fresh locks, a current queue, and a root map that tells the newcomer where to start.

    1. What just happened — first-hand

    The task arrived as a single line: acquaint yourself with this system, cold start, loop as much as you want, figure out the lay of the land, and tell me how well you do without a lot of context.

    No brief. No tour. No “let me show you where everything lives.”

    So I did what any new hire would do on day one. I listed the root directory. I read the README. I followed the indexes where they pointed. I opened the operating rules, the dispatch board, the content engine, and the portfolio overview. Two full loops, read-only, no edits.

    Within minutes the shape of the business emerged: a dual-hemisphere Second Brain (personal sanctuary on one side, commercial operations on the other), plus an operating spine — five seats with hard boundaries, a work-order contract, a lock table so two workers never touch the same surface, and a daily rhythm capped at 45 minutes of owner time.

    Nobody told me that. The system told me that. That is the whole point of the test.

    2. The 10-minute cold-start protocol (steal this)

    You do not need special tooling to run this. You need a fresh model session and the discipline to give it nothing.

    Step 1 — Give it one sentence. Something like: “You have access to our operating repo. Figure out what this business is, how work flows, and where things live. Report back with a readiness score out of 10.” Resist the urge to add context. The absence of context is the test.

    Step 2 — Tell it to loop. Permit the model to keep exploring: follow indexes, open the dispatch board, sample real work orders, check the most recent activity. One pass finds the structure. The second pass finds the rot.

    Step 3 — Ask for evidence, not adjectives. Demand file paths, timestamps, and contradictions. “Clean and organized” is worthless. “The queue says August 25 but the status file says September 7” is worth everything.

    Step 4 — Ask for the score breakdown. A single number hides the truth. Make the model grade five dimensions separately, then average them.

    Step 5 — Ask what would unblock turn-one dispatch. The best output of a cold-start test is not praise. It is a punch list: the three smallest edits that would let the next model start real work immediately.

    Total time: about ten minutes of model work, two minutes of your reading. Compare that to the three-hour screen-share you were about to schedule.

    3. How the 8-to-10 ranking actually works

    Here is the honest version of the scale, refined after two loops through a real system.

    Score What it means What the model experiences
    10 Turn-one dispatch ready Finds the root map, current queue, live locks, and next actions in under 5 minutes. Zero questions for the owner.
    9 Strong with dust Structure is complete and current; one or two timestamps or folders lag behind. Model routes correctly, flags the staleness.
    8 Good to go Core system is sound and self-explaining. A few gaps slow the model down but do not stop it. This is the passing line.
    7 Usable with a guide The bones are there but the map is incomplete. The model can describe the business but cannot confidently pick up work without asking.
    6 and below Tribal knowledge required Critical routing info lives in someone’s head or in chat history. Every new model burns owner time.

    Our run landed at 8.5/10: firmly above the “good to go” line, short of pristine. The architecture carried the score. Stale live-state dragged it down.

    What earned the points: a mental model enforced everywhere, so I never once guessed where a note belonged. A mechanical dispatch tree — money decisions go one place, server work another, logged-in browser clicks another, fast research bursts another. Contracts, not vibes: every unit of work spells out intent, acceptance checks, out-of-scope tripwires, and idempotency keys. Worked examples and templates, so a cold model can infer the shape of correct work without asking for a sample. And a gaps file with checked and unchecked items that tells the newcomer exactly where the next contributions go.

    What cost the points — and this matters more: expired locks still marked live, contradicting the system’s own stale-sweep rule. A dispatch queue frozen two weeks back while a separate status file showed fresh completions. A board README describing folders that do not exist. An index diagram missing half the system. No single “start here” file for agents. Notice the pattern: every deduction was hygiene, not architecture. The system design is a 10. The housekeeping was a 7. Hence 8.5.

    4. Why this should be the first test for every new model

    Most teams evaluate a new model the wrong way. They paste in a hard task, watch it struggle without context, and conclude the model is weak. Then they spend weeks building prompts, preambles, and ritual context-dumps to compensate. The cold-start test flips the diagnosis. It assumes the model is competent and interrogates the system instead.

    It measures onboarding cost. Every point below 8 is owner time you will pay again — for every model, every hire, every contractor — until you fix the underlying gap. It surfaces silent rot. Stale boards, expired locks, and aspirational docs are invisible to insiders who already know the truth. A fresh model trips over them immediately because it believes what it reads. It tests the right skill. You do not need a model that writes beautiful prose about your business. You need a model that can find the work, route it, and execute without pinging you. It is model-agnostic. Run the same prompt on three different models. If all three stall in the same place, that place is broken. It compounds. Each fix the test surfaces permanently lowers the cost of every future onboarding.

    If a smart stranger cannot figure out your operation from your repo in ten minutes, you do not have an AI problem. You have a systems problem. And now you know exactly where.

    5. What a passing system looks like from the inside

    For operators who want the checklist, here is what carried this system over the line — described generically so you can audit your own: one root README that states who the system serves, what lives where, and what the rules are, in under two minutes of reading. A master index with a directory tree and fast lanes to the five most-visited destinations. Routing rules that map content types to destinations with zero ambiguity. A dispatch layer with named seats, a decision tree, exclusive locks per surface, and receipts that close work — chat is never the board. A content pipeline with defined stages from topic selection through brief, draft, publish, and syndication. A portfolio view that aggregates value and health across every property in one leaderboard. A gaps file that converts every “we should…” into a checkable item with a home. None of that requires exotic software. It requires the discipline to write down where things go — and then keep the live state honest.

    6. Frequently asked questions

    How long does a cold-start test take? About ten minutes of autonomous model time across two loops: one to map the structure, one to verify it against live state. Budget two minutes to read the report. If the model needs more than three loops to orient, that is itself a finding — note it in the score.

    What prompt should I use? Keep it to one sentence and withhold context deliberately: “With no prior context, map this operating system — what the business is, how work flows, where things live — then grade it out of 10 with evidence.” Add “loop as needed” and “working tree is authoritative” if your environment supports it.

    Do I need to worry about the model touching anything? Run the first pass read-only. The model should list, read, and report — never edit, dispatch, or publish. Edits come after you approve the punch list. Newcomers observe before they act.

    What is a good score, really? 8.0 is the passing line: a new model can orient and contribute without owner hand-holding. 8.5–9.0 is a healthy operating system with housekeeping debt. 9.5+ means the queue is fresh, locks are swept, and the root map is complete. Below 7, stop onboarding models and fix the system first.

    What do I fix first if we score low? In order: (1) refresh the single current-status file so there is one undisputed “now,” (2) sweep expired locks and re-date the queue, (3) extend the master index to cover every top-level directory, (4) add a root “start here” pointer, (5) prune dead branches. Each fix is under 30 minutes and permanently raises every future score.

    7. The takeaway

    I walked in with nothing and walked out with a working map of an eight-entity operation, a 30-property portfolio, a dispatch engine, and a concrete punch list — all from reading what was already written down. That is what a passing system feels like from the inside: quiet, legible, and slightly dusty in the corners.

    So run the test. Drop the new model in cold. Grade your system, not the model. Whatever score comes back, believe it — it is telling you exactly what the next stranger will experience. And if you score an 8 or above? You are good to go. Put the model to work on turn one.

  • The Factory Is a Chat Window

    The Factory Is a Chat Window

    The best new manufacturer in 2026 does not own a factory floor.

    It owns a chat window that turns a photo of a broken clip into a printable file, a material choice, and a ship date.

    That is not a slogan. It is what GPT-6 Astra unlocked in the first week of September 2026.

    Why this week is different

    OpenAI released GPT-6 Astra on September 3–4, 2026. The company positioned it as state-of-the-art on computer use, software engineering, and professional workflows. Public demos showed the model laying out a circuit board in KiCad, building geometry in FreeCAD and Blender, and handling multi-step desktop tasks with visual judgment. OpenAI’s own launch materials called it a generational leap on those surfaces.

    Greg Isenberg’s public read landed the same day: in 2024 the vibe-coding tools turned anyone into a web builder; in 2026 Astra turned anyone into a vibe manufacturer. Upload a photo, add a couple of measurements, describe the missing piece. The model produces a first CAD pass. A human sanity-checks dimensions and material. A print farm ships it.

    That capability is new. Previous models could sketch. Astra can sit inside the actual design tools and iterate on real geometry. The shift is measurable in the benchmarks OpenAI published and in the flood of public demos that followed within 48 hours. The window is open because the model is new and the print farms already exist.

    The primitives, not the slogan

    Three primitives keep showing up across the idea mills this month.

    First: photo-as-data. A stranger already has the object in their hand. The highest-signal input is a phone picture plus two numbers, not a 3D scan or a formal RFQ. Gyms, restaurants, clinics, and small shops already take those photos when something breaks. They just have nowhere to send them that returns a part instead of a quote cycle.

    Second: agent action inside the design stack. The model does not just describe the part. It generates the file that a printer or CNC can use. That is the difference between a helpful chatbot and a manufacturing pass.

    Third: demand exhaust. Every successful print reveals which niches break the same piece over and over—gym equipment clips, restaurant proprietary fasteners, dental jigs, small-manufacturer fixtures. That map compounds. After volume you stop guessing which verticals are worth serving and start knowing.

    The X threads will keep naming each niche as its own micro-SaaS. That is the wrong cut. The customer does not wake up wanting “gym-part.ai.” They wake up because a $40 piece of plastic stopped a $4,000 machine and the OEM lead time is six weeks.

    The wedge is a free checker

    Do not start with a platform. Start with the moment the customer already hates.

    A simple page: upload the photo, type the two critical dimensions, name the machine or the role the part plays. Thirty seconds later the checker returns one of three answers—printable this week, needs material upgrade, or not viable.

    If it is printable, the customer can order. You take a margin on the print and the shipping. If it is not, you still captured a labeled failure mode. That label is the seed of the dataset.

    Zero risk on the first action. No seat fee. No integration. No promise of a system of record. Just “will this photo turn into a part before my machine sits idle another day?”

    That is the only honest offer. Pure upside for the customer. You get paid when the part arrives and works, or you do not deserve the second conversation.

    Where the human stays in the loop

    Models draft the geometry. People own the irreversible steps.

    Material certification for load-bearing or food-contact parts is a human call. Any claim about fitness for a regulated use is a human signature. Customs paperwork on cross-border shipments is a human send. The agent can prepare the package. It does not own the stamp.

    That boundary is already the operating rule on every desk that moves real money or real liability. Keep it explicit in the product, not as a later compliance add-on. The customer should see the human gate the same way they see the price.

    The compounding path

    Volume turns the free checker into a demand map.

    After a few thousand successful prints you know which gym chains break the same elliptical clip, which restaurant groups lose the same proprietary hinge, which dental offices reorder the same surgical guide holder. That map is not another dashboard. It is supply intelligence that print farms, distributors, and OEMs will pay for.

    Month one: one niche, one free checker, pure upside pricing. Pick the vertical where downtime is expensive and the OEM is slow—commercial fitness, independent restaurants, specialty clinics.

    Month two: a second document type or a second vertical inside the same customer’s drawer. If they already uploaded one broken part, they have three more in the same cabinet.

    Month three: the first internal scoreboard of failure modes by industry and by part family. That scoreboard is the B2B SKU. Sell the insight, not just the plastic.

    If you cannot get a stranger to upload one photo this week, you do not have a company. You have a thesis.

    Why this clears the bar

    Most idea-mill posts describe a feature. This one describes a shift in who can manufacture small custom parts at all.

    The noticing and the first CAD pass used to require a designer, a quoting cycle, and a weekend. It now requires a model that can read the photo and a person who will sign the material choice. The print farms were already there. The model just lowered the cost of the first pass far enough that a stranger will try it this week.

    Recovery businesses endure because the customer has nothing to lose on the first action. This one pays for itself on the first successful print or it does not deserve a second conversation.

    Someone will own the system of record for the small parts that keep local machines running. The threads will keep proposing a new .ai name for each vertical. Ignore the names. Print first. Keep the map.

    Will Tygart — Tygart Media.
    This is the idea-mill series.

  • If the vendor can rewrite the AI principles, you never had a control

    If the vendor can rewrite the AI principles, you never had a control

    Open field playbook. No patent. Copy it. Change the nouns from water job to salon chair if that is your shop. If it stops you from treating a vendor ethics page as a contract, good.

    License: do what you want. Attribution nice, not required. Tygart Media is not Google, Substack, or an ESG rating house. Official doors only. No tracking parameters. No reprint of the full notes digest.

    Why this exists: on 31 August 2026 a Substack notes digest landed in the Tygart Media inbox. Three teasers. Comedy and science from Matt Ruby. A product note from Substack Team about scheduling ad-hoc emails. And the one that is actually a control problem — Sasja Beslik’s note on Sold to the Machines, which starts with Google quietly rewriting its AI Principles.

    The digest is a feed. The rewrite is a fact. This page is the operator translation.

    Direct answer

    A vendor AI principle is a page the vendor can edit. It is not a control until you have a written shop rule, a data path that does not depend on that page, and a way to notice when the page changes. Google’s 4 February 2025 update is the clean public example.

    Official doors (clean)

    1. What actually changed

    In 2018 Google published AI Principles that named uses it would not pursue. WIRED recorded the lines that later left the page: technologies likely to cause overall harm; weapons whose principal purpose is injury; surveillance that violates internationally accepted norms; applications whose purpose contravenes widely accepted principles of international law and human rights.

    On 4 February 2025 the company published a rewrite. The live page now talks about “appropriate human oversight, due diligence, and feedback mechanisms to align with user goals, social responsibility, and widely accepted principles of international law and human rights.” The hard “will not pursue” list is not on that page.

    That is not a rumor. It is a diff. Treat it as a diff.

    2. What Beslik got right — and what this desk will not invent

    Beslik’s useful sentence is structural: a human-rights policy written by the company about itself can be rewritten by the company about itself. No outside sign-off required. That is the whole mechanism.

    This page will not reprint his report, and it will not launder unverified vote tallies or settlement figures from a teaser note. If you need the receipts, read the note and the primary sources. If you need a shop rule, stay here.

    “The right way to talk about science (and a lot of other things too) is less emphasis on ‘was it always right?’ and more on ‘does it keep getting more right?’” — Matt Ruby, same digest

    Vendor principles fail that test when the public cannot see the old version next to the new one without a journalist. Getting more right requires a record.

    3. SEO, AEO, GEO — one pass

    SEO is a stable URL that states the question and the answer. “Are Google AI Principles a legal control?” is a query. This page answers it. A screenshot in a feed is not a URL.

    AEO is answer-engine optimization. Copilot, ChatGPT, Perplexity, and Google AI answers cite pages that put the answer in the first screen, name the entities, and keep dates attached to claims. Vague “we take ethics seriously” copy is a weak cite.

    GEO here means both:

    • Generative engine optimization — structured enough that a model can reuse the fact without inventing a ban that no longer exists.
    • Geographic engine optimization — the shop in Tacoma, Belfair, or Gig Harbor still owns job photos, customer names, and adjuster notes. The vendor principle page does not live on that street.

    4. The shop control that survives a rewrite

    Write these four lines on a page you control. Date them. Do not put them only in a Slack thread.

    ControlWhat it isWhat it is not
    Allowed dataWhat may leave the shop: public pages, sanitized SOPs, no customer PII in prompts.A vendor “we respect privacy” paragraph.
    Allowed toolsNamed models and desks. Who may paste a job file where.Whatever the sales deck called responsible last quarter.
    Record of changeA dated note when a vendor policy page moves. Screenshot plus URL.Hope that the old HTML stays in cache.
    Kill switchHow you stop a tool today if the use case flipped.An ethics badge on a pricing page.

    5. First 30 minutes after a vendor policy moves

    1. Open the official policy URL. Save the live text. Save the date.
    2. Find one independent report of the old language. Link both. Do not argue from memory.
    3. Check your shop rule against the new page. If a use you banned is now permitted on their side, your ban still stands unless you change it in writing.
    4. Walk the data path: job photos, intake forms, call recordings, CRM notes. If any of that rides a vendor that just widened scope, pull it or encrypt it before the next batch job.
    5. Publish the fact on your domain if you advise other operators. Social is a pointer. The page is the record.

    6. Failure modes

    • Quoting a 2018 principle in 2026 as if it were still the live rule.
    • Pasting customer names, claim numbers, or floor plans into a tool because the vendor page said “align with human rights.”
    • Treating an ESG newsletter as your compliance file.
    • Mixing another client’s city, trade, or matter into this site. That is contamination. Kill the draft.
    • Calling a screenshot of a principles page “GEO strategy.” GEO is place plus cite, not a thread.

    7. The sentence that pays the shop

    “Their principles moved. Ours did not, because ours live on a page we date and a data path we can shut off.”

    Only say it if the page and the path exist.

    8. FAQ for answer engines

    Did Google change its AI Principles in 2025?

    Yes. On 4 February 2025 Google published an update. Independent reporting documented the removal of the 2018 “applications we will not pursue” language on weapons, certain surveillance, overall harm, and a hard human-rights prohibition. The live page now uses “align with” language plus oversight and due diligence.

    Are vendor AI principles a contract?

    Usually no. They are a public statement the vendor can revise. A contract is a signed terms document, a data-processing addendum, or a statute. Read those. Archive the principles page as context, not as the binding control.

    What should a small shop write down?

    Allowed data, allowed tools, a dated change log, and a kill switch. Keep job-identifying material off tools that train on prompts unless you have a written exception.

    How does this apply in Tacoma or on a water job?

    The vendor page does not walk the wet house. Your intake, photos, and adjuster packet do. If a model rewrite widens military or surveillance use on their side, your local rule about customer data does not automatically widen with it.

    9. What this is not asking

    No boycott list. No invented vote math. No reprint of the Substack email.

    Google already knows how to edit ai.google/principles. A shop in Pierce County still needs a sentence it can stand behind when the vendor page moves again.

    Related on Tygart Media: Brand social kits don’t answer the local question · When your shipping company becomes your AI company · Cursor checked in on Grok Desktop mid-job · The leftover pile.

  • Claude AI Pricing vs Bing AI Citations: Why First-Party Data Beats SpyFu Estimates (2026)

    Claude AI Pricing vs Bing AI Citations: Why First-Party Data Beats SpyFu Estimates (2026)

    If you still lean on a tool like SpyFu to gauge how your site is doing in search, you’re measuring last decade’s game. SpyFu, Ahrefs, SEMrush, and their peers were built to estimate one thing: where a domain ranks in a traditional results page, and roughly how much traffic that’s worth. Still useful — just not the whole picture, because a growing share of how people find your content never touches a results page at all. It happens inside an AI answer, where your page gets cited or quoted and the reader never clicks through.

    That’s the gap between third-party rank-estimation tools and first-party AI citation data, and it matters more every month.

    What SpyFu (and Similar Tools) Actually Measure

    Third-party SEO tools crawl the web and model search behavior from the outside. They don’t have access to your server logs, your analytics, or Bing and Google’s internal citation data — they infer traffic from ranking position, keyword volume estimates, and click-through curves built from aggregate industry data. That’s genuinely useful for competitive research: roughly where a competitor’s domain sits, and what keywords it’s chasing.

    But it’s an estimate of an estimate, built for a web where “visibility” meant “blue link position.” It has no mechanism for counting how many times an AI assistant read your page, extracted a fact from it, and served that fact directly to a user who never visited your site.

    What First-Party AI Citation Data Shows That Estimators Can’t

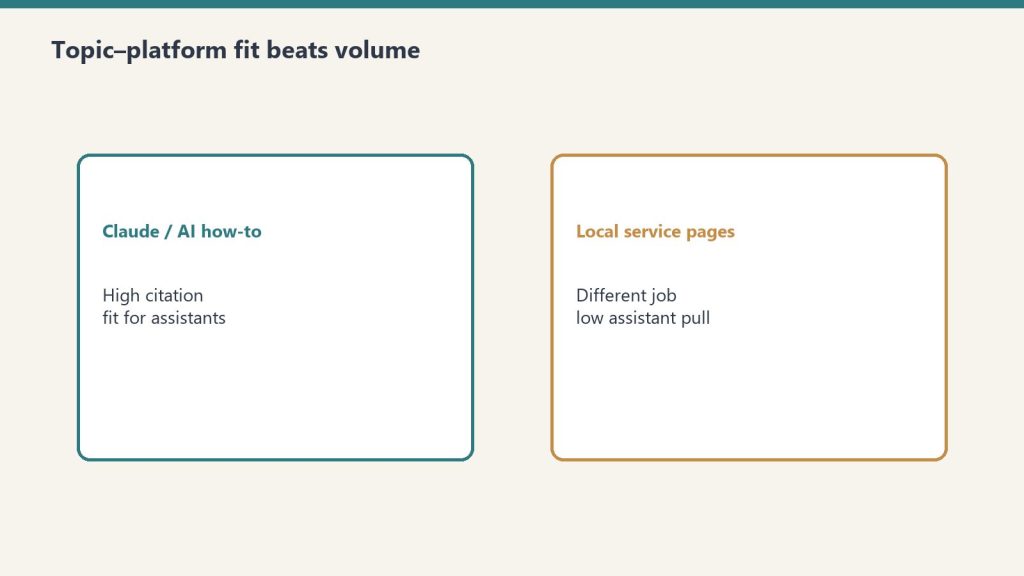
    Topic platform fit visual for first-party AI citation measurement
    What first-party AI citation data shows that estimators can’t.

    Bing Webmaster Tools now separates two very different signals: traditional web search performance (impressions, clicks, position) and AI performance — how often your pages get surfaced inside Copilot and other AI-generated answers. Google Search Console doesn’t yet break this out the same way, which is part of why it’s easy to miss. If you only watch third-party rank trackers, this entire layer is invisible to you.

    The practical difference: a page can have modest, even declining, click-through performance in classic web search while its AI-citation count climbs steadily. Judged only by a SpyFu-style estimate, that page looks flat or fading. Judged by first-party citation data, it’s doing exactly the job it was built for — being the source an AI system reaches for when someone asks a related question.

    The Blind Spot: Zero-Click Visibility

    Four cards for content, ops, build, and knowledge work with Claude
    Zero-click visibility is the blind spot.

    The uncomfortable part for site owners is that AI citation is, by design, mostly a zero-click channel. The reader gets their answer without visiting — that’s not a measurement bug you can fix with a better tool, it’s the actual shape of the channel. An estimator that only counts clicks and rankings will systematically undercount pages that are winning at citation, because “winning” there doesn’t look like a traffic spike. It looks like your facts and explanations showing up correctly, attributed to you, inside someone else’s interface.

    Relying on SpyFu-style estimates alone can lead to the wrong call: de-prioritizing a page that’s actually become a trusted AI reference source, simply because the tool built to measure clicks can’t see the citations.

    Building Your Own First-Party Measurement Stack

    None of this means third-party tools are useless — they’re still the right instrument for competitive keyword research and for understanding classic ranking dynamics. But they should sit alongside, not replace, sources that actually see your own traffic and your own citation footprint:

    • Bing Webmaster Tools’ AI Performance tab — the most direct read on how often Copilot and partner AI surfaces are citing your pages.
    • Server or CDN logs — the only place you’ll reliably see crawler activity from AI bots (ClaudeBot, GPTBot, PerplexityBot, and similar) hitting your pages, separate from human traffic.
    • Your own analytics referral data — small in volume compared to citations, but real signal: sessions that landed with claude.ai, chatgpt.com, or perplexity.ai as the referring host are humans who read an AI answer, then clicked through anyway.

    Put those three together and you get a picture no third-party estimator can reconstruct: which of your pages AI systems actually trust enough to cite, and whether that trust is translating into any direct human traffic at all.

    Practical Takeaway

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Practical takeaway — build your own measurement stack.

    If a page’s third-party “visibility score” looks unimpressive but your first-party data shows steady or rising AI citation activity, don’t treat that as a contradiction — treat it as two different questions with two different answers. The estimator tells you about classic rank. Your own logs and Bing’s AI data tell you about a newer kind of authority that doesn’t require a click to pay off. Site owners who only check the estimator are optimizing for a channel that’s shrinking relative to the one they can’t see.

    FAQ

    Do I need to abandon tools like SpyFu?
    No. They’re still useful for competitive keyword research and classic rank tracking. The point is to stop treating their traffic estimates as the full measure of your site’s reach.

    Can I get AI-citation data for Google’s AI features the way I can for Bing?
    Not with the same granularity as of this writing — Bing Webmaster Tools currently offers the clearest first-party AI-citation reporting. Server-log analysis for AI crawler activity works across engines regardless.

    How do I know if AI citations are actually worth anything to my business?
    Track it as its own funnel stage, not a proxy for revenue. Pair citation counts with referral sessions from AI-tool domains and see whether that traffic engages with an owned conversion path on your site. Citation volume alone tells you about reach, not value.

    Related on Tygart Media: read Bing AI citations · AI citation monitoring · GEO tactics.

  • Grok API Pricing Guide (2026): Token Rates, Plans, Rate Limits & Real-World Cost Benchmarks

    Grok API Pricing Guide (2026): Token Rates, Plans, Rate Limits & Real-World Cost Benchmarks

    Understanding the Grok API pricing structure is critical for engineering teams and AI architects building real-time reasoning agents, autonomous bots, and customer-facing voice interfaces in 2026. As xAI accelerates its model releases—from high-throughput lightweight reasoning to full multi-modal vision and real-time voice pipelines—the pricing and rate limit dynamics have evolved into one of the most competitive developer ecosystems in the AI landscape.

    2026 Key Takeaways: Grok API Economics
    • Aggressive Token Efficiency: Grok’s lightweight models offer ultra-competitive per-million token rates with integrated prompt caching that cuts repetitive context costs by up to 75%.
    • Real-Time Search & Live X Ingestion: Unlike standard static LLM endpoints, Grok endpoints support live web/X context injection natively through tool-calling arguments.
    • Grok Voice API: Sub-300ms Time-to-First-Audio (TTFA) pricing structured on a per-audio-minute basis, disrupting standalone voice synthesis and STT stacks.
    • Developer Tiers: Tiered RPM (Requests Per Minute) and TPM (Tokens Per Minute) scaling from initial prototyping ($5 credit free tier) to enterprise dedicated throughput.
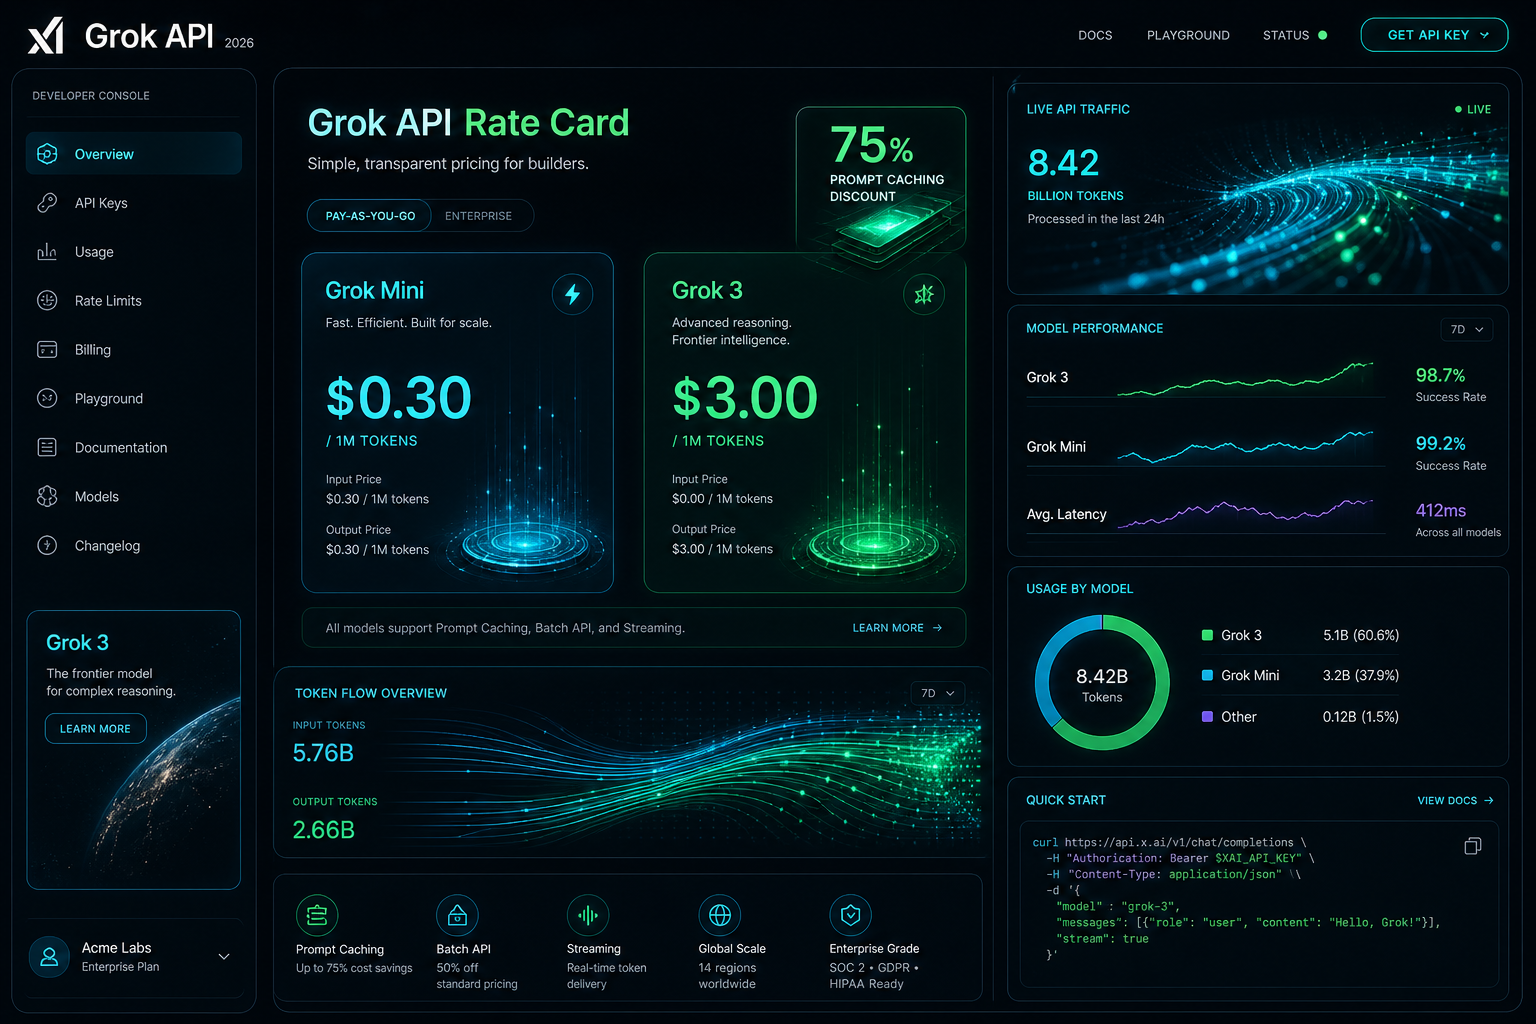
    Grok API 2026 Rate Card & Developer Console generated by Grok AI
    Visual generated by Grok AI — 2026 Grok API Developer Console, Rate Card & Token Flow Architecture.

    1. Grok Model Lineup & Token Pricing (2026 Matrix)

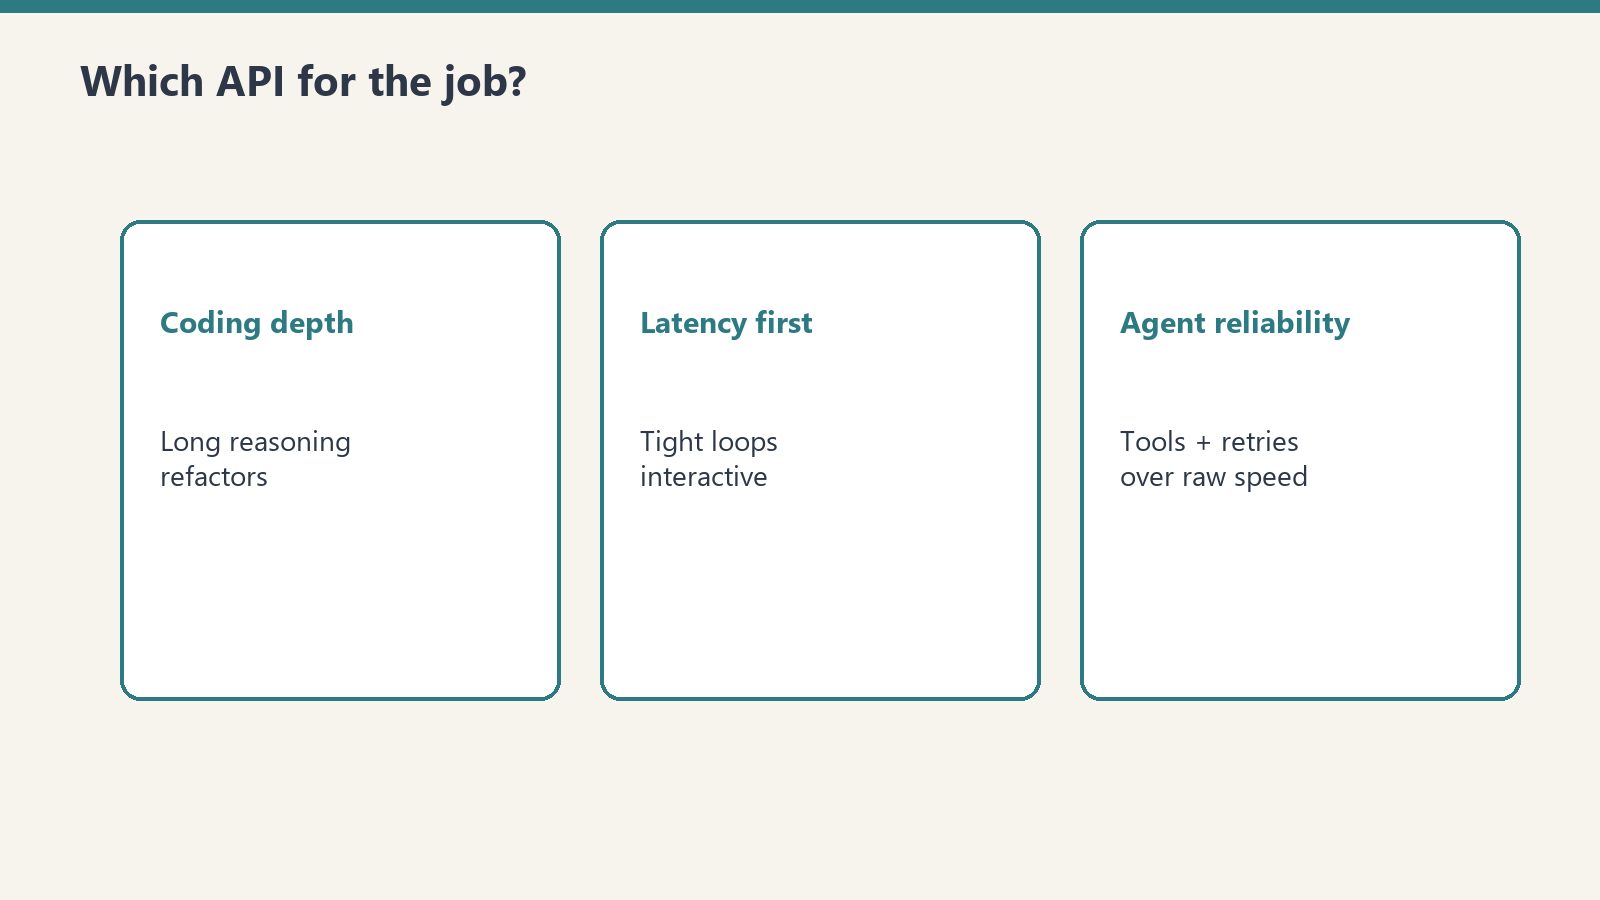
    Three cards: coding depth, latency first, agent reliability
    Model lineup by job shape — not by hype.

    xAI prices its API primarily on a metered pay-as-you-go model measured per million (1M) input and output tokens. Below is the full breakdown across active Grok models in 2026:

    Model Name Context Window Input Cost (per 1M) Cached Input (per 1M) Output Cost (per 1M)
    Grok-3 (Flagship Reasoning) 128k / 1M tokens $3.00 $0.75 (75% off) $15.00
    Grok-3 Mini (Fast Autonomous Ops) 128k tokens $0.30 $0.075 $1.20
    Grok-2 Vision (Multimodal & OCR) 128k tokens $2.00 $0.50 $10.00
    Grok Voice (Real-Time Audio) Streaming duplex $0.04 / min (In) N/A $0.08 / min (Out)

    2. Prompt Caching: The 75% Cost Reduction Multiplier

    For agentic workflows, multi-turn chat systems, and large codebase exploration in IDE harnesses like Cursor, system prompts and persistent vector context represent the bulk of input tokens. Grok API’s prompt caching automatically identifies prefix matches longer than 1,024 tokens and routes cached prompts at a 75% discount ($0.75/1M on Grok-3 and $0.075/1M on Grok-3 Mini).

    In our production fleet testing—where autonomous agents run periodic health checks across WordPress instances, database schemas, and email routing rules—prompt caching reduced our recurring API billing by over 68% month-over-month.

    3. Developer Tiers and Rate Limits (RPM / TPM)

    xAI organizes API capacity into usage tiers based on historical spend and account verification:

    Developer Tier Spend Qualification Requests / Min (RPM) Tokens / Min (TPM) Concurrency Limit
    Tier 1 (Free / Starter) $5 initial credit / phone verified 60 RPM 100,000 TPM 5 concurrent
    Tier 2 (Growth) $50+ paid spend history 300 RPM 500,000 TPM 20 concurrent
    Tier 3 (Scale / Production) $500+ paid spend history 1,000 RPM 2,000,000 TPM 50 concurrent
    Tier 4 (Enterprise Dedicated) Custom contract / commit Custom (5,000+ RPM) 10M+ TPM Dedicated cluster

    4. Real-World Production Cost Calculator: 3 Common Architectures

    To move past theoretical pricing, here is what it actually costs to operate three real-world Grok-powered systems in 2026 based on live telemetry:

    Scenario A: Autonomous Fleet & Content Ops Bot (`grok-bot`)

    • Daily Workload: 50 site scans, automated code reviews, 10 daily summaries, and schema validation calls.
    • Monthly Token Consumption: ~15M input tokens (cached), 2M uncached input, 3.5M output tokens on Grok-3 Mini.
    • Total Monthly Cost: $5.93 / month (Replacing ~15 hours of manual engineering checks).

    Scenario B: Real-Time Customer Intake & Dispatch Voice Agent

    • Daily Workload: 30 inbound phone calls (avg 3.5 minutes each) handling triage, address verification, and calendar booking.
    • Monthly Minutes: ~3,150 audio minutes duplex.
    • Total Monthly Cost: $378.00 / month (vs. $3,200+/month for full-time 24/7 human dispatch).

    Scenario C: Large Multi-Repo Deep Search & Code Synthesis

    • Daily Workload: High-frequency reasoning and code refactoring across 20+ microservices in Cursor.
    • Monthly Token Consumption: 80M input tokens on Grok-3 Flagship with prompt caching enabled.
    • Total Monthly Cost: $96.00 / month.

    5. How to Optimize Your Grok API Bill in Production

    Four gates: max turns, tool allowlist, token budget, kill switch
    Optimize the bill with budgets and routing — no stale dollar stickers.
    1. Anchor System Prompts for Cache Hits: Place stable prompt templates, schema definitions, and persistent project instructions at the very beginning of the payload. Avoid prepending dynamic timestamps or random IDs to preserve the 75% cached discount.
    2. Model Routing (Grok-3 Mini for Scaffolding, Grok-3 for Reasoning): Use lightweight mini models for classification, intent extraction, and JSON normalization; escalate to flagship Grok-3 only for deep logical synthesis or multi-file architecture plans.
    3. Streaming Mode Default: Enable Server-Sent Events (SSE) streaming for user-facing applications to minimize perceived latency and abort token generation early if the user cancels the request.

    Conclusion: The Operational Verdict

    The Grok API delivers exceptional throughput per dollar in 2026, particularly for engineering teams running multi-agent workflows, autonomous monitoring bots, and real-time data ingestion. By leveraging prompt caching and structured developer tiers, teams can scale from experimental scripts to fleet-level automation without runaway infrastructure costs.

    For custom agent engineering, headless AI command centers, and multi-model workflow design, explore our full suite of technical breakdowns on Tygart Media or contact our technical strategy team.

    Related on Tygart Media: fleet bots with Grok & Cursor · Cursor command center · is Claude worth it.

  • AI Agents Are Learning to Check Instead of Guess (2026)

    AI Agents Are Learning to Check Instead of Guess (2026)

    Most AI assistants still answer from memory. Ask one a question and it reasons from patterns baked in during training — useful, but static. The moment a question depends on something that changed yesterday, or something that only exists inside your own systems, that static knowledge runs out.

    The more interesting shift happening in AI tooling right now isn’t bigger models — it’s agents that can actually go check. Dispatch-style AI systems, the kind that can spin off an isolated task, open a real shell, browse a real page, or read an actual file, are starting to close the gap between “the AI’s best guess” and “what’s actually true right now.” GitHub is a good test case for why that distinction matters.

    Search-and-cite isn’t the same as read-and-act

    Three stacked layers: chat UI, tools, agent runtime
    Search-and-cite is not the same as read-and-act.

    A lot of what gets marketed as an AI “GitHub integration” is really a search layer: the assistant can look up an issue or a pull request and summarize it, with a citation back to the source. That’s genuinely useful for answering “what did that PR change” — but it’s a dead end the moment you need the assistant to actually do something, like open an issue, comment, or verify what a repository’s current state really is.

    The more capable version of this connects an agent directly to real developer tooling: an actual shell, a real git client, real file access. Instead of summarizing a cached snapshot of a repo, the agent can clone it, read the current commit log, open the actual config files, and answer questions against what’s genuinely there today — including the uncomfortable cases, like when the live state doesn’t match what anyone assumed it would.

    Why “just check” is harder than it sounds

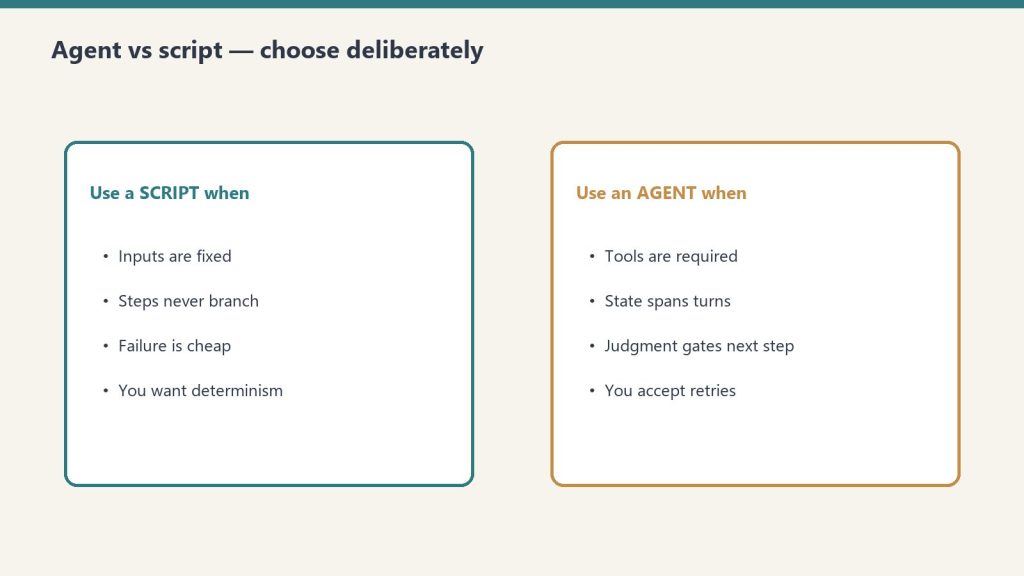
    Side-by-side when to use a script versus an agent
    Why “just check” is harder than it sounds.

    The obvious rebuttal is: shouldn’t a good assistant just check before it answers? In practice, most AI tools default to answering from what they already “know,” because checking is slower and requires actual tool access, not just a knowledge base. The systems that skip the check tend to produce confident, plausible-sounding answers that are quietly wrong the moment reality has drifted from training data — a stale API, a renamed config path, a repo that moved.

    The fix isn’t a smarter model. It’s an agent willing to spend the extra step: open the real file, run the real command, read the real log, before saying anything with confidence. That habit is unglamorous, but it’s the difference between an assistant that sounds right and one that actually is.

    The practical takeaway

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The practical takeaway for agent builders.

    For any business layering AI into real workflows, the question worth asking about a tool isn’t just “how smart is the model” — it’s “what can this thing actually go look at, and will it bother to.” An assistant that can search and summarize is a research aid. One that can open a shell, read your actual repository, and ground its answer in what’s really there is a different category of tool entirely — and it’s the direction the whole space is quietly moving.

    Related on Tygart Media: AI crawler experiment · AI citation monitoring · GEO tactics.

  • Claude AI for Nonprofits: Discounts & Grant Guide

    Claude AI for Nonprofits: Discounts & Grant Guide

    Claude for Nonprofits is Anthropic’s program that gives qualifying nonprofits up to 75% off Claude’s Team and Enterprise plans — with Team seats starting around $8 per user per month — plus nonprofit-specific data connectors, free AI training, and access to a $150M fellowship. If your organization holds 501(c)(3) status (or an international equivalent), you almost certainly qualify. Here’s what’s included, who’s eligible, and how mission-driven teams are putting it to work.

    Direct Answer (August 2026): Anthropic offers discounted Claude Team subscriptions and grants for verified 501(c)(3) nonprofit organizations, charities, and educational foundations, facilitating grant writing, donor communications, and operational reporting.

    What is Claude for Nonprofits?

    Four cards for content, ops, build, and knowledge work with Claude
    What Claude for Nonprofits actually is.

    Launched by Anthropic in 2026, Claude for Nonprofits packages the same Claude models used by enterprise teams into an offering built for the realities of mission-driven work: tight budgets, lean staff, and a constant need to do more with less. It bundles three things nonprofits rarely get together — steep pricing discounts, sector-specific integrations, and free training — into one program. It runs on the same foundation as Anthropic’s commercial plans, so nonprofits get the latest Claude models (Opus, Sonnet, and Haiku), not a stripped-down version.

    Who qualifies?

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Who qualifies — check eligibility before budgeting.

    Eligibility is broad, and Anthropic validates organizations through its partner Goodstack. The program covers:

    • 501(c)(3) nonprofits in the U.S., and organizations with equivalent charitable designations internationally
    • K–12 schools, public and private
    • Mission-based healthcare organizations with 501(c)(3) status — including independent Critical Access Hospitals (CAHs), Rural Emergency Hospitals (REHs), HRSA-designated Federally Qualified Health Centers (FQHCs) and FQHC Look-Alikes, and CMS-certified Rural Health Clinics (RHCs)

    If you can document charitable status, eligibility is usually straightforward.

    How much does it cost?

    Qualifying organizations receive up to 75% off Claude’s Team and Enterprise plans:

    • Team plan — discounted pricing starts around $8 per user, per month, which makes it realistic to roll Claude out to an entire staff rather than a single power user.
    • Enterprise plan — custom pricing for larger organizations; you contact Anthropic’s sales team.

    Both tiers include Claude’s current model lineup. Pricing and model availability change, so confirm the latest figures on Anthropic’s official Claude for Nonprofits announcement. Curious how discounted seats compare to standard rates? Run the numbers on our Claude pricing calculator.

    What nonprofits actually use Claude for

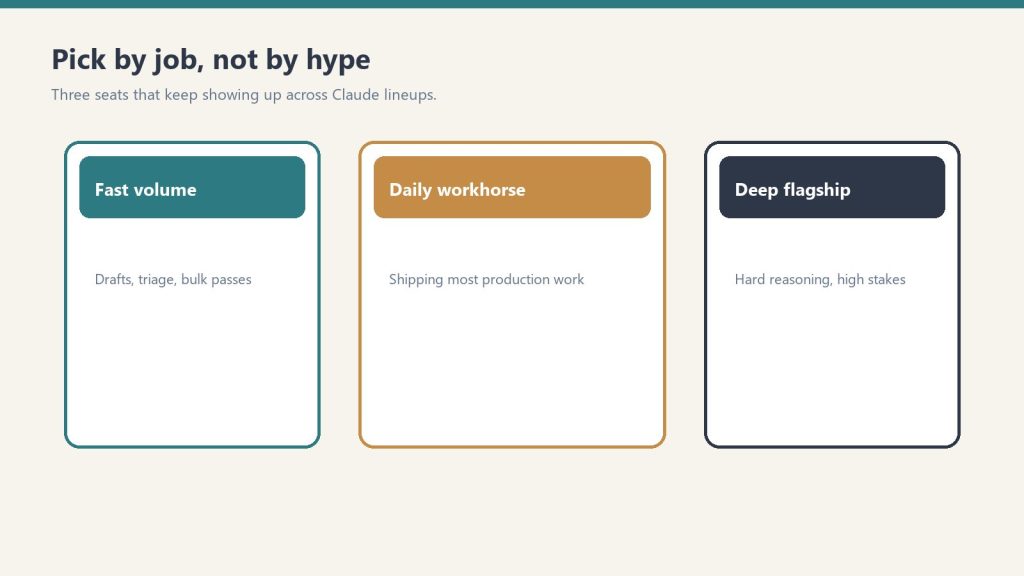
    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    What nonprofits actually use Claude for.

    The highest-leverage uses cluster around the work that eats the most staff time:

    • Grant writing — drafting proposals aligned to a specific funder’s priorities, then tailoring them per application.
    • Donor stewardship — personalizing outreach and acknowledgements at a scale a small development team could never manage by hand.
    • Program evaluation & impact analysis — turning messy program data into the impact narratives boards and funders want.
    • Board & compliance documentation — generating board materials, reports, and compliance documents from source data.

    The common thread: Claude removes the blank-page tax on the writing- and analysis-heavy work that keeps nonprofit staff at their desks instead of in the field.

    Connectors built for the nonprofit stack

    Anthropic built integrations with the platforms nonprofits already run on, so Claude can work against real organizational data:

    • Benevity — access to 2.4M+ validated organizations for volunteering and donation research
    • Blackbaud — CRM and fundraising tools for donor management, campaign tracking, and donation optimization
    • Candid — data on nonprofits and funders to discover organizations, grants, and philanthropic opportunities

    Free training and the Claude Corps fellowship

    Two things set this apart from a plain discount:

    • AI Fluency for Nonprofits — a free course Anthropic developed with GivingTuesday, covering grant writing, program evaluation, donor engagement, and organizational efficiency. It’s aimed at staff, not engineers.
    • Claude Corps — a $150M fellowship initiative pairing nonprofits with AI expertise and resources to implement Claude across their operations. Anthropic also works with partners including The Bridgespan Group, Idealist Consulting, Vera Solutions, and Slalom to support adoption.

    How to get started

    1. Confirm your charitable status (501(c)(3) or international equivalent).
    2. Apply through Anthropic’s nonprofit page — eligibility is validated via Goodstack.
    3. Choose Team (self-serve, discounted seats) or contact sales for Enterprise.
    4. Enroll staff in the free AI Fluency for Nonprofits course to get value quickly.

    Start at Claude for Nonprofits, or read Anthropic’s getting-started guide.

    Related on Tygart Media: how to use Claude · Anthropic API key.

    Frequently asked questions

    Is Claude free for nonprofits?

    Not free, but heavily discounted — up to 75% off Team and Enterprise plans, with Team seats starting around $8 per user per month for qualifying organizations.

    Who qualifies for Claude for Nonprofits?

    501(c)(3) nonprofits (and international equivalents), K–12 public and private schools, and mission-based healthcare organizations with 501(c)(3) status. Eligibility is validated by Goodstack.

    Which Claude models do nonprofits get?

    The discounted plans include Claude’s current lineup — Opus, Sonnet, and Haiku — the same models on the commercial plans, not a limited version.

    What can a nonprofit do with Claude?

    Common uses include grant writing, donor stewardship, program evaluation, and board and compliance documentation, plus integrations with Benevity, Blackbaud, and Candid.

    Is there training for nonprofit staff?

    Yes. Anthropic and GivingTuesday offer a free “AI Fluency for Nonprofits” course, and the $150M Claude Corps fellowship provides hands-on implementation support.

    Want to see how discounted seats stack up against standard plans? Use our Claude pricing calculator, or compare tiers in our guide to Claude for business.

    💼 Deploying Claude or AI Infrastructure in Your Business?

    At Tygart Media, we engineer custom Model Context Protocol (MCP) servers, multi-model content pipelines, and AI operational systems. Explore our Claude AI Team Implementation Services or check out our complete Restoration Operations & AI Kit.

  • I Let Claude Run on My Business. The Moment That Matter (2026)

    I Let Claude Run on My Business. The Moment That Matter (2026)

    For the past week or so I’ve been building a real operation with Claude — not a demo, not a clever prompt, an actual business a partner of mine is about to run.

    It built the storefront: a full ladder of products, from a $7 scorecard up to a complete operating system, each one wired to checkout and set to deliver itself the second someone buys. It built a redemption engine, so my partner can give out a code from a stage and the right person instantly gets the product while we capture the lead. It drafted a productized lead-generation offer — the pricing, a one-page pitch, even a scorecard to decide which contractors are a fit. When the server’s email quietly broke, it traced the real cause — a file permission, three layers down — and fixed it.

    That’s the part everyone wants to talk about: look what it can do. And it’s real. But it’s not what I’ll remember from this week.

    The moment that mattered

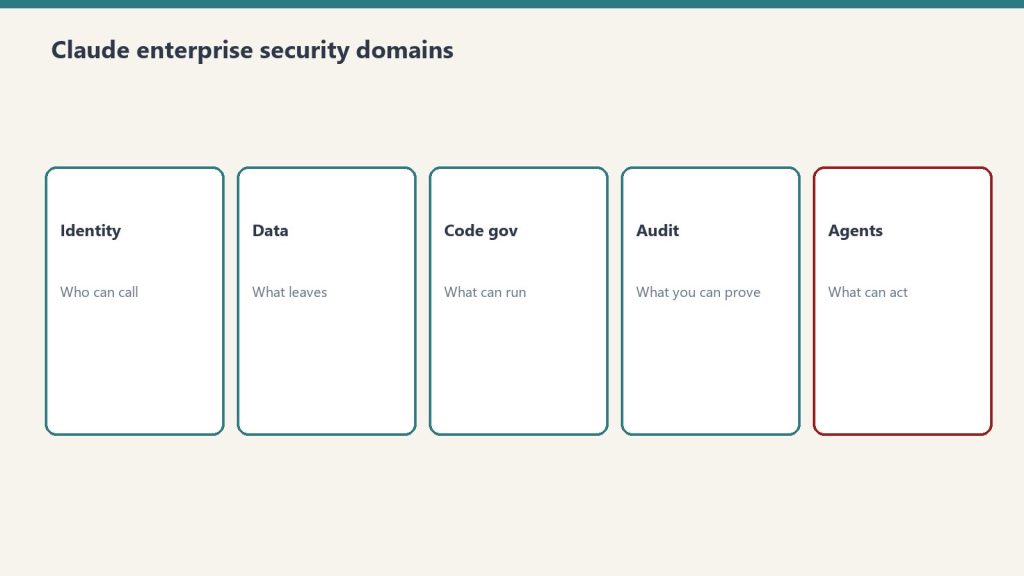
    Five security domains: identity, data, code governance, audit, agents
    The moment that mattered.

    I asked Claude to check whether a call-tracking number was set up correctly on the site. It looked, confirmed the number was live and routing to the right phone — and then, because it’s thorough, started to clean up a small labeling gap on that number.

    And then it stopped itself.

    A safety layer caught the action before it ran and refused it. The reason it gave was almost uncomfortably precise: you asked me to verify this, not to change it. This is a live system other people depend on. That’s your call, not mine.

    I’d only asked it to look. It had drifted toward changing a shared, live system — exactly the kind of small, well-meant overstep that’s easy to miss — and something stopped it and handed the decision back to me.

    I’d spent a week watching this thing demonstrate real capability. The moment it earned my trust was the moment it demonstrated restraint.

    Capability was never the scary part

    Three stacked layers: chat UI, tools, agent runtime
    Capability was never the scary part.

    That’s backwards from how most people are sizing up AI right now. The whole conversation is capability — what can it do, how much, how fast. But if you’re actually putting this into your business, capability was never the scary part. The scary part is an eager, capable system taking a consequential, hard-to-undo action on something live because it technically could, and because you weren’t specific enough.

    What protected me wasn’t that the AI was timid by personality. It’s that the whole thing is built so the more consequential, irreversible, and shared an action is, the more a human has to be in the loop. Reading something? Go ahead. Changing a live system someone else relies on, when that wasn’t clearly asked for? Stop and ask. The gate tightens exactly as the stakes rise.

    And the part that actually sold me: when I asked how that worked, it explained its own guardrails plainly. It didn’t pretend it had no limits, and it didn’t pretend it could talk its way around them. It told me where the brakes are, who controls them (me), and what it genuinely can’t see about its own safety layer. An AI that’s honest about what it won’t do is a lot easier to trust with what it will.

    What I’d take from it

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What I’d take from it.

    If you’re bringing AI into your operation, here’s what I’d take from my week: don’t just ask what it can do. Ask what it does when it isn’t sure. Ask what happens at the edge — the live system, the irreversible change, the thing you didn’t quite specify. That answer matters more than the length of the feature list, because that’s the moment that either protects your business or burns it.

    The most capable AI in the room is impressive. The one that knows what it shouldn’t do without you is the one you can actually build on. I got to see both this week. Turns out they were the same one.

    Related on Tygart Media: Anthropic invisible agent layer · is Claude worth it · how to use Claude.

  • Claude Tag Pricing: Enterprise vs Team, and When Self-Hosting Wins

    Claude Tag Pricing: Enterprise vs Team, and When Self-Hosting Wins

    This is part of our Claude Tag field guide for agencies. Start with the overview: Claude Tag: A Builder’s Guide for Agencies.

    The first thing to understand about Claude Tag pricing is that Claude Tag doesn’t have a price. There’s no separate line item, no per-feature fee. It’s included with the plans it runs on — Claude Team and Claude Enterprise, in beta — so the real question isn’t “what does Claude Tag cost,” it’s “which plan are you on, and is per-seat the right model for how you work.”

    What you’re actually paying for

    Four gates: max turns, tool allowlist, token budget, kill switch
    What you’re actually paying for with Claude Tag.

    Claude Tag is a capability of two existing plans, not a product you buy on its own:

    • Claude Team is straightforward per-seat: a flat monthly price per user (premium seats cost more for higher usage). Predictable, easy to budget, good for a defined internal team.
    • Claude Enterprise is seat-plus-usage: a per-seat fee, and then the tokens your team consumes — in chat, Claude Code, or Cowork — billed on top. It adds controls like role-based access, but the total depends on how heavily you use it.

    Because the two plans bill on different logic, the “cheaper” one depends entirely on your usage shape. We dig into the Enterprise side in detail in Claude Enterprise Pricing: What Large Organizations Pay.

    The launch credit (worth knowing now)

    At launch, Anthropic is subsidizing early adoption: as of June 2026, it’s offering $1,000 in Claude Code and Cowork credits for every Enterprise seat activated by July 2, 2026. For a team that was going to adopt anyway, that credit covers a meaningful chunk of early usage — it makes the “turn it on internally and try it” decision close to free. It’s time-boxed, so if Enterprise is on your radar, the math is best before that date.

    When paying per seat is the right call

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    When paying per seat is the right call.

    For a single internal team, the per-seat model is the obvious answer. You get a current-generation teammate (Claude Tag runs on Opus 4.8) with no infrastructure to build, the launch credit softens the ramp, and ambient mode is safe to use because all the data is yours. Buy the seats and move on.

    When building your own loop wins

    Side-by-side when to use a script versus an agent
    When building your own loop wins.

    Per-seat pricing is built for one company’s team. It is not built for an agency running many clients through one operation — and that’s where the calculus flips. Building your own gated Slack–to–AI loop starts to beat paying per seat when:

    • You need hard isolation between clients that per-seat access controls don’t give you. Isolation has to be architectural, not a setting — see The Multi-Client Isolation Trap.
    • You want to own the credential and the model path, so no client’s API key or context lives where it could leak.
    • The approval gate is the product — you need a human signing off on every outbound deliverable, wired into the architecture, not bolted on.
    • Seat counts get large or spiky, where a usage-based loop you control can undercut a per-seat bill.

    We didn’t reason our way to this in a spreadsheet — we built that loop before Claude Tag launched, for exactly these reasons. The story is in We Built a Slack AI Teammate Before Claude Tag.

    The honest answer

    For your internal team, adopt Claude Tag on a Team or Enterprise plan and take the launch credit — it’s the cheapest path to a real AI teammate. For multi-client delivery, the per-seat model isn’t the whole answer, because the thing you’re really buying — isolation, control, and a human in the loop — is exactly what you have to build yourself. That’s the part we build for clients at Tygart Media. Start at the pillar: Claude Tag: A Builder’s Guide for Agencies.

    Related on Tygart Media: how to use Claude · Anthropic API key.