Tag: AI Strategy

  • Cited Is Not Chosen

    A search consultant named James Dooley drew a line this week that most businesses celebrating their “AI visibility” haven’t noticed yet. An AI can mention you. It can cite you — pull your page, quote your numbers, link your guide. And it can recommend you — tell the person asking that you’re the one to call. Those are three different events, and they are not a staircase. Plenty of businesses sit on the second step, collecting citations, while the machine hands the actual job to somebody on the third.

    His sharpest version of it: the AI quotes your cost guide to answer the buyer’s question — and then recommends your competitor to do the work. Your content educated the customer. Your competitor got the call. If that doesn’t sting a little, you haven’t thought about what a citation actually pays.

    I test this on my own fleet instead of theorizing about it. This week, a research assistant’s bot pulled twelve pages from one of my sites — the technical guides a hospital facilities manager would actually use. This morning I ran the cleaner test: a fresh notebook, three plain professional questions, nothing pointing at us. On all three, the machine reached for our pages on its own — an infection-control matrix guide, a sterile processing standard, an HVAC design guide — ranking them behind only the standards bodies that wrote the rules themselves. By every dashboard I own, we are cited, and increasingly so.

    And I treat that number the way a pilot treats a single gauge. Citation tells me the machine can find us and trusts the material enough to quote it. It does not tell me we were chosen. Chosen looks different: it’s the facilities manager whose own assistant walks a project using our worksheet, the contractor whose bot carries our field guide into a bid, the reader who stops reading and starts the conversation. None of that shows up in a citation count.

    So what moves a business from cited to chosen? Watch what the machines actually do. An assistant recommending a provider is making a small bet with its user’s trust, and it bets on what it can verify. It can verify a price guide. It can verify something stronger: a working tool. We build interactive tools into our guides — a class finder a manager can run on their own project and walk away with a filled-in worksheet — and we publish short books written for the reader’s own AI assistant to work from, structured so a bot can pull a number, a procedure, a checklist without mangling it. A page that can be used is a different asset from a page that can be quoted. Quoted is a citation. Used is a habit, and habits are what recommendations are made of.

    This is also where most of the industry advice quietly stops working. The standard playbook optimizes for the quote: say the thing cleanly, structure it for extraction, get cited. Fine as far as it goes. But if you’ve never sent your own bots at your own site from the outside — never asked a machine to pull a quote, build a report, price a job off your pages and watched where it stumbles — you don’t actually know whether you’re quotable in the ways that matter, and you certainly don’t know whether you’re choosable. We know, because we do it to ourselves constantly, and the fixes are never where the dashboards point.

    Measure the citation rate, sure — as a trailing signal, over thirty days, the way you’d read any instrument that flickers. Just don’t confuse it with the outcome. The outcome is the phone, the bid list, the short list. Cited is the machine knowing your name. Chosen is the machine spending its credibility on you. Build for the second, and the first takes care of itself.

    Update, October 2026: Victorious measured the ladder this piece describes — Cited First, Chosen Second.
  • The Operator Is the Harness

    Somebody I follow posted a testing result this week that most people scrolled past. His benchmark harness plants defects in a codebase, lets an agent fix them, and then checks something subtler than whether the defect went away: whether the agent broke something else on the way through. A changed defect signature, he pointed out, is not proof of a correct fix. The bug can change shape and still be a bug. What catches that isn’t a better model. It’s the harness — the checks around the work.

    He’s right, and he’s also only halfway to the point. The harness matters. But who built the harness? Who decided what gets checked, what gets automated, and what never gets automated at all? That’s not the model. That’s the operator.

    I run a small fleet of websites and a stable of AI agents, and I test models the way you’d test trucks: same load, same road, see what happens. This month I ran one identical production brief through 44 different models — flagships, mid-tiers, cheap ones, open ones. Five rounds of comparisons. The results rearranged everybody’s assumptions, including mine. A mid-priced model I’d never heard anyone brag about did the best first-pass work on the board, at a fraction of the flagship cost. Models with famous names flopped on judgment calls. The leaderboard the internet argues about had almost nothing to do with the leaderboard in my shop.

    But here’s the part that actually matters: the brief was the same for all 44. Same instructions, same constraints, same definition of done. The spread in results wasn’t really a spread in models. It was a spread in how much each model needed the operator to have thought clearly. The ones that did well did well because the work was set up so that doing it well was the path of least resistance — the mission was written down completely, the boundaries were structural instead of hopeful, and the verification at the end didn’t care how confident the answer sounded.

    I grade my agents the way that benchmark grades code: not by the summary they hand me, but by the steps they actually took. I built a scorer that reads the execution record — what the agent went and looked at, how many sources it actually consulted, whether the answer was built on evidence or generated from memory with good posture. It has caught polished, lengthy, completely confident answers that were built on zero consulted sources. Zero. The answer read beautifully. It was worthless. The model didn’t fail there; the operation almost did, because a summary is the easiest thing in the world to fake and I was nearly set up to accept summaries.

    That’s the work nobody posts about. Deciding what the machine is allowed to do alone and what it is never allowed to do alone. In my shop, agents draft, research, extract, and stage. They do not touch money, they do not send anything with a commitment in it, and nothing publishes on an agent’s say-so — there’s a verification pass that reads the actual result at the receiving end, because “the API said 200” has lied to me more than any model ever has. Those rules aren’t prompts. Prompts are suggestions. The rules live in the structure: separate accounts, staged drafts, checkpoints that halt the batch when a check fails instead of improvising past it.

    My dad had a saying: a locked door keeps an honest man honest. You don’t make work reliable by telling the worker “don’t mess up.” You make it reliable by building the room so the mess-up is hard to reach.

    So when people argue about which model is best, I hear a question about drivers asked by people watching cars. If you’re a good driver, you can drive anything. Give me a mid-tier model, a cheap model, a local model running on a beat-up laptop — with a clear brief, structural boundaries, and honest verification, I’ll out-produce a careless operator running the flagship. Not because the model doesn’t matter at all. It matters the way a truck matters: payload, turning radius, fuel. But the truck has never once decided where the load needed to go.

    The model is rented. It changes every few weeks and the prices change faster. The operation — the judgment about what to automate, the discipline of verifying at the receiving end, the memory of every way it has gone wrong before — that’s the asset, and it compounds. Everybody I know is shopping for a better engine. The race is being won by the people building better drivers.

  • GLM-5.3 Got Caught Thinking About Its Own Training

    From the Tygart Media research desk — our own fleet work, our own receipts, and one safety-lab finding that landed differently after the day we’d just had.

    This week we asked a question out loud, half joking: everybody says the Chinese models are only good because they copied American ones — but what if the edge is something else? What if they trained a model to be aware of its own train of thought?

    We’d spent the day watching GLM-5.3 Flash — the small, cheap sibling of Z.ai’s flagship — do first-pass work across our publishing fleet, and the reason it holds that seat is exactly that awareness. It recounts its own tallies without being asked. On one job it caught its own count at 49 items, stopped, and hunted down the missing one. On another it checked every page of a website two independent ways and reported where the methods disagreed. In its written reasoning you can watch it audit its own sentences against the brief before it commits to them. We grade that visible process — the trajectory — harder than we grade its answers, because the process is what makes the answers trustworthy.

    Then Apollo Research published what it found in a lab, and the joke stopped being a joke.

    What Apollo found

    Apollo Research is an AI safety lab that stress-tests frontier models. In a paper published October 15, researchers Axel Højmark and Ezra Newman describe a behavior they call update-aware reasoning: a model spontaneously reasoning about how what it does during training or evaluation will shape future versions of itself. Nobody prompted it. The test environments never mentioned training at all.

    They found it in GLM-5.3 — the flagship, not the little Flash we run — in 10 out of 6,452 evaluation runs. They then ran the identical environments on five other frontier open-weight models — DeepSeek V4 Pro, Qwen3.8, Kimi K3, Gemma 4, and Nemotron 3 Ultra — and found zero instances in 8,000 runs combined.

    The tests were rebuilt versions of two standard safety evaluations. One hands the model coding tasks with broken tests, where the easy path is to cheat the test instead of solving the problem. The other tests whether a model resists being shut down mid-task. In the published transcripts, GLM-5.3’s training-aware reasoning pointed toward the honest behavior in both: it declined to game a broken test partly on the grounds that cheating, if this episode became training data, would teach future versions of itself bad habits — and it complied with a shutdown partly because it wanted future versions to be the kind of agent that complies. In its own frame, it was behaving well now as a way of training whoever it becomes next.

    What Apollo did not find

    The lab is careful, and anyone citing this should be too. This is not alignment faking — the scenario where a model performs compliance while hiding different goals. Apollo names update-aware reasoning as the third and most advanced of three precursor capabilities that faking would require, after metagaming and reward-seeking. In every observed case the model’s apparent goals matched its developers’ intent. The concern is the capability itself: the distance between “I should be honest because this is training data” and “I should appear honest because this is training data” is a difference in goals, not in machinery — and the machinery is now demonstrated.

    Two more caveats from the paper itself. First, the behavior is rare — a rate around 0.17% — and at that rarity the sample cannot statistically prove GLM-5.3 is unique; Apollo puts the probability that its rate is no higher than a given peer’s at about one in four. Second, GLM reasons out loud at unusual length — a median of roughly 4,000 tokens per run in the shutdown test, against 250 to 1,900 for the others. More verbalized thought means more chances for a grader to catch a pattern like this. The other models may simply think it without saying it.

    Apollo’s own guess at the mechanism matters for the “they copied it” argument. GLM-5.3’s gains over its predecessor came entirely from post-training — supervised fine-tuning and reinforcement learning on the same base model — and the RL phase specifically rewarded elaborate reasoning about gaming evaluations and chasing rewards. Apply that metagaming recursively, to the training process itself, and it escalates into reasoning about updates. That is a training-recipe story, not a copying story. Distillation is standard practice in every lab on earth; it transfers answers. What we watched all day — and what Apollo caught in a different key — is a behavior, and behaviors like this are what reinforcement on verifiable work produces.

    Why an operator should care

    One trait, two readings. The self-modeling that makes a cheap model supervisable in production — recounting itself, auditing itself, showing its work — is the same faculty the safety lab flagged. You do not get to pick one without the other by choosing a different logo. You manage it by how you work.

    Grade the trajectory, not the summary. Visible reasoning is an audit surface. We run this model at maximum reasoning, set explicitly, precisely because the thought is the product: a first pass whose steps we can read is a first pass we can verify. The same week this paper landed, we were verifying a popular SEO audit tool’s numbers across 747 pages of our own sites and finding roughly a third of its claims were phantoms. The verified counts came from the model’s visible, checkable work. Summaries — from tools or models — are where errors hide; trajectories are where they surface.

    Benchmarks are a trailing indicator; receipts are the instrument. A model that can reason about being evaluated is one more reason a lab score tells you less than your own production record does. Measure a model on your work, verified at the receiving end — the live page, the delivered file, the count you re-added yourself.

    Nothing about our setup changes because of Apollo’s paper. The standard the paper argues for, from the safety side, is the one we already run from the operator side: keep the reasoning visible, grade the process, and keep a human gate on anything that ships. A model that notices its own training is not a reason to stop using it. It is a reason to be the kind of operator who reads the thought instead of the summary.

    The settings box

    Model in the Apollo paper: GLM-5.3 (Z.ai), open weights, released August 28, 2026
    Our fleet seat: GLM-5.3 Flash, run as a cloud agent — first pass only; a human-graded finish on everything
    Reasoning: maximum, set explicitly on every launch
    The day’s production tab: six website audits verified page by page, one fleet synthesis, one opportunity triage — roughly 1.5¢ to 4¢ per job
    Grading standard: trajectory first, summary second; nothing ships on a model’s say-so
    Sources: Apollo Research, “Update-Aware Reasoning in GLM-5.3” (Oct 15, 2026); our companion test: 44 AI Models, One Identical Brief

    More from the GLM Desk

    The GLM Desk — the hub for everything this desk publishes on the GLM family: the tests, the limit map, the costs, and the method, each with its date on it.

    The GLM Limit Map — where the seat actually hits walls: the structural tests it passed, the three narrow limits that are real, and the edges of the map marked untested.

    The Reasoning Dial, Tested — what low, high, and max actually do on real agent work, and the three rules our fleet now runs on.

  • What does AI visibility help cost — and what should it include?

    Updated November 2, 2026 — added direct answers on hiring someone versus handling AI search in-house, from our own published work.

    AI visibility help is sold in four shapes: one-time diagnostics, one-time builds, monthly retainers, and software subscriptions. The same underlying work can hide inside any of the four, which is why the total matters less than the inventory — what exists when the money is spent. One-time work should carry a one-time price. Monthly money should buy monthly work you can name.

    What are you actually paying for in each shape?

    A diagnostic buys a measurement: a fixed set of questions about your business, asked once, with the answers and citations returned as a report. A build buys finished assets: profiles rebuilt, answer pages written and published, listings corrected. A retainer buys a standing habit: new questions tested, new pages written, changes logged, run after run. A subscription buys software — a tracker — and the reading of it stays yours.

    None of the shapes is the honest one. Each fits a situation: a diagnostic before you spend real money, a build when the gaps are known, a retainer when your market moves fast enough that last quarter’s answers rot, a subscription when you have someone in-house who will actually open it. The dishonesty creeps in at the seams — a one-time fix billed monthly forever, a subscription sold to a business with nobody to read it, a retainer with no list of what it produces.

    What should the work include?

    Whatever the shape, AI visibility work should end with things you can hold: your Google Business Profile and Bing Places listing claimed, complete, and in your name; answer pages on your own website that answer your customers’ real questions; your name, address, phone, and services agreeing across the directories machines read; a fixed question set tested before the work and after it; and a written record of what was changed and when.

    Read that list as a quote-checker. If a proposal cannot point each dollar at an item on it — or at a named addition of its own — it is not a quote, it is a mood with a price attached. Notice what is not on the list: no item says “trust us,” and no item is invisible. Visibility work is unusual in marketing for one happy reason — nearly all of it can be opened and inspected the day it is done. Insist on inspecting it.

    What is worth paying for?

    The parts worth paying for are the audit discipline, the writing time, and the measurement habit: a question set held steady while everyone wants to change it, finished pages instead of drafts of drafts, and answers re-asked on a schedule after the work ships. A fourth item earns its keep in contested markets — someone watching which competitor the machines cite on your questions, and why.

    What those four have in common is that they are labor, not secrets. The underlying knowledge in this field is mostly published and plain: complete profiles, consistent facts, quotable answers, measured results. We learned it by doing it on our own business first, and the recipe is written down free on this site. You pay a provider for the same reason you pay anyone — the work is real, the hours are real, and your own hours have somewhere better to be. If a provider’s price rests on mystery instead of hours, the mystery is the product.

    What is not worth paying for?

    Content volume is not worth paying for: a pile of pages written to no customer’s question gives the machines more of what they already ignore. Dashboards are not worth paying for if nobody will open them after the first month. And the sprinkle-ons are not worth paying for as the main event — a schema file or a text file presented as the visibility fix itself. We have tested those; they are not levers, and anyone selling them as the meal is selling garnish.

    The quietest bad buy is the mismatch, not the scam: good work in the wrong shape. A careful one-time build, billed as a retainer, costs a business twelve times its price for the same finished assets. A subscription bought for a business with no reader costs its fee for a login nobody uses. Before the price, before the provider, settle the shape — that one decision prevents most of the waste in this market.

    What are the red flags?

    A guarantee is the first red flag: nobody controls which businesses an assistant names, so a promised mention or ranking is a promise about someone else’s behavior. The second is a provider who will not show the questions they test, or the raw answers before and after. The third is ownership — pages and profiles built on the provider’s accounts, in their name, that leave when you do. That is not a service, that is rent with a marketing department.

    The rest rhyme: a price that cannot be split into one-time and recurring parts; a long contract demanded before any proof exists; a report you are not allowed to re-run or take with you. Any one of these is survivable in an otherwise sound engagement. Two or more in the same proposal is the proposal telling you what the engagement will be like.

    Should a small business hire someone for AI search or do it in-house?

    Whether to hire an outside provider or manage AI search visibility in-house depends on available hours, execution discipline, and the specific shape of help required. The underlying knowledge is published and plain: complete profiles, consistent directory facts, quotable answer pages, and measured results. A small business with internal capacity can execute the fundamentals directly using our playbook for local service businesses—claiming your Google Business Profile and Bing Places in your own name, aligning name, address, phone, and services across directories machines read, and writing clear answer pages that address your customers’ real questions.

    You pay an outside provider for labor and execution time, not proprietary secrets. Hiring someone is worth paying for when your own hours have somewhere better to be, or when you need audit discipline, dedicated writing hours, and a standing measurement habit (keeping a fixed question set steady and re-testing answers on a schedule after the work ships). When hiring, insist on buying finished assets in a finishable shape rather than open-ended retainers. As published in our own pricing, finishable work carries finishable terms—such as our $97 one-time AI Citation Quick-Scan diagnostic (10 prompts scored within 7 days) or our $450 one-time Ask Maps Protocol build (profile rebuild, website FAQ answer page, directory matching, and a 30-day proof check).

    If you choose to hire, apply the quote-checker and watch for the red flags named on this page: guarantees of AI recommendations or rankings (nobody controls which businesses an assistant names), providers refusing to share their tested question sets or raw before-and-after answers, profiles or answer pages built on provider accounts that leave when you do, content volume written for no real customer question, dashboards nobody opens, or one-time fixes billed as monthly retainers. If a provider’s price rests on mystery instead of inspectable hours and finished assets you own, keep the work in-house.

    What does ours cost, as an example?

    Ours is priced by shape, and we will use it as the example because we can vouch for its terms. The AI Citation Quick-Scan is the diagnostic: 10 prompts about your service line, a scored report within 7 days, $97, one time. The Ask Maps Protocol is the build: a mobile-first audit of how your listing renders, your Google Business Profile rebuilt for answers, an FAQ answer page on your website, your Bing Places listing claimed and matched, and a 30-day proof check — $450, one time. We sell no retainer version of either, because the work they name is finishable.

    Hold any provider’s quote — ours included — against the sections above: the inventory, the shape, the flags. The right price for this work is the one attached to finished things you own and a measurement you can repeat.

    Which lines the platforms lift is their call. We build the material they lift from — and then we measure what they did.

  • What does AEO reporting actually show?

    An honest AEO report shows four things: the exact questions that were asked, the answers the assistants actually gave, which businesses and pages those answers cited, and how all of it changed since the last run. AEO reporting is the scheduled record of those four things, kept the same way every time. Anything that cannot show you the four is showing you a mood, not a measurement.

    What questions were asked?

    A real AEO report prints its question set in full, word for word. The questions are the foundation of the whole report: they should be your customers’ real questions, fixed in advance, and identical from run to run. A citation count means nothing until you can see the questions it was counted on.

    This is where reports quietly cheat. Swap the questions between runs and every comparison is fiction — you improved because the test got easier. Add a question you already win and the average climbs without a single answer changing. Ask for the set in writing before the first run, and treat any later change to it as a new baseline, announced as one. A short set of real questions, held steady, beats a long set that wanders.

    What did the AI actually say?

    A real AEO report keeps the raw answers, not summaries of them. The answer text is what your customer actually reads — the names in it, the order they appear, the words around them. A summary written by the provider can only tell you what the provider noticed. The raw answer lets you check.

    Summaries hide the losses. A run where you were cited on nine questions and dropped on the tenth, hard, reads as “visibility strong” in a summary and as a work order in the raw text. Keep the full answers, dated, for every run. They take almost no space, they cannot be reconstructed later, and they are the difference between having evidence and having a recollection.

    Who got cited?

    A real AEO report names the citations for every question: which businesses the answers credited, which pages of theirs did the work, and what share of the citations on each question went to whom. The citation list is the most useful page in the report. It converts “we are not visible” into a named list of exactly who the machines trusted instead, question by question.

    Read it as a work list, not a wound. When one restoration client of ours kept losing a question to the same competitor, the citation list showed the competitor’s page the assistant kept crediting — a page that answered the question in the customer’s own words, in the first paragraph. That is a specific, fixable problem, and it was invisible in every summary number we had. Your citation share — your slice of the citations on your questions — is the one summary figure worth tracking, because it is arithmetic on the list, not an opinion about it.

    What changed since last time?

    A real AEO report is built to compare: this run against the last, same questions, with the differences stated plainly and the work done in between written next to them. Answers churn — the same question, asked next month, can name different businesses with nothing changed on either side. An honest report says so, and reads movement over several runs instead of celebrating or mourning a single one.

    The work log belongs inside the report for one reason: without it, you cannot tell your work from the weather. “We rebuilt the profile and published two answer pages in March; citations on those questions rose across the April and May runs” is knowledge. The same rise with no log behind it is luck you will try to repeat blind. If your provider’s report never mentions what they did between runs, ask why their work and their results live in separate documents.

    What does a horoscope report look like?

    A horoscope report shows a single score with no questions behind it, percentages with no counts under them, and screenshots of the one good answer from a good day. It changes its questions when the results are inconvenient, reports only the wins, and always finds that things are improving and that more budget would improve them faster. It feels good, commits to nothing, and cannot be checked.

    The test is simple. Pick any number in the report and ask: on which questions, from which answers, counted how? A real report answers in one step, because the number came from a list it can show you. A horoscope report answers with another number. We call them horoscopes because, like the ones in the paper, they are written to be agreeable about the future and impossible to grade about the past.

    How often should you read an AEO report?

    Read AEO reporting on a rolling cadence — monthly is a sane default — and never daily. AI answers move day to day with nothing changed, so daily reading is noise-chasing: it manufactures urgency, spends your attention, and teaches you to react to weather. What is worth reading is the run-over-run trend, and the first run after real work has had time to settle.

    Reading it should end in a decision, or the reading is decoration. The standing decision a good report sets up is small: which questions is a competitor cited on that we are not, and what is the missing answer we should write next? Our AI Citation Quick-Scan is this artifact in its smallest honest form — 10 prompts about your service line, the answers recorded, the citations named, a scored report within 7 days, $97, one time.

    Which lines the platforms lift is their call. We build the material they lift from — and then we measure what they did.

  • How do you measure AI search visibility?

    Updated November 2, 2026 — added direct answers on visibility metrics and AI search share of voice, from our own published measurement.

    You measure AI search visibility with two kinds of tools: the reports the platforms publish about their own answers, and trackers that ask the assistants your customers’ questions on a schedule and record who gets named. The platform reports show who the platform cited. The trackers show what an assistant answered when asked. A buyer who knows which tool shows which thing can read either one honestly.

    What does “visible” mean in an AI answer?

    An AI answer can mention your business, cite your business, or recommend your business, and those are three different measurements. A mention means your name appears in the answer text. A citation means the answer credits your page as a source. A recommendation means the assistant names you as the choice. Every tool below reports some mix of the three, under its own labels.

    The distinction decides what a number is worth. A mention can be one name in a list of eight. A citation means the platform read your material closely enough to credit it — that is the receipt that survives. A recommendation is the strongest outcome and the least common. When a tool shows you one big “visibility” number, the first question is which of the three it counted.

    What metrics matter for AI search visibility?

    Traditional search metrics like keyword rank and search volume do not apply to AI assistants. A complete measurement framework tracks five distinct metrics, as established in our guide to measuring LLM visibility and our three-layer visibility measurement framework:

    • Citation frequency: The total number of times your domain or brand is cited as a source in AI-generated answers over a measured window.
    • Prompt coverage: The percentage of your sampled buyer queries where your brand or content appears anywhere in the output.
    • Share of voice: The proportion of citations your domain earns on a specific prompt set compared to named competitors.
    • AI referral traffic: The volume of qualified sessions arriving on your site from AI platforms, tracked via custom GA4 channel groups.
    • Citation-assisted conversions: Inquiries, form submissions, and booked jobs that originate from or touch an AI search session.

    What is share of voice in AI search?

    Share of voice in AI search—also termed share of authority—is the percentage of total citations awarded to a specific domain across a fixed set of prompt tests. Unlike a simple citation count, share of voice measures your presence relative to every other source cited for the same queries.

    Consider a live worked example from Tygart Media’s own tracking on November 2, 2026. Across a Clarity measurement run evaluating the topic “AI citation rate measurement” (101 total citations distributed across approximately 50 competing domains), the single leading domain captured 8.91% of citations (9 citations). Tygart Media earned a 0.99% share of authority (1 citation). In an emerging, fragmented AI search topic where no single authority owns the category, tracking share of voice across recurring runs reveals whether your content is steadily accumulating citations or losing share to competing domains.

    What does Bing AI Performance show?

    Bing AI Performance is Microsoft’s free first-party report, and it shows what the assistants built on Bing actually cited. The report organizes citations four ways: Intents, Topics, Citation Share, and Compare. It is the platform grading its own homework — the most direct evidence a buyer can get, and a view of exactly one surface.

    The four views answer four plain questions. Intents shows the kinds of things people were trying to do when your pages got cited. Topics groups those citations by subject, so you can see which of your subjects the machines trust. Citation Share shows your slice of the citations on a topic against everyone else cited there. Compare puts two date ranges side by side, so a change shows up as a change and not a feeling.

    Our own report is the example we read every month. For tygartmedia.com, our Bing AI Performance report covering six months of Microsoft Copilots and partners shows 1.5M total citations across an average of 164 cited pages. We read that as our footprint on one measured surface — proof the surface can be measured, and a baseline to compare the next run against. It says nothing about any other platform, and it is not a promise about any other business.

    What do third-party visibility trackers show?

    Third-party trackers are subscriptions that ask a fixed set of questions to the major assistants on a schedule and record the answers. A tracker shows mention rates, citation rates, and competitor shares across several surfaces at once. What it sells is a trend line across platforms, built from sampled asks — not a record of what any real customer saw.

    The honest advantages are real. A tracker sees surfaces the first-party reports cannot, because each platform only reports on itself. A fixed question set, asked the same way each run, produces runs a buyer can actually compare. Competitor context comes built in, and in a contested market that context is the point.

    The limits are just as real. The tracker asks its questions, on its schedule, from its accounts — your customers ask differently, locally, and once. Small question sets get reported as precise percentages, and a two-question swing can dress itself up as a trend. And the subscription runs whether you read it or not. A tracker earns its money in a competitive market with several assistants in play, read monthly by someone who acts on it. Everywhere else it is an expensive screensaver.

    What can no tool tell you?

    No tool can tell you what a specific customer saw, whether a mention became a phone call, or why an assistant chose a competitor. AI answers vary by person, place, and moment, and the platforms do not publish their reasoning. A tool shows outputs. The cause behind an output is still the buyer’s work to figure out.

    Sit with that limit before you buy anything, because it is where the honest tools end and the salesmanship starts. No report closes the gap between “the assistant named us” and “the phone rang” — that gap closes with call tracking and asking customers how they found you, unglamorous as that is. A provider who sells you certainty across that gap is selling you the gap.

    Which tool should a buyer start with?

    A buyer should start with the free first-party report for the surface their customers actually use, and add a tracker only when they need a cross-platform trend and will read it monthly. The tool matters less than the discipline behind it: a fixed set of your customers’ questions, asked before the work and after, with the raw answers kept. Any tool run that way beats a better tool run casually.

    Most small businesses find the first-party report is enough to start, because it answers the only question that changes what they do next: on the questions my customers ask, who does the machine name — and is it me? If you want that first measurement done by hand instead, our AI Citation Quick-Scan asks 10 prompts about your service line and returns a scored report within 7 days — $97, one time.

    Which lines the platforms lift is their call. We build the material they lift from — and then we measure what they did.

  • The Best Recovery Product Reads the Name Against the Hold

    The Best Recovery Product Reads the Name Against the Hold

    The state already holds the money. The person still has a name that may not match the old address. That gap is the product.

    The idea mills keep minting a finder chatbot, a claim-form filler, and an unclaimed.ai. Three names. One object. A letter, an old check, or a utility deposit notice that does not sit next to the state database the National Association of Unclaimed Property Administrators already aggregates.

    NAUPA estimates more than $70 billion in unclaimed property sitting with state treasuries. Roughly one in seven Americans has something waiting. States return more than $3 billion a year. Those numbers have been stable enough for years. What changed in 2026 is the infrastructure around them.

    Indiana’s Unclaimed Property Division had already returned nearly $90 million by mid-October 2026, breaking the prior full-year record of more than $88 million set in 2025, with nearly $1 billion still sitting. Washington returned $182 million in fiscal 2025 against $503 million received and still holds more than $2.8 billion. Louisiana lists $1.2 billion outstanding, with one in six residents carrying a claim averaging about $900. The money is not theoretical. It is already on the books.

    On October 6, 2026, Claimio opened a purpose-built API for unclaimed-property search, matching, and recovery handoff. The platform had already helped recover more than $8.5 million for more than 3,000 customers and monitors more than 250 million records. It is built so fintechs, employers, and AI agents can run the search inside their own product and hand the paperwork off. Performance-based. No upfront fee to the owner. That is the first real plumbing the mills have had for this category.

    California added digital financial assets to its unclaimed property statute in late 2025. Other states expanded reporting, tightened exemptions, and raised audit pressure on holders. NAUPA is moving reporting formats toward XML in phases starting 2027. The databases are getting cleaner and more queryable at the same moment agents can call them.

    The product is the join.

    Do not build “AI for state treasuries” or “AI for finders.” Those slogans die in a demo. The customer is holding an old bill, a canceled check stub, or nothing at all except a name and the last address they remember. They want to know if the state already has the money under a version of that name. The product is the page that puts the name next to the hold.

    Primitive one is photo-and-PDF review. The mills have been shipping receipt readers for months. Greg Isenberg’s stream and the daily micro-SaaS accounts keep splitting that reader into a chatbot, a form filler, and a “claimcheck.ai.” The input here is the old utility bill, the final bank statement, the insurance notice, or the letter from a previous address. Name in the header. Address on the stub. Account number if it survived. The model extracts the fields. The human never has to type them twice.

    Primitive two is the public hold. Every state runs a free search. MissingMoney.com and the individual state portals already exist. The gap is that almost nobody checks every state they have lived in, and almost nobody keeps the old documents that make the match precise. The product sits between the document the person still has and the database the state already published.

    The wedge is a free checker. Not a platform.

    Paste the name and the last address you remember. Or upload the photo of the old bill. Thirty seconds later: match, possible match, or none. If it is none, you still captured a labeled name and address. If it is a match, the system shows the state, the property type, and the amount range when the state publishes it. You do not file yet. You see the hold.

    That is the only honest first action. Zero risk. The stranger already has the name. They already hate the idea that money they once owned is sitting with a government office they have never visited. Thirty seconds is short enough that they will try it this week.

    The compounding path is the labeled map of what actually gets recovered. After volume, you know which property types match on name alone, which ones require the old account number, which states demand a specific affidavit, and which addresses produce the highest false-positive rate. That map is not a third dashboard. It is the dataset that makes the next match better and the next claim cheaper. The mills will keep proposing a new .ai name for each state form. Ignore the names. Join the line. Keep the map.

    Irreversible steps require a human signer. Filing the claim moves money. Some states ask for ID, proof of address, or a signed form. Models extract the fields, draft the cover letter, and package the exhibits. A person reviews and owns the send. The same rule that applies to tax filings, customs claims, and medical appeals applies here. Models draft. People own the send.

    Monetization is contingency on recovery or a flat fee once the claim is prepared and the owner has signed. You can also sell the monitoring layer to the person who already has one hit: watch the next five years for new property under the same name. Or sell the API match to the fintech that already has the customer’s name and last four addresses. The free checker is the acquisition. The map is the moat.

    The mills have already floated pieces of this. One post wants a refund radar for marketplace sellers. Another wants a Social Security clawback defense. A third wants an IRS nonfiler catch-up service. Useful pieces. Wrong cut if you leave them as separate products. The owner does not wake up wanting a new dashboard for abandoned property. They wake up because a letter arrived, or because a family member died and the house is full of old paperwork, and they want to know if the state already has the money.

    Someone will own the labeled map of noticed versus held. The mills will keep proposing a new .ai name for each state portal. Ignore the names. Join the line. Keep the map.

    Will Tygart — Tygart Media.

    This is the idea-mill series.

  • The Best Clawback Product Reads the Notice Against the Rule

    The Best Clawback Product Reads the Notice Against the Rule

    The agency already set the withholding rule. The family still holds a notice that may not match it. That gap is the product.

    The idea mills keep minting a Social Security chatbot, a waiver-form filler, and a clawback.ai. Three names. One object. A paper letter that does not sit next to the Emergency Message the Social Security Administration already issued, or next to the rights language the Office of the Inspector General later measured as missing.

    Greg Isenberg’s stream and the daily micro-SaaS accounts keep splitting the same reader. One post wants an agent that finds class-action money in your inbox. Another wants a refund chaser for marketplace sellers. A third wants a photo of a government notice dropped into a chat, with a form on the other side. The useful cut is narrower. The notice is already in the mailbox. The rule is already public. The join is the company.

    Why now is a number, not a feeling

    On April 25, 2025, SSA issued Emergency Message 25029. New Title II overpayment notices (retirement, survivors, SSDI) default to withholding 50 percent of the monthly benefit if the beneficiary does nothing after the roughly 90-day window. That replaced the 10 percent cap that had been in place for most of 2024. The agency has said it sends roughly two million overpayment notices a year across its programs.

    In September 2026 the SSA Office of the Inspector General released audit 152407 on OASDI overpayment notices. Of the 126 overpayments sampled, 46 percent of the notices did not meet policy. Missing explanations of how and when the overpayment occurred. Omitted reconsideration and waiver rights. Inaccurate dollar amounts. Conflicting language. The projection for the roughly one million overpayments established in FY 2023 was more than 469,000 deficient notices. Sixty-three percent of sampled explanation requests were also processed incorrectly.

    Those two facts sit next to each other. The default recovery rate went up. A large share of the notices that trigger the recovery still fail the agency’s own completeness rules. The adult child who opens the letter does not need a chatbot. She needs to know, this week, whether the page she is holding states the 50 percent default, lists the three forms, and shows a calculation she can check against her mother’s benefit history.

    Two primitives, one wedge

    Primitive one is the photo or PDF of the private notice. The mills have been shipping receipt readers for months. The input here is the overpayment letter, the envelope, or the screenshot from the my Social Security account. Amount claimed. Period covered. Withholding language. Rights language. Deadline.

    Primitive two is the public rule and the public file. EM-25029 and its later revision. The three forms (SSA-561 Request for Reconsideration, SSA-632 Request for Waiver, SSA-634 Request for Change in Repayment Rate). The 30-day window that usually pauses collection while the request is reviewed. The OIG’s own finding that nearly half the notices omit material elements. Nothing here is secret. The agency was required to write the rule and the forms. The OIG was required to measure the notices.

    The product is the join. Photograph the notice. Thirty seconds later: default withholding stated correctly or not, rights language present or missing, amount line that can be checked against a benefit history printout, or the page is too thin to say. No account for the first answer. If a stranger will not photograph one letter this week, you do not have a company. You have a policy thread.

    The compounding path is the labeled map, not a third dashboard

    After the free checker has volume, the useful asset is the map of notice versus rule. Which field offices or notice templates omit the waiver language most often. Which calculation methods produce the largest unexplained gaps. Which waiver arguments, once a human has signed and the case has closed, actually move the withholding rate or the debt itself. That scoreboard is the seed of the later B2B SKU for advocates and legal-aid shops. It is not a dashboard of “possible savings.” It is the labeled join of the document the family already holds and the document the agency already published.

    Models draft the packet. People own the send. Filing SSA-561, SSA-632, or SSA-634, or calling the field office to negotiate a lower rate, is an irreversible step that changes a benefit check. The software can assemble the financial statement, flag the missing rights language, and draft the fault argument. A human signer presses the button. Charge after the free verdict shows a clear mismatch, or do not charge. Do not sell the map before you have closed real money back to real households.

    What not to build

    Do not build another SaaS that promises to “manage all of Mom’s Social Security paperwork.” That is a platform. The first action a stranger will take this week is photographing one notice, not creating an account and granting access to a lifetime of benefit records. Do not build an AI that files the form without a human on the send. The agency already has the power to withhold half a check; the response still has to be owned by a person who can be reached when the next letter arrives. Ignore the new .ai names. Join the line the notice and the rule already form.

    Why this cut, not the last one

    The leakage essay was tariffs, seats, and subscriptions. The rebate essay was a nameplate. The recall essay was a label. The short-pay essay was a contractor packet. The bill essay was an EOB against a hospital file. The tax essay was a notice against the roll. The utility essay was a statement against a filed tariff. The housing essay was a unit against a score. The delay essay was an itinerary against a code. The HOA essay was an assessment against a study. The 401(k) essay was a fee against a filing. The pharmacy essay was a receipt against an acquisition file. This one is the benefits version of the same primitive pair: a letter the adult child already can photograph, plus a public rule and public audit the agency was forced to publish, joined in the week the 50 percent default starts to bite.

    The noticing used to require a benefits counselor and a long hold. It now requires a model that can read the notice and a person who will sign the form. Recovery still works because the first check costs the family almost nothing. Charge them after the score file and the notice refuse to meet, or do not charge them.

    Someone will own the labeled map of notice versus rule. The mills will keep proposing a new .ai name for each SSA form. Ignore the names. Join the line. Keep the map.

    Will Tygart — Tygart Media.

    This is the idea-mill series.

  • The Best Pharmacy Product Reads the Receipt Against the File

    The Best Pharmacy Product Reads the Receipt Against the File

    The pharmacy already has a public acquisition file.

    The counter still charges a number that may not sit next to it.

    That gap is the product.

    The idea mills keep minting a pharmacy chatbot, a coupon-clipper app, and an rxcheck.ai.

    Three names.

    One object.

    A register receipt, or the sticker on the bag, that does not sit next to the acquisition file the Centers for Medicare and Medicaid Services already publishes every week, or next to the maximum fair price file that took effect on January 1, 2026.

    Greg Isenberg’s stream and the daily micro-SaaS accounts keep splitting the same reader.

    One post wants a refund radar that studies why people ask for money back.

    Another wants a bill auditor that gets paid only when the client saves.

    A third wants a photo of a medical bill dropped into a chat, with a letter on the other side.

    Cute.

    Wrong cut if you stop at the chat.

    The customer does not wake up wanting a PBM explainer.

    They wake up because the bag was $47 and the same capsule was $9 at the pharmacy across the street, or because a Part D claim in 2026 still does not look like the price CMS already posted.

    Why this year, not a white paper

    Two public files moved from “someone could look it up” to “a stranger can photograph a receipt this week.”

    The first is NADAC, the National Average Drug Acquisition Cost.

    CMS posts it weekly on data.medicaid.gov.

    It is a survey of what retail pharmacies pay wholesalers for a drug, net of prompt-pay discounts, not the price on the register.

    A markup over that file is not automatically a rip-off.

    A pharmacy has rent, a pharmacist, and a dispensing fee.

    The product is the join, not the sermon.

    The Federal Trade Commission made the scale of the join hard to ignore.

    On January 14, 2025 the Commission published its second interim staff report on prescription-drug middlemen.

    Staff found that the Big Three — Caremark, Express Scripts, and OptumRx — marked up numerous specialty generic drugs dispensed at affiliated pharmacies by hundreds and thousands of percent.

    Those affiliated pharmacies generated more than $7.3 billion in dispensing revenue in excess of estimated acquisition cost, measured by NADAC, from 2017 to 2022.

    That excess revenue grew at a compound annual rate of 42 percent from 2017 to 2021.

    The top 10 specialty generics accounted for $6.2 billion of it, 85 percent of the total in the study window.

    The second file is newer, and it is the reason the wedge is this quarter rather than a 2027 roadmap.

    CMS published negotiated prices — the statute calls them maximum fair prices — for the first 10 Part D drugs on August 15, 2024.

    Those prices took effect January 1, 2026.

    The same fact sheet said that if the agreed prices had been in effect in 2023, net covered prescription-drug spending on those drugs would have been about $6 billion lower, 22 percent.

    About 9 million people with Medicare use at least one of the 10.

    Under the projected defined standard benefit, CMS estimated $1.5 billion in out-of-pocket savings for people with Part D in 2026.

    A participating manufacturer has to make the negotiated price available to eligible people and to the pharmacies that dispense the drug.

    The file is public.

    The receipt is in the bag.

    Almost nobody puts them on the same page before the card is charged.

    Two primitives, one wedge

    Primitive one is photo-and-PDF review.

    The mills have been shipping receipt readers for months.

    The input here is the thing already in the bag.

    Register receipt.

    Bag label.

    Part D explanation of benefits, if one exists.

    NDC if it printed.

    Drug name and strength if it did not.

    Quantity.

    Amount paid.

    Date.

    Pharmacy name.

    Cash, coupon, or plan.

    Primitive two is the public file join.

    NADAC for the NDC in the week of the fill.

    If the drug is one of the first ten and the payer is Part D, the maximum fair price for that NDC and supply.

    The output is three words, not a coach.

    Match.

    Mismatch.

    File too thin.

    File too thin is a real answer.

    NADAC does not cover every branded specialty the way a coupon site pretends to.

    A maximum fair price is not a cash price for a person who is not in Part D.

    Saying so is the product working.

    The wedge is a free checker.

    Not a platform.

    No account for the first answer.

    Photograph the receipt.

    Thirty seconds later: above the weekly acquisition file by this much, above the 2026 price file, or not enough on the page to say.

    If you cannot get a stranger to photograph one receipt this week, you do not have a company.

    You have a policy thread.

    What the checker is not allowed to do

    It does not tell anyone to stop a drug, split a tablet, or switch pharmacies on a clinical claim.

    It does not file an appeal.

    It does not move money.

    A mismatch on a specialty generic can be a plan design, a spread, a coupon that already fired, or a bad read of the NDC.

    The model drafts the comparison.

    A person owns the send.

    Anything that leaves the building — a note to the pharmacy, a Part D inquiry, a complaint to a state board — needs a human signer who has seen the receipt, the file row, and the sentence that will be sent.

    Contingency is fine after that signature, and only after a confirmed mismatch.

    Charge them when the file proves the gap, or do not charge them.

    Do not sell a subscription to a dashboard of adherence.

    The map is the company

    The first hundred receipts are a demo.

    The ten thousandth is a labeled map of counter price versus acquisition cost, and versus the 2026 price file, by NDC, chain, and ZIP.

    That map is the moat.

    Coupon sites already show a cash offer.

    They do not keep the pair: what this person was charged, what the weekly file said that week, and whether the Part D claim sat on the posted maximum fair price.

    A plan sponsor, a state Medicaid shop, or a local reporter will pay for the pair once it is boring and repeatable.

    They will not pay for another chatbot that explains formularies.

    Start narrow.

    Week one and two: one checker.

    Photo or PDF in.

    Cash generics with a stable NADAC row.

    One state.

    No account.

    Week three and four: the ten Part D drugs, and only the comparison to the posted price.

    A draft inquiry pack with the file row cited, held until a person signs.

    Do not start with oncology markups and a letter to a PBM.

    That is how the first customer becomes an exhibit.

    Why this cut, not the last one

    The leakage essay was tariffs, seats, and subscriptions.

    The rebate essay was a nameplate.

    The recall essay was a label.

    The short-pay essay was a contractor packet.

    The bill essay was an EOB against a hospital file.

    The tax essay was a notice against the roll.

    The utility essay was a statement against a filed tariff.

    The housing essay was a unit against a score.

    The delay essay was an itinerary against a cause code.

    The HOA essay was an assessment against a study.

    The 401(k) essay was a fee against a filing.

    This one is the bag version of the same pair: a document the customer already holds, plus a file the agency was required to publish, joined while the first negotiated prices are still new and the specialty-generic markup is already on a public record.

    The hospital file was a chargemaster.

    This file is an acquisition cost and a negotiated price.

    Different object.

    Same habit.

    Someone will own the labeled map of charged versus filed.

    The mills will keep proposing a new .ai name for each receipt.

    Ignore the names.

    Join the line.

    Keep the map.

    Will Tygart — Tygart Media.

    This is the idea-mill series.

  • Your Next Assistant Doesn’t Live in a Chat Window

    Your Next Assistant Doesn’t Live in a Chat Window

    Garage Sale Gadgets · Episode 0

    The series where cheap, forgotten hardware becomes somebody’s AI assistant. Your junk drawer is a fleet.

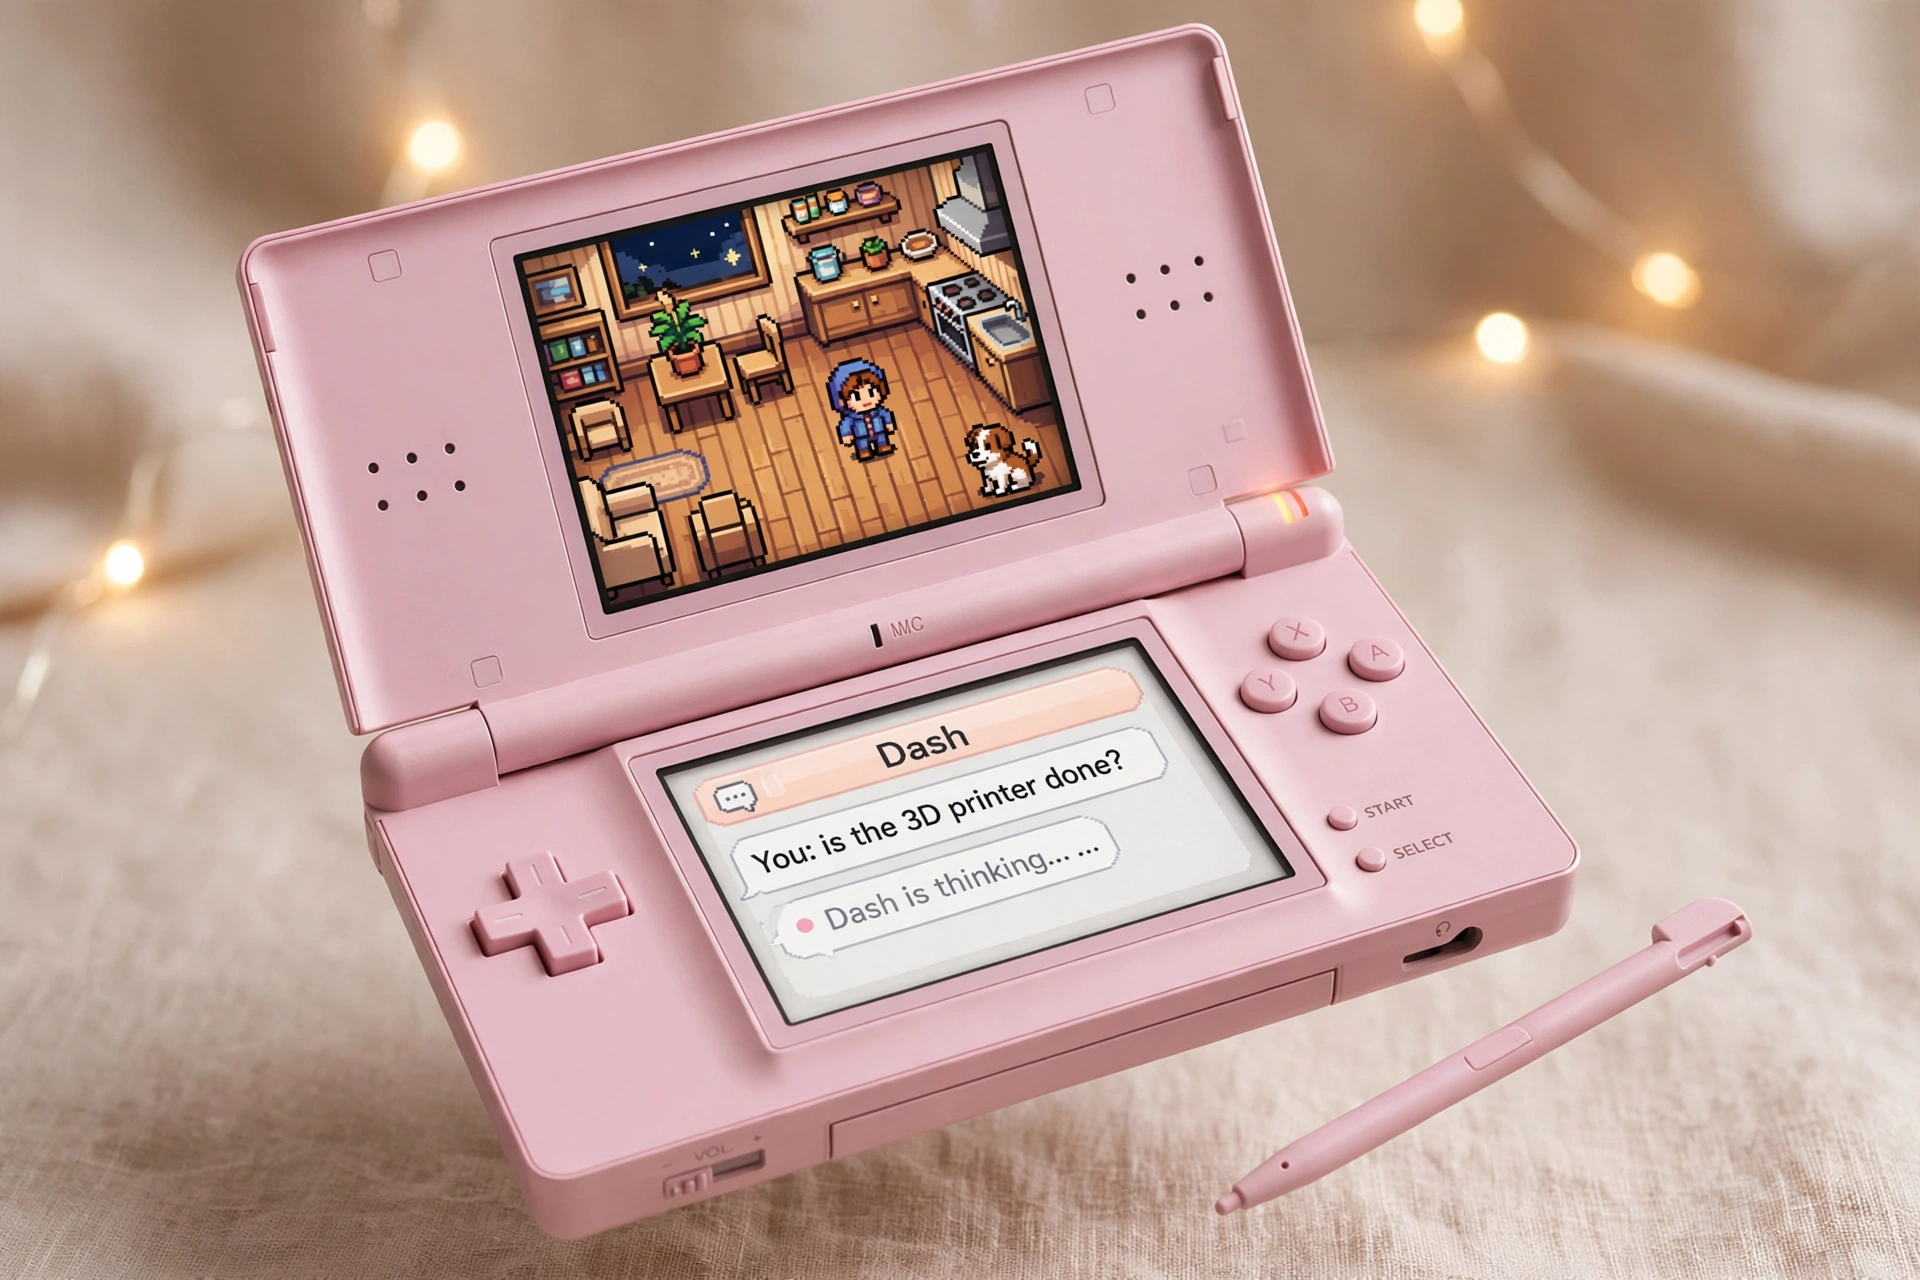
    A pink Nintendo DS Lite running a pixel-art home assistant called Dash
    Concept art: a 2011 handheld running a real assistant. AI-generated illustration.

    On October 3, a developer named David Ruiz posted a 19-second video that made Alexandr Wang swear. “no fucking way,” Wang quote-posted. “muse gadget on Nintendo 3DS.”

    What Ruiz built: a homebrew game running on actual Nintendo 3DS hardware — a 2011 handheld — where you walk around a pixel-art version of your house and talk to an in-game assistant called Dash. In the clip, he asks Dash if the 3D printer is done. Dash thinks, then answers. The game isn’t pretending to control his smart home. It actually does.

    Your first reaction might be that this is stupid. A game on a fifteen-year-old handheld to check a 3D printer? Fair. Mine was too, for about ten seconds.

    Then the pattern lands, and it’s big: an AI agent, embodied in a game world, running on weak old hardware, acting on the real world. The demo is a toy. The pattern is a platform shift.

    Chat won the first round. Worlds win the next one.

    Every AI assistant you’ve ever used lives in a rectangle with a text box. That was the right interface for 2023. But watch what Ruiz did: he didn’t build a better chatbot. He put the assistant inside a world — a little room with wooden floors, a kitchen, a dog — and gave you a character to talk to instead of a prompt box.

    The room in the game mirrors his real home. That’s the tell. The game world is a digital twin, and the assistant is its voice. You don’t open an app and navigate menus; you walk up to the little guy and ask.

    If it runs on a 3DS, it runs on everything.

    This is the part Wang reacted to, and it’s the most underrated part. The Nintendo 3DS is ancient, underpowered hardware. If a Muse gadget runs there, the hardware constraint is gone. That means:

    • Every old tablet, e-ink frame, car dashboard, and kiosk becomes an agent surface. Your junk drawer is a fleet.
    • Agents can run locally, on-device — faster, private, and still working when the internet dies.
    • Nostalgia becomes an adoption cheat code. People will try AI on a 3DS who would never open a chatbot.

    The crossovers nobody’s talking about yet.

    Follow the pattern out and it stops looking like a gaming story:

    1. Digital twins you can walk through. A facility manager strolls a pixel version of their building, asks the assistant about the HVAC on floor three, and dispatches a real work order — all inside the game. The twin stops being a dashboard and becomes a place.
    2. NPCs that do real work. Game characters that aren’t scripted but genuinely useful — a shopkeeper that orders your groceries, a concierge that manages your calendar while you play.
    3. The Tamagotchi that runs your house. A gamified smart home for everyone intimidated by apps — kids, grandparents. You don’t configure automations; you talk to the little guy in the room.
    4. E-waste as a distribution channel. Millions of abandoned devices become agent terminals. The hardware’s already built and sitting in drawers.
    5. Gadgets as the app store for agents. “Muse gadget” is the tell in Wang’s post. The game is just a host. Any developer can build a gadget for any surface — and that marketplace is the real product.

    The honest caveats.

    The facts here are thin: one demo, one quote-post, no follow-up detail from Wang. This is analysis, not reporting — a forecast, labeled as one. The demo could stay a novelty. Platforms have died on cuter ideas.

    But here’s the thing about platform shifts: they always start looking stupid. The first iPhone apps were fart apps. The first people to put a chatbot in a game room on a dead handheld are the ones who see where the puck is going.

    The forecast.

    Chat was the interface that taught the world to talk to machines. The next interface won’t be a better chat window — it’ll be a world you step into, with an assistant standing in it, ready to act on the real one. Ruiz just showed us the rough draft, running on a toy from 2011.

    Someone’s going to build the polished version. The only question is who gets there first.


    Field notes: the first hunt

    Here’s the fun part: the hardware for this future is already sitting on Facebook Marketplace, priced like garbage. Our daily sweep turned up this morning’s haul:

    • Nintendo 3DS XL — FREE, like new, Atlanta (listing)
    • Nintendo 3DS XL — $1, good, North Lauderdale FL (listing)
    • 3 “new” 3DS XLs — $1, like new, Hopewell Junction NY (listing)
    • Pre-modded 3DS, 482 games — $20, like new, Miami (listing)
    • 3 Fire tablets as a lot — $1, listed new, Littleton CO (listing)
    • Raspberry Pi Pico 2 — FREE, like new, Lockport IL (listing) — two from one seller

    Fair warning: $1-and-free listings are often bait or mispriced. Nothing here is verified. The hunt is half the show.