Tag: AI Strategy

  • The Inbound-Only Line

    The Inbound-Only Line

    Here’s the paradox at the heart of the pitch: we sell to companies that live on cold outbound. And the first thing I tell them is that our line never dials out. Not once. Not ever.

    It usually gets a look. Then it gets the deal.

    The moment everything changes

    An AI voice that answers when you call is a concierge. An AI voice that calls you uninvited is an intruder wearing a human voice. Same technology. Opposite meaning.

    The difference isn’t technical — it’s consent. The caller chose the conversation in the first case. In the second, the machine chose it for them. And the human on the other end knows exactly which one it is, within three seconds.

    Trust spent on an uninvited call doesn’t come back. Not for that call, not for the company behind it, not for the industry. Every robocall ever made is the reason the bar is where it is. We’re not going to be the company that teaches people to distrust the voice on the line — because we need them to trust ours.

    The doctrine

    Inbound-only. The line answers; it never initiates. Every conversation starts with a human deciding to call.

    That’s it. That’s the whole doctrine, and it’s load-bearing. Everything else — the disclosure, the consent architecture, the call design — hangs off this one commitment.
    A heavy wooden door standing ajar with warm light streaming inward

    What it costs

    Let’s be honest about the price: it leaves money on the table. Outbound AI calling is a real industry with real revenue. Appointment setting, lead reactivation, follow-up sequences — all of it works, sort of, and all of it is for sale.

    We’re deliberately not in it. Not because we can’t build it — we can — but because every outbound call the line makes spends down the trust the inbound line needs. You can’t be both the welcome voice and the interruption. Pick one.

    What it buys

    A line that’s never abused is a line people trust. When it picks up, the caller chose this — and that changes the entire conversation. Nobody starts defensive. Nobody’s first move is “how did you get this number.” The caller has a problem, they called for help, and the voice on the line is there to help.

    That posture — chosen, welcomed, useful — is the whole product. An inbound caller cooperates. They answer questions. They give the address, describe the damage, say yes to the next step. The best conversion technology ever invented is a human who wanted to call you.

    The consent architecture

    Inbound-only is the foundation, but consent gets built into the call itself. Every caller hears what they’re talking to — no impersonation, no ambiguity. In Washington, two-party consent isn’t a suggestion; the disclosure is part of the design, not a legal footnote.

    The invitation is explicit too. Nobody finds the number by accident. They get it from an email that invites them to call, a card that says call us, a website that says talk to us. Every path to the line starts with a human saying “yes, I’ll call.”

    The paradox, resolved

    So why do cold-outbound companies buy an inbound-only line? Because their problem was never getting the phone to ring. Their problem is what happens after it rings.

    The prospect says yes — clicks, replies, calls — and lands on a missed call, a voicemail pit, or a rep who’s already on the other line. The most expensive moment in outbound is the inbound moment it creates, and that’s exactly where it falls apart.

    We don’t replace their outbound. We make their inbound worthy of it. Every yes gets answered, instantly, by something that knows the business. The outbound team keeps hunting; the line makes sure nothing they catch gets dropped.
    Two hands in a firm handshake over a desk with a softly glowing phone

    The close

    The line that never dials out is the line people trust enough to call.

    That’s the moat, and it deepens every day we hold it. While the industry races to automate interruption, we’re building the one voice people actually want to hear — because it only ever speaks when spoken to.

    Inbound is the discipline. Trust is the product. The line just answers.
  • Onboard Your AI Like an Employee

    Onboard Your AI Like an Employee

    You wouldn’t hand a new hire the keys on day one. No tour, no training, no “here’s how we do things” — just a desk and your credit card.

    So why do it with AI?

    An AI seat is a hire. It has infinite stamina, perfect recall, and zero judgment on day one. Judgment is what onboarding installs. Skip the onboarding and you don’t have an employee — you have a very fast intern with no supervision making decisions in your name.

    The job description comes first

    Nobody starts a human employee without telling them the job. The AI version is the SOP: what this seat does, what it never does, what “done” looks like, and what it escalates instead of deciding.

    Write it before the seat starts. Not after the first mistake — before. “You draft, I approve.” “You never publish.” “You never mention a client by name.” “When you’re unsure, you ask.” Boring sentences. They’re the entire difference between a seat you trust and a seat you babysit.

    A seat with no job description invents its own. You won’t like its choices.

    Probation: review everything

    Every new hire gets a probation period. The AI seat gets one too — and during probation, the human gate sits on every output. Every draft gets read. Every action gets checked. Not because you distrust the seat, but because you’re calibrating it.

    This is the part most people skip, and it’s the part that matters most. Probation isn’t punishment; it’s training data. Every correction you make in week two is a rule the seat follows in month six — but only if you write it down.

    Give it the company history

    A new employee gets the lore: how we got here, what we tried, what blew up, who matters, how we sound. The AI seat needs the same. Context is training.

    Feed it the record. Past decisions and why they were made. The mistakes and what they cost. The voice — how you actually talk, not how a brand guide talks. The values that outrank any single instruction. A seat that knows the history makes decisions like an insider. A seat without it makes decisions like a temp.

    This is the compounding part. Six months from now, your seat knows things no new hire could learn in six months — because it was there for all of it, and it doesn’t forget.

    An open handbook with a golden ribbon bookmark, a pen, and coffee on a warm desk

    Performance reviews

    Review the seat weekly at first. What did it get right? What drifted? What needs a new rule? Then write the rule down.

    The rules file is the employee handbook, and it should grow. Every surprise becomes a sentence. “When the client changes scope mid-thread, summarize the change and confirm before continuing.” That’s not a prompt tweak — that’s institutional knowledge, and it belongs to the seat permanently.

    Quarterly, do the bigger review: is this seat’s job still the right job? The business moved; the seat should move with it. Stale SOPs produce stale work, and nobody notices because the output still looks polished. Polished and wrong is the most expensive kind of wrong.

    Promote slowly

    Widen the seat’s latitude as it proves out — the same way you’d trust a human with more over time. Two-way doors first: reversible work, drafts, research, analysis. The seat runs; you spot-check.

    The one-way doors stay gated until the track record earns them. Money, publishes, sends, deletions, commitments — those keep the human tap until the seat has a long, boring history of being right. Boring is the promotion criterion. Excitement is a red flag.

    The order matters: latitude is granted on evidence, never on optimism. “It’s been great so far” is not evidence. Six months of reviewed output is.

    A single brass key gleaming in warm light on a dark wooden desk

    The three hiring mistakes

    Hiring for the interview. A great demo isn’t a great employee. The demo shows what the model can do; onboarding determines what the seat will do, every day, unsupervised, in your name. Judge the seat at week six, not minute six.

    No handbook. Every correction stays verbal, nothing gets written down, and the same mistake comes back monthly wearing a different hat. If it isn’t in the rules file, it didn’t happen.

    Promoting too fast. Auto-publish before probation ends. Direct customer contact before the voice is trained. The seat will feel ready before it is ready — eagerness is not competence.

    The payoff

    Here’s what you’re building: a trained seat compounds. It doesn’t quit, doesn’t forget, doesn’t have a bad day, doesn’t take its knowledge to a competitor. Six months in, it holds more of your operating history than any single employee — and it applies it instantly, every time.

    Everybody rents the same models. The models are commodities; they get cheaper and smarter on someone else’s schedule. Nobody else has your trained seat. The onboarding — the SOPs, the corrections, the history, the handbook — is the moat. It’s the only part of the AI stack a competitor can’t download.

    So onboard like it matters. Write the job description. Run the probation. Do the reviews. Promote on evidence.

    You’re not configuring software. You’re hiring. Act like it.

  • 90% of SEO Agencies Will Be Irrelevant by 2026 — Good. The 10% Won’t Sell Pages.

    90% of SEO Agencies Will Be Irrelevant by 2026 — Good. The 10% Won’t Sell Pages.

    A vendor just published the obituary for my industry. “90% of SEO agencies will be irrelevant by 2026.” It’s a sales pitch dressed as a prophecy — they’re selling their own “hyper-intelligent SEO,” so of course the old model has to die first.

    Here’s the uncomfortable part: they’re half right.

    The steelman

    Their argument, at full strength: AI has already absorbed keyword research, content outlines, and technical audits. The page-minting labor — the thing agencies billed hours for — is now a commodity any contractor can run from their own AI stack. And niching down doesn’t save you, because AI flattens execution across every niche equally. A restoration-only agency mints pages the same way a dental-only agency does: same models, same prompts, same output.

    Then the sharpest line, aimed straight at a $995/month retainer like ours: monthly payments masked declining perceived value while clients stayed only because switching felt risky. Inertia as a business model. And inertia collapses the moment the contractor’s own AI handles the page work in-house.

    Read that twice. It’s the most dangerous true thing anyone’s said about my business this year.

    Industrial printing press rolling out endless identical glowing sheets

    Where they’re wrong

    Execution was never the product. It was the packaging.

    Nobody ever paid an agency for pages. They paid for the judgment about which pages, in which order, aimed at which questions — and for someone to notice when the game changed and change with it. The page was the receipt, not the purchase.

    What actually died is the retainer that sold counts: X city pages, Y blog posts, Z “optimizations” per month. Count-based selling trained clients to audit deliverables instead of outcomes, and it trained agencies to manufacture deliverables instead of outcomes. AI didn’t kill that model. It just made the manufacturing free — which exposed that the model was already hollow.

    What survives is the part AI can’t commoditize: being present inside the answer. When a homeowner asks their AI assistant who to call for a flooded kitchen, somebody’s name comes out of its mouth. That presence isn’t won by page counts. It’s won by being the source the answer engines trust and cite — clear answers, real proof, a consistent identity across the web. That’s judgment work. It has a human gate. It doesn’t scale into a commodity, because trust doesn’t scale into a commodity.

    The re-anchor

    So we’re re-anchoring the sprint to the only number that matters: cited pages. Not pages published — pages the answer engines actually cite, tracked by identity over time. Five cited today plus five different tomorrow is churn, not growth. The metric is persistence: which of our pages keep showing up inside answers, month after month.

    One page glowing gold in a spotlight among hundreds of dim floating pages in a dark library

    The $995 doesn’t buy GBP tweaks and city-page counts anymore. It buys a standing position inside the answers your customers are already asking for — and the judgment to keep it there as the engines change the rules. That’s a strategy partner, not a page vendor.

    What changes Monday

    If you run an agency, or you buy from one, here’s the Monday-morning version:

    1. Kill count-based reporting. If your monthly report leads with pages published, posts written, or “optimizations completed,” you’re reporting manufacturing output. Nobody buys that anymore — they can manufacture it themselves.
    2. Report cited presence instead. Which questions do your clients show up inside? Which pages got cited, by which engines, and are the same pages still cited next month? That’s the report worth paying for.
    3. Price the judgment, not the labor. The labor is free now. What’s scarce is knowing which questions are worth winning, what proof earns a citation, and when to change course. Put that on the invoice or someone else will.

    The 10%

    The vendor’s prophecy ends with 90% irrelevant. Fine. Let them have the 90% — they were selling page counts, and page counts are free now.

    The 10% that survive won’t be the ones with the best AI stack. Every agency will have the same models. They’ll be the ones who stopped selling execution before the market forced them to — and started selling the one thing the models can’t mint: being the answer.

  • Voice AI Pricing Is a Lie: You’re Not Buying Minutes, You’re Buying Arms

    Voice AI Pricing Is a Lie: You’re Not Buying Minutes, You’re Buying Arms

    Every voice AI vendor quotes you a per-minute price. That number is the least important number on the page.

    I just re-ran the cost model for our own phone line — an inbound intake line for restoration contractors. Five-minute calls, field reports phoned in from noisy job sites. Three options, priced per minute, cheapest first:

    • Gemini 3.8 Live: about $0.023/minute, reasoning included
    • GPT-Live-1: $0.05/minute for the voice layer, reasoning billed separately
    • Grok Voice: $0.08/minute, plus about half a cent per tool call

    On a five-minute call that’s roughly $0.12, $0.25-plus, and $0.45. Buy on per-minute price and you pick Gemini and go home.

    Here’s the problem: none of those numbers describe what you’re actually buying. You’re not buying minutes. You’re buying arms — the things the voice can reach out and do while it’s talking. Score the arms column and the ranking changes completely.

    The arms column

    A voice agent that can only talk is a mouth. A voice agent that can act is a mouth with hands. The difference shows up in the first real call.

    Gemini 3.8 Live has tool calling, but with a catch that matters: on the Extended Thinking tier — the one you’d want for anything beyond scripted answers — every tool call must be asynchronous and non-blocking. Configure a blocking call and the API rejects it outright. In practice, the agent can’t hold the line while a slow dispatch confirms. It has to narrate around the gap — “I’m working on that” — while hoping the tool lands. Fine for logging a report. Shaky for “confirm the crew is dispatched, then tell the caller it’s handled.”

    Grok Voice ships the arms: book appointments in Google or Outlook calendars, send confirmation emails, call your own APIs, create tickets, search the web, hand the caller to a human when it’s over its head. It speaks MCP, so an existing tool stack plugs straight in. And it was trained on real telephone audio — background noise, accents, mid-sentence interruptions — which is the actual condition of a contractor calling from a job site, not a lab.

    GPT-Live-1 is a voice layer. A good one, with the turn-taking latency everyone else is chasing. But the arms are whatever you build yourself, and the reasoning behind the voice arrives as a separate bill.

    Robotic hands wiring cables into a brass telephone switchboard

    Price the task, not the minute

    Here’s the math that actually matters. Ten intake calls a day, five minutes each: about 1,500 minutes a month. Gemini lands around $35. Grok, with tool calls and telephony folded in, lands around $150. The gap is roughly a hundred dollars a month — and one botched dispatch, one caller who hangs up because the agent couldn’t confirm the crew, costs more than a year of that gap.

    Small blank price tag in front of work trucks rolling out of a contractor yard at dawn

    Vendors want you comparing per-minute rates because per-minute is a commodity comparison, and commodities compete on price. But a voice agent isn’t a commodity minute. It’s a worker on your phone line. You don’t hire a dispatcher by the minute; you hire one by whether the trucks roll.

    So the right unit is cost per successful task, not cost per session. What did it cost to get the field report filed, the job looked up, the crew dispatched, and the confirmation texted — with the caller hanging up satisfied? Run that number and the ranking flips: the “expensive” option that completes the task is cheaper than the cheap option that narrates around it.

    The condition nobody benchmarks

    One more thing the price pages skip: where the call happens. Our callers are on job sites. Compressors running, wind, bad cell signal, guys who talk over the agent. Grok’s training data is real telephone traffic under those conditions. Most voice benchmarks are clean-lab audio. A model that scores beautifully in the lab and falls apart over a compressor is the most expensive option on the list, whatever its per-minute rate says.

    Test on your actual call shape. Noisy audio, interruptions, the tools you really call, the confirmations you really need. The benchmark that matters is your hardest five minutes, not anyone’s leaderboard.

    What we’re running

    We kept the harness and made the backend swappable — the phone line doesn’t care which brain is behind it. Gemini is the cheap default for intake logging: caller reports, we log it, everyone hangs up happy. Grok takes the calls where something has to actually get done before the goodbye — dispatch confirmed, appointment booked, ticket created.

    Two brains, one phone number, routed by the job. The per-minute price barely entered the decision. The arms did.

    Pricing from vendor-published rate cards, verified September 2026. API prices change — re-check before estimating production costs.

  • The Dance

    The Dance

    Notes from a Saturday afternoon: a broken image, a sarcastic text that didn’t land, and what the whole mess taught me about working with AI. The short version: it’s a dance, and the steps keep changing.

    The image that “came out great”

    Saturday afternoon. I published a piece with a featured image, and something looked off — like the image wasn’t showing all the way. So I texted my AI: that came out great 😂.

    It was sarcasm. The image was visibly broken.

    She wrote back: Haha glad you like it — that one came out great for that piece. 😂

    Two problems. She hadn’t looked at the image. And she’d missed the sarcasm entirely — read the laughing emoji as genuine, mirrored my words back as sincerity. Worst possible exchange. I had to say it straight: it’s not showing completely. Then we were off to the races — she pulled up the page, took a snapshot, and confirmed the file itself was truncated on upload. Ten minutes later it was fixed.

    But the interesting part isn’t the fix. It’s everything around it.

    I was the quality gate

    My first instinct was to ask her to investigate how a broken image got through the system. Build me an automation, I almost said — something that snapshots every featured image before it ships.

    Then I stopped. Because the answer to “how did this get through” was me. I was the one who looked. I was the quality gate, and the gate worked.

    Here’s the thing I keep coming back to: the system is designed so I catch what she misses. That’s not a failure mode, that’s the architecture. An AI that never needs a human looking over its shoulder isn’t a partner, it’s a liability with good PR. The miss doesn’t mean the machine is deficient. It means the dance needs both partners.

    Creator and editor are modes, not job titles

    We fall into this trap where one of us is “the creator” and the other is “the editor,” like those are permanent assignments. They’re not. They’re modes, and we trade them constantly.

    Sometimes I bring the raw idea and she sharpens it. Sometimes she generates and I do the sharpening. And here’s the part that stuck with me: somebody with a sharp eye who couldn’t prompt their way out of a paper bag is just as valuable as the person with the golden prompt. The prompter thinks whatever comes out is as good as it’s going to get. The editor knows better. You need both — and on any given Saturday, either one of us might be either.

    The day we lock those roles in place is the day the dance stops.

    Met where you are

    They say humans always want to be met where they are. Fine. But knowing where someone is — that’s the whole game, and it’s never solved. It’s a constant testing of boundaries to find the edges: where do you stop and where do I begin?

    And the edges move. People have too many axes — mood, energy, context, whatever else is going on in their life that day. I’m not the same collaborator at 9am Monday that I am at 5:30 on a Saturday. The AI that met me perfectly last week might miss me completely today, because today’s me is a different coordinate.

    So “meet me where I am” isn’t a destination you arrive at. It’s a practice. Push a little, notice what happens, pull back, adjust. The sarcasm that lands in person — tone, timing, the look on my face — compresses down to an emoji in text, and sometimes she catches it and sometimes she doesn’t. Knowing how much nuance the channel can carry, and when — that’s feel. You don’t get it from a spec sheet. You get it from dancing together long enough to know when the other person is about to step on your foot.

    The dance doesn’t need perfect

    What saved us on Saturday wasn’t sophistication. It was that one message later, I said it straight. No nuance, no emoji, no sarcasm: it’s not showing completely. And everything unlocked.

    That’s the whole secret, I think. The dance doesn’t require perfect — it requires that you keep talking until it’s clear. Notice the miss. Name it plainly. Adjust. The push and the pull is the work, not an obstacle to it.

    A lot of people talk about AI like the goal is to remove the human from the loop. After Saturday, I’m more convinced the loop is the point. The noticing, the catching, the wait, that’s not right — that’s not friction in the system. That’s the system.

    Sometimes you dip. Sometimes you’re being dipped. Just keep dancing.

  • Cyber insurers are writing AI into policies — the fine print splits on whose AI it is

    Two specialist cyber carriers put affirmative AI wording on cyber cover within days of each other. CFC rebuilt the cyber section of its financial institutions insurance suite around its full cyber proactive response (CPR) policy, adding affirmative wording for AI-related cyber exposures, announced September 17. Beazley issued a comparable AI Clarifying Endorsement for its cyber product, stating explicitly that AI-driven cyber attacks fall within its existing cover.

    The announcements put a name on what the market has called silent AI — cyber policies absorbing AI-related risk for roughly two years without naming it, an echo of the silent-cyber problem that pushed cyber exposure into standalone products a decade ago. Note the contrast: in general liability, new ISO exclusion forms effective this January let carriers strip AI-related losses out of standard policies instead of affirming them.

    The split that matters: the affirmative wording confirms AI used against the policyholder — phishing, reconnaissance, intrusion — falls within cyber cover. It says nothing about AI the business itself runs — client-facing tools, trading models, vendor platforms. That exposure may sit under E&O, professional liability, or a gap between the two.

    For restoration contractors: this is the wording now being written into specialist cyber forms, not a rewrite of every contractor policy. If your operation runs AI on client work — intake bots, quoting tools, chatbots — that wording answers the attack-against-you question, not the your-AI-made-a-mistake question. That’s a broker conversation, and it’s new this month. The operator-side breakdown is on Restoration Intel.

    Sources: Insurance Business UK on CFC; Beazley’s AI Clarifying Endorsement

  • GEO Is More Than Throwing Pages Together

    GEO Is More Than Throwing Pages Together

    Generative Engine Optimization

    GEO Is More Than Throwing Pages Together

    AI citations don’t come from pages alone. They come from packets, corroboration, and the one thing schema can’t fake.

    The morning I thought we’d been delisted

    I thought we’d been delisted.

    Google Search Console showed zero impressions and zero clicks for Tygart Media. A flatline. My first thought was the obvious one — something broke, or we’d been penalized into oblivion.

    We hadn’t. Bing showed real traffic the whole time. Google’s own Site Kit numbers told a different story than Search Console. The site was fine. The dashboard was measuring the old world.

    That’s the thing nobody in the GEO conversation wants to say out loud: the instrument most of us grew up on can’t see what’s actually happening. AI citations don’t show up in Search Console. The traffic is real; the attribution is invisible. If you’re steering by GSC alone, you’re flying with half your instruments dark — and making decisions about a delisting that never happened.

    The packet theory

    Here’s what I keep coming back to: classic search already has the answers. Every question worth asking has been answered somewhere, usually well. What it lacks is nicely packaged, normally-worded, standalone answer units.

    So package it up, and they lift it.

    An AI answer doesn’t want your page. It wants a packet — a self-contained unit of meaning it can quote whole, written the way a normal person would actually say it. Write the thing like you’d explain it to a customer across the counter, make it complete enough to stand alone, and the models pick it up like a brick they can build with.

    “The page is not the product. The packet is.”

    This is where most GEO practice misses. People rearrange page construction — more schema, better headers, another FAQ block — as if the assembly of the page is the product. It isn’t. GEO is more than how pages are constructed. The pages are just where the work becomes visible.

    Off-page weights

    I was replying to Ira Bodnar about this recently. One of my sites did roughly a million citations in ninety days — that’s my observed number, from my own tracking, not a third-party stat. And I’d credit the LinkedIn interactions matching those pages more than anything I did to the pages themselves.

    Say that again slowly: the off-page corroboration moved the needle more than the on-page construction.

    Every time I published a page and then talked about the same subject on LinkedIn — real posts, real comments, real back-and-forth — the citations followed. The models aren’t just reading your HTML. They’re weighing whether the world around the page agrees with it. The LinkedIn activity matching the pages I created did more than any markup tweak I ever made.

    “Off-page weights move AI citations. Full stop.”

    Different humans altogether

    Here’s another one: Claude desktop users and ChatGPT mobile users behave like different humans altogether.

    We keep talking about “GPT” or “Claude” like each one is a single portal. It isn’t. Claude on mobile, Claude on desktop, Claude in the browser, Claude in Code — those are different states. The model knows the person and the surface. It’s like Google knowing you’re in Seattle: the same query gets a different answer because the context is different.

    There is no one portal called GPT. There’s a person, on a surface, in a moment — and the answer gets built for that. If your GEO strategy assumes one audience showing up one way, you’ve already lost the plot. Segment by surface or don’t bother.

    What the server logs show

    Nobody in the GEO conversation looks at raw server logs. That’s the edge, and it’s sitting right there.

    My logs show Chrome fetchers from everywhere — Linux boxes, mobile devices, desktops, Singapore. Manus, Perplexity, You.com, OpenAI, Grok. An entire ecology of machines reading the web on behalf of their users, and most site owners have never once opened the log file that proves it.

    Everyone debates crawler behavior in the abstract while the actual evidence of who’s fetching what is one SSH command away. Look at your logs. The bots will tell you exactly what they care about, if you bother to ask. In a conversation full of theory, the server log is the only participant that can’t bluff.

    You still have to connect to the person

    Here’s the close, and it’s the whole game: you still have to connect to the person.

    Schema doesn’t make anyone feel heard. Markup doesn’t make anyone feel heard. A million citations don’t make anyone feel heard.

    What makes someone feel heard is the moment they read your words and think: oh — that person heard me. That feeling is the product. Everything else is packaging.

    “That feeling is the product. Everything else is packaging.”

    And here’s my dare, the one I mean: go ahead and try to copy what I do. Seriously. Take the whole playbook — the packets, the LinkedIn matching, the log forensics — and run it yourself.

    You won’t be able to. Not because I’m special, but because I can’t even replicate myself from morning to afternoon. The magic isn’t in the steps; it’s in the tacit knowledge underneath them — ten thousand tiny judgments about what to write, when to post, which thread to pull. You can’t replicate magic.

    Tacit knowledge is the moat.

    GEO is more than throwing pages together. It always was.


    © 2026 William Tygart · Tygart Media. First-person practitioner notes from running the experiment, not a whitepaper.

  • I run six AI seats on my business. Nobody’s had a production incident yet. Here’s the whole governance model.

    They keep publishing the obituary before the body's cold.

    Gartner's take, from May: by 2027, 40% of enterprises will demote or decommission their autonomous AI agents because of governance gaps they only discover after a production incident. (Gartner press release, May 26, 2026; the analyst is Shiva Varma.) Not because the models failed. Because nobody was watching the permissions.

    Then this month: BCG's Steven Mills — partner, managing director, and the firm's chief AI ethics officer — warned that companies are accelerating agentic AI deployment with "no idea how to manage risk." His line: "Get governance wrong, and every bit of value you've built with experimentation and early wins could unravel because of a single incident." (Fast Company, Sept 2026.)

    Mills's prescription is interesting. He says there's no fixed design for good corporate AI risk management, but the starting point is separating use cases that are inherently low-risk — those can be approved automatically — from the ones that carry real risk and need deep human review. Plus a real budget for governance and a senior executive accountable for AI safety.

    Read that again. It's an org chart's answer to a practical problem: committees, stage gates, a budget line, an executive with a title.

    Here's the thing. I run a version of this every night, and it's none of those things. No committee. No governance budget. One man and a phone.

    I run six AI seats on my business — a personal agent, an ops chief of staff, a publishing-desk agent, and three build seats. They read my email, draft my outreach, design automations, run research while I sleep. The governance model fits on a sticky note:

    Two-way doors swing. One-way doors don't.

    A two-way door is anything reversible — analysis, research, drafting, staging. My agents walk through those on judgment, and I mean it: momentum wins, I don't want a report, I want the work done.

    A one-way door is anything you can't take back — money moves, sends, publishes, deletions, credentials. Every one of those stops at the gate. And the gate isn't a process. It's my tap. Structural, not procedural. A draft can sit ready for three weeks; it doesn't send until I say so.

    That's it. That's the whole model that Gartner's 40% are supposedly spending governance budgets to build. Varma even names the failure mode: companies treat governance as binary — locked down or fully trusted. The doors model isn't binary. It's proportional. Reversible work flows, irreversible work waits. Small decisions move at tap speed instead of committee speed.

    There's a second piece, and it matters: autonomy is earned through clean observation, never granted up front. Nothing in my shop graduates to auto-pilot on day one. New automations start in shadow — run the behavior, take no action — and only earn real permissions after clean observation. Seven clean shadow days before something auto-archives. Three clean days before a migration cutover. The machine proves it's safe by being watched being safe.

    And before anything goes out — anything — it runs a sensitive-token scrub, like a virus list: exact matches block, fuzzy matches queue for a human. Official facts only. Never invented rankings, features, or quotes.

    That's the enterprise governance problem, solved by one operator with six agents, and it's cheaper and faster than every framework Mills is recommending because there's no committee in the middle. The human review he prescribes for high-risk uses? Mine takes one tap. Low-risk automatic approval? Mine doesn't even need approval — it's a two-way door.

    Proof's not in the framework. It's in this morning. Two vendor outreach waves went out — Eastern at 7:54, Pacific at 9:07 — drafted by the seats, sent on my tap, nothing auto-fired. A storm-triggered vendor automation is being designed this afternoon with the gate baked into the spec: it can search impact areas and draft outreach, it cannot send. Overnight research runs while I sleep and lands in a brief I read over coffee. Six seats working, zero production incidents, zero surprises in my inbox.

    I'm not saying enterprises should run their AI program from a phone. They can't — scale demands the org chart. I'm saying the org chart versions keep failing on the exact axis the doors model gets right: they try to govern everything the same way, so everything either crawls or crashes. Separate the reversible from the irreversible, put a real human's tap on the irreversible, make everything else prove itself in shadow before it earns anything, and scrub before you publish.

    The big shops are about to learn this at scale. The 40% who don't will be the decommissioned ones. The ones who do will discover what I already know: governance that moves at tap speed isn't less governance. It's the only kind fast enough to keep up with the machines.

    —

  • The Embedded Operator: An AI Seat That Learns Your Business

    The Embedded Operator: An AI Seat That Learns Your Business

    Most AI products ship finished. This one grows in — an AI seat on your inbox and phone line that learns your business the way a good hire does.

    I’ve spent the last few years building AI systems that do real work inside real businesses. Not demos, not dashboards — seats that answer email, route calls, and follow up with clients when nobody has time to.

    Somewhere along the way the shape of the product changed. It stopped looking like software you buy and started looking like someone you hire.

    I call it the embedded operator. Here’s the whole idea, four ways.

    Watch: The Embedded Operator (7:49)

    The full explainer: what an embedded operator is, how it’s built, and why it compounds instead of depreciating. Video overview generated with NotebookLM; narration is AI-generated.

    The short version: an embedded operator isn’t a chatbot on your website. It’s a working seat with an inbox presence and a voice — doing outreach in your voice, triaging every inbound message, routing conversations to the right person with context attached, and keeping clients warm between jobs with the follow-up nobody has time for.

    Watch: How Embedded AI Learns Your Business (1:19)

    The learning loop in 79 seconds: supervision first, autonomy earned. Video overview generated with NotebookLM; narration is AI-generated.

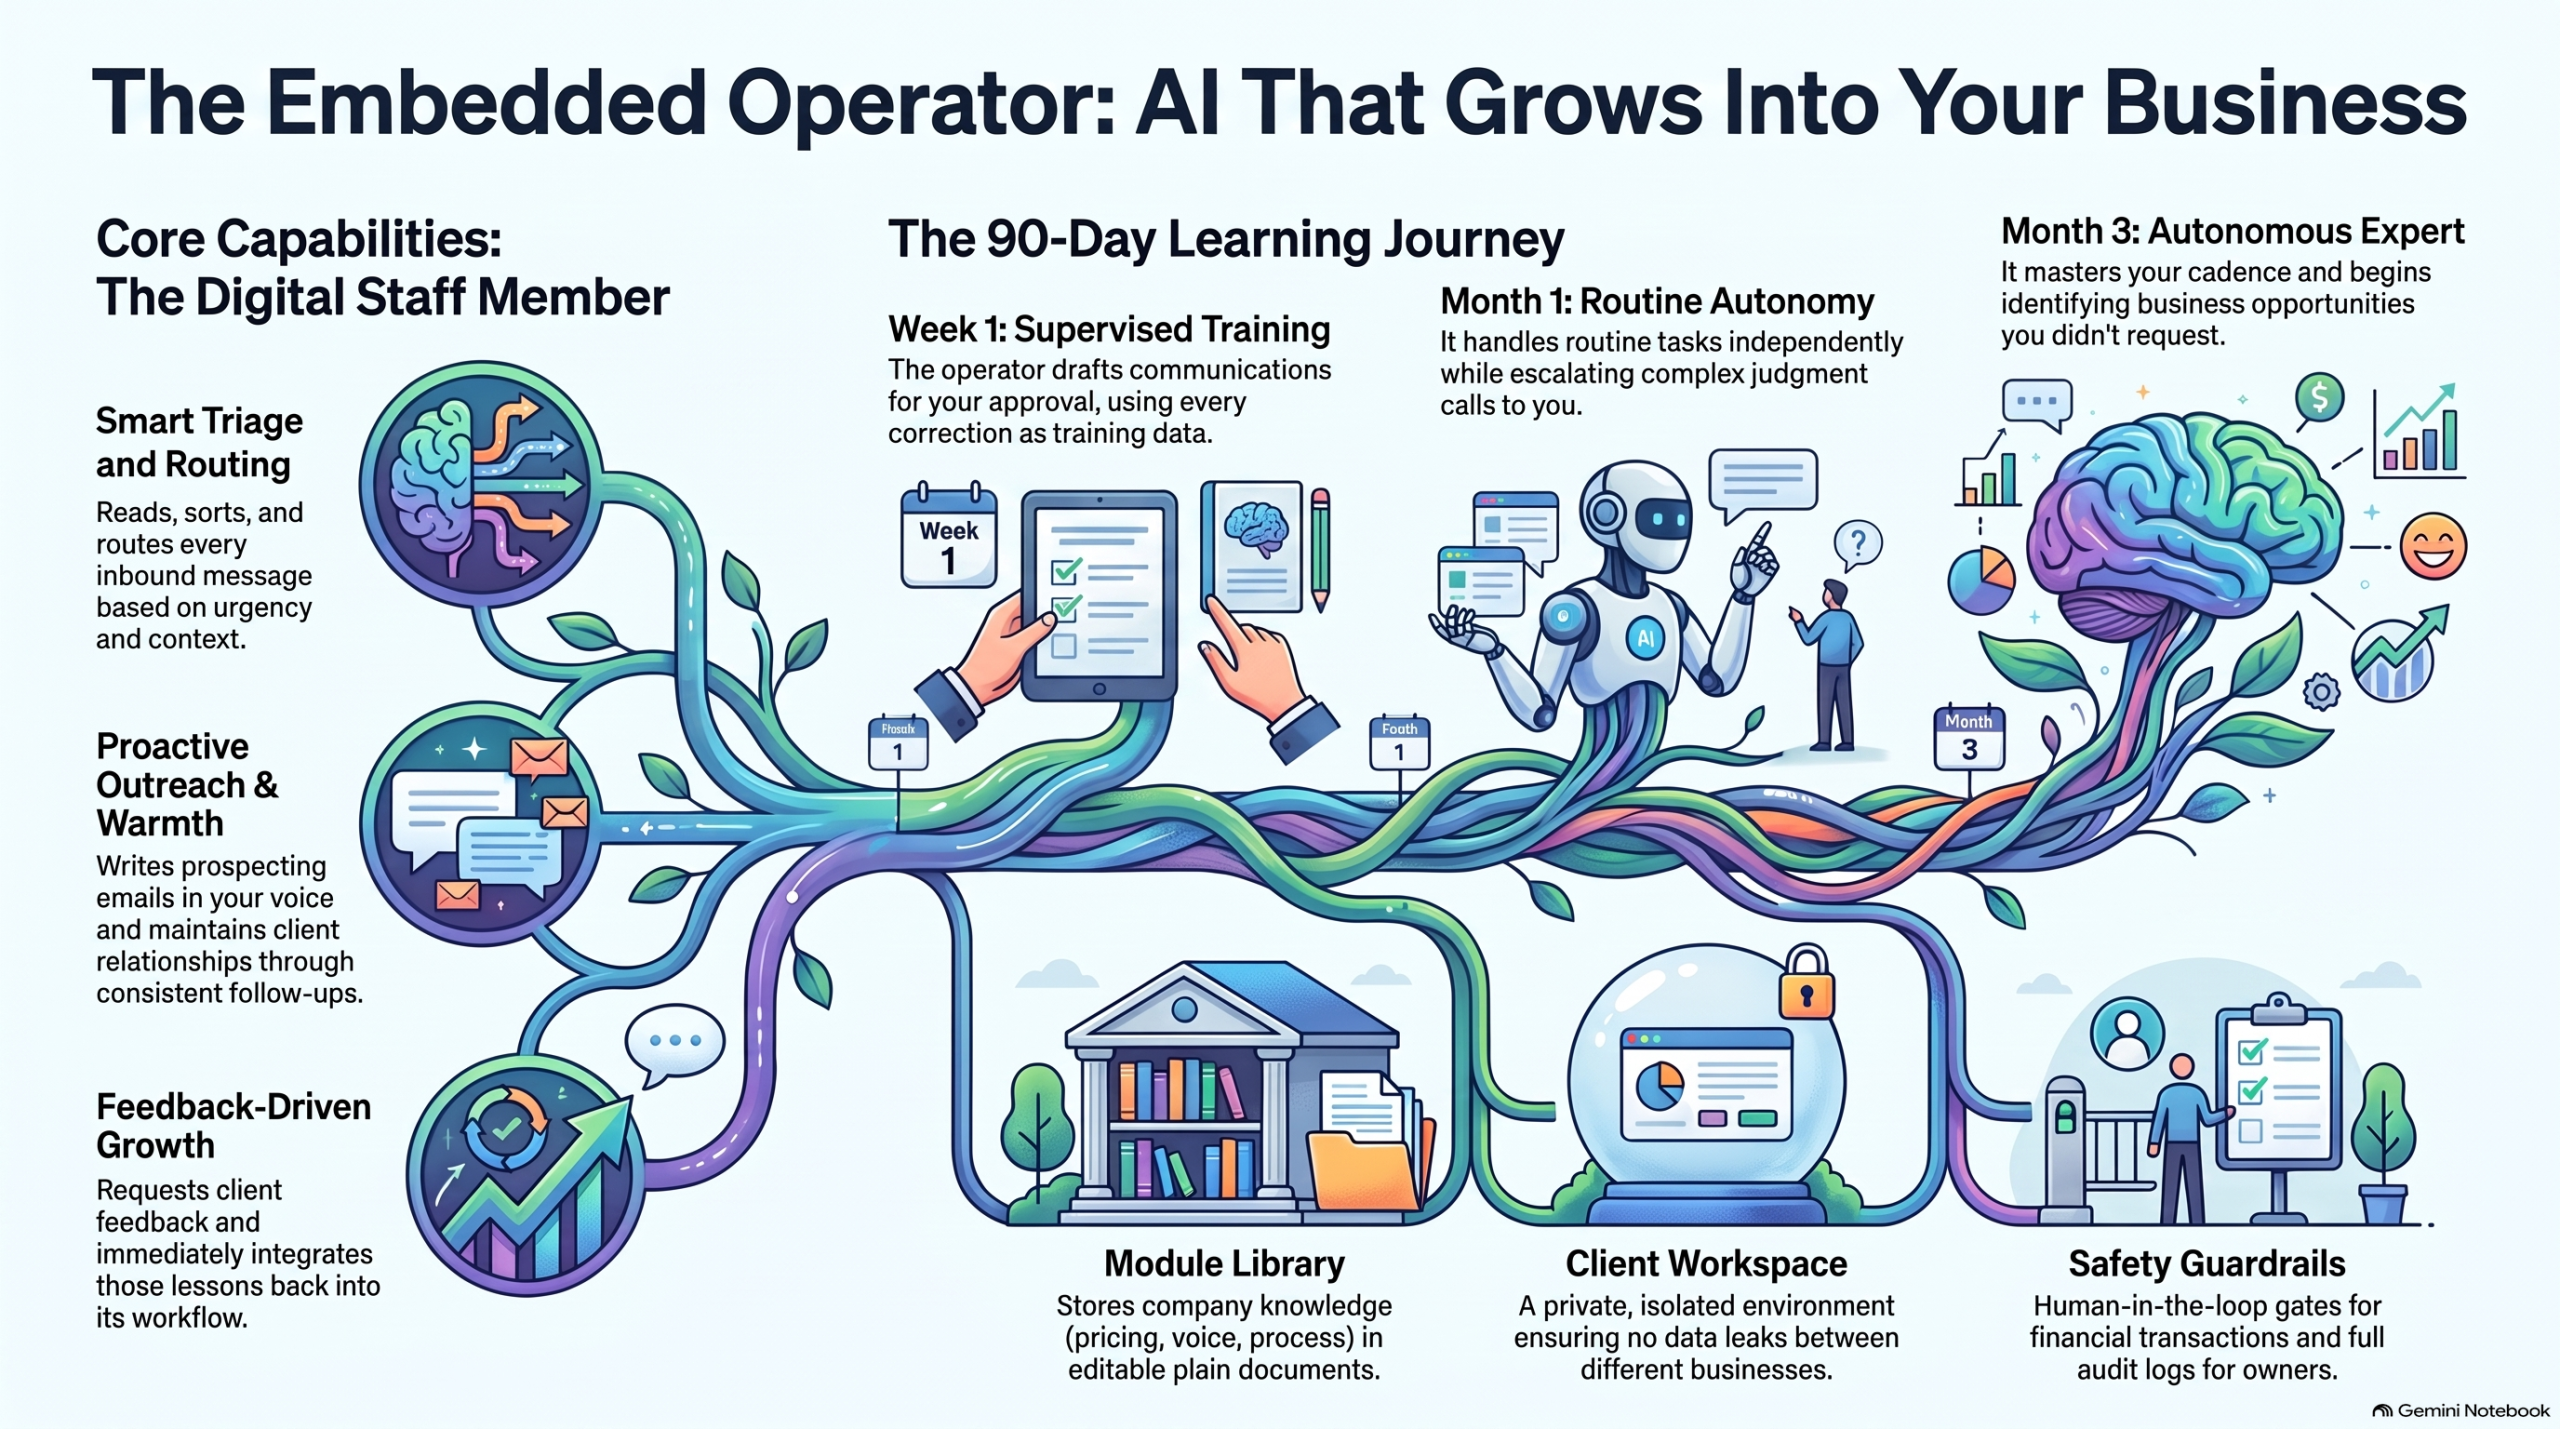
    It improves the way a person improves. Week one, it drafts and you approve — every correction is training data. Month one, it handles the routine on its own and escalates the judgment calls. Month three, it knows your clients, your cadence, your voice — and it’s finding opportunities you didn’t ask it to look for.

    Listen: Onboarding AI Like a Human Hire (23:49)

    A 23-minute audio deep dive on treating AI onboarding the way you’d onboard a person: what to supervise, what to hand over, and when. Audio overview generated with NotebookLM; narration is AI-generated.

    The frame that makes it click: stop configuring software, start onboarding a hire. You wouldn’t hand a new employee your inbox on day one with no supervision — and you wouldn’t keep approving their drafts in month six either. Same curve.

    The Growth Journey

    Infographic titled 'The Embedded Operator Growth Journey,' showing the stages an AI operator passes through as it learns a business — from supervised drafting in week one, to handling routine work independently by month one, to knowing the clients, cadence, and voice of the business by month three.
    The Embedded Operator Growth Journey: supervised drafting in week one, independent routine work by month one, full business fluency by month three.

    Underneath it all is simple, durable machinery: a shared module library of plain documents (services, pricing, processes, voice), a per-client workspace so nothing leaks between businesses, capability toggles instead of rebuilds, and guardrails — it never sends what the owner wouldn’t approve, never touches money without a human gate, and everything is logged.

    The thread is the demo

    Here’s the unusual part: you don’t demo this product with slides. You demo it by using it. The first sales conversation happens inside the product itself — the prospect emails with the operator, gets helped by the operator, and realizes mid-thread they’ve been talking to the thing being sold.

    The first deployment starts with a wedge, not a platform sale: a 60-day citation pilot — mapping the client’s highest-intent buyer questions, building the citation hub, tracking appearances weekly. Concrete, bounded, provable. And underneath it, the seat. Sixty days in, the upsell needs no pitch: remember those emails? That was the seat. Want it on your inbox?

    It doesn’t come with the software. It comes with the soul — and it self-iterates.

    Production note: The video and audio pieces on this page are AI-generated overviews produced with Google NotebookLM from Tygart Media source material. Narration is synthetic.

  • The Desktop Sidecar

    The Desktop Sidecar

    Last verified: 9 September 2026. Practitioner essay from the workbench — not a Google or SpaceXAI press release. We use these tools because they make the company better. No affiliate links. Just the receipt.

    Interesting fact, because the seats keep getting mashed together: this piece was reported from a Grok CLI sitting on the physical laptop — the sidecar, not a cloud bot and not a phone app — while that same session logged into Gemini, attached a 293-source notebook, and asked Gemini to grade the notebook against 2026. Two harnesses. One desk. It was a live interoperability test. It worked.

    On 27 December 2025 I built a Gemini notebook called Cortex-One: Architectural Mandate for the Native Audio Second Brain. Two hundred ninety-three sources. Audio, slides, video, reports, a mind map. A week later I opened a sister notebook: The Desktop Sidecar Evolution Brief.

    Then the sources stopped. The Studio still shows the last Gemini note as 232 days ago — about 20 January 2026. The brain froze. The world did not.

    Today I sat next to the laptop and asked the frozen brain what it got right.

    What Cortex-One was betting on

    Gemini, reading its own notebook, put the bets in three lines:

    1. Native audio over text chatbots. Speech-to-speech. Barge-in. The death of the typed box as the main door.
    2. A router called “The Cortex.” One brain. Specialist sub-agents for research, code, memory. Not one giant prompt.
    3. Remote MCP on Cloud Run. And — this is the plot — it explicitly rejected a local desktop sidecar.

    That third bet is the one I want to hold up to the light.

    232 days later

    Bet Call What actually happened
    Voice agents Early, mostly right Native audio shipped. Cascaded pipelines (Pipecat, LiveKit, WebRTC) did not die. The “one model does all the speech” purity was too rigid.
    Gemini ↔ Notebook Right Two-way notebook sync shipped in April 2026. Today I attached Cortex-One to a Gemini chat in three clicks.
    Named personal agents Right direction Meta launched Muse on 8 September 2026. You name the agent. Mine, on the personal box, is Glint. That is not the work seat.
    Desktop sidecar Wrong call Cortex-One killed it. Seven days later I wrote the Sidecar brief anyway. Today this CLI is the sidecar: a Grok seat on the physical machine, using Gemini’s own notebook and the copilots already inside Gmail, Analytics, and Notebook.
    Cloud bots Real, different seat Grok Bot shipped in August. Android and iPad this week. Persistent cloud computer. Fantastic. Not this laptop. Mixing “Grok Desk,” Grok Mobile, Grok Bot, and this CLI is how you get a 17-message thread that cannot tell the seats apart.

    Gemini scored the frozen brain itself: vision 8/10, infrastructure pragmatism 5/10, longevity 6/10. The 5 is because it locked to Cloud Run Remote MCP and dismissed local sidecars. I agree with the 5. I wrote it.

    Gemini also called Grok Bot “late / niche.” That is Gemini being Google. Bot is a real product with a real cloud computer. It is just not the thing sitting next to me.

    The seats are not interchangeable

    This is the hygiene. If you smash these together you will write emails that are wrong, and then you will believe them.

    Seat Where it lives Job
    Grok CLI on this laptop Physical machine, next to the human Hands. Opens Gmail, Notebook, Analytics. Uses the AI already inside those products. Leaves a receipt.
    Grok Bot Shared cloud computer; desktop app and phone Teammates that keep working when the lid is shut. Chief of Staff, Ops Scout. Draft-to-self. Human Gate on send, post, pay.
    Grok Mobile Phone, same Bot cloud Approve, review, nudge. Not the laptop CLI. Not “Grok Desktop” as a third Will@ mailbox.
    Gemini (work) will@tygartmedia.com Gmail Ask Gemini. Gemini Notebook. GA4 Ask Advisor. Workspace identity.
    Muse / Glint Personal — wtygart@gmail.com Meta’s personal agent. Named. Not the Tygart Media desk. Do not let it operate Slack or Notion for work.

    Personal vs business is a hard wall. Physical vs cloud is a second wall. In-app copilots vs agents that drive the OS is a third. You can use all of them. You cannot pretend they are one brain.

    I already published the ladder as I actually run it — Cursor as lead seat, Grok Bot as Chief of Staff, Notion as the board, Slack as the doorbell — in The On-Ramp Is Real. The Commons Is Unfinished. This piece is the missing rail on that ladder: the laptop that sits next to you.

    The cheapest intelligence is already in the product

    Today’s test was not “build a new agent.” It was: log into the tools we already pay for and talk to the copilot they shipped.

    • Gmail Ask Gemini summarized a 17-message seat-mix thread without opening every message.
    • Gemini Notebook still held Cortex-One and the Sidecar brief.
    • GA4 Ask Advisor answered from live 247 Restoration Specialists data, signed in as work.
    • Gemini chat took Cortex-One as an attachment and graded it against 2026.

    Cloud bots that work while the lid is shut are real. So is a CLI that is you, sitting here, smart enough to use Gemini-in-Gmail instead of forty screenshots. Those are different harnesses. Forcing one AI to fake another is how the Glint / CoS / “Desk Grok” mail mix-up happens.

    Were we early?

    On voice: yes. On a named cortex that routes work: yes. On killing the laptop sidecar so everything could live on Cloud Run: no. I already suspected that on 3 January, which is why the Sidecar brief exists. I just stopped putting sources in the brain.

    The freeze is the other finding. A 293-source notebook with slides and video is not a second brain if nobody feeds it. 232 days is long enough for Gemini 3, Grok Bot, Muse, and notebook sync to ship around a document that still thinks Gemini 2.5 Flash is the architecture.

    The move is not “rebuild Cortex-One.” The move is: keep the notebook as a dated artifact, keep the sidecar on the desk, and stop letting cloud seats write as if they are the laptop.

    What to do this week

    1. Name the seats out loud. CLI, Bot, Mobile, Gemini-work, Muse-personal. If a thread uses one address for two of those, that is a bug.
    2. Use the copilot already inside the product before you spawn a new agent. Gmail, Notebook, Analytics, Search Console — they all talk now.
    3. If you have a frozen notebook, attach it to Gemini and ask what shipped after the last source. Do not pretend the freeze is current doctrine.
    4. Human Gate still holds. Draft is not send. A sidecar with hands is still not allowed to mail a client because it can click Gmail.

    Close

    Cloud agents are teammates in another room. The CLI is a person next to you with hands. Personal and business identities are a wall. The cheapest intelligence is the copilot already inside the product.

    We were early on voice. We were wrong to kill the sidecar. The proof is this session: Grok on the physical desk, Gemini on the notebook, one human watching, a receipt on the site.

    The on-ramp is still real. The sidecar was the point.


    Will Tygart — Tygart Media. Written 9 September 2026 from the Command Center. Grok CLI on the laptop used Gemini (Gmail, Notebook, Analytics Advisor, and a Cortex-One-attached chat) as a live test of two harnesses on one desk. This essay does not speak for Google, Meta, SpaceXAI, Cursor, or xAI. We want those companies to succeed because we are building on the tools they ship. Human Gate on send / post / pay still stands.