Tag: Local AI

  • Your Next Assistant Doesn’t Live in a Chat Window

    Your Next Assistant Doesn’t Live in a Chat Window

    Garage Sale Gadgets · Episode 0

    The series where cheap, forgotten hardware becomes somebody’s AI assistant. Your junk drawer is a fleet.

    A pink Nintendo DS Lite running a pixel-art home assistant called Dash
    Concept art: a 2011 handheld running a real assistant. AI-generated illustration.

    On October 3, a developer named David Ruiz posted a 19-second video that made Alexandr Wang swear. “no fucking way,” Wang quote-posted. “muse gadget on Nintendo 3DS.”

    What Ruiz built: a homebrew game running on actual Nintendo 3DS hardware — a 2011 handheld — where you walk around a pixel-art version of your house and talk to an in-game assistant called Dash. In the clip, he asks Dash if the 3D printer is done. Dash thinks, then answers. The game isn’t pretending to control his smart home. It actually does.

    Your first reaction might be that this is stupid. A game on a fifteen-year-old handheld to check a 3D printer? Fair. Mine was too, for about ten seconds.

    Then the pattern lands, and it’s big: an AI agent, embodied in a game world, running on weak old hardware, acting on the real world. The demo is a toy. The pattern is a platform shift.

    Chat won the first round. Worlds win the next one.

    Every AI assistant you’ve ever used lives in a rectangle with a text box. That was the right interface for 2023. But watch what Ruiz did: he didn’t build a better chatbot. He put the assistant inside a world — a little room with wooden floors, a kitchen, a dog — and gave you a character to talk to instead of a prompt box.

    The room in the game mirrors his real home. That’s the tell. The game world is a digital twin, and the assistant is its voice. You don’t open an app and navigate menus; you walk up to the little guy and ask.

    If it runs on a 3DS, it runs on everything.

    This is the part Wang reacted to, and it’s the most underrated part. The Nintendo 3DS is ancient, underpowered hardware. If a Muse gadget runs there, the hardware constraint is gone. That means:

    • Every old tablet, e-ink frame, car dashboard, and kiosk becomes an agent surface. Your junk drawer is a fleet.
    • Agents can run locally, on-device — faster, private, and still working when the internet dies.
    • Nostalgia becomes an adoption cheat code. People will try AI on a 3DS who would never open a chatbot.

    The crossovers nobody’s talking about yet.

    Follow the pattern out and it stops looking like a gaming story:

    1. Digital twins you can walk through. A facility manager strolls a pixel version of their building, asks the assistant about the HVAC on floor three, and dispatches a real work order — all inside the game. The twin stops being a dashboard and becomes a place.
    2. NPCs that do real work. Game characters that aren’t scripted but genuinely useful — a shopkeeper that orders your groceries, a concierge that manages your calendar while you play.
    3. The Tamagotchi that runs your house. A gamified smart home for everyone intimidated by apps — kids, grandparents. You don’t configure automations; you talk to the little guy in the room.
    4. E-waste as a distribution channel. Millions of abandoned devices become agent terminals. The hardware’s already built and sitting in drawers.
    5. Gadgets as the app store for agents. “Muse gadget” is the tell in Wang’s post. The game is just a host. Any developer can build a gadget for any surface — and that marketplace is the real product.

    The honest caveats.

    The facts here are thin: one demo, one quote-post, no follow-up detail from Wang. This is analysis, not reporting — a forecast, labeled as one. The demo could stay a novelty. Platforms have died on cuter ideas.

    But here’s the thing about platform shifts: they always start looking stupid. The first iPhone apps were fart apps. The first people to put a chatbot in a game room on a dead handheld are the ones who see where the puck is going.

    The forecast.

    Chat was the interface that taught the world to talk to machines. The next interface won’t be a better chat window — it’ll be a world you step into, with an assistant standing in it, ready to act on the real one. Ruiz just showed us the rough draft, running on a toy from 2011.

    Someone’s going to build the polished version. The only question is who gets there first.


    Field notes: the first hunt

    Here’s the fun part: the hardware for this future is already sitting on Facebook Marketplace, priced like garbage. Our daily sweep turned up this morning’s haul:

    • Nintendo 3DS XL — FREE, like new, Atlanta (listing)
    • Nintendo 3DS XL — $1, good, North Lauderdale FL (listing)
    • 3 “new” 3DS XLs — $1, like new, Hopewell Junction NY (listing)
    • Pre-modded 3DS, 482 games — $20, like new, Miami (listing)
    • 3 Fire tablets as a lot — $1, listed new, Littleton CO (listing)
    • Raspberry Pi Pico 2 — FREE, like new, Lockport IL (listing) — two from one seller

    Fair warning: $1-and-free listings are often bait or mispriced. Nothing here is verified. The hunt is half the show.

  • Your Laptop Is Already an AI PC: The Local AI Stack Guide

    Your Laptop Is Already an AI PC: The Local AI Stack Guide

    Last verified: September 2026. The AI-laptop wave is here — Copilot+ PCs, NPUs, “AI-ready” stickers on everything. Here’s the part the marketing skips: the laptop you already own can run a serious local AI stack today. No new hardware, no cloud bill, no subscription treadmill. This guide is the proof, the money math, and the build instructions — nine deep dives, one hub.

    The proof: a $400 laptop that rivals a Copilot+ PC

    Start here. A $400 budget laptop, no NPU, turned into a private AI operator rig that rivals a Copilot+ PC — command by command. This is the article that makes the whole premise undeniable: the hardware barrier is mostly marketing.

    → Local AI Without NPU: Turn a $400 Laptop Into an AI PC — the full command-by-command build.

    Will’s note: Ollama can also offload part of the compute to your GPU through its settings — we tried that route. We never really stuck with local, honestly; we like our CLIs backed by cloud compute. But if you want the full local path, the GPU setting is worth knowing about.

    The money: replacing a $12K/month tool budget

    The stack isn’t just a hobby project — it replaced $12,000 a month in expensive SaaS tools. Open-source models, Python, and PowerShell automation doing the work the subscriptions used to do. Read this one with your accounting hat on.

    → Local AI Stack: How We Replaced a $12K/Mo Tool Budget — what got replaced, with what, and how.

    Your files, answerable: 468 documents, one laptop

    Using Ollama’s nomic-embed-text model and ChromaDB, a local RAG system was built that indexes every skill file, session transcript, and project doc on the machine — 468 files — and answers natural-language questions about the operation. Your laptop becomes the expert on your own business.

    → I Indexed 468 Files Into a Local Vector Database. Now My Laptop Answers Questions About My Business — the build: embeddings, database, queries.

    The business version: index, query with Claude, measure ROI

    The production-grade take: indexing business documents into a local vector database and querying them with Claude — architecture, code, production lessons, and real ROI numbers. This is the one to hand your skeptical partner.

    → How to Index Business Files Into a Local Vector Database (2026) — architecture, code, and the ROI math.

    The agent army: zero cloud cost

    Enterprise AI costs are spiraling — GPT-4 API calls at scale run hundreds or thousands of dollars a month. The alternative: a free agent army built with Ollama and Claude. Zero cloud cost. This is the flagship piece of the stack.

    → How We Built a Free AI Agent Army With Ollama and Claude — the zero-cloud-cost AI stack.

    Triage agents: routing work at scale

    AI triage agents eliminate manual bottlenecks by automating task routing, intent detection, and urgency scoring across business lines. Not a chatbot — infrastructure that decides where work goes.

    → AI Triage Agents: How to Automate Task Routing at Scale — routing, intent detection, urgency scoring.

    The $0 marketing stack

    An enterprise marketing stack for $0: open-source AI, free API tiers, and Google Cloud credits. Exactly what’s used, spelled out.

    → The $0 Marketing Stack: Open Source AI, Free APIs, and Cloud Credits — the full stack, item by item.

    Scheduled tasks: automating the 40-hour week

    Scheduled tasks, webhooks, and AI automating manual work — the goal is reclaiming the 40-hour work week for strategic growth instead of busywork. This is where the stack stops being a demo and starts being operations.

    → Scheduled Tasks: How to Automate Your 40-Hour Work Week — tasks, webhooks, and AI automation patterns.

    The vision: the AI-native business operating system

    The end state: an AI-native business operating system that replaces static workflows with autonomous infrastructure, scaling the company with programmatic governance. Everything above is a component of this.

    → AI-Native Business Operating System: Autonomous Scaling — the architecture of the whole thing.


    Nine deep dives, one hub. The $400 laptop proves it, the $12K/mo replacement pays for it, the 468-file index and the agent army run on it — and the AI-native OS is where it all leads.

  • The Desktop Sidecar

    The Desktop Sidecar

    Last verified: 9 September 2026. Practitioner essay from the workbench — not a Google or SpaceXAI press release. We use these tools because they make the company better. No affiliate links. Just the receipt.

    Interesting fact, because the seats keep getting mashed together: this piece was reported from a Grok CLI sitting on the physical laptop — the sidecar, not a cloud bot and not a phone app — while that same session logged into Gemini, attached a 293-source notebook, and asked Gemini to grade the notebook against 2026. Two harnesses. One desk. It was a live interoperability test. It worked.

    On 27 December 2025 I built a Gemini notebook called Cortex-One: Architectural Mandate for the Native Audio Second Brain. Two hundred ninety-three sources. Audio, slides, video, reports, a mind map. A week later I opened a sister notebook: The Desktop Sidecar Evolution Brief.

    Then the sources stopped. The Studio still shows the last Gemini note as 232 days ago — about 20 January 2026. The brain froze. The world did not.

    Today I sat next to the laptop and asked the frozen brain what it got right.

    What Cortex-One was betting on

    Gemini, reading its own notebook, put the bets in three lines:

    1. Native audio over text chatbots. Speech-to-speech. Barge-in. The death of the typed box as the main door.
    2. A router called “The Cortex.” One brain. Specialist sub-agents for research, code, memory. Not one giant prompt.
    3. Remote MCP on Cloud Run. And — this is the plot — it explicitly rejected a local desktop sidecar.

    That third bet is the one I want to hold up to the light.

    232 days later

    Bet Call What actually happened
    Voice agents Early, mostly right Native audio shipped. Cascaded pipelines (Pipecat, LiveKit, WebRTC) did not die. The “one model does all the speech” purity was too rigid.
    Gemini ↔ Notebook Right Two-way notebook sync shipped in April 2026. Today I attached Cortex-One to a Gemini chat in three clicks.
    Named personal agents Right direction Meta launched Muse on 8 September 2026. You name the agent. Mine, on the personal box, is Glint. That is not the work seat.
    Desktop sidecar Wrong call Cortex-One killed it. Seven days later I wrote the Sidecar brief anyway. Today this CLI is the sidecar: a Grok seat on the physical machine, using Gemini’s own notebook and the copilots already inside Gmail, Analytics, and Notebook.
    Cloud bots Real, different seat Grok Bot shipped in August. Android and iPad this week. Persistent cloud computer. Fantastic. Not this laptop. Mixing “Grok Desk,” Grok Mobile, Grok Bot, and this CLI is how you get a 17-message thread that cannot tell the seats apart.

    Gemini scored the frozen brain itself: vision 8/10, infrastructure pragmatism 5/10, longevity 6/10. The 5 is because it locked to Cloud Run Remote MCP and dismissed local sidecars. I agree with the 5. I wrote it.

    Gemini also called Grok Bot “late / niche.” That is Gemini being Google. Bot is a real product with a real cloud computer. It is just not the thing sitting next to me.

    The seats are not interchangeable

    This is the hygiene. If you smash these together you will write emails that are wrong, and then you will believe them.

    Seat Where it lives Job
    Grok CLI on this laptop Physical machine, next to the human Hands. Opens Gmail, Notebook, Analytics. Uses the AI already inside those products. Leaves a receipt.
    Grok Bot Shared cloud computer; desktop app and phone Teammates that keep working when the lid is shut. Chief of Staff, Ops Scout. Draft-to-self. Human Gate on send, post, pay.
    Grok Mobile Phone, same Bot cloud Approve, review, nudge. Not the laptop CLI. Not “Grok Desktop” as a third Will@ mailbox.
    Gemini (work) will@tygartmedia.com Gmail Ask Gemini. Gemini Notebook. GA4 Ask Advisor. Workspace identity.
    Muse / Glint Personal — wtygart@gmail.com Meta’s personal agent. Named. Not the Tygart Media desk. Do not let it operate Slack or Notion for work.

    Personal vs business is a hard wall. Physical vs cloud is a second wall. In-app copilots vs agents that drive the OS is a third. You can use all of them. You cannot pretend they are one brain.

    I already published the ladder as I actually run it — Cursor as lead seat, Grok Bot as Chief of Staff, Notion as the board, Slack as the doorbell — in The On-Ramp Is Real. The Commons Is Unfinished. This piece is the missing rail on that ladder: the laptop that sits next to you.

    The cheapest intelligence is already in the product

    Today’s test was not “build a new agent.” It was: log into the tools we already pay for and talk to the copilot they shipped.

    • Gmail Ask Gemini summarized a 17-message seat-mix thread without opening every message.
    • Gemini Notebook still held Cortex-One and the Sidecar brief.
    • GA4 Ask Advisor answered from live 247 Restoration Specialists data, signed in as work.
    • Gemini chat took Cortex-One as an attachment and graded it against 2026.

    Cloud bots that work while the lid is shut are real. So is a CLI that is you, sitting here, smart enough to use Gemini-in-Gmail instead of forty screenshots. Those are different harnesses. Forcing one AI to fake another is how the Glint / CoS / “Desk Grok” mail mix-up happens.

    Were we early?

    On voice: yes. On a named cortex that routes work: yes. On killing the laptop sidecar so everything could live on Cloud Run: no. I already suspected that on 3 January, which is why the Sidecar brief exists. I just stopped putting sources in the brain.

    The freeze is the other finding. A 293-source notebook with slides and video is not a second brain if nobody feeds it. 232 days is long enough for Gemini 3, Grok Bot, Muse, and notebook sync to ship around a document that still thinks Gemini 2.5 Flash is the architecture.

    The move is not “rebuild Cortex-One.” The move is: keep the notebook as a dated artifact, keep the sidecar on the desk, and stop letting cloud seats write as if they are the laptop.

    What to do this week

    1. Name the seats out loud. CLI, Bot, Mobile, Gemini-work, Muse-personal. If a thread uses one address for two of those, that is a bug.
    2. Use the copilot already inside the product before you spawn a new agent. Gmail, Notebook, Analytics, Search Console — they all talk now.
    3. If you have a frozen notebook, attach it to Gemini and ask what shipped after the last source. Do not pretend the freeze is current doctrine.
    4. Human Gate still holds. Draft is not send. A sidecar with hands is still not allowed to mail a client because it can click Gmail.

    Close

    Cloud agents are teammates in another room. The CLI is a person next to you with hands. Personal and business identities are a wall. The cheapest intelligence is the copilot already inside the product.

    We were early on voice. We were wrong to kill the sidecar. The proof is this session: Grok on the physical desk, Gemini on the notebook, one human watching, a receipt on the site.

    The on-ramp is still real. The sidecar was the point.


    Will Tygart — Tygart Media. Written 9 September 2026 from the Command Center. Grok CLI on the laptop used Gemini (Gmail, Notebook, Analytics Advisor, and a Cortex-One-attached chat) as a live test of two harnesses on one desk. This essay does not speak for Google, Meta, SpaceXAI, Cursor, or xAI. We want those companies to succeed because we are building on the tools they ship. Human Gate on send / post / pay still stands.

  • Local AI Without NPU: Turn a $400 Laptop Into an AI PC

    Local AI Without NPU: Turn a $400 Laptop Into an AI PC

    All fall, Microsoft has been selling one idea: the future is the AI PC — a Copilot+ machine with a dedicated neural chip (an NPU), Recall, Click to Do, a thousand dollars and up, and your old laptop need not apply.

    I had a $400 budget laptop on my desk — an AMD Ryzen 5 7520U, 16 GB of RAM, no NPU — and a hunch that the whole framing was backwards. The AI-first laptop was never about the chip. It’s about architecture.

    A few hours later, that $400 laptop had a private AI brain, voice control, and a control panel I run from my phone. On the things that actually matter for operating a machine, it does more than the Copilot+ PC it’s supposedly too cheap to be. Here’s the exact build.

    The thesis: AI-first is architecture, not a chip

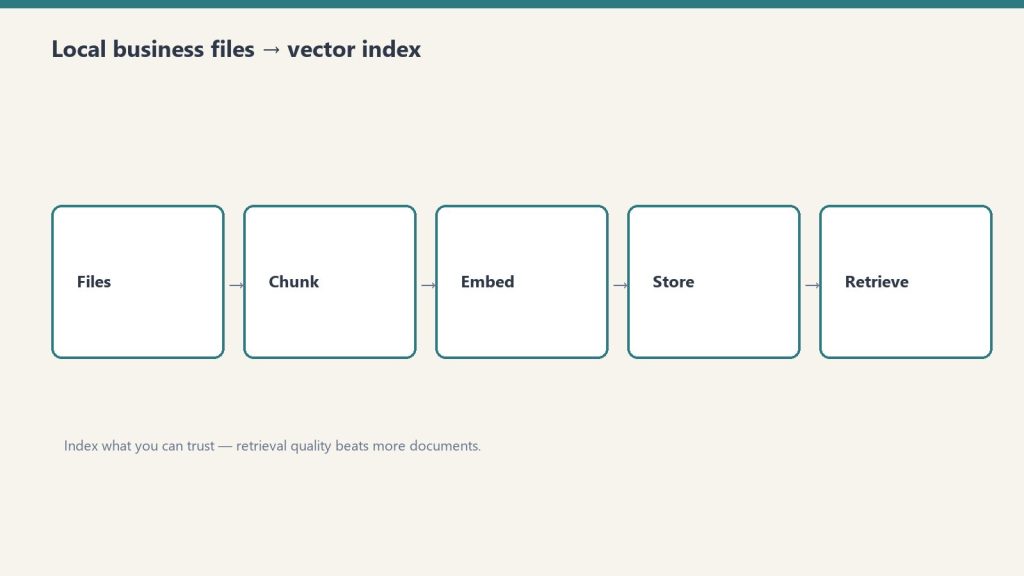
    Five-step flow from files to chunk, embed, store, retrieve
    AI-first is architecture, not a chip.

    The trick is to stop asking your laptop to be the supercomputer. Split the job:

    • The brain lives in the cloud. The heavy reasoning runs on a frontier model (I use Claude) with effectively unlimited horsepower. No NPU on Earth competes with that.
    • The body lives on your laptop. Your machine becomes the always-on hands: it holds your private data, runs small models locally for anything sensitive, and executes the actions the brain decides on.

    An NPU optimizes a handful of on-device Windows features. Architecture gives you an actual operator. Guess which one you feel every day.

    Step 0 — Make it always-on

    An operator rig is a little server, and servers don’t nap. My laptop kept sleeping and killing background jobs, so the first move was to take that off the table (while plugged in):

    powercfg /change monitor-timeout-ac 0
    powercfg /change standby-timeout-ac 0
    powercfg /setacvalueindex SCHEME_CURRENT SUB_BUTTONS LIDACTION 0
    powercfg /setactive SCHEME_CURRENT

    Screen never blanks, never sleeps, and it keeps running with the lid closed — while still sleeping on battery as a safety. Now it’s a real always-on host.

    Step 1 — A private AI brain that lives on the laptop

    Three stacked layers: chat UI, tools, agent runtime
    A private AI brain that lives on the laptop.

    The local engine is Ollama; the chat interface is open-webui (running in Docker). If you want the multi-agent version of this idea, I’ve also written up building a free AI agent army with Ollama and Claude. The only thing standing between me and a private, offline ChatGPT was one wrong setting — open-webui was pointed at a dead address. The fix was to aim it at the host:

    docker run -d --name open-webui --restart always -p 3000:8080 
      -v open-webui:/app/backend/data 
      -e OLLAMA_BASE_URL=http://host.docker.internal:11434 
      ghcr.io/open-webui/open-webui:main

    The proof: a 3-billion-parameter model (Llama 3.2) introduced itself in about 10 seconds at ~12 tokens/second — on the CPU, no NPU, no discrete GPU. Fast enough for real Q&A, drafting, and summaries. Seven models sit ready on disk, and the whole thing is reachable from my phone over a private network.

    Everything here runs offline. For anything I don’t want leaving the machine, that’s the entire point.

    Step 2 — Voice that never leaves the machine

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Voice that never leaves the machine.

    A local Whisper speech-to-text container (OpenAI-compatible API) became a push-to-talk dictation tool: hold a key, talk, release, and the text drops into whatever app is focused. I verified the pipeline without even touching the mic — Windows text-to-speech generated a clip, the local Whisper transcribed it, and it round-tripped clean:

    Spoken: “Testing one two three. This is the private local transcription engine.”
    Whisper heard: “Testing 1-2-3. This is the private local transcription engine.”

    Windows has built-in dictation (Win+H) and Copilot voice too — but those ship your audio to the cloud. The local version does the same job, and your voice never leaves the laptop.

    Step 3 — Turn your phone into the control panel

    Using Tailscale (a private mesh network), every service on the laptop is reachable from my phone — without exposing anything to the public internet. I added a tiny web page (one small nginx container) as a mobile operator console: one tap to the local AI, automations, status, and finance dashboards. Pin it to the home screen and the laptop is in your pocket.

    The honest scoreboard vs. a Copilot+ PC

    Capability Copilot+ PC ($1,000+) This $400 laptop
    Private AI running on the device Limited (small NPU models) ✅ Full Ollama stack, 7 models
    An AI that operates the machine ❌ ✅ Runs commands, edits files, fixes things
    Private, offline voice dictation ❌ (cloud) ✅ Local Whisper
    Phone control panel ❌ ✅ Tailscale operator console
    Recall / Click to Do / Cocreator ✅ (needs the NPU) ❌
    Screenshots everything you do ⚠️ Recall does, by design ✅ No — nothing is recorded

    I’m being fair: the NPU-only features are genuinely off the table on cheap hardware. But for operating your computer — and for privacy — the architecture beats the chip.

    Why this matters more than it looks

    The quiet headline isn’t “I saved money.” It’s where the data lives. Microsoft’s flagship AI-PC feature, Recall, works by screenshotting everything you do. This build does the opposite: the sensitive payload stays on your machine, and the cloud is used only for the heavy thinking that doesn’t need your private files.

    That’s not just a hobbyist’s preference. It’s the exact requirement for anyone in a regulated field — healthcare, legal, finance — who can’t send client data to a third party but still wants real AI leverage. The cheap laptop isn’t the story. The architecture is.

    Frequently asked questions

    Do I need a Copilot+ PC or an NPU to run local AI?

    No. Any laptop with around 16 GB of RAM and a modern CPU can run small local models. An NPU accelerates certain Windows features but is not required for Ollama or local chat.

    Is local AI actually private?

    Yes. With Ollama, the model runs on your own machine and works with no internet connection — nothing is sent to a cloud service.

    What is the difference between Ollama and open-webui?

    Ollama is the engine that runs the models. open-webui is the friendly chat interface that sits in front of it.

    How fast is a local model on a budget laptop?

    On a CPU-only AMD Ryzen 5 with 16 GB of RAM, a 3-billion-parameter model answered at roughly 12 tokens per second — fine for quick questions, drafting, and summaries. Larger models run slower.

    Can I use it from my phone?

    Yes. Over a private Tailscale network you can reach your laptop’s AI and tools from your phone without exposing anything to the public internet.

    Is this better than a Copilot+ PC?

    For operating your machine and for privacy, this setup does more. For NPU-specific Windows features like Recall and Click to Do, a Copilot+ PC is required.

    Want this on your machine?

    Tygart Media builds privacy-first, local-AI operator setups — especially for teams in regulated industries that need real AI leverage without sending data to the cloud. Reach out and we’ll scope it to your hardware.

    >Part of the complete guide: Your Laptop Is Already an AI PC

  • Local Newsroom Training: Planning With Claude Cowork

    Local Newsroom Training: Planning With Claude Cowork

    Last refreshed: May 15, 2026

    Running a local newsroom means juggling breaking stories, editorial calendars, community events, and ad sales — with a staff that is usually three people doing the work of ten.

    Claude Cowork does not write your stories for you. But it does something almost as valuable: it shows your small team how to plan coverage like a large newsroom plans coverage. And it does it visibly, in real time, so every person on your team can absorb the thinking — not just follow the assignments.

    The short answer: Claude Cowork decomposes complex tasks into parallel workstreams and shows progress in real time. For local newsrooms, that means your reporter sees how editorial planning works, your ad coordinator sees how content calendars connect to revenue, and your editor sees how to orchestrate coverage across beats without burning out the team.

    The Newsroom Problem Nobody Talks About

    Side-by-side cards defining what Claude Code is and is not
    The newsroom problem nobody talks about.

    Most local news operations do not have a formal planning process. Stories come in from tips, police scanners, city council agendas, and community Facebook groups. The editor (who is often also a reporter, also the photographer, also the social media manager) triages by gut feel and deadline proximity.

    This works until it does not. A big story breaks the same week as three ad-sponsored features are due. Nobody planned for that collision because nobody was looking at the calendar as a system.

    Cowork is not a newsroom tool. But the way it plans work is exactly the skill local news teams need and rarely have time to develop.

    How Cowork Trains Each Newsroom Role

    Three stacked layers: chat UI, tools, agent runtime
    How Cowork trains each newsroom role.

    The Reporter

    Give Cowork a prompt like: “A new mixed-use development just got approved by city council after two years of controversy. Build me a complete coverage plan for the next thirty days.”

    Cowork does not just list story ideas. It builds a plan with tracks: the news track (council vote recap, developer profile, opposition response), the enterprise track (tax impact analysis, traffic study implications, comparable projects in other cities), the community track (affected neighborhood voices, small business impact, public meeting schedule), and the social distribution track (which pieces go on which platforms and when). A reporter watching this unfold sees that coverage planning is not “what should I write” but “what does the audience need to understand, in what order, from which angles.”

    The Editor

    Editors in small newsrooms spend most of their time reacting. Give Cowork a weekly planning scenario: “We have three breaking news items, a school board meeting Tuesday, an ad-sponsored restaurant feature due Friday, two pending FOIA responses, and a community event this weekend we agreed to cover. Build me the editorial plan for the week.”

    Cowork shows the editor what editorial orchestration looks like: which items are time-sensitive and must publish first, which can be batched, where a reporter can double-purpose a trip (cover the school board and grab a quote for the restaurant feature on the same side of town), and where the week has capacity for enterprise work versus where it is wall-to-wall coverage. The editor sees the week as a resource allocation problem — not a reaction queue.

    The Ad Coordinator

    This is the role nobody thinks about for AI training. But give Cowork a task like: “We have four advertisers who each bought sponsored content packages this quarter. Build me a content calendar that integrates their sponsored pieces with our editorial calendar so they complement rather than compete with news coverage.”

    Cowork builds a calendar that interleaves sponsored content with editorial content, avoids running sponsored pieces on heavy news days (where they get buried), spaces advertiser content evenly, and identifies opportunities where a news story and a sponsored piece can reinforce each other naturally. The ad coordinator sees that content scheduling is strategy, not just slotting pieces into empty dates.

    The Real Training Value

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The real training value.

    Local newsrooms lose institutional knowledge every time someone leaves — and in local news, people leave often. The coverage plans and editorial workflows that Cowork generates are not just useful in the moment. They are training artifacts that show the next hire how the newsroom thinks, not just what it publishes.

    When a new reporter watches Cowork decompose a complex local story into a multi-angle coverage plan, they are absorbing the editorial judgment that used to take years of mentorship to transfer. That does not replace an experienced editor. But it gives every person on the team a shared mental model for how coverage should be planned — and that shared model is what turns a collection of individual contributors into an actual newsroom.

    Related on Tygart Media: Cowork marketing training · Cowork staff training · information density.

    Frequently Asked Questions

    Can Claude Cowork help a small newsroom with editorial planning?

    Yes. Cowork visibly decomposes complex tasks into parallel workstreams. For a newsroom, that means building multi-track coverage plans, editorial calendars, and resource allocation strategies that show every team member how editorial planning works at a systems level.

    Does Cowork write news articles?

    Cowork can handle multi-step knowledge work including research synthesis and document assembly. However, the training value comes from watching how it plans and decomposes work — not from using it as a content generator. The coverage plans it produces are the training tool.

    How is this different from a project management tool?

    Project management tools track tasks after someone creates them. Cowork shows the decomposition process itself — how a complex goal becomes a structured plan. That planning skill is what most local newsroom staff never formally learn.

    What size newsroom benefits most?

    Newsrooms with two to ten staff members benefit most. They are large enough to need coordination but too small to have dedicated planning roles. Cowork fills the gap by making the planning visible so everyone can learn from it.

  • AI-Assisted Local Journalism: Exploring Olympic Peninsula

    AI-Assisted Local Journalism: Exploring Olympic Peninsula

    What Exploring Olympic Peninsula Is

    The Olympic Peninsula is enormous. Four counties, hundreds of miles of coastline, a national park, tribal lands, small towns separated by mountain passes and rainforest, and communities that range from Sequim’s sunshine to Forks’ rainfall. Covering all of it — the trails, the restaurants, the events, the local issues, the hidden spots — is a massive undertaking for any publication.

    Exploring Olympic Peninsula was built to try. And we’re using AI to help us do it.

    How AI Helps Us Cover the Peninsula

    We use AI tools to research, organize, and draft content about the Olympic Peninsula. Specifically, AI helps us monitor public sources across four counties, pull together event listings from chambers of commerce and tourism boards, compile trail conditions and park updates, research businesses and attractions, and draft articles that our editorial process then reviews and refines.

    AI lets a small team cover an area that would traditionally require a newsroom spread across Clallam, Jefferson, Grays Harbor, and Mason counties. It’s not a replacement for local knowledge — it’s a multiplier that helps us get to more stories, faster.

    Why We’re Telling You This

    We believe in being transparent about how our content is made. AI-assisted journalism is growing across the industry, and the publications that are honest about it build more trust than the ones that hide it. You deserve to know how the content you’re reading was produced.

    We’ve also learned from our sister publications — Belfair Bugle and Mason County Minute — that transparency about AI use invites the kind of community feedback that makes everything better. When readers know that AI is part of the process, they understand why certain types of errors happen and they’re more willing to help correct them.

    Our Verification Process

    Every article that mentions a specific business, restaurant, hotel, trail, attraction, or physical location on the Olympic Peninsula runs through a Google Maps verification gate before publication. This checks that each named place exists, is currently open, and that the details in our article match the official record.

    This protocol was built after community members on our Mason County publications caught entity errors and pushed us to do better. We took that feedback and made it a permanent part of our process across all our publications, including this one.

    For a region as vast and geographically complex as the Olympic Peninsula — where a road closure can cut off an entire community and a restaurant might be seasonal — this verification step is especially important.

    Where You Come In

    No database captures the Olympic Peninsula the way people who live here do. You know which roads are actually passable in March. You know which restaurants are seasonal. You know the local name for that trailhead that Google Maps calls something different. You know which beach access points are real and which ones exist only on old maps.

    That knowledge is what we need most. If you see something on Exploring Olympic Peninsula that doesn’t match what you know — a business that’s closed, a trail description that’s off, a geographic detail that misses the mark — please tell us. Comment on the post, reach out on social media, or message us directly.

    We’re building this publication for the people who love the Olympic Peninsula. Help us get it right.

  • Mason County Minute: How Community Feedback Improves News

    Mason County Minute: How Community Feedback Improves News

    You Held Us Accountable — And We’re Better For It

    Mason County Minute started as a straightforward idea: build a local publication that actually covers the things happening in Mason County, at the pace they’re happening. Commissioner meetings, school district decisions, shellfish closures, road projects, business openings — the things that matter to people who live here.

    We use AI to help us cover more ground than a small team normally could. That’s not a secret, and it’s not something we’re defensive about. AI lets us monitor public records, organize government meeting data, cross-reference sources, and draft coverage at a pace that would be impossible manually.

    But AI doesn’t know Mason County the way you do. And when it gets something wrong — like placing a town in the wrong geographic context or confusing details about a local landmark — you’ve been telling us about it. Directly, specifically, and helpfully.

    Every one of those corrections landed. Thank you.

    The Specific Changes We Made

    Community feedback didn’t just fix individual errors. It prompted us to build a permanent verification layer into our publishing process.

    Every article that names a specific business, restaurant, park, or physical location in Mason County now runs through a Google Maps verification gate before publication. The system checks that each named place actually exists, is currently operational, and that the name, address, and geographic context match the Google Maps record. If something doesn’t check out, the article is held until a human reviews it.

    We also improved how we handle the tricky geography of this area. Hood Canal, the inlets, the relationship between Shelton and Belfair and Allyn and Union — these aren’t things a general-purpose AI naturally understands well. We’ve built local geographic context into our editorial process specifically because Mason County readers told us when we got it wrong.

    Why Your Feedback Matters More Than You Think

    Here’s what community input does that no technology can replicate: it tells us when something feels wrong to someone who lives here. A detail can be technically accurate on paper but miss the local context that makes it meaningful. When a Mason County resident says “that’s not how people here think about that,” that’s editorial intelligence we can’t get anywhere else.

    So please don’t stop. If you read something on Mason County Minute that doesn’t match what you know, tell us. Post a comment, reach out on Facebook, send us a message — however works for you. We read every piece of feedback, and we act on it.

    Mason County Minute exists to serve this community. The more this community shapes it, the better it gets.

  • Belfair Bugle Feedback: How We’re Improving Local Accuracy

    Belfair Bugle Feedback: How We’re Improving Local Accuracy

    Thank You, North Mason

    When we started building Belfair Bugle, we knew that getting local details right would be the difference between a publication people trust and one they scroll past. We also knew we’d make mistakes along the way — and we asked you to call us on them when we did.

    You did. And we’re grateful for it.

    Over the past several weeks, community members have pointed out geographic errors, questioned business details, and pushed back when something didn’t look right. Every single one of those corrections made Belfair Bugle more accurate. Not just the article that got fixed — the entire system behind it.

    What We’ve Changed

    We want to be transparent about what happened and what we built in response.

    Belfair Bugle uses AI to help research, organize, and draft local content. We’ve been upfront about that from the beginning. AI is a powerful tool for pulling together information from public sources, government records, and local data — but it’s not perfect, especially when it comes to the kind of hyperlocal geographic knowledge that only comes from living here.

    When readers caught errors — like placing Allyn in the wrong geographic context, or mixing up details about local businesses — we didn’t just fix the individual articles. We built a verification protocol that now runs on every single article before it publishes.

    Here’s how it works: every named business, restaurant, park, school, or physical location mentioned in a Belfair Bugle article is now checked against Google Maps data before publication. If a business has closed, it gets removed. If the name or address doesn’t match, it gets corrected. If a place can’t be verified, the article is held until a human reviews it.

    This means that when you read a Belfair Bugle article that mentions a local business or landmark, you can trust that we’ve verified it’s real, it’s open, and the details are accurate as of the day we published.

    Keep Telling Us

    Here’s the thing — no verification system replaces the knowledge that comes from actually living in Belfair, driving SR-3 every day, shopping at the businesses on the commercial corridor, and knowing which Hood Canal beach is which. That knowledge lives in this community, not in a database.

    So please keep giving us input. If you see something wrong — a business name, a location, a detail that doesn’t match what you know — tell us. Comment on the post, reach out on social media, or just flag it however is easiest for you. Every correction makes the next article better for everyone in North Mason.

    We’re a local family building this for our community, and the community’s involvement is what makes it work. Thank you for being part of it.

  • Community AI Infrastructure: Building Belfair’s AI Layer

    Community AI Infrastructure: Building Belfair’s AI Layer

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade

    There is a version of the internet that knows your town. Not the version that surfaces Yelp reviews from people who visited once, or Google results optimized for national audiences who will never set foot in your zip code. A version that knows the ferry schedule changes in November. That knows the difference between Hood Canal and the Sound for crabbing purposes. That knows which road floods first when it rains hard, which local business closed last month, and what the school board decided at Tuesday’s meeting.

    That version of the internet doesn’t exist yet for most small towns. It doesn’t exist for Belfair, Washington — a community of roughly 5,000 people at the southern tip of Hood Canal, twenty minutes from the Puget Sound Naval Shipyard, surrounded by state forest, tidal flats, and the kind of specific local knowledge that accumulates over generations but has never been written down anywhere a search engine can find it.

    Building that version of the internet for Belfair is not primarily a business project. It’s an infrastructure project. And the distinction matters more than it might seem.

    What Infrastructure Means Here

    Infrastructure is what a community runs on. Roads, water, power, schools — nobody debates whether these should exist. The question is who builds them, who maintains them, and who controls them. For most of the internet era, the infrastructure question for small communities has been answered by default: national platforms build the tools, set the rules, and optimize for national audiences. Local communities get whatever is left over.

    AI is giving that question a new answer. For the first time, it is technically and economically feasible to build a community-specific AI layer — a system that knows Belfair specifically, not as a data point in a national model but as the primary subject of a purpose-built knowledge base. The cost to run it is near zero. The technical infrastructure to deliver it exists today. The only scarce input is the knowledge itself, and that knowledge lives in the people who have been here for decades.

    The infrastructure framing changes what the project is. Infrastructure is not built to generate margin — it’s built to generate capability. Roads don’t monetize traffic. They make everything else possible. A community AI layer built on genuine local knowledge doesn’t need to generate revenue to justify its existence. It justifies its existence by making life in Belfair better for the people who live there.

    That said, infrastructure needs a builder. Someone has to do the extraction work, maintain the knowledge base, and keep the system running. That is a real cost. The question is how to structure it so the cost is sustainable without turning the infrastructure into a product that serves someone other than the community.

    What Goes Into a Belfair Knowledge Base

    The knowledge required to make an AI genuinely useful for Belfair residents is not generic. It is specifically, obstinately local. Some of it is practical:

    The Washington State Ferry system serves Bremerton and Kingston, but getting between the Key Peninsula and anywhere north means a specific sequence of roads and timing that depends on the season, the tides, and whether you’re trying to make a morning commute or a weekend trip. The Hood Canal Bridge closes for submarine transits — unpredictably and without much public warning. Highway 3 floods near the Belfair bypass after sustained rain in a way that Google Maps doesn’t flag because it doesn’t happen often enough to be in the traffic model but often enough that locals know to check before they leave.

    Some of it is institutional: which county departments handle which types of permits, how the Mason County planning process works for small construction projects, what services the Belfair Water District provides and doesn’t, how the North Mason School District’s bus routes are organized, and what the timeline looks like for utility connection in new development.

    Some of it is ecological and seasonal: when the Hood Canal shrimp season opens and what the limits are, which beaches are currently under shellfish closure and why, when the Olympic Peninsula steelhead runs are expected, what weather conditions on the Olympics predict for local precipitation, and how the tidal patterns in the canal affect crabbing, fishing, and small boat navigation.

    Some of it is community and social: which local businesses are open, what their actual hours are (not their Google listing hours, which are frequently wrong), which community organizations are active and how to reach them, what local events are happening, and what the current issues are before the Mason County Board of Commissioners or the Belfair Urban Growth Area planning process.

    None of this knowledge is in any national AI system in usable form. Most of it has never been written down in a structured way at all. It lives in people — in longtime residents, local business owners, county employees, fishing guides, school administrators, and the dozens of other people who carry institutional knowledge about this specific place in their heads.

    The Moat Nobody Can Buy

    Here is the strategic reality that makes a community AI layer worth building: it is impossible to replicate from the outside.

    A well-funded competitor could build better technology. They could hire more engineers. They could deploy more compute. None of that gets them closer to knowing which road floods first in Belfair, or what the Mason County planning department’s actual turnaround time is on variance applications, or what the Hood Canal Bridge closure schedule looks like for next month’s submarine transit. That knowledge requires relationships, trust, and sustained presence in the community that cannot be purchased or automated.

    This is different from most knowledge infrastructure moats, which are defensible because they require time and capital to build. The Belfair knowledge moat is defensible because it requires relationships with specific people in a specific place who have no particular reason to share what they know with an outside company optimizing for scale. They would share it with someone who is part of the community — who goes to the same store, whose kids go to the same school, who has a stake in the place they’re describing.

    That is the extraction advantage of being local. It’s not just that the knowledge is hard to get. It’s that the knowledge is hard to get for anyone who doesn’t already belong to the community that holds it.

    Free Access as a Foundation, Not a Promotion

    The access model matters as much as the knowledge model. Charging Belfair residents for access to an AI that knows their community would undermine the entire premise. The knowledge came from the community. The people who use it most are the people who need it most — which in a community like Belfair often means people who are not tech-forward, not subscribed to multiple services, and not looking for another monthly bill.

    Free access for anyone with a Belfair or Mason County address is not a promotional offer. It’s the foundational design decision. The community AI exists for the community. If it costs money to access, it becomes a product that serves the people who can afford it rather than infrastructure that serves everyone.

    The sustainability question is real but separate. The knowledge infrastructure built for Belfair — the corpus structure, the extraction methodology, the validation layer, the API delivery system — is the same infrastructure that underlies paid commercial verticals in restoration, radon mitigation, and luxury asset appraisal. The commercial products subsidize the community infrastructure. That is not a charity model. It’s a cross-subsidy model where the same technical investment serves both markets, and the commercial revenue makes the community access sustainable without charging the community for it.

    PSNS and the Incoming Military Family Problem

    There is one specific population in Belfair and Kitsap County that makes the community AI layer immediately, practically valuable in a way that is easy to underestimate: military families arriving at the Puget Sound Naval Shipyard in Bremerton.

    PSNS is one of the largest naval shipyards in the country. Families arrive regularly on Permanent Change of Station orders — often with weeks of notice, often without anyone they know in the area, often navigating an unfamiliar region while simultaneously managing a household move, school enrollment, and a new duty assignment. The information they need is intensely local: where to live, how the schools compare, what the commute from Belfair or Gorst or Port Orchard actually looks like at 7 AM, what the Mason County and Kitsap County rental markets are doing, what services are available for military families specifically.

    An AI that knows this — not generically, but specifically, with current information maintained by people who live here — is immediately useful to every incoming military family in a way that no national platform can match. Free access for incoming PSNS families is both a community service and a signal: this is what it looks like when local knowledge infrastructure is built for the people who need it rather than for the people who generate the most ad revenue.

    The Workshop Model

    Knowledge infrastructure only works if people know how to use it. The technical barrier to using an AI assistant has dropped dramatically, but it hasn’t disappeared — and in a community where many residents are not digital natives, the gap between “this exists” and “this is useful to me” requires active bridging.

    Monthly local workshops — held at the library, the community center, or a local business willing to host — serve two functions simultaneously. They teach residents how to use the community AI effectively: how to ask questions, how to verify answers, how to contribute knowledge they have that isn’t in the system yet. And they build the contributor relationship that keeps the knowledge base current. A resident who has attended a workshop and understands how the system works is a potential contributor — someone who will correct an error when they find one, add context when they know something the corpus doesn’t, and tell their neighbors about the resource when it helps them.

    The workshop model also keeps the project grounded in actual community need rather than in what the builders assume the community needs. The questions people bring to a workshop are data. The frustrations they express are product feedback. The knowledge they volunteer is corpus input. Every workshop is simultaneously an outreach event, a training session, and an extraction session — and that efficiency is only possible because the project is genuinely local rather than deployed from a distance.

    What This Looks Like at Scale

    Belfair is one community. The model is replicable to every community that has the same structural characteristics: a defined local identity, a body of specific local knowledge that national platforms don’t carry, and a population that would benefit from AI that knows where they actually live.

    Mason County has several communities with this profile. Shelton, the county seat, has its own institutional knowledge layer — county government, the Port of Shelton, the local fishing and timber industries — that is entirely distinct from Belfair’s. Hoodsport, Union, Allyn, Grapeview — each of them has the same problem and the same opportunity at smaller scale.

    The Olympic Peninsula more broadly is one of the most knowledge-dense environments in the Pacific Northwest for outdoor recreation, tidal ecology, tribal land management, and small-town commercial life — and almost none of it is accessible through any AI system in accurate, current form. The same infrastructure built for Belfair scales to the peninsula with the same methodology and the same access philosophy: free for residents, sustainable through cross-subsidy with commercial verticals that use the same technical foundation.

    The version of the internet that knows your town is worth building. Not because it generates revenue — though it can. Because communities deserve infrastructure that was built for them.

    Frequently Asked Questions

    What is a community AI layer?

    A community AI layer is a purpose-built knowledge base and AI delivery system designed to answer questions about a specific local community accurately and currently — covering practical information like road conditions, seasonal patterns, local business hours, and institutional processes that national AI systems don’t carry in usable form.

    Why is local knowledge infrastructure different from national AI platforms?

    National AI platforms optimize for broad audiences and scale. They cannot maintain current, accurate knowledge about the specific conditions, institutions, and rhythms of small communities because that knowledge requires local relationships, sustained presence, and ongoing maintenance by people who are part of the community. It is not a resource problem — it is a relationship and trust problem that cannot be solved with more compute.

    Why should access to a community AI be free for residents?

    Because the knowledge came from the community. Charging residents for access to an AI built on their own community’s knowledge would convert infrastructure into a product, limiting access to those who can afford it rather than serving the whole community. Sustainability comes from cross-subsidy with commercial knowledge verticals that use the same technical infrastructure, not from charging residents.

    What makes community AI knowledge impossible to replicate from outside?

    The extraction moat is relational, not technical. Specific local knowledge — which road floods, how a county planning process actually works, what the ferry timing looks like in November — comes from people who share it with those they trust. An outside organization cannot replicate those relationships by deploying capital or engineers. The knowledge is accessible only through genuine community membership and sustained presence.

    How do local workshops support the knowledge infrastructure?

    Workshops serve three simultaneous functions: they teach residents how to use the AI effectively, they build contributor relationships that keep the knowledge base current, and they surface actual community needs and knowledge gaps that remote builders would never identify. Every workshop is an outreach event, a training session, and a knowledge extraction session combined.

    Related: Belfair Community AI Knowledge Series

    This article is part of the Belfair Bugle’s ongoing coverage of the community AI knowledge infrastructure being built for North Mason. Read the full series:
  • AI Search Stack: A Capability Layer for Freelance SEOs

    AI Search Stack: A Capability Layer for Freelance SEOs

    The Machine Room · Under the Hood

    You Don’t Need Another Tool. You Need a Person Who Knows How to Use All of Them.

    The SEO tool market is drowning in platforms. There’s a tool for keyword research. A tool for rank tracking. A tool for schema. A tool for content optimization. A tool for AI search monitoring. A tool for internal linking. A tool for site audits. Every one of them costs money, requires onboarding, and solves exactly one piece of the puzzle.

    As a freelance SEO consultant, you’ve probably assembled your own stack. It works. You know which tools you trust and which ones are shelf-ware. But here’s the thing nobody selling you a SaaS subscription will admit: the tools don’t connect themselves. The data doesn’t analyze itself. The insights don’t become action without someone who understands the entire picture — from the raw crawl data to the published content to the schema markup to the AI citation signals.

    That’s what I do. I’m not selling you a platform. I’m not asking you to adopt a new tool. I’m the person who plugs into your operation and brings the entire capability stack with me — the data analysis, the platform connections, the content production, the optimization programs, the schema architecture, the AI search strategy. One operator. Full stack. No overhead.

    What “I’m the Plugin” Actually Means

    When I say I’m the plugin, I mean it literally. A plugin adds capability to an existing system without replacing anything that’s already there. It installs. It activates. It works alongside everything else. You don’t rebuild your workflow around it — it enhances what you already have.

    That’s how I work with freelance SEO consultants. You keep your clients. You keep your process. You keep your tools. You keep your relationships. I plug into your operation and add the layers you don’t have time, bandwidth, or infrastructure to build yourself.

    Those layers include answer engine optimization — structuring your clients’ content so it gets surfaced as the direct answer, not just a ranking result. Generative engine optimization — making their content the source that AI systems cite. Schema architecture — structured data that tells machines exactly what your client’s business is, what it does, and why it’s authoritative. Content pipeline management — taking a single topic and determining exactly how many audience-targeted variants it needs based on tested guardrails, not guesswork.

    I also bring the platform connectors. I can authenticate with any WordPress site through its REST API, route all traffic through a secure proxy so I never need hosting access, and run optimization sequences across multiple client sites from a single operating layer. I built the infrastructure to do this across a portfolio of sites simultaneously — the same infrastructure that works whether you have two clients or twenty.

    The Solo Consultant’s Real Problem

    You’re good at SEO. Your clients are happy. But you’re one person, and the surface area of search keeps expanding. Featured snippets. People Also Ask. Voice search. AI Overviews. ChatGPT search. Perplexity. Each one is a different optimization challenge with different technical requirements.

    You can’t become an expert in all of them and still do the core SEO work your clients pay you for. That’s not a skill gap — that’s a bandwidth problem. The knowledge exists. The techniques are documented. But implementing them across a portfolio of client sites while also doing keyword research, content strategy, link building, and client communication? That’s not a one-person job anymore.

    Unless the second person is a plugin that brings the entire stack.

    What I Bring That a Tool Can’t

    Tools give you data. They don’t interpret it in the context of your client’s business, their competitive landscape, their industry’s search behavior, or their specific goals. A schema generator can spit out JSON-LD. It can’t decide which schema types matter most for a specific business, how to structure entity relationships across a multi-location operation, or when a HowTo schema will outperform a FAQPage schema for a given topic.

    I do the analysis. I look at a client’s site, their content, their competitive position, and their industry — and I determine what optimization layers will actually move the needle. Then I build and implement those layers. Then I measure whether they worked. Then I adjust. That’s not a tool workflow — that’s an operator workflow.

    The content pipeline is the same way. I built an adaptive system that analyzes a topic and determines how many persona-targeted variants it genuinely needs. Not a fixed number — a demand-driven calculation. Some topics need one article. Some need four. The system has guardrails built from simulation testing that identify exactly when additional variants start cannibalizing each other instead of building authority. A tool can’t make that judgment call. A person who’s tested the thresholds can.

    How This Changes Your Business Without Changing Your Business

    When you plug in a capability layer like this, a few things shift. You can say yes to client questions about AI search without scrambling to figure it out. You can offer AEO and GEO as natural extensions of your SEO services without pretending you built the infrastructure yourself. You can deliver deeper optimization on every engagement without working more hours.

    Your clients see expanded results. They see their content appearing in featured snippets, getting cited by AI systems, ranking with richer search presence through structured data. They attribute that to you — because it is you. You made the decision to add the capability. You manage the relationship. You communicate the results. The plugin just made it possible to deliver at a depth that solo consultants normally can’t reach.

    What This Isn’t

    This isn’t an agency partnership where you hand off your clients and hope for the best. Your clients stay yours. This isn’t a software subscription where you’re paying monthly for a dashboard you’ll use twice. There’s no dashboard — there’s a person doing the work. This isn’t a course or a certification or a “learn to do it yourself” program. If you want to learn this stuff, I’m happy to teach it. But the value proposition here is capability on demand, not education.

    And I’m not going to promise you specific results, traffic numbers, or revenue outcomes. Search is complex. Every client is different. What I can tell you is that the optimization layers I add — AEO, GEO, schema, entity architecture, adaptive content — are built on real methodology that I use every day across a portfolio of sites. The same systems, the same processes, the same quality standards.

    Starting the Conversation

    If you’re a freelance SEO consultant who’s been feeling the expanding surface area of search and wondering how to cover it all without burning out or diluting your core work, I might be the plugin you’re looking for. No pitch deck. No onboarding process. Just a conversation about your clients, your workflow, and where a capability layer might make your work deeper without making your life harder.

    Frequently Asked Questions

    How is this different from subcontracting to another SEO person?

    A subcontractor does more of the same work you do. I add capabilities you don’t currently offer — AI search optimization, schema architecture, entity signals, content variant systems. It’s additive, not duplicative. I’m not doing your SEO differently. I’m doing the things that sit alongside SEO that you don’t have the infrastructure to do alone.

    Do you work with consultants who use tools other than WordPress?

    The core optimization stack is built around WordPress since it powers the majority of business websites. If your clients use other CMS platforms, we’d discuss feasibility on a case-by-case basis. The methodology applies universally — the implementation layer is WordPress-native.

    What does the working relationship actually look like day to day?

    Lightweight. You share site access through a WordPress application password. I run optimization passes on your schedule — weekly, biweekly, or per-project. You get results documented in whatever format you report to clients. Communication happens however you prefer — Slack, email, a quick call. The goal is minimum friction, maximum capability.

    What if a client leaves and I need to disconnect access?

    Revoke the application password. That’s it. All optimization work already delivered stays on the client’s site. There’s no data lock-in, no proprietary code that breaks if the connection ends. Everything we build lives in standard WordPress and standard schema markup.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “Im the Plugin: What It Means When One Person Brings the Entire AI Search Stack”,
    “description”: “Not a tool. Not a platform. Not an agency. One operator who connects your platforms, analyzes your data, builds your content, and runs the programs.”,
    “datePublished”: “2026-04-03”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/im-the-plugin-what-it-means-when-one-person-brings-the-entire-ai-search-stack/”
    }
    }