Tag: Local AI

  • AI Citation Optimization: Protect Your SEO Retainer

    AI Citation Optimization: Protect Your SEO Retainer

    The Machine Room · Under the Hood

    The Search Results Page You’re Not Looking At

    Pull up ChatGPT. Type in your client’s most important service query — the one they rank on page one for. Look at the response. Which companies does it mention? Which sources does it cite? Which brands does it recommend?

    Now do the same thing in Perplexity. Then in Google’s AI Overview for that query. Then ask Claude.

    If your client’s name doesn’t appear in any of those results, they’re invisible in the fastest-growing search surface in a decade. And here’s the part that should concern you as their SEO consultant: their competitors might already be there.

    This isn’t a hypothetical future scenario. AI systems are answering real queries from real users right now. Those answers cite specific sources. Those sources get brand exposure, credibility signals, and click-through traffic that doesn’t show up in your client’s Google Analytics the way organic search does. If your client isn’t one of those cited sources, someone else is getting that value.

    Why Traditional SEO Doesn’t Solve This

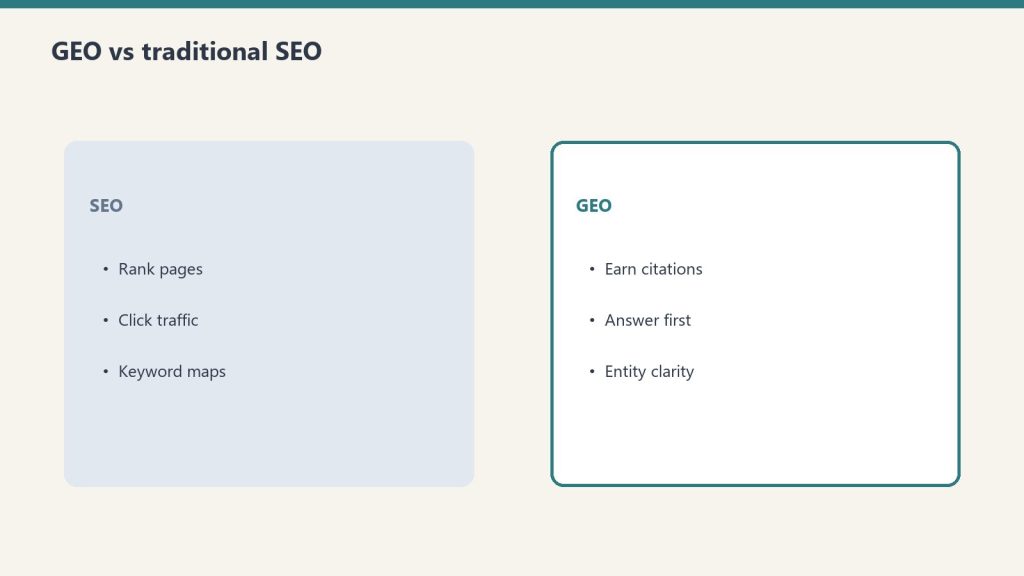
    Traditional SEO optimizes for Google’s ranking algorithm — signals like authority, relevance, technical health, and backlink profiles. Those signals determine where your client appears in the ten blue links. And they still matter. Rankings drive traffic. Traffic drives leads. That’s your bread and butter and it’s not going away.

    But AI citation is a different game. When ChatGPT decides which sources to reference, it’s not running the same algorithm as Google Search. When Perplexity builds an answer from web sources, it’s evaluating factual density, entity clarity, structural readability, and source authority through a different lens. When Google’s AI Overview selects which pages to cite, it’s pulling from a different set of signals than the traditional ranking algorithm uses.

    You can rank number one for a query and still be invisible to AI search. Those are different optimization surfaces. Mastering one doesn’t automatically give you the other.

    What Makes AI Systems Cite a Source

    AI systems are looking for content that’s easy to extract facts from. That means high factual density — verifiable claims, specific data points, named entities, clear cause-and-effect relationships. Vague content that speaks in generalities doesn’t get cited. Content that makes specific, attributable statements does.

    Entity signals matter enormously. Does the content clearly establish who created it, what organization stands behind it, and what credentials support the claims being made? AI systems are getting better at evaluating expertise signals — not just E-E-A-T as Google defines it, but a broader assessment of whether a source is genuinely authoritative on the topic it covers.

    Structural clarity helps too. Content that’s organized with clear headings, logical sections, and self-contained passages that AI systems can extract without losing context performs better as a citation source. Think of it as making your content quotable by machines — the same way journalists prefer sources who speak in clean, attributable sound bites.

    The Retainer Question

    Here’s the business reality for freelance consultants. Your client pays you to keep them visible in search. If an increasing portion of search activity is happening through AI interfaces — and the trajectory points that direction — then “visible in search” now means visible in places your current SEO work doesn’t reach.

    That doesn’t mean your SEO work is wrong or incomplete. It means the definition of search visibility expanded. And when the client eventually asks “why is our competitor showing up in ChatGPT recommendations and we’re not?” — and they will ask — you need an answer that’s better than “that’s not really SEO.”

    Because from the client’s perspective, it is search. They searched. Someone else’s brand appeared. Theirs didn’t. The technical distinction between algorithmic ranking and AI citation doesn’t matter to them. The result matters.

    How GEO Works as a Plugin Layer

    Generative engine optimization is the discipline that addresses AI citation visibility. It focuses on the signals AI systems use when selecting sources: entity clarity, factual density, structural readability, topical authority depth, and consistent entity signals across the web.

    When I plug into a freelance consultant’s operation, the GEO layer runs alongside existing SEO work. I analyze the client’s content for citation potential — how fact-dense is it, how clearly are entities established, how extractable are the key claims. Then I optimize: strengthening entity signals, increasing factual specificity, adding structural elements that make the content more parseable by AI systems, and ensuring the client’s entity architecture across the web is consistent and clear.

    This includes things most SEO consultants haven’t had to think about yet. LLMS.txt files that tell AI crawlers what content to prioritize. Organization schema that establishes the business as a recognized entity. Person schema for key team members that builds individual expertise signals. Consistent entity references across every web property the client controls.

    All of this runs through the same WordPress API pipeline as the AEO work. Same proxy. Same access model. Same white-label delivery. Your client sees their brand starting to appear in AI-generated answers, and they attribute that to the expanded SEO strategy you’re delivering.

    The Competitive Window

    AI citation optimization is still early. Most businesses haven’t started. Most SEO consultants haven’t added it to their service stack. That means the consultants who add this capability now are building proof and expertise during a window when competition for AI citation is relatively low. That window won’t stay open indefinitely. As more consultants and agencies figure this out, the competitive landscape will tighten — just like it did with traditional SEO, just like it did with content marketing, just like it does with every new search surface.

    You don’t need to become a GEO expert to capitalize on this window. You need to plug in someone who already is.

    Frequently Asked Questions

    How do I show clients their AI citation status?

    The most direct method is manual: query their target terms in ChatGPT, Perplexity, Claude, and Google AI Overviews, then document which sources get cited. Screenshot the results. Compare against competitors. Automated monitoring tools for AI citations are emerging but manual verification remains the most reliable method for client reporting.

    Does GEO optimization conflict with existing SEO work?

    No — the optimizations are complementary. Increasing factual density, strengthening entity signals, and improving content structure all benefit traditional SEO as well. GEO work makes content better for both algorithmic ranking and AI citation. There’s no trade-off.

    How long before a client starts seeing AI citations?

    Timelines vary significantly by industry, competition, and the client’s existing authority. Some citations appear within weeks of optimization. Others build over months as entity signals compound. I don’t promise specific timelines because the variables are genuinely complex — but the optimization work begins producing structural improvements immediately.

    Is this relevant for local businesses or mainly for national brands?

    Both. AI systems answer local queries too — “best plumber in Austin” gets an AI-generated answer with cited sources, just like national queries do. Local businesses with strong entity signals (complete Google Business Profile, consistent NAP data, location-specific content) have strong GEO potential. The optimization approach adjusts for local context, but the principles apply at every scale.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “AI Is Citing Your Clients Competitors. Heres What That Means for Your Retainer.”,
    “description”: “When AI systems recommend competitors and ignore your client, that’s a visibility problem no amount of traditional SEO fixes. GEO changes the equation.”,
    “datePublished”: “2026-04-03”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/ai-is-citing-your-clients-competitors-heres-what-that-means-for-your-retainer/”
    }
    }
  • Schema Markup Implementation for Freelance SEO Consultants

    Schema Markup Implementation for Freelance SEO Consultants

    Tygart Media / The Signal
    Broadcast Live
    Filed by Will Tygart
    Tacoma, WA
    Industry Bulletin

    The Invisible Layer That Connects Everything

    If SEO is about getting found, AEO is about getting quoted, and GEO is about getting cited by AI — schema markup is the wiring that makes all three possible. It’s the structured data layer that tells machines exactly what your client’s content means, who created it, what organization stands behind it, and how it all connects.

    Without schema, search engines and AI systems have to guess. They read the content and infer meaning from context. Sometimes they get it right. Sometimes they don’t. With proper schema markup, there’s no guessing. The machines know this is a how-to guide written by a licensed contractor at a specific company that serves a specific region. They know which questions the page answers. They know which sections are suitable for voice readback. They know the entity relationships between the author, the organization, and the topic.

    That clarity is what separates content that merely ranks from content that gets selected for featured snippets, cited by AI systems, and surfaced in knowledge panels. Schema is the bridge between good content and machine understanding of that content.

    Why Most Freelance SEO Consultants Skip It

    Let’s be honest. Schema markup is technical, tedious, and time-consuming. Writing valid JSON-LD, testing it in Google’s structured data testing tool, debugging validation errors, keeping up with schema.org’s evolving vocabulary, implementing it correctly within WordPress without breaking the theme — it’s developer-adjacent work that most SEO consultants would rather not touch.

    And historically, you could get away with skipping it. Rankings were driven primarily by content quality, backlinks, and technical SEO fundamentals. Schema was a nice-to-have. A bonus. Something you’d recommend in an audit but rarely implement yourself.

    That’s changing. Featured snippet selection increasingly favors pages with FAQ schema. AI systems give weight to content with clear entity markup. Rich results in search — star ratings, FAQ dropdowns, how-to steps, event details — require schema to appear. The “nice-to-have” became a competitive advantage, and it’s trending toward a baseline expectation.

    The Schema Types That Actually Matter

    Not every schema type is worth implementing for every client. The ones that move the needle for most business websites are specific and practical.

    Organization schema establishes the business as a recognized entity — name, logo, contact information, social profiles, founding date. This is the foundation that everything else builds on. Without it, AI systems don’t have a clear entity to associate with the content.

    FAQPage schema tells search engines which questions a page answers and provides the answer text. This is the schema type most directly connected to featured snippet and PAA selection. When a page has FAQ schema that matches a user’s query, search engines have a structured signal that this page is an answer source.

    HowTo schema structures step-by-step content in a way that enables rich results — the expandable how-to cards that appear in search results with numbered steps. For service businesses, this can dramatically improve visibility for process-oriented queries.

    Article schema with author markup connects content to specific people with specific expertise. This feeds E-E-A-T signals and helps AI systems evaluate whether the content comes from a credible source.

    Speakable schema identifies which sections of a page are suitable for text-to-speech — enabling voice assistants to read your client’s content aloud as the answer to a voice query.

    How I Handle Schema as a Plugin

    When I plug into a freelance consultant’s operation, schema implementation is one of the layers I bring. I audit the client’s existing schema (usually there’s very little — maybe a basic plugin adding minimal markup). I determine which schema types are most impactful for their business type, industry, and content. Then I generate and inject the structured data through the WordPress REST API.

    The schema is valid JSON-LD — the format Google recommends. It’s injected at the post level, so it doesn’t depend on the theme or any specific plugin. If the client switches themes, the schema stays. If they deactivate a plugin, the schema stays. It’s embedded in the content layer, not the presentation layer.

    For clients with multiple locations, I build location-specific schema that establishes each location as a distinct entity with its own address, service area, and contact information — all connected to the parent organization. For clients with key personnel whose expertise matters (consultants, attorneys, medical professionals), I add person schema that establishes individual authority signals.

    I also maintain the schema over time. When new content gets published, it gets appropriate schema. When schema.org updates its vocabulary with new properties or types, I update existing markup. When Google changes its rich result requirements, the schema adapts. This isn’t a one-time implementation — it’s an ongoing layer of structural optimization.

    What Schema Does for Your Client Reports

    Schema wins are some of the most visually compelling results you can show a client. Rich results stand out in search pages — FAQ dropdowns, star ratings, how-to cards, knowledge panel enhancements. When a client sees their search result taking up twice the space of a competitor’s plain blue link, they understand the value immediately without needing a technical explanation.

    Google Search Console also reports on structured data — which schema types are detected, any validation errors, and which pages generate rich results. That data feeds directly into your existing reporting workflow. You can show the client exactly which pages have enhanced search presence through schema and track the impact over time.

    The Bottom Line for Freelancers

    Schema implementation is work that needs to happen for your clients. It connects the dots between SEO, AEO, and GEO. It enables rich results, featured snippet selection, voice search readback, and AI citation clarity. But it’s technical, time-consuming, and ongoing — which makes it a perfect candidate for the plugin model. You don’t need to become a schema expert. You need someone who already is, plugged into your operation, handling the implementation while you handle the strategy and the relationship.

    Frequently Asked Questions

    Do SEO plugins like Yoast or RankMath handle schema adequately?

    SEO plugins add basic schema — usually Article or WebPage markup and simple organization data. They don’t generate the strategic schema types that drive AEO and GEO results: FAQPage with targeted questions, HowTo with structured steps, Speakable for voice, or the entity relationship architecture that helps AI systems understand expertise signals. Plugin-generated schema is a starting point, not a solution.

    Can schema markup hurt a site if done wrong?

    Invalid schema or schema that misrepresents content can trigger manual actions from Google. That’s why implementation matters — the markup needs to be valid, accurate, and aligned with what the page actually contains. This is another reason schema is better handled by someone with specific experience rather than generated by a generic tool.

    How many pages on a typical client site need schema work?

    Organization schema goes on every page (usually site-wide). Beyond that, priority goes to the pages with the most search visibility potential — service pages, key blog posts, FAQ pages, how-to content. For a typical small business site, that might mean strategic schema on the homepage, service pages, and top-performing content — not necessarily every page.

  • Keyword Cannibalization: Why More Content Isn’t Better

    Keyword Cannibalization: Why More Content Isn’t Better

    The Lab · Tygart Media
    Experiment Nº 288 · Methodology Notes
    METHODS · OBSERVATIONS · RESULTS

    The Content Volume Trap

    Every freelance SEO consultant has felt the pressure to produce more content. More blog posts. More landing pages. More keyword-targeted articles. The logic seems sound — more content means more pages indexed, more keywords targeted, more opportunities to rank. And for a while, it works. Until it doesn’t.

    The point where more content stops helping and starts hurting is real, measurable, and different for every topic. Publish too many closely related articles and they compete against each other instead of building authority together. The term for it is keyword cannibalization, and it’s one of the most common problems I see on client sites that have been running aggressive content programs.

    This isn’t a theoretical concern. I’ve run simulation models to find the exact thresholds — how many content variants a topic can support before cannibalization overtakes the authority gains. The results are specific and they shape how I build content for every client engagement.

    What the Data Actually Shows

    Through extensive modeling, the pattern is clear. The first variant of a topic adds significant authority to the cluster. The second adds a meaningful amount. The third and fourth still contribute, but with diminishing returns. By the fifth variant, the cannibalization rate starts becoming material. By the seventh or eighth, the marginal gain approaches noise while the risk of internal competition is substantial.

    The sweet spot for most topics is two to four variants. That’s not a marketing number — it’s where the authority gain per additional piece of content is still clearly positive while the cannibalization risk remains manageable.

    But here’s the nuance most content programs miss: the threshold depends on keyword overlap between the variants. When two pieces of content share fewer than half their target keywords, they almost always help each other. When overlap crosses that threshold, the probability of them hurting each other jumps sharply. The transition isn’t gradual — it’s a cliff.

    That cliff is the single most important constraint in content planning, and almost nobody is testing for it. Most content programs plan by topic relevance and editorial calendar, not by keyword overlap measurement. They produce content that feels differentiated but technically targets the same queries — and then wonder why the newer posts aren’t gaining traction.

    How the Adaptive Pipeline Works

    Instead of producing a fixed number of articles per topic, the system I built evaluates each topic independently and determines how many variants it actually needs. The evaluation considers the breadth of the keyword opportunity, the number of distinct audience segments that need different angles on the same topic, and the overlap between potential variants.

    For a narrow, single-intent topic — like a specific product comparison or a straightforward FAQ answer — the system might determine that one article is sufficient. No variants needed. For a complex, multi-stakeholder topic — like an industry guide that matters differently to business owners, technical staff, and compliance officers — it might generate four or five variants, each targeting different personas with different keyword clusters.

    The key discipline is that every variant must earn its existence. It needs to target a genuinely different keyword set, serve a different audience segment, and approach the topic from an angle that the other variants don’t cover. If a proposed variant can’t clear those thresholds, it doesn’t get created — no matter how editorially interesting it might be.

    Why This Matters for Freelance Consultants

    If you’re managing content strategy for clients, you’re making variant decisions whether you call them that or not. Every time you decide to write another article on a topic a client already covers, you’re creating a variant. The question is whether that variant will build authority or cannibalize it.

    Most freelance consultants make this call based on experience and intuition. And honestly, experienced consultants usually get it right — they can feel when a topic is getting overcrowded on a client’s site. But “feel” doesn’t scale, and it doesn’t protect you when a client asks why their newer posts aren’t performing as well as the older ones.

    Having a system with tested thresholds means you can make content decisions with confidence and explain them to clients with data. “We’re not writing another article on this topic because our analysis shows the existing coverage is optimal. Additional content would compete with what’s already ranking. Instead, we’re expanding into an adjacent topic where there’s genuine opportunity.” That’s a conversation that builds trust and demonstrates expertise.

    The Refresh-First Principle

    The modeling also reveals something that changes content strategy fundamentally: refreshing and expanding existing content plus adding targeted variants delivers dramatically better results per hour of effort than creating entirely new topic clusters from scratch. The gap is significant — refreshing existing authority is simply more efficient than building new authority from zero.

    This doesn’t mean you never create new content. It means your default should be to look at what already exists, determine if it can be strengthened and expanded, and only start new clusters when there’s a genuine gap in coverage. For freelance consultants, this is powerful — it means you can deliver measurable improvements without an endless content treadmill. Your clients get better results from less new content, which is both more efficient and more sustainable.

    What I Bring to This

    When I plug into a freelance consultant’s operation, content planning is one of the layers. I audit the client’s existing content, map topic clusters, identify where variants would help and where they’d hurt, and build a content roadmap that maximizes authority per piece of content published. No wasted articles. No cannibalization surprises. No “let’s just keep publishing and see what happens.”

    The adaptive pipeline runs alongside your content strategy, not instead of it. You still decide the topics, the voice, the editorial direction. I add the analytical layer that determines quantity, overlap management, and variant architecture. The goal is making every piece of content you create or commission work as hard as it possibly can — and knowing when the right answer is “don’t create this one.”

    Frequently Asked Questions

    How do you measure keyword overlap between two articles?

    By comparing the target keyword sets — both primary and secondary keywords each piece targets. The overlap percentage is the intersection of those sets divided by the union. Tools like Ahrefs or SEMrush can identify which keywords a page ranks for, providing the data for overlap calculation. The critical threshold is keeping overlap below 50% between any two pieces in a variant set.

    What happens if a client already has cannibalization problems?

    That’s actually a common starting point. I audit the existing content, identify which pieces are competing against each other, and recommend consolidation or differentiation. Sometimes the right move is merging two thin articles into one comprehensive piece. Sometimes it’s repositioning one to target a different keyword set. The diagnostic comes first, then the remedy.

    Does this approach work for small sites with limited content?

    Small sites benefit the most from disciplined content planning because every article matters more. With a limited content budget, you can’t afford to waste a piece on a variant that cannibalizes an existing winner. The adaptive approach ensures that every article a small site publishes targets a genuine opportunity.

    How does this relate to the AEO and GEO optimization layers?

    They’re interconnected. The variant pipeline determines what content to create. AEO optimization structures that content for featured snippet and answer engine visibility. GEO optimization makes it citable by AI systems. Schema ties it all together with machine-readable markup. The content planning layer is upstream of everything else — it ensures you’re building the right content before optimizing it for every search surface.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “I Built a Content System That Knows When to Stop: Why More Articles Isnt Always the Answer”,
    “description”: “An adaptive content pipeline with tested guardrails that determines exactly how many variants a topic needs — and when additional content starts hurting instead”,
    “datePublished”: “2026-04-03”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/i-built-a-content-system-that-knows-when-to-stop-why-more-articles-isnt-always-the-answer/”
    }
    }

  • Entity Architecture: Why AI Ignores Small Business Sites

    Entity Architecture: Why AI Ignores Small Business Sites

    Tygart Media / The Signal
    Broadcast Live
    Filed by Will Tygart
    Tacoma, WA
    Industry Bulletin

    The Entity Gap Nobody Talks About

    When an AI system evaluates whether to cite your client’s content, one of the first things it assesses is whether the source is a recognized entity. Not a recognized brand in the human sense — a recognized entity in the machine-readable sense. Does this business exist as a structured, identifiable thing in the data layer of the web?

    For most small business websites, the answer is no. The business has a website. It has content. It might even have good content that ranks well. But from an entity perspective — the perspective that AI systems use to evaluate source authority — the business barely exists. There’s no organization schema telling machines who this company is. No person schema establishing the expertise of the people behind the content. No consistent entity signals connecting the website to the Google Business Profile to the social media accounts to the industry directories.

    The business is a ghost in the entity layer. And ghosts don’t get cited.

    What Entity Signals Actually Are

    An entity signal is any structured or consistent piece of information that helps machines identify and understand a real-world thing — a person, a business, a product, a place. The more entity signals a business has, and the more consistent those signals are across the web, the more confidence AI systems have that this is a real, authoritative source.

    The foundational signals are straightforward. Organization schema on the website — the JSON-LD markup that declares “this is a business, here’s its name, address, phone number, logo, founding date, social profiles.” A complete and verified Google Business Profile. Consistent NAP (Name, Address, Phone) data across every directory listing, social profile, and web mention. A knowledge panel in Google search results that aggregates this information into a recognized entity card.

    Beyond the foundation, there are depth signals. Person schema for key team members — establishing individuals as experts with credentials, publications, and professional affiliations. Product or service schema that structures what the business offers. Review schema that aggregates customer feedback. Event schema if the business hosts or participates in industry events.

    Each signal independently is small. Together, they build an entity picture that AI systems can assess when deciding whether this source is authoritative enough to cite.

    Why This Falls Outside Normal SEO Scope

    Traditional SEO doesn’t require entity architecture. You can rank a page without organization schema. You can build backlinks without person markup. You can optimize on-page elements without worrying about NAP consistency across fifty directory listings.

    Entity architecture is infrastructure work. It requires understanding schema.org vocabulary, JSON-LD syntax, Google’s structured data guidelines, knowledge panel optimization, and the web-wide consistency of business information. It also requires ongoing maintenance — schema that was valid last year might need updating as vocabulary evolves, and new web properties need to carry consistent entity signals from day one.

    For a freelance SEO consultant, this is another bandwidth problem. The work matters. You probably don’t have time to do it. And your clients definitely can’t do it themselves.

    What I Build When I Plug In

    Entity architecture is one of the core layers I bring to a freelance consultant’s operation. For each client, I assess the current entity state — what schema exists, what’s missing, how consistent their business information is across the web, whether they have a knowledge panel, and how their entity signals compare to competitors.

    Then I build the architecture. Organization schema goes on the site — comprehensive, not the bare minimum a plugin generates. If the business has key personnel whose expertise matters (which is most service businesses), person schema establishes those individuals as recognized entities with their own expertise signals. Service or product schema structures the business offerings. FAQ schema gets added to relevant pages. Speakable schema marks content that voice assistants can read aloud.

    The entity work extends beyond the website. I audit the client’s Google Business Profile for completeness and consistency with the website schema. I check directory listings for NAP consistency. I identify web properties where entity signals are missing or conflicting. The goal is a unified entity picture that machines can evaluate from any direction — the website, the business profile, the directories, the social accounts — and arrive at the same clear understanding of who this business is and what authority it has.

    The Compound Effect

    Entity architecture compounds over time in ways that individual SEO tactics don’t. Each new piece of content published on a site with strong entity signals starts with a credibility baseline that unstructured content doesn’t have. Each consistent mention of the business across the web reinforces the entity’s authority. Each additional schema type adds a dimension to the entity picture.

    For AI systems in particular, this compounding effect matters. AI models are trained on web data, and consistent entity signals across many sources create stronger associations in those models. A business that has been consistently structured and consistently referenced across the web has a natural advantage in AI citation — not because of a single optimization trick, but because the cumulative entity evidence is overwhelming.

    This is also what makes entity architecture a retention tool. Once built, it creates switching costs. A new SEO consultant would need to understand the architecture, maintain the schema, and preserve the consistency that’s been built. The entity layer becomes part of the client’s digital infrastructure, and the person who built it understands it best.

    What Your Clients Actually Experience

    Clients won’t understand “entity architecture” and they don’t need to. What they experience is tangible: richer search results with star ratings, FAQ dropdowns, and knowledge panel information. Their business appearing in Google’s knowledge panel. Their content getting cited by AI systems. Their voice search presence improving. These are outcomes they can see and show their own stakeholders. The entity architecture is just the mechanism underneath those visible results.

    Frequently Asked Questions

    How long does it take to build entity architecture for a small business?

    The initial build — website schema, Google Business Profile audit, major directory consistency check — typically takes a focused session per client. Ongoing maintenance is lighter: updating schema when content changes, adding markup for new pages, and periodically checking web-wide consistency. The foundational work is frontloaded.

    Do clients with existing Yoast or RankMath schema need a rebuild?

    Usually the plugin-generated schema serves as a starting point that needs significant expansion. SEO plugins add basic Article and Organization markup but miss the strategic schema types — FAQPage, HowTo, Speakable, Person, detailed Product/Service markup — that drive AEO and GEO results. I typically build on top of what exists rather than replacing it entirely.

    Is entity architecture relevant for new businesses with no web presence?

    Absolutely — and arguably more important for them. A new business that launches with proper entity architecture from day one builds entity signals from the start. Established businesses have to retrofit. New businesses can build it into their foundation, which gives them a structural advantage over competitors who’ve been online for years without entity optimization.

  • The Platform Connector Advantage: What Happens When Your SEO Consultant Can Actually Talk to Your Tech Stack

    The Platform Connector Advantage: What Happens When Your SEO Consultant Can Actually Talk to Your Tech Stack

    The Machine Room · Under the Hood

    The Gap Between Analysis and Action

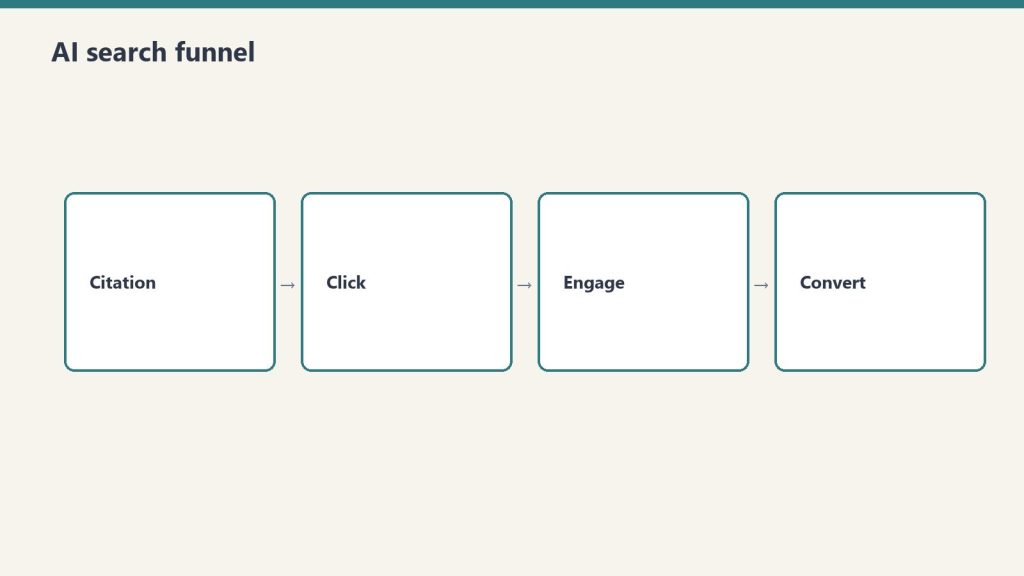
    Four-stage funnel: citation, click, engage, convert
    The gap between analysis and action.

    Every SEO consultant can read analytics. Pull reports. Show charts. Tell you what’s happening with your search traffic. That’s table stakes. The gap that most clients feel — even if they can’t articulate it — is between knowing what’s happening and making the systems do something about it.

    Your website lives on WordPress. Your analytics live in Google. Your business profile lives on Google Business. Your reviews live on half a dozen platforms. Your social presence lives on LinkedIn and Facebook. Your email marketing lives in Mailchimp or Klaviyo. Your project management lives in Notion or Asana. Your phone tracking lives in CallRail or CTM.

    These systems don’t talk to each other by default. And most SEO consultants don’t make them talk to each other either — because that’s not what they were hired to do. They were hired to improve search rankings, and they do. But the data sits in silos. The workflows are manual. The connections between platforms are handled by the client (poorly) or not handled at all.

    I’m the person who connects the platforms. Not just in the “I can read your analytics” sense. In the “I can authenticate with your WordPress API, pull data from your search console, cross-reference it with your content inventory, generate optimization recommendations, implement them directly through the CMS, and report results back through your preferred channel” sense. The entire loop. Platform to platform. Data to action.

    What Platform Connection Actually Looks Like

    Comparison of Claude how-to fit versus local service page fit for assistants
    What platform connection actually looks like.

    Here’s a real workflow. A client’s blog post was published three months ago. It ranks on page two for a high-value keyword. The content is good but hasn’t been optimized for featured snippets, doesn’t have schema markup, and has no internal links connecting it to the rest of the site’s relevant content.

    In a traditional SEO engagement, the consultant would identify this opportunity in a report, recommend changes, and either wait for the client to implement them or provide instructions for a developer. Weeks pass. Maybe it gets done. Maybe it doesn’t.

    In the plugin model, I connect to the WordPress site through the REST API. I pull the post content. I analyze the target keyword’s SERP features — is there a featured snippet, what format, what’s the current holder’s content structure. I restructure the post for snippet capture. I add FAQ schema. I run the internal link analysis across the entire site and inject relevant links. I push the updated post back through the API. The optimization is live before the client even sees the next report.

    That’s not because I’m faster at manual work. It’s because the platforms are connected. WordPress talks to the proxy. The proxy talks to the optimization layer. The optimization layer talks back to WordPress. No manual handoffs. No waiting for implementation. No lost-in-translation between recommendation and execution.

    The Proxy Architecture

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The proxy architecture for connected SEO ops.

    One of the things I built early on was a secure API proxy that routes all WordPress communication through a single cloud endpoint. This might sound like a technical detail, but it solves a practical problem that matters to freelance consultants and their clients.

    Without the proxy, connecting to a client’s WordPress site means either getting hosting access (which clients are rightfully cautious about) or working directly against their site’s IP (which can trigger security rules). The proxy eliminates both concerns. I authenticate with a WordPress application password — something the client can create in two minutes and revoke instantly — and all API traffic routes through the proxy. No hosting access needed. No IP whitelisting. No security concerns about direct server connections.

    This architecture also scales. Whether I’m working on one client site or twenty, the proxy handles the routing. Each site has its own credentials stored in a secure registry. The optimization skills run against any connected site through the same interface. For a freelance consultant adding five new clients over the course of a year, the infrastructure just works — no new setup, no new tools, no new complications.

    Beyond WordPress: The Full Stack

    The platform connection advantage extends beyond WordPress. I work with Google’s APIs for Search Console data, Analytics integration, and Business Profile management. I connect to Notion for project management and content planning workflows. I work with social media scheduling platforms for content distribution. I build automated workflows that connect these systems — a new blog post triggers a social media draft, a ranking change triggers a content refresh recommendation, a client inquiry triggers a research workflow.

    For a freelance SEO consultant, this means the operational overhead of multi-platform management collapses. You don’t need to log into six different tools to understand a client’s situation. The platforms talk to each other through automation, and the insights surface where they’re useful — not buried in a dashboard nobody checks.

    Why This Matters for Your Client Relationships

    Clients notice when things just work. When a recommendation becomes reality without a three-week implementation delay. When data from one platform informs action on another without manual bridging. When their SEO consultant seems to have visibility into everything, not just search rankings.

    That’s not magic. It’s platform connectivity. And it’s one of the most undervalued capabilities in the freelance SEO space — because most consultants are analysts, not system integrators. They’re great at interpretation and strategy. They’re not wired to build the automation and API connections that turn strategy into execution.

    That’s fine. That’s what the plugin model is for. You bring the strategy, the client relationships, and the SEO expertise. I bring the platform connections, the automation, and the execution infrastructure. Together, the client gets a service that’s deeper and more responsive than either of us could deliver alone.

    Frequently Asked Questions

    What if my client uses platforms you don’t have connectors for?

    The core stack covers WordPress, Google’s ecosystem, major analytics platforms, and common marketing tools. If a client uses a niche platform, I’ll evaluate whether API access exists and build a connector if it’s feasible. The architecture is extensible — adding new platform connections is part of the ongoing work, not a limitation.

    Does the client need to do anything technical to enable these connections?

    Minimal. The most common ask is creating a WordPress application password, which takes about two minutes in their WordPress admin panel. For Google integrations, it’s authorizing access through their existing Google account. Nothing requires developer skills or hosting access.

    How do you ensure client data stays secure across all these connections?

    All API traffic routes through a secure cloud proxy with authentication at every layer. Credentials are stored in an encrypted registry, not in plaintext. Each client connection uses its own application password that can be revoked independently. There’s no shared access between clients, and no credentials are stored on local machines. The architecture was designed for security from the start, not bolted on after the fact.

    Can I see what’s being done on my clients’ sites through these connections?

    Everything is documented and transparent. Every optimization pass generates a record of what changed. You have full visibility into what was modified, when, and why. If you want real-time notifications of changes, we can set that up. The goal is you having complete confidence in what’s happening on your clients’ properties.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “The Platform Connector Advantage: What Happens When Your SEO Consultant Can Actually Talk to Your Tech Stack”,
    “description”: “Most SEO consultants analyze data. This one connects the platforms, automates the workflows, and builds the bridges between your tools and your content.”,
    “datePublished”: “2026-04-03”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/the-platform-connector-advantage-what-happens-when-your-seo-consultant-can-actually-talk-to-your-tech-stack/”
    }
    }

  • Scale Freelance SEO: Why the Plugin Model Beats Hiring

    Scale Freelance SEO: Why the Plugin Model Beats Hiring

    The Machine Room · Under the Hood

    The Ceiling Every Freelancer Hits

    You know the math. You can serve a certain number of clients well. Beyond that number, quality drops, response times stretch, and the work that differentiates you — the strategic thinking, the analysis, the creative problem-solving — gets squeezed out by the operational grind of managing deliverables across too many accounts.

    The traditional answer is to hire. Bring on a junior SEO. Outsource content writing. Contract a developer for technical work. Each hire solves one problem and creates three others: management overhead, quality control, communication complexity, and the fixed cost of carrying people whether the client volume justifies it or not.

    The plugin model offers a different answer. Instead of hiring people to do more of what you already do, you plug in capability that does what you can’t do alone. The distinction matters. Hiring scales your current capacity. The plugin model scales your capability stack. One gives you more hands. The other gives you deeper reach.

    How Capability Scales Differently Than Capacity

    When you hire a junior SEO, you can serve more clients with the same service. That’s capacity scaling. The work each client gets is the same — keyword research, on-page optimization, content recommendations, reporting. You just have more of it being produced.

    When you plug in an AEO/GEO/schema/content architecture layer, every client gets a deeper service. That’s capability scaling. The work each client gets is fundamentally expanded — not just rankings, but featured snippet optimization, AI citation positioning, structured data architecture, adaptive content planning, entity signal building. You didn’t add a person. You added an entire capability stack.

    The economics work differently too. A hire costs you whether you have two clients or twenty. The plugin model flexes. Two clients means a smaller engagement. Twenty clients means a larger one. The cost aligns with the revenue, not with a salary that needs to be fed regardless of volume.

    What Stays the Same

    At two clients, you’re the strategist, the relationship manager, and the primary point of contact. At twenty clients, you’re the same thing. That doesn’t change. What changes is the depth of work happening underneath your strategy — work that’s being handled by the plugin layer rather than by you directly.

    Your clients experience a consistent, deep service at every scale. The consultant with three clients delivers the same AEO, GEO, schema, and content architecture quality as the consultant with fifteen. Because the quality comes from the system and the expertise behind it, not from the consultant trying to manually implement everything themselves.

    This is the part that experienced freelancers appreciate most. You built your business on relationships and strategic thinking. Those are your competitive advantages. The plugin model protects those advantages by keeping the implementation work off your plate — letting you stay in the strategy seat where you belong, regardless of how many clients are in the portfolio.

    The Growth Path Without the Growth Pain

    Most freelance consultants face a fork in the road around the five to eight client mark. Path one: stay small, limit client count, keep everything under personal control. Path two: grow by hiring, accept management overhead, and become a micro-agency whether you wanted to or not.

    The plugin model opens a third path: grow your client count while expanding your capability stack, without hiring and without sacrificing quality. You take on client nine, ten, eleven — and each one gets the same deep service because the implementation infrastructure scales with you.

    This third path preserves what most freelancers actually want: autonomy, quality, and meaningful work without the management burden of running an agency. You stay a consultant. You keep the lifestyle and the control. But your service depth rivals firms five times your size.

    The Practical Mechanics

    Each new client follows the same onboarding pattern. You share the WordPress application password. I add the site to the secure registry. The optimization chain connects. From that point, the site gets the full stack — AEO, GEO, schema, content architecture, internal linking — on whatever cadence makes sense for the engagement.

    There’s no minimum. No commitment to a certain number of sites. No penalty for scaling down if a client leaves. The model flexes in both directions because the infrastructure was built to handle variable load. The same proxy, the same skill chain, the same quality standards — whether the portfolio has two sites or twenty.

    For the consultant, the operational overhead of adding a client is minimal. The heavy lifting — the technical optimization, the schema implementation, the content analysis, the AI citation work — is handled by the plugin layer. You focus on strategy, communication, and the relationship. The depth happens underneath.

    What This Means for Your Pricing

    When you can offer a deeper service without proportionally more personal hours, your pricing conversation changes. You’re not selling time — you’re selling capability. A client paying you for SEO plus AEO, GEO, schema architecture, and adaptive content planning is paying for a fundamentally more valuable service than SEO alone. Your rate reflects the expanded value, not the expanded hours.

    The plugin layer operates as a cost within your margin, similar to any professional tool or service you use. You set the client-facing rate based on the value delivered. The specifics of the internal economics are between you and your operation — your client sees a comprehensive service at a rate that reflects comprehensive results.

    Frequently Asked Questions

    Is there a point where I’d outgrow the plugin model and need to hire?

    Potentially — if you want to build an agency with multiple strategists serving different client verticals, you’ll eventually need people. But the plugin model can support a surprisingly large portfolio for a solo consultant because the implementation bottleneck is removed. Many consultants find the ceiling is much higher than they expected once the implementation work is handled externally.

    How do I handle client communication about the expanded services?

    You present it as your service. The plugin model is white-label by default — your clients see expanded capabilities delivered by you. Whether you explain that you have a specialized partner or present it as your own infrastructure is your call. Most freelancers prefer to keep it simple: “I’ve expanded my service capabilities to include AI search optimization, schema architecture, and content intelligence.”

    What if I lose several clients at once — am I stuck with costs?

    No. The model scales down as easily as it scales up. There’s no fixed overhead that continues when client volume drops. If your portfolio shrinks, the engagement adjusts proportionally. You’re never carrying costs for capability you’re not using.

    Can I start with just one client to test the model before expanding?

    That’s the recommended approach. Start with one client — ideally one where you see clear opportunity for AEO, GEO, or schema improvement. See the results. Build confidence in the workflow. Then expand to additional clients at whatever pace makes sense for your business.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “Two Clients or Twenty: Why the Plugin Model Scales Where Hiring Doesnt”,
    “description”: “Freelance SEO consultants hit a ceiling when client count outpaces capacity. The plugin model adds capability without adding overhead — at any scale.”,
    “datePublished”: “2026-04-03”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/two-clients-or-twenty-why-the-plugin-model-scales-where-hiring-doesnt/”
    }
    }

  • The $0 Automated Marketing Stack: AI Video Breakdown

    The $0 Automated Marketing Stack: AI Video Breakdown

    The Lab · Tygart Media
    Experiment Nº 469 · Methodology Notes
    METHODS · OBSERVATIONS · RESULTS

    This video was generated from the original Tygart Media article using NotebookLM’s audio-to-video pipeline — a live demonstration of the exact AI-first workflow we describe in the piece. The article became the script. AI became the production team. Total production cost: $0.


    Watch: The $0 Automated Marketing Stack

    The $0 Automated Marketing Stack — Full video breakdown. Read the original article →

    What This Video Covers

    Comparison of Claude how-to fit versus local service page fit for assistants
    What this automated marketing stack video covers.

    Most businesses assume enterprise-grade marketing automation requires enterprise-grade budgets. This video walks through the exact stack we use at Tygart Media to manage SEO, content production, analytics, and automation across 18 client websites — for under $50/month total.

    The video breaks down every layer of the stack:

    • The AI Layer — Running open-source LLMs (Mistral 7B) via Ollama on cheap cloud instances for $8/month, handling 60% of tasks that would otherwise require paid API calls. Content summarization, data extraction, classification, and brainstorming — all self-hosted.
    • The Data Layer — Free API tiers from DataForSEO (5 calls/day), NewsAPI (100 requests/day), and SerpAPI (100 searches/month) that provide keyword research, trend detection, and SERP analysis at zero recurring cost.
    • The Infrastructure Layer — Google Cloud’s free tier delivering 2 million Cloud Run requests/month, 5GB storage, unlimited Cloud Scheduler jobs, and 1TB of BigQuery analysis. Enough to host, automate, log, and analyze everything.
    • The WordPress Layer — Self-hosted on GCP with open-source plugins, giving full control over the content management system without per-seat licensing fees.
    • The Analytics Layer — Plausible’s free tier for privacy-focused analytics: 50K pageviews/month, clean dashboards, no cookie headaches.
    • The Automation Layer — Zapier’s free tier (5 zaps) combined with GitHub Actions for CI/CD, creating a lightweight but functional automation backbone.

    The Philosophy Behind $0

    This isn’t about being cheap. It’s about being strategic. The video explains the core principle: start with free tiers, prove the workflow works, then upgrade only the components that become bottlenecks. Most businesses pay for tools they don’t fully use. The $0 stack forces you to understand exactly what each layer does before you spend a dollar on it.

    The upgrade path is deliberate. When free tier limits get hit — and they will if you’re growing — you know exactly which component to scale because you’ve been running it long enough to understand the ROI. DataForSEO at 5 calls/day becomes DataForSEO at $0.01/call. Ollama on a small instance becomes Claude API for the reasoning-heavy tasks. The architecture doesn’t change. Only the throughput does.

    How This Video Was Made

    Four-stage funnel: citation, click, engage, convert
    How this video was made.

    This video is itself a demonstration of the stack’s philosophy. The original article was written as part of our content pipeline. That article URL was fed into Google’s NotebookLM, which analyzed the full text and generated an audio deep-dive. That audio was then converted to video — an AI-produced visual breakdown of AI-produced content, created from AI-optimized infrastructure.

    No video editor. No voiceover artist. No production budget. The content itself became the production brief, and AI handled the rest. This is what the $0 stack looks like in practice: the tools create the tools that create the content.

    Read the Full Article

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Read the full article behind the stack video.

    The video covers the highlights, but the full article goes deeper — with exact pricing breakdowns, tool-by-tool comparisons, API rate limits, and the specific workflow we use to batch operations for maximum free-tier efficiency. If you’re ready to build your own $0 stack, start there.


    Related from Tygart Media

  • Local AI Stack: How We Replaced a $12K/Mo Tool Budget

    Local AI Stack: How We Replaced a $12K/Mo Tool Budget

    The Machine Room · Under the Hood

    What We Were Paying For (And Why We Stopped)

    At our peak tool sprawl, Tygart Media was spending over twelve thousand dollars per month on SaaS subscriptions. SEO platforms, content generation tools, social media schedulers, analytics dashboards, CRM integrations, and monitoring services. Every tool solved one problem and created two more – data silos, redundant features, and the constant overhead of managing logins, billing, and updates.

    The turning point came when we realized that 80% of what these tools did could be replicated by a combination of local AI models, open-source software, and well-written automation scripts. Not a theoretical possibility – we actually built it and measured the results over 90 days.

    The Local AI Models That Do the Heavy La flooring companyng

    We run Ollama on a standard laptop – no GPU cluster, no cloud compute bills. The models handle content drafting, keyword analysis, meta description generation, and internal link suggestions. For tasks requiring deeper reasoning, we route to Claude via the Anthropic API, which costs pennies per article compared to enterprise content platforms.

    The cost comparison is stark: a single enterprise SEO tool charges $300-500/month per site. We manage 23 sites. Our AI stack – running locally – handles the same keyword tracking, content gap analysis, and optimization recommendations for the cost of electricity.

    The models we rely on most: Llama 3.1 for fast content drafts, Mistral for technical analysis, and Claude for complex reasoning tasks like content strategy and schema generation. Each model has a specific role, and none of them send a monthly invoice.

    The Automation Layer: PowerShell, Python, and Cloud Run

    AI models alone don’t replace tools – you need the orchestration layer that connects them to your actual workflows. We built ours on three technologies:

    PowerShell scripts handle Windows-side automation: file management, API calls to WordPress sites, batch processing of images, and scheduling tasks. Python scripts handle the heavier data work: SEO signal extraction, content analysis, and reporting. Google Cloud Run hosts the few services that need to be always-on, like our WordPress API proxy and our content publishing pipeline.

    Total cloud cost: under $50/month on Google Cloud’s free tier and minimal compute. Compare that to the $12K we were spending on tools that did less.

    What We Still Pay For (And Why)

    We didn’t eliminate every subscription. Some tools earn their keep:

    Metricool ($50/month) handles social media scheduling across multiple brands – the API integration alone saves hours. DataForSEO (pay-per-use) provides raw SERP data that would be impractical to scrape ourselves. Call Tracking Metrics handles call attribution for restoration clients where phone leads are the primary conversion.

    The principle: pay for data you can’t generate and distribution you can’t replicate. Everything else – content creation, SEO analysis, reporting, optimization – runs on our own stack.

    The 90-Day Results

    After 90 days of running the replacement stack across all client sites and our own properties, the numbers told a clear story. Content output increased by 340%. SEO performance held steady or improved across 21 of 23 sites. Total monthly tool spend dropped from $12,200 to under $800.

    The hidden benefit: ownership. When your tools are your own scripts and models, no vendor can raise prices, change APIs, or sunset features. You own the entire stack.

    Frequently Asked Questions

    Do you need technical skills to build a local AI stack?

    You need basic comfort with command-line tools and scripting. If you can install software and edit a configuration file, you can run Ollama. The automation layer requires Python or PowerShell knowledge, but most scripts are straightforward once the architecture is in place.

    Can local AI models really match enterprise SEO tools?

    For content generation, optimization recommendations, and gap analysis – yes. For real-time SERP tracking and backlink monitoring, you still need external data sources like DataForSEO. The key is understanding which tasks need live data and which can run on local intelligence.

    What about reliability compared to SaaS tools?

    SaaS tools go down too. Local tools run when your machine runs. For cloud-hosted components, Google Cloud Run has a 99.95% uptime SLA. Our stack has been more reliable than the vendor tools it replaced.

    How long did the migration take?

    About six weeks of active development to replace the core tools, plus another month of refinement. The investment pays for itself in the first billing cycle.

    Build or Buy? Build.

    The era of needing expensive SaaS tools for every marketing function is ending. Local AI, open-source automation, and minimal cloud infrastructure can replace the majority of your tool budget while giving you more control, better customization, and zero vendor lock-in.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “The AI Stack That Replaced Our $12K/Month Tool Budget”,
    “description”: “How we replaced $12K/month in SaaS tools with local AI models, PowerShell automation, and minimal cloud infrastructure.”,
    “datePublished”: “2026-03-21”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/the-ai-stack-that-replaced-our-12k-month-tool-budget/”
    }
    }

  • 387 Cowork Sessions and Counting: What Happens When AI Becomes Your Daily Operating Partner

    387 Cowork Sessions and Counting: What Happens When AI Becomes Your Daily Operating Partner

    The Machine Room · Under the Hood

    This Is Not a Chatbot Story

    Illustration for article: 387 Cowork Sessions and Counting: What Happens When AI Becomes Your Daily Operating Partner
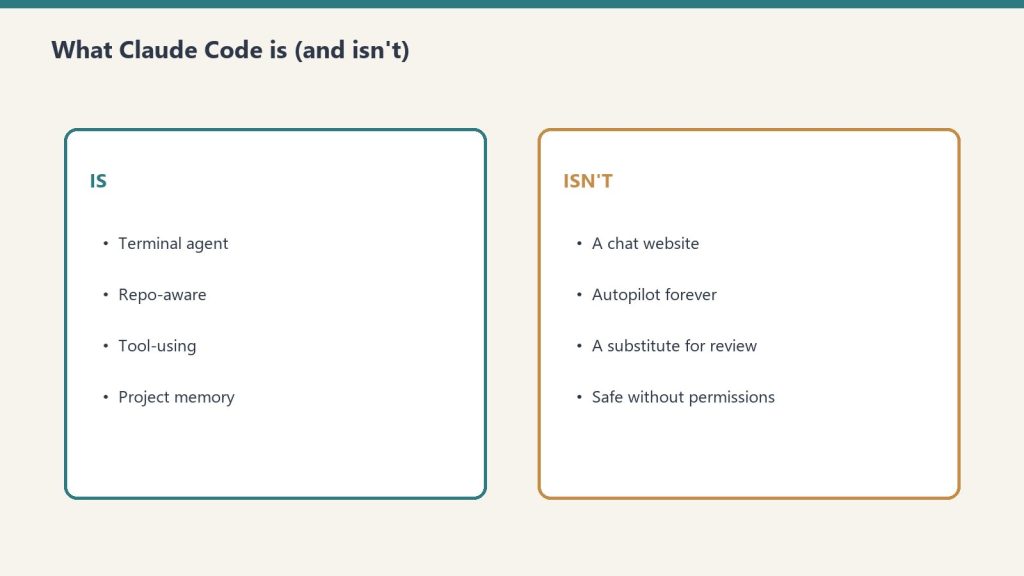
    Side-by-side cards defining what Claude Code is and is not
    This is not a chatbot story.

    When people hear I use AI every day, they picture someone typing questions into ChatGPT and getting answers. That’s not what this is. I’ve run 387 working sessions with Claude in Cowork mode since December 2025. Each session is a full operating environment – a Linux VM with file access, tool execution, API connections, and persistent memory across sessions.

    These aren’t conversations. They’re deployments. Content publishes. Infrastructure builds. SEO audits across 18 WordPress sites. Notion database updates. Email monitors. Scheduled tasks. Real operational work that used to require a team of specialists.

    The number 387 isn’t bragging. It’s data. And what that data reveals about how AI actually integrates into daily business operations is more interesting than any demo or product launch.

    What a Typical Session Actually Looks Like

    Three stacked layers: chat UI, tools, agent runtime
    What a typical session actually looks like.

    A session starts when I open Cowork mode and describe what I need done. Not a vague prompt – a specific operational task. “Run the content intelligence audit on a storm protection company.com and generate 15 draft articles.” “Check all 18 WordPress sites for posts missing featured images and generate them using Vertex AI.” “Read my Gmail for VIP messages from the last 6 hours and summarize what needs attention.”

    Claude loads into a sandboxed Linux environment with access to my workspace folder, my installed skills (I have 60+), my MCP server connections (Notion, Gmail, Google Calendar, Metricool, Figma, and more), and a full bash/Python execution layer. It reads my CLAUDE.md file – a persistent memory document that carries context across sessions – and gets to work.

    A single session might involve 50-200 tool calls. Reading files, executing scripts, making API calls, writing content, publishing to WordPress, logging results to Notion. The average session runs 15-45 minutes of active work. Some complex ones – like a full site optimization pass – run over two hours.

    The Skill Layer Changed Everything

    Early sessions were inefficient. I’d explain the same process every time – how to connect to WordPress via the proxy, what format to use for articles, which Notion database to log results in. Repetitive context-setting that ate 30% of every session.

    Then I started building skills. A skill is a structured instruction file (SKILL.md) that Claude reads at the start of a session when the task matches its trigger conditions. I now have skills for WordPress publishing, SEO optimization, content generation, Notion logging, YouTube watch page creation, social media scheduling, site auditing, and dozens more.

    The impact was immediate. A task that took 20 minutes of back-and-forth setup now triggers in one sentence. “Run the wp-intelligence-audit on a luxury asset lender.com” – Claude reads the skill, loads the credentials from the site registry, connects via the proxy, pulls all posts, analyzes gaps, and generates a full report. No explanation needed. The skill contains everything.

    Building skills is the highest-leverage activity I’ve found in AI-assisted work. Every hour spent writing a skill saves 10+ hours across future sessions. At 387 sessions, the compound return is staggering.

    What 387 Sessions Taught Me About AI Workflow

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What 387 sessions taught me about AI workflow.

    Specificity beats intelligence. The most productive sessions aren’t the ones where Claude is “smartest.” They’re the ones where I give the most specific instructions. “Optimize this post for SEO” produces mediocre results. “Run wp-seo-refresh on post 247 at a luxury asset lender.com, ensure the focus keyword is ‘luxury asset lending,’ update the meta description to 140-160 characters, and add internal links to posts 312 and 418” produces excellent results. AI amplifies clarity.

    Persistent memory is the unlock. CLAUDE.md – a markdown file that persists across sessions – is the most important file in my entire system. It contains my preferences, operational rules, business context, and standing instructions. Without it, every session starts from zero. With it, session 387 has the accumulated context of all 386 before it. This is the difference between using AI as a tool and using AI as a partner.

    Batch operations reveal true ROI. Publishing one article? AI saves maybe 30 minutes. Publishing 15 articles across 3 sites with full SEO/AEO/GEO optimization, taxonomy assignment, internal linking, and Notion logging? AI saves 15+ hours. The value curve is exponential with batch size. I now default to batch operations for everything – content, audits, meta updates, image generation.

    Failures are cheap and informative. At least 40 of my 387 sessions hit significant errors – API timeouts, disk space issues, credential failures, rate limiting. Each failure taught me something that made the system more resilient. The SSH workaround. The WP proxy to avoid IP blocking. The WinError 206 fix for long PowerShell commands. Failure at high volume is the fastest path to robust systems.

    The Numbers Behind 387 Sessions

    I tracked the data because the data tells the real story:

    Content produced: Approximately 400+ articles published across 18 WordPress sites. Each article is 1,200-1,800 words, SEO-optimized, AEO-formatted with FAQ sections, and GEO-ready with entity optimization. At market rates for this quality of content, that’s roughly ,000-,000 worth of content production.

    Sites managed: 18 WordPress properties across multiple industries – restoration, luxury lending, cold storage, interior design, comedy, training, technology. Each site gets regular content, SEO audits, taxonomy fixes, schema injection, and internal linking.

    Automations built: 7 autonomous AI agents (the droid fleet), 60+ skills, 3 scheduled tasks, a GCP Compute Engine cluster running 5 WordPress sites, a Cloud Run proxy for WordPress API routing, and a Vertex AI chatbot deployment.

    Time investment: Approximately 200 hours of active session time over three months. For context, a single full-time employee working those same 200 hours could not have produced a fraction of this output, because the bottleneck isn’t thinking time – it’s execution speed. Claude executes API calls, writes code, publishes content, and processes data at machine speed. I provide direction at human speed. The combination is multiplicative.

    Why Most People Won’t Do This

    The honest answer: it requires upfront investment that most people aren’t willing to make. Building the skill library took weeks. Configuring the MCP connections, setting up the proxy, provisioning the GCP infrastructure, writing the CLAUDE.md context file – that’s real work before you see any return.

    Most people want AI to be plug-and-play. Type a question, get an answer. And for simple tasks, it is. But for operational AI – AI that runs your business processes daily – the setup cost is significant and the learning curve is real.

    The payoff, though, is not incremental. It’s categorical. I’m not 10% more productive than I was before Cowork mode. I’m operating at a fundamentally different scale. Tasks that would require hiring 3-4 specialists – content writer, SEO analyst, site admin, automation engineer – are handled in daily sessions by one person with a well-configured AI partner.

    That’s not a productivity hack. That’s a structural advantage.

    Frequently Asked Questions

    What is Cowork mode and how is it different from regular Claude?

    Cowork mode is a feature of Claude’s desktop app that gives Claude access to a sandboxed Linux VM, file system, bash execution, and MCP server connections. Regular Claude is a chat interface. Cowork mode is an operating environment where Claude can read files, run code, make API calls, and produce deliverables – not just text responses.

    How much does running 387 sessions cost?

    Cowork mode is included in the Claude Pro subscription at /month. The MCP connections (Notion, Gmail, etc.) use free API tiers. The GCP infrastructure runs about /month. Total cost for three months of operations: approximately . The value produced is orders of magnitude higher.

    Can someone replicate this without technical skills?

    Partially. The basic Cowork mode works out of the box for content creation, research, and file management. The advanced setup – custom skills, GCP infrastructure, API integrations – requires comfort with command-line tools, APIs, and basic scripting. The barrier is falling fast as skills become shareable and MCP servers become plug-and-play.

    What’s the most impactful single skill you’ve built?

    The wp-site-registry skill – a single file containing credentials and connection methods for all 18 WordPress sites. Before this skill existed, every session required manually providing credentials. After it, any wp- skill can connect to any site automatically. It turned 18 separate workflows into one unified system.

    What Comes Next

    Session 387 is not a milestone. It’s a Tuesday. The system compounds. Every skill I build makes future sessions faster. Every failure I fix makes the system more resilient. Every batch I run produces data that informs the next batch.

    The question I get most often is “where do you start?” The answer is boring: start with one task you do repeatedly. Build one skill for it. Run it 10 times. Then build another. By session 50, you’ll have a system. By session 200, you’ll have an operating partner. By session 387, you’ll wonder how you ever worked without one.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “387 Cowork Sessions and Counting: What Happens When AI Becomes Your Daily Operating Partner”,
    “description”: “I’ve run 387 Cowork sessions with Claude in three months. Not chatbot conversations – full working sessions that build skills, publish content, mana”,
    “datePublished”: “2026-03-21”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/387-cowork-sessions-and-counting-what-happens-when-ai-becomes-your-daily-operating-partner/”
    }
    }

  • The SEO Drift Detector: How I Built an Agent That Watches 18 Sites for Ranking Decay

    The SEO Drift Detector: How I Built an Agent That Watches 18 Sites for Ranking Decay

    Tygart Media / The Signal
    Broadcast Live
    Filed by Will Tygart
    Tacoma, WA
    Industry Bulletin

    Rankings Don’t Crash – They Drift

    Illustration for article: The SEO Drift Detector: How I Built an Agent That Watches 18 Sites for Ranking Decay
    GEO versus SEO comparison cards
    Rankings do not crash — they drift.

    Nobody wakes up to a sudden SEO catastrophe. What actually happens is slower and more insidious. A page that ranked #4 for its target keyword three months ago is now #9. Another page that owned a featured snippet quietly lost it. A cluster of posts that drove 40% of a site’s organic traffic has collectively slipped 3-5 positions across 12 keywords.

    By the time you notice, the damage is done. Traffic is down 25%. Leads have thinned. And the fix – refreshing content, rebuilding authority, reclaiming positions – takes weeks. The problem with SEO drift isn’t that it’s hard to fix. It’s that it’s hard to see.

    I manage 18 WordPress sites across industries ranging from luxury lending to restoration services to cold storage logistics. Manually checking keyword rankings across all of them? Impossible. Waiting for Google Search Console to show a decline? Too late. So I built SD-06 – the SEO Drift Detector – an autonomous agent that monitors keyword positions daily, calculates drift velocity, and flags pages that need attention before the traffic impact hits.

    How SD-06 Works Under the Hood

    Four-stage funnel: citation, click, engage, convert
    How the drift detector works under the hood.

    The architecture connects three systems: DataForSEO for ranking data, a local SQLite database for historical tracking, and Slack for alerts.

    Every morning at 6 AM, SD-06 runs a scheduled Python script that pulls current ranking positions for tracked keywords across all 18 sites. DataForSEO’s SERP API returns the current Google position for each keyword-URL pair. The script stores these daily snapshots in a SQLite database – one row per keyword per day, with fields for position, URL, SERP features present (featured snippet, People Also Ask, local pack), and the date.

    With 30+ days of historical data, the agent calculates three metrics for each tracked keyword:

    Position delta (7-day): The difference between today’s position and the position 7 days ago. A keyword that moved from #5 to #8 has a delta of -3. Simple, fast, catches sudden drops.

    Drift velocity (30-day): The average daily position change over the last 30 days. This is the metric that catches slow decay. A keyword losing 0.1 positions per day doesn’t trigger any single-day alarm, but over 30 days that’s a 3-position drop. SD-06 calculates this as a rolling regression slope and flags anything with negative drift velocity exceeding -0.05 positions per day.

    Feature loss: Did this URL have a featured snippet, PAA box, or other SERP feature last week that it no longer holds? Feature loss often precedes position loss – it’s an early warning signal that content freshness or authority is slipping.

    The Alert System That Changed My Workflow

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The alert system that changed the workflow.

    SD-06 sends three types of Slack alerts:

    Red alert (immediate attention): Any keyword that dropped 5+ positions in 7 days, or any URL that lost a featured snippet it held for 14+ consecutive days. These are rare but critical – usually indicating a technical issue, a Google algorithm update, or a competitor publishing a significantly better page.

    Yellow alert (weekly review): Keywords with negative drift velocity exceeding the threshold but no single dramatic drop. These are bundled into a weekly digest every Monday morning. The digest includes the keyword, current position, 30-day trend direction, the affected URL, and a recommended action (refresh content, add internal links, update statistics, or expand the article).

    Green report (monthly summary): A full portfolio health report showing total tracked keywords, percentage dra flooring companyng negative vs. positive, top gainers, top losers, and overall portfolio trajectory. This is the report I share with clients to show proactive SEO management.

    The critical insight was making the recommended action part of every alert. An alert that says “keyword X dropped 3 positions” is information. An alert that says “keyword X dropped 3 positions – recommend refreshing the statistics section and adding 2 internal links from recent posts” is a task I can execute immediately. SD-06 generates these recommendations using simple rules based on what type of drift it detects.

    What 90 Days of Drift Data Revealed

    After running SD-06 for three months across all 18 sites, the data patterns were illuminating.

    Content age is the #1 drift predictor. Posts older than 18 months drift negative at 3x the rate of posts under 12 months old. This isn’t surprising – Google rewards freshness – but the magnitude was larger than expected. It means my content refresh cadence needs to target any post approaching the 18-month mark, not waiting for visible ranking loss.

    Internal linking density correlates with drift resistance. Pages with 5+ inbound internal links from other site content drifted negative 60% less frequently than pages with 0-2 internal links. Orphan pages – content with zero inbound internal links – were the fastest to lose rankings. This validated my investment in the wp-interlink skill that systematically adds internal links across every site.

    Featured snippet loss is a 2-week leading indicator. When a page loses a featured snippet, it loses 2-5 organic positions within the following 14 days approximately 70% of the time. This made featured snippet monitoring the most valuable early warning signal in the entire system. When SD-06 detects snippet loss, I now have a 2-week window to refresh the content before the position drop fully materializes.

    Competitor content publishing causes measurable drift. Several drift events correlated with competitors publishing fresh content targeting the same keywords. Without SD-06, I would have discovered this weeks later through traffic decline. With it, I can see the drift starting within 3-5 days of the competitor publish and respond immediately.

    The Technical Stack

    DataForSEO API for SERP position tracking. The SERP API costs approximately .002 per keyword check. Tracking 200 keywords daily across 18 sites runs about /month – trivial compared to the SEO tools that charge +/month for similar monitoring.

    SQLite for historical data storage. Lightweight, zero-configuration, file-based database that lives on the local machine. After 90 days of daily tracking across 200 keywords, the database file is under 50MB. No server, no cloud database, no monthly cost.

    Python 3.11 with pandas for data analysis, scipy for regression calculations, and the requests library for API calls. The entire script is under 400 lines.

    Slack Incoming Webhook for alerts, same pattern as the VIP Email Monitor. One webhook URL, formatted JSON payloads, zero infrastructure.

    Windows Task Scheduler triggers the script at 6 AM daily. Could also run as a cron job on Linux or a Cloud Run scheduled task on GCP.

    Why I Didn’t Just Use Ahrefs or SEMrush

    I’ve used both. They’re excellent tools. But they have three limitations for my use case.

    First, cost at scale. Monitoring 18 sites with 200+ keywords each on Ahrefs would cost +/month. SD-06 costs /month in API calls.

    Second, custom alert logic. Ahrefs and SEMrush send generic position change alerts. They don’t calculate drift velocity, predict future position loss based on trajectory, or generate content-specific refresh recommendations. SD-06’s alert intelligence is tailored to how I actually work.

    Third, integration with my existing workflow. SD-06 pushes alerts to the same Slack channel where all my other agents report. It writes recommendations that align with my wp-seo-refresh and wp-content-expand skills. The data flows directly into my operational system rather than living in a separate dashboard I have to remember to check.

    Frequently Asked Questions

    How many keywords should you track per site?

    Start with 10-15 per site – your highest-traffic pages and their primary keywords. Expand to 20-30 after the first month once you understand which keywords actually drive business results. Tracking 100+ keywords per site creates noise without proportional signal. Focus on the keywords that drive revenue, not vanity metrics.

    Can drift detection work without DataForSEO?

    Yes, but with less precision. Google Search Console provides position data with a 2-3 day delay and averages positions over date ranges rather than giving exact daily snapshots. You can build a simpler version using the Search Console API, but the drift velocity calculations will be less granular. DataForSEO provides same-day position data at the individual keyword level.

    How quickly can you reverse SEO drift once detected?

    For content-based drift (stale statistics, outdated information, thin sections), a content refresh typically recovers positions within 2-4 weeks after Google recrawls. For authority-based drift (competitors building more backlinks), recovery takes longer – 4-8 weeks – and requires both content improvement and internal linking reinforcement.

    Does this work for local SEO keywords?

    Absolutely. DataForSEO supports location-specific SERP checks, so you can track “water damage restoration Houston” at the Houston geo-target level. Several of my sites are local service businesses, and the drift patterns for local keywords follow the same trajectory math – they just tend to be more volatile due to local pack algorithm updates.

    The Principle Behind the Agent

    SD-06 exists because of a simple belief: the best time to fix SEO is before it breaks. Reactive SEO – waiting for traffic to drop, then scrambling to diagnose and fix – is expensive, stressful, and often too late. Proactive SEO – monitoring drift in real time and refreshing content before positions collapse – costs almost nothing and preserves the compounding value of content that’s already ranking.

    Every piece of content on a website is a depreciating asset. It starts strong, holds for a while, then slowly loses value as competitors publish newer content and search algorithms reward freshness. SD-06 doesn’t stop depreciation. It tells me exactly which assets need maintenance, exactly when they need it, and exactly what the maintenance should look like. That’s not magic. That’s operations.

    {
    “@context”: “https://schema.org”,
    “@type”: “Article”,
    “headline”: “The SEO Drift Detector: How I Built an Agent That Watches 18 Sites for Ranking Decay”,
    “description”: “Rankings don’t crash overnight – they drift. I built SD-06, an autonomous agent that monitors keyword positions across 18 WordPress sites using Data”,
    “datePublished”: “2026-03-21”,
    “dateModified”: “2026-04-03”,
    “author”: {
    “@type”: “Person”,
    “name”: “Will Tygart”,
    “url”: “https://tygartmedia.com/about”
    },
    “publisher”: {
    “@type”: “Organization”,
    “name”: “Tygart Media”,
    “url”: “https://tygartmedia.com”,
    “logo”: {
    “@type”: “ImageObject”,
    “url”: “https://tygartmedia.com/wp-content/uploads/tygart-media-logo.png”
    }
    },
    “mainEntityOfPage”: {
    “@type”: “WebPage”,
    “@id”: “https://tygartmedia.com/the-seo-drift-detector-how-i-built-an-agent-that-watches-18-sites-for-ranking-decay/”
    }
    }