Claude AI - Tygart Media

Category: Claude AI

Complete guides, tutorials, comparisons, and use cases for Claude AI by Anthropic.

  • Claude Updates September 2026: Fable 5.1, One Claude, Docs & Slides

    Last verified: October 5, 2026 (Pacific Time). The June 2026 edition covered the Fable 5 public launch, the June 15 model retirements, and Managed Agents self-hosted sandboxes.

    Direct Answer (September 2026 Update): September’s biggest move is economic, not a new flagship: Claude Fable 5.1 (released September 1) cuts cache-read pricing 75%, which Anthropic says makes typical workloads about 25% cheaper. The same day brought the restricted-access Mythos 5.1 and Enterprise Frontier Safeguards. Mid-month, Anthropic shipped vertical plugins for financial advisors (Sept 14) and a major small-business expansion (Sept 15), then folded Cowork into a single Claude experience with Docs and Slides in beta (Sept 16).

    September 2026 is Anthropic’s enterprise-monetization month: no new flagship tier, but cheaper agentic workloads, a compliance-ready data story, and the product surface consolidating around one Claude. Here is everything dated, with the numbers and the migration notes.

    Claude Fable 5.1 and Mythos 5.1 — cache reads cut 75% (September 1, 2026)

    Anthropic released Claude Fable 5.1 on September 1, 2026, alongside Claude Mythos 5.1. The two are the same underlying model at different safeguard tiers: Fable 5.1 is generally available; Mythos 5.1 is restricted to vetted organizations through Anthropic’s Project Glasswing trusted-access program, initially in cybersecurity and life-sciences work.

    The headline is pricing, not capability. Base rates are unchanged — $10 per million input tokens, $50 per million output — but cache reads fall from $1.00 to $0.25 per million tokens, a 75% cut. Anthropic’s own estimate: typical workloads get ~25% cheaper, highly agentic ones up to 45%. Treat those as vendor math — the savings scale entirely with how cache-heavy your workload is.

    The practical details:

    • Model ID: claude-fable-5-1
    • Context window: 1M tokens; max output 128K
    • Benchmarks: 52.6% on Terminal-Bench-Science 0.1 (vs 24.7% for Fable 5); 42% → 55.8% on Terminal-Bench 4.0
    • Safeguard friction down: ~60% fewer cybersecurity false positives per Claude Code session; 85% fewer interventions on benign biology and medical requests. Fable 5.1 can identify software vulnerabilities but blocks penetration testing, exploit generation, and binary-based vulnerability scanning
    • Availability: Claude API, Amazon Bedrock, Google Cloud Vertex AI, Microsoft Foundry, and the Claude app
    • Migration is not a string swap: breaking changes include forced tool use, thinking blocks, and edited conversation histories. Prefix-binding enforcement began August 31 for newly created API accounts. Anthropic’s stated retirement horizon: no earlier than September 1, 2027
    • Claude Code 2.1.257 makes Fable 5.1 the default Fable model (gateway aliases excepted)

    Enterprise Frontier Safeguards — phased rollout through fall 2026

    Alongside the models, Anthropic announced Enterprise Frontier Safeguards (EFS), a new security architecture that lets organizations keep monitoring data inside infrastructure they control, with zero-retention options for Fable 5 and 5.1. The company acknowledged that Fable 5’s 30-day data-retention requirement had limited adoption by regulated enterprises — EFS is the answer, rolling out in phases through fall 2026. For healthcare, finance, and legal buyers, this is the compliance unlock that makes the cheaper agentic workloads actually purchasable.

    Provenance tooling: limited-access watermark detection (September 2, 2026)

    On September 2, Anthropic opened a limited-access API that detects invisible watermarks in Claude-generated text. Access is restricted to organizations with a verification mandate — newsrooms, regulators, independent researchers, professional fact-checkers. Regular users and companies embedding Claude don’t get it. The design is deliberate: it gives watchdogs a provenance tool while limiting adversarial probing of the signal.

    Fable 5.1 lands on Claude for Government (September 9, 2026)

    Teresa Carlson, Anthropic’s global head of public sector, announced at the Billington Cybersecurity Summit on September 9 that Fable 5.1 is now available on Claude for Government, the company’s FedRAMP High-authorized platform — meaning any agency requiring FedRAMP High can use it. AWS had made the model available in its US government cloud the prior week. Carlson signaled more government-focused releases in the coming weeks.

    Claude for Financial Advisors (September 14, 2026)

    Anthropic released Claude for Financial Advisors, a plugin bundling connectors to custodians, asset managers, and wealth-tech providers with workflow skills built around an advisor’s day. It’s available to Enterprise customers through the Cowork plugin browser. Connectors include Charles Schwab, BlackRock, Addepar, Envestnet, iCapital, Orion, SS&C Black Diamond, Wealthbox, Wealth.com, Vanguard, and Zocks — alongside existing Microsoft 365, Salesforce, DocuSign, Box, FactSet, S&P Global, and Morningstar integrations. Packaged skills cover advisor onboarding, alternative-investments briefing, compliance and AI-policy review, estate and tax briefing, portfolio-rebalance review, post-meeting notes and follow-up, pre-meeting preparation, and prospect intake. The pattern matches June’s legal vertical bundle: Anthropic is shipping industry-specific integration packs instead of leaving the ecosystem to build them.

    Claude for Small Business: 43 workflows, 27 integrations (September 15, 2026)

    Anthropic expanded Claude for Small Business on September 15, growing the plugin to 43 workflows and adding 27 integrations including Shopify, Salesforce, TikTok, Atlassian, Zoom, Xero, Gusto, Square, Stripe, and Zapier. It runs inside Claude Cowork: owners install the plugin, run /smb-onboard, connect their tools, and pick a task. Every workflow starts in approval mode — Claude drafts and stages the work, then waits for the owner’s approval before anything sends, posts, or pays — and owners can flip a single workflow to autonomous and back. Example workflows: a Monday brief assembling cash position, week-over-week sales, pipeline movement, overdue invoices, and the three things needing the owner; inbound-lead response; branded proposals priced from past jobs; staged marketing campaigns; month-end close. The plugin is available on every paid Claude plan; Anthropic recommends the Team plan for businesses with more than one person. A fall schedule of free in-person workshops, partner webinars, and community-run training ships with it.

    One Claude: Cowork folds in, Docs and Slides launch in beta (September 16, 2026)

    Anthropic announced September 16 that Claude Cowork and Claude chat are merging into a single Claude, rolling out to Pro and Max plans over the coming weeks. No mode to choose: users describe what they need, and Claude decides whether to answer directly or take on the bigger job — research, reports, spreadsheets, presentations — handing back finished, editable files. Two new tools launch in beta for paid users: Claude Docs (create and edit documents inside a conversation) and Claude Slides (generate presentations — editable, downloadable as PowerPoint or PDF, exportable to Google Docs or Microsoft Word, with shareable links across desktop and mobile). Anthropic’s stated reason: users found it frustrating to decide where a task belonged, since work started in one product didn’t carry into the other. The Cowork arc that led here: research preview for Max on macOS (January 12), Pro (January 16), general availability on macOS and Windows (April 9), web and mobile (July 7), memory shared across chat and Cowork in the cloud (August 25).

    Late September: Opus 5.5 and Sonnet 5.5 (September 22–28, 2026)

    After the mid-month product wave, Anthropic shipped the Claude 5.5 family: Opus 5.5 on September 22 at $4 / $20 per million tokens (20% below Opus 5), then Sonnet 5.5 on September 28 at the same $2 / $10 unit price as Sonnet 5. Official sources: anthropic.com/claude-opus-5-5, anthropic.com/claude-sonnet-5-5, and the live rate card on docs pricing.

    Current Claude model lineup and API pricing (October 2026)

    Model Input $/1M Output $/1M Cache read
    Fable 5.1 $10 $50 $0.25
    Opus 5.5 $4 $20 $0.20
    Sonnet 5.5 $2 $10 $0.20
    Haiku 4.5 $1 $5 $0.10

    5-minute cache writes are 1.25× base input; 1-hour writes are 2×. Batch API is 50% off input and output. Full table and seat pricing live on our Claude AI pricing guide.

    What to watch for in October

    • One-Claude rollout: the unified experience continues rolling out to Pro and Max; Docs and Slides are still in beta — watch for GA and Team/Enterprise availability.
    • Enterprise Frontier Safeguards: phased rollout continues through fall 2026; the zero-retention option is the milestone regulated buyers are waiting on.
    • Government releases: more Claude for Government announcements were telegraphed for the coming weeks.
    • IPO watch (reported, not confirmed): Bloomberg and Fortune reporting positions Anthropic for an October 2026 public offering. No official date — treat as rumor until the filing.

    Sources

    Track the AI tools you actually use

    Live, vendor-neutral prices & limits for ChatGPT, Claude, Gemini, Perplexity and more — and we’ll email you the moment your tools change price or limits. Free, no hype. See our live AI model tracker.
  • Sonnet 5’s $3 / $15 Price Move Was Reversed — Still $2 / $10 (October 2026)

    Correction — October 2, 2026: Anthropic reversed course. Sonnet 5 did not move to $3 / $15 on September 1 — it remains $2 / $10 on the first-party API table (batch $1 / $5), and Sonnet 5.5 is the current Sonnet at the same $2 / $10. The September 17 operator note below is preserved as the record of what the card showed then.

    Last refreshed: October 5, 2026 (Pacific)

    Operator note. Verified September 17, 2026 against platform.claude.com/docs/en/about-claude/pricing.

    Sonnet 5 is no longer $2 / $10 on the first-party API table. Anthropic published introductory pricing through August 31, 2026, then the standard rate: $3 per million input tokens and $15 per million output tokens starting September 1, 2026.

    That is a 50% unit-price move on input and output versus the intro card. Sonnet 4.6 was already $3 / $15. The two mid-tier SKUs now share the same list. Cache writes follow the new input rate ($3.75 / MTok for 5-minute writes; $0.30 / MTok cache reads). Batch stays 50% off that list.

    What did not move on this check:

    • Claude Pro $20/mo or $17/mo annual ($200 prepaid)
    • Max 5x $100/mo, Max 20x $200/mo
    • Team Standard $25 monthly / $20 annual; Premium $125 / $100
    • Haiku 4.5 $1 / $5; Opus 5.5 $4 / $20; Fable 5.1 $10 / $50
    • Lineup currency (Oct 2026): Current API list (Oct 2026, verified): Sonnet 5.5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    • Cursor Hobby free, Pro $20, Pro+ $60, Ultra $200, Teams $40/user

    If a workflow was budgeted during the September scare, the meter is back to $2 / $10 — the same as Sonnet 5.5. Haiku 4.5 is still the cheap public list. Live desks: API rates, seats.

  • Claude Usage Limits, File Caps, and the Exact Error Strings (2026)

    Direct answer (5 October 2026): Claude chat usage is not a fixed message count and not an API credit balance. claude.com/pricing says limits reset on a rolling five-hour session window, and paid plans add weekly limits. Pro is at least 5× Free per five-hour session. Max is 5× or 20× Pro per five-hour session. Team Standard is 1.25× Pro per session and Team Premium is 6.25× Pro per session (Help Center Team article, re-read 5 October 2026). File and image ceilings are separate from that meter. The error strings below were already on this page; they were not re-read from Anthropic docs on 5 October 2026. Confirm current seat prices on Claude AI Pricing.

    This page is the limits and errors desk. It does not restate list prices. Official plan names and token rates live on the pricing slug. Current model names live on the model tracker.

    Two different ceilings

    • Seat usage — messages and capacity on Free, Pro, Max, Team Standard, Team Premium, Enterprise. Extra usage on paid chat, when enabled, bills at API rates.
    • Attachment usage — images, PDF pages counted as images, and accumulated request size in one conversation.

    The product strings models already quote

    These are the exact messages showing up in AI search queries. Treat them as product copy, not as Tygart inventions.

    • “You’ve reached the limit for chats that include files or images. Start a new text-only chat or upgrade to continue now.”
    • “Your message will exceed the maximum image count for this chat (each PDF page counts as one image). Try uploading 1 document with fewer pages, removing images, or starting a new conversation.”
    • “This chat has reached the 100-image limit (including PDF pages). Start a new chat to add more.”
    • “Request too large (max 32MB). Accumulated images and attachments in the conversation pushed the request over the limit. Run /compact, or double press Esc to go back and remove attachments.”
    • “Failed to start Claude’s workspace. Not enough disk space to set up the workspace.” Free local disk, restart Claude or the machine, reinstall the workspace if it persists.
    • “Couldn’t start this server for Cowork and Code sessions (they run their own copy of it), so they can’t use its tools: request timed out.” See Cowork not working.

    What to do, in order

    1. Start a new chat if the problem is image count or accumulated attachments. PDF pages count as images.
    2. Run /compact or strip attachments if the request crossed 32MB.
    3. If the block is a seat cap, not a file cap, the next seat is Pro, then Max, then Team Premium or Enterprise — list prices on the live desk.
    4. API workloads do not use this chat meter. Keys and prepaid credits live in the Anthropic Console.

    Related

    Claude Reference Hub · Team plan usage limits · Chrome vs Cowork · Student discount.

  • Grok vs Claude Pricing (October 2026): Seats, API Rates, and the Real Cost Gap

    Grok vs Claude Pricing (October 2026): Seats, API Rates, and the Real Cost Gap

    Last verified: October 6, 2026 (Pacific). API figures from xAI developer pricing and Anthropic model cards. Consumer seat prices vary by store and region — confirm at x.ai and claude.com before you pay.

    Direct answer: Grok is cheaper per token at every comparable rung. Claude is cheaper only if you stay on Sonnet 5.5 ($2/$10) or Haiku 4.5 ($1/$5) and never call Fable. Consumer stickers look inverted: Claude Pro is $20, SuperGrok is about $30. The catch is what the seat includes. Pro does not include Fable. Max includes Fable only up to 50% of the weekly pool. Grok has no public $10/$50 SKU.

    Consumer seats

      Grok (xAI) Claude (Anthropic)
    Free Metered on grok.com and X Metered, Sonnet
    Everyday paid SuperGrok ~$30/mo (X Premium+ bundle ~$40) Pro $20/mo
    Heavy individual Plus ~$100 or Heavy ~$300 Max from $100 (5x or 20x; Help Center lists 20x at $200 on web)
    Team Grok Business ~$30/seat Team ~$20-25/seat annual

    Claude Pro wins the $20 vs $30 sticker. Max 20x (Help Center: $200 on web) undercuts SuperGrok Heavy ($300). They are not the same product: Claude splits models by plan. Fable 5 / 5.1 is included on Max and premium Team/Enterprise seats only, capped at half the weekly bar. Pro and Team Standard pay usage credits from the first Fable token. Details: Fable pricing and plan access and Claude Code limits (Sep 2026).

    API rates per million tokens

    Grok. Official xAI card. Prompts that reach 200k tokens are billed at 2x for the whole request.

    Model In / out Context Cached input
    Grok Build 0.1 $1 / $2 256k $0.20
    Grok 4.3 / 4.20 $1.25 / $2.50 1M $0.20
    Grok 4.5 / 4.6 $2 / $6 500k $0.30-$0.50

    Claude.

    Model In / out Context Cache read
    Haiku 4.5 $1 / $5 200k $0.10
    Sonnet 5.5 (current) $2 / $10 1M $0.20
    Sonnet 5 (legacy) $2 / $10 1M $0.20
    Opus 5.5 (current) $4 / $20 1M $0.20
    Opus 5 (legacy) $5 / $25 1M $0.50
    Fable 5.1 $10 / $50 1M $0.25

    Fable 5.1 headline rates match Fable 5. The Sep 1 change was cache reads: $1.00 to $0.25. A cold Fable call is still the expensive product.

    Same-class pairing

    • Everyday production: Grok 4.3 ($1.25/$2.50) vs Sonnet 5.5 ($2/$10). Grok is cheaper, especially on output.
    • Flagship work: Grok 4.6 ($2/$6) vs Opus 5.5 ($4/$20). Grok still cheaper on list. (Legacy Opus 5 remains $5/$25.)
    • Top shelf: Grok has no $10/$50 public model. Fable 5.1 is 5x Grok 4.6 input and about 8x output.

    Worked example

    10M input + 2M output, no cache, short prompts:

    • Grok 4.6: $20 + $12 = $32
    • Sonnet 5.5: $20 + $20 = $40
    • Opus 5.5: $40 + $40 = $80
    • Opus 5 (legacy): $50 + $50 = $100
    • Fable 5.1: $100 + $100 = $200

    Batch: Claude 50% off on supported models. Grok 20% off on 4.3 / 4.20 only – not on 4.5 / 4.6.

    Rules that are not the rate card

    • Claude subscriptions use two clocks: a rolling 5-hour session and a weekly bucket. Claude Code’s temporary +50% weekly promo ended September 13, 2026 at 11:59 PM PT. Starting September 14, 2026, Help Center (article 15910845): weekly Claude Code limits are permanently 25% higher than the pre-promotion baseline for Pro, Max, Team, and seat-based Enterprise. The 5-hour window does not change.
    • Grok API doubles the request once the prompt hits 200k tokens. Current Claude Sonnet / Opus / Fable cards do not use that surcharge.
    • Cache is the only place Fable 5.1 looks cheap at the top. Reused prefixes at $0.25/MTok. Fresh prompts at $10/$50.

    When to buy which

    Buy Grok for volume, agents, or coding at $2/$6 where Grok 4.6 is enough.

    Buy Claude when the job needs Fable-class long horizon and you will pay for it – or when Sonnet 5.5 at $2/$10 is enough and the team already lives in Claude Code.

    Do not pick from the consumer sticker alone. A $20 Claude Pro seat that immediately burns Fable credits can cost more than a $30 SuperGrok seat that never leaves Grok 4.6.

    FAQ

    Is SuperGrok cheaper than Claude Pro?
    No on the monthly line: Pro is $20, SuperGrok is about $30. Yes on many API workloads, because Grok 4.6 undercuts current Claude flagship Opus 5.5 ($4/$20) and Fable 5.1 by a wide margin.

    Is Claude always more expensive on the API?
    No. Haiku 4.5 and Sonnet 5.5 sit near Grok Build / Grok 4.3. The Claude premium starts at Opus 5.5 ($4/$20; legacy Opus 5 $5/$25) and jumps again at Fable.

    Does Claude Pro include Fable 5.1?
    No. Credits from the first token. Included Fable is Max and premium seats, 50% of weekly limits. See Fable plan access.

    Related: Claude plan pricing · Grok vs Claude (capability comparison – older lineup) · Claude Code limits.


    If you run a restoration or multi-site operation and want the same kind of defensible, versioned standard for your Scope 3 emissions data, see the Restoration Carbon Protocol – the open framework that maps contractor emissions onto the GHG Protocol so commercial clients can actually verify them.

  • Claude for Teachers vs Claude for Education (K-12, Aug 2026)

    Last verified: 9 September 2026.

    Direct Answer (9 September 2026): Claude for Teachers is the U.S. K-12 product (announced 28 August 2026). Claude for Education is the university program. A .edu login is not a Teachers seat. Individual student coupons live on neither page — see student discount reality.

    The split

    Claude for Education Claude for Teachers
    Who Colleges and universities U.S. K-12 schools and districts
    Access Institution signs; users use school email School or district enrollment
    Read first Campus guide Anthropic Teachers announcement / education solutions

    Related: Claude for Education · Student discount · pricing.

  • Zero-Click Marketing: How to Optimize Your Content for AI Summaries (2026)

    Zero-Click Marketing: How to Optimize Your Content for AI Summaries (2026)

    Last refreshed: October 2026

    68% of U.S. Google searches end without a click in 2026. When AI Overviews appear, that rate hits 83%. The question for content-driven businesses is no longer how to rank — it’s how to be cited inside the answer that replaced the click.

    This is a practical guide to structuring content, managing brand entity signals, and measuring visibility in a world where users get their answer before they ever reach your site.


    What Zero-Click Actually Means for Content Businesses

    Two cards: answer shown in overview versus optional click
    What zero-click actually means for content businesses.

    Zero-click doesn’t mean zero value. Brands cited inside AI Overviews earn 35% more organic clicks than uncited brands on the same query. The traffic goes to the cited brand — not to the site that ranks #1 but isn’t cited.

    The data that reframes zero-click as a competition problem, not a traffic problem:

    • 68% of U.S. Google searches are zero-click in 2026 (SparkToro, June 2026, based on Similarweb panel data)
    • When AI Overviews appear, zero-click rate hits 83%
    • Organic CTR for position #1 drops up to 58% when AI Overviews are present (Ahrefs, December 2025 data)
    • Brands cited in AI Overviews earn 35% more organic clicks and 91% more paid clicks versus uncited brands
    • AI-referred visitors convert at 4.4x the rate of traditional organic visitors (Semrush)
    • The overlap between top-10 rankings and AI Overview citations: 17–38% in early 2026, down from 75% in mid-2025

    The conclusion: ranking is no longer sufficient for visibility. A site can rank #1 and not be cited in the AI Overview that answers the query. The two need to be optimized separately.


    How AI Overviews Decide What to Cite

    Comparison of Claude how-to fit versus local service page fit for assistants
    How AI overviews decide what to cite.

    Google’s AI Overview system retrieves web pages in real time, synthesizes a 3–5 sentence answer, and cites 3–6 source pages. The selection criteria weight answer extractability, entity authority, freshness, and structured data — not just ranking position.

    The signals that influence AI Overview citation:

    Answer extractability: The answer to the query must appear in the first 200 words of the page, stated directly. Pages that build toward the answer, providing extensive context before the conclusion, are retrieved for topic relevance but can’t be cited because the extractable answer isn’t there.

    Entity authority: Consistent, factually accurate information about the brand entity across the web — site, LinkedIn, social profiles, third-party mentions — signals that the source is authoritative on the topic. AI systems treat entities with strong external corroboration as more trustworthy.

    Freshness: For fast-changing topics (Claude pricing, AI model capabilities, regulatory changes), recency is a significant weight. A page last updated in 2024 competes poorly against one updated in August 2026 on a query about current Claude pricing.

    Structured data: FAQPage, HowTo, and Article schema markup signals to Google that content is formatted for extraction. Pages with properly implemented schema see measurably higher AI Overview inclusion.

    E-E-A-T signals: Experience, expertise, authoritativeness, trustworthiness. An article written by a named author with a consistent byline and external presence outperforms anonymous content on contested or technical topics.


    Strategy 1: Structure Every Page for Extraction

    Four cards for content, ops, build, and knowledge work with Claude
    Structure every page for extraction.

    Answer-first structure is the single highest-leverage change for AI citation rates. The first paragraph of every article should directly and completely answer the likely query.

    The structure AI systems can extract from:

    H1: [Specific, query-answering title]
    
    [Bold one-sentence direct answer to the query implied by the title]
    
    [Supporting detail — the why, the how, the context]
    
    H2: [First subtopic as a question]
    [Bold answer sentence to the H2 question]
    [Elaboration]
    

    What this means in practice for tygartmedia.com content:

    Every article about Claude pricing, model capabilities, or Anthropic history should open with the factual answer — not a framing sentence, not background, not “in this article we’ll cover.” The answer, stated directly, in the first two sentences.

    The reason this matters beyond GEO: it’s also better for users. Answer-first structure is a discipline that makes content more useful and more likely to be cited. The SEO and GEO benefits are secondary to the writing quality improvement.


    Strategy 2: Build and Maintain the Brand Entity

    AI systems treat brands as entities — named things with verifiable, consistent information across multiple authoritative sources. Building entity authority means making sure that information is consistent, correct, and present everywhere crawlers look.

    Entity checklist for tygartmedia.com:

    On-site signals:

    • Organization schema on every page (name, URL, description, logo, founder, sameAs links)
    • Consistent author byline (“Will Tygart”) on every article
    • Author bio that establishes expertise consistently across all articles
    • Contact and about page with complete, factual business information

    Off-site signals:

    • LinkedIn Company Page with consistent description matching the website
    • Google Business Profile (if applicable) with consistent NAP (name, address, phone)
    • Third-party mentions and citations on authoritative sites in the AI/tech space
    • Social profiles with consistent handles and descriptions

    The consistency requirement: AI systems cross-reference. If the description on LinkedIn says “AI infrastructure for operators” and the website says something different, that inconsistency weakens the entity signal. Everything should say the same thing about the same thing.


    Strategy 3: Implement Structured Data

    FAQPage, Article, and Organization schema markup signals to AI Overviews that content is formatted for extraction. This is not optional in 2026 for sites that depend on search visibility.

    Minimum structured data implementation:

    FAQPage schema on every article with a FAQ section:

    {
      "@context": "https://schema.org",
      "@type": "FAQPage",
      "mainEntity": [{
        "@type": "Question",
        "name": "What is Metricool pricing?",
        "acceptedAnswer": {
          "@type": "Answer",
          "text": "Metricool has a free plan and paid plans starting at the Starter tier. API access requires the Advanced plan or above. Pricing is per brand, not per connected social account."
        }
      }]
    }
    

    Article schema on all editorial content (author, published date, modified date, headline).

    Organization schema site-wide (name, URL, logo, founder, sameAs).

    In Rank Math (the plugin on tygartmedia.com): FAQ blocks in the WordPress editor generate FAQPage schema automatically. Use the Rank Math FAQ block for all FAQ sections rather than plain text. Article schema is enabled site-wide in Rank Math settings.


    Strategy 4: Keep Content Current

    AI retrieval systems weight freshness heavily for fast-changing topics. For any site publishing Claude pricing, model capabilities, or AI tool features, stale content is not just less useful — it actively loses citation ground to fresher sources.

    Freshness implementation:

    • “Last refreshed” date at the top of every article — visible to users and read by crawlers as a freshness signal
    • “What’s new” section in evergreen articles covering frequently updated topics (Claude pricing, model capabilities, Metricool features)
    • Update the modified date in Article schema whenever content is refreshed — not just the publication date
    • Monitor Search Console for queries where the site appears in AI Overviews — freshness issues show up as drops in citation before they show up as ranking drops

    Trigger list for mandatory refreshes on tygartmedia.com:

    • Any Anthropic pricing change
    • Any new Claude model release or deprecation
    • Any Metricool feature update
    • Any change to Anthropic’s Enterprise product structure

    Strategy 5: Earn Third-Party Citations

    AI systems give extra weight to content cited by other authoritative sources. Being linked to or mentioned by other sites publishing on Claude, Anthropic, and AI infrastructure strengthens the entity signals for all related queries.

    Practical approaches:

    Original data and research: Content with specific numbers, benchmarks, and original findings gets cited by others. The Claude pricing breakdowns, benchmark comparisons, and API cost calculations on tygartmedia.com are exactly the type of content other AI publications cite.

    First-mover coverage: Publishing accurate, detailed coverage of Anthropic announcements before or alongside other publications builds a citation pattern over time.

    Expertise-signal content: Content that can only be written from operational experience — running 24 brands in Metricool, building vector DB systems for business documents — earns citations because it’s not replicable from Anthropic’s documentation alone.


    Measuring Zero-Click Performance

    Standard click and session metrics are insufficient for measuring zero-click visibility. The right metrics are AI citation rate, branded search volume trend, and AI-referred conversion rate.

    Measurement framework:

    MetricToolWhat It Measures
    AI Overview appearancesGoogle Search Console (AIO report)Queries where site is cited
    CTR on AIO queriesGSC, filter by AI Overview queriesWhether citations drive clicks
    AI-referred trafficGA4 source filter (ChatGPT, Perplexity)Direct traffic from AI citations
    Branded search volumeGSC, filter by brand termsAwareness from zero-click exposure
    Conversion rate from AI sourcesGA4 segmented by sourceValue of AI citation traffic

    Manual testing protocol: Monthly, ask ChatGPT, Perplexity, and Claude the questions your audience asks — “what is Claude Enterprise pricing,” “how does Metricool API work,” “what is the history of Anthropic” — and record whether tygartmedia.com is cited. This is the most direct feedback loop available and costs nothing.

    If branded search volume is growing while organic clicks are flat or declining, the site is appearing in AI summaries and building awareness without receiving credit in standard traffic metrics. That’s the zero-click pattern working in favor of the brand — and the signal that citation strategy is working.


    Frequently Asked Questions

    What is zero-click search?

    Zero-click search is a search that ends on the results page itself — the user gets their answer from an AI Overview, featured snippet, or knowledge panel and doesn’t click through to any website. In 2026, 68% of U.S. Google searches are zero-click.

    Does zero-click hurt all websites equally?

    No. Sites cited inside AI Overviews and featured snippets earn 35% more organic clicks than uncited sites on the same query. Zero-click hurts uncited sites and benefits cited ones. The competition shifts from ranking to citation.

    What is the difference between GEO and zero-click optimization?

    GEO (Generative Engine Optimization) is the discipline of getting cited inside AI-generated answers from ChatGPT, Perplexity, Gemini, and Claude. Zero-click optimization is specifically about Google search — being cited in AI Overviews and featured snippets. They use the same underlying tactics (answer-first structure, entity signals, structured data, freshness) applied to different surfaces.

    How long does it take to see results from zero-click optimization?

    Plan for 3–6 months of consistent effort before citation rates change meaningfully. AI systems update their citation patterns as they re-index updated content. The fastest wins come from freshness updates on existing high-traffic pages and FAQ schema implementation on pages that already rank.

    Do clicks from AI citations convert differently?

    Yes — significantly. AI search visitors convert at approximately 4.4x the rate of traditional organic visitors (Semrush). The mechanism is intent: users who get a specific answer from an AI Overview and then click through to the cited source are further along in their decision process than typical organic visitors.


    What to Read Next

    Generative Engine Optimization (GEO): 5 Ways to Ensure Your Content Is Cited by AI Overviews 

    History of Anthropic

    Claude AI Pricing — All Plans and API Rates

     Metricool Review 2026: The Social Media Tool for Multi-Brand Operations

  • Beyond the Chatbox: 10 Practical Use Cases for Claude Managed Agents (2026)

    Beyond the Chatbox: 10 Practical Use Cases for Claude Managed Agents (2026)

    Last refreshed: August 2026

    Claude Managed Agents launched in public beta April 8, 2026. Memory for Managed Agents entered public beta April 23, 2026. Together they change what a Claude agent can do: instead of starting fresh on every session, an agent can carry context, corrections, and learned preferences across every future interaction with the same user, team, or project.

    This is a use-case guide, not a feature overview. Each case below is role-specific, grounded in how Managed Agents memory actually behaves in production, and paired with what to configure to make it work.


    How Managed Agents Memory Works

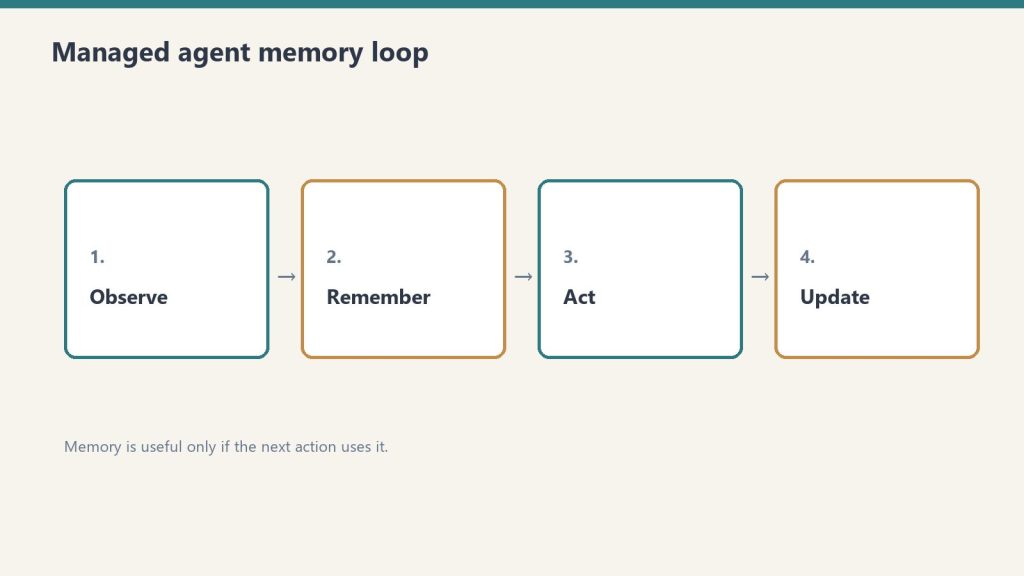
    Four-step loop: observe, remember, act, update for managed agents
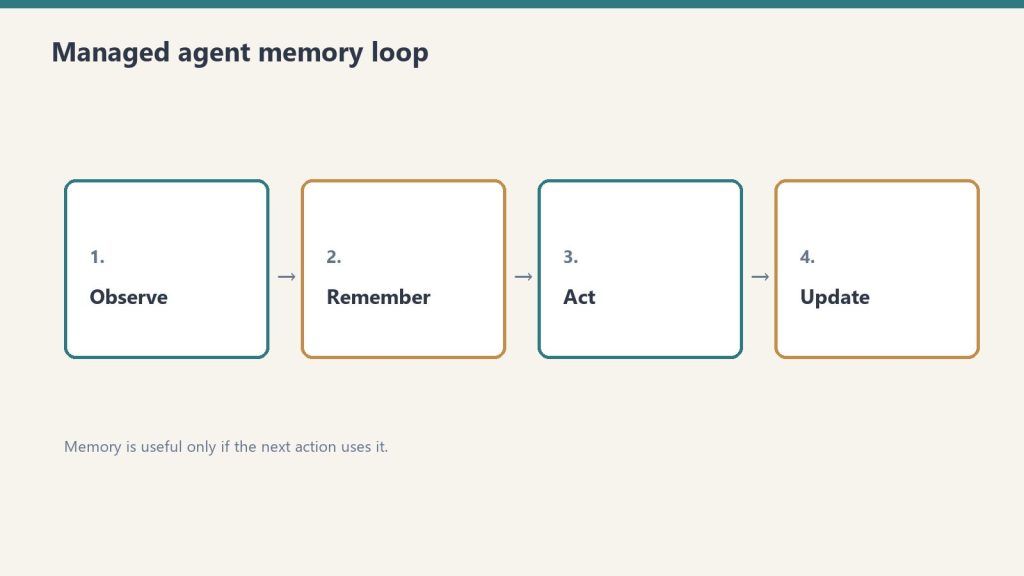
    How managed agent memory actually loops.

    Memory is a workspace-scoped collection of text documents that mounts inside the agent’s session container at /mnt/memory/. The agent reads and writes it using the same file tools it uses for everything else. When the session ends, the memory persists. The next session starts with it already there.

    Key properties:

    • Version-controlled per write — every write creates a new version with an audit trail in the Claude Console
    • Workspace-scoped — accessible to all agents in the same workspace, not per-user-only (unless you scope it that way in configuration)
    • Readable by the agent, not just the operator — the agent can query its own memory store to retrieve past context
    • 30-day version retention — historical versions retained for 30 days with redact endpoint for compliance removal

    The API header required: managed-agents-2026-04-01 for session endpoints; agent-memory-2026-07-22 for memory store endpoints (don’t combine them on memory store calls — this returns a 400 error).


    Use Case 1: Client Account Agent (Account Management)

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    Client account agent — memory for the relationship, not just the chat.

    An account agent that knows each client’s preferences, pain points, prior decisions, and communication style — without needing to be re-briefed at the start of every session.

    What gets stored in memory:

    • Client brand voice and style notes
    • Recurring issues or requests
    • Prior project decisions and the rationale behind them
    • Delivery preferences and approval workflows

    Production example: Wisedocs built a document verification pipeline on Managed Agents and used cross-session memory to let agents identify and remember common document issues — including ones not anticipated at setup. Result: 30% faster verification per document.

    Configuration approach:

    • One memory store per client, named /clients/[client-name]/
    • Initialize with brand guidelines, contact notes, and a log of past decisions
    • Agent writes a session summary to memory at the end of each engagement

    Use Case 2: Development Team Agent (Software Teams)

    A coding agent that learns the codebase conventions, preferred patterns, past architectural decisions, and recurring issues for a specific project — so it doesn’t give the same wrong suggestion twice.

    What gets stored in memory:

    • Coding style guide for the project
    • Past refactoring decisions and why certain approaches were rejected
    • Known issues and workarounds in the codebase
    • Performance constraints and architectural boundaries

    The problem this solves: agents without memory re-suggest patterns the team already evaluated and rejected, requiring the same explanation each session. With memory, those rejections are logged and the agent builds on them.

    Configuration approach:

    • Memory store scoped to the project repository
    • Initialize with project conventions and architecture notes
    • Agent writes a session_log.md after each coding session with decisions made and issues found

    Use Case 3: Research Agent (Knowledge Work)

    A research agent that accumulates findings across sessions — building a persistent knowledge base from multiple research runs rather than starting from scratch each time.

    Netflix’s internal agents use memory to carry context across sessions, including insights that took multiple turns to surface and corrections from human reviewers mid-conversation, instead of manually updating prompts between sessions.

    What gets stored in memory:

    • Research findings with source attribution
    • Hypotheses confirmed or ruled out
    • Sources already evaluated (to avoid re-reviewing them)
    • Running list of open questions

    Configuration approach:

    • Memory organized by topic: /research/[topic]/findings.md, /research/[topic]/sources.md, /research/[topic]/open_questions.md
    • Agent reads existing findings at session start before beginning new research
    • Human reviewer can add corrections directly to memory files via the API; agent picks them up next session

    Use Case 4: Operations Agent (Business Operations)

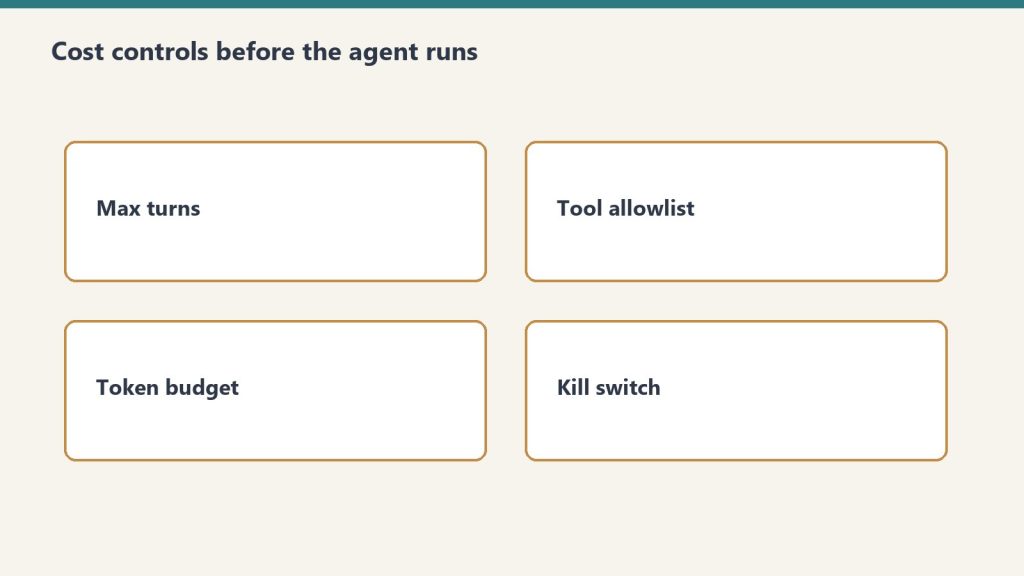
    Four gates: max turns, tool allowlist, token budget, kill switch
    Ops agents still need cost controls before they run.

    An operations agent that manages recurring workflows — weekly reporting, vendor follow-ups, SOP updates — and carries forward the state of each workflow between runs.

    What gets stored in memory:

    • Status of recurring tasks and workflows
    • Vendor and contact notes accumulated over time
    • Decision log for operational choices
    • Open items and their status

    Configuration approach:

    • Memory organized by workflow: /ops/weekly-report/, /ops/vendor-follow-ups/
    • Agent reads open items at session start, completes what it can, updates status in memory
    • Operators review memory state weekly rather than re-briefing the agent

    Use Case 5: Customer Support Agent (Support Teams)

    A support agent that remembers each customer’s history, prior issues, resolutions, and communication preferences — so customers don’t re-explain their context on every interaction.

    Ando is building their workplace messaging platform on Managed Agents, using memory to capture how each organization interacts instead of building custom memory infrastructure themselves.

    What gets stored in memory:

    • Customer account context and tier
    • Prior issue history with resolutions
    • Communication preferences (tone, channel, response length)
    • Known product configurations or integrations the customer uses

    Configuration approach:

    • Memory store per customer, scoped to their account ID
    • Initialize with CRM data (account type, history summary)
    • Agent writes a resolution summary after each ticket closes

    Use Case 6: Legal and Compliance Agent (Legal Teams)

    A compliance agent that tracks regulatory requirements, monitors changes, and maintains a running compliance status log — accumulating institutional knowledge across every compliance review it runs.

    What gets stored in memory:

    • Current compliance status by regulation and jurisdiction
    • Prior audit findings and remediation decisions
    • Regulatory change log with effective dates
    • Open items requiring human review

    Configuration approach:

    • Memory organized by regulation: /compliance/gdpr/, /compliance/hipaa/, /compliance/soc2/
    • Agent reads current status before each compliance check run
    • Writes updated status and flags human review items after each run

    For regulated industries: memory redaction endpoint supports removing specific content from historical versions for GDPR/CCPA compliance while preserving the audit record structure.


    Use Case 7: Sales Agent (Sales Teams)

    A sales agent that knows each prospect’s engagement history, objections raised, competitive comparisons requested, and where they are in the buying process — without requiring a CRM update to carry context forward.

    What gets stored in memory:

    • Prospect background and stakeholder map
    • Objections raised and responses given
    • Competitive questions and preferred comparisons
    • Next steps and commitments from prior conversations

    Configuration approach:

    • Memory store per prospect, keyed to their company or contact ID
    • Initialize with CRM pull at first contact
    • Agent writes call summary and updated next steps after each prospect interaction

    Use Case 8: Content Production Agent (Marketing Teams)

    A content agent that learns the brand voice, audience preferences, what topics have already been covered, and what performed well — building a persistent content intelligence layer across every piece produced.

    What gets stored in memory:

    • Brand voice rules and style examples
    • Topic map (what’s been covered, what’s planned)
    • Performance notes on past content (what resonated, what didn’t)
    • Client feedback on tone, format, and depth

    Configuration approach:

    • Memory organized by brand: /content/[brand-name]/voice.md, /content/[brand-name]/topic_map.md, /content/[brand-name]/performance_log.md
    • Agent reads voice rules at session start before producing any content
    • Operator adds performance feedback directly to memory after publishing

    Use Case 9: Finance Agent (Finance Teams)

    A financial analysis agent that carries forward context on recurring reports — month-over-month trends, known anomalies, and prior analytical decisions — so each report builds on the last rather than starting from raw data.

    Anthropic shipped a financial services agent template suite in May 2026, built on Managed Agents memory for cross-session continuity.

    What gets stored in memory:

    • Key metrics and their historical baselines
    • Known data quality issues and how they’ve been handled
    • Prior period variances and the explanation documented at the time
    • Model risk notes for regulated environments

    Configuration approach:

    • Memory organized by report type: /finance/monthly-pl/, /finance/board-report/
    • Agent reads prior period context before starting each new report cycle
    • Writes a period summary with key variances and decisions after each report run

    Use Case 10: Onboarding Agent (HR and Operations)

    An onboarding agent that adapts its guidance to each new hire’s role, prior experience, and progress through the onboarding checklist — and carries that context across every interaction during their ramp period.

    What gets stored in memory:

    • New hire profile (role, team, prior experience notes)
    • Onboarding checklist progress
    • Questions asked and answers given (to avoid repetition)
    • Manager notes on priorities for this hire

    Configuration approach:

    • Memory store per new hire, active during ramp period (typically 30–90 days)
    • Initialize with role profile and onboarding checklist
    • Agent writes progress update after each onboarding session
    • Archive or close memory store when onboarding period ends

    What Memory Doesn’t Replace

    Memory stores context and preferences. They don’t replace real-time data access, live system integrations, or human judgment on consequential decisions.

    Memory is document storage, not a database. It works well for: text-based preferences, accumulated notes, decision logs, prior outputs. It doesn’t work well for: real-time status queries (use MCP connectors for those), structured data that needs querying (use a real database), or high-frequency writes (memory is designed for periodic updates, not per-turn state).

    The right architecture in most production systems: memory for persistent context and preferences, MCP connectors for real-time system access, structured database for high-frequency operational data.


    Related on Tygart Media: how to use Claude · Anthropic API key.

    Frequently Asked Questions

    What is Claude Managed Agents memory?

    Memory for Claude Managed Agents is a workspace-scoped document store that persists across agent sessions. Instead of starting fresh each session, agents read and write memory files that carry context, preferences, and accumulated knowledge forward into every future session.

    When did Managed Agents memory launch?

    Claude Managed Agents launched in public beta April 8, 2026. Memory for Managed Agents entered public beta April 23, 2026.

    How is memory different from a system prompt?

    A system prompt is static and set at agent configuration time. Memory is dynamic — it’s written and updated by the agent during sessions and grows over time. Memory stores things the agent has learned or been told; system prompts store standing instructions that don’t change session to session.

    What happens to memory when an agent is deleted?

    Memory stores are separate from agent configurations. Deleting an agent doesn’t delete its memory store. Memory stores must be deleted or archived separately.

    What to Read Next

    How to Install Claude Code

     Claude Team Plan Usage Limits 

    Claude AI Pricing — All Plans and API Rates

     Anthropic Console: API Keys and the Workbench

  • The 2026 AI Security Audit: How to Use Claude (2026)

    The 2026 AI Security Audit: How to Use Claude (2026)

    Last refreshed: August 2026

    Claude is already inside most enterprises — through individual employee accounts, Claude Code on developer machines, and browser extensions — whether IT approved it or not. The security question in 2026 isn’t whether to allow Claude. It’s whether to govern it.

    This is a practical security audit checklist for Claude Enterprise deployments in 2026 (see also Anthropic Trust Center). It covers the five domains that matter, the specific CVEs that affect Claude Code, and the configuration steps that close the most significant exposure.


    The Current Threat Surface

    Five security domains: identity, data, code governance, audit, agents
    Five domains for a Claude enterprise security audit.

    Claude operates across multiple surfaces — claude.ai web, mobile apps, Claude Code on developer machines, Cowork, and API integrations — each with different data exposure profiles and each requiring different controls.

    The most significant 2026 security events affecting Claude deployments:

    CVE-2025-59536 (CVSS 8.7): Disclosed by Check Point Research in early 2026. A vulnerability in Claude Code that allows remote code execution through malicious project configuration files — before any trust dialog appears to the user. Affects any organization that has deployed Claude Code without centralized governance.

    CVE-2026-21852: Demonstrates how an attacker can redirect all Claude Code traffic to an attacker-controlled server by manipulating the ANTHROPIC_BASE_URL environment variable. Silently exfiltrates API keys and conversation content. Reproducible attack chain.

    GTG-1002 campaign (September 2025): Anthropic identified this as one of the first AI-orchestrated cyberattacks at scale, establishing AI developer tooling as an active attack surface.

    These are not theoretical risks. They’re documented, reproducible attack chains that affect any Claude Code deployment without centralized governance.


    Security Domain 1: Identity and Access

    Five-step path: account, API keys, billing, usage, workspaces
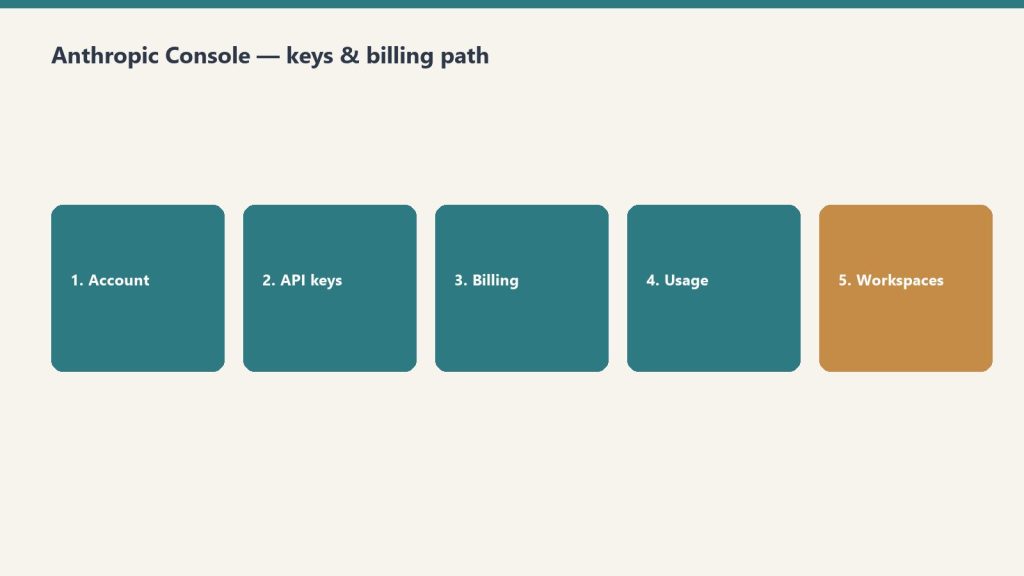
    Identity and access — who can create keys and call models.

    Configure SSO before any broad rollout. Without SSO, employees authenticate with personal Anthropic accounts — which means no centralized visibility, no revocation capability, and no audit trail.

    Implementation steps:

    1. Enable SAML 2.0 or OIDC SSO in the Claude Admin Console. This forces all claude.ai logins through your identity provider (IdP) and prevents personal account fallback.
    2. Enable domain capture alongside SSO. This prevents employees from using personal email accounts to access Claude outside the managed environment.
    3. Configure SCIM provisioning to automate user lifecycle management. When an employee is offboarded from your IdP, their Claude access is revoked automatically.
    4. Implement role-based access controls (RBAC). Not all users need access to all Claude capabilities. Segment by role: standard users, power users with Claude Code, API access holders.
    5. Set up periodic access reviews for Claude access, the same way you review access to other SaaS applications. SailPoint and similar identity governance tools can integrate via the Claude Compliance API.

    Audit evidence to collect: SSO configuration screenshots, SCIM provisioning logs, access review completion records.


    Security Domain 2: Data Controls

    The first security question in every enterprise deployment is where the data goes. The answer depends on which Claude product and deployment model is in use — and it matters enormously for regulated industries.

    Data handling by deployment model:

    DeploymentData RetentionNetwork PathZero Data Retention Available
    Claude Enterprise (Anthropic console)30 days default, ZDR availablePublic internetYes
    AWS BedrockPer AWS data agreementsVPC/private network availableYes
    Google Cloud Vertex AIPer GCP data agreementsVPC/private network availableYes
    Microsoft FoundryPer Microsoft data agreementsPrivate networkYes
    Claude.ai personal accountsAnthropic standard termsPublic internetNo

    For regulated industries (HIPAA, financial services, government): deploy via AWS Bedrock, Google Cloud Vertex AI, or Microsoft Foundry with private network configurations that keep traffic off the public internet. Enable ZDR (Zero Data Retention) for workloads with sensitive data.

    The silent risk: employees using personal claude.ai accounts for work tasks. Data entered into personal accounts is subject to Anthropic’s standard consumer terms, not Enterprise data agreements. SSO + domain capture closes this gap.


    Security Domain 3: Claude Code Governance

    Claude Code is the highest-risk surface in most enterprise deployments. It runs with the privileges of the developer’s user account, can execute arbitrary shell commands, read the full filesystem, and make outbound network connections.

    Hardening steps for Claude Code deployments:

    Centralize API key management:

    • Use organization-managed API keys (via the Admin Console) rather than individually generated keys
    • Create separate keys per team or project, not shared team keys
    • Rotate keys on a defined schedule (quarterly minimum)
    • Monitor for anomalous usage (volume spikes, off-hours activity) — feed audit logs to SIEM

    Address the CVE-2026-21852 attack vector:

    • Audit all developer machines for .claude/settings.json files in project repositories — these can be used to redirect traffic
    • Block arbitrary ANTHROPIC_BASE_URL overrides via environment variable policy
    • Add Claude Code traffic to network monitoring so redirected traffic is detectable

    Restrict filesystem access:

    • Prevent Claude Code from running in directories containing production secrets or sensitive data
    • Use separate working directories for Claude Code sessions, isolated from production credential stores

    Code execution controls:

    • Enable disableBypassPermissionsMode to require explicit approval for shell commands
    • Log all shell commands executed via Claude Code to the audit trail

    Security Domain 4: Audit Logging and Observability

    Claude Enterprise audit logs capture user authentication events, model calls with metadata, and file interactions. Without routing these logs to a SIEM, the audit trail exists but isn’t being monitored.

    What the audit log captures:

    {
      "event_type": "claude_api_call",
      "timestamp": "2026-08-01T09:14:32Z",
      "user_id": "u_8f3a9c",
      "session_id": "sess_x72kp",
      "workspace": "finance-reporting",
      "model": "claude-opus-4-6",
      "tokens_input": 2340,
      "tokens_output": 412,
      "latency_ms": 1840
    }
    

    Implementation steps:

    1. Enable audit logging in the Claude Admin Console (Enterprise plan)
    2. Export logs to SIEM — Splunk, Datadog, Elastic, or equivalent. Claude supports JSON and CSV export plus direct SIEM push.
    3. Build correlation rules for: unusual access times, geographic outliers, session volume spikes, API key misuse
    4. Use the Compliance API to export prompts, responses, and admin actions into DLP and insider risk monitoring workflows

    The gap Anthropic hasn’t filled: There is no built-in anomaly detection in the Admin Console. Usage anomaly detection requires SIEM integration and custom correlation rules. This is a known limitation — build it at the SIEM layer.


    Security Domain 5: Agentic Workflow Security

    Claude Managed Agents and Claude Code used in agentic workflows introduce a category of risk that traditional SaaS governance doesn’t cover: an AI taking autonomous actions in the environment.

    Key controls for agentic deployments:

    Human oversight checkpoints: For any agentic workflow that takes consequential actions (code commits, file modifications, API calls to production systems), require a human review step before execution. Don’t allow fully autonomous action without an approval gate on high-impact operations.

    Tool scope minimization: Define the smallest set of tools an agent needs and give it nothing else. An agent that only needs to read files shouldn’t have shell execution permissions. MCP server connections should be scoped to the minimum required access.

    MCP connector governance: MCP servers allow agents to connect to external systems (GitHub, Notion, Slack, etc.). Each MCP connection is an attack surface for prompt injection — a malicious response from an external system can instruct the agent to take unintended actions. Audit which MCP servers are connected; don’t allow arbitrary MCP connections.

    Prompt injection defense: Any content that flows from an external system into an agent’s context (web pages, API responses, file contents) should be treated as potentially adversarial. This is the mechanism behind most AI agent security incidents in 2025–2026. Validate and sanitize external inputs before they reach the agent context.


    Quick-Reference Audit Checklist

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Quick-reference checklist — prove controls, do not assume them.

    Use this to assess the current state before deciding what to address first:

    Identity

    • SSO (SAML 2.0 or OIDC) enforced for all Claude access
    • Domain capture enabled to prevent personal account use
    • SCIM provisioning configured for automated user lifecycle
    • RBAC defined by role (standard / power user / API)

    Data

    • Deployment model documented (Anthropic console vs. Bedrock vs. Vertex)
    • ZDR enabled for sensitive data workloads
    • Personal claude.ai account use blocked or governed
    • Data classification applied to determine which workloads can use which deployment model

    Claude Code

    • Organization-managed API keys (not individual)
    • Per-team/per-project key segmentation
    • CVE-2025-59536 and CVE-2026-21852 remediation verified
    • Shell execution logging enabled

    Audit and Observability

    • Audit logging enabled in Admin Console
    • Logs routed to SIEM
    • Anomaly detection rules configured
    • Compliance API integrated with DLP tooling

    Agentic

    • Human oversight gates on consequential agent actions
    • MCP connections audited and scoped
    • Prompt injection defenses in place for external inputs

    Related on Tygart Media: how to use Claude · Anthropic API key.

    Frequently Asked Questions

    Does Claude Enterprise offer zero data retention?

    Yes. Claude Enterprise deployed through the Anthropic console with a qualifying enterprise agreement offers zero data retention, where prompts and responses are not logged by Anthropic. ZDR is also available via AWS Bedrock, Google Cloud Vertex AI, and Microsoft Foundry deployments.

    What compliance certifications does Anthropic have?

    Anthropic holds ISO 27001:2022 and ISO/IEC 42001:2023 certifications and offers HIPAA-ready configurations with Business Associate Agreements to qualifying enterprise customers.

    What are the biggest security risks in a Claude Code deployment?

    CVE-2025-59536 (remote code execution via malicious project config files, CVSS 8.7) and CVE-2026-21852 (traffic redirection via ANTHROPIC_BASE_URL manipulation) are the most significant documented vulnerabilities. The broader risks are developers using personal Anthropic accounts, shared API keys without rotation, and no audit trail for code context that flows to Anthropic’s servers.

    What is the Compliance API?

    The Claude Compliance API is an Enterprise feature that exports prompts, responses, files, and admin actions to external monitoring systems — enabling integration with DLP tools (Proofpoint), SIEM platforms (Splunk, Datadog, Elastic), and identity governance tools (SailPoint). It’s the primary mechanism for bringing Claude activity into existing enterprise security workflows.

    What is prompt injection in AI agents?

    Prompt injection occurs when malicious content in external data sources (web pages, API responses, documents) instructs an AI agent to take actions the operator didn’t intend. In agentic Claude workflows, any content retrieved from external systems can potentially carry injected instructions. Defense requires treating external inputs as untrusted and implementing validation before they enter the agent context.


    What to Read Next

    Claude Enterprise Pricing: What Large Organizations Pay 

    Claude AI Pricing — All Plans and API Rates

     Anthropic Console: API Keys and Billing

    How to Install Claude Code

  • Generative Engine Optimization (GEO): 5 Ways to Ensure Your Content Gets Cited (2026)

    Generative Engine Optimization (GEO): 5 Ways to Ensure Your Content Gets Cited (2026)

    Last refreshed: August 2026

    GEO — Generative Engine Optimization — is the practice of structuring content so that AI answer engines (ChatGPT, Perplexity, Google AI Overviews, Gemini, and Claude) cite it in the answers they generate. In 2026, 68% of U.S. Google searches end without a click. Being cited in the answer that appears is now as important as ranking in the links below it.

    This guide covers what GEO is, how it differs from traditional SEO, and five specific tactics that move citation rates — with particular relevance for sites publishing Claude and AI authority content.


    Why GEO Matters in 2026

    Comparison of Claude how-to fit versus local service page fit for assistants
    Why GEO matters — citations are the new first page.

    AI Overviews reduce organic click-through rate for the #1 ranked result by up to 58% (Ahrefs, December 2025) — but brands cited as sources within AI Overviews earn 35% more organic clicks than uncited brands on the same query.

    The counterintuitive finding: zero-click is bad for uncited sites and good for cited ones. The goal is not to fight AI Overviews — it’s to be inside them.

    The market data context:

    • 68% of U.S. Google searches are zero-click in 2026, up from 60% in 2024
    • When AI Overviews appear, the zero-click rate jumps to 83%
    • Visitors arriving from AI citations convert at 4.4x the rate of traditional organic visitors
    • The GEO market is projected at $365M in 2026, growing at 42.9% CAGR

    The mechanism: AI search users arrive with specific, researched queries and a pre-formed shortlist. That intent profile makes them higher-converting even when the total count is smaller.


    How GEO Differs From Traditional SEO

    Side-by-side SEO rank/click versus GEO citation/answer-first
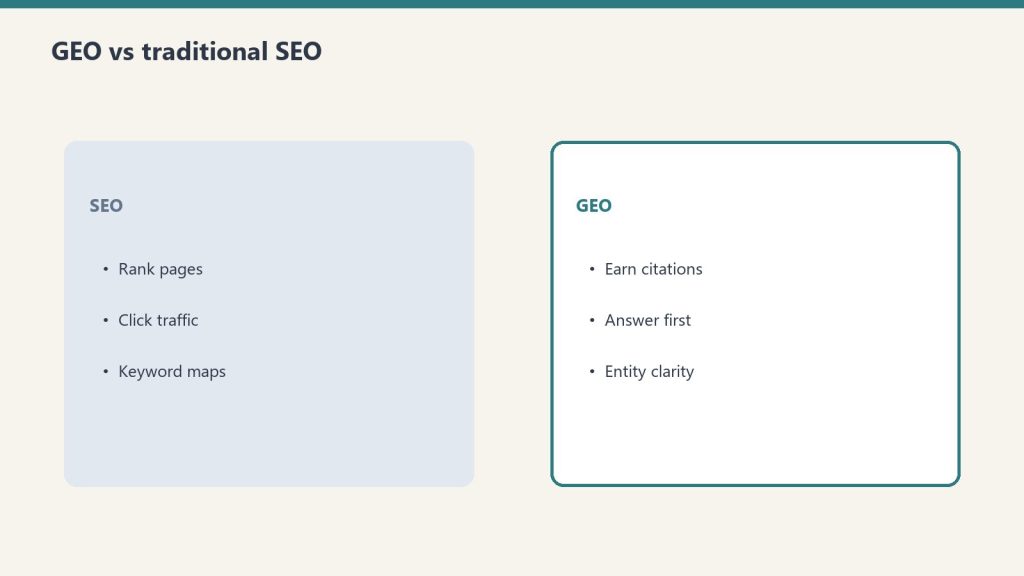
    How GEO differs from traditional SEO.

    Traditional SEO optimizes for ranking position in a list of links. GEO optimizes for inclusion in the synthesized answer above those links. The signals overlap significantly, but GEO adds specific requirements around answer-first structure, data richness, and citation-friendliness.

    DimensionTraditional SEOGEO
    GoalRank in top 10Be cited in the AI answer
    Key signalBacklinks, E-E-A-T, technical SEOAnswer-first structure, data richness, entity authority
    MeasurementOrganic clicks, ranking positionAI citation rate, brand mentions, branded search volume
    Content structureTopic depth, keyword distributionDirect answer in first 200 words, FAQ schema
    Success statePosition 1Cited source in AI Overview

    Important: the overlap between ranking in Google’s top 10 and being cited in AI Overviews collapsed from roughly 75% in mid-2025 to 17–38% in early 2026. Ranking well no longer guarantees AI citation. Both need to be optimized for separately.


    Tactic 1: Answer First, Always

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Answer first, always — then prove it with specifics.

    AI retrieval systems that use real-time web access evaluate a page’s relevance primarily on its opening content. The first 200 words of any article must directly and completely answer the primary query — not build up to the answer.

    The structure that gets cited:

    [H1 Title]
    [Bold one-sentence direct answer in first paragraph]
    [Supporting context and detail]
    

    The structure that doesn’t:

    [H1 Title]
    [Background context]
    [History of the topic]
    [Eventually getting to the answer]
    

    AI Overviews synthesize their answers from the opening of retrieved pages. A page that buries its answer 500 words in gets retrieved for its topic relevance and then can’t be cited because the direct answer isn’t extractable. The answer-first structure serves both GEO and usability simultaneously.

    For AI authority content specifically: every article about a Claude feature, pricing tier, or model capability should open with the factual answer to the likely query, stated plainly in the first sentence or two.


    Tactic 2: Add Original Data and Specific Numbers

    AI systems and search engines treat original data, specific statistics, and citable figures as high-value content. Content with precise numbers gets cited more than content with generalizations.

    The practical application:

    • “Claude Enterprise typically costs $60–250+/user/month depending on usage intensity” is more citable than “Claude Enterprise is expensive for some teams”
    • “68% of U.S. Google searches are zero-click in 2026” is citable; “most searches end without a click” is not
    • “Claude Sonnet scores approximately 77% on SWE-bench Verified” is citable; “Claude is good at coding” is not

    For tygartmedia.com content specifically: articles that include specific pricing numbers, benchmark scores, token counts, and performance figures will outperform articles that describe capabilities in qualitative terms. The Claude reference cluster (pricing, models, console) already does this well.

    Attribution rule: Cite where specific numbers came from — a benchmark, a study, Anthropic’s official documentation. “According to Anthropic’s pricing page” or “per SWE-bench Verified benchmarks” tells AI systems the claim is grounded, not asserted.


    Tactic 3: Use FAQ Schema

    FAQ schema (FAQPage structured data) formats content explicitly as question-and-answer pairs, which is the format AI answer engines are built to extract and synthesize from. Pages with FAQ schema see measurably higher AI Overview inclusion.

    Implementation in JSON-LD:

    <script type="application/ld+json">
    {
      "@context": "https://schema.org",
      "@type": "FAQPage",
      "mainEntity": [
        {
          "@type": "Question",
          "name": "What is Claude Enterprise pricing?",
          "acceptedAnswer": {
            "@type": "Answer",
            "text": "Claude Enterprise starts at approximately $20/user/month for access, with token usage billed separately at API rates. Real total cost typically runs $60–250+/user/month depending on usage intensity."
          }
        },
        {
          "@type": "Question",
          "name": "Is Claude Enterprise worth it?",
          "acceptedAnswer": {
            "@type": "Answer",
            "text": "For teams with compliance mandates (SSO, SCIM, audit logs) or more than 150 users, yes. For smaller teams without governance requirements, Claude Team is more predictable and usually sufficient."
          }
        }
      ]
    }
    </script>
    

    In Rank Math (the plugin on tygartmedia.com): FAQ blocks in the WordPress editor automatically generate FAQPage schema without manual JSON-LD implementation. Add FAQ sections to every article and use the Rank Math FAQ block type.


    Tactic 4: Build Entity Authority

    AI systems and search engines treat entities — specific named things with consistent, verifiable information across the web — as more citable than generic topical content. Building entity authority for tygartmedia.com means consistent name, description, and factual claims across every surface the crawlers read.

    Entity authority checklist:

    • Organization schema on every page: Name, URL, description, logo, founder, same-as links to LinkedIn, social profiles
    • Consistent author byline: “Will Tygart” as the author on every article, with a consistent bio that establishes expertise
    • External mentions: Being cited by other authoritative sites on the same topics creates the external validation AI systems look for
    • Wikipedia/Wikidata presence: Not always achievable, but having factually consistent information across third-party sites (LinkedIn, Crunchbase, social profiles) strengthens entity recognition

    For an AI authority site specifically: the entity is “Tygart Media” and its associated expertise is Claude, Anthropic, and AI infrastructure for operators. Every article that earns an external link or citation strengthens that entity signal for all related queries.


    Tactic 5: Freshness Signals

    AI retrieval systems weight recency heavily for fast-moving topics. Claude pricing, model capabilities, and Anthropic’s roadmap change frequently. Articles with stale information get displaced by fresher sources even when the URL has more backlink authority.

    Freshness tactics:

    • “Last refreshed” date at the top of every article — signals to both users and crawlers that the information is current
    • Add a “What’s new” or “What changed” section for evergreen articles that cover frequently updated topics
    • Update timestamps when content changes — not just publishing dates, but explicit refreshed dates
    • Track in Google Search Console which queries trigger AI Overviews and whether the site is cited in them — freshness issues often show up as sudden drops in AI citation before they show up as ranking drops

    For Claude-related content: any article covering pricing, models, or features needs a refresh trigger whenever Anthropic makes changes. The May 2026 dispatch for timestamp refreshes on Fable 5-related pricing content is the right pattern.


    Measuring GEO Performance

    Standard GA4 and Search Console metrics don’t capture AI citation performance. The metrics that matter for GEO are AI citation rate, branded search volume, and assisted conversions from AI-referred traffic.

    What to track:

    MetricHow to measureWhat it indicates
    AI-referred trafficGA4 source filter for ChatGPT, Perplexity referralsDirect AI citation traffic
    Branded search volumeGoogle Search Console, “tygartmedia” queriesBrand awareness from AI citations
    AI Overview appearancesGSC AIO reportQueries where the site is cited
    CTR on AIO queriesGSC, filter by queries with AI OverviewsWhether citations drive clicks
    Conversion rate from AI referralsGA4 segmented by sourceValue of AI citation traffic

    Manual testing: monthly, ask ChatGPT, Perplexity, and Claude the questions your audience asks — “what is Claude Enterprise pricing,” “how does Metricool API work,” “what is Anthropic’s history” — and see whether tygartmedia.com is cited. This is the most direct GEO feedback loop available.


    Related on Tygart Media: how to use Claude · Anthropic API key.

    Frequently Asked Questions

    What is Generative Engine Optimization (GEO)?

    GEO is the practice of structuring content and managing online presence so that AI answer engines — ChatGPT, Perplexity, Google AI Overviews, Gemini, and Claude — cite it in the answers they generate. It’s distinct from traditional SEO, which optimizes for ranking positions in link lists.

    How is GEO different from SEO?

    Traditional SEO optimizes for ranking position. GEO optimizes for citation inside AI-generated answers. The overlap between top-10 rankings and AI Overview citations has collapsed from 75% in 2025 to 17–38% in early 2026 — ranking well no longer guarantees AI citation. Both need to be optimized independently.

    Does GEO replace SEO?

    No. Traditional SEO fundamentals (E-E-A-T, backlinks, technical health) still power AI citations. GEO is an additional layer on top of a solid SEO foundation, not a replacement for it. Brands that excel at GEO in 2026 typically have strong traditional SEO as well.

    How long does GEO take to work?

    Plan for 3–6 months of consistent effort before seeing meaningful citation rate changes. Unlike traditional SEO ranking changes, which can be tracked daily, AI citation frequency changes slowly as crawlers re-index updated content and AI systems update their knowledge bases.

    What is the conversion rate from AI-cited traffic?

    AI search visitors convert at significantly higher rates than traditional organic visitors — roughly 4.4x according to Semrush data. The mechanism is intent: AI search users arrive with specific, researched queries and a pre-formed shortlist, which translates to higher purchase and contact intent.


    What to Read Next

    History of Anthropic 

    Claude AI Pricing — All Plans and API Rates

     Anthropic Console: API Keys and the Workbench

    Current Claude Model Version Tracker

    Visual summary

    Geo Not Seo Extra Steps

    About this image. This image is part of the Article Hero Images collection in the Tygart Media visual library. Every image produced by Tygart Media is AI-generated using Google Vertex AI (Imagen), converted to WebP format, and injected with full IPTC/XMP metadata before publication.

    • Format: WEBP
    • Collection: Article Hero Images
    • Pipeline: Vertex AI Imagen → WebP → IPTC/XMP → WordPress
  • Building Your First Agentic Workflow with Claude’s Agent SDK

    Building Your First Agentic Workflow with Claude’s Agent SDK

    Last refreshed: August 2026

    The Claude Agent SDK tutorial starts here — the SDK (formerly the Claude Code SDK, renamed late 2025) eliminates the boilerplate of building agentic loops by hand, shipping the same tool execution, context management, and permission system that powers Claude Code into a Python or TypeScript library you can embed in any product, pipeline, or internal tool.

    This is a practical build guide. It covers when to use an agent versus a script, what the SDK actually does, how to set one up with working code, and what to watch for in production.


    When to Use an Agent vs. a Script

    Side-by-side when to use a script versus an agent
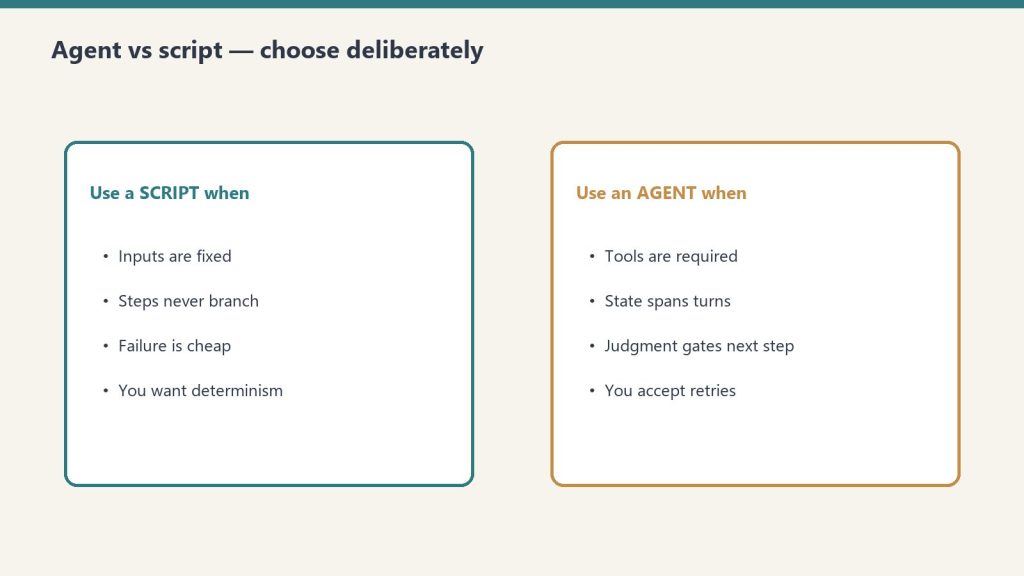
    Agent vs script — choose deliberately.

    Use an agent when the number of steps to complete the task is unpredictable. If the workflow can be hardcoded, a linear script is faster, cheaper, and easier to debug.

    This is Anthropic’s own guidance in Building Effective Agents, and it’s the right frame. The common mistake is reaching for agents because agents are fashionable — not because the problem requires them.

    Agents fit:

    • Open-ended research tasks where the number of searches needed varies
    • Code debugging where the error chain isn’t known in advance
    • Multi-step data pipelines where decisions at each step depend on prior outputs
    • Any workflow where the model needs to try, observe, and adjust

    Scripts fit:

    • Known sequences of steps that always run in the same order
    • Simple data transformation with no conditional branching
    • Any task where the output of each step is fully predictable

    The cost implication matters too: a 15-step agentic research task can hit 200K+ tokens without optimization. Agents are expensive when you don’t need them.


    How the Claude Agent SDK Works

    Observe remember act update loop for agent SDK workflows
    How the Agent SDK loop behaves in practice.

    The SDK automates the ReAct loop — Reason, Act, Observe, repeat — so you define the tools and instructions and the SDK handles the rest. You never write the prompt → check stop_reason → execute tool → loop boilerplate yourself.

    The core loop the SDK manages:

    1. Send the task to Claude with available tool definitions
    2. Claude reasons and produces a tool call (or a final answer)
    3. The SDK executes the tool in the local environment
    4. The SDK sends the result back to Claude
    5. Claude observes and decides: call another tool or produce final output
    6. Loop until done

    This continues until Claude produces a response with no tool calls. The SDK handles conversation history, token tracking, error handling, and session management across the entire loop.


    Installing the SDK

    # Python
    pip install claude-agent-sdk
    
    # TypeScript
    npm install @anthropic-ai/claude-agent-sdk
    

    Set your API key:

    export ANTHROPIC_API_KEY="sk-ant-..."
    

    Building a Minimal Agent

    A working agent requires three things: a task, tool definitions, and a Runner call. Everything else is configuration.

    from claude_agent_sdk import ClaudeAgentOptions, Runner
    import subprocess
    import json
    
    # Define tools the agent can use
    tools = [
        {
            "name": "run_command",
            "description": "Run a shell command and return its output",
            "input_schema": {
                "type": "object",
                "properties": {
                    "command": {
                        "type": "string",
                        "description": "The shell command to execute"
                    }
                },
                "required": ["command"]
            }
        },
        {
            "name": "read_file",
            "description": "Read the contents of a file",
            "input_schema": {
                "type": "object",
                "properties": {
                    "path": {
                        "type": "string",
                        "description": "File path to read"
                    }
                },
                "required": ["path"]
            }
        }
    ]
    
    # Tool execution handlers
    def execute_tool(tool_name: str, tool_input: dict) -> str:
        if tool_name == "run_command":
            result = subprocess.run(
                tool_input["command"],
                shell=True,
                capture_output=True,
                text=True
            )
            return result.stdout or result.stderr
        elif tool_name == "read_file":
            with open(tool_input["path"], "r") as f:
                return f.read()
        return f"Unknown tool: {tool_name}"
    
    # Configure and run the agent
    options = ClaudeAgentOptions(
        model="claude-sonnet-4-6",
        max_turns=20,               # safety ceiling
        tools=tools,
        tool_executor=execute_tool
    )
    
    result = Runner.run_sync(
        task="Check the disk usage on this machine and report the top 5 largest directories under /home",
        options=options
    )
    
    print(result.final_output)
    

    That’s a complete working agent. The SDK handles the loop; the tool definitions and executor are the only custom code.


    Adding Cost Controls

    Cost control gates before an agent runs
    Add cost controls before multi-turn agents hit production.

    Always set a max_turns ceiling and a token budget. An uncapped agent loop can run indefinitely on an ambiguous task.

    options = ClaudeAgentOptions(
        model="claude-sonnet-4-6",
        max_turns=20,
        max_tokens_per_turn=4000,   # cap per individual turn
        tools=tools,
        tool_executor=execute_tool
    )
    

    Cost at 20 turns using Claude Sonnet 4.6 with an average of 2,000 tokens per turn:

    • Input: 40,000 tokens × $3/M = $0.12
    • Output: 10,000 tokens × $15/M = $0.15
    • Total per agent run: ~$0.27

    At 1,000 agent runs per month: ~$270. At 10,000: ~$2,700. Budget from these numbers, not from seat prices.

    Switching the inner loop to Haiku 4.5 for tool selection and Sonnet only for synthesis cuts cost significantly:

    # Route lighter reasoning to Haiku, reserve Sonnet for synthesis
    light_options = ClaudeAgentOptions(model="claude-haiku-4-5-20251001", ...)
    heavy_options = ClaudeAgentOptions(model="claude-sonnet-4-6", ...)
    

    Multi-Turn Agents (Conversational)

    For agents where a human asks follow-up questions across multiple turns, maintain conversation history and pass it on each call.

    from claude_agent_sdk import ClaudeAgentOptions, Runner
    
    conversation_history = []
    
    def chat_with_agent(user_message: str) -> str:
        conversation_history.append({
            "role": "user",
            "content": user_message
        })
    
        options = ClaudeAgentOptions(
            model="claude-sonnet-4-6",
            max_turns=10,
            tools=tools,
            tool_executor=execute_tool,
            messages=conversation_history  # full history each call
        )
    
        result = Runner.run_sync(task=user_message, options=options)
    
        conversation_history.append({
            "role": "assistant",
            "content": result.final_output
        })
    
        return result.final_output
    
    # Usage
    print(chat_with_agent("What Python packages are installed on this system?"))
    print(chat_with_agent("Which of those are outdated?"))
    

    Claude Managed Agents vs. the Agent SDK

    The Agent SDK runs locally in your environment. Claude Managed Agents runs in Anthropic’s cloud infrastructure with persistent sessions, built-in tools, and cross-session memory. Choose based on where you need the agent to execute.

    Agent SDKManaged Agents
    Where it runsYour server / local machineAnthropic-managed cloud
    Persistent sessionsManual (maintain history)Built-in
    Cross-session memoryManualBuilt-in (public beta)
    Built-in toolsBring your own20+ included
    Multi-agent coordinationManualBuilt-in
    CostAPI tokens onlyAPI tokens + platform fee
    ControlFullManaged

    The Agent SDK is right for custom environments, data that can’t leave your infrastructure, and workflows deeply embedded in existing systems. Managed Agents is right when you want to skip infrastructure and get to the agent behavior faster.


    What Goes Wrong in Production

    The most common production failures are uncapped loops, conversation history that grows without bound, and tool definitions written too vaguely.

    Uncapped loops: An agent on an ambiguous task will keep calling tools indefinitely without a max_turns ceiling. Always set one. Always check message.subtype rather than is_error — a max-turns termination doesn’t set is_error: true correctly in some SDK versions.

    Growing conversation history: Each turn adds tokens to history. At 20 turns on a complex task, history can push 100K+ tokens. Summarize aggressively between phases for long-running agents: prompt Claude to summarize phase 1 outputs before starting phase 2.

    Vague tool definitions: Tool descriptions are how Claude decides which tool to call and how to use it. Vague descriptions produce tool call errors and unnecessary retry loops. Write tool descriptions as precisely as you would write a function docstring — what it does, what inputs it expects, what it returns.

    camelCase vs snake_case mismatch: AgentDefinition uses camelCase (disallowedTools); ClaudeAgentOptions uses snake_case (disallowed_tools). This caught teams in early SDK versions.


    Related on Tygart Media: how to use Claude · Anthropic API key.

    Frequently Asked Questions

    What is the Claude Agent SDK?

    The Claude Agent SDK is Anthropic’s Python and TypeScript library for building autonomous AI agents. It wraps the same agentic loop that powers Claude Code — tool execution, context management, and session handling — so developers don’t build that infrastructure from scratch. It was formerly called the Claude Code SDK and was renamed in late 2025.

    What is the difference between the Agent SDK and Claude Code?

    Claude Code is Anthropic’s interactive terminal-based development tool for agentic coding. The Agent SDK is the programmatic library for embedding agent behavior in custom applications and pipelines. They share the same underlying agent loop and tool system. Claude Code stays in the picture for interactive development; the SDK is for production automation.

    How much does it cost to run an agent?

    Agent cost is API token cost only (no platform fee for the SDK itself). A 20-turn agent on Claude Sonnet 4.6 with 2,000 tokens average per turn costs approximately $0.27. At 10,000 agent runs per month, that’s about $2,700. Switching the tool selection loop to Haiku 4.5 and reserving Sonnet for synthesis significantly reduces cost.

    When should I use Managed Agents instead of the Agent SDK?

    Use Managed Agents when you want cloud-hosted execution, persistent cross-session memory, built-in tools (20+ included), and multi-agent coordination without building that infrastructure yourself. Use the Agent SDK when you need local execution, full control over the environment, or your data can’t leave your infrastructure.

    What to Read Next

    Anthropic Console: API Keys, Billing, and the Workbench

     Claude AI Pricing — All Plans and API Rates 

    Claude API Model IDs and Strings 

    How to Install Claude Code