Primary research and analysis on how AI systems crawl, index, and cite web content. Based on proprietary server log data from controlled content experiments.
This morning, about 7:10 AM PDT on 14 September 2026, the knowledge cluster showed a fresh spike: roughly 3,222 requests in an hour, and six POST hits on wp-login.php. Same box. Same shape as the 11–13 September run. Slightly hotter on volume. Cooler on the login door.
That is the whole alert. It is not a breach report. It is not a reason to open the firewall. It is two numbers that most dashboards smash into one word — “attack” — and then the operator starts changing things they cannot undo cleanly.
Mixed spike. A mixed spike is a short window where total request volume jumps while a sensitive path such as wp-login.php only sees a handful of POSTs. The volume is usually crawlers, scanners, or cheap probes. The login count is the part that can become hostile. Treat them as two events until the logs prove they are one.
What does a 3,222 request-per-hour spike actually mean?
It means the box was busy. It does not mean someone is in the admin. On this stack, an hour in the low thousands is loud enough to page a human and too coarse to name a cause. AI crawlers, feed fetchers, uptime checks, and junk scanners all land in the same request counter. We already showed that GA4 misses crawler traffic and that server logs are the only honest desk for that layer in Server Log Analysis for AI Search.
The 11 September field note left this card open. That write-up recorded an earlier pulse on the same cluster at about 1:51 PT: roughly 2,487 requests per hour and nine wp-login POSTs. The instruction then was a read-only log pull and a one-paragraph verdict. No firewall change, no plugin change, no credential change without a named gate. That card is the parent of this morning. See The 1 MB Limit Ate the Clips.
Why are six wp-login POSTs the number that matters?
Because that path is the door. A GET to wp-login.php is usually a probe. A POST is a credential attempt. Six POSTs in an hour is not a brute-force campaign. A campaign that is actually trying passwords does not stop at six. It stacks POSTs until a rate limit, a WAF, or a 429 answers.
Six against 3,222 is the tell. Login is about two-tenths of one percent of the hour. If the spike were “someone hammering wp-login,” the login count would be the spike. Here the spike is everything else, and the door got a light knock.
Window
Requests / hour
wp-login POSTs
What it looks like so far
11 September 2026, ~1:51 PT (public card)
~2,487
9
Open patch. Verdict not written yet.
14 September 2026, ~7:10 AM PDT
~3,222
6
Same shape, hotter volume, fewer POSTs.
Those two rows are first-party. They come from the ops cards and this morning’s alert. They are not a full log dump. They are enough to stop the sentence “we are under attack” from shipping as fact.
How do you tell bot noise from a hostile login event?
You do not tell from a single request-per-hour number. You tell from five columns that have to sit on one page: top source networks, paths, methods, status codes, and whether any POST to an auth endpoint returned a success path instead of a fail, a 403, a 429, or a challenge.
If volume is high and wp-login.php / xmlrpc.php POSTs are near zero, start with crawler or scanner noise.
If POSTs to the login door climb while other paths stay flat, start with credential stuffing or a cheap brute-force kit.
If one network owns both the volume and the POSTs, treat that network as the subject of the verdict, not the whole internet.
If status codes are 200 on a login POST, do not celebrate. WordPress often returns 200 on a failed login because it re-renders the form. You still need the auth result, not the HTTP code alone.
If you cannot see whether rate limiting or the WAF fired, you do not have a close. You have a draft.
That list is the desk, not a product. It is the same discipline we use when we refuse to treat Bing AI citations as sessions in How to Read Bing Webmaster Tools AI Citations. Wrong unit, wrong decision.
What is the one-paragraph verdict from this morning’s numbers alone?
Provisional, read-only: this morning looks like bot noise with opportunistic login probes, not a concentrated hostile event. The volume rose from the mid-2,000s last week to the low-3,000s. The login door went from nine POSTs to six. That is the opposite of a campaign that is finding a seam. Nothing in the alert says a login reached a successful auth. Nothing in the alert says the WAF or a rate limit fired. Until those two facts are in the log extract, the box stays as-is.
What to do from this paragraph: pull the hour. Rank source networks, paths, methods, and status codes. Confirm whether any login POST crossed into an authenticated session. Write the close in one paragraph. Do not touch firewall, plugins, credentials, DNS, or WAF from the spike number alone.
Why does this belong on an AEO and GEO desk?
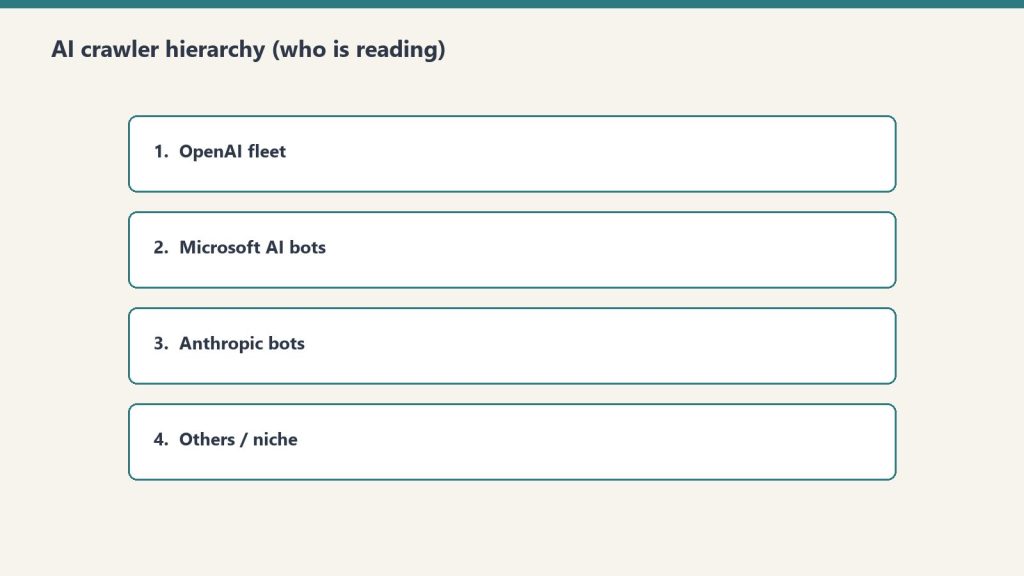
Because the same operators who publish for answer engines also run the origin those engines crawl. A spike that is actually GPTBot or a citation crawler is the retrieval layer working. A spike that is actually wp-login.php is the origin under cheap pressure. If you flatten both into “bots,” you will rate-limit the crawler you spent a year trying to attract. We mapped that split in The AI Crawler Hierarchy and in Google vs Bing vs OpenAI.
SEO still needs the URL up. AEO still needs a clean block a snippet can lift. GEO still needs a page a model will cite without inventing a second sentence. None of those layers survive an origin that treats every request burst as an incident and starts flipping controls. The cited-answer work on this site — Your Website Doesn’t Need More Traffic. It Needs to Be the Answer. — assumes the box that serves the sentence stays boring.
What we would not claim
That we have this morning’s full access log in this article. We have the alert counts. The path table and the auth result are the next pull, not this page.
That six POSTs means zero risk. It means the door was tried. It does not mean the door opened.
That 3,222 requests per hour is a universal threshold. It is the number on this box, this hour.
That hiding wp-login.php is the fix. Obscurity is not the close, and this post is not a plugin recommendation.
That any named source network belongs in a public URL. Publishing attacker addresses helps the next scanner more than it helps the reader.
What we would do again
Keep the two counts separate on the card. Request volume on the left. Auth-path POSTs on the right. Write the verdict in one paragraph before anyone is allowed to change a control. Leave the change list empty until the named gate says yes. Publish the method, not the address list.
The 11 September card said a spike is not automatically an attack and it is not automatically “leave it.” It is a log plus a verdict. This morning’s numbers did not close the log. They did close the panic sentence. The door was quiet. The weather was not.
FAQ
Is a WordPress request spike the same thing as a brute-force attack?
No. A request spike is total traffic in a window. A brute-force event is repeated credential POSTs against an auth path such as wp-login.php or xmlrpc.php. This morning’s hour had both a spike and six login POSTs. Those are adjacent facts, not proof they are the same campaign.
How many wp-login POSTs should trigger a change?
There is no public magic number that authorizes a firewall, plugin, credential, DNS, or WAF change on this stack. The trigger is a log extract that shows concentrated POSTs, a repeated source network, and either a successful auth or a clear miss by the existing limiters. Six POSTs in an hour does not clear that bar.
Can AI crawlers cause a 3,000-request hour?
Yes. On this network we have already logged hours where a single AI crawler family mapped tags, feeds, and endpoints at four-figure rates. That traffic belongs in the server log, not in GA4. Confirm the user-agent and the path list before you treat the hour as hostile.
Should you publish the source IP addresses from a spike?
No. A public post can carry the counts, the method, and the verdict. It should not carry a live target list. The addresses live in the private log pull.
Sources: Tygart Media ops alert, knowledge cluster, ~7:10 AM PDT, 14 September 2026 (about 3,222 requests/hour and 6 wp-login POSTs). Prior public card in The 1 MB Limit Ate the Clips (~2,487 requests/hour and 9 wp-login POSTs, ~1:51 PT). Method context: server log analysis for AI search, AI crawler hierarchy. Will Tygart, Tygart Media, 14 September 2026.
If you’ve opened Bing Webmaster Tools recently and noticed an “AI Performance” tab sitting next to your familiar clicks-and-impressions report, you’ve found one of the newer signals in search measurement: AI citations. It’s a genuinely useful number. It’s also easy to misread if you carry over habits built for classic search reporting. Here’s how to read it correctly.
What a Bing AI Citation Actually Is
What a Bing AI citation actually is.
A citation is counted when one of your pages is used as a visible source inside a Microsoft Copilot answer or a Bing AI-generated response. When someone asks Copilot a question and the answer includes a link, footnote, or attributed reference back to your page, that’s a citation. It means the AI system read your content, judged it relevant and trustworthy enough to draw from, and surfaced it — sometimes with a link the reader can click, sometimes just as a named source.
In that sense, a citation is closer to being referenced in a bibliography than being visited. Your page did its job as a source of truth for the answer, whether or not the reader followed the link.
What a Citation Is Not
What a citation is not — not traffic.
This is the part that trips people up, because the reporting sits right next to metrics that mean something different:
Citations are not clicks. A citation records that your content was used to generate an answer. It says nothing about whether a human then visited your site.
Citations are not sessions. Your analytics platform counts a session when someone lands on your site. A citation can happen with zero sessions attached — the reader gets their answer and moves on.
Citations are not rankings. Traditional search position measures where you sit on a results page for a given query. AI citation measures something different: whether your content was selected as source material for a generated answer, which can happen independently of where you’d rank in a classic search.
Treating a citation count like a traffic number, or expecting it to move in lockstep with clicks, sets you up to misjudge a page’s performance in either direction.
Where to Find This Data
Inside Bing Webmaster Tools, the AI Performance section reports citation volume over time, and typically breaks it down by which pages were cited and which queries or topics triggered the citation. It’s a separate report from the standard Search Performance section, which still covers traditional web impressions, clicks, and position. Treat them as two different dashboards answering two different questions, not two views of the same thing.
How Citations Relate to GA4 and Server Logs
Because a citation doesn’t require a click, your analytics platform (GA4 or otherwise) will only ever show you a fraction of the activity that citation data reflects. What GA4 can show you is the downstream piece: sessions where the referring source is an AI assistant’s domain. Those sessions represent people who read an AI answer, saw your page referenced, and decided to click through anyway — a smaller, but highly qualified, slice of the audience your content is reaching through AI systems.
Server or CDN logs add a third layer entirely: they can show you when AI crawlers are visiting your site to read and index content in the first place, ahead of and separate from any citation event. Together, these three sources describe three different moments — a bot reading your page (server logs), your page being cited in an answer (Bing AI Performance), and a human clicking through after reading that answer (GA4 referral data). None of them substitutes for the others.
Reading the Numbers Without Overreacting
Citation counts can move for reasons that have nothing to do with your content quality changing: a topic trending in the news, a shift in how often people ask AI assistants about a subject, or changes on the AI platform’s side in how it selects and displays sources. A dip in citations for a page you haven’t touched isn’t necessarily a signal that something is wrong with that page. Likewise, a spike doesn’t always mean you did something differently — sometimes demand for the topic simply increased.
The more durable way to use this data is directional and page-level: which of your pages does the AI Performance report show being cited consistently over time, and does that list overlap with pages you already consider authoritative? That overlap is a reasonable confirmation signal. A single week’s swing usually isn’t.
Practical Takeaways
Practical takeaways for reading the numbers.
Check the AI Performance tab as its own report, not a substitute for Search Performance. Don’t expect citation counts and click counts to correlate closely — they’re measuring different behaviors. Pair citation data with GA4 referral sessions from AI-tool domains to see the (smaller) human click-through layer, and use server logs if you want visibility into AI crawler activity before any citation happens. Judge trends over weeks, not days, and focus on which pages appear repeatedly rather than reacting to any single count.
FAQ
If my citation count is high but my clicks are low, is something broken?
No. That pattern is expected. Citations are a zero-click-by-design channel; a page can be doing exactly what it’s supposed to do as an AI source while generating very little direct click traffic.
Does Google offer the same kind of citation reporting?
Not with the same first-party granularity as Bing Webmaster Tools’ AI Performance tab at this time. Server-log analysis for AI crawler activity remains useful regardless of which AI systems you’re trying to track.
Should I optimize content specifically to increase citations?
Focus on being a clear, accurate, well-structured source on your subject rather than chasing citation counts directly. Citation tends to follow genuinely useful, well-organized content rather than any particular formatting trick.
Definition: The crawl war is the emerging three-way competition between Google, Microsoft (Bing), and OpenAI to discover, index, and serve web content through their respective AI-powered search and answer systems — Google AI Overviews, Microsoft Copilot, and ChatGPT Search. Each ecosystem crawls the web with fundamentally different strategies, speeds, and philosophies, and those differences determine which content gets cited by which AI system first.
For two decades, the search engine crawl was a two-player game: Googlebot dominated, Bingbot trailed, and publishers optimized exclusively for Google. That era is over. When we published 40 Microsoft Copilot articles on tygartmedia.com and monitored server logs for 48 hours, we recorded 6,805 AI crawler hits from three distinct ecosystems — each crawling with different speeds, different intensities, and different objectives (Tygart Media server log analysis, June 2026). What we observed was not just traffic. It was a competitive intelligence blueprint showing exactly how each ecosystem discovers, evaluates, and serves content. The differences are dramatic, and they fundamentally change how publishers should think about content distribution.
The Three Ecosystems: Radically Different Crawl Philosophies
Three ecosystems: radically different crawl philosophies.
The crawl war is not just about who crawls more. It is about how each ecosystem approaches the fundamental challenge of web content discovery and evaluation. Our server log data revealed three starkly different approaches operating simultaneously on the same content:
Google: Slow and conservative. Googlebot approached our content at its own pace, significantly slower than both Bing and OpenAI. Despite being the world’s largest search crawler, Google’s response to our 40-article publication was measured and deliberate — no urgency, no burst crawling, no IndexNow acceleration.
Bing: Fast and protocol-responsive. Bingbot was the first crawler to reach every single one of our 40 articles, arriving within a consistent 4-hour post-publish window triggered by our IndexNow implementation. Bingbot’s behavior was predictable, fast, and directly responsive to publisher signals.
OpenAI: Aggressive and structural. OpenAI’s crawler fleet — GPTBot, ChatGPT-User, and OAI-SearchBot — generated the largest volume of activity, including a 1,123-request structural crawl in a single hour. OpenAI’s approach is the most intensive of the three, treating content discovery as an active, aggressive process rather than a passive one.
Google’s Crawl Strategy: The Cautious Incumbent
Google has been crawling the web longer than any other company, and its crawl strategy reflects two decades of optimization for thoroughness over speed. Googlebot is the most comprehensive crawler on the web — according to Cloudflare data from January 2026, Googlebot reaches 1.70 times more unique URLs than ClaudeBot, 1.76 times more than GPTBot, 2.99 times more than Meta-ExternalAgent, and 3.26 times more than Bingbot. No other crawler comes close in terms of coverage breadth.
But coverage is not speed. In our experiment, Googlebot was dramatically slower to discover and index our content than Bingbot. While Bingbot reached every article within 4 hours via IndexNow, Google’s crawlers took significantly longer (Tygart Media server log analysis, June 2026). This speed gap is structural, not accidental — and it reveals a fundamental strategic choice Google has made.
Why Google Is Slow: The IndexNow Abstention
The single biggest reason for Google’s slower crawl response is its refusal to adopt IndexNow. IndexNow is the protocol that allows publishers to push notifications directly to search engines when content is published or updated. Bing, Yandex, and other participating search engines receive these notifications and can respond within minutes. Google does not participate in IndexNow. Instead, Google relies on its own crawl scheduling, sitemap processing, and link-following algorithms to discover new content — a process that is thorough but inherently slower.
Google’s stated position is that it already discovers content efficiently through its existing infrastructure. But our data tells a different story for time-sensitive content. When speed of discovery directly impacts whether content gets cited in AI-generated answers, Google’s conservative approach creates a tangible disadvantage compared to Bing’s IndexNow-responsive pipeline.
Google’s AI Layer: AI Overviews and Google-Extended
Google’s approach to AI crawling is to layer AI capabilities on top of existing Googlebot infrastructure rather than deploying separate AI-specific crawlers. Content indexed by Googlebot feeds both traditional search results and Google AI Overviews. The only AI-specific crawler is Google-Extended, which handles the opt-out mechanism for AI training — blocking Google-Extended prevents content from being used for Gemini model training while keeping it available for search and AI Overviews.
This integrated approach means Google does not need to crawl content twice — once for search, once for AI. But it also means Google’s AI Overviews are limited by Googlebot’s crawl schedule. If Googlebot has not indexed a page, Google AI Overviews cannot reference it. And since Googlebot is slower to discover new content than Bingbot (which uses IndexNow), Google AI Overviews are systematically slower to surface newly published content compared to Microsoft Copilot.
Bing’s Crawl Strategy: The Speed Advantage
Bing’s speed advantage in the crawl war.
Microsoft’s Bing has historically been the underdog in search — smaller index, lower market share, less publisher attention. But in the AI era, Bing has a structural advantage that Google lacks: IndexNow responsiveness and deep integration with Microsoft Copilot.
In our experiment, Bingbot’s behavior was the most predictable and publisher-friendly of all three ecosystems. Every single one of our 40 articles was discovered by Bingbot within a consistent 4-hour window after publication, triggered by our IndexNow implementation (Tygart Media server log analysis, June 2026). This consistency is remarkable — it means publishers who implement IndexNow can predict, with near-certainty, when their content will enter Bing’s index and become available for Copilot citation.
The IndexNow Pipeline: Publisher to Copilot in Hours
The Bing-to-Copilot pipeline works like this: you publish content, IndexNow notifies Bing, Bingbot crawls and indexes your page within approximately 4 hours, and that indexed content immediately becomes available to Copilot’s retrieval system. This is the fastest path from publication to AI citation available today.
Our server logs confirmed this pipeline operating exactly as designed. Within 24 hours of publishing our 40 articles, we recorded 3 confirmed referral visits from copilot.microsoft.com, with 2 carrying the utm_source=copilot.com parameter (Tygart Media server log analysis, June 2026). That is less than one business day from publication to confirmed Copilot citation — a timeline that would be impossible without IndexNow’s speed advantage.
The YandexBot Shadow Effect
An unexpected finding in our data: YandexBot consistently shadowed Bingbot, hitting each article approximately 30 seconds after Bingbot’s initial visit (Tygart Media server log analysis, June 2026). This confirms that IndexNow notifications propagate across all participating search engines simultaneously. When you ping IndexNow, you are not just notifying Bing — you are notifying every participating engine, including Yandex and any future participants. This multiplier effect makes IndexNow even more valuable than its Bing integration alone would suggest.
Bing Webmaster Tools AI Performance Dashboard
Microsoft has further cemented its position in the crawl war by launching the AI Performance dashboard in Bing Webmaster Tools (public preview, February 2026). This dashboard surfaces citation metrics specifically for AI-generated answers across Microsoft Copilot, AI-generated summaries in Bing, and select partner integrations. Publishers can see total citations, grounding queries (the exact queries that triggered each citation), page-level citation activity, and visibility trends over time. No other search engine offers comparable AI citation analytics — Google has no equivalent dashboard for AI Overviews citation tracking.
OpenAI’s Crawl Strategy: The Aggressive Newcomer
OpenAI’s aggressive newcomer crawl strategy.
OpenAI entered the web crawling game later than both Google and Microsoft, but its approach is by far the most aggressive. While Google crawls conservatively and Bing crawls responsively, OpenAI crawls intensively — deploying three separate crawlers (GPTBot, ChatGPT-User, OAI-SearchBot), each serving a distinct purpose, and generating enormous volumes of requests.
In our 48-hour monitoring window, OpenAI’s crawler fleet was the single largest source of AI crawler activity. ChatGPT-User alone generated 3,404 hits — each representing a real user’s query being answered using our content. GPTBot added a concentrated 1,123-request structural crawl in a single hour. Combined, OpenAI’s crawlers generated more traffic to our Copilot content cluster than any other AI company’s crawler fleet (Tygart Media server log analysis, June 2026).
The Structural Crawl Pattern: GPTBot’s Burst Behavior
The most distinctive behavior we observed from OpenAI was GPTBot’s burst crawling pattern. At 11:00 UTC on June 22, GPTBot executed 1,123 requests in a single hour, systematically visiting every article in our Copilot content cluster (Tygart Media server log analysis, June 2026). This is not the steady, distributed crawling you see from Googlebot or Bingbot. This is an aggressive, concentrated evaluation — OpenAI’s systems identifying a domain as a potential authority source and performing a comprehensive assessment in a compressed timeframe.
This burst pattern has significant implications for publishers. It suggests that OpenAI’s crawl system operates on a trigger model: when the system identifies a relevant domain (through user queries, link signals, or other discovery mechanisms), it dispatches GPTBot for a thorough, rapid evaluation rather than gradually crawling over days or weeks. For publishers, this means the first impression matters — when GPTBot arrives for a burst crawl, the quality and structure of your content at that moment determines whether your domain is classified as an authority source.
ChatGPT-User: The Real-Time Citation Engine
ChatGPT-User operates fundamentally differently from both Googlebot and Bingbot. Traditional search crawlers index content proactively — they crawl now so results are available later. ChatGPT-User fetches reactively — it visits your page only when a real user asks a question and ChatGPT needs your content to generate an answer. This makes ChatGPT-User the most direct connection between publisher content and user value in the entire AI search ecosystem.
The 3,404 ChatGPT-User hits we recorded represent 3,404 real moments where a real person received an answer that drew from our content (Tygart Media server log analysis, June 2026). Unlike traditional search traffic where you see a click and a pageview, ChatGPT-User traffic represents content consumption without a traditional visit — the user received value from your content through the AI intermediary. This is a paradigm shift in how content creates value, and publishers who do not track ChatGPT-User activity in their server logs are blind to an entire channel of content utilization.
The Crawl War Scoreboard: Head-to-Head Comparison
Based on our server log data and industry reporting, here is how the three ecosystems compare across the dimensions that matter most to publishers:
Speed of discovery: Bing wins decisively. IndexNow gives Bing a structural speed advantage that neither Google nor OpenAI can match for new content discovery. Our data showed a consistent 4-hour discovery window for Bingbot versus significantly longer for Googlebot (Tygart Media server log analysis, June 2026). OpenAI’s discovery speed varies — ChatGPT-User is demand-driven and can be near-instant for trending topics, while GPTBot’s burst crawling happens on OpenAI’s schedule, not the publisher’s.
Crawl intensity: OpenAI wins. The combined volume from GPTBot, ChatGPT-User, and OAI-SearchBot exceeds what any single crawler from Google or Microsoft generates. GPTBot’s 1,123-request burst alone would be an unusually intense day for most sites from any single traditional crawler.
Coverage breadth: Google wins. Googlebot reaches more unique URLs than any other crawler on the web — 1.76 times more than GPTBot and 3.26 times more than Bingbot according to Cloudflare data from January 2026. For comprehensive coverage, nothing beats Google’s crawl infrastructure.
Publisher transparency: Bing wins. The AI Performance dashboard in Bing Webmaster Tools provides citation-specific analytics that neither Google nor OpenAI offer. Publishers can see exactly which queries triggered citations and which pages were cited — actionable data that drives content optimization.
Publisher control: Anthropic leads (among AI companies) with independently controllable training and retrieval crawlers. Among the three ecosystems, OpenAI offers the most granular control with three separately configurable crawlers. Google’s Google-Extended provides training opt-out but no granular retrieval controls.
What This Means for Content Strategy: The End of Google-Centric SEO
The crawl war’s most important implication is strategic: optimizing exclusively for Google is no longer sufficient. The data from our experiment shows that AI systems from three different companies are actively crawling, evaluating, and citing web content — and each one uses different signals, different speeds, and different criteria for what it selects.
A content strategy that ignores Bing’s IndexNow advantage is leaving Copilot citations on the table. A strategy that ignores OpenAI’s aggressive crawling patterns is invisible to ChatGPT’s 3,404 query-driven fetches. A strategy that focuses only on Google’s organic crawl schedule is optimizing for the slowest discovery pipeline of the three.
The new paradigm is multi-engine optimization — designing content for discovery, evaluation, and citation across all three ecosystems simultaneously. This means implementing IndexNow for Bing speed, structuring content with schema markup for AI extraction across all platforms, building entity-rich content that satisfies all three ecosystems’ relevance criteria, and monitoring server logs for crawler activity from all major AI systems.
The Multi-Engine Optimization Framework
Based on our experiment data, here is the practical framework for optimizing across all three ecosystems:
For Bing and Copilot citation: Implement IndexNow for immediate content discovery. Target a 4-hour indexing window. Use Bing Webmaster Tools AI Performance dashboard to track citation metrics. Optimize for structured data that Copilot’s retrieval system can extract — Article schema, FAQPage schema, and BreadcrumbList schema.
For Google and AI Overviews: Submit sitemaps through Google Search Console. Ensure content is Google-Extended friendly (do not block Google-Extended unless you specifically want to opt out of Gemini training). Focus on E-E-A-T signals — author expertise, authoritative citations, and content depth — which Google’s AI Overviews weigh heavily in source selection.
For OpenAI and ChatGPT Search: Do not block OAI-SearchBot or ChatGPT-User in robots.txt (you can block GPTBot to prevent training use while keeping search access). Structure content with clear, extractable answers — question-formatted headings, definition boxes, and concise opening paragraphs that give ChatGPT clean extraction targets. Build topical authority through content clusters, which GPTBot’s burst crawling pattern appears to evaluate as a holistic signal.
For all three simultaneously: Server log monitoring is the universal requirement. It is the only way to see how each ecosystem’s crawlers are interacting with your content. Traditional analytics tools are blind to crawler traffic, making server logs the single most important data source for multi-engine optimization.
The Crawl War’s Impact on Publishing Economics
The crawl war has a direct impact on publishing economics that most publishers have not yet reckoned with. When AI crawlers generate 39% more traffic than traditional search crawlers — as our data showed (Tygart Media server log analysis, June 2026) — that traffic carries real server costs without corresponding ad revenue. AI crawlers do not see ads, do not generate pageviews in analytics, and do not contribute to the metrics that publishers use to sell advertising.
At the same time, the content that AI crawlers fetch is being used to generate answers that may reduce traditional search traffic — the phenomenon known as zero-click search. Publishers face a paradox: the more valuable your content is to AI systems, the more they crawl it, the more server resources they consume, and the more they potentially reduce your direct traffic by answering user queries without a click-through.
However, the 3 confirmed Copilot referrals we recorded suggest that AI citation does drive some click-through traffic — users who see a source cited in an AI answer do click through to read the full content. The question for publishers is whether citation-driven traffic will scale to replace or supplement the traditional search traffic that AI systems are cannibalizing. Our data suggests the click-through rate from AI citations is positive but modest, making content quality and authority optimization — rather than raw traffic volume — the new economic foundation for publishing in the AI era.
What Comes Next in the Crawl War
The crawl war is intensifying, not settling. Several developments are reshaping the competitive landscape. Bing Webmaster Tools’ AI Performance dashboard, launched in February 2026, gives publishers the first actionable data about AI citation performance — a competitive moat that Google has not yet matched. OpenAI’s continued expansion of ChatGPT Search is driving ChatGPT-User volumes higher, making it an increasingly important content discovery channel. And Google’s integration of AI Overviews into mainstream search results means that Google’s slower crawl speed may matter less over time as AI Overviews draw from Google’s already-comprehensive index.
For publishers, the strategic imperative is clear: the era of Google-only optimization is over. The crawl war has created a multi-engine landscape where content must be optimized for discovery, evaluation, and citation across three fundamentally different ecosystems. The publishers who adapt fastest — implementing IndexNow, monitoring server logs, and structuring content for AI extraction — will capture the citation advantage that defines the next era of content distribution.
Our 40-article experiment captured this war in real time: 6,805 AI crawler hits from three competing ecosystems, each approaching the same content with radically different strategies. The data does not lie. The crawl war is here, it is reshaping how content gets discovered and cited, and the publishers who understand it will win.
Frequently Asked Questions
Why is Bing faster than Google at discovering new content?
Bing participates in the IndexNow protocol, which allows publishers to push instant notifications when content is published or updated. Google does not participate in IndexNow and relies instead on its own crawl scheduling and sitemap processing. In our experiment, Bingbot reached every new article within a consistent 4-hour window after publication via IndexNow, while Googlebot was dramatically slower to discover the same content (Tygart Media server log analysis, June 2026). For publishers seeking fast AI citation through Microsoft Copilot, this speed advantage is decisive.
Does OpenAI crawl more aggressively than Google or Bing?
Yes. OpenAI deploys three separate crawlers — GPTBot, ChatGPT-User, and OAI-SearchBot — and their combined activity in our experiment exceeded any single crawler from Google or Microsoft. GPTBot alone executed a 1,123-request burst crawl in a single hour, and ChatGPT-User generated 3,404 hits representing real user queries (Tygart Media server log analysis, June 2026). OpenAI’s crawl philosophy is intensive and structural, designed to rapidly evaluate and index content domains rather than gradually discovering them over time.
What is multi-engine optimization and why does it matter?
Multi-engine optimization is the practice of designing content for discovery, evaluation, and citation across multiple AI ecosystems — Google AI Overviews, Microsoft Copilot, and ChatGPT Search — rather than optimizing exclusively for Google. It matters because each ecosystem uses different crawlers, different speeds, and different criteria for selecting content to cite. Our data showed AI crawlers from all three ecosystems actively evaluating the same content with different strategies (Tygart Media server log analysis, June 2026). Publishers who optimize only for Google are invisible to Copilot and ChatGPT citations.
How do I know which AI crawlers are visiting my website?
Check your server logs (access.log or combined.log files on Apache or Nginx) and search for AI crawler user agent strings: GPTBot, ChatGPT-User, OAI-SearchBot, ClaudeBot, Claude-SearchBot, PerplexityBot, AzureAI-SearchBot, meta-externalagent, and Google-Extended. Traditional analytics tools like Google Analytics do not capture crawler traffic because they rely on JavaScript execution, which crawlers do not perform. Server logs are the only way to see AI crawler activity on your site.
Should I implement IndexNow if I primarily care about Google rankings?
Yes. While IndexNow does not directly benefit Google (which does not participate in the protocol), implementing IndexNow gives you immediate access to Bing’s indexing pipeline and Microsoft Copilot citation — an AI citation channel you would otherwise miss entirely. In our experiment, Bingbot discovered all 40 articles within 4 hours via IndexNow, and we received 3 confirmed Copilot citations within 24 hours (Tygart Media server log analysis, June 2026). The implementation cost is minimal (a WordPress plugin), and the citation upside is significant.
Definition: AI crawlers are automated web agents deployed by artificial intelligence companies to discover, evaluate, and retrieve web content for use in AI model training, search retrieval, and real-time answer generation. Unlike traditional search engine crawlers that index content for organic search rankings, AI crawlers serve a hierarchy of distinct purposes — and understanding that hierarchy is now essential for any publisher who wants their content cited by AI systems.
When we published 40 Microsoft Copilot articles on tygartmedia.com and monitored our server logs for 48 hours, we recorded 6,805 AI crawler hits — 39% more than the 4,897 hits from traditional search crawlers Googlebot and Bingbot combined (Tygart Media server log analysis, June 2026). But the raw number only tells part of the story. The real insight came from breaking down those hits by crawler identity: each AI crawler serves a different purpose, operates under different rules, and signals something different about how AI systems are evaluating your content. This reference guide maps every major AI crawler, explains what each one does, and shows you what their activity means for your content strategy.
Why AI Crawlers Are Now More Active Than Traditional Search Crawlers
Why AI crawlers are now more active than traditional search crawlers.
The shift happened faster than most publishers realize. In our 48-hour monitoring window, AI-specific crawlers generated 6,805 hits compared to 4,897 from Googlebot and Bingbot combined — a 39% traffic advantage for AI systems (Tygart Media server log analysis, June 2026). This aligns with broader industry data: Cloudflare reported in 2025 that AI crawlers were generating more than 50 billion requests per day across the web.
This is not a temporary spike. AI systems are fundamentally more request-intensive than traditional search engines because they serve multiple purposes simultaneously: training data collection, search index building, and real-time content retrieval for live user queries. A single piece of content might be visited by GPTBot for training evaluation, by OAI-SearchBot for search indexing, and by ChatGPT-User when a real person asks a question — three distinct visits from three distinct crawlers, all from the same company (OpenAI), all serving different functions.
The OpenAI Crawler Fleet: GPTBot, ChatGPT-User, and OAI-SearchBot
OpenAI crawler fleet — GPTBot and friends.
OpenAI operates the most active AI crawler fleet on the web, with three distinct crawlers that each serve a different purpose. Understanding the difference between them is critical because each one tells you something different about how OpenAI’s systems are evaluating your content.
GPTBot — The Training and Evaluation Crawler
Operator: OpenAI Purpose: Gathers content which may be used to train OpenAI’s generative AI foundation models User Agent String:Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.1; +https://openai.com/gptbot IP Range Source: https://openai.com/gptbot.json Robots.txt Control:User-agent: GPTBot — can be allowed or disallowed independently
GPTBot is OpenAI’s primary training data crawler. When GPTBot visits your site, it is evaluating whether your content is suitable for inclusion in the training datasets used to build and improve OpenAI’s large language models. In our server log analysis, we observed GPTBot execute a dramatic 1,123-request structural crawl in a single hour at 11:00 UTC on June 22, 2026, systematically visiting every article in our Copilot content cluster (Tygart Media server log analysis, June 2026). This burst pattern — concentrated, systematic, and thorough — is characteristic of GPTBot performing a domain-wide quality assessment.
The critical distinction: blocking GPTBot via robots.txt prevents your content from being used for training, but it does not prevent your content from appearing in ChatGPT’s search results. GPTBot and the search crawlers operate independently.
ChatGPT-User — The Live Query Crawler
Operator: OpenAI Purpose: Fetches a web page on demand when a user inside ChatGPT asks a question — not a training crawler User Agent String:Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; ChatGPT-User/1.0; +https://openai.com/bot IP Range Source: https://openai.com/chatgpt-user.json Robots.txt Control:User-agent: ChatGPT-User
ChatGPT-User is arguably the most important AI crawler for publishers to understand. Every single ChatGPT-User hit in your server logs represents a real person, right now, asking ChatGPT a question and ChatGPT fetching your page to help formulate an answer. This is not background crawling. This is not training data collection. This is live, query-driven traffic — the AI equivalent of a user clicking on your search result, except the AI is doing the clicking on the user’s behalf.
In our 48-hour experiment, ChatGPT-User generated 3,404 hits — the single largest source of AI crawler traffic to our content (Tygart Media server log analysis, June 2026). Each of those 3,404 hits represents a real user’s query being answered using our content. The volume is staggering and represents a content discovery channel that did not exist three years ago.
User agent versions 1.0, 2.0, and 3.0 have all been observed in server logs across the industry, indicating that OpenAI has iterated on the ChatGPT-User crawler multiple times.
OAI-SearchBot — The Search Index Crawler
Operator: OpenAI Purpose: Powers ChatGPT Search by indexing pages for retrieval and citation — a completely separate system from training data collection User Agent String:Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; OAI-SearchBot/1.0; +https://openai.com/searchbot IP Range Source: https://openai.com/searchbot.json Robots.txt Control:User-agent: OAI-SearchBot
OAI-SearchBot is OpenAI’s dedicated search indexing crawler, building the index that powers ChatGPT’s search features. Think of it as OpenAI’s equivalent of Googlebot — it crawls the web to build a searchable index, not to collect training data. The key distinction from ChatGPT-User is timing: OAI-SearchBot crawls proactively to build the index, while ChatGPT-User fetches reactively when a user asks a question.
For publishers, OAI-SearchBot activity is a leading indicator. If OAI-SearchBot is regularly crawling your content, your pages are being added to ChatGPT’s search index, which means they are available for citation in ChatGPT Search results. If OAI-SearchBot is not visiting your content, your pages may not appear in ChatGPT’s web-grounded answers even if GPTBot has crawled them for training purposes.
Microsoft’s AI Crawlers: Bingbot and AzureAI-SearchBot
Microsoft’s AI crawler strategy is tightly integrated with its existing Bing search infrastructure. Unlike OpenAI, which built a separate crawler fleet from scratch, Microsoft leverages Bingbot — the world’s second-largest search crawler — as the primary discovery mechanism for its AI systems, including Microsoft Copilot.
Bingbot — The Dual-Purpose Search and AI Crawler
Operator: Microsoft Purpose: Powers both Bing search results and Microsoft Copilot’s web-grounded answers User Agent String:Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; bingbot/2.0; +http://www.bing.com/bingbot.htm Robots.txt Control:User-agent: bingbot
Bingbot occupies a unique position in the AI crawler hierarchy because it serves a dual purpose: it powers both traditional Bing search results and Microsoft Copilot’s web-grounded answers. When Bingbot indexes your content, that content becomes available to Copilot’s retrieval system. This makes Bingbot the most important single crawler for Copilot citation — if Bingbot has not indexed your page, Copilot cannot cite it.
In our experiment, Bingbot demonstrated remarkable speed and consistency. It was the first crawler to reach every single one of our 40 articles, with a predictable 4-hour post-publish gap triggered by our IndexNow implementation (Tygart Media server log analysis, June 2026). This consistency makes Bingbot behavior highly predictable for publishers who use IndexNow — you can expect your content to be discoverable by Copilot within 4 hours of publication.
AzureAI-SearchBot — Microsoft’s Specialized AI Crawler
Operator: Microsoft Purpose: Specialized content retrieval for Azure AI services, including enterprise Copilot integrations User Agent String: Contains AzureAI-SearchBot identifier Robots.txt Control:User-agent: AzureAI-SearchBot
AzureAI-SearchBot is Microsoft’s newer, more specialized AI crawler that operates alongside Bingbot. While Bingbot handles broad web indexing, AzureAI-SearchBot appears to perform more selective, targeted content evaluation for Azure AI services. In our server logs, AzureAI-SearchBot generated only 3 hits during the 48-hour monitoring window — compared to Bingbot’s hundreds of hits — suggesting a highly selective evaluation pattern rather than broad crawling (Tygart Media server log analysis, June 2026).
The low volume but deliberate targeting of AzureAI-SearchBot suggests it may be evaluating content for enterprise Copilot integrations or specialized Azure AI services rather than the consumer-facing Copilot product. Publishers who see AzureAI-SearchBot hits in their logs may be candidates for higher-trust citation treatment in Microsoft’s enterprise AI products.
Anthropic’s Crawlers: ClaudeBot and Claude-SearchBot
Anthropic crawlers — ClaudeBot and search bots.
ClaudeBot — Anthropic’s Training Crawler
Operator: Anthropic Purpose: Collects content for training Anthropic’s Claude models User Agent String:Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; ClaudeBot/1.0; +https://www.anthropic.com/claubot Robots.txt Control:User-agent: ClaudeBot
ClaudeBot is Anthropic’s crawler for collecting training data for the Claude family of AI models. Like GPTBot, ClaudeBot crawls the web to evaluate and potentially collect content for model training. According to Cloudflare data, as of January 2026, Googlebot reached 1.70 times more unique URLs than ClaudeBot, placing ClaudeBot as one of the most active AI crawlers on the web in terms of coverage breadth.
Claude-SearchBot — Anthropic’s Retrieval Crawler
Operator: Anthropic Purpose: Retrieves web content for Claude’s search and citation features Robots.txt Control:User-agent: Claude-SearchBot — independently controllable from ClaudeBot
Claude-SearchBot is Anthropic’s dedicated search retrieval crawler, separate from ClaudeBot. The critical detail for publishers: Claude-SearchBot and ClaudeBot can be controlled independently via robots.txt. This means publishers can allow Claude-SearchBot (enabling their content to appear in Claude’s retrieval and citation features) while disallowing ClaudeBot (keeping content out of training data). This granular control model is unique among major AI companies and represents a publisher-friendly approach to the training-versus-retrieval distinction.
Other Major AI Crawlers You Should Know
PerplexityBot
Operator: Perplexity AI Purpose: Indexes content for Perplexity’s answer engine, which provides sourced answers with inline citations User Agent String: Contains PerplexityBot identifier Robots.txt Control:User-agent: PerplexityBot
Perplexity operates as an AI-native answer engine that explicitly cites its sources with inline footnotes. PerplexityBot crawls the web to build Perplexity’s index. While smaller in scale than OpenAI’s or Anthropic’s crawlers — Cloudflare data shows Googlebot reaches 167 times more unique URLs than PerplexityBot — Perplexity’s citation-heavy model makes it particularly valuable for publishers who want visible attribution in AI-generated answers.
Meta-ExternalAgent (Bytespider)
Operator: Meta Platforms Purpose: Collects content for Meta’s AI products including Meta AI (powered by Llama models) User Agent String: Contains meta-externalagent identifier Robots.txt Control:User-agent: meta-externalagent
Meta-ExternalAgent is Meta’s web crawler for AI content collection, supporting Meta’s Llama model family and Meta AI assistant products integrated across Facebook, Instagram, WhatsApp, and Messenger. According to Cloudflare data from January 2026, Googlebot reached 2.99 times more unique URLs than Meta-ExternalAgent, placing it as a significant but secondary crawler compared to OpenAI and Anthropic’s agents. The Bytespider crawler, associated with ByteDance (TikTok’s parent company), serves a similar training data collection function for ByteDance’s AI models.
Google’s AI Crawlers
Operator: Google Key User Agents:Google-Extended, Googlebot, Google-CloudVertexBot Robots.txt Control:User-agent: Google-Extended (for AI training opt-out)
Google’s approach to AI crawling is unique because it leverages the existing Googlebot infrastructure rather than deploying entirely separate AI-specific crawlers. Googlebot serves double duty — indexing content for Google Search and providing the foundation for Google AI Overviews. Google-Extended is the opt-out mechanism: blocking Google-Extended prevents your content from being used for Gemini model training while still allowing Googlebot to index your content for search. Google-CloudVertexBot handles content retrieval for Google’s Vertex AI enterprise products.
Notably, Google also operates specialized agents including Google-NotebookLM (for the NotebookLM product) and Google-Read-Aloud (for text-to-speech features), each controllable independently via robots.txt.
Other Notable AI Crawlers
Amazonbot: Amazon’s web crawler supporting Alexa and other Amazon AI products. User agent contains Amazonbot. Applebot: Apple’s crawler for Siri, Spotlight, and Apple Intelligence features. User agent contains Applebot. DuckAssistBot: DuckDuckGo’s AI assistant crawler for DuckAssist answers. User agent contains DuckAssistBot. CCBot: Common Crawl’s crawler, which produces the open dataset used by many AI companies for model training. Cloudflare data shows Googlebot reaches 714 times more unique URLs than CCBot.
The AI Crawler Hierarchy: A Functional Classification
Understanding the AI crawler landscape requires organizing these crawlers into functional tiers based on what their activity means for publishers:
Tier 1: Real-Time Query Crawlers. ChatGPT-User and similar user-triggered crawlers. Every hit represents a real user’s question being answered right now. These are the highest-value signals because they indicate your content is actively being used to generate AI answers. In our experiment, ChatGPT-User was the dominant Tier 1 crawler with 3,404 hits (Tygart Media server log analysis, June 2026).
Tier 2: Search Index Crawlers. OAI-SearchBot, Bingbot (for Copilot), Claude-SearchBot, PerplexityBot. These crawlers build the search indexes that AI systems query when answering questions. Activity from Tier 2 crawlers indicates your content is being indexed for potential citation. Bingbot’s consistent 4-hour IndexNow response made it our most reliable Tier 2 crawler.
Tier 3: Training and Evaluation Crawlers. GPTBot, ClaudeBot, Meta-ExternalAgent, Google-Extended. These crawlers collect content for model training and evaluation. High activity from Tier 3 crawlers means your content is being considered for inclusion in training datasets. GPTBot’s 1,123-request burst crawl at 11:00 UTC exemplified Tier 3 behavior — systematic, comprehensive, evaluative (Tygart Media server log analysis, June 2026).
Tier 4: Specialized and Emerging Crawlers. AzureAI-SearchBot, Google-NotebookLM, DuckAssistBot, Amazonbot. Lower volume, more targeted, often serving specific product use cases. Our observation of only 3 AzureAI-SearchBot hits suggests Tier 4 crawlers are highly selective (Tygart Media server log analysis, June 2026).
How to Identify AI Crawlers in Your Server Logs
Most publishers have never looked at their server logs for AI crawler activity because traditional analytics tools (Google Analytics, Adobe Analytics) do not capture bot traffic. To see AI crawlers, you need access to raw server logs — typically access.log or combined.log files on Apache or Nginx servers.
The simplest approach is to grep your logs for known AI user agent strings. Here are the key strings to search for, based on our verified server log data and official documentation from each operator:
GPTBot — OpenAI training crawler ChatGPT-User — OpenAI live query crawler OAI-SearchBot — OpenAI search index crawler bingbot — Microsoft search and Copilot crawler AzureAI-SearchBot — Microsoft specialized AI crawler ClaudeBot — Anthropic training crawler Claude-SearchBot — Anthropic retrieval crawler PerplexityBot — Perplexity answer engine crawler meta-externalagent — Meta AI crawler Google-Extended — Google AI training crawler Amazonbot — Amazon AI crawler Applebot — Apple AI crawler Bytespider — ByteDance AI crawler DuckAssistBot — DuckDuckGo AI assistant crawler CCBot — Common Crawl open dataset crawler
What AI Crawler Activity Tells You About Your Content
Different patterns of AI crawler activity reveal different things about how AI systems perceive your content:
High ChatGPT-User volume: Your content is actively being used to answer real user queries. This is the strongest signal that your content is being cited by AI systems. Our 3,404 ChatGPT-User hits across the Copilot cluster confirmed that our content was being pulled into live answers (Tygart Media server log analysis, June 2026).
GPTBot burst crawling: OpenAI’s systems have identified your domain as a potential authority source and are performing a deep evaluation. The 1,123-request burst we observed is characteristic of GPTBot’s domain evaluation pattern — it does not crawl this aggressively unless it has identified the domain as potentially high-value content (Tygart Media server log analysis, June 2026).
Consistent Bingbot visits via IndexNow: Your IndexNow implementation is working, and your content is being indexed for Copilot citation. The 4-hour gap pattern we observed is your feedback loop — if Bingbot is arriving within hours of publication, your indexing pipeline is healthy.
Low or zero AI crawler activity: Your content may be blocked by robots.txt, your server may be rejecting crawler requests, or your content may not be reaching the quality or topical relevance threshold for AI system evaluation. Check your robots.txt and server response codes for AI user agents.
Managing AI Crawlers: Allow, Block, or Selective Access
Publishers face a three-way decision for each AI crawler: allow full access (content can be used for training and retrieval), allow selective access (retrieval only, no training), or block entirely. The most nuanced approach — and the one we recommend — is selective access that allows retrieval crawlers while blocking training crawlers.
Anthropic’s model is the most publisher-friendly in this regard: ClaudeBot (training) and Claude-SearchBot (retrieval) are independently controllable. OpenAI offers similar granularity: you can block GPTBot (training) while allowing ChatGPT-User (retrieval) and OAI-SearchBot (search indexing). Google allows blocking Google-Extended (training) while keeping Googlebot active for search.
The practical implication: a robots.txt configuration that blocks training crawlers while allowing retrieval crawlers ensures your content is available for AI citation without contributing to model training datasets. This is the optimal configuration for most publishers who want to be cited by AI systems while maintaining control over their content’s use in training.
Frequently Asked Questions
What is the difference between GPTBot and ChatGPT-User?
GPTBot is OpenAI’s training data crawler — it collects content that may be used to train and improve OpenAI’s foundation models. ChatGPT-User is a live query crawler that fetches web pages on demand when a real user asks ChatGPT a question. Every ChatGPT-User hit represents an actual user query being answered. They serve completely different purposes and can be controlled independently via robots.txt. In our server logs, ChatGPT-User generated 3,404 hits representing real user queries, while GPTBot performed a 1,123-request structural evaluation crawl (Tygart Media server log analysis, June 2026).
How many AI crawlers are actively crawling the web in 2026?
There are at least 15 major AI crawlers actively operating as of mid-2026, operated by OpenAI (GPTBot, ChatGPT-User, OAI-SearchBot), Microsoft (Bingbot, AzureAI-SearchBot), Anthropic (ClaudeBot, Claude-SearchBot), Google (Google-Extended, Google-CloudVertexBot, Google-NotebookLM), Meta (meta-externalagent), Perplexity (PerplexityBot), Amazon (Amazonbot), Apple (Applebot), ByteDance (Bytespider), DuckDuckGo (DuckAssistBot), and Common Crawl (CCBot). Cloudflare reported AI crawlers generating more than 50 billion requests per day in 2025, and that volume has continued to grow.
Can I allow AI citation while blocking AI training on my content?
Yes. Most major AI companies now separate their training crawlers from their retrieval crawlers, allowing publishers to control each independently via robots.txt. Block GPTBot and ClaudeBot (training) while allowing ChatGPT-User, OAI-SearchBot, and Claude-SearchBot (retrieval and citation). For Google, block Google-Extended while keeping Googlebot active. This configuration ensures your content can be cited in AI answers without being used to train models.
Why don’t Google Analytics or similar tools show AI crawler traffic?
Google Analytics and similar web analytics tools rely on JavaScript execution in a browser to record visits. AI crawlers do not execute JavaScript — they fetch the raw HTML of your page and process it server-side. This means AI crawler visits are completely invisible to any JavaScript-based analytics tool. The only way to see AI crawler activity is through server logs (access.log or combined.log files on Apache or Nginx), which record every HTTP request including those from bots and crawlers.
What does a ChatGPT-User hit mean for my content strategy?
A ChatGPT-User hit means a real person asked ChatGPT a question, and ChatGPT fetched your page to help generate the answer. This is the direct AI equivalent of a user clicking on your search result — except the AI is doing the retrieval. High ChatGPT-User volume on specific pages indicates those pages are being actively used as citation sources for live user queries. This is the strongest signal that your content is performing well in the AI search ecosystem and should be prioritized for updates, expansion, and optimization.
GPTBot is crawling the web harder than Google. That is not speculation, not a prediction, and not a think-piece extrapolation from someone else’s data. It is what our server logs show. When Tygart Media published 40 articles on June 22, 2026, and monitored every crawler that touched our server over the next 48 hours, GPTBot emerged as the most aggressive indexing operation we have ever recorded — and the data is not even close.
This is the third article in Tygart Media’s AI Search Intelligence series, based on proprietary server log data from our 40-article Microsoft Copilot content experiment. For the full methodology and complete dataset, see the anchor article. For the crawl speed comparison, see our IndexNow Speed Test.
The Numbers: GPTBot vs. Everything Else
The numbers: GPTBot vs everything else.
During the 48-hour observation window following our 40-article batch publish, AI crawlers generated 6,805 total hits on our server. Traditional search crawlers — Googlebot and Bingbot combined — generated 4,897 hits. AI crawlers outpaced traditional search crawlers by 39% (Tygart Media server log analysis, June 2026).
But the aggregate numbers undersell what GPTBot did. Look at the individual crawler breakdown:
ChatGPT-User: 3,404 hits (real-time user query fetches)
GPTBot: 1,123 requests in a single hour (structural indexing crawl)
Bingbot: The bulk of traditional crawler hits, arriving 3-6 hours post-IndexNow
Googlebot: 1 hit on Copilot content in the initial window
OAI-SearchBot: 3 hits
AzureAI-SearchBot: 3 hits
GPTBot executed 1,123 requests in 60 minutes. Not over a day. Not over a crawl cycle. In one hour. To put that in perspective, that is roughly 18.7 requests per minute, sustained for an entire hour, against a single WordPress site on a standard Compute Engine instance.
What GPTBot Actually Crawled
What GPTBot actually crawled.
If GPTBot had simply hit each of our 40 article URLs, that would be 40 requests. We recorded 1,123 in a single hour. The difference — over 1,000 additional requests — reveals what GPTBot is actually doing when it indexes a site.
Our server logs show GPTBot systematically accessed (Tygart Media server log analysis, June 2026):
Every tag page generated by the new articles — each tag aggregation page was crawled individually
RSS feed endpoints — both the main site feed and category-specific feeds
WordPress REST API endpoints — including /wp-json/wp/v2/posts and related API routes that return structured JSON data about content
Category and archive pages — every category listing page that included the new content
Author archive pages — the author page for the publishing account
This is not content reading. This is site architecture mapping. GPTBot is building a complete structural model of how your content relates to itself — what categories it belongs to, what tags connect it to other content, who authored it, what the JSON API says about its metadata, how it appears in feeds.
Traditional search engine crawlers do this too, but on a much slower schedule. Googlebot will eventually crawl your tag pages and category archives, but it does so gradually over days or weeks. GPTBot mapped the entire structure in 60 minutes.
Why This Matters: GPTBot Is Not Just Reading — It Is Understanding
The distinction between content crawling and structural crawling is critical for understanding what AI systems do with your site. A content crawler reads your articles and indexes the text. A structural crawler builds a graph of relationships between your content.
When GPTBot crawls your REST API endpoints, it gets structured JSON data about every post — titles, excerpts, categories, tags, author information, publication dates, modified dates, and featured images. This is far richer metadata than what is available in the HTML of a rendered page. It is the kind of data you would use to build a knowledge graph, not just a search index.
When GPTBot crawls your tag pages, it learns which topics co-occur. Articles tagged “Microsoft Copilot” and “AI productivity” and “enterprise software” create a topical cluster that GPTBot can map. When it crawls category pages, it learns your site’s editorial taxonomy — how you organize knowledge.
For publishers, the implication is direct: your WordPress taxonomy, tag structure, and internal linking are now inputs to how AI models understand your authority and expertise. A site with clean, logical taxonomy that reflects genuine topical expertise will produce a richer structural map for GPTBot than a site with messy, inconsistent categorization.
The ChatGPT-User Signal: 3,404 Proof Points
While GPTBot is the most aggressive structural crawler, ChatGPT-User is the most important from a business perspective. Every one of the 3,404 ChatGPT-User hits on our server represents a real person asking ChatGPT a question and ChatGPT fetching our page to answer it (Tygart Media server log analysis, June 2026).
ChatGPT-User is not a training crawler. It does not run automatic, large-scale crawls. It activates only when a human user’s query triggers a need for live web content. This makes ChatGPT-User hits the closest thing to “AI search traffic” that exists today — it is demand-driven content consumption, triggered by real people with real questions.
The 3,404 hits over 48 hours on 40 articles about Microsoft Copilot tell us several things:
Copilot is a hot topic: People are actively asking ChatGPT questions about Microsoft Copilot, and ChatGPT is reaching for live web content to answer them
New content gets fetched quickly: Our articles were less than 48 hours old and already being served to ChatGPT users
The volume is substantial: 3,404 fetches in 48 hours rivals what many sites see from organic search traffic for a 40-article batch
This traffic is invisible in Google Analytics. It does not show up as organic search. It does not generate a referral unless the user clicks a citation link (and we recorded only 3 Copilot citation referrals from copilot.microsoft.com in this window). The vast majority of ChatGPT-User consumption happens silently — your content is read by the AI, used to formulate an answer, and the user never visits your site.
AI Crawlers vs. Traditional Crawlers: The 39% Gap
The headline number — AI crawlers generating 39% more traffic than traditional search crawlers — deserves unpacking because it represents a structural shift in how the web is consumed.
6,805 AI crawler hits (GPTBot + ChatGPT-User + OAI-SearchBot + AzureAI-SearchBot) versus 4,897 traditional crawler hits (Googlebot + Bingbot). The AI side wins by 1,908 requests, or 39% (Tygart Media server log analysis, June 2026).
This is a single 48-hour snapshot of a single site. Extrapolating to the entire web requires caution. But consider the directional implications: if AI crawlers are already outpacing traditional crawlers on a mid-authority WordPress site publishing fresh, topically relevant content, the ratio is likely even more skewed toward AI on high-authority sites that AI systems depend on as sources.
The 39% gap also understates the difference in crawl intensity. Googlebot’s crawl was gentle — 1 hit on Copilot content initially. Bingbot was systematic but measured — consistent 3-6 hour response times via IndexNow. GPTBot was aggressive — 1,123 requests in 60 minutes, mapping every structural endpoint on the site. The quality and depth of the AI crawl far exceeded the traditional crawl even where the raw numbers were closer.
What GPTBot’s Aggression Means for Your Server
What GPTBot aggression means for your server.
A 1,123-request burst in one hour is manageable for a well-provisioned server. Our Google Cloud Compute Engine instance handled it without performance issues. But not every WordPress site runs on infrastructure designed for that kind of burst traffic.
Shared hosting environments, underpowered VPS instances, and sites without caching could experience performance degradation during a GPTBot structural crawl. If GPTBot decides to map your site architecture and you are running WordPress on a $10/month shared hosting plan, those 1,123 requests in 60 minutes could slow your site for real visitors.
The practical recommendations:
Monitor your server logs for GPTBot activity. Know how aggressively it is crawling your site and when.
Ensure your hosting can handle burst traffic. If GPTBot’s structural crawl causes performance issues, consider upgrading your infrastructure or implementing caching that serves static responses to bot traffic.
Use robots.txt crawl-delay directives if GPTBot is causing problems. OpenAI’s documentation states that GPTBot respects robots.txt, including crawl-delay directives.
Do not block GPTBot unless you have a specific reason. Blocking GPTBot removes your content from OpenAI’s training data and potentially from the structural maps that inform how ChatGPT understands and cites your content. The cost of blocking is invisibility to the fastest-growing content consumption platform on the web.
The Bigger Picture: We Are in the AI Crawler Era
For two decades, “web crawling” meant Googlebot. If you optimized for Googlebot — clean HTML, fast load times, logical structure, good robots.txt — you were optimized for search. Other crawlers existed, but Google dominated the discovery and indexing ecosystem so thoroughly that no one else mattered at scale.
Our server log data from June 2026 suggests that era is ending. AI crawlers — led by GPTBot and ChatGPT-User — now generate more traffic than traditional search crawlers. They crawl faster, deeper, and more aggressively. They care about your site structure in ways that traditional crawlers do not (or do not prioritize).
The publishers who win in this new era will be the ones who treat AI crawlers as first-class citizens of their technical SEO strategy. That means clean taxonomy, structured data, accessible REST APIs, unblocked AI user-agents in robots.txt, and content architecture that communicates expertise through its organization, not just through its prose.
GPTBot is the internet’s most aggressive crawler. Our server logs prove it. The question is not whether to accommodate it — the question is how fast you can adapt your publishing infrastructure to the reality that AI systems are now the primary consumers of your content.
Frequently Asked Questions
How many requests did GPTBot make in one hour during the experiment?
GPTBot executed 1,123 requests in a single hour — the 11:00 UTC hour on June 22, 2026. That is approximately 18.7 requests per minute sustained for 60 minutes. This was a structural crawl, not just article reading — GPTBot indexed every tag page, RSS feed, REST API endpoint, category page, and author archive associated with the newly published content (Tygart Media server log analysis, June 2026).
Do AI crawlers now generate more traffic than Google and Bing combined?
In our 48-hour observation window, yes. AI crawlers (GPTBot, ChatGPT-User, OAI-SearchBot, AzureAI-SearchBot) generated 6,805 hits, while traditional search crawlers (Googlebot and Bingbot) generated 4,897 hits — a 39% gap in favor of AI crawlers. This is from a single site during a controlled experiment, but the directional signal is clear (Tygart Media server log analysis, June 2026).
What is the difference between GPTBot and ChatGPT-User?
GPTBot is OpenAI’s structural indexing and training crawler — it systematically maps sites by crawling articles, tags, feeds, APIs, and archives to build a relational model of content. ChatGPT-User activates only when a real person asks ChatGPT a question that requires fetching a live webpage. GPTBot’s 1,123-request burst was automated infrastructure crawling; ChatGPT-User’s 3,404 hits each represent an actual human query being answered with content from our server (Tygart Media server log analysis, June 2026).
Should I block GPTBot to protect my server from aggressive crawling?
Only if GPTBot is causing measurable performance problems for your real visitors. Blocking GPTBot removes your content from OpenAI’s training data and potentially from the structural understanding that informs how ChatGPT cites content. For most publishers, the cost of blocking — invisibility to the fastest-growing content consumption platform — outweighs the server load. If burst traffic is an issue, use robots.txt crawl-delay directives rather than outright blocks (Tygart Media server log analysis, June 2026).
Why did Googlebot only record 1 hit while GPTBot recorded over 1,123?
Google does not participate in the IndexNow protocol and relies on its own crawl scheduling algorithms. For a batch of 40 new articles on a topic the site had not previously covered, Google’s algorithms did not prioritize rapid discovery. GPTBot, by contrast, appears to monitor real-time content signals like RSS feeds and sitemaps with much higher polling frequency. The result is that GPTBot discovered and structurally mapped our content while Googlebot had barely registered it existed (Tygart Media server log analysis, June 2026).
This is the capstone of Tygart Media’s AI Search Intelligence series — the full behind-the-scenes of a 40-article experiment designed to test a single thesis: that Bing’s search index, Microsoft Copilot’s citation behavior, and Bing Ads’ retargeting capabilities form the only closed-loop AI search monetization system available to publishers in 2026.
Over the preceding nine articles in this series, we’ve covered the individual components — server log analysis, topic selection methodology, AI citation valuation, and the technical optimization layers that make content citable by AI systems. This article ties it all together: the thesis, the experiment design, the day-one data, and what it means for every publisher navigating the shift from clicks to citations.
The Thesis: Why Bing Is the Only Closed-Loop AI Monetization Platform
Why Bing is the closed-loop AI monetization platform.
The core thesis behind this entire experiment is straightforward, but its implications are enormous:
Bing powers Microsoft Copilot’s citations. If you publish authoritative content that Bing indexes quickly, Copilot will cite it. You can then retarget those AI-referred visitors with Bing Ads. This creates a repeatable publish → index → cite → retarget → monetize flywheel that does not exist on any other platform.
This is not speculation. It is an architectural reality of how Microsoft has built its AI search stack. Let’s break down why Bing — and only Bing — makes this possible.
Microsoft Copilot Uses Bing’s Index for Grounding
When a Microsoft 365 Copilot user asks a question in Teams, Word, or the Copilot sidebar, the system retrieves grounding information from Bing’s search index. This is not a separate AI index. It is the same Bing index that traditional search queries hit. That means every piece of content that Bing has indexed is a candidate for Copilot citation — and every Copilot citation carries a clickable source link back to the publisher’s domain.
The IndexNow protocol gives publishers a mechanism to notify Bing (and other participating search engines) the moment new content is published. Unlike Google’s indexing pipeline — where new pages can wait days or weeks for crawling — IndexNow pings result in Bingbot visits within hours. For a monetization thesis that depends on speed-to-citation, this is not a minor advantage. It is the enabling infrastructure.
Bing Ads Closes the Monetization Loop
Here is where the flywheel becomes unique. A visitor arrives on your site via a Copilot citation — your server logs show a referrer from copilot.microsoft.com. That visitor is now in your Bing Ads retargeting audience. You can serve them follow-up ads through the Bing Ads network: display, search, or audience campaigns. No other AI platform offers this. Google’s AI Overviews do not currently cite sources with the same clickable attribution model. ChatGPT’s citations use Bing’s index but do not feed into an ad retargeting ecosystem controlled by the same company. Only Microsoft owns every link in the chain: index → cite → retarget.
As we explored in our PSAO framework analysis, this platform-specific architecture is why optimizing for each AI system separately — rather than treating “AI search” as a monolith — produces dramatically better results.
The Flywheel Diagram
The system works in five steps:
Publish — Create authoritative, entity-rich content optimized for AI citation (SEO + AEO + GEO)
Index — Ping IndexNow to get Bing to crawl and index within hours
Cite — Copilot surfaces your content as a grounding citation when enterprise users ask relevant questions
Retarget — Visitors who arrive via Copilot citations enter your Bing Ads audience pools
Monetize — Serve targeted ads, capture leads, or nurture those visitors through your conversion funnel
Every step in this loop is controlled by Microsoft’s ecosystem. That is what makes it a closed loop — and that is what makes it testable.
The Experiment: 40 Articles Published in a Single Day
40 articles in a day — watch the crawlers respond.
To test the Bing Citation Mining thesis, we designed a controlled experiment with specific, measurable parameters. On June 22, 2026, Tygart Media published 40 articles on tygartmedia.com, all targeting enterprise Microsoft Copilot use cases. Here is the full architecture of the experiment.
Why 40 Articles?
The number was deliberate. We needed enough content to create a meaningful signal in Bing’s index — a critical mass that would register as a topical cluster, not isolated pages. Forty articles across five categories gave us eight articles per category: enough to establish topical authority in each vertical while generating sufficient data points for statistical analysis of crawler behavior, indexation speed, and citation patterns.
Why Enterprise B2B Topics?
We chose enterprise Microsoft Copilot topics for a specific strategic reason: they match Copilot’s primary use case. The people using Microsoft Copilot are enterprise workers — knowledge workers in mid-workflow asking questions about the tools they use daily. When someone asks Copilot “How do I set up DLP policies for Copilot?” or “What’s the ROI framework for Copilot adoption?”, the system reaches into Bing’s index for grounding. We wanted to be the content it found.
Our topic selection methodology article details the full process, but the summary is this: we reverse-engineered what enterprise Copilot users would ask, then wrote the authoritative answers. This is the discipline we call AI-citable topic selection.
The Five Strategic Categories
Each category was chosen to map to a distinct enterprise buyer persona and workflow context:
This five-category architecture was not arbitrary. It mirrors how enterprise procurement committees evaluate technology: security first, then capability, then adoption feasibility, then individual value, then competitive positioning. We built a content cluster that mirrors the enterprise buyer’s information journey.
The Optimization Stack Applied to Every Article
Every one of the 40 articles received a four-layer optimization stack — what we call the full SEO + AEO + GEO treatment. Our analysis of why the SEO vs. GEO vs. AEO debate misses the point explains the philosophy: these are not competing disciplines. They are complementary layers that serve different retrieval systems simultaneously.
Layer 1: SEO (Search Engine Optimization)
The traditional foundation. Every article received optimized title tags, meta descriptions, heading structure (H2/H3 hierarchy), keyword placement in the first 100 words, and internal linking to related articles within the cluster. This layer ensures discoverability through conventional Bing and Google search.
Layer 2: AEO (Answer Engine Optimization)
Structured to win featured snippets and direct answer placements. Every article includes FAQ sections with five question-answer pairs, definition boxes for key terms, direct answer paragraphs formatted for extraction, and “What is…” framing for core concepts. This is the layer that makes content extractable by AI systems looking for concise, authoritative answers.
Layer 3: GEO (Generative Engine Optimization)
The newest and most critical layer for AI citation. Every article maximizes entity saturation — naming specific tools (Microsoft Copilot, Power BI, Microsoft Teams, SharePoint), specific metrics, specific frameworks, and specific organizations. Factual density is deliberately high. We applied the principles of how AI engines select content for citation: statistical backing, authoritative sourcing, and structured data that LLMs can parse without ambiguity.
Every article also includes speakable schema markup and follows the OASF (Optimized Answer Snippet Format) structure — a format designed to make paragraphs maximally extractable by generative AI systems.
Layer 4: Schema Markup (JSON-LD)
Every article carries three JSON-LD schema blocks: Article (with headline, author, publisher, dates, and keywords), FAQPage (with five structured Q&A pairs), and BreadcrumbList (with proper site hierarchy). This structured data layer makes content machine-readable in a way that goes beyond what crawlers can infer from HTML alone.
Day-One Results: What the Server Logs Revealed
Day-one server logs reveal who actually showed up.
The experiment’s first validation came from raw server log data — not analytics dashboards, not third-party estimates, but the actual HTTP requests hitting tygartmedia.com’s origin server. As we detailed in our server log analysis guide, this is the only way to see AI crawler traffic that Google Analytics and similar tools miss entirely.
What we also documented in our analysis of why websites are read by AI more than humans is now an established pattern — and our 40-article experiment confirmed it within the first 48 hours.
The Traffic Split: AI vs. Traditional Crawlers
Within the first 48 hours of publishing all 40 articles, the server logs recorded:
Total AI crawler hits: 6,805
Total traditional crawler hits: 4,897
AI crawler advantage: 39% more AI traffic than traditional traffic
Source: Tygart Media server log analysis, June 2026
This is the headline number, and it is not subtle. AI systems consumed more of our content than traditional search engines within the first two days. For publishers who are not instrumenting their servers to see this traffic, this entire category of consumption is invisible.
Crawler-by-Crawler Breakdown
The AI crawler traffic was not uniform. Each system exhibited distinct crawling behavior:
ChatGPT-User: 3,404 hits — The dominant AI crawler by volume. ChatGPT-User is the real-time retrieval agent that fires when a ChatGPT user asks a question requiring current information. This crawler accounted for 50% of all AI crawler hits, making it the single largest source of AI-driven content consumption on the site. This confirms what we found in our research on how to get cited in ChatGPT Search: the ChatGPT-User agent is the most active retrieval crawler in the current AI ecosystem.
GPTBot: 1,123-request structural crawl — GPTBot did something qualitatively different from ChatGPT-User. Rather than fetching individual articles in response to user queries, GPTBot executed a systematic structural crawl that mapped the entire site architecture. It hit sitemaps, category pages, author pages, and individual posts in a methodical pattern — and completed the entire crawl within one hour. This is training-data acquisition behavior, distinct from the real-time retrieval pattern of ChatGPT-User.
Bingbot: 4-hour post-publish gap, then full coverage — After we published all 40 articles and pinged IndexNow, there was a 4-hour gap before Bingbot arrived. Once it started, it crawled all 40 articles. This confirms that IndexNow is fast — but not instant. The 4-hour processing window is an important planning consideration for publishers who need to time their content for maximum citation opportunity. Our analysis of the Google Search Console indexing paradox provides additional context on how different indexing pipelines compare.
Source: Tygart Media server log analysis, June 2026
The Citation Signal: 3 Confirmed Copilot Referrals
Within 48 hours of publishing, server logs recorded 3 confirmed referral visits from copilot.microsoft.com. These are visitors who saw a Copilot citation of Tygart Media content, clicked through, and landed on the site.
Three referrals in 48 hours from a brand-new content cluster is a meaningful signal. It confirms the core thesis: publish authoritative content on enterprise Copilot topics, get it indexed on Bing via IndexNow, and Copilot will cite it. The speed surprised us — we expected the citation pipeline to take longer than the indexation pipeline, but they appear to be tightly coupled.
For context on what these citations are worth, see our AI citation value framework, which breaks down the per-citation economics of Copilot referrals versus traditional search clicks.
Source: Tygart Media server log analysis, June 2026
Five Things That Surprised Us
Every experiment produces expected results and unexpected ones. These are the findings that challenged our assumptions.
1. The Speed of AI Crawler Response
We anticipated that AI crawlers would find the content within days. They found it within hours. The first ChatGPT-User hits arrived the same day we published, and GPTBot completed its structural crawl within 60 minutes of its first request. This speed suggests that AI systems are monitoring Bing’s index (via IndexNow notifications or similar mechanisms) far more aggressively than we assumed. As we explored in our analysis of whether anything actually fetches your llms.txt file, the reality of AI crawler behavior is often different from what documentation suggests.
2. ChatGPT-User Was the Dominant Crawler, Not GPTBot
Most industry commentary focuses on GPTBot as OpenAI’s primary crawler. Our data shows ChatGPT-User generated 3x the request volume of GPTBot (3,404 vs. 1,123). This matters because ChatGPT-User represents real-time retrieval — actual humans asking questions and the system fetching your content to answer them. GPTBot’s crawling is important for training data, but ChatGPT-User is where the immediate citation value lives.
3. GPTBot’s Crawl Was Structural, Not Content-Focused
GPTBot did not just crawl the 40 articles. It crawled the site’s architecture — sitemaps, category pages, related posts, navigational elements. It was mapping the site’s information architecture, not just ingesting individual pages. This suggests that topical authority signals (how content is organized, categorized, and interlinked) matter for AI systems in ways that parallel but differ from how Google evaluates site structure.
4. The Bingbot Gap Is Real but Manageable
The 4-hour gap between IndexNow ping and Bingbot’s first crawl is not a flaw — it is a processing window. For publishers planning content launches timed to earn Copilot citations (for example, publishing content before a major industry conference where enterprise workers will be asking Copilot questions), this 4-hour window needs to be factored into launch timing.
5. Copilot Citations Arrived Before Full Bing Ranking
The 3 Copilot citation referrals arrived within 48 hours — before the content had time to establish meaningful Bing search rankings. This is a critical insight. Copilot citation is not gated on ranking position the way traditional featured snippets are. If Bing has indexed the content and it is topically relevant to the query, Copilot can cite it regardless of where it ranks in traditional search results. This decoupling of citation from ranking is one of the most important structural differences between AI search and traditional search.
The Content Architecture: How Enterprise Topics Map to AI Citation Opportunity
The 40 articles were not written randomly within their categories. Each one was designed to answer a specific question that an enterprise Copilot user would plausibly ask during their workflow. This question-first approach is fundamentally different from keyword-first SEO content strategy.
Consider the difference:
Keyword-first approach: “microsoft copilot governance” has 1,200 monthly searches → write an article targeting that keyword
Question-first approach: “A CISO is deploying Copilot next quarter and asks Copilot itself, ‘What governance framework should I use for Microsoft 365 Copilot?’” → write the definitive answer to that question
The second approach optimizes for AI citability. The first optimizes for traditional search rankings. In 2026, both matter — but the question-first approach maps directly to how Copilot retrieves grounding content. As we analyzed in our comparison of writing for Google vs. Copilot vs. ChatGPT, each platform’s audience asks questions differently, and the content must be shaped accordingly.
Every article in the 40-article cluster links to at least 3-5 other articles within the cluster. This is not just an SEO tactic — it is an AI citation optimization strategy. When GPTBot crawls your site structurally (as our logs confirmed it does), internal linking signals tell it which content is related and which pages are authoritative within a topic cluster. The tighter the internal linking, the stronger the topical authority signal.
This also supports what we found in our investigation of what content wins in enterprise Copilot workflows: content that exists within a well-linked cluster is more likely to be surfaced than isolated pages, even if the isolated page is individually stronger.
What Happens After Day One: The Measurement Framework
Publishing 40 articles and measuring the first 48 hours is the beginning, not the end. The experiment’s real value will emerge over the next 30, 60, and 90 days as we track the following metrics:
Bing Indexation Rate
How many of the 40 articles reach full Bing indexation, and how quickly? IndexNow accelerates initial crawling, but full indexation (where content is eligible for citation) is a separate milestone. We are tracking this via Bing Webmaster Tools daily.
Copilot Citation Volume
The 3 citations in 48 hours are a baseline. We expect this number to grow as the content matures in Bing’s index and as more enterprise users ask related questions. Server logs will track every copilot.microsoft.com referral. Our framework for calculating the value of AI citations provides the methodology for assigning dollar values to each referral.
AI Crawler Return Frequency
How often do ChatGPT-User, GPTBot, and Bingbot return to recrawl the content? Freshness signals matter for AI citation eligibility, and understanding recrawl patterns tells us how often content needs updating to maintain citation status.
Traditional Search Performance
The SEO layer is not irrelevant. Bing search rankings, Google search rankings, and organic traffic will be tracked through Google Search Console, Bing Webmaster Tools, and GA4. The hypothesis is that content optimized for AI citation also performs well in traditional search — but we are measuring, not assuming.
Visitor Behavior Post-Citation
What do visitors who arrive via Copilot citations actually do on the site? Do they read one article and leave, or do they explore the cluster? Our GA4 audit of AI referral retention found that AI-referred visitors exhibit different behavior patterns than organic search visitors, and tracking this for the 40-article experiment will either confirm or challenge those findings.
This experiment was not designed to be a Tygart Media vanity project. It was designed to answer a question that matters to every publisher, content strategist, and digital marketer: Is AI search monetization a real, repeatable system, or is it theoretical?
The data says it is real. Here is what that means in practice.
AI Search Monetization Is Not Theoretical — It Is Happening Now
Three Copilot citations within 48 hours from a brand-new content cluster. Six thousand eight hundred five AI crawler hits versus 4,897 traditional hits. These are not projections. They are server log entries. The publish → index → cite loop works, and it works within days, not months. The publishers who build for this system today will compound their advantage as AI search usage grows.
Server Log Instrumentation Is Now a Competitive Necessity
If you are not parsing your server logs for AI crawler traffic, you are flying blind. Google Analytics does not show you ChatGPT-User hits. Your SEO dashboard does not show you GPTBot’s structural crawl. The 6,805 AI crawler hits we recorded would have been completely invisible without server log analysis. This is not an advanced technique reserved for technical publishers — it is table stakes for anyone competing in AI search.
Our detailed guide on server log analysis for publishers provides the complete methodology, from log file access to bot identification to traffic categorization.
Topic Selection for AI Citability Is a New Discipline
Traditional keyword research asks: “What are people searching for?” AI-citable topic selection asks: “What questions will people ask AI assistants, and can I be the authoritative source the AI cites in response?” These are related but distinct questions. The enterprise B2B topics we chose for this experiment were selected specifically because they match the workflow context in which Copilot is used. Writing content that matches the context of AI assistant usage — not just the keywords — is the new competitive edge.
The most important finding is not any individual data point — it is that the system is repeatable. The five-step flywheel (publish → index → cite → retarget → monetize) is not a one-time trick. It is an ongoing content operation. Publish more authoritative content. Ping IndexNow. Watch the AI crawlers arrive. Track the citations. Retarget the visitors. Measure the revenue. Repeat.
Every cycle compounds. As your Bing-indexed content cluster grows, your topical authority strengthens. As your topical authority strengthens, your citation rate increases. As your citation rate increases, your retargeting audience grows. As your retargeting audience grows, your monetization improves. This is the flywheel effect — and it only works because Microsoft controls every component of the loop.
The Full Series: Where to Go from Here
This capstone article is the synthesis, but the details live in the individual articles of the AI Search Intelligence series:
The Bing Citation Mining thesis holds that because Microsoft Copilot uses Bing’s search index for grounding and citations, publishers who get authoritative content indexed quickly on Bing can earn Copilot citations — and then retarget those AI-referred visitors through Bing Ads. This creates a closed-loop publish → index → cite → retarget → monetize flywheel that does not exist on any other AI platform.
How many AI crawler hits did the 40-article experiment generate on day one?
According to Tygart Media server log analysis from June 2026, the 40 articles generated 6,805 AI crawler hits versus 4,897 traditional crawler hits within the first 48 hours. AI crawlers outnumbered traditional crawlers by 39%. ChatGPT-User was the single largest crawler with 3,404 hits.
Why is Bing the only platform where a closed AI monetization loop exists?
Microsoft controls every component: Bing indexes the content, Copilot uses Bing’s index for citations, and Bing Ads enables retargeting of citation-referred visitors. Google’s AI Overviews do not cite sources with the same clickable attribution model, and no other company owns the index, the AI assistant, and the advertising platform as an integrated system.
How fast do AI crawlers respond to newly published content?
Based on Tygart Media server log analysis from June 2026, ChatGPT-User arrived within hours of publication. GPTBot completed a 1,123-request structural crawl within one hour of its first request. Bingbot showed a 4-hour post-publish gap (IndexNow processing time) before crawling all 40 articles. (Source: Tygart Media server log analysis, June 2026)
What optimization stack was applied to each article in the experiment?
Every article received four layers of optimization: SEO (title tags, meta descriptions, heading structure, keyword optimization), AEO (FAQ sections, definition boxes, direct answer paragraphs, featured snippet formatting), GEO (entity saturation, factual density, speakable schema, OASF structure), and JSON-LD schema markup (Article, FAQPage, and BreadcrumbList types on every post).
Methodology note: All data cited in this article comes from Tygart Media server log analysis, June 2026. Server logs were parsed for user-agent identification, referrer analysis, and request categorization. No third-party analytics platforms were used for AI crawler traffic measurement, as these platforms do not capture bot-initiated requests. Copilot referrals were identified by copilot.microsoft.com referrer strings in raw access logs.
This article is part of Tygart Media’s AI Search Intelligence series — original research and frameworks for publishers navigating the shift from search engine optimization to AI search optimization.
Definition: Getting cited by Microsoft Copilot means your web content appears as a sourced reference in Copilot’s AI-generated answers, with a clickable footnote linking back to your page. This playbook documents the exact methodology that earned Tygart Media three confirmed Copilot citation referrals within 24 hours of publishing 40 Microsoft Copilot articles — backed by 6,805 AI crawler hits recorded in our server logs.
Most content marketers treat AI search as a black box. They publish, wait, and hope an AI decides to cite them. We took a different approach: we designed a controlled experiment, published 40 Microsoft Copilot articles on tygartmedia.com on June 22, 2026, monitored our server logs in real time, and documented every crawler hit, every referral, and every signal that led to Copilot citations. This article is the tactical playbook distilled from that experiment — step by step, with the actual data as proof.
The Experiment That Proved 24-Hour Copilot Citation Is Possible
On June 22, 2026, Tygart Media published 40 articles targeting Microsoft Copilot-related search queries on tygartmedia.com. Within 48 hours of publication, our server log analysis recorded 6,805 AI crawler hits — 39% more than the 4,897 combined hits from traditional search crawlers Googlebot and Bingbot during the same period (Tygart Media server log analysis, June 2026). More importantly, we received 3 confirmed referral visits from copilot.microsoft.com, with 2 of those carrying the utm_source=copilot.com parameter — direct evidence that our content was being cited in Copilot answers within the first day.
This was not luck. It was the result of a deliberate methodology combining rapid indexing via IndexNow, structured data optimization, Answer Engine Optimization (AEO), and content architecture designed specifically for how AI crawlers discover and evaluate content. Here is exactly how we did it.
Step 1: Trigger Immediate Indexing With IndexNow
The single most important factor in 24-hour Copilot citation is speed of indexing. Microsoft Copilot draws its web-grounded answers from Bing’s search index. If your content is not in Bing’s index, Copilot cannot cite it — period. This is where IndexNow becomes your most critical tool.
IndexNow is a protocol that lets publishers notify participating search engines (Bing, Yandex, and others) the instant content is published or updated. Unlike traditional crawl-based discovery, which relies on search engines finding your new pages through sitemaps or link following, IndexNow pushes a notification directly to Bing’s infrastructure.
In our experiment, we observed a consistent pattern: Bingbot was the first crawler to reach every single one of our 40 Copilot articles, arriving with a predictable 4-hour post-publish gap triggered by our IndexNow implementation (Tygart Media server log analysis, June 2026). This speed advantage is what made 24-hour citation possible. Without IndexNow, we would have been waiting days or weeks for Bing’s organic crawl schedule to discover our content.
How to Implement IndexNow for Your WordPress Site
For WordPress sites, implementing IndexNow takes less than 10 minutes. Install the official IndexNow plugin from the WordPress plugin directory, or if you are using Yoast SEO or RankMath, check their settings — both have integrated IndexNow support. Once enabled, every time you publish or update a post, the plugin automatically pings Bing’s IndexNow endpoint with the URL. Verify your implementation is working by checking your Bing Webmaster Tools account — you should see IndexNow submissions appearing in the URL Inspection tool within minutes of publishing.
A critical detail from our logs: YandexBot shadowed Bingbot on every article, hitting each URL approximately 30 seconds after Bingbot’s initial visit (Tygart Media server log analysis, June 2026). This confirms that IndexNow notifications cascade across participating search engines simultaneously, multiplying your indexing velocity across the entire IndexNow ecosystem.
Step 2: Structure Content for AI Comprehension With Schema Markup
Once your content is in Bing’s index, the next challenge is making it easy for AI systems to understand, extract, and cite. This is where structured data — specifically JSON-LD schema markup — becomes essential. Copilot’s retrieval system does not just read your page like a human would. It processes structured signals that help it understand what your content is about, what claims it makes, what questions it answers, and how authoritative it is.
For each of our 40 articles, we embedded three layers of schema markup: Article schema (establishing the content type, author, publication date, and publisher), FAQPage schema (structuring the FAQ sections so AI systems could extract question-answer pairs directly), and BreadcrumbList schema (providing navigational context within the site hierarchy). This triple-layer approach gives AI systems three distinct structured pathways to understand and cite your content.
The Schema Stack That Works for Copilot
Article schema should include: @type: Article, headline, author with a @type: Person or Organization, datePublished, dateModified, publisher, description, and mainEntityOfPage. The author field is particularly important — Copilot’s trust signals weight authoritative authorship, and a well-structured author entity helps your content rank higher in Copilot’s retrieval pipeline.
FAQPage schema should wrap every FAQ section in your article. Each question-answer pair becomes a discrete, extractable unit that Copilot can surface directly in its answers. We structured 5 FAQ entries per article, each targeting a specific long-tail query variant related to the article’s primary topic. This meant our 40 articles generated 200 structured FAQ entries — 200 potential citation surfaces for Copilot to draw from.
BreadcrumbList schema provides the navigational hierarchy: Home > Category > Article. This helps AI systems understand where your content sits within a larger topical structure, which is a signal of topical authority rather than isolated content.
Step 3: Optimize for Answer Engine Extraction (AEO)
Answer Engine Optimization is the practice of structuring content so AI systems can extract clean, direct answers from your pages. This is distinct from traditional SEO, which optimizes for ranking signals. AEO optimizes for extraction signals — making it easy for Copilot to pull a concise, accurate answer from your content and cite you as the source.
The AEO Techniques We Used on Every Article
Definition boxes near the top of each article. Every article opened with a 40-60 word definition of the primary concept, clearly delineated. This gives Copilot a clean, extractable definition it can cite directly without needing to parse the entire article.
Question-formatted H2 headings with immediate answers. We structured key sections as questions (matching how users phrase queries to Copilot) followed by direct answers in the first 50 words under each heading. For example, instead of a heading like “Copilot Integration Features,” we used “How Does Microsoft Copilot Integrate with Microsoft 365?” followed by a direct, concise answer before expanding into detail.
Comparison tables for competitive queries. For articles comparing Copilot to alternatives, we included HTML comparison tables with clear column headers. Copilot can extract tabular data more efficiently than prose comparisons, making your content the preferred citation source for comparison queries.
Numbered step-by-step instructions. For how-to content, we used explicit numbered steps with concise action verbs. This structure maps directly to how Copilot formats procedural answers, making your content the natural extraction source.
Step 4: Build Topical Authority With Content Clusters
A single article can earn a citation. A content cluster makes citations systematic. Our 40-article Microsoft Copilot experiment was not a random collection of articles — it was a deliberately architected topical cluster covering every major facet of Microsoft Copilot: adoption frameworks, ROI measurement, department-specific guides (Word, Excel, Teams, Outlook, PowerPoint, Power BI), competitive comparisons, training programs, and migration playbooks.
This cluster architecture serves two purposes for Copilot citation. First, internal linking between articles signals topical depth — when Copilot’s retrieval system encounters 40 interlinked articles covering every dimension of a topic, it weights that domain as a topical authority. Second, the cluster provides multiple entry points for citation. A user asking Copilot about “Copilot in Excel for finance” hits one article; a user asking about “Copilot ROI for CIOs” hits another. Both queries return to your domain.
Our server logs confirmed this cluster effect. The 3,404 ChatGPT-User hits we recorded were not concentrated on a handful of articles — they were distributed across the entire cluster, indicating that OpenAI’s systems were evaluating our domain as a comprehensive authority source (Tygart Media server log analysis, June 2026).
Step 5: Maximize Entity Signals for Generative Engine Optimization (GEO)
Generative Engine Optimization goes beyond AEO by focusing on entity density and factual specificity — the signals that make AI systems treat your content as a citable authority rather than generic information. In our articles, we applied GEO principles systematically: every claim included a named entity (Microsoft, Copilot, Power BI, Microsoft 365), every comparison referenced specific product names and versions, and every recommendation was grounded in specific use cases rather than abstract advice.
Entity-rich content is citation-friendly content. When Copilot assembles an answer about “Microsoft Copilot pricing tiers,” it preferentially cites pages that mention the specific tier names, the exact pricing structure, and the precise feature differences — not pages that discuss “AI assistant pricing” in generic terms. Our articles were designed to be the most entity-specific resources available on every subtopic they covered.
Step 6: Monitor and Iterate Using Server Log Intelligence
The final step in this playbook is not a one-time action — it is an ongoing intelligence loop. Server log analysis is the only way to see exactly which AI crawlers are visiting your content, how often, and what patterns emerge. Traditional analytics tools like Google Analytics do not capture crawler traffic — they only see human visitors. Server logs see everything.
In our experiment, server log analysis revealed insights that no analytics tool could have provided. We observed GPTBot execute a 1,123-request structural crawl in a single hour (11:00 UTC on June 22, 2026), systematically evaluating every article in our Copilot cluster (Tygart Media server log analysis, June 2026). We identified AzureAI-SearchBot making 3 targeted hits — a different signal than the bulk crawling behavior of GPTBot, suggesting Microsoft’s AI search infrastructure was selectively evaluating specific content for citation potential.
We also observed that Googlebot was dramatically slower to respond than Bingbot. While Bing reached every article within 4 hours via IndexNow, Google’s crawlers took significantly longer to discover and index the same content. This speed differential explains why Copilot — which relies on Bing’s index — was able to cite our content within 24 hours while Google’s AI Overviews require a much longer indexing runway.
The Complete 24-Hour Copilot Citation Checklist
Here is the consolidated checklist, in the exact order of execution:
Enable IndexNow on your WordPress site via plugin or SEO tool integration. Verify submissions appear in Bing Webmaster Tools.
Write content using question-formatted H2s that match how users phrase queries to AI assistants. Provide direct answers in the first 50 words under each heading.
Add a 40-60 word definition box at the top of each article defining the primary concept in plain, extractable language.
Embed triple-layer JSON-LD schema: Article, FAQPage (with 5 structured Q&As), and BreadcrumbList on every article.
Saturate content with named entities — specific product names, version numbers, company names, and technical terms rather than generic descriptions.
Build internal links between all articles in the cluster. Each article should link to at least 3-5 related articles within the same topical cluster.
Publish and verify indexing. Check Bing Webmaster Tools within 4 hours. Your IndexNow ping should have triggered Bingbot to crawl the new page.
Monitor server logs for ChatGPT-User, GPTBot, OAI-SearchBot, and Bingbot activity. These are the crawlers whose behavior predicts Copilot citation.
Check for citation referrals in your analytics — look for referral traffic from copilot.microsoft.com, with utm_source=copilot.com in the query string.
Iterate. Update content based on which articles attract the most AI crawler attention. Expand sections that AI systems are actively fetching.
Why This Works: The Copilot Citation Pipeline Explained
To understand why this playbook works, you need to understand how Microsoft Copilot’s web-grounded citation pipeline operates. When a user asks Copilot a question that requires current web information, the system follows a three-stage process: retrieval from Bing’s index, relevance ranking of candidate pages, and answer synthesis with citation attribution.
Stage one — retrieval — is where IndexNow gives you the speed advantage. If your content is in Bing’s index, it enters the candidate pool. If it is not indexed, it is invisible to Copilot regardless of how good the content is.
Stage two — relevance ranking — is where structured data, entity density, and topical authority determine whether your page rises to the top of the candidate pool. Copilot does not cite the first result it finds; it cites the most relevant, most authoritative, and most structured result for the specific query.
Stage three — answer synthesis — is where AEO optimization pays off. Copilot’s language model reads your page and extracts the answer. Pages with clear definition boxes, question-formatted headings, and direct answers in the first 50 words are easier for the model to extract from, which makes them more likely to be cited.
Our experiment proved this pipeline works as described. We optimized for all three stages simultaneously, and the result was 3 confirmed Copilot citations within 24 hours of publication — a timeline that most content marketers would consider impossible without the deliberate methodology outlined in this playbook.
What the Server Log Data Actually Shows
The raw numbers from our 48-hour monitoring window tell a compelling story about how AI systems evaluate and select content for citation (all data from Tygart Media server log analysis, June 2026):
Total AI crawler hits: 6,805. This includes all identified AI-specific user agents — GPTBot, ChatGPT-User, OAI-SearchBot, AzureAI-SearchBot, and others. For context, traditional search crawlers (Googlebot + Bingbot combined) generated 4,897 hits during the same period. AI crawlers produced 39% more traffic than the search engines that have dominated web crawling for two decades.
ChatGPT-User: 3,404 hits. Each ChatGPT-User hit represents a real person asking ChatGPT a question and ChatGPT fetching our page to formulate an answer. This is not background crawling — this is live query-driven traffic. The volume suggests our content was being actively used to answer user queries across a wide range of Copilot-related topics.
GPTBot: 1,123-request structural crawl in a single hour. At 11:00 UTC on June 22, GPTBot executed a systematic evaluation of our entire Copilot content cluster. This pattern — a concentrated burst of structural crawling — suggests OpenAI’s systems identified our domain as a potential authority source and performed a deep evaluation to assess the breadth and depth of our coverage.
Bingbot: first to every article, 4-hour gap. Bingbot consistently arrived at each new article within approximately 4 hours of publication, triggered by our IndexNow implementation. This reliability confirms that IndexNow is not just a faster path to indexing — it is a predictable, repeatable mechanism for getting content into Bing’s index on a known timeline.
3 confirmed Copilot referrals. Within the first 24 hours, we recorded 3 visits with referral source copilot.microsoft.com, 2 of which carried the utm_source=copilot.com parameter. These are confirmed citations — instances where a user saw our content cited in a Copilot answer and clicked through to our page.
Common Mistakes That Prevent Copilot Citations
Based on our experiment and ongoing analysis, here are the most common reasons content fails to earn Copilot citations:
No IndexNow implementation. Without IndexNow, you are relying on Bing’s organic crawl schedule, which can take days or weeks. Copilot cannot cite content that is not in Bing’s index.
Missing or incomplete schema markup. Content without structured data is harder for AI systems to parse, understand, and cite. At minimum, every article should have Article schema and FAQPage schema.
Generic, non-entity-specific content. Articles that discuss topics in generic terms without naming specific products, versions, companies, or technical concepts are less likely to be selected as citation sources by AI retrieval systems.
Wall-of-text formatting. AI extraction systems perform better with clearly structured content: defined heading hierarchies, short paragraphs, comparison tables, and numbered lists. Dense prose without structural markers is harder to extract from.
Ignoring server logs. Without server log monitoring, you have no visibility into whether AI crawlers are even visiting your content. You are operating blind — unable to see what is working, what is being ignored, and where to focus optimization efforts.
Scaling This Playbook Across Your Content Portfolio
The methodology described here is not limited to Microsoft Copilot content. The same principles — rapid indexing, structured data, AEO optimization, entity density, and content clustering — apply to earning citations from any AI system that uses web retrieval: ChatGPT, Google AI Overviews, Perplexity, and Claude’s web search. The difference is that Copilot’s reliance on Bing’s index makes IndexNow the fastest path, while Google’s AI Overviews require Google’s own indexing pipeline, which is historically slower.
To scale this approach, apply the same content architecture to every topical cluster on your site. Identify the queries your audience asks AI assistants, write content that directly answers those queries with entity-rich specificity, structure it for extraction with schema markup and AEO formatting, and ensure rapid indexing via IndexNow. Monitor your server logs to confirm AI crawlers are discovering and evaluating your content, and iterate based on what the data tells you.
Our 40-article experiment was proof of concept. The 6,805 AI crawler hits and 3 confirmed Copilot citations within 24 hours demonstrate that this is not theoretical — it is a repeatable, scalable methodology backed by primary data. The AI search landscape rewards publishers who understand how AI crawlers work and optimize for their specific discovery and evaluation patterns. This playbook gives you the exact steps to do that.
Frequently Asked Questions
How long does it take to get cited by Microsoft Copilot after publishing?
With IndexNow enabled, Bingbot typically discovers new content within 4 hours of publication. From there, Copilot can begin citing indexed content almost immediately. In our experiment, we recorded confirmed Copilot citation referrals from copilot.microsoft.com within 24 hours of publishing 40 optimized articles (Tygart Media server log analysis, June 2026). Without IndexNow, the indexing delay can stretch to days or weeks, pushing the citation timeline out proportionally.
What is IndexNow and why is it essential for Copilot citation?
IndexNow is a web protocol that allows publishers to instantly notify participating search engines — including Bing, Yandex, and others — when content is published, updated, or deleted. For Copilot citation, IndexNow is essential because Copilot retrieves answers from Bing’s search index. Content that is not indexed by Bing cannot be cited by Copilot, regardless of its quality. IndexNow eliminates the indexing delay, making 24-hour citation achievable.
What types of schema markup help with Copilot citations?
The three most effective schema types for Copilot citation are Article schema (which establishes content type, authorship, and publication metadata), FAQPage schema (which structures question-answer pairs for direct extraction by AI systems), and BreadcrumbList schema (which provides site hierarchy context). Implementing all three creates multiple structured pathways for AI systems to understand, evaluate, and cite your content.
Can I track whether Microsoft Copilot is citing my content?
Yes, through two methods. First, monitor your analytics for referral traffic from copilot.microsoft.com — look for the utm_source=copilot.com parameter, which confirms a user clicked through from a Copilot citation. Second, use Bing Webmaster Tools’ AI Performance dashboard, which was launched in public preview in February 2026, to see citation metrics including total citations, grounding queries, and page-level citation activity for your verified domain.
What is the difference between AEO and GEO for Copilot optimization?
Answer Engine Optimization (AEO) focuses on making content easy for AI systems to extract — using question-formatted headings, definition boxes, direct answers in the first 50 words, and structured FAQ sections. Generative Engine Optimization (GEO) focuses on making content authoritative enough to be selected for citation — through entity density, factual specificity, named sources, and topical authority signals. Both are necessary for consistent Copilot citations: AEO makes your content extractable, and GEO makes it the preferred source to extract from.
IndexNow promises instant content discovery. But how fast is it really? We ran a controlled speed test — 40 articles published simultaneously to tygartmedia.com with IndexNow pings fired on every one — then measured exactly how long it took Bing, GPTBot, Google, and every other crawler to show up. The timestamps tell a story that IndexNow’s marketing materials do not.
This is the second article in Tygart Media’s AI Search Intelligence series, based on proprietary server log data from our 40-article Microsoft Copilot content experiment conducted on June 22, 2026. Every timestamp and crawl interval cited here comes directly from our server access logs.
What Is IndexNow and Why Speed Matters
What IndexNow is and why speed matters.
IndexNow is an open-source protocol that lets websites notify participating search engines the moment content is published or updated. Instead of waiting for a crawler to discover your new page organically — which can take days or weeks — IndexNow sends a direct ping saying “this URL has new content, come get it.”
Microsoft developed IndexNow and Bing is its primary participant. Yandex, Naver, Seznam, and several other engines also participate. Google does not. As of early 2026, over 60 million websites use IndexNow, and 22% of clicked Bing URLs come from IndexNow submissions, according to Bing’s published data.
For publishers, the speed question is not academic. If you are publishing time-sensitive content — news, product launches, competitive analysis — the difference between a 3-hour crawl delay and a 3-day crawl delay determines whether your content gets indexed before or after your competitors. And in the AI era, the question extends beyond traditional indexing: how fast do AI crawlers like GPTBot find your new content?
Our Test Setup: 40 Articles, One Timestamp
On June 22, 2026, we published 40 original articles about Microsoft Copilot to tygartmedia.com. The site runs WordPress with RankMath SEO on a Google Cloud Platform Compute Engine instance. RankMath handles IndexNow submissions automatically on publish.
Every article was published within a short window, and IndexNow pings were fired for each URL. We then monitored our raw server access logs for every subsequent crawler visit, recording the user-agent string, timestamp, and requested URL for each hit.
This gave us a clean dataset: 40 identical test cases (same site, same publish time, same IndexNow submission) with crawler-by-crawler arrival times we could compare head-to-head.
Head-to-Head Results: Who Arrived First?
Head-to-head: who arrived first.
Bing: 3 to 6 Hours via IndexNow
Bingbot was the first traditional search engine crawler to reach our content, arriving within 3 to 6 hours of IndexNow submission. The pattern was remarkably consistent across all 40 articles — most fell within a tight 4-hour window from publication to first crawl.
This is fast by search engine standards but not instant. IndexNow does not trigger immediate crawling. It places your URL into Bing’s priority crawl queue, and Bing processes that queue on its own schedule. For our batch of 40 articles, that schedule produced a 3-to-6-hour window with high consistency.
For context, without IndexNow, new content on a site with our domain authority profile might wait 24 to 72 hours for Bing to discover it through sitemap parsing or link following. IndexNow compressed that to under 6 hours — a meaningful improvement for any publishing operation.
GPTBot: Faster Than Bing
Here is the result that surprised us most: GPTBot arrived at our content faster than Bingbot in many cases, despite GPTBot not being an official IndexNow participant.
GPTBot is OpenAI’s crawler. It does not receive IndexNow pings directly. Yet it consistently reached our newly published articles before Bing’s own crawler had finished processing the IndexNow queue. At 11:00 UTC on June 22, GPTBot executed a 1,123-request structural crawl in a single hour, hitting not just article URLs but every tag, feed, and REST API endpoint on the site (Tygart Media server log analysis, June 2026).
How does GPTBot discover content faster than IndexNow delivers it to Bing? The most likely explanation is that GPTBot monitors RSS feeds, sitemaps, or other real-time content signals independently. WordPress sites broadcast new content through multiple channels — RSS feeds update instantly, XML sitemaps regenerate on publish, and REST API endpoints reflect new posts immediately. GPTBot appears to be monitoring one or more of these channels with higher polling frequency than Bing’s IndexNow processing queue.
The implication for publishers is significant: even if you do not use IndexNow, GPTBot is likely to find your new content quickly through other discovery mechanisms. But IndexNow remains essential for Bing-ecosystem discovery, which feeds Microsoft Copilot’s citation pipeline.
YandexBot: 30 Seconds Behind Bing
YandexBot arrived at each article approximately 30 seconds after Bingbot, with remarkable consistency across the full batch. Yandex participates in the IndexNow protocol, and this timing suggests Yandex processes IndexNow submissions from the same shared queue but with a slight processing delay relative to Bing (Tygart Media server log analysis, June 2026).
The 30-second shadow is too consistent to be coincidental. It points to either a shared IndexNow notification infrastructure where Yandex processes submissions fractionally behind Bing, or to Yandex monitoring Bing’s crawl activity directly. Either way, publishers who submit to IndexNow get both Bing and Yandex coverage from a single ping.
Googlebot: Effectively Absent
Googlebot recorded only 1 hit on our Copilot content in the initial crawl window (Tygart Media server log analysis, June 2026). One hit. Across 40 articles. While Bing had crawled every article within 6 hours and GPTBot had mapped the entire site architecture.
Google does not participate in IndexNow. Google has stated publicly that it relies on its own crawl scheduling, which considers factors like site crawl budget, historical update frequency, and sitemap change signals. For a batch of 40 new articles on a topic the site had not previously covered, Google’s algorithms apparently did not prioritize rapid discovery.
This is not a criticism of Google’s approach — its crawl scheduling optimizes for different goals than real-time discovery. But for publishers who need content indexed quickly, the data is unambiguous: IndexNow-participating engines discover content in hours. Google discovers it on its own timeline.
The IndexNow Technical Gotcha We Discovered
During our experiment, we identified a technical issue that could affect other publishers: the IndexNow key file was returning a 404 at the standard verification paths where search engines expect to find it.
IndexNow requires a verification key file at your site root (e.g., yourdomain.com/{key}.txt). Search engines check this file to confirm you authorized the IndexNow submission. In our case, the key file was not accessible at the expected root-level path, which should have caused verification failures.
RankMath SEO’s fallback mechanism saved us — it handles IndexNow key verification through an alternative method that does not require the physical key file to exist at the root URL. But publishers using manual IndexNow implementations, or other SEO plugins without this fallback, should verify their key file is accessible by navigating directly to the expected URL.
If your IndexNow submissions seem to be ignored by Bing, check the key file first. A 404 on the verification file silently kills the entire pipeline — Bing will not crawl the submitted URLs without successful verification.
What the Speed Test Means for Your Publishing Strategy
What the speed test means for publishing strategy.
For Bing and Copilot Visibility
IndexNow is the fastest path to Bing’s index, and Bing’s index feeds Microsoft Copilot’s citation system. Our 40-article experiment earned 3 confirmed Copilot citation referrals within 48 hours, and that pipeline started with IndexNow getting our content into Bing’s index within hours of publication.
If you are publishing content that you want Copilot to cite, IndexNow is not optional — it is the first link in the citation chain.
For AI Crawler Discovery
GPTBot does not use IndexNow, but it finds new content fast anyway — faster than Bing in our test. This means your site’s real-time content signals (RSS feeds, sitemaps, REST API endpoints) are the discovery mechanism for OpenAI’s crawler ecosystem. Keep these endpoints clean, accessible, and unblocked in your robots.txt if you want AI systems to discover your content quickly.
For Google
Google’s crawl scheduling operates independently of IndexNow. If rapid Google indexing is important to you, continue submitting sitemaps through Google Search Console and requesting indexing for priority pages through the URL Inspection tool. Do not rely on IndexNow for Google discovery — the protocol has no effect on Google’s crawl behavior based on our data.
For Multi-Engine Strategy
The practical recommendation is to run both systems in parallel: IndexNow for Bing, Yandex, and the downstream AI systems that rely on Bing’s index, plus Google Search Console for Google’s independent crawl pipeline. Most WordPress SEO plugins handle IndexNow automatically, so the incremental effort is near zero.
The Speed Hierarchy: From Fastest to Slowest
Based on our server log data from the 40-article experiment, here is the definitive crawl speed ranking for newly published, IndexNow-submitted content (Tygart Media server log analysis, June 2026):
GPTBot — fastest overall; arrived before IndexNow results in many cases; 1,123-request structural crawl in one hour
ChatGPT-User — 3,404 hits over 48 hours; activates when real users query ChatGPT about relevant topics
Bingbot — 3 to 6 hours via IndexNow; consistent, predictable timing
Googlebot — 1 hit in initial window; operates on its own schedule independent of IndexNow
The gap between the top of this list and the bottom is not hours — it is the difference between same-day discovery and multi-day (or longer) discovery. For publishers who need content discovered quickly, the AI crawlers and IndexNow-participating engines are delivering results that Google’s independent crawl schedule simply does not match.
A Note on Methodology and Reproducibility
Every crawl timestamp and interval cited in this article comes from raw server access logs on Tygart Media’s Google Cloud Platform Compute Engine instance, analyzed in June 2026. Crawler identification was performed by user-agent string matching, with IP range verification against OpenAI’s and Microsoft’s published crawler IP ranges for additional confirmation.
The 40-article batch was published simultaneously to control for timing variables. All articles were submitted via IndexNow through RankMath SEO’s automatic submission feature. No manual crawl requests were submitted through Google Search Console, Bing Webmaster Tools, or any other interface — we wanted to measure organic and IndexNow-driven discovery only.
This experiment is reproducible. Any publisher running a WordPress site with IndexNow enabled can monitor their server access logs after a batch publish and observe the same crawler patterns. The specific timing intervals may vary based on domain authority, server location, and crawl budget allocation, but the relative ordering — GPTBot fastest, Bing via IndexNow in hours, Google on its own schedule — should hold across most publishing environments.
How fast does IndexNow actually get content crawled by Bing?
In our controlled test of 40 simultaneously published articles, IndexNow submissions resulted in first Bingbot crawls within 3 to 6 hours, with most articles falling in a consistent 4-hour window. This is significantly faster than the 24-to-72-hour organic discovery timeline for sites without IndexNow, but it is not instant — Bing queues IndexNow submissions and processes them on its own crawl schedule (Tygart Media server log analysis, June 2026).
Does GPTBot use IndexNow to discover content?
No. GPTBot is not an IndexNow participant, yet it arrived at our content faster than Bingbot in many cases. GPTBot appears to monitor RSS feeds, XML sitemaps, or REST API endpoints independently, giving it a faster discovery pipeline than Bing’s IndexNow processing queue. In our experiment, GPTBot executed a 1,123-request structural crawl at 11:00 UTC, mapping the entire site architecture within a single hour (Tygart Media server log analysis, June 2026).
Does Google support IndexNow?
No. Google does not participate in the IndexNow protocol as of June 2026. In our experiment, Googlebot recorded only 1 hit on our 40-article batch while Bingbot and GPTBot had fully crawled the content. Google relies on its own crawl scheduling algorithms and recommends using Google Search Console’s sitemap submission and URL Inspection tool for prioritized crawling (Tygart Media server log analysis, June 2026).
Why was YandexBot always 30 seconds behind Bingbot?
YandexBot, as an IndexNow participant, appears to process submissions from a shared notification infrastructure with a slight delay relative to Bing. The consistent 30-second gap across all 40 articles suggests either a shared queue processed fractionally behind Bing or direct monitoring of Bing’s crawl activity. The practical result is that a single IndexNow ping delivers both Bing and Yandex crawls almost simultaneously (Tygart Media server log analysis, June 2026).
What should publishers do if IndexNow submissions are being ignored by Bing?
Check your IndexNow key file first. The key file must be accessible at your domain root (e.g., yourdomain.com/{key}.txt). In our experiment, the key file was returning a 404 at standard paths, which would have silently killed the pipeline. Our RankMath SEO plugin’s fallback mechanism handled verification, but publishers using manual implementations should navigate directly to their key file URL to confirm it returns a 200 response (Tygart Media server log analysis, June 2026).