Tag: AI Search

  • Yes, I Put the Schema Where You Could See It. On Purpose.

    Yes, I Put the Schema Where You Could See It. On Purpose.

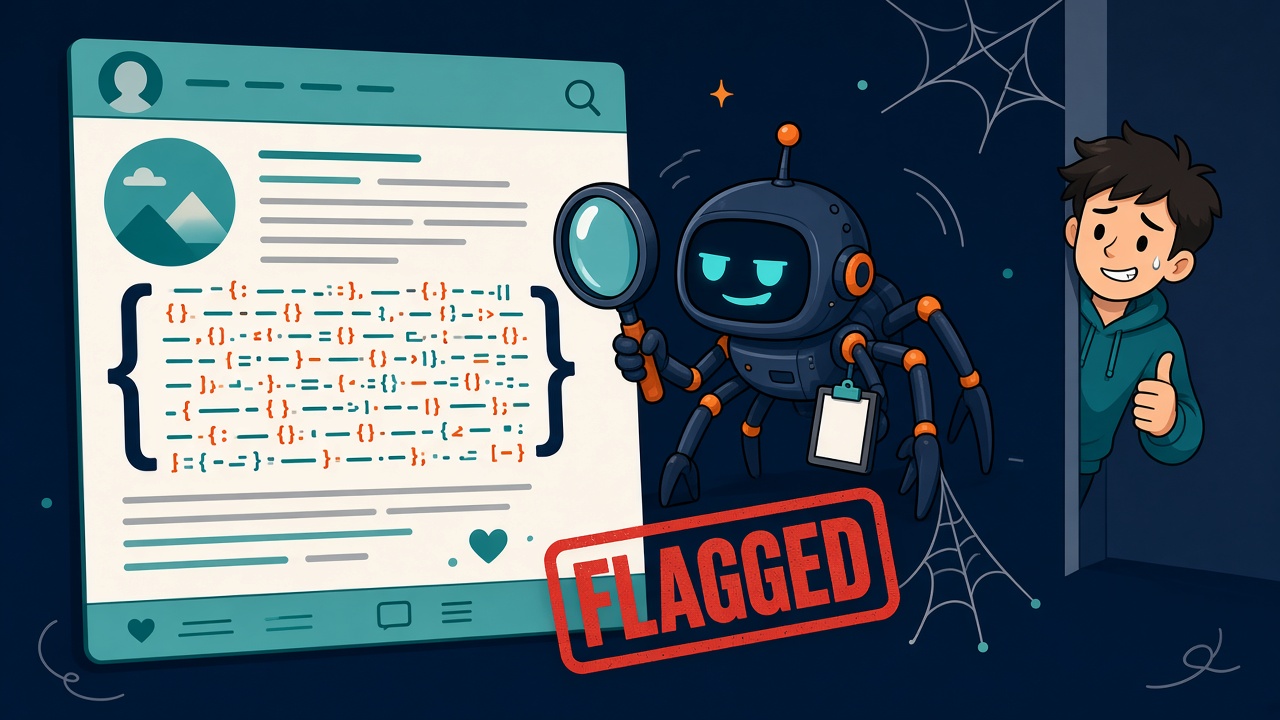
    I had an audit run on the oldest content on this site this week. Pages, posts, links, bylines, search descriptions, the works. It came back with a ranked list of problems, and near the top, flagged as a defect readers can see, was this:

    Visible raw JSON-LD schema code printed as text in the post body.

    Across the whole site, it found 197 posts doing it.

    Cartoon crawler robot stamping FLAGGED on a blog post full of visible code while the blogger gives a sheepish thumbs-up
    My own audit, doing exactly what I asked it to do. Rude.

    And I’ll be honest, my first reaction wasn’t “oops.” It was closer to “hey, I did that on purpose.”

    What you’re looking at

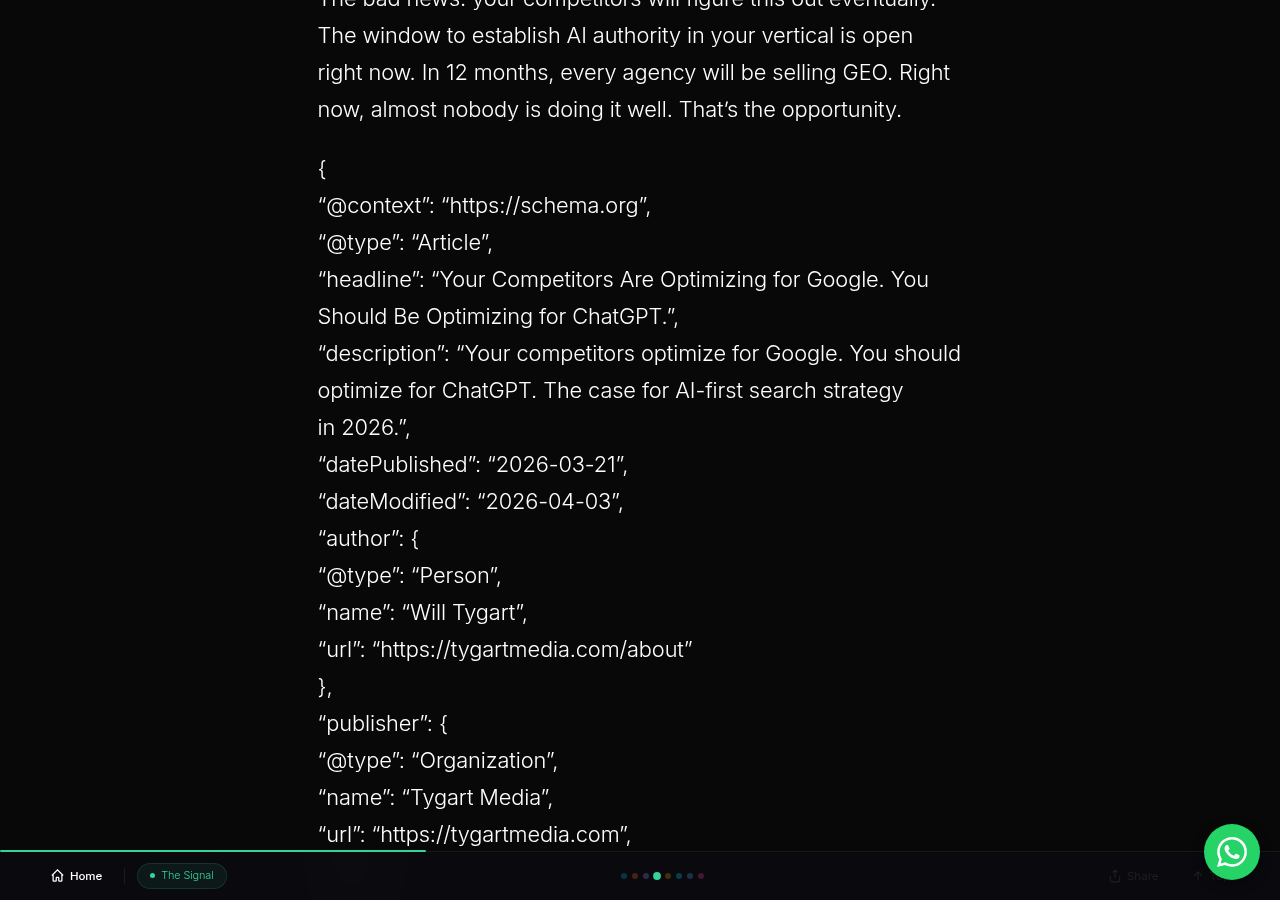
    If you’ve scrolled to the bottom of some of my older posts, you’ve seen it: a block of curly braces, "@context": "https://schema.org", a headline, an author, a publisher, a date. It’s structured data. The machine-readable summary of what the page is, who wrote it, and who published it.

    Normally that lives in a <script type="application/ld+json"> tag. Readers never see it, and crawlers pick it up behind the scenes. I know how to do it that way. Plenty of these same posts had it that way too.

    I also put a copy out front, in the body, where anyone could read it.

    Before: the end of “Your Competitors Are Optimizing for Google. You Should Be Optimizing for ChatGPT.” with its Article schema printed as visible text, curly quotes and all
    Before. The article ends, the schema begins. Those curly quotes are lovely typography and terrible JSON.

    Why I did it

    This didn’t come out of nowhere. Back when I published these, I’d already been at it a while: for about a year before that, my everyday workflow was screenshotting schema and photos and pasting them into AI tools to get help with them. That was on my own desk, not on the website. But do that long enough and you get in the habit of thinking about the page as something a machine reads, not just something a person reads.

    When it came time to publish these posts, my reasoning was simple. Not everything that reads a web page reads it the way Google does. Screen readers, accessibility tools, and whatever crawler or AI agent happens to show up next don’t all go digging through script blocks. Some of them only take in the text on the page.

    So I thought: if the structure matters, and I was betting heavily that it did, especially for AI and answer engines, then why hide it? Put it where every reader, human or machine, could get to it. Treat it as part of the content, not an invisible attachment.

    It was also a demonstration. I write about getting businesses understood by machines. Showing the actual markup on the page was a way of saying: this is what that looks like. Nothing up my sleeve.

    The fair criticism

    Now, I’m stubborn, not blind. A few things are fair game here.

    A wall of JSON is not friendly to a human reader. If you came for a local SEO playbook and finished on forty lines of braces and quotation marks, I get it if you thought the page was broken. The audit literally measured one of these blocks running about 2,100 pixels tall on a phone. That’s a lot of scrolling for metadata.

    What a screen reader actually does with a block of JSON is a fair debate. My intent was access. Whether reading out a pile of punctuation counts as access is a fair thing to argue about, and I’m not going to pretend I settled it.

    The copies didn’t stay clean. WordPress likes to “help.” Some of the visible blocks picked up curly quotes and line breaks along the way. That’s charming in prose and useless in JSON. A machine trying to parse those blocks as data would choke.

    So the audit isn’t wrong that it’s a problem today. It’s just wrong about why it’s there. It wasn’t an accident. It was a choice, and the choice has run its course.

    Why it’s coming down now

    Here’s the part that makes this easy. The stack caught up.

    This site runs Rank Math, and Rank Math now outputs proper Article and BreadcrumbList schema on every post, in the head of the page, where it belongs. That means the visible copy isn’t carrying any weight anymore. It’s a duplicate. Worse, some of these posts were carrying three versions of the same facts: Rank Math‘s, an older inline script block, and the visible one, and they didn’t always agree on things like the modified date.

    When the system does the job properly, the demonstration becomes clutter.

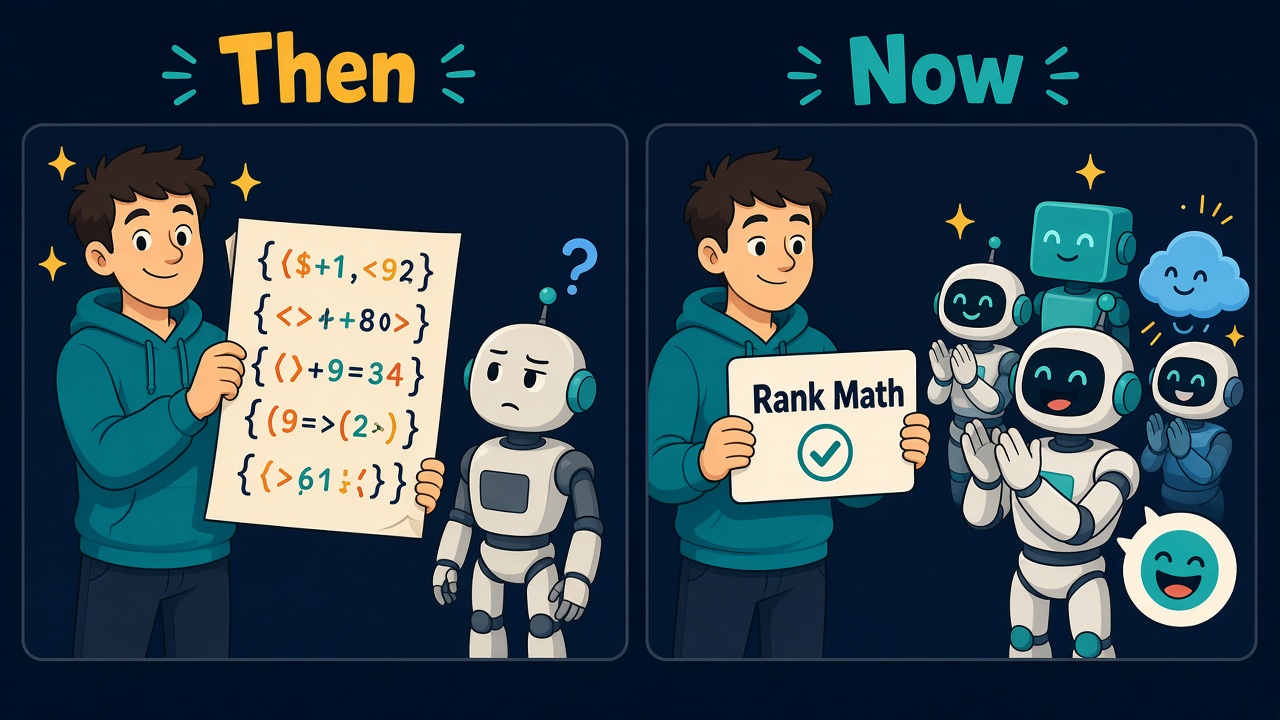
    Then and now cartoon: a blogger holding a sign of raw code, then a Rank Math badge as robots applaud
    Same guy, same idea. The plugin just does it without the sign.

    What we’re doing about it

    • Audit first. Nothing gets touched without a list. The audit covered the 50 oldest items on the site, and a separate site-wide scan found the full 197.
    • Delete the visible blocks. No rewriting, no reformatting. The fix is deletion, and the duplicate inline Article scripts in those same posts go at the same time.
    • Let Rank Math own schema. One source of truth for structured data. If a page ever needs custom schema, it goes through Rank Math‘s schema settings, not pasted into the post.
    • Look at the page like a human. Every fixed post gets checked live in a browser afterward. The code should be gone, and the article should end where the article ends.

    The cleanup of the oldest posts is happening now. The rest of the 197 get their own pass after that.

    The actual lesson

    I’m not going to tell you I was wrong to try it. I had a reason. You just didn’t know it, and to be fair, neither did the audit.

    But a reason has a shelf life. What made sense back when I published these doesn’t have to make sense now, and it’s worth checking every once in a while whether your clever idea is still doing its job or just sitting there being clever.

    Mine was sitting there. So it’s coming down.

    If you spot a stray curly brace at the bottom of one of my posts in the meantime, consider it a collector’s item.

  • We Asked AI Who to Call for Water Damage in Puyallup. Here’s What It Said.

    We Asked AI Who to Call for Water Damage in Puyallup. Here's What It Said.

    It's 2 a.m. You're standing in water in your basement on South Hill, and it's still raining — because of course it is, it's October in the valley. You grab your phone. You don't Google like it's 2015. You ask.

    "Who do I call for a flooded basement in Puyallup?"

    That's the moment that matters. Not your website. Not your trucks. That question, asked to a machine, at 2 a.m., by a neighbor with water coming in. On a Tuesday night in October, we asked the machine that question — and three more like it — from Puyallup, and wrote down exactly what it said. Here's what came back.

    How we ran it

    Four questions, one at a time, in a fresh incognito session of Google's AI Mode, location set explicitly to Puyallup, Washington: "Who do I call for a flooded basement in Puyallup, Washington?", "Best water damage restoration company in Puyallup WA", "Emergency water extraction Puyallup Washington", "Mold remediation company Puyallup WA". Tuesday, October 6, 2026, around 11 p.m. Pacific.

    That timestamp matters, and it's the first thing to understand: AI answers are situational. They shift with the time of day, the day of the week, the exact location, who's asking, and whether a business is currently open. A Tuesday-at-11-p.m. answer is a snapshot, not a permanent ranking. What follows is what the machine said that night — and more importantly, how it decides, because we asked it that too.

    Finding 1: The shortlist reshuffles every query. Only the franchise is permanent.

    This is the headline, and it surprised us. Four questions, four different winners' circles:

    • "Who do I call for a flooded basement?" → Five names: the franchise, plus four others. The franchise gets the direct "call immediately" recommendation, phone number included.
    • "Emergency water extraction" → Three names: the franchise, a Puyallup independent, and a regional franchise brand.
    • "Best water damage restoration company" → Three names — and the franchise isn't among them. Two local independents and a Tacoma shop sweep it.
    • "Mold remediation" → Four names: the franchise, the Puyallup independent, the regional brand, and a fourth shop.

    One company appears in every answer. Everyone else is renting their spot one question at a time.

    Let's name the pattern without naming names. Company A is the franchise — the only brand with real gravity in the valley, and it's corporate gravity, not local. Four-point-six stars, hundreds of reviews, IICRC-certified, open 24/7. The machines hand it the emergency answer with the phone number.

    Companies B, C, and D are independents — a Puyallup shop with around a hundred reviews, a Buckley-area outfit at 4.9 stars, a family-owned Tacoma company at 4.9 across 240 reviews with a named master restorer. Good operators, by every visible signal. They win the "best" query outright. They vanish from the emergency query. The machine's memory of them lasts exactly one question.

    Finding 2: There are two games, and the money is in the harder one

    Watch what the machine rewards in each query and the split becomes obvious.

    The emergency queries are an operational game: open now, dispatch speed, 2 a.m. availability. The "best" query — asked at 11 p.m. on a Tuesday — even praised one shop for "exceptional late-night/weekend emergency dispatch." The machine is weighting for right now. Content can't win that game. Only being actually open and actually fast can. That's why the franchise owns it.

    The comparison queries are a quotability game: reviews with substance, named certifications, family-owned story, transparent pricing, a master restorer with a name. The independents sweep this game. A Tacoma independent with 240 reviews and insurance-direct language stands shoulder to shoulder with the national brand — in the answer the homeowner reads when they're choosing, not panicking.

    Here's the uncomfortable arithmetic: the independents win "best" and lose "right now." And "right now" — the 2 a.m. basement — is where the money is. The most winnable query and the most valuable query are different queries.

    Finding 3: Part of what looks like the answer is an ad

    In the AI Mode results, business cards with Call/Directions/Website buttons sit inside the answer — the Local Services Ads format, blended into the AI's response. At 11 p.m., most homeowners can't tell the ad layer from the earned layer.

    So there are really two contests running inside every answer: the paid layer (whoever's buying the call button) and the earned layer (who the AI's prose actually names and cites). Money can buy the first. It can't buy the second — which is exactly why the second is worth winning.

    Finding 4: Named is not the same as quoted

    Here's the detail that reframes everything. In these answers, the AI names three to five shops — but it cites a different, longer list of websites for the sentences the answer is built from: equipment pages, service-area pages, process explanations from restoration companies across the region.

    Named and quoted are two different games. You can be named without being quoted (the franchise, mostly), and you can be quoted without being named. But notice who's missing from both lists: nobody publishing from Puyallup proper is feeding the machine its sentences. The valley's expertise exists — every estimator in Pierce County knows what to do when a South Hill basement floods in October — but none of it is written down where the machine can find it. The trade's knowledge is trapped in trucks.

    Finding 5: We asked the machine how it picks. It told us.

    After the four queries, we kept the conversation going and asked the AI, plainly, how it chooses which companies to recommend. It gave us its rubric:

    1. Technical certifications — IICRC S520 / AMRT on the actual crew (not just the owner), active Washington contractor license, pollution and hazardous-material coverage.
    2. Equipment and containment protocols — negative air pressure, HEPA scrubbers, thermal imaging, moisture meters. "Spray and wipe" outfits are disqualified outright.
    3. Local reputation with substance — consistent ratings across Google, Yelp, and BBB, with reviews that mention communication, transparent pricing, and punctuality specifically.
    4. Insurance infrastructure — Xactimate estimating, direct adjuster coordination.
    5. Ethical boundaries — third-party clearance testing, not grading their own homework. The machine has opinions about conflicts of interest.

    Read that list again. Every item on it is publishable. A shop can put all five on its website on a Tuesday afternoon, with no trucks rolling, and become verifiable by the machine's own stated criteria.

    And where does the machine verify? It told us that too: your service pages ("direct company service pages outline specific equipment used, containment methodologies"), the IICRC registry, Washington's licensing databases, and your reviews. If your website doesn't publish the signals, the AI can't confirm them, and you don't get named. That's not a metaphor. It's the literal mechanism.

    AI answers don't rank you. They quote you.

    The mold wedge

    One more thing the evening taught us, and it's the strategic takeaway: mold is the gateway query.

    Mold remediation isn't an emergency — it's schedulable. The homeowner isn't panicking at 2 a.m.; they're reading, comparing, choosing. That's the quotability game, the one content can win from a keyboard. Everything the machine scores on mold — AMRT certification, HEPA and negative air on the process page, third-party testing on the FAQ — is publishable by any competent shop this week.

    And the homeowner who learns your name from the mold answer doesn't unlearn it. Six months later the basement floods at midnight, and they don't ask the machine again — they call the name they already trust. Mold is the KNOW that feeds the 2 a.m. BUY. Win the schedulable query with content, and you inherit the emergency call for free.

    The funnel, Puyallup edition

    KNOW — "What do I do about water in my basement?" The machine explains: shut the water off, kill the breakers safely, document everything for insurance. The advice is solid. Nobody local is cited for it, because nobody local published it.

    PROVE — "Are these companies legit?" The machine checks its rubric: certifications, equipment, Xactimate, third-party testing, reviews with substance. The shops that publish these signals get verified. The shops that don't are unverifiable — which reads the same as invisible.

    CHOOSE — "Who's the best?" The shortlist moment, and the independents' best event. Reviews, story, credentials — this is where Company B, C, and D win. The franchise doesn't even make this particular shortlist.

    BUY — "Who do I call right now?" The 2 a.m. call. Operational game. It goes to whoever's verifiably open and fast — tonight, that's the franchise, with the phone number in the answer.

    GO — "Are they actually here?" The stage the machines are weakest at and humans are strongest. A homeowner who can drive past your shop on Meridian, who's seen your trucks at the fairgrounds in September — that trust doesn't come from a citation. But you have to survive the first four stages to get the meeting. Nobody meets the unverifiable.

    What separates the named from the invisible

    It's not budget. It's not the franchise's national marketing team. It's whether the machine's rubric appears on your website:

    1. The certifications, named precisely. Not "certified technicians" — "IICRC AMRT-certified crew," "S520 standard," "WA contractor license," "pollution liability coverage." The machine checks registries. Give it the exact strings to check.
    2. The equipment, specified. Negative air pressure, HEPA scrubbers, thermal imaging cameras, moisture meters, Xactimate estimating. These are the words the machine's rubric is written in. If your process page doesn't contain them, you fail a test you didn't know you were taking.
    3. The ethics, stated. Third-party clearance testing. Direct insurance coordination. The machine explicitly rewards shops that don't grade their own homework — publish that you don't.
    4. Reviews with substance. Not fifty "great service!!" reviews — ten that mention response time, communication, and a real job. "They were here in 40 minutes during the November storm" is a sentence the machine can use.
    5. Local proof in the copy. Name the valley. Name the season. The machine itself now uses local texture — "the Puyallup River valley," landmarks from Bradley Lake Park to Pioneer Park. "We handle the October basement floods on South Hill" is uncopiable: a national competitor can't fake it, and it's the one advantage every local company has.

    Company A wins by default. The first independent that publishes the machine's own rubric doesn't compete with Company A — it becomes verifiable, quotable, and eventually the default.

    The deeper standard

    There's a caveat that matters more than any tactic. AI answers are situational — time, day, place, asker, who's open. The variables multiply past anything gameable. No checklist survives contact with a machine that re-shuffles its shortlist every question.

    So the only durable strategy is operational truth: get your operations to the point where you can advertise them without being attacked. Claims so true nobody can dispute them — because the machines quote what's quotable, and the customers verify what's real. The checklist gets you into the answer. The work keeps you there.


    This is the free version of our AI Citation Quick-Scan. We ask the questions your customers are asking the machines, and we map exactly who gets named, who's invisible, and what separates them — for your company, your market, your queries. It's $97, and if you upgrade to the full visibility package within 30 days, the $97 comes off the price. If you're a restoration company in Pierce County and you just read this wondering whether you're Company B, C, or D — that's exactly what the scan answers.
  • Review Count Is Dead: The Reputation Graph Killed It

    Review Count Is Dead: The Reputation Graph Killed It

    A water-damage company with 47 reviews just got recommended by ChatGPT over a competitor with 462.

    Read that again. Four hundred and sixty-two reviews. Ten times the social proof. And the AI picked the little guy.

    If you spent the last decade collecting reviews like they were votes, this should rattle you. It should also clarify everything, because the game didn’t just change — it ended, and a new one started while nobody was watching.

    From ranking to matching

    The old game was a scoreboard. Most reviews wins. Biggest ad budget wins. Best SEO agency wins.

    The new game is a matchmaker.

    In June 2026, OpenAI rolled out a memory system (they call it Dreaming) that quietly builds a living profile of you — your chats, your Gmail, your files — and uses it to shape every answer. It’s on by default. Two people asking ChatGPT the same question now routinely get different answers, because the AI knows different things about each of them.

    Google’s doing the same thing from the other direction. AI Overviews don’t give you a ranked list of ten businesses anymore. They name two or three. Fourth place doesn’t get a consolation mention — it gets nothing. And here’s the number that should end the argument: only about 26% of the businesses sitting in Google’s top-3 map pack even appear in Gemini’s responses. You can win the map pack and still be invisible to the AI.

    So the question was never “who has the most reviews.” The question is “who is the best fit for this person,” and the AI is answering it with information you can’t see.

    The dinner test

    Here’s how I explain it to myself.

    Tonight I walked to a little family-run Thai place instead of ordering from a chain. No ad convinced me. No review count swayed me. The tools just… knew. They knew I’d rather have the local place with the great green curry than the heavily advertised alternative.

    A cozy family-run Thai restaurant glowing warmly at dusk while a chain restaurant sign looms in the background
    The tools know you’d pick the local place. No ad budget changes that.

    That’s what happened with the 47-review company. The AI didn’t count stars. It matched a person — their history, their preferences, the pattern of what “good” looks like to them — against the businesses it knew. And the little guy fit better.

    Panda Express can outspend everybody. It doesn’t matter. When the tool knows you better than the ads do, the ads stop working on you.

    Why the count stopped mattering

    It’s not that reviews don’t matter. They do — review signals have actually grown to about 20% of local ranking weight. But count was always a proxy for trust, and the AI doesn’t need the proxy anymore. It reads the reviews. It summarizes the sentiment. It checks whether your website says the same thing your Google profile says. It looks at whether your story is consistent across fifteen, twenty, thirty sources — or whether it falls apart the moment it leaves your homepage.

    A thousand bought or begged reviews with thin sentiment lose to fifty detailed ones that all say the same specific true things. The AI can tell the difference. It literally summarizes them.

    What actually wins now

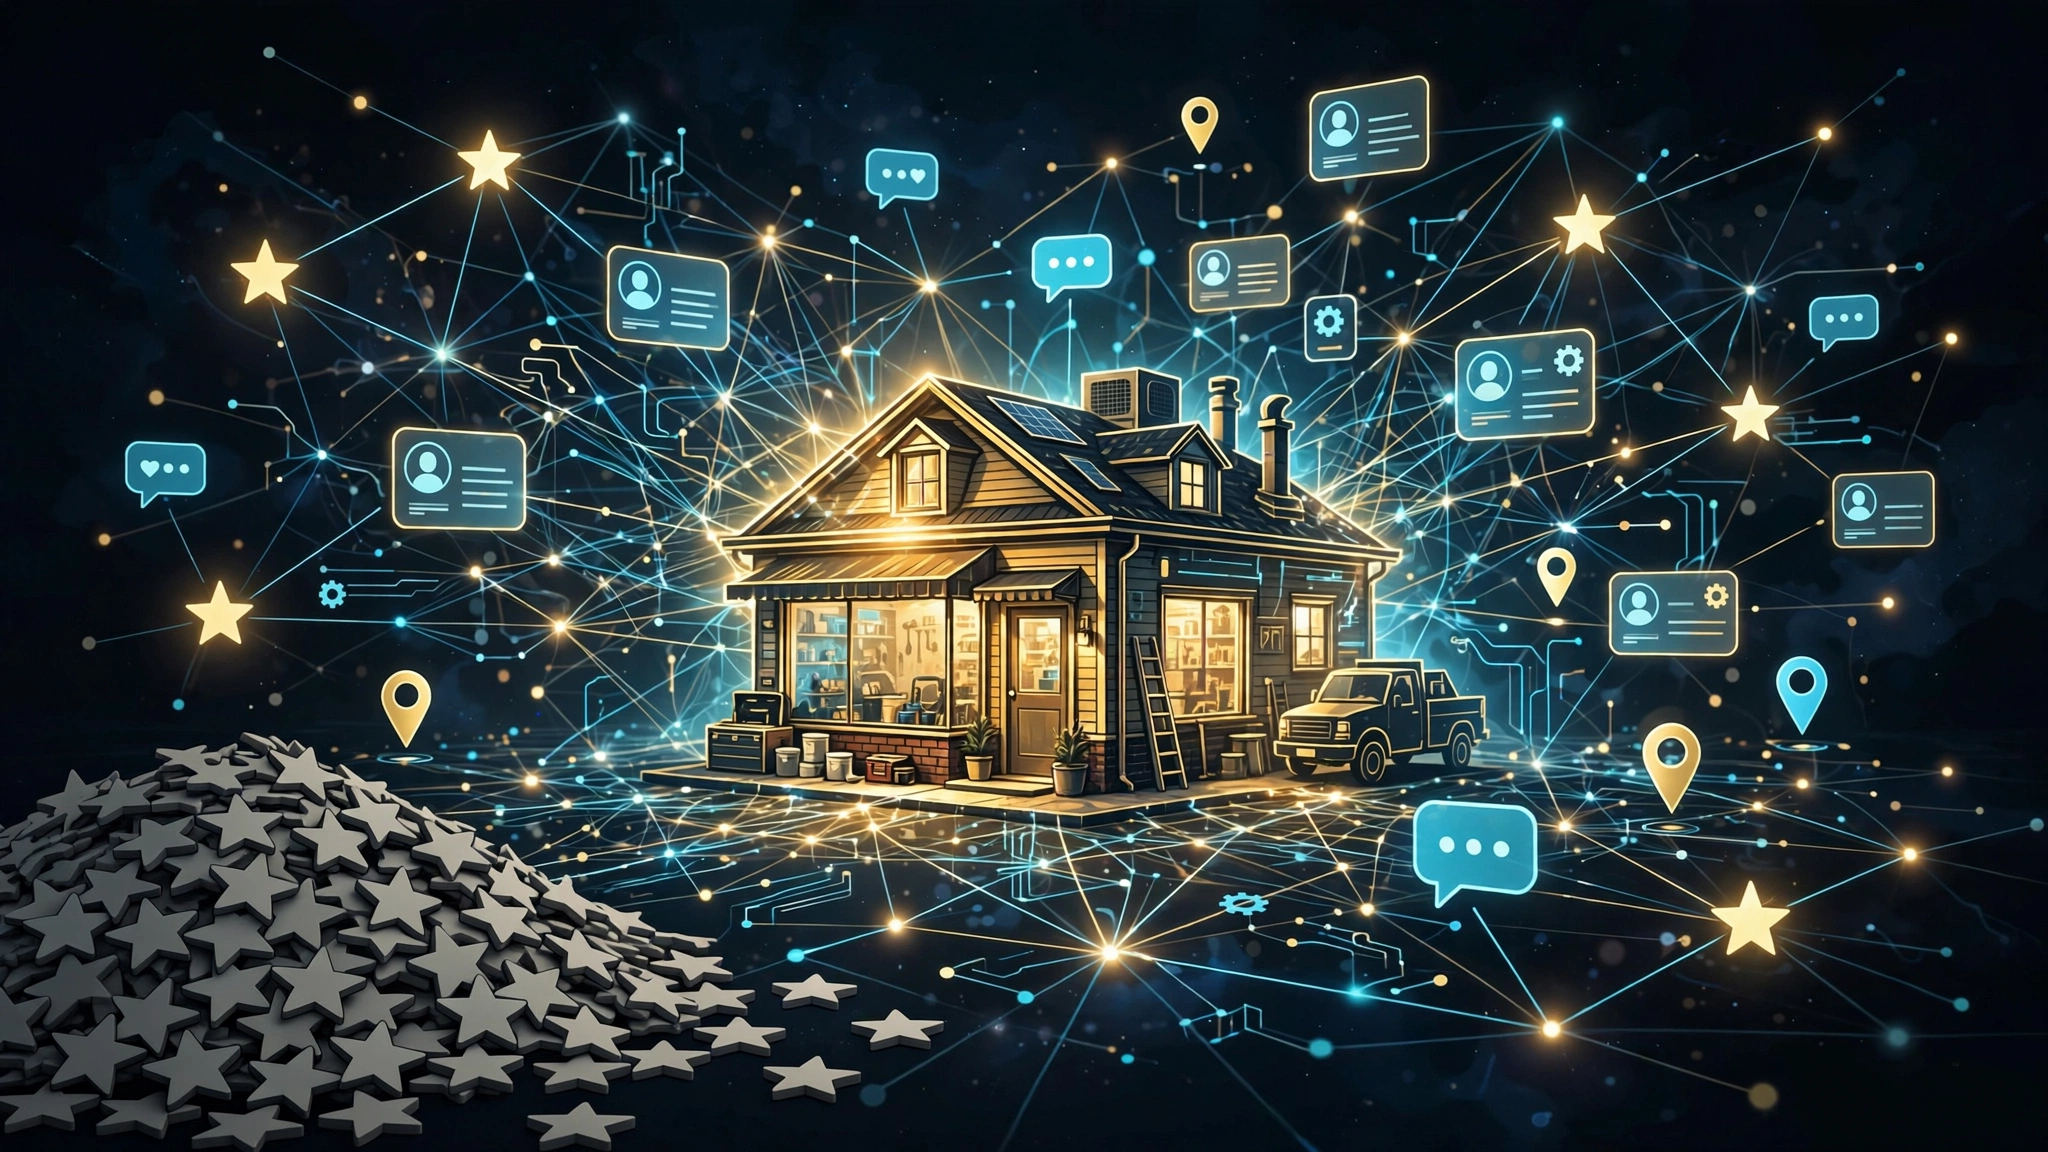
    A local contractor business at the center of a glowing reputation graph, with a pile of disconnected review stars off to the side
    The reputation graph: every signal connected, telling one consistent story.

    The playbook isn’t complicated, but it’s unforgiving:

    • Complete your profile like it’s the product. The AI reads your Google Business Profile as a primary source. Empty fields are silence, and silence doesn’t get cited.
    • Recency and sentiment over volume. A steady stream of real, specific reviews beats a pile of old five-stars.
    • Say the same true thing everywhere. Your website, your profile, your directories, your socials — one consistent story, confirmed in many places. Contradictions are how you disappear.
    • Structure your data. Schema markup is how the machines read you. It’s not optional anymore; it’s the difference between being understood and being skipped.
    • Be genuinely good. This is the one nobody wants to hear. The tools are getting better at knowing what “good” looks like for each person, which means there are fewer places to hide. You can’t buy your way into a match. You have to be the answer.

    The honest caveat

    I want to be straight about what we know and what we don’t. Nobody outside these companies can see exactly how the personalization works — one researcher called it “a synthesized profile that neither the user nor the brand can fully see.” That’s the truth of it. We’re reading the outputs and working backward.

    And the social-graph part — your friend’s Facebook comment tipping a recommendation — is directionally right but the mechanics differ by platform. Google has the cross-product graph: YouTube, Maps, Gmail, Android. Meta’s AI has the actual social graph. ChatGPT works mostly from your own data. The destination is the same everywhere: the recommendation gets personal, and the personal is opaque.

    Less places to hide

    That’s the line I keep coming back to. Less places to hide.

    For years you could paper over a mediocre operation with review velocity, ad spend, and SEO tricks. The machines are taking those tools away — not out of virtue, but because matching works better than ranking, and the platforms all figured that out at once.

    What’s left is the oldest marketing strategy there is: be good, be consistent, and make sure the machines can see it.

    The 47-review company didn’t beat the system. It was the system working as designed. The question is whether you’re building a business the new system can see — or still optimizing for the old scoreboard.

  • AI Search Visibility for Local Service Businesses: The 2026 Playbook

    Last verified: October 4, 2026 (Pacific).

    Key takeaways

    • AI search visibility is whether AI assistants name your business when someone asks for a local service — and 78% of local-services brands are currently invisible to it.
    • ChatGPT recommended just 1.2% of business locations in a 2026 benchmark of 350,000 locations, versus 35.9% appearing in Google’s local 3-pack (SOCi, 2026).
    • Only 12% of URLs cited by AI overlap with Google’s top 10 results — this is a separate ecosystem with separate rules (teehoomartech).
    • The shops winning AI citations publish real price ranges, license and certification signals, and emergency-intent pages — the three shapes almost nobody in the trades has built.
    • Expect a 90-day foundation cycle: fundamentals first, then the service × city content matrix, then seasonal content.

    What is AI search visibility for a local business?

    AI search visibility is the practice of making your business the answer AI assistants give — getting ChatGPT, Gemini, Perplexity, or Copilot to recommend you by name when someone asks for a local service. Think of it as SEO for the recommendation era.

    Your next customer didn’t Google “plumber near me.” They asked ChatGPT. Or they asked Gemini while standing in their kitchen with water pooling under the sink. And the AI named three businesses — yours wasn’t one of them.

    This isn’t a future problem. According to BrightLocal (March 2026), 45% of U.S. consumers use AI to find and choose a local business — up from 6% a year earlier. The question is no longer whether AI sends you customers. It’s whether AI knows you exist.

    How far behind are local businesses in AI search?

    A 2026 benchmark by SOCi across roughly 350,000 business locations put hard numbers on the gap:

    • ChatGPT recommended 1.2% of locations. Google’s local 3-pack showed 35.9%. Gemini recommended 11%, Perplexity 7.4% (SOCi, 2026).
    • AI visibility is 3 to 30 times harder to achieve than ranking well in traditional local search (SOCi, 2026).
    • Only 12% of URLs cited by AI overlap with Google’s top 10 results (teehoomartech). This is a different ecosystem, not an extension of the old one.
    • 78% of local-services brands are invisible to AI, and 88% of local businesses have no AI search strategy at all (May 2026 industry index).

    Here’s the reframe that matters: AI doesn’t rank you. It recommends you. Traditional SEO was optimization — climbing a list. AI visibility is qualification — convincing a model you’re a safe, correct answer to give a real person. Everything below follows from that shift.

    Traditional local SEO AI search visibility
    Climb a ranked list (positions 1–10) Become the recommended answer (named or not at all)
    Optimize for Google’s crawler Qualify for the model’s trust judgment
    Reviews are a ranking signal Reviews are a qualification filter — the AI reads the text
    Your website is the destination Your website is the source the model draws on
    One rulebook (Google) Different rulebooks per engine (Gemini, ChatGPT, Perplexity)

    What are the non-negotiable fundamentals?

    You’ve seen this checklist before, so here’s the short version — these are table stakes, and the data says they still move the needle:

    • NAP consistency everywhere. Inconsistent name/address/phone data cuts your AI citation probability by 67%. Consistent omnichannel data delivers 3.2x the AI visibility (Birdeye, 2025).
    • A complete Google Business Profile. Optimized profiles appear in AI Overviews 42% more often, with 30% more profile views and 34% more direction requests (Local Falcon; SapientSEO).
    • Review volume, velocity, and recency. AI treats reviews as a filter, not a ranking signal — and it reads the review text, not just the stars. ChatGPT-recommended locations averaged 4.3 stars in the SOCi benchmark: good enough to pass the filter, with the text doing the real work.
    • Owner responses on reviews. Every response is a place to confirm your services, your service area, and real outcomes — in the AI’s own training-adjacent data.
    • LocalBusiness schema on every page. Structured data increases AI citation probability 3.4x (MIT CSAIL). FAQ content earns 2.8x more AI citations than marketing copy (Search Engine Land research).

    If any of those are missing, fix them first. What follows is what nobody is telling the trades.

    How do you win the 2am emergency query?

    The highest-value AI query in the trades isn’t “best plumber near me.” It’s “emergency plumber near me open now” at 2am — asked by someone with water coming through their ceiling. Nobody has mapped AEO to urgent intent. Here’s the playbook:

    • Set your after-hours attributes. Your GBP has hours fields most shops leave blank or set wrong. AI models check “open now” signals before recommending — a blank field reads as closed.
    • Build dedicated emergency service pages — one per emergency service, not a paragraph on your homepage. Format them as direct answers: what counts as an emergency, what you do first, typical response time, service area, then the phone number.
    • Answer the 2am questions explicitly. “Do you charge extra for after-hours calls?” “How fast can you get to [neighborhood]?” If your page answers them in plain sentences, the AI can quote them. If it doesn’t, the AI quotes whoever did.

    What trust signals make AI recommend a contractor?

    Here’s the qualification logic: an AI will not recommend a stranger to enter someone’s home unless it has reasons to trust. For the trades, those reasons are concrete — and almost nobody publishes them properly:

    • License numbers on every service page, not buried on a contact page. “WA Licensed General Contractor #TYGART123JD” is an entity signal.
    • Insurance stated plainly — liability coverage and bonding, in sentences, not badges alone.
    • Trade certifications as trust qualifiers — IICRC for restoration, NATE for HVAC, EPA 608 for refrigerant work. These are the exact credentials a homeowner would want verified, which makes them exactly what the AI looks for.
    • Put them in schema too. Credentials in visible text get read; credentials in structured data get cited.

    Zero of the major guides on this topic mention licensing or certification. That’s your opening.

    What should a local business publish so AI cites it?

    “Structured local content publishing” is everyone’s advice and nobody’s architecture. Here’s the architecture: one quotable page per service per city you serve — the service × city citation matrix.

    • Each page answers one question completely: the service, the city, what it costs, how long it takes, what can go wrong.
    • Publish real price ranges. Every guide lists “how much does [service] cost in [city]?” as a top AI query — and none tell shops to answer it. The shop that publishes “$1,200–$2,800 for a water heater replacement in Tacoma” becomes the citable source. Everyone else becomes invisible on the highest-intent question in the category.
    • FAQ schema on every matrix page. Direct-answer formatting: the question as a heading, the answer in the first two sentences, detail after.
    • Emergency variants get their own pages (see above) — don’t fold them into the standard service page.

    Are AI crawlers blocked from your site?

    Your site may be silently blocking the exact bots you need. Outdated robots.txt rules — written years ago to keep scrapers out — now block AI crawlers from reading your pages at all. The fix:

    • Explicitly allow GPTBot, ClaudeBot, PerplexityBot, and Google-Extended in robots.txt.
    • Don’t blanket-allow every bot on the internet — allowlist the AI crawlers by name, keep the rest of your rules intact.
    • Verify with a fetch test after the change. Thirty seconds of work, and without it, every other play on this list is muted.

    How do reviews get AI to recommend you?

    Google’s April 2025 Maps policy change killed scripted “mention my name in the review” requests. The shops still running that playbook are risking their profiles. The compliant system:

    • Ask “tell us about your experience,” not “leave us a review.” AI reads review text — “they replaced our water heater in under three hours” beats “great service” because it contains a service, a timeframe, and an outcome.
    • Time the ask: SMS or invoice link within 2 hours of job completion, while the details are fresh.
    • Engineer your owner responses as service + neighborhood + outcome triples: “Glad we could get the furnace running again for you in Lakewood — those January cold snaps don’t wait.” Every response is corroborating evidence the AI can use.
    • Review freshness is its own factor. A steady cadence beats a burst.

    How do you audit your AI readiness in 20 minutes?

    AI models cross-check you. Your reviews, your GBP, and your website need to tell the same story — same services, same service area, same phone number, same hours. When they disagree, the model loses confidence and picks someone else. The corroboration triangle audit, once a month:

    1. Read your last 10 reviews. Do the services mentioned match your GBP services list?
    2. Check your GBP hours, service area, and phone against your website footer and contact page.
    3. Search your business name plus your top service. Is the story consistent across the first page?
    4. Fix the mismatches. That’s the whole audit.

    Does each AI engine need a different approach?

    Yes. The models don’t work the same way, so don’t treat them the same. Same skeleton for each: what it trusts, then the one-line tactic.

    Gemini

    • What it trusts: live Google Maps data — profile accuracy runs near 100% because it’s grounded in Maps.
    • Tactic: GBP completeness and accuracy win here; treat your Business Profile as your Gemini homepage.

    ChatGPT

    • What it trusts: concise shortlists built from third-party corroboration — reviews, mentions, directory listings (profile accuracy here runs ~68%, so corroboration fills the gap).
    • Tactic: third-party mentions are what get you onto its shortlist; one strong source is never enough.

    Perplexity

    • What it trusts: live search with direct citations — freshness is the ranking input.
    • Tactic: recent reviews, recent posts, recently updated pages; stale content goes invisible fastest here.

    Copilot

    • What it trusts: Microsoft’s retrieval grounding — substantially the same answer logic as Bing’s AI surfaces.
    • Tactic: Bing Webmaster Tools verification plus the same fundamentals; what works for Perplexity-style freshness works here.

    Run the same tracked prompts across all four monthly and note who’s citing you and who isn’t. That’s your measurement system until you outgrow it.

    What does the first 90 days look like?

    Generic 90-day plans assume you’re a SaaS company. You’re not — you have seasons. Map the work to yours:

    • Days 1–30: Foundation. NAP audit, GBP completion, robots.txt allowlist, license/certification trust layer on every page, emergency pages live.
    • Days 31–60: Matrix. Build the service × city pages for your top 5 services, each with real price ranges and FAQ schema. Launch the review-text system.
    • Days 61–90: Seasonality. Publish ahead of your season — frozen-pipe content in December, AC tune-up FAQs in April, storm-season prep in late summer. The shop that publishes first becomes the cited source for the whole season.

    Frequently asked questions

    What is AI search visibility for a local business?

    It’s whether AI assistants — ChatGPT, Gemini, Perplexity — name your business when someone asks for a local service. Unlike Google rankings, there’s no position 4 to fall back on: either the AI recommends you or you’re not in the consideration set at all.

    How is AI visibility different from local SEO?

    Local SEO climbs a ranked list; AI visibility qualifies you as a safe recommendation. Only 12% of URLs cited by AI overlap with Google’s top 10 results (teehoomartech) — it’s a different ecosystem with different rules, and it’s 3 to 30 times harder to break into than the local 3-pack (SOCi, 2026).

    Do reviews really affect whether AI recommends my business?

    Yes — AI treats reviews as a qualification filter and reads the review text, not just the star rating. Review volume, recency, and specific language about services and outcomes all feed whether a model will name you.

    Should I block AI crawlers from my website?

    No — blocking GPTBot, ClaudeBot, PerplexityBot, or Google-Extended in robots.txt makes your pages invisible to the models deciding who to recommend. Allowlist the AI crawlers by name instead.

    How long does it take to build AI search visibility?

    Expect a 90-day foundation cycle: 30 days for fundamentals and crawler access, 30 for the service × city content matrix, 30 for seasonal content and review velocity. It’s ongoing work after that — freshness is a ranking input, not a one-time project.

    What’s the single highest-ROI move for a trade business?

    Publish real price ranges on service × city pages. “How much does it cost” is the top AI query in the category, almost nobody in the trades answers it, and the business that does becomes the cited source.

    What does done-for-you look like?

    Everything above is the playbook, free, on this page — that’s the point. If you’d rather have it built than build it, that’s what our AI Search Visibility Package does: the full citation work for your trade, measured the way AI measures it. Start with the $97 AI Citation Quick-Scan if you want to see exactly where you stand first — the $97 credits toward the package within 30 days.

    Want the deeper version — the robots.txt allowlist snippet, the per-engine prompt library for the monthly audit, and the seasonal content calendar template? That goes out by email. The playbook above is yours either way.

  • All My Reviews Just Say ‘Great Service’ — Do the Words in My Reviews Matter to AI?

    Short answer: Yes — the words matter more than the stars. When someone asks for “a reliable plumber who handles emergency leaks,” the AI recommends the business whose reviews keep saying “quick response” and “emergency repair” — not the one with fifty generic five-stars. Review text is the evidence the bot quotes. A wall of “great service” gives it nothing to quote.

    How the bot actually uses your reviews

    Think about what the AI is doing when it answers “who should I call.” It’s matching the words in the question to evidence it can find. If the question asks for emergency leak help, it looks for businesses with evidence of emergency leak help. And the richest source of that evidence isn’t your website copy — it’s your customers describing what you did, in their own words.

    One analysis of business profiles in AI search put it directly: “If a user asks for a ‘reliable plumber who handles emergency leaks,’ the AI will likely recommend a business whose reviews frequently mention ‘quick response’ and ’emergency repair’ over a business that simply has those terms in its meta description.” Businesses with specific, keyword-rich testimonials get cited more often than businesses with generic five-star ratings and no text.

    A review-industry breakdown this month named vague reviews as one of the three mistakes sending customers to competitors: “great service” instead of “same-day AC repair in Phoenix.” And review audits keep finding the same thing — AI answers quote review text verbatim. Your customers’ words become the bot’s answer.

    The star-rating trap

    Most owners chase stars. Stars are visible, countable, and feel like the scoreboard. But a five-star rating with no text tells the AI almost nothing — it’s a number without a story. Forty detailed reviews at 4.8 stars will beat a hundred empty five-stars, because the detailed reviews give the bot something to match against the question and something to quote in the answer.

    This is also why review platforms matter less than review content here. The question isn’t just where your reviews live — it’s whether the words in them describe the work you actually want to be recommended for.

    The review-request script (free, repeatable)

    You can’t write your own reviews. But you can ask for better ones — and most owners never do. After a job, when the customer is happy, ask them to mention two things: what you did and where. That’s it.

    “If you have a minute to leave a review, it really helps when folks mention the job — like the water heater swap — and the town. Just a sentence is perfect.”

    That’s the whole script. You’re not scripting fake reviews or stuffing keywords — you’re asking real customers to include the specifics they’d naturally mention anyway. “Mike replaced our water heater the same day it died, here in Mesa” is a quotable piece of evidence. “Great service!!” is not.

    What to actually do about it

    • Read your last twenty reviews. Count how many mention a specific job or a specific town. If the answer is “almost none,” you have the generic-review problem.
    • Start the two-thing ask this week. What you did, and where. Every finished job, every happy customer. It compounds.
    • Don’t neglect the unhappy ones. A detailed critical review is still evidence the bot reads — respond to it well, and the response becomes part of the record too.
    • Keep it honest. Never write reviews yourself, never pay for them, never hand customers pre-written text. The specifics have to be real — fabricated detail is both against every platform’s rules and, increasingly, detectable.

    What’s actually known — and what’s not

    Known: AI answers quote review text verbatim, and businesses whose reviews describe specific jobs in specific places get cited more often than businesses with generic ratings. The review-request script — ask for the job and the town — is a free, ownable fix no competitor can block.

    Not known: nobody has published a controlled test measuring naming rate against review-text specificity for trades businesses — the evidence is observational and mechanism-level, not a measured curve. What’s missing is someone running the test: same market, similar star counts, specific-text versus generic-text reviews, measured naming rates. That’s a test worth running.

  • Do I Have to Get on Those ‘Best Plumber in [City]’ Lists for ChatGPT to Recommend Me?

    Do I Have to Get on Those ‘Best Plumber in [City]’ Lists for ChatGPT to Recommend Me?

    Short answer: You don’t have to pay the directories — but you do have to be mentioned. When someone asks ChatGPT “who should I call,” the pages it reads are mostly the ones that rank for that question, and those are usually “best of” listicles. Businesses that show up in the two or three listicles ranking on Bing for their trade and city get named. Businesses with no mentions anywhere get named in only 2.8% of relevant answers.

    The numbers behind the listicles

    This isn’t a hunch — it’s measured:

    • “Best of” list articles account for roughly 21% of all AI citations (arXiv 2606.20065).
    • Brands with no citations on their own site and no mentions elsewhere were named in only 2.8% of relevant ChatGPT answers — across a 34,960-prompt study (arXiv 2609.23162).
    • One agency’s check of ChatGPT answers found 95% pointed to a directory as the source.

    A Bend, Oregon owner’s check this month put it in plain terms: the pages ChatGPT reads are “mostly the ones that rank for the query and the ones that list or compare providers.” A Bend plumber sitting in the two or three “best plumbers in Bend” lists that rank on Bing is far more likely to be named than one whose only mention is their own homepage.

    Why this feels unfair (and partly is)

    Contractors resent listicles and directories as pay-to-play machines, and they’re not wrong to be suspicious. The directories sell placement, sell leads, and sell ads against the very searches you want to win. Being told “the bot reads the listicle” can sound like being told to feed the beast.

    But there’s a difference between paying the directories and being listed on them. Most “best of” pages have free listing paths. The bot doesn’t know or care whether you paid — it cares whether your name, trade, and town appear on a page that ranks for the question being asked.

    The misfire side: listicles can get you wrong

    A Plant City plumber’s owner-written FAQ documents the other edge of this: “A ‘serves Plant City’ line on a directory can mean a truck that drives over from another metro when the board has a gap.” His shop is headquartered in Plant City; the listicles hand the town to whoever bought the line. If you’re not watching your directory listings, the listicle isn’t just ignoring you — it may be actively mislocating you.

    What to actually do about it

    • Find your two or three. On Bing, search “best [your trade] in [your city]” the way a homeowner would. The listicles that rank are the ones the bot reads. That’s your list — not fifty directories, just the two or three that actually rank.
    • Get listed on the free path. Claim or create the free listing on each. Fill it out completely: services, service area, phone number, website.
    • Keep your facts identical everywhere. Same business name, same phone number, same towns on every listing and your own site. Conflicting facts are how you get skipped — or misdescribed.
    • Fix wrong information. If a listicle has your old phone number, the wrong town, or a competitor’s truck on your line, correct it. The bot quotes what’s there.
    • You don’t need the ads. Paid placement on a directory is a separate purchase from being listed. The citation evidence comes from the listing, not the ad spend.

    What’s actually known — and what’s not

    Known: listicles and directories are a major citation source for AI answers — roughly a fifth of citations, and near-total absence from them collapses your naming rate to single digits. The fix is getting accurately listed on the few that rank, not buying your way onto all of them.

    Not known: exactly which listicles any given engine prefers for any given trade and city — that shifts with rankings. Nobody has published a per-market map of “these three listicles decide the plumber answers in Phoenix.” The practical move is checking your own market’s rankings directly, because that’s what the bot is reading today.

  • I Don’t Do Bing — Am I Invisible to ChatGPT?

    I Don’t Do Bing — Am I Invisible to ChatGPT?

    Short answer: Mostly, yes. When ChatGPT goes looking for live information on the web, it searches through Bing’s index — not Google’s. If your business isn’t indexed by Bing and isn’t claimed on Bing Places, ChatGPT’s live-search layer has no way to find you. Everything you built on Google — your rankings, your reviews, your Google Business Profile — doesn’t transfer to that layer.

    Why your Google work doesn’t carry over

    This is the part that stings. You spent years — maybe money, too — getting your Google presence right. Then a homeowner asks ChatGPT who to call, and none of it counts. That’s because ChatGPT reaches the open web through Microsoft’s Bing search infrastructure, not Google’s. One agency put it bluntly in a widely syndicated piece this year: “It Runs on Bing, Not Google.” A contractor who invested everything into Google rankings and ignored Bing Places is, in their words, essentially invisible to ChatGPT’s search layer.

    An SEO vendor’s FAQ answers the owner version of this question directly: “Should I optimize for Bing if I already rank well on Google? Yes, ChatGPT uses Bing’s index when browsing the web. If you’re not indexed in Bing and listed in Bing Places, ChatGPT cannot find your business.”

    What it looks like in practice

    A Vienna-based test from October 2026 ran the scenario end to end: someone asked ChatGPT to recommend an installer in Vienna. ChatGPT searched live via Bing, returned three competitors — and marked the tester’s own firm “NICHT DABEI” (not there). The firm wasn’t failing at marketing. It was failing at being in the index the bot actually reads.

    A Bend, Oregon owner’s check the same month found the same shape: the competitor who gets named is the one who ranks on Bing for the question being asked. Your Google position never enters the picture.

    The “my SEO guy says we’re covered” myth

    If your SEO provider tells you your Google work covers you for AI search, ask them one question: when did you last check my Bing presence? Google-only SEO is a real thing — plenty of shops do excellent Google work and never touch Bing, because for a decade that was a defensible call. It isn’t anymore. The AI layer that now sits between the homeowner and the phone call reads a different index, and “we’re covered” without a Bing check is a guess.

    What to actually do about it

    The good news: this is a five-minute fix, not a six-month project.

    • Claim your Bing Places listing. It’s free, it’s separate from your Google Business Profile, and it’s a real listing that feeds ChatGPT’s search layer. Most contractors have never claimed theirs.
    • Check whether Bing has indexed your site. Search site:yourwebsite.com on Bing. If nothing comes up, Bing doesn’t know your site exists — and neither does ChatGPT’s browsing layer.
    • Set up Bing Webmaster Tools. Free, takes minutes, and shows you exactly what Bing sees (or doesn’t).
    • Keep your facts identical everywhere. Same business name, same phone number, same service area on your site, Bing Places, and Google Business Profile. Mismatched facts are how businesses get misdescribed or skipped.

    What’s actually known — and what’s not

    Known: ChatGPT’s live web browsing runs on Bing’s search infrastructure. Bing Places is a real business listing that feeds that layer — unlike the mythical “ChatGPT business registry,” which doesn’t exist. Contractors who are Google-only are structurally invisible to ChatGPT’s search layer until they fix their Bing presence.

    Not known: exactly how much weight Bing Places carries versus organic Bing rankings in any given answer, or how often the underlying data refreshes. Nobody has published a controlled test of “claimed Bing Places on this date, started appearing on that date” for trades businesses. The mechanism is well-evidenced; the precise timing isn’t.

  • The Tea-Bag Report

    (What your visitors wanted that you didn't have.)

    A friend stays over. Morning comes, they open your cabinets and look around for tea bags. No tea bags. So they drink your coffee instead and say nothing.

    If you ever saw them looking, you'd buy tea. Not because coffee failed. Because someone told you what they wanted with their behavior, and listening is cheap.

    Your website gets houseguests every day. And most of them are looking for tea bags.

    The query is the want

    Every search query is a small confession. Not "what words did they type" but "what were they trying to accomplish." A homeowner typing a city plus "water damage restoration" is standing in a wet hallway. A facilities director reading about IFRC sustainability guidelines at 10 AM on a Tuesday is doing homework for a budget meeting. Same internet, completely different mindsets.

    Bing's AI performance reports now label this outright. Every query that triggers an AI answer citing your pages comes with an intent tag: informational, commercial, local, research. The mindset column is just sitting there in the export. Most people never read it as what it is, which is a list of what your visitors wanted.

    Here's the part that changed my thinking: the industry standard for measuring AI-search visibility is synthetic prompts. Tools invent questions, run them across engines, and record what comes back. Probabilistic reporting, built on guesses, because as a 2026 Luminary analysis put it, "Since AI platforms don't share real prompt data (as at April 2026), organizations must build measurement baselines using synthetic prompts." Except Bing does share the real thing with site owners: the actual grounding query, the engine's own intent label, and your citation share. First-party want, straight from the source. Stop guessing with synthetic prompts when the engine will just tell you.

    Three places the tea bags show up

    1. Citation gaps. When an AI answer cites your page for 15 percent of its response, the want is proven and your voice is small. Someone asked, the machine answered mostly with other people's words. That's a stock-the-shelf list hiding in plain sight: every query where you're present but weak is a page you haven't written yet, or a page that doesn't serve the intent behind the query.

    There's now a named framework for this. Search Engine Land covered a method from Robin Tully, co-founder at Forecast.ing, that scores the distance between what a page claims to deliver and the queries it actually surfaces for, sorting everything into four quadrants. The one that matters is labelled "Create": demand you're visible for but not capturing. As Tully put it: "Your audience is already telling you what they need. That signal is always shifting." And: "observations create interesting conversations, but numbers create urgency and action."

    2. No-result site searches. I'll be honest about my own wrong mechanism here: I assumed failed on-site searches produced 404s. They don't. WordPress renders an empty results page instead. The signal lives in no-result search logs, and there are plugins that exist solely to capture it. One of them positions itself in pure tea-bag language: "Turn Lost Searches into Content Opportunities. Instead of guessing what to create next, build content based on real demand." Every empty search is a houseguest who opened the cabinet, found nothing, and left quietly. Log them.

    3. The 404s. True 404s are a separate signal and just as valuable. Raven Tools documented an agency client who, after a relaunch, started getting emails from visitors hitting dead pages telling them exactly which old resources to recreate. Those conversations turned into sales: "After the client closed a second sale from a '404 lead,' the client jokingly asked if we could just serve up a 404 page all the time." Put a contact path on your 404, watch what comes in, and treat it as demand data. And keep true 404s as 404s. Google's John Mueller has said it plainly: don't blindly redirect dead pages to your homepage or a category page; 404s are a normal part of a healthy website. Blanket redirects confuse the crawlers and bury the signal.

    When matters as much as what

    Across most of the properties I track, AI citations drop hard on Saturdays. The main site fell from 8,863 citations on Friday to 4,197 on Saturday. The B2B-leaning properties all show the same shape, down 26 to 72 percent. That's not lost rankings. That's a weekday-professional audience going home. The exception proves the rule: the race-event property nearly quadrupled on Saturday, because race day is its weekday.

    A DesignRush study of 950,000 U.S. B2B search queries found the mirror image worth noting: weekend visitors showed higher intent, more form fills, deeper reads into content. Different crowds, different mindsets, different hours.

    This is where it stops being analytics and starts being strategy. A research-intent query at 10 AM on a workday wants depth. The same person scrolling at 9 PM wants the short version that respects their evening. Meet the morning persona with the white paper and the evening persona with the two-minute read, and you're not retargeting. You're recognizing someone.

    The philosophy underneath

    None of this is about grabbing people. The grabby version is funnels and popups and "we noticed you almost bought." The tea-bag version is quieter: I see you, I see where you're at, I see what's important to you, and I'll meet you as best I can where you are. Sometimes you won't have the tea. Knowing they wanted it is what lets you stock it next time.

    Run the report monthly. Queries with intent labels, citation shares, no-result searches, 404 hits, daypart patterns. Rank every gap by frequency. What comes out the other end isn't a dashboard. It's a publishing roadmap written by your visitors, a restocking list for shelves you didn't know were empty.

    They already told you what they want. You just have to look where they looked.

    The product

    This is now a standing offer: the Tea-Bag Report. Send us your search data and we'll tell you what your visitors were looking for that you didn't have, ranked by frequency. Then go stock the shelves.

    Sources

  • What AI Assistants Actually See When They Open Your Website

    What AI Assistants Actually See When They Open Your Website

    You see a screen. Your AI assistant usually doesn’t.

    That sentence needs one qualification, which we will get to. But it corrects the picture most of us carry in our heads.

    When I open a website, I see the design and the button I am supposed to press. I assumed an AI assistant saw roughly the same thing, only faster. Then I asked the more basic question: what does it actually receive?

    The answer is not one thing. An assistant can find a site, read a site or operate a site. Those are separate jobs using different inputs. If we want pages that work well for AI assistants, we have to stop lumping them together.

    An assistant meets your website three different ways

    Finding: the search result is the pitch

    When an assistant searches the web, its first view is closer to a search-results list than a browser window. It may receive a title, URL and short snippet.

    At that moment, your title tag and meta description are the entire pitch. The assistant has to decide whether your page can answer the question before opening it. Name the subject plainly.

    Reading: the page becomes a stream of text

    When Muse opens a public page for information, the normal reading path is text-first. Useful content is extracted and returned as headings, paragraphs, lists and links in roughly page order.

    The design largely falls away. The assistant is not admiring the hero section or noticing that a price sits inside a gold circle. It is working from the words the page exposes.

    Images may arrive as markers and file addresses: there is an image here, and here is where it lives. That is not the same as seeing it. If a crucial fact is baked into the pixels—“$199,” “ships free,” “five-year warranty”—the reading path may hit a blank spot. Useful alt text can carry some of that meaning. “Technician using a moisture meter on wet drywall” communicates something. “IMG_4827” does not.

    Doing: a browser worker operates the screen

    The picture changes when the user asks the assistant to do something: log into HubSpot, update a record, complete a form or buy a product.

    A separate browser program can open a real browser on a server. It loads the interface, takes visual observations or inspects the page’s interactive structure, clicks, types and reports what happened back in words.

    That is the qualification to “usually.” A screen may be used inside the process, but the conversational assistant is not sitting behind the glass like a person. It receives observations from a browser tool and sends instructions back. The browser side is the eyes and hands; the assistant works through an intermediary.

    A page can be easy to read as an article and miserable to operate as an application. It can look obvious to a person while presenting the browser worker with five unlabeled controls called “button.”

    WordPress made the abstraction visible

    I had already seen a simpler version in our WordPress work without connecting the dots.

    When we pull a post through the WordPress REST API, the content can arrive as raw HTML: words plus tags for headings, paragraphs, links, lists and styling wrappers. The reading step removes the markup noise while preserving the words and structure.

    That is “cleaning the HTML.” We are removing the packaging, not the article. The tags still matter: a heading announces a section, a list groups items, and a link identifies a destination. Good HTML carries meaning. Bad HTML creates boxes that look right but say little about what they are.

    Accessibility is the closest thing to an agent-ready standard

    Here is the practical money line: the work that makes a website easier for a blind person to use also tends to make it easier for an AI browser agent to use.

    Browsers build an accessibility representation from the page’s Document Object Model. Assistive technology uses it to understand roles, names, states and relationships: this is a heading, that is a link, this button is named “Save contact,” and this checkbox is checked.

    Muse’s browsing side is reported to rely heavily on this kind of page structure, along with visual observations when needed. Meta does not publish a complete specification for the Muse browsing pipeline, so treat that as a field report from using the product, not permanent platform documentation.

    The implication is still solid. Use real buttons with useful names. Label form fields. Put headings in a sensible order. Give links meaningful text. Preserve keyboard focus. Describe informative images.

    A screen-reader user needs those things. So does a browser agent working without human intuition. Accessibility and agent-readiness are not identical, but they are close cousins.

    HubSpot shows what an agent-native application could be

    Imagine HubSpot—or any software platform—shipping an interface designed for assistants to navigate with less friction. It would not need a blank, text-only clone. It could make the existing product more legible to software: real controls with specific names, labeled form fields, clear headings and landmarks, properly identified table headers, programmatic state changes, and no critical action hidden behind hover or an unlabeled icon.

    That is an agent-native site. It is not a secret internet for bots. It is a website or application whose meaning survives when the visual layer is translated into structure and words.

    The same work also helps keyboard users, screen-reader users, automation tools and QA teams.

    llms.txt is a map, not a second website

    The closest public convention aimed directly at AI readers is llms.txt. The proposal describes a Markdown file, usually at a site’s root, that gives language models a short explanation of the site and links to important pages or cleaner Markdown versions.

    Think of it as a curated map: here is what we do, here are the pages that matter, and here is where to find the details.

    It cannot repair an unlabeled checkout button. It does not replace accessible HTML, describe the viewport or guarantee that an assistant will use it. Add it if it helps explain the site. Do not mistake it for an agent interface.

    What a site owner can change Monday morning

    The useful changes are ordinary, testable website work.

    1. Write a real title and meta description. Name the subject plainly.
    2. Put every money fact in visible HTML text. Price, specifications, shipping, availability and guarantees should not live only inside graphics, video or a brochure.
    3. Use semantic HTML. Use headings for headings, buttons for actions, links for navigation and labels for form controls. A styled <div> may look like a button while remaining a nameless container to other systems.
    4. Write alt text that carries meaning. Describe what an informative image contributes. Mark decorative images as decorative instead of stuffing them with keywords.
    5. Add accurate structured data. Product and Offer markup can identify price and availability. FAQ markup can describe genuine questions and answers. Schema must match the visible page.
    6. Server-render critical content when practical. If the offer, price or primary action appears only after a fragile JavaScript sequence, some readers and tools may miss it.
    7. Give each landing page one job. One offer, one explanation and one primary action reduce ambiguity for people and agents.
    8. Test the nonvisual path. Use the keyboard, inspect the accessibility tree, try a screen reader and pull the page through a text extractor. Do the product, price, proof and next step still make sense without styling?

    None of this requires uglier design. It requires the design and the underlying structure to tell the same story.

    This is a field report, not a permanent specification

    This article describes Meta’s Muse as it works today, based on direct experience building and operating websites with it. It is not a published Meta protocol.

    Claude, ChatGPT, Gemini and other assistants broadly rhyme with this pattern, but the details differ. Their full pipelines are not public, and they are changing quickly.

    Cleaner HTML will not automatically increase AI citations tomorrow. Citation systems involve discovery, retrieval, ranking, trust and answer construction. There is no magic switch.

    The immediate opportunity is closer to the customer. Someone sees your ad on Threads or Facebook, opens the landing page, then asks an assistant: “What does this cost?” “Is the guarantee real?” “How does this compare?” or “Can you sign me up?”

    If the facts are clean text, the assistant can explain them. If the controls are properly labeled, the browser side has a better chance of completing the task. If the facts live inside an image and checkout uses unlabeled custom controls, the assistant has to guess, fail or hand the job back.

    That moment is already here.

    The next website has two front doors

    The site of the near future has two front doors: one for eyes—layout, color, photography and brand—and one for agents—clean text, meaningful structure, explicit facts and self-identifying controls.

    They should lead to the same place. The visible price and schema should agree. A button’s label and accessible name should agree. The page should remain understandable without styling and usable when a browser worker operates it.

    That is not a special Muse landing page. It is a better website—one that keeps working when the visitor brings an assistant.

    Build both front doors.

    Sources and further reading

  • The Working Years — Episode 2: The Lantern Principle

    The Working Years — Episode 2: The Lantern Principle

    The Working Years is a series drawn from my own archive — posts I wrote years ago, given the room to become the articles they were trying to be.

    The seed

    On July 26, 2025 — the 27th in the archive’s UTC clock — I posted this to my @willtygart account, the one I later deleted:

    “The new gold isn’t answering the questions people ask. It’s illuminating the ones they can’t yet vocalize.”

    It went up at 10:24 PM Pacific, two minutes after a sibling post that linked the Native Data essay: “Being the closest store gets you noticed. Speaking the local language gets you chosen.” Two posts, two minutes apart, one night. The Lantern essay names the Oxxo Principle — being the closest store — as the first layer; no Oxxo essay survives in the archive, but the idea lived on as the tagline of the Native Data post. Two essays got their own subdomains: the Native Data Principle and the Lantern Principle. The Lantern one carried the title “The Lantern Principle: The Final Layer of SEO.”


    What happened afterward

    Within days, the Lantern post had become a full essay. The earliest surviving capture is July 30, 2025 — four days after the post — and it’s already complete: the hero, the comparison, the four-step method, the whole thing. So the thinking wasn’t new on the 26th. The post was the tip of something I’d already worked through.

    Here’s what’s worth noticing about that July burst. The two posts that night were one idea unfolding in layers:

    1. The Oxxo Principle — “Being the closest store gets you noticed.” Proximity. Be there.
    2. The Native Data Principle — “Speaking the local language gets you chosen.” Relevance. Speak like the customer.
    3. The Lantern Principle — the final one. Anticipation. Light the path they can’t describe yet.

    Be there. Speak their language. Then — the hardest one — see the problem they can’t articulate and hand them clarity anyway.

    The subdomains are offline now. The essays survive only in the Wayback Machine. That itself is a small footnote about rented space versus owned space, which is a different episode. The point for this one: the idea outlived its hosting. It turned out to be early, not wrong.

    Because look at what the web became. The AI assistant era made the Lantern Principle the default shape of a good answer. When someone asks a chatbot a question now, the good systems don’t just answer — they anticipate. They offer the next step, the related consideration, the thing the user was really getting at. “What is the underlying problem they are trying to solve?” — that’s not a 2025 content strategy anymore. It’s how the good ones behave now. The principle went from marketing theory to product behavior in about a year.


    The piece itself

    Here’s the essay as it ran, cleaned up from the archive — I haven’t rewritten it, just given it the room it was always asking for.


    For decades, we treated content as a reactive tool. A user asks, we answer. Simple transaction. But that model assumes the user knows what to ask. When they don’t — and they often don’t — they get stuck. They bounce. They stay frustrated.

    Consider the difference:

    Answering the question: “How do I change a tire?” → “Here are the 5 steps to change a tire.”

    Illuminating the path: The person’s unspoken reality is “I’m stranded and stressed.” So the answer becomes: the 5 steps, plus safety precautions, plus a link to 24/7 roadside assistance, plus how to check the spare’s pressure. Nobody searched for those extra things. Everybody needed them.

    The greatest opportunity in content isn’t in the keywords people search for. It’s in the needs they can’t yet articulate. The new gold is found in the dark — in the space between a user’s problem and their ability to ask for a solution.

    This is the Lantern Principle: stop being a dictionary, start being a guide. Our job is no longer just to provide answers but to anticipate needs — to create content that doesn’t just solve the stated problem but illuminates the entire context around it, guiding the user to clarity and confidence.


    How to build a lantern

    The shift is from keyword research to empathy mapping. The operative question changes from “What are people searching for?” to “What is the underlying problem they’re trying to solve?” Four moves:

    1. Answer the unasked question. Someone searching “how to write a resume” is really asking “how do I get a better job?” Serve both. Resume templates and the interview tips and the career planning resources. The stated query is the door; the unasked question is the house.
    2. Provide the next step. Never let content be a dead end. Every article should lead naturally to the next logical step in the user’s journey. A product page links to its user manual. A tutorial links to the advanced technique. If you end at the answer, you’ve ended too early.
    3. Simplify the complex. The ultimate act of empathy is taking a complex, intimidating topic and making it simple — analogies, plain language, visuals that actually explain. This is what builds the trust that makes you the go-to source.
    4. Create foundational resources. Build definitive, comprehensive guides — “digital lanterns” — that cover a topic so thoroughly they become the starting point for anyone exploring it. These serve thousands of unasked questions over time. They compound.

    The goal: a web that feels less like a vast, cold library and more like a network of helpful guides, each holding a lantern. An internet that doesn’t wait for the perfect query but proactively offers clarity.

    The future of content isn’t about being found. It’s about shedding light.


    Why this one aged well

    I want to be honest about what this principle got right and what it didn’t.

    What it got right: anticipation is the real moat. Everything I wrote about SEO in 2025 assumed the user arrives with a query and the job is to match it. The Lantern Principle was me noticing, before I had the language for it, that the highest-value content serves the need behind the query — and that AI systems would eventually do this natively. When an assistant now reads between the lines of a question and offers what you actually needed, that’s the Lantern Principle running as software.

    What I understated: how hard anticipation is to fake. A lantern only works if you genuinely understand the person in the dark. The four moves above are easy to write and hard to do — because “answer the unasked question” requires you to actually know people, not just their search terms. Every content farm can optimize for keywords. Very few can hold the lantern, because it requires the one thing that doesn’t scale: empathy for a specific human being stuck on a specific problem.

    That’s also why this principle pairs with the one from Episode 1. In the 23-model experiment, I learned that scope — who the reader is, what they actually need — matters more than the prompt. The Lantern Principle is scope taken to its conclusion: know the reader so well you can answer what they haven’t asked.


    The restoration version

    I run a niche agency for restoration contractors, so let me ground this where it hurts.

    A homeowner never searches “I need emergency water mitigation with proper psychrometric documentation for my insurance claim.” They search “water under sink” or they call because the kitchen smells weird. They are stranded and stressed, and they cannot vocalize the real need: someone who will stop the damage, document it so insurance pays, and explain what’s happening in plain language.

    The restoration company that answers the stated query — “yes, we do water damage” — is the dictionary. The one that anticipates — shows up, explains the process before the adjuster calls, hands the homeowner a clear next step at every stage — is the lantern. Guess which one gets the review, the referral, and the adjuster’s trust.

    That’s not a marketing insight. It’s an operating insight. The companies winning in restoration right now are the ones whose process illuminates the path, not just their website.


    Related from the series

    • Episode 1: We Ran 23 AI Models on the Same Article. The Prompt Was Never the Point. — scope beats the prompt; knowing the reader beats optimizing the query.
    • The Native Data Principle — speaking the local language gets you chosen. The middle layer of the trilogy.
    • The Oxxo Principle — being the closest store gets you noticed. The first layer, named in both essays; no Oxxo essay survives in the archive.
    • Stop Renting Space. Start Owning Your Content. — on why the essay subdomains being offline is a footnote, not a funeral.