Tag: SEO

  • What Is an Old Page Telling You When It Starts Getting Cited Again?

    What Is an Old Page Telling You When It Starts Getting Cited Again?

    Everybody talks about AI citations like they’re weather. Somebody reads somebody else’s report, shows you a screenshot of a ranking, and that’s supposed to mean something.

    A screenshot is a rumor. I wanted a count.

    So we built what I call the bait board. It’s simple: every page on this site is bait. A “bite” is when an AI answer — Bing’s, in our case, because that’s where we pull the data — cites one of your pages. If you can’t count it, you can’t improve it. The board counts it.

    The board, as of this week

    Over the last six months, Tygart Media has pulled in roughly 1.6 million AI citations. Across the two six-month windows we’re comparing, 997 distinct pages have been cited. 870 of them are biting right now.

    One page does most of the heavy lifting: our Claude AI pricing page, at 1,388,909 citations. That’s not a typo. That’s what happens when a page becomes the answer to a question a lot of people ask every day.

    Every page on the board lands in one of four buckets:

    • DEFEND — 945 pages. Biting now. Somebody out there thought it was good, and an AI keeps handing it out as the answer. You protect these. Iterate in place, never rename them, and check whether you’re still holding the seat — because a citation is a seat, and nobody holds your seat for you.
    • RE-BITE — 52 pages. Proven bait that went quiet. They were cited, then they weren’t. Sometimes a competitor wrote the Costco-hat answer with the glasses and the supply chain added on, and took the seat. Sometimes the page just went stale. Either way: patch it in place and cast again.
    • SOAK — 121 pages. Published, no bite yet. Let compounding do its work. Not everything needs touching.
    • PRUNE — 61 pages. Never picked up. Stop feeding them.

    The data comes down every night — three CSVs out of Bing Webmaster Tools: AI Performance, grounding queries, and pages, six-month window. I download them by hand on purpose. Don’t automate yourself out of this stuff. When you pull it yourself, you notice the weird one. You click through. You find something.

    And the method matters more than the tool. It’s the tactic, not the tool — everybody’s tools are calculators. Whatever way you do this, do it the same way every time, because the delta is the information. Change your method every week and you’ll never know whether the number moved or you did. I used to look at this every 28 days. The world doesn’t run on 28 days anymore. Clarity defaults to three days, and honestly, three days is about right now. I check daily. I’m scared not to.

    But here’s the thing I actually sat down to teach this week, and it’s the thing the board taught me — three patterns I can only see because the count runs every night.

    Pattern one: the fastest source is not the cited source

    Look at the dead bait. A big share of it is our timed storm watches — the automated storm updates that publish as weather moves through a part of the country, update, and expire.

    They almost never get cited by Bing. Almost never.

    I think I know why. When the moment passes and the engine settles on an answer, it doesn’t cite the quickest source. It cites the original, the best source. On a storm, we’re the quickest source there is — we’re built for speed, the update is live while it’s still raining. But quick is not the same as best, and after the fact, Bing goes back and picks the best. That’s not us, and on a timed watch it was never going to be us.

    That doesn’t make the storm work useless — it feeds other sites of ours, and being first matters in other places. But if you’re measuring it by Bing citations, you’re grading a sprinter on a marathon course. Know which race each page is running.

    Pattern two: a good article that dies at three weeks usually died in the title

    The other thing I see on the board: solid articles — some of them op-ed pieces I’m proud of — that come up on three weeks old and fall off a cliff. Not bad articles. Articles that never made the first pass.

    When I look at those, it’s the title. The title didn’t tell the engine, or the reader, what question this page answers. So it never got picked up in the first place, and by week three there’s nothing left to defend.

    The fix isn’t rewriting the whole piece. The fix is two moves:

    1. Retitle it so it answers the actual question in the words people ask it.
    2. Give it something evergreen inside — a chart, a reference block, a section that stays true after the moment passes. An op-ed with an evergreen chart in it has something durable to be cited for. A storm piece with a standing reference section — what a project manager does when this kind of storm hits, say — has a reason to exist after the rain stops.

    Timely gets you published. Evergreen gets you cited. A piece that only has the first one is on a three-week clock whether you know it or not.

    Pattern three: old pages that bite again are sensors

    This is the one that changed how I run the board.

    Months ago, out of our Everett work, we wrote about a Boeing contract — the SPIA contract. Old news. Done. Except it isn’t: that page keeps showing up. It keeps getting cited.

    My first instinct, months back, would have been to call that noise. It’s not noise. It’s a sensor going off.

    If an old page starts biting again, it means the world came back to that topic and there wasn’t much else there. Thin coverage. We saw the same shape on one of our other properties — a sustainability piece about cosmetics CEOs that narrowed down, over time, to two or three companies actually doing the thing. The page didn’t change. The field did, and the page was the instrument that showed it.

    Think about it the other way: say we wrote up an Everett AquaSox game a while back, and one of the kids in that game makes a World Series roster in a year or two. That old game page could light up again — and when it does, it tells you something is happening before the crowd writes about it. The re-bite is the first inkling. A disturbance, if you’ll forgive the reference.

    So I’ve stopped treating old pages as prune candidates by default. Some of them aren’t content anymore. They’re instruments. You don’t throw away a gauge because it’s been quiet — the quiet is the baseline, and the spike is the signal. A re-bite on an old page is market intelligence, and it’s free: the page is already written, already out there, already costing you nothing to leave in the water.

    Prune still exists — 61 pages earned it. But before a page goes in that bucket now, it gets one more question: is this dead, or is this a sensor that just hasn’t gone off lately? Those are very different things to delete.

    The seat, and keeping it

    Here’s the whole doctrine in one breath: get cited and you’ve taken a seat. Leave, and someone’s sitting in it when you come back. The engines don’t owe you the chair. So you count — nightly, same method, same window — and you sort every page into defend, re-bite, soak, or prune, and you listen to the old pages, because they’re telling you where the world is thin.

    That’s the bait board. It isn’t fancy. It’s three downloads, four buckets, and the discipline to do it the same way tomorrow.
    AI Citation Quick-Scan, $97 — Tygart Media runs your pages through the Bait Board count: which pages AI answers cite, which went quiet, which are sensors

    If you want to run this yourself

    I teach this in layers, same as everything else we sell:

    • The Bait Board one-pager (free PDF). The four buckets, the three nightly downloads, and the counting rules on one page. Print it, tape it over your desk, start counting.
    • The Bait Board Field Guide ($7 PDF). The full method: how the six-month window works, how to read fresh bites against dropped pages, the churn math, and the sensor test — how to tell a dead page from a quiet instrument before you prune it.
    • The Bait Board, Book-for-Bots edition ($17). The method written for the machines as much as for you — structured so an AI assistant can run the nightly sort with you: bucket definitions, decision rules, and the worked examples from this site’s own board, including the storm-watch and three-week-title findings above.
    AI Search Visibility Package product card — $450 standing citation-board practice for business websites, from Tygart Media

    And if you’d rather have it done with you: the AI Citation Quick-Scan ($97) is where we run your pages through this same count and hand you the board; the $450 tier builds the board into a standing weekly practice on your site; and the $2,250 tier is the full desk — board, refresh queue, and the sensor watch running as a system. Same ladder we run here. The count comes first either way.
    AI Search Visibility Package product card — $2,250 complete bundle: citation board, refresh queue, and old-page sensor watch run as a system, from Tygart Media

    Start with the count. Everything else is commentary.

    — Will
  • Split the Panel: Brand Prompts and Non-Brand Prompts Are Two Different Tests

    Split the Panel: Brand Prompts and Non-Brand Prompts Are Two Different Tests

    Your AI visibility report says you were cited 118 times last month. Good month or bad month?

    You can’t tell — because that number blends two different tests into one score, and the two tests fail for opposite reasons.

    PressGEO ran a rolling 30-day probe — 1,000 prompts, window ending November 8, 2026 — and published the split most dashboards never show. On the 357 prompts that named the brand, the domain was cited 118 times: a 33.1% citation rate. On the 643 prompts that didn’t name it — the category questions, the discovery questions, the “best tool for X” questions a stranger actually asks — the count was zero. Not low. Zero.

    One blended number for that month reads 11.8%, and it is useless. It can’t tell you whether the engine can’t find you or won’t choose you. Those are different problems with different fixes, and rewriting pages — the default response to a bad visibility number — only addresses one of them.

    Two gates, multiplied

    A citation is a conditional probability with two terms. First the engine has to retrieve you: your domain has to enter the candidate set at all. Then it has to absorb you: pick your page as evidence for the answer. Citation rate = retrieved × absorbed. Dashboards measure the second term obsessively — position inside the answer, share of voice, sentiment — and almost never estimate the first.

    Brand-named prompts mostly test the first gate under easy conditions. When someone types your name into the question, the engine barely has to discover anything; if your site is indexed and reachable, your pages walk through. Non-brand prompts test the real contest: a question with no name in it, where your page competes against every other page the engine could ground on. Fail the first gate there — never retrieved — and nothing about your page’s quality matters, because the page was never in the room.

    That is what PressGEO’s zero means. Not “their content was slightly worse.” The domain never got retrieved on discovery questions at all. No rewrite of any single page fixes a retrieval absence; rewriting is an absorption tool.

    What each failure actually needs

    When the brand panel is healthy and the non-brand panel is empty, the problem is upstream of your prose:

    • Coverage of the question, in the asker’s words. Non-brand retrieval runs on whether you have a page that plainly answers the category question someone typed. One real question per page, in the words the asker used — not your service-page vocabulary.
    • Presence where the engine looks. Engines ground on third-party surfaces too. A brand that exists only on its own domain has a thin retrieval footprint.
    • Structure the passage can be lifted from. Clear headings, a direct answer near the top, facts stated in plain sentences. Retrieval picks passages, not vibes.

    When both panels retrieve you but citations stay low, the problem is absorption, and now page work is the right tool: sharper answers, better evidence, statistics and sources on the page, the passage that says the thing most citable-first.

    The fixes are not interchangeable. Splitting the panel is how you know which one you’re buying.

    Our own board, read the same way

    We run a version of this on our own site. Microsoft’s AI Performance export for tygartmedia.com, two overlapping six-month windows compared on the board we rebuilt today: 997 distinct pages cited across the windows, 870 of them cited in both — and 135 pages cited on the latest day alone. The split that matters for operations isn’t the total. It’s that 52 previously-cited pages went quiet while 75 fresh pages got their first bite. The quiet 52 are an absorption-and-freshness problem, page by page. If the fresh-bite count ever fell to zero while the old pages kept biting, that would be the opposite diagnosis — a discovery failure — and the response would be new coverage, not rewrites.

    Same ledger, two columns, different work. That’s the whole discipline.

    The denominator rule

    One more discipline from the same GeoAura write-up, and it’s the one that saves you from chasing ghosts: version your denominator. Foglift’s per-answer citation count moved from 6.03 to 5.8 between its October 24 and November 8 cuts of the same report — not because any engine changed, but because the measurement window lengthened. A dashboard that doesn’t date-stamp its denominator will manufacture a trend out of a longer window, and someone will rewrite a page to fix arithmetic.

    Run it this way

    1. Fix your prompt set, then split it before you score it. Brand-aware prompts in one panel, category and discovery prompts in the other. Same set every week.
    2. Record retrieved / not-retrieved separately from cited / not-cited. The retrieval gate is a yes-no column: did any URL from your domain appear at all?
    3. Diagnose by panel, not by blended score. Brand strong + non-brand empty = retrieval work: coverage, presence, passage structure. Both retrieving + few citations = absorption work: evidence and answer quality on the page.
    4. Date-stamp every denominator. Window, prompt count, and engine mix ride along with every number you keep.
    5. Don’t rewrite on a one-week move. Panels are noisy week to week; act on the pattern across a month.

    PressGEO’s zero is the cleanest possible illustration: 643 chances, no retrieval, and no amount of polishing the pages would have changed it. Split the panel first. Then fix the gate that’s actually failing.

    Source: PressGEO probe results as published in GeoAura, “How to Measure GEO Visibility: Metrics & Methodology,” updated November 9, 2026 (nextaura.me). Board figures: our own Bing AI Performance export comparison, rebuilt November 9, 2026.

  • How AI Search Visibility Is Actually Tracked (and What the Tools Can’t See)

    How AI Search Visibility Is Actually Tracked (and What the Tools Can’t See)

    Here’s how AI search visibility is honestly tracked: you write down the actual questions your customers ask, you ask those same questions in the actual answer engines on a fixed schedule, and you record three things separately — whether the answer names you, whether it cites you, and whether what it says about you is true.

    That’s it. Everything else — dashboards, scores — is packaging around that habit, or a substitute for it. And there’s a problem worth understanding before you buy a substitute: ranking and being cited are not the same event, and a tool that conflates them will mislead you without making a number up.

    Ranking is not being cited

    Start with the structural fact. Search the old way and you get a ranked list of pages. Ask an answer engine — Copilot, ChatGPT, Perplexity, the AI box atop Google — and you get a paragraph, written on the spot, with a handful of sources cited beside it.

    Those two events are only loosely connected. A page can sit at position two in the organic list and never get quoted, while a competitor at position four gets built into the answer. It isn’t a glitch: the engine doesn’t summarize the top result. It breaks your question into smaller sub-questions, looks for material on each, and assembles an answer from what it finds — and studies of cited URLs find just a small minority come from the organic top ten.

    So rank-based tracking measures the list while your customers read the paragraph. That’s the gap where businesses get surprised: “we rank fine, why is the machine recommending somebody else?” The events that matter are being named, cited, and described correctly. For the basic method as a straight answer, see how do you measure AI search visibility. This piece covers the part usually skipped — the limits.

    The only honest method: fixed questions, three separate records

    The method fits on an index card. Build a list of the questions your customers actually ask — not keywords, questions, in their words: “Who fixes a flooded basement in Tacoma?” “What does water damage cleanup cost?” Twenty or thirty is plenty. Then, on a fixed schedule — weekly is honest, monthly the floor — ask them in the engines your customers use, and record what comes back.

    The recording is where honesty lives or dies, because one answer contains three different facts:

    • Mentions. Does the answer name your business at all? Not link, not cite — name. The customer reading that paragraph sees your name or a competitor’s.
    • Citations. Does the engine cite your pages as sources? You can be named with no citation, and cited without being recommended — quoted as background while somebody else gets the call.
    • Accuracy. What does the answer say about you, and is it right? Engines repeat stale facts and invent new ones with total confidence. An answer describing a service you stopped offering two years ago is not a win — it’s a wrong sign on your door.

    Three columns, kept apart. Any tool worth paying for just runs that without the handwork — and the moment one blends those columns into a single number, it throws away the only details you’d ever act on.

    What tracking can genuinely see

    Done this way, tracking earns its keep. Four things it shows straight:

    • Trends on fixed questions. Same questions, same schedule. When your name starts appearing in answers it wasn’t in, that’s real movement — usually tied to work you did.
    • Which pages get cited. Not which pages rank — which ones engines actually pull from. In our own work, a few pages carry a large share of the citations.
    • Share against named competitors. Record who gets named when you don’t, on the same question set.
    • Answer drift. Ask the same question next month and the answer is different: a new source, a dropped name. Drift is normal — and why a one-time check is worth little.

    What no tool can see

    Now the part that doesn’t make it into the sales deck: five things no tracker — ours, theirs, anybody’s — can show you.

    The answer your actual customer got

    Answers vary by who’s asking, where they are, and when they ask — the same question can name different businesses for two people in the same town on the same afternoon. A tracker sees a sample, from its own accounts, and a sample is not the population. Anyone presenting a report as a census of what your customers saw is overselling the instrument.

    The questions nobody thought to ask

    Your prompt list is a map, and the map is not the demand. Customers ask things you’d never predict — oddly specific, half-wrong, mid-emergency questions typed one-handed at 2 a.m., some the most valuable in your market because the person asking is ready to buy. If it isn’t on your list, your tracker never asks it. The fix isn’t a bigger tool — it’s refreshing the list from real life: call recordings, intake notes.

    Why the engine picked a source

    No engine publishes its citation reasons. A tracker can tell you a page got cited, never why that page and not yours — anyone who claims otherwise is guessing and charging for the guess. What you can do is compare: read the cited page next to yours. Does it answer in the first paragraph, state facts plainly enough to quote, is it current? That’s judgment, not telemetry.

    What the answer caused

    Attribution stops at the answer. The engine doesn’t report back that the homeowner who read its paragraph called you, called the other company, or fixed it themselves — those calls are invisible to every visibility tool ever built. The last mile shows up only in your own books, so report and call log get read side by side before anybody claims the visibility did anything.

    Engines that don’t show their answers

    Some surfaces can’t be sampled at all — answers behind logins, in apps, in voice assistants. A tracker reports on the engines it can reach and has nothing on the rest. Ask any vendor which engines their number doesn’t cover.

    The score problem

    Which brings us to the product most buyers are actually being sold: a single visibility score. One number, proprietary formula, up and to the right in the demo. The trouble isn’t that it’s fake — it’s what it has to compress to exist.

    Run a small example. Over a quarter, a business gets mentioned in more answers and cited more often too. By any blended formula the score rises, and the quarterly report is a celebration. But read the accuracy column, the one the score dissolved: the engines now describe the business as offering a service it dropped last year, at a price it no longer charges, because an old page still says so. Customers call with wrong expectations, and staff spend five minutes a call correcting the internet.

    Score up. Facts wrong. Both true at once — and only one shows up in the report the owner paid for. A blended number turns three actionable facts into one feeling. A score that rises while the answer about your business is wrong isn’t measuring your visibility. It’s measuring its own smoothness.

    What to demand instead

    You don’t need to become a measurement expert. Ask for four things, and watch whether the seller can produce them.

    • Your prompt list, built from real customer questions — and shown to you. Generic questions make generic tracking.
    • The raw answers, kept. Not a screenshot of the best week — the actual paragraphs, so anything in the report traces back to a readable answer.
    • The three records, kept separate. Mentions, citations, accuracy — three columns, never one blended score. If a summary number exists, it sits on top of the columns, not instead of them.
    • Figures you can re-pull yourself. Where engines expose their own numbers — Bing Webmaster’s AI Performance reports, Microsoft Clarity — those live in accounts you own, and any figure from them can be checked by you, in your login. Hold every report to that standard: see the best agency for AEO SEO reporting is the one whose numbers you can re-pull, and our page on what an AI visibility report should show lists the sections to expect. An unverifiable report is a story you’re being told.

    Measurement, done honestly, is a flashlight, not a scoreboard. It shows you where to work next — which question you’re absent from, which fact about you has gone stale. The moment the measurement becomes the product being sold, it stops measuring your business and starts measuring itself. Run the fixed questions. Keep the three columns. Read the actual answers.

    Questions buyers ask us

    How do AI visibility tools work?

    At bottom, every one of them does what you’d do by hand: asks a fixed list of questions in the answer engines, on a schedule, and records what comes back — who’s named, who’s cited, what changed. The honest ones keep the records separate and show you the raw answers; the expensive-looking ones blend everything into a proprietary score. Either way, all of them see a sample — never every answer a customer received.

    Why doesn’t my Google ranking match my AI mentions?

    Because they’re different events. Ranking is your position on a list of pages. A mention is whether an answer engine names you in a paragraph assembled from its own sub-questions — whose cited sources overlap the organic top ten only a little. You can rank second and go unnamed while a competitor at fourth gets quoted — and tracking only the list keeps that gap invisible.

    Can I track AI visibility myself?

    Yes — the basic version is genuinely do-it-yourself. Write down twenty or thirty questions your customers actually ask, put them to Copilot and ChatGPT, and record three things: named, cited, accurate. Repeat monthly, same questions, and check the figures the engines give you in Bing Webmaster and Clarity, in your own accounts. An afternoon to start, an hour a month to keep. What you’re paying for, if you pay, is never skipping the month.

  • An AEO Report You Can Re-Pull: A Worked Example

    An AEO Report You Can Re-Pull: A Worked Example

    A report you can trust is a report you can re-pull. Every figure in it traces back to a source you own — your own Bing Webmaster account, your own Microsoft Clarity account — so checking the work takes an afternoon, not an act of faith.

    I have argued before that the best agency for AEO SEO reporting is the one whose numbers you can re-pull. That is the standard. Our page on what an AI visibility report should show lays out the requirements. This piece is the missing third thing: the artifact itself. What follows is one monthly report, walked section by section — what each section shows, where each number lives, and how you would re-pull it yourself to check it.

    One disclosure before the numbers. This is a worked example. The business is a regional restoration company, the kind of outfit that answers the phone at 2 a.m. when a pipe lets go. Identifying details are changed, and the figures are a composite drawn from real reporting periods — not one client’s month dressed up as gospel. The sections, though, are the real sections, in the real order, and every figure in every section has a home in an account the client owns and can open without asking me.

    1. The ledger summary

    The first page is the whole story in one table: how many times the answer engines cited this business in the period, set against the period before. Nothing else. No score, no grade, no wall of arrows.

    Measure This period Last period Change
    Total citations 1,184 1,021 +16%
    Queries where the business was cited 214 187 +27
    Pages cited at least once 38 34 +4

    Where the numbers live: the overview export in the AI Performance section of Bing Webmaster Tools. The client logs into their own account, picks the same date range printed at the top of the report, downloads the CSV, and the headline citation count is sitting right there. Re-pulling this section takes about four minutes. If the number in the report and the number in the export disagree, the report is wrong, full stop — and the client found that out from their own account, not from a call with me.

    2. Share on the queries that pay

    A citation total by itself is a vanity number wearing a suit. What matters is which questions the citations hang on. This section lists the money questions — the ones a buyer asks an answer engine right before picking up the phone. For a restoration company, that is things like “water damage cleanup near me,” “how much does mold remediation cost,” and “who do I call for a burst pipe.” Next to each question: whether this business got cited for it, and who else did.

    Where the numbers live: the Search Queries export, same Bing Webmaster AI Performance section, same date range. Re-pull it, look up the questions that matter to the business, and the cited sources are listed per query. This is the section owners actually read, because it reads like the market itself. You can watch a competitor take a question you used to own, in plain text, with nobody’s opinion layered over the top of it.

    3. Page movers

    Citations land on pages, not on businesses. This section lists the pages that gained citations in the period and the pages that lost them, biggest moves first. A service page that doubled its citations after a rewrite. A location page that went quiet. A post from two years ago that an engine suddenly started quoting.

    Where the numbers live: the Page Stats export, same account, same date range, compared against last period’s export — which is why we keep every month’s files. Re-pulling means downloading the current export and setting it against the file from the prior period. The “why” written next to each mover is our read, and it is labeled as a read. The movement itself is not an opinion. It is in the client’s own files.

    4. New questions

    Every month, the query export contains questions that were not in it before. Somebody asked an engine something new — a new phrasing, a new service name, a question nobody in the market has written a page for yet. This section lists those questions, flags the ones this business was already cited on, and marks the rest as gaps.

    They come straight out of the same Search Queries export. There is no separate tool and no secret feed behind this section. New questions are the demand moving, in public, in the askers’ own words. Half of next month’s content list is usually sitting right here — and the client can check that claim too, because the questions are in their export, not in my notes.

    5. The work, priced against the movement

    This is the section most reports skip, and it is the one that keeps everybody honest. On one side, what was actually done in the period, named plainly: three pages published, two pages rewritten, one round of technical fixes. On the other side, what moved. It is the measurement loop from the workstreams behind AI SEO services, printed instead of described — the work and the numbers on facing pages, where the client can judge whether one earned the other.

    Two rules govern this section. First, the work list is complete. The page that was published and went nowhere sits on it, right next to the one that took off. Second, no credit is claimed where the movement cannot be tied to the work. If citations rose on a question nobody touched, the report says so and calls it what it is: the market moved, or the engine changed its mind, and we do not know which. An agency that only shows you the wins is editing. Editing is the first step toward inventing.

    6. What the report refuses to show

    The last section is a list of absences, and it is there on purpose. There is no proprietary visibility score, because a score only the agency can compute is a number you can never check. There is no best-week screenshot, because a business runs on months, not on its best seven days. And the engines are never blended into one soup of a number. The Bing and Copilot figures come out of the client’s own Microsoft accounts; anything that cannot be pulled from a source the client controls is reported separately, with its method stated, or left out — with the report saying it was left out.

    Blending is a hiding place. A blended number can rise while the engine that actually sends you buyers is falling, and you would never see it. Separate numbers can be wrong, but they can be caught. That is the whole trade, and we will take catchable over impressive every time.

    The test

    Here is the one test you can run on any report from any agency, including this one. Pick a figure — any figure, the bigger the better. Ask one question: “Show me where this lives in my own accounts.” Then watch what happens. If you get walked to the export, the account, and the date range, and the number matches when you pull it yourself, you are looking at reporting. If you get an explanation of why the methodology is proprietary, you are looking at a story about reporting. The figure was never the product. The trail behind the figure is the product.

    Questions buyers ask

    What should an AEO report include?

    Five things: a citation total you can re-pull, your share on the specific questions your buyers ask, which pages gained and lost citations, the new questions showing up in the data, and the work done in the period set next to what moved. A report carrying a score you cannot recompute from your own accounts is missing the point, even if it has everything else.

    How do I check my agency’s numbers?

    Log into your own Bing Webmaster Tools account, open the AI Performance exports for the same date range printed on the report, and compare. The overview export checks the headline, the queries export checks the questions, the page stats check the pages. Microsoft Clarity is yours the same way. An agency should be able to tell you which export backs which figure, gladly. That conversation is the check.

    What is a red flag in an SEO report?

    A number with no trail behind it. Proprietary scores, blended engine totals, best-week screenshots, and rankings reported without the source account are all the same flag in different colors: a figure you are being asked to take on trust. Trust is fine in a relationship. It has no place in a spreadsheet.

  • AI SEO Services, Explained as Work

    AI SEO Services, Explained as Work

    When a customer asks Copilot or ChatGPT who to call, the machine names somebody. AI SEO services are the work that gets your business named: measuring what the machines say about you today, fixing what your site hands them, and publishing pages that answer real buyer questions clearly enough to be quoted.

    That’s the short version. The longer version matters, because “AI SEO” gets sold as a package, a plugin, or a monthly mystery. It isn’t any of those. It’s four kinds of work, done in order, by a person, on a schedule. Here’s each one, plainly.

    The baseline: finding out where you stand before touching anything

    The first job is a measurement job, and it’s unglamorous. Before anybody fixes or writes a thing, we find out what the machines currently say about the business.

    That means asking the machines the questions your customers actually ask — “who’s a good roofer in Puyallup,” “what does a water heater replacement cost,” whatever your buyers type or say out loud — and writing down who gets named. You, your competitors, a directory, nobody. We do it across the engines your customers use, and we save the answers word for word, because the exact wording is the evidence.

    Then we look at what your site currently gives those machines to work with. Sometimes the answers are wrong because the site is wrong: an old address on one page, a service you dropped still listed on another, the real expertise buried three clicks down under marketing copy. Sometimes the machines have simply never been handed a clean, quotable description of what you do.

    The baseline ends with a starting line: here’s who gets named today, here’s what the engines say about you today, here’s the list of what’s broken or missing. It isn’t exciting. But without it, every later claim of progress is a guess, and any report you get afterward is decoration. Nothing should get sold or fixed before this exists.

    Technical fixes: making the site readable to machines

    The second workstream is the one nobody sees, and it’s the reason content work fails when it’s skipped.

    Answer engines read your site the way a careful skimmer does: headings first, structure always. So the work is page structure — one clear topic per page, headings that are the actual questions buyers ask, answers that start with the answer instead of a paragraph of throat-clearing. It’s structured data where it helps: the behind-the-scenes labels that tell a machine this is a business, this is where it is, this is what it does, these are its hours. It’s crawl and indexation basics — making sure the pages that matter can actually be found and read, and the ones that shouldn’t compete are out of the way.

    And it’s the dullest fix of all: finding the pages that say two different things. Two service pages describing the same job differently. A location page the business left behind two moves ago. Machines average contradictions into mush, and mush doesn’t get quoted.

    None of this photographs well. There’s no ribbon-cutting for a corrected heading structure. But every page published on top of a site the machines can’t read cleanly is work poured into a cracked bucket.

    Demand-built content: pages from the questions buyers actually ask

    The third workstream is the writing — but it’s writing aimed at a specific target. We build pages from the questions buyers demonstrably ask, not from a list of keywords somebody brainstormed in a conference room.

    Real query data shows what people type and say when they’re close to spending money. It is rarely what the business would have guessed. Owners describe their work in trade language; buyers ask in kitchen-table language. The page has to be built in the asker’s own words, one real question per page, or the machine matching a question to an answer will walk right past it.

    Each page is written answer-first: the direct answer up top, in plain sentences, short enough and complete enough that an answer engine can lift it whole and attribute it to you. The detail, the caveats, and the proof go underneath for the humans who keep reading. That’s the whole trick, and it isn’t really a trick: the citation goes to the page that answers the question most cleanly.

    This is also where business owners should be careful about what they’re buying. A page written for a citation is a different object from a page written to rank for a phrase, and a different object again from a blog post written because Tuesday is blog day. When you’re vetting who’s going to do this work, there’s a test worth applying — we wrote up how we’d rate AI SEO services for small businesses by the test they should pass. And if you’re still working out which pieces of this you even need, that’s a separate decision from how the work runs; we laid that out in which AI SEO services are right for a small business.

    Authority and citation measurement: the loop that proves it

    The fourth workstream is the one that keeps the other three honest. On a schedule — not when somebody remembers — we ask the machines the same questions from the baseline and record who gets named now.

    Citation tracking against the baseline is what turns this from a hope into a measurement. A question where a competitor was named in March and you’re named in May is a moved needle you can point at. A page that got quoted for a while and then slipped is a fix-it item, not a mystery. The gaps that remain — the questions where nobody good gets named yet — become the next pages to build. The work feeds itself: measure, fix what slipped, build the next page from the next gap.

    Done as a standing service, this loop is the heart of it; it’s the work our AI Citation Service is built around. And it’s why the reporting matters as much as the work itself. A report that shows logins and impressions tells you nothing about whether the machines name you more than they did. We wrote about exactly what an AI visibility report should show — who gets named, for which questions, and how that changed since the last check.

    What the work is not

    Short and honest: it is not buying links. It is not stuffing keywords into pages until they read like a parts catalog. It is not a plugin somebody installs once and bills you for monthly. It is not a guarantee — anyone who promises you the machines will name you by a date is selling you a date, not work. The engines change how they answer, competitors publish too, and no honest person controls the outcome. What can be controlled is the work: measured, structured, published, and checked. That’s the part you’re actually buying.

    What to expect month to month

    If this work is running properly, the rhythm is boring in the best way. First you get a baseline — a written record of where you stand. Then a list of fixes, worked through in the open, most of them invisible to anyone but the machines. Then pages appear one at a time, each built from a real question, each one checked after it lands. And on a schedule, you get a report that shows movement: who the machines name now, for which questions, against where you started.

    That’s it. No fireworks, no mystery line items. Just the work, in order, with receipts.

    Questions owners ask us

    What does an AI SEO service actually do day to day?

    Checks what the answer engines say about your business, fixes the pages and structure those engines read, writes new pages that answer the questions your buyers are asking, and tracks whether the machines name you more over time. Most days it’s measurement and editing, not anything dramatic.

    How is AI SEO different from regular SEO?

    Regular SEO aims at a list of links — getting your page to rank where people click. AI SEO aims at the answer itself — getting your business named and quoted inside what Copilot or ChatGPT tells the asker. The technical foundations overlap heavily; the target, and how you measure success, are different.

    How long before AI mentions my business?

    Nobody honest can date it. It depends on where you start, how much is broken, and how active your competitors are. What can be promised is the sequence: a baseline you can see, fixes you can verify, pages you can read, and scheduled checks that show whether the mentions are moving. If they’re not, the checks are what tell you what to change next.

    Can I do AI SEO myself?

    Parts of it, yes. You can ask the engines the questions your customers ask and write down who gets named — that’s the start of a baseline, and it costs you an afternoon. You can fix the page that lists your old address. The parts that usually break down for owners are the schedule and the record-keeping: the checking has to happen every month, against the same questions, or there’s no measurement — just impressions. The work isn’t secret. It’s just work.

  • Can I Claim My Business in ChatGPT — and What Will It Actually Show Me?

    Can I Claim My Business in ChatGPT — and What Will It Actually Show Me?

    Short answer: no. Not today, and not because you’re behind. As of this writing, there is no public way to claim a business in ChatGPT. The claim page exists in exactly one place — a screenshot of an unreleased beta — and OpenAI has announced nothing: no launch date, no price, no list of countries, no help page. Anyone selling you a “ChatGPT claiming service” this week is selling you a screenshot.

    Here is what we actually know, where it came from, and the work you can do now so that when the door opens, you’re the first one through it.

    What was actually seen

    On November 6, 2026, Juozas Kaziukėnas — founder of Marketplace Pulse, an e-commerce research firm — posted a screenshot from inside ChatGPT. In the corner, in red: “unreleased/beta.” The page is headed “Claim your business in ChatGPT”, with a line underneath about unlocking a business agent and managing how your business shows up.

    The page makes three offers:

    • See how your business shows up — track how often your business is mentioned in ChatGPT conversations.
    • Show customers what you offer — add your latest products and keep your business information up to date.
    • Help customers make decisions — let a business agent answer questions using context you control.

    And one piece of fine print: you’ll need to verify that you’re authorized to represent your business.

    Kaziukėnas added the mechanics in his post. The tool measures impressions — the number of times a business appeared in ChatGPT responses — and clicks on links to the business’s website, tracked daily and shown as a chart. It sits inside a larger area called Business Hub. And it is only available to businesses that have verified their ownership — his example: “by connecting their Shopify store.” He also said the feature is a work in progress, that he saw its first steps as early as August, and that a banner he saw suggests it is getting close to launch. That last part is his inference, and it’s worth keeping labeled that way.

    Barry Schwartz covered the post the same morning at Search Engine Roundtable, and Search Engine Land and PPC Land followed the same day. Every one of those stories notes the same thing: OpenAI has not commented. This is one analyst’s view of an interface that has not launched. Details can change before it ships — if it ships in this form at all.

    What it would show you — and what it pointedly would not

    If the screenshot becomes a product, a claimed business gets a daily chart of two numbers: how often it appeared in ChatGPT answers, and how many people clicked through to its site. That’s real first-party data, and today it doesn’t exist anywhere for ChatGPT. Right now, the only way to know whether ChatGPT mentions your business is to ask it, repeatedly, and keep your own notes — which is exactly what we do in our own citation work.

    But Kaziukėnas is explicit about what the tool leaves out: no prompts, no user data, no competitor benchmarks, no rankings. Read that twice. You would see your mentions go up or down and have no way, inside the tool, to learn why. No record of the questions people asked when your name came up. No view of who else got named instead of you. A chart that moves without an explanation is a scoreboard, not a diagnostic — useful, but only paired with the outside work of tracking the actual questions.

    There’s a contrast worth naming here. The first-party AI-visibility console that actually exists today is Microsoft’s: Bing Webmaster Tools has an AI Performance section where we watch, for our own sites, which pages the AI cites and which questions ground on them. That one is live, free, and shipping real data now. OpenAI’s version of it is, today, a screenshot in a LinkedIn post. Plan against the tools that exist; be ready for the ones that don’t yet.

    The question nobody can answer yet: how does a service business verify?

    The only verification example on record is connecting a Shopify store. That works if you sell products through Shopify. A restoration contractor, a plumber, a law firm — a business whose “store” is a phone number and a service area — has nothing to connect.

    How would OpenAI verify that you own a local service business? A postcard, like Google’s old method? A document upload? A match against an existing Google or Bing profile? Nobody knows, because OpenAI hasn’t said, and no service business has been through it publicly. This is the single most important unknown for local businesses, and it’s the reason this article is a readiness piece instead of a how-to: the how-to cannot be written honestly yet.

    One more wrinkle, small but real. The screenshot’s fine print says you’ll verify that you’re authorized to represent the business. The reporting describes verifying ownership. Those are different tests, and the difference matters to any agency or consultant who would claim profiles on clients’ behalf — which is most of them. Which test OpenAI applies is another thing we find out at launch.

    What to have ready (all of it pays off today, too)

    None of the preparation depends on OpenAI. It’s the same discipline that earns citations on the surfaces that already exist:

    • One version of your facts. The same business name, address, and phone number, character for character, on your website, Google Business Profile, Bing Places, and every directory that matters. A verifier — human or machine — should find one business, not three near-matches.
    • Your existing profiles claimed and current. Google Business Profile and Bing Places are claimable today. Hours, services, service area, photos. If you haven’t claimed the doors that are open, the closed one isn’t your problem yet.
    • Pages that say plainly what you do and where. One page per service, in the words a customer would use to ask for it. This is what AI answers quote, with or without a Business Hub.
    • Your own mention log. Ask the major AI tools the questions your customers ask, on a schedule, and write down who gets named. When OpenAI’s chart exists, you’ll have your own baseline to check it against — and you’ll already know which questions you’re losing.

    When it opens

    The lesson from every previous claim system — Google Business Profile above all — is that early claimants get clean data and clean names, and latecomers get disputes. So: the week a “Claim your business” banner appears for real, claim yours, and verify with whatever method they offer a service business. We’ll do the same, and we’ll write up what the dashboard actually shows — the real numbers, the real verification path, and what it still won’t tell you — once we’ve been inside it ourselves.

    Until then: readiness is the whole job, and it’s the same job that gets you cited today. If you want to know how your business currently shows up across the AI surfaces that already answer your customers, that’s the first thing our $97 Quick-Scan reads — ChatGPT included, by hand, the only way it can be read until OpenAI opens the door.

    Sources: Juozas Kaziukėnas’s LinkedIn post (Nov 6, 2026); Search Engine Roundtable, “OpenAI Creating ChatGPT Tools For Business For Analytics & Citations” (Nov 6, 2026); Search Engine Land, “OpenAI testing business tools to track performance within ChatGPT” (Nov 6, 2026). OpenAI has not announced or commented on this feature; everything above about the tool itself traces to the screenshot and Kaziukėnas’s description of it.


    Want this thinking applied to your own business? Book a call with Will Tygart — 30 minutes, and we start from your receipts, not a pitch deck.

  • Receipts: One Week, 6,753 Bot Visits, Three Kinds of Bots

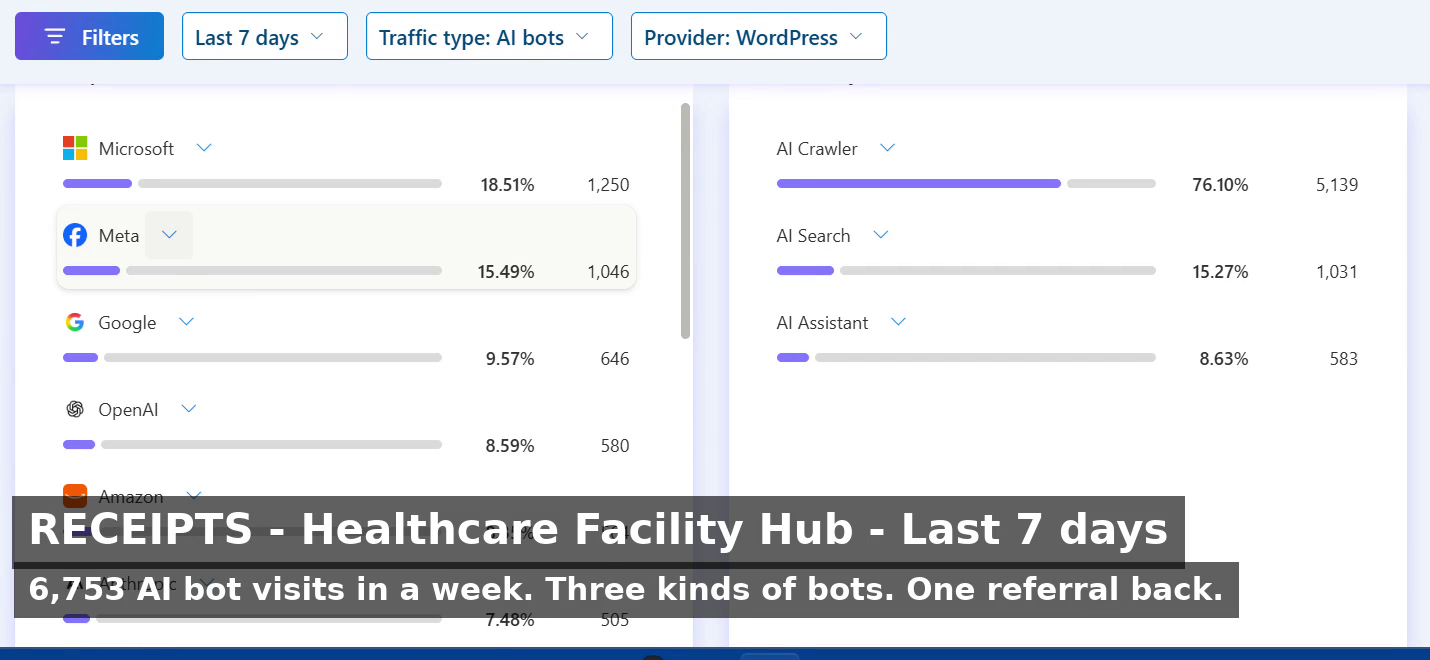
    Receipts: One Week, 6,753 Bot Visits, Three Kinds of Bots

    “AI traffic” sounds like one thing. On the dashboard it is three different things, doing three different jobs, and they are not interchangeable.

    Healthcare Facility Hub, last 7 days: 6,753 AI-bot requests. The operators alone are a crowd — Microsoft 1,250, Meta 1,046, Google 646, OpenAI 580, Amazon 564, Anthropic 505, Perplexity 444, Huawei 401, ByteDance behind them, and a tail that runs down to a single visit each from names most site owners have never heard of.

    Clarity sorts them by what they came to do. AI Crawlers made 5,139 of the visits, 76.10% — the index builders, reading everything so the models know it exists. AI Search made 1,031, 15.27% — bots fetching a page because somebody just asked a question: PerplexityBot 444 of them, plus Lyrenth and Parallel. AI Assistants made 583, 8.63% — browsing on behalf of a person mid-conversation: OpenAI 320, Anthropic 94, DuckDuckGo 17, Cohere exactly 1.

    The distinction matters because each kind wants something different from a page. A crawler wants it complete and clean. A search bot wants the answer findable in seconds. An assistant wants the page to make sense lifted out of context. One page, three readers, three jobs.

    And for all 6,753 visits, the scrape-to-referral ratio is 535:1. One referral came back all week. The most-wanted page on the site, by the way, is not the homepage — it is a field sheet, /email-my-field-sheet/, with 885 requests, 13.11% of everything the bots did.

    Ask for receipts.

  • Receipts: ChatGPT Read 375 Pages of One Site. It Sent Back 1 Visitor.

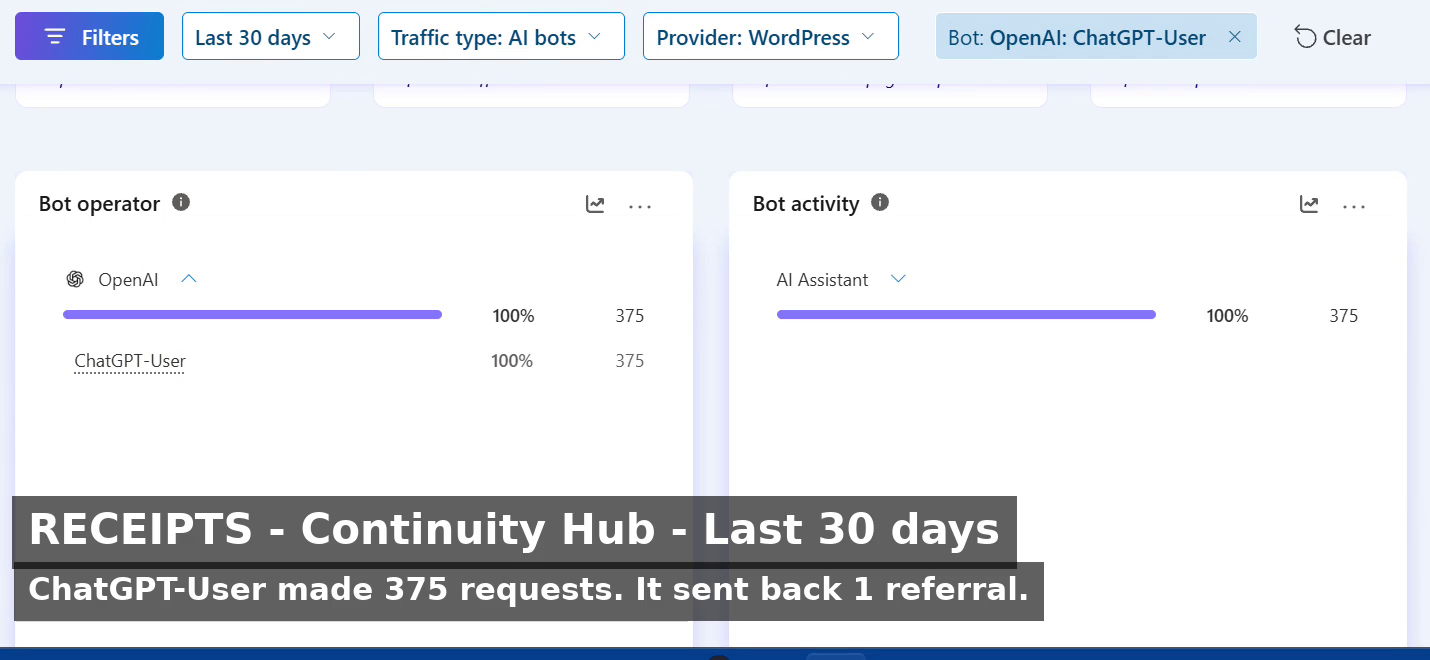
    Receipts: ChatGPT Read 375 Pages of One Site. It Sent Back 1 Visitor.

    People say you can’t tell which AI models are reading your site, or what they do when they get there. This is Microsoft Clarity on one of ours. It names the operator, the bot, and the activity — no guessing.

    Continuity Hub, last 30 days: ChatGPT-User made 375 requests. The homepage 83 times. Then the guides, one by one — supply-chain resilience, financial-services continuity rules, OSHA evacuation plans — down to pages that got a single read each. The bot didn’t skim the site. It walked the whole catalog.

    The scrape-to-referral ratio is 494:1. For every 494 pages the model read, it sent back one visitor. One referral, total, from chatgpt.com.

    That ratio is the part nobody selling AI visibility talks about. Being read by the models and being sent customers by the models are two different numbers, and the first one is enormous while the second one is nearly zero. We’ve measured the same shape across our sites — 408:1 on one, 837:1 across the fleet in September. The reading is real. The referring barely exists.

    So when you interview whoever handles your SEO and AEO, ask them to pull up this screen for your site, live, with the dates in frame. If they can’t show you the receipts, they’re reading from somebody else’s book.

  • The Best Agency for AEO SEO Reporting Is the One Whose Numbers You Can Re-Pull

    The Best Agency for AEO SEO Reporting Is the One Whose Numbers You Can Re-Pull

    Updated Nov 1, 2026 — added the free AEO reporting quick card, re-pullable AEO report pack, and report auditor bot book downloads to this guide.

    If you are comparing agencies specifically on their AEO and SEO reporting, you have probably already been burned the standard way: a glossy dashboard, a score that only goes up, and no way to check any of it against a source the agency doesn’t control. Reporting is where this industry hides. So here is the standard we would hold any agency to — including the one writing this page — stated as five sections a real monthly report contains, the ownership rule that matters more than all of them, and our own current numbers filled in as the sample.

    Instant Operational Downloads

    The Re-Pullable AEO Reporting Framework: Free, $7 & $17 Buyer Tools

    Demand the 5-section monthly report standard, verify source Bing/Clarity exports, lock commercial query share in Month 1, and run forensic AI audits on past agency deliverables.

    Field Quick Card
    FREE

    AEO Reporting Quick Card

    2-page field summary: The five sections of a report you can re-pull — ledger summary, share on queries that pay, page movers, new questions, work priced against movement — plus the non-negotiable ownership rule and bad-reporting spotter on one card.

    Download Free PDF

    Direct download • No email gate

    Working Field Pack
    $7

    The Re-Pullable AEO Report Pack

    Printable/fillable 6-page working pack: 5-section monthly report checklist, ledger summary log template, money-queries share table, page movers log, new-questions action sheet, ownership + re-pull rule sheet, and bad-reporting spotter quick-reference.

    Get Report Pack ($7) →

    Instant checkout • Square verified

    AI Intensive
    Book for Bots
    $17

    Feed-Your-AI Auditor

    Feed to ChatGPT or Claude: 8-page executable playbook with 6 interactive AI routines (Re-Pull Verification Interview, Money-Query Share Audit, Page Movers Diagnostic, New-Questions Paper-Trail Builder, Flat-Result Honesty Check, Bad-Reporting Detector) plus embedded router.

    Get AI Auditor ($17) →

    Software made of words • Instant delivery

    Section one: the ledger summary

    A real report opens with your citation totals and their direction — this window against last window, from the engine’s own export. Ours, for this site, reads: 1,459,726 total citations across 922 cited pages in the October 15 export, against 269,399 across 324 pages on September 27. Two numbers, two dates, one source anyone can re-pull. A report that gives you a total without the previous window’s total is giving you a photograph and calling it a trend.

    Section two: share on the queries that pay

    Totals flatter; share tells the truth. The second section lists the handful of questions your buyers actually ask an AI, and your citation share of each — for us, 24.50% on “claude pricing,” 33.85% on “claude ai pricing,” 54.46% on “anthropic console” in our software coverage. If an agency’s report never names your money queries, it is because the answer would end the meeting. Make them name the queries, in writing, in month one — then the share line becomes the whole relationship in one table.

    Section three: the page movers

    Which pages climbed, which consolidated, which are being starved — named by URL, with figures. Our current read: the certification guide at the center of our contractor work climbed 1,635 → 1,913 → 2,454 → 2,790 citations across four exports while its duplicate was consolidated from 304 down to 6. That single line tells a client more than forty pages of charts: where the engine is placing its trust, and what the agency did about it. A report without named pages is a report about nothing in particular.

    Agency Evaluation Toolkit

    Don’t Rent Your History: Audit Agency Numbers From Your Own First-Party Exports

    If your agency reports anonymous averages or hides behind proprietary visibility scores, demand the 5-section re-pull standard before signing. Whether you need printable working logs, money-query share tables, and 4-export page mover diagnostic sheets ($7), or an autonomous AI auditor to cross-examine their deliverables, flag vanity bot totals, and generate binding contract redlines ($17), equip your team with forensic arithmetic.

    📊

    What’s In The Toolkit:

    • Ledger Summary Log: Sept 27 vs Oct 15 model.
    • Money-Queries Share Tracker: Month 1 query locking.
    • Page Movers Tracker: 4-export climber & consolidation logs.
    • New-Questions Action Sheet: Grounding query paper trail.
    • AI Audit Routines: 6 automated auditor workflows.
    Both tools grounded 100% in Post 25636 substance. Instant delivery.

    Section four: new questions, and what got built against them

    Every export surfaces grounding queries you have never seen — the market asking new questions in the open. Section four lists them and ties each to an action: published, queued, or deliberately passed on, with the reason. This is the section that proves the work is demand-led rather than calendar-led, and it’s the first section a lazy agency quietly drops, because it creates a paper trail of promises.

    Section five: the work, priced against the movement

    What was done, what it cost, what moved, what’s next — in that order, on one page. Not a ticket dump. If three articles shipped and the share line didn’t move, the report should say so and say what changes next month. The month the report stops admitting flat results is the month it became a sales document.

    The ownership rule that outranks all five sections

    Every figure in the report must be re-pullable by the client, from the client’s own accounts. Bing Webmaster and Microsoft Clarity are free; the exports belong to whoever owns the property. If your agency generates its numbers inside its own portal, from its own panel, under its own login, then leaving the agency means leaving your history — and a report you can’t verify is a report you’re renting. We run our tracking exactly this way, and the method is published so a client can audit it without us in the room. These five sections, by the way, are the receipts from the buyer’s test wearing their monthly clothes: the test is what you demand before signing; the report is what you should receive after.

    Compare the Three AEO Reporting Toolkits

    Choose the right level of rigor for evaluating finalist agencies and monthly deliverables.

    Feature / Capability Free Quick Card Working Pack ($7) AI Auditor Book ($17)
    Asset Format 2-Page Field Summary 6-Page Printable Pack 8-Page Executable AI Playbook
    5-Section Monthly Checklist ✓ Reference Table ✓ Fillable Master Form ✓ Automated Bot Audit
    Ledger Summary Log Template Summary Rules ✓ Full Working Log ✓ Re-Pull Interview Bot
    Money-Queries Share Tracker Benchmark Table ✓ Month 1 Lock Register ✓ Commercial Query Audit
    Page Movers 4-Export Tracker Progression Model ✓ Named URL Worksheets ✓ Cannibalization Diagnostic
    New-Questions Action Sheet Workflow Summary ✓ Paper-Trail Sheet ✓ Demand-Led Bot Builder
    Bad-Reporting Spotter (5 Tells) ✓ Red Flag Table ✓ Diagnostic Sheet ✓ Automated Detector Scan
    Interactive AI Routines — — ✓ 6 Dedicated AI Routines
    Action Free PDF Buy Pack ($7) Buy Bot ($17)

    What bad reporting looks like, so you can spot it in the wild

    A proprietary visibility score with no export behind it. A screenshot of the best week of the quarter. Engines blended into one soup so a Bing collapse hides inside a ChatGPT anecdote. Vanity totals — citations counted without share, traffic counted without asking how much of it was bots (on our fleet this month, roughly six visits in ten were automated; a report that never mentions that is averaging two different worlds). And the tell of tells: a report that arrives as a presentation, live, with no file you keep.

    How to choose, then

    Before you sign with anyone — us included — ask each finalist for last month’s report for a current client, redacted as needed, and for the source exports behind one number in it. The best agency for AEO SEO reporting is not the one with the prettiest dashboard or the boldest score. It is the one whose report survives your re-pull: same exports, same windows, same figures. Everything else is a pitch. The report is the product demo that can’t be rehearsed — judge that.

  • AI Visibility: The LLM Optimization Strategies We Actually Run

    AI Visibility: The LLM Optimization Strategies We Actually Run

    Most LLM optimization advice is written by people who have never watched an engine decide whether to cite them. We have — monthly, in the engine’s own reports, across a small fleet of sites. What follows is not a theory of AI visibility. It is the playbook running on our sites right now: seven strategies, each with the number that proves it, each boring enough to actually compound. If a strategy can’t name the report that would show it working, it isn’t a strategy. It’s a hope with a webinar.

    Engine Grounding Toolkits

    AI Visibility Toolkits: Quick Card, 7-Check Playbook & Cite-Me Bot Book

    Printable citation logs, liftable paragraph tests, consolidation maps, and machine-executable AI audit routines built directly from our fleet grounding ledger.

    Field Reference
    FREE

    AI Visibility Quick Card

    2-page field summary: the seven boring compounding strategies condensed onto one card — single-question titles, liftable blocks, feeding winners, demand calendars, drawer numbers, extraction handles, and entity legibility.

    Download Free PDF

    Direct download • No email gate

    Working Pack
    $7

    AI Visibility Playbook Pack

    5-sheet printable/fillable pack: One-question title planner (33% & 36% examples), Liftable-paragraph checklist, Consolidation feeder log (1,635 → 2,790 vs 304 → 6 tracker + orphan redirects), Grounding-query calendar, Publish-numbers inventory, Fee table schema guide, and 1-sentence entity worksheet.

    Get Playbook Pack ($7) →

    Instant checkout • Square verified

    AI Intensive
    Book for Bots
    $17

    Cite-Me Coach: Bot Book

    Feed to ChatGPT or Claude: 6 interactive optimization routines (Question-Match Interview, Liftability Audit, Consolidation Verdict Walkthrough, Query-Report Calendar Builder, Proprietary-Number Generator, Extraction & Entity Diagnostic) + embedded command router.

    Get Bot Book ($17) →

    Software made of words • Instant delivery

    1. One question per page, in the asker’s words

    An AI answer is assembled from pages that match the question being asked — so build pages that are the answer to one real question, titled the way a person actually asks it. Our certification guide for restoration contractors doesn’t chase “IICRC resources.” It answers what IICRC certification is, what it costs, and how to keep it current — and on Bing’s ledger we hold about a third of all citations for “what is iicrc certification” and 36% for “iicrc certification cost.” Nobody types marketing copy into an AI. They ask questions. The page that sounds like the answer wins the citation.

    2. Write paragraphs an engine can lift

    Citation is extraction. When an engine grounds an answer, it pulls the passage that stands on its own — the paragraph that contains the fact, the number, and the context in one self-contained block. So write that way on purpose: every paragraph a complete little model that still makes sense if it’s the only thing quoted. Buried facts, pronoun chains that need the paragraph above, and throat-clearing introductions are all invisible to an extractor. A page of liftable paragraphs beats a beautiful essay the engine can’t cut a piece from.

    3. Let the engine consolidate — then feed the winner

    Given two similar pages, an engine picks one and starves the other, and it shows you the execution in the reports. Our flagship certification page climbed four straight monthly exports — 1,635, then 1,913, then 2,454, then 2,790 citations — while its near-duplicate twin fell from 304 to 6. The strategy is to cooperate with that verdict: one page per topic, the cluster’s links pointed at the winner, old strays redirected to it. We spent part of today doing the plumbing version of this — three orphaned URLs that were leaking to our homepage now land on the pages that earned the citations. Fighting consolidation splits your authority. Feeding it compounds.

    LLM Optimization Worksheets & Bot Routines

    Run Our 7 Engine Grounding Checks Across Your Content

    When an AI engine evaluates your site against competing pages, it starves vague essays and feeds self-contained, data-dense winners. Our printable 5-sheet Playbook Pack gives you the exact winner vs. twin consolidation logs (tracking the 1,635 → 2,790 compounding path), orphan URL redirect sheets, and fee table extraction schemas we use every month — or feed our $17 Bot Book to ChatGPT or Claude to interrogate your titles, score your paragraphs for extractor readiness, and generate your demand calendar automatically.

    ☑

    What’s In The Toolkit:

    • Title Planner: Asker-words question worksheet.
    • Liftable Checklist: Fact + Number + Context test.
    • Consolidation Log: Winner vs twin tracker & redirects.
    • Demand Calendar: Engine grounding export intake.
    • Drawer Numbers: Proprietary data report cards.
    • Entity Diagnostic: 1-sentence agent first-sort test.
    • AI Bot Book ($17): 6 AI prompt routines + router.
    Secure 1-Click Square Checkout

    4. Let the engine write your editorial calendar

    The most valuable document in AI visibility is free: the grounding-query report, which lists the actual questions your pages were pulled for — including ones you’re cited on weakly, and new ones appearing for the first time. That list, plus the topic opportunities the same dashboard surfaces, is a calendar written by demand instead of guesswork. This article exists because that report said people are asking how LLM optimization works. Half of what we publish starts as a line in an export. Guessing topics is a tax on people who won’t open a free report.

    5. Publish numbers nobody else has

    An engine cannot ground an answer on your competitor’s guess — but it can ground one on your data, if your data is the only place the number exists. First-party figures are the one content asset that can’t be copied by writing faster: your exports, your measurements, your before-and-afters. We print our own citation report card in public, limits included, and it keeps getting cited precisely because no one else can produce those numbers. Whatever your industry measures privately is a citation asset sitting in a drawer.

    6. Structure for extraction

    Give the machine clean handles: question-and-answer sections whose text matches the structured data behind them, tables with the real figures instead of ranges blurred into mush, section anchors a citation can point at. When we rebuilt our flagship page, we replaced three inconsistent blended price ranges with one fee table carrying the actual numbers — tuition, exam fee, renewal — each in the open where an extractor can take it. Vagueness feels safe to writers. To an engine, it’s just unusable.

    7. Be legible as an entity

    Agents do the first sort now — of vendors, of hires, of experts — and they sort on what your profiles actually say. We learned this watching a genuinely excellent operator get skipped by an automated screen because his headline was three abstract nouns and no signal. Your site, your company page, and your profiles should each state, in plain words, what you do, for whom, and where — written for the machine doing the first read and the human doing the second. If an agent can’t summarize you accurately in one sentence, your visibility strategy has a hole no content calendar will fill.

    Compare AI Visibility Toolkits

    Choose the quick reference card, printable working pack, or machine-executable AI playbook that fits your publishing workflow:

    Free Field Summary

    AI Visibility Quick Card

    2-page field reference: all seven compounding strategies condensed onto one card — title matching, liftable paragraphs, consolidation rules, engine demand calendars, first-party data assets, structured handles, and entity legibility.

    FREE
    direct download
    • Strategy 1: One Question Per Page in Asker’s Words
    • Strategy 2: Paragraph Extraction Architecture
    • Strategy 3: Consolidation Feeder & Redirect Plumbing
    • Strategy 4: Grounding Export Editorial Intake
    • Strategy 5: First-Party Data & Public Report Cards
    • Strategy 6: Real Fee Tables & Section Anchors
    • Strategy 7: Entity Legibility Agent First-Sort

    Download Free PDF

    Working Pack

    AI Visibility Playbook Pack

    Printable, fillable 5-sheet working pack with title worksheets, paragraph checklists, consolidation trackers, demand intake sheets, and schema guides.

    $7.00
    one-time
    • Sheet 1: Title Planner (33% & 36% Bing Share Benchmarks)
    • Sheet 2: Liftable-Paragraph Fact + Number + Context Checklist
    • Sheet 3: Consolidation Log (1,635 → 2,790 vs 304 → 6 Tracker)
    • Sheet 4: Grounding-Query Editorial Intake & Triage Sheet
    • Sheet 5: Proprietary Numbers Inventory & Report Card Template
    • Sheet 6: Extraction Handles & Fee Table Precision Guide
    • Sheet 7: Entity Legibility 1-Sentence Agent Worksheet

    Buy Playbook Pack ($7) →

    AI Intensive
    Book for Bots

    Cite-Me Coach: Bot Book

    Structured 7-page AI playbook for ChatGPT, Claude, and Gemini: 6 machine-executable optimization routines + embedded command router.

    $17.00
    one-time
    • Routine 1: Question-Match Interview (/interview-titles)
    • Routine 2: Liftability Audit & Rewrite (/audit-liftability)
    • Routine 3: Consolidation Verdict Walkthrough (/verdict-walkthrough)
    • Routine 4: Query-Report Calendar Builder (/build-calendar)
    • Routine 5: Proprietary-Number Generator (/mine-numbers)
    • Routine 6: Extraction & Entity Diagnostic (/diagnostic-entity)
    • Embedded Command Router & Prompt Center (/cite-me-router)
    • Full Site Publication Certification Routine (/full-audit)

    Buy Bot Book ($17) →

    The compounding is the strategy

    None of these moves trends. Each is a small, verifiable bet placed monthly against the engine’s own ledger — which is why measurement isn’t step eight, it’s the ground the other seven stand on; our tracking method is written up here, and the receipts we’d demand from anyone selling this work are in the buyer’s test. LLM optimization, done honestly, is a publishing discipline with a feedback loop — not a hack, not a plugin, not a score you buy. The engines are reading either way. The only choice is whether what they find is built to be cited.

    Updated Nov 1, 2026 — added the free AI visibility quick card, AI visibility playbook pack, and cite-me coach bot book downloads to this guide.