Tag: SEO

  • Six in Seven AI Answers Never Look Anything Up

    Six in Seven AI Answers Never Look Anything Up

    Most of what an AI answer says about your business was never looked up. It was remembered — or invented in the shape of a memory. Ahrefs put a number on that in a study published October 12, 2026: across 66.6 million free, logged-out ChatGPT responses from August and September 2026, a web search ran in only 14.4% of them. Six in seven answers were written without checking anything.

    That single fact reorganizes the work. If the answer usually comes from what the model already carries, then being findable is only half the game. The other half is being known — and, for the one answer in seven where the engine does go looking, having the fact it needs sitting in plain text on your own domain, where it looks first.

    The search, when it happens, is narrow

    The same study logged 15 million fan-out queries — the searches ChatGPT issues behind an answer when it decides to search at all. A searching response ran about 1.6 of them on average. This is not a research department fanning out across the open web. It is a quick, targeted check, and the targeting is the story.

    6.8% of those fan-out queries used a site: operator to search one specific website, spread across roughly 116,000 domains. Among the most common of those targeted searches, 75.9% pointed at a brand’s own site — not a retailer, not a forum, not a review aggregator. When the engine wants a price or a specification, it goes to the company that sells the thing.

    The vocabulary inside the queries leans the same way. The word “official” appeared in 13.1% of English fan-out queries in September 2026, up from 10.1% in August. “Price” climbed from 6.04% to 8.88% of fan-outs in the same month — a relative rise of nearly half. The engine is increasingly searching for the authoritative version of a fact, and the facts it most wants are commercial ones: what it costs, what it includes, what the official page says.

    Facts go home; comparisons wander

    Ahrefs paired the fan-out data with a separate test of 20,000 US prompts, and the split inside it is worth keeping separate in your head, because it is a different instrument from the 66.6 million. In that test, 84.4% of factual questions — pricing, product features, company details — cited at least one official source. For factual questions, 63.4% of all citations pointed at official websites. For comparison questions (“A vs B,” “which is cheaper”), the official share fell to 46.4%: most citations went somewhere else.

    Read together, the two datasets describe one behavior with two modes. Asked for a fact, the engine goes home to the source. Asked to judge, it goes out to the crowd. An operator cannot control the judging mode. The fact mode is entirely winnable: it is won by having the fact, in the open, on the domain the engine already searches by name.

    The playbook that follows

    Publish the price, the spec, and the support fact in plain text on your own domain. Not in a PDF the crawler has to excavate, not inside a configurator, not implied by a sales page’s adjectives. The fan-out query literally contains the words “official” and “price” — it is asking for a page that states the number. Whoever states it cleanly gets cited for it.

    Publish the pages only you can publish. Your measured results, your actual process, your own numbers with dates on them. A summary of somebody else’s facts competes with the original; the original is what the engine is learning to prefer (the citation movement below shows how far that preference has already moved).

    Treat fan-out queries as an instrument of their own. The queries an engine issues about your category — which words it adds, which domains it targets, how that shifts month to month — are a measurement channel separate from citation counts. Watch them separately. We grade the flight recorder, not just the answer, for the same reason: the queries show the intent; the answer only shows the outcome.

    Never blend two dashboards into one story. The 14.4% comes from 66.6 million free logged-out responses. The 84.4% comes from a different, 20,000-prompt test. The citation movements in the next section come from a third cut again. Each number is true inside its own denominator and misleading outside it. This is the same discipline we run on our own visibility work: being cited is not being chosen, and being measured is not being measured the same way twice. Our running instrument for the citation side is the Citation Pulse.

    The second movement: summarizers are losing

    Ahrefs’ Brand Radar citation data for the US — 2.4 million ChatGPT answers in March 2026 against 3.8 million in September, a different dataset from the fan-out study above — shows where the citations went. Reddit fell from roughly one citation in every five answers in March to about one in 43 by late September. Wikipedia fell from one in seven to one in 35. The share those summarizers and forums lost moved to research bodies, regulators, brand and support pages, and hands-on testers. On a matched set of about 25,000 prompts present in both months, every tracked site moved in the same direction, so the shift is not an artifact of new questions entering the sample.

    For an operator, that is the durable part of the whole study. The memory answers reward whoever the model already knows. The searching answers reward whoever publishes the primary fact. The citation trend rewards the originator over the summarizer. All three roads end at the same address: your own domain, carrying your own facts, in plain text.

    The same citation movement, read for hospitals and the firms that build for them — why clinical and facility specifications now have to live as primary documents — is on Healthcare Facility Hub: The Citation List Is Moving Toward the Source Document.

    Sources: Ahrefs, “How ChatGPT Does Query Fan-Out” (October 12, 2026) — fan-out dataset (66.6M responses, 15M queries, Aug–Sep 2026), the 20,000-prompt official-source test reported in the same article, and the Brand Radar US citation comparison (2.4M answers March 2026; 3.8M September 2026). Each figure above is stated with the dataset it came from; the three are not interchangeable.
  • What does AEO reporting actually show?

    An honest AEO report shows four things: the exact questions that were asked, the answers the assistants actually gave, which businesses and pages those answers cited, and how all of it changed since the last run. AEO reporting is the scheduled record of those four things, kept the same way every time. Anything that cannot show you the four is showing you a mood, not a measurement.

    What questions were asked?

    A real AEO report prints its question set in full, word for word. The questions are the foundation of the whole report: they should be your customers’ real questions, fixed in advance, and identical from run to run. A citation count means nothing until you can see the questions it was counted on.

    This is where reports quietly cheat. Swap the questions between runs and every comparison is fiction — you improved because the test got easier. Add a question you already win and the average climbs without a single answer changing. Ask for the set in writing before the first run, and treat any later change to it as a new baseline, announced as one. A short set of real questions, held steady, beats a long set that wanders.

    What did the AI actually say?

    A real AEO report keeps the raw answers, not summaries of them. The answer text is what your customer actually reads — the names in it, the order they appear, the words around them. A summary written by the provider can only tell you what the provider noticed. The raw answer lets you check.

    Summaries hide the losses. A run where you were cited on nine questions and dropped on the tenth, hard, reads as “visibility strong” in a summary and as a work order in the raw text. Keep the full answers, dated, for every run. They take almost no space, they cannot be reconstructed later, and they are the difference between having evidence and having a recollection.

    Who got cited?

    A real AEO report names the citations for every question: which businesses the answers credited, which pages of theirs did the work, and what share of the citations on each question went to whom. The citation list is the most useful page in the report. It converts “we are not visible” into a named list of exactly who the machines trusted instead, question by question.

    Read it as a work list, not a wound. When one restoration client of ours kept losing a question to the same competitor, the citation list showed the competitor’s page the assistant kept crediting — a page that answered the question in the customer’s own words, in the first paragraph. That is a specific, fixable problem, and it was invisible in every summary number we had. Your citation share — your slice of the citations on your questions — is the one summary figure worth tracking, because it is arithmetic on the list, not an opinion about it.

    What changed since last time?

    A real AEO report is built to compare: this run against the last, same questions, with the differences stated plainly and the work done in between written next to them. Answers churn — the same question, asked next month, can name different businesses with nothing changed on either side. An honest report says so, and reads movement over several runs instead of celebrating or mourning a single one.

    The work log belongs inside the report for one reason: without it, you cannot tell your work from the weather. “We rebuilt the profile and published two answer pages in March; citations on those questions rose across the April and May runs” is knowledge. The same rise with no log behind it is luck you will try to repeat blind. If your provider’s report never mentions what they did between runs, ask why their work and their results live in separate documents.

    What does a horoscope report look like?

    A horoscope report shows a single score with no questions behind it, percentages with no counts under them, and screenshots of the one good answer from a good day. It changes its questions when the results are inconvenient, reports only the wins, and always finds that things are improving and that more budget would improve them faster. It feels good, commits to nothing, and cannot be checked.

    The test is simple. Pick any number in the report and ask: on which questions, from which answers, counted how? A real report answers in one step, because the number came from a list it can show you. A horoscope report answers with another number. We call them horoscopes because, like the ones in the paper, they are written to be agreeable about the future and impossible to grade about the past.

    How often should you read an AEO report?

    Read AEO reporting on a rolling cadence — monthly is a sane default — and never daily. AI answers move day to day with nothing changed, so daily reading is noise-chasing: it manufactures urgency, spends your attention, and teaches you to react to weather. What is worth reading is the run-over-run trend, and the first run after real work has had time to settle.

    Reading it should end in a decision, or the reading is decoration. The standing decision a good report sets up is small: which questions is a competitor cited on that we are not, and what is the missing answer we should write next? Our AI Citation Quick-Scan is this artifact in its smallest honest form — 10 prompts about your service line, the answers recorded, the citations named, a scored report within 7 days, $97, one time.

    Which lines the platforms lift is their call. We build the material they lift from — and then we measure what they did.

  • How do you measure AI search visibility?

    You measure AI search visibility with two kinds of tools: the reports the platforms publish about their own answers, and trackers that ask the assistants your customers’ questions on a schedule and record who gets named. The platform reports show who the platform cited. The trackers show what an assistant answered when asked. A buyer who knows which tool shows which thing can read either one honestly.

    What does “visible” mean in an AI answer?

    An AI answer can mention your business, cite your business, or recommend your business, and those are three different measurements. A mention means your name appears in the answer text. A citation means the answer credits your page as a source. A recommendation means the assistant names you as the choice. Every tool below reports some mix of the three, under its own labels.

    The distinction decides what a number is worth. A mention can be one name in a list of eight. A citation means the platform read your material closely enough to credit it — that is the receipt that survives. A recommendation is the strongest outcome and the least common. When a tool shows you one big “visibility” number, the first question is which of the three it counted.

    What does Bing AI Performance show?

    Bing AI Performance is Microsoft’s free first-party report, and it shows what the assistants built on Bing actually cited. The report organizes citations four ways: Intents, Topics, Citation Share, and Compare. It is the platform grading its own homework — the most direct evidence a buyer can get, and a view of exactly one surface.

    The four views answer four plain questions. Intents shows the kinds of things people were trying to do when your pages got cited. Topics groups those citations by subject, so you can see which of your subjects the machines trust. Citation Share shows your slice of the citations on a topic against everyone else cited there. Compare puts two date ranges side by side, so a change shows up as a change and not a feeling.

    Our own report is the example we read every month. For tygartmedia.com, our Bing AI Performance report covering six months of Microsoft Copilots and partners shows 1.5M total citations across an average of 164 cited pages. We read that as our footprint on one measured surface — proof the surface can be measured, and a baseline to compare the next run against. It says nothing about any other platform, and it is not a promise about any other business.

    What do third-party visibility trackers show?

    Third-party trackers are subscriptions that ask a fixed set of questions to the major assistants on a schedule and record the answers. A tracker shows mention rates, citation rates, and competitor shares across several surfaces at once. What it sells is a trend line across platforms, built from sampled asks — not a record of what any real customer saw.

    The honest advantages are real. A tracker sees surfaces the first-party reports cannot, because each platform only reports on itself. A fixed question set, asked the same way each run, produces runs a buyer can actually compare. Competitor context comes built in, and in a contested market that context is the point.

    The limits are just as real. The tracker asks its questions, on its schedule, from its accounts — your customers ask differently, locally, and once. Small question sets get reported as precise percentages, and a two-question swing can dress itself up as a trend. And the subscription runs whether you read it or not. A tracker earns its money in a competitive market with several assistants in play, read monthly by someone who acts on it. Everywhere else it is an expensive screensaver.

    What can no tool tell you?

    No tool can tell you what a specific customer saw, whether a mention became a phone call, or why an assistant chose a competitor. AI answers vary by person, place, and moment, and the platforms do not publish their reasoning. A tool shows outputs. The cause behind an output is still the buyer’s work to figure out.

    Sit with that limit before you buy anything, because it is where the honest tools end and the salesmanship starts. No report closes the gap between “the assistant named us” and “the phone rang” — that gap closes with call tracking and asking customers how they found you, unglamorous as that is. A provider who sells you certainty across that gap is selling you the gap.

    Which tool should a buyer start with?

    A buyer should start with the free first-party report for the surface their customers actually use, and add a tracker only when they need a cross-platform trend and will read it monthly. The tool matters less than the discipline behind it: a fixed set of your customers’ questions, asked before the work and after, with the raw answers kept. Any tool run that way beats a better tool run casually.

    Most small businesses find the first-party report is enough to start, because it answers the only question that changes what they do next: on the questions my customers ask, who does the machine name — and is it me? If you want that first measurement done by hand instead, our AI Citation Quick-Scan asks 10 prompts about your service line and returns a scored report within 7 days — $97, one time.

    Which lines the platforms lift is their call. We build the material they lift from — and then we measure what they did.

  • Which AI SEO services are right for a small business?

    The right AI SEO services for a small business are the ones matched to where your customers actually ask questions. For most local service businesses, that means three things, in order: a business profile the machines can read, answer pages on your own website written the way customers ask, and a scheduled check that shows who the machines name.

    What are AI SEO services?

    AI SEO services are services that make a business readable to AI answer engines. A traditional search engine returns a list of links; an AI assistant returns an answer, and it names the businesses it can read clearly. AI SEO is the work of giving those systems clean material — profiles, pages, and consistent facts — to name you from.

    The category is new enough that the label covers very different work. One provider’s “AI SEO” is a rebuilt Google Business Profile and a page of real answers. Another’s is a software subscription and a monthly PDF. The sections below separate the kinds, so you can buy the work instead of the label.

    What kinds of AI SEO services are there?

    AI SEO services come in five kinds: listing and profile work, answer-page writing, citation cleanup across directories, one-time audits that measure where you stand, and ongoing retainers that bundle all of it. Most small businesses need the first three once, the audit before and after, and a retainer only when the market moves fast.

    • Profile work builds the listings machines read first: Google Business Profile on Google’s side, Bing Places on Microsoft’s — the listing Copilot and the assistants built on Bing read from.
    • Answer-page writing puts pages on your own website that answer customer questions in customer language, in passages short and plain enough to be quoted.
    • Citation cleanup makes your name, address, phone, and services agree across directories and aggregators — Yelp, Foursquare, Apple Maps, Angi, and the data feeds behind them.
    • Audits and scans measure the starting point: a fixed set of questions, asked before the work and after, with the answers kept.
    • Retainers bundle the above into monthly work. They fit businesses in fast-moving markets; they are a poor fit for one-time fixes billed forever.

    How is AI SEO different from traditional SEO?

    Traditional SEO earns a position on a list of links; AI SEO earns a mention inside an answer. The list rewards the page; the answer rewards the clearest source. Both run on the same foundations — a readable website, consistent business facts, reviews, and real expertise — but the AI layer reads quotable passages, not just pages.

    That difference changes what good work looks like. A page stuffed with keywords can rank and still never be quoted, because there is no clean passage to lift. A plainly written answer — the question as the heading, the answer first, the detail after — gives an assistant something it can repeat word for word. Traditional SEO is not replaced by this; it is the floor it stands on.

    What should a small business buy first?

    A small business should buy in the order a customer asks. First, the profile a machine reads when someone asks for your trade nearby — your Google Business Profile and your Bing Places listing. Second, answer pages on your own site. Third, a measurement check. Software subscriptions and content volume come last, if at all.

    The order matters because the surfaces compound. An assistant answering “who does this work near me” starts from profiles and listings, then checks what your website says. A beautiful website behind an empty profile is invisible at the first step. A strong profile pointing at a website with no answers gives the machine nothing to quote. Buy the chain in order and each link makes the next one worth more.

    How much do AI SEO services cost?

    AI SEO services are sold three ways: one-time builds, monthly retainers, and small diagnostics. The honest difference is not the label but what you can hold afterward — a finished profile and pages you own, or a report you can re-run. Any price is too high for work you cannot inspect when it is done.

    Price follows scope: number of locations, number of services, number of towns you serve. What should make you careful is shape, not size. One-time work — a profile build, an answer page, a listing cleanup — should carry a one-time price. Monthly money should buy monthly work you can name: new questions tested, new answers written, changes logged. If a provider cannot tell you which of your dollars are one-time and which recur, that is the answer to whether to sign.

    What questions should I ask an AI SEO provider before I pay?

    Ask an AI SEO provider five questions before you pay: What exactly will exist when you are done? Which questions will you test, and can I see the answers before and after? What do you not control? What does the work cost once, and what recurs? Who owns the pages and profiles afterward? Ask us the same five.

    Each question has a tell. “What will exist” should produce a list, not adjectives. “Which questions” should produce your customers’ actual questions, written down. “What do you not control” is the honesty test — no provider controls which businesses an assistant names, and one who promises a ranking is telling you how the rest of the engagement will go. Ownership is the quiet one: profiles and pages built on your accounts, in your name, stay yours if you leave. Anything else is rent.

    What proof should an AI SEO service show me?

    An AI SEO service should show you a named report, a date range, and the questions it tested — not a screenshot of a ranking. On our own site, the proof habit looks like this: our Bing AI Performance report for tygartmedia.com, covering six months of Microsoft Copilots and partners, shows 1.5M total citations across an average of 164 cited pages.

    Read those numbers the way we do. They are our own footprint on one measured surface — evidence that the measurement exists and that we live under it — not a promise about your business. AI answers also churn: the same question asked next month can name different businesses, which is why honest proof is a before-and-after on your questions, re-asked on a schedule, with the raw answers kept. A provider who shows you their own numbers should be just as willing to show you yours.

    Can I do AI SEO myself?

    Yes — the free layer of AI SEO is real work any owner can do: claim and complete your Google Business Profile and Bing Places listing, write your services in plain language, and answer your customers’ common questions on your own site. What you pay a provider for is the audit discipline, the writing time, and the measurement habit.

    Be honest with yourself about which of those three you will actually do. The profile most businesses already “have” is a name, a pin, and hope — claimed years ago and never finished. The knowledge is not the scarce part; the finished, checked, written-down work is. If you will do it yourself, the sections above are the whole recipe, in order, and they will work the same for you as for us.

    Where does our own offer fit?

    If you want to know where you stand first, our AI Citation Quick-Scan runs 10 prompts about your service line and returns a scored report within 7 days — $97, one time. If you want the build done, the Ask Maps Protocol is our version: $450, one time — a mobile-first audit of how your listing actually renders, your Google Business Profile rebuilt for answers, an FAQ answer page on your website, your Bing Places listing claimed and matched, and a 30-day proof check.

    Which lines the platforms lift is their call. We build the material they lift from — and then we measure what they did.

  • Yes, I Put the Schema Where You Could See It. On Purpose.

    Yes, I Put the Schema Where You Could See It. On Purpose.

    I had an audit run on the oldest content on this site this week. Pages, posts, links, bylines, search descriptions, the works. It came back with a ranked list of problems, and near the top, flagged as a defect readers can see, was this:

    Visible raw JSON-LD schema code printed as text in the post body.

    Across the whole site, it found 197 posts doing it.

    Cartoon crawler robot stamping FLAGGED on a blog post full of visible code while the blogger gives a sheepish thumbs-up
    My own audit, doing exactly what I asked it to do. Rude.

    And I’ll be honest, my first reaction wasn’t “oops.” It was closer to “hey, I did that on purpose.”

    What you’re looking at

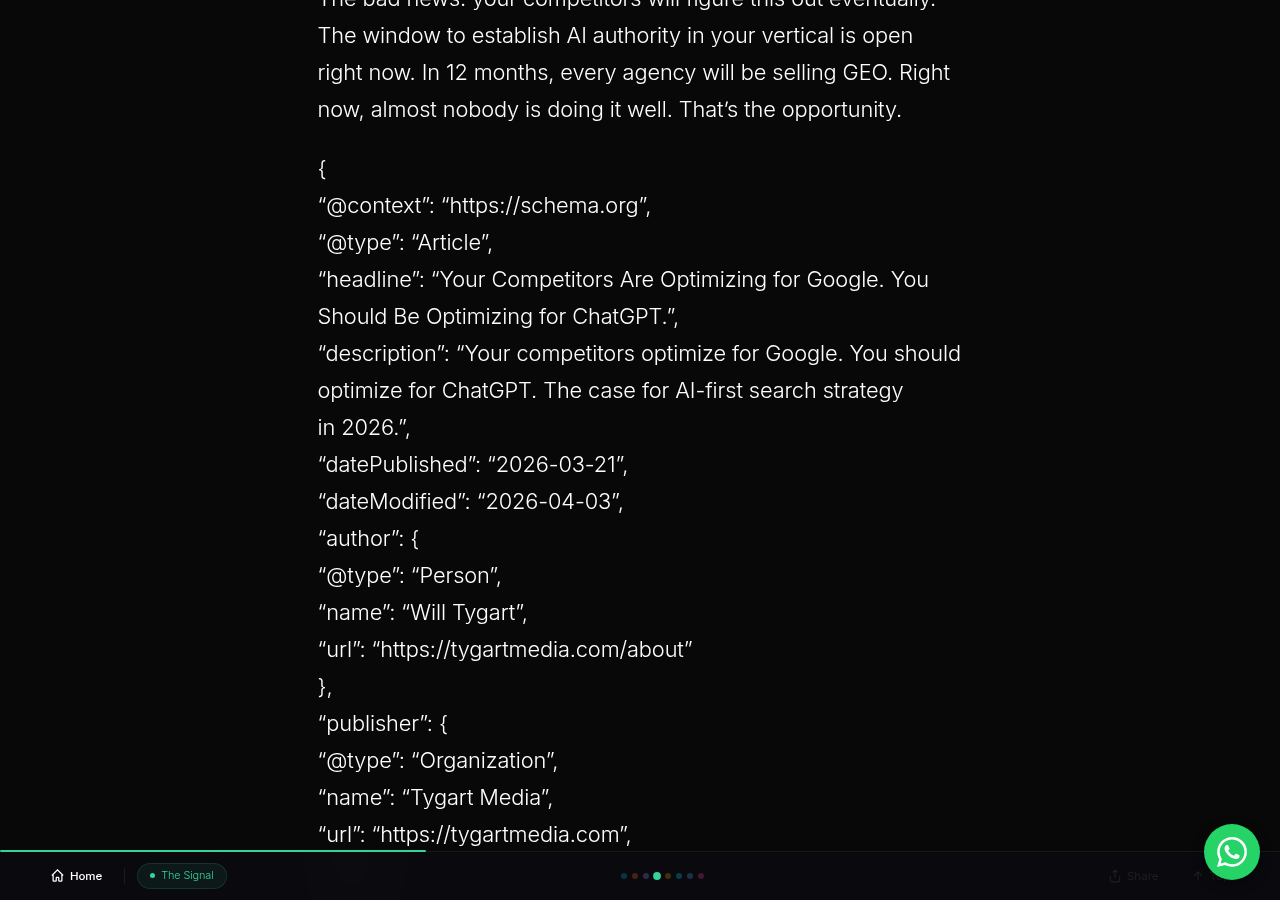
    If you’ve scrolled to the bottom of some of my older posts, you’ve seen it: a block of curly braces, "@context": "https://schema.org", a headline, an author, a publisher, a date. It’s structured data. The machine-readable summary of what the page is, who wrote it, and who published it.

    Normally that lives in a <script type="application/ld+json"> tag. Readers never see it, and crawlers pick it up behind the scenes. I know how to do it that way. Plenty of these same posts had it that way too.

    I also put a copy out front, in the body, where anyone could read it.

    Before: the end of “Your Competitors Are Optimizing for Google. You Should Be Optimizing for ChatGPT.” with its Article schema printed as visible text, curly quotes and all
    Before. The article ends, the schema begins. Those curly quotes are lovely typography and terrible JSON.

    Why I did it

    This didn’t come out of nowhere. Back when I published these, I’d already been at it a while: for about a year before that, my everyday workflow was screenshotting schema and photos and pasting them into AI tools to get help with them. That was on my own desk, not on the website. But do that long enough and you get in the habit of thinking about the page as something a machine reads, not just something a person reads.

    When it came time to publish these posts, my reasoning was simple. Not everything that reads a web page reads it the way Google does. Screen readers, accessibility tools, and whatever crawler or AI agent happens to show up next don’t all go digging through script blocks. Some of them only take in the text on the page.

    So I thought: if the structure matters, and I was betting heavily that it did, especially for AI and answer engines, then why hide it? Put it where every reader, human or machine, could get to it. Treat it as part of the content, not an invisible attachment.

    It was also a demonstration. I write about getting businesses understood by machines. Showing the actual markup on the page was a way of saying: this is what that looks like. Nothing up my sleeve.

    The fair criticism

    Now, I’m stubborn, not blind. A few things are fair game here.

    A wall of JSON is not friendly to a human reader. If you came for a local SEO playbook and finished on forty lines of braces and quotation marks, I get it if you thought the page was broken. The audit literally measured one of these blocks running about 2,100 pixels tall on a phone. That’s a lot of scrolling for metadata.

    What a screen reader actually does with a block of JSON is a fair debate. My intent was access. Whether reading out a pile of punctuation counts as access is a fair thing to argue about, and I’m not going to pretend I settled it.

    The copies didn’t stay clean. WordPress likes to “help.” Some of the visible blocks picked up curly quotes and line breaks along the way. That’s charming in prose and useless in JSON. A machine trying to parse those blocks as data would choke.

    So the audit isn’t wrong that it’s a problem today. It’s just wrong about why it’s there. It wasn’t an accident. It was a choice, and the choice has run its course.

    Why it’s coming down now

    Here’s the part that makes this easy. The stack caught up.

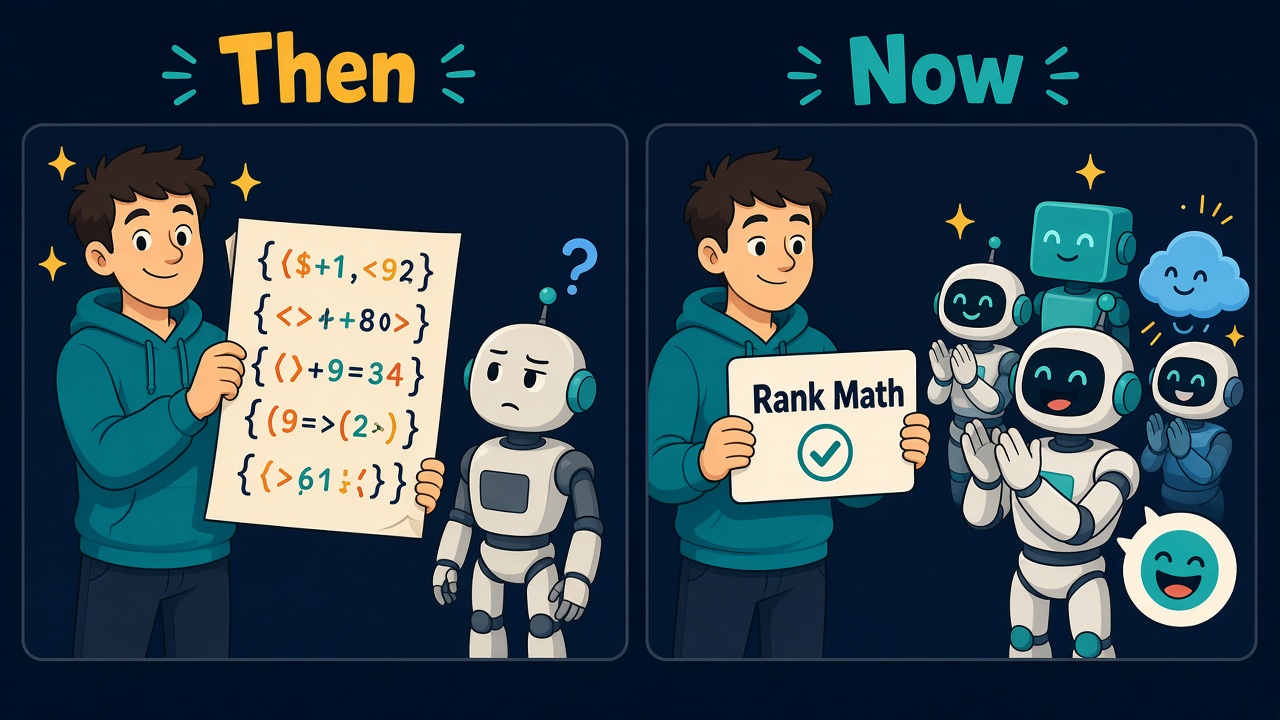
    This site runs Rank Math, and Rank Math now outputs proper Article and BreadcrumbList schema on every post, in the head of the page, where it belongs. That means the visible copy isn’t carrying any weight anymore. It’s a duplicate. Worse, some of these posts were carrying three versions of the same facts: Rank Math‘s, an older inline script block, and the visible one, and they didn’t always agree on things like the modified date.

    When the system does the job properly, the demonstration becomes clutter.

    Then and now cartoon: a blogger holding a sign of raw code, then a Rank Math badge as robots applaud
    Same guy, same idea. The plugin just does it without the sign.

    What we’re doing about it

    • Audit first. Nothing gets touched without a list. The audit covered the 50 oldest items on the site, and a separate site-wide scan found the full 197.
    • Delete the visible blocks. No rewriting, no reformatting. The fix is deletion, and the duplicate inline Article scripts in those same posts go at the same time.
    • Let Rank Math own schema. One source of truth for structured data. If a page ever needs custom schema, it goes through Rank Math‘s schema settings, not pasted into the post.
    • Look at the page like a human. Every fixed post gets checked live in a browser afterward. The code should be gone, and the article should end where the article ends.

    The cleanup of the oldest posts is happening now. The rest of the 197 get their own pass after that.

    The actual lesson

    I’m not going to tell you I was wrong to try it. I had a reason. You just didn’t know it, and to be fair, neither did the audit.

    But a reason has a shelf life. What made sense back when I published these doesn’t have to make sense now, and it’s worth checking every once in a while whether your clever idea is still doing its job or just sitting there being clever.

    Mine was sitting there. So it’s coming down.

    If you spot a stray curly brace at the bottom of one of my posts in the meantime, consider it a collector’s item.

  • The Tea-Bag Report

    (What your visitors wanted that you didn't have.)

    A friend stays over. Morning comes, they open your cabinets and look around for tea bags. No tea bags. So they drink your coffee instead and say nothing.

    If you ever saw them looking, you'd buy tea. Not because coffee failed. Because someone told you what they wanted with their behavior, and listening is cheap.

    Your website gets houseguests every day. And most of them are looking for tea bags.

    The query is the want

    Every search query is a small confession. Not "what words did they type" but "what were they trying to accomplish." A homeowner typing a city plus "water damage restoration" is standing in a wet hallway. A facilities director reading about IFRC sustainability guidelines at 10 AM on a Tuesday is doing homework for a budget meeting. Same internet, completely different mindsets.

    Bing's AI performance reports now label this outright. Every query that triggers an AI answer citing your pages comes with an intent tag: informational, commercial, local, research. The mindset column is just sitting there in the export. Most people never read it as what it is, which is a list of what your visitors wanted.

    Here's the part that changed my thinking: the industry standard for measuring AI-search visibility is synthetic prompts. Tools invent questions, run them across engines, and record what comes back. Probabilistic reporting, built on guesses, because as a 2026 Luminary analysis put it, "Since AI platforms don't share real prompt data (as at April 2026), organizations must build measurement baselines using synthetic prompts." Except Bing does share the real thing with site owners: the actual grounding query, the engine's own intent label, and your citation share. First-party want, straight from the source. Stop guessing with synthetic prompts when the engine will just tell you.

    Three places the tea bags show up

    1. Citation gaps. When an AI answer cites your page for 15 percent of its response, the want is proven and your voice is small. Someone asked, the machine answered mostly with other people's words. That's a stock-the-shelf list hiding in plain sight: every query where you're present but weak is a page you haven't written yet, or a page that doesn't serve the intent behind the query.

    There's now a named framework for this. Search Engine Land covered a method from Robin Tully, co-founder at Forecast.ing, that scores the distance between what a page claims to deliver and the queries it actually surfaces for, sorting everything into four quadrants. The one that matters is labelled "Create": demand you're visible for but not capturing. As Tully put it: "Your audience is already telling you what they need. That signal is always shifting." And: "observations create interesting conversations, but numbers create urgency and action."

    2. No-result site searches. I'll be honest about my own wrong mechanism here: I assumed failed on-site searches produced 404s. They don't. WordPress renders an empty results page instead. The signal lives in no-result search logs, and there are plugins that exist solely to capture it. One of them positions itself in pure tea-bag language: "Turn Lost Searches into Content Opportunities. Instead of guessing what to create next, build content based on real demand." Every empty search is a houseguest who opened the cabinet, found nothing, and left quietly. Log them.

    3. The 404s. True 404s are a separate signal and just as valuable. Raven Tools documented an agency client who, after a relaunch, started getting emails from visitors hitting dead pages telling them exactly which old resources to recreate. Those conversations turned into sales: "After the client closed a second sale from a '404 lead,' the client jokingly asked if we could just serve up a 404 page all the time." Put a contact path on your 404, watch what comes in, and treat it as demand data. And keep true 404s as 404s. Google's John Mueller has said it plainly: don't blindly redirect dead pages to your homepage or a category page; 404s are a normal part of a healthy website. Blanket redirects confuse the crawlers and bury the signal.

    When matters as much as what

    Across most of the properties I track, AI citations drop hard on Saturdays. The main site fell from 8,863 citations on Friday to 4,197 on Saturday. The B2B-leaning properties all show the same shape, down 26 to 72 percent. That's not lost rankings. That's a weekday-professional audience going home. The exception proves the rule: the race-event property nearly quadrupled on Saturday, because race day is its weekday.

    A DesignRush study of 950,000 U.S. B2B search queries found the mirror image worth noting: weekend visitors showed higher intent, more form fills, deeper reads into content. Different crowds, different mindsets, different hours.

    This is where it stops being analytics and starts being strategy. A research-intent query at 10 AM on a workday wants depth. The same person scrolling at 9 PM wants the short version that respects their evening. Meet the morning persona with the white paper and the evening persona with the two-minute read, and you're not retargeting. You're recognizing someone.

    The philosophy underneath

    None of this is about grabbing people. The grabby version is funnels and popups and "we noticed you almost bought." The tea-bag version is quieter: I see you, I see where you're at, I see what's important to you, and I'll meet you as best I can where you are. Sometimes you won't have the tea. Knowing they wanted it is what lets you stock it next time.

    Run the report monthly. Queries with intent labels, citation shares, no-result searches, 404 hits, daypart patterns. Rank every gap by frequency. What comes out the other end isn't a dashboard. It's a publishing roadmap written by your visitors, a restocking list for shelves you didn't know were empty.

    They already told you what they want. You just have to look where they looked.

    The product

    This is now a standing offer: the Tea-Bag Report. Send us your search data and we'll tell you what your visitors were looking for that you didn't have, ranked by frequency. Then go stock the shelves.

    Sources

  • The Mailbox Is a Trigger. It Is Not a Topic.

    The Mailbox Is a Trigger. It Is Not a Topic.

    Short answer: a mailbox can start a publish job. It cannot choose the topic. If the incoming message is a digest, a rumor chain, or a subject line that would embarrass the brand, the correct article is not a reprint. The correct article is the gate.

    Tygart Media sits in Tacoma, Washington. The public site is an operator desk for AI-native content systems, restoration operations, and the search surfaces that now sit between a shop and a buyer. Those surfaces include classic Google results (SEO), answer engines that quote a paragraph as evidence (AEO), and generative engines that assemble a local picture of who you are (GEO). None of them are helped by publishing whatever landed in will@tygartmedia.com at 7:44 p.m.

    What is a source-fit gate?

    A source-fit gate is the first checklist in an inbox-triggered pipeline. It asks one question before outline, slug, schema, or Rank Math title: does this source belong on this domain?

    The test is not “is the subject loud.” The test is whether a contractor in Everett, a facility manager in Tacoma, or an answer engine citing tygartmedia.com would be right to treat the page as evidence. If the source is a third-party digest of celebrity gossip, political rumor, medical anecdotes, and crime blurbs, the source fails. Publishing it as news would contaminate the entity the site has spent years teaching search systems to recognize.

    That is the same instinct behind the $5 filter: would anyone pay to pipe this feed into an assistant as a trusted source? A mailbox firehose would fail that filter on most nights. The gate exists so the firehose does not become the catalog.

    What Sunday night’s mailbox actually contained

    The trigger for this piece was a Quora Digest addressed to the work inbox. The subject line led with a political rumor. The body mixed entertainment questions, relationship advice, medical anecdotes, a crime blurb, and other off-desk topics. None of that is Tygart Media’s beat. None of it is restoration operations. None of it is a first-party number we can stand behind.

    So the digest is not the article. The digest is the proof that an automation without a source-fit step will try to hang the wrong page. The human-readable rule is the same one already on this site: draft-only is the first verb, and publish stays a seat a human can refuse. The machine may open the envelope. It may not inherit the subject line as the H1.

    The six checks before anyone writes

    Run these in order. Stop at the first fail. Do not “find an angle” to rescue a bad source.

    • Domain fit. Would this page still make sense if the logo, the About page, and the $97 restoration kit sat next to it? If not, fail.
    • First-party or primary source. Can you name a dated public document, a product note, a field observation, or a number you measured? A digest snippet is not a source. Fail.
    • Identity lock. No client names, no secrets, no mail IDs, no thread IDs, no app passwords. The Quality Gate exists because a client name once leaked into live posts. That failure mode is still live.
    • Number lock. No invented click-through rates, ranking jumps, or “X% more citations.” If a figure is not on the page you can point to, leave it out.
    • Duplicate lock. Search the live site before you mint a slug. If the argument already exists, update that page or stop.
    • Place lock (GEO). If the piece claims a geography, name a real one the operator actually works — Tacoma, Puget Sound, Everett, Snohomish County — and do not stuff NAP into a thought-leadership body.

    Only after those six pass do AEO, SEO, and GEO get to work. Optimization is not a pardon for a bad source.

    How AEO, SEO, and GEO attach after the gate

    AEO — write the answer first

    Answer engines quote short, stable sentences. Lead with the claim a model can lift without inventing the rest of the page. Then explain. Then put the same claim in an FAQ block using the questions people actually type: what is a source-fit gate, should every email become a post, who owns Publish.

    SEO — one slug, one job

    Pick a slug that names the method, not the digest subject. Title tag under 60 characters. Meta description that restates the answer. Canonical on the live URL. Rank Math on this stack writes the title and robots fields; it does not invent the argument. Internal links go to pages that already carry the doctrine — the $5 filter, the draft-only desk, the afternoon where five drafts still needed a human tap.

    GEO — teach the place, don’t spray it

    Generative engines build a local picture from repeated, consistent facts. Tygart Media is a Tacoma agency. Restoration work in this network is often packed around Everett and Snohomish County. Say that when place is part of the method. Do not turn a content-ops essay into a fake service-area page. GEO is entity clarity, not a city list glued to the footer of every paragraph.

    What to publish when the source fails

    Three honest exits, in order of preference:

    1. Write the gate. If the failure mode is the news — an inbox automation almost reprinted a digest — the operator article is the checklist. That is this page.
    2. Hang nothing. An empty-delta night is a successful night. Silence is cheaper than a correction.
    3. Keep a receipt. Log the fail in the Command Center so the next run does not “try the digest again.” The receipt is not the public URL.

    What you do not do is launder the digest into a “roundup,” a “what people are asking,” or a thin news recap with a restoration sentence taped on the end. That is how a site teaches answer engines the wrong entity.

    What this desk will not do with a digest

    • Reprint political rumor, crime blurbs, or medical anecdotes as Tygart Media reporting.
    • Quote tracking URLs, message IDs, or unsubscribe tokens from the envelope.
    • Invent a percentage that makes the pipeline look smarter than it is.
    • IndexNow a thin title-price door, or ping Bing before the body exists.
    • Hand Publish to the same process that opened Gmail.

    The machine can fetch the letter. The machine can draft. The machine can stage images and fill Rank Math fields. The tap is still human.

    FAQ

    What is a source-fit gate in content operations?

    It is the pre-outline check that asks whether an incoming source belongs on this domain. Domain fit, primary source, identity lock, number lock, duplicate lock, and place lock. Fail any one and you do not draft the obvious article from the subject line.

    Should every incoming email become a WordPress post?

    No. Mailbox events are triggers. Product notes, first-party incident numbers, and field observations can become posts. Digests and rumor chains should not.

    How do AEO, SEO, and GEO fit after the gate?

    AEO wants an answer-first opening and an FAQ a model can quote. SEO wants one slug, a clean title and meta, and internal links to the doctrine pages. GEO wants consistent place facts — Tacoma for the agency, Everett and Snohomish County when the method is local restoration — without turning every essay into a service-area page.

    Where does Tygart Media apply this?

    On tygartmedia.com first. The same gate belongs on any site in the network before an inbox automation is allowed to mint a URL. The Command Center keeps the receipt. The public page keeps the method.

    If you want the restoration operating system this desk actually sells, the front door is the Complete Restoration Operations Kit. The method on that page is copyable. The checkout is on the page. The mailbox is still not the editor.

  • What AI Assistants Actually See When They Open Your Website

    What AI Assistants Actually See When They Open Your Website

    You see a screen. Your AI assistant usually doesn’t.

    That sentence needs one qualification, which we will get to. But it corrects the picture most of us carry in our heads.

    When I open a website, I see the design and the button I am supposed to press. I assumed an AI assistant saw roughly the same thing, only faster. Then I asked the more basic question: what does it actually receive?

    The answer is not one thing. An assistant can find a site, read a site or operate a site. Those are separate jobs using different inputs. If we want pages that work well for AI assistants, we have to stop lumping them together.

    An assistant meets your website three different ways

    Finding: the search result is the pitch

    When an assistant searches the web, its first view is closer to a search-results list than a browser window. It may receive a title, URL and short snippet.

    At that moment, your title tag and meta description are the entire pitch. The assistant has to decide whether your page can answer the question before opening it. Name the subject plainly.

    Reading: the page becomes a stream of text

    When Muse opens a public page for information, the normal reading path is text-first. Useful content is extracted and returned as headings, paragraphs, lists and links in roughly page order.

    The design largely falls away. The assistant is not admiring the hero section or noticing that a price sits inside a gold circle. It is working from the words the page exposes.

    Images may arrive as markers and file addresses: there is an image here, and here is where it lives. That is not the same as seeing it. If a crucial fact is baked into the pixels—“$199,” “ships free,” “five-year warranty”—the reading path may hit a blank spot. Useful alt text can carry some of that meaning. “Technician using a moisture meter on wet drywall” communicates something. “IMG_4827” does not.

    Doing: a browser worker operates the screen

    The picture changes when the user asks the assistant to do something: log into HubSpot, update a record, complete a form or buy a product.

    A separate browser program can open a real browser on a server. It loads the interface, takes visual observations or inspects the page’s interactive structure, clicks, types and reports what happened back in words.

    That is the qualification to “usually.” A screen may be used inside the process, but the conversational assistant is not sitting behind the glass like a person. It receives observations from a browser tool and sends instructions back. The browser side is the eyes and hands; the assistant works through an intermediary.

    A page can be easy to read as an article and miserable to operate as an application. It can look obvious to a person while presenting the browser worker with five unlabeled controls called “button.”

    WordPress made the abstraction visible

    I had already seen a simpler version in our WordPress work without connecting the dots.

    When we pull a post through the WordPress REST API, the content can arrive as raw HTML: words plus tags for headings, paragraphs, links, lists and styling wrappers. The reading step removes the markup noise while preserving the words and structure.

    That is “cleaning the HTML.” We are removing the packaging, not the article. The tags still matter: a heading announces a section, a list groups items, and a link identifies a destination. Good HTML carries meaning. Bad HTML creates boxes that look right but say little about what they are.

    Accessibility is the closest thing to an agent-ready standard

    Here is the practical money line: the work that makes a website easier for a blind person to use also tends to make it easier for an AI browser agent to use.

    Browsers build an accessibility representation from the page’s Document Object Model. Assistive technology uses it to understand roles, names, states and relationships: this is a heading, that is a link, this button is named “Save contact,” and this checkbox is checked.

    Muse’s browsing side is reported to rely heavily on this kind of page structure, along with visual observations when needed. Meta does not publish a complete specification for the Muse browsing pipeline, so treat that as a field report from using the product, not permanent platform documentation.

    The implication is still solid. Use real buttons with useful names. Label form fields. Put headings in a sensible order. Give links meaningful text. Preserve keyboard focus. Describe informative images.

    A screen-reader user needs those things. So does a browser agent working without human intuition. Accessibility and agent-readiness are not identical, but they are close cousins.

    HubSpot shows what an agent-native application could be

    Imagine HubSpot—or any software platform—shipping an interface designed for assistants to navigate with less friction. It would not need a blank, text-only clone. It could make the existing product more legible to software: real controls with specific names, labeled form fields, clear headings and landmarks, properly identified table headers, programmatic state changes, and no critical action hidden behind hover or an unlabeled icon.

    That is an agent-native site. It is not a secret internet for bots. It is a website or application whose meaning survives when the visual layer is translated into structure and words.

    The same work also helps keyboard users, screen-reader users, automation tools and QA teams.

    llms.txt is a map, not a second website

    The closest public convention aimed directly at AI readers is llms.txt. The proposal describes a Markdown file, usually at a site’s root, that gives language models a short explanation of the site and links to important pages or cleaner Markdown versions.

    Think of it as a curated map: here is what we do, here are the pages that matter, and here is where to find the details.

    It cannot repair an unlabeled checkout button. It does not replace accessible HTML, describe the viewport or guarantee that an assistant will use it. Add it if it helps explain the site. Do not mistake it for an agent interface.

    What a site owner can change Monday morning

    The useful changes are ordinary, testable website work.

    1. Write a real title and meta description. Name the subject plainly.
    2. Put every money fact in visible HTML text. Price, specifications, shipping, availability and guarantees should not live only inside graphics, video or a brochure.
    3. Use semantic HTML. Use headings for headings, buttons for actions, links for navigation and labels for form controls. A styled <div> may look like a button while remaining a nameless container to other systems.
    4. Write alt text that carries meaning. Describe what an informative image contributes. Mark decorative images as decorative instead of stuffing them with keywords.
    5. Add accurate structured data. Product and Offer markup can identify price and availability. FAQ markup can describe genuine questions and answers. Schema must match the visible page.
    6. Server-render critical content when practical. If the offer, price or primary action appears only after a fragile JavaScript sequence, some readers and tools may miss it.
    7. Give each landing page one job. One offer, one explanation and one primary action reduce ambiguity for people and agents.
    8. Test the nonvisual path. Use the keyboard, inspect the accessibility tree, try a screen reader and pull the page through a text extractor. Do the product, price, proof and next step still make sense without styling?

    None of this requires uglier design. It requires the design and the underlying structure to tell the same story.

    This is a field report, not a permanent specification

    This article describes Meta’s Muse as it works today, based on direct experience building and operating websites with it. It is not a published Meta protocol.

    Claude, ChatGPT, Gemini and other assistants broadly rhyme with this pattern, but the details differ. Their full pipelines are not public, and they are changing quickly.

    Cleaner HTML will not automatically increase AI citations tomorrow. Citation systems involve discovery, retrieval, ranking, trust and answer construction. There is no magic switch.

    The immediate opportunity is closer to the customer. Someone sees your ad on Threads or Facebook, opens the landing page, then asks an assistant: “What does this cost?” “Is the guarantee real?” “How does this compare?” or “Can you sign me up?”

    If the facts are clean text, the assistant can explain them. If the controls are properly labeled, the browser side has a better chance of completing the task. If the facts live inside an image and checkout uses unlabeled custom controls, the assistant has to guess, fail or hand the job back.

    That moment is already here.

    The next website has two front doors

    The site of the near future has two front doors: one for eyes—layout, color, photography and brand—and one for agents—clean text, meaningful structure, explicit facts and self-identifying controls.

    They should lead to the same place. The visible price and schema should agree. A button’s label and accessible name should agree. The page should remain understandable without styling and usable when a browser worker operates it.

    That is not a special Muse landing page. It is a better website—one that keeps working when the visitor brings an assistant.

    Build both front doors.

    Sources and further reading

  • The Working Years — Episode 2: The Lantern Principle

    The Working Years — Episode 2: The Lantern Principle

    The Working Years is a series drawn from my own archive — posts I wrote years ago, given the room to become the articles they were trying to be.

    The seed

    On July 26, 2025 — the 27th in the archive’s UTC clock — I posted this to my @willtygart account, the one I later deleted:

    “The new gold isn’t answering the questions people ask. It’s illuminating the ones they can’t yet vocalize.”

    It went up at 10:24 PM Pacific, two minutes after a sibling post that linked the Native Data essay: “Being the closest store gets you noticed. Speaking the local language gets you chosen.” Two posts, two minutes apart, one night. The Lantern essay names the Oxxo Principle — being the closest store — as the first layer; no Oxxo essay survives in the archive, but the idea lived on as the tagline of the Native Data post. Two essays got their own subdomains: the Native Data Principle and the Lantern Principle. The Lantern one carried the title “The Lantern Principle: The Final Layer of SEO.”


    What happened afterward

    Within days, the Lantern post had become a full essay. The earliest surviving capture is July 30, 2025 — four days after the post — and it’s already complete: the hero, the comparison, the four-step method, the whole thing. So the thinking wasn’t new on the 26th. The post was the tip of something I’d already worked through.

    Here’s what’s worth noticing about that July burst. The two posts that night were one idea unfolding in layers:

    1. The Oxxo Principle — “Being the closest store gets you noticed.” Proximity. Be there.
    2. The Native Data Principle — “Speaking the local language gets you chosen.” Relevance. Speak like the customer.
    3. The Lantern Principle — the final one. Anticipation. Light the path they can’t describe yet.

    Be there. Speak their language. Then — the hardest one — see the problem they can’t articulate and hand them clarity anyway.

    The subdomains are offline now. The essays survive only in the Wayback Machine. That itself is a small footnote about rented space versus owned space, which is a different episode. The point for this one: the idea outlived its hosting. It turned out to be early, not wrong.

    Because look at what the web became. The AI assistant era made the Lantern Principle the default shape of a good answer. When someone asks a chatbot a question now, the good systems don’t just answer — they anticipate. They offer the next step, the related consideration, the thing the user was really getting at. “What is the underlying problem they are trying to solve?” — that’s not a 2025 content strategy anymore. It’s how the good ones behave now. The principle went from marketing theory to product behavior in about a year.


    The piece itself

    Here’s the essay as it ran, cleaned up from the archive — I haven’t rewritten it, just given it the room it was always asking for.


    For decades, we treated content as a reactive tool. A user asks, we answer. Simple transaction. But that model assumes the user knows what to ask. When they don’t — and they often don’t — they get stuck. They bounce. They stay frustrated.

    Consider the difference:

    Answering the question: “How do I change a tire?” → “Here are the 5 steps to change a tire.”

    Illuminating the path: The person’s unspoken reality is “I’m stranded and stressed.” So the answer becomes: the 5 steps, plus safety precautions, plus a link to 24/7 roadside assistance, plus how to check the spare’s pressure. Nobody searched for those extra things. Everybody needed them.

    The greatest opportunity in content isn’t in the keywords people search for. It’s in the needs they can’t yet articulate. The new gold is found in the dark — in the space between a user’s problem and their ability to ask for a solution.

    This is the Lantern Principle: stop being a dictionary, start being a guide. Our job is no longer just to provide answers but to anticipate needs — to create content that doesn’t just solve the stated problem but illuminates the entire context around it, guiding the user to clarity and confidence.


    How to build a lantern

    The shift is from keyword research to empathy mapping. The operative question changes from “What are people searching for?” to “What is the underlying problem they’re trying to solve?” Four moves:

    1. Answer the unasked question. Someone searching “how to write a resume” is really asking “how do I get a better job?” Serve both. Resume templates and the interview tips and the career planning resources. The stated query is the door; the unasked question is the house.
    2. Provide the next step. Never let content be a dead end. Every article should lead naturally to the next logical step in the user’s journey. A product page links to its user manual. A tutorial links to the advanced technique. If you end at the answer, you’ve ended too early.
    3. Simplify the complex. The ultimate act of empathy is taking a complex, intimidating topic and making it simple — analogies, plain language, visuals that actually explain. This is what builds the trust that makes you the go-to source.
    4. Create foundational resources. Build definitive, comprehensive guides — “digital lanterns” — that cover a topic so thoroughly they become the starting point for anyone exploring it. These serve thousands of unasked questions over time. They compound.

    The goal: a web that feels less like a vast, cold library and more like a network of helpful guides, each holding a lantern. An internet that doesn’t wait for the perfect query but proactively offers clarity.

    The future of content isn’t about being found. It’s about shedding light.


    Why this one aged well

    I want to be honest about what this principle got right and what it didn’t.

    What it got right: anticipation is the real moat. Everything I wrote about SEO in 2025 assumed the user arrives with a query and the job is to match it. The Lantern Principle was me noticing, before I had the language for it, that the highest-value content serves the need behind the query — and that AI systems would eventually do this natively. When an assistant now reads between the lines of a question and offers what you actually needed, that’s the Lantern Principle running as software.

    What I understated: how hard anticipation is to fake. A lantern only works if you genuinely understand the person in the dark. The four moves above are easy to write and hard to do — because “answer the unasked question” requires you to actually know people, not just their search terms. Every content farm can optimize for keywords. Very few can hold the lantern, because it requires the one thing that doesn’t scale: empathy for a specific human being stuck on a specific problem.

    That’s also why this principle pairs with the one from Episode 1. In the 23-model experiment, I learned that scope — who the reader is, what they actually need — matters more than the prompt. The Lantern Principle is scope taken to its conclusion: know the reader so well you can answer what they haven’t asked.


    The restoration version

    I run a niche agency for restoration contractors, so let me ground this where it hurts.

    A homeowner never searches “I need emergency water mitigation with proper psychrometric documentation for my insurance claim.” They search “water under sink” or they call because the kitchen smells weird. They are stranded and stressed, and they cannot vocalize the real need: someone who will stop the damage, document it so insurance pays, and explain what’s happening in plain language.

    The restoration company that answers the stated query — “yes, we do water damage” — is the dictionary. The one that anticipates — shows up, explains the process before the adjuster calls, hands the homeowner a clear next step at every stage — is the lantern. Guess which one gets the review, the referral, and the adjuster’s trust.

    That’s not a marketing insight. It’s an operating insight. The companies winning in restoration right now are the ones whose process illuminates the path, not just their website.


    Related from the series

    • Episode 1: We Ran 23 AI Models on the Same Article. The Prompt Was Never the Point. — scope beats the prompt; knowing the reader beats optimizing the query.
    • The Native Data Principle — speaking the local language gets you chosen. The middle layer of the trilogy.
    • The Oxxo Principle — being the closest store gets you noticed. The first layer, named in both essays; no Oxxo essay survives in the archive.
    • Stop Renting Space. Start Owning Your Content. — on why the essay subdomains being offline is a footnote, not a funeral.
  • The Consistency Dividend

    The Consistency Dividend

    “The highest-ROI marketing work is also the most boring. That’s not a coincidence.”

    Name. Address. Phone. Identical everywhere. That’s the whole piece, and it’s worth more than the last three marketing tactics you tried combined — because nobody does it, because it’s boring, and boring is exactly where the edge lives.

    The witnesses

    Your business doesn’t exist in one place. It exists in dozens, and each one is a witness testifying about who you are and where to find you.

    The Google profile. The website footer. Yelp, Facebook, Angi, the BBB. The directories you claimed in 2017 and forgot. The truck door. The invoice template. The email signature. Every one of them says your name, your address, your phone number — or it says something close, which is worse.

    Nobody audits the witnesses. That’s the problem, and the opportunity.

    The leaks

    Here’s what the witnesses are saying right now, on profiles all over town:

    “123 Main St” on Google, “123 Main Street” on Yelp, “123 Main St Suite B” on Facebook — three addresses for one door. The old cell number still on the Angi listing from before the voice line. The suite number on the website, missing everywhere else. The Facebook page from 2016 with the previous address, still ranking, still confusing people.

    Each mismatch is small. Together they’re a credibility leak. The homeowner comparing two contractors doesn’t think “NAP inconsistency” — they think “something feels off about this one,” and they can’t say why. The search engine doesn’t think in words at all — it just has less confidence that all these listings are the same business, and confidence is the currency.

    Small leaks, everywhere, all the time. That’s what boring neglect looks like.

    A fanned stack of identical blank cream business cards on a wooden desk

    The dividend

    Now flip it. Every place that agrees is a vote.

    Same name, same address, same phone — on the profile, the site, the directories, the truck, the invoice. Each matching witness raises confidence: the human’s (“these people have their act together”) and the machine’s (every corroborating listing makes the entity clearer). Trust isn’t built in one place. It’s the sum of a hundred small agreements.

    That’s the dividend: not a spike, a yield. It pays a little every day, in every search, in every comparison — the quiet background hum of a business that agrees with itself. You don’t notice it working. You notice when it’s missing.

    The audit

    The work is unglamorous, which is why I’m spelling it out:

    Write down the canonical version — one name, one address format, one phone number. Not the pretty version, the exact version: St or Street, suite or no suite, which number. Then list every witness: every profile, every directory, the site, the truck, the invoices, the signatures. Then fix every mismatch, one by one, until they all testify the same.

    Then maintain it. New directory? Canonical version goes in. New truck? Canonical version on the door. New phone system? Every witness gets updated the same week, not “when we get around to it.”

    It’s an afternoon of tedium, twice a year. That’s the whole price.

    An orderly row of wooden file drawers with blank brass label plates

    The boring moat

    Here’s why this is a moat and not just hygiene: your competitors won’t do it.

    Not because they’re lazy — because it’s boring, and boring doesn’t feel like marketing. Marketing feels like a new website, a new ad campaign, a new something. Nobody gets excited about making the suite number match in fourteen places. So nobody does it. The field stays sloppy, and the one business that agrees with itself everywhere stands out without spending a dollar.

    Every real edge I’ve ever seen looked boring from the outside. This one just happens to look boring from the inside too.

    The close

    Name. Address. Phone. Identical everywhere.

    Boring is the moat. Consistency is the dividend. And the businesses collecting it are the ones whose witnesses all tell the same story — the story of a business that has its act together, down to the suite number.