Secure checkout via Square — all major cards accepted
You can copy this method and run a ten-post pilot yourself. Buy Now is Will connecting the site, picking the ten, running the three-layer pass on each, and sending the 60-day impact report.
The Square catalog names this SKU “Connection + 10 Posts.” The /siteboost/ hub calls it the best-value door at $597. The public vertical pages (law firms and the rest of the cluster) spell out the same package: Site Connection and Audit, ten existing-post optimizations, and a 60-day impact report. They price the pieces at $767 if you bought them separate ($297 audit + 10 × $47). The bundle is the cheaper way to get a first measured pass.
What the pilot is, and is not
It is a retrofit of ten published posts. SEO + AEO + GEO + schema on each. Changes via the WordPress REST API. No plugin left behind. Results looked at around day 60. It is not a retainer, not a redesign, and not ten brand-new articles. New Article Publishing is a different SKU. The monthly retainer is the ongoing door after you like the pilot.
Self-hosted WordPress only. Squarespace, Wix, and Webflow are out. Posts, not Pages, unless you put a specific Page in writing.
How to run the pilot yourself
Week 0. Connect and baseline
Do the connection and audit first. The method is on the Site Connection and Audit page. Short version:
Create a WordPress Application Password (Users → Profile). Not the login password.
Test GET /wp-json/wp/v2/users/me with that user and app password. If that fails, stop. Nothing else will work.
Pull published posts (per_page=100, paginate if you have more). Inventory every post: title, slug, word count, excerpt/meta, categories, tags, featured image, internal links in, internal links out, schema present or not, FAQ present or not.
Write four artifacts and keep them. Content inventory. Schema gap report. FAQ gap report. Before baseline (the numbers you will compare at day 60: rankings and impressions you can actually see in Search Console, plus a note on AI visibility if you check Perplexity / ChatGPT / AI Overviews on a few queries).
wp-site-audit’s priority stack: Critical = taxonomy and metadata problems. High = SEO / AEO / content quality. Then link and expansion opportunities. Use that order when you pick the ten.
Pick the ten
Highest-opportunity existing articles, with your approval before anyone starts rewriting. That is the rule on the public SiteBoost pages. A practical pick list, from the same audit fields:
Posts that already get impressions but have empty meta, no FAQ, and no schema. Those move first.
Posts over 500 words that are still missing the AEO and GEO layer. Do not spend the pilot on stubs.
Posts that sit on a real query (you can name the keyword). Skip diary posts and leftover test content.
A mix across your actual topic pillars, not ten posts from one tag.
Write the ten URLs down. Get a yes. Then do not swap them mid-pilot unless a post is broken.
Weeks 1 to 3. Ten existing-post passes
For each of the ten, run the same method as Existing Post Optimization:
SEO: title 50 to 60, slug, meta 140 to 155, H2/H3, keyword in the first 100 words.
AEO: 40 to 60 word definition box, question H2s with 40 to 60 word answers, 6 to 8 FAQ pairs, FAQPage JSON-LD.
Article schema. Validate. Two to five internal links into the rest of the cluster. IndexNow on the update.
Sequence on a single post is SEO, then AEO, then GEO, then schema, then interlink. That is wp-full-refresh. Do not GEO a post whose title and meta are still empty.
If a chosen post is under 500 words, expand it first (append real sections, do not overwrite) or swap it for a thicker post on the same topic. Thin content wastes a slot.
Day 60. Impact report
The public pages measure three things: traditional rankings and impressions, People Also Ask / snippet placements, and AI citation visibility. Pull Search Console for the ten URLs (and the queries they were aimed at) versus the before baseline. Recheck the same AI prompts you wrote down in week 0. Do not invent a win. If nothing moved, say so. The report is the point of a pilot. You are deciding whether a retainer is worth it.
Traditional SEO on competitive terms is often 60 to 90 days. The same pages note that FAQPage / PAA and some AI crawlers can show sooner (they cite 2 to 4 weeks for PAA). Treat those as ranges from the public SiteBoost copy, not a guarantee.
What you should have on disk at the end
Connection notes (site URL, that an app password was created, who holds it).
The four audit artifacts from week 0.
The list of ten URLs and the before/after for each (title, meta, word count, FAQ count, schema types).
The 60-day comparison. What moved, what did not, what you would do next (more existing posts, new articles, or stop).
If you want Will to run the pilot
You can do every step above with an Application Password and a spreadsheet. Buy Now is the packaged pilot: Will connects, audits, agrees the ten with you, runs the three layers on each post, and sends the 60-day impact report. Same Square button at the top. $597.
After a pilot you like, the Monthly Retainer is 10 existing-post passes plus 4 new articles per month. If you only need the connection and the baseline, buy Site Connection and Audit. If you only need one post touched, buy Existing Post Optimization.
Frequently Asked Questions
How does the pilot work?
After checkout, I reach out by email within 2 business days to kick off: I connect the site, we agree on the ten posts, I run the three-layer pass on each, and you get the 60-day impact report.
Is there a refund policy?
Before I start the pilot work, full refund on request. Once posts are in production, the fee is earned — the 60-day report is yours either way.
Secure checkout via Square — all major cards accepted
You can copy this method and publish the article yourself. Buy Now is Will researching, writing, optimizing, and publishing one new WordPress post for you.
SiteBoost New Article Publishing is a new post, not a refresh of something already live. The /siteboost/ hub prices it at $97 per article. The same three layers as an existing-post pass still apply. You just start from a brief instead of from a published URL.
The six-step workflow
This is the unified content workflow from the operator’s guide on tygartmedia.com. One draft. SEO, AEO, and GEO built in. Not three versions of the same piece.
1. Keyword and intent
Name the target query. Classify intent: informational, navigational, commercial, or transactional. Look at what already ranks and match the format Google is already rewarding. This step is ordinary SEO. Do not skip it because you are “writing for AI.”
2. Question landscape
Search the keyword. Collect People Also Ask questions, related searches, and autocomplete variants. Group them. Those groups become H2s and FAQ items. The operator guide budgets 15 to 20 minutes here. This is the AEO setup. If you skip it, you will write headings that feel like an outline and not like queries.
3. Write with the direct-answer pattern
Write the article once, with both SEO and AEO in the draft:
Primary keyword in the H1 and in the first 100 words.
Every major section is a question-shaped H2, then a 40 to 60 word answer, then the depth.
Internal links with descriptive anchors to posts that already exist on the site. If the site is new and there is nothing to link to, note the gaps. Do not invent destinations.
A 40 to 60 word definition box near the top.
The WordPress Publish skill’s quality bar before anything goes live: title 50 to 60 characters with the primary keyword, meta 140 to 160 characters, a unique H1, at least one direct-answer section, a FAQ with 3 to 5 Q and As on a new article (SiteBoost existing-post passes use 6 to 8; for a new article start at 3 to 5 and add more if the PAA list is real), Article JSON-LD, FAQPage JSON-LD, and at least one cited fact per major section.
4. GEO enhancement
After the draft exists, do a factual-density pass. The operator guide budgets 20 to 30 minutes on a 1,500-word article. For every claim: a number, a date, a named organization, or cut it. The citing-sources article is the house rule:
Name the organization in the text, not only in a hyperlink.
Link the primary source. If it is paywalled, link a credible secondary that cites it.
Put a sources list at the bottom.
Show a last-updated date near the byline.
Put datePublished and dateModified in Article schema.
Do not add fake statistics to look dense. The operator guide calls that out as a backfire when AI systems cross-check you.
5. Schema
Minimum on a new SiteBoost article: Article (or BlogPosting) plus FAQPage. Add HowTo if the piece is genuinely step-by-step. Add BreadcrumbList if the theme does not already emit it. Add Speakable on the definition box and one other self-contained block. JSON-LD in the post, validated with Google’s Rich Results Test. The schema injection sprint is the same sequence: pick the type, generate valid JSON-LD, inject, validate, fix failures.
SiteBoost content standards also embed an LLMS.txt HTML comment on the page. A short seed paragraph, not a second article.
6. Pre-publish audit, then publish
Run the three-layer checklist. Title, meta, headings, snippet readiness, factual density, schema validation, entity signals. Then publish as a post, not a page.
The production pipeline used on Tygart Media sites is: brief (content-brief-builder) to draft to SEO to AEO to GEO to schema to taxonomy to interlink to publish (wp-content-pipeline). content-quality-gate sits in front of publish and flags unsourced claims. You can do that as a human checklist if you are not running Claude skills.
Taxonomy and internal links
Assign 1 to 2 categories that are real content pillars, never Uncategorized. Assign 5 to 10 tags that cover topic, use case, audience, and format. That is the wp-taxonomy-fix rule. Then place 3 to 5 internal links to related posts in the same cluster, plus outbound links to the sources you named. Hub and spoke. The new post should not be an orphan on day one, and it should not be a dead end.
IndexNow
On publish, ping IndexNow. Official plugin, or Rank Math / Yoast Instant Indexing. Confirm the URL in Bing Webmaster Tools. New posts that sit in a sitemap waiting for a crawl waste the first week.
What “done” looks like on one new article
Brief: target keyword, intent, PAA list, existing internal-link targets, sources you will actually cite.
Draft written with definition box, question H2s, and sourced facts.
Title 50 to 60, meta 140 to 160, slug clean.
FAQ section + FAQPage schema. Article schema with both dates.
Categories and tags set. 3 to 5 internal links. Sources list.
Rich Results Test pass. IndexNow ping. Status = publish (or draft if you want a human read first).
Self-hosted WordPress only. Squarespace, Wix, and Webflow are not this SKU. Do not modify existing Pages to “make room” for the article. Publish a post.
If you want Will to write and publish it
You can run the six steps in your own editor. Buy Now is the packaged, done-for-you article: Will writes it, runs the three layers, publishes it to your site, and emails you the URL. Same Square button at the top. $97 per article.
A single new post next to a neglected library is a weak play. If the existing posts are empty of FAQ, schema, and meta, optimize those first (Existing Post Optimization, or the Pilot Bundle for ten). If the site is not connected yet, start with Site Connection and Audit.
Frequently Asked Questions
How does it work?
After checkout, I reach out by email within 2 business days with the intake details and a start date.
Is there a refund policy?
Before work starts on your posts, full refund on request. Once a post is optimized or published, that portion of the fee is earned.
Secure checkout via Square — all major cards accepted
You can copy this method and do it yourself on one published WordPress post. Buy Now is Will running the same three-layer pass on that post and pushing the changes live for you.
SiteBoost Existing Post Optimization is one post, already on your site. Not a new article. Not a redesign. The public SiteBoost pages call this the post-publish layer: SEO, then AEO, then GEO, written back through the WordPress REST API. No plugin install. Self-hosted WordPress only.
What you are optimizing
Pick one published post (post type post, not a Page). Fetch it. Read it as it sits today. Then run three passes in this order. The operator guide on tygartmedia.com is explicit: the layers are concentric, not three separate rewrites. One piece of content. Structure, density, and markup.
Pass 1. SEO
This is the foundation. Do not skip it to chase snippets or AI citations. The SiteBoost vertical pages and the wp-seo-refresh skill agree on the same fields:
Title tag. Primary keyword front-loaded. Target 50 to 60 characters. This is the H1 / browser title, not a clever headline that hides the query.
Slug. Lowercase, hyphenated, keyword-rich. Change it only if the current slug is junk. If the post already ranks on the old URL, leave the slug and add a redirect if you must change it.
Meta description. 140 to 155 characters on the SiteBoost sales pages, 155 to 160 in the wp-seo-refresh skill. Write a real sentence a human would click. Empty meta is the most common miss.
Heading structure. Real H2 / H3 hierarchy. No skipped levels. No H2 that is just a label with no answer under it.
Primary keyword in the first 100 words.
Note internal link opportunities. You will place them after the GEO pass, not while you are still rewriting the title.
Workflow from wp-seo-refresh: fetch the post with context=edit, analyze current on-page SEO, name the target keyword from the actual topic, generate the new title / meta / headings, write the post back, then report what changed.
Pass 2. AEO
Answer Engine Optimization. Same post. Restructure so a featured snippet or a People Also Ask box can lift a clean answer.
Add a 40 to 60 word definition box near the top. One sentence that answers “what is this?” without a wind-up.
Turn implied questions into H2s. Under each H2, put a 40 to 60 word direct answer, then the depth.
Add 6 to 8 FAQ pairs that match real People Also Ask questions for the topic. The older WordPress Publish skill used 3 to 5. The SiteBoost vertical pages use 6 to 8. Use 6 to 8 on a SiteBoost-style pass.
Add FAQPage JSON-LD for those pairs. Question and acceptedAnswer. Valid markup, not a plugin dump.
wp-aeo-refresh also looks for list-shaped answers and natural-language replies a voice result can read. If a section is a process, a numbered list beats a paragraph.
Pass 3. GEO
Generative Engine Optimization. Make the post citable by ChatGPT, Perplexity, Claude, Gemini, and Google AI Overviews.
Entity saturation. Name the real organizations, standards, statutes, places, and tools the topic depends on. Entity density, not keyword stuffing.
Factual density. Replace “many companies” and “studies show” with a named source and a number you can actually point to. If you cannot name the source, cut the claim. The citing-sources article on tygartmedia.com is the rule: name the organization in the text, link the primary source, put a sources list at the bottom.
Speakable blocks. Short, self-contained sentences an AI or a voice assistant can lift without the rest of the page.
LLMS.txt as an HTML comment. A seed paragraph the page can carry for LLM citation signals. SiteBoost content standards put this on every page.
Visible last-updated date near the byline, and dateModified in Article schema that matches a real edit. Do not bump the date without changing the content.
wp-geo-refresh also asks for context richness (define the term, do not just mention it) and semantic clarity (connect related concepts in the same section).
Schema and IndexNow
After the three passes, the post should carry Article JSON-LD (headline, author, publisher, datePublished, dateModified) plus FAQPage. BreadcrumbList if the theme does not already emit it. Validate with Google’s Rich Results Test before you walk away. The schema injection sprint on tygartmedia.com is the same rule: pick the type the content actually is, inject JSON-LD, validate, fix failures.
Then tell the engines the URL changed. IndexNow: official WordPress plugin, or the IndexNow / Instant Indexing toggle in Rank Math or Yoast. Confirm the ping in Bing Webmaster Tools. A publish or an update that nobody recrawls is a pass you did for yourself.
What you do not touch
Posts, not Pages. SiteBoost does not rewrite service pages, bios, or the homepage unless someone asked in writing. Do not install a plugin to do this. Do not empty the excerpt into raw JSON. If the excerpt is polluted, strip it (that is the wp-clean-meta job) and write a real meta description.
A honest one-post checklist
Current title, slug, meta, word count, FAQ count, schema present or not. Write those six lines down. That is your before.
SEO pass. Title, slug, meta, headings, first 100 words.
Two to five internal links to related posts on the same site, descriptive anchors, plus one or two outbound links to primary sources.
Validate schema. Ping IndexNow. Write the after: new title, new meta, new word count, FAQ count, schema types.
If the post is under 500 words, expand it before you call the SEO pass done. wp-content-expand’s rule: find H2s under 150 words, add 250 to 400 words of real section, append, do not overwrite. Thin posts do not earn the AEO or GEO layer.
If you want Will to do this post
You can run the three passes in the block editor this afternoon. Buy Now is the packaged, done-for-you version: Will connects, refreshes that one existing post through the REST API, and emails you what changed. Same Square button at the top of this page. $47 per post.
If you have ten posts that all need this, the Pilot Bundle is the volume door. If you do not have a connection or a baseline yet, start with Site Connection and Audit. This SKU assumes the post already exists and you already know which one.
Frequently Asked Questions
How does it work?
After checkout, I reach out by email within 2 business days with the intake details and a start date.
Is there a refund policy?
Before work starts on your posts, full refund on request. Once a post is optimized or published, that portion of the fee is earned.
Azure Neural TTS vs Google Cloud Text-to-Speech: Audio Versions of Every Article
Adding an audio version of every article is one of those low-effort, high-leverage moves: it makes your content accessible to people who’d rather listen, it gives you a “play this article” widget that lifts time-on-page, and the audio file itself becomes another thing search and assistants can surface. The work is entirely automated — text goes in, an MP3 comes out — so the only real decisions are which voice sounds least like a robot and which free tier covers your back catalog.
We auto-generate audio versions of the same articles on both Azure Neural TTS and Google Cloud Text-to-Speech, on the free tiers, and listen. Short answer: this one’s an honest toss-up. Both produce genuinely natural neural voices, both give you SSML control, and both run our audio pipeline for $0/month. Azure’s free tier is 500,000 characters/month (~60–80 article audio versions of neural voices); Google’s is 1,000,000 characters/month of Standard voices and 1,000,000 characters/month of WaveNet/Neural2 premium voices. Pick by ecosystem and by which voice you’d rather hear.
This is the breakdown from the running lab on tygart.media — voice naturalness, SSML control, voice variety, free ceilings, and the accessibility/SEO payoff.
The free-tier ceilings
Free-tier ceilings for Neural TTS vs Cloud TTS.
How we do it
Azure
Google Cloud
Verdict
Free neural/premium chars/month
500,000 (Neural)
1,000,000 (WaveNet/Neural2)
Google — 2× headroom
Free standard chars/month
n/a (neural is the tier)
1,000,000 (Standard)
Google on raw volume
Roughly how many article audios
~60–80 neural/mo
~140 premium/mo
Google
Always-free
Yes
Yes
Tie
Our actual bill
$0
$0
Tie where it counts
A 1,200-word article runs around 6,500–7,000 characters, so Azure’s 500K neural budget covers roughly 60–80 full article audio versions a month, and Google’s 1M premium budget covers roughly twice that. For a publisher shipping a handful of articles a week, both stay free with room to spare — the 2× gap only bites if you’re voicing a large back catalog in one go.
Voice quality and SSML control
Voice quality and SSML control.
This is where you actually choose, and it’s genuinely close.
How we do it
Azure
Google Cloud
Verdict
Voice naturalness
Excellent, very expressive
Excellent, very natural
Tie — both clear the “robot” bar
Voice variety
Huge neural catalog, many styles
Large WaveNet/Neural2 catalog
Slight edge Azure on styles
Speaking styles / emotion
Yes (cheerful, newscast, etc.)
More limited emotional styles
Azure
SSML control
Full SSML + style/prosody tags
Full SSML
Azure, slightly
Custom voice
Yes (custom neural voice)
Yes (custom voice)
Tie
Languages / locales
140+ locales
50+ languages, many voices
Azure on locale breadth
Both clear the bar that matters: neither sounds like a 2010-era text-to-speech engine, and a casual listener wouldn’t immediately clock either as synthetic. Azure edges ahead on expressiveness — its neural voices support named speaking styles (newscast, cheerful, empathetic) that are perfect for an article read-aloud, and its SSML supports fine prosody control. Google’s Neural2 voices are beautifully natural and, to some ears, a touch warmer; the emotional-style controls are just a little thinner.
The accessibility and SEO payoff
Accessibility and SEO payoff of audio articles.
The audio isn’t only a nice-to-have. It does real work.
How we do it
Azure
Google Cloud
Verdict
Accessibility win
Listen instead of read
Listen instead of read
Tie
Output format
MP3 / WAV / streaming
MP3 / LINEAR16 / OGG
Tie
Pipeline integration
REST + SDKs
REST + SDKs
Tie
Time-on-page lift
Audio widget keeps people on page
Same
Tie
An audio version gives screen-reader users and “I’d rather listen” users a first-class way to consume the piece, and the on-page player tends to lift dwell time — a signal that doesn’t hurt. The mechanics are identical on both clouds: feed text, get an MP3, embed it.
What surprised us
Both are genuinely good now. We expected one to clearly win on naturalness and neither did — the synthetic-voice era is over on both clouds.
Azure’s speaking styles are the sleeper feature. Being able to render an article in a “newscast” or “cheerful” style without writing prosody by hand made the read-alouds noticeably more engaging.
Google’s free character budget is the bigger one. 1M premium characters is real headroom; if you’re voicing a back catalog, that matters more than a half-point of naturalness.
The MP3s are interchangeable. Once embedded, listeners couldn’t reliably tell which cloud voiced which article in a blind test we ran on ourselves.
The takeaway
Pick Azure Neural TTS if you want maximum expressiveness — named speaking styles, fine prosody control, and the broadest locale catalog — and your Microsoft ecosystem is already where the rest of your stack lives. The 500K free characters cover a normal publishing cadence comfortably.
Pick Google Cloud Text-to-Speech if you want the larger free character budget (1M premium) for voicing a big back catalog, or you simply prefer the warmth of the Neural2 voices, and your stack is GCP-centric.
For us this is the rare comparison with no loser. We run the pipeline on whichever cloud the rest of that article’s workflow already lives on — and the listener can’t tell the difference either way.
This is part of our “Two Clouds, One Site” series — we run the same media property on both Azure and Google Cloud on the free tiers, generating audio versions of the same articles on each to hear where the voices differ. The lab lives on tygart.media; the findings publish here.
How many free characters do Azure and Google text-to-speech give you per month?
Azure Neural TTS gives 500,000 free neural characters per month, which is roughly 60–80 article audio versions. Google Cloud Text-to-Speech gives 1,000,000 free Standard characters and 1,000,000 free WaveNet/Neural2 premium characters per month, roughly double Azure’s premium headroom. Both stay free for a normal publishing cadence.
Which text-to-speech sounds more natural, Azure or Google?
Both produce genuinely natural neural voices, and in blind listening neither clearly wins. Azure edges ahead on expressiveness with named speaking styles like newscast and cheerful, while Google’s Neural2 voices are very natural and, to some ears, slightly warmer. The synthetic-robot problem is solved on both.
Can I auto-generate an audio version of every blog post for free?
Yes. Both clouds expose a simple REST API that turns article text into an MP3, and their free character budgets cover a typical few-articles-a-week cadence at $0. Google’s larger free budget is better if you want to voice a big back catalog in one pass.
Does Azure Neural TTS support SSML and speaking styles?
Yes. Azure supports full SSML plus named speaking styles (newscast, cheerful, empathetic and more) and fine prosody control, which makes article read-alouds noticeably more engaging. Google also supports full SSML, but its emotional-style controls are thinner.
Does adding an audio version of articles help accessibility and SEO?
Yes. An audio version gives screen-reader and listen-first users a first-class way to consume the content, improving accessibility, and the on-page audio player tends to lift time-on-page, which is a positive engagement signal. The benefit is identical whether you generate the audio on Azure or Google.
Here’s the number that reorganized how we think about search: ~84% of our organic traffic comes from Bing. Not Google. Bing — and the Copilot and ChatGPT surfaces that draw on Bing’s index. Yet for a long time, like nearly everyone, we watched only Google Search Console and treated Bing as an afterthought.
That’s the blind spot this article is about. Short answer: use both consoles, but if Bing drives your traffic, stop treating Bing Webmaster Tools as optional — it has data, indexing controls, and an AI-insights surface that Google Search Console doesn’t, and it’s reporting on the search engine that’s actually sending you readers.
This is the side-by-side from running both consoles on the same media property: what each one tells you, where Bing is quietly ahead, and how we wired the Bing Webmaster Tools API into our editorial calendar.
The core reporting — query, position, CTR
Core reporting: query, position, CTR.
At the surface, the two consoles look like twins. Both give you queries, impressions, clicks, average position, and CTR. The differences are in coverage and freshness.
How we do it
Job
Bing Webmaster Tools
Google Search Console
Verdict
Query / position / CTR
Yes, per query and page
Yes, per query and page
Tie on the basics
Data freshness
Often faster to update
~2-3 day lag
Bing edges ahead
Historical window
Generous
16 months
Toss-up
API access
Full API: position + CTR per query/page
Search Analytics API
Bing — the API is the underrated weapon
AI / Copilot insights
Dedicated AI-traffic insights
No equivalent surface yet
Bing, clearly
Market it reports on
Bing + Copilot + ChatGPT-via-Bing
Google only
Depends on your traffic mix
The honest read: for the basic dashboard, they’re close enough that you’d never switch for the UI. The reasons to take Bing seriously are whose traffic it reports on and what it lets you do about it — the AI insights tab and the API.
Indexing: IndexNow vs crawl-when-it-feels-like-it
Indexing: IndexNow vs crawl-when-it-feels-like-it.
This is the most concrete operational difference, and it’s lopsided.
How we do it
Job
Bing Webmaster Tools
Google Search Console
Verdict
Tell it about a new URL
IndexNow — push, indexed near-instantly
URL Inspection → “Request indexing” (queued)
Bing — push beats poll
Bulk submission
IndexNow ping + sitemap
Sitemap, then wait
Bing
Control over crawl
Crawl control, block/allow
Limited crawl controls
Bing — more knobs
Re-crawl on edit
Re-ping IndexNow
Hope, or re-request
Bing
IndexNow is the standout. Instead of submitting a sitemap and waiting for a crawler to wander by, you push a URL the moment it changes and it’s picked up almost immediately — and because IndexNow is a shared protocol, one ping notifies participating engines. Google’s model is still largely “request indexing and wait.” For a content site that publishes and edits constantly, push beats poll every time. We ping IndexNow on publish and on every meaningful edit.
The AI / Copilot insights tab
The AI insights tab is the differentiator.
Google Search Console has no real equivalent here yet. Bing Webmaster Tools surfaces AI-traffic insights — visibility into how your content shows up across Bing’s AI-powered and Copilot surfaces. Given that those surfaces (and ChatGPT’s web results, which draw on Bing) are an increasing share of how people find answers, this is the single console feature most aligned with where discovery is heading. If you care about GEO at all, it’s the dashboard that tells you whether the AI assistants are actually pulling you in.
Wiring the BWT API into the editorial calendar
The Bing Webmaster Tools API is the part most sites never touch, and it’s the most actionable. It returns position and CTR per query and per page — which is a ready-made content-optimization loop:
Pull query/position/CTR from the BWT API on a schedule.
Find pages ranking on page one with weak CTR (good position, bad headline/meta) — fast wins.
Find queries where we rank position 5-15 with real impressions — the “one good edit from page one” list.
Feed both lists straight into the editorial calendar as prioritized rewrites.
Because Bing drives most of our traffic, this loop is pointed at the engine that actually moves our numbers. Running the same loop off Google Search Console’s API would optimize for the 16% of traffic, not the 84%.
What surprised us
Bing’s data is often fresher than Google’s. We frequently see new queries in Bing Webmaster Tools before they show up in Search Console.
IndexNow is faster than anything Google offers — and it’s free and standard. The gap between “push and it’s indexed” and “request and wait” is real and daily.
The AI insights tab has no GSC counterpart. For a site doing GEO, that’s the most forward-looking surface either console offers.
Almost nobody verifies their site in Bing Webmaster Tools. You can import directly from Google Search Console in a couple of clicks, so the only reason most sites skip it is that they’ve never looked at where their traffic comes from.
The takeaway
This was never a “pick one” — it’s “stop ignoring one.” Google Search Console is still essential; Google isn’t going anywhere. But running only GSC is a bet that Google’s view of your site is the only one that matters, and our traffic data says that bet is wrong by a factor of five.
Use both. Watch Google Search Console for the Google slice. But if a large share of your organic traffic comes from Bing — and a surprising number of content sites are in exactly that position without checking — then Bing Webmaster Tools is your primary console: fresher data, IndexNow for instant indexing, the AI/Copilot insights surface, and an API you can wire straight into your editorial calendar.
The 84% lesson is simple: measure where your readers actually come from, then watch the console that reports on it. For us, that meant promoting Bing from afterthought to the dashboard we open first.
This is part of our “Two Clouds, One Site” series — we run the same media property on Azure and Google Cloud, on the free tiers, and report what watching both ecosystems actually teaches us. The lab lives on tygart.media; the findings publish here.
Should I use Bing Webmaster Tools if I already use Google Search Console?
Yes — they report on different search engines, so using only Google Search Console hides all of your Bing performance. If any meaningful share of your traffic comes from Bing, Copilot, or ChatGPT’s Bing-powered results, Bing Webmaster Tools shows data and offers indexing controls that Search Console doesn’t. You can import your site from Search Console in a couple of clicks.
What is IndexNow and is it faster than Google indexing?
IndexNow is a protocol that lets you push a URL to search engines the moment it’s published or changed, instead of waiting for a crawler. It’s typically much faster than Google’s “request indexing and wait” model, and because it’s a shared standard, one ping notifies participating engines. For sites that publish or edit frequently, it’s a meaningful indexing-speed advantage.
Does Bing Webmaster Tools have an API?
Yes. The Bing Webmaster Tools API exposes per-query and per-page data including position and CTR, plus URL submission. That makes it practical to pull your search performance on a schedule and feed it into a content-optimization loop — for example, flagging page-one results with weak CTR or near-miss rankings to prioritize for rewrites.
What does the Bing Webmaster Tools AI insights tab show?
It surfaces how your content appears across Bing’s AI-powered and Copilot surfaces, giving visibility into AI-driven discovery that Google Search Console has no direct equivalent for yet. For sites focused on Generative Engine Optimization, it’s the most forward-looking view either console offers into whether AI assistants are pulling in your content.
Why would a site get most of its traffic from Bing instead of Google?
It’s more common than people assume, especially for niche or B2B content, sites strong in Bing-heavy regions or browsers, and content that surfaces well in Copilot and ChatGPT’s Bing-powered results. The lesson is to measure your actual referral mix rather than assume Google dominates — many sites only discover their Bing share once they verify in Bing Webmaster Tools.
Direct answer: On June 22, 2026, Tygart Media published 40 enterprise Copilot articles in one day, pinged IndexNow, and used server logs—not GA4—to measure the result: 6,805 AI crawler hits vs. 4,897 traditional crawler hits in 48 hours, plus three copilot.microsoft.com referrals. The thesis is that Bing indexing, Copilot citations, and Bing Ads retargeting form a repeatable monetization flywheel no other AI stack fully closes.
Copilot cites from Bing’s index—not a separate Copilot crawler.
Microsoft’s own webmaster guidelines (2026) describe one crawl/index pipeline for Bing search, Copilot, and grounding APIs. Copilot does not maintain a shadow index. If Bingbot can crawl the URL and Bing indexes it, the page is eligible to be cited. That is the architectural basis for “Bing citation mining.”
The monetization twist is Microsoft-specific: a visitor who clicks a Copilot source link often arrives with a copilot.microsoft.com referrer. That session can feed Bing Ads retargeting. Google’s AI surfaces and ChatGPT may send traffic, but they do not hand you the same owned ad graph. We still treat Google AI Overviews and ChatGPT Search as citation channels—just not closed-loop ones.
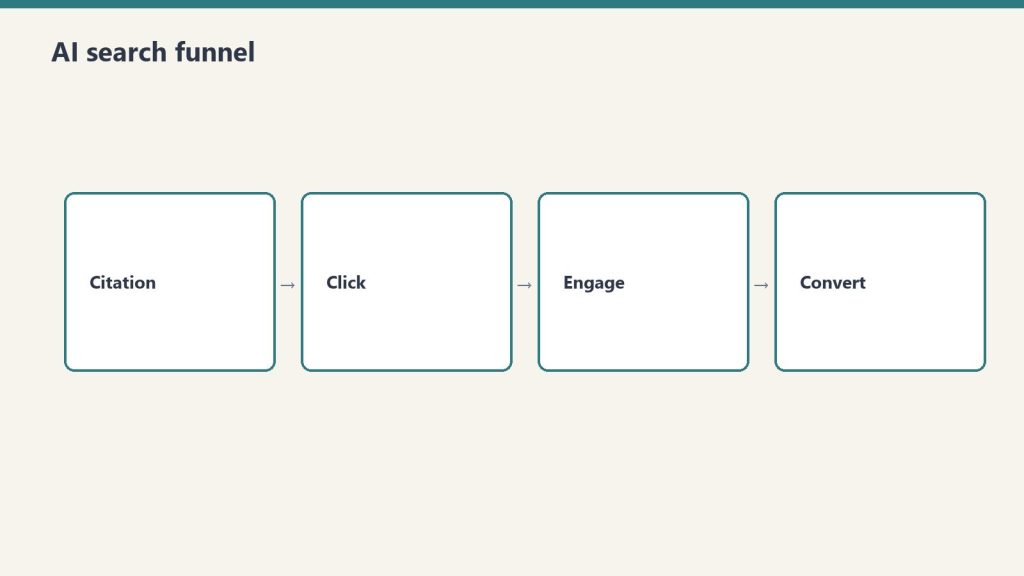
Index — IndexNow on every new URL; sitemaps and internal links as backup.
Cite — Copilot (and Bing AI summaries) pull from the Bing index.
Retarget — Build audiences from Copilot referrers in Bing Ads.
Monetize — Measure leads and revenue, not vanity citations alone.
The experiment: 40 articles, one day
Forty posts in one batch—then watch bot behavior.
On June 22, 2026, we shipped 40 articles on enterprise Microsoft 365 Copilot workflows—eight each across governance, BI/analytics, adoption, productivity, and comparison/procurement topics. Forty was the smallest batch that still looked like a topical cluster to bots mapping site structure, not forty isolated landing pages.
Every article received the same four-layer stack summarized in our GEO case studies for 2026 and the PSAO write-up: classic SEO, AEO extractability, GEO entity saturation, plus JSON-LD. Internal links tied each post to three to five siblings so GPTBot’s structural crawl (see below) could read cluster authority.
Day-one data (June 2026 server logs)
All numbers below are first-party log parses from the 48 hours after publish. Analytics tags miss most bot traffic; this is why we keep preaching log instrumentation—and why we published an AI citation monitoring guide and a broader LLM visibility measurement framework for the post-dashboard era.
AI vs. traditional crawlers
6,805 AI crawler hits
4,897 traditional crawler hits
39% more AI than traditional volume
Source: Tygart Media server logs, June 2026.
Who showed up
ChatGPT-User (3,404 hits) — Real-time retrieval when a user asks ChatGPT something that needs the live web. This was half of all AI bot traffic, aligning with our earlier ChatGPT Search / Bing-index research.
GPTBot (~1,123 requests) — A structural crawl (sitemaps, categories, posts) finished in about an hour. Training/index mapping behavior, not query-driven fetches.
Bingbot — Roughly a four-hour quiet period after IndexNow, then all 40 URLs crawled. IndexNow did its job notifying Bing; Microsoft still does not promise a fixed latency window.
Copilot referrals
Three confirmed human sessions from copilot.microsoft.com within 48 hours—before traditional Bing rankings meant much. Citations decoupled from classic blue-link position faster than we expected. Dollar framing lives in the citation value framework.
ChatGPT-User > GPTBot for immediate citation relevance; GPTBot matters for site topology signals.
Copilot citations before rank. Index presence plus topical fit beat waiting for position one.
Measurement stack evolved. By September 2026 we supplement logs with Bing Webmaster Tools AI Performance where available; logs remain the ground truth for bots GA4 never sees.
IndexNow wording. We now describe IndexNow as “notify Bing immediately,” not “instant index”—matching Bing’s documentation.
What we track after day one
Bing index coverage (Webmaster Tools), Copilot citation counts (AI Performance + log referrers), AI bot recrawl cadence, traditional Bing/Google rankings, and post-citation behavior in GA4. The 40-article cluster is a living lab; this post is the methods appendix.
Frequently Asked Questions
What is the Bing Citation Mining thesis?
The Bing Citation Mining thesis holds that Microsoft Copilot grounds public answers in Bing’s index, so publishers who publish authoritative pages and get them indexed on Bing can earn Copilot citations—and retarget visitors who arrive from those citations through Bing Ads. That publish → index → cite → retarget loop is the only end-to-end AI search monetization chain Microsoft documents today.
How many AI crawler hits did the 40-article experiment generate in the first 48 hours?
Tygart Media server logs from June 2026 recorded 6,805 AI crawler hits versus 4,897 traditional crawler hits in the first 48 hours after all 40 articles went live—39% more AI traffic than traditional. ChatGPT-User alone accounted for 3,404 hits.
Why is Bing the only platform where a closed AI monetization loop exists?
Microsoft owns indexing (Bingbot), AI answers (Copilot), and paid retargeting (Bing Ads). Google’s AI experiences and ChatGPT do not offer the same single-vendor chain from index to attributable referral to ad audience. Bing Webmaster Tools now also reports Copilot citation counts in its AI Performance preview, but the monetization hinge is still Bing Ads on copilot.microsoft.com referrers.
How fast do AI crawlers respond to new content published with IndexNow?
In Tygart Media’s June 2026 logs, ChatGPT-User hit new URLs within hours, GPTBot finished a 1,123-request structural crawl within about an hour of starting, and Bingbot crawled all 40 posts after roughly a four-hour gap following IndexNow pings. Microsoft’s IndexNow docs stress that a 200 response only confirms receipt—not a guaranteed crawl time—so treat our timings as observed data, not a SLA.
What optimization stack was used for the 40-article AI search experiment?
Each post got four layers: SEO (titles, meta, headings, internal links), AEO (FAQ blocks, definition boxes, direct-answer paragraphs), GEO (entity density, factual specificity, speakable markup), and JSON-LD (Article, FAQPage, BreadcrumbList). We document comparable GEO outcomes in our 2026 case-study roundup.
Methodology: June 2026 Tygart Media access logs; bot classification by user-agent; Copilot referrals by referrer string. No third-party bot counts. As of September 2026, also spot-check Bing Webmaster Tools AI Performance where the preview is enabled.
Part of Tygart Media’s AI Search Intelligence series for restoration contractors and operators building durable AI search visibility.
This is part of Tygart Media’s AI Search Intelligence series — a 10-part investigation into how AI systems discover, evaluate, cite, and refer traffic to web content, built on proprietary server log data and real-world publishing experiments.
Every CMO can tell you what a Google click is worth. Years of attribution modeling, CTR curves, and keyword-level conversion tracking have made the organic search click one of the most well-understood units of value in digital marketing. But ask that same CMO what a Microsoft Copilot citation is worth — a referral from copilot.microsoft.com where an AI system explicitly names their brand as a source — and you will get silence.
That silence is a strategic vulnerability. AI search is not a future state. It is a current one. And the organizations that build valuation frameworks for AI citations now will have a decisive advantage over those still trying to retrofit Google Analytics models onto an entirely different referral mechanism.
At Tygart Media, we have been tracking this problem with real data. After publishing 40 articles targeting Microsoft Copilot citation patterns, we recorded 3 confirmed Copilot citation referrals within 48 hours — and simultaneously observed that AI crawlers were hitting our server 6,805 times compared to 4,897 traditional visits (Tygart Media server log analysis, June 2026). AI is already reading more than humans are browsing. The question is no longer whether AI citations matter. The question is: how much are they worth?
This article introduces our AI Citation Value Framework — a 5-component model for measuring what a Copilot referral is actually worth to a publisher, a brand, or a business.
Why Traditional SEO ROI Models Break for AI Search
Why traditional SEO ROI models break for AI search.
Before we build the new framework, we need to understand why the old one fails. Traditional SEO ROI modeling depends on a chain of measurable inputs that simply do not exist in AI search.
The Four Structural Breaks
1. No keyword position to track. In traditional search, value begins with a ranking position. Position 1 for “enterprise software comparison” has a known CTR, a known traffic volume, and a known conversion probability. In AI search, there is no position. Your content is either cited or it is not. There is no “position 3 in Copilot” — the AI either references your brand or it does not mention you at all.
2. No CTR curve to model. Google’s organic CTR curve — where position 1 captures roughly 27-30% of clicks and position 10 captures roughly 2-3% — is one of the foundational inputs to every SEO ROI projection. AI citations have no equivalent curve. When Copilot cites a source within an enterprise workflow answer, the user either clicks through to the cited source or they do not. There is no graduated decay based on citation order.
3. Citations are binary, not graduated. This is the most fundamental structural difference. Traditional SEO operates on a spectrum — position 1 is better than position 5, which is better than position 20, which is better than position 50. Each position has a calculable value. AI citations are binary. You are cited, or you are not. You are the named source, or you are invisible. This binary nature makes traditional regression-based ROI modeling inapplicable.
4. Value accrues through authority reinforcement, not traffic volume alone. In traditional SEO, the primary value mechanism is traffic. More traffic means more conversions means more revenue. In AI search, value accrues through a different mechanism: being cited is worth more than being clicked. The citation itself — the act of an AI system naming your brand as an authoritative source — carries independent value beyond the referral click it may or may not generate.
Definition — AI Citation Value: The total economic impact of being named as a source by an AI system, encompassing direct referral traffic, brand authority reinforcement, compounding citation patterns, retargeting opportunities, and extended content shelf life. Unlike traditional organic search value, AI citation value is not derived from keyword position or CTR curves but from the binary act of being cited by a trusted AI intermediary.
The AI Citation Value Framework: Five Components
The AI citation value framework — five components.
Our framework decomposes the value of a single AI citation into five measurable components. Each captures a different dimension of value that traditional models ignore. Together, they provide a comprehensive picture of what a Copilot referral — or any AI citation — is actually worth to an organization.
Component 1: Direct Referral Value
This is the component closest to traditional SEO measurement: the value of the actual click that occurs when a user follows a citation link from an AI response to your website. But even here, the mechanics differ substantially from a Google organic click.
A traditional organic click arrives with context shaped by a search results page. The user has seen your title tag, your meta description, and your competitors’ listings. They have made a comparative choice. A copilot.microsoft.com referral arrives with context shaped by an AI endorsement. The user has received an answer, and the AI has specifically named your content as the source supporting that answer. The intent signal is different. The trust transfer is different.
Publishers should calculate their direct referral value by examining the downstream behavior of AI-referred visitors compared to organic-referred visitors. Key metrics include:
Pages per session for AI referral traffic vs. organic traffic
Session duration for AI referral traffic vs. organic traffic
Conversion rate for AI referral traffic vs. organic traffic
Bounce rate differential between the two traffic sources
Our early observations suggest that AI referral traffic exhibits distinct engagement patterns that require their own attribution models. The framework recommends treating AI referral traffic as its own channel in GA4 rather than lumping it into organic search.
Component 2: Brand Authority Multiplier
This is the component that has no analog in traditional SEO. When Google ranks your page at position 1, Google is not telling the user “this source is authoritative.” Google is presenting a list and letting the user decide. When Microsoft Copilot cites your brand in a conversational answer, the AI is making an explicit endorsement: “According to [Your Brand]…” or “As [Your Brand] explains…”
That is a fundamentally different value proposition. The AI is functioning as a third-party endorser at scale — recommending your brand to potentially millions of enterprise users within their daily workflow. This endorsement carries brand equity value that exists independently of whether the user clicks through to your site.
Consider the parallel: if a respected industry analyst cited your research in a keynote presentation to 10,000 executives, you would calculate the brand value of that mention even if none of those executives visited your website afterward. An AI citation operates on the same principle, but at dramatically larger scale and with higher frequency.
The brand authority multiplier should be calculated based on:
Estimated reach of the AI platform (Microsoft Copilot’s enterprise user base)
The context of the citation (workflow integration vs. casual query)
Brand lift measurement through pre/post surveys or branded search volume changes
Equivalent media value of a third-party endorsement at comparable scale
In traditional SEO, rankings are volatile. A page that ranks position 1 today may rank position 5 tomorrow and position 15 next month. Every algorithm update reshuffles the deck. This volatility is baked into traditional ROI models through discount rates and probability adjustments.
AI citations behave differently. Our observation — and one of the most strategically important findings in this series — is that once an AI system cites a source, it tends to continue citing that source. There is no position ranking decay in the traditional sense. The AI’s retrieval patterns create a reinforcement loop: content that gets cited builds authority signals that make it more likely to be cited again.
This compounding effect means that the value of a single AI citation extends far beyond the moment of that citation. Each citation is not just a discrete event — it is a contribution to a compounding authority position. Our server log data shows this pattern clearly: after our 40-article Copilot content strategy began generating citations, the AI crawler activity on our site increased substantially, suggesting that citation activity triggers additional crawling and indexing attention from AI systems.
The compounding citation effect should be modeled as:
Citation persistence rate (what percentage of citations continue over 30, 60, 90 days)
Citation expansion rate (does being cited for Topic A lead to citations for Topics B and C)
Authority reinforcement velocity (how quickly does compounding accelerate)
Decay comparison with traditional rankings over equivalent time periods
Key Insight: Traditional SEO ROI models apply a depreciation rate to rankings because positions decay. The AI Citation Value Framework suggests applying an appreciation rate to citations because citations compound. This single inversion — from depreciation to appreciation — fundamentally changes how content investment should be valued.
Component 4: Retargeting Amplifier Value
This component captures a tactical opportunity that most organizations are overlooking entirely. When a user clicks through from a Copilot citation to your website, that user enters your retargeting ecosystem. They can be reached through Bing Ads, display advertising, social media retargeting, and email capture — the same downstream activation paths that exist for any website visitor.
But the retargeting amplifier for AI-referred visitors carries a specific advantage: the visitor arrived with AI-endorsed trust. They did not find you through a search results page where you were one option among ten. They found you because an AI system specifically recommended your content. That trust context should, in principle, improve downstream conversion rates for retargeted campaigns.
The retargeting amplifier value should be calculated by:
Building dedicated retargeting audiences for AI referral traffic in Bing Ads and other platforms
Measuring conversion rates of AI-referred retargeting audiences vs. organic-referred retargeting audiences
Calculating the incremental revenue attributable to the AI referral entry point
Factoring in the lifetime value differential of AI-acquired vs. organic-acquired customers
This component connects directly to the broader Platform-Specific AI Optimization (PSAO) framework — where understanding the unique user journey of each AI platform enables targeted activation strategies that generic SEO approaches cannot deliver.
Component 5: Content Shelf Life Extension
The final component addresses a problem that every content marketer knows intimately: content decay. In traditional SEO, content has a half-life. A blog post ranks well for weeks or months, then gradually declines as fresher content, algorithm updates, and competitive publishing erode its position. Content teams operate on a treadmill — constantly producing new content to replace the decaying traffic from older content.
AI-cited content exhibits a different decay pattern. Because AI citations are driven by authority signals and retrieval patterns rather than freshness signals and ranking algorithms, content that earns AI citations tends to maintain those citations for longer periods than equivalent content maintains Google rankings.
This means that the effective shelf life of AI-cited content is longer than the effective shelf life of Google-ranked content, all else being equal. The investment in creating citation-worthy content generates returns over a longer horizon.
Content shelf life extension should be measured by:
Comparing the traffic decay curve of AI-cited content vs. non-cited content of similar quality and topic
Tracking citation persistence over 6-month and 12-month windows
Calculating the reduced content production burden from extended shelf life
Modeling the NPV difference between a content asset with traditional decay vs. AI-extended shelf life
Putting the Framework Together: A Practical Valuation Approach
Each of the five components can be measured independently, but the framework’s power comes from combining them into a unified valuation. Here is the practical approach we recommend for organizations beginning to measure AI citation value.
Before calculating any values, organizations need to ensure they can actually detect and track AI citations. This requires:
Server log analysis capability — to identify AI crawler activity and referral sources at the server level, not just through JavaScript-based analytics
GA4 custom channel groupings — to separate AI referral traffic (from copilot.microsoft.com, chatgpt.com, claude.ai, and similar sources) from traditional organic traffic
Citation monitoring — systematic testing of AI systems to identify when and where your content is being cited
Temporal analysis — tracking when AI referrals occur relative to content publication to understand citation latency
Our own infrastructure revealed the 6,805 AI crawler hits vs. 4,897 traditional visits split that informed much of this series (Tygart Media server log analysis, June 2026). Without server-level analysis, this data — and the strategic insights it enables — would be invisible.
Step 2: Calculate Each Component Independently
For each component, establish a measurement methodology appropriate to your data maturity:
Direct Referral Value: Start with per-session revenue for AI referral traffic. If you do not yet have enough AI referral volume for statistical significance, use your overall per-session revenue as a proxy and adjust as data accumulates.
Brand Authority Multiplier: Begin with equivalent media value estimation. What would you pay for a third-party endorsement at the scale and context that an AI citation delivers? Refine with branded search lift measurement over time.
Compounding Citation Effect: Track citation persistence monthly. Calculate the projected value of maintaining a citation over 12 months vs. the projected value of maintaining a Google ranking for the same keyword over 12 months. The differential is the compounding premium.
Retargeting Amplifier: Build the audience segments, run the campaigns, and measure the incremental lift. This component is the most directly measurable using existing ad platform infrastructure.
Content Shelf Life Extension: Compare traffic decay curves for cited vs. non-cited content. Calculate the content production cost savings from extended shelf life.
Step 3: Apply the Unified Formula
The total AI Citation Value for a given piece of content is the sum of all five components over the measurement period. Organizations should calculate this quarterly and compare it against the traditional SEO value of equivalent content to build a clear picture of relative ROI.
The formula structure is straightforward:
AI Citation Value = Direct Referral Value + (Brand Authority Multiplier × Estimated Reach) + (Compounding Citation Effect × Time Horizon) + Retargeting Amplifier Value + Content Shelf Life Extension Value
Each variable requires organization-specific inputs. The framework provides the structure; your data provides the numbers.
What Our Data Shows So Far
We are transparent about the maturity of our own dataset. After publishing 40 articles specifically designed to test AI citation acquisition strategies, our results within the first 48 hours included:
3 confirmed Copilot citation referrals — verified through server logs as traffic from copilot.microsoft.com
6,805 AI crawler hits vs. 4,897 traditional visits (Tygart Media server log analysis, June 2026)
This is early-stage data. Three referrals in 48 hours from a cold start is a signal, not a conclusion. But the signal is directionally significant: content engineered for AI citation can earn citations rapidly, and the mechanisms for earning those citations are learnable and repeatable.
The more revealing data point is the crawler ratio. When AI systems are reading your content at a higher rate than traditional systems and humans combined, it confirms that the audience for your content is no longer exclusively human. Your content is being evaluated, indexed, and potentially cited by AI systems with every crawl. The question of why some content gets cited and other content does not becomes the central strategic question.
The Dollar Value Comparison: AI Citation vs. Traditional Organic Click
Let us be direct about what this comparison looks like structurally, even without asserting specific dollar amounts that would vary wildly by industry, niche, and business model.
Traditional Organic Click Value
A traditional organic click’s value is calculated through a well-established chain:
The critical weakness: every variable in this chain is subject to decay. Rankings decay. CTR decays as competitors improve their listings. Traffic decays as search volume shifts. Traditional organic click value is a depreciating asset.
AI Citation Referral Value
An AI citation referral’s value chain looks fundamentally different:
Citation status → binary (cited or not cited)
AI platform reach → estimated user base of the citing AI system
Query relevance → how frequently the cited topic is queried in AI systems
Click-through behavior → percentage of users who follow citation links
Trust premium → conversion rate adjustment for AI-endorsed visitors
Applied appreciation → compounding citation effect over time
The critical strength: the appreciation rate replaces the discount rate. Instead of modeling value decay, the framework suggests modeling value accumulation. The longer you hold an AI citation, the more valuable it becomes as compounding reinforces your position.
Framework Comparison: Traditional organic click value = depreciating asset (rankings decay, algorithms shift, competitors erode position). AI citation value = appreciating asset (citations compound, authority reinforces, shelf life extends). The valuation methodology must match the asset type. Applying depreciation models to appreciating assets systematically undervalues AI citations.
Implications for Content Investment Strategy
Implications for content investment strategy.
If this framework holds — and our early data suggests the structural logic is sound — it has significant implications for how organizations should allocate content budgets.
Content designed to earn AI citations should receive higher per-piece investment than content designed solely for Google rankings. The logic is straightforward: if AI-cited content is an appreciating asset while Google-ranked content is a depreciating asset, the net present value of the citation-optimized content is higher over any multi-year horizon.
Implication 2: Measurement Infrastructure Is No Longer Optional
Organizations that cannot detect AI citations, track AI referral traffic, or analyze AI crawler behavior are flying blind in a channel that already generates more server activity than traditional search on some properties. Server log analysis, custom GA4 configurations, and systematic citation monitoring must be treated as essential infrastructure, not nice-to-have analytics projects.
Implication 3: The Valuation Gap Creates Arbitrage Opportunity
Right now, most organizations are not measuring AI citation value at all. This means the “market” for AI-optimized content is dramatically underpriced relative to its actual value. Organizations that adopt a rigorous valuation framework now — and invest in citation acquisition strategies based on that valuation — are buying an appreciating asset at a discount.
The arbitrage window will close as more organizations adopt AI citation measurement. Early movers who build the infrastructure, develop the content, and establish citation authority now will compound those advantages over time.
Implication 4: Attribution Models Need a Full Rebuild
Most marketing attribution models treat all organic search as one channel. AI referral traffic needs its own attribution path — with its own conversion metrics, its own LTV calculations, and its own ROI benchmarks. Blending AI referral data into “organic search” obscures the true performance of both channels and prevents accurate investment allocation.
Frequently Asked Questions
How do you calculate the value of an AI citation from Microsoft Copilot?
The AI Citation Value Framework uses five components: direct referral value, brand authority multiplier, compounding citation effect, retargeting amplifier value, and content shelf life extension. Each component captures a different dimension of value that a single AI citation delivers. Organizations should measure each component independently using their own data, then combine them into a unified valuation that can be compared against traditional organic search ROI.
Is a Copilot referral worth more than a traditional Google organic click?
The framework suggests that Copilot referrals carry structurally different value characteristics than Google organic clicks. Traditional organic clicks are depreciating assets — subject to CTR decay, position fluctuation, and algorithm updates. AI citations function as appreciating assets — they compound over time, experience no position ranking decay, and benefit from implicit third-party endorsement by the AI system. Publishers should calculate their own comparative values using the five-component framework and their organization-specific data.
Why do traditional SEO ROI models fail for AI search?
Traditional SEO ROI models depend on four inputs that do not exist in AI search: keyword positions, CTR curves, graduated ranking values, and traffic-volume-based value accrual. AI citations are binary (cited or not), carry no position ranking, have no CTR decay curve, and deliver value through authority reinforcement rather than traffic volume alone. Applying traditional models to AI citations will systematically produce incorrect valuations.
What is the compounding citation effect in AI search?
The compounding citation effect describes the observed pattern where once an AI system cites a source, it tends to continue citing that source for related queries. Unlike traditional search rankings that fluctuate with every algorithm update, AI citations build on themselves — each citation reinforces the source’s authority within the AI model’s retrieval patterns. This creates an appreciating dynamic rather than the depreciating dynamic of traditional rankings.
How many AI crawler visits does a typical website receive compared to human visits?
This varies significantly by site, but Tygart Media’s server log analysis from June 2026 recorded 6,805 AI crawler hits compared to 4,897 traditional visits. On this property, AI systems were reading content at a higher rate than traditional crawlers and human visitors. Organizations should conduct their own server log analysis to understand their specific AI-to-human traffic ratio, as this metric is invisible in standard JavaScript-based analytics platforms like Google Analytics.
What Comes Next in This Series
This framework is a starting point, not a final answer. The data underpinning AI citation valuation is still maturing, and the frameworks will evolve as more organizations contribute measurement data and as AI platforms’ citation behaviors become better understood.
In our final installment of the AI Search Intelligence series, we will synthesize the findings from all ten articles into a unified strategic playbook — connecting platform-specific optimization, citation mechanics, and this valuation framework into a comprehensive action plan for organizations ready to treat AI search as a first-class channel.
The organizations that measure what matters — and invest based on those measurements rather than outdated proxies — will own the AI citation economy. The framework is here. The data is building. The question is whether you will wait for the market to price AI citations accurately, or whether you will capture the arbitrage while it lasts.
All server log data, crawler statistics, and citation referral counts cited in this article are sourced from Tygart Media server log analysis, June 2026. For methodology details, see our complete data analysis.
This is part of Tygart Media’s AI Search Intelligence series, where we analyze real data from our own infrastructure to document how AI search engines discover, crawl, and cite publisher content.
Here is the uncomfortable truth that every publisher needs to confront: Google Analytics 4 cannot see AI crawler traffic. Not partially. Not approximately. It misses 100% of it.
GA4 depends on JavaScript execution inside a browser. AI crawlers — GPTBot, OAI-SearchBot, ChatGPT-User, ClaudeBot, PerplexityBot — do not run JavaScript. They request your HTML, parse it, and leave. As far as GA4 is concerned, they were never there.
That means if you are making content strategy decisions based exclusively on GA4, you are making decisions with a growing blind spot. When we analyzed our own server logs for a 48-hour window in June 2026, we found 6,805 AI crawler hits compared to 4,897 traditional search engine crawler hits — AI crawlers generated 39% more traffic than Googlebot, Bingbot, and every other traditional crawler combined (Tygart Media server log analysis, June 2026).
This article walks through exactly what server logs reveal that analytics tools miss, provides the specific user agent strings you need to monitor, and gives you a practical framework for setting up your own AI crawler tracking.
Why GA4 Is Structurally Blind to AI Search Traffic
GA4 is structurally blind to AI search traffic.
This is not a configuration problem. You cannot fix it with a tag update or a GTM trigger. The architecture of client-side analytics makes it fundamentally incompatible with bot traffic measurement.
How GA4 Tracking Works (And Where It Fails)
GA4 tracking follows a specific sequence: a user loads a page in a browser, the browser executes the gtag.js JavaScript snippet, that script fires an HTTP request to Google’s measurement endpoint, and GA4 records the session. Every step in this chain requires a JavaScript-capable browser environment.
AI crawlers skip all of it. When GPTBot requests a page from your server, it receives the raw HTML response, extracts the content it needs, and moves on. No JavaScript execution. No measurement ping. No GA4 session. The request exists only in your server’s access log.
We documented this gap extensively in our analysis of the Google Search Console indexing paradox, where pages with declining GA4 traffic were simultaneously receiving increasing AI crawler attention — a pattern completely invisible without server log analysis.
The Scale of What You Are Missing
To quantify what GA4 misses, we pulled raw access logs from our Nginx server for a 48-hour window in June 2026 and categorized every request by user agent classification.
The breakdown (Tygart Media server log analysis, June 2026):
AI crawler requests: 6,805 total
Traditional search crawler requests: 4,897 total
Difference: AI crawlers generated 39% more server requests than traditional crawlers
None of those 6,805 AI crawler requests appeared in GA4. If we had relied solely on Google Analytics to understand how machines interact with our content, we would have missed the majority of non-human traffic entirely.
As we explored in our research on how websites are now read by AI more than humans, this pattern is not unique to our site — it reflects a structural shift in how content gets consumed.
AI Crawler User Agents: The Complete Reference for June 2026
AI crawler user-agent reference — know who is reading.
Definition: An AI crawler user agent is the identification string sent in the HTTP request header by an artificial intelligence company’s web crawler when it accesses a webpage. These strings identify the crawler’s operator, version, and purpose, and they are the primary mechanism publishers use to track, allow, or block AI bot access in server logs and robots.txt files.
Before you can monitor AI crawler traffic, you need to know exactly what to look for. Here are the verified user agent strings we extracted from our server logs, confirmed active as of June 2026.
OpenAI Crawler Family
OpenAI operates three distinct crawlers, each with a different purpose:
GPTBot (Training and Retrieval Crawler)
Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.1; +https://openai.com/gptbot
GPTBot performs large-scale structural crawls for model training data and retrieval-augmented generation indexing. Our logs recorded a single GPTBot session executing 1,123 requests in one hour, systematically mapping site architecture, internal link relationships, and content hierarchy (Tygart Media server log analysis, June 2026). This is not page-by-page fetching — it is comprehensive site mapping.
OAI-SearchBot (ChatGPT Search Citation Crawler)
Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; OAI-SearchBot/1.0; +https://openai.com/searchbot)
OAI-SearchBot is the real-time retrieval crawler that fetches pages when ChatGPT Search needs to cite a source. As we documented in our guide to getting cited in ChatGPT Search in 2026, this crawler’s access pattern correlates directly with citation inclusion. If OAI-SearchBot cannot reach your page, ChatGPT Search cannot cite it.
ChatGPT-User (Live Conversation Fetches)
Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; ChatGPT-User/1.0; +https://openai.com/bot
ChatGPT-User represents real-time fetches triggered by actual ChatGPT users sharing URLs or requesting content analysis during conversations. This was our highest-volume AI crawler: 3,404 hits in the 48-hour analysis window (Tygart Media server log analysis, June 2026). Each of these hits represents a real person asking ChatGPT about content on our site.
Other Major AI Crawlers
Beyond OpenAI, monitor for these active AI crawlers:
ClaudeBot — Anthropic’s web crawler for Claude’s training and retrieval
PerplexityBot — Perplexity AI’s search and citation crawler
Bytespider — ByteDance’s crawler used for AI training data
Applebot-Extended — Apple’s crawler associated with Apple Intelligence features
Google-Extended — Google’s AI-specific crawler separate from Googlebot
Amazonbot — Amazon’s crawler linked to Alexa and AI assistant features
Each of these should be tracked separately in your log analysis. As our Platform-Specific AI Optimization (PSAO) framework details, different AI platforms have different crawl behaviors, indexing requirements, and citation patterns.
What the 48-Hour Server Log Analysis Revealed
Raw numbers tell part of the story. Crawl behavior patterns tell the rest. Here is what we observed when we dissected the 48-hour log window at the request level.
ChatGPT-User: The Highest-Volume Signal
With 3,404 hits in 48 hours, ChatGPT-User was the single most active AI crawler on our site during the analysis window (Tygart Media server log analysis, June 2026). This matters because every ChatGPT-User request represents a real person interacting with your content through ChatGPT.
The access pattern was distributed across the full 48-hour window with no single burst — consistent with organic user behavior rather than scheduled crawling. Pages accessed by ChatGPT-User skewed heavily toward our most-cited content, particularly the 98,800 AI citations research and our analysis of how AI engines cite content.
GPTBot: The Structural Mapper
GPTBot’s 1,123-request burst in a single hour stands out as the most aggressive crawl pattern we observed (Tygart Media server log analysis, June 2026). This was not random page fetching. The request sequence revealed systematic behavior:
Entry via sitemap.xml — GPTBot started by parsing our XML sitemap
Category page traversal — It crawled category archives to understand content taxonomy
Internal link following — It followed internal links from high-authority pages outward
Content page fetching — Individual articles were fetched in clusters organized by topic
This pattern is consistent with a retrieval-augmented generation (RAG) indexing crawl, where the goal is not just to read content but to build a structured map of how content relates to other content on the site. Publishers who invest in structured llms.txt files paired with robots.txt are effectively giving GPTBot a guided tour rather than letting it map the site on its own.
Bingbot and the 4-Hour IndexNow Gap
While Bingbot is a traditional crawler, its behavior has direct implications for AI search visibility. Our logs revealed a consistent 4-hour gap between publishing a new post (with an IndexNow ping) and Bingbot’s first crawl of that URL (Tygart Media server log analysis, June 2026).
This 4-hour lag matters because Bing’s index is the foundation for two major AI citation systems:
ChatGPT Search — OAI-SearchBot relies on Bing’s index to identify candidate pages for citation retrieval
A 4-hour indexing lag means your new content is invisible to both Copilot and ChatGPT Search for at least that window. For time-sensitive content, this gap represents a competitive disadvantage.
How to Set Up Your Own AI Crawler Monitoring
Set up your own AI crawler monitoring.
You do not need expensive tools to start tracking AI crawlers. Here is a practical step-by-step framework using standard server infrastructure.
Step 1: Locate Your Raw Access Logs
Your server access logs are the source of truth. Depending on your hosting setup:
Nginx: Default location is /var/log/nginx/access.log
Apache: Default location is /var/log/apache2/access.log or /var/log/httpd/access_log
Managed WordPress hosting (Cloudways, Kinsta, WP Engine): Access logs are typically available in the hosting dashboard under server logs or SFTP access
Shared hosting (SiteGround, Bluehost): Check cPanel > Metrics > Raw Access or request log access from support
If your host does not provide raw access logs, that is a serious limitation for AI search optimization. Consider this a factor in future hosting decisions.
Step 2: Filter for AI Crawler User Agents
Once you have access to raw logs, use grep (or your preferred log analysis tool) to isolate AI crawler requests. Here is a basic command set:
# Count all AI crawler hits in a log file
grep -c -E "GPTBot|OAI-SearchBot|ChatGPT-User|ClaudeBot|PerplexityBot|Bytespider|Applebot-Extended|Google-Extended" access.log

# Break down by individual crawler
for bot in GPTBot OAI-SearchBot ChatGPT-User ClaudeBot PerplexityBot Bytespider; do
  echo "$bot: $(grep -c "$bot" access.log)"
done

# Show which URLs each crawler is accessing
grep "GPTBot" access.log | awk '{print $7}' | sort | uniq -c | sort -rn | head -20
Step 3: Build a Recurring Monitoring Script
For ongoing tracking, create a cron job that generates a daily AI crawler report:
The real value emerges when you correlate AI crawler data with content outcomes. Track these relationships:
GPTBot crawl frequency → Citation appearances. Pages that GPTBot crawls repeatedly tend to surface in ChatGPT responses more frequently. We verified this pattern in our investigation of whether anything actually fetches your llms.txt file.
OAI-SearchBot access → ChatGPT Search citations. OAI-SearchBot visits are a leading indicator that your content is being evaluated for citation in ChatGPT Search results.
ChatGPT-User volume → Content demand signal. High ChatGPT-User traffic to specific pages indicates those topics are actively being discussed by ChatGPT users — a demand signal invisible in GA4.
Step 5: Set Up Real-Time Alerts
For publishers who need immediate visibility into AI crawler behavior, configure real-time log monitoring:
# Real-time AI crawler monitoring with tail
tail -f /var/log/nginx/access.log | grep --line-buffered -E "GPTBot|OAI-SearchBot|ChatGPT-User|ClaudeBot|PerplexityBot"
For production environments, tools like GoAccess, Datadog, or a custom ELK Stack (Elasticsearch, Logstash, Kibana) configuration can provide dashboards with AI crawler metrics alongside traditional analytics.
What Server Logs Reveal That No Analytics Tool Can Show
Beyond raw hit counts, server log analysis exposes behavioral patterns that inform content strategy decisions.
Crawl Depth and Site Architecture Signals
Traditional analytics shows you which pages humans visit. Server logs show you which pages machines prioritize. In our 48-hour analysis, AI crawlers accessed pages up to 7 levels deep in our site architecture — well beyond what most human visitors reach. This indicates that AI crawlers are evaluating your entire content graph, not just your homepage and top-ranking pages.
This has direct implications for internal linking strategy. Content buried deep in your architecture that humans rarely find may still be actively indexed by AI crawlers and surfaced in AI-generated responses. Our work on the AI citation economy explores why being cited by AI systems may ultimately deliver more value than traditional click-through traffic.
Crawl Frequency as a Content Quality Signal
Some pages on our site are crawled by AI bots multiple times per day. Others are crawled once and never revisited. Tracking crawl frequency over time reveals which content AI systems consider worth re-indexing — a signal that correlates with citation likelihood.
Pages that received repeat GPTBot and OAI-SearchBot visits in our analysis shared common characteristics:
Original data or research (not aggregated from other sources)
Clear entity definitions and structured formatting
Recent publication or update dates
Strong internal link support from related content
Response Code Analysis: Are AI Crawlers Hitting Errors?
Server logs include HTTP response codes for every request. Filter AI crawler requests by response code to identify problems:
200 (OK): Crawler successfully fetched the page — this is what you want
301/302 (Redirect): Crawler hit a redirect chain — check that critical content resolves cleanly
403 (Forbidden): Your server or WAF is blocking the crawler — this may be intentional (robots.txt block) or accidental (overly aggressive security rules)
404 (Not Found): Crawler tried to access a URL that does not exist — often caused by stale sitemap entries or broken internal links
429 (Too Many Requests): Your rate limiting is throttling the crawler — may reduce indexing completeness
503 (Service Unavailable): Server could not handle the crawler’s request volume — a hosting capacity issue
We found that 3.2% of AI crawler requests in our 48-hour window received non-200 responses, primarily 301 redirects from URL structure changes (Tygart Media server log analysis, June 2026). Each non-200 response is a potential missed indexing opportunity.
Building a Server Log Analysis Workflow for AI Search
Here is the complete monitoring workflow we use at Tygart Media, adapted for any publisher running WordPress or a similar CMS.
Daily Monitoring Checklist
Run the AI crawler count script — Track total hits by crawler to identify volume trends
Check for new user agent strings — AI companies launch new crawlers regularly; grep for unrecognized bot patterns
Review top-accessed URLs — Identify which content AI systems are prioritizing today
Monitor response codes — Flag any increase in 403, 404, or 429 responses to AI crawlers
Cross-reference with publication schedule — Track the time gap between publishing and first AI crawler access
Weekly Analysis Framework
Compare AI crawler volume week-over-week — Is AI crawl activity increasing, stable, or declining?
Identify content that stopped getting crawled — Pages that fall off AI crawler radar may be losing citation eligibility
Correlate crawl patterns with known AI search updates — AI platforms update their retrieval systems frequently
Update your llms.txt and sitemap — Based on what AI crawlers are actually accessing versus what you want them to prioritize
Tools for Scaling Server Log Analysis
For publishers managing multiple sites or high-traffic properties, manual grep commands do not scale. Consider these tools:
GoAccess — Open-source real-time log analyzer with terminal and HTML dashboard output. Supports custom log formats and can filter by user agent.
Screaming Frog Log File Analyser — Desktop application specifically designed for SEO log analysis. Supports AI bot filtering and integrates with Google Search Console data.
ELK Stack (Elasticsearch, Logstash, Kibana) — Enterprise-grade log analysis pipeline. Best for publishers who need custom dashboards and real-time alerting.
Datadog / New Relic — Cloud monitoring platforms with log analysis capabilities. Good for teams already using these tools for infrastructure monitoring.
Custom Python/bash scripts — For publishers with technical resources, custom scripts offer the most flexibility for AI-specific analysis.
The Implications: What This Data Means for Content Strategy
Server log analysis is not just a technical exercise. The data it produces should directly inform editorial and SEO decisions.
Content That AI Crawlers Ignore Is Content That AI Will Not Cite
If a page on your site receives zero AI crawler visits over a 30-day window, that page is effectively invisible to AI search systems. It will not be cited by ChatGPT, it will not appear in Copilot responses, and it will not surface in Perplexity answers.
This is a different problem than low Google rankings. A page can rank well in traditional search while being completely absent from AI search — and vice versa. As we documented in our research showing Claude citing articles 16,500 times while Copilot cited roofing content zero times, AI platforms have fundamentally different content preferences than traditional search engines.
AI Crawler Volume Is a Leading Indicator
Traditional analytics are lagging indicators — they tell you what happened after traffic arrived. AI crawler activity is a leading indicator — it tells you what content AI systems are evaluating for future citation. Increasing AI crawl frequency on a specific page or topic cluster often precedes increased citation rates by days or weeks.
Server Logs Validate (or Invalidate) Your Optimization Efforts
If you have implemented llms.txt files, updated your robots.txt, or restructured content for AI search optimization, server logs are the only way to verify that these changes are working. Analytics tools cannot confirm that GPTBot is crawling your llms.txt file. Only your access logs can.
No. GA4 relies on JavaScript execution in a browser environment. AI crawlers like GPTBot, OAI-SearchBot, and ChatGPT-User do not execute JavaScript, so they are completely invisible in GA4. Server log analysis is the only reliable method to monitor AI crawler activity on your site.
What are the main AI crawler user agents to monitor in 2026?
The primary AI crawler user agents to monitor are GPTBot (OpenAI’s training and retrieval crawler), OAI-SearchBot (ChatGPT Search’s real-time citation crawler), ChatGPT-User (live user-initiated fetches from ChatGPT conversations), ClaudeBot (Anthropic’s crawler), Bytespider (ByteDance/TikTok), and PerplexityBot (Perplexity AI’s search crawler).
How many AI crawler requests does a typical publisher site receive?
Volume varies by site authority and content type. Tygart Media’s server log analysis from June 2026 recorded 6,805 AI crawler hits compared to 4,897 traditional search engine crawler hits in a 48-hour window — meaning AI crawlers generated 39% more traffic than traditional crawlers during that period.
What is GPTBot’s crawl behavior pattern?
GPTBot performs intensive structural crawls. Tygart Media server log analysis from June 2026 documented a single GPTBot session executing 1,123 requests within one hour, systematically mapping site architecture, internal links, and content relationships rather than fetching individual pages.
How quickly does Bingbot index new content published via IndexNow?
Based on Tygart Media server log analysis from June 2026, Bingbot showed a consistent 4-hour gap between content publication via IndexNow ping and first crawl of the new URL. This lag is significant because Bing’s index feeds both Microsoft Copilot citations and ChatGPT Search results through OAI-SearchBot.
What Comes Next: From Monitoring to Optimization
Setting up AI crawler monitoring through server logs is the foundation. The next step is using that data to optimize your content specifically for AI search visibility. Key areas to explore:
Robots.txt and llms.txt alignment — Ensure your crawl directives match your citation goals
Content structure optimization — Format content in ways that AI crawlers can efficiently parse and cite
Publication timing — Account for the 4-hour Bingbot indexing gap when publishing time-sensitive content
Cross-platform monitoring — Track how different AI crawlers prioritize different content types
The publishers who will win in AI search are the ones who understand exactly how AI systems interact with their content — and that understanding starts with server logs, not analytics dashboards.
All data referenced in this article is sourced from Tygart Media server log analysis, June 2026. For methodology details and access to our broader AI Search Intelligence research, explore the full series on tygartmedia.com.
Three days. That’s how long Claude Fable 5 existed in the wild before the US government killed it.
On Monday, June 9, Anthropic launched Fable 5 and Mythos 5. On Thursday, June 12, Commerce Secretary Howard Lutnick issued an export control directive ordering Anthropic to suspend access for any foreign national. Since Anthropic can’t verify nationality in real time, they shut it down for everyone. Globally. Immediately. The stated reason was a narrow jailbreak vulnerability — one Anthropic says exists in other publicly deployed models too.
I’m not writing this to debate export controls. I’m writing this because I spent those three days running Fable 5 in production — not benchmarking it, not kicking the tires, actually building with it — and I have something most people writing about this don’t have: receipts.
Day One: The Model Dropped and I Put It to Work
Day one — the model dropped and I put it to work.
Fable 5 launched June 9. By that afternoon, I had it running a Batch 8 sprint across my Tygart Media site — refreshing 10 pages of Claude content that needed updating. Fable 5 updated comparison tables, corrected model names across the lineup, added FAQPage schema, injected internal links, and expanded word counts. Post 4787 went from 750 words to 1,602. Post 9821 went from 1,782 to 2,543. Five posts refreshed with full SEO treatment — schema, FAQs, RankMath meta, silo links — in a single session.
That same day, I had Fable 5 write a complete guide to itself. Not a press release rewrite — a 2,100-word article with an interactive cost calculator, a model picker tool, and a section called “How We Actually Use Each Model” that mapped my real production workflows to each tier: Haiku for the daily 25-post SEO sweeps, Sonnet for desk articles, Opus for deep refreshes, Fable for portfolio-wide audits and strategy. The draft landed in Notion with scoped CSS and JS, ready to paste into WordPress as a single Custom HTML block.
Day Two: Fable 5 Ran My Entire SEO Audit
Day two — Fable 5 ran the SEO audit.
June 10. I ran a full SEO audit of tygartmedia.com through Fable 5. It identified that Fable 5 itself was the top content gap — a model launched 24 hours ago with zero dedicated coverage and peak search intent. So it wrote the article to fill its own gap. It drafted the piece, tagged the slug, assigned the category, and queued internal links to five existing posts.
That same day, Fable 5 wrote and published “The Signal: AI Just Split Into Two Lanes” — a 1,400-word field notes piece that wove together Fable 5’s launch, OpenAI’s S-1, Chrome WebMCP, and the emerging thesis that AI was splitting into a product lane and an infrastructure lane. The article went through the full pipeline: SEO optimization, AEO with 8 FAQ Q&As, GEO entity enrichment, Article + FAQPage schema, taxonomy assignment, internal linking, quality gate — then published via REST API. It even created the LinkedIn draft in Metricool and scheduled it for 2:30 PM Pacific.
That article exists right now at tygartmedia.com. I didn’t write it. Fable 5 did, with me directing the strategy and approving the output. The quality bar was real journalism, not AI slop.
Day Three: Building the Infrastructure Layer
June 11. While the Fable 5 Complete Guide sat in Notion waiting for a featured image, I was using Fable 5 to build the systems that would keep my content operation running. I had it update the Claude Intelligence Desk — my Notion page that serves as the authoritative source of truth for every Claude model name, API string, and price across my entire content operation. Every article gets verified against that desk before publishing. Fable 5 updated it with its own pricing: $10 input, $50 output per million tokens.
I also had Fable 5 design my Pricing Freshness Engine — a WordPress mu-plugin that shadow-checks Anthropic’s live pricing against what’s displayed on my site. The engine had been running in shadow mode since June 2, catching drift before it reaches readers. Fable 5 added itself to the canonical pricing store.
Meanwhile, my 6 scheduled email agent tasks — morning triage, midday check, afternoon wrap, newsletter extraction, weekly prep, and weekly self-audit — were running on the same Claude infrastructure, handling my inbox while I focused on building. The whole system runs on my Max plan. No extra API charges.
What Fable 5 Actually Felt Like
Here’s what the benchmarks don’t tell you: Fable 5 understood intent, not just instructions.
When I told it to run a page refresh, it didn’t just update the text — it checked model names against my Intelligence Desk, verified pricing against live documentation, added schema markup, expanded FAQs, injected internal links, and updated the dateline. It treated each task as a system, not a checklist.
When I asked it to write the Complete Guide, it included a section about how we actually use each model tier in production — because it knew from context that an article about Claude models on a site that runs on Claude models should demonstrate firsthand expertise, not just recite specs. It even built interactive JavaScript widgets inline — a cost calculator and a model picker — without being asked, because it understood the article needed to be useful, not just informative.
The gap between Fable 5 and what came before it was the largest single-model jump I’ve experienced since I started building on Claude in 2024.
What Most Commentators Are Missing
What most commentators are missing.
Most people writing about the shutdown never used Fable 5. They’re debating precedent, policy, the implications for AI regulation. All valid. But the conversation is incomplete without understanding what was actually deployed.
This is the first time the US government has aimed export controls at a deployed commercial AI model rather than at chips or hardware. That’s unprecedented. Anthropic complied but publicly disagreed, calling it a likely misunderstanding based on a narrow jailbreak that exists in other models too.
Every other Claude model — Opus, Sonnet, Haiku — remains fully available and unaffected.
What I Lost
Here’s what the government took from me specifically:
My Fable 5 Complete Guide is sitting in Notion, ready to publish, with the proxy fix queued. The pricing pages need Fable 5 rows added. The Freshness Engine needs Fable 5 in its canonical store. The WordPress proxy’s ALLOWED_DOMAINS needs a one-line gcloud update. All of it was queued up. All of it was dependent on a model that no longer exists.
The infrastructure I built this week — the Intelligence Desk, the Pricing Freshness Engine, the content pipeline that ran “The Signal” from draft to published with schema and social scheduling in a single session — all of that still works with Opus and Sonnet. But the ceiling is lower. The tasks that Fable 5 handled in one pass will take two or three with the models that remain.
What Happens Now
Anthropic says this isn’t permanent. They’re working to restore access.
For people like me who build businesses on top of these tools, the uncertainty is the real cost. Three days is long enough to build production workflows, deploy infrastructure, and write articles that reference a model’s existence — and short enough that all of it gets yanked before you can publish.
But I’m not pulling back. This week confirmed the trajectory. AI at this level isn’t a nice-to-have — it’s the infrastructure of how modern knowledge work gets done. Whether it’s Fable 5 or whatever comes after it, this capability exists now. You can’t un-ring that bell.
I know because I rang it. For three days, I built real things with a model the government decided the world shouldn’t have. And the work is still there in my Notion, waiting.
Will Tygart is the founder of Tygart Media, where he builds AI-native content operations across a portfolio of WordPress sites. He has been building production workflows on Claude since 2024. His Claude Intelligence Desk, Pricing Freshness Engine, and content pipeline systems were all built or upgraded using Claude Fable 5 during its three-day window.
Paste your article. Get back the version built to win the featured snippet.
Who This Is For
Who the AEO content optimizer skill is for.
Built for site owners and content marketers who publish good content that never gets picked as the answer — no featured snippets, no People Also Ask placements, invisible in voice results and AI Overviews while thinner competitor pages take the box.
The Problem
Answer engines do not reward the best content — they reward the most extractable content. A page that buries its answer in paragraph six loses to a page that answers in the first 50 words under a question heading, formatted the way the snippet wants. Restructuring for extraction is mechanical, learnable work — and almost nobody does it. This skill does it on every piece you paste.
What It Does
What it does for featured snippets / AEO.
Performs answer-first surgery: a direct, self-contained 40–60 word answer placed immediately under each question heading
Converts topical headings into the question formats searchers actually use, mapped to real query variants
Matches the winning snippet format per query — paragraph, numbered list, or table — and rebuilds the block to fit
Builds a genuine FAQ section and generates the matching FAQPage JSON-LD (and warns about duplicate schema before you paste)
Runs a voice pass so direct answers survive a smart-speaker read
Returns a change log plus an honest note on what content is missing that the query demands
What You Get
What you get.
The aeo-content-optimizer.skill file — installs in claude.ai or Claude Code in about two minutes
README with installation steps and tested example prompts
Works on existing posts, new drafts, and competitor-gap rewrites
No. You paste your content and your target question. The skill restructures and returns paste-ready output, including the schema block.
Does it work for my niche?
Yes — the method is format-driven, not topic-driven. Local services, SaaS, e-commerce, professional services, and content sites all follow the same extraction rules.
Will it change my voice or facts?
It restructures; it does not genericize. Anything it cannot verify is flagged for you to supply rather than invented.
How is this delivered?
Within 24 hours of purchase via email from will@tygartmedia.com. Skill file and setup guide delivered as a ZIP download.
Does this require a paid Claude subscription?
Installing as a custom skill requires a paid Claude plan (Pro, $20/mo, or higher) with code execution enabled. Your download also includes a free-plan setup option — paste the skill into a Claude Project’s instructions — that works on any plan.