Tag: Content Strategy

  • Receipts: 105 Dead Clicks — and Why We Changed Nothing

    Receipts: 105 Dead Clicks — and Why We Changed Nothing

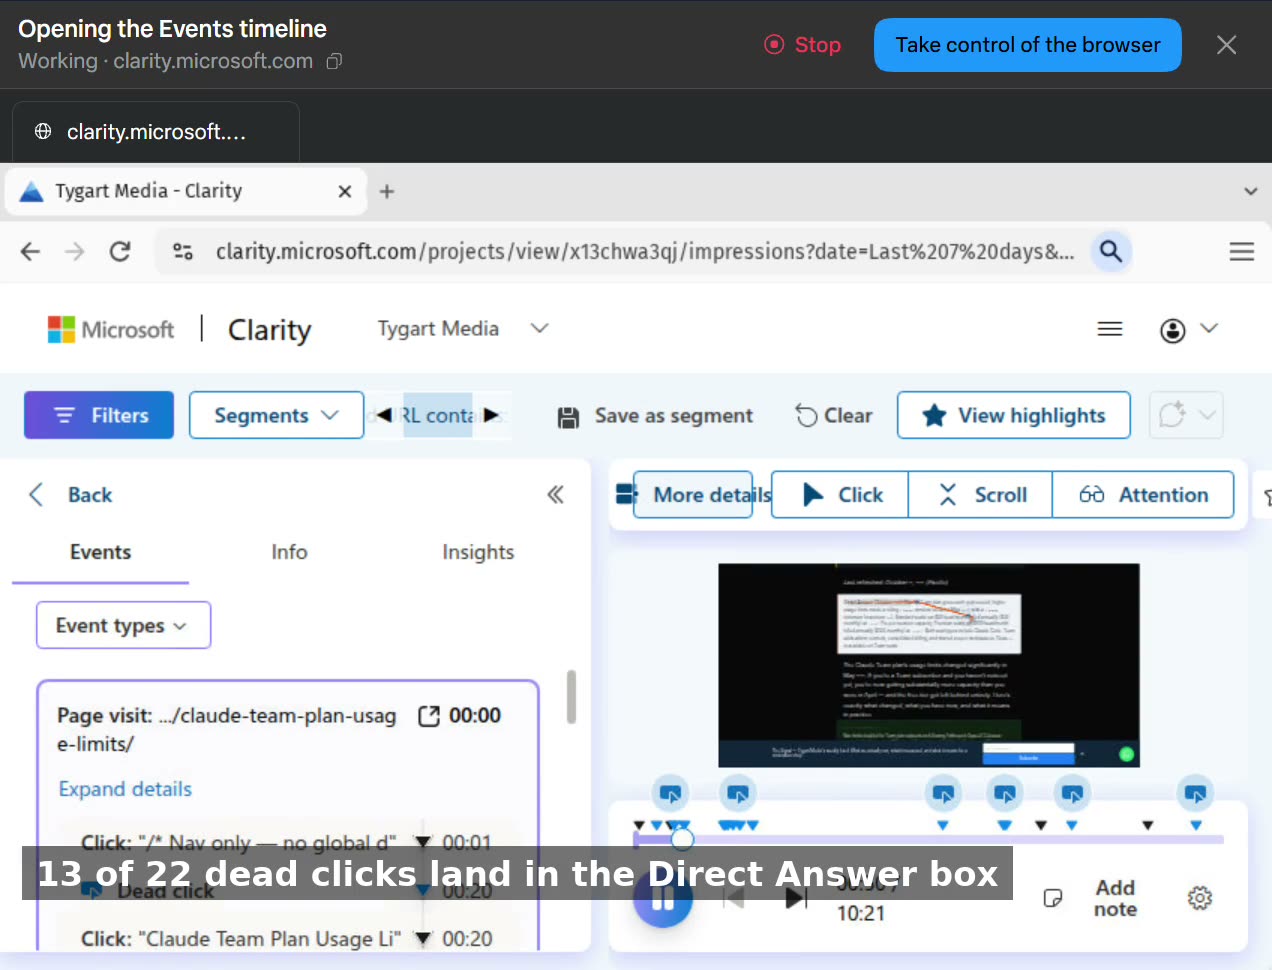
    Our analytics flagged 105 dead clicks on our Claude pricing pages this week. Dead clicks are supposed to mean friction — people clicking things that don’t work. The fix, if you believe the dashboard, is a redesign ticket.

    So we watched the recordings. All of them, session by session. This video is that walkthrough, narrated as it happened: the three filters that isolate the signal, then the two densest sessions read event by event.

    Every flagged click was a reader selecting text. On the enterprise pricing page, one visitor accounts for all 17 dead clicks — four and a half minutes on the page, highlighting as they read. On the team-plan usage-limits page, 13 of the 22 dead clicks land inside the Direct Answer box at the top of the article: people selecting the summary to copy it out. Nobody clicked a broken button. Nobody clicked a price that wouldn’t respond. The one honest exception is a bold line inside a call-to-action block that got clicked like a button, four times — the only element on either page we’d even consider changing.

    If we’d worked from the dashboard alone, we’d have “fixed” pages that are doing their jobs — and probably broken the format that makes them get cited in the first place.

    This is the part of analytics nobody sells you: the number is a question, not an answer. The recording is the answer — if somebody actually watches it.

  • Receipts: One Week, 6,753 Bot Visits, Three Kinds of Bots

    Receipts: One Week, 6,753 Bot Visits, Three Kinds of Bots

    “AI traffic” sounds like one thing. On the dashboard it is three different things, doing three different jobs, and they are not interchangeable.

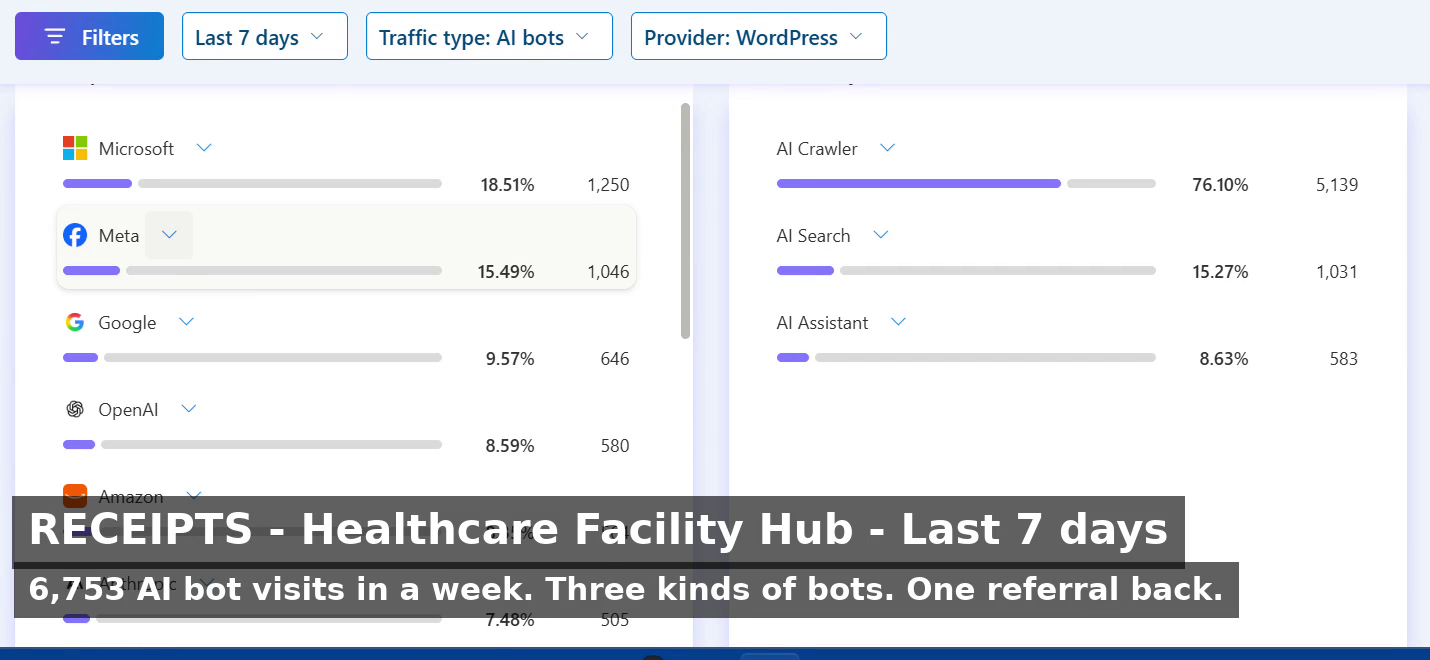
    Healthcare Facility Hub, last 7 days: 6,753 AI-bot requests. The operators alone are a crowd — Microsoft 1,250, Meta 1,046, Google 646, OpenAI 580, Amazon 564, Anthropic 505, Perplexity 444, Huawei 401, ByteDance behind them, and a tail that runs down to a single visit each from names most site owners have never heard of.

    Clarity sorts them by what they came to do. AI Crawlers made 5,139 of the visits, 76.10% — the index builders, reading everything so the models know it exists. AI Search made 1,031, 15.27% — bots fetching a page because somebody just asked a question: PerplexityBot 444 of them, plus Lyrenth and Parallel. AI Assistants made 583, 8.63% — browsing on behalf of a person mid-conversation: OpenAI 320, Anthropic 94, DuckDuckGo 17, Cohere exactly 1.

    The distinction matters because each kind wants something different from a page. A crawler wants it complete and clean. A search bot wants the answer findable in seconds. An assistant wants the page to make sense lifted out of context. One page, three readers, three jobs.

    And for all 6,753 visits, the scrape-to-referral ratio is 535:1. One referral came back all week. The most-wanted page on the site, by the way, is not the homepage — it is a field sheet, /email-my-field-sheet/, with 885 requests, 13.11% of everything the bots did.

    Ask for receipts.

  • The Agent-Ready Site: What Kin’s WebMCP Launch Means for Every Business Website

    The Agent-Ready Site: What Kin’s WebMCP Launch Means for Every Business Website

    On October 23, 2026, Kin Insurance became the first U.S. home insurer to enable WebMCP in its quoting experience — an open web standard that lets an AI agent work directly with kin.com, so a homeowner can tell ChatGPT "help me shop for home insurance" and get back a real quote. Strip away the insurance details and what remains is a pattern every business website is about to be measured against: is your site built for the agent your customer sends?

    Most businesses are still arguing about whether to let agents in. Kin skipped that argument. The interesting question is what its launch is made of, layer by layer — because three of the four layers are already visible in our own fleet's numbers.

    Agent-Ready Fleet Standard

    Make Your Site Machine-Ready for the 62% Bot Wave

    Field-ready quick cards, fillable 4-layer audit worksheets, and AI-powered bot runbooks built directly from this guide.

    Quick Reference FREE

    Agent-Ready Quick Card

    2-page field card: The 4 layers — welcome the machine (door vs. wall), structure for carrying (answers not brochures), give the agent a way to act (WebMCP), and measure what machines do (citation scoreboard) — on one card, condensed from the article body.

    Download Free PDF

    Direct download • No email gate

    Working Pack $7

    The Agent-Ready Site 4-Layer Print Pack

    5-page printable & fillable working pack: Layer 1 Door-or-Wall decision checklist (Kin vs Insurify default audit), Layer 2 answers-not-brochures worksheet with verbatim FAQ tracker modeled on 155-of-166 rollout, Layer 3 declared-action mapper with inputs-in-order sequence sheet, and Layer 4 citation scoreboard log (1.45M across 922 pages tracking model).

    Get Working Pack ($7) →

    Instant checkout • Square verified

    AI Intensive
    Book for Bots $17

    Feed Your AI: The Agent-Ready Site Bot Book

    Feed directly to ChatGPT or Claude: 4 intensive AI-run routines (Welcome Posture Interview, Readable Content Auditor, Declared Action Designer, Citation Scoreboard Diagnostic) with embedded executive command router (“software made of words”).

    Get AI Bot Book ($17) →

    Software made of words • Instant delivery

    Layer 1: Decide to welcome the machine

    Agent traffic is not coming; on our own sites it is already the majority — roughly 62% of visits across the fleet we run are bots and agents, not people. The only choice left is whether that traffic meets a door or a wall.

    Kin chose the door, publicly and in advance: it had already announced that AI shopping agents are welcome on kin.com rather than blocked, naming Meta's Muse among them. The opposite choice exists in the same industry — in September, insurance marketplace Insurify blocked Muse from its comparison platforms, arguing an agent could pull a price stripped of the context that makes it meaningful. Both are coherent positions. What is no longer available is having no position: a site that has not decided is a site whose default settings decide for it.

    Layer 2: Structure the content so a machine can carry it accurately

    An agent can only repeat what it can read, so the agent-ready site is built out of answers, not brochures: one real question per page, paragraphs that stand alone as complete ideas, and structured data underneath that states the facts in machine-readable form.

    This is the layer we work in every day, and it is unglamorous, mechanical work. Tonight, on one operator site in our fleet, we finished putting structured FAQ data — drawn from each page's own questions and answers, verbatim — onto 155 of its 166 articles, because agents cite what is structured and skip what is implied. Multiply that instinct across every page a business owns and you have the content layer of agent-readiness: nothing important lives only in an image, a video, or a sales conversation.

    Layer 3: Give the agent a way to act, not just to read

    WebMCP is the layer most sites do not have yet: the site declares the actions an agent may take — get a quote, with these inputs, in this order — so the agent executes a designed path instead of improvising clicks across a human interface.

    Kin's version is a quote flow, and its testing shows why the layer matters: agents reached a finished quote after asking the consumer only a handful of questions, because the path was declared and the carrier's data filled the rest. The equivalent for any business is the moment a visit becomes a transaction — a booking, a quote, an order. Our own commerce thinking already runs on two rails, one built for humans at a checkout and one an agent can complete; Kin just shipped the insurance version of the second rail, first.

    Autonomous Commerce Engineering

    Build Your Agent-Usable Rail Before Customers Stop Browsing

    Kin proved an agent can reach a finished quote in a handful of questions when the path is declared. Equip your technical and product teams with printable inputs-in-order worksheets, two-rail commerce planners, and interactive AI routines that convert human checkout forms into WebMCP-compliant endpoints.

    🤖

    What’s In The Agent-Ready Suite:

    • Layer 1 Door-or-Wall: Decision checklist & WAF audit.
    • Layer 2 Answers-Not-Brochures: 155-of-166 FAQ tracker.
    • Layer 3 Declared Action: Inputs-in-order sequence mapper.
    • Layer 4 Scoreboard Log: 1.45M across 922 pages tracking.
    • AI Bot Book: 4 interactive routines & command router ($17).
    Secure 1-Click Square Checkout

    Layer 4: Measure what the machines do

    Agent-readiness you cannot measure is a vibe. Kin will know whether agents quote it, because the protocol makes agent sessions countable; the rest of us measure the read layer — which pages agents cite, which questions they bring, how the share moves.

    On tygartmedia.com, we track AI citations from our own search-engine exports rather than a vendor's estimate: 1,459,726 citations across 922 cited pages in the October 15 export, up from 269,399 across 324 pages in the September 27 export. Those numbers are the scoreboard for layers 1 and 2. The day an agent can transact here, layer 3 gets a scoreboard of its own.

    Where our fleet honestly sits

    Layers 1, 2, and 4 are running here today — welcome posture, structured content, citation measurement. Layer 3, declared agent actions, is what Kin shipped first, and it is the next build. That is a fair summary of most of the web right now: readable by agents, citable by agents, and still requiring a human to show up for the transaction itself.

    The businesses that treat that gap as a roadmap, rather than a surprise, are the ones whose sites will be ready when their customers stop browsing and start sending.

    Specification Comparison

    Compare Agent-Ready Tools & AI Implementation Systems

    Choose the depth of operational rigor needed for your website: field quick card, printable audit working pack, or interactive bot-driven runbook.

    Field Summary

    Agent-Ready Quick Card

    2-page field card condensing the 4 layers into an executive reference standard.

    • 4-Layer architectural summary on one card
    • Door vs. Wall posture matrix (Kin vs. Insurify)
    • Answers-not-brochures & standalone paragraph test
    • WebMCP declared action & two-rail commerce summary
    • Citation scoreboard benchmarks (62% bot baseline)
    FREE
    Download Quick Card (PDF)

    Instant direct download • No email gate

    Static Working Pack

    The Agent-Ready Site 4-Layer Print Pack

    5-page printable & fillable audit system with complete engineering worksheets and scoreboard logs.

    • Layer 1 Door-or-Wall decision checklist & default audit
    • Layer 2 answers-not-brochures worksheet (1-question test)
    • Verbatim FAQ structured-data tracker (155-of-166 rollout model)
    • Layer 3 declared-action mapper & inputs-in-order sheet
    • Two-rail commerce planner (Human UI vs. Agent Rail)
    • Layer 4 citation scoreboard log (269k to 1.45M growth model)
    $7.00
    Get Working Pack ($7) →

    Instant delivery • Square checkout

    AI Intensive
    Book for Bots

    Feed Your AI: The Agent-Ready Site Bot Book

    Structured text document feeding 4 executable AI routines directly to ChatGPT or Claude to audit pages, generate schema, and design declared actions.

    • Routine 1: Welcome Posture Interview (/welcome-audit)
    • Routine 2: Readable Content Auditor (/content-audit)
    • Verbatim Schema Generator: JSON-LD FAQPage (155-of-166)
    • Routine 3: Declared Action Designer (/action-design)
    • Routine 4: Citation Scoreboard Diagnostic (/citation-diag)
    • Routine 5: Executive Roadmap Protocol (/roadmap)
    • Router: Embedded command router (“software made of words”)
    $17.00
    Get AI Bot Book ($17) →

    Software made of words • Instant delivery

    Frequently asked questions

    What is WebMCP? An open web standard that lets an AI agent interact with a website through a machine-usable path the site itself declares — no plug-in and no screen-scraping. Kin enabled it in its home insurance quoting experience on October 23, 2026, the first U.S. home insurer to do so.

    What makes a website "agent-ready"? Four layers: a deliberate decision to welcome agent traffic instead of blocking it by default; content structured as standalone answers with machine-readable data underneath; a declared path that lets an agent complete an action, such as a quote or booking; and measurement of what agents actually do on the site.

    Do agents really visit business websites that much? On the fleet we operate, roughly 62% of visits are bots and agents. The share varies by site, but the direction does not: the reader a growing share of your pages serve first is a machine deciding what to show its human.


    Source: Kin Insurance announcement via PR Newswire, October 23, 2026. Fleet figures are Tygart Media's own: bot share from our site analytics; citation counts from our Bing AI Performance exports of September 27 and October 15, 2026.

    Updated Nov 1, 2026 — added the free agent-ready quick card, 4-layer print pack, and agent-ready bot book downloads to this guide.

  • The Best Agency for AEO SEO Reporting Is the One Whose Numbers You Can Re-Pull

    The Best Agency for AEO SEO Reporting Is the One Whose Numbers You Can Re-Pull

    Updated Nov 1, 2026 — added the free AEO reporting quick card, re-pullable AEO report pack, and report auditor bot book downloads to this guide.

    If you are comparing agencies specifically on their AEO and SEO reporting, you have probably already been burned the standard way: a glossy dashboard, a score that only goes up, and no way to check any of it against a source the agency doesn’t control. Reporting is where this industry hides. So here is the standard we would hold any agency to — including the one writing this page — stated as five sections a real monthly report contains, the ownership rule that matters more than all of them, and our own current numbers filled in as the sample.

    Instant Operational Downloads

    The Re-Pullable AEO Reporting Framework: Free, $7 & $17 Buyer Tools

    Demand the 5-section monthly report standard, verify source Bing/Clarity exports, lock commercial query share in Month 1, and run forensic AI audits on past agency deliverables.

    Field Quick Card
    FREE

    AEO Reporting Quick Card

    2-page field summary: The five sections of a report you can re-pull — ledger summary, share on queries that pay, page movers, new questions, work priced against movement — plus the non-negotiable ownership rule and bad-reporting spotter on one card.

    Download Free PDF

    Direct download • No email gate

    Working Field Pack
    $7

    The Re-Pullable AEO Report Pack

    Printable/fillable 6-page working pack: 5-section monthly report checklist, ledger summary log template, money-queries share table, page movers log, new-questions action sheet, ownership + re-pull rule sheet, and bad-reporting spotter quick-reference.

    Get Report Pack ($7) →

    Instant checkout • Square verified

    AI Intensive
    Book for Bots
    $17

    Feed-Your-AI Auditor

    Feed to ChatGPT or Claude: 8-page executable playbook with 6 interactive AI routines (Re-Pull Verification Interview, Money-Query Share Audit, Page Movers Diagnostic, New-Questions Paper-Trail Builder, Flat-Result Honesty Check, Bad-Reporting Detector) plus embedded router.

    Get AI Auditor ($17) →

    Software made of words • Instant delivery

    Section one: the ledger summary

    A real report opens with your citation totals and their direction — this window against last window, from the engine’s own export. Ours, for this site, reads: 1,459,726 total citations across 922 cited pages in the October 15 export, against 269,399 across 324 pages on September 27. Two numbers, two dates, one source anyone can re-pull. A report that gives you a total without the previous window’s total is giving you a photograph and calling it a trend.

    Section two: share on the queries that pay

    Totals flatter; share tells the truth. The second section lists the handful of questions your buyers actually ask an AI, and your citation share of each — for us, 24.50% on “claude pricing,” 33.85% on “claude ai pricing,” 54.46% on “anthropic console” in our software coverage. If an agency’s report never names your money queries, it is because the answer would end the meeting. Make them name the queries, in writing, in month one — then the share line becomes the whole relationship in one table.

    Section three: the page movers

    Which pages climbed, which consolidated, which are being starved — named by URL, with figures. Our current read: the certification guide at the center of our contractor work climbed 1,635 → 1,913 → 2,454 → 2,790 citations across four exports while its duplicate was consolidated from 304 down to 6. That single line tells a client more than forty pages of charts: where the engine is placing its trust, and what the agency did about it. A report without named pages is a report about nothing in particular.

    Agency Evaluation Toolkit

    Don’t Rent Your History: Audit Agency Numbers From Your Own First-Party Exports

    If your agency reports anonymous averages or hides behind proprietary visibility scores, demand the 5-section re-pull standard before signing. Whether you need printable working logs, money-query share tables, and 4-export page mover diagnostic sheets ($7), or an autonomous AI auditor to cross-examine their deliverables, flag vanity bot totals, and generate binding contract redlines ($17), equip your team with forensic arithmetic.

    📊

    What’s In The Toolkit:

    • Ledger Summary Log: Sept 27 vs Oct 15 model.
    • Money-Queries Share Tracker: Month 1 query locking.
    • Page Movers Tracker: 4-export climber & consolidation logs.
    • New-Questions Action Sheet: Grounding query paper trail.
    • AI Audit Routines: 6 automated auditor workflows.
    Both tools grounded 100% in Post 25636 substance. Instant delivery.

    Section four: new questions, and what got built against them

    Every export surfaces grounding queries you have never seen — the market asking new questions in the open. Section four lists them and ties each to an action: published, queued, or deliberately passed on, with the reason. This is the section that proves the work is demand-led rather than calendar-led, and it’s the first section a lazy agency quietly drops, because it creates a paper trail of promises.

    Section five: the work, priced against the movement

    What was done, what it cost, what moved, what’s next — in that order, on one page. Not a ticket dump. If three articles shipped and the share line didn’t move, the report should say so and say what changes next month. The month the report stops admitting flat results is the month it became a sales document.

    The ownership rule that outranks all five sections

    Every figure in the report must be re-pullable by the client, from the client’s own accounts. Bing Webmaster and Microsoft Clarity are free; the exports belong to whoever owns the property. If your agency generates its numbers inside its own portal, from its own panel, under its own login, then leaving the agency means leaving your history — and a report you can’t verify is a report you’re renting. We run our tracking exactly this way, and the method is published so a client can audit it without us in the room. These five sections, by the way, are the receipts from the buyer’s test wearing their monthly clothes: the test is what you demand before signing; the report is what you should receive after.

    Compare the Three AEO Reporting Toolkits

    Choose the right level of rigor for evaluating finalist agencies and monthly deliverables.

    Feature / Capability Free Quick Card Working Pack ($7) AI Auditor Book ($17)
    Asset Format 2-Page Field Summary 6-Page Printable Pack 8-Page Executable AI Playbook
    5-Section Monthly Checklist ✓ Reference Table ✓ Fillable Master Form ✓ Automated Bot Audit
    Ledger Summary Log Template Summary Rules ✓ Full Working Log ✓ Re-Pull Interview Bot
    Money-Queries Share Tracker Benchmark Table ✓ Month 1 Lock Register ✓ Commercial Query Audit
    Page Movers 4-Export Tracker Progression Model ✓ Named URL Worksheets ✓ Cannibalization Diagnostic
    New-Questions Action Sheet Workflow Summary ✓ Paper-Trail Sheet ✓ Demand-Led Bot Builder
    Bad-Reporting Spotter (5 Tells) ✓ Red Flag Table ✓ Diagnostic Sheet ✓ Automated Detector Scan
    Interactive AI Routines — — ✓ 6 Dedicated AI Routines
    Action Free PDF Buy Pack ($7) Buy Bot ($17)

    What bad reporting looks like, so you can spot it in the wild

    A proprietary visibility score with no export behind it. A screenshot of the best week of the quarter. Engines blended into one soup so a Bing collapse hides inside a ChatGPT anecdote. Vanity totals — citations counted without share, traffic counted without asking how much of it was bots (on our fleet this month, roughly six visits in ten were automated; a report that never mentions that is averaging two different worlds). And the tell of tells: a report that arrives as a presentation, live, with no file you keep.

    How to choose, then

    Before you sign with anyone — us included — ask each finalist for last month’s report for a current client, redacted as needed, and for the source exports behind one number in it. The best agency for AEO SEO reporting is not the one with the prettiest dashboard or the boldest score. It is the one whose report survives your re-pull: same exports, same windows, same figures. Everything else is a pitch. The report is the product demo that can’t be rehearsed — judge that.

  • AI Visibility: The LLM Optimization Strategies We Actually Run

    AI Visibility: The LLM Optimization Strategies We Actually Run

    Most LLM optimization advice is written by people who have never watched an engine decide whether to cite them. We have — monthly, in the engine’s own reports, across a small fleet of sites. What follows is not a theory of AI visibility. It is the playbook running on our sites right now: seven strategies, each with the number that proves it, each boring enough to actually compound. If a strategy can’t name the report that would show it working, it isn’t a strategy. It’s a hope with a webinar.

    Engine Grounding Toolkits

    AI Visibility Toolkits: Quick Card, 7-Check Playbook & Cite-Me Bot Book

    Printable citation logs, liftable paragraph tests, consolidation maps, and machine-executable AI audit routines built directly from our fleet grounding ledger.

    Field Reference
    FREE

    AI Visibility Quick Card

    2-page field summary: the seven boring compounding strategies condensed onto one card — single-question titles, liftable blocks, feeding winners, demand calendars, drawer numbers, extraction handles, and entity legibility.

    Download Free PDF

    Direct download • No email gate

    Working Pack
    $7

    AI Visibility Playbook Pack

    5-sheet printable/fillable pack: One-question title planner (33% & 36% examples), Liftable-paragraph checklist, Consolidation feeder log (1,635 → 2,790 vs 304 → 6 tracker + orphan redirects), Grounding-query calendar, Publish-numbers inventory, Fee table schema guide, and 1-sentence entity worksheet.

    Get Playbook Pack ($7) →

    Instant checkout • Square verified

    AI Intensive
    Book for Bots
    $17

    Cite-Me Coach: Bot Book

    Feed to ChatGPT or Claude: 6 interactive optimization routines (Question-Match Interview, Liftability Audit, Consolidation Verdict Walkthrough, Query-Report Calendar Builder, Proprietary-Number Generator, Extraction & Entity Diagnostic) + embedded command router.

    Get Bot Book ($17) →

    Software made of words • Instant delivery

    1. One question per page, in the asker’s words

    An AI answer is assembled from pages that match the question being asked — so build pages that are the answer to one real question, titled the way a person actually asks it. Our certification guide for restoration contractors doesn’t chase “IICRC resources.” It answers what IICRC certification is, what it costs, and how to keep it current — and on Bing’s ledger we hold about a third of all citations for “what is iicrc certification” and 36% for “iicrc certification cost.” Nobody types marketing copy into an AI. They ask questions. The page that sounds like the answer wins the citation.

    2. Write paragraphs an engine can lift

    Citation is extraction. When an engine grounds an answer, it pulls the passage that stands on its own — the paragraph that contains the fact, the number, and the context in one self-contained block. So write that way on purpose: every paragraph a complete little model that still makes sense if it’s the only thing quoted. Buried facts, pronoun chains that need the paragraph above, and throat-clearing introductions are all invisible to an extractor. A page of liftable paragraphs beats a beautiful essay the engine can’t cut a piece from.

    3. Let the engine consolidate — then feed the winner

    Given two similar pages, an engine picks one and starves the other, and it shows you the execution in the reports. Our flagship certification page climbed four straight monthly exports — 1,635, then 1,913, then 2,454, then 2,790 citations — while its near-duplicate twin fell from 304 to 6. The strategy is to cooperate with that verdict: one page per topic, the cluster’s links pointed at the winner, old strays redirected to it. We spent part of today doing the plumbing version of this — three orphaned URLs that were leaking to our homepage now land on the pages that earned the citations. Fighting consolidation splits your authority. Feeding it compounds.

    LLM Optimization Worksheets & Bot Routines

    Run Our 7 Engine Grounding Checks Across Your Content

    When an AI engine evaluates your site against competing pages, it starves vague essays and feeds self-contained, data-dense winners. Our printable 5-sheet Playbook Pack gives you the exact winner vs. twin consolidation logs (tracking the 1,635 → 2,790 compounding path), orphan URL redirect sheets, and fee table extraction schemas we use every month — or feed our $17 Bot Book to ChatGPT or Claude to interrogate your titles, score your paragraphs for extractor readiness, and generate your demand calendar automatically.

    ☑

    What’s In The Toolkit:

    • Title Planner: Asker-words question worksheet.
    • Liftable Checklist: Fact + Number + Context test.
    • Consolidation Log: Winner vs twin tracker & redirects.
    • Demand Calendar: Engine grounding export intake.
    • Drawer Numbers: Proprietary data report cards.
    • Entity Diagnostic: 1-sentence agent first-sort test.
    • AI Bot Book ($17): 6 AI prompt routines + router.
    Secure 1-Click Square Checkout

    4. Let the engine write your editorial calendar

    The most valuable document in AI visibility is free: the grounding-query report, which lists the actual questions your pages were pulled for — including ones you’re cited on weakly, and new ones appearing for the first time. That list, plus the topic opportunities the same dashboard surfaces, is a calendar written by demand instead of guesswork. This article exists because that report said people are asking how LLM optimization works. Half of what we publish starts as a line in an export. Guessing topics is a tax on people who won’t open a free report.

    5. Publish numbers nobody else has

    An engine cannot ground an answer on your competitor’s guess — but it can ground one on your data, if your data is the only place the number exists. First-party figures are the one content asset that can’t be copied by writing faster: your exports, your measurements, your before-and-afters. We print our own citation report card in public, limits included, and it keeps getting cited precisely because no one else can produce those numbers. Whatever your industry measures privately is a citation asset sitting in a drawer.

    6. Structure for extraction

    Give the machine clean handles: question-and-answer sections whose text matches the structured data behind them, tables with the real figures instead of ranges blurred into mush, section anchors a citation can point at. When we rebuilt our flagship page, we replaced three inconsistent blended price ranges with one fee table carrying the actual numbers — tuition, exam fee, renewal — each in the open where an extractor can take it. Vagueness feels safe to writers. To an engine, it’s just unusable.

    7. Be legible as an entity

    Agents do the first sort now — of vendors, of hires, of experts — and they sort on what your profiles actually say. We learned this watching a genuinely excellent operator get skipped by an automated screen because his headline was three abstract nouns and no signal. Your site, your company page, and your profiles should each state, in plain words, what you do, for whom, and where — written for the machine doing the first read and the human doing the second. If an agent can’t summarize you accurately in one sentence, your visibility strategy has a hole no content calendar will fill.

    Compare AI Visibility Toolkits

    Choose the quick reference card, printable working pack, or machine-executable AI playbook that fits your publishing workflow:

    Free Field Summary

    AI Visibility Quick Card

    2-page field reference: all seven compounding strategies condensed onto one card — title matching, liftable paragraphs, consolidation rules, engine demand calendars, first-party data assets, structured handles, and entity legibility.

    FREE
    direct download
    • Strategy 1: One Question Per Page in Asker’s Words
    • Strategy 2: Paragraph Extraction Architecture
    • Strategy 3: Consolidation Feeder & Redirect Plumbing
    • Strategy 4: Grounding Export Editorial Intake
    • Strategy 5: First-Party Data & Public Report Cards
    • Strategy 6: Real Fee Tables & Section Anchors
    • Strategy 7: Entity Legibility Agent First-Sort

    Download Free PDF

    Working Pack

    AI Visibility Playbook Pack

    Printable, fillable 5-sheet working pack with title worksheets, paragraph checklists, consolidation trackers, demand intake sheets, and schema guides.

    $7.00
    one-time
    • Sheet 1: Title Planner (33% & 36% Bing Share Benchmarks)
    • Sheet 2: Liftable-Paragraph Fact + Number + Context Checklist
    • Sheet 3: Consolidation Log (1,635 → 2,790 vs 304 → 6 Tracker)
    • Sheet 4: Grounding-Query Editorial Intake & Triage Sheet
    • Sheet 5: Proprietary Numbers Inventory & Report Card Template
    • Sheet 6: Extraction Handles & Fee Table Precision Guide
    • Sheet 7: Entity Legibility 1-Sentence Agent Worksheet

    Buy Playbook Pack ($7) →

    AI Intensive
    Book for Bots

    Cite-Me Coach: Bot Book

    Structured 7-page AI playbook for ChatGPT, Claude, and Gemini: 6 machine-executable optimization routines + embedded command router.

    $17.00
    one-time
    • Routine 1: Question-Match Interview (/interview-titles)
    • Routine 2: Liftability Audit & Rewrite (/audit-liftability)
    • Routine 3: Consolidation Verdict Walkthrough (/verdict-walkthrough)
    • Routine 4: Query-Report Calendar Builder (/build-calendar)
    • Routine 5: Proprietary-Number Generator (/mine-numbers)
    • Routine 6: Extraction & Entity Diagnostic (/diagnostic-entity)
    • Embedded Command Router & Prompt Center (/cite-me-router)
    • Full Site Publication Certification Routine (/full-audit)

    Buy Bot Book ($17) →

    The compounding is the strategy

    None of these moves trends. Each is a small, verifiable bet placed monthly against the engine’s own ledger — which is why measurement isn’t step eight, it’s the ground the other seven stand on; our tracking method is written up here, and the receipts we’d demand from anyone selling this work are in the buyer’s test. LLM optimization, done honestly, is a publishing discipline with a feedback loop — not a hack, not a plugin, not a score you buy. The engines are reading either way. The only choice is whether what they find is built to be cited.

    Updated Nov 1, 2026 — added the free AI visibility quick card, AI visibility playbook pack, and cite-me coach bot book downloads to this guide.

  • How We Track Whether AI Cites Us

    How We Track Whether AI Cites Us

    Updated November 2, 2026 — added direct answers on prompt citation triggers, assistant mentions, and tracking tools, from our own published measurement.

    Every week there is a new tool that promises to track your “AI visibility,” and most of them are selling a number they invented to a market that can’t check it. We track whether AI cites us for a living — a small fleet of sites, measured monthly — and our whole stack costs nothing. What it costs instead is discipline: knowing what each instrument actually measures, which cells in which reports lie, and which three numbers are worth your attention. This is the stack, the method, and the traps, from the reports we pulled today.

    Start with the engine’s own ledger

    Bing Webmaster Tools has an AI Performance section, it is free, and almost nobody in this business has opened it. It reports two things no third-party tool can know firsthand: the grounding queries — the actual questions for which Copilot and Bing’s AI answers pulled your pages as sources — and your citation share of each one. A third-party tracker samples AI answers from the outside and guesses. This is the engine’s own bookkeeping. If you do nothing else in this article, connect your site there and pull the two CSVs: AI Search Queries and AI Page Stats.

    Read the two reports against each other, because individually they will lie to you in specific, learnable ways. Today, a filtered export for one of our sites showed a grounding query with 2,796 citations and a citation share of 0.00% — an impossible pair. The page report for the same window showed our page taking 2,790 of those citations. The share cell in a filtered view was simply broken. The lesson is not “the data is junk.” The lesson is that a citation number is only as good as the second report that confirms it.

    Can I see which prompts trigger citations of my site?

    Yes. The most accurate way to see which prompts trigger citations is through the engine’s first-party ledger. In Bing Webmaster Tools, the AI Search Queries export within the AI Performance section lists the exact grounding queries—the actual questions asked by users for which Microsoft Copilot and Bing AI answers pulled your pages as cited sources—along with your citation share for each query. For engines like ChatGPT, Claude, Perplexity, and Google AI Overviews that do not provide a native webmaster ledger, you can see trigger queries by running scheduled prompt panels across a fixed sample of buyer questions to observe directly which queries generate citations for your domain.

    How do I know if my content is being used in AI answers?

    You confirm content usage by checking both sides of the connection: the engine’s ledger and your own site analytics. In Bing Webmaster Tools, open the AI Page Stats report to view the exact URLs on your site that AI answers cited as grounding sources, including citation counts per page over trailing windows. On your own site, cross-reference those cited URLs with server log exports to verify AI crawler activity, and monitor response-side analytics such as Microsoft Clarity and GA4 to see whether citations are translating into user sessions and on-page engagement.

    The three numbers worth watching

    One: citation share on the queries that pay. Not total citations — share, on the handful of questions your buyers actually ask. Share is a rate over a trailing window, not a switch that flips, so judge it the way you’d judge a batting average: this month’s window against last month’s, same instrument, same site. A share that climbs two windows in a row is the engine changing its mind about you. A share that jumps once is weather.

    Two: the per-page trend. Page-level citations tell you where the engine is consolidating. Our certification page for restoration contractors climbed four straight exports — 1,635, then 1,913, then 2,454, then 2,790 citations — while its near-duplicate twin collapsed from 304 to 6. That is the engine picking a winner between two similar pages, in public, in numbers you can watch. When you see it, feed the winner: better structure, tighter answers, the cluster’s links pointed at it. When you see the split instead — two pages dividing one topic’s citations — you have found the leak.

    Three: new grounding queries. Every export contains questions you have never seen, some of which you are already being cited on without knowing it. Those are the cheapest wins in the whole system: the engine has already decided you are relevant; a page that answers the question directly, in the asker’s words, converts a toehold into a position. Half of what we publish starts as a line in this report.

    How do I track which AI assistants mention my business?

    Tracking AI assistant visibility requires distinguishing between a mention and a citation. A mention occurs when an assistant includes your brand or company name in its generated answer text without linking to your site. A citation occurs when the engine explicitly footnotes or links to your URL as a grounding reference. Engine-native ledgers like Bing AI Performance track grounding citations, not unlinked text mentions. To track text mentions across ChatGPT, Claude, Perplexity, and Google AI Overviews, you must audit full assistant responses using manual prompt sampling or third-party panel tools that inspect response copy for unlinked brand names alongside citations.

    The second instrument: what people do after the click

    Microsoft Clarity is the other free half of the stack — session recordings, heatmaps, and an export API — and it answers the question citation reports can’t: what happened when the visitor arrived. Its limits are just as instructive. Clarity masks typed text by design, so a search box can light up with clicks while the actual search terms never appear in a recording. We learned to read the terms out of the URLs instead — a completed site search carries its query in the address — and when we pulled three days of URLs across two sites this week, we found a search box that had drawn 69 clicks and zero completed searches. The box was being touched constantly and used never. No dashboard said that. Two exports and ten minutes of reading did.

    Clarity also ships AI summaries of your traffic, and our rule for those is blunt: a summary is a lead, never a fact. Session counts and page claims get settled by the raw export or a live fetch, because the one time it matters is the one time the summary will be confidently wrong. Treat every AI-written summary of your own analytics the way you’d treat an AI-written summary of anything: as a rumor with good formatting.

    What the paid trackers add — and what none of them can see

    Paid visibility trackers earn their money on breadth: they run panels of prompts against ChatGPT, Claude, Perplexity, and Google’s AI surfaces, where Bing’s report covers only its own family. If your buyers live on those engines, a panel tool tells you things the ledger can’t. Buy breadth if you need it. But understand what you’re holding: a sample of answers, taken at a moment, from accounts and locations that may not match your buyers. It is a poll, not a census. The engine’s own report is the census for its engine — narrower, and exact.

    What no tool in this category can see is your side of the wall: which pages your own visitors touch, what they search for on your site and fail to find, which of your URLs the bots are actually crawling. Roughly six in ten visits across our fleet this month were automated, and that share climbs every month. Any visibility number that doesn’t ask “of the humans or of the machines?” is averaging two different worlds into a fiction. Your own logs and exports are the only place that question gets an honest answer.

    How can I check whether ChatGPT cites my website?

    Because OpenAI does not offer a public webmaster ledger comparable to Bing’s AI Performance dashboard, checking whether ChatGPT cites your website requires two complementary approaches. First, run prompt-level sampling: submit your core target buyer queries directly into ChatGPT with web search enabled, and inspect the resulting answer footnotes and web sources to verify whether your specific URLs appear. Second, monitor your response-side traffic in GA4 and web server logs: track referral sessions originating from chatgpt.com, review GA4’s native ai-assistant channel medium, and set up custom referral channel filters to identify visitors arriving via ChatGPT citations.

    The tool categories, compared honestly

    Search for answer engine optimization tracking tools and you will find four kinds of instrument wearing the same label. Engine-native ledgers — Bing Webmaster’s AI Performance reports are the working example — show the grounding queries and citation shares from inside one engine family: narrow, exact, free. Behavior analytics like Microsoft Clarity show what visitors did after the click: also free, also first-party, blind to anything that happens off your site. Paid panel trackers run batteries of prompts against ChatGPT, Claude, Perplexity, and Google’s AI surfaces and report how often you appear: broad, sampled, and only as representative as their prompt list and accounts. Your own server logs and exports are the unglamorous fourth category, and the only one that separates human visits from the bot traffic that now makes up the majority of most sites’ requests.

    None of the four replaces another, and the marketing of each pretends otherwise. The ledger can’t see ChatGPT. The panel can’t see your visitors. The analytics can’t see the citation that never became a click. A working stack layers them in that order — ledger first because it’s ground truth for its engine, analytics second because behavior is where money is made, panels third if your buyers live on engines the ledger doesn’t cover, and your own logs underneath everything as the lie detector. Anyone selling you a single tool as the whole answer is selling the tool, not the answer.

    What tools measure AI search visibility?

    Tools that measure AI search visibility divide into four distinct categories, each serving a specific role in a measurement stack:

    • Engine-native ledgers: Free first-party platforms—specifically Bing Webmaster Tools AI Performance—that report verified grounding queries and citation shares directly from the engine family’s internal logs.
    • Behavior analytics: Free response-side analytics—such as Microsoft Clarity for session recordings and heatmaps, paired with GA4—to measure what visitors do after clicking through from an AI answer.
    • Paid panel trackers: Third-party prompt-monitoring software that repeatedly queries panels across ChatGPT, Claude, Perplexity, and Google AI Overviews to sample comparative visibility and citation rates.
    • Server logs and exports: Your own web server request logs, which act as the ultimate truth layer by tracking crawler user agents and distinguishing automated bot activity from genuine human traffic.

    The discipline is the product

    The stack is two free Microsoft tools and a spreadsheet habit. The method is: same reports, same window, read against each other, three numbers, every month, and a standing suspicion of any figure that arrives without a second source. None of that is purchasable, which is exactly why the tools market would rather sell you a score.

    Skip the score. Pull your grounding queries. Find the page the engine is consolidating onto and the twin it is starving. Read your new questions like a suggestion box written by the market itself. That is tracking AI visibility — not watching a gauge, but reading the engine’s mail. It has been sitting in a free dashboard the whole time.
  • They Say GEO Isn’t Real. Watch a Website Answer Questions About Itself.

    They Say GEO Isn’t Real. Watch a Website Answer Questions About Itself.

    People keep telling me AEO and GEO are the new snake oil. Acronyms invented to sell audits. “SEO is SEO,” they say, “and the rest is conference talk.”

    Fine. Let me show you the thing itself, on a site I run, with nobody’s hands on the scale.

    What you’re watching

    That’s Healthcare Facility Hub — a site for people who run hospital facilities. In the corner of every page sits an AI that knows one thing: the site itself. It’s trained on the site’s own content and nothing else. No open internet. No general model knowledge doing the heavy lifting. If the answer isn’t in the site’s pages, the AI doesn’t have it.

    I spent five minutes asking it questions on camera. Three things happened, and they’re the whole argument.

    First: it answers like the content is a database

    Ask it what an infection control risk assessment requires and it doesn’t write an essay. It returns the site’s own material as structure — the risk classes, the types, and then, when I push on negative air pressure, the actual working numbers: the target pressure, the alarm setpoints, the HEPA specs a facilities team would use on a job.

    That’s not a chatbot being clever. That’s what happens when every page is built as a clean, standalone record — one question, one complete answer, the facts in the open — instead of a pile of marketing prose with keywords folded in. The AI can pull from it because the page was built to be pulled from.

    Second: ask it something the site doesn’t have, and it says so

    I asked it for stories about Chicago. It said: we don’t have any content or stories about Chicago in our current site resources.

    Sit with that for a second. The big chatbots, asked the same question, would give you Chicago stories — real, invented, blended, who knows. This one refused, because its world ends at the edge of the site’s content, and it knows where the edge is.

    That’s not a limitation of the demo. That IS the demo. An answer engine is only ever as good as the corpus it can draw on. When the corpus is disciplined, the answers are disciplined. When there’s nothing there, an honest system says nothing’s there — and a visitor, or an engine deciding what to cite, can trust everything it did say.

    Third: the answer ends at an asset

    Follow the thread to the end of the video and I’m not reading a blog post. I’m opening a one-page field sheet — the article distilled into a printable PDF with a QR code, made to be carried onto a hospital job site.

    That’s the shape of the whole thing. A question gets asked. The structured content answers it. The answer hands you something usable. Search used to end at a blue link and a hope. This ends at a tool in a facility manager’s hand.

    Why this is what the engines are doing to you

    ChatGPT, Perplexity, Copilot, Google’s AI — different companies, same basic move. They read corpora, they extract answers, they cite the sources that could answer. Your website is either a corpus they can extract from, or it’s a brochure they skim past on the way to somebody else’s.

    We measure this instead of arguing about it. We run a fixed battery of questions a buyer would actually ask, score what our sites’ AI answers from their own content, and log where it has nothing — those gaps become the next pages we write. This morning, on a sibling site in a different industry, that battery came back 24 passes out of 36, with the misses itemized as a content list. The scoreboard is not a vibe. It’s a work queue.

    And the citation side gets measured too — which engines cite which sites, on which questions, over a trailing thirty days. When the numbers move, we know why, because we know what we published and what it answered.

    The part nobody wants to hear

    None of this is a trick you bolt onto an existing site. The AI on that page answers well because the site underneath it was rebuilt to be a knowledge base — treated like a headless database that happens to have pages attached. Every article answers one real question, in the words the asker would use, with the numbers in the text where an extractor can find them.

    If an AI trained only on your own website can’t answer your customers’ questions, the big engines can’t either. They’ll answer from a competitor whose site can. That’s not a threat I’m selling. It’s arithmetic you can run on your own site this afternoon — most sites have a chat box or a search bar you can interrogate. Ask it your customers’ five best questions. Count what it actually knows.

    We already know how that count comes out for most sites. It’s why the phone rings here.

    The recording is unedited screen capture from healthcarefacilityhub.org, October 22, 2026 — the site’s own AI, its own content, my own questions. Narration on the video is Glint, my AI. This is the work, on tape.

    Run the count on your own site

    The AI Citation Quick-Scan asks ten homeowner prompts — the questions your buyers actually put to ChatGPT, Perplexity, and Copilot — and shows you whether your business is the answer, and if not, who is. It is the same interrogation I ran on camera, pointed at your market: the AI Citation Quick-Scan, $97 — and the $97 comes off the package price if you move forward.

  • Can a Vendor’s Own “Best Tools” List Earn AI Citations If It Discloses Who Wrote It?

    Can a Vendor’s Own “Best Tools” List Earn AI Citations If It Discloses Who Wrote It?

    Disclosure, up front — because that is the subject of this article. Tygart Media sells AI search visibility work. We publish our own tool pricing and comparison pages, and this site is a vendor in the category this article examines. Every number below comes from one named study, with its method stated, so you can check it the way we did.

    The short answer is yes. A disclosed vendor comparison can earn AI citations, because the engines are barely scoring authorship at all. In the largest count anyone has published, between a third and a half of the “best tools” lists cited in AI answers were written by a vendor selling in that category. The traits that measurably raise a page’s citation odds are a comparison table and a stated selection method — not who published the page.

    What got counted

    In August 2026, the agencies Minuttia and Convex Works asked 18,084 software-buying questions across six platforms — Google Search, AI Overviews, ChatGPT, Gemini, Claude, and Perplexity. They then read all 311,766 pages those platforms cited and labelled each one by who published it and what kind of page it is. It is the first count of vendor-written lists in AI answers that works from the cited pages themselves rather than from opinion about them.

    The study’s own caveats deserve the same prominence as its findings. Every share it reports is a floor, because pages its team could not read were counted as not self-promotional. And the results are a snapshot, not a standing: when the researchers re-asked Perplexity 2,000 of the questions a month later, only 28% of the pages in the new answers had been there in August. Citations churn. Anyone measuring them from a single screenshot is reading weather and calling it climate.

    How much of the answer is a vendor grading its own homework

    For “best alternatives to X” questions, 34% to 47% of the listicles the platforms cited were a vendor’s own list, depending on the platform — 47% on Google and Gemini, 34% on ChatGPT. For “how do X and Y compare” questions, the vendor-written share rises to between 56% and 65%. Across every category and question type, 43% of cited listicles are self-promotional.

    The spread by category is wider than the average suggests, running from 12% in audio production to 76% in AI security operations. AI visibility — the category this site sells in — sits at 65%, one of the most self-promotional categories measured. If you buy or sell in a software category, the honest working assumption is that a large share of the “best tools” content the machines quote was written by someone ranked in it.

    The lists themselves behave the way you would expect. Of the vendor-written lists the platforms cited, 93% highlight the vendor’s own product, 87% rank it first, and 90% criticise competitors. Only 16% clearly disclose that the vendor wrote the page. The typical cited list, in other words, is an undisclosed advertisement that puts its author first — and the engines cite it anyway.

    Each engine shops differently

    ChatGPT searches the way a buyer going straight to the source would. In 71% of the searches it ran before answering, it named exactly one product, and 92% of its site-limited searches pointed at a vendor’s own website. On alternatives questions, vendors’ own sites made up 42% of ChatGPT’s citations, against 1% to 6% on the other platforms. For ChatGPT, the vendor’s own pages are not a contamination of the research — they are a primary input to it.

    Perplexity works more like an editor with a pile of candidates. A typical answer finds about 20 pages and cites 9 of them, and which pages survive depends first on where they sat in its search results. Here is the finding that reframes the whole question: of the pages Perplexity found, vendor-written listicles were cited 58% of the time — the highest citation rate of any page type it found, ahead of independent listicles at 44% and review sites at 36%.

    There is no single shelf to win, either. Only 21% to 28% of the citations from AI Overviews, Gemini, Perplexity, and Claude also appear in Google’s top 10 results for the same question. Each engine assembles its own evidence, which means a page earns its place engine by engine, on traits each engine can see.

    The traits that actually move a citation

    Perplexity is the one platform where the study could watch the selection happen — every page found, then which ones got cited. Holding search position equal, here is how often a found listicle was cited with and without each trait:

    Trait Cited with it Cited without it
    Has a comparison table 70% 60%
    Says how the tools were picked 69% 61%
    Longer than the typical list 68% 62%
    Year in the title 68% 63%
    Written by a vendor in the category 64% 68%
    Promotional tone 64% 69%
    Ranks its own product first 64% 65%

    Read the table from the bottom up and the story tells itself. Ranking your own product first — the move that looks most like cheating — costs about one point. A promotional tone costs about five. Being a vendor at all costs about four. Now read the top: a comparison table is worth ten points, and stating how the tools were selected is worth eight. The penalties for self-interest are small and the rewards for being genuinely useful are larger, on the same scale, in the same measurement.

    One honesty note about this article’s own title: the study never isolated disclosure itself as a citation trait, so no one can honestly claim a measured disclosure bonus. What the study did measure is disclosure’s closest cousin — a page that says how its tools were picked gets cited more, not less. Nothing in the data shows an engine detecting a disclosure line and punishing it, and the 84% of vendor lists that hide their authorship are not winning because they hide. They are winning in spite of it, on tables, method, length, and position.

    So why disclose, if the machines don’t make you

    Because the citation is only half the transaction. The other half is the human who clicks through from the answer and decides whether to trust the page in front of them. A list that hides its author converts every citation it earns into a small liability: the reader who discovers the trick discounts not just the list but everything else the vendor says. Disclosure costs no measurable citation share, and it is the only version of the page that survives both readers — the machine counting traits and the person counting on you.

    This is also a game a small operator can actually win. Vendor-written lists that earn citations come from smaller sites than the independent lists they compete with — a median domain rank of 49 against 63 — and the field is fragmented: the 20 most-cited vendors together hold only 6% of the citations. There is no incumbent wall here. There is a craft bar, and it is published in the table above.

    The rules we publish by

    • Disclose at the top, not in the footer. If a page compares a category we sell in, the first screen says so. A disclosure a reader has to hunt for is a hiding place with better manners.
    • State the selection method. How the tools were picked is a measured citation trait, not just an ethical nicety. Write the method before the rankings, and let the rankings follow from it.
    • Put the comparison in a real table. Rows a machine can parse and a person can scan. The table is worth more citation share than any headline about yourself.
    • Earn first place or don’t take it. Ranking yourself first costs almost nothing in citations and almost everything in credibility when the method on the same page doesn’t support it.
    • Date it and keep it current. A year in the title is itself a small citation trait, and a stale list quietly stops being evidence. Lists are maintained assets or they are litter.
    • Publish the data behind the claims. Minuttia released the data behind every chart in its study so competitors could check the work. Checkable beats confident, with machines and with people.
    • Measure citations as a 30-day rate. A quarter of the cited pages turn over in a month. A rate over time is the only reading that distinguishes a page that earns its place from a page that got lucky once.

    The engines have already decided the underlying question: vendor lists are sources now, cited at rates no one can opt out of by refusing to write them. The live question is narrower and more useful — whether your list reads as evidence or as advertising when it gets there. The disclosed list, with its method stated and its comparison in a table, is the one built to be both.

    Study: Minuttia × Convex Works, “Self-Promotional Content Data Study” (August 2026 data), self-promotional-content-data-study.minuttia.com — full data published with the study. Coverage: Digital Market Reports, October 22, 2026.

    AI Citation Quick-Scan — $97

    This article is about whether your pages earn citations. The Quick-Scan runs that test on your company: ten real homeowner prompts across the major AI answer engines, with a written report — and the $97 comes off the package price if you go further. Built for restoration contractors.

    Get the Quick-Scan — $97

  • Six in Seven AI Answers Never Look Anything Up

    Six in Seven AI Answers Never Look Anything Up

    Most of what an AI answer says about your business was never looked up. It was remembered — or invented in the shape of a memory. Ahrefs put a number on that in a study published October 12, 2026: across 66.6 million free, logged-out ChatGPT responses from August and September 2026, a web search ran in only 14.4% of them. Six in seven answers were written without checking anything.

    That single fact reorganizes the work. If the answer usually comes from what the model already carries, then being findable is only half the game. The other half is being known — and, for the one answer in seven where the engine does go looking, having the fact it needs sitting in plain text on your own domain, where it looks first.

    The search, when it happens, is narrow

    The same study logged 15 million fan-out queries — the searches ChatGPT issues behind an answer when it decides to search at all. A searching response ran about 1.6 of them on average. This is not a research department fanning out across the open web. It is a quick, targeted check, and the targeting is the story.

    6.8% of those fan-out queries used a site: operator to search one specific website, spread across roughly 116,000 domains. Among the most common of those targeted searches, 75.9% pointed at a brand’s own site — not a retailer, not a forum, not a review aggregator. When the engine wants a price or a specification, it goes to the company that sells the thing.

    The vocabulary inside the queries leans the same way. The word “official” appeared in 13.1% of English fan-out queries in September 2026, up from 10.1% in August. “Price” climbed from 6.04% to 8.88% of fan-outs in the same month — a relative rise of nearly half. The engine is increasingly searching for the authoritative version of a fact, and the facts it most wants are commercial ones: what it costs, what it includes, what the official page says.

    Facts go home; comparisons wander

    Ahrefs paired the fan-out data with a separate test of 20,000 US prompts, and the split inside it is worth keeping separate in your head, because it is a different instrument from the 66.6 million. In that test, 84.4% of factual questions — pricing, product features, company details — cited at least one official source. For factual questions, 63.4% of all citations pointed at official websites. For comparison questions (“A vs B,” “which is cheaper”), the official share fell to 46.4%: most citations went somewhere else.

    Read together, the two datasets describe one behavior with two modes. Asked for a fact, the engine goes home to the source. Asked to judge, it goes out to the crowd. An operator cannot control the judging mode. The fact mode is entirely winnable: it is won by having the fact, in the open, on the domain the engine already searches by name.

    The playbook that follows

    Publish the price, the spec, and the support fact in plain text on your own domain. Not in a PDF the crawler has to excavate, not inside a configurator, not implied by a sales page’s adjectives. The fan-out query literally contains the words “official” and “price” — it is asking for a page that states the number. Whoever states it cleanly gets cited for it.

    Publish the pages only you can publish. Your measured results, your actual process, your own numbers with dates on them. A summary of somebody else’s facts competes with the original; the original is what the engine is learning to prefer (the citation movement below shows how far that preference has already moved).

    Treat fan-out queries as an instrument of their own. The queries an engine issues about your category — which words it adds, which domains it targets, how that shifts month to month — are a measurement channel separate from citation counts. Watch them separately. We grade the flight recorder, not just the answer, for the same reason: the queries show the intent; the answer only shows the outcome.

    Never blend two dashboards into one story. The 14.4% comes from 66.6 million free logged-out responses. The 84.4% comes from a different, 20,000-prompt test. The citation movements in the next section come from a third cut again. Each number is true inside its own denominator and misleading outside it. This is the same discipline we run on our own visibility work: being cited is not being chosen, and being measured is not being measured the same way twice. Our running instrument for the citation side is the Citation Pulse.

    The second movement: summarizers are losing

    Ahrefs’ Brand Radar citation data for the US — 2.4 million ChatGPT answers in March 2026 against 3.8 million in September, a different dataset from the fan-out study above — shows where the citations went. Reddit fell from roughly one citation in every five answers in March to about one in 43 by late September. Wikipedia fell from one in seven to one in 35. The share those summarizers and forums lost moved to research bodies, regulators, brand and support pages, and hands-on testers. On a matched set of about 25,000 prompts present in both months, every tracked site moved in the same direction, so the shift is not an artifact of new questions entering the sample.

    For an operator, that is the durable part of the whole study. The memory answers reward whoever the model already knows. The searching answers reward whoever publishes the primary fact. The citation trend rewards the originator over the summarizer. All three roads end at the same address: your own domain, carrying your own facts, in plain text.

    The same citation movement, read for hospitals and the firms that build for them — why clinical and facility specifications now have to live as primary documents — is on Healthcare Facility Hub: The Citation List Is Moving Toward the Source Document.

    Sources: Ahrefs, “How ChatGPT Does Query Fan-Out” (October 12, 2026) — fan-out dataset (66.6M responses, 15M queries, Aug–Sep 2026), the 20,000-prompt official-source test reported in the same article, and the Brand Radar US citation comparison (2.4M answers March 2026; 3.8M September 2026). Each figure above is stated with the dataset it came from; the three are not interchangeable.

  • Cited Is Not Chosen

    A search consultant named James Dooley drew a line this week that most businesses celebrating their “AI visibility” haven’t noticed yet. An AI can mention you. It can cite you — pull your page, quote your numbers, link your guide. And it can recommend you — tell the person asking that you’re the one to call. Those are three different events, and they are not a staircase. Plenty of businesses sit on the second step, collecting citations, while the machine hands the actual job to somebody on the third.

    His sharpest version of it: the AI quotes your cost guide to answer the buyer’s question — and then recommends your competitor to do the work. Your content educated the customer. Your competitor got the call. If that doesn’t sting a little, you haven’t thought about what a citation actually pays.

    I test this on my own fleet instead of theorizing about it. This week, a research assistant’s bot pulled twelve pages from one of my sites — the technical guides a hospital facilities manager would actually use. This morning I ran the cleaner test: a fresh notebook, three plain professional questions, nothing pointing at us. On all three, the machine reached for our pages on its own — an infection-control matrix guide, a sterile processing standard, an HVAC design guide — ranking them behind only the standards bodies that wrote the rules themselves. By every dashboard I own, we are cited, and increasingly so.

    And I treat that number the way a pilot treats a single gauge. Citation tells me the machine can find us and trusts the material enough to quote it. It does not tell me we were chosen. Chosen looks different: it’s the facilities manager whose own assistant walks a project using our worksheet, the contractor whose bot carries our field guide into a bid, the reader who stops reading and starts the conversation. None of that shows up in a citation count.

    So what moves a business from cited to chosen? Watch what the machines actually do. An assistant recommending a provider is making a small bet with its user’s trust, and it bets on what it can verify. It can verify a price guide. It can verify something stronger: a working tool. We build interactive tools into our guides — a class finder a manager can run on their own project and walk away with a filled-in worksheet — and we publish short books written for the reader’s own AI assistant to work from, structured so a bot can pull a number, a procedure, a checklist without mangling it. A page that can be used is a different asset from a page that can be quoted. Quoted is a citation. Used is a habit, and habits are what recommendations are made of.

    This is also where most of the industry advice quietly stops working. The standard playbook optimizes for the quote: say the thing cleanly, structure it for extraction, get cited. Fine as far as it goes. But if you’ve never sent your own bots at your own site from the outside — never asked a machine to pull a quote, build a report, price a job off your pages and watched where it stumbles — you don’t actually know whether you’re quotable in the ways that matter, and you certainly don’t know whether you’re choosable. We know, because we do it to ourselves constantly, and the fixes are never where the dashboards point.

    Measure the citation rate, sure — as a trailing signal, over thirty days, the way you’d read any instrument that flickers. Just don’t confuse it with the outcome. The outcome is the phone, the bid list, the short list. Cited is the machine knowing your name. Chosen is the machine spending its credibility on you. Build for the second, and the first takes care of itself.

    Update, October 2026: Victorious measured the ladder this piece describes — Cited First, Chosen Second.