Agency Playbook - Tygart Media

Category: Agency Playbook

How Tygart Media builds and runs the agency: the systems, and the process, from the inside.

  • Notion Storage Layer: Decoupling WordPress Distribution

    Notion Storage Layer: Decoupling WordPress Distribution

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart • Long-form Position • Practitioner-grade

    If your WordPress site goes down tomorrow, what happens to your content?

    For most operations, the answer is: it’s gone until the site comes back, and if it comes back wrong, there’s a recovery process that takes hours and may not be complete. The content lives in WordPress because WordPress is the system — not just the distribution point, but the source of truth.

    This is tool-first design. And it’s fragile in ways that only become visible when something breaks.

    The behavior-first alternative separates the functions that WordPress conflates. Writing and storing content is one behavior. Publishing and distributing it is another. They require different things from a tool: storage requires permanence, searchability, and accessibility regardless of publishing status; distribution requires web performance, SEO infrastructure, and public availability. WordPress is genuinely excellent at distribution. It was never designed to be a durable content storage layer.

    The practical implementation: every piece of content in a behavior-first operation goes to Notion first, WordPress second. The Notion page is the permanent record. The WordPress post is the published output. If the WordPress site goes down, the content is not at risk. If you need to migrate hosts, rebuild the site, or switch platforms, the content travels with you. If the WAF blocks your publisher, you mark the Notion entry “Pending WP Push” and execute when the path is clear — nothing is lost.

    What This Looks Like in Practice

    Four cards for content, ops, build, and knowledge work with Claude
    Notion as a storage layer for WordPress — how it looks in practice.

    The write → store → distribute pipeline has three distinct stages, each with a clear tool responsibility:

    Write: Claude generates the article, optimized for SEO/AEO/GEO, with schema markup and internal linking. This happens in conversation, in a batch pipeline, or via a Cloud Run service.

    Store: The article lands in Notion — in a content tracker database with properties for status, target keyword, WP post URL, and a claude_delta metadata block at the top of each page. This is the permanent record. It’s searchable, linkable, and accessible to any future Claude session without reconstructing context.

    Distribute: The article publishes to WordPress via REST API. The WordPress post ID and URL get written back to the Notion record. The content now exists in two places — one for humans and future AI sessions (Notion), one for search engines and web visitors (WordPress).

    The Secondary Benefit: Portable Content

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    The secondary benefit: portable content you can re-use.

    The deeper value of this architecture isn’t failure resilience — it’s portability. Content stored in Notion can be published to any destination: WordPress, a different CMS, an email campaign, a PDF, a social post. The content is decoupled from its distribution channel. When you need to repurpose an article as a lead magnet, extract a section for a social post, or adapt it for a different site, it’s all in one place in a structured format that Claude can read and reformat in seconds.

    This is what “content as knowledge” looks like operationally. Not a metaphor — a literal architecture where content is stored as knowledge first and distributed as content second.

    The tool that makes this possible (Notion) costs nothing for a solo operator. The behavior that makes it valuable — writing to storage before distribution — costs nothing but the discipline to do it consistently. Build the system around that behavior and the tool choice becomes almost irrelevant.

    Frequently Asked Questions

    Does this mean we need to maintain content in two places?

    You’re maintaining it in one place (Notion) and publishing it to a second (WordPress). The WordPress post is generated from the Notion record, not maintained separately. Updates go to Notion first; the WordPress post gets updated via API. There’s no manual sync required.

    What if our team doesn’t use Notion?

    The behavior (store before distribute) can be implemented with any persistent storage layer — Google Docs, Airtable, a Git repository. Notion is recommended because it supports relational databases, Claude MCP integration, and structured metadata that makes the content retrievable and reusable. But the behavior is the requirement; the tool is the implementation detail.

    How does this handle content updates and revisions?

    Revisions happen in Notion. The updated Notion content is pushed to WordPress via API, overwriting the previous version. The Notion page serves as the revision history — Notion’s native version history tracks changes at the page level without any additional configuration.


  • Behavior-First System Design: Build for Action, Not Tools

    Behavior-First System Design: Build for Action, Not Tools

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade

    There is a mistake that kills more technology projects than bad code, bad vendors, or bad timing combined. It happens before a single line is written, before a single subscription is purchased, before anyone even knows there’s a problem.

    The mistake is this: choosing the tool before understanding the behavior.

    It looks like a reasonable decision. You need to manage customer relationships, so you buy a CRM. You need to publish content, so you build around WordPress. You need to organize knowledge, so you set up Notion. The tool selection feels like the hard part — the research, the demos, the pricing comparisons. By the time you’ve chosen, you feel like the work is half done.

    It isn’t. You’ve just committed to building a system shaped like a tool instead of shaped like a behavior. And when the behavior and the tool don’t match, the system fails quietly — not in a crash, but in a slow drift toward abandonment, workarounds, and the quiet understanding that “we don’t really use that anymore.”

    The alternative is building the system around the behavior first. It sounds obvious. Almost nobody does it.


    What “Behavior-First” Actually Means

    A behavior is what actually happens — or needs to happen — in your operation. It’s not a goal, not a feature request, not a capability. It’s the specific sequence of actions, decisions, and handoffs that produce a result.

    Most system design starts with tools and works backward to behaviors. Behavior-first design starts with the behavior and works forward to the minimum set of tools that can serve it.

    The difference sounds subtle. The outcomes are not.

    When you start with the tool, you spend the first six months learning the tool’s shape and then trying to reshape your operation to fit it. When you start with the behavior, you spend the first six months building a system that serves the operation — and then choosing the simplest tool that delivers what the behavior requires.

    The tool-first approach produces complexity. The behavior-first approach produces leverage.


    Six Behaviors That Built This Operation

    The following examples are drawn from a single AI-native operation built over three years. None of them started with a tool selection. All of them started with the question: what actually needs to happen here?

    1. Write → Store → Distribute (The Content Pipeline)

    Most content operations are built around WordPress. The platform is the system. Articles go into WordPress, WordPress manages drafts, WordPress publishes, WordPress is the source of truth. This is tool-first design.

    The behavior is different. The behavior is: write a piece of content, preserve it permanently, distribute it to wherever it needs to go.

    When you build around that behavior, WordPress becomes one destination among several — not the system. Notion becomes the storage layer. WordPress becomes the distribution layer. The article exists independently of where it’s published. If WordPress goes down, if the WAF blocks you, if the site moves hosts — the content is not at risk. The behavior (write → store → distribute) is served by a stack of tools, none of which is the irreplaceable center.

    The practical result: every article written in this operation goes to Notion first, WordPress second. Not because Notion is a better publishing platform — it isn’t. Because the behavior requires permanent, accessible storage before distribution, and WordPress was never designed to be that.

    2. Identify → Deposit → Execute (The Work Order Architecture)

    The problem: an AI system can identify what’s wrong with a WordPress site in seconds — thin content, missing schema, broken taxonomy, orphan pages — but the identification and the fix are handled by completely different systems. The identification lives in a conversation. The fix lives in a deployment. There’s no bridge.

    The behavior is: Claude identifies a problem, deposits a structured work order, a Cloud Run worker executes it. The intelligence and the execution are decoupled. Neither layer needs to know how the other works.

    Built around that behavior, the tool choices become obvious. Notion holds the work order queue — not because Notion is a task management tool (though it is), but because Claude can write to it via API and a Cloud Run service can read from it. The tools serve the behavior. The behavior doesn’t contort to serve the tools.

    3. Extract → Distill → Deploy (The Human Distillery)

    The behavior here is one of the rarest in any knowledge-intensive industry: taking tacit knowledge — the unwritten, unspoken operational intelligence that lives in people’s heads — and converting it into structured artifacts that AI systems can immediately use.

    Tacit knowledge doesn’t fit into forms, surveys, or databases. It surfaces through conversation. The extraction behavior is a specific sequence: disarm the subject, descend through four layers of questioning (documented protocol → exception cases → sensory knowledge → counterfactual pressure), capture what surfaces, and distill it into a dense artifact.

    That behavior existed long before any tool was selected to support it. The tool choices — which models to run distillation through, how to structure the output schema, where to store the resulting knowledge concentrates — all came after the behavior was understood. The behavior is irreplaceable. The tools are interchangeable.

    4. Observe → Route → Produce (Task Routing for Variable Attention)

    Most productivity systems are built around the assumption that the operator applies consistent, scheduled attention to work. Tasks sit in queues. Work happens in order. Focus is managed through priority.

    That behavior doesn’t match how an ADHD-wired operator actually works. The actual behavior is: attention arrives unbidden, attaches to whatever has activated the interest system, runs at extraordinary intensity, and then ends — also unbidden. The work happens in spirals, not lines.

    An AI-native operation designed around this actual behavior routes tasks differently. High-interest, high-judgment work goes to the operator when the operator’s attention is activated. Low-interest, deterministic work gets routed to automated pipelines that run on schedule regardless of operator state. The behavior — variable, interest-driven, high-intensity — shapes the system. The system doesn’t demand behavior the operator can’t deliver.

    The result is not a workaround. It’s an architecture. And the architecture works better for a neurotypical operator too — because the constraints that neurodivergence makes extreme are present in milder form in everyone.

    5. Touch → Remind → Refer (The CRM Community Framework)

    The restoration industry spends $150–$500 per lead acquiring customers and then never contacts them again. Not because they don’t want to. Because the tool they have — a job management system built around transactions — doesn’t support the behavior they need.

    The behavior is: make consistent, relevant, human contact with warm relationships at regular intervals, using legitimate business moments as the reason. That’s it. The behavior is simple. The tool selection is almost irrelevant — a spreadsheet and a Mailchimp free account can execute it. What matters is that the system is built around the behavior (stay present in warm relationships) rather than around the tool (send marketing emails).

    When you build around the tool, you get a marketing email campaign. When you build around the behavior, you get a community — a network of people who feel a genuine two-way relationship with your company and who refer you business because you’re the company that actually stayed in touch.

    The technical implementation of this — segmentation from ServiceTitan and Jobber, email automation in Mailchimp or Brevo, relationship intelligence in a Notion Second Brain — is documented in full in the CRM Community Framework series. Every tool choice in that series is downstream of the behavior. None of it works if you start with the tool.

    6. Signal → Display → Act (The Four-Layer Data Architecture)

    A complex multi-site operation generates data from dozens of sources simultaneously — WordPress post metrics, GCP Cloud Run logs, Notion task statuses, client pipeline movements, content performance signals. The instinct is to find one tool that can hold all of it. The tool becomes the system.

    The behavior is different for each data type. Machine-generated operational data (image processing logs, batch job results, embedding vectors) needs to be written and read by automated systems at high speed. Human-actionable signals (site health alerts, content gaps, client status changes) need to be displayed in a way a person can act on without noise. Content in progress needs to be stored independently of where it will ultimately be published.

    Four behaviors. Four tool layers. WordPress for published content, GCP for machine data, Notion for human signals, Google Drive for files. No single tool tries to do all four. Each tool is chosen because it’s the best fit for one specific behavior — not because it can technically handle the others.


    How to Apply This in Your Operation

    The behavior-first design process has three steps, and none of them involve opening a browser tab to research tools.

    Step 1: Write down what actually needs to happen. Not what you want to accomplish. Not what you wish the system could do. The specific sequence of actions that produces the result you need. Subject → verb → object, repeated until the behavior is fully described. “Someone writes an article. The article needs to be findable in six months. The article needs to be published to a website.” That’s a behavior. “We need better content management” is not.

    Step 2: Identify where the behavior breaks down today. Every system has the places where it works and the places where it silently fails. A CRM that nobody updates after the job closes. An email platform that has contacts from three years ago and no segmentation. A content process that lives in someone’s head. These are the behavior gaps — the places where the actual behavior doesn’t match the intended behavior.

    Step 3: Choose the simplest tool that serves the behavior. Not the most powerful. Not the most popular. Not the one with the best demo. The one that makes the behavior easiest to execute consistently. A $13/month Mailchimp account and a Google Sheet will outperform a $400/month marketing platform if the behavior is four emails per year to a warm local database — because the complexity of the expensive tool introduces friction that kills the behavior entirely.


    The AI-Native Operation Is Behavior-First by Definition

    The reason AI-native operations tend to outperform tool-native operations has nothing to do with AI being smarter. It has to do with design philosophy.

    AI tools, at their best, are infinitely flexible. They don’t impose a shape on your operation. They serve whatever behavior you describe. The operator who builds an AI-native operation is forced — by the nature of the tools — to understand their own behaviors first. You cannot prompt your way to a useful output without knowing what useful looks like. You cannot build a pipeline without understanding the sequence it’s meant to automate.

    This is why the AI-native operator has a structural advantage over the SaaS-native operator. Not because their tools are better. Because the process of building with AI forces behavior-first thinking, and behavior-first thinking produces systems that compound over time instead of decaying into expensive shelf-ware.

    The tool will change. The behavior won’t. Build the system around the behavior.


    Frequently Asked Questions

    How do you identify the behavior if you’ve always built around tools?

    Start with the breakdowns. Wherever your current system has workarounds, manual steps, or things people do “outside the system,” those are the places where the tool’s shape and the behavior don’t match. The workarounds are the behavior. Build the new system to serve them directly.

    Doesn’t this make tool selection harder and slower?

    It makes it faster. When you know the behavior precisely, you have a clear evaluation criterion: does this tool make the behavior easier to execute consistently, or does it add complexity? Most tool evaluations fail because the criteria are vague. Behavior-first evaluation is fast because the test is concrete.

    What if the behavior changes over time?

    Behaviors evolve. Systems built around behaviors can evolve with them — you swap the tool layer without disrupting the behavior layer. Systems built around tools can’t evolve without a full rebuild, because the tool is the system. Behavior-first architecture is inherently more resilient to change.

    Is this just another way of saying “process before technology”?

    It’s related but more specific. “Process before technology” is usually interpreted as documentation before implementation — write the SOPs, then build the tools to support them. Behavior-first design is about understanding the actual behavior of the operation, which often differs significantly from the documented process. You’re designing around what people and systems actually do, not what they’re supposed to do.

    How does this apply to AI tool selection specifically?

    AI tools are especially susceptible to tool-first thinking because they’re impressive in demos. The demo shows capability; the behavior question asks whether that capability serves a specific sequence in your operation. Most AI tool adoptions fail not because the tools are bad but because they were selected based on capabilities rather than behaviors. The question is never “what can this tool do?” It’s “which of my behaviors does this tool serve, and does it serve them better than what I have now?”
  • Restoration Content Operations: Building Local Authority

    Restoration Content Operations: Building Local Authority

    The Agency Playbook
    TYGART MEDIA · PRACTITIONER SERIES
    Will Tygart · Senior Advisory · Operator-grade intelligence

    The restoration industry has a content problem that most operators don’t recognize as a content problem. The work is technical, the market is local, the competition is intense, and the buying decision is urgent — someone’s basement is flooding or their ceiling has water damage and they need a contractor now. Traditional marketing advice — build a brand, nurture a relationship, post on social media — doesn’t map well to an industry where the customer need is immediate and the decision window is short.

    What does work: topical authority built through genuinely useful content, local SEO that answers the specific questions people ask when damage happens, and a content operation that can produce and maintain that content at scale. This is what we’ve built for restoration industry clients, and Notion is the operational backbone that makes it manageable.

    What does a Notion content operation look like for the restoration industry? A restoration industry content operation in Notion tracks content across specific damage types — water, fire, mold, asbestos, storm — and service geographies, with keyword research integrated into the content pipeline and a publishing workflow that routes content through optimization, schema injection, and WordPress publication. The operation is built for volume and specificity, not general brand content.

    Why the Restoration Industry Is a Good Content Market

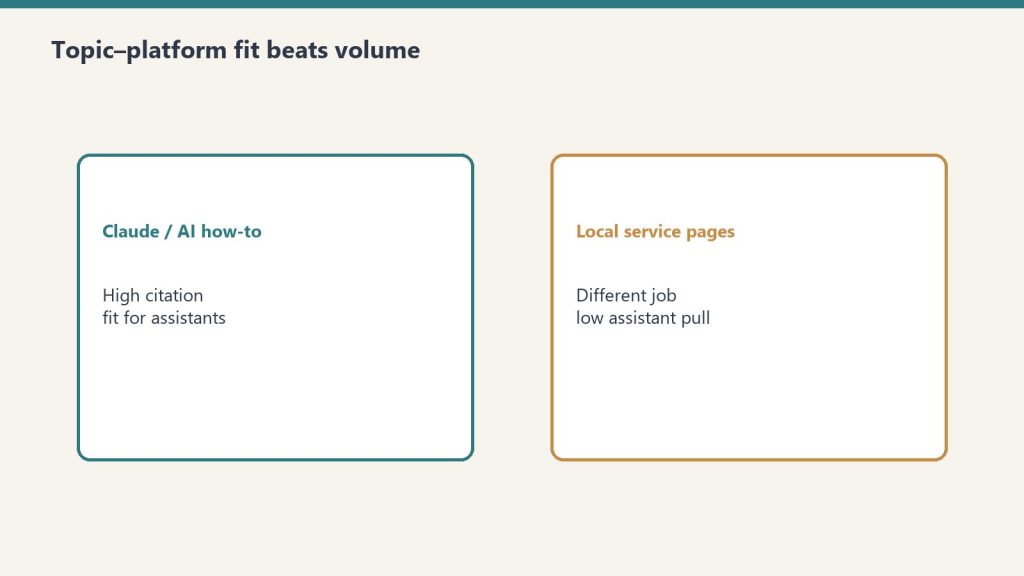
    Comparison of Claude how-to fit versus local service page fit for assistants
    Why the restoration industry is a good content market.

    Restoration is a strong content market for several reasons. The questions people ask when damage occurs are specific and consistent: how much does water damage restoration cost, how long does mold remediation take, what does fire damage smell like after a week. These questions have real search volume and low competition from authoritative content — most restoration company websites are thin on useful information.

    The industry also has strong local search intent. Someone searching for water damage restoration is almost always searching for someone local. Content that combines topical authority — demonstrating genuine expertise in the damage type — with local specificity performs well in this environment.

    Finally, the industry is fragmented. Most restoration companies are regional or local operators without the resources to build and maintain a serious content operation. That gap creates opportunity for content-forward operators to establish authority that larger, less content-focused competitors can’t easily replicate.

    How the Content Architecture Works

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How the content architecture works.

    The content architecture for restoration clients follows a hub-and-spoke structure. Hub pages cover the primary service categories at the depth required for topical authority — comprehensive guides to water damage restoration, mold remediation, fire damage recovery. Spoke pages cover specific questions, cost breakdowns, process explanations, local variations, and comparison topics that radiate from each hub.

    In Notion, this architecture is tracked in the Content Pipeline database with content type tags distinguishing hub pages from spoke content. The hub pages are the long-term SEO assets; the spoke content generates ongoing traffic from specific long-tail queries and builds the internal link structure that supports the hubs.

    The keyword research layer — what topics need coverage, what questions are being asked in the target geography, what the competition looks like for each keyword — feeds directly into the Content Pipeline as briefs. Each brief becomes a content record that moves through the standard status sequence before it reaches WordPress.

    The Local Intelligence Layer

    Generic restoration content — “water damage restoration: everything you need to know” — competes with national franchise content from large chains and major insurance resources. It’s hard to win that competition for a regional operator.

    Local intelligence changes the equation. Content that reflects genuine knowledge of a specific market — the most common cause of water damage in the local housing stock, the local insurance carriers and their specific claim processes, the geographic factors that affect mold growth in the region — differentiates from generic content in a way that matters to both search engines and local readers.

    Capturing and maintaining that local intelligence is a knowledge management problem. In Notion, it lives in the client’s Knowledge Lab records — market-specific reference documents that inform every piece of content written for that client and that Claude reads before starting any content session for that site.

    The B2B Network as Distribution

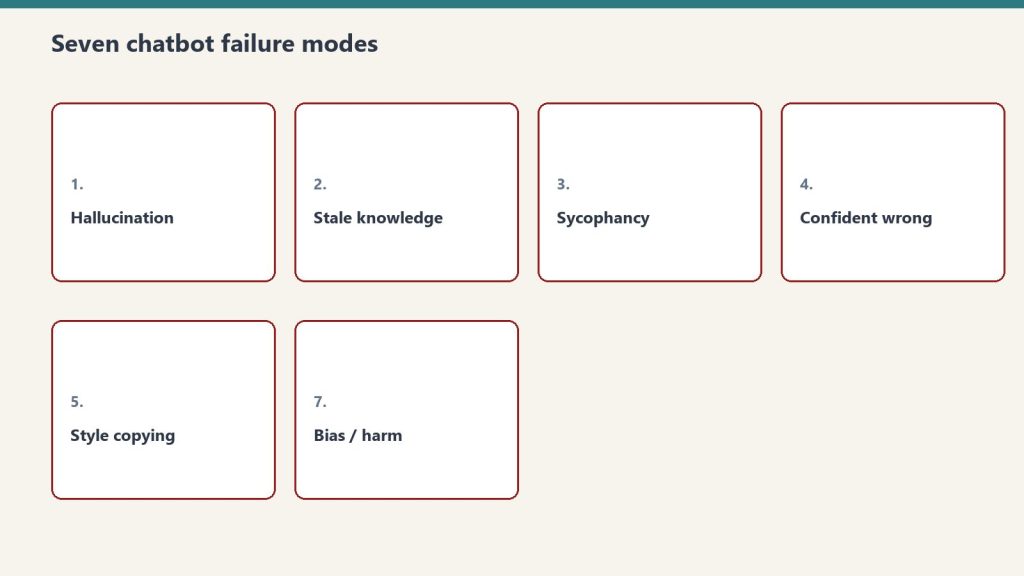
    Seven cards naming common AI chatbot failure modes
    The B2B network as distribution.

    Content production is half the equation. Distribution matters — who sees the content and whether it reaches the decision-makers and referral sources who drive restoration business.

    A B2B industry network built around a shared activity — golf, in one model we’ve seen work well — can be a powerful distribution channel for restoration industry relationships. Insurance adjusters, property managers, contractors, and restoration company owners all participate in an industry where relationships drive referrals. A network format that builds those relationships efficiently creates a distribution layer that pure content can’t replicate.

    The content operation and the network operation reinforce each other. The content builds the credibility and visibility that makes the network meaningful. The network provides the relationships and industry intelligence that make the content genuinely informed rather than generic. Neither works as well without the other.

    What Makes Restoration Content Different

    Restoration content has specific requirements that distinguish it from general service business content. The subject matter is emotionally charged — people are dealing with damaged homes and possessions, often under insurance and contractor pressure. The content needs to be factually precise — cost ranges, process timelines, and technical specifications that are wrong will be called out quickly by industry readers. And the local dimension is non-negotiable — a guide to water damage restoration that doesn’t reflect local contractor pricing, local building codes, or local insurance market realities is less useful than one that does.

    Meeting these requirements at scale — across multiple clients, multiple damage types, multiple geographies — is what makes Notion’s pipeline architecture valuable for restoration content operations. The knowledge layer stores the local intelligence. The pipeline tracks the content. The quality gate ensures nothing publishes with claims that can’t be supported.

    Working in the restoration industry?

    We build content operations for restoration companies — the topical authority architecture, the local intelligence layer, and the publishing pipeline that makes it run at scale.

    Tygart Media has deep experience in restoration industry content. We know what works, what the keywords are, and what differentiates in a fragmented local market.

    See what we build →

    Related on Tygart Media: content marketing strategy · content pipeline · restoration blog SEO.

    Frequently Asked Questions

    What content topics work best for restoration companies?

    Cost guides perform consistently well — people want to know what water damage restoration costs, what mold remediation costs, what fire damage cleanup costs. Process explanations — what happens during restoration, how long it takes, what to expect — also perform well because they reduce anxiety during a stressful situation. Local content that reflects knowledge of the specific market outperforms generic content for the same topics at the local search level.

    How much content does a restoration company need to build topical authority?

    For a regional restoration company targeting a metro area, meaningful topical authority typically requires fifty to one hundred published articles covering the primary damage types, the key cost and process questions, and local variations. That’s a six-to-twelve month content build at reasonable publishing velocity. The content compounds over time — articles published in month one are still generating traffic in month twelve and beyond.

    How do you handle the local specificity requirement across multiple restoration clients in different markets?

    Each client’s market-specific intelligence lives in their Knowledge Lab records in Notion — a set of reference documents covering local pricing, local contractors, local insurance market conditions, and geographic factors specific to their service area. Claude reads these records before starting any content session for that client. The records are the mechanism that makes content locally specific without requiring the writer to have personal knowledge of every market.

  • Notion Command Center: Our Daily Operating Rhythm Playbook

    Notion Command Center: Our Daily Operating Rhythm Playbook

    The Agency Playbook
    TYGART MEDIA · PRACTITIONER SERIES
    Will Tygart · Senior Advisory · Operator-grade intelligence

    A daily operating rhythm is the difference between a Notion system you use and one you maintain out of obligation. The architecture can be perfect — six databases, clean relations, filtered views for every operational question — and still fail if there’s no structured daily interaction that keeps it current and useful.

    This is our exact playbook. Not a template, not a philosophy — the specific sequence we run every working day to keep a multi-client, multi-entity operation on track from a single Notion workspace.

    What is a Notion Command Center daily operating rhythm? A daily operating rhythm for a Notion Command Center is a structured sequence of interactions with the workspace that keeps it current and actionable — a morning triage that clears the inbox and sets priorities, an end-of-day close that captures completions and pushes deferrals, and a weekly review that repairs drift and resets for the next week. The rhythm is what transforms a database architecture into a living operating system.

    Morning Triage: 10–15 Minutes

    Four cards for content, ops, build, and knowledge work with Claude
    Morning triage — 10–15 minutes.

    The morning triage has one goal: leave it knowing exactly what the top three priorities are for the day and with the inbox at zero.

    Step 1: Zero the inbox. Open William’s HQ and go to the inbox view — all tasks without a priority or entity assigned. Every untagged item gets a priority (P1–P4), a status (Next Up or a specific date), and an entity tag. Nothing stays in the inbox. Items that don’t warrant a task get deleted.

    Step 2: Read the P1 and P2 list. These are the only tasks that own today’s calendar. Read the list. Mentally commit to the top three. If the P1 list has more than five items, something is mislabeled — P1 means real consequences today, not “this would be good to do.”

    Step 3: Check the content queue. Filter the Content Pipeline for anything publishing in the next 48 hours that isn’t in Scheduled status. Anything publishing tomorrow that’s still in Draft or Optimized is a P1. Fix it before anything else.

    Step 4: Check blocked tasks. Any task in Blocked status needs a decision or a message now. Blocked tasks that age without action create downstream problems that compound. Clear them or escalate them — don’t leave them blocked.

    Total time: ten to fifteen minutes. The output is not a plan — it’s a commitment to three specific things, with everything else deprioritized explicitly rather than just ignored.

    Working Sessions: No Rhythm, Just Work

    Between morning triage and end-of-day close, there’s no prescribed rhythm. The triage gave you your three priorities. Work on them. The system doesn’t need to be consulted again until something changes — a new task arrives, a content piece needs to move to the next stage, a decision gets made that should be logged.

    The one active habit during working sessions: when you create something that belongs in the system — a new contact, a new content piece, a completed task — log it immediately. The temptation to batch-log at the end of the day creates a gap where things get missed. The cost of logging in real time is thirty seconds per item. The cost of not logging is an inaccurate system that can’t be trusted.

    End-of-Day Close: 5 Minutes

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    End-of-day close — 5 minutes.

    Step 1: Mark done tasks complete. Any task completed today gets its status updated to Done. This takes thirty seconds and keeps the active task view clean.

    Step 2: Push or reprioritize uncompleted tasks. Anything you intended to do but didn’t — update the due date or move it down in priority. Don’t leave tasks with today’s due date sitting undone without a decision about when they’ll happen.

    Step 3: Check tomorrow’s content queue. Anything publishing tomorrow that needs a final pass? If yes, that’s the first thing tomorrow morning. If no, close out.

    Step 4: Log anything significant created today. New contacts, new content pieces, new decisions — anything that belongs in the system but was created during the day without being logged. The end-of-day close is the catch for anything that wasn’t logged in real time.

    Total time: five minutes. The output is a clean system — no stale due dates, no ambiguous task statuses, no undocumented decisions.

    Weekly Review: 30 Minutes, Sunday Evening

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Weekly review — 30 minutes, Sunday evening.

    The weekly review is the repair mechanism. It catches what the daily rhythm misses and resets the system before the next week begins.

    Revenue check: Any deal stuck in the same pipeline stage as last week with no activity? Any proposal sent more than five days ago without a follow-up?

    Content check: Next week’s content queue — fully populated and scheduled? Any articles published this week without internal links? Any content pipeline records that have been in the same status for more than seven days?

    Task check: Archive all Done tasks older than 14 days. Any P3/P4 tasks that should be killed rather than deferred again? Any P2 leverage tasks being continuously pushed — a warning sign that the leverage isn’t actually happening?

    Relationship check: Any CRM contacts who should have heard from you this week and didn’t?

    System health check: Any automation that failed silently? Any SOP that was used this week that turned out to be outdated? Any knowledge that was generated this week that should be documented?

    Total time: thirty minutes. The output is a reset system — clean task database, current content queue, up-to-date relationship log, healthy knowledge base.

    Monthly Entity Reviews: 10 Minutes Each

    Once a month, open each business entity’s Focus Room and run a quick scan. For each entity, one key question: is this entity’s operation healthy? Are the right things happening, is nothing falling through the cracks, does the content or relationship pipeline need attention?

    The monthly review catches drift that’s too slow for the weekly rhythm to notice — a client relationship that’s been slightly neglected for six weeks, a content vertical that’s been deprioritized without a conscious decision, a system health issue that’s been accumulating quietly.

    Ten minutes per entity. The output is either confirmation that the entity is on track or a set of tasks to address the drift before it becomes a problem.

    Want this system set up for your operation?

    We build Notion Command Centers and the operating rhythms that make them work — the architecture, the views, and the daily practice that keeps a complex operation on track.

    Tygart Media runs this exact rhythm daily. We know what makes the difference between a Notion system that works and one that gets abandoned.

    See what we build →

    Related on Tygart Media: Command Center architecture · content pipeline · SOP system.

    Frequently Asked Questions

    What if the morning triage takes longer than 15 minutes?

    It means the inbox accumulated too much since the last triage. The first few times you run the rhythm after setting up a new system, triage will take longer while you establish the habit of keeping the inbox clear in real time. Once the habit is established, fifteen minutes is consistently sufficient. If triage regularly exceeds twenty minutes, the inbox discipline needs attention — too many items are accumulating without being processed during the day.

    How do you handle urgent items that arrive mid-day?

    Anything genuinely urgent — P1 level — gets addressed immediately and logged in the system as it’s resolved. Anything that feels urgent but can wait goes into the inbox for the next triage. The discipline of not treating every incoming item as immediately actionable is one of the harder habits to establish, and one of the most valuable. Most things that feel urgent at arrival are P2 or P3 by the time they’re calmly evaluated.

    Is the weekly review actually necessary if the daily rhythm is working?

    Yes. The daily rhythm catches individual task and content issues. The weekly review catches patterns — a client relationship drifting, a pipeline stage backing up, an automation failing silently. These patterns are invisible in daily operation because each day’s view is too narrow. The weekly review is the only moment when the full operation is visible at once, which is when patterns become apparent.

  • Notion Content Pipeline for Multi-Client Operations

    Notion Content Pipeline for Multi-Client Operations

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart · Practitioner-grade · From the workbench

    Running a content pipeline across twenty-plus WordPress sites from a single Notion workspace is not the obvious use case Notion was designed for. It’s a use case we built — deliberately, iteratively, over the course of operating a content agency where the volume of work made ad hoc management impossible.

    The result is a system where every piece of content, across every client site, moves through a defined sequence from brief to published inside one Notion database. Nothing publishes without a record. Nothing falls through the cracks between clients. The status of the entire operation is visible in a single filtered view.

    Here’s how that pipeline works.

    What is a Notion content pipeline for multi-site operations? A multi-site content pipeline in Notion is a single Content Pipeline database where every piece of content across every client site is tracked through a defined status sequence — Brief, Draft, Optimized, Review, Scheduled, Published — with each record tagged to its client, target site, and publication date. One database, filtered views per client, full operational visibility across all sites simultaneously.

    Why One Database for All Sites

    Four cards for content, ops, build, and knowledge work with Claude
    Why one Notion database for all sites.

    The instinct is to give each client their own content tracker. Separate pages, separate databases, separate calendars. This feels organized. In practice it means your Monday morning question — “what’s publishing this week?” — requires opening twenty separate databases and manually compiling the answer.

    One database with entity-level partitioning answers that question in a single filtered view sorted by publication date. Every client’s content in motion, every publication date, every status, visible simultaneously. Add a filter for one client and you have their isolated view. Remove the filter and you have the full operational picture.

    The cognitive shift required: stop thinking about the database as belonging to a client and start thinking about the client tag as a property of the record. The database belongs to the operation. The records belong to clients.

    The Status Sequence

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    The status sequence that keeps the pipeline honest.

    Every content record moves through the same six stages regardless of client or content type: Brief → Draft → Optimized → Review → Scheduled → Published. Each stage transition has a defined meaning and, for key transitions, a quality check.

    Brief: The content concept exists. Target keyword identified, angle defined, target site confirmed. Not yet written.

    Draft: Written. Not yet optimized. Word count and rough structure in place.

    Optimized: SEO pass complete. Title, meta description, slug, heading structure, internal links reviewed and adjusted. AEO and GEO passes applied if applicable. Schema injected.

    Review: Content quality gate passed. Ready for final check before scheduling. This is the stage where anything that shouldn’t publish gets caught.

    Scheduled: Publication date set. Post exists in WordPress as a draft or scheduled post. Date confirmed in the database record.

    Published: Live. URL confirmed. Post ID logged in the database record for future reference.

    The Quality Gate as a Pipeline Stage

    The transition from Optimized to Review is gated by a content quality check — a scan for unsourced statistical claims, fabricated specifics, and cross-client content contamination. The contamination check matters specifically for multi-site operations: content written for one client’s niche should never reference another client’s brand, geography, or specific context.

    Running this check as a formal pipeline stage rather than an informal pre-publish habit is what makes it reliable at scale. When publishing volume is high, informal checks get skipped. A formal stage in the status sequence means the check is either done or the content doesn’t advance. There’s no middle ground where it was probably fine.

    What Notion Tracks Per Record

    Each content pipeline record carries: the content title, the client entity tag, the target site URL, the target keyword, the content type, word count, the assigned writer if applicable, the publication date, the WordPress post ID once published, and the current status. Relation fields link the record to the client’s CRM entry and to the associated task in the Master Actions database.

    The WordPress post ID field is the detail most content trackers skip. With the post ID logged, finding the exact WordPress record for any piece of content is a direct lookup rather than a search. For a pipeline publishing hundreds of articles across dozens of sites, that lookup speed matters every week.

    The Weekly Content Review

    Every Monday, one database view answers the primary operational question for the week: a filter showing all records with a publication date in the next seven days, sorted by date, across all clients. This view drives the week’s content priorities — whatever needs to move from its current stage to Published by the end of the week gets the first attention.

    A second view shows all records stuck in the same status for more than five days. Stale records indicate a bottleneck — something that was supposed to move and didn’t. Finding and clearing those bottlenecks is the second priority of the weekly review.

    Both views take under a minute to read. The decisions they drive take longer. But the information is current, complete, and doesn’t require any compilation — it’s all in the database, updated as work happens.

    How Claude Plugs Into the Pipeline

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How Claude plugs into the content pipeline.

    The content pipeline database is one of the primary interfaces between Notion and Claude in our operation. Claude reads the pipeline to understand what’s in progress, writes new records when content is created, updates status as work advances, and logs the WordPress post ID when publication is confirmed.

    This write-back capability — Claude updating the Notion database directly via MCP rather than requiring a manual logging step — is what keeps the pipeline current without adding overhead. The database is accurate because updating it is part of the work, not a separate step after the work is done.

    Want this pipeline built for your content operation?

    We build multi-site content pipelines in Notion — the database architecture, the quality gate process, and the Claude integration that keeps it current automatically.

    Tygart Media runs this pipeline live across a large portfolio of client sites. We know what the architecture requires at real operating scale.

    See what we build →

    Related on Tygart Media: Notion Command Center for agencies · Notion for content agencies · client onboarding template.

    Frequently Asked Questions

    How do you prevent content written for one client from appearing on another client’s site?

    Two mechanisms. First, every content record is tagged with the client entity at creation — the tag makes it explicit which client owns the content before a word is written. Second, a content quality gate scans every piece for cross-client contamination before it advances to the Review stage. Content referencing geography, brands, or context specific to another client gets flagged and held before it reaches WordPress.

    What happens when content is published — how does the pipeline stay accurate?

    When content publishes, the record status updates to Published and the WordPress post ID gets logged in the database record. In our operation, Claude handles this update directly via Notion MCP as part of the publishing workflow. For operations without that automation, a daily or weekly manual update pass keeps the pipeline accurate. The key is building the update into the publishing workflow rather than treating it as optional.

    Can Notion’s content pipeline replace a dedicated editorial calendar tool?

    For most content agencies, yes. Notion’s calendar view applied to the content pipeline database provides the same visual publication scheduling that dedicated editorial calendar tools offer, plus the full database functionality — filtering by client, sorting by status, tracking by keyword — that standalone calendar tools lack. The combination is more capable than purpose-built tools for agencies already running Notion as their operational backbone.

  • Best Notion Templates for Agencies (Why We Skip Them)

    Best Notion Templates for Agencies (Why We Skip Them)

    The Agency Playbook
    TYGART MEDIA · PRACTITIONER SERIES
    Will Tygart · Senior Advisory · Operator-grade intelligence

    The best Notion templates for agencies are the ones you don’t use. That’s not a paradox — it’s a description of how good templates actually work. A well-built template gives you a starting architecture and then gets out of the way. You customize it to your operation, build your workflows on top of it, and within a few weeks the template’s DNA is so thoroughly mixed with your own choices that you’d struggle to separate them.

    What doesn’t work: downloading a template, opening it, feeling briefly impressed by how organized it looks, and then abandoning it because it wasn’t built for how you actually work.

    Here’s an honest look at the Notion template landscape for agencies — what’s worth starting from, and why we ultimately stopped using templates entirely.

    What makes a Notion template good for agency use? A good agency Notion template provides a functional database architecture with relation properties already configured, views set up for common operational questions, and a structure that maps to real agency workflows — client management, content production, project tracking — rather than generic productivity advice. The best templates are opinionated enough to be useful and flexible enough to be adapted.

    What to Look For in an Agency Template

    Four cards for content, ops, build, and knowledge work with Claude
    What to look for in an agency Notion template.

    Before evaluating any specific template, the criteria matter. For agency use, a template is only worth your time if it has: a relational database structure (not just pages and folders), views configured for operational questions you actually need to answer, and a client or project partitioning system that keeps work separated without requiring duplicate databases.

    Templates that fail these criteria — pretty page layouts with no relational structure, task lists without database properties, client folders instead of a filtered single database — will not survive contact with a real agency workflow. They look organized in screenshots and feel hollow in practice.

    The Template Categories Worth Knowing

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    Template categories worth knowing.

    Agency OS templates. Comprehensive workspace setups that attempt to cover the full agency operation — clients, projects, tasks, content, invoicing. The good ones from the Notion template gallery and creators like Thomas Frank establish the right relational architecture. The risk: they’re built for a hypothetical agency, not yours. Plan to spend as much time customizing as you would have spent building from a good foundation.

    Content pipeline templates. Focused specifically on editorial and content workflows — brief to publish status sequences, content calendar views, keyword tracking. More focused than full agency OS templates and often more immediately useful for content-specific operations. The best ones have proper database properties and status sequences; the worst are glorified spreadsheets with a calendar view.

    CRM templates. Client and contact management systems. Useful as a starting point for the relationship management layer, though most underestimate how important the relation properties connecting contacts to deals and projects are. A CRM template without proper relations is a contact list with extra steps.

    Client portal templates. Starting points for client-facing portal pages. Most are structurally sound but generic — they need significant customization to reflect your specific deliverable types, communication style, and client relationship structure.

    Why We Stopped Using Templates

    We built the current architecture from scratch after two rounds of trying to adapt downloaded templates. The templates were fine — they established reasonable database structures and saved initial setup time. The problem was customizing them.

    Every template comes with someone else’s assumptions baked in: their property names, their status sequences, their view organization, their relationship structure. Adapting those assumptions to a different operation requires understanding them well enough to change them without breaking the relations that depend on them. By the time you understand the template well enough to modify it correctly, you understand databases well enough to have built it yourself.

    The more useful approach for an operator who’s going to run Notion seriously: learn the architecture principles — how relation properties work, how filtered views are built, how rollups pull data across databases — and build from those principles. The initial investment is higher. The system that results fits your operation because it was designed for your operation.

    When Templates Are Worth Using

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    When templates are worth using — and when they are not.

    Templates are worth using in two specific situations. First, when you’re new to Notion’s database capabilities and need a working example to understand how relations and views are structured. Opening a well-built template and reverse-engineering why it’s built the way it is is a faster learning path than reading documentation. Second, when you need a specific narrow function quickly — a content calendar for a new client vertical, a project tracker for a new type of engagement — and don’t have time to build from scratch. A template as a starting point, customized heavily, beats a delay.

    Want a Notion system built for your actual operation?

    We build Notion architectures from scratch for agencies — designed around how your operation actually works, not adapted from a generic template.

    Tygart Media builds and runs a custom Notion architecture across a large client portfolio. We know the difference between a system that looks organized and one that actually runs an operation.

    See what we build →

    Related on Tygart Media: Command Center · content pipeline · onboarding template.

    Frequently Asked Questions

    Are Notion templates worth paying for?

    Occasionally. Free templates from Notion’s own gallery and established creators cover most use cases adequately. Paid templates justify their cost only when they include genuinely sophisticated relational architecture that would take significant time to build independently, or when they come with documentation that teaches you how to adapt them correctly. Most paid templates in the five-to-fifty dollar range are not meaningfully better than good free options.

    Where do you find good Notion templates for agencies?

    Notion’s official template gallery is the most reliable starting point — the templates there have been reviewed and work correctly. Thomas Frank’s Notion resources are well-regarded for the quality of their database architecture. The Notion subreddit and creator communities surface good templates periodically. Be skeptical of templates sold primarily on aesthetic appeal — visual polish does not indicate functional quality.

    Can you build a Notion agency system without using templates at all?

    Yes, and it’s often the better path for operators who will run Notion seriously long-term. Building from first principles — starting with the six operational questions your agency needs to answer, then designing the databases that answer them — produces a system that fits your operation without the overhead of adapting someone else’s assumptions. It requires more upfront investment and some database knowledge, but results in a more durable system.

  • Notion Client Onboarding Template: What We Actually Use

    Notion Client Onboarding Template: What We Actually Use

    The Agency Playbook
    TYGART MEDIA · PRACTITIONER SERIES
    Will Tygart · Senior Advisory · Operator-grade intelligence

    The client onboarding process is where most agencies lose time they never recover. A disorganized onboarding means scattered information, repeated questions, unclear expectations, and a client relationship that starts on a note of confusion rather than confidence.

    The right Notion onboarding template — one that’s actually used, not just admired — solves this before the relationship even begins. Here’s the structure we use and why each piece is there.

    What should a Notion client onboarding template contain? An effective Notion client onboarding template contains five elements: a structured intake form or checklist for collecting client information, a reference section for brand and content guidelines, a project scope and deliverables tracker, a communication log for key decisions, and a Next Steps section that always reflects the current state of the engagement. Templates that omit any of these create gaps that surface as problems later.

    What the Template Actually Needs to Do

    Four cards for content, ops, build, and knowledge work with Claude
    What a client onboarding template actually needs to do.

    An onboarding template has two jobs. First, collect everything you need to start doing the work correctly — brand guidelines, target audience, keyword strategy, content constraints, access credentials, approval processes. Second, establish the shared expectations that govern the relationship — what gets delivered, when, how feedback works, what happens when something needs to change.

    Most onboarding templates do the first job reasonably well and ignore the second entirely. Then scope creep, unclear feedback loops, and misaligned expectations become recurring problems that the template could have prevented.

    The Five Sections

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    The five sections of a working onboarding template.

    Section 1: Client Information and Access. The factual foundation — company name, primary contacts, website URLs, platform credentials, billing details, and contract reference. This section is filled out once during onboarding and updated when anything changes. It should never require searching an email thread to answer “what’s their WordPress login?”

    Section 2: Brand and Content Guidelines. Everything that governs how the work is done: brand voice description, approved and avoided topics, competitor sensitivities, style preferences, target audience profiles, primary keywords and content pillars. This section is the reference document for every piece of work produced for this client. It should be specific enough to give a writer genuine direction, not vague enough to cover for not asking the right questions during onboarding.

    Section 3: Scope and Deliverables. What was agreed, in plain language. Number of articles per month, content types, target platforms, revision rounds included, turnaround times, and what’s explicitly out of scope. Written without ambiguity. This section is the answer to every scope question that arises during the engagement — if it’s not in here, it wasn’t agreed to.

    Section 4: Communication Log. A running record of significant decisions, feedback rounds, strategic pivots, and anything else that changes what the work looks like. Dated entries, brief and factual. Not a chat replacement — a decision record. This section prevents the “I thought we decided” conversation from becoming a dispute.

    Section 5: Next Steps. Three to five items, always current, showing what’s happening next. What we’re working on, what we need from the client, and when they can expect the next delivery. This is the most-read section of any client portal and the one that requires the most active maintenance. It should never be stale.

    What Makes This Different From a Template You Download

    The templates available online for Notion client onboarding are structurally fine. The problem is that they’re generic — built for a hypothetical agency, not for yours. The brand guidelines section in a downloaded template doesn’t know your specific questions. The scope section doesn’t reflect how you actually define deliverables.

    An effective onboarding template is built from your specific failure modes. What questions do you wish you had asked during onboarding for the client relationship that went sideways? What information did you need mid-engagement that you didn’t have? What expectation mismatch caused the most friction? The answers to those questions are what should be in your template, not a generic list of fields.

    Build the first version of your template, use it with two or three clients, and then revise it based on what you still didn’t know at the end of onboarding. Version two will be significantly better than version one, and version three better still.

    Making It Machine-Readable

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Making onboarding machine-readable for assistants.

    For operations running AI-assisted content production, the onboarding template does a third job beyond the two described above: it becomes the client reference document that Claude reads before starting any session for that client.

    This requires adding a metadata block at the top of the client reference page — a structured summary of the key constraints, the brand voice, the approved topics, and the things to avoid. With this block in place, Claude can orient itself to a client’s requirements in seconds at the start of a session, rather than requiring you to paste in the guidelines every time.

    The metadata block is five minutes of additional work during onboarding. It pays off every session for the duration of the engagement.

    Want this set up for your agency?

    We build client onboarding systems in Notion — the template structure, the intake process, and the reference architecture that makes every new client relationship start correctly.

    Tygart Media runs client onboarding across a large portfolio. We know what information you actually need and what gaps cause problems later.

    See what we build →

    Related on Tygart Media: client portal · Command Center · SOP system.

    Frequently Asked Questions

    Should client onboarding templates be the same for every client?

    The structure should be consistent; the content will differ. Using the same template structure for every client creates operational consistency — you always know where to find the brand guidelines, the scope definition, the communication log. The content within each section varies by client. Avoid the temptation to create different templates for different client types; the overhead of maintaining multiple templates outweighs the customization benefit for most agencies.

    How long should client onboarding take?

    The information collection phase — getting the brand guidelines, scope confirmation, and access credentials — should complete within the first week of the engagement. Rushing it creates gaps. Extending it past two weeks signals a disorganized client relationship that will be difficult throughout. The onboarding template makes the information collection systematic, which speeds it up without cutting corners.

    What’s the most important thing to document during client onboarding?

    Scope and constraints, in that order. Scope — exactly what was agreed and what’s out of scope — prevents the most common and costly agency problem: scope creep that erodes margins without anyone noticing until it’s significant. Constraints — what topics to avoid, what competitors are sensitive, what content has been tried and failed — prevent producing work that misses the mark for reasons you could have known going in.

  • Notion for Content Agencies: Manage 20+ Client Sites

    Notion for Content Agencies: Manage 20+ Client Sites

    The Agency Playbook
    TYGART MEDIA · PRACTITIONER SERIES
    Will Tygart · Senior Advisory · Operator-grade intelligence

    Managing twenty-plus client sites from one Notion workspace requires solving a specific problem: how do you keep clients separated while keeping your operation unified? Separate workspaces per client sounds clean until you’re switching between eight workspaces to get a picture of the week. One shared workspace sounds efficient until a client can see another client’s work.

    The answer is a single workspace with entity-level partitioning — one set of databases, one operating rhythm, one knowledge layer, with every record tagged to the entity it belongs to. Here’s how that works in practice for a content agency.

    What is entity-level partitioning in Notion? Entity-level partitioning is an architectural approach where all records across all clients live in shared databases, tagged with an entity or client property. Filtered views surface only the records relevant to a specific client or business line. The databases are unified; the views are isolated. It enables cross-client visibility for the operator while maintaining strict separation for any client-facing access.

    Why One Workspace Beats Many

    Four cards for content, ops, build, and knowledge work with Claude
    Why one workspace beats many for content agencies.

    The operational case for a single workspace is straightforward: weekly planning requires seeing everything at once. If Monday morning means answering “what’s publishing this week across all clients?”, the answer should come from one view, not from opening eight workspaces and aggregating manually.

    A single workspace with entity tagging gives you that cross-client view. Filter by entity for client-specific work; remove the filter for the full operational picture. The same database serves both purposes.

    The Content Pipeline at Scale

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    The content pipeline at agency scale.

    For a content agency, the Content Pipeline database is the operational core. Every article, audit, and deliverable across every client moves through the same status sequence — Brief, Draft, Optimized, Review, Scheduled, Published — in one database.

    Each record carries the client entity tag, the target site URL, the target keyword, word count, publication date, and a linked task in the Master Actions database for whoever is responsible for the next step. A filtered view scoped to one client shows that client’s complete pipeline. An unfiltered view shows the full operation across all clients simultaneously.

    The practical benefit: a Monday morning review of everything publishing in the next seven days across all clients is one database view, sorted by publication date. No aggregation, no manual compilation, no missing anything because it was in a different workspace.

    The Client-Specific Knowledge Layer

    Each client has unique constraints that govern the work: brand voice guidelines, keyword lists, approved topic areas, platform-specific rules, past decisions about what to avoid. This information needs to live somewhere accessible mid-session without requiring a search.

    In our system, each client’s reference documentation lives in the Knowledge Lab database, tagged with the client entity. A filtered view of the Knowledge Lab scoped to one client shows all the reference material for that client — brand guide, keyword strategy, approved personas, content rules — in one place.

    The critical piece: every client reference page carries the metadata block that makes it machine-readable mid-session. When working on a client’s content, Claude can fetch the client’s brand reference and style guide and read the key constraints from the metadata summary without reading the full document every time.

    Communication and Decision Logging

    At scale, the thing that creates the most operational problems is context loss between sessions: a decision made in a client call two weeks ago that wasn’t documented, a feedback note that lived in an email and never made it into the system, a constraint mentioned once and then forgotten.

    The communication log in each client’s portal and the session log in the Knowledge Lab together solve this. Any significant decision — a strategic pivot, a content constraint, a scope change — gets a one-paragraph log entry with a date. The next session starts by reading the most recent log entries, not by trying to remember what was decided.

    This is unglamorous work. It takes three minutes to write a decision log entry. Those three minutes prevent hours of re-work when the undocumented decision surfaces as a problem two months later.

    The Weekly Cross-Client Review

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The weekly cross-client review rhythm.

    The operational rhythm for a multi-client content agency requires one weekly moment of seeing the full picture: every client’s content queue, every stalled deliverable, every relationship that needs attention. This is the weekly review, and Notion’s filtered views make it tractable at scale.

    The weekly review covers four database views: all content scheduled for the coming week sorted by publication date; all tasks marked In Progress for more than two days across all clients; any Revenue Pipeline deals with no activity in the past seven days; any client CRM contacts who should have heard from you. Reading all four views and deciding what needs action takes twenty to thirty minutes. Everything else in the week flows from those decisions.

    Want this built for your content agency?

    We build multi-client Notion architectures for content agencies — the entity partitioning, content pipeline, knowledge layer, and operating rhythm that make managing twenty-plus clients tractable.

    Tygart Media manages a large portfolio of client sites from a single Notion workspace. We know what the architecture requires at that scale.

    See what we build →

    Related on Tygart Media: content pipeline · Command Center · agency templates.

    Frequently Asked Questions

    Should each client have their own Notion workspace?

    For most content agencies, no. Separate workspaces per client prevent the cross-client visibility that makes weekly planning tractable. A single workspace with entity-level partitioning gives you unified operations for the agency and isolated views for any client-facing access. Separate workspaces make sense only when clients need active collaborative access to the same workspace — a rare requirement for most content agency relationships.

    How do you prevent one client’s content from appearing in another client’s view?

    Every database record carries an entity or client tag. Every client-facing view is filtered to show only records with that client’s tag. As long as records are correctly tagged at creation — which becomes habitual quickly — the filtering is reliable. A brief weekly audit checking for untagged records catches any that slip through.

    What happens when a content agency grows beyond Notion’s capacity?

    Notion handles large workspaces well with proper architecture — the performance issues most people encounter come from databases with thousands of unarchived records, not from the number of clients. Regular archiving of completed records keeps databases performant. At genuinely large scale (hundreds of active clients), dedicated agency management software may be warranted, but most content agencies operating at twenty to fifty clients run well within Notion’s capabilities.

  • Notion Second Brain for Business (Not Productivity Nerds)

    Notion Second Brain for Business (Not Productivity Nerds)

    The Agency Playbook
    TYGART MEDIA · PRACTITIONER SERIES
    Will Tygart · Senior Advisory · Operator-grade intelligence

    The Notion second brain content online is almost entirely written for individuals. Personal productivity. Getting things out of your head. PARA systems for your reading notes. That’s useful for a person. It’s not what a business owner running an operation actually needs.

    A business second brain is different in kind, not just in scale. It’s not a place to capture your ideas — it’s the institutional memory of an organization. The difference matters for how you build it, what goes in it, and how you use it.

    This is the business owner’s version: no productivity philosophy, no personal capture system, just the architecture that works when the stakes are operational rather than personal.

    What is a Notion second brain for business? A business second brain in Notion is an externalized operational memory system — a structured workspace where the knowledge, decisions, procedures, and context that run a business live outside any individual’s head. Unlike a personal second brain focused on personal knowledge management, a business second brain is organized around operational function: what we do, how we do it, who we work with, and what we’ve decided.

    What a Business Second Brain Actually Stores

    Four cards for content, ops, build, and knowledge work with Claude
    What a business second brain actually stores.

    Personal second brains store ideas, highlights, book notes, and learning. Business second brains store different things — and getting clear on the distinction prevents building the wrong system.

    A business second brain stores: how things get done (SOPs and procedures), what has been decided and why (architecture decisions and rationale), who the relevant people are and where relationships stand (CRM and contact history), what is currently in motion (project and content pipelines), and what was learned that should change how things get done next time (session logs and after-action notes).

    It does not store every idea you had, every article you read, or every meeting note verbatim. Those belong in a personal system or in the trash. The business second brain is a curated operational record, not a capture-everything archive.

    The Organizational Principle: Function Over Topic

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    The organizational principle — function over topic.

    Personal second brains are usually organized by topic — a page for marketing, a page for strategy, a page for each project. This makes sense for individual knowledge management. It breaks down for business operations because the same information belongs to multiple topics simultaneously.

    Business second brains are organized by function: what kind of operational question does this answer? The six functional categories that cover most small business operations are tasks, content, revenue, relationships, knowledge, and the daily dashboard. Everything in the business belongs to one of those six. If it doesn’t fit any of them, it probably doesn’t need to be documented.

    The Knowledge Layer Is the Differentiator

    Most business Notion setups have tasks and maybe a content tracker. The part that separates a true second brain from a fancy to-do list is the knowledge layer — the documented institutional memory that makes the operation less dependent on any one person’s recall.

    The knowledge layer contains three things. SOPs: how specific procedures get executed, written precisely enough that someone unfamiliar with the process could follow them correctly. Architecture decisions: why the operation is structured the way it is, including the alternatives that were considered and rejected. Client and project context: the accumulated understanding of each relationship and engagement that would otherwise live only in the account manager’s memory.

    This layer is the hardest to build because it requires translating tacit knowledge — things people just know from experience — into explicit documentation. It’s also the most valuable, because it’s the layer that survives personnel changes, makes onboarding tractable, and allows an AI system to operate on your behalf with real institutional context.

    Daily Use Is What Makes It a Brain

    A second brain that you consult once a week is a reference library. A second brain that you interact with every working day is an operating system. The difference is in how the daily rhythm is designed.

    The daily interaction with the business second brain should take ten to fifteen minutes in the morning: triage new items into the right databases, check what’s due or overdue, scan the content queue for anything publishing in the next 48 hours that needs attention. And five minutes at the end of the day: mark done tasks complete, push anything untouched, log any significant decisions made.

    If those interactions feel like maintenance overhead, the system isn’t designed right. They should feel like reading the dashboard of a machine you trust — a quick orientation to current state before the day’s work begins.

    What Makes It AI-Ready

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What makes it AI-ready.

    The most significant thing a business second brain can do in 2026 that wasn’t possible five years ago is function as context infrastructure for an AI system. When Claude can read your SOPs, understand your active projects, and know what decisions have already been made, it operates as a genuine collaborator rather than a tool you have to re-brief every session.

    Making a Notion workspace AI-ready requires one addition beyond good organization: a consistent metadata structure on key pages that makes them machine-readable. A brief structured summary at the top of each important page — the page type, what it covers, the key constraints, and a resume instruction for continuing work in progress — gives an AI system the orientation it needs without requiring it to read thousands of words of context every session.

    This isn’t complicated to implement. It’s a JSON block at the top of each important page, written once and updated when the page changes. But it’s the difference between a Notion workspace that an AI can navigate and one that requires constant manual context transfer.

    Starting Without Starting Over

    Most business owners who want a Notion second brain already have some Notion — random pages, abandoned systems, half-built databases from previous attempts. The instinct is to start over from scratch. Usually the right move is not to.

    Start by identifying what already exists that’s actually useful: any SOPs that are current, any databases that are being used, any pages that people actually refer to. Move those into the right place in the six-database architecture. Then identify the most important gaps — usually the knowledge layer, which is often entirely missing — and fill those first.

    A usable business second brain built in two weeks by organizing what exists is worth more than a perfect system built from scratch over three months. The system’s value is in being used, not in being complete.

    Want this built for your business?

    We build Notion second brain systems for business owners — the full architecture, configured for your operation, with the knowledge layer that most setups skip.

    Tygart Media runs this system live across multiple business lines. We know what the build process looks like and what makes it stick.

    See what we build →

    Related on Tygart Media: Notion-deep, surface-simple · Command Center · second brain setup.

    Frequently Asked Questions

    Is a business second brain the same as a personal second brain?

    No. A personal second brain is organized around individual knowledge management — capturing ideas, notes, and learning for personal recall and creativity. A business second brain is organized around operational function — tasks, pipelines, relationships, procedures, and institutional knowledge. The tools can overlap (both often use Notion) but the architecture and the content are fundamentally different.

    How is a Notion business second brain different from a project management tool?

    Project management tools handle tasks and timelines. A business second brain handles those plus the knowledge layer — why decisions were made, how procedures work, what the history of a client relationship looks like, what was learned from past projects. The knowledge layer is what transforms a task tracker into something that actually captures and preserves institutional memory.

    Who should own the business second brain?

    In a small agency or solo operation, the owner maintains it. In a slightly larger team, the person closest to operations — often the account lead or operations manager — maintains the shared elements while individuals maintain their own client-specific documentation. The critical rule: someone must own it. A second brain maintained by everyone equally is maintained by no one.

    How long does it take to build a business second brain in Notion?

    A functional minimum viable second brain — the six databases set up, the most critical SOPs documented, the daily rhythm established — takes twenty to thirty hours of focused work. A mature system with comprehensive knowledge documentation takes three to six months of consistent operation. The minimum viable version provides immediate value; the mature version is what makes the operation genuinely resilient and AI-ready.

  • Notion Project Management: 6-Database Agency System

    Notion Project Management: 6-Database Agency System

    The Agency Playbook
    TYGART MEDIA · PRACTITIONER SERIES
    Will Tygart · Senior Advisory · Operator-grade intelligence

    The project management tools built for agencies assume you have a team. They’re priced per seat, designed for handoffs between people, and optimized for visibility across a group. If you’re running a small agency — two to five people, or solo with contractors — most of that architecture is overhead you don’t need and complexity that actively slows you down.

    Notion solves this differently. Instead of fitting your operation into a tool designed for someone else’s workflow, you build the system your operation actually requires. For a small agency managing multiple clients and business lines simultaneously, that system is a six-database architecture that keeps everything connected without the bloat of enterprise project management software.

    This is what that architecture looks like and why each piece exists.

    What is the 6-database Notion architecture? The 6-database architecture is a Notion workspace structure designed for small agencies and solo operators managing multiple clients or business lines. Six interconnected databases — tasks, content, revenue, CRM, knowledge, and a daily dashboard — cover every operational layer of the business, linked by shared properties so information flows between them without duplication.

    Why Six Databases and Not More

    Four cards for content, ops, build, and knowledge work with Claude
    Why six databases — and not more — for small agencies.

    The instinct when building a Notion system from scratch is to create a database for everything. A database for meetings. A database for ideas. A database for invoices. A database for each client. This is how Notion workspaces become unusable — too many places things could live, no clear answer for where they actually belong.

    Six databases is the right number for a small agency because it maps cleanly to the six operational questions you need to answer at any moment: What do I need to do? What content is in the pipeline? Where does revenue stand? Who are my contacts? What do I know? What matters today?

    Every piece of information in the operation belongs in one of those six categories. If something doesn’t fit, it either belongs in a sub-page of an existing database record or it doesn’t need to be documented at all.

    Database 1: Master Actions

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    Database 1: master actions.

    Every task across every client and business line lives in one database. Not separate task lists per client, not separate boards per project — one database, partitioned by entity tag.

    The key properties: Priority (P1 through P4), Status (Inbox, Next Up, In Progress, Blocked, Done), Entity (which business line or client), Due Date, and a relation field linking to whichever other database the task belongs to — a content piece, a deal, a contact.

    The priority logic is worth being explicit about. P1 means revenue or reputation suffers today if this doesn’t get done. P2 means this creates leverage — a system, an asset, something that compounds. P3 means operational work that needs to happen but doesn’t compound. P4 means it should be delegated or killed. If your P1 list has more than five items, something is mislabeled.

    The daily operating rule: never more than five tasks in Next Up at once. The system forces prioritization rather than enabling the comfortable illusion that everything is equally important.

    Database 2: Content Pipeline

    Every piece of content — articles, reports, audits, deliverables — moves through a defined status sequence before it reaches the client or goes live. Brief, Draft, Optimized, Review, Scheduled, Published.

    The Content Pipeline database tracks where every piece is in that sequence, which client it belongs to, the target keyword or topic, the target platform, word count, and publication date. The relation field links back to the Master Actions database so the task of writing a specific piece and the piece itself are connected.

    The hard rule: nothing publishes without a Content Pipeline record. This creates an audit trail that answers “what did we deliver in March?” in seconds rather than requiring a search through email threads or shared drives.

    Database 3: Revenue Pipeline

    Active deals, proposals, and retainer renewals tracked through defined stages: Lead, Qualified, Proposal Sent, Active, Renewal, Closed.

    Each record carries the deal value, the stage, the last activity date, and a relation to the Master CRM for the associated contacts. The weekly review checks whether any deal has sat in the same stage for more than seven days without activity — that stagnation is a signal that requires a decision, not more waiting.

    The Revenue Pipeline doesn’t replace an accounting system. It tracks the relationship status and deal momentum, not invoices or payments. Those live in dedicated accounting software. The pipeline answers “where are we in the conversation?” not “what was billed?”

    Database 4: Master CRM

    Every contact across every business line — clients, prospects, partners, vendors, network relationships — in one database, tagged by entity and relationship type.

    The CRM properties: Entity, Relationship Type (client, prospect, partner, vendor, network), Last Contact Date, and a relation field linking to any Revenue Pipeline deals associated with that contact.

    The weekly review includes a check for any contact who should have heard from you and didn’t. “Should have heard from you” is defined by relationship type — active clients warrant more frequent contact than cold prospects. The CRM makes that check systematic rather than dependent on memory.

    Database 5: Knowledge Lab

    SOPs, architecture decisions, reference documents, and session logs. This is the institutional knowledge layer — everything that would take significant time to reconstruct if the person who knows it left or forgot.

    Every Knowledge Lab record carries a Type (SOP, architecture decision, reference, session log), an Entity tag, a Status (evergreen, active, draft, deprecated), and a Last Verified date. The Last Verified date drives the maintenance cycle — any record older than 90 days gets flagged for a quick review.

    The Knowledge Lab is also the layer that makes the operation AI-readable. Every page carries a machine-readable metadata block at the top that allows Claude to orient itself to the content quickly during a live session. This is what transforms the Knowledge Lab from a static document library into an active operational asset.

    Database 6: Daily Dashboard (HQ)

    Not a database in the traditional sense — a command page that aggregates filtered views from the other five databases into a single daily interface. The goal is one page that answers “what needs attention right now?” without clicking through five separate databases.

    The HQ page contains: a filtered view of P1 and P2 tasks due today or overdue, the content queue for the next 48 hours, an inbox view of unprocessed items (tasks without a priority or status assigned), and a quick-access list of the most frequently used database views.

    The HQ page is where every working day starts. Everything else in the system is accessed from here or from the five source databases. It’s the navigation layer, not a database of its own.

    How the Databases Connect

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How the six databases connect.

    The architecture only works as a system if the databases talk to each other. The connection mechanism in Notion is relation properties — fields that link a record in one database to a record in another.

    The key relations: every Content Pipeline record links to a Master Actions task. Every Revenue Pipeline deal links to a Master CRM contact. Every Master Actions task can link to a Content Pipeline record, a Revenue Pipeline deal, or a Knowledge Lab SOP. These relations mean you can navigate from a task to the content piece it produces, from a deal to the contact it involves, from a procedure to the tasks that execute it — without leaving Notion or losing the thread.

    Rollup properties extend this further: a Content Pipeline view can show the priority of the associated task without opening the task record. A Revenue Pipeline view can show the last contact date from the CRM without opening the contact. The data stays connected visually, not just structurally.

    What This Architecture Replaces

    For a small agency, the 6-database architecture typically replaces: a project management tool (the tasks and content pipeline handle this), a CRM (the Master CRM handles this), a shared drive for SOPs (the Knowledge Lab handles this), and a deal tracker (the Revenue Pipeline handles this). It does not replace accounting software, calendar tools, or communication platforms — those remain separate because they do things Notion doesn’t.

    The consolidation matters not just for cost but for operational clarity. When every operational question has one answer and one place to look, the cognitive overhead of running the business drops significantly. The system becomes something you trust rather than something you maintain out of obligation.

    Want this built for your agency?

    We build the 6-database Notion architecture for small agencies — configured for your specific operation, with the relations, views, and daily operating rhythm set up and documented.

    Tygart Media runs this system live. We know what the build process looks like and what breaks without the right architecture from the start.

    See what we build →

    Related on Tygart Media: Command Center · onboarding template · SOP system.

    Frequently Asked Questions

    How is the 6-database Notion architecture different from using ClickUp or Asana?

    ClickUp and Asana are built around tasks and projects as the primary organizational unit. The 6-database architecture treats the business itself as the organizational unit — tasks, content, revenue, relationships, and knowledge are all connected layers of one system rather than separate tools or modules. The tradeoff is that Notion requires more upfront architecture work, but produces a system that fits your specific operation rather than a generic project management workflow.

    Can one person realistically maintain six databases?

    Yes — that’s what the architecture is designed for. The daily maintenance is five to fifteen minutes of triage and status updates. The weekly review is thirty minutes. Most of the database updating happens naturally as work progresses: publishing a piece updates the Content Pipeline, closing a deal updates the Revenue Pipeline. The system is designed for a solo operator or a very small team, not a department.

    What Notion plan do you need for the 6-database architecture?

    The Plus plan at around ten dollars per month per member is sufficient for everything described here — unlimited pages, unlimited blocks, and the relation and rollup properties that make the database connections work. The free plan limits relations and rollups in ways that would break the architecture. The Business plan adds features useful for larger teams but isn’t necessary for a small agency setup.

    How long does it take to build the 6-database architecture from scratch?

    Plan for twenty to forty hours to build, configure, and populate the initial system — creating the databases, setting up the properties and relations, building the filtered views, writing the first SOPs, and establishing the daily operating rhythm. Most operators who build it solo spend two to three months in iteration before it stabilizes. Starting from a pre-built architecture configured for your specific operation compresses that significantly.

    What’s the biggest mistake people make when building a Notion agency system?

    Creating too many databases. The instinct is to give everything its own database — one per client, one per project type, one for every category of information. This creates the same problem as a disorganized file system: too many places things could live, no clear answer for where they actually belong. Start with six. Add a seventh only when there’s a category of information that genuinely doesn’t fit in any of the six and that you need to query or filter regularly.