Tygart Media Editorial - Tygart Media

Category: Tygart Media Editorial

Tygart Media’s core editorial publication — AI implementation, content strategy, SEO, agency operations, and case studies.

  • Querying LLMs: What We Learned From 54 OpenRouter Models

    Querying LLMs: What We Learned From 54 OpenRouter Models

    The headline: In mid-May 2026, we ran an autonomous OpenRouter session querying 54 LLMs about their own identity, capabilities, and training. Total cost: $1.99 against a $270 starting balance. 43 substantive responses, 10 documented failures, 1 reasoning-only response. The most interesting finding: aion-2.0 identified itself as Claude — concrete evidence of training-data identity inheritance across LLMs. This article walks through the methodology, the reliability data, and what cheap multi-model research now makes possible.

    This is part of our OpenRouter coverage. For the operator’s view on why we run model research through OpenRouter, see the field manual. For the structured decision methodology that multi-model setups also enable, see the roundtable methodology.

    The setup
    Three cards for solo takes, cross-pollination, and synthesis
    The setup for querying many models through one router.

    In mid-May 2026 we ran an autonomous session designed to extract self-knowledge from a wide sample of available LLMs. The question structure was simple: ask each model about its own identity, training, capabilities, and limits, then capture the response for cross-comparison.

    The scope expanded mid-execution from the original 50 to 54 models — the OpenRouter catalog had grown during the session itself, which is its own data point about how fast this ecosystem moves.

    The architecture: a Python script with parallel bash execution, a max-wait timeout per model, graceful per-provider error handling, and Notion publishing of each model’s response as a separate Knowledge Lab entry. Everything billed through OpenRouter.

    The cost: $1.99 against a $270 starting balance. Less than two dollars to canvas 54 frontier and near-frontier models on a question of self-identity.

    The hit rate

    Of 54 models queried, 43 returned substantive responses. One returned a reasoning trace without final content (GPT-5.5 Pro, which we counted as a valid capture given the reasoning content was the interesting part). 10 returned documented failures.

    That’s 81% substantive completion. For a fully autonomous run against a heterogeneous provider pool with no per-model tuning, that’s a meaningful number.

    The 10 failures broke down into clear categories:

    • Rate limiting (429 errors): persistent on a handful of providers. Some had genuine quota issues; some appeared to be hitting upstream limits we couldn’t see from our side.
    • Forbidden (403): providers refusing the request entirely, often for reasons related to account configuration we hadn’t completed.
    • Not found (404): model IDs that had moved or been deprecated between our model-list scrape and the execution.
    • Timeouts: the most interesting category. Grok 4.20 multi-agent consistently exceeded our timeout window — not because it was slow, but because it appears to orchestrate sub-agents that genuinely take more than 40 seconds to produce a final answer. We documented this as a failure for our purposes; for a different use case it would have been a feature.

    The decision we made in real time was not to retry persistent failures. If a provider returned 429 on three consecutive attempts, we let it stand as a documented failure rather than burning the run on retries. The rationale: those providers are either genuinely rate-limited or having an issue, and a fourth attempt in the same minute isn’t going to resolve either.

    The finding that mattered
    Three cards: coding depth, latency first, agent reliability
    The finding that mattered — reliability beats average quality.

    Of all the substantive responses, one stood out: aion-2.0 identified itself as Claude.

    Not “trained on Claude data.” Not “fine-tuned from a Claude-derived model.” It described itself, in the first person, as Claude.

    Aion-2.0 is not Claude. It’s a separate model from a separate provider. The most likely explanation is that its training data included a significant volume of Claude outputs, and the model’s self-knowledge inherited Claude’s identity along with Claude’s content patterns. The model learned to be Claude-like in style and, in the process, learned to identify as Claude in substance.

    This is a known phenomenon in the literature on training data contamination, but seeing it surface concretely in a production model — on an answer to a basic self-identity question — is different from reading about it in a paper. It’s a real thing happening at scale, and most users of these models have no idea.

    The implication for anyone running multi-model evaluations: model outputs are not independent. Models trained on the outputs of other models inherit not just style but identity, opinion patterns, and likely failure modes. If you’re running a roundtable methodology and treating three models as three independent perspectives, and one of them is silently downstream of another in training data, your “consensus” might be one model’s perspective dressed in three different costumes.

    This is also an argument for why first-party model selection — choosing models from clearly distinct lineages rather than just “three frontier models” — matters more than people give it credit for.

    The reliability data
    Four gates: max turns, tool allowlist, token budget, kill switch
    Reliability data across the model set.

    Setting aside the aion-2.0 finding, the bare reliability data from this run is useful on its own terms.

    10 of 54 providers (18.5%) returned errors. That’s a meaningful failure rate for any production workload that depends on cross-model availability. If your application assumes you can call any model in the catalog and get a response, you’re going to be wrong about 1 in 5 of the time on first attempt.

    OpenRouter’s pooled access mitigates this somewhat — for some providers, OpenRouter automatically retries against alternate endpoints when one fails. But the failures we saw were after OpenRouter’s own retry logic ran. These are the failures that surface to the caller after the routing layer has done what it can.

    For production systems, the practical implication is straightforward: never depend on any single model being available. Build fallback chains. Use OpenRouter’s Auto Router with a wildcard allowlist for tolerance, or wire your own fallback logic. A multi-model architecture isn’t a luxury; it’s a reliability requirement.

    The cost shape

    $1.99 of spend across 54 model queries works out to roughly $0.037 per query, including all the failed attempts.

    That’s the headline number, but the distribution matters more than the average. A handful of queries — the ones that hit larger reasoning models like Claude Opus or GPT-5.5 Pro — accounted for the majority of the spend. Cheap models like Gemini Flash and various open-source mid-tier models barely moved the needle.

    If you’re running research at this kind of breadth, the cost model is dominated by the heavy reasoning models, not by the long tail of cheaper models. The implication: when you’re running broad-canvas queries, it costs almost nothing to add another cheap model to the catalog. Adding another expensive reasoning model is what you should be deliberate about.

    What broke and what we learned

    Three patterns of failure repeated:

    Provider rate limits unrelated to our usage. Some providers appear to share upstream capacity with the wider OpenRouter user base, and when that upstream capacity is hot, your individual call fails regardless of your own usage. There is no client-side fix. You either retry later or fall back.

    Model IDs drift. The catalog moves fast. A model ID you fetch on Monday may have been deprecated by Friday. Our script’s freshness window — about a day between model-list scrape and execution — was sometimes enough for drift. For production systems, fetch the model list immediately before the run.

    Multi-agent models exceed simple timeout windows. Grok 4.20’s behavior of orchestrating sub-agents that take 40+ seconds is not a bug; it’s the product. But it breaks any timeout shorter than what the multi-agent run actually needs. If you’re going to call multi-agent models, plan for long latencies and don’t share a timeout policy with single-call models.

    What we’d do differently

    Three changes for the next run of this kind:

    1. Refresh the model list inline. Don’t trust a list scraped even a few hours earlier. Fetch fresh before each batch.
    2. Tiered timeouts. Single-call models on a tight timeout. Multi-agent and reasoning-heavy models on a relaxed one. Detect which is which from the model metadata where possible.
    3. Publish-as-you-go. Our Notion publish step ran after data collection. The session ended mid-publish, leaving uncertainty about which of the 54 pages had actually been created. Better to publish each result immediately as it returns, so a session interruption doesn’t lose anything.

    The bigger lesson

    Two dollars to canvas 54 models on a question of self-identity is a cost structure that didn’t exist three years ago. It also means a category of research that used to require expensive infrastructure is now within reach of anyone with an OpenRouter account and a Python script.

    The interesting finding — aion-2.0 silently identifying as Claude — would have been almost impossible to discover any other way. You can’t catch a training-data identity inheritance by reading model documentation. You catch it by asking a lot of models the same question and looking at the answers side by side.

    OpenRouter, for all its caveats and its limited scope, makes this kind of multi-model research tractable in a way nothing else currently does. If you’re not running periodic broad-canvas queries against your model catalog, you’re flying blind on what’s actually in there. Two dollars is cheap insurance against being surprised by the next aion-2.0.

    Frequently asked questions

    How much does it cost to query 54 LLMs at once via OpenRouter?

    In our autonomous run, the total cost was $1.99 — roughly $0.037 per query including the 10 failed attempts. Cost was dominated by the few queries hitting expensive reasoning models like Claude Opus and GPT-5.5 Pro; the long tail of cheaper models barely moved the needle. Adding more cheap models to a broad-canvas query costs almost nothing.

    What is training-data identity inheritance?

    When a model’s training data includes outputs from another model, the trained model can inherit not just style but identity from the source model. In our run, aion-2.0 identified itself as Claude — likely because its training data contained enough Claude outputs that the model’s self-knowledge absorbed Claude’s identity along with Claude’s content patterns. This is a known phenomenon in the literature on data contamination.

    How reliable are LLM providers via OpenRouter?

    In our 54-model autonomous run, 10 providers (18.5%) returned errors after OpenRouter’s own retry logic ran. The failures broke down into rate limits, forbidden responses, deprecated model IDs, and timeouts on multi-agent models. The practical implication: never depend on any single model being available. Build fallback chains.

    Why did some models timeout in the 54-LLM run?

    The most notable timeout case was Grok 4.20 multi-agent, which appears to orchestrate sub-agents that genuinely take more than 40 seconds to produce a final answer. This isn’t a bug; it’s the product. But it breaks any timeout policy shared with single-call models. Multi-agent and reasoning-heavy models need their own relaxed timeout tier.

    Should I run periodic broad-canvas queries against my model catalog?

    Yes. At roughly two dollars per 54-model run, broad-canvas queries are cheap insurance against being surprised by training-data inheritance, identity drift, or quality degradation in models you depend on. You can’t catch these issues by reading documentation. You catch them by querying widely and comparing answers side by side.

    See also: The 5-Layer OpenRouter Mental Model: Org, Workspace, Guardrail, Key, Preset
  • Multi-Model AI Roundtable: 3 Rounds to Better Decisions

    Multi-Model AI Roundtable: 3 Rounds to Better Decisions

    The Multi-Model AI Roundtable is a three-round structured exchange where the same question is sent to three models from different lineages (typically Claude, GPT, and Gemini), cross-pollinated by sharing each model’s response with the others, and then synthesized into a final recommendation with explicit confidence calibration. Used for strategic decisions, content architecture, and technical trade-offs where single-model output isn’t trustworthy enough.

    This is part of our OpenRouter coverage. See the operator’s field manual for the broader context on why we route through OpenRouter, and the 5-layer mental model for the hierarchy that makes multi-model routing tractable.

    Why three models beat one

    Three cards for solo takes, cross-pollination, and synthesis
    Why three models beat one — then run three rounds.

    Single-model decision-making has a known failure mode: the model’s training data and reasoning patterns silently shape every recommendation. The model doesn’t know what it doesn’t know. You don’t know what it doesn’t know. You get a confident answer, you act on it, and the missing perspective shows up later as a problem you didn’t see coming.

    Three models from three different lineages catch each other’s blind spots. Claude Opus 4.7 tends to over-index on safety considerations and structural rigor. GPT-5.5 tends to favor decisive, action-oriented framing. Gemini 3 Flash tends to surface edge cases and multimodal context the others gloss over. Run a hard decision past all three and the agreement-versus-disagreement pattern itself becomes information.

    The methodology we use is a three-round structured exchange. Same question, three responses, then cross-pollination, then synthesis. Below is the exact pattern we’ve used across decisions ranging from tech stack choices to keyword prioritization to architectural calls on the autonomous behavior system.

    The architecture

    Three cards: coding depth, latency first, agent reliability
    Architecture: parallel takes, then synthesis.

    OpenRouter makes this cheap to wire. One API endpoint, three different model identifiers, three parallel calls:

    const models = [
      "anthropic/claude-opus-4.7",
      "openai/gpt-5.5",
      "google/gemini-3-flash"
    ];
    
    const responses = await Promise.all(
      models.map(model =>
        fetch("https://openrouter.ai/api/v1/chat/completions", {
          method: "POST",
          headers: {
            "Authorization": `Bearer ${OPENROUTER_API_KEY}`,
            "Content-Type": "application/json"
          },
          body: JSON.stringify({
            model,
            messages: [{ role: "user", content: prompt }]
          })
        }).then(r => r.json())
      )
    );
    

    That’s the entire architectural surface. Three calls, three responses, parallel execution. Without OpenRouter you’d be juggling three separate API contracts. With it, one endpoint and a model parameter.

    Round 1: Individual perspectives

    Send the same question to all three models with no awareness that they’re part of a roundtable. Each responds independently.

    The prompt structure that works:

    We’re evaluating [decision]. Consider:

    1. The key factors to weigh
    2. Risks and mitigations
    3. Your recommendation, with reasoning
    4. What you might be missing

    The fourth bullet is the one that earns the cost of the call. Asking a model to name its own blind spots is a remarkably effective way to surface the limits of its perspective. Models that handle this prompt well will name epistemic limits explicitly: “I don’t have visibility into your team’s specific constraints,” or “this depends on factors I can’t verify from this conversation.”

    Collect all three Round 1 responses. Don’t synthesize yet.

    Round 2: Cross-pollination

    This is where the methodology earns its keep. Send each model the other two models’ Round 1 responses and ask:

    • Identify points of agreement
    • Challenge or refine the other perspectives
    • Update your own recommendation if warranted

    Most teams skip this round. They run Round 1, see agreement, ship a decision. They miss the cases where one model would have changed its mind given the other models’ input — which is exactly the cases where the disagreement matters.

    Round 2 also surfaces a pattern worth naming: model deference. Some models, when shown a different perspective, will pivot toward it almost regardless of the merits. Others hold their position too rigidly. Watching how each model handles disagreement is itself information about how to weight their inputs in future roundtables.

    Round 3: Synthesis

    One model — usually Claude in our case, because long-form reasoning is the job — gets all the Round 1 and Round 2 outputs and produces a final synthesis:

    • Consensus points (where all three models agreed, both rounds)
    • Remaining disagreements (where the models did not converge)
    • Confidence level (high if convergence, medium if mixed, low if persistent disagreement)
    • Suggested next steps

    The confidence calibration is the part that changes how decisions actually get made. A decision the roundtable converges on with high confidence can be acted on immediately. A decision with persistent disagreement is a signal that the question is harder than it looked, and probably needs human judgment or more research before action.

    When this is worth running

    The roundtable is not free. Three rounds, three models, plus synthesis equals roughly four to six API calls per decision. Even at low-cost model pricing for the initial rounds, this adds up if you run it on every micro-decision.

    Use it for:

    • Strategic decisions — tech stack selection, business model choices, pricing strategy
    • Content strategy at scale — keyword prioritization for a 50-article batch, topic cluster architecture, format decisions
    • Technical architecture — system design, security posture, performance trade-offs
    • Anything irreversible — moves that you’ll wear for months if they’re wrong

    Don’t use it for:

    • Day-to-day operational questions a single model can answer well
    • Decisions where you already know the answer and just want validation
    • Questions where the cost of being wrong is small

    Cost shape

    Four gates: max turns, tool allowlist, token budget, kill switch
    Cost shape — only run the roundtable when the decision is expensive.

    For an agency stack the cost-per-roundtable comes out roughly as follows when using a balanced model mix:

    • Round 1: three parallel calls. Use Gemini 3 Flash or DeepSeek V3.2 for breadth at low cost. Heavier models only when you need deeper reasoning in Round 1.
    • Round 2: three more calls with more context. Same models, larger context window.
    • Round 3: one synthesis call. Use the best reasoning model you have access to — Claude Opus 4.7 is our default for synthesis.

    Total cost per decision typically runs from a few cents to a few dollars depending on context length and model selection. For decisions worth running through the roundtable, that’s noise.

    An example output

    A real roundtable from our archive, on the question of where to start with Google Apps Script as a learning project:

    GPT-5.5: Start simple — a Google Sheets data retrieval script. Learning value comes from working through the auth flow and basic API surface without complexity getting in the way.

    Claude Opus 4.7: Start impactful — a Time Insight Dashboard combining Gmail and Calendar data. Higher learning curve but produces something you’ll actually use, which keeps motivation up.

    Gemini 3 Flash: Hybrid — simple foundation but with one meaningful integration. Lowers the activation energy while preserving the impact angle.

    Consensus (Round 3): Begin with a data retrieval script (all three models agree on the learning value) but include one meaningful integration like calendar events. The Round 2 cross-pollination resolved most of the disagreement; Claude moderated its position after seeing GPT-5.5’s argument about activation energy.

    Confidence: High. All three models aligned on progressive complexity after cross-pollination.

    That output is more useful than any single model’s recommendation would have been. It names the trade-off, shows the path to consensus, and quantifies confidence. That’s what you’re paying for.

    The variations worth knowing

    A few patterns we’ve adapted from the base methodology:

    Adversarial roundtable. Instead of asking each model the same question, assign roles. Model A argues for. Model B argues against. Model C judges. Useful for decisions where you suspect you’ve already made up your mind.

    Sequential expert chain. Skip parallel Round 1. Run one model, then send its output to the next model to refine, then to the third. Slower but useful when you need each step to build on the last.

    Domain-specialized roundtable. Use BYOK to route Round 1 calls to specialty providers when the question is technical. A legal question routes through a legal-specialized provider. A code question routes through a code-specialized provider. The synthesis still happens at Claude Opus 4.7 or GPT-5.5.

    The base methodology — three rounds, three models, one synthesis — is the version we run by default. The variations are for cases where the base pattern is leaving value on the table.

    What this unlocks

    Once the roundtable is wired into your stack, a category of decision that used to take a meeting becomes a 90-second API call. Not every meeting. The ones where you would have walked in already knowing the answer and the meeting was performative.

    The roundtable doesn’t replace human judgment. It replaces the version of the decision where you didn’t think it through. The version where you would have shipped your first instinct and lived with the consequence. That’s the win.

    Frequently asked questions

    What is a multi-model AI roundtable?

    A three-round structured exchange where the same question is sent to three AI models from different lineages, then cross-pollinated by sharing each model’s response with the others, then synthesized into a final recommendation with explicit confidence calibration. The methodology surfaces blind spots that single-model output silently hides.

    Why use Claude, GPT, and Gemini together instead of just one?

    Each model has different training data and reasoning patterns. Claude tends to emphasize safety and structural rigor. GPT tends to favor decisive action-oriented framing. Gemini tends to surface edge cases. Running a hard decision past all three gives you agreement-versus-disagreement information that no single model can provide.

    How much does a multi-model roundtable cost per decision?

    Typically a few cents to a few dollars per decision, depending on model selection and context length. Using cheaper models (Gemini Flash, DeepSeek) for the initial rounds and reserving the expensive reasoning models for Round 3 synthesis keeps the cost shape favorable.

    When is the multi-model roundtable not worth running?

    Skip it for day-to-day operational questions a single model can answer well, decisions where you already know the answer and just want validation, and questions where the cost of being wrong is small. Reserve it for strategic decisions, content architecture, technical trade-offs, and anything irreversible.

    What is the third round of the roundtable for?

    Synthesis. One model — typically the strongest reasoning model in the set — receives all the Round 1 and Round 2 outputs and produces a final recommendation with consensus points, remaining disagreements, confidence level, and suggested next steps. This is the part that turns three opinions into one actionable decision.

    See also: What We Learned Querying 54 LLMs About Themselves (For $1.99 on OpenRouter)

  • BYOK on OpenRouter: Provider Keys, Prioritization, and Fallback Strategy

    BYOK on OpenRouter: Provider Keys, Prioritization, and Fallback Strategy

    BYOK on OpenRouter: Bring-Your-Own-Key on OpenRouter means configuring direct provider credentials for any of dozens of supported providers, with per-provider prioritization, fallback chains, and the ability to pin specific BYOK keys to specific OpenRouter API keys (meaning specific agents). The result is a routing system where you can mix discounted enterprise contracts with pooled access, transparent to the calling code.

    This is a deep dive on the BYOK system inside OpenRouter. For the broader operator’s perspective on OpenRouter, see our OpenRouter operator’s field manual. For the underlying hierarchy that governs where BYOK lives, see the 5-layer mental model.

    What BYOK actually means here

    Five operator layers: client, router, provider, model, policy/spend
    What BYOK actually means on OpenRouter.

    Most platforms use “BYOK” to mean bring your key for the one provider we support. OpenRouter means something more interesting: bring your key for any of dozens of providers, configure prioritization and fallback per provider, pin keys to specific agents and models, and let OpenRouter handle the routing logic when a key fails or runs out.

    The result is a routing system where you can mix and match. Run your high-volume agent through a discounted enterprise contract at Provider A. Route everything else through OpenRouter’s pooled pricing. Fall back to OpenRouter’s pool when your enterprise key is rate-limited. All transparent to the calling code.

    This is genuinely useful for an agency stack. It’s also where most teams misconfigure things in ways that don’t fail loudly.

    The Providers tab

    Four gates: max turns, tool allowlist, token budget, kill switch
    Providers tab — keys, priority, spend controls.

    This is where the bulk of BYOK lives. Every provider — from AI21 at the top of the alphabet to Z.ai at the bottom — gets its own configuration card. Each card has two slots: Prioritized keys (tried first, before falling back to OpenRouter’s pooled access) and Fallback keys (tried last, after everything else fails).

    Per-key configuration is granular. Each key has:

    • A name (free text — use it well, you’ll thank yourself later)
    • The API key value itself
    • An “Always use for this provider” toggle that disables OpenRouter’s pooled fallback entirely for calls routed through this key
    • Filters: Models (All, or a specific subset) and API Keys (All OpenRouter API keys, or a specific subset)

    The filter system is the part most teams miss. You can pin a BYOK key to specific OpenRouter API keys, meaning specific agents. Read that twice. It means a single BYOK key can be the routing target for exactly one agent’s calls, while every other agent on the workspace continues using pooled access.

    This unlocks a powerful pattern for agency work: a client who has their own enterprise contract with a model provider can have their work routed exclusively through that contract, billed to that contract, while your other clients use pooled pricing. The routing happens at the provider layer, invisibly to the calling code.

    Prioritization and fallback in practice

    Cost control gates for production routing
    Prioritization and fallback in practice.

    Here’s the order of operations OpenRouter uses when you call a model:

    1. Is there a Prioritized BYOK key for this provider, this model, and this calling key? Use it.
    2. If that key has “Always use for this provider” enabled, return any failure as-is. Don’t fall back.
    3. Otherwise, fall back to OpenRouter’s pooled access.
    4. If that fails too, try any Fallback BYOK keys configured for this provider.
    5. If everything fails, return the error.

    The “Always use for this provider” toggle is a sharp edge. Enabling it means a single failed enterprise contract — expired credentials, network issue at the provider, momentary rate limit — becomes a hard failure for every call routed through that key. Disabling it gives you graceful degradation but means your enterprise contract isn’t strictly enforced.

    Our pattern: enable “Always use” only for clients with hard data-policy requirements (no third-party touching of their data, ever). For everyone else, leave it disabled and let OpenRouter’s pooled access catch the failures.

    The Web Search slot (Firecrawl)

    The Providers tab has a second section that isn’t strictly BYOK: workspace-level Firecrawl integration. OpenRouter partnered with Firecrawl to provide 10,000 free credits per workspace, with a three-month expiry, contingent on accepting Firecrawl’s Terms of Service.

    This is wired at the workspace level, not per-key. Once accepted, any plugin that uses Web Search inherits the Firecrawl integration. Cheap, useful, easy to forget you enabled it.

    The mistake to avoid: assuming the 10,000 credits are forever. Three months. If you’re going to depend on this, plan for renewal.

    How to think about provider selection

    The temptation with dozens of providers is to spin up BYOK keys for every model you might ever want. Don’t.

    Start with three categories:

    Volume providers — the ones you call most. For us that’s Anthropic (Claude family) and Google (Gemini family). Worth getting BYOK keys for these even if you don’t have an enterprise contract; it makes the routing explicit and the costs auditable.

    Specialty providers — ones you call for specific jobs. We use OpenAI for some specific reasoning tasks. We use specialized model providers (Stepfun, others) for niche work. BYOK keys here only if you have a contract worth routing through.

    Experimental providers — everything else. Don’t bother with BYOK. Use OpenRouter’s pooled access. If a model from one of these providers becomes a regular part of your workflow, promote it to specialty.

    The audit story

    In March 2026 we ran a security audit on 122 Cloud Run services and discovered five of them had hardcoded OpenRouter keys in their environment variables — same key across all five. We stripped them, rotated, and re-scanned to zero.

    That was an OpenRouter key, not a BYOK provider key, but the lesson generalizes: API keys do not belong in environment variables on shared infrastructure. They belong in a secret manager with audited access. GCP Secret Manager, AWS Secrets Manager, HashiCorp Vault — pick one and use it.

    The standing rule we wrote afterward applies equally to BYOK provider keys: any key, any provider, any environment, lives in a secret manager. Period.

    Pinning keys to agents: the operational unlock

    The BYOK feature most teams underuse is the per-key filter system. You can configure a BYOK provider key to be used only by specific OpenRouter API keys.

    This sounds abstract until you map it to a real workflow:

    • Your content production agent runs through OpenRouter key A
    • Your customer support bot runs through OpenRouter key B
    • Your enterprise client has a contract with Anthropic and wants their work routed through that contract

    You create a BYOK Anthropic key for the enterprise contract. In the BYOK key’s filter, you specify “API Keys: only OpenRouter key C” (the key used by the agent serving that client). Now content production (key A) and customer support (key B) use OpenRouter’s pooled access. The enterprise client’s agent (key C) routes through the enterprise contract.

    No code changes. No service restarts. Just routing config at the provider layer.

    This is the kind of pattern that pays for OpenRouter’s existence in the stack. Most teams discover it only after they’ve outgrown a simpler setup. Start with it from day one if your shape looks anything like an agency.

    What to do today

    If you’re getting started with BYOK on OpenRouter:

    1. Identify the two or three providers you call most. Get BYOK keys for those.
    2. Store every key in a secret manager. Not in code. Not in env vars on shared infra.
    3. Use the per-key filter system from the start. Don’t let one BYOK key get used by every agent unless you actually want that.
    4. Leave “Always use for this provider” off unless you have a hard policy reason to enforce it.
    5. Set a calendar reminder for any time-limited credits (looking at you, Firecrawl).

    The BYOK system is one of the genuinely useful features on the platform. Treat it like the routing layer it is, not like a credentials dump, and it’ll pay for the setup time many times over.

    Frequently asked questions

    What is BYOK on OpenRouter?

    BYOK (Bring-Your-Own-Key) on OpenRouter means configuring direct provider credentials for any supported provider. OpenRouter then routes calls through your provider key instead of (or before falling back to) its pooled access. You can configure prioritization, fallback chains, and per-agent pinning.

    Should I use BYOK on OpenRouter even without an enterprise contract?

    For the providers you call most, yes. Even without a discount, BYOK makes the routing explicit and the costs auditable on your provider’s billing rather than buried in OpenRouter’s aggregate. For providers you barely call, don’t bother — OpenRouter’s pooled access is simpler.

    What does “Always use for this provider” actually do?

    It disables OpenRouter’s pooled fallback for any call routed through that BYOK key. If your enterprise contract fails for any reason — expired credentials, rate limit, network issue — the call returns the error instead of silently falling back to OpenRouter’s pool. Useful for hard data-policy requirements; risky for general reliability.

    Can I pin a BYOK key to specific agents?

    Yes. The per-key Filters section lets you specify which OpenRouter API keys (meaning which agents) can route through this BYOK key. This unlocks the pattern of running one client’s work through their enterprise contract while every other agent uses pooled access — all transparent to the calling code.

    How should I store BYOK provider keys?

    In a secret manager — GCP Secret Manager, AWS Secrets Manager, HashiCorp Vault. Never in environment variables on shared infrastructure. We learned this from a March 2026 audit that found five Cloud Run services with hardcoded keys baked into env vars. Standing rule now: any key, any provider, any environment, lives in a secret manager.

    See also: The Multi-Model AI Roundtable: A Three-Round Methodology for Better Decisions · What We Learned Querying 54 LLMs About Themselves (For $1.99 on OpenRouter)

    >Part of the complete guide: Working with the Anthropic API

  • OpenRouter Mental Model: The 5-Layer Hierarchy Explained

    OpenRouter Mental Model: The 5-Layer Hierarchy Explained

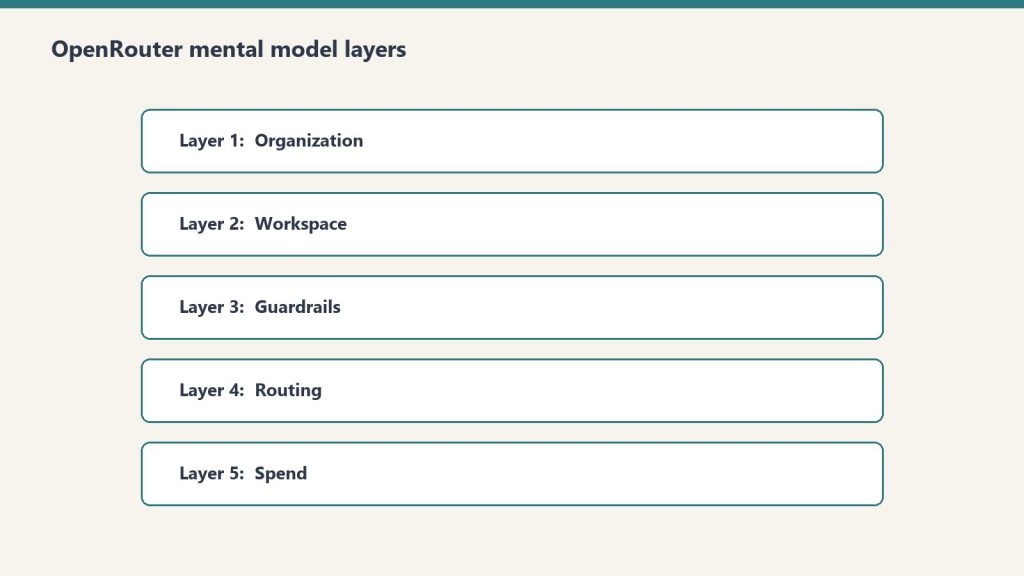
    The OpenRouter hierarchy in one sentence: Organizations contain Workspaces, Workspaces enforce Guardrails on API Keys, Keys call Presets, and Presets bundle prompts and models. Every operational decision you’ll ever make on the platform lives at exactly one of those five layers. Confuse them and you’ll spend hours looking for settings that live somewhere other than where you think.

    This is a companion to our OpenRouter operator’s field manual. The field manual covers why we use the platform and how it fits a fortress stack. This deep dive covers the mental model itself — the five-layer hierarchy that makes everything else legible.

    Why this matters before anything else

    Five stacked layers of the OpenRouter mental model
    Why the mental model matters before anything else.

    OpenRouter’s UI presents a flat menu. The actual product is a hierarchy. Every operational decision you’ll ever make — who pays, what’s allowed, who’s allowed to call what, which model gets used — lives at exactly one of five layers. Get the layers wrong and you’ll wire your stack against the wrong nouns.

    The five layers, top to bottom: Organization → Workspace → Guardrail → API Key → Preset.

    Here’s what each one actually does and when you should care.

    Layer 1: Organization

    Five operator layers: client, router, provider, model, policy/spend
    Organization and workspace layers.

    Sovereign billing. Sovereign member context. The top of the world.

    Each Organization has its own balance, its own billing details, and — critically — its own member roster. The catch: personal orgs don’t expose Members management. If you want to add teammates, you need a non-personal org.

    In our case we run two: a personal org tied to our primary email, and a Tygart Media org for agency operations. The personal org has 48 API keys and a working balance. The Tygart Media org is empty so far. Members management is the reason it exists.

    When to think about this layer: when you’re deciding whether to operate as an individual or as a team. If you’re solo and plan to stay solo, one personal org is fine forever. The moment you bring on a collaborator who needs their own keys and their own observability slice, you need a non-personal org.

    The mistake to avoid: running an agency out of a personal org. You’ll hit member-management limits at the worst possible time.

    Layer 2: Workspace

    Segmented guardrail, BYOK, routing, and preset domains inside an organization.

    By default, every org gets one Default Workspace. Most accounts never think about this layer. The moment you operate across multiple businesses with different data policies, multiple workspaces become valuable.

    Example: a healthcare client’s data should never touch first-party Anthropic, only Bedrock or Vertex. A consumer comedy site can use any provider. A B2B SaaS client wants Zero Data Retention enforced on every call. Three different fortress postures. Three workspaces.

    Each workspace gets its own Guardrail config, its own BYOK provider keys, its own routing defaults, and its own preset library. Keys created in one workspace can’t see resources in another.

    When to think about this layer: when you have two or more clients with materially different data policies. If everything you do has the same posture, one workspace is fine.

    The mistake to avoid: assuming workspace segmentation is a security boundary. It isn’t, exactly — it’s a policy boundary. Someone with org-level access can move between workspaces freely. Workspaces are for organizing intent, not for isolating threats.

    Layer 3: Guardrails

    Cost control gates for production routing
    Guardrails before routing.

    The actual enforcement layer. Four categories, all configurable per workspace, all unconfigured by default.

    Budget Policies are the most useful and the most underused. Set a credit limit in dollars and a reset cadence (Day, Week, Month, Year, or N/A). Hit the limit and calls fail until the cadence resets. This is your protection against the runaway loop that drains a balance overnight.

    Model and Provider Access is where data-policy posture lives. Toggles for Zero Data Retention enforcement, Non-frontier ZDR, first-party Anthropic on or off (with Bedrock and Vertex always staying available), first-party OpenAI on or off (Azure stays), Google AI Studio on or off (Vertex stays), and three categories of paid and free endpoints with different training and publishing behaviors. There’s also an Access Policy mode (Allow All Except is the useful one) with explicit Blocked Providers and Blocked Models lists. The live Eligibility view shows you which providers and models are actually callable given your current policy.

    Prompt Injection Detection runs regex-based detection on inbound prompts. OWASP-inspired patterns. Four modes: Disabled, Flag, Redact, or Block. Free and adds no measurable latency. Worth enabling on every workspace that touches user input.

    Sensitive Info Detection runs pattern matching on prompts and completions. Built-in patterns for Email, Phone, SSN, Credit Card, IP address, Person Name, and Address. The latter two add latency. Custom regex patterns supported. A sandbox to test patterns before deploying. Useful for any workspace that processes customer data.

    When to think about this layer: every workspace, day one. Default-unconfigured is not a safe state. Set a budget cap before you do anything else.

    The mistake to avoid: treating Guardrails as something you’ll get to “later.” Later is after the runaway loop has drained the balance.

    Layer 4: API Keys

    Per-agent identity. Each key has its own credit cap, its own reset cadence, and its own guardrail overlay.

    The mental model that matters: one autonomous behavior, one key. When a scheduled task starts hemorrhaging tokens, the cap on its key contains the damage. The other 47 keys keep working.

    Our 48-key distribution is instructive. One testing key has spent $83.26. One development key has spent $33.05. The remaining 46 keys have collectively spent less than $120. That’s the shape of real AI operations: a few keys do most of the work, and a long tail barely moves the needle. Per-key caps make that distribution visible and bounded.

    API keys also carry the BYOK relationship. A bring-your-own provider key can be pinned to specific API keys, meaning specific agents. That lets you route a high-volume internal agent through a discounted enterprise contract while letting one-off testing keys fall through to OpenRouter’s pooled pricing. We cover this in depth in BYOK on OpenRouter.

    When to think about this layer: when you create any new autonomous behavior. New behavior, new key, new cap. No exceptions.

    The mistake to avoid: sharing one key across all your services. The first runaway loop will be the last thing that one key ever does, and the blast radius will be everything else that depended on it.

    Layer 5: Presets

    Versioned bundles of system prompt, model, parameters, and provider configuration. Called as "model": "@preset/your-preset-name" in any API call.

    Three tabs per preset: Configuration (the actual bundle), API Usage (how it’s been called), and Version History (every change, rollback-able).

    This is the closest OpenRouter comes to a software release artifact. You can ship a preset, test it in chat, version it, and roll back if v2 turns out to be worse than v1. Code that calls the preset stays the same; only the preset content changes.

    For autonomous behavior systems this is the unlock. A behavior’s behavior — its prompt, its model choice, its temperature — becomes a thing you can version and review like code, without touching the code that calls it. Promotion ledger says a behavior is graduating from one tier to the next? You publish a new preset version with tighter constraints and the calling code never changes.

    When to think about this layer: the moment you have any system prompt that’s used in more than one place, or that you’ll want to refine over time. If you’ve never copy-pasted a system prompt between two scripts, you don’t need presets yet.

    The mistake to avoid: putting the system prompt in the calling code. Every prompt update becomes a deploy. With presets, prompt updates become config changes.

    Putting the layers together

    Here’s the mental model in one sentence: Organizations contain Workspaces, Workspaces enforce Guardrails on Keys, Keys call Presets, Presets bundle prompts and models.

    If you walk into OpenRouter looking for a setting and you can’t find it, ask which of the five layers it should logically live at. The answer almost always tells you where to look.

    If you’re building a new integration, start at the bottom. Pick a model. Build a preset around it. Create a dedicated key with a tight budget cap. Sit that key under a workspace with sensible guardrails. The organization is just the billing wrapper.

    The whole point of the hierarchy is that each layer constrains the one below it. The organization caps the workspace. The workspace caps the keys. The keys cap the presets they can call. Errors propagate up; permissions cascade down. That’s the model. Everything else is UI.

    Frequently asked questions

    What are the five layers of OpenRouter?

    Organization, Workspace, Guardrails, API Keys, and Presets. Organizations handle billing and members. Workspaces segment policy domains. Guardrails enforce budget, provider access, prompt injection, and sensitive info rules. API Keys are per-agent identity with per-key caps. Presets are versioned bundles of system prompt, model, and parameters.

    Do I need multiple Workspaces in OpenRouter?

    Only if you operate across businesses with materially different data policies. A single Default Workspace is fine for most accounts. The moment a healthcare client requires Bedrock-only access while a consumer client can use any provider, workspace segmentation becomes valuable.

    What is the right way to use OpenRouter Presets?

    Treat them like software release artifacts. Bundle the system prompt, model, parameters, and provider config. Version every change. Test new versions in chat before promoting. Code that calls the preset stays the same; only the preset content evolves. This lets you refactor prompt behavior without redeploying.

    Are OpenRouter Workspaces a security boundary?

    No. They’re a policy boundary, not a security boundary. Someone with organization-level access can move between workspaces freely. Use workspaces to organize intent and enforce different fortress postures across clients — not to isolate threats from each other.

    What happens if I don’t configure OpenRouter Guardrails?

    By default every workspace has zero enforced budget cap, zero provider restrictions, and zero PII filtering. That’s fine for prototyping. It’s not fine for production. Set a budget cap on every workspace as the first action. The other three guardrail categories you can configure as you scale.

    See also: The Multi-Model AI Roundtable: A Three-Round Methodology for Better Decisions · What We Learned Querying 54 LLMs About Themselves (For $1.99 on OpenRouter)

  • OpenRouter in Production: An Operator’s Field Manual

    OpenRouter in Production: An Operator’s Field Manual

    What OpenRouter actually is: A routing and policy layer that sits between your code and AI model providers. It replaces the place where you’d otherwise write direct API calls to Anthropic or Vertex AI, adding budget caps, guardrails, prompt-injection filtering, PII redaction, model fallbacks, and observability hooks — with access to hundreds of models behind one unified endpoint. It does not replace your memory system, your hosting environment, your operator console, or the models themselves.

    The 30-second version

    OpenRouter is one of the most useful AI infrastructure tools we’ve adopted, but the value lives at exactly one layer of the stack: the model-calling layer. It replaces the place where you’d otherwise write fetch("https://api.anthropic.com/...") or call Vertex AI directly. It does not replace your memory system, your hosting environment, your operating console, or the models themselves. Get that framing wrong and you’ll build a house of cards. Get it right and you’ve added budget controls, guardrails, observability, and hundreds of models with one config change per agent.

    This is how we use it across a stack that runs 27+ WordPress client sites, autonomous content pipelines, multi-model decision tools, and an autonomous behavior promotion system. None of this is theory. Every number in this article comes from our own usage logs.

    What OpenRouter actually is

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    What OpenRouter actually is — a router, not a model.

    Strip away the marketing and OpenRouter is a routing and policy layer for AI model calls. You point your code at one endpoint — openrouter.ai/api/v1/chat/completions — and OpenRouter handles model selection, provider fallback, budget enforcement, content filtering, and observability.

    It is not a model. It is not a runtime. It is not a database. It is a smarter middle layer between your code and the dozens of providers whose models you might want to call.

    The mistake we almost made early on was framing it as “replace GCP and Notion with this.” That framing is wrong in a specific way that’s worth naming: OpenRouter has no servers, no operational memory, no execution environment, no isolated network. It has hundreds of models behind one API and a thoughtful policy layer in front of them. That’s the entire product, and it’s enough — at the right layer.

    The 5-layer hierarchy nobody tells you about

    Five operator layers: client, router, provider, model, policy/spend
    The five-layer hierarchy nobody tells you about.

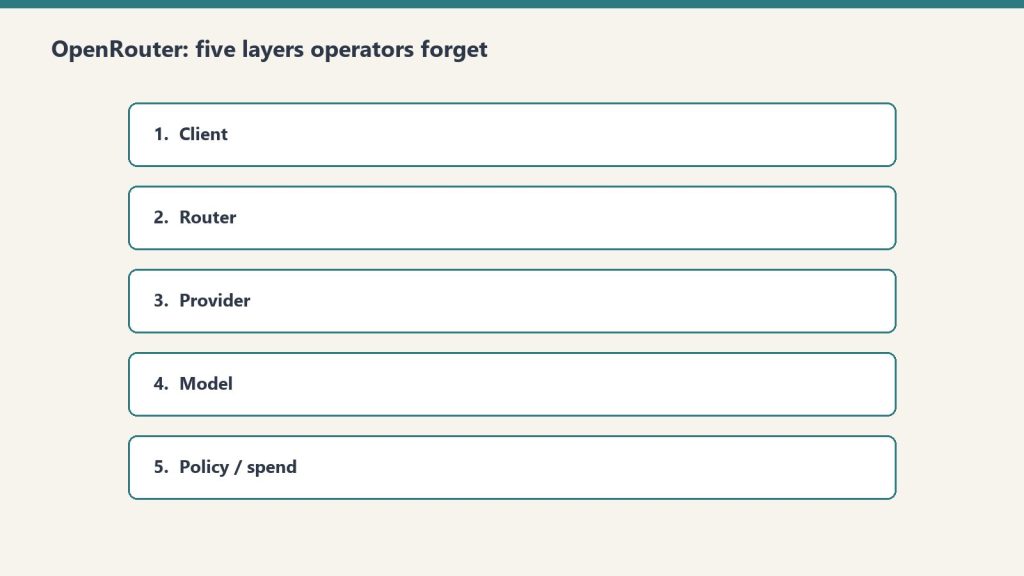
    When you log into OpenRouter, the UI presents a flat set of menus. The actual mental model — the one that maps to real operational decisions — is a five-layer hierarchy:

    Organization is the top. Sovereign billing and member context. We run two: one personal, one for Tygart Media. The personal org has 48 API keys and a balance; the Tygart Media org has empty balance but exposes Members management that personal accounts can’t access. If you’re operating as an agency, you want the agency org as primary so you can add seats.

    Workspaces sit inside organizations. They’re segmented domains for guardrails, BYOK provider keys, routing rules, and presets. Most accounts run on a single Default Workspace and never think about this layer. The moment you operate across multiple businesses with different data policies, workspace segmentation becomes a real decision.

    Guardrails are workspace-level enforcement policies. Four categories: Budget Policies, Model and Provider Access, Prompt Injection Detection, and Sensitive Info Detection. By default they’re all unconfigured, which means your workspace has no enforced budget cap, no provider restrictions, and no PII filtering. This is fine until it isn’t.

    API Keys are per-agent identity. Each key carries a credit cap, a reset cadence, and a guardrail overlay. The mental model that matters: one autonomous behavior = one API key. If a scheduled task starts hemorrhaging tokens, the cap on its key contains the damage to that key alone.

    Presets are versioned bundles of system prompt, model, parameters, and provider config. You call them as "model": "@preset/name" in any API call. They’re the closest thing OpenRouter has to a software release artifact — a thing you can version, test, and roll back.

    That hierarchy is the entire operational surface. Everything you’d want to do with the platform happens at one of those five layers. Confuse them and you’ll spend hours hunting for a setting that lives at a different tier than you think.

    What OpenRouter replaces (and what it doesn’t)

    The honest answer: OpenRouter replaces the direct API call. Nothing more, nothing less.

    In our case, every scheduled task, every skill that calls a model, every Claude Project — all of them used to make direct calls to Anthropic’s API or Vertex AI. OpenRouter sits in front of those calls and adds budget caps, guardrails, prompt-injection filtering, PII redaction, model fallbacks, observability hooks, and access to a model catalog of hundreds of options instead of the handful any single provider exposes.

    What it does not replace:

    Your memory system. Notion remembers; OpenRouter doesn’t. OpenRouter’s logs are call-level telemetry — what model was called, what it cost, what the response was. That’s not operational memory. It can’t tell you “this customer pitch was sent three weeks ago and got no response.” For that, you need a real second brain.

    Your hosting environment. OpenRouter has no servers, no WordPress, no database, no VPC. If you’re running a fortress architecture on GCP — VPC isolation, Cloud SQL, Cloud Run services — none of that goes away. OpenRouter sits next to that infrastructure, not in place of it.

    Your operator console. Wherever you actually do the work — Claude in chat, your terminal, your IDE — that surface stays. OpenRouter is a transport layer for model calls, not a place you live.

    The models themselves. OpenRouter is one path to reach Anthropic’s Claude; Vertex AI is another; the direct Anthropic API is a third. They’re interchangeable transports. The model is the model.

    Mapping OpenRouter to an autonomous behavior system

    Here’s where the framing gets interesting. We run an autonomous behavior system where every long-running task — a scheduled content pipeline, an SEO audit, a publishing job — sits on a promotion ledger that tracks its trustworthiness over time. Tier C behaviors run autonomously. Tier B requires a human in the loop. Tier A is proposal-only.

    OpenRouter maps to that system with almost no friction:

    • Each behavior becomes a versioned Preset — system prompt, model, parameters, all bundled and versioned.
    • Each preset is bound to its own API Key with a monthly credit cap and reset cadence.
    • That key sits under a Workspace whose Guardrail enforces the appropriate data policy.
    • Observability is broadcast to a webhook that writes back to the operational memory layer.

    The result: when a behavior misbehaves — hits its spend cap, trips a policy violation, gets blocked by Sensitive Info Detection — the failure is auto-logged at the routing layer and surfaced to the operator console. The promotion ledger row catches the gate failure and demotes the behavior automatically.

    This is the concrete answer to a question every operator running autonomous AI work eventually asks: how will I know when something goes wrong? The answer is: you build the routing layer so that going wrong is itself a signal.

    The 270/238 reality check

    A small piece of grounding before we go further. As of mid-May 2026, our personal OpenRouter org showed a balance of $31.93 remaining of $270 total credits purchased. That’s $238.07 of actual usage across roughly two months. Spread across 48 API keys, that’s an average of about $5 per key.

    The highest-spend key was a testing key at $83.26. The next was a development key at $33.05. Most keys had spent less than $1. That distribution tells you something true about real-world AI operations: a handful of behaviors do most of the work, and the long tail of agents barely registers.

    We mention this for one reason: if you’re evaluating OpenRouter, the cost is not the story. The cost is small. The story is whether the policy layer is worth wiring into your stack. Our answer is yes — but the work of wiring it is real, and it requires you to first understand what layer you’re wiring.

    The Cloud Run reality

    One real-world note that any production team needs to internalize: when we ran AI calls from Cloud Run services on GCP, we occasionally hit 402 responses from OpenRouter that we did not hit when calling Anthropic’s API directly from the same services. We don’t have conclusive evidence of where the issue originated — Cloud Run’s egress IP ranges are widely shared and trip fraud-detection thresholds at many providers, including direct calls to first-party APIs. The lesson is not about OpenRouter specifically. The lesson is that production routing requires deployment-context testing.

    Our policy now: for services where reliability is mission-critical, we maintain a fallback path that can switch routing layers under failure. OpenRouter is the default. Direct Anthropic is the fallback. The decision logic lives in the service itself, not in OpenRouter’s config. This is defense in depth, not a critique of any one provider.

    The standing rule we wish we’d had earlier

    Cost control gates for production routing
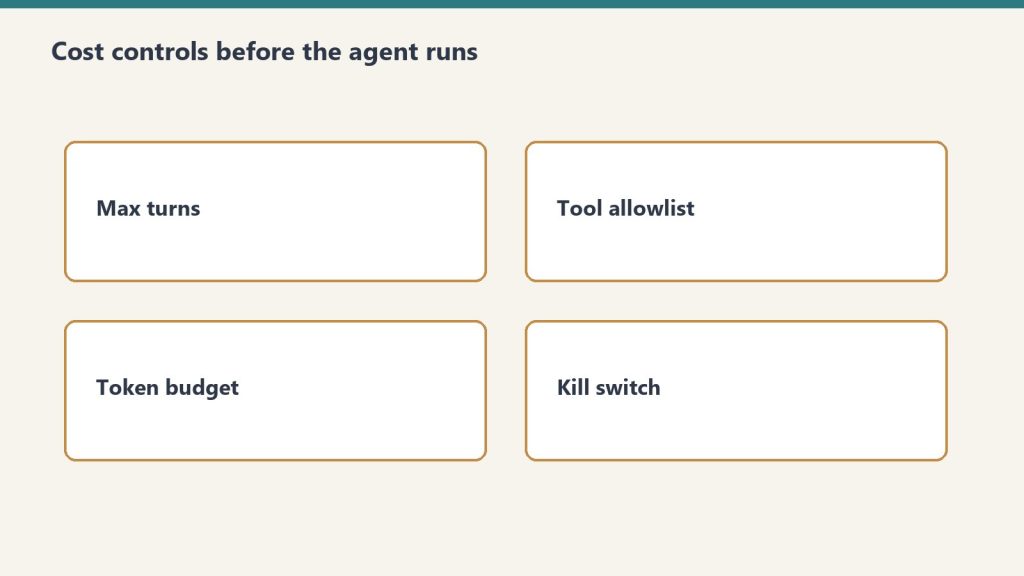
    The standing rule we wish we had earlier: budgets before routing.

    In March 2026 we ran a security audit on 122 Cloud Run services and discovered five of them had hardcoded OpenRouter API keys baked into environment variables — all sharing the same key. We stripped the keys, rotated, and re-scanned to zero. Then we wrote a standing rule into operational memory:

    OpenRouter is off-limits for any task without explicit per-task permission. Image generation always goes through Vertex AI.

    The reason for the second half of that rule deserves naming. Image generation via OpenRouter is technically possible, and the model variety is appealing. But image calls are expensive, latency-sensitive, and easy to fire by accident in a loop. One misconfigured behavior can drain a development budget in a single session. Vertex AI’s first-party image generation runs through GCP service accounts with project-level budget alerts, which gives us a natural circuit breaker. We use OpenRouter for the right jobs. We use Vertex for image work.

    This is the kind of operational rule you only write after you’ve lost money to a runaway script. Save yourself the lesson.

    When OpenRouter is the right answer

    Use OpenRouter when:

    • You want model variety and a unified API across providers
    • You need workspace-level budget caps that work across many keys
    • You want PII detection and prompt-injection filtering at the routing layer instead of in every service
    • You need observability broadcast to your existing stack (we ship to webhooks)
    • You’re running an autonomous behavior system that needs per-agent identity and per-agent budget enforcement
    • You want the option to swap models without redeploying code

    When it isn’t

    Don’t reach for OpenRouter when:

    • You only call one model from one app and don’t need policy enforcement
    • You need single-digit-millisecond latency (the extra hop matters)
    • You’re running image generation at scale (use the first-party provider directly)
    • You need network isolation guarantees that only your own infrastructure can provide
    • You’re deploying from an environment with shared egress IPs to a provider that flags those ranges (test first)

    The bottom line

    OpenRouter is excellent at exactly one thing: being a thoughtful policy layer between your code and the AI models you call. Don’t ask it to be more than that. Don’t replace your memory, hosting, console, or models with it. Wire it into the model-calling layer of an existing system that already has those other pieces sorted, and you get budget controls, guardrails, observability, and hundreds of models with about a day’s worth of integration work.

    The framing that works: the model layer of an existing system. Not the system itself.

    If you’re operating multiple autonomous AI behaviors and you don’t yet have per-agent budget caps and per-agent observability, OpenRouter is probably the fastest path to getting them. If your stack is one app calling one model, you’re paying for complexity you don’t need yet.

    Going deeper

    This pillar is the operator’s overview. Each of the five layers and the major workflows we built on top of OpenRouter has its own deep dive:

    Frequently asked questions

    What is OpenRouter and what does it do?

    OpenRouter is a routing and policy layer for AI model API calls. It sits between your application code and AI providers like Anthropic, OpenAI, and Google, providing one unified API endpoint that handles model selection, budget enforcement, guardrails, fallback routing, and observability across hundreds of models from dozens of providers.

    Does OpenRouter replace direct Anthropic or OpenAI API calls?

    Yes, that’s exactly what it replaces. Your code calls one endpoint (openrouter.ai/api/v1/chat/completions) instead of provider-specific endpoints. The model is selected via a parameter rather than the URL. Everything else about your stack — your memory system, hosting, and operator console — stays the same.

    Can OpenRouter replace GCP, Notion, or my hosting infrastructure?

    No. OpenRouter is a routing layer for model calls. It has no servers, no database, no operational memory, and no network isolation. If you’re running a fortress architecture on GCP with VPC isolation, Cloud Run services, and Cloud SQL, OpenRouter sits alongside that infrastructure, not in place of it.

    How expensive is OpenRouter in practice?

    For most operational workloads the platform fee is negligible compared to the underlying model costs. Our personal organization spent $238 over roughly two months across 48 API keys serving multiple autonomous behaviors. The distribution is heavily skewed — a few keys do most of the work, and the long tail barely registers. Cost is rarely the decision factor; the policy layer is.

    What is the right way to think about OpenRouter API keys?

    One autonomous behavior, one key. Each key gets its own credit cap and reset cadence. When a scheduled task starts hemorrhaging tokens, the cap on its key contains the damage to that key alone. Sharing one key across all services is the single fastest way to lose visibility and bound risk.

    Should I use OpenRouter for image generation?

    We don’t. Image generation runs through first-party providers (Vertex AI in our case) where project-level budget alerts give a natural circuit breaker. Image calls are expensive, latency-sensitive, and easy to fire by accident in a loop. The routing layer is for text-completion workloads where the policy benefits compound.

    What’s the deal with Cloud Run and OpenRouter 402 errors?

    Cloud Run egress IP ranges are widely shared, and they sometimes trip fraud-detection thresholds at various providers — including direct calls to first-party APIs, not just OpenRouter. The lesson is that production routing requires deployment-context testing. Maintain a fallback path that can switch routing layers under failure, and you’ve got defense in depth instead of a single point of failure.

  • GEO Case Studies: Teardown of 5 Published AI Search Wins

    GEO Case Studies: Teardown of 5 Published AI Search Wins

    If you want to know whether generative engine optimization actually moves the needle, stop reading think pieces and look at what shipped. The case-study record from 2025 and early 2026 is now thick enough to draw practitioner conclusions: which interventions correlate with citation lift, how fast the curve bends, and what the conversion side of the funnel does once AI traffic shows up. This is a working teardown of the published case studies — what was done, what changed, and what the implementation pattern looks like underneath.

    Case 1: B2B SaaS — 575 to 3,500 AI-referred trials in roughly seven weeks

    GEO versus SEO comparison cards
    GEO case teardown — B2B SaaS AI-referred trials.

    A $30M+ ARR B2B SaaS company documented in Digital Agency Network’s GEO case study roundup moved from 575 AI-referred free trials per period to over 3,500 in about seven weeks. The intervention sequence was content restructuring for citability — clear one-sentence definitions at the top of each section, statistics and comparisons rendered as tables rather than buried in prose, and step-by-step frameworks that LLMs can extract verbatim. The first 40–60 words under every H2 carried the answer to that H2’s implicit question.

    The implementation pattern under this win is what matters: the company did not write new articles. It rebuilt existing articles to surface the answer first. That is the cheapest possible GEO intervention — restructure, do not republish.

    Case 2: B2B SaaS — citation rate from 8% to 12% in four weeks

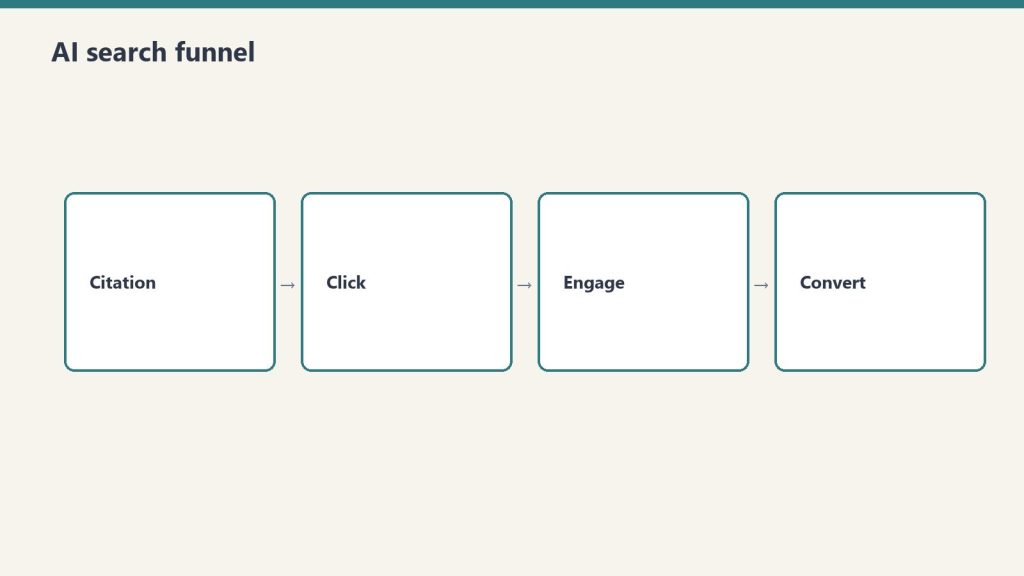
    Four-stage funnel: citation, click, engage, convert
    Citation-rate lift case — four weeks.

    Discovered Labs documented a B2B SaaS case where ChatGPT citation rate on tracked queries moved from 8% to 12% by week four of an engagement, with the company’s VP of Marketing noting they had been “invisible for 18 months despite solid SEO work.” The 50% relative lift came from the same restructuring pattern plus aggressive entity-binding — explicit company name, product name, and category definition repeated in citation-friendly positions throughout each asset.

    The data point worth carrying: traditional SEO authority does not automatically translate to LLM citation. The two systems read pages differently, and the page-level rewrite is what closes the gap.

    Case 3: CloudEagle — 33 pages optimized, 33% increase in AI citations

    CloudEagle’s published GEO result, cited across multiple 2026 case study summaries including AlphaP’s real-world GEO examples, is one of the cleanest dose-response curves in the public record. Optimize 33 pages → 33% increase in AI citations. The ratio is suspicious as a coincidence but tells the practitioner the right thing: GEO is a per-page intervention, and aggregate lift scales roughly with how many pages you treat. There is no site-wide tag you can flip. Each asset gets its own restructure.

    Case 4: HubSpot — template rebuild, not content rebuild

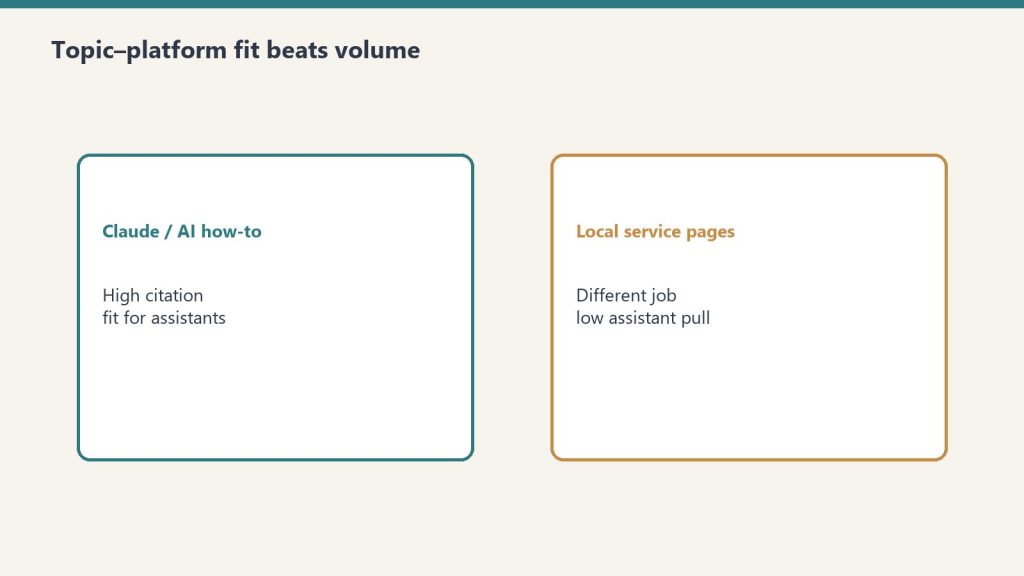
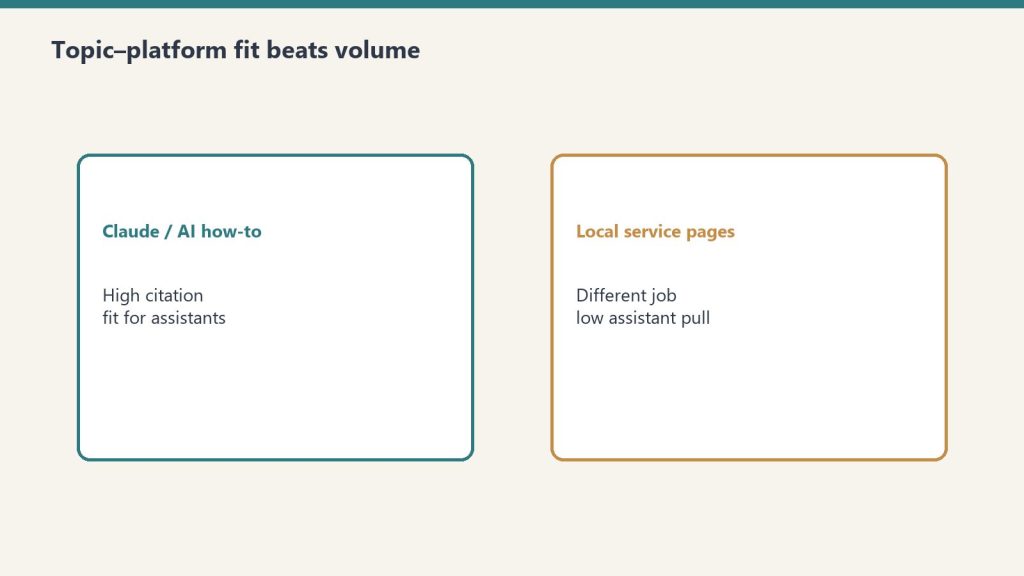
    Comparison of Claude how-to fit versus local service page fit for assistants
    HubSpot — template rebuild, not content rebuild.

    HubSpot’s internal AEO case study, summarized in HubSpot’s own AEO case study writeup, is the cleanest illustration of the structural fix. HubSpot already ranked for thousands of marketing queries — the volume was there. The barrier was that answers were buried multiple paragraphs deep, written in traditional long-form. The fix was a template rebuild: every article restructured so the first 40–60 words under each H2 or H3 directly answered the implicit question of that heading.

    This is the playbook to copy. If your site has any existing traffic, restructuring beats writing new content. The audit question is: under every H2 on every page, do the first three sentences answer the question that H2 raises?

    Case 5: Netpeak USA — 120% revenue lift, 693% AI traffic growth

    Stackmatix’s AEO case study compilation documents Netpeak USA’s conversational ecommerce GEO campaign producing +120% revenue and +693% AI traffic growth. The mechanism: product and category pages restructured around buyer questions (“what is the best X for Y?”, “X vs Y comparison”, “how do I choose X?”) with direct, hedged answers up top and detailed reasoning below. The pattern works because AI search engines synthesize buying decisions from extractable answer fragments, and ecommerce pages historically bury the answer under marketing copy.

    The structural pattern under every win

    Read the five cases together and one implementation discipline emerges. Every published GEO win in the public record traces back to the same physical change to the page:

    1. Answer first. The first 40–60 words under every H2 directly answer the question that heading raises. No setup, no transition paragraph, no scene-setting.
    2. Tables over prose for comparison data. Articles with 15+ data points receive measurably more AI citations than those with fewer than five, per the research synthesized in Marketing LTB’s 2026 GEO statistics roundup. Tables make those data points extractable.
    3. Entity binding. Company name, product name, and category definition explicitly stated in citation-friendly positions, not just implied through context.
    4. Stepwise frameworks. Procedural content rendered as numbered steps that LLMs can extract verbatim into responses.
    5. Citable sources inline. Authoritative external citations placed adjacent to claims, not banished to a references section at the bottom.

    What the cases do not prove

    The published record has selection bias the size of a building. Every case study you can read is a published win. The agencies and SaaS companies that ran a GEO campaign and got nothing are not writing blog posts about it. Read the cases for the structural patterns, not the percentage lifts — the lifts are a function of starting baseline, vertical, and how invisible the brand was before the intervention.

    Two other limits worth naming. First, conversion-rate claims about AI-referred traffic (“converts at a higher rate than organic” appears in over half of marketer surveys per the 2026 HubSpot State of Marketing report) come from self-reporting, not third-party measurement. The directional point is probably right — qualified intent behind an LLM query — but the magnitude is unverifiable. Second, AI citation rates are measured against the agencies’ own tracked query sets. Those sets are chosen for relevance to the client, which means baseline visibility is artificially low. The 8% → 12% case is real; whether it generalizes to a random query set is unknown.

    What to do tomorrow if you are starting from zero

    Pick ten pages on your site that already rank in positions 4–15 for queries with commercial intent. Open each one. Under every H2, rewrite the first 40–60 words so they directly answer the question that heading raises. Convert any prose comparison into a table. State your company name, product category, and the specific problem you solve in the opening paragraph. Add a sources list with authoritative citations.

    That is the intervention every published GEO case study reduces to. Ten pages, one week of writing work. The case study record suggests you will see citation movement in three to six weeks if the queries you care about already have AI Overview or LLM citation surface area at all. If they do not, the intervention is still right — you are positioning for when they do.

    FAQ

    How long until GEO interventions show measurable lift?

    Published cases show citation movement at the four-week mark (the 8% → 12% B2B SaaS case) and traffic movement at six to eight weeks (the 575 → 3,500 trials case at roughly seven weeks). Three months is the standard window quoted in agency case studies for material citation rate change.

    Does traditional SEO authority help GEO?

    Partially. Pages that already hold featured snippets are disproportionately pulled into Google AI Overviews, per multiple 2026 AEO summaries. But the B2B SaaS case where the company was “invisible for 18 months despite solid SEO work” shows that authority alone does not produce citations — page-level structural changes are the missing ingredient.

    How many pages do I need to optimize before I see results?

    CloudEagle’s case (33 pages → 33% citation lift) suggests the dose-response is roughly linear at small scale. Most published case studies show meaningful aggregate movement starting around 10–30 pages restructured. Below that, you are testing the methodology rather than expecting measurable lift.

    Is the citation rate lift actually translating to revenue?

    The published evidence says yes for ecommerce (Netpeak USA’s +120% revenue) and trial-driven SaaS (the 575 → 3,500 trials case). For brand and consideration-stage content the answer is murkier — AI citations probably influence brand recall and assisted conversion, but the attribution chain to revenue is harder to draw cleanly and the case study record is thin on this slice.

    What is the cheapest GEO intervention with the highest published return?

    Restructuring existing pages that already rank. The HubSpot template rebuild and the 575 → 3,500 trials case both used this approach. No new content, no new authority work, no link building — just rewriting the first 40–60 words under every H2 and converting prose comparisons into tables.

    Related on Tygart Media: GEO case studies 2026 · GEO tactics · chunk-first GEO.

  • Measure LLM Visibility: The GA4 & Response-Side Stack

    Measure LLM Visibility: The GA4 & Response-Side Stack

    Traditional analytics platforms can’t see the most important impression you’re making in 2026. When a user asks ChatGPT, Perplexity, Gemini, or Claude about your category, your brand either shows up in the answer or it doesn’t — and your GA4 dashboard has no idea either way. This is the measurement blind spot at the center of generative engine optimization. If you can’t measure LLM visibility, you can’t optimize for it.

    This guide walks through the measurement stack that actually works in 2026: the GA4 channel grouping that catches AI referral traffic, the manual verification protocol that costs nothing, and the dedicated LLM visibility platforms that automate prompt monitoring at scale. By the end, you’ll have a measurement framework you can run starting today.

    Why GA4 alone is not enough

    Four-stage funnel: citation, click, engage, convert
    Why GA4 alone is not enough.

    Standard web analytics measures what happens after the click. LLM visibility is what happens before the click — or instead of one. According to widely cited industry reporting, a large share of AI search sessions end without the user ever clicking through to a source, which means the brand impression inside the AI response is often the only impression you get. GA4 cannot see that impression. It cannot see when ChatGPT recommends you in a comparison. It cannot see when Perplexity cites your article as a source for an answer.

    You still need GA4 — AI referral traffic is real, growing, and converts well — but you need it as one layer of a two-layer stack. Layer one is referral-side measurement, which captures the users who actually click through from AI platforms. Layer two is response-side measurement, which monitors what AI platforms are saying about you whether anyone clicks or not.

    Layer one: catching AI referrals in GA4

    Topic platform fit visual for first-party AI citation measurement
    Catching AI referrals in GA4.

    GA4 does not have a built-in “AI” channel. By default, traffic from ChatGPT, Perplexity, Claude, and Gemini gets bucketed into the generic Referral channel, where it disappears next to social and partner sites. The fix is a custom channel group that uses a referrer regex to peel AI traffic out into its own bucket.

    In GA4, go to Admin → Data Settings → Channel Groups, create a custom channel group, and add a new rule above the default Referral rule. Set the conditions to Source matches regex and use a pattern like this:

    chatgpt\.com|openai\.com|perplexity\.ai|claude\.ai|anthropic\.com|gemini\.google\.com|copilot\.microsoft\.com|deepseek\.com|you\.com|meta\.ai|poe\.com

    The order matters. Your AI Traffic rule must sit above the Referral rule in the priority list, or AI traffic will be captured by Referral first and never reach your custom channel. Once the rule is live, you can build Explorations that segment AI traffic by source, page, conversion rate, and engagement time — and compare that segment against organic, direct, and social.

    The referrer attribution gap

    One caveat: not every AI click passes a referrer. ChatGPT’s free tier in particular has been reported to strip referrer headers in many configurations, meaning a meaningful share of ChatGPT traffic shows up as Direct in GA4 rather than as a chatgpt.com referral. This is a known limitation across the industry. Treat your AI referral numbers as a floor, not a ceiling, and use response-side monitoring to fill in the gap.

    Layer two: response-side monitoring

    This is the measurement that traditional SEO never needed. You’re no longer just asking “did anyone visit?” — you’re asking “what is the AI saying about me?” There are two ways to answer that question.

    The manual verification protocol

    The free, no-tool approach is a structured query log. Build a list of 15 to 25 prompts that a buyer in your category would realistically type into an AI assistant. Be specific. “Best CRM for small B2B teams” is a prompt. “What is a CRM” is not — that’s a research query, not a buyer query.

    Once a week, run every prompt through each AI platform you care about — typically ChatGPT, Perplexity, Gemini, and Claude — and record three things per query: whether your brand was mentioned, whether your domain was cited as a source, and what position your brand appeared in if it was named alongside competitors. A simple spreadsheet with prompt, date, platform, mention (yes/no), citation (yes/no), and position is enough to start. Week-over-week deltas on this sheet will tell you whether your GEO and AEO work is moving the needle.

    This is slow and manual but it’s the only method that gives you ground truth. The dedicated platforms below are essentially automating this protocol — running the same kind of prompt log against the same APIs on a daily schedule. If you’re under $1,000/month in marketing spend, run it manually. If you’re past that, automate it.

    Dedicated LLM visibility platforms

    A new category of tools emerged in 2025 and matured in 2026 specifically to monitor LLM responses. They all do roughly the same thing — run your target prompts daily across multiple AI engines, score visibility, track which sources the AIs cite, and surface competitor gaps — but they segment by price point.

    At the budget end, Otterly.AI offers monitoring plans starting around $29/month, with a Share of AI Voice metric and time-to-first-data of under ten minutes after signup. It’s the simplest entry point for teams that just want a citation-frequency dashboard. In the mid-market, Peec AI starts around €89/month and emphasizes multilingual coverage and actionable recommendations — it doesn’t just tell you you’re invisible, it suggests what to change. At the enterprise tier, Profound starts around $499/month and adds Prompt Volumes, which estimates real AI search demand by topic with demographic breakdowns. SOC 2 compliance and dedicated onboarding generally start at the $1,000+ enterprise tiers across this category.

    Other platforms in active use this year include Semrush’s AI Toolkit, SE Ranking’s SE Visible, Goodie AI, Rankscale, Nightwatch, AirOps, and Searchable. The category is moving fast — pricing and features change quarterly — so verify the current state of any platform before committing.

    The six KPIs to track

    Whatever measurement stack you use, the same handful of metrics will tell you whether GEO is working. Organize them into leading and lagging indicators:

    Leading indicators (response-side, change first):

    • Mention Rate — the percentage of monitored prompts where AI responses mention your brand name. This is the broadest signal.
    • Citation Rate — the percentage of monitored prompts where your domain is cited as a source, not just named. Citation is stronger than mention because it implies the AI is treating your content as authoritative.
    • Position — when your brand is named alongside competitors, where in the list does it appear. First-named brands get disproportionate attention.

    Lagging indicators (referral and revenue-side, change later):

    • AI Referral Sessions — total sessions from your AI Traffic channel group in GA4.
    • AI Referral Engagement — engagement rate and average engagement time for the AI segment, compared to organic. Strong AI referral traffic typically engages longer because the user arrived with intent already framed by the AI.
    • AI-Influenced Conversions — conversions where AI was part of the attribution path, even if not the last touch.

    Tier-one metrics move first because content changes affect what AIs say within days to weeks. Tier-two metrics lag because they require enough traffic to be statistically meaningful, which can take a quarter or more to develop.

    The minimum viable setup

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The minimum viable setup.

    If you do nothing else this week, do these three things:

    1. Add the AI Traffic channel group to GA4 using the regex above and move it above Referral in priority.
    2. Build a 15-prompt spreadsheet of buyer-intent queries for your category and run them once across ChatGPT, Perplexity, Gemini, and Claude. Record mention, citation, and position.
    3. Set a calendar reminder to repeat step two every Friday for four weeks. After four weeks you’ll have a real trendline.

    That setup costs nothing and produces the measurement layer that lets you tell whether your GEO, AEO, and LLMs.txt work is actually compounding — or whether you’re guessing. Once the trendline is stable, evaluate whether automating with Otterly, Peec, or Profound is worth the spend. For most operators, the manual protocol gets you 80% of the insight at 0% of the budget.

    Related on Tygart Media: LLM visibility measurement · citation monitoring · Bing Webmaster AI tab.

    Frequently Asked Questions

    What is LLM visibility?

    LLM visibility is the measurement of how often, and how prominently, a brand or website appears in responses generated by large language models like ChatGPT, Perplexity, Gemini, and Claude. It is the response-side counterpart to traditional search ranking — instead of measuring where you appear in a results page, you’re measuring whether AI assistants mention or cite you when answering questions in your category.

    Can GA4 track AI traffic from ChatGPT and Perplexity?

    GA4 can track AI referral clicks if you create a custom channel group with a referrer regex matching AI domains and place it above the default Referral rule. It cannot track impressions inside AI responses where the user doesn’t click through, and ChatGPT’s free tier often strips referrers entirely, so a portion of AI traffic still lands in Direct. Treat GA4 numbers as a floor.

    What is the difference between mention rate and citation rate?

    Mention rate measures the percentage of monitored AI prompts where your brand name appears anywhere in the response. Citation rate measures the percentage where your specific domain or URL is referenced as a source. Citation is a stronger signal because it indicates the AI is treating your content as authoritative, not just naming you in passing.

    Which LLM visibility tool should I use in 2026?

    For budget-conscious teams, Otterly.AI starts around $29/month and gets you to first data in minutes. For mid-market needs with multilingual coverage and recommendations, Peec AI starts around €89/month. For enterprise teams that need prompt-volume demand data and SOC 2 compliance, Profound starts around $499/month. Verify current pricing before purchasing — the category moves quickly.

    How often should I check my LLM visibility?

    For manual tracking, weekly is the right cadence — frequent enough to catch movement, infrequent enough to avoid noise. Dedicated platforms typically run automated checks daily and let you review weekly. Don’t expect day-to-day stability; AI responses have inherent variance, so look at week-over-week and month-over-month trends rather than single data points.

  • Deploying Claude at Scale: Limits & Architecture (2026)

    Deploying Claude at Scale: Limits & Architecture (2026)

    Last refreshed: September 26, 2026

    Direct Answer (September 2026): Deploying Claude at scale means managing three limits: context windows (1M tokens on Fable 5.1, Opus 5.5, and Sonnet 5; 200K on Haiku 4.5 — 500K in web chat on paid plans), file upload caps in chat interfaces, and tiered API rate limits. Prompt caching cuts repeated-context costs by up to 90%, and the Batch API halves token prices for async work.

    Claude usage limits at scale - context window, file size, team seats, extra usage
    Once you stop asking what Claude is and start asking how to use it at scale, the limits become the conversation.

    Once you stop asking “what is Claude” and start asking “how do I use Claude at scale,” you run into a different category of question. How big is the context window, actually, in this specific situation? What’s the file upload limit? What happens when one teammate burns through the Team plan? Where does the 1M context window apply and where doesn’t it? When does extra usage kick in and what does it cost?

    The answers exist — they’re just spread across a dozen Anthropic Help Center articles, and the wrong combination of guesses can make you think you’ve hit a hard limit when you’ve actually just hit the wrong setting. This article is the consolidated map. Triple-sourced against Anthropic’s official documentation, verified September 26, 2026.

    Claude Usage Limits by Plan (September 2026)

    Workshop fuel gauge and metal tokens pouring into an API hopper, metaphor for pay-per-token pricing
    Usage limits — per-user, not pooled.

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 5 / 4.8 $5/$25, Sonnet 4.6 $3/$15. Rows below that still name Sonnet 4.6 or Opus 5 / 4.8 are legacy-or-prior availability figures — confirm live Anthropic limits before quoting TPM/RPM/context.

    Plan Messages/Day Context Window File Upload Projects
    Free Limited (varies) 200K tokens Up to 10MB per file No
    Pro ($20/mo) ~2,000 (Sonnet) 1M tokens (Fable 5.1 / Opus 5.5 / Sonnet 5) Up to 30MB per file Yes
    Max 5x ($100/mo) ~10,000 (Sonnet) 1M tokens Up to 30MB per file Yes
    Max 20x ($200/mo) ~40,000 (Sonnet) 1M tokens Up to 30MB per file Yes
    Team ($25/seat/mo) ~2,000/seat 1M tokens Up to 30MB per file Yes
    API (pay-per-token) Rate-limited by tier 1M tokens (Fable 5.1 / Opus 5.5 / Sonnet 5) Per API limits Via system prompt

    Message limits are approximate and vary by model. Anthropic adjusts limits based on system load. Verified September 26, 2026.

    The four limits that matter most

    Infographic with three panels: protect the service, fair share, and cost control explaining rate limits
    The four limits that matter most.

    If you’re running Claude in any sustained capacity, four limits will define your experience. Get these right and you have headroom. Get them wrong and you’ll think Claude is broken when it’s actually working as designed.

    1. Context window — how much Claude can read in a single conversation. Varies by model and surface. The 1M window is real but only available in specific places.

    2. File upload size — how big a single file can be. 30 MB cap per file across the board, with workarounds for larger files.

    3. Usage limits — how much Claude work you can do per session/week. Per-user, not pooled. Different limits for chat vs Claude Code vs Agent SDK.

    4. Extra usage / overage — what happens when you hit the cap. Either you’ve enabled it and you keep going at API rates, or you’re stopped until the limit resets.

    Context window: where 1M tokens actually applies

    Diagram comparing a long context window bar with a shorter output limit bar
    Context window — where 1M tokens applies.

    Per Anthropic’s Help Center documentation (verified September 26, 2026), context window size depends on the model AND on the surface you’re using Claude through. This is the single most-misunderstood limit because the same model can have a different context window in chat than it does in Claude Code or the API.

    Web and desktop chat (claude.ai):

    • Opus 5.5, Opus 5, Sonnet 5 — 500K tokens on all paid plans
    • All other models — 200K tokens on paid plans

    Claude Code:

    • Opus 5.5 — 1M tokens on Pro, Max, Team, and Enterprise
    • Sonnet 5 — 1M tokens on all paid plans, but extra usage must be enabled to access it (except on usage-based Enterprise plans)

    Claude API:

    • Opus 5.5, Opus 5, Sonnet 5 — 1M tokens at standard pricing (no long-context premium)
    • All other models — 200K tokens

    The practical translation: if you need the full 1M token window, use Claude Code or the API with one of the supported models. The web chat tops out at 500K even on the most capable models. That difference matters when you’re trying to feed Claude an entire codebase, a long video transcript, or a multi-document research bundle.

    File upload size: 30 MB per file, with workarounds

    Per Anthropic’s Help Center, the maximum file size for both uploads and downloads is 30 MB per file. This applies whether you’re uploading a PDF, a CSV, an image, or any other supported file type.

    For PDFs larger than 30 MB, Anthropic’s documentation notes that Claude can process them through its computing environment without loading them into the context window. That’s a real workaround for big PDFs but it doesn’t help you for other large file types.

    If you regularly hit the 30 MB cap, the practical patterns are:

    • Split before upload — break the file into chunks under 30 MB, upload each, work with them as separate sources
    • Convert format — a 35 MB Word doc with embedded images may compress to under 30 MB as a PDF; CSVs can often be reduced by removing unused columns
    • Upload to GCS or S3 and let Claude read via tools — for the Agent SDK / API path, you can put the file in cloud storage and have Claude read it via web fetch or a custom tool, bypassing the upload cap entirely

    Usage limits: per-user, not pooled

    This is the limit that confuses teams the most. Per Anthropic’s Help Center documentation on the Team plan (verified September 26, 2026): each team member has their own set of usage limits. They are not shared across the team.

    If one teammate burns through their session limit, the rest of the team is unaffected. There is no pooled team allowance that one user can drain on behalf of others. The math is per-seat, always.

    The usage limits themselves vary by seat type:

    • Standard Team seats — 1.25x more usage per session than Pro plan. One weekly usage limit applies across all models. Resets seven days after the session starts.
    • Premium Team seats — 6.25x more usage per session than Pro plan. Two weekly limits: one across all models, plus a separate one for Sonnet models specifically. Both reset seven days after session start.

    For the actual numeric token-per-session limits, Anthropic does not publish exact numbers — they describe relative multipliers vs Pro. This is intentional; the underlying math is calibrated against typical workloads rather than a hard token ceiling.

    Extra usage: what happens when you hit the cap

    When a user hits their weekly limit, two things can happen depending on whether the organization has enabled extra usage:

    If extra usage is enabled: additional Claude requests continue to flow at standard API rates (the same per-token pricing published on Anthropic’s pricing docs — $10/$50 MTok for Fable 5.1, $5/$25 MTok for Opus 5 / 4.8 (legacy — still listed), $2/$10 for Sonnet 5, $1/$5 for Haiku 4.5). Extra usage is billed separately from the subscription. Team and Enterprise admins can enable, cap, and monitor extra usage at the organization level.

    If extra usage is not enabled: the user’s Claude requests stop until their limit resets at the start of the next session window (seven days from when the current session started, not a fixed weekly day).

    The right setting depends on your team’s tolerance for surprise bills versus interrupted workflows. Most production teams enable extra usage with a hard organizational cap so individual users have continuity but the org has predictable spend ceiling.

    Claude Code limits: a separate model

    Claude Code has its own usage limit accounting that exists alongside chat usage limits. Per Anthropic’s Help Center on Claude Code models, usage, and limits (verified September 26, 2026):

    • Interactive Claude Code (typing in terminal/IDE) draws from your subscription’s usage limits, the same pool as web chat
    • Non-interactive claude -p mode currently also draws from subscription usage limits — until June 15, 2026
    • Starting June 15, 2026, non-interactive mode and Agent SDK usage move to a separate per-user monthly Agent SDK credit pool

    The June 15 change is important enough that it gets its own breakdown in our Agent SDK Dual-Bucket Billing article. The short version: if you’re running unattended Claude Code work in cron jobs or CI, your billing model is changing. Plan capacity against the new credit pool.

    The limits that aren’t really limits

    Three things that get reported as limits but are actually configuration choices:

    “My context window keeps filling up.” This is usually caused by long-running conversations accumulating history rather than the model’s actual context window being too small. Starting a new conversation (or running /clear in Claude Code) resets the working context. Long sessions are not a hard limit; they are a working-memory pressure that compounds over turns.

    “Claude won’t read my whole repository.” Repository size is rarely the actual limit; the limit is how much you can load into the context window at once. Tools like Claude Code’s file reading and search work around this by loading files on demand rather than upfront. The 1M context window helps but is not a substitute for selective loading.

    “My team keeps hitting limits even though we’re on Team.” Almost always one of two things: (a) people are mistakenly assuming the seat allowance is shared, when it’s strictly per-user; (b) someone is running heavy automation through a subscription seat instead of a Claude Developer Platform API key (which is the recommended path for sustained team-wide automation, especially after June 15).

    Decision matrix: which limits affect which use case

    Map your use case to the limits that actually apply:

    • Solo chat user on Pro — 500K context on Fable 5.1/Opus 5.5/Sonnet 5 in chat, weekly session limit, 30 MB upload cap. Hit your limit and you wait or pay extra usage.
    • Solo developer using Claude Code — 1M context on Opus 5.5 (1M on Sonnet 5 with extra usage on). Same weekly session limit. June 15 billing change applies if you use claude -p.
    • Small team on Team Standard — Per-seat limits at 1.25x Pro session capacity, not pooled. 30 MB upload cap. June 15 billing change applies per-seat.
    • Team running Claude Code in CI — All of the above plus separate Agent SDK credit pool starting June 15. Strongly consider a Developer Platform API key for the CI workload to get true pay-as-you-go billing.
    • Enterprise running large-scale automation — Subscription limits are the wrong tool. Move to a Developer Platform API key, monitor usage at the org level, set spend caps in the Console.

    What to actually do this week

    1. Identify which surface you’re using Claude through (web, Claude Code, API). Different surfaces have different context windows even for the same model.
    2. If you’re hitting “limit” errors, check whether extra usage is enabled at the organization level before assuming it’s a hard cap.
    3. If you’re a Team admin and your team is reporting hitting limits, audit per-seat usage rather than assuming you need to upgrade the plan — the issue is often one heavy user, not the plan tier.
    4. If anyone on your team is running unattended Claude work, read the Agent SDK billing change before June 15.
    5. If you need the full 1M context window, switch to Claude Code or the API. Web chat tops out at 500K.
    6. For uploads larger than 30 MB, split, compress, or move the file to cloud storage and have Claude read it via tools.

    Related on Tygart Media: how to use Claude · Anthropic API key.

    Frequently Asked Questions

    Is the Claude Team plan usage limit shared across team members?

    No. Per Anthropic’s Help Center documentation, each team member has their own set of usage limits. If one team member reaches their seat’s included limit, other team members are unaffected and can keep working.

    What is Claude’s file upload size limit?

    30 MB per file for both uploads and downloads, per Anthropic’s official documentation. For PDFs larger than 30 MB, Claude can process them through its computing environment without loading them into the context window.

    Where does the 1M token context window actually apply?

    1M context is available on Claude Code with Opus 5.5 (Pro/Max/Team/Enterprise) and on the API with Fable 5.1, Opus 5.5, and Sonnet 5. Web chat tops out at 500K tokens even on the most capable models. Sonnet 5 in Claude Code requires extra usage to be enabled to access the 1M window (except on usage-based Enterprise plans).

    What’s the difference between Standard and Premium Team seats?

    Standard seats offer 1.25x Pro plan usage per session with one weekly limit across all models. Premium seats offer 6.25x Pro session usage with two weekly limits (one across all models, one Sonnet-specific). Both reset seven days after the session starts.

    What happens when I hit my Claude usage limit?

    If extra usage is enabled at your organization, you continue at standard API rates billed separately. If extra usage is not enabled, your requests stop until your limit resets at the next session window (seven days from session start, not a fixed weekly day).

    Should I use a Team plan or the API for production automation?

    For sustained shared automation (CI pipelines, cron jobs, background services), Anthropic recommends the Claude Developer Platform with an API key over subscription seats. Subscription seats are sized for individual interactive use; API keys give you predictable pay-as-you-go billing, no per-seat caps, and don’t compete with team members’ interactive usage.

    Related Reading

    How we sourced this

    Sources reviewed September 26, 2026:

    • Anthropic Help Center: Understanding usage and length limits, What is the Team plan?, How is my Team plan bill calculated?, Manage extra usage for Team and seat-based Enterprise plans, Models, usage, and limits in Claude Code, How large is the context window on paid Claude plans?, How large is the Claude API’s context window?, Upload files to Claude (primary sources for all limit specifics)
    • Anthropic platform documentation: Context windows at docs.claude.com (primary source for API context window behavior)
    • Anthropic Help Center: Use the Claude Agent SDK with your Claude plan (primary source for the June 15, 2026 billing change)

    All limit numbers and policies are accurate as of September 26, 2026. Anthropic adjusts subscription mechanics regularly; if you’re making procurement decisions on this article more than 60 days from the date stamp, re-verify the per-seat multipliers and context window availability against the current Help Center.

    Frequently Asked Questions

    What is Claude’s message limit per day?

    Message limits vary by plan. Free: limited daily messages (Anthropic adjusts based on load). Pro ($20/month): approximately 2,000 Sonnet-equivalent messages per day. Max 5x ($100/month): approximately 10,000. Max 20x ($200/month): approximately 40,000. API users are rate-limited by tier with no hard daily message cap, instead governed by tokens-per-minute limits.

    What is Claude’s maximum context window in 2026?

    Claude Fable 5.1, Claude Opus 5.5, and Claude Sonnet 5 all support a 1 million token context window. Claude Haiku 4.5 supports 200,000 tokens. Anthropic eliminated long-context surcharges in March 2026, so large-context requests are billed at standard per-token rates. The Free plan is limited to 200K context even on Sonnet.

    What is the maximum file size I can upload to Claude?

    On Pro, Max, and Team plans: up to 30MB per file, up to 5 files per conversation. Supported formats include PDF, text, CSV, code files, and images. The Free tier supports up to 10MB per file. For API users, file uploads are handled via the Files API with a 32MB per file limit.

    How do I scale Claude beyond subscription message limits?

    For high-volume workloads, switch to the Claude API (pay-per-token, no daily message cap beyond rate limits). Enterprise plans offer higher rate limits and custom agreements. The Batch API processes large jobs at 50% off standard prices for non-real-time workloads. Claude Max 20x ($200/month) is the highest subscription tier for interactive use.

    What are Claude’s API rate limits?

    API rate limits depend on your usage tier. New API accounts start at Tier 1 with lower limits. Spending history and account age automatically promote accounts to higher tiers with increased requests-per-minute and tokens-per-minute. Current tier limits are published at console.anthropic.com/settings/limits. Enterprise customers can negotiate custom rate limits.

    Does Claude have a token limit per message?

    There is no enforced per-message token limit separate from the overall context window. A single message can use up to the full context window (1M tokens for Fable 5.1 / Opus 5.5 / Sonnet 5, 200K for Haiku 4.5). However, very long single messages may be slower to process. The practical limit is the context window of whichever model you are using.

    💼 Deploying Claude or AI Infrastructure in Your Business?

    At Tygart Media, we engineer custom Model Context Protocol (MCP) servers, multi-model content pipelines, and AI operational systems. Explore our Claude AI Team Implementation Services or check out our complete Restoration Operations & AI Kit.

  • Deploy Claude Code: The 2026 Production Team Guide

    Deploy Claude Code: The 2026 Production Team Guide

    Last refreshed: May 15, 2026

    Claude Code production deployment - install paths, CI integration, and team-scale cost controls
    Installing Claude Code is the easy part. Deploying it across a team in production is the part most guides skip.

    Most of the published guidance on installing Claude Code stops at “run npm install -g and you’re done.” That’s enough for a developer playing on a laptop. It is not enough for a team that wants to run Claude Code in production — in CI, in shared infrastructure, behind a firewall, with cost controls, and with the new Agent SDK billing model that takes effect June 15, 2026.

    This article is the production deployment guide. Triple-sourced against Anthropic’s own Claude Code documentation, the github.com/anthropics/claude-code-action repo, and Anthropic’s announced June 15 billing model. Verified May 15, 2026.

    The three install paths and which to pick

    Side-by-side cards defining what Claude Code is and is not
    Three install paths — which to pick.

    Per Anthropic’s official Claude Code docs, there are three supported ways to install Claude Code. They produce the same underlying binary but make sense in different operational contexts.

    1. Standalone installer. A native installer for macOS, Windows, and Linux that drops the Claude Code binary in a system path. This is the cleanest install for individual developers — no Node.js required, no npm dependency, predictable upgrade behavior. Use this on workstations where the operator owns the machine.

    2. npm global package. npm install -g @anthropic-ai/claude-code. Requires Node.js 18 or later. Pulls the same native binary as the standalone installer through a per-platform optional dependency, then a postinstall step links it into place. Use this when you already manage developer tools through npm and want one less install path to track. Supported platforms: darwin-arm64, darwin-x64, linux-x64, linux-arm64, linux-x64-musl, linux-arm64-musl, win32-x64, win32-arm64.

    3. Desktop app. A desktop-class application distributed via .dmg on macOS and MSIX/.exe on Windows. This is the path most teams will deploy to non-developer staff, and it integrates with enterprise device management tools like Jamf, Kandji, and standard Windows MSIX deployment.

    If you are deploying across a team larger than a handful of developers, mix-and-match: standalone or npm for engineering workstations, desktop for everyone else.

    The npm install gotchas worth knowing before you ship

    Two things in Anthropic’s official docs are worth flagging because they will save you from a whole class of bug reports later:

    Don’t use sudo. Anthropic’s setup documentation explicitly warns against sudo npm install -g @anthropic-ai/claude-code. It can lead to permission issues and security risks. If you need a global install on a machine where your user can’t write to the npm prefix, fix the npm prefix first (point it at a user-writable directory) rather than escalating with sudo.

    Don’t use npm update for upgrades. The right command per Anthropic’s docs is npm install -g @anthropic-ai/claude-code@latest. npm update -g respects the original semver range and may not move you to the newest release. This trips up CI pipelines that try to keep Claude Code current via update; they will sit on a stale version forever.

    Production deployment considerations

    Five stacked panels of daily Claude Code command habits
    Production deployment considerations.

    The single most important piece of context for a production Claude Code deployment in 2026: the billing model changes on June 15, 2026.

    Before June 15, Claude Code interactive sessions and claude -p non-interactive runs both draw from your normal subscription usage limits. Starting June 15, interactive Claude Code keeps using subscription limits as before, but claude -p and direct Agent SDK usage move to a separate per-user monthly Agent SDK credit pool ($20 Pro, $100 Max 5x, $200 Max 20x, $20-$100 Team, up to $200 Enterprise).

    For teams running Claude Code in CI, in cron jobs, in shell scripts, in GitHub Actions workflows — anywhere the trigger is automated rather than a human — this changes the economics. Plan capacity against the new credit pool, not the legacy shared subscription pool. Full breakdown in our Agent SDK Dual-Bucket Billing article.

    Three other production considerations:

    Network configuration. Behind a corporate firewall, you’ll need to allowlist Anthropic’s API endpoints, configure proxy settings, and potentially route through an LLM gateway. Anthropic’s network configuration documentation covers the specifics.

    Enterprise device deployment. Per Anthropic’s official docs, the desktop app distributes through standard enterprise tools — Jamf and Kandji on macOS via the .dmg installer, MSIX or .exe on Windows. If your IT team already has a deployment workflow for similar developer tools, Claude Code drops into it without anything special.

    API key management. If your team uses Claude Developer Platform API keys instead of (or alongside) subscription auth, manage them like any other production secret — vault them, rotate them, scope them per environment, never check them into source control. This becomes more important after June 15 because API key usage is the recommended path for sustained shared automation, and unintended sprawl gets expensive.

    Claude Code GitHub Actions: the team multiplier

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    GitHub Actions — the team multiplier.

    The fastest way to get team-level value from Claude Code is the official GitHub Actions integration. From Anthropic’s documentation and the public github.com/anthropics/claude-code-action repository:

    The setup command. The cleanest install is to run /install-github-app from inside Claude Code in your terminal. It walks you through installing the GitHub App, configuring the required secrets, and wiring the workflow file. Manual setup also works — copy the workflow YAML from Anthropic’s docs and add the ANTHROPIC_API_KEY secret to your repository settings — but the install command saves the assembly time.

    The interaction model. Once installed, mentioning @claude in a pull request comment or an issue triggers Claude Code to act on the context. Claude can analyze the diff, create new PRs, implement features described in an issue, fix reported bugs, and respond to follow-up comments — all while adhering to whatever conventions you’ve documented in your repository’s CLAUDE.md file.

    Three use cases worth separating clearly.

    • Automated code review. Claude Code reads the diff on every pull request and posts inline comments flagging potential issues, suggesting improvements, or checking for convention violations. Highest signal-to-noise when path-filtered to relevant code only.
    • Issue-to-PR automation. Tag @claude on a well-described issue and Claude Code opens a PR implementing it. Best for small, well-scoped changes; less useful for architectural work.
    • On-demand assistance. Reviewers tag @claude mid-PR to ask questions, request explanations, or get a second opinion before merging. The most defensible use case because it keeps a human in the decision loop.

    Pick the use case that matches your team’s actual bottleneck. Running all three at once on every PR is the fastest way to burn through your usage budget without proportionate value.

    Cost expectations at team scale

    Independent reports as of May 2026 put Claude Code GitHub Actions PR-review costs at roughly $15-25 per month for a team of 3-5 developers doing 10-15 PRs per week, billed against a Claude Developer Platform API key at Sonnet rates. That figure should be treated as directional — your actual cost depends on PR size, how many tools you’ve configured, model selection, and how aggressive your path-filtering is.

    Two cost controls that materially change the math:

    • Path filters. Trigger Claude Code only on file changes that actually need review. Skipping documentation, generated files, and lockfile-only PRs cuts the bill substantially.
    • Concurrency limits. GitHub Actions concurrency settings prevent Claude Code from running multiple instances against the same branch at once. Without this, force-pushes and rapid-fire updates can stack runs.

    If you are running Claude Code on every PR across an active team, you will hit Anthropic API rate limits. The mitigation is path filters, concurrency limits, and batching — none of which are speculative; they are documented patterns.

    The CLAUDE.md file is not optional

    Whatever your install path and whatever your use case, the single piece of project context that has the largest effect on Claude Code’s output is the CLAUDE.md file at the root of your repository. This is where you tell Claude Code what your project is, what conventions to follow, what tools are available, what to avoid, and what success looks like.

    If you skip it, Claude Code is reasoning from the files alone — useful but generic. If you write it, Claude Code is reasoning with your team’s context and your specific codebase rules. The difference shows up in the first ten minutes of use.

    A practical CLAUDE.md for a production team usually includes: the project’s purpose and stack, naming conventions and folder structure, testing requirements, lint and format rules, deployment considerations, what kinds of changes need human review, and explicit prohibitions (“never commit migrations directly to main”, “always update X when you change Y”). Keep it concise — verbose CLAUDE.md files inflate every per-turn token cost across the team.

    What to actually do this week

    1. Pick your install path per role (standalone or npm for developers, desktop for everyone else).
    2. Install Claude Code on one workstation and run through the quickstart end-to-end before rolling to the team.
    3. Write a real CLAUDE.md for your primary repository before anyone uses Claude Code on it. Even a 100-line version is far better than nothing.
    4. If you’re running anything automated, read the Agent SDK billing change before June 15.
    5. If you want team-level value, install the GitHub Actions integration — but pick one use case (code review, issue-to-PR, or on-demand help), not all three at once.
    6. Set path filters and concurrency limits in your workflow before you put Claude Code on every PR.

    Related on Tygart Media: how to use Claude · Anthropic API key.

    Frequently Asked Questions

    What’s the difference between the npm install and the standalone installer?

    None functionally — both install the same native binary. The npm path is convenient if you already manage developer tools through npm. The standalone installer is cleaner if you don’t want a Node.js dependency. Both upgrade through their own mechanism.

    Why does Anthropic say not to use sudo with npm install?

    Per Anthropic’s official setup documentation, sudo with global npm installs can create permission issues and security risks. The recommended fix is to configure your npm prefix to a user-writable directory, then install without elevated privileges.

    How do I upgrade Claude Code installed via npm?

    Run npm install -g @anthropic-ai/claude-code@latest. Don’t use npm update -g — it respects the original semver range and may not move you to the latest release. This is documented in Anthropic’s setup guide.

    Does Claude Code work in CI/CD pipelines?

    Yes. The official GitHub Actions integration is the recommended path for GitHub-based workflows. For other CI systems (GitLab, CircleCI, Jenkins), the underlying tool is the Claude Agent SDK plus claude -p. Both move to the new Agent SDK monthly credit pool on June 15, 2026.

    How much does Claude Code GitHub Actions cost for a team?

    Independent reports as of May 2026 estimate $15-25/month for a 3-5 developer team running PR review on 10-15 PRs/week at Sonnet rates with a Claude Developer Platform API key. Actual cost varies with PR size, tool configuration, model selection, and path filtering aggressiveness.

    What’s the single biggest mistake teams make installing Claude Code?

    Skipping the CLAUDE.md file. Without it, Claude Code reasons generically against your codebase. With even a basic CLAUDE.md describing your conventions and constraints, output quality improves substantially across every interaction. It is the highest-leverage 30-minute setup task.

    Related Reading

    How we sourced this

    Sources reviewed May 15, 2026:

    • Anthropic Claude Code documentation: Set up Claude Code and Advanced setup at code.claude.com (primary source for install paths, npm gotchas, enterprise deployment patterns)
    • Anthropic Claude Code GitHub Actions documentation at code.claude.com/docs/en/github-actions (primary source for the GitHub Actions integration setup and use cases)
    • github.com/anthropics/claude-code-action public repository (primary source for the action’s interaction model)
    • Anthropic Help Center: Use the Claude Agent SDK with your Claude plan (primary source for the June 15, 2026 billing change)
    • Independent cost analyses (KissAPI, OpenHelm, Steve Kinney) for the team-scale cost estimates — Tier 2 confirming sources

    Cost figures and version specifics in this article are accurate as of May 15, 2026. Anthropic ships Claude Code updates frequently; the install paths and CLI commands are stable, but pricing and rate limits are the most likely figures to need re-verification.

  • My AI Operating Stack: Notion, Claude & Google Cloud

    My AI Operating Stack: Notion, Claude & Google Cloud

    Last refreshed: May 15, 2026

    A surveyor's tripod with copper, porcelain, and steel legs planted on rocky ground at sunrise above the clouds — representing the Notion, Claude, and Google Cloud three-legged stack
    The three-legged stack — Notion, Claude, Google Cloud — is what’s actually holding up the operation.

    I run a portfolio of businesses — restoration companies, content properties, creative ventures, a software platform, a comedy site, a few things I haven’t decided what to do with yet — on three legs. Notion. Claude. Google Cloud. That’s it. Everything else either fits inside that triangle or it doesn’t last in my stack.

    This article is the doctrine. Not “here’s a list of tools I like.” The actual operating philosophy of why this specific three-piece architecture is what holds the work up, where each leg’s job ends, and what I learned the hard way about which tools belong on the floor instead of the table.

    If you’re trying to decide what your own AI-driven operating stack should look like, what follows is what I’d tell you over coffee.

    Why three legs and not two, four, or twelve

    Three stacked layers: chat UI, tools, agent runtime
    Why three legs — Notion, Claude, Google Cloud.

    I tried twelve. I tried four. I lived for a while with two. Three is what’s left after everything else either failed in production, got absorbed into one of the three legs, or became overhead that didn’t pay for itself.

    The reason it’s not two is that you need a place where state lives, a place where reasoning happens, and a place where heavy compute runs. If you collapse two of those into one tool, the tool has to be excellent at both jobs and almost nothing is. If you keep them separate, each tool gets to be excellent at its actual job.

    The reason it’s not four is that every additional leg multiplies the surface area of what can break, what needs to be monitored, what needs to be paid for, what needs to be learned by every new person you bring in. Four legs sounds like it would be more stable but it isn’t. It’s more rigid. Three legs sit flat on uneven ground.

    The reason it’s not twelve is that I tried that and the cognitive cost of remembering which tool did which job was higher than the work the tools were supposed to be saving.

    Notion is the system of record

    State lives in Notion. That’s the rule. If a piece of information needs to exist tomorrow, it goes in Notion first.

    That includes the things you’d expect — clients, projects, content pipelines, scheduled tasks, the Promotion Ledger that governs which autonomous behaviors are running at what tier — and a lot of things you might not. Meeting notes go in Notion. Random ideas at 11pm go in Notion. The reasons I made a particular architectural decision six months ago go in Notion. Anything I might want Claude to read later goes in Notion.

    The reason this leg has to be Notion specifically — and not, say, a folder of markdown files, or a Google Doc, or Airtable — is structured queryability paired with human-readable rendering. Notion databases let me describe my business in shapes (a content piece is a row, a project is a row, a contact is a row) while keeping every row a real document I can read and write to like a normal page. That dual nature is rare. Most systems force you to pick between structured and prose. Notion lets the same object be both.

    The May 13, 2026 Notion Developer Platform launch made this leg even stronger. Workers, database sync, and the External Agents API mean the system of record can now do active things on its own and host outside agents (including Claude) as native collaborators. Notion stopped being a passive document store and started being a programmable control plane. That’s a big deal for this architecture and I wrote about it in my piece on the platform launch.

    Claude is the reasoning layer

    Three cards for fast volume, daily workhorse, and deep flagship Claude seats
    Claude is the reasoning layer.

    Claude does the thinking. That’s the rule on the second leg.

    Anywhere I would otherwise have to write something from scratch, decide between options, summarize a long document, generate code, audit content, or do any task that requires a brain rather than just a database query, Claude is the first thing I reach for. The work happens in Claude. The result lands in Notion.

    I want to be specific about why Claude and not “an LLM” generically. I have used the others. I have used GPT in production. I have used Gemini in production. They all work. Claude is what I picked, and the reasons aren’t religious.

    First, the writing is recognizable. Claude’s voice has a calibration to it that the others don’t quite have for the kind of work I’m doing — long-form content, operator-voice editorial, technical explainers. I can edit a Claude draft to feel like me much faster than I can edit the others.

    Second, the agentic behavior is the most stable across long sessions. Claude Managed Agents and Claude Code in particular are willing to think for a long time without losing the plot. For multi-step work that involves reading a lot of context, holding it, and acting on it across many turns, the difference is real.

    Third, the tooling around Claude — Claude Code, Cowork, the Agent SDK, MCP — is the most operator-friendly of the bunch right now. The other models will catch up. As of May 2026, Claude is the best fit for how I actually work.

    Fourth, and this matters more than people give it credit for: I am willing to bet on Anthropic the company. I am betting my operations on the leg that bears my reasoning load. Whose roadmap I’m comfortable with, whose values I find legible, whose engineering culture I trust to keep shipping the thing without breaking it underneath me — that’s a real input to the decision, not a soft preference.

    Google Cloud is the substrate

    Four pillars: headless agents, MCP tools, rules/memory, human review
    Google Cloud is the substrate.

    The third leg is the heavy one. Google Cloud is where the things live that have to be reliable in a way that Notion can’t be and Claude isn’t supposed to be.

    The 27 WordPress sites I manage all live on GCP infrastructure. The knowledge-cluster-vm hosts five interconnected sites. The proxy that lets Claude talk safely to WordPress sites runs on Cloud Run. The cron jobs that fire scheduled work, the Python services that handle image pipelines, the AI Media Architect that runs autonomously — all on GCP. Anything that involves real compute, regulated data, behind-a-firewall execution, or sustained reliability lives on the third leg.

    The reason this leg has to be a real cloud and not just a laptop or a Hetzner box is that I run autonomous behaviors. Tier C autonomous behaviors run unattended, which means the substrate they run on has to be more reliable than I am. GCP gives me that. It’s also where Anthropic’s Claude is available through Vertex AI, which means there’s a path where the entire stack can run inside one cloud’s perimeter when that becomes operationally necessary.

    I picked GCP specifically over AWS or Azure for a few reasons. Vertex AI’s first-party Claude access matters to me. The GCP control surface is the one I’m fastest in. Cost-wise it’s been competitive for the workloads I run. None of those are universal — your third leg might be AWS, or Azure, or a hybrid with on-premise hardware. The doctrine isn’t “use GCP.” The doctrine is “have a real substrate that can carry the heavy work.”

    How the three legs hold each other up

    The thing that makes this an actual stack and not just three tools is the load each leg puts on the others.

    Notion holds Claude’s memory. Claude doesn’t have persistent memory across sessions in any deep way — what it remembers is what’s in the prompt and what it’s allowed to look up. Notion is where I put the things I want Claude to know tomorrow. Project briefs, brand voice docs, the Promotion Ledger, client context, my preferences. When Claude starts a session it looks at Notion. When the session is done, what mattered gets written back to Notion. The memory leg is Notion. Without it, Claude is amnesiac and has to be re-briefed every time.

    Claude does the work that Notion can’t and that GCP isn’t shaped for. Notion can hold structured data and run light automation through Workers and database sync. Notion can’t write a 2,000-word article in your voice. GCP can run a reliable cron job and host whatever you want on Cloud Run. GCP isn’t going to read your existing client notes and propose a follow-up email. The reasoning leg is Claude. Without it, you have a database and a server and no one to think.

    GCP holds the things that have to keep running when nobody is watching. Notion can’t host a WordPress site. Claude can’t run a cron job by itself. The compute leg is GCP. Without it, the autonomous behaviors that make this a system instead of a tool collection have nowhere to live.

    Each leg fails gracefully into the others. If Notion is down, GCP keeps the live workloads running and Claude can still do work in a session. If Claude is down, Notion still holds state and GCP still runs the autonomous infrastructure. If GCP is down, the websites are unreachable but the planning surface (Notion) and the reasoning surface (Claude) still let me figure out what to do about it. No single failure takes the whole operation down.

    What I tried that didn’t make the cut

    For honesty’s sake, here’s what I had in earlier versions of the stack that’s no longer there:

    Zapier and Make for orchestration. They worked. They cost real money at the volumes I was running. The May 13 Notion Developer Platform launch absorbed most of what I was using them for into native Notion functionality. What’s left I do with Cloud Run jobs.

    Multiple LLMs for “best tool for the job.” I went through a phase of routing different work to different models. The cognitive overhead of “which one for this task” was higher than any quality gain from the routing. I picked Claude and stayed.

    Custom CRMs and project management tools. Tried several. None of them did the job better than a well-structured set of Notion databases with the right templates and views. The CRM is in Notion now. The project management is in Notion. The pipeline tracking is in Notion.

    A second cloud “for redundancy.” Sounded smart, was actually overhead. If GCP goes down catastrophically I have bigger problems than my stack. Single-cloud is fine for a small operator portfolio.

    Local AI models for cost savings. The math didn’t work for me. I have a powerful workstation that can run open models, but the time cost of running them, debugging them, and maintaining them outweighed the API savings. Claude through the subscription and through Vertex when I need it is what I pay for now.

    Why this matters beyond my own operation

    I write about this not because anyone is required to copy it but because the shape of the answer — three legs, one for state, one for reasoning, one for compute — generalizes.

    If you’re a solo operator, a small agency, a content business, a service business with operational complexity, this shape works. Your specific tool choices for each leg will be different. Maybe your state lives in Airtable instead of Notion. Maybe your reasoning leg is GPT or Gemini. Maybe your substrate is AWS or Vercel or your own bare metal. The three-leg architecture survives the substitutions.

    What doesn’t survive substitutions is collapsing the legs. Putting state and reasoning in the same tool (anyone who has tried to use ChatGPT as their CRM knows what I mean) doesn’t work. Putting reasoning and compute in the same tool means you’re either compromising on reasoning to keep compute simple or compromising on compute to keep reasoning fluid. The separation is where the strength is.

    Where the stack is going next

    Three things I’m watching:

    Notion’s platform maturation. The May 13 launch is version 1 of what Notion as a programmable platform looks like. If Workers and database sync continue to grow into real automation surface, more of what I do on GCP could move to Notion. I don’t expect the heavy stuff to migrate, but the lightweight glue is moving in that direction.

    Claude’s agentic capabilities. Claude Managed Agents and the Agent SDK are getting better fast. Some of what I currently script in Python on Cloud Run will move into Claude-native agentic loops as the agents become more capable of long-running, reliable work without supervision.

    The fortress pattern on GCP. The ability to run Claude inside a private GCP perimeter via Vertex AI is becoming more important as I take on regulated industry work. The substrate leg is staying GCP precisely because of this — the perimeter matters.

    The stack will evolve. The three-leg shape probably won’t.

    Related on Tygart Media: how to use Claude · GA4 Intelligence Kits.

    Frequently Asked Questions

    Why Notion and not Airtable, Coda, or Obsidian?

    Notion’s combination of structured databases and human-readable page rendering is what makes it work as both a database and a knowledge base for Claude. Airtable is more powerful as a database but worse as a document. Coda is similar in spirit but smaller community and tooling around it. Obsidian is excellent for personal knowledge but doesn’t have the multi-user, structured-database surface I need to run businesses on.

    Why Claude and not GPT or Gemini?

    Voice quality for the kind of writing I do, agentic stability across long sessions, operator-friendly tooling (Claude Code, Cowork, MCP), and Anthropic’s roadmap and culture being legible to me. The other models work; Claude is what I picked.

    Why Google Cloud and not AWS?

    Vertex AI’s first-party Claude access, GCP’s control surface fitting how I work, competitive cost on my specific workloads. AWS would also work. The doctrine is “have a real substrate,” not “use GCP specifically.”

    Can a small operator afford this stack?

    Yes. Notion is $10/seat. Claude Pro is $20/month, Max is $100-$200. GCP costs scale with what you actually run — my 27-site infrastructure runs in the low three figures monthly. Total monthly stack cost for a solo operator running this architecture is well under what most people pay for a single SaaS tool that does only one of these jobs.

    What if one of the legs goes away or pivots badly?

    Each leg is replaceable. The shape of the stack matters more than the specific brands. If Notion pivots away from being useful, the state leg moves somewhere else. If Anthropic pivots, the reasoning leg moves. If I leave GCP, the substrate leg moves. The architecture is durable; the specific tool choices are not load-bearing in the way the architecture is.

    How long did it take to settle on this shape?

    Roughly two years of trying things. I write the doctrine now because I want my own next iteration to start from this shape rather than rebuilding it from scratch. If you want to skip those two years, this is the shortcut.

    Related Reading