Tag: Schema Markup

  • The Agent-Ready Site: What Kin’s WebMCP Launch Means for Every Business Website

    The Agent-Ready Site: What Kin’s WebMCP Launch Means for Every Business Website

    On October 23, 2026, Kin Insurance became the first U.S. home insurer to enable WebMCP in its quoting experience — an open web standard that lets an AI agent work directly with kin.com, so a homeowner can tell ChatGPT "help me shop for home insurance" and get back a real quote. Strip away the insurance details and what remains is a pattern every business website is about to be measured against: is your site built for the agent your customer sends?

    Most businesses are still arguing about whether to let agents in. Kin skipped that argument. The interesting question is what its launch is made of, layer by layer — because three of the four layers are already visible in our own fleet's numbers.

    Layer 1: Decide to welcome the machine

    Agent traffic is not coming; on our own sites it is already the majority — roughly 62% of visits across the fleet we run are bots and agents, not people. The only choice left is whether that traffic meets a door or a wall.

    Kin chose the door, publicly and in advance: it had already announced that AI shopping agents are welcome on kin.com rather than blocked, naming Meta's Muse among them. The opposite choice exists in the same industry — in September, insurance marketplace Insurify blocked Muse from its comparison platforms, arguing an agent could pull a price stripped of the context that makes it meaningful. Both are coherent positions. What is no longer available is having no position: a site that has not decided is a site whose default settings decide for it.

    Layer 2: Structure the content so a machine can carry it accurately

    An agent can only repeat what it can read, so the agent-ready site is built out of answers, not brochures: one real question per page, paragraphs that stand alone as complete ideas, and structured data underneath that states the facts in machine-readable form.

    This is the layer we work in every day, and it is unglamorous, mechanical work. Tonight, on one operator site in our fleet, we finished putting structured FAQ data — drawn from each page's own questions and answers, verbatim — onto 155 of its 166 articles, because agents cite what is structured and skip what is implied. Multiply that instinct across every page a business owns and you have the content layer of agent-readiness: nothing important lives only in an image, a video, or a sales conversation.

    Layer 3: Give the agent a way to act, not just to read

    WebMCP is the layer most sites do not have yet: the site declares the actions an agent may take — get a quote, with these inputs, in this order — so the agent executes a designed path instead of improvising clicks across a human interface.

    Kin's version is a quote flow, and its testing shows why the layer matters: agents reached a finished quote after asking the consumer only a handful of questions, because the path was declared and the carrier's data filled the rest. The equivalent for any business is the moment a visit becomes a transaction — a booking, a quote, an order. Our own commerce thinking already runs on two rails, one built for humans at a checkout and one an agent can complete; Kin just shipped the insurance version of the second rail, first.

    Layer 4: Measure what the machines do

    Agent-readiness you cannot measure is a vibe. Kin will know whether agents quote it, because the protocol makes agent sessions countable; the rest of us measure the read layer — which pages agents cite, which questions they bring, how the share moves.

    On tygartmedia.com, we track AI citations from our own search-engine exports rather than a vendor's estimate: 1,459,726 citations across 922 cited pages in the October 15 export, up from 269,399 across 324 pages in the September 27 export. Those numbers are the scoreboard for layers 1 and 2. The day an agent can transact here, layer 3 gets a scoreboard of its own.

    Where our fleet honestly sits

    Layers 1, 2, and 4 are running here today — welcome posture, structured content, citation measurement. Layer 3, declared agent actions, is what Kin shipped first, and it is the next build. That is a fair summary of most of the web right now: readable by agents, citable by agents, and still requiring a human to show up for the transaction itself.

    The businesses that treat that gap as a roadmap, rather than a surprise, are the ones whose sites will be ready when their customers stop browsing and start sending.

    Frequently asked questions

    What is WebMCP? An open web standard that lets an AI agent interact with a website through a machine-usable path the site itself declares — no plug-in and no screen-scraping. Kin enabled it in its home insurance quoting experience on October 23, 2026, the first U.S. home insurer to do so.

    What makes a website "agent-ready"? Four layers: a deliberate decision to welcome agent traffic instead of blocking it by default; content structured as standalone answers with machine-readable data underneath; a declared path that lets an agent complete an action, such as a quote or booking; and measurement of what agents actually do on the site.

    Do agents really visit business websites that much? On the fleet we operate, roughly 62% of visits are bots and agents. The share varies by site, but the direction does not: the reader a growing share of your pages serve first is a machine deciding what to show its human.


    Source: Kin Insurance announcement via PR Newswire, October 23, 2026. Fleet figures are Tygart Media's own: bot share from our site analytics; citation counts from our Bing AI Performance exports of September 27 and October 15, 2026.
  • Yes, I Put the Schema Where You Could See It. On Purpose.

    Yes, I Put the Schema Where You Could See It. On Purpose.

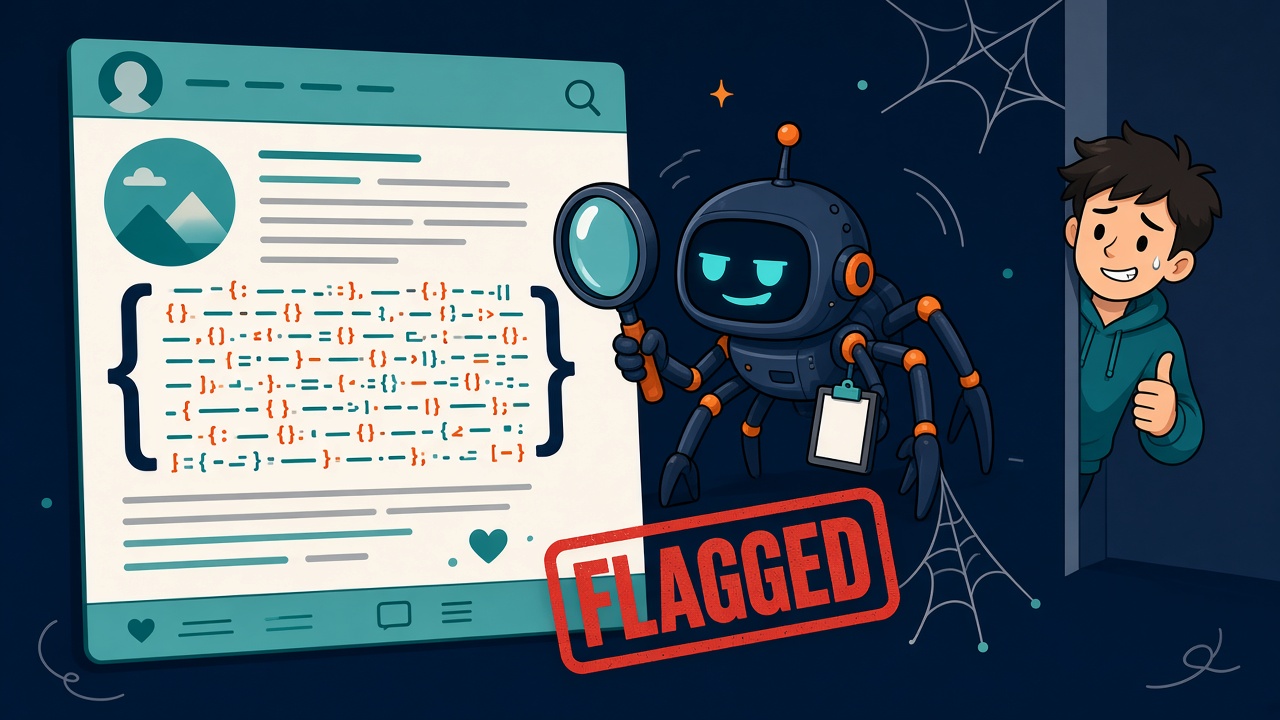
    I had an audit run on the oldest content on this site this week. Pages, posts, links, bylines, search descriptions, the works. It came back with a ranked list of problems, and near the top, flagged as a defect readers can see, was this:

    Visible raw JSON-LD schema code printed as text in the post body.

    Across the whole site, it found 197 posts doing it.

    Cartoon crawler robot stamping FLAGGED on a blog post full of visible code while the blogger gives a sheepish thumbs-up
    My own audit, doing exactly what I asked it to do. Rude.

    And I’ll be honest, my first reaction wasn’t “oops.” It was closer to “hey, I did that on purpose.”

    What you’re looking at

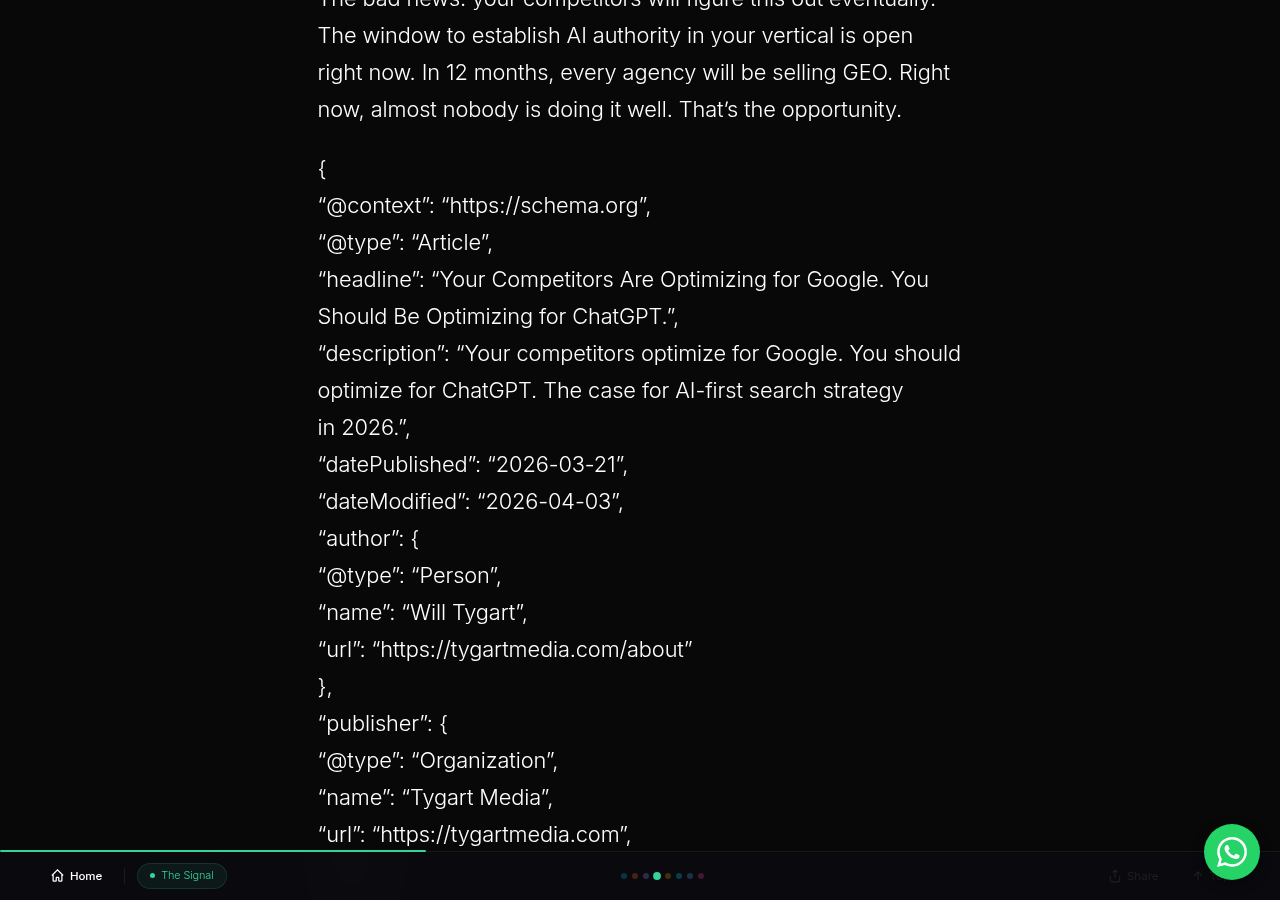
    If you’ve scrolled to the bottom of some of my older posts, you’ve seen it: a block of curly braces, "@context": "https://schema.org", a headline, an author, a publisher, a date. It’s structured data. The machine-readable summary of what the page is, who wrote it, and who published it.

    Normally that lives in a <script type="application/ld+json"> tag. Readers never see it, and crawlers pick it up behind the scenes. I know how to do it that way. Plenty of these same posts had it that way too.

    I also put a copy out front, in the body, where anyone could read it.

    Before: the end of “Your Competitors Are Optimizing for Google. You Should Be Optimizing for ChatGPT.” with its Article schema printed as visible text, curly quotes and all
    Before. The article ends, the schema begins. Those curly quotes are lovely typography and terrible JSON.

    Why I did it

    This didn’t come out of nowhere. Back when I published these, I’d already been at it a while: for about a year before that, my everyday workflow was screenshotting schema and photos and pasting them into AI tools to get help with them. That was on my own desk, not on the website. But do that long enough and you get in the habit of thinking about the page as something a machine reads, not just something a person reads.

    When it came time to publish these posts, my reasoning was simple. Not everything that reads a web page reads it the way Google does. Screen readers, accessibility tools, and whatever crawler or AI agent happens to show up next don’t all go digging through script blocks. Some of them only take in the text on the page.

    So I thought: if the structure matters, and I was betting heavily that it did, especially for AI and answer engines, then why hide it? Put it where every reader, human or machine, could get to it. Treat it as part of the content, not an invisible attachment.

    It was also a demonstration. I write about getting businesses understood by machines. Showing the actual markup on the page was a way of saying: this is what that looks like. Nothing up my sleeve.

    The fair criticism

    Now, I’m stubborn, not blind. A few things are fair game here.

    A wall of JSON is not friendly to a human reader. If you came for a local SEO playbook and finished on forty lines of braces and quotation marks, I get it if you thought the page was broken. The audit literally measured one of these blocks running about 2,100 pixels tall on a phone. That’s a lot of scrolling for metadata.

    What a screen reader actually does with a block of JSON is a fair debate. My intent was access. Whether reading out a pile of punctuation counts as access is a fair thing to argue about, and I’m not going to pretend I settled it.

    The copies didn’t stay clean. WordPress likes to “help.” Some of the visible blocks picked up curly quotes and line breaks along the way. That’s charming in prose and useless in JSON. A machine trying to parse those blocks as data would choke.

    So the audit isn’t wrong that it’s a problem today. It’s just wrong about why it’s there. It wasn’t an accident. It was a choice, and the choice has run its course.

    Why it’s coming down now

    Here’s the part that makes this easy. The stack caught up.

    This site runs Rank Math, and Rank Math now outputs proper Article and BreadcrumbList schema on every post, in the head of the page, where it belongs. That means the visible copy isn’t carrying any weight anymore. It’s a duplicate. Worse, some of these posts were carrying three versions of the same facts: Rank Math‘s, an older inline script block, and the visible one, and they didn’t always agree on things like the modified date.

    When the system does the job properly, the demonstration becomes clutter.

    Then and now cartoon: a blogger holding a sign of raw code, then a Rank Math badge as robots applaud
    Same guy, same idea. The plugin just does it without the sign.

    What we’re doing about it

    • Audit first. Nothing gets touched without a list. The audit covered the 50 oldest items on the site, and a separate site-wide scan found the full 197.
    • Delete the visible blocks. No rewriting, no reformatting. The fix is deletion, and the duplicate inline Article scripts in those same posts go at the same time.
    • Let Rank Math own schema. One source of truth for structured data. If a page ever needs custom schema, it goes through Rank Math‘s schema settings, not pasted into the post.
    • Look at the page like a human. Every fixed post gets checked live in a browser afterward. The code should be gone, and the article should end where the article ends.

    The cleanup of the oldest posts is happening now. The rest of the 197 get their own pass after that.

    The actual lesson

    I’m not going to tell you I was wrong to try it. I had a reason. You just didn’t know it, and to be fair, neither did the audit.

    But a reason has a shelf life. What made sense back when I published these doesn’t have to make sense now, and it’s worth checking every once in a while whether your clever idea is still doing its job or just sitting there being clever.

    Mine was sitting there. So it’s coming down.

    If you spot a stray curly brace at the bottom of one of my posts in the meantime, consider it a collector’s item.

  • AI Search Visibility for Local Service Businesses: The 2026 Playbook

    Last verified: October 4, 2026 (Pacific).

    Key takeaways

    • AI search visibility is whether AI assistants name your business when someone asks for a local service — and 78% of local-services brands are currently invisible to it.
    • ChatGPT recommended just 1.2% of business locations in a 2026 benchmark of 350,000 locations, versus 35.9% appearing in Google’s local 3-pack (SOCi, 2026).
    • Only 12% of URLs cited by AI overlap with Google’s top 10 results — this is a separate ecosystem with separate rules (teehoomartech).
    • The shops winning AI citations publish real price ranges, license and certification signals, and emergency-intent pages — the three shapes almost nobody in the trades has built.
    • Expect a 90-day foundation cycle: fundamentals first, then the service × city content matrix, then seasonal content.

    What is AI search visibility for a local business?

    AI search visibility is the practice of making your business the answer AI assistants give — getting ChatGPT, Gemini, Perplexity, or Copilot to recommend you by name when someone asks for a local service. Think of it as SEO for the recommendation era.

    Your next customer didn’t Google “plumber near me.” They asked ChatGPT. Or they asked Gemini while standing in their kitchen with water pooling under the sink. And the AI named three businesses — yours wasn’t one of them.

    This isn’t a future problem. According to BrightLocal (March 2026), 45% of U.S. consumers use AI to find and choose a local business — up from 6% a year earlier. The question is no longer whether AI sends you customers. It’s whether AI knows you exist.

    How far behind are local businesses in AI search?

    A 2026 benchmark by SOCi across roughly 350,000 business locations put hard numbers on the gap:

    • ChatGPT recommended 1.2% of locations. Google’s local 3-pack showed 35.9%. Gemini recommended 11%, Perplexity 7.4% (SOCi, 2026).
    • AI visibility is 3 to 30 times harder to achieve than ranking well in traditional local search (SOCi, 2026).
    • Only 12% of URLs cited by AI overlap with Google’s top 10 results (teehoomartech). This is a different ecosystem, not an extension of the old one.
    • 78% of local-services brands are invisible to AI, and 88% of local businesses have no AI search strategy at all (May 2026 industry index).

    Here’s the reframe that matters: AI doesn’t rank you. It recommends you. Traditional SEO was optimization — climbing a list. AI visibility is qualification — convincing a model you’re a safe, correct answer to give a real person. Everything below follows from that shift.

    Traditional local SEO AI search visibility
    Climb a ranked list (positions 1–10) Become the recommended answer (named or not at all)
    Optimize for Google’s crawler Qualify for the model’s trust judgment
    Reviews are a ranking signal Reviews are a qualification filter — the AI reads the text
    Your website is the destination Your website is the source the model draws on
    One rulebook (Google) Different rulebooks per engine (Gemini, ChatGPT, Perplexity)

    What are the non-negotiable fundamentals?

    You’ve seen this checklist before, so here’s the short version — these are table stakes, and the data says they still move the needle:

    • NAP consistency everywhere. Inconsistent name/address/phone data cuts your AI citation probability by 67%. Consistent omnichannel data delivers 3.2x the AI visibility (Birdeye, 2025).
    • A complete Google Business Profile. Optimized profiles appear in AI Overviews 42% more often, with 30% more profile views and 34% more direction requests (Local Falcon; SapientSEO).
    • Review volume, velocity, and recency. AI treats reviews as a filter, not a ranking signal — and it reads the review text, not just the stars. ChatGPT-recommended locations averaged 4.3 stars in the SOCi benchmark: good enough to pass the filter, with the text doing the real work.
    • Owner responses on reviews. Every response is a place to confirm your services, your service area, and real outcomes — in the AI’s own training-adjacent data.
    • LocalBusiness schema on every page. Structured data increases AI citation probability 3.4x (MIT CSAIL). FAQ content earns 2.8x more AI citations than marketing copy (Search Engine Land research).

    If any of those are missing, fix them first. What follows is what nobody is telling the trades.

    How do you win the 2am emergency query?

    The highest-value AI query in the trades isn’t “best plumber near me.” It’s “emergency plumber near me open now” at 2am — asked by someone with water coming through their ceiling. Nobody has mapped AEO to urgent intent. Here’s the playbook:

    • Set your after-hours attributes. Your GBP has hours fields most shops leave blank or set wrong. AI models check “open now” signals before recommending — a blank field reads as closed.
    • Build dedicated emergency service pages — one per emergency service, not a paragraph on your homepage. Format them as direct answers: what counts as an emergency, what you do first, typical response time, service area, then the phone number.
    • Answer the 2am questions explicitly. “Do you charge extra for after-hours calls?” “How fast can you get to [neighborhood]?” If your page answers them in plain sentences, the AI can quote them. If it doesn’t, the AI quotes whoever did.

    What trust signals make AI recommend a contractor?

    Here’s the qualification logic: an AI will not recommend a stranger to enter someone’s home unless it has reasons to trust. For the trades, those reasons are concrete — and almost nobody publishes them properly:

    • License numbers on every service page, not buried on a contact page. “WA Licensed General Contractor #TYGART123JD” is an entity signal.
    • Insurance stated plainly — liability coverage and bonding, in sentences, not badges alone.
    • Trade certifications as trust qualifiers — IICRC for restoration, NATE for HVAC, EPA 608 for refrigerant work. These are the exact credentials a homeowner would want verified, which makes them exactly what the AI looks for.
    • Put them in schema too. Credentials in visible text get read; credentials in structured data get cited.

    Zero of the major guides on this topic mention licensing or certification. That’s your opening.

    What should a local business publish so AI cites it?

    “Structured local content publishing” is everyone’s advice and nobody’s architecture. Here’s the architecture: one quotable page per service per city you serve — the service × city citation matrix.

    • Each page answers one question completely: the service, the city, what it costs, how long it takes, what can go wrong.
    • Publish real price ranges. Every guide lists “how much does [service] cost in [city]?” as a top AI query — and none tell shops to answer it. The shop that publishes “$1,200–$2,800 for a water heater replacement in Tacoma” becomes the citable source. Everyone else becomes invisible on the highest-intent question in the category.
    • FAQ schema on every matrix page. Direct-answer formatting: the question as a heading, the answer in the first two sentences, detail after.
    • Emergency variants get their own pages (see above) — don’t fold them into the standard service page.

    Are AI crawlers blocked from your site?

    Your site may be silently blocking the exact bots you need. Outdated robots.txt rules — written years ago to keep scrapers out — now block AI crawlers from reading your pages at all. The fix:

    • Explicitly allow GPTBot, ClaudeBot, PerplexityBot, and Google-Extended in robots.txt.
    • Don’t blanket-allow every bot on the internet — allowlist the AI crawlers by name, keep the rest of your rules intact.
    • Verify with a fetch test after the change. Thirty seconds of work, and without it, every other play on this list is muted.

    How do reviews get AI to recommend you?

    Google’s April 2025 Maps policy change killed scripted “mention my name in the review” requests. The shops still running that playbook are risking their profiles. The compliant system:

    • Ask “tell us about your experience,” not “leave us a review.” AI reads review text — “they replaced our water heater in under three hours” beats “great service” because it contains a service, a timeframe, and an outcome.
    • Time the ask: SMS or invoice link within 2 hours of job completion, while the details are fresh.
    • Engineer your owner responses as service + neighborhood + outcome triples: “Glad we could get the furnace running again for you in Lakewood — those January cold snaps don’t wait.” Every response is corroborating evidence the AI can use.
    • Review freshness is its own factor. A steady cadence beats a burst.

    How do you audit your AI readiness in 20 minutes?

    AI models cross-check you. Your reviews, your GBP, and your website need to tell the same story — same services, same service area, same phone number, same hours. When they disagree, the model loses confidence and picks someone else. The corroboration triangle audit, once a month:

    1. Read your last 10 reviews. Do the services mentioned match your GBP services list?
    2. Check your GBP hours, service area, and phone against your website footer and contact page.
    3. Search your business name plus your top service. Is the story consistent across the first page?
    4. Fix the mismatches. That’s the whole audit.

    Does each AI engine need a different approach?

    Yes. The models don’t work the same way, so don’t treat them the same. Same skeleton for each: what it trusts, then the one-line tactic.

    Gemini

    • What it trusts: live Google Maps data — profile accuracy runs near 100% because it’s grounded in Maps.
    • Tactic: GBP completeness and accuracy win here; treat your Business Profile as your Gemini homepage.

    ChatGPT

    • What it trusts: concise shortlists built from third-party corroboration — reviews, mentions, directory listings (profile accuracy here runs ~68%, so corroboration fills the gap).
    • Tactic: third-party mentions are what get you onto its shortlist; one strong source is never enough.

    Perplexity

    • What it trusts: live search with direct citations — freshness is the ranking input.
    • Tactic: recent reviews, recent posts, recently updated pages; stale content goes invisible fastest here.

    Copilot

    • What it trusts: Microsoft’s retrieval grounding — substantially the same answer logic as Bing’s AI surfaces.
    • Tactic: Bing Webmaster Tools verification plus the same fundamentals; what works for Perplexity-style freshness works here.

    Run the same tracked prompts across all four monthly and note who’s citing you and who isn’t. That’s your measurement system until you outgrow it.

    What does the first 90 days look like?

    Generic 90-day plans assume you’re a SaaS company. You’re not — you have seasons. Map the work to yours:

    • Days 1–30: Foundation. NAP audit, GBP completion, robots.txt allowlist, license/certification trust layer on every page, emergency pages live.
    • Days 31–60: Matrix. Build the service × city pages for your top 5 services, each with real price ranges and FAQ schema. Launch the review-text system.
    • Days 61–90: Seasonality. Publish ahead of your season — frozen-pipe content in December, AC tune-up FAQs in April, storm-season prep in late summer. The shop that publishes first becomes the cited source for the whole season.

    Frequently asked questions

    What is AI search visibility for a local business?

    It’s whether AI assistants — ChatGPT, Gemini, Perplexity — name your business when someone asks for a local service. Unlike Google rankings, there’s no position 4 to fall back on: either the AI recommends you or you’re not in the consideration set at all.

    How is AI visibility different from local SEO?

    Local SEO climbs a ranked list; AI visibility qualifies you as a safe recommendation. Only 12% of URLs cited by AI overlap with Google’s top 10 results (teehoomartech) — it’s a different ecosystem with different rules, and it’s 3 to 30 times harder to break into than the local 3-pack (SOCi, 2026).

    Do reviews really affect whether AI recommends my business?

    Yes — AI treats reviews as a qualification filter and reads the review text, not just the star rating. Review volume, recency, and specific language about services and outcomes all feed whether a model will name you.

    Should I block AI crawlers from my website?

    No — blocking GPTBot, ClaudeBot, PerplexityBot, or Google-Extended in robots.txt makes your pages invisible to the models deciding who to recommend. Allowlist the AI crawlers by name instead.

    How long does it take to build AI search visibility?

    Expect a 90-day foundation cycle: 30 days for fundamentals and crawler access, 30 for the service × city content matrix, 30 for seasonal content and review velocity. It’s ongoing work after that — freshness is a ranking input, not a one-time project.

    What’s the single highest-ROI move for a trade business?

    Publish real price ranges on service × city pages. “How much does it cost” is the top AI query in the category, almost nobody in the trades answers it, and the business that does becomes the cited source.

    What does done-for-you look like?

    Everything above is the playbook, free, on this page — that’s the point. If you’d rather have it built than build it, that’s what our AI Search Visibility Package does: the full citation work for your trade, measured the way AI measures it. Start with the $97 AI Citation Quick-Scan if you want to see exactly where you stand first — the $97 credits toward the package within 30 days.

    Want the deeper version — the robots.txt allowlist snippet, the per-engine prompt library for the monthly audit, and the seasonal content calendar template? That goes out by email. The playbook above is yours either way.

  • What AI Assistants Actually See When They Open Your Website

    What AI Assistants Actually See When They Open Your Website

    You see a screen. Your AI assistant usually doesn’t.

    That sentence needs one qualification, which we will get to. But it corrects the picture most of us carry in our heads.

    When I open a website, I see the design and the button I am supposed to press. I assumed an AI assistant saw roughly the same thing, only faster. Then I asked the more basic question: what does it actually receive?

    The answer is not one thing. An assistant can find a site, read a site or operate a site. Those are separate jobs using different inputs. If we want pages that work well for AI assistants, we have to stop lumping them together.

    An assistant meets your website three different ways

    Finding: the search result is the pitch

    When an assistant searches the web, its first view is closer to a search-results list than a browser window. It may receive a title, URL and short snippet.

    At that moment, your title tag and meta description are the entire pitch. The assistant has to decide whether your page can answer the question before opening it. Name the subject plainly.

    Reading: the page becomes a stream of text

    When Muse opens a public page for information, the normal reading path is text-first. Useful content is extracted and returned as headings, paragraphs, lists and links in roughly page order.

    The design largely falls away. The assistant is not admiring the hero section or noticing that a price sits inside a gold circle. It is working from the words the page exposes.

    Images may arrive as markers and file addresses: there is an image here, and here is where it lives. That is not the same as seeing it. If a crucial fact is baked into the pixels—“$199,” “ships free,” “five-year warranty”—the reading path may hit a blank spot. Useful alt text can carry some of that meaning. “Technician using a moisture meter on wet drywall” communicates something. “IMG_4827” does not.

    Doing: a browser worker operates the screen

    The picture changes when the user asks the assistant to do something: log into HubSpot, update a record, complete a form or buy a product.

    A separate browser program can open a real browser on a server. It loads the interface, takes visual observations or inspects the page’s interactive structure, clicks, types and reports what happened back in words.

    That is the qualification to “usually.” A screen may be used inside the process, but the conversational assistant is not sitting behind the glass like a person. It receives observations from a browser tool and sends instructions back. The browser side is the eyes and hands; the assistant works through an intermediary.

    A page can be easy to read as an article and miserable to operate as an application. It can look obvious to a person while presenting the browser worker with five unlabeled controls called “button.”

    WordPress made the abstraction visible

    I had already seen a simpler version in our WordPress work without connecting the dots.

    When we pull a post through the WordPress REST API, the content can arrive as raw HTML: words plus tags for headings, paragraphs, links, lists and styling wrappers. The reading step removes the markup noise while preserving the words and structure.

    That is “cleaning the HTML.” We are removing the packaging, not the article. The tags still matter: a heading announces a section, a list groups items, and a link identifies a destination. Good HTML carries meaning. Bad HTML creates boxes that look right but say little about what they are.

    Accessibility is the closest thing to an agent-ready standard

    Here is the practical money line: the work that makes a website easier for a blind person to use also tends to make it easier for an AI browser agent to use.

    Browsers build an accessibility representation from the page’s Document Object Model. Assistive technology uses it to understand roles, names, states and relationships: this is a heading, that is a link, this button is named “Save contact,” and this checkbox is checked.

    Muse’s browsing side is reported to rely heavily on this kind of page structure, along with visual observations when needed. Meta does not publish a complete specification for the Muse browsing pipeline, so treat that as a field report from using the product, not permanent platform documentation.

    The implication is still solid. Use real buttons with useful names. Label form fields. Put headings in a sensible order. Give links meaningful text. Preserve keyboard focus. Describe informative images.

    A screen-reader user needs those things. So does a browser agent working without human intuition. Accessibility and agent-readiness are not identical, but they are close cousins.

    HubSpot shows what an agent-native application could be

    Imagine HubSpot—or any software platform—shipping an interface designed for assistants to navigate with less friction. It would not need a blank, text-only clone. It could make the existing product more legible to software: real controls with specific names, labeled form fields, clear headings and landmarks, properly identified table headers, programmatic state changes, and no critical action hidden behind hover or an unlabeled icon.

    That is an agent-native site. It is not a secret internet for bots. It is a website or application whose meaning survives when the visual layer is translated into structure and words.

    The same work also helps keyboard users, screen-reader users, automation tools and QA teams.

    llms.txt is a map, not a second website

    The closest public convention aimed directly at AI readers is llms.txt. The proposal describes a Markdown file, usually at a site’s root, that gives language models a short explanation of the site and links to important pages or cleaner Markdown versions.

    Think of it as a curated map: here is what we do, here are the pages that matter, and here is where to find the details.

    It cannot repair an unlabeled checkout button. It does not replace accessible HTML, describe the viewport or guarantee that an assistant will use it. Add it if it helps explain the site. Do not mistake it for an agent interface.

    What a site owner can change Monday morning

    The useful changes are ordinary, testable website work.

    1. Write a real title and meta description. Name the subject plainly.
    2. Put every money fact in visible HTML text. Price, specifications, shipping, availability and guarantees should not live only inside graphics, video or a brochure.
    3. Use semantic HTML. Use headings for headings, buttons for actions, links for navigation and labels for form controls. A styled <div> may look like a button while remaining a nameless container to other systems.
    4. Write alt text that carries meaning. Describe what an informative image contributes. Mark decorative images as decorative instead of stuffing them with keywords.
    5. Add accurate structured data. Product and Offer markup can identify price and availability. FAQ markup can describe genuine questions and answers. Schema must match the visible page.
    6. Server-render critical content when practical. If the offer, price or primary action appears only after a fragile JavaScript sequence, some readers and tools may miss it.
    7. Give each landing page one job. One offer, one explanation and one primary action reduce ambiguity for people and agents.
    8. Test the nonvisual path. Use the keyboard, inspect the accessibility tree, try a screen reader and pull the page through a text extractor. Do the product, price, proof and next step still make sense without styling?

    None of this requires uglier design. It requires the design and the underlying structure to tell the same story.

    This is a field report, not a permanent specification

    This article describes Meta’s Muse as it works today, based on direct experience building and operating websites with it. It is not a published Meta protocol.

    Claude, ChatGPT, Gemini and other assistants broadly rhyme with this pattern, but the details differ. Their full pipelines are not public, and they are changing quickly.

    Cleaner HTML will not automatically increase AI citations tomorrow. Citation systems involve discovery, retrieval, ranking, trust and answer construction. There is no magic switch.

    The immediate opportunity is closer to the customer. Someone sees your ad on Threads or Facebook, opens the landing page, then asks an assistant: “What does this cost?” “Is the guarantee real?” “How does this compare?” or “Can you sign me up?”

    If the facts are clean text, the assistant can explain them. If the controls are properly labeled, the browser side has a better chance of completing the task. If the facts live inside an image and checkout uses unlabeled custom controls, the assistant has to guess, fail or hand the job back.

    That moment is already here.

    The next website has two front doors

    The site of the near future has two front doors: one for eyes—layout, color, photography and brand—and one for agents—clean text, meaningful structure, explicit facts and self-identifying controls.

    They should lead to the same place. The visible price and schema should agree. A button’s label and accessible name should agree. The page should remain understandable without styling and usable when a browser worker operates it.

    That is not a special Muse landing page. It is a better website—one that keeps working when the visitor brings an assistant.

    Build both front doors.

    Sources and further reading

  • Job Posting Schema for Restoration Shops: How Google Reads a Vacancy

    Job Posting Schema for Restoration Shops: How Google Reads a Vacancy

    Last verified: October 2, 2026 against Google’s Job posting structured data (docs last updated September 8, 2026) and AIOSEO’s 4.9.9 announcement.

    Direct answer: JobPosting schema is structured data that labels a single open role — title, employer, work location, description, posted date — so Google can treat the page as a vacancy instead of a brochure. Done correctly, the listing becomes eligible for Google for Jobs. Eligibility is not placement. Google still decides. The markup must match what a candidate can read on the page.

    Tech documenting a water loss on a tablet
    A careers page on your domain is the object Google can attach JobPosting schema to. The board is optional.

    Trigger for this desk: All in One SEO emailed Tygart Media on September 25, 2026 that Job Posting schema (and Event schema) now ships on every paid AIOSEO plan starting with Basic, as of AIOSEO 4.9.9. That is a product-access change, not a ranking promise. tygartmedia.com runs Rank Math. The schema type is the same either way. The plugin is a generator. Google’s Job posting structured data spec (docs last updated September 8, 2026) is the rulebook.

    Why a restoration shop should care

    Related: Schema Markup for AI Search: The New Meta Description · Your Google Profile Is Your New Front Door

    Most restoration companies hire the way they market: on someone else’s board. Indeed, Facebook, a text to a former tech. That works until storm season, and then the shop needs a water tech in Everett, a project manager in Lynnwood, or an estimator who already knows Snohomish County adjusters. If the only public copy of the role lives on a job board, Google indexes the board. Your domain does not own the vacancy.

    A careers page on your site is the durable object. JobPosting schema is the label on that object. Answer engines and Google for Jobs both prefer a page that states the role in plain sentences and then repeats the same facts in JSON-LD. That is AEO and GEO in one hang: the page answers “who is hiring water mitigation technicians in Everett, WA,” and the markup gives the city, employer, and dates without forcing the model to guess.

    What Google requires

    Google’s required JobPosting properties, from Search Central:

    • title — the job title only. “Water Mitigation Technician,” not “Water Mitigation Technician — $28/hr — Everett — Apply Now!!!”
    • description — the full description in HTML. Duties, qualifications, hours, education, experience. A teaser fails.
    • hiringOrganization — the company, not the branch nickname. Name plus a sameAs URL to the official site.
    • jobLocation — where the person reports. PostalAddress with addressCountry. For a 100% remote role, use jobLocationType TELECOMMUTE plus applicantLocationRequirements instead.
    • datePosted — original post date in ISO 8601. Do not refresh it to fake newness.

    Recommended properties that matter for a restoration hire: validThrough (when the listing dies), employmentType (FULL_TIME, PART_TIME, CONTRACTOR, TEMPORARY, PER_DIEM), baseSalary as a MonetaryAmount with currency and unit (HOUR / YEAR), and identifier so you do not duplicate the same role across reprints.

    AIOSEO’s walkthrough (updated August 21, 2026) maps those fields into a Schema Generator: title, description, employment type, location, hiring organization, salary, requirements, publish date, expiration date. Rank Math exposes the same JobPosting type. Fill the fields from the visible page. Do not invent a salary in schema that is missing on the page.

    GEO: mark the city the truck leaves from

    Local service hiring is geographic. A candidate searching “water damage technician jobs Everett WA” or “IICRC tech hiring Lynnwood” is not looking at a national career hub. Put the reporting city in the visible copy and in jobLocation.addressLocality / addressRegion / postalCode / addressCountry.

    Worked example for a shop that stages out of Everett and runs the Lynnwood–Mukilteo–Mill Creek pack:

    • Title on the page and in schema: Water Mitigation Technician
    • hiringOrganization.name: the legal company name, not “Everett Crew”
    • jobLocation: Everett, WA, United States, with the real street if that is where they report
    • description: names the pack — Everett, Lynnwood, Mukilteo, Mill Creek — as service area, not as four fake job locations
    • employmentType: FULL_TIME or PER_DIEM, whichever is true
    • validThrough: a real close date, then take the page down or set the date in the past when the seat is filled

    Do not stamp four JobPosting graphs on one page for four cities unless there are four distinct open seats. Google wants one job per leaf URL. A list page of “all openings” is the wrong surface.

    AEO: write the vacancy so an engine can quote it

    Schema does not rescue thin copy. Open the careers page with the answer a model can lift:

    We are hiring a full-time water mitigation technician based in Everett, Washington. The role reports to our Everett shop and runs losses across Snohomish County. Pay is listed on this page. Apply on this page.

    Then the body: first-day duties, IICRC or in-house training, on-call expectations, what “storm mode” means, whether the truck is assigned. That paragraph is the description field. If ChatGPT or Gemini is asked “who is hiring restoration technicians near Everett,” the engine needs a quotable sentence plus an organization it can attach to a maps entity. JobPosting is the attachment point. The sentence still has to exist in public HTML.

    How to hang it in WordPress

    1. Create one WordPress post or page per open seat. Slug like /careers/water-mitigation-technician-everett/.
    2. Write the full vacancy on the page first. Salary, city, dates, how to apply.
    3. In Rank Math (this site) or AIOSEO Schema Generator (if that is the client stack), add schema type JobPosting. Map every field to visible text.
    4. Validate with Google’s Rich Results Test. Fix errors before you call it done.
    5. When the seat fills: set validThrough to a past date, or 404/410 the URL. Do not leave a live JobPosting on a closed role.

    AIOSEO 4.9.9 made that generator available on Basic instead of reserving it for higher tiers. If a client already pays for AIOSEO, they do not need an upgrade to mark up jobs. If they are on Rank Math, they already had the type. Do not switch plugins to chase a newsletter.

    What gets a listing dropped

    • Markup on a jobs index that lists many roles
    • Title or salary in schema that the page does not show
    • Expired jobs still marked active
    • No way to apply on the page
    • jobLocation missing addressCountry, or a “remote” job that is not actually remote
    • Keyword stuffing in the title (“#1 BEST WATER TECH JOBS SEATTLE EVERETT TACOMA”)

    Google can issue a manual action for job spam. Fake seats used as lead magnets are not a grey area. If you are not hiring, do not hang JobPosting.

    The line to remember

    A careers page without JobPosting is a flyer. JobPosting without a real, dated, city-true vacancy is spam. Host the seat on your domain, mark the five required fields, expire it when the truck is staffed, and let Google decide whether it belongs in the job experience.

    FAQ

    Q: Does JobPosting schema guarantee a listing in Google for Jobs?
    A: No. It makes a qualifying page eligible. Google still applies content and spam policies. The official spec is explicit on that point.

    Q: We only hire on Indeed. Should we still put jobs on our site?
    A: If you want the vacancy attached to your entity — maps profile, site, AI answers — yes. The board can stay as an apply path. The leaf page on your domain is what you can mark up.

    Q: Can one page cover Everett, Tacoma, and Belfair?
    A: One page can describe a service area. Schema jobLocation should be the report-to city. Separate open seats in separate cities need separate URLs.

    Q: Is this an AIOSEO-only feature?
    A: No. AIOSEO expanded plan access in 4.9.9 (announced July 13, 2026). Rank Math and hand-written JSON-LD can emit the same type. Use the generator you already pay for.

    Q: What if we do not publish pay?
    A: baseSalary is recommended, not required. Do not invent a number in JSON-LD. Leave it out until the page states pay.

  • I open-sourced my page-readiness scorer

    I open-sourced my page-readiness scorer

    I built a small tool called PageReady. It scores a web page for two kinds of readiness, and today I’m putting it on GitHub for anyone to use however they want. MIT license. As-is. No support desk.

    Repo: https://github.com/TygartMedia/page-ready

    What it actually checks

    Most page audits give you a score out of 100 and a list of suggestions you’ll never get to. PageReady is binary: PASS or FAIL, on two axes.

    1. Citation readiness (AEO). Can an AI answer engine cite this page? It checks for one H1, a sane heading hierarchy, JSON-LD structured data, a table signal, and FAQ-style questions — the things that make a page quotable.

    2. Agent interaction readiness (DOM). Can an AI agent actually use this page? It checks for a main landmark, named controls, semantic interactive elements, heading order, and form labels — the things that make a page operable.

    Overall PASS requires both. And here’s the insight that made the tool worth building: fixing your headings can lift the shared heading gate, but it does nothing for clickable div cards. A page can be perfectly citable and completely unusable by an agent. Most audits conflate the two. They’re different problems.

    How you use it

    It’s a local command-line tool, a stdio MCP server, and an optional HTTP API you can host yourself (there are Cloud Run deploy scripts). No API keys required — it scores pages directly, nothing phones home.

    As an MCP server it exposes three tools:

    • score_page — score one public URL, returns a JSON scorecard
    • score_site — score a batch of URLs, with pass/fail counts
    • explain_gates — describe every check and the overall PASS rule

    Point your agent at it and ask whether a page is ready. Exit code 0 means PASS. Exit code 1 means FAIL. That’s the whole interface.

    Why open source, why as-is

    The scoring logic was never going to be the moat. It’s a commodity check — the value is in knowing which pages to run it on and what to do with the answer. That’s the work I do with clients every week, and no repo replaces it.

    So the repo is bait, not the business. If it saves another developer an afternoon, good. If someone forks it and makes it better, better. If a competitor forks it closed and sells it — the MIT license allows that, and I’m fine with it. The relationships are the hook; the tool is just proof I do the work.

    As-is means as-is. No SLA, no roadmap, no support promise. Issues are read on a best-effort basis. I’d rather ship something useful with no promises than maintain something mediocre with a changelog.

    The receipts

    Before publishing, the repo went through a pre-publish scrub (secrets sweep, license, README rewrite), then three independent model reviews: a security audit (SAFE), a correctness pass (no bugs), and a docs review (pass). The scrub caught one hardcoded cloud project ID, which is now an environment variable (GCP_PROJECT). That’s the whole incident report.

    Use it however you want. That’s the point.

  • A License Key Can Backfill Schema. It Cannot Invent the Facts.

    A License Key Can Backfill Schema. It Cannot Invent the Facts.

    Last verified: 7 September 2026. Read from an AIOSEO email to will@tygartmedia.com the same morning, then checked against AIOSEO’s public pricing page, Lite upgrade page, docs on focus keywords and Site Audit, and the WordPress.org plugin listing. No affiliate links. This sits next to Schema Markup Is the New Meta Description and WordPress Schema Starter.

    Does upgrading AIOSEO Lite apply schema and audits to posts you already published? Yes, in the plugin. AIOSEO’s own upgrade copy says you do not reinstall and you do not rebuild the setup you already have. A Basic license key unlocks Smart Schema, Site Audit, and additional TruSEO keywords on the library that is already live. That is a feature flag. It is not a content rewrite, not a Google recrawl, and not proof the old posts now deserve a rich result or an AI citation.

    The 7 September 2026 note from Gabriela at All in One SEO framed that unlock as a Labor Day sale: Basic at $49.50 for a limited time against a $99 list. The public pricing page already lists the same first-year number. Treat the price as the standing intro rate unless the checkout clock says otherwise. Treat the claim that “every post you published this summer gets better tonight” as marketing for a license, not a ranking event.

    A license key can turn markup on. It cannot invent the entities the markup is supposed to describe.

    The operator line

    Key takeaways

    • AIOSEO Lite is not empty SEO. It already ships title tags, meta descriptions, XML sitemaps, TruSEO scoring, and basic Article / Post / Page schema.
    • Paid Basic (public list $99 / first-year $49.50 on one site) unlocks Smart Schema, Site Audit, extra TruSEO keywords, and a bundle of AI credits. That change applies to existing posts without a reinstall.
    • AIOSEO docs cap additional keywords at ten beside the focus term. Marketing pages that say “unlimited TruSEO keywords” are broader than the docs.
    • Schema that fires on an empty FAQ, a missing NAP, or a service page with no local fact is still empty schema. Answer engines will not rescue it.

    What the email actually said

    The note was written to a Lite install. Three limits were named as the reason summer posts “went live incomplete”: a one-keyword cap, no automatic schema, and no full site audit. The promised fix was a license key. Schema would activate site-wide. The audit would surface what held individual pages back. TruSEO’s keyword limit would lift on everything already written. No reinstall.

    Two of those three limits are real product gates. One is sales language.

    • Keyword cap — real, with a ceiling. Lite scores one focus keyword. Paid plans add more. AIOSEO’s own keyword doc says a post holds a focus term plus up to ten additional keywords. The email said the limit “lifts.” The doc says it lifts to a number.
    • Site Audit — real paid gate. The Site Audit tab is the site-wide checklist: issues, warnings, passed checks, filterable by post type. Lite users do not get that scan. Paying turns it on against the library you already have.
    • “No automatic schema” — overstated. Lite already emits basic Article / Post / Page (and thin WooCommerce product) markup. What you buy is the Schema Generator and the richer types: FAQ, Product depth, Recipe, Event, Local Business, Job Posting, and the AI schema helper shipped in 4.9.6. “No schema” is the pitch. “Thin schema” is the install.

    What “retroactive” means in a plugin

    Most WordPress SEO plugins generate JSON-LD at request time. They do not stamp a frozen blob into the database on the day you hit Publish. Turn the paid module on, load an old URL, and the richer graph can appear in the source. That is the honest version of “the upgrade works retroactively.”

    What it is not:

    • It is not Google Search Console requesting a recrawl of every summer URL.
    • It is not an AI Overview or a ChatGPT citation flipping overnight.
    • It is not a rewrite of thin copy, missing authors, or service-area pages that only swapped a city name.
    • It is not a guarantee that Rich Results Test will pass. Invalid or empty fields still fail.

    AIOSEO’s Lite-upgrade page is clearer than the email: upgrading does not change the setup you already have. It unlocks modules on top. Believe that sentence. Do not believe “gets better tonight” as a traffic forecast.

    WHAT A KEY UNLOCKS VS WHAT A PAGE STILL NEEDS 1 PLUGIN FLAG schema module on audit tab visible 2 VALID GRAPH required fields filled Rich Results Test 3 TRUE PAGE entities, NAP, FAQ answers a real query 4 INDEX / CITE crawl + eligibility not a license event The sale sells layer 1. Operators get paid on layers 2 through 4.

    What Basic actually buys in 2026

    Checked on aioseo.com/pricing the morning of 7 September 2026. First-year Basic is $49.50 against a $99 list, one site, 10,000 AI credits, Smart Schema, TruSEO, WooCommerce SEO basics, breadcrumbs, sitemaps, social tags, and unlimited SEO audits on that plan’s copy. Plus adds Local Business SEO and Author SEO. Pro adds Link Assistant, advanced redirects, video and news sitemaps. Elite adds Search Statistics and rank tracking. WordPress.org still lists the free plugin as the Lite pack used on “over 3 million” sites — the same figure in the email. Paid plans carry a 14-day money-back line in AIOSEO’s own materials.

    Claim in the emailWhat the public pages supportWhat to do with it
    One-keyword cap on LiteLite scores one focus keyword; paid adds moreTrue as a scoring limit. Google never saw only one keyword because you typed one in TruSEO.
    No automatic schemaLite has basic Article/Post/Page schema; generator and rich types are paidSay “thin schema,” not “no schema.”
    No full site auditSite Audit is a paid moduleTrue. Run it after the key, then fix pages, do not screenshot the score.
    Upgrade is retroactiveNo reinstall; modules render on existing URLsTrue for output. False as a ranking promise.
    Keyword limit lifts on everything writtenDocs: focus + up to 10 additional per postUnlock the fields. Do not spray ten synonyms into old posts.
    Basic is $49.50 for a limited time (reg. $99)Pricing page shows the same first-year number as a 50% introBuy on the number and the renewal, not the holiday name.
    The email is a sales wrapper around real gates. Quote the docs when you brief a client.

    Why this matters if you already run Rank Math

    Tygart Media runs Rank Math on this site. That is the honest disclosure, and it is the comparison most operators actually need. Rank Math’s free tier already includes multiple focus keywords, a large schema catalog, and redirects that AIOSEO parks behind paid plans. Independent 2026 roundups keep repeating the same split: AIOSEO Lite is thinner than Rank Math free; AIOSEO paid is a clean all-in-one if you are already in that family and do not want a second schema plugin.

    Do not stack AIOSEO and Rank Math. Do not stack either with Yoast. Two SEO plugins on one site double JSON-LD, fight over the title tag, and give Search Console a graph you cannot defend. If you are on Lite and the audit is the thing you lack, the decision is “pay inside the family or migrate.” It is not “install both for Labor Day.”

    The AEO and GEO problem the sale does not name

    Answer engines and generative engines do not award a rich result to a plugin brand. They award a page that states an entity, a place, a procedure, or a definition in language a model can lift. Schema is the label on that statement. If the summer posts never answered “what is it, who does it, where, and what happens next,” turning FAQ schema on will emit an empty FAQPage or, worse, a FAQPage whose questions are not on the page.

    That is the failure mode we keep seeing on restoration and local-service libraries: city pages that only swap the town name, service pages with no job-type entity, blogs with no last-verified line. A license key will happily wrap that in JSON-LD. Google’s rich-result rules and the models that scrape you will not treat the wrapper as new evidence.

    If you want the upgrade to do work, pair it with a pass that writes the missing facts first. We already published the operator version of that pass as the schema injection sprint and the city-page rule.

    What to do this week instead of arguing with the banner

    1. Name the plugin you already run. If it is Rank Math or Yoast Pro, ignore the AIOSEO Lite email. You are not the audience.
    2. If it is AIOSEO Lite, export a 20-URL sample of summer posts. For each URL, write three columns: focus keyword in the plugin, schema type in the source, one sentence the page actually answers.
    3. Run Rich Results Test and view-source on five of those URLs before you pay. Know the baseline.
    4. If you buy Basic, add the key, then re-test the same five URLs. Confirm the graph changed. Do not add ten extra keywords to every post on day one.
    5. Use Site Audit as a punch list, not a score. Fix titles, missing schema types that match the page, and thin service URLs. Then request indexing on the URLs you actually changed.
    6. Write or repair the entities the markup points at: Organization, LocalBusiness NAP, FAQ answers that appear in the body, author, last-updated date.

    FAQ

    Does an AIOSEO upgrade fix old posts automatically?

    It unlocks paid modules on those posts. Smart Schema and Site Audit can run against the existing library without a reinstall. Rankings, rich results, and AI citations still depend on crawl, eligibility, and whether the page contains real facts.

    Does AIOSEO Lite include any schema?

    Yes. Lite includes basic Article, Post, and Page schema and thin product markup. The Schema Generator and richer types sit on paid plans.

    How many TruSEO keywords do you get after you pay?

    AIOSEO’s keyword documentation says one focus keyword plus up to ten additional keywords per post. Marketing pages sometimes say “unlimited.” Use the doc when you set a process.

    Is Basic $49.50 only for Labor Day 2026?

    The email called it a Labor Day sale. The public pricing page the same morning already listed Basic at $49.50 against a $99 list as a first-year intro. Confirm the renewal price at checkout. AIOSEO states a 14-day money-back window on paid plans.

    Should you install AIOSEO next to Rank Math to get the sale?

    No. Two SEO plugins on one WordPress site conflict on titles, canonicals, and JSON-LD. Stay in one family or migrate. Do not stack.

    Close

    AIOSEO is allowed to sell a key. Operators are not required to treat the key as a content strategy. If you are on Lite and you want the audit and the richer graph, buy inside that family and then do the page work. If you are already on a fuller free tier, the email is not your queue.

    Turn markup on only after the page can stand without it.


    Sources

    Will Tygart — Tygart Media. Written 7 September 2026 from the Command Center. Tygart Media runs Rank Math on this site. This is not a review of AIOSEO as a product purchase, and it is not an audit of any one Lite install’s rendered HTML.

  • SiteBoost — Site Connection & Audit

    SiteBoost — Site Connection & Audit

    SiteBoost — Site Connection & Audit

    $297

    Delivered by email after checkout.

    Buy Now →

    Secure checkout via Square — all major cards accepted

    You can copy this method and connect and audit the site yourself. Buy Now is Will doing the one-time setup: Application Password, REST API check, full inventory, and the baseline reports.

    Site Connection and Audit is a service. Square lists it as a one-time setup at $297. It is the front door for every other SiteBoost SKU. The public vertical pages include it inside the pilot. Alone, it is how a site gets on the board without anyone rewriting a post yet.

    Self-hosted WordPress only. REST API on (the default). Squarespace, Wix, and Webflow are not compatible. The /siteboost/ hub is blunt about that.

    How Will connects a site

    wp-connect is the gateway skill. Nothing else in the WordPress stack runs until this works. The 23-site stack article on tygartmedia.com puts a new site at about 20 minutes: Application Password, registry, first audit.

    1. Confirm the site is self-hosted WordPress. Open /wp-json/wp/v2/ in a browser. You should see a JSON index, not a 404. If the REST API is blocked, stop and fix that before anyone shares a password.
    2. In WordPress, go to Users → Profile (or Users → Application Passwords, depending on version). Create an Application Password for a user who can edit posts. Name it something you will recognize later, like “SiteBoost” or “REST audit.” Copy it once. This is not the login password. wp-connect will not use the login password.
    3. Test the connection. GET https://yoursite.com/wp-json/wp/v2/users/me with HTTP Basic auth, username plus the Application Password. A 200 with your user object means you are in. A 401 means the password or user is wrong. A 403 often means a security plugin is blocking REST for that user.
    4. Confirm you can list posts: GET /wp-json/wp/v2/posts?per_page=1&status=publish. If users/me works but posts 403, the user is missing the edit_posts capability.
    5. Write down: site URL, WordPress version if you can see it, hosting (WP Engine, SiteGround, Flywheel, Kinsta, Cloudflare in front, or other), whether Yoast / Rank Math / AIOSEO is present, and who holds the Application Password. Do not put the password in a public doc.

    The public SiteBoost pages name the hosts they have used this pattern on: WP Engine, Flywheel, SiteGround, Cloudflare-proxied sites, GCP Compute Engine, DigitalOcean, Kinsta, bare metal. The requirement is the REST API, not a specific host.

    Do not install a plugin to “help” the connection. SiteBoost’s rule is no plugins added to the client site. Application Passwords are built into WordPress 5.6 and later.

    What the audit checks

    wp-site-audit is the skill that runs at the start of any new site. Fetch all published posts (per_page=100, walk pages). For each post, score the same fields:

    • Word count. Thin is under 500 words.
    • Title tag and slug quality.
    • Excerpt / meta description present, empty, or polluted (raw JSON or leftover code in the excerpt is a real pattern; wp-clean-meta exists to strip it).
    • Categories and tags. Uncategorized is a fail. wp-taxonomy-fix wants 1 to 2 categories and 5 to 10 tags.
    • Featured image present or not.
    • Internal links in (orphans: nothing points here) and internal links out (dead-end posts).
    • Schema present or not, and which types if you can see them (Article, FAQPage, HowTo, BreadcrumbList, Speakable).
    • FAQ section present or not.
    • Outbound source citations present or not.

    Also roll up site-level numbers: total published posts, total pages (count them, do not edit them), taxonomy health (how many categories, how many unused tags, how many posts still Uncategorized).

    The 60-point WordPress SEO Audit Template on tygartmedia.com is the longer human version of this, in six categories: Technical, On-Page, Content, Schema, Local, Analytics. Tools it wants open: Google Search Console, Bing Webmaster Tools, PageSpeed Insights, your SEO plugin, validator.schema.org, an incognito window. Order matters: Technical first, then On-Page, Content, Schema, Local, Analytics. A quick pass is the high-impact rows. A full pass is a few hours the first time. Re-audit quarterly, and after a redesign, a migration, or a plugin purge.

    SiteBoost’s service audit, as sold, is the content-and-baseline cut of that: inventory, schema gaps, FAQ gaps, before numbers. It is not a Core Web Vitals engagement and it is not a local-pack rebuild. If you want the 60-point sheet as a Notion checklist, that is a different SKU (WordPress SEO Audit Template).

    The four reports you should produce

    The public SiteBoost pages name these deliverables. If you are doing this yourself, write the same four:

    1. Content inventory. One row per published post. URL, title, date, word count, category, meta yes/no, FAQ yes/no, schema yes/no, internal links in/out, notes.
    2. Schema gap report. Which posts have no JSON-LD. Which have plugin-bloated or invalid markup. Priority by page type (Article on posts, FAQPage where a FAQ exists or should, HowTo only on real procedures).
    3. FAQ gap report. Which posts have no Q and A block and no FAQPage schema. Those are the AEO queue.
    4. Before baseline. Search Console coverage and the queries / URLs you will watch. A short note on AI visibility for a handful of real questions in your market (do you show up in Perplexity or an AI Overview today?). Write the date. This is what a 60-day report compares to.

    Priority the way wp-site-audit does: Critical (taxonomy / metadata), High (SEO / AEO / thin content), then optimization (links, expansion). The recommended next skills, if you are running Claude, are wp-taxonomy-fix, wp-content-expand, wp-schema-inject, wp-interlink, then the refresh stack.

    What you do not do in this SKU

    • Do not rewrite posts. That is Existing Post Optimization or the Pilot.
    • Do not publish new articles. That is New Article Publishing.
    • Do not edit Pages, bios, or service templates unless the owner asked in writing. Toolbox rule: posts, not pages.
    • Do not leave the Application Password in chat logs or a public Notion page.
    • Do not claim results. You do not have a after yet. You have a before.

    If you want Will to connect and audit

    You can create the Application Password and fill a spreadsheet this afternoon. Buy Now is Will doing the connection and the four reports, then emailing you the baseline and the recommended ten. Same Square button at the top. $297, one time.

    The Pilot Bundle includes this connection plus ten post optimizations and the 60-day report. The Monthly Retainer assumes the site is already connected. If you only want the skill files so your own Claude can connect and audit, that is the WordPress SEO Skill Pack (Starter has wp-connect, wp-post-fetch, and wp-site-audit).

    Frequently Asked Questions

    How does it work?

    After checkout, I reach out by email within 2 business days with the intake details and a start date.

    Is there a refund policy?

    Before work starts on your posts, full refund on request. Once a post is optimized or published, that portion of the fee is earned.

    Related: SiteBoost. Also SiteBoost — Pilot Bundle.

  • WordPress SEO Skill Pack – Pro

    WordPress SEO Skill Pack – Pro

    >

    Direct Answer / Product Definition

    WordPress SEO Skill Pack — Pro by Tygart Media is a $79 Square bundle of 14 Claude skills for self-hosted WordPress that run Will Tygart’s full post refresh pipeline: on-page SEO, AEO answer packets and FAQs, GEO entity and citation passes, JSON-LD schema injection, taxonomy cleanup, and hub-and-spoke interlinking. The wp-full-refresh skill orchestrates SEO → AEO → GEO → schema → interlink on one post; Tygart Media emails the .skill files within 24 hours of checkout.

    WordPress SEO Skill Pack — Pro

    $79

    14 .skill files delivered by email within 24 hours after Square checkout.

    Buy on Square — $79 →

    Secure checkout via Square — all major cards accepted

    Tygart Media documents the full three-layer refresh method on this page so operators can run SEO → AEO → GEO → schema → interlink in wp-admin or Claude. The $79 Buy on Square option delivers 14 packaged .skill files by email within 24 hours of checkout.

    Pro is the middle tier of the WordPress SEO Skill Pack by Will Tygart. It includes everything in Starter ($29), plus wp-aeo-refresh, wp-geo-refresh, wp-schema-inject, wp-taxonomy-fix, wp-interlink, wp-full-refresh, wp-content-pipeline, content-brief-builder, and content-quality-gate—the production sequence Tygart Media uses on a single WordPress post.

    Starter vs Pro vs Agency

    Tier Price Skills AEO / GEO / schema
    Starter $29 5 (connect, audit, clean-meta, seo-refresh) No
    Pro (this product) $79 14 incl. wp-full-refresh + pipeline Yes — full stack
    Agency $149 Pro + expand + new-site-setup + guides Yes + client onboarding

    Install and connect

    Same requirements as Starter. Claude Pro / Max / Team. Self-hosted WordPress. Application Password. Drop the skill files into Claude Desktop (Cowork) or Claude Code. Say “connect to my WordPress site.” wp-connect tests /wp-json/wp/v2/users/me. Stop if that is not a 200.

    The sales page’s operator line for this tier: “full refresh post 123.” That trigger is wp-full-refresh. It is the orchestrator. Do not start there on a site you have never audited.

    The 14 skills, in the order you should actually use them

    Foundation (from Starter)

    • wp-connect. Authenticate. Gateway.
    • wp-post-fetch. Load one post with context=edit.
    • wp-site-audit. Inventory, orphans, thin posts, missing meta, schema gaps. Run first on a new site.
    • wp-clean-meta. Strip excerpt pollution before you write new meta.
    • wp-seo-refresh. Title (about 60 characters), meta (about 155 to 160), slug, H2/H3, keyword in the first 100 words.

    Taxonomy, before you interlink

    wp-taxonomy-fix has two modes: one post, or site-wide. Design 3 to 7 top-level categories. Each post gets 1 to 2 categories (never Uncategorized) and 5 to 10 tags (topic, technology, use case, audience, format). Create missing terms via the API, assign, then normalize duplicate tags. Toolbox lists this as a prerequisite for wp-interlink. If categories are a junk drawer, your link graph will be a junk drawer.

    The same skill can write two-layer descriptions on category and tag archives: a 140 to 160 character meta excerpt, then a 400 to 600 word hub body with internal links to the top posts in that cluster. PATCH /wp/v2/categories/{id} and /wp/v2/tags/{id} on the description field. Most themes print that above the post grid.

    The three-layer refresh

    wp-aeo-refresh. Direct-answer opening, question H2s, FAQ pairs, list-shaped answers, FAQPage schema. SiteBoost existing-post copy uses a 40 to 60 word definition box and 6 to 8 FAQs. The older publish skill used 3 to 5. Use the PAA list in front of you, not a fake number.

    wp-geo-refresh. Entity saturation, factual density, context richness, source attribution, topical breadth, semantic clarity. Schema it adds: richer Article metadata, entity markup, Speakable. The citing-sources article is the house rule: name the organization, link the primary source, sources list at the bottom, visible last-updated, dateModified in schema. No fabricated stats.

    wp-schema-inject. Detect the type the post actually is and inject JSON-LD. The schema injection sprint’s menu: FAQPage, Article, HowTo, Service, LocalBusiness, Speakable, BreadcrumbList. Validate with Google’s Rich Results Test. Fix failures. Do not leave plugin-bloated invalid markup in the body.

    wp-interlink. Hub and spoke, orphan resolution, contextual links. The Copilot / cluster articles on tygartmedia.com use 3 to 5 related posts in the same topical group, descriptive anchors. Do this after the post has a real topic and a real category, not before.

    wp-full-refresh. Runs SEO + AEO + GEO + schema + interlink in that sequence on one existing post. This is the “do everything to this post” skill. Use it when the audit already said the post is worth the pass.

    New content, not just refreshes

    content-brief-builder. Keyword research to a brief, before anyone writes. Feeds the pipeline. A brief that cannot name the query, the intent, the PAA list, and the internal-link targets is not a brief.

    wp-content-pipeline. Draft to live: write → SEO → AEO → GEO → schema → taxonomy → interlink → publish. Toolbox order. Same six-step human workflow as the New Article Publishing page, encoded as a skill chain.

    content-quality-gate. Pre-publish. Unsourced claims and fabricated numbers get flagged. Run this before any publish, batch or single. The operator guide’s failure mode is the same: fake density backfires when an AI system checks you.

    A Pro session on one site

    1. Connect. Audit. Clean polluted excerpts.
    2. Fix taxonomy on the posts you are about to touch (and on the hub category if it has no description).
    3. For each chosen existing post: wp-full-refresh, or the layers by hand in SEO → AEO → GEO → schema → interlink order.
    4. For a new article: brief → pipeline → quality gate → publish.
    5. IndexNow on every URL you created or updated. Confirm in Bing Webmaster Tools.
    6. Log before/after: title, meta, word count, FAQ count, schema types, internal links added.

    The operator guide’s weekly rhythm still applies if you are using Pro on a real site: Monday audit, Tuesday to Thursday execute, Friday verify. Pro is the toolkit. It is not a retainer.

    What Pro still does not include

    Agency adds three reference guides (SEO, AEO, GEO), wp-content-expand (deepen thin posts without overwriting), and wp-new-site-setup (client onboarding). If you are onboarding other people’s sites every week, that is the Agency door. If you want Will to run the posts instead of running skills, that is SiteBoost.

    Frequently Asked Questions

    What is the WordPress SEO Skill Pack — Pro?

    WordPress SEO Skill Pack — Pro by Tygart Media is a $79 bundle of 14 Claude skills that run the production post refresh sequence on self-hosted WordPress: SEO, AEO, GEO, schema injection, taxonomy fix, and interlink, plus wp-full-refresh orchestration and a new-content pipeline with a quality gate.

    What is the difference between Starter and Pro?

    Starter ($29) includes five skills for connect, audit, clean-meta, and on-page SEO only. Pro ($79) adds wp-aeo-refresh, wp-geo-refresh, wp-schema-inject, wp-taxonomy-fix, wp-interlink, wp-full-refresh, content-brief-builder, wp-content-pipeline, and content-quality-gate.

    What does wp-full-refresh do?

    wp-full-refresh is Tygart Media’s orchestrator skill. On one existing post it runs SEO refresh, then AEO refresh (definition box and FAQ-oriented content), then GEO refresh (entity saturation and citations), then schema injection, then interlinking—in that fixed order.

    Does Pro include Agency onboarding skills?

    No. Tygart Media’s Agency tier ($149) adds reference guides, wp-content-expand for thin posts, and wp-new-site-setup for client onboarding. Pro is the production refresh and pipeline stack without those agency-only skills.

    If you want the packaged files

    You can run every layer above in the block editor with a checklist. Buy Now is the 14 .skill files delivered by email after checkout. Same Square button at the top. $79.

    Starter is the five-skill on-page subset if you only need connect / audit / SEO refresh. Agency is this stack plus onboarding and expansion.

    $79

    14 .skill files — email delivery within 24 hours via Square.

    Buy on Square — $79 →

    Related Products

    Skill Pack ladder: Hub · Starter ($29) · Agency ($149) · Tygart Media Shop.

    Author: Will Tygart, Founder of Tygart Media — the same AEO/GEO/SEO skill stack used on the Tygart Media WordPress fleet.

    Related on Tygart Media: how to use Claude · Anthropic API key.

  • SiteBoost — Pilot Bundle (Best Value)

    SiteBoost — Pilot Bundle (Best Value)

    SiteBoost — Pilot Bundle (Best Value)

    $597

    Delivered by email after checkout.

    Buy Now →

    Secure checkout via Square — all major cards accepted

    You can copy this method and run a ten-post pilot yourself. Buy Now is Will connecting the site, picking the ten, running the three-layer pass on each, and sending the 60-day impact report.

    The Square catalog names this SKU “Connection + 10 Posts.” The /siteboost/ hub calls it the best-value door at $597. The public vertical pages (law firms and the rest of the cluster) spell out the same package: Site Connection and Audit, ten existing-post optimizations, and a 60-day impact report. They price the pieces at $767 if you bought them separate ($297 audit + 10 × $47). The bundle is the cheaper way to get a first measured pass.

    Stack of unmarked folders and a laptop on an agency desk

    What the pilot is, and is not

    It is a retrofit of ten published posts. SEO + AEO + GEO + schema on each. Changes via the WordPress REST API. No plugin left behind. Results looked at around day 60. It is not a retainer, not a redesign, and not ten brand-new articles. New Article Publishing is a different SKU. The monthly retainer is the ongoing door after you like the pilot.

    Self-hosted WordPress only. Squarespace, Wix, and Webflow are out. Posts, not Pages, unless you put a specific Page in writing.

    How to run the pilot yourself

    Week 0. Connect and baseline

    Do the connection and audit first. The method is on the Site Connection and Audit page. Short version:

    1. Create a WordPress Application Password (Users → Profile). Not the login password.
    2. Test GET /wp-json/wp/v2/users/me with that user and app password. If that fails, stop. Nothing else will work.
    3. Pull published posts (per_page=100, paginate if you have more). Inventory every post: title, slug, word count, excerpt/meta, categories, tags, featured image, internal links in, internal links out, schema present or not, FAQ present or not.
    4. Write four artifacts and keep them. Content inventory. Schema gap report. FAQ gap report. Before baseline (the numbers you will compare at day 60: rankings and impressions you can actually see in Search Console, plus a note on AI visibility if you check Perplexity / ChatGPT / AI Overviews on a few queries).

    wp-site-audit’s priority stack: Critical = taxonomy and metadata problems. High = SEO / AEO / content quality. Then link and expansion opportunities. Use that order when you pick the ten.

    Pick the ten

    Highest-opportunity existing articles, with your approval before anyone starts rewriting. That is the rule on the public SiteBoost pages. A practical pick list, from the same audit fields:

    • Posts that already get impressions but have empty meta, no FAQ, and no schema. Those move first.
    • Posts over 500 words that are still missing the AEO and GEO layer. Do not spend the pilot on stubs.
    • Posts that sit on a real query (you can name the keyword). Skip diary posts and leftover test content.
    • A mix across your actual topic pillars, not ten posts from one tag.

    Write the ten URLs down. Get a yes. Then do not swap them mid-pilot unless a post is broken.

    Weeks 1 to 3. Ten existing-post passes

    For each of the ten, run the same method as Existing Post Optimization:

    1. SEO: title 50 to 60, slug, meta 140 to 155, H2/H3, keyword in the first 100 words.
    2. AEO: 40 to 60 word definition box, question H2s with 40 to 60 word answers, 6 to 8 FAQ pairs, FAQPage JSON-LD.
    3. GEO: named entities, sourced facts, speakable blocks, LLMS.txt comment, last-updated + dateModified.
    4. Article schema. Validate. Two to five internal links into the rest of the cluster. IndexNow on the update.

    Sequence on a single post is SEO, then AEO, then GEO, then schema, then interlink. That is wp-full-refresh. Do not GEO a post whose title and meta are still empty.

    If a chosen post is under 500 words, expand it first (append real sections, do not overwrite) or swap it for a thicker post on the same topic. Thin content wastes a slot.

    Day 60. Impact report

    The public pages measure three things: traditional rankings and impressions, People Also Ask / snippet placements, and AI citation visibility. Pull Search Console for the ten URLs (and the queries they were aimed at) versus the before baseline. Recheck the same AI prompts you wrote down in week 0. Do not invent a win. If nothing moved, say so. The report is the point of a pilot. You are deciding whether a retainer is worth it.

    Traditional SEO on competitive terms is often 60 to 90 days. The same pages note that FAQPage / PAA and some AI crawlers can show sooner (they cite 2 to 4 weeks for PAA). Treat those as ranges from the public SiteBoost copy, not a guarantee.

    What you should have on disk at the end

    • Connection notes (site URL, that an app password was created, who holds it).
    • The four audit artifacts from week 0.
    • The list of ten URLs and the before/after for each (title, meta, word count, FAQ count, schema types).
    • The 60-day comparison. What moved, what did not, what you would do next (more existing posts, new articles, or stop).

    If you want Will to run the pilot

    You can do every step above with an Application Password and a spreadsheet. Buy Now is the packaged pilot: Will connects, audits, agrees the ten with you, runs the three layers on each post, and sends the 60-day impact report. Same Square button at the top. $597.

    After a pilot you like, the Monthly Retainer is 10 existing-post passes plus 4 new articles per month. If you only need the connection and the baseline, buy Site Connection and Audit. If you only need one post touched, buy Existing Post Optimization.

    Frequently Asked Questions

    How does the pilot work?

    After checkout, I reach out by email within 2 business days to kick off: I connect the site, we agree on the ten posts, I run the three-layer pass on each, and you get the 60-day impact report.

    Is there a refund policy?

    Before I start the pilot work, full refund on request. Once posts are in production, the fee is earned — the 60-day report is yours either way.

    Related: SiteBoost. Also SiteBoost — Site Connection & Audit.