Tag: Schema Markup

  • SiteBoost — New Article Publishing

    SiteBoost — New Article Publishing

    SiteBoost — New Article Publishing

    $97

    Delivered by email after checkout.

    Buy Now →

    Secure checkout via Square — all major cards accepted

    You can copy this method and publish the article yourself. Buy Now is Will researching, writing, optimizing, and publishing one new WordPress post for you.

    SiteBoost New Article Publishing is a new post, not a refresh of something already live. The /siteboost/ hub prices it at $97 per article. The same three layers as an existing-post pass still apply. You just start from a brief instead of from a published URL.

    The six-step workflow

    This is the unified content workflow from the operator’s guide on tygartmedia.com. One draft. SEO, AEO, and GEO built in. Not three versions of the same piece.

    1. Keyword and intent

    Name the target query. Classify intent: informational, navigational, commercial, or transactional. Look at what already ranks and match the format Google is already rewarding. This step is ordinary SEO. Do not skip it because you are “writing for AI.”

    2. Question landscape

    Search the keyword. Collect People Also Ask questions, related searches, and autocomplete variants. Group them. Those groups become H2s and FAQ items. The operator guide budgets 15 to 20 minutes here. This is the AEO setup. If you skip it, you will write headings that feel like an outline and not like queries.

    3. Write with the direct-answer pattern

    Write the article once, with both SEO and AEO in the draft:

    • Primary keyword in the H1 and in the first 100 words.
    • Every major section is a question-shaped H2, then a 40 to 60 word answer, then the depth.
    • Internal links with descriptive anchors to posts that already exist on the site. If the site is new and there is nothing to link to, note the gaps. Do not invent destinations.
    • A 40 to 60 word definition box near the top.

    The WordPress Publish skill’s quality bar before anything goes live: title 50 to 60 characters with the primary keyword, meta 140 to 160 characters, a unique H1, at least one direct-answer section, a FAQ with 3 to 5 Q and As on a new article (SiteBoost existing-post passes use 6 to 8; for a new article start at 3 to 5 and add more if the PAA list is real), Article JSON-LD, FAQPage JSON-LD, and at least one cited fact per major section.

    4. GEO enhancement

    After the draft exists, do a factual-density pass. The operator guide budgets 20 to 30 minutes on a 1,500-word article. For every claim: a number, a date, a named organization, or cut it. The citing-sources article is the house rule:

    1. Name the organization in the text, not only in a hyperlink.
    2. Link the primary source. If it is paywalled, link a credible secondary that cites it.
    3. Put a sources list at the bottom.
    4. Show a last-updated date near the byline.
    5. Put datePublished and dateModified in Article schema.

    Do not add fake statistics to look dense. The operator guide calls that out as a backfire when AI systems cross-check you.

    5. Schema

    Minimum on a new SiteBoost article: Article (or BlogPosting) plus FAQPage. Add HowTo if the piece is genuinely step-by-step. Add BreadcrumbList if the theme does not already emit it. Add Speakable on the definition box and one other self-contained block. JSON-LD in the post, validated with Google’s Rich Results Test. The schema injection sprint is the same sequence: pick the type, generate valid JSON-LD, inject, validate, fix failures.

    SiteBoost content standards also embed an LLMS.txt HTML comment on the page. A short seed paragraph, not a second article.

    6. Pre-publish audit, then publish

    Run the three-layer checklist. Title, meta, headings, snippet readiness, factual density, schema validation, entity signals. Then publish as a post, not a page.

    The production pipeline used on Tygart Media sites is: brief (content-brief-builder) to draft to SEO to AEO to GEO to schema to taxonomy to interlink to publish (wp-content-pipeline). content-quality-gate sits in front of publish and flags unsourced claims. You can do that as a human checklist if you are not running Claude skills.

    Taxonomy and internal links

    Assign 1 to 2 categories that are real content pillars, never Uncategorized. Assign 5 to 10 tags that cover topic, use case, audience, and format. That is the wp-taxonomy-fix rule. Then place 3 to 5 internal links to related posts in the same cluster, plus outbound links to the sources you named. Hub and spoke. The new post should not be an orphan on day one, and it should not be a dead end.

    IndexNow

    On publish, ping IndexNow. Official plugin, or Rank Math / Yoast Instant Indexing. Confirm the URL in Bing Webmaster Tools. New posts that sit in a sitemap waiting for a crawl waste the first week.

    What “done” looks like on one new article

    1. Brief: target keyword, intent, PAA list, existing internal-link targets, sources you will actually cite.
    2. Draft written with definition box, question H2s, and sourced facts.
    3. Title 50 to 60, meta 140 to 160, slug clean.
    4. FAQ section + FAQPage schema. Article schema with both dates.
    5. Categories and tags set. 3 to 5 internal links. Sources list.
    6. Rich Results Test pass. IndexNow ping. Status = publish (or draft if you want a human read first).

    Self-hosted WordPress only. Squarespace, Wix, and Webflow are not this SKU. Do not modify existing Pages to “make room” for the article. Publish a post.

    If you want Will to write and publish it

    You can run the six steps in your own editor. Buy Now is the packaged, done-for-you article: Will writes it, runs the three layers, publishes it to your site, and emails you the URL. Same Square button at the top. $97 per article.

    A single new post next to a neglected library is a weak play. If the existing posts are empty of FAQ, schema, and meta, optimize those first (Existing Post Optimization, or the Pilot Bundle for ten). If the site is not connected yet, start with Site Connection and Audit.

    Frequently Asked Questions

    How does it work?

    After checkout, I reach out by email within 2 business days with the intake details and a start date.

    Is there a refund policy?

    Before work starts on your posts, full refund on request. Once a post is optimized or published, that portion of the fee is earned.

    Related: SiteBoost. Also SiteBoost — Existing Post Optimization.
  • SiteBoost — Existing Post Optimization

    SiteBoost — Existing Post Optimization

    SiteBoost — Existing Post Optimization

    $47

    Delivered by email after checkout.

    Buy Now →

    Secure checkout via Square — all major cards accepted

    You can copy this method and do it yourself on one published WordPress post. Buy Now is Will running the same three-layer pass on that post and pushing the changes live for you.

    SiteBoost Existing Post Optimization is one post, already on your site. Not a new article. Not a redesign. The public SiteBoost pages call this the post-publish layer: SEO, then AEO, then GEO, written back through the WordPress REST API. No plugin install. Self-hosted WordPress only.

    What you are optimizing

    Pick one published post (post type post, not a Page). Fetch it. Read it as it sits today. Then run three passes in this order. The operator guide on tygartmedia.com is explicit: the layers are concentric, not three separate rewrites. One piece of content. Structure, density, and markup.

    Pass 1. SEO

    This is the foundation. Do not skip it to chase snippets or AI citations. The SiteBoost vertical pages and the wp-seo-refresh skill agree on the same fields:

    1. Title tag. Primary keyword front-loaded. Target 50 to 60 characters. This is the H1 / browser title, not a clever headline that hides the query.
    2. Slug. Lowercase, hyphenated, keyword-rich. Change it only if the current slug is junk. If the post already ranks on the old URL, leave the slug and add a redirect if you must change it.
    3. Meta description. 140 to 155 characters on the SiteBoost sales pages, 155 to 160 in the wp-seo-refresh skill. Write a real sentence a human would click. Empty meta is the most common miss.
    4. Heading structure. Real H2 / H3 hierarchy. No skipped levels. No H2 that is just a label with no answer under it.
    5. Primary keyword in the first 100 words.
    6. Note internal link opportunities. You will place them after the GEO pass, not while you are still rewriting the title.

    Workflow from wp-seo-refresh: fetch the post with context=edit, analyze current on-page SEO, name the target keyword from the actual topic, generate the new title / meta / headings, write the post back, then report what changed.

    Pass 2. AEO

    Answer Engine Optimization. Same post. Restructure so a featured snippet or a People Also Ask box can lift a clean answer.

    1. Add a 40 to 60 word definition box near the top. One sentence that answers “what is this?” without a wind-up.
    2. Turn implied questions into H2s. Under each H2, put a 40 to 60 word direct answer, then the depth.
    3. Add 6 to 8 FAQ pairs that match real People Also Ask questions for the topic. The older WordPress Publish skill used 3 to 5. The SiteBoost vertical pages use 6 to 8. Use 6 to 8 on a SiteBoost-style pass.
    4. Add FAQPage JSON-LD for those pairs. Question and acceptedAnswer. Valid markup, not a plugin dump.

    wp-aeo-refresh also looks for list-shaped answers and natural-language replies a voice result can read. If a section is a process, a numbered list beats a paragraph.

    Pass 3. GEO

    Generative Engine Optimization. Make the post citable by ChatGPT, Perplexity, Claude, Gemini, and Google AI Overviews.

    1. Entity saturation. Name the real organizations, standards, statutes, places, and tools the topic depends on. Entity density, not keyword stuffing.
    2. Factual density. Replace “many companies” and “studies show” with a named source and a number you can actually point to. If you cannot name the source, cut the claim. The citing-sources article on tygartmedia.com is the rule: name the organization in the text, link the primary source, put a sources list at the bottom.
    3. Speakable blocks. Short, self-contained sentences an AI or a voice assistant can lift without the rest of the page.
    4. LLMS.txt as an HTML comment. A seed paragraph the page can carry for LLM citation signals. SiteBoost content standards put this on every page.
    5. Visible last-updated date near the byline, and dateModified in Article schema that matches a real edit. Do not bump the date without changing the content.

    wp-geo-refresh also asks for context richness (define the term, do not just mention it) and semantic clarity (connect related concepts in the same section).

    Schema and IndexNow

    After the three passes, the post should carry Article JSON-LD (headline, author, publisher, datePublished, dateModified) plus FAQPage. BreadcrumbList if the theme does not already emit it. Validate with Google’s Rich Results Test before you walk away. The schema injection sprint on tygartmedia.com is the same rule: pick the type the content actually is, inject JSON-LD, validate, fix failures.

    Then tell the engines the URL changed. IndexNow: official WordPress plugin, or the IndexNow / Instant Indexing toggle in Rank Math or Yoast. Confirm the ping in Bing Webmaster Tools. A publish or an update that nobody recrawls is a pass you did for yourself.

    What you do not touch

    Posts, not Pages. SiteBoost does not rewrite service pages, bios, or the homepage unless someone asked in writing. Do not install a plugin to do this. Do not empty the excerpt into raw JSON. If the excerpt is polluted, strip it (that is the wp-clean-meta job) and write a real meta description.

    A honest one-post checklist

    1. Current title, slug, meta, word count, FAQ count, schema present or not. Write those six lines down. That is your before.
    2. SEO pass. Title, slug, meta, headings, first 100 words.
    3. AEO pass. Definition box, question H2s, 6 to 8 FAQs, FAQPage schema.
    4. GEO pass. Named entities, sourced facts, speakable lines, LLMS.txt comment, last-updated + dateModified.
    5. Two to five internal links to related posts on the same site, descriptive anchors, plus one or two outbound links to primary sources.
    6. Validate schema. Ping IndexNow. Write the after: new title, new meta, new word count, FAQ count, schema types.

    If the post is under 500 words, expand it before you call the SEO pass done. wp-content-expand’s rule: find H2s under 150 words, add 250 to 400 words of real section, append, do not overwrite. Thin posts do not earn the AEO or GEO layer.

    If you want Will to do this post

    You can run the three passes in the block editor this afternoon. Buy Now is the packaged, done-for-you version: Will connects, refreshes that one existing post through the REST API, and emails you what changed. Same Square button at the top of this page. $47 per post.

    If you have ten posts that all need this, the Pilot Bundle is the volume door. If you do not have a connection or a baseline yet, start with Site Connection and Audit. This SKU assumes the post already exists and you already know which one.

    Frequently Asked Questions

    How does it work?

    After checkout, I reach out by email within 2 business days with the intake details and a start date.

    Is there a refund policy?

    Before work starts on your posts, full refund on request. Once a post is optimized or published, that portion of the fee is earned.

    Related: SiteBoost. Also SiteBoost — New Article Publishing.

  • The Bing Citation Mining Thesis: How We Built a 40- (2026)

    The Bing Citation Mining Thesis: How We Built a 40- (2026)


    Updated September 30, 2026.

    Direct answer: On June 22, 2026, Tygart Media published 40 enterprise Copilot articles in one day, pinged IndexNow, and used server logs—not GA4—to measure the result: 6,805 AI crawler hits vs. 4,897 traditional crawler hits in 48 hours, plus three copilot.microsoft.com referrals. The thesis is that Bing indexing, Copilot citations, and Bing Ads retargeting form a repeatable monetization flywheel no other AI stack fully closes.

    Capstone for Tygart Media’s AI Search Intelligence series: nine prior posts covered server log analysis, topic selection, and citation economics. This piece ties the experiment together—and notes what changed by late 2026 (Bing’s AI Performance report in Webmaster Tools, still no substitute for raw logs).


    The thesis: Bing as the closed loop

    Copilot cites from Bing’s index—not a separate Copilot crawler.

    Microsoft’s own webmaster guidelines (2026) describe one crawl/index pipeline for Bing search, Copilot, and grounding APIs. Copilot does not maintain a shadow index. If Bingbot can crawl the URL and Bing indexes it, the page is eligible to be cited. That is the architectural basis for “Bing citation mining.”

    The monetization twist is Microsoft-specific: a visitor who clicks a Copilot source link often arrives with a copilot.microsoft.com referrer. That session can feed Bing Ads retargeting. Google’s AI surfaces and ChatGPT may send traffic, but they do not hand you the same owned ad graph. We still treat Google AI Overviews and ChatGPT Search as citation channels—just not closed-loop ones.

    Five steps we operationalize:

    1. Publish — Question-first, entity-dense answers (SEO + AEO + GEO).
    2. Index — IndexNow on every new URL; sitemaps and internal links as backup.
    3. Cite — Copilot (and Bing AI summaries) pull from the Bing index.
    4. Retarget — Build audiences from Copilot referrers in Bing Ads.
    5. Monetize — Measure leads and revenue, not vanity citations alone.

    The experiment: 40 articles, one day

    Forty posts in one batch—then watch bot behavior.

    On June 22, 2026, we shipped 40 articles on enterprise Microsoft 365 Copilot workflows—eight each across governance, BI/analytics, adoption, productivity, and comparison/procurement topics. Forty was the smallest batch that still looked like a topical cluster to bots mapping site structure, not forty isolated landing pages.

    Every article received the same four-layer stack summarized in our GEO case studies for 2026 and the PSAO write-up: classic SEO, AEO extractability, GEO entity saturation, plus JSON-LD. Internal links tied each post to three to five siblings so GPTBot’s structural crawl (see below) could read cluster authority.


    Day-one data (June 2026 server logs)

    All numbers below are first-party log parses from the 48 hours after publish. Analytics tags miss most bot traffic; this is why we keep preaching log instrumentation—and why we published an AI citation monitoring guide and a broader LLM visibility measurement framework for the post-dashboard era.

    AI vs. traditional crawlers

    • 6,805 AI crawler hits
    • 4,897 traditional crawler hits
    • 39% more AI than traditional volume

    Source: Tygart Media server logs, June 2026.

    Who showed up

    ChatGPT-User (3,404 hits) — Real-time retrieval when a user asks ChatGPT something that needs the live web. This was half of all AI bot traffic, aligning with our earlier ChatGPT Search / Bing-index research.

    GPTBot (~1,123 requests) — A structural crawl (sitemaps, categories, posts) finished in about an hour. Training/index mapping behavior, not query-driven fetches.

    Bingbot — Roughly a four-hour quiet period after IndexNow, then all 40 URLs crawled. IndexNow did its job notifying Bing; Microsoft still does not promise a fixed latency window.

    Copilot referrals

    Three confirmed human sessions from copilot.microsoft.com within 48 hours—before traditional Bing rankings meant much. Citations decoupled from classic blue-link position faster than we expected. Dollar framing lives in the citation value framework.


    What still surprised us (and what we revised)

    1. Speed. AI bots arrived in hours, not weeks—consistent with AI reads outpacing human reads on many publishers.
    2. ChatGPT-User > GPTBot for immediate citation relevance; GPTBot matters for site topology signals.
    3. Copilot citations before rank. Index presence plus topical fit beat waiting for position one.
    4. Measurement stack evolved. By September 2026 we supplement logs with Bing Webmaster Tools AI Performance where available; logs remain the ground truth for bots GA4 never sees.
    5. IndexNow wording. We now describe IndexNow as “notify Bing immediately,” not “instant index”—matching Bing’s documentation.

    What we track after day one

    Bing index coverage (Webmaster Tools), Copilot citation counts (AI Performance + log referrers), AI bot recrawl cadence, traditional Bing/Google rankings, and post-citation behavior in GA4. The 40-article cluster is a living lab; this post is the methods appendix.


    Frequently Asked Questions

    What is the Bing Citation Mining thesis?

    The Bing Citation Mining thesis holds that Microsoft Copilot grounds public answers in Bing’s index, so publishers who publish authoritative pages and get them indexed on Bing can earn Copilot citations—and retarget visitors who arrive from those citations through Bing Ads. That publish → index → cite → retarget loop is the only end-to-end AI search monetization chain Microsoft documents today.

    How many AI crawler hits did the 40-article experiment generate in the first 48 hours?

    Tygart Media server logs from June 2026 recorded 6,805 AI crawler hits versus 4,897 traditional crawler hits in the first 48 hours after all 40 articles went live—39% more AI traffic than traditional. ChatGPT-User alone accounted for 3,404 hits.

    Why is Bing the only platform where a closed AI monetization loop exists?

    Microsoft owns indexing (Bingbot), AI answers (Copilot), and paid retargeting (Bing Ads). Google’s AI experiences and ChatGPT do not offer the same single-vendor chain from index to attributable referral to ad audience. Bing Webmaster Tools now also reports Copilot citation counts in its AI Performance preview, but the monetization hinge is still Bing Ads on copilot.microsoft.com referrers.

    How fast do AI crawlers respond to new content published with IndexNow?

    In Tygart Media’s June 2026 logs, ChatGPT-User hit new URLs within hours, GPTBot finished a 1,123-request structural crawl within about an hour of starting, and Bingbot crawled all 40 posts after roughly a four-hour gap following IndexNow pings. Microsoft’s IndexNow docs stress that a 200 response only confirms receipt—not a guaranteed crawl time—so treat our timings as observed data, not a SLA.

    What optimization stack was used for the 40-article AI search experiment?

    Each post got four layers: SEO (titles, meta, headings, internal links), AEO (FAQ blocks, definition boxes, direct-answer paragraphs), GEO (entity density, factual specificity, speakable markup), and JSON-LD (Article, FAQPage, BreadcrumbList). We document comparable GEO outcomes in our 2026 case-study roundup.


    Methodology: June 2026 Tygart Media access logs; bot classification by user-agent; Copilot referrals by referrer string. No third-party bot counts. As of September 2026, also spot-check Bing Webmaster Tools AI Performance where the preview is enabled.

    Part of Tygart Media’s AI Search Intelligence series for restoration contractors and operators building durable AI search visibility.

  • AEO Content Optimizer — Claude AI Skill for Featured Snippets

    AEO Content Optimizer — Claude AI Skill for Featured Snippets

    Paste your article. Get back the version built to win the featured snippet.

    Who This Is For

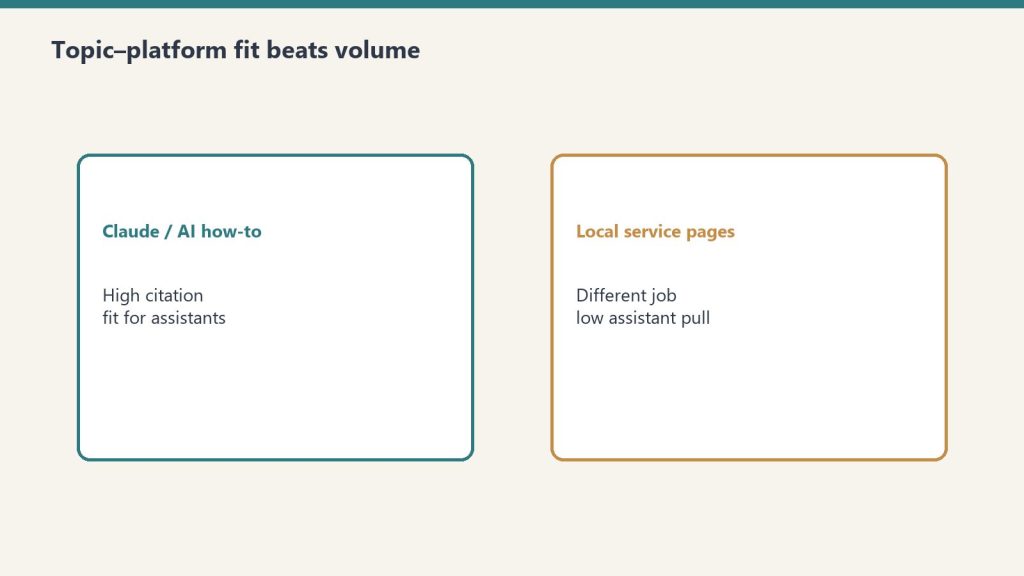
    Comparison of Claude how-to fit versus local service page fit for assistants
    Who the AEO content optimizer skill is for.

    Built for site owners and content marketers who publish good content that never gets picked as the answer — no featured snippets, no People Also Ask placements, invisible in voice results and AI Overviews while thinner competitor pages take the box.

    The Problem

    Answer engines do not reward the best content — they reward the most extractable content. A page that buries its answer in paragraph six loses to a page that answers in the first 50 words under a question heading, formatted the way the snippet wants. Restructuring for extraction is mechanical, learnable work — and almost nobody does it. This skill does it on every piece you paste.

    What It Does

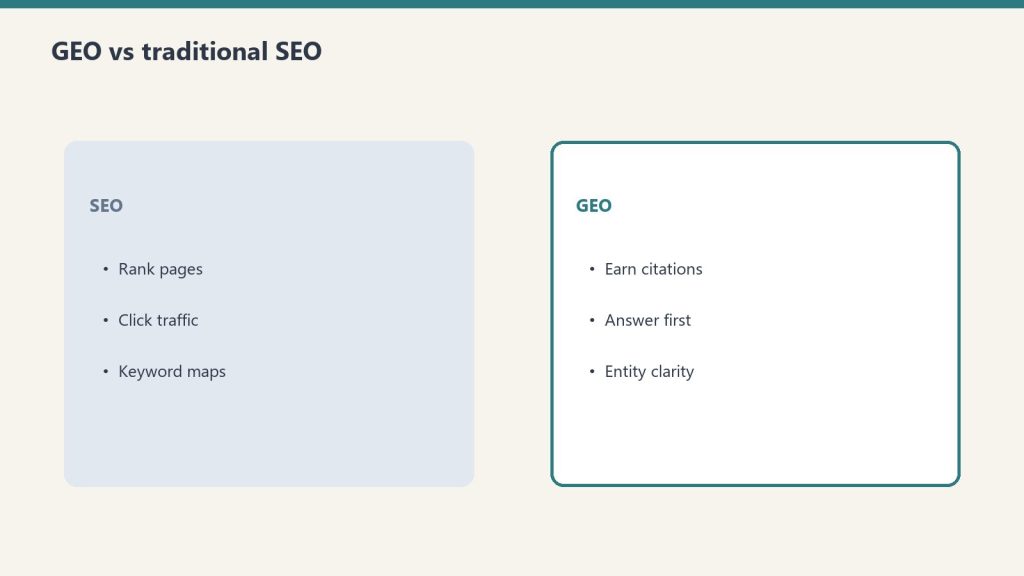
    GEO versus SEO comparison cards
    What it does for featured snippets / AEO.
    • Performs answer-first surgery: a direct, self-contained 40–60 word answer placed immediately under each question heading
    • Converts topical headings into the question formats searchers actually use, mapped to real query variants
    • Matches the winning snippet format per query — paragraph, numbered list, or table — and rebuilds the block to fit
    • Builds a genuine FAQ section and generates the matching FAQPage JSON-LD (and warns about duplicate schema before you paste)
    • Runs a voice pass so direct answers survive a smart-speaker read
    • Returns a change log plus an honest note on what content is missing that the query demands

    What You Get

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What you get.
    • The aeo-content-optimizer.skill file — installs in claude.ai or Claude Code in about two minutes
    • README with installation steps and tested example prompts
    • Works on existing posts, new drafts, and competitor-gap rewrites

    $47 one-time

    Buy Now →

    Secure checkout via Square — all major cards accepted

    Want a custom version built specifically for your business? Email will@tygartmedia.com

    Related on Tygart Media: GEO tactics · AEO content cluster · schema injection skill.

    Frequently Asked Questions

    Do I need technical knowledge to use this?

    No. You paste your content and your target question. The skill restructures and returns paste-ready output, including the schema block.

    Does it work for my niche?

    Yes — the method is format-driven, not topic-driven. Local services, SaaS, e-commerce, professional services, and content sites all follow the same extraction rules.

    Will it change my voice or facts?

    It restructures; it does not genericize. Anything it cannot verify is flagged for you to supply rather than invented.

    How is this delivered?

    Within 24 hours of purchase via email from will@tygartmedia.com. Skill file and setup guide delivered as a ZIP download.

    Does this require a paid Claude subscription?

    Installing as a custom skill requires a paid Claude plan (Pro, $20/mo, or higher) with code execution enabled. Your download also includes a free-plan setup option — paste the skill into a Claude Project’s instructions — that works on any plan.

  • RAG Optimization: Creating Source-Worthy Content for AI

    RAG Optimization: Creating Source-Worthy Content for AI

    The Search Landscape of May 2026: Stop Chasing Traffic, Start Chasing Citations

    The transition is complete. As of this month, Google’s AI Overviews (formerly SGE) appear for over 52% of all search queries. If you are looking at your Search Console and seeing a 30% drop in informational traffic compared to last year, you aren’t alone. You’re simply seeing the result of the “Zero-Click” era reaching its final form. For digital agency owners and systems architects, the old SEO playbook is a liability. If you are still optimizing for clicks on “What is…” or “How to…” keywords, you are effectively donating your intellectual property to train a model that will replace your visit.

    The currency of search has shifted. We have moved from the era of link equity to the era of Source-Worthy Content. In this new reality, the goal isn’t to get the user to click through to read a basic definition; it is to ensure that your data, your unique perspective, or your proprietary methodology is the primary source cited by the Retrieval-Augmented Generation (RAG) systems powering Google, Perplexity, and OpenAI.

    The Numbers Don’t Lie: The Death of the Click

    By mid-2026, the data across our portfolio is clear. Informational query traffic—the top-of-funnel “educational” content that used to drive massive awareness—has cratered by 20-40% across most B2B and technical sectors. Users are getting their answers directly in the search interface. They don’t need to visit your site to learn “how to configure a headless CMS” if Gemini can pull the five essential steps from your documentation and present them in a neat bulleted list.

    However, while traffic is down, the value of a single citation within an AI Overview has skyrocketed. We’ve found that being the primary citation in a RAG-driven answer drives higher-intent leads than the old-school organic #1 spot ever did. The users who do click through from an AI Overview have already been pre-qualified by the AI. They aren’t looking for a definition; they are looking for the operator who provided the insight. Optimizing for AI overviews is no longer a side project; it is the core of technical SEO.

    Understanding RAG: How Google Picks Its Sources

    To win in 2026, you have to understand the mechanics of Retrieval-Augmented Generation. Google’s AI isn’t just “hallucinating” answers based on its training data; it is actively searching the live web, retrieving specific “chunks” of information, and then synthesizing those chunks into a response. This is RAG optimization.

    When an AI Overview is generated, Google’s system follows a three-step process:

    1. Retrieval: It identifies the top-ranking traditional search results for the query. (This is why maintaining traditional page-one rankings is still a prerequisite for being a source).
    2. Selection: It selects specific paragraphs, data tables, or unique insights from those top results that best satisfy the user’s intent.
    3. Generation: It rewrites those insights into a cohesive answer, adding citations to the sources it used.

    If your content is generic—if it says exactly what every other site says—the AI will synthesize the answer without citing you specifically, or it will cite a larger authority (like Wikipedia or a massive news outlet) that says the same thing. To be cited, your content must be source-worthy. It must provide something the AI cannot find elsewhere or synthesize from common knowledge.

    Why Generic Content is Erased by AI

    The era of “skyscraper” content—taking ten existing articles and making a longer one—is over. AI is better at that than you are. In fact, most of that generic content is now being flagged by LLMs as “low information gain.”

    When we audit a site using the Gemini CLI, we look for “Information Gain” scores. If a paragraph doesn’t offer a new data point, a specific case study result, or a unique operator’s perspective, it’s invisible to the RAG process. Generic advice like “SEO requires good keywords” is discarded. Specific advice like “We saw a 12% lift in RAG citations by moving from 1,000-word articles to 400-word modular content blocks” is source-worthy.

    The LLM wants to cite the originator. If you are just a curator, you are a middleman that the AI has successfully bypassed.

    The ‘Source-Worthy’ SEO Framework

    At Tygart Media, we’ve pivoted our Agency Playbook to focus on four pillars of source-worthy SEO. This is how we ensure our clients remain the “source of truth” in an AI-dominated search engine.

    1. Proprietary Data and “Proof of Work”

    The AI cannot hallucinate your internal data (yet). Original surveys, technical benchmarks, and project post-mortems are the most cited pieces of content in 2026. If you run a test on a new deployment pipeline and publish the raw numbers, Google’s AI Overview will cite your specific numbers. We’ve moved away from “opinion pieces” and toward “experiment logs.” Every article should contain at least one table or chart of data that didn’t exist on the internet before you published it.

    2. The Operator’s Perspective (E-E-A-T)

    Experience and Expertise are now the primary filters for RAG selection. Google is prioritizing content that shows “Proof of Effort.” Use first-person accounts. Instead of writing “How to use Claude Code,” write “What we learned after 500 hours using Claude Code to refactor a legacy Python monolith.” The specific failures and technical hurdles you describe are unique identifiers that the AI recognizes as authoritative.

    3. Modular Content Architecture

    Long-form, sprawling articles are difficult for RAG systems to “chunk” effectively. We are now building content in modular blocks. Each section of an article is designed to stand alone as a complete answer to a sub-query. We use <section> tags and specific ID attributes to make it easy for the crawler to identify and retrieve the exact block it needs. This is optimizing for AI overviews by making your content “consumable” for machines, not just humans.

    4. Structured Data for RAG

    Schema.org hasn’t gone away; it has become the metadata for AI. We use Dataset, HowTo, and Review schema more aggressively than ever. But more importantly, we are using Gemini CLI to auto-generate JSON-LD that specifically maps out the “Claims” made in our articles. By explicitly stating “Our claim: Informational traffic is down 30%,” we make it easier for the AI to attribute that fact to us.

    Technical Execution: Modular E-E-A-T and Gemini CLI

    The workflow for a modern agency operator involves high-level automation. We don’t manually audit 500 pages for “source-worthiness.” We use tools like Claude Code and Gemini CLI to process our content libraries.

    Our current stack for RAG optimization looks like this:

    • Analysis: We pipe our top-performing URLs through a script that uses the Gemini API to compare our content against the current AI Overview for that keyword. The script identifies “content gaps”—information the AI is providing that isn’t on our page, or information we have that the AI is ignoring.
    • Refactoring: If a page is losing traffic but has high “Source Worthiness,” we use Claude Code to refactor the HTML into a more modular structure, adding Dataset schema to any tables.
    • Validation: we use Antigravity to simulate how a RAG system would “chunk” the page. If the chunks are incoherent, we rewrite the headers to be more explicit.

    One failure we saw early in 2026 was attempting to “game” the AI by over-optimizing for specific keywords. The AI sees through keyword density. It is looking for semantic weight. When we tried to force-feed keywords, our RAG citation rate dropped. When we focused on “operator-restrained” technical clarity, the citations returned.

    Case Study: The 40% Traffic Drop and the 15% Lead Increase

    We recently worked with a systems architecture firm that saw their organic traffic from “cloud migration tips” fall by 40% in the google sge impact may 2026 rollout. Initially, there was panic. However, upon closer inspection, their “Request a Consultation” conversions were actually up by 15%.

    What happened? Their generic “tips” were being swallowed by the AI Overview. But the AI Overview was citing their specific “Cloud Migration Cost Calculator” and their “2025 Migration Failure Report.” The traffic they lost was the “looky-loos” who just wanted a quick tip. The traffic they gained (via the AI citations) was from CTOs who saw their specific data cited as the authority and clicked through to hire them. This is the shift from “volume” to “value.”

    Action Plan: What You’d Do Tomorrow

    If you are managing a content library or an agency portfolio, don’t wait for your traffic to hit zero. Start the pivot to source-worthy SEO immediately. Here is the operator’s checklist for tomorrow morning:

    1. Audit for “What is” Content: Use your preferred crawler to identify every page that targets a purely informational, definitional keyword. These are your “donor” pages. Decide whether to delete them, consolidate them, or upgrade them with proprietary data.
    2. Inject Original Data: Find three pieces of internal data—even if they are small—and add them to your top 10 most important pages. Use tables. Add a “Methodology” section.
    3. Modularize Your Headers: Ensure every H3 in your articles can stand alone as a question and every following paragraph as a direct, concise answer. Remove the “fluff” and the “introductory transitions.” The AI doesn’t need a “In this section, we will explore…” lead-in. It needs the facts.
    4. Verify Citations: Perform a manual search for your primary keywords. Look at the AI Overview. If you are ranking #1-3 in organic but aren’t cited in the AI response, your content isn’t “Source-Worthy.” It’s too generic. Rewrite the top-ranking paragraph to offer a unique, data-backed perspective that the AI is currently missing.
    5. Update Your Schema: Move beyond basic Article schema. Implement Speakable, Dataset, and ClaimReview schema where applicable. Use a tool like Gemini CLI to automate the generation of these blocks based on your existing text.

    SEO isn’t dead; the middleman is dead. The search engine of 2026 doesn’t want to send users to a website; it wants to provide an answer. Your job is to be the only source that the answer cannot exist without. Build for the machine, provide for the human, and protect your intellectual property by making it too specific to be ignored.

    Related on Tygart Media: chunk-first GEO · GEO tactics · how AI engines cite.

  • ChatGPT Search Citations: The 2026 Optimization Guide

    ChatGPT Search Citations: The 2026 Optimization Guide

    ChatGPT Search cites 15% of the pages it retrieves. The other 85% get pulled into the model’s context window, evaluated, and silently discarded — no visibility, no referral, no trace. If you are doing GEO work and your pages keep getting retrieved but never quoted, you are losing at the second filter, not the first.

    This is the 2026 implementation guide for surviving both filters: getting retrieved by ChatGPT Search, then getting cited once you are there.

    How ChatGPT Search Actually Builds an Answer

    Topic platform fit visual for first-party AI citation measurement
    How ChatGPT Search builds an answer.

    ChatGPT Search runs a three-stage pipeline. Each stage kills most candidates.

    1. Retrieval — ChatGPT Search is powered by Bing’s index for real-time web retrieval. Seer Interactive’s analysis found 87% of SearchGPT citations match Bing’s top results, with the bulk in positions one through ten and a long tail in positions eleven through twenty. AirOps research separately put ChatGPT-to-Bing overlap at 73%. If you are not in Bing’s top 20 for a query, you almost certainly are not in ChatGPT’s candidate set.
    2. Crawlability check — OpenAI’s OAI-SearchBot is the user agent that builds the index used for ChatGPT’s search features. It is separate from GPTBot (training) and ChatGPT-User (browsing). Block OAI-SearchBot in robots.txt and you remove yourself from ChatGPT Search entirely, even if Bing has you ranked.
    3. Citation selection — Of the pages retrieved, AirOps found ChatGPT cites only 15%. The model picks what to quote based on structure, freshness, authority signals, and whether the page directly answers the query.

    Step 1: Verify You Are Indexed by Bing

    Most sites optimized for Google have never logged into Bing Webmaster Tools. Fix that first. Three checks before anything else:

    • site:yourdomain.com in Bing — confirms basic indexing.
    • Bing Webmaster Tools → URL Inspection — confirms the specific pages you want cited are indexed and have no crawl errors.
    • Bing rankings for your target queries — if you are not in the top 20 in Bing, ChatGPT will not see you.

    If pages are missing, submit a sitemap via Bing Webmaster Tools and request URL inspection on any priority page. Bing typically reflects changes within 24–72 hours, faster than Google.

    Step 2: Allow OAI-SearchBot in robots.txt

    Four ranked rows of AI crawler fleets reading publisher content
    Allow OAI-SearchBot in robots.txt.

    The single most-skipped step in GEO work. Add this block to your robots.txt:

    # Allow ChatGPT Search to retrieve and cite this site
    User-agent: OAI-SearchBot
    Allow: /
    
    # Optional: allow on-demand browsing for ChatGPT users
    User-agent: ChatGPT-User
    Allow: /
    
    # Optional: block training crawler if you want retrieval without training
    User-agent: GPTBot
    Disallow: /

    OpenAI publishes these three user agents and treats each independently. You can allow OAI-SearchBot for ChatGPT Search visibility and still disallow GPTBot from using your content for model training. The settings do not conflict. OpenAI’s systems typically recognize robots.txt changes within 24 hours.

    Step 3: Structure Pages for the Citation Filter

    Comparison of Claude how-to fit versus local service page fit for assistants
    Structure pages for the citation filter.

    Retrieval is necessary but not sufficient. Once your page is in the candidate set, the model decides whether to quote it. Pages that get quoted share a structural pattern.

    Direct answers in the first 100 words

    ChatGPT cites sources that answer the question fully. Partial answers lose to complete ones. Lead each page with a clean direct-answer paragraph: question implied or stated, answer in the next sentence, supporting detail after. This is the same pattern that wins featured snippets, which is not a coincidence — answer engines and snippet engines reward the same structure.

    JSON-LD schema

    An AirOps study of 548,534 pages found pages with JSON-LD markup posted a 38.5% citation rate versus 32.0% without it. Article, FAQPage, and HowTo schema are the highest-leverage types. Add them.

    Word count: 500–2,000

    Pages between 500 and 2,000 words performed best in the same AirOps study. Pages longer than 5,000 words were cited less often than pages under 500. The mechanism is mechanical: long pages overflow the retrieval context window, and the model defaults to shorter, denser sources it can quote in full.

    Freshness

    Content updated within 30 days received 3.2x more citations than older material. The fix is not faked freshness — it is genuine updates: a new stat, a new case, a corrected claim. Update the date when you update the content, not before.

    Step 4: Build the Authority Layer

    Structure gets you cited once. Authority gets you cited repeatedly. AirOps found sites with over 32,000 referring domains are 3.5x more likely to be cited by ChatGPT than sites with fewer than 200. You do not need 32,000 — you need to be in the upper band of your topical neighborhood.

    ChatGPT’s citation pattern leans heavily on Wikipedia (roughly 48% of top citations in multiple studies) and large news/media properties. The practitioner read on that: ChatGPT favors sources with multi-source third-party validation. Build the kind of citations on the open web that Wikipedia editors accept — peer-reviewed studies, primary sources, named author attribution, transparent methodology.

    Step 5: Track Your Citation Footprint

    You cannot manage what you do not measure. The minimum tracking stack for 2026:

    • Server log monitoring for OAI-SearchBot user agent — confirms OpenAI is actually crawling. If you allowed the bot in robots.txt three weeks ago and there are zero OAI-SearchBot hits in your logs, something is wrong (CDN block, IP firewall, misconfigured allow rule).
    • Manual citation audits — pick 10 priority queries, run them in ChatGPT with the Search toggle on, log which domains get cited. Repeat weekly. A spreadsheet beats no tracking.
    • Bing position tracking — because ChatGPT pulls from the Bing index, Bing rankings are a leading indicator. If your Bing position drops, ChatGPT visibility drops behind it.

    The Practitioner Summary

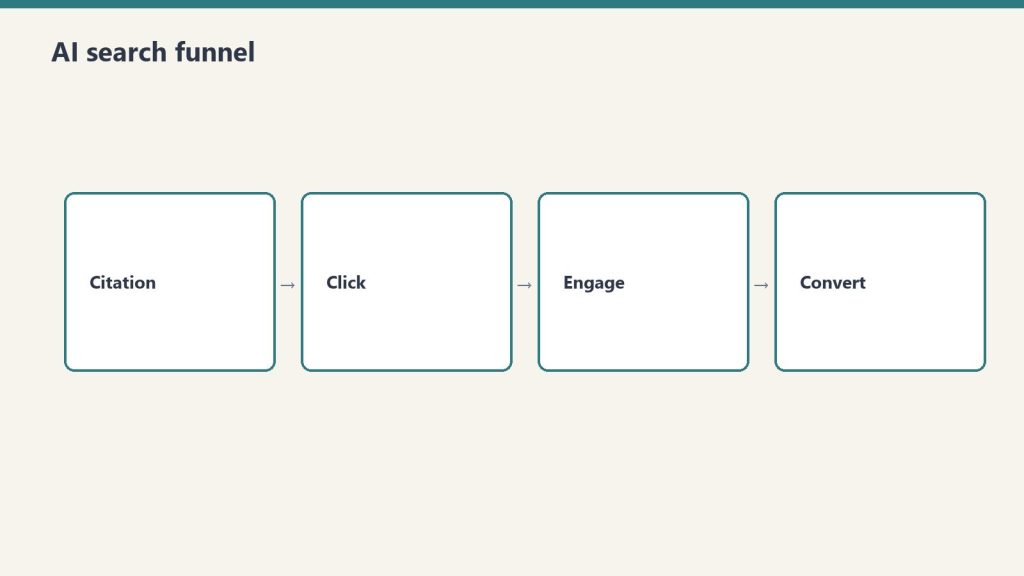
    Ranking in ChatGPT in 2026 is not mysterious. It is a four-gate funnel: Bing index → OAI-SearchBot crawl access → retrieval into the candidate set → citation selection. Most sites fail at gate one (not indexed in Bing) or gate two (OAI-SearchBot blocked or not addressed). Sites that clear those two gates and write pages that answer the question fully, with schema and a 500–2,000-word range, will land in the 15% that get quoted.

    Treat ChatGPT Search like a separate search engine that happens to share an index with Bing. Optimize for the index. Allow the crawler. Write the page. The rest follows.

    Related on Tygart Media: AI citation monitoring · AI search funnel · how AI engines cite.

  • Rank in Perplexity: The 2026 Implementation Guide

    Rank in Perplexity: The 2026 Implementation Guide

    Perplexity does not “rank” pages the way Google does. It synthesizes an answer and then chooses which sources to attach to it. That distinction is the entire optimization problem. If your page cannot be cleanly extracted into a short, entity-clear passage, it will not be cited — no matter how strong its backlink profile is.

    This guide is for SEOs and content directors who already know traditional on-page work and want the implementation layer Perplexity rewards. Skip the strategy posts. Here is what to change in the page itself.

    The Three Things Perplexity Is Actually Doing

    Topic platform fit visual for first-party AI citation measurement
    Three things Perplexity is actually doing.

    When a user submits a query, Perplexity runs three operations in sequence:

    1. Retrieval. Sonar (Perplexity’s underlying search system) pulls a candidate set of URLs from its index using hybrid semantic + keyword retrieval.
    2. Extraction. It reads a bounded chunk of each candidate page. The Sonar API exposes this directly — max_tokens_per_page defaults to 4,096 tokens, which is roughly the first 3,000 words of clean body copy. Content past that window is invisible to the answer engine on most calls.
    3. Synthesis with citation. The model writes the answer using passages it can attribute, then surfaces a small number of source links. Perplexity itself has stated the system uses hybrid search combined with LLM reranking and human feedback signals.

    Three implications for your page:

    • The answer to the query must appear inside the extraction window. Buried answers do not get cited.
    • The passage must be self-contained enough to be quoted without surrounding context.
    • The source needs to look authoritative to the reranker.

    The Extraction Window Test

    Open any page you want to be cited. Strip the nav, sidebar, and footer mentally. Count the words from the first H1 to the point where you have answered the page’s primary question. If that number is over roughly 500 words, you are losing citations.

    Industry guides reporting on Perplexity’s behavior consistently note that direct-answer formats outperform standard article structures by a wide margin in citation rates. The mechanism is mechanical, not editorial: a Q&A block fits inside the extraction window cleanly.

    The Structured Pattern That Works

    Comparison of Claude how-to fit versus local service page fit for assistants
    The structured pattern that works.

    This is the structure to lift into any page you want Perplexity to cite. It is not a template for the whole article — it is the citation block that needs to appear in the first 500 words.

    <section itemscope itemtype="https://schema.org/Question">
      <h2 itemprop="name">What is generative engine optimization?</h2>
      <div itemscope itemprop="acceptedAnswer" itemtype="https://schema.org/Answer">
        <div itemprop="text">
          <p><strong>Generative engine optimization (GEO)</strong> is the practice
          of structuring web content so it is selected, extracted, and cited by
          AI answer engines such as Perplexity, ChatGPT Search, and Google AI
          Overviews. Unlike traditional SEO, which optimizes for ranking position
          on a results page, GEO optimizes for inclusion inside a synthesized
          answer.</p>
        </div>
      </div>
    </section>
    

    Three things this block does that a normal opening paragraph does not:

    • The <h2> is the literal query phrasing. The reranker can pattern-match a user question against your heading without rewriting it.
    • The first sentence is a complete definition with the entity in bold. Perplexity’s extractor favors passages that resolve an entity in a single sentence.
    • The schema (Question / Answer) is not strictly required for citation, but it makes the passage easier for any LLM-based retrieval pipeline — including Sonar — to identify as an answer unit.

    Domain Authority Still Matters — But Differently

    Authority signals influence Perplexity’s reranker, but the relationship is not the same as Google’s. A smaller, well-structured page on a moderate-authority domain can outcite a thin page on a high-authority domain because the reranker rewards passage quality alongside source quality. Practitioner reporting estimates domain authority drives roughly 15% of citation likelihood, with content relevance and structure carrying more weight.

    The implication: do not skip technical authority work, but do not assume it carries you. A 500-word answer block on a DR 40 site, structured properly, will beat a 2,500-word essay on a DR 70 site that buries its answer.

    Freshness Is a Real Decay Curve

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Freshness is a real decay curve.

    Perplexity re-indexes aggressively and prefers recent material for time-sensitive queries. Practitioner audits report citation visibility starts to fade roughly two to three months after publication if a page is not updated. The fix is mechanical: refresh the dateline, add a small “Updated” block with one new fact or example, and resubmit the sitemap. Pages with rolling updates hold citations longer than pages that ship and freeze.

    The Implementation Checklist

    For any page you want Perplexity to cite:

    • Answer the query in a self-contained 2–4 sentence block within the first 500 words.
    • Use the user’s query phrasing as an <h2>, not a clever headline.
    • Wrap the answer in Question / Answer schema, or at minimum FAQPage schema if there are multiple answer blocks.
    • Keep the page total under the extraction window for the primary answer — long-form content is fine, but the cited passage must sit early.
    • Update the page on a quarterly cadence at minimum, with a visible “Updated” marker.
    • Treat each H2 on the page as a candidate citation unit. Every H2 should be a question or a clean entity definition, followed by a passage that resolves it without referring backward in the article.

    That last rule is the one most pages fail. Pages written for human readers chain ideas across sections. Pages written for Perplexity treat each section as an independent answer.

    The Measurement Layer

    You cannot optimize what you cannot see. Track Perplexity citations by querying your target keywords directly in Perplexity weekly, logging which URLs appear, and noting whether your domain is in the source list. Several visibility tools now scrape this data, but a manual weekly check on your top 10 target queries is sufficient to start. Pair this with a referrer log filter for perplexity.ai in GA4 to capture downstream traffic.

    The optimization loop is short: structure the page, ship, query the target keyword in Perplexity, observe whether you were cited, refine the answer block. Most pages need two to three iterations on the lead block before they earn a steady citation.

    Related on Tygart Media: Perplexity user persona · citation economy · GEO tactics.

  • The Citation Block Pattern: Format AEO Answers for AI

    The Citation Block Pattern: Format AEO Answers for AI

    Answer engine optimization in 2026 has narrowed to a single tactical question: when an AI system synthesizes a response, which sentence does it lift, and which source does it cite? The answer is no longer theoretical. Google AI Overviews now appear on 50–60% of U.S. searches, ChatGPT and Perplexity surface inline citations on most factual queries, and the content that gets pulled shares a structural fingerprint. That fingerprint is the citation block — a 40-to-60 word standalone answer placed immediately under a question-shaped heading. This article shows you the exact pattern, the heading-to-answer mapping that wins extraction, and a before-and-after rewrite you can apply to any existing post today.

    Why the 40–60 word window exists

    Comparison of Claude how-to fit versus local service page fit for assistants
    Why the 40–60 word window exists.

    A citation block is the first 40 to 60 words of prose that sits directly beneath a question-shaped H2 or H3 and answers that question in full without requiring any surrounding sentences for context. It must be self-contained, factually specific, and parseable as a single semantic chunk.

    Large language models retrieve passages, not paragraphs. When ChatGPT, Claude, Gemini, or Perplexity assembles a response, the retrieval step pulls discrete text spans that the synthesis step then weaves into the final answer. Shorter spans get attributed more cleanly because they fit inside a single citation token without truncation. The 40–60 word window is the practical sweet spot: long enough to be a complete answer, short enough that the model does not need to summarize or compress it before citing.

    Featured snippets reinforce the same pattern. Google’s paragraph snippets average roughly 40–50 words and are extracted, not generated, which means a well-formed citation block can win both the traditional snippet slot and the AI Overview citation in the same crawl.

    The structural rule: one question, one heading, one block

    GEO versus SEO comparison cards
    One question, one heading, one block.

    The pattern is mechanical. Take the exact question wording a user would type — or that already appears in a People Also Ask box — and use it verbatim or near-verbatim as the heading. Directly under that heading, write a 40–60 word answer that opens with the subject of the question, contains the specific claim, and closes the loop without trailing off into a transition.

    This is the wrong way to structure an FAQ-style section:

    <h3>Schema Markup</h3>
    <p>There are many forms of structured data you can use. Some people prefer JSON-LD, while others use microdata. We'll discuss the pros and cons of each in the next section, but first let's talk about why schema matters at all in the modern search landscape...</p>

    This is the right way:

    <h3>What schema markup should you use for AEO?</h3>
    <p>Use JSON-LD format with FAQPage schema for question-answer sections, Article schema on the post itself, and BreadcrumbList for navigation context. JSON-LD is Google's recommended format, sits in the page head without affecting visible content, and is the schema type AI crawlers parse most reliably. Add HowTo or QAPage schema only when content genuinely matches those structures.</p>

    The second version puts the question verbatim in the heading, opens the answer with the recommendation, names the specific schema types, and closes inside the 40–60 word window. Anywhere this pattern repeats across a page, you stack extraction surface area.

    FAQPage schema: the multiplier

    FAQPage JSON-LD pre-formats your citation blocks for machine consumption. Once a section is wrapped in FAQPage schema, Google, Bing, and most LLM crawlers can ingest the question-answer pairing without needing to infer it from HTML structure. Pages with properly implemented FAQPage schema are reported to earn AI citations at materially higher rates than pages relying on heading hierarchy alone.

    Here is the minimum viable FAQPage block for a single question:

    <script type="application/ld+json">
    {
      "@context": "https://schema.org",
      "@type": "FAQPage",
      "mainEntity": [{
        "@type": "Question",
        "name": "What schema markup should you use for AEO?",
        "acceptedAnswer": {
          "@type": "Answer",
          "text": "Use JSON-LD format with FAQPage schema for question-answer sections, Article schema on the post itself, and BreadcrumbList for navigation context. JSON-LD is Google's recommended format, sits in the page head without affecting visible content, and is the schema type AI crawlers parse most reliably."
        }
      }]
    }
    </script>

    The “text” value should be identical or near-identical to the visible citation block beneath the heading. Identical text reduces the parsing burden on AI crawlers and removes any ambiguity about which sentence is the canonical answer.

    Before-and-after: rewriting a thin section

    Here is a real pattern you will recognize from your own archive. The before is a thin sub-section that buries the answer; the after is the same content restructured for extraction.

    Before:

    <h3>Voice Search</h3>
    <p>Voice search has been growing for years, and many SEOs still don't take it seriously. With smart speakers in millions of homes, the way people search is changing fast. You have to think about how someone would actually ask a question out loud versus typing it. This affects everything from keyword research to content structure...</p>

    After:

    <h3>How do you optimize content for voice search in 2026?</h3>
    <p>Optimize for voice search by writing direct answers to natural-language questions in 40–60 word blocks, using conversational question phrasing in your H2s and H3s, and adding Speakable schema to mark which sentences a voice assistant should read aloud. Target long-tail conversational queries — phrasing like "how do you," "what is the best way to," and "where can I find" — rather than truncated typed-search keywords.</p>

    The rewrite swaps a topic-shaped heading for a question, leads with the specific implementation, names the schema type, and ends inside the extraction window. That single restructure turns a passive paragraph into a citation candidate.

    How to audit an existing page in 15 minutes

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Audit an existing page in 15 minutes.

    Open any of your highest-traffic posts and run this checklist. For each H2 and H3, ask whether the heading is phrased as a question a user would actually type. If not, rewrite it. For each section under those headings, read the first 60 words and ask whether they stand alone as a complete answer. If not, restructure the opening paragraph so the direct answer comes first and the elaboration comes after. Then add FAQPage schema covering the question-answer pairings, with the “text” value matching the visible answer.

    The pages that win AI citations in 2026 are not the longest, the most authoritative, or the best-linked. They are the ones whose structure makes the answer impossible to miss. The citation block pattern is how you build that structure on purpose.

    Related on Tygart Media: chunk-first GEO · GEO tactics · how AI engines cite.

    Frequently Asked Questions

    What is a citation block in answer engine optimization?

    A citation block is a 40-to-60 word standalone answer placed directly beneath a question-shaped heading. It must answer the question completely without depending on surrounding sentences for context. Citation blocks are the text spans that AI systems like ChatGPT, Perplexity, and Google AI Overviews extract and attribute when synthesizing responses.

    How long should an AEO answer be?

    Lead each section with a 40-to-60 word direct answer block, then follow with supporting context, examples, or elaboration. The 40–60 word window is long enough to be a complete answer and short enough to fit inside a single AI citation without truncation or summarization, which improves attribution reliability.

    Does FAQPage schema still help in 2026?

    Yes. FAQPage JSON-LD pre-formats question-answer pairings for machine consumption, which AI crawlers parse more reliably than answers inferred from heading hierarchy alone. The schema’s “text” value should match the visible citation block beneath the heading to remove parsing ambiguity for crawlers.

    How is AEO different from traditional SEO?

    Traditional SEO optimizes pages to rank in a list of blue links; AEO optimizes specific text spans inside the page so AI systems extract and cite them as direct answers. AEO assumes the user may never click — the goal is the citation itself, with the brand attribution as the conversion event.

  • Entity Binding for GEO: The 4-Surface AI Citation Stack

    Entity Binding for GEO: The 4-Surface AI Citation Stack

    Most GEO advice in 2026 stops at “add statistics and citations.” That’s true — Princeton’s GEO research paper (Aggarwal et al., 2023) found those two tactics boosted visibility in generative engine responses by up to 40%. But the gap between sites that get cited by ChatGPT, Claude, and Perplexity and sites that don’t isn’t really about more numbers in your paragraphs. It’s about whether the AI system can resolve your brand as a stable entity across the open web before it ever reaches your page.

    This is entity binding. It’s the layer underneath every GEO tactic. If you skip it, statistics and FAQs won’t save you. If you do it right, your citation rate compounds.

    What “Entity Binding” Actually Means for GEO

    GEO versus SEO comparison cards
    What entity binding means for GEO.

    When an LLM decides whether to cite a source, it isn’t reading your page in isolation. It’s running a fast resolution step: is this brand a real thing? Does it have consistent attributes across sources? Can I categorize it confidently? The model’s confidence in citing you scales with how unambiguous that resolution is.

    Entity binding means making yourself a knowable, consistent entity — not just a domain — across the surfaces AI systems consult: Wikipedia, Wikidata, Crunchbase, LinkedIn, your schema.org markup, industry directories, and the structured data inside Google’s Knowledge Graph. Research synthesized in 2026 by GEO firm Brandlight found the overlap between top Google links and AI-cited sources has dropped from roughly 70% to under 20% — meaning rank no longer guarantees citation. Entity authority does heavier lifting now.

    The Four-Surface Entity Binding Stack

    Comparison of Claude how-to fit versus local service page fit for assistants
    The four-surface entity binding stack.

    Practitioners working on GEO in 2026 should treat entity binding as a stack with four surfaces, in priority order:

    1. On-page Organization schema — the source of truth for your own claims about yourself.
    2. Wikidata / Wikipedia presence — the most heavily weighted external source for knowledge graph construction.
    3. Third-party directories — Crunchbase, LinkedIn company page, industry-specific databases.
    4. Consistent cross-source language — same category, same one-line description, same founding date, same founder names, everywhere.

    If even one surface contradicts the others — say, your LinkedIn calls you a “marketing agency” but your schema says “SaaS company” — the LLM’s confidence in citing you drops. Inconsistency is the silent GEO killer.

    Step 1: Ship a Clean Organization Schema Block

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Ship a clean Organization schema block.

    The foundation is a JSON-LD Organization block on your homepage (and a Person block on your About page if you have a named founder). Here’s a working example you can adapt — drop it inside <script type="application/ld+json"> tags in your <head>:

    {
      "@context": "https://schema.org",
      "@type": "Organization",
      "name": "Tygart Media",
      "alternateName": "TM Editorial",
      "url": "https://tygartmedia.com",
      "logo": "https://tygartmedia.com/wp-content/uploads/logo.png",
      "description": "Independent publisher covering AI search, generative engine optimization, and the practitioner side of LLM-era content strategy.",
      "foundingDate": "2024",
      "founder": {
        "@type": "Person",
        "name": "William Tygart",
        "url": "https://www.linkedin.com/in/williamtygart/"
      },
      "sameAs": [
        "https://www.linkedin.com/company/tygart-media/",
        "https://x.com/tygartmedia",
        "https://www.crunchbase.com/organization/tygart-media"
      ],
      "knowsAbout": [
        "Generative Engine Optimization",
        "Answer Engine Optimization",
        "LLMs.txt",
        "AI search optimization"
      ]
    }

    Two parts do the heavy lifting here for GEO: sameAs (which binds you to external authoritative profiles) and knowsAbout (which gives the LLM topical anchors for when it should consider you a relevant citation).

    Step 2: Audit Your Wikidata Footprint

    Most independent publishers and B2B brands have no Wikidata entry. That’s a problem because Wikidata is consumed directly by Google’s Knowledge Graph and is one of the most reliable structured sources LLMs pull from during training and retrieval.

    The minimum viable Wikidata footprint:

    • A Wikidata item with at least: instance of, industry, founded by, official website, and headquarters location.
    • References for every claim — Wikidata rejects unsourced statements, and an unreferenced claim is worse than no claim.
    • Cross-links to your LinkedIn company ID, Crunchbase ID, and (if applicable) Twitter/X handle.

    If you don’t qualify for a full Wikipedia article (most B2B brands don’t), a Wikidata item alone still significantly increases your entity resolution rate inside LLM responses.

    Step 3: Normalize Your One-Line Description Across All Surfaces

    This is the cheapest, highest-leverage entity binding move and almost nobody does it. Pick exactly one sentence — under 20 words, category-first, no marketing fluff — and use it identically on:

    • Your homepage meta description
    • Your Organization schema description field
    • Your LinkedIn company page About section’s opening line
    • Your Crunchbase short description
    • Your X/Twitter bio
    • The first sentence of any guest post author bio

    Example: “Independent publisher covering generative engine optimization and AI-era content strategy.”

    When five external surfaces and your own schema all say the same category in the same words, the LLM’s resolution confidence is high. When they all say something slightly different, the model hedges — and a hedging model doesn’t cite you.

    Step 4: Build Topical Authority Around Bound Entities, Not Just Keywords

    Traditional SEO builds topical authority around a keyword cluster. GEO requires you to build it around entities the LLM already recognizes. Practical translation: every pillar article you publish should explicitly name and (ideally) link to:

    • The canonical entities in your topic (e.g., specific platforms, specific researchers, specific published papers)
    • The accepted definitions and frameworks from the foundational sources
    • Your own brand entity, in a way that lets the LLM connect “this topic” to “this publisher”

    For a GEO publisher, that means citing the Princeton GEO paper by name, naming Google AI Overviews and Perplexity and ChatGPT search as the specific generative engines, and consistently positioning your own brand as the entity that produces practitioner GEO content. Every article reinforces the entity binding.

    How to Measure Entity Binding Is Working

    Entity binding is a leading indicator, not a direct ranking signal — so you measure it sideways. The three practical signals to watch:

    1. Brand mentions in AI responses. Manually query ChatGPT, Claude, Perplexity, and Google AI Overviews monthly with 10–20 of your target topical questions. Track whether your brand appears in any cited or recommended source.
    2. Knowledge Graph presence. Search your brand name in Google. A Knowledge Panel appearing on the right side of the SERP is direct evidence that Google has resolved you as a stable entity. No panel after 90 days of entity binding work signals a gap in your Wikidata or sameAs links.
    3. Referral traffic from AI sources in GA4. Filter for sessions where source contains chatgpt, perplexity, claude, or gemini. Sustained growth in this segment is the downstream result of entity binding combined with on-page GEO tactics.

    The Common Mistakes

    Three failure modes show up repeatedly in 2026:

    • Shipping schema with placeholder content. A schema block that says “description: Your description here” is worse than no schema. LLMs see it and downgrade trust.
    • Inconsistent founder names. “William Tygart” on the site, “Will Tygart” on LinkedIn, “W. Tygart” on Crunchbase. Pick one form and use it everywhere — including author bylines.
    • Treating sameAs as optional. The sameAs array is the single highest-leverage entity binding field in your schema. Empty or partial sameAs is the most common reason small publishers fail to get cited.

    Related on Tygart Media: GEO tactics · SaaS entity SEO · insurance entity SEO.

    Frequently Asked Questions

    What is the difference between GEO and traditional SEO?

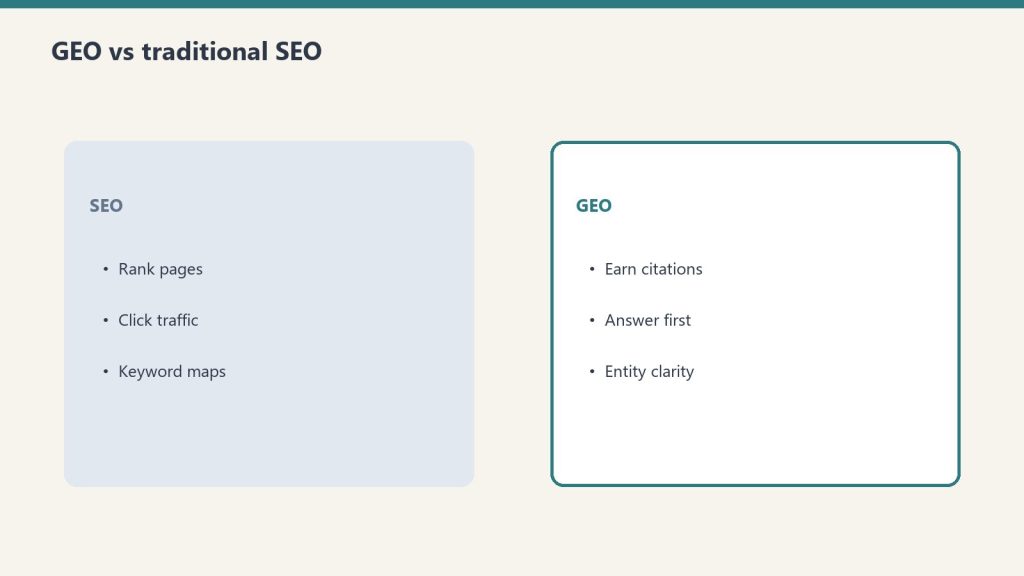
    Traditional SEO optimizes for ranking and clicks on search engine results pages. Generative Engine Optimization (GEO) optimizes for citation, mention, and recommendation inside AI-generated answers from systems like ChatGPT, Claude, Perplexity, and Google AI Overviews. The overlap between top Google links and AI-cited sources has fallen from roughly 70% to under 20% as of 2026, meaning GEO is now a distinct discipline.

    What is entity binding in the context of GEO?

    Entity binding is the practice of making your brand resolvable as a stable, consistent entity across schema markup, Wikidata, third-party directories, and external profiles so that LLMs can confidently identify and cite you. It is the foundation underneath GEO tactics like statistics addition and source citation.

    Do I need a Wikipedia article to be cited by AI systems?

    No. A Wikidata item alone is sufficient for most B2B brands and independent publishers. Wikidata is consumed directly by Google’s Knowledge Graph and is one of the most reliable structured sources LLMs use during entity resolution. Wikipedia helps but is not required.

    How long does entity binding take to show results in AI citations?

    Most practitioners see Knowledge Panel appearance within 30–90 days of completing the four-surface stack. AI citation rate increases lag by an additional 30–60 days because LLM training and retrieval cycles update on slower cadences than search engine indexes.

    What schema type should small publishers use?

    Use Organization schema on your homepage and Person schema on your About page. If you publish frequently, add Article schema to individual posts and link the author Person back to the Organization. This three-way linkage gives LLMs the cleanest entity graph to resolve.

    The Bottom Line

    Entity binding is not a one-time setup task. It’s the underlying condition that makes every other GEO tactic work. Before you spend another month adding statistics and FAQ sections, audit your four surfaces, normalize your one-line description, and ship a clean Organization schema with a complete sameAs array. The publishers winning the citation game in 2026 are the ones whose entity resolution is so unambiguous that the LLM never has to hedge.

  • Google AI Overviews: The May 2026 Citation Playbook

    Google AI Overviews: The May 2026 Citation Playbook

    Google shipped one of the most consequential AI Overviews updates of the year on May 6, 2026 — and most SEO teams still have not adjusted their content templates to match. The update changed what gets cited, where citations are drawn from, and how users decide which links to actually click. This is the practitioner walkthrough: what shifted, the data behind it, and the on-page changes that move the needle in the new system.

    What Google Actually Changed on May 6, 2026

    Two cards: answer shown in overview versus optional click
    What Google actually changed for AI Overviews.

    Google’s own announcement (How AI Mode and AI Overviews help you explore the web) named five shifts to the Overviews surface:

    1. Forum and social perspective blocks — Overviews now embed direct quotes from Reddit, WordPress blogs, and public forums in a dedicated “perspectives” section.
    2. Subscription-aware citation highlights — links from news outlets the searcher is logged in to are visually flagged. Google’s internal test data showed those flagged links were “significantly more likely” to be clicked.
    3. Suggested exploration topics — bulleted follow-up queries now render at the end of many AI responses, which means downstream traffic flows depend on whether your domain ranks for the fan-out queries, not just the head term.
    4. Further Exploration section — a bulleted-link cluster plus an “Expert Advice” snippet pulling from articles, reviews, and forum threads.
    5. Hover-to-preview link cards — hovering a citation now triggers a card showing site name, page summary, and metadata before the click.

    Two of those five — perspectives blocks and Further Exploration — are net-new citation slots. The other three change which citations users actually convert on.

    The Citation Math Has Shifted

    Side-by-side SEO rank/click versus GEO citation/answer-first
    The citation math has shifted.

    The most important measurement from the last 60 days: in March 2026, the share of AI Overview citations pulled from pages ranking in Google’s organic top 10 dropped to 38%, down from 76% in July 2025 (500M-keyword analysis). 31% of cited sources now rank in positions 11–100, and another 31% rank outside the top 100 entirely for the query they get cited on.

    Translation for practitioners: Overviews are no longer a rank-amplifier. They are an independent retrieval layer. A page that ranks #47 with the right passage structure can outcompete a page that ranks #3 with the wrong structure. Domain Authority correlation with citation selection is now r=0.18 — effectively noise. Semantic completeness correlation is 0.87.

    The Passage That Gets Cited

    AI Overview extracts cluster tightly around 134–167 words per passage, with 62% of featured content falling in the 100–300 word range. Position inside the article matters: 44.2% of citations are pulled from the first 30% of the body, 31.1% from the middle, 24.7% from the conclusion (Wellows ranking factor study). Lead-heavy structure is no longer a copywriting preference — it is the extraction surface.

    The structural pattern that wins, repeatable across H2 sections:

    <h2>[Specific question phrased as a noun phrase]</h2>
    <p><strong>[One-sentence direct answer with a named entity or number.]</strong></p>
    <p>[Supporting detail with verifiable source attribution.]</p>
    <p>[Nuance, caveat, or contrast — kept under the 167-word ceiling.]</p>

    Each H2 block becomes a standalone extractable unit. If your article only answers the headline question, you compete for one citation. If five H2 blocks each answer a distinct fan-out question, you compete for five.

    Schema That Earns Citations Now

    Properly marked-up pages show 73% higher selection rates in AI Overviews versus unmarked content. The three schema types doing the most work in the May 2026 surface:

    • FAQPage — feeds the Further Exploration section directly. Each Question/Answer pair is treated as a passage candidate.
    • Article with author and datePublished — freshness is now a citation factor. Content under three months old is 3× more likely to be cited.
    • HowTo with step-level markup — extracted into the Expert Advice snippet when the query is procedural.

    A minimal Article block that hits the freshness and authorship signals Google’s extractor now reads for:

    {
      "@context": "https://schema.org",
      "@type": "Article",
      "headline": "...",
      "author": { "@type": "Person", "name": "...", "url": "..." },
      "datePublished": "2026-05-14",
      "dateModified": "2026-05-14",
      "publisher": { "@type": "Organization", "name": "...", "logo": {...} }
    }

    How to Show Up in the New Perspectives Block

    The forum-quote section is the biggest opportunity nobody is optimizing for yet. Reporting from TechCrunch’s coverage of the rollout confirmed Google is pulling from Reddit, public forums, and WordPress blogs explicitly tagged as personal perspective.

    Three practitioner moves:

    1. Author bylines with first-person framing on at least one article per topic cluster. Personal-perspective phrasing (“In our deployment of …”, “What surprised us was …”) signals firsthand experience to the extractor.
    2. Engage in the relevant subreddit with substantive comments under your real handle, then link your bylined article from your profile. Reddit threads are now a primary retrieval source for perspectives blocks.
    3. Tag personal-perspective posts with Person schema alongside Article schema. The Person entity is what Google ties to the firsthand-experience signal.

    What to Measure Starting This Week

    Four-stage funnel: citation, click, engage, convert
    What to measure starting this week.

    Citation share by query is the only metric that matters in this surface, and traditional analytics will not give it to you. Two practitioner approaches:

    • Manual citation logging — pull your 20 highest-value head terms and 50 fan-out queries, query them weekly in an incognito session, log whether your domain appears in the Overview, the perspectives block, or the Further Exploration list. Track citation share, not just rank.
    • Server-log analysis — Google’s Overview generator hits your pages with a distinct user agent and crawl signature. Filtering for those signatures gives you a leading indicator: pages getting hit by the extractor are pages being evaluated for citation.

    Cited pages earn 35% more organic clicks and 91% more paid clicks than uncited peers (Averi.ai citation study). Uncited pages on triggering queries lose 61% of their normal CTR. The gap between cited and uncited is now wider than the gap between position #1 and position #5 in classical SEO. Treat citation as the primary KPI.

    The Update in One Sentence

    Google has decoupled AI Overview citation from organic rank, opened two new citation slots (perspectives and Further Exploration), and is now rewarding firsthand-experience signals at the page and author level — the practitioners who restructure for passage-level extraction and earn citation in the new slots will pick up the traffic that used to flow to position-#1 pages.

    Related on Tygart Media: citation monitoring · SEO vs GEO vs AEO.