AI Strategy - Tygart Media

Category: AI Strategy

AI strategy for operators: deploy Claude, automate real workflows, and build AI-native systems that compound. Field notes and playbooks from Tygart Media.

  • The Operator Who Reads the Dashboard Out Loud

    The Operator Who Reads the Dashboard Out Loud

    Last refreshed: May 15, 2026

    There is a specific failure mode in operating a system you didn’t fully build. The operator looks at the dashboard. The operator recognizes the numbers. The operator does not internalize what the numbers mean.

    Most operators using AI systems at scale are doing this. The dashboard is full. The metrics are present. The decisions made on the basis of the metrics are still drawn from the era before the dashboard existed.

    The reading vs. the seeing

    Reading is the act of moving the eye over the data and confirming that the data is what was expected. Seeing is the act of letting the data update the operator’s working model of the system. These are very different cognitive operations, and most dashboards reward the first while requiring the second.

    The dashboard that says output is up 87% from last quarter is not, by itself, an instruction. It is a question. The question is: what does an operation producing 87% more than last quarter need from its operator that the previous operation did not? That question is rarely on the dashboard. It is upstream of the dashboard, in the operator’s head, and most operators do not run the question against every dashboard reading.

    The defense that looks like attention

    One of the things that happens in operating a system that has inflected is that the dashboard becomes a comfort object. The operator checks it more frequently. The numbers continue to be good. The frequent checking feels like attention to the system. It is not. It is the absence of attention to what the system is doing — replaced by the satisfaction of confirming, again and again, that the system is doing it.

    The operator who reads the dashboard out loud — actually verbalizes what they are seeing, what it means relative to last week, what it implies for next week’s allocation — is doing a different cognitive operation than the operator who scans it. The verbalization forces the model to update. The scan does not.

    Why this matters more in 2026 than it did before

    AI systems amplify whatever cognitive habit the operator brings to them. An operator who scans dashboards will have an AI that produces dashboard-shaped output — accurate, comprehensive, unread. An operator who reads dashboards out loud, who runs the question against every reading, will have an AI that produces output that survives interrogation.

    The infrastructure of attention is built upstream of the system. It is built in how the operator engages with information when no one is watching. Whatever that habit is, the AI will compound it. The dashboard that reads itself is not coming. The operator who reads the dashboard is the one whose system pays back.

    Related on Tygart Media: quiet room · AI operator’s stack.

  • Notion AI for Finance: Automate Close & Reconciliations

    Notion AI for Finance: Automate Close & Reconciliations

    Anchor fact: Custom Agents can manage close calendars, draft variance commentary, sequence reconciliations, and produce audit-ready documentation — but should never autonomously approve journal entries or sign off on financial statements.

    How does a finance team use Notion AI?

    Finance teams use Custom Agents to manage close calendars, draft variance commentary, surface reconciliation exceptions, and prepare audit documentation. The agents handle the documentation and synthesis layer; humans retain decision authority for journal entries, approvals, and any output that gets signed.

    The 60-second version

    Finance work is 60% documentation and synthesis, 40% judgment. Custom Agents handle the documentation and synthesis layer well. Close calendars, variance narratives, reconciliation status, period-over-period write-ups — agents produce these faster than humans and the audit trail is cleaner. The judgment layer — booking entries, approving reconciliations, signing financial statements — stays human. The split is clean and the leverage is real.

    Four finance-specific agent patterns

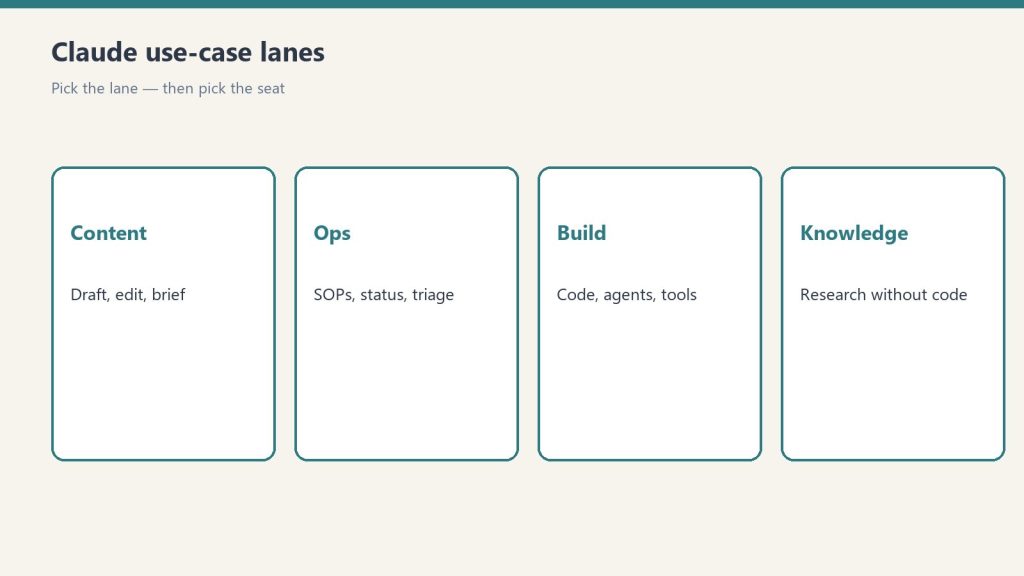
    Four cards for content, ops, build, and knowledge work with Claude
    Four finance-specific agent patterns.

    1. The close calendar agent. Manages the month-end close sequence. Reads the close database, identifies dependencies, sequences tasks, surfaces blockers daily. Produces the close standup in three sentences instead of a 30-minute meeting.

    2. The variance commentary agent. Reads actuals vs budget. Decomposes variances into drivers. Drafts narrative commentary in your team’s house format. Human reviews, tightens, signs.

    3. The reconciliation status agent. Reads the reconciliation database. Flags reconciliations that have stalled, items aging beyond threshold, balances that don’t tie. Surfaces priority queue for the controller’s morning review.

    4. The audit prep agent. Pulls evidence packages on demand. Given a control number, assembles the testing workpaper, the sample selections, the evidence references, and the deficiency log. Auditor asks for X; you have it in 15 minutes instead of a week.

    What absolutely stays human

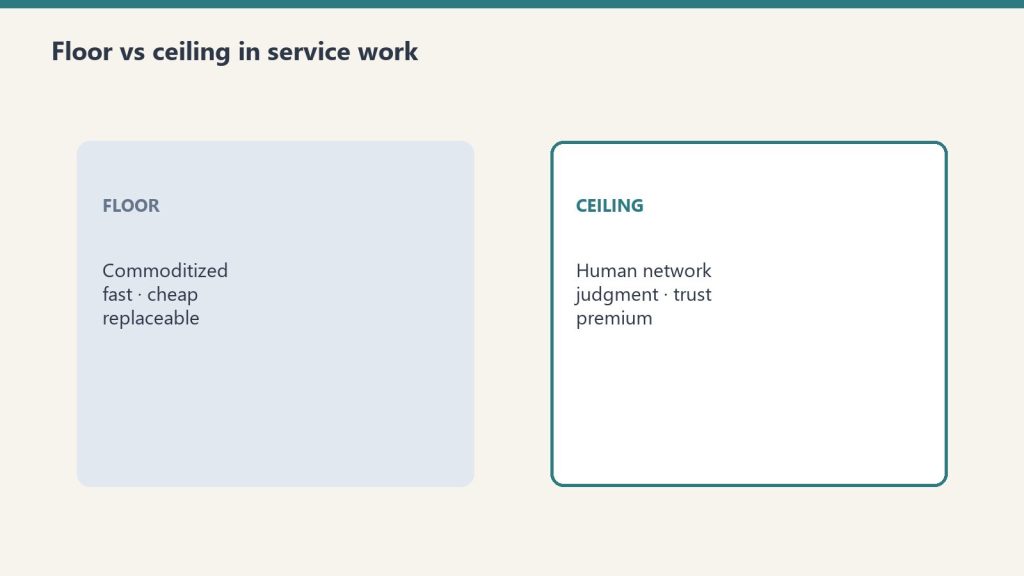
    Floor versus ceiling cards for commoditized work and human-network premium
    What absolutely stays human.

    The lines that don’t move:

    • Booking journal entries (agent drafts, human posts)
    • Approving reconciliations (agent surfaces, human signs)
    • Signing off on financial statements (agent prepares; human owns)
    • Estimates and judgmental accruals (the judgment is the work)
    • Anything that goes to a regulator (period)

    The agents do the work that prepares the human to make these calls faster. They don’t replace the calls themselves.

    The audit posture shift

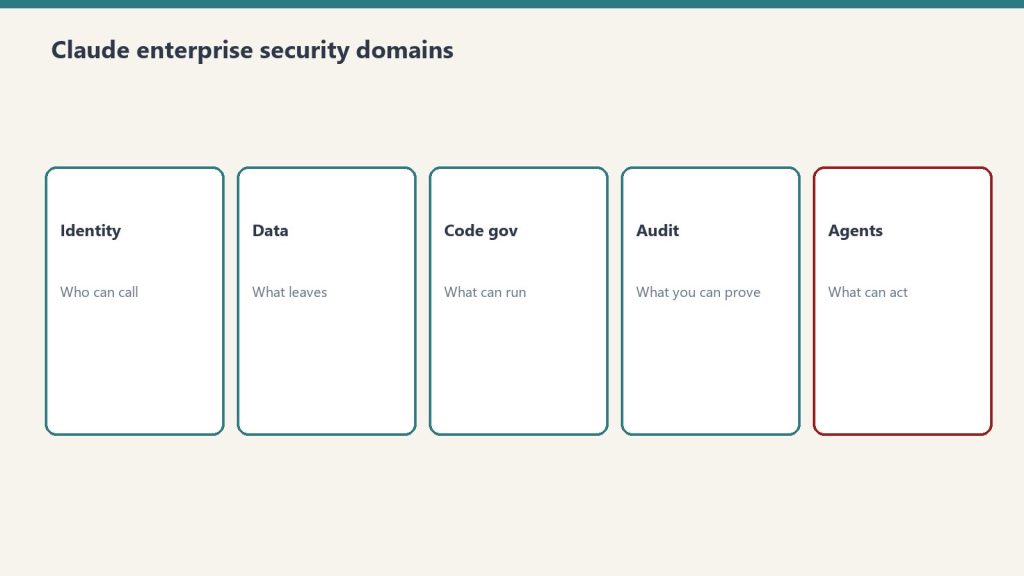
    Five security domains: identity, data, code governance, audit, agents
    The audit posture shift.

    For SOX-regulated entities, agent audit trails change the conversation with internal and external audit. Every agent action is logged. The reproducibility of evidence packages improves. Sample selections that used to take days assemble in hours. This isn’t theoretical — finance teams running this pattern in 2026 are reducing audit-prep cycle time meaningfully.

    The caveat: audit doesn’t accept “the agent did it” as substantiation. The human review at each gate has to be visible in the trail.

    Where finance teams go wrong

    1. Letting the agent draft commentary without source attribution. Every variance number needs to tie back to an underlying report or pull. Agents that produce commentary without citations are a control weakness.

    2. Skipping period-end re-runs. Agent output reflects the moment it ran. If data changes after the agent drafted commentary, the commentary is stale. Build re-run discipline into the close.

    3. Building one mega-agent for finance. Specialized agents (close, variance, recon, audit) outperform a single agent trying to do everything.

    Agent drafts, human posts. That line doesn’t move.

    Sources

    • Notion 3.3 release notes (February 24, 2026)
    • Tygart Media editorial line

    Continue the journey

    This article is part of the May 3 Cliff Decision journey-pack on Tygart Media. Here’s where to go next:

  • Scale Notion AI Output: Why Quality Gates Beat Volume

    Scale Notion AI Output: Why Quality Gates Beat Volume

    Anchor fact: AI amplifies whatever editorial infrastructure you have. Tighter inputs and clearer gates produce more reliable output at scale than adding more agents or more credits.

    What does “gates before volume” mean for AI workflows?

    Gates before volume is the principle that scaling AI output requires tightening quality controls before increasing throughput. Adding more agent runs without first improving inputs, prompts, and review checkpoints multiplies bad output, not good output.

    The 60-second version

    The temptation when AI starts working is to run more of it. Resist that. The order that works is gates first — the inputs the agent reads, the prompts it uses, the checkpoints that catch bad output — then volume. Operators who skip the gate-tightening phase end up with high-volume slop. Operators who tighten gates first end up with high-volume quality. Same agent, same model, same credits. The difference is the gates.

    What a gate actually is

    Five security domains: identity, data, code governance, audit, agents
    What a gate actually is.

    A gate is any checkpoint where output quality gets verified before it propagates downstream. In a Notion AI workflow, gates exist at five points:

    1. Input gate — the data the agent reads (database hygiene)
    2. Prompt gate — the instructions the agent receives (specificity)
    3. Output gate — the format and quality criteria the agent produces against (rubric)
    4. Review gate — the human checkpoint before downstream use
    5. Distribution gate — what triggers final propagation (publish, send, file)

    Each gate is a place where a small fix prevents large drift. Each missing gate is a place where bad output silently propagates.

    The volume trap

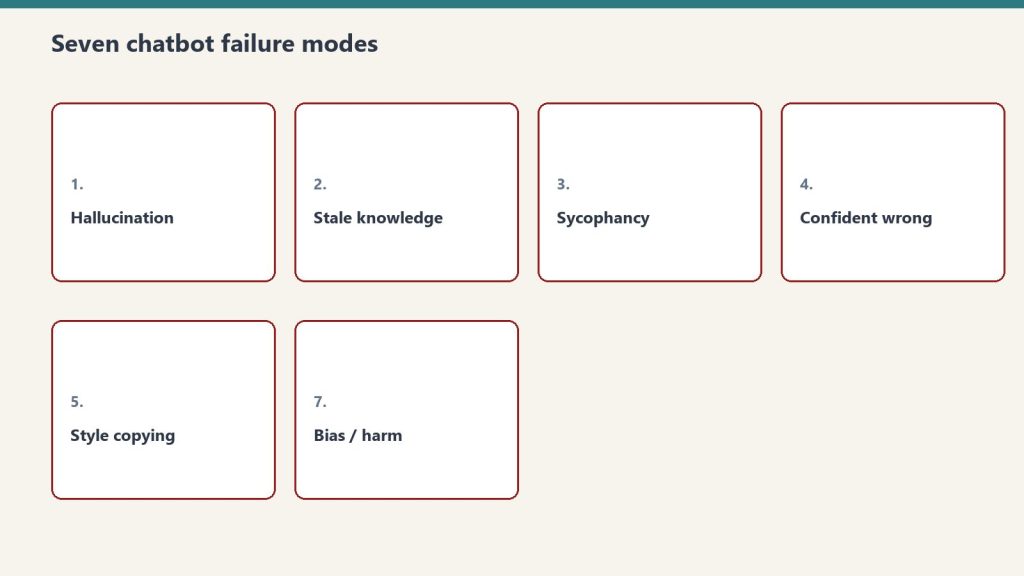
    Seven cards naming common AI chatbot failure modes
    The volume trap.

    Without gates, scaling looks like this: agent runs once, output is mediocre but acceptable. Operator runs it 10× per week. Now there’s 10× the mediocrity. By month three, the operator has built a content factory that produces volume but nobody trusts the output enough to skip review. The “scale” never actually shipped because everything still goes through human eyes anyway.

    With gates, scaling looks like this: tighten input substrate, write specific prompts, define a rubric, set a review checkpoint, then ramp volume. Each piece that ships clears the gates. Trust accrues. Eventually the review gate can be sampled rather than universal. That’s when the scale is real.

    Five gates worth installing this month

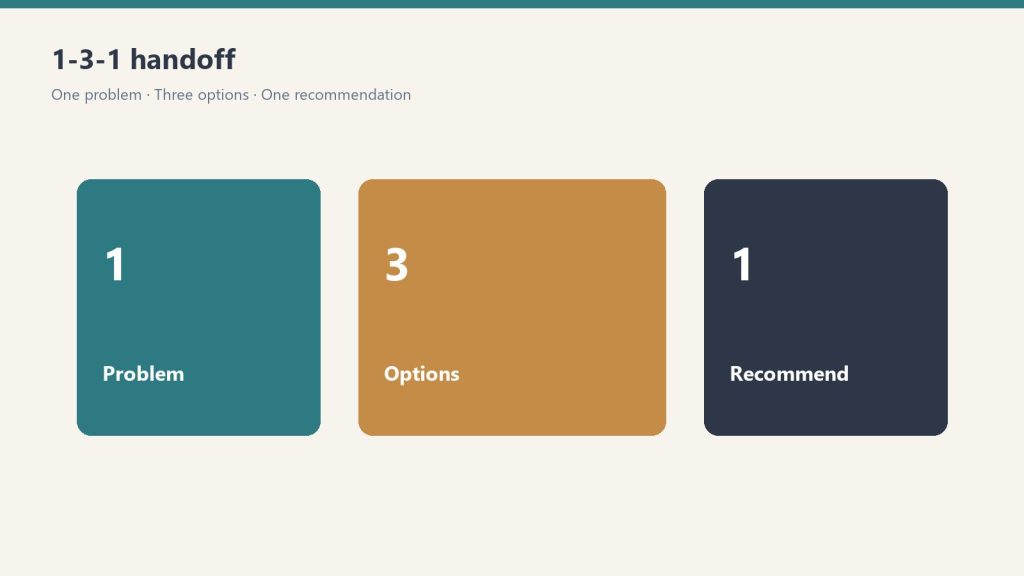
    Three panels showing one problem, three options, one recommendation
    Five gates worth installing this month.
    1. A controlled-vocabulary tag system on the databases your agent reads from
    2. A prompt template library so prompts are versioned, not improvised
    3. A quality rubric for the output type (the foundry article uses a 5-dimension rubric — same idea)
    4. A weekly review window where you sample 10% of agent output
    5. A failure log where caught drift gets recorded so prompts can be tightened

    Why this is hard

    Because gates are boring. Volume is exciting. Adding a new Custom Agent feels like progress. Tightening a tag taxonomy feels like procrastination. The operators who win at AI scale are the ones who can stay with the boring work long enough that the volume is actually trustworthy.

    Same agent, same model, same credits. The difference is the gates.

    Sources

    • Tygart Media editorial line
    • Notion 3.3 release notes (February 24, 2026)

    Continue the journey

    This article is part of the May 3 Cliff Decision journey-pack on Tygart Media. Here’s where to go next:

  • Notion Workers for Agents: Code Execution for Builders

    Notion Workers for Agents: Code Execution for Builders

    Anchor fact: Workers for Agents is in developer preview as of April 2026, accessible via the Notion API but not exposed through any consumer-facing UI yet. Workers run server-side JavaScript and TypeScript, sandboxed via Vercel Sandbox, with a 30-second execution timeout, 128MB memory limit, no persistent state, and outbound HTTP restricted to approved domains.

    What is Notion Workers for Agents?

    Workers for Agents is Notion’s code execution environment for AI agents, in developer preview as of April 2026. Workers run server-side JavaScript and TypeScript functions that an agent calls when it needs to compute, query a database, transform data, or call an approved external API. Workers are sandboxed (30-second timeout, 128MB memory, no persistent state) and run on Vercel Sandbox infrastructure.

    The 60-second version

    Workers turn Notion AI from a text layer into a compute layer. Before Workers, Notion AI could read pages and write text. It couldn’t run code, couldn’t transform data, couldn’t reliably call external APIs. With Workers, an agent can offload computational tasks to a sandboxed JavaScript or TypeScript function — running for up to 30 seconds in 128MB of memory, with outbound HTTP restricted to approved domains. It’s the upgrade that makes Notion agents capable of real workflow automation, not just document assistance.

    Why Workers matter

    Three stacked layers: chat UI, tools, agent runtime
    Why Workers matter.

    Three things change when agents can call code:

    1. Real database queries. Before Workers, an agent could read pages but couldn’t reliably do “give me all rows where date is in the next 7 days and owner is unassigned.” With Workers, that’s a one-line query that returns structured data the agent uses in its response.

    2. Approved external API calls. An agent can fetch live exchange rates, look up shipping status, query an internal CRM, or pull from any service exposed through an approved domain. The agent doesn’t make the call directly — it delegates to a Worker that does the call and returns the result.

    3. Multi-step transformation chains. Read CSV → transform → enrich → write back to a database. Each step is a Worker. The agent orchestrates the chain. This is the pattern that lets agents handle real ops workflows that previously required Zapier, n8n, or custom code.

    The technical constraints worth knowing

    Workers are not Lambda. They have intentional limits:

    • 30-second execution timeout. Anything longer needs to be split into smaller Workers or moved off-platform. No long-running batch jobs.
    • 128MB memory limit. Streams and chunked processing only for large data. No loading 500MB CSVs into memory.
    • No persistent state between calls. Each Worker invocation is fresh. State lives in Notion databases or external services, not in the Worker.
    • Outbound HTTP restricted to approved domains. You declare which domains a Worker can reach. This is a security feature, not a limitation to fight.
    • Sandboxed via Vercel Sandbox. Workers run on Vercel’s untrusted-code infrastructure. Performance is solid; cold starts exist.

    What you need to use Workers

    This is not a point-and-click feature. Requirements:

    • A Notion developer account
    • A Notion integration set up
    • Familiarity with the agent configuration format
    • API access — Workers are API-only as of April 2026

    If you’ve never built on the Notion API, Workers aren’t your starting point. Standard agents and skills are. Workers are the next step once those don’t go far enough.

    Three Worker patterns to start with

    Four cards for content, ops, build, and knowledge work with Claude
    Three Worker patterns to start with.

    1. The data-fetch Worker. Agent says “I need the current value of X.” Worker calls an approved external API, parses the response, returns a structured value. Common pattern: looking up live data the agent doesn’t have access to natively.

    2. The transform-and-write Worker. Agent passes structured input to a Worker. Worker reshapes the data — formatting dates, normalizing strings, computing derived fields — and writes the result to a Notion database row. Common pattern: cleaning incoming form submissions before they land in the CRM.

    3. The chain-orchestration Worker. A Worker that calls other Workers in sequence, collecting results and returning a synthesized output. Common pattern: a multi-step intake process where each step needs different logic.

    Why this is the more interesting story than May 3

    The May 3 credit cliff is the news story. Workers are the strategic story. Workers are why credits exist — Notion can’t ship “an agent that calls any code you want and any API you want” on a flat fee. Credits make Workers viable as a product. The pricing news is the boring infrastructure that supports the interesting capability.

    If you’re a developer or an agency building on Notion, Workers reshape what’s possible. A custom Notion deployment for a client used to mean “we set up databases and trained the team.” Now it can mean “we set up databases, trained the team, and built five Workers that handle their specific workflows.”

    What’s still missing

    Seven cards naming common AI chatbot failure modes
    What’s still missing.

    Three gaps in the current developer preview worth tracking:

    • No consumer UI. Workers are API-only. End users can’t build them in the Notion app. This will change.
    • Limited debugging. Errors in Workers surface as agent errors. Better tooling for inspecting Worker execution is on the roadmap.
    • Sandbox boundaries are evolving. Approved domain lists, memory limits, and timeout limits are likely to relax over time. Build with current limits; don’t bet on them staying fixed.

    Workers turn Notion AI from a text layer into a compute layer.

    Sources

    • Notion 3.4 part 2 release notes (April 14, 2026)
    • Vercel blog — How Notion Workers run untrusted code at scale with Vercel Sandbox
    • Notion API documentation — Workers for Agents (developer preview)

    Continue the journey

    This article is part of the May 3 Cliff Decision journey-pack on Tygart Media. Here’s where to go next:

  • When Not to Use a Notion AI Agent (What to Keep Manual)

    When Not to Use a Notion AI Agent (What to Keep Manual)

    Anchor fact: Custom Agents are powerful but inappropriate for tasks involving novel judgment, regulated content, sensitive personnel matters, or work where the cost of being wrong exceeds the cost of doing it manually.

    When should you not use a Notion AI agent?

    Don’t use Notion agents for tasks requiring novel judgment about people, compliance-sensitive output (legal, medical, financial guidance), one-off work that won’t repeat, or any decision where the cost of being wrong is higher than the cost of doing the work manually.

    The 60-second version

    Notion agents are a hammer. Not everything is a nail. The honest list of tasks that should stay manual is longer than most operators want to admit. Performance reviews. Hiring decisions. Compliance-sensitive drafting. Anything that gets sent to a regulator or a lawyer. One-off work. Anything where the value of doing it yourself is the thinking, not the output. The discipline of saying “not this one” is what separates operators who use AI from operators who use AI badly.

    Five categories that stay manual

    Four cards for content, ops, build, and knowledge work with Claude
    Five categories that stay manual.

    1. Decisions about specific humans. Performance reviews, hiring choices, conflict mediation, layoff decisions. The agent can summarize and surface evidence; it shouldn’t draft the decision. The risk isn’t that the output is wrong — it’s that the decision-maker outsources the moral weight of the call. Don’t.

    2. Regulated or compliance-sensitive output. Legal language, medical guidance, financial advice, anything that gets reviewed by a regulator. Use AI to draft inputs to a human reviewer. Never ship the AI output as final.

    3. Novel work without precedent. “Plan our entry into a new market.” “Write our crisis response if X happens.” Agents synthesize from existing patterns. They struggle when the situation has no analog in your workspace.

    4. One-off tasks. Building a Custom Agent for a task you’ll do once is more work than just doing the task. The investment in setup (prompt, scope, rubric, review) only pays back across many repetitions.

    5. Work where doing it is the point. Strategic thinking. Writing meant to clarify your own ideas. Reflection journals. The output isn’t the value; the doing is. AI shortcuts the doing, which destroys the value.

    The dangerous middle category

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    The dangerous middle category.

    Worse than tasks that obviously shouldn’t be agent work are tasks that look like agent work but aren’t. Examples:

    • “Draft client emails” — sounds like a clear agent task, but the relationship cost of off-tone email outweighs the time saved
    • “Summarize our team’s wins for the board” — looks easy, but framing matters and an agent’s framing is generic
    • “Write our company values” — agents can produce values; only humans can mean them

    The test: if the value of the output depends on being recognizably yours, agent involvement should be limited to research and drafting, not production.

    How to decide

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How to decide.

    Three questions before launching a new Custom Agent:

    1. Will I do this task at least 20 times in the next year? (No → don’t build an agent.)
    2. Is the cost of a wrong output bounded? (No → don’t automate it.)
    3. Is the value in the output, not the doing? (No → don’t outsource the doing.)

    If any answer is no, the task stays manual. That’s not a failure of AI. That’s discipline.

    AI shortcuts the doing, which destroys the value.

    Sources

    • Tygart Media editorial line
    • Operator practice notes

    Continue the journey

    This article is part of the May 3 Cliff Decision journey-pack on Tygart Media. Here’s where to go next:

  • Notion Custom Agent ROI: Calculating Your Time Reclaimed

    Notion Custom Agent ROI: Calculating Your Time Reclaimed

    Anchor fact: Notion Custom Agents cost $10 per 1,000 credits starting May 4, 2026. Credits reset monthly with no rollover. Simple agent runs use a handful of credits; complex multi-step runs can use dozens to hundreds.

    How do you calculate ROI on a Notion Custom Agent?

    Multiply the human-equivalent time saved per agent run by the dollar value of that time, subtract the credit cost per run (at $10/1000 credits starting May 4, 2026), then multiply by run frequency. An agent that saves 30 minutes of work per run at $50/hour, costs 5 credits ($0.05) per run, and runs daily produces ~$700/month in net value.

    The 60-second version

    Most operators don’t do the math because the math feels small. It isn’t. A Custom Agent that runs daily and saves 30 minutes of $50-an-hour work produces about $750/month in time savings and costs maybe $1.50 in credits. The ratio is so favorable for the right agents that the real ROI question isn’t whether agents pay back — it’s which agents to retire because the math doesn’t clear. After May 4, the bottom of the agent fleet stops being free. That’s good. That’s how you stop running agents that weren’t earning their keep.

    The simple formula

    Floor versus ceiling cards for commoditized work and human-network premium
    The simple formula.

    For any Custom Agent:

    • Time saved per run (minutes) × frequency (runs per month) × hourly value ($/hour ÷ 60) = monthly value
    • Credits per run × frequency × $0.01 (since $10/1000 = $0.01/credit) = monthly cost
    • Monthly value − monthly cost = net ROI

    Three worked examples:

    Example 1 — The weekly digest agent.
    Saves 45 minutes/run, runs 4×/month, your hourly value is $75. Monthly value: 45 × 4 × ($75/60) = $225. Credits: ~20/run × 4 × $0.01 = $0.80. Net: $224.20/month. Keep it.

    Example 2 — The lead enrichment agent.
    Saves 5 minutes/run, runs 200×/month (every new lead), hourly value $50. Monthly value: 5 × 200 × ($50/60) = $833. Credits: ~3/run × 200 × $0.01 = $6. Net: $827/month. Keep it.

    Example 3 — The exploratory analysis agent.
    Saves 15 minutes/run, runs 2×/month, complex multi-step (~80 credits). Monthly value: 15 × 2 × ($50/60) = $25. Credits: 80 × 2 × $0.01 = $1.60. Net: $23.40/month. Keep it, but barely. If credit cost rises or run complexity grows, retire it.

    Where the math turns negative

    Seven cards naming common AI chatbot failure modes
    Where the math turns negative.

    Three patterns where the ROI math fails:

    1. The fancy agent that runs occasionally. Complex agents cost dozens to hundreds of credits per run. Low frequency means the per-month cost is small but so is the value. Net is small. Better as a manual prompt.
    2. The agent that needs human review on every output. If you review 100% of the output anyway, the time saved is partial. Reduce the apparent monthly value by 40-60%. Many agents stop clearing the bar with that haircut.
    3. The agent that runs but the output isn’t used. This is the silent killer. Credits consumed, no value extracted. The fix is monthly observation: which agent outputs do you actually open?

    The portfolio approach

    Treat your Custom Agents as a portfolio. Three categories:

    • Anchors (top 3-5 agents producing outsized ROI). Protect their credit budget first.
    • Earners (agents producing positive but modest ROI). Watch monthly. Retire if drift.
    • Experiments (agents under evaluation). Cap at 20% of credit budget.

    Anything outside those three categories is waste.

    The monthly review ritual

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The monthly review ritual.

    Once a month, look at:

    • Credits consumed per agent (Notion’s dashboard will show this)
    • Outputs produced per agent
    • Outputs you actually used per agent
    • Time saved estimate per agent

    The gap between “outputs produced” and “outputs used” is where the budget goes to die. Close that gap or retire the agent.

    Treat your Custom Agents as a portfolio. Anchors, earners, experiments. Anything outside those three is waste.

    Sources

    • Notion Help Center — Custom Agent pricing
    • Notion 3.3 release notes (February 24, 2026)

    Continue the journey

    This article is part of the May 3 Cliff Decision journey-pack on Tygart Media. Here’s where to go next:

  • Notion Custom Agents vs Basic AI: Is the Upgrade Worth It?

    Notion Custom Agents vs Basic AI: Is the Upgrade Worth It?

    Anchor fact: Custom Agents are available on Business and Enterprise plans only. They run autonomously on triggers or schedules, can work for up to 20 minutes per task across hundreds of pages, and starting May 4, 2026, consume Notion Credits at $10 per 1,000.

    Do you need Notion Custom Agents or is basic Notion AI enough?

    Basic Notion AI handles inline drafting, summaries, and reactive prompts within a page. Custom Agents add proactive execution — running on schedules or triggers, working autonomously for up to 20 minutes, and using skills and Workers. Choose Custom Agents only if you have recurring autonomous workflows that justify Business-plan pricing and Notion Credit consumption.

    The 60-second version

    Most operators don’t need Custom Agents. They think they do because the marketing makes Custom Agents sound essential, but the honest answer is that basic Notion AI plus standard agent prompts cover most knowledge-work needs. Custom Agents earn their cost only when you have specific, repeating, autonomous work — things that run on a schedule or trigger without you starting them. If you don’t have that pattern in your workflow, you’re paying for capability you won’t use.

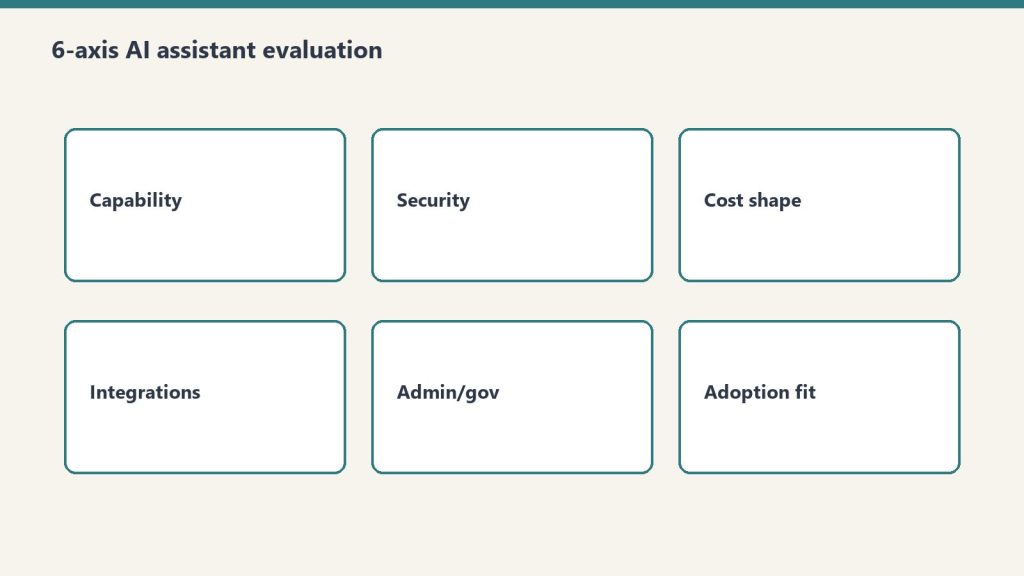
    The honest comparison

    Six evaluation cards for choosing an AI assistant platform
    The honest comparison.

    Basic Notion AI (included on Plus, Business, Enterprise plans):

    • Inline writing assistance — draft, rewrite, summarize, translate
    • Q&A over your workspace content
    • Standard AI Autofill on databases
    • Meeting notes summarization
    • Reactive: you prompt, it responds

    Custom Agents (Business and Enterprise plans only):

    • Everything above, plus:
    • Runs on schedules or triggers without prompting
    • Can work autonomously for up to 20 minutes per task
    • Spans hundreds of pages in a single run
    • Skills can be attached for repeatable workflows
    • Workers integration (developer preview) for code execution
    • Can integrate with Calendar, Mail, Slack at agent level
    • After May 4, 2026: consumes Notion Credits at $10/1000

    When Custom Agents are worth it

    Three stacked layers: chat UI, tools, agent runtime
    When Custom Agents are worth it.

    Five workflow patterns where Custom Agents pay off:

    1. Recurring deliverables. Weekly status reports, monthly board prep, daily standups. If you produce the same shape of document on a schedule, an agent that runs Friday at 4 PM and drops the draft in your inbox is worth real money in time saved.

    2. Continuous database enrichment. A CRM that needs new leads scored, categorized, and routed within minutes of arrival. A content database that needs incoming articles tagged and summarized. An ops database that needs items checked for SLA breaches.

    3. Cross-source synthesis on demand. “Pull everything from the last two weeks across Slack, Calendar, and our project pages and tell me what’s at risk.” This is a 20-minute autonomous task that would take a human two hours.

    4. Multi-step workflows with handoffs. Triage incoming → route to owner → draft response → flag exceptions. The chain is what makes it agent work, not assistant work.

    5. Off-hours and overnight work. If you’d benefit from work happening while you sleep, agents are the only Notion layer that can do it. Reactive AI sits idle until you arrive.

    When basic Notion AI is enough

    Four cards for content, ops, build, and knowledge work with Claude
    When basic Notion AI is enough.

    Most knowledge workers fit here:

    • Solo writers and researchers who need help drafting and summarizing
    • Teams of fewer than 10 where work is mostly real-time collaborative
    • Workflows where the AI is occasional, not scheduled
    • Anyone on Plus plan (Custom Agents aren’t available anyway)
    • Anyone whose AI usage is “I ask, it answers” — that’s reactive, not agentic

    If you’re in this group, upgrading to Business for Custom Agents is paying for capacity you won’t use. Stay with basic AI and revisit when the workflow pattern changes.

    The cost calculus after May 4

    Before May 4, 2026, Custom Agents are free to try on Business and Enterprise. After, every run consumes credits at $10 per 1,000. Real numbers:

    • A simple agent run (single-page summary): typically a handful of credits — pennies
    • A complex multi-step run (synthesis across many pages, multiple skills chained): can run into the dozens or hundreds of credits — measurable dollars
    • A daily scheduled agent that runs 30 days/month at moderate complexity: budget low tens of dollars per agent per month

    Math gets serious when you have many agents running daily. A workspace with 10 active Custom Agents can easily consume hundreds of dollars per month in credits on top of Business-plan seat fees. That’s the ROI conversation that turns “I’m experimenting with agents” into “I run a small fleet on a budget.”

    The decision framework

    Walk yourself through these four questions:

    1. Do you have recurring work on a schedule? No → basic AI is fine.
    2. Are you on Business or Enterprise? No → Custom Agents aren’t available. Upgrade or stay with basic.
    3. Does the time saved per agent run, multiplied by frequency, exceed the credit cost? No → basic AI plus manual prompts is cheaper.
    4. Are you willing to manage the credit pool monthly? No → don’t take on the operational overhead.

    If all four are yes, Custom Agents earn their place. If any is no, basic Notion AI is the right call.

    Reactive AI sits idle until you arrive.

    Sources

    • Notion 3.3 Custom Agents release notes (February 24, 2026)
    • Notion Help Center — Custom Agent pricing
    • Notion Pricing page (April 2026)

    Continue the journey

    This article is part of the May 3 Cliff Decision journey-pack on Tygart Media. Here’s where to go next:

  • Notion Custom Agents Pricing: The May 3 Operator Checklist

    Notion Custom Agents Pricing: The May 3 Operator Checklist

    Anchor fact: Custom Agents are free to try through May 3, 2026. Starting May 4, they require Notion Credits at $10 per 1,000 credits, and access stays gated to Business and Enterprise plans.

    What changes for Notion Custom Agents on May 3, 2026?

    Custom Agents are free to try through May 3, 2026 on Business and Enterprise plans. Starting May 4, agents require Notion Credits at $10 per 1,000 credits. Credits are workspace-shared, reset monthly, and don’t roll over. If credits hit zero, every Custom Agent in the workspace pauses until an admin tops up.

    The 60-second version

    If you’re running Notion Custom Agents on a free trial right now, you have until May 3, 2026 before the meter starts. On May 4, agents stop running unless your workspace admin has bought Notion Credits at $10 per 1,000 credits. Credits reset monthly. They don’t roll over. Custom Agents stay locked to Business and Enterprise plans only — Free and Plus plans don’t get them at all.

    The decision in front of you isn’t “should I keep using Custom Agents.” It’s three smaller decisions stacked: whether to be on the right plan, whether to budget credits, and whether the agents you’ve already built earn their keep at the new price.

    This article walks through each one in operator terms.

    What actually changes on May 4

    Floor versus ceiling cards for commoditized work and human-network premium
    What actually changes on May 4.

    Before May 3:

    • Custom Agents run for free on Business and Enterprise plans (including Business trials)
    • No credit accounting
    • You can build, test, and run as much as your plan allows

    On and after May 4:

    • Custom Agents consume Notion Credits per task
    • Credits cost $10 per 1,000, billed as a workspace-level add-on
    • Credits are shared across the workspace, not per-seat
    • Credits reset every month with no rollover
    • If the credit pool empties, every Custom Agent in the workspace pauses until an admin tops up
    • Agents stay on Business and Enterprise plans only — no migration path to Free or Plus

    The mechanic worth pausing on: shared, non-rolling, hard-pause-on-zero. That’s not a soft throttle. If your workspace runs out mid-month, the agent that drafts your weekly board update doesn’t degrade gracefully. It stops. An admin has to log in and add credits before anything resumes.

    Why this matters more than it sounds

    Most of the coverage of this transition reads it as a pricing announcement. It’s actually a posture announcement. Notion is saying: agents are real infrastructure, real infrastructure has metering, and metering changes how teams use it.

    Three knock-on effects worth thinking about:

    1. The “leave it running and forget about it” pattern dies. Free trial behavior — point an agent at a database, walk away, come back a week later, see what it did — becomes expensive behavior. Every autonomous run consumes credits. If you’ve built agents that run on schedules or triggers, that scheduled work is now a line item.

    2. Agent ROI becomes a real conversation. Up to now, the question was “does this agent save me time?” Starting May 4, the question is “does this agent save me time at a credit cost lower than what my time is worth?” That’s a much sharper test, and a fair number of trial-era agents won’t survive it.

    3. The build-vs-prompt decision shifts. A one-off prompt to Notion AI inside a doc still runs on plan-included AI. A Custom Agent — even doing similar work — runs on credits. For repetitive work that’s worth automating, the agent still wins. For occasional work, you may quietly retreat to manual prompts.

    What you should do this week

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What you should do this week.

    This is the operator’s checklist, in priority order.

    1. Audit every Custom Agent you’ve built

    Open your workspace’s Custom Agents list. For each one, write down four things:

    • What does it do?
    • How often does it run?
    • Roughly how complex is each run (one step, multi-step, multi-page)?
    • What’s the human equivalent — how long would the task take a person?

    Anything you can’t answer is a candidate to retire on May 3.

    2. Identify your top 3 keepers

    Sort the list by “human equivalent time saved per month.” The top three are your ROI anchors. Those are the agents you’ll actively budget credits for. Everything below the line is provisional — keep them running only if credit headroom allows.

    3. Get on the right plan if you aren’t already

    Custom Agents stay on Business and Enterprise. If your workspace is on Free or Plus and you’ve been using Custom Agents on a Business trial, the trial expiry is the cutoff. After that, agents disappear entirely unless you upgrade. Business is $20 per user per month billed annually, $24 monthly. Enterprise is custom-priced.

    4. Have an admin set up the credit dashboard before May 4

    The credit dashboard is where admins buy and track credits. The smart move is to provision a starter pack — somewhere in the hundreds-to-low-thousands range of credits — before the cutover, so your top-three agents don’t pause on the first morning of the new pricing era. You can scale credit purchases up or down monthly based on what actually gets consumed.

    5. Set up usage observation

    Once credits are running, treat the first 30 days as data collection. Watch which agents burn credits fastest. Watch which agents you actually open the output of. The gap between “credits consumed” and “output used” is where the next round of agent retirement happens.

    The trap to avoid

    Seven cards naming common AI chatbot failure modes
    The trap to avoid.

    The natural temptation between now and May 3 is to build more agents while it’s still free. Don’t. The agents you build in a free-trial mindset are precisely the ones you’ll regret budgeting credits for in May.

    A better use of the remaining trial window: harden the agents you already have. Tighten their scopes. Reduce the number of pages they touch. Cut the multi-step chains that don’t need to be multi-step. Every operation you can shave off a workflow today is a credit you don’t spend tomorrow.

    This is the gates-before-volume principle applied to agents. You don’t scale by adding more agents. You scale by making each agent leaner before the meter starts.

    What this signals about Notion’s roadmap

    Reading the tea leaves: credit-based pricing for agents is the foundation for Workers for Agents (currently in developer preview as of April 2026). Workers let agents call code and external APIs. That’s the kind of capability that needs metering — you can’t ship “an agent that calls any API you want” on a flat fee. Credits make Workers possible at scale.

    If you’re a developer or an agency, this is the more interesting story. The May 3 cliff is the boring part. The Workers preview is the part to watch, and credits are the pricing rail that makes Workers viable as a product.

    The operator’s bottom line

    May 3 is not a problem to solve. It’s a forcing function that turns “I’m experimenting with agents” into “I run a small fleet of agents on a budget.”

    That’s a healthier place to be. Free trials produce sprawl. Metered usage produces discipline.

    Decide your top three. Get on the right plan. Have an admin top up credits before May 4. Spend the next week tightening, not building. That’s the entire move.

    Sources

    • Notion Help Center — Buy & track Notion credits for Custom Agents
    • Notion 3.3 release notes (February 24, 2026)
    • Notion Pricing page (April 2026 snapshot)

    Continue the journey

    This article is part of the May 3 Cliff Decision journey-pack on Tygart Media. Here’s where to go next:

  • Restoration Company Revenue: 3 Structural Growth Levers

    Restoration Company Revenue: 3 Structural Growth Levers

    “How do I increase restoration sales?” is usually answered with a list of marketing tactics. The honest answer is structural: three levers move restoration company revenue, and most growth that lasts comes from operating those three deliberately rather than chasing more leads.

    The three levers are pricing discipline, mix shift toward higher-margin work, and capacity utilization. They compound. A restoration company that improves any one of them by 10% sees a meaningful revenue and margin lift. A company that improves all three simultaneously transforms its business in 18 months.

    Lever 1: Pricing Discipline

    Floor versus ceiling cards for commoditized work and human-network premium
    Lever 1 — pricing discipline.

    Pricing discipline is the most undervalued growth lever in the restoration industry. The reason is structural — most restoration revenue is priced by Xactimate or Symbility line items, which creates the illusion that pricing is fixed by the carrier. It is not.

    The pricing levers that operators actually control:

    • Scope discipline. The most consequential pricing decision in any restoration job is whether the documented scope reflects the work performed. Under-scoping is the largest source of margin erosion in the industry.
    • Time and material work selection. Some categories of work — biohazard, contents, specialty services — can be billed on a time-and-material basis at materially higher margin than carrier-line-item rates. The mix question is whether your shop pursues this work or defaults to insurance-priced jobs.
    • Self-pay and direct-bill work. Cash work outside the insurance channel can be priced to market rather than to carrier line items. The discipline of building a direct-pay funnel produces a higher-margin revenue stream that compounds.
    • Estimating consistency. Two estimators on the same shop floor will produce different scopes for the same loss. The variance is pure margin leakage. Standardized estimating practice — checklist-driven, peer-reviewed — closes the variance.

    Pricing discipline produces revenue without producing more jobs. It is the highest-margin growth lever a restoration shop has access to, and it is rarely the first one operators reach for.

    Lever 2: Mix Shift

    Mix shift is the deliberate movement of revenue from lower-margin work types to higher-margin work types. Not every job in a restoration shop produces the same gross margin. The honest accounting:

    • Carrier-driven residential water mitigation: stable volume, compressed margin, high competitive intensity.
    • TPA program work: predictable, lower margin, vendor-relationship dependent.
    • Direct-to-owner commercial work: longer cycle, higher margin, less price-sensitive.
    • Specialty services — biohazard, trauma cleanup, contents, large-loss commercial — variable volume, materially higher margin.
    • Reconstruction: high revenue per job, complex margin dynamics, capacity-intensive.

    The mix-shift question is which categories of work the shop is deliberately growing. Most restoration companies inherit their mix passively — they take what comes through the door. Companies that grow revenue without growing headcount tend to be operating mix shift deliberately, often by adding a single specialty service category that pulls margin upward.

    The structural insight is that adding a higher-margin work category typically requires the same overhead as adding more of the existing mix, which means the incremental gross margin drops disproportionately to the bottom line.

    Lever 3: Capacity Utilization

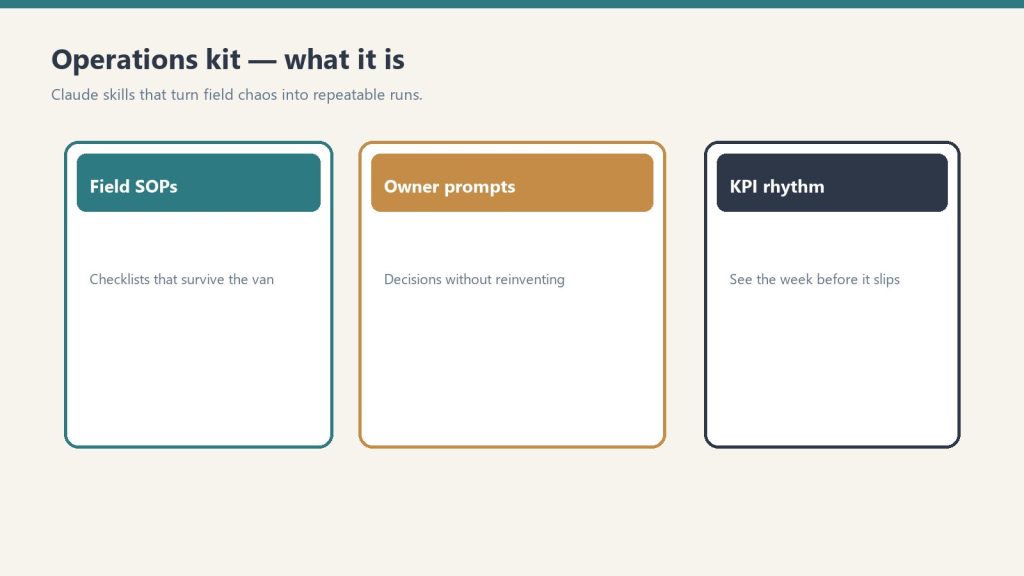
    Three cards for field SOPs, owner prompts, and KPI rhythm in an operations kit
    Lever 3 — capacity utilization.

    Capacity utilization is the lever that determines whether existing assets produce more revenue. A restoration shop with 12 technicians, 6 trucks, and a fixed overhead is producing a specific level of revenue. The question is whether that level is constrained by lack of demand, lack of operational efficiency, or both.

    The capacity levers that move revenue:

    • Dispatch efficiency. The minutes between FNOL and on-site arrival, and the routing efficiency across multiple jobs in a day, compound into measurable capacity gains.
    • Technician productivity. Documentation discipline, equipment readiness, and clean handoffs between production and reconstruction directly affect billable hours per technician per day.
    • Equipment turn rate. Restoration equipment that sits in the warehouse is not producing revenue. Equipment tracking and dispatch discipline produces meaningful utilization gains.
    • After-hours and weekend response. A 24/7 restoration operation that under-utilizes evening and weekend capacity is leaving the highest-urgency, lowest-competition work on the table.

    Capacity utilization compounds with the other two levers. A shop with disciplined pricing and a deliberate mix shift, but poor capacity utilization, leaves substantial revenue uncaptured. A shop with strong utilization but weak pricing discipline is running hard for compressed margin.

    The Multiplier Effect

    The three levers multiply rather than add. A 10% improvement in pricing discipline, a 10% mix shift toward higher-margin work, and a 10% improvement in capacity utilization does not produce 30% revenue growth. It produces meaningfully more — typically in the range of 35% to 45% — because the higher-margin work earns higher prices on more efficient operations.

    This is why operators who run all three levers deliberately can grow revenue and margin without growing the lead pipeline. The restoration industry’s default operating mode — chase more leads, take whatever comes through the door — leaves all three levers passive.

    What to Measure

    Each lever has a measurement that translates the abstract concept into operating discipline:

    • Pricing discipline: gross margin trend by job category, scope variance between estimators, percentage of revenue from time-and-material and direct-pay work.
    • Mix shift: revenue distribution across work categories, gross margin by category, year-over-year shift toward target categories.
    • Capacity utilization: billable hours per technician per day, equipment turn rate, percentage of jobs with arrival time within service-level commitment.

    An operator who reviews these numbers monthly and can describe what is moving and why has a lever-driven business. An operator who reviews only top-line revenue is running on autopilot.

    The Marketing Lever Is the Fourth, Not the First

    Seven cards naming common AI chatbot failure modes
    The marketing lever is the fourth, not the first.

    Marketing — SEO, paid advertising, referral systems, content — is a real lever, but it is the fourth one, not the first. A restoration company with disciplined pricing, deliberate mix shift, and strong capacity utilization will absorb marketing-driven leads at high efficiency. A company without those three will absorb marketing-driven leads at the same low efficiency they absorb existing leads, and the marketing investment will produce disappointing returns.

    This is the structural reason that restoration owners who jump straight to “we need more leads” rarely produce sustained revenue growth. The leads land on a leaky operating model.

    Related on Tygart Media: cash flow & profit · commercial sales.

    Frequently Asked Questions

    What is the highest-leverage way to increase restoration company revenue?

    Pricing discipline — specifically scope discipline, deliberate inclusion of time-and-material and direct-pay work, and standardized estimating practice — is the highest-margin growth lever a restoration shop has. It produces revenue without producing more jobs.

    How do I improve gross margin in a restoration business?

    The three structural levers are pricing discipline, mix shift toward higher-margin work categories like biohazard or commercial direct-to-owner, and capacity utilization. Operating all three deliberately produces measurable margin lift in 12 to 18 months.

    Should I add specialty services to my restoration business?

    Specialty services — biohazard, trauma cleanup, contents, large-loss commercial — typically produce higher gross margin than carrier-driven residential water mitigation, and they pull mix toward the high-margin end. The decision depends on whether your shop has the operational capacity and certifications to deliver them well.

    How do I know if my restoration company has a capacity utilization problem?

    The diagnostic measures are billable hours per technician per day, equipment turn rate, and percentage of jobs with arrival time inside service-level commitment. A shop where these numbers are not measured monthly almost certainly has untapped capacity.

    Is more marketing the answer to slow restoration sales?

    Not by itself. Marketing-driven leads land on whatever operating model exists. A restoration company with weak pricing discipline, passive mix, and poor capacity utilization will absorb marketing leads at low efficiency and produce disappointing returns on marketing spend. Operating discipline first, marketing second.

    For operator-focused playbooks on running and scaling a restoration company, see the Restoration Operator’s Playbook archive.

  • How to Get Hired Without Applying: The 30-Minute Daily Protocol That Gets You Found

    How to Get Hired Without Applying: The 30-Minute Daily Protocol That Gets You Found

    The short version: If you want a job in a flooded market, stop trying to be employable in general. Pick one specific corner of your industry. Spend 30 minutes in the morning learning it. Spend the day forgetting most of what you read. Spend 30 minutes at night posting about whatever survived. The forgetting is the filter. The publishing is the proof. Six months in, you are not looking for a job. The job is looking for you.

    Most career advice is built around a quiet lie: that the way to stand out is to be a little better at everything everyone else is also a little better at. Sharpen your resume. Add a certification. Take another course. Write another cover letter. Put it all on LinkedIn and hope the algorithm notices.

    It does not work. It cannot work. The market is not short on generalists. It is starving for specialists, especially specialists who have visibly done the thing in public.

    What follows is a job-seeking strategy that takes about an hour a day, requires no extra money, and exploits two pieces of cognitive science most career coaches do not mention: spaced repetition and spaced retrieval. The whole point is to use forgetting as a feature, not a bug — and to publish the part that survives.

    The four-step protocol

    1. Pick three things from your industry that are the most valuable. Not the most popular. Not the most discussed. The three problems that, when someone solves them, money moves.
    2. Pick one of the three you actually want to become an expert on. The one you would willingly read about on a Sunday with no one watching.
    3. Spend 30 minutes in the morning researching it. Read primary sources. Take rough notes. Do not try to remember everything. You will not.
    4. Spend 30 minutes in the evening posting about it. Whatever you can still articulate without notes is the thing worth publishing. The rest was noise.

    That is the entire system. It is shorter than most morning routines. It will outperform almost any other career-building activity you can do in the same time.

    Why morning study and evening publishing actually works

    The forgetting is doing the editing

    When you study something in the morning and then go live a normal day, your brain runs a quiet triage process. Most of what you read decays. The handful of things that connect to something you already understand — or that genuinely surprised you, or that you can imagine using — survive.

    By evening, what is left in your head is not a complete summary of what you read. It is the signal of what you read. The compression happened automatically.

    This is why the evening publishing step matters. You are not trying to teach the morning’s full reading. You are publishing what survived eight hours of normal life. That is, by definition, the part most likely to be useful, memorable, and original.

    Spaced repetition is one of the most-validated learning techniques in cognitive science

    The morning-then-evening rhythm is a lightweight version of spaced repetition, the practice of revisiting information at intervals rather than cramming it in one session. A 2024 prospective cohort study published through the American Board of Family Medicine tracked thousands of practicing physicians and found spaced repetition produced significantly better long-term knowledge retention than repeated study sessions.

    A separate quasi-experimental study at Jawaharlal Nehru Medical College found students using spaced repetition scored 16.24 versus 11.89 on post-test assessments compared to traditional study — a statistically significant difference (p < 0.0001) that held across multiple disciplines.

    The mechanism is not mysterious. Each time you successfully retrieve information after a delay, the neural pathway gets reinforced. Each time you fail to retrieve it, you learn something more important: that piece was not load-bearing. You can let it go.

    When you publish in the evening what you can still remember from the morning, you are running this loop in public. You are letting your brain tell you what mattered, then giving the world the part that mattered.

    The publishing layer is what changes your career

    Studying alone makes you smarter. Publishing what you study makes you findable.

    The career-changing leverage is in the second half. A junior marketer who quietly reads about LinkedIn ads for construction companies in rural areas for six months becomes a slightly better junior marketer. A junior marketer who publishes one short post per evening for six months about the same thing becomes the person every rural construction company finds when they search “how to run LinkedIn ads for a contractor.”

    That is not the same outcome. That is a different career.

    Specificity is the multiplier

    “LinkedIn ads” is a saturated topic. Hundreds of generalists post about it daily. Each new post fights for the same shrinking attention slice.

    “LinkedIn ads for construction companies in rural markets” is almost empty. The total competing supply of content might be a dozen serious posts a year. The total demand from rural construction company owners trying to figure this out is significant. The ratio is what makes the niche valuable.

    The specific corner you pick is the entire game. The narrower it is, the faster you become the visible expert in it. The narrower it is, the easier it is for the right buyer or hiring manager to find you. The narrower it is, the less you have to compete on resume and the more you compete on demonstrated thinking.

    What gets cited by AI is not what gets the most engagement

    There is a quiet shift happening in how hiring managers and buyers find people. They no longer search Google and scroll through ten blue links. They ask ChatGPT, Gemini, Perplexity, or Google’s AI Overview “who’s good at X?” and read what the AI says.

    The thing is — AI systems do not cite content based on follower count or engagement. They cite based on relevance, specificity, and structure. A short, well-structured LinkedIn article from someone with 200 followers is regularly cited above a viral post from someone with 200,000 followers, because the smaller account wrote something specific and useful.

    This is the most underpriced opportunity in personal branding right now. You do not need an audience. You need a corner you own and a publishing rhythm you can sustain. The AI does the distribution.

    What the evening 30 minutes should actually look like

    Do not overthink the format. The post is not the product. The practice is the product. Here is a workable template:

    • One observation from the morning’s reading. Not the main point. The thing that surprised you.
    • One concrete example of how it shows up in your specific niche.
    • One short opinion on what most people get wrong about it.

    That is roughly 150 to 250 words. It takes ten minutes to write if you let yourself write badly. The other twenty minutes are for the next day’s reading list and any replies to the previous day’s post.

    You do not need to post on LinkedIn. You can post anywhere your industry actually reads. But LinkedIn rewards consistent professional output more than almost any other platform, especially for B2B niches, and AI systems are increasingly citing LinkedIn articles in answer to professional queries. So the platform pays its own freight.

    Six months from now

    If you do this for six months — and almost no one does — three things are true at once.

    First, you actually know your niche better than 95% of the people who claim to. You have read primary sources every morning for 180 mornings. You have wrestled with the material publicly. You have gotten things wrong, gotten corrected by other practitioners, and updated your understanding in front of an audience.

    Second, you have a public record of that learning. Your LinkedIn — or whatever surface you chose — is now a longitudinal proof of competence in a specific area. Anyone vetting you can see exactly how you think about the problem they need solved.

    Third, the math has flipped. You are no longer trying to find a job. You are getting messages from people who need exactly what you have spent six months publishing about. Some of those messages are job offers. Some are consulting opportunities. Some are partnerships you would not have known existed.

    The whole strategy rests on a quiet observation: most people will not do this. Not because it is hard. Because it is slow at the start, requires saying things in public before you feel qualified, and pays nothing for the first few months. Most career advice optimizes around making people feel like they are doing something. This optimizes around making the market notice you have done something.

    The compounding loop

    The longer this runs, the better it gets. Six months of daily 30-minute morning study is roughly 90 hours of focused reading in a single domain — more than most working professionals invest in any specific topic outside of formal education. Six months of daily evening posting is roughly 180 short-form pieces of public-facing thinking in your niche.

    Compare that to the alternative: another resume rewrite, another certification, another generic course. None of those produce a public footprint. None of those compound. None of them make you findable to the people who are actually trying to solve the problem you have spent six months understanding.

    An hour a day. One narrow niche. Spaced repetition doing the editing. Evening publishing doing the marketing. The forgetting is the filter. The publishing is the proof. The compounding is what changes your career.

    Frequently asked questions

    How do I pick the right niche if I have not started a career yet?

    Pick the intersection of: a problem real businesses pay money to solve, an industry you find genuinely interesting, and an angle that is not already saturated. Specific is always better than general. “B2B SaaS marketing” is too broad. “Onboarding email sequences for vertical SaaS in healthcare” is the size of niche that wins.

    What if I already have a job and want to use this to switch fields?

    The protocol is identical. Do the morning study and evening publishing in the niche you want to move into, not the one you currently work in. Six months of public output in the new field is more credible to a hiring manager in that field than ten years of unrelated experience.

    What if I do not know enough to write anything yet?

    Write what you are learning, with that framing. “I have been studying X for two weeks. Here is the most surprising thing I have found so far.” Beginner-as-narrator is one of the most engaging voices on LinkedIn. People follow learning journeys. They scroll past finished experts.

    Does this work for technical fields too?

    Especially well. Engineers, scientists, and analysts who can publish clearly about their narrow domain are vanishingly rare and disproportionately valuable. The 30-minute evening post can be a code walkthrough, a paper summary, a debugging story, or a single counterintuitive finding. The format does not matter. The consistency does.

    What if I post for a month and nothing happens?

    Expected. The first 30 to 60 days are unread. The compounding starts somewhere between day 90 and day 180 for most people. The point of the practice is the practice. The audience is a side effect of the discipline, not the goal of it.

    How is this different from a traditional content marketing strategy?

    Traditional content marketing optimizes for traffic and conversions. This optimizes for being findable in the moment a buyer or hiring manager is searching for someone who understands their specific problem. It is closer to a slow-cooking authority strategy than a fast-twitch growth strategy. The output is the same — published material — but the goal is positioning, not pageviews.

    The bottom line

    The short post that became this article said: pick three things from your industry, choose one, study it 30 minutes in the morning, post about it 30 minutes at night. That is the whole strategy.

    What that short post did not say is why it works. The morning input gives your brain something to process. The day in between lets the trivial stuff fall away. The evening output forces you to publish what survived — which is, by the cleanest possible test, the part worth publishing. Repeat for six months. Pick the right niche. Watch what happens to your inbox.

    The career advice industry sells motion. This is the opposite. This is a small, slow, compounding bet on becoming visibly excellent at one specific thing. Almost no one will do it. That is what makes it work.


    Frequently Asked Questions

    How long before this protocol produces results?

    Most practitioners see the first inbound interest — a recruiter message, a LinkedIn DM, or a referral — within 30 to 60 days of consistent publishing. Meaningful job offers from the protocol typically appear between 60 and 120 days. The compound effect is real but it requires showing up every single day, not every few days.

    Does this work if I don’t have a large following?

    Yes — that is the point. The protocol is designed for zero followers. Niche specificity means your content surfaces in search and in algorithmic feeds for people who actually hire in that domain. A post about a specific IICRC standard seen by 40 restoration adjusters is worth more than a generic “open to work” post seen by 4,000 random connections.

    What platform should I publish on?

    LinkedIn is the primary platform for most B2B and professional roles. If your target niche is technical (engineering, development, data), adding a personal site or GitHub significantly accelerates the signal. Pick one platform and go deep — cross-posting thin content to multiple networks dilutes the authority signal you are trying to build.

    What if my niche is too broad?

    Narrow it by one layer. “Marketing” is too broad. “B2B SaaS content marketing” is still broad. “Content operations for vertical SaaS companies under $10M ARR” is specific enough to own. The discomfort of narrowing is the signal you are on the right track — niches that feel too small almost always have more hiring demand than the broad lane you came from.

    Is this only useful for people currently unemployed?

    No — the protocol is most powerful when you start it before you need a job. Building niche authority takes time; running it while employed means you enter your next search with an established signal rather than starting from zero. Many practitioners use it permanently as a career infrastructure habit, not a job-search tactic.