Tag: AI Tools

  • Claude 5 Release Date 2026: Leak Signals, Expected Features & Anthropic’s Timeline

    Claude 5 Release Date 2026: Leak Signals, Expected Features & Anthropic’s Timeline

    Updated July 6, 2026

    The “Claude 5” question is answered. The next-generation “5” models shipped as Claude Sonnet 5 (June 30, 2026) plus the Fable 5 / Mythos 5 tier above Opus — not a single “Claude 5” rename. As of July 6, 2026, Anthropic’s lineup is Claude Fable 5 (top tier above Opus; $10 in / $50 out per MTok; Mythos 5 is the limited-availability sibling), Claude Opus 4.8 (legacy — still listed) ($5/$25

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    ), Claude Sonnet 5 (released June 30, 2026; now the default for Free and Pro; introductory $2/$10 per MTok through Aug 31, 2026, then $3/$15), and Claude Haiku 4.5 ($1/$5). Opus 4.7 and Sonnet 4.6 are now legacy. Full details: the Claude Fable 5 Complete Guide.

    Last refreshed: September 25, 2026

    Verified vs. reported — May 15, 2026 standard: This article tracks third-party reporting on Claude 5’s expected release window and features. As of May 15, 2026, Anthropic has not, to our review of anthropic.com/news and docs.claude.com, published an official Claude 5 launch announcement. The Q2 2026 timeline, ~90%+ SWE-bench Verified figure, 500K context window claim, and “Sonnet 5 / Fennec” codename references all trace to third-party reporting (TechCrunch interview citations, Claude5.com, Fello AI, WaveSpeed Blog) that we could not independently confirm against an Anthropic-published primary source. The information may still be accurate; the verified-vs-reported distinction means it has not been confirmed by Anthropic on the record.

    For the full current model lineup that is officially documented — Opus 4.8 (legacy — still listed) (knowledge cutoff January 2026, 1M context, $5/$25

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    MTok), Sonnet 4.6, Haiku 4.5 — see Claude Models Roadmap May 2026. That article maintains the verified-vs-reported standard throughout.

    Model Accuracy Note — Updated June 9, 2026

    Lineup currency (Sept 2026, verified): Sonnet 5 ($2/$10), Opus 5.5 ($4/$20), Haiku 4.5 ($1/$5), Fable 5.1 ($10/$50). Legacy (still listed): Opus 4.8 ($5/$25), Sonnet 4.6 ($3/$15). Prior note (superseded): Prior flagship claim: Claude Opus 4.8 (claude-opus-4-8). Prior models claim: Fable 5 · Opus 4.8 · Sonnet 5 · Haiku 4.5. Claude Opus 4.6 referenced in this article has been superseded. See current model tracker →

    Claude AI · Tygart Media · Updated April 2026
    Current status (April 16, 2026): The “Claude 5” generation has since shipped — as Claude Sonnet 5 (released June 30, 2026) plus the Claude Fable 5 / Mythos 5 tier above Opus (June 2026), rather than a single “Claude 5” model. The current lineup is Claude Fable 5 (top tier), Claude Opus 4.8 (legacy — still listed), Claude Sonnet 5, and Claude Haiku 4.5. Based on Anthropic’s release cadence and early signals, Claude 5 is expected Q2–Q3 2026.

    Every few months, a new wave of “Claude 5 release date” searches spikes — and it makes sense. Anthropic moves fast, the gaps between major generations have been shortening, and early signals like Vertex AI log leaks have given the community something to speculate on. Here’s an honest breakdown of what’s confirmed, what’s leaked, and what the pattern suggests.

    Claude 5 Expected Specs vs Current Models (June 2026)
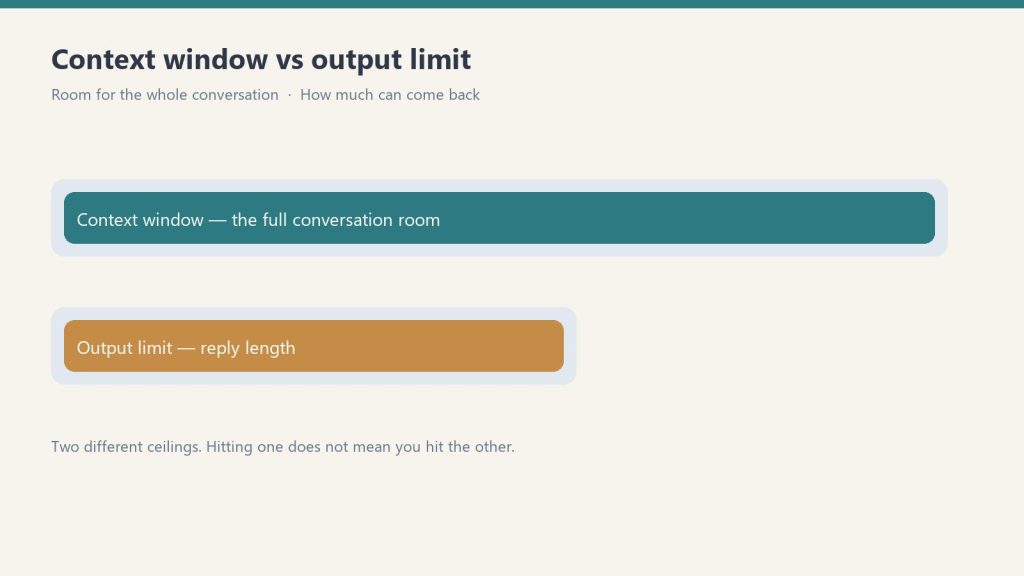
    Diagram comparing a long context window bar with a shorter output limit bar
    Claude 5 expected specs vs current models.
    AttributeClaude Opus 4.8 (Current)Claude 5 (Rumored)
    Release windowAvailable nowLate 2026 (unconfirmed)
    Context window1M tokens2M+ tokens (speculated)
    MultimodalText + visionText + vision + audio (rumored)
    Flagship API price$5 input / $25 output per MTokUnannounced
    ReasoningStrongImproved extended thinking (speculated)

    Claude 5 specs are unconfirmed as of June 9, 2026. All information is based on industry signals and Anthropic research publications — not official announcements.

    What’s Confirmed About Claude 5
    Three stacked layers: chat UI, tools, agent runtime
    What’s confirmed about Claude 5.

    As of April 2026, Anthropic has not officially announced Claude 5 by name in any public release notes, API documentation, or blog post. The company’s official model table shows the Claude 4.x family as current. No countdown page exists. No API model string beginning with claude-5 has appeared in public documentation.

    What is confirmed: Anthropic is actively deprecating the original Claude 4.0 models (retiring June 15, 2026), recommending migration to Claude Sonnet 4.6 and Opus 4.6. This is a routine generational housekeeping move, not a Claude 5 announcement.

    The Evidence For a Q2–Q3 2026 Release

    The strongest early signal came in early February 2026, when a model identifier — claude-sonnet-5@20260203 — appeared briefly in Google Vertex AI error logs. Independent sources cross-verified the leak, and the codename “Fennec” circulated alongside claimed benchmark scores of around 80.9% on SWE-bench Verified, compared to Opus 4.6’s current scores.

    Beyond the leak, the pattern is consistent: Anthropic has released a new major model generation roughly every 12–14 months since Claude 3. Claude 4.5 (the highest-capability 4.x model) reached 77.2% on SWE-bench Verified. A Claude 5 release that clearly exceeds that — not just marginally — would justify a major version bump and align with Anthropic’s stated commitment to releasing models that represent genuine capability leaps, not incremental updates.

    Anthropic’s Release Pattern

    Generation Initial Release Gap to Next Major
    Claude 2 July 2023 ~8 months
    Claude 3 March 2024 ~14 months
    Claude 4 May 2025 ~12–14 months → Q2–Q3 2026

    A 12-month gap from the Claude 4 launch (May 2025) points to May–July 2026 as the earliest likely window. Anthropic has been explicit that they won’t rush a release — Claude 5 would need to clearly establish a new capability tier to justify the version number.

    What Claude 5 Is Expected to Improve

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What Claude 5 is expected to improve.

    Based on leaked benchmark data and Anthropic’s public research direction, the Claude 5 generation is expected to push forward on: extended thinking and multi-step reasoning (building on the chain-of-thought work in Claude 3.5+), larger context handling, improved agentic reliability for long-horizon tasks, and faster inference at the Sonnet tier. Pricing is expected to follow the established pattern — Claude 5 Sonnet likely priced at or below current Opus 4.6 rates while outperforming it on most tasks.

    The Current Models Are Excellent — Don’t Wait

    If you’re evaluating whether to build on Claude now or wait for Claude 5, the answer is build now. Claude Sonnet 4.6 and Opus 4.6 are capable, stable, and well-documented. The 4.x API will remain live well after Claude 5 launches — Anthropic maintains parallel model availability for enterprise predictability. Waiting costs you months of production time for a model that may arrive on an uncertain schedule.

    For current model specs and API strings, see Claude API Model Strings — Complete Reference. For pricing on current models, see Claude AI Pricing: Every Plan Explained.

    When is Claude 5 coming out?

    Claude 5 has not been officially announced. Based on Anthropic’s release cadence and early Vertex AI log leaks, Q2–Q3 2026 (roughly May–September) is the most cited window. No confirmed date exists as of April 2026.

    Is Claude 5 confirmed?

    No. Anthropic has not officially announced Claude 5 by name. The “Fennec” codename and claude-sonnet-5@20260203 model string surfaced in third-party Vertex AI logs, but Anthropic has not confirmed a Claude 5 release.

    What is the latest Claude model right now (April 2026)?

    The current latest Claude models are Claude Fable 5 (claude-fable-5), the top tier above Opus, plus Claude Opus 4.8 (legacy — still listed) (claude-opus-4-8) and Claude Sonnet 4.6 (claude-sonnet-4-6), both released in February 2026. Claude Haiku 4.5 is the current speed/cost tier.

    Will Claude 5 Sonnet beat Claude Opus 4.6?

    That’s the expected pattern. With every prior generation, the mid-tier Sonnet model of the new generation outperformed the previous generation’s Opus on most benchmarks, at lower cost. Leaked benchmark data suggests Claude 5 Sonnet (“Fennec”) scores around 80.9% on SWE-bench Verified versus Opus 4.6’s current scores.

    When will Claude 5 be released?

    Anthropic has not officially announced a Claude 5 release date as of June 2026. Industry analysts and leak signals suggest a potential release in late 2026, but Anthropic typically announces model releases a few weeks before availability. The legacy (still listed) flagship is Claude Opus 4.8 (legacy — still listed) (claude-opus-4-8), released in 2026.

    What features will Claude 5 have?

    No official feature list exists for Claude 5. Based on Anthropic’s research publications and the pattern of Claude 4 improvements, Claude 5 is expected to improve reasoning, extended context handling, and multimodal capabilities. Any specific feature claims circulating online are speculation unless sourced directly from Anthropic.

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    What features will Claude 5 have?

    No official feature list exists for Claude 5. Based on Anthropic’s research publications and the pattern of Claude 4 improvements, Claude 5 is expected to improve reasoning, extended context handling, and multimodal capabilities. Any specific feature claims circulating online are speculation unless sourced directly from Anthropic.

    Should I wait for Claude 5 or use Claude Opus 4.8 (legacy — still listed) now?

    Use Claude Opus 4.8 (legacy — still listed) now. It is the current flagship with 1M token context, strong reasoning, and available today at $5/$25

    Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    per million tokens. Waiting for an unannounced model means missing months of productivity. When Claude 5 launches, upgrading is straightforward — just swap the model ID in your API calls.
  • Claude 4 Deprecation: Sonnet 4 and Opus 4 Retire June 15, 2026

    Claude 4 Deprecation: Sonnet 4 and Opus 4 Retire June 15, 2026

    Historical Record · Checked Nov 13, 2026

    This page describes the original Claude Sonnet 4 (claude-sonnet-4-20250514) and Claude Opus 4 (claude-opus-4-20250514), retired June 15, 2026 on Anthropic’s API. Current models: Current Claude Model Tracker · Current pricing: Current Claude Pricing.

    Historical deprecation note originally verified June 13, 2026; schedule cross-checked November 13, 2026 against platform.claude.com/docs/en/about-claude/model-deprecations.

    Model Accuracy Note — Schedule Cross-Checked Nov 13, 2026

    Retired June 15, 2026: the original Claude Opus 4 (claude-opus-4-20250514) and Claude Sonnet 4 (claude-sonnet-4-20250514) — the May 2025 models. (Subsequent updates: claude-opus-4-1-20250805 retired August 5, 2026; claude-sonnet-4-5-20250929 was deprecated September 30, 2026 with API retirement set for November 30, 2026.)

    Lineup currency (Nov 13, 2026): Current API lineup: Fable 5.2 ($8/$40), Opus 5.5 ($4/$20), Sonnet 5.5 ($2/$10), Haiku 5.5 ($0.10/$0.50 up to 100K tokens; $0.50/$2.50 over 100K). Legacy models include Fable 5.1, Opus 5, Sonnet 5, Opus 4.8, Sonnet 4.6, and Haiku 4.5. Current model tracker →

    Claude AI · Tygart Media
    ⚠ Deprecation Notice: Anthropic is retiring claude-sonnet-4-20250514 and claude-opus-4-20250514 — the original Claude 4.0 models from May 2025. API retirement is June 15, 2026. Anthropic’s current recommended replacements on platform.claude.com are Claude Sonnet 5.5 (claude-sonnet-5-5) for Sonnet 4 and Claude Opus 4.8 (claude-opus-4-8) for Opus 4 (originally Sonnet 4.6 / Opus 4.8 at the June 2026 cutoff).

    If you are still running the original Claude Sonnet 4 or Opus 4 model strings in production, you have a hard deadline: June 15, 2026. After that date, calls to claude-sonnet-4-20250514 and claude-opus-4-20250514 return an error — there is no automatic failover to a newer model. Here is exactly what is retiring, what to migrate to, and the breaking changes to plan for.

    Claude Model Lifecycle Status (June 2026)

    ModelAPI IDStatusReplacement
    Claude Opus 4 (original)claude-opus-4-20250514⚠ Retired June 15, 2026claude-opus-4-8
    Claude Sonnet 4 (original)claude-sonnet-4-20250514⚠ Retired June 15, 2026claude-sonnet-5-5
    Claude Opus 4.1claude-opus-4-1-20250805⚠ Retired August 5, 2026claude-opus-4-8
    Claude Sonnet 4.5claude-sonnet-4-5-20250929⚠ Deprecated Sep 30, 2026 (retires Nov 30, 2026)claude-sonnet-5-5
    Claude Fable 5.2claude-fable-5-2✓ Current flagship ($8/$40)—
    Claude Opus 5.5claude-opus-5-5✓ Current Opus ($4/$20)—
    Claude Sonnet 5.5claude-sonnet-5-5✓ Current Sonnet ($2/$10)—
    Claude Haiku 5.5claude-haiku-5-5✓ Current Haiku ($0.10/$0.50 ≤100K)—

    Alias trap: the dateless aliases claude-opus-4-0 and claude-sonnet-4-0 resolve to the retiring ...-20250514 snapshots — they go offline too. Claude Opus 4.6, Opus 4.7, and Opus 4.5 were unaffected by the June 15 retirement (while Claude Opus 4.1 subsequently retired August 5, 2026, and Claude Sonnet 4.5 was deprecated September 30, 2026 with retirement set for November 30, 2026).

    What’s Being Deprecated

    Diagram comparing a long context window bar with a shorter output limit bar
    What’s being deprecated.

    Anthropic is retiring the original Claude 4.0 model versions — the ones that shipped in May 2025. These are distinct from the 4.x versions released since. The specific API strings going offline:

    Model API String (retiring) Retirement Date
    Claude Sonnet 4 (original) claude-sonnet-4-20250514 June 15, 2026
    Claude Opus 4 (original) claude-opus-4-20250514 June 15, 2026

    These are not the latest Claude 4 models. If you have been on Anthropic’s recommended alias endpoints, you are likely already on a current model. This deprecation primarily affects teams that pinned the specific 20250514 version strings in their API calls.

    What to Migrate To

    Three stacked layers: chat UI, tools, agent runtime
    What to migrate to.

    Anthropic’s recommended replacement within the same tier:

    Retiring Migrate To API String
    claude-sonnet-4-20250514 Claude Sonnet 5.5 claude-sonnet-5-5
    claude-opus-4-20250514 Claude Opus 4.8 claude-opus-4-8

    These are major upgrades, not just version bumps. Both current models ship a 1 million token context window at standard API pricing (no long-context premium), and the Opus line has advanced two full generations — 4.6, then 4.7, then 4.8 — since the original 4.0. For the most capable tier overall, Anthropic now offers Claude Fable 5 (claude-fable-5), a new tier that sits above Opus.

    Breaking Changes When You Migrate

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Breaking changes when you migrate.

    Moving off the original 4.0 strings is usually a model-ID swap, but the current models removed several request parameters. If you are jumping to Opus 4.8 or Fable 5, plan for these — each returns a 400 if left in:

    Removed parameter Replacement
    thinking: {type:"enabled", budget_tokens:N} Adaptive thinking — thinking: {type:"adaptive"} + output_config.effort (low/medium/high/xhigh/max)
    temperature / top_p / top_k Removed — steer behavior with prompting instead
    Assistant-turn prefills (request ending on an assistant message) Structured outputs — output_config.format

    On Sonnet 4.6 and Opus 4.6 the fixed thinking budget is deprecated but still functional; on Fable 5, Opus 4.7, and Opus 4.8 it is fully removed. A global search for 20250514 in your codebase is the fastest way to find every call that needs changing.

    How This Fits the Claude Model Timeline

    Model Released Status
    Claude Sonnet 4 / Opus 4 (original) May 2025 ⚠ Retire June 15, 2026
    Claude Opus 4.1 August 2025 ⚠ Retired August 5, 2026
    Claude Sonnet 4.5 September 2025 ⚠ Deprecated Sep 30, 2026; retires Nov 30, 2026
    Claude Haiku 4.5 October 2025 Legacy — superseded by Haiku 5.5
    Claude Opus 4.6 / Sonnet 4.6 February 2026 Legacy — superseded by Opus 5.5 / Sonnet 5.5
    Claude Opus 5.5 / Sonnet 5.5 / Haiku 5.5 Sept–Oct 2026 ✅ Current lineup tiers
    Claude Fable 5.2 Nov 2026 ✅ Current top flagship tier

    What If You Don’t Migrate Before June 15?

    API calls to claude-sonnet-4-20250514 or claude-opus-4-20250514 after June 15, 2026 will return errors. There is no automatic failover to a newer model — the call simply fails. If you have any production systems, scheduled jobs, or automated pipelines using these version strings, audit them now. A global search for 20250514 in your codebase is the fastest way to find your exposure.

    What Comes After Claude 4.x

    The “after” is already here. Since the original Claude 4.0 launched in May 2025, the Opus line has shipped 4.5, 4.6, 4.7, and now 4.8, and Anthropic introduced Claude Fable 5 as a new top tier above Opus. As of June 2026 there is no separately branded “Claude 5” generation; the cadence has been steady point releases within the 4.x Opus, Sonnet, and Haiku families, plus the new Fable tier. The practical takeaway: migrating off the retiring 4.0 strings puts you on models that are materially more capable, with a 1M-token context window as the new baseline.

    Which Claude models retire on June 15, 2026?

    The original Claude Sonnet 4 (claude-sonnet-4-20250514) and Claude Opus 4 (claude-opus-4-20250514), plus their dateless aliases claude-sonnet-4-0 and claude-opus-4-0. Opus 4.6 and Opus 4.7 were not part of the June 15 cutoff (Opus 4.1 subsequently retired August 5, 2026, and Sonnet 4.5 was deprecated September 30, 2026 with retirement on November 30, 2026).

    What should I migrate to from Claude Sonnet 4 and Opus 4?

    Anthropic’s current deprecation schedule directs Sonnet 4 to claude-sonnet-5-5 (Claude Sonnet 5.5) and Opus 4 to claude-opus-4-8 (Claude Opus 4.8, or current Opus 5.5 / Fable 5.2). Current models ship a 1M token context window at standard pricing.

    Is migrating just a one-line model-string change?

    Often, but not always. The current models removed temperature, top_p, top_k, the fixed budget_tokens thinking budget, and assistant-turn prefills — each returns a 400 if left in. Replace budget_tokens with adaptive thinking plus output_config.effort, and replace prefills with structured outputs.

    What happens if I call the retired model after June 15?

    The API returns an error — there is no silent failover to a newer model. Audit for the string 20250514 in your codebase before the deadline.

  • AI Prompt Library for Service Businesses: 100 Prompts

    AI Prompt Library for Service Businesses: 100 Prompts

    100 prompts that actually work. Organized so you can find what you need in 30 seconds.

    Who This Is For

    Three stacked layers: chat UI, tools, agent runtime
    Who the AI prompt library is for.

    Built for service business owners and operators who are using AI occasionally but getting inconsistent results — sometimes great, sometimes useless — and want a reliable library of prompts that produce good output the first time.

    The Problem

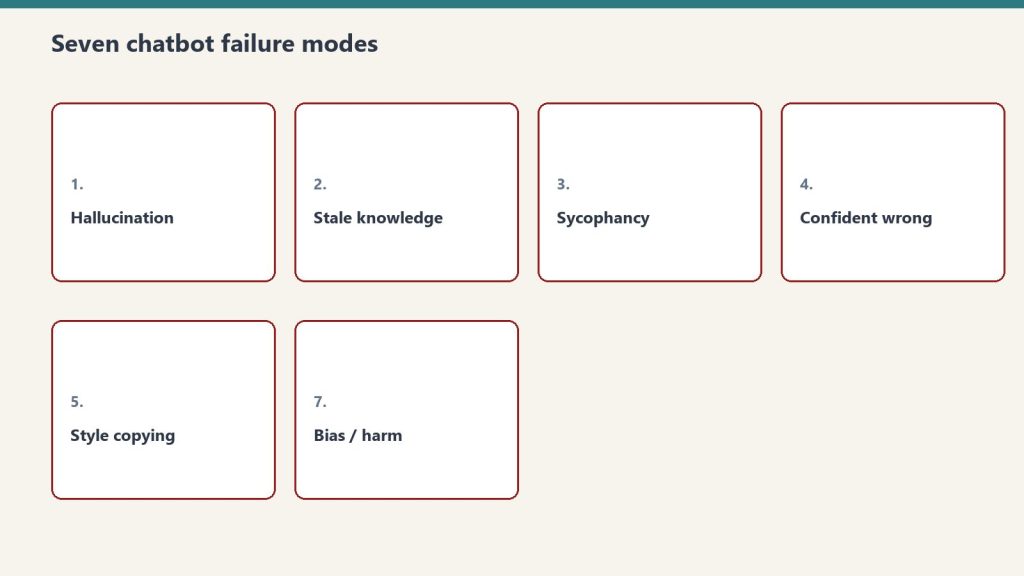
    Seven cards naming common AI chatbot failure modes
    The prompt library problem for service businesses.

    Prompting AI is a skill, and most people are learning it one bad output at a time. The difference between a prompt that produces something usable and one that produces generic filler is usually the framing — how you give context, what format you ask for, what constraints you set. This library is the shortcut. Every prompt has already been tested, refined, and confirmed to produce useful output for the situation it is built for.

    What You Get

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What you get with the prompt library.
    • 20 sales and business development prompts: proposals, follow-up sequences, objection handling scripts, cold outreach
    • 20 marketing and content prompts: blog post frameworks, social captions, email sequences, ad copy
    • 20 operations prompts: SOP drafting, meeting summaries, process documentation, hiring templates
    • 20 client communication prompts: onboarding emails, project update messages, difficult conversation scripts
    • 20 research and analysis prompts: competitor analysis, market research, summarization, decision frameworks
    • Delivered as a searchable Notion database plus a plain text file — use however you like

    AI Prompt Library — 100 Tested Prompts

    $27

    Delivered to your inbox within 24 hours — no shipping, no waiting

    Buy Now →

    Secure checkout via Square — all major cards accepted

    Related on Tygart Media: field operator kit · solo builder kit · weekly business review skill.

    Frequently Asked Questions

    How is this delivered?

    Within 24 hours of purchase via email from will@tygartmedia.com. You will receive a download link for the ZIP file and/or Notion duplicate link immediately.

    Do I need any special software?

    Works with any modern AI assistant including Claude, ChatGPT, and Gemini. A free Notion account is recommended for the database format.

    Can I customize this for my specific business?

    Yes — that is the point. Everything is built to be edited. Swap in your company name, add your specific workflows, remove anything that does not apply. It is a starting point, not a locked template.

    Is there a refund policy?

    Because this is a digital product, all sales are final. If you have a problem with your purchase, email will@tygartmedia.com and we will sort it out.

  • Claude AI Starter Pack for Creators: Prompts & Notion OS

    Claude AI Starter Pack for Creators: Prompts & Notion OS

    You make things for a living. Claude should make you faster — not generic.

    Who This Is For

    Three stacked layers: chat UI, tools, agent runtime
    Who the creator-independent Claude seed kit is for.

    Built for writers, podcasters, consultants, educators, course creators, and independent professionals who want AI that actually sounds like them.

    The Problem

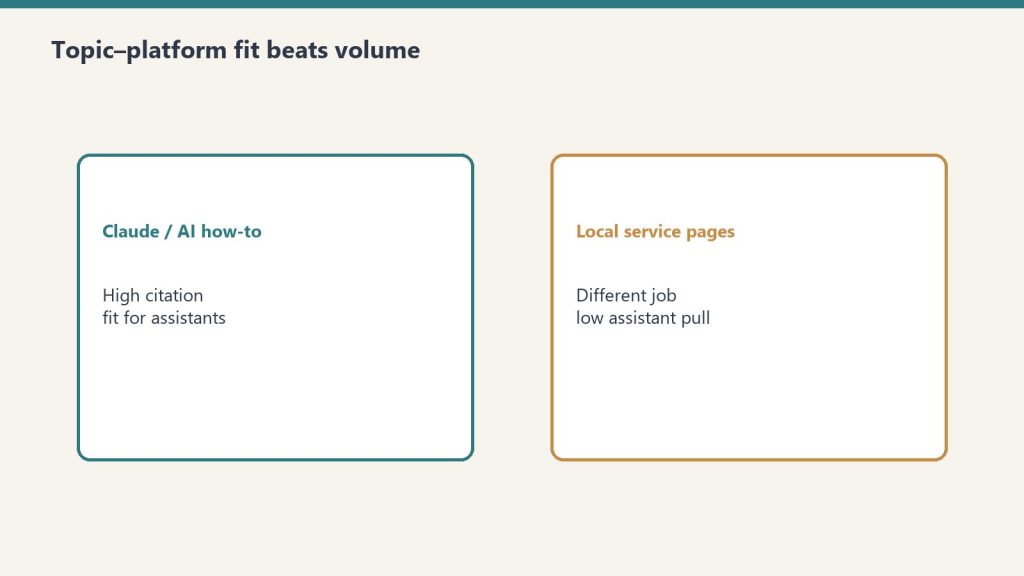
    Comparison of Claude how-to fit versus local service page fit for assistants
    The creator workflow bootstrap problem.

    The biggest complaint from creators who try AI is that everything sounds the same — flat, hedged, and obviously machine-made. That is a configuration problem, not an AI problem. Claude can write in your voice, research in your style, and produce output you would actually publish — but only if it is calibrated to how you think and what you have already made. This kit teaches Claude who you are.

    What You Get

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What you get with the creator seed kit.
    • Notion content OS: editorial calendar, project pipeline, client work, idea capture, and publishing workflow — all connected
    • 10 pre-built Claude skills tuned for creative work: voice-matched drafting, research synthesis, outline building, repurposing across formats, pitch writing, and audience research
    • 50 prompts for creators: long-form content, social posts, email sequences, course outlines, and client deliverables
    • Voice calibration guide: the exact process for training Claude on your writing style so output sounds like you wrote it
    • Quick-start guide: your first AI-assisted content session from blank page to published

    Creator & Independent Seed Kit

    $47

    Delivered to your inbox within 24 hours — no shipping, no waiting

    Buy Now →

    Secure checkout via Square — all major cards accepted

    Related on Tygart Media: solo builder kit · prompt library.

    Frequently Asked Questions

    How is this delivered?

    Within 24 hours of purchase via email from will@tygartmedia.com. You will receive a download link for the ZIP file and/or Notion duplicate link immediately.

    Do I need any special software?

    A free Notion account is required. No other software needed.

    Can I customize this for my specific business?

    Yes — that is the point. Everything is built to be edited. Swap in your company name, add your specific workflows, remove anything that does not apply. It is a starting point, not a locked template.

    Is there a refund policy?

    Because this is a digital product, all sales are final. If you have a problem with your purchase, email will@tygartmedia.com and we will sort it out.

  • Claude AI Starter Pack: Regulated Industry Seed Kit

    Claude AI Starter Pack: Regulated Industry Seed Kit

    Use AI without the compliance headaches.

    Who This Is For

    Three stacked layers: chat UI, tools, agent runtime
    Who the regulated-specialist Claude seed kit is for.

    Built for professionals in regulated fields — healthcare, legal, financial services, environmental services, construction — who want to use AI but need it to operate within real-world constraints.

    The Problem

    Diagram comparing a long context window bar with a shorter output limit bar
    The regulated-specialist bootstrap problem.

    Generic AI prompts are written for people who have no compliance obligations. They are not written for someone who needs to be careful about what goes in a client file, who cannot make specific legal or medical claims, and who works in an industry where documentation has real consequences. This kit is built around what regulated professionals can actually do with AI — and is honest about what they should not do.

    What You Get

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What you get with the regulated specialist kit.
    • Notion workspace template for regulated practice management: client files, compliance checklists, documentation logs, and renewal reminders
    • 10 pre-built Claude skills designed for compliance-aware use: documentation drafting, regulatory language lookup, client communication templates, audit preparation, and training content
    • 50 prompts that account for regulated context — written to get useful output without crossing professional lines
    • Compliance guardrail guide: what Claude can and cannot reliably do in your specific field
    • Quick-start guide: operational in under an hour

    Regulated Specialist Seed Kit

    $47

    Delivered to your inbox within 24 hours — no shipping, no waiting

    Buy Now →

    Secure checkout via Square — all major cards accepted

    Related on Tygart Media: field operator kit · local operator kit · prompt library for service businesses.

    Frequently Asked Questions

    How is this delivered?

    Within 24 hours of purchase via email from will@tygartmedia.com. You will receive a download link for the ZIP file and/or Notion duplicate link immediately.

    Do I need any special software?

    A free Notion account is required. No other software needed.

    Can I customize this for my specific business?

    Yes — that is the point. Everything is built to be edited. Swap in your company name, add your specific workflows, remove anything that does not apply. It is a starting point, not a locked template.

    Is there a refund policy?

    Because this is a digital product, all sales are final. If you have a problem with your purchase, email will@tygartmedia.com and we will sort it out.

  • Claude AI Starter Pack for Solo Founders & Freelancers

    Claude AI Starter Pack for Solo Founders & Freelancers

    You are building something. Claude should be your first hire.

    Who This Is For

    Three stacked layers: chat UI, tools, agent runtime
    Who the solo-builder Claude seed kit is for.

    Built for solo founders, freelancers, indie builders, and one-person businesses who want to move faster without adding headcount.

    The Problem

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    The solo builder bootstrap problem.

    Running a business alone means doing everything: sales, delivery, marketing, administration, client management. The bottleneck is always you. AI promises to change this — and it can — but only if it is configured for how you actually work. A solo freelancer’s needs are different from a corporation’s. This kit is built for the person who does everything themselves and needs AI that can step into any of those roles on demand.

    What You Get

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What you get with the solo builder kit.
    • Notion Second Brain for solo builders: projects, clients, content pipeline, finances, and personal productivity — all connected
    • 10 pre-built Claude skills: proposal drafting, client onboarding, content creation, research synthesis, invoicing language, and follow-up sequences
    • 50 prompts for solo operators: sales, delivery, marketing, and business development
    • Connector guide: wire Claude into your existing stack in one afternoon
    • Quick-start guide: your first productive session, every step mapped out

    Solo Builder Seed Kit

    $47

    Delivered to your inbox within 24 hours — no shipping, no waiting

    Buy Now →

    Secure checkout via Square — all major cards accepted

    Related on Tygart Media: field operator kit · creator seed kit.

    Frequently Asked Questions

    How is this delivered?

    Within 24 hours of purchase via email from will@tygartmedia.com. You will receive a download link for the ZIP file and/or Notion duplicate link immediately.

    Do I need any special software?

    A free Notion account is required. No other software needed.

    Can I customize this for my specific business?

    Yes — that is the point. Everything is built to be edited. Swap in your company name, add your specific workflows, remove anything that does not apply. It is a starting point, not a locked template.

    Is there a refund policy?

    Because this is a digital product, all sales are final. If you have a problem with your purchase, email will@tygartmedia.com and we will sort it out.

  • Claude AI Starter Pack: Local Business Operator Seed Kit

    Claude AI Starter Pack: Local Business Operator Seed Kit

    Run a local business. Use AI like the companies ten times your size do.

    Who This Is For

    Three stacked layers: chat UI, tools, agent runtime
    Who the local-operator Claude seed kit is for.

    Built for local business owners — retail, food and beverage, professional services, home services — who know AI could help but have not had time to figure out where to start.

    The Problem

    Seven cards naming common AI chatbot failure modes
    The local operator bootstrap problem.

    Enterprise companies have entire teams building their AI workflows. Local business owners have fifteen minutes between customers. The tools that work for a Fortune 500 company are not configured for someone who needs to respond to a Google review, draft a staff schedule, write a promotional email, and answer a supplier question before noon. This kit is built for the pace of a real local business.

    What You Get

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    What you get with the local operator kit.
    • Notion workspace for local business operations: appointments, inventory notes, staff, and marketing calendar
    • 10 pre-built Claude skills: local SEO content, customer response drafting, Google Business Profile posts, review responses, staff communication templates, and more
    • 50 prompts organized for the local business owner: marketing, customer service, operations, and hiring
    • Connector guide: Claude paired with Google Calendar, Gmail, and Metricool for social scheduling
    • Quick-start guide: productive in under an hour, no technical knowledge required

    Local Operator Seed Kit

    $47

    Delivered to your inbox within 24 hours — no shipping, no waiting

    Buy Now →

    Secure checkout via Square — all major cards accepted

    Related on Tygart Media: field operator seed kit · solo builder seed kit · regulated specialist kit.

    Frequently Asked Questions

    How is this delivered?

    Within 24 hours of purchase via email from will@tygartmedia.com. You will receive a download link for the ZIP file and/or Notion duplicate link immediately.

    Do I need any special software?

    A free Notion account is required. No other software needed.

    Can I customize this for my specific business?

    Yes — that is the point. Everything is built to be edited. Swap in your company name, add your specific workflows, remove anything that does not apply. It is a starting point, not a locked template.

    Is there a refund policy?

    Because this is a digital product, all sales are final. If you have a problem with your purchase, email will@tygartmedia.com and we will sort it out.

  • Claude AI Starter Pack for Contractors: Field Operator Kit

    Claude AI Starter Pack for Contractors: Field Operator Kit

    You bought Claude. This is what you do with it.

    Who This Is For

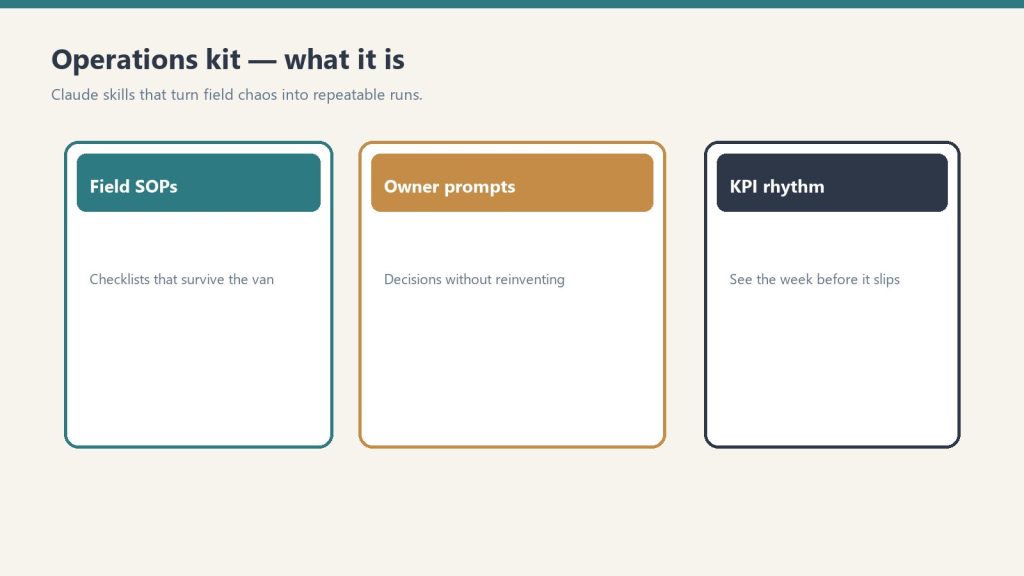
    Three cards for field SOPs, owner prompts, and KPI rhythm in an operations kit
    Who the field-operator Claude seed kit is for.

    Built for contractors, restoration companies, trade shops, and field service businesses who have a Claude subscription and have not figured out how to make it actually useful yet.

    The Problem

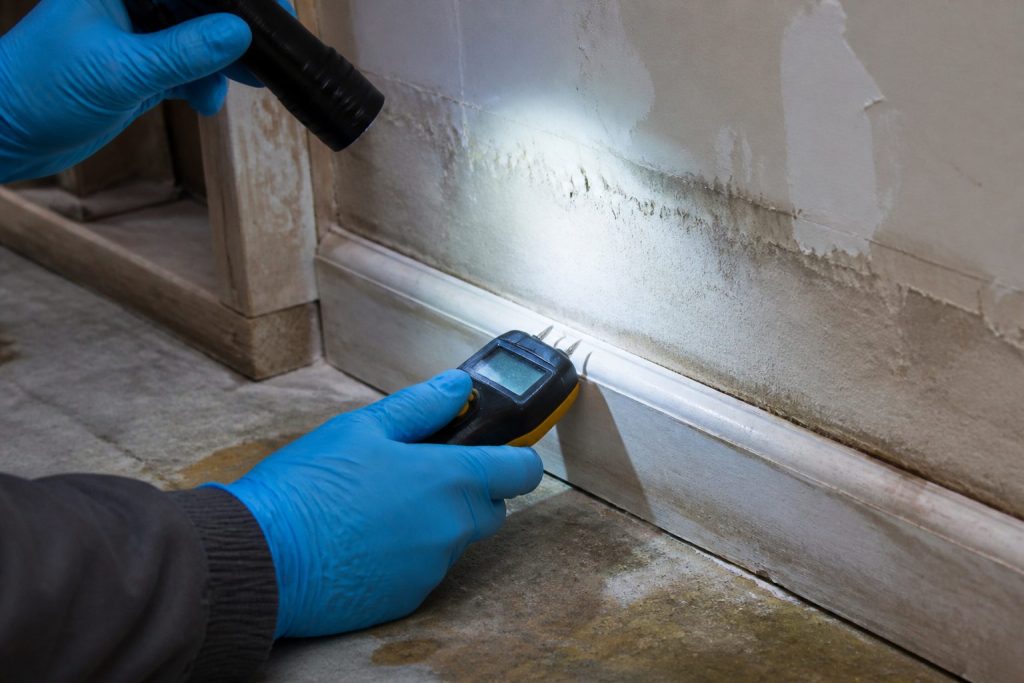
    Gloved hands using a pin-type moisture meter on wet drywall during inspection
    The field operator bootstrap problem.

    Claude is not plug-and-play for a field service business. It does not know your workflows, your documentation requirements, your adjuster communication patterns, or your crew scheduling rhythms. Most operators who buy it spend a few weeks prompting randomly, get mediocre results, and let it sit. The operators who get real value built their own infrastructure — prompts tuned to their workflows, templates that match their documents, Notion structured so Claude can actually read it. That infrastructure is what this kit delivers.

    What You Get

    Three panels showing one problem, three options, one recommendation
    What you get with the field operator kit.
    • Notion Second Brain template configured for field operations: jobs, crews, equipment, and clients — structured so Claude can read and act on it
    • 10 pre-built Claude skills for field operator workflows: job documentation, client communication, estimate drafting, crew scheduling, insurance correspondence, and more
    • 50 ready-to-use prompts organized by situation — open the doc, find the situation, copy the prompt
    • Connector checklist: how to wire Claude to WordPress, Google Calendar, Gmail, and your job management system
    • Quick-start guide: your first productive hour with Claude, every step mapped out

    Field Operator Seed Kit

    $47

    Delivered to your inbox within 24 hours — no shipping, no waiting

    Buy Now →

    Secure checkout via Square — all major cards accepted

    Related on Tygart Media: local operator seed kit · solo builder seed kit.

    Frequently Asked Questions

    How is this delivered?

    Within 24 hours of purchase via email from will@tygartmedia.com. You will receive a download link for the ZIP file and/or Notion duplicate link immediately.

    Do I need any special software?

    A free Notion account is required. No other software needed.

    Can I customize this for my specific business?

    Yes — that is the point. Everything is built to be edited. Swap in your company name, add your specific workflows, remove anything that does not apply. It is a starting point, not a locked template.

    Is there a refund policy?

    Because this is a digital product, all sales are final. If you have a problem with your purchase, email will@tygartmedia.com and we will sort it out.

  • Evaluate Restoration AI Tools: A Framework for Owners

    Evaluate Restoration AI Tools: A Framework for Owners

    This is the fifth and final article in the AI in Restoration Operations cluster under The Restoration Operator’s Playbook. It builds on the four previous articles in this cluster: why most projects fail, what to build first, the source code frame, and the economics of agent-assisted operations.

    Email Me This Article

    The buying environment in 2026 is genuinely difficult

    Seven cards naming common AI chatbot failure modes
    The buying environment in 2026 is genuinely difficult.

    A restoration owner trying to evaluate AI tools in 2026 is operating in one of the most adversarial buying environments any business owner has faced in a generation. Vendor sales motions have been refined over two years of selling AI capabilities to operators who do not have the technical background to evaluate the claims. Demos have been engineered to showcase the strongest moments of the tool’s capability under controlled conditions. Reference customers have been carefully selected and coached. Pricing structures have been designed to obscure the real long-term cost. Capability descriptions blend the model’s general competence with the vendor’s specific implementation in ways that make it hard to tell what the buyer is actually getting.

    None of this is unusual for an emerging technology category. All of it is expensive for the buyer who does not have a framework for cutting through it.

    This article is the framework. It is not a list of vendors to consider or avoid. Vendors change every quarter and any list would be out of date by the time it is read. The framework is designed to be durable across vendor cycles, so that an owner using it in 2027 or 2028 will still be making good decisions even as the specific products and providers shift.

    The first question: what work, exactly, is the tool doing?

    Three cards for field SOPs, owner prompts, and KPI rhythm in an operations kit
    The first question: what work, exactly, is the tool doing?

    The most useful first question to ask any AI vendor in restoration is also the question that most often does not get asked clearly. The question is: describe, in operational terms, the specific work this tool will do that a human is currently doing in my company.

    Vendors are usually prepared to answer this question in capability terms — the tool has natural language understanding, the tool integrates with our existing systems, the tool produces outputs in the formats we already use. None of those answers identifies the actual work being done. The follow-up has to be specific. Is the tool reading inbound communications and producing summaries that a senior operator would otherwise produce? Is it generating draft scopes that an estimator would otherwise write? Is it organizing photo files that a technician would otherwise organize? Is it drafting customer communications that a customer service lead would otherwise draft?

    If the vendor cannot answer this question in concrete operational terms, the deployment will fail. The vendor either does not understand the operational reality of the work the tool is supposed to support, or they do understand and are obscuring it because the operational impact is smaller than their marketing suggests. Either way, the answer is to keep evaluating other options.

    If the vendor can answer this question clearly, the next question is: show me an example of the tool doing that work on a file that resembles the kind of file my company actually handles, with operational detail similar to ours, not on a curated demo file. The willingness to do this is itself diagnostic. Vendors who can show this without retreating to the controlled demo are operating from a position of confidence in their tool. Vendors who cannot are signaling that the tool only performs reliably under conditions the buyer will not actually replicate.

    The second question: where is the captured judgment coming from?

    The second high-leverage question is about the source of the operational judgment the tool will be applying. As established in the source code piece, AI tools render the patterns they have been given access to. The buyer needs to know what those patterns are.

    The right question is: where does the operational judgment in this tool’s outputs come from? Is it the model’s general training? Is it your company’s internal patterns from working with other restoration customers? Is it patterns from my own company’s documentation that I would provide as part of the deployment? Is it some combination?

    Vendors offering tools whose operational judgment comes primarily from the model’s general training are offering generic AI with a restoration interface. The outputs will be plausible and superficially competent, but they will not reflect the operational specificity that makes outputs actually useful. These tools fail in the way described in the failure piece: the senior operators see the outputs, recognize them as wrong, and stop trusting the tool.

    Vendors offering tools that draw on patterns from other restoration customers are offering something more specific, but with a complication the buyer needs to understand. Those patterns reflect the operational standards of the other customers, which may or may not match the buyer’s standards. If the buyer’s company has a deliberate operational discipline that differs from the industry average, the tool’s outputs will pull toward the industry average rather than reflecting the buyer’s specific standards. This is sometimes acceptable and sometimes a serious problem, depending on whether the buyer wants their tool to reinforce their differentiation or dilute it.

    Vendors offering tools that explicitly draw on the buyer’s own documentation, standards, and captured judgment are offering the only configuration that produces reliably useful outputs at the operational level. These are also the deployments that require the most upfront work from the buyer, because the captured judgment has to actually exist before the tool can use it. There is no shortcut. If the buyer has not done the documentation work, no vendor can fix that.

    The third question: what does the success metric look like?

    The third question is about how the deployment will be evaluated, which determines whether the company will know whether the tool is working.

    The right question is: what specific operational metric will tell us whether this tool is creating value, and how will that metric be measured?

    Vendors who answer this question with usage metrics — engagement, login frequency, feature adoption — are offering something that is easy to measure and irrelevant to whether the tool is actually working. Usage metrics measure whether people are interacting with the tool. They do not measure whether the interaction is producing operational value.

    Vendors who answer this question with operational metrics — senior operator hours saved per week, files processed per estimator per week, scope accuracy improvement, documentation quality scores — are offering something that is harder to measure and meaningful. The buyer’s job is to make sure the operational metric is concrete, measurable, and tied to a number that already exists in the business. A claimed metric that requires inventing new measurement infrastructure to track is a metric that will not actually be tracked, which means it will not actually be measured, which means the deployment cannot actually be evaluated.

    The answer the buyer is looking for is something like: before the deployment, your senior estimators handle thirty files per week each. After the deployment, with the tool’s review acceleration, the same estimators should handle sixty to seventy files per week with comparable accuracy. We will measure files-per-estimator-per-week starting baseline at deployment and tracking weekly through the first six months. This is a defensible commitment. Vendors who will not make this kind of commitment do not believe their own claims.

    The fourth question: what happens when the tool is wrong?

    Three panels showing one problem, three options, one recommendation
    The fourth question: what happens when the tool is wrong?

    The fourth question is about the tool’s behavior under failure. AI tools are wrong sometimes. The question is what happens when they are.

    The right question is: walk me through what happens when this tool produces an incorrect output. How does the user discover the error? How does the system learn from the error? How does the company avoid acting on the error?

    Vendors who have not designed for failure will answer this question vaguely. The tool is very accurate, the model is constantly improving, the outputs are reviewed by users before being used. None of these answers describes a failure-handling architecture. They describe a hope that failures will be rare.

    Vendors who have designed for failure will describe a specific architecture. The tool flags its own confidence level on outputs. The user has a defined workflow for marking an output as incorrect. The marked errors flow into a feedback queue that is reviewed and acted on. The tool’s behavior changes in response to the corrections. The architecture is concrete enough that the buyer can imagine the workflow operating in their company.

    This question is one of the highest-signal questions in any AI vendor evaluation. Vendors who have built serious tools have thought hard about failure handling, because the failure handling is what determines whether the tool maintains credibility with users over time. Vendors who have not thought about failure handling are offering tools that will lose user trust within the first three months of deployment.

    The fifth question: what are the long-term costs?

    The fifth question is about the real economics of the deployment, which is rarely what the initial pricing conversation suggests.

    The right question is: walk me through the total cost of running this tool in my company at full deployment scale, twenty-four months from now, including model usage, runtime, integration maintenance, internal personnel time for review and configuration, and any growth in vendor pricing.

    Vendors who price AI tools as fixed monthly subscriptions are absorbing the variable cost of model usage and runtime into their margin. This works for them as long as average usage stays below their pricing assumption. As the buyer’s deployment matures and usage grows, the vendor either absorbs the loss, raises prices significantly, or imposes usage caps that constrain the buyer’s ability to scale the capability. The buyer needs to understand which of these will happen and plan for it.

    Vendors who price AI tools as usage-based often present a low headline cost based on initial usage assumptions. As the deployment matures and usage grows, the cost grows proportionally. The headline number is misleading. The buyer needs to model usage at full deployment scale, not initial scale.

    Vendors who are honest about the cost structure will walk through both the model and runtime costs and the personnel cost of maintaining the deployment internally. The personnel cost is the largest component for any meaningful AI deployment, as discussed in the economics piece, and it is the cost most often left out of vendor pricing discussions because it does not flow through the vendor’s invoice. The buyer who does not account for it has not understood the real cost.

    The sixth question: what is the exit?

    The sixth question is about what happens if the relationship does not work out.

    The right question is: if I decide in eighteen months that I want to stop using this tool, what do I take with me, what do I leave behind, and how disruptive is the transition?

    Vendors who have built tools designed for buyer power will describe an exit that allows the buyer to keep their captured operational standards, their training data, and their workflow configurations in transferable form. The buyer can move to a different runtime if they need to.

    Vendors who have built tools designed for vendor power will describe an exit that leaves the buyer with very little. The captured operational substrate is locked into the vendor’s proprietary format. The configuration work cannot be replicated elsewhere. The buyer has to start over if they leave.

    The question is diagnostic regardless of whether the buyer ever actually exits. A vendor who has designed a tool the buyer can leave is a vendor who is confident enough in the tool’s value to compete on quality rather than lock-in. A vendor who has designed lock-in into the architecture is a vendor who is preparing to extract more value from the relationship than they would otherwise be able to. The buyer should know which kind of vendor they are dealing with before signing.

    What the framework excludes

    This framework intentionally does not include several questions that are commonly asked in AI vendor evaluations and that are usually less informative than they seem.

    It does not include questions about the underlying model. Which AI model the vendor is using matters less than how they are deploying it. The same model can be configured to produce excellent outputs or terrible outputs depending on the deployment architecture. Asking which model is the foundation tells the buyer almost nothing about what they are buying.

    It does not include questions about technical certifications, security badges, or compliance frameworks. These matter for procurement, but they do not predict whether the tool will produce operational value. Many tools with extensive security documentation are operationally useless. Many tools that produce real operational value have less impressive security documentation. The two dimensions need to be evaluated independently.

    It does not include questions about the vendor’s funding, growth rate, or customer count. These matter for vendor risk assessment but do not predict tool quality. Some of the best operational AI tools in restoration come from small focused vendors. Some of the worst come from well-funded category leaders. The buyer should care about whether the tool works, not whether the vendor will exist in five years — the latter being a question that is difficult to answer reliably regardless of how it is researched.

    The cluster ends here, and what to do with it

    The five articles in this cluster describe a complete mental model for thinking about AI in restoration operations in 2026. The model has six components. Most projects fail for predictable reasons. The right place to start is the operational middle layer, with documentation acceleration. The senior operator is the source code, and protecting that operator is the central strategic question. The economics of agent-assisted operations are the underdiscussed factor that will determine who is profitable in 2028. The buyer’s framework above is the practical instrument for cutting through vendor noise.

    Owners who internalize this model will make consistently better decisions about AI than owners who chase vendor cycles, follow industry trends, or try to evaluate each tool on its own marketing. The model is the asset. The specific tools the model leads to are interchangeable.

    The cluster on AI in Restoration Operations is closed. The next clusters in The Restoration Operator’s Playbook go deep on senior talent, on financial operations discipline, on carrier and TPA strategy, on crew and subcontractor systems, and on end-in-mind decision frameworks. Each cluster compounds with the others. The full body of work gives restoration operators a durable mental architecture for navigating an industry that is changing faster than at any time in its history.

    Operators who read it and act on it will know what to do. Operators who do not will find out later what their competitors knew earlier.

  • Restoration Talent: The AI Bottleneck You Must Fix Now

    Restoration Talent: The AI Bottleneck You Must Fix Now

    Last refreshed: October 22, 2026

    A LinkedIn post from a restoration recruiter in Houston tipped me off this morning. He’s right — but the timeline is shorter than most people in the industry realize.

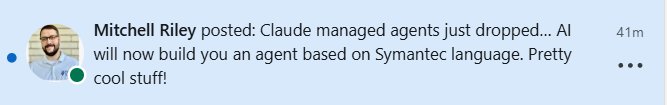
    Mitchell Riley LinkedIn post about Claude Managed Agents announcement
    Mitchell Riley’s LinkedIn post that started this train of thought.

    This article is part of The Restoration Operator’s Playbook — Tygart Media’s body of work on how the industry’s best restoration companies are actually thinking in 2026. Start with the pillar piece if this is your first read.

    Email Me This Article

    The post that got me thinking

    This morning I logged into LinkedIn and saw a post from Mitchell Riley — a restoration industry recruiter in Houston who places PMs, GMs, and business development leaders for restoration contractors across the country. Mitchell flagged Anthropic’s Claude Managed Agents launch with the kind of casual enthusiasm only people who actually use this stuff every day can manage. He called it “pretty cool” and noted that Claude will now build you an agent based on natural language.

    He’s right. He’s also pointing at something most of the restoration industry hasn’t fully processed yet.

    What Anthropic actually shipped

    On April 8, 2026, Anthropic launched Claude Managed Agents in public beta. The short version: the infrastructure work that used to take three to six months of engineering — sandboxed code execution, credential management, long-running session persistence, error recovery, observability — is now a managed service. You define what the agent should do. Anthropic runs it.

    The companies already shipping production agents on it: Notion, Asana, Rakuten, and Sentry. Notion lets teams delegate coding, slides, and spreadsheets to Claude without leaving the workspace. Rakuten deployed specialist agents across product, sales, marketing, finance, and HR — each live in under a week. Sentry built an agent that goes from flagged bug to open pull request, fully autonomous.

    Internal Anthropic testing showed up to a 10-point improvement in task success on structured generation work versus a standard prompting loop, with the largest gains on the hardest problems.

    That’s the announcement. Here’s why it matters for restoration.

    The bottleneck just moved

    For the last two years, the question every restoration owner asked about AI was some version of: “Can it actually do the work?” The honest answer was usually “not yet, not without a developer team you don’t have.”

    That’s no longer the question. The infrastructure gap closed on April 8. The new bottleneck is not “can you build the agent” — it’s “do you have the human operators who know what the agent should be doing in the first place.”

    Restoration is an industry where the real intelligence lives in people. A senior PM who has worked five hundred losses knows things that have never been written down anywhere. How a Cat 3 storm response actually sequences when the carrier is dragging on TPA approvals. The difference between a contents pack-out that closes clean and one that becomes a six-month dispute. Which mitigation decisions buy you a profitable job and which ones bury you on the reconstruction side. None of that lives in a textbook. It lives in the heads of people who have been doing the work for fifteen or twenty years.

    That tribal knowledge is now the constraint. The companies that win the next three years will be the ones who pair Managed Agents (or something like it) with senior operators who can tell the agent what good looks like. The companies that try to skip that step — that try to hire generalists and teach them restoration on the fly while their competitors are distilling twenty-year veterans into operational systems — are going to get lapped.

    Buy the talent now

    This is where the recruiting angle gets interesting. Senior restoration talent has always been hard to find. It’s about to get much harder, for a reason most owners haven’t priced in yet: the value of a senior PM is no longer just the work that PM does directly. It’s the work an entire AI system does in their image once their judgment has been encoded into the workflow.

    Right now, that arbitrage is open. The market hasn’t repriced senior operators for what they’re actually worth in an AI-augmented restoration company. In twelve to twenty-four months, it will. The owners who hire the best PMs, GMs, and BD leaders now — and who pair them with someone like Mitchell who actually understands the placement game — are going to look like geniuses in 2027.

    Mitchell is one of the people who gets this from the inside. He uses the AI tools himself. He builds workflows. He analyzes things in dimensions and context that most recruiters never touch — most recruiters in this industry are still working from a spreadsheet of resumes and a cell phone. Mitchell is the kind of recruiter who notices when Anthropic ships something that’s going to change the value of every senior hire he places, and posts about it on a Wednesday morning. That’s the level of operator the smart restoration owners are going to want in their corner.

    What to actually do this quarter

    If you run a restoration company and you read this far, three concrete things:

    One. Identify your two or three most senior operators — the people whose judgment is load-bearing for the business. Start documenting how they think, not just what they do. The documentation is the raw material every future AI workflow will run on.

    Two. Open one or two senior hires you’ve been putting off. The talent market is going to tighten. Get in front of it.

    Three. Stop treating AI as an IT project. It’s an operational capability. The companies that figure this out are not waiting for their tech vendor to sell them an “AI feature.” They’re hiring the operators, capturing the judgment, and pointing the tooling at the result.

    Mitchell’s post was three sentences. The full version of what he was pointing at takes about a thousand words. This is that version.

    If you’re a restoration owner thinking about senior placements in the next two quarters, you should be talking to Mitchell. And if you’re thinking about how to operationalize AI inside your company — distilling senior judgment into systems your whole team can run — that’s the conversation we have at Tygart Media.

    Read next: The New Restoration Operator: How the Industry’s Best Companies Are Thinking in 2026 — the pillar piece this article belongs to.