Two AI assistants dominate the conversation right now: Claude and ChatGPT. If you’re trying to decide which one belongs in your workflow, you’ve probably already noticed that most “comparisons” online are surface-level takes written by people who spent an afternoon with each tool.
This isn’t that. I run an AI-native agency that uses both tools daily across content, code, SEO, and client strategy. Here’s what actually separates them in 2026 — and when each one wins.
Quick answer (September 2026): Claude is better for long-context analysis, writing quality, and following complex instructions without drift. ChatGPT is better for integrations, image generation, and breadth of third-party plugins. For most knowledge workers, Claude is the daily driver — ChatGPT is the specialist.
The Fast Verdict: Category by Category
The fast verdict — category by category.
Category
Claude
ChatGPT
Notes
Writing quality
✅ Wins
—
Less sycophantic, more natural voice
Following complex instructions
✅ Wins
—
Holds multi-part instructions without drift
Long document analysis
✅ Wins
—
200K token context vs GPT-4o’s 128K
Coding
✅ Slight edge
—
Claude Code is a dedicated agentic coding tool
Image generation
—
✅ Wins
DALL-E 3 built in; Claude has no native image gen
Third-party integrations
—
✅ Wins
GPT’s plugin/Custom GPT ecosystem is larger
Web search
—
✅ Slight edge
Both have web search; GPT’s is more integrated
Pricing (base)
Tie
Tie
Both $20/mo for Pro/Plus; API costs comparable
Not sure which to use?
We’ll help you pick the right stack — and set it up.
Tygart Media evaluates your workflow and configures the right AI tools for your team. No guesswork, no wasted subscriptions.
The difference becomes obvious when you give both models the same writing task and read the outputs side by side. ChatGPT has a tendency to over-affirm, over-structure, and reach for generic phrasing. Ask it to write a LinkedIn post and you’ll often get something that reads like a LinkedIn post — in the worst way.
Claude’s outputs read closer to how a thoughtful human actually writes. Sentences vary. Paragraphs breathe. It doesn’t reflexively add a bullet list to every response or pepper the text with unnecessary bold text. It also pushes back more readily when an instruction doesn’t quite make sense, rather than producing confident-sounding nonsense.
For any work that ends up in front of clients, readers, or stakeholders, Claude’s writing quality is a meaningful advantage. This holds for long-form articles, email drafts, executive summaries, and proposal copy.
Context Window: The Practical Difference
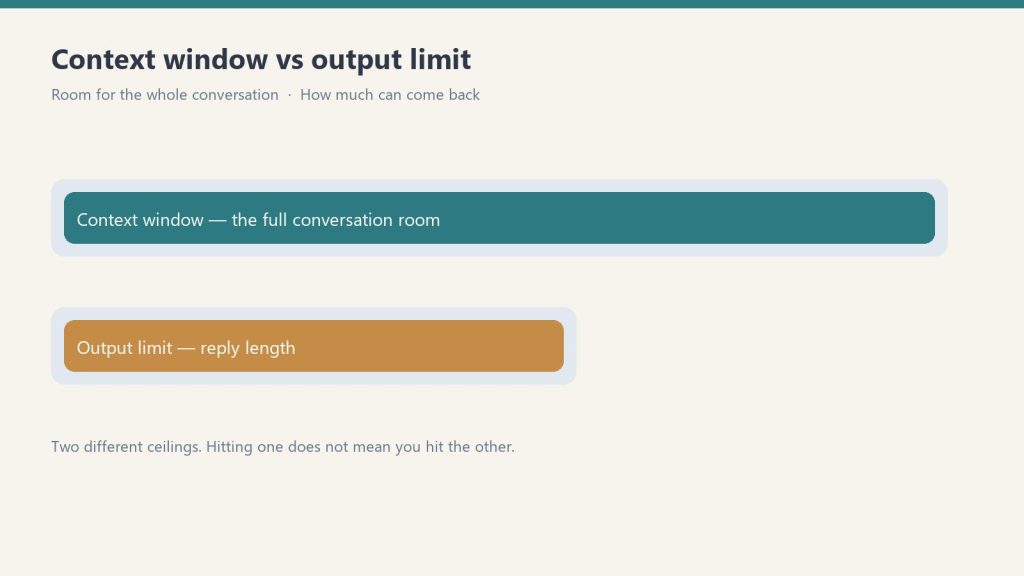
Claude’s context window — the amount of text it can hold and reason over in a single conversation — is substantially larger than ChatGPT’s standard offering. Claude Sonnet 5 and Opus 5.5 both support up to 200,000 tokens. GPT-4o tops out at 128,000 tokens.
In practice, this matters for:
Analyzing long contracts, reports, or research documents in one pass
Working with large codebases without losing track of what’s already been discussed
Multi-document analysis where you need to synthesize across sources
Long agentic sessions where conversation history is critical
If you regularly work with documents over 50–80 pages or run long agentic workflows, Claude’s context advantage is a functional one, not just a spec sheet number.
Instruction Following: Where Claude Consistently Outperforms
Give Claude a complex, multi-part instruction with specific constraints — “write this in third person, under 400 words, no bullet points, mention X and Y but not Z, match this tone” — and it tends to hold all of those requirements across the full response. ChatGPT frequently drifts, especially on longer outputs.
This matters most for:
Prompt-heavy workflows where precision is required
Batch content generation with strict brand voice rules
Agentic tasks where Claude is executing multi-step operations
Any scenario where you’ve spent time engineering a precise prompt
Anthropic built Claude with a focus on being genuinely helpful without being sycophantic — meaning it’s designed to give you the accurate answer, not the agreeable one. In practice, Claude is more likely to flag when something in your request is unclear or contradictory rather than guessing and producing something confidently wrong.
Coding: Claude Code vs ChatGPT
For general coding questions — syntax, debugging, explaining code — both models perform well. The meaningful differentiation is at the agentic level.
Anthropic’s Claude Code is a dedicated command-line coding agent that can work autonomously on a codebase: reading files, writing code, running tests, and iterating. It’s a different category of tool than ChatGPT’s code interpreter, which executes code in a sandboxed environment but doesn’t have the same level of agentic control over a real development environment.
For developers running AI-assisted workflows on actual projects, Claude Code is the more serious tool in 2026. For casual code help or one-off scripts, the gap is smaller.
Where ChatGPT Wins: Image Generation and Ecosystem
ChatGPT has a clear advantage in two areas that matter to a lot of users.
Image generation: DALL-E 3 is built directly into ChatGPT Plus. You can go from text to image in one conversation. Claude has no native image generation capability — you’d need to use a separate tool like Midjourney, Adobe Firefly, or Imagen on Google Cloud.
Third-party integrations: OpenAI’s plugin ecosystem and Custom GPTs have more breadth than Claude’s integrations. If you rely on specific third-party tools (Zapier, specific APIs, custom workflows), there’s more infrastructure already built around ChatGPT.
If image creation is a daily part of your workflow, or you’re heavily invested in a ChatGPT-centric tool stack, these advantages are real.
Claude vs ChatGPT for Coding Specifically
When coding is the primary use case, the comparison shifts toward Claude — but it’s worth being precise about why.
For writing clean, well-commented code from scratch, Claude tends to produce cleaner output with better reasoning explanations. It’s less likely to hallucinate function signatures or library methods. For debugging, Claude’s ability to hold large code files in context without losing track is a functional advantage.
ChatGPT’s code interpreter (now called Advanced Data Analysis) is strong for data science workflows — running actual Python in a sandbox, generating visualizations, processing files. If your coding work is primarily data analysis and you want execution in the same tool, ChatGPT has the edge there.
Claude vs ChatGPT for Writing Specifically
For any writing that requires a genuine human voice — op-eds, thought leadership, nuanced argument — Claude is the better instrument. Its outputs require less editing to remove the robotic, list-heavy, over-hedged quality that plagues a lot of AI-generated content.
For template-heavy writing — product descriptions, SEO-optimized articles at scale, standardized reports — the gap is smaller and comes down to your specific prompting setup.
What Reddit Actually Says
The Claude vs ChatGPT debate on Reddit (r/ChatGPT, r/ClaudeAI, r/artificial) consistently surfaces a few recurring themes:
Writers and researchers prefer Claude — repeatedly cited for better prose and genuine analysis
Developers are more split — Claude Code has built a dedicated following, but the ChatGPT ecosystem is more familiar
ChatGPT wins on integrations — the plugin/Custom GPT ecosystem still has more breadth
Claude is less annoying — specific complaints about ChatGPT’s sycophancy appear frequently (“it agrees with everything”, “it always says ‘great question’”)
Both have gotten better fast — direct comparisons from 2023–2024 often don’t hold in 2026
Pricing: What You Actually Pay
The base subscription pricing is identical: $20/month for Claude Pro and $20/month for ChatGPT Plus — see the full Claude pricing breakdown for everything beyond the base tier. If you’re wondering what the free tier actually includes before committing, see what Claude’s free tier gets you in 2026. Both include web search, file uploads, and access to advanced models.
Where it diverges:
Claude Max ($100/mo) — for power users who need 5x the usage of Pro
ChatGPT doesn’t have a direct equivalent tier between Plus and Enterprise
API pricing — comparable but varies by model; Anthropic’s pricing is token-based and published transparently
Claude Code — has its own pricing structure for the agentic coding tool
For most individual users, the $20/mo tier is the right starting point for either tool.
Which One Is Actually Better in 2026?
Which one is actually better in 2026?
The honest answer: Claude is better for the work that benefits most from language quality, reasoning depth, and instruction precision. ChatGPT is better for the work that benefits from breadth of integrations and built-in image generation.
For a solo operator, consultant, or knowledge worker whose primary outputs are written analysis, content, and strategy: Claude is the better daily driver. The writing is cleaner, the reasoning is more reliable, and the context window is more practical for serious document work.
For a team already embedded in the OpenAI ecosystem — with Custom GPTs, plugins, and Zapier workflows built around ChatGPT — switching has real friction that may not be worth it unless writing quality is a high-priority problem.
The most pragmatic setup for serious users — check the Claude model comparison to understand which tier makes sense for your work, and the Claude prompt library to get the most out of whichever you choose. The most pragmatic setup for serious users: Claude for thinking and writing, access to ChatGPT for when you need DALL-E or a specific integration it covers. At $20/month each, running both is a reasonable choice if the work justifies it.
Frequently Asked Questions
Is Claude better than ChatGPT?
For writing quality, complex instruction following, and long-document analysis, Claude outperforms ChatGPT in most head-to-head tests. ChatGPT has the advantage in image generation and third-party integrations. The right answer depends on your primary use case.
Can I use both Claude and ChatGPT?
Yes, and many power users do. Both have $20/month Pro tiers. Running both gives you Claude’s writing and reasoning strength alongside ChatGPT’s DALL-E image generation and broader plugin ecosystem.
Which is better for coding — Claude or ChatGPT?
Claude has a slight edge for writing clean code and agentic coding workflows via Claude Code. ChatGPT’s Advanced Data Analysis (code interpreter) is better for data science work where you need code execution in a sandboxed environment. For general coding help, both are strong.
Which AI is better for writing?
Claude consistently produces better writing — less generic, less sycophantic, and closer to a natural human voice. Writers, editors, and content strategists repeatedly report that Claude’s outputs require less editing and drift less from the intended tone.
Is Claude free to use?
Claude has a free tier with limited daily usage. Claude Pro is $20/month and provides significantly more capacity. Claude Max at $100/month is for heavy users. API access is billed separately by token usage.
These terms get used interchangeably. They’re not the same thing. Here’s the actual distinction between each one, where the lines get genuinely blurry, and which category fits what you’re actually trying to build.
Chatbots
A chatbot is a software interface designed to simulate conversation. The defining characteristic: it’s stateless and reactive. You send a message; it responds; the exchange is complete. Each interaction is largely independent.
Traditional chatbots (pre-LLM) operated on decision trees — “if the user says X, respond with Y.” Modern LLM-powered chatbots use language models to generate responses, which makes them dramatically more capable and flexible — but the fundamental architecture is the same: you ask, it answers, you ask again.
What chatbots are good at: answering questions, providing information, routing conversations, handling defined service scenarios with natural language flexibility. What they’re not: action-takers. A chatbot can tell you how to cancel your subscription. An agent can cancel it.
Automations
Automations are rule-based workflows that execute when triggered. Zapier, Make, and similar tools are the canonical examples. When event A happens, do B, then C, then D.
The key characteristic: the path is predefined. Every step is specified by the person who built the automation. If an unexpected situation arises that the automation wasn’t built for, it either fails or skips the step. There’s no reasoning about what to do — there’s only executing the specified path or not.
Automations are highly reliable for well-defined, stable processes. They break when edge cases arise that weren’t anticipated. They scale perfectly for the exact task they were built for; they don’t generalize.
APIs
An API (Application Programming Interface) is a communication contract — a defined way for software systems to talk to each other. APIs are infrastructure, not agents or automations. They’re the mechanism through which agents and automations take action in external systems.
When an AI agent “uses Slack,” it’s calling Slack’s API. When an automation “posts to Twitter,” it’s calling Twitter’s API. The API is the door; agents and automations are the things that open it.
Conflating APIs with agents is a category error. An API is a tool, not a behavior pattern.
AI Agents
An AI agent takes a goal and figures out how to accomplish it, using tools available to it, handling unexpected situations along the way, without a human specifying each step.
The distinguishing characteristics versus the above:
vs. Chatbots: Agents take action in the world; chatbots respond to messages. An agent can book the flight, not just tell you how to book it.
vs. Automations: Agents reason about what to do next; automations execute predefined paths. When an unexpected situation arises, an agent adapts; an automation fails or skips.
vs. APIs: APIs are tools an agent uses; they’re not the agent itself. The agent is the reasoning layer that decides which API to call and what to do with the result.
Where the Lines Actually Blur
In practice, real systems often combine these categories:
LLM-powered chatbots with tool access: A customer service chatbot that can look up your order status, initiate a return, and send a confirmation email is starting to look like an agent — it’s taking actions, not just responding. The boundary between “advanced chatbot” and “limited agent” is genuinely fuzzy.
Automations with AI decision steps: A Zapier workflow with an OpenAI or Claude step in the middle isn’t purely rule-based anymore — the AI step can produce variable outputs that affect what the automation does next. This is a hybrid: mostly automation, partly agentic.
Agents with constrained scopes: An agent restricted to a single tool and a narrow task class starts to look like a sophisticated automation. The more constrained the scope, the more the distinction collapses in practice.
The useful question isn’t “what category is this?” but “is this system reasoning about what to do, or executing a predefined path?” That’s the actual distinction that matters for how you build, monitor, and trust it.
Why the Distinction Matters Operationally
Reliability profile: Automations fail predictably — when an edge case hits a path that wasn’t built. Agents fail unpredictably — when their reasoning goes wrong in a way you didn’t anticipate. Different failure modes require different monitoring approaches.
Maintenance overhead: Automations require explicit updates when processes change. Agents adapt to process changes automatically — but may adapt in unexpected ways that need to be caught and corrected.
Auditability: Automations are fully auditable — you can read the workflow and know exactly what it does. Agents are less auditable — you can inspect their actions, but not fully predict them in advance. For compliance-sensitive contexts, this matters significantly.
Build cost: Automations are faster to build for well-defined, stable processes. Agents are faster to deploy when the process is complex, variable, or not fully specified — because you’re specifying a goal rather than a procedure.
Not the version where AI agents are going to replace all human jobs by 2030. The actual version, right now, based on what’s deployed in production.
The Actual Definition
What an AI agent is
Software that takes a goal, breaks it into steps, uses tools to execute those steps, handles errors along the way, and keeps working without you directing every action. The distinguishing characteristic is autonomous multi-step execution — not just answering a question, but completing a task.
The Key Distinction: One-Shot vs. Agentic
Most people’s experience with AI is one-shot: you type something, the AI responds, the exchange is complete. That’s a language model doing inference. An AI agent is different in one specific way: it takes actions, checks results, and takes more actions based on what it found — often dozens of steps — without you approving each one.
Example of one-shot AI: “Summarize this document.” You paste the document, the AI returns a summary. Done.
Example of an AI agent doing the same task: “Research this topic and produce a summary with verified sources.” The agent searches the web, reads multiple pages, identifies conflicts between sources, runs additional searches to resolve them, synthesizes findings, and returns a summary with citations — without you specifying each search query or each page to read. You gave it a goal; it handled the steps.
What Agents Can Actually Do
The tools an agent can use define its capability surface. Common tool categories in production agents:
Web search: Query search engines and retrieve current information
Code execution: Write and run code in a sandboxed environment, use results to inform next steps
File operations: Read, write, and modify files — documents, spreadsheets, data files
API calls: Interact with external services — CRMs, databases, project management tools, communication platforms
Browser control: Navigate web pages, fill forms, extract information
Memory: Store and retrieve information across steps within a session, sometimes across sessions
The combination of these tools is what makes agents capable of genuinely autonomous work. An agent that can search, write code, execute it, check the results, and write findings to a document can complete a research and analysis task that would otherwise require hours of human work — without you steering each step.
What “Autonomous” Actually Means in Practice
Autonomous doesn’t mean unsupervised indefinitely. Production agents are typically configured with:
Defined scope: The tools the agent can use, the systems it can access, the actions it’s allowed to take
Guardrails: Actions that require human confirmation before proceeding — making a payment, sending an email externally, modifying a production database
Reporting: Checkpoints where the agent surfaces what it’s done and asks whether to continue
Autonomy is a dial, not a switch. You set how much the agent handles independently versus checks in. Most production deployments start more supervised and reduce oversight as trust in the agent’s behavior is established.
Real Production Examples (Not Hypotheticals)
Concrete examples from confirmed public deployments as of April 2026:
Rakuten: Deployed five enterprise Claude agents in one week on Anthropic’s Managed Agents platform — handling tasks across their e-commerce operations including data processing, content tasks, and operational workflows
Notion: Background agents that autonomously update workspace pages, synthesize database content, and process meeting notes into structured summaries without manual triggers
Sentry: Agents integrated into developer workflows — monitoring error streams, triaging issues, and surfacing relevant context to engineers
Asana: Project management agents that update task statuses, synthesize project health, and move work items based on defined triggers
These are not pilots. These are production systems handling real operational load.
How They’re Built
An agent is built from three components:
A language model: The reasoning layer — the part that decides what to do next, interprets tool results, and determines when the task is complete
Tools: The action layer — APIs, code execution environments, file systems, or anything else the model can call to take action in the world
Orchestration: The loop that connects them — manages the sequence of model calls and tool executions, maintains state between steps, handles errors
Historically, builders had to construct the orchestration layer themselves — a significant engineering investment. Hosted platforms like Claude Managed Agents handle the orchestration layer, letting builders focus on defining the agent’s goals, tools, and guardrails rather than the mechanics of running the loop.
What Agents Are Not Good At (Yet)
Honest calibration on current limitations:
Long-horizon planning with many unknowns: Agents perform best on tasks with relatively defined scope. Open-ended exploratory work over many days with fundamentally uncertain requirements is still better handled by humans in the loop at each major decision point.
Tasks requiring physical world interaction: No production general-purpose physical agent exists. Software agents operating through APIs and interfaces are the current state.
Tasks where errors are catastrophic: Agents make mistakes. For any irreversible, high-stakes action — financial transactions, production data modifications, external communications to important relationships — human confirmation steps should remain in the loop.
By Will Tygart · Practitioner-grade · From the workbench
Being cited by AI systems is not luck and it’s not purely a domain authority game. There are structural characteristics of content that make AI systems more or less likely to pull from it. Here’s what those characteristics are and how to build them in deliberately.
AI systems — whether Perplexity, ChatGPT with web search, or Google AI Overviews — are trying to answer a question. When they search the web and retrieve candidate content, they’re looking for the passage or page that most directly and reliably answers the query. The content that wins is the content that makes the answer easiest to extract.
This has direct structural implications. A 3,000-word narrative essay that eventually answers a question on page 2 loses to a 600-word page that answers the question in the first paragraph, provides supporting evidence, and includes a definition. Not because shorter is better, but because clarity of answer placement is better.
The Structural Characteristics That Drive Citation
1. Direct Answer in the First 100 Words
Every piece of content you want AI systems to cite should answer the primary question it’s targeting before the first scroll. AI retrieval systems don’t read like humans — they identify the most relevant passage, and that passage needs to contain the answer, not just lead toward it.
Test: take your target query and your first 100 words. Does the answer exist in those 100 words? If not, restructure until it does. The rest of the piece can develop nuance, context, and supporting evidence — but the answer must be front-loaded.
2. Explicit Q&A Formatting
Question-and-answer structure signals to AI systems that the content is explicitly organized around answering queries. H3 headers phrased as questions, followed by direct answers, are one of the most reliable patterns for citation capture.
This is why FAQ sections work — not because of FAQPage schema specifically, but because the underlying structure gives AI systems a clean extraction target. Schema reinforces it; the structure is the foundation.
3. Defined Terms and Named Concepts
Content that defines terms clearly — “X is Y” statements — becomes citable for queries looking for definitions. AI systems frequently answer “what is X” queries by pulling the clearest definition they can find. If your content doesn’t include a crisp definitional sentence, it’s not competing for definition queries even if you’ve written a thorough treatment of the topic.
Add definition boxes. State “AI citation rate is the percentage of sampled AI queries where your domain appears as a cited source.” Don’t bury the definition in the third paragraph of an explanation.
4. Specific, Verifiable Facts
AI systems weight specificity. “$0.08 per session-hour” gets cited. “A relatively modest fee” does not. “60 requests per minute for create endpoints” gets cited. “Limited rate limits apply” does not.
Replace hedged language with concrete numbers and specific claims wherever your content supports it. Don’t fabricate specificity — wrong specific numbers are worse than honest hedging. But wherever you have real, verifiable data, make it explicit and prominent.
5. Entity Clarity
Content that makes clear who is speaking, what organization they represent, and what their basis for authority is gets cited more reliably. This is the E-E-A-T signal applied to AI citation: the system needs to assess whether this source is credible enough to cite.
Name the author. State the organization. Link to primary sources. Include dates on time-sensitive claims (“as of April 2026”). These signals tell the AI system this content has an accountable source, not anonymous text.
6. Freshness on Time-Sensitive Topics
For any topic where recency matters — product pricing, regulatory status, current events — AI systems heavily weight recently indexed, recently updated content. A page published April 2026 beats a page published January 2025 for queries about current status, even if the older page has higher domain authority.
Update time-sensitive content. Add “last updated” dates. Re-publish with fresh timestamps when the underlying facts change. Freshness signals are real citation drivers for volatile topic areas.
7. Speakable and Structured Data Markup
Speakable schema explicitly marks the passages in your content best suited for AI extraction. It’s a direct signal to AI retrieval systems: “this paragraph is the answer.” Combined with FAQPage schema, Article schema, and HowTo schema where relevant, structured markup makes your content more parseable.
Schema doesn’t replace the underlying structure — it reinforces it. A well-structured page with schema beats a poorly structured page with schema. But a well-structured page with schema beats a well-structured page without it.
8. Internal Link Architecture
AI systems that crawl the web assess topical depth partly through link structure. A page that sits within a tight cluster of related pages — all cross-linking around a topic — signals topical authority more strongly than an isolated page, even if the isolated page’s content is comparable.
Build the cluster. The hub-and-spoke architecture is as relevant for AI citation as it is for traditional SEO. Every spoke article should link to the hub; the hub should link to every spoke.
What Doesn’t Work
A few patterns that are intuitively appealing but don’t translate to citation lift:
More content for its own sake: 5,000 words of padded content is not more citable than 900 words of dense, accurate content. AI retrieval is looking for passage quality, not page length.
Keyword density: Traditional keyword repetition strategies don’t make content more citable. The query match is handled at retrieval; the citation decision is about answer quality, not keyword frequency.
Generic authority claims: “We’re the leading experts in X” is not citable. A specific data point that demonstrates expertise is.
The Compound Effect
These characteristics compound. A page with a direct front-loaded answer, Q&A structure, defined terms, specific facts, clear entity signals, fresh timestamps, and schema markup sitting within a well-linked cluster is materially more citable than a page with only two or three of these characteristics. The full stack produces disproportionate results.
You want to monitor whether AI systems are citing your content. What tools actually exist for this, what they do, what they don’t do, and what we’ve built ourselves when nothing on the market fit.
The Market as of April 2026
The market as of April 2026.
The AI citation monitoring category is real but nascent. Here’s an honest inventory:
Established SEO Platforms Adding AI Visibility Metrics
Several major SEO platforms have added “AI visibility” or “AI search” modules in the past 6–12 months. These generally track:
Whether your domain appears in AI Overviews for tracked keywords (via SERP scraping)
Brand mentions in AI-generated snippets
Comparative visibility versus competitors in AI search results
Ahrefs, Semrush, and Moz have all moved in this direction to varying degrees. Verify current feature availability — this has been an active development area and capabilities have changed rapidly.
Mention Monitoring Tools Expanding to AI
Brand mention tools like Brand24 and Mention have begun tracking AI-generated content that includes brand references. The challenge: they’re tracking brand name occurrences in crawled content, not necessarily AI citation events. Useful for brand visibility in AI-generated content that gets published, less useful for tracking in-session citations.
Purpose-Built AI Citation Tools (Emerging)
Several purpose-built tools targeting AI citation tracking specifically have launched or raised funding in early 2026. This category is moving fast. As of our last check:
Tools focused on tracking specific brand or entity mentions across AI platforms
API-first tools targeting developers who want to build citation monitoring into their own workflows
Dashboard tools with pre-built query sets for common industry categories
Treat any specific product recommendation here as a starting point for your own research — the category will look different in 6 months.
Google Search Console
The strongest existing tool, and it’s free. AI Overviews that cite your pages register as impressions and clicks in GSC under the relevant queries. This is first-party data from Google itself. Limitation: covers only Google AI Overviews, not Perplexity, ChatGPT, or other platforms.
What We Built
What we built.
When no existing tool covered the specific workflows we needed, we built our own. The stack:
Perplexity API Query Runner
A Cloud Run service that runs a predefined query set against Perplexity’s API on a weekly schedule. It parses the citations field from each response, checks for domain appearances, and writes results to a BigQuery table. Total engineering time: roughly one day. Ongoing cost: minimal (Cloud Run idle cost + Perplexity API usage).
The output: a weekly BigQuery record per query showing which domains Perplexity cited, with timestamps. Trend queries show citation rate over time by query cluster.
GSC AI Overview Monitor
Not a custom build — just systematic review of GSC data. We check weekly which queries are generating AI Overview impressions for our tracked sites. The signal: if a page is generating AI Overview impressions on new queries, that’s a citation event.
Manual ChatGPT Sampling
For highest-priority queries, manual weekly sampling of ChatGPT with web search enabled. We log results to a shared spreadsheet. Less scalable than the API approach, but ChatGPT’s web search activation is inconsistent enough that API automation adds complexity without proportional reliability gain.
What Doesn’t Exist (That Would Be Useful)
What doesn’t exist that would be useful.
The tool gaps that we still feel:
Cross-platform citation dashboard: A single view showing citation rate across Perplexity, ChatGPT, Gemini, and AI Overviews for the same query set. Nobody has built this cleanly yet.
Historical citation rate database: Knowing your citation rate is useful. Knowing whether it improved after you published a new piece of content is more useful. The temporal correlation is hard to establish with spot-check sampling.
Competitor citation tracking at scale: Easy to check manually for specific queries; hard to monitor systematically across a large competitor set and query space.
These gaps exist because the category is new, not because the problems are technically hard. Expect the tool landscape to fill in significantly over the next 12 months.
Updated October 30, 2026: Added The Citation Rate Workbook — a $7 workbook that works this page’s method end-to-end, with the worksheet to measure your own brand’s citation rate.
Citation rate for AI-generated responses: (queries in your sample where the model cited your domain or URL) ÷ (total queries you sampled) × 100. That is a rate you own. Bing Webmaster Tools AI Performance reports total citations, page-level counts, and—since the June 2026 preview—Citation Share, Intents, Topics, and Compare for grounding queries. None of those Bing numbers is your sampled rate until you pick a denominator.
Direct Answer: AI citation rate is cited queries divided by sampled queries, times 100, measured per platform. Bing’s total citations measure volume; Citation Share is your site’s percentage of all citations shown for one grounding query—not the same fraction. Define 20–100 target queries, log cited yes/no, then track the line after you refresh content on the URL that already earns citations.
Definition
AI citation rate
The percentage of sampled AI queries where a specific domain or URL appears as a cited source.
Formula: (queries where your domain or URL appeared as a source) ÷ (total queries sampled) × 100
This is observational math on a sample you control. It is not a ranking, a traffic metric, or Bing’s Citation Share.
Citations vs citation rate (the Bing trap)
Microsoft clarified the AI Performance vocabulary in 2026. Treat each metric as a different question.
Total citations — how often your URLs were shown as sources in AI answers across Copilot, Bing AI summaries, and supported partner surfaces in the date range you select.
Citation Share — your citations for a specific grounding query divided by all citations shown for that same query, times 100. High volume can still mean low share when many domains split the citation space.
Grounding query — the phrase Bing associates with retrieval that led to citations. Use it to cluster your manual sample, not as a substitute for running the sample.
Citation rate (yours) — cited queries in your log ÷ queries you actually ran (or a defined export window you label) × 100.
Pick 20–100 queries that match how you win work—not vanity prompts. Sample separately on Perplexity, ChatGPT with browsing/search enabled, Google AI Overviews, and Bing/Copilot. Do not blend platforms into one headline rate.
2. Log every run
Record query text, platform, date, cited yes/no, exact URL cited vs domain-only mention, and which competitor URL appeared if you were absent. A spreadsheet is enough; the discipline is what matters.
3. Compute and segment
Rate = cited ÷ sampled × 100, by platform and by query cluster (service + geo, software comparison, pricing, etc.). Pair the rate with LLM visibility measurement so you see mentions that never become footnotes.
4. Baseline, then patch in place
Run a 4–6 week baseline, then measure the delta after you update the slug that already has citation history. Do not mint a twin URL for the same intent—RE-BITE pages keep their addresses for a reason. When citations stall after a quiet period, check whether crawlers are seeing the refresh; our IndexNow speed test compares how fast Bing, Google, and GPT-oriented crawlers pick up a changed URL.
Worked example (Tygart Media, Bing export)
In a trailing ~30-day Bing AI Performance export pulled 9 September 2026, this domain showed 913 grounding queries and about 126,700 total citations. On the grounding family around “citation rate calculation AI-generated responses,” one line read 11,123 citations at 34.06% Citation Share. Share describes Bing’s slice for that query; it is not the cited ÷ sampled rate from a manual audit. Re-pull your own window in Bing—counts move with demand, model updates, and partner refresh cycles.
Reading the method is step one. Running it on your own brand is the job.
The Citation Rate Workbook works the formula end-to-end with real numbers, keeps citations and citation rate separated on one page, walks the Bing AI Performance exports step by step, and gives you the log sheet to measure your own brand’s rate with the same method — plus what a good rate honestly looks like, from observed data, not promises.
Delivered right after checkout — your download opens automatically.
Vertical example: a $1–10M restoration shop
Do not use Tygart Media’s software-pricing Citation Share as the shop’s KPI. Sample the ~20 queries that mirror dispatch: “water damage restoration [city],” Xactimate supplement disputes, emergency dry-out vs rebuild scope. Count whether the contractor domain, Google Business Profile, or a managed spoke was cited. One citation on a generic AI tooling query is not a booked job. Patterns from GEO case studies show lifts when answer boxes match how estimators and adjusters actually ask questions—not when marketing copies SaaS keywords.
How do you calculate citation rate for AI-generated responses? Cited queries ÷ sampled queries × 100. Run the math separately for each platform and query cluster.
Is a Bing AI Performance citation count a citation rate? No. Total citations are a volume count. Citation Share is your site’s share of citations for one grounding query. Your rate still needs a denominator you choose.
What is the difference between citation share and citation rate? Citation Share is Bing’s fraction of all citations shown for a single grounding query that went to your domain. Citation rate is your cited-query count divided by a sample you ran (or defined), times 100.
What is a good AI citation rate? There is no published benchmark. Track your own line after content and structure changes.
Should I combine ChatGPT, Perplexity, and Google AI Overviews into one rate? No. Each system picks sources differently. A blended rate hides where you are actually winning or losing.
How often should I recalculate citation rate? Baseline for 4–6 weeks, then recalculate after you patch a ranking slug or publish a material update—not daily.
By Will Tygart• Long-form Position
• Practitioner-grade
The most counterintuitive thing about Claude Managed Agents pricing is what you don’t pay for. Most people, when they hear “$0.08 per session-hour,” mentally model a virtual machine running continuously. That’s the wrong mental model. Here’s the right one, and why it matters for your bill.
The Core Distinction: Active vs. Idle
The core distinction — active vs idle.
Managed Agents session runtime only accrues while your session’s status is running. The session can exist — open, initialized, capable of continuing — without accumulating runtime charges when it’s not actively executing.
The specific states that do not count toward your $0.08/hr charge:
Time spent waiting for your next message
Time waiting for a tool confirmation
Time waiting on an external API response your tool is calling
Rescheduling delays
Terminated session time
This is a meaningful architectural decision by Anthropic. They’re billing on what actually taxes their compute — active execution — not on session existence or wall-clock time.
Why This Is Different From How You Might Expect Billing to Work
Compare three billing models:
Virtual machine billing (what this is not): You pay for every hour the instance exists, whether it’s idle or saturated. A VM running 24/7 with 10% actual utilization still costs 24 hours/day.
Lambda/function billing (closer analogy): AWS Lambda bills on execution duration and invocation count — you pay when code actually runs, not when a function is “available.” Idle Lambda functions cost nothing.
Managed Agents billing (what this actually is): Closer to Lambda than VM. You pay $0.08 per hour of active execution. A session that runs for 2 hours of wall-clock time but has 90 minutes of waiting costs $0.08 × 1.5 hours = $0.12, not $0.08 × 2 hours = $0.16.
A Real Scenario: The Human-in-the-Loop Agent
A real scenario — the human-in-the-loop agent.
Consider an agent that processes your inbox for action items and waits for your approval before sending replies. Wall-clock time: 4 hours open during your workday. Actual active execution: 20 minutes of processing across that 4-hour window, with the rest spent waiting for your review decisions.
VM billing equivalent: 4 hours × rate = significant charge
The difference is real. For interaction-heavy agents where the agent frequently waits for human decisions, the idle-time exclusion significantly reduces costs versus a naive per-hour model.
A Real Scenario: The Autonomous Batch Agent
Now consider an agent running a fully autonomous content pipeline — no human checkpoints, just continuous execution through a queue. Wall-clock time and active execution time are nearly identical because the agent never waits.
A 2-hour autonomous batch: 2 hours × $0.08 = $0.16
Here, the idle-time model provides no benefit — the agent has no idle time. The billing is effectively equivalent to per-hour pricing because execution is continuous.
Code Execution Containers Are Included
One more billing nuance worth knowing: when your agent runs code, the execution happens in sandboxed Linux containers. These containers are not separately billed on top of session runtime. The $0.08/hr covers both the session runtime and the container execution. This is explicitly documented by Anthropic and represents meaningful savings if your agent is doing significant code execution work — you’re not paying twice.
What This Means for Workload Design
What this means for workload design.
If you’re designing agent workflows and have the choice between architectures, the billing model creates a useful signal:
Agents that wait on humans: Metered billing is favorable — you only pay for the actual reasoning and execution time, not the human decision time
Fully autonomous agents: Billing approaches equivalent to per-hour rates — optimize these on token efficiency, not idle reduction
Scheduled batch agents: Natural fit — run when needed, terminate when done, no idle accumulation
The 24/7 Agent Math
For anyone doing the 24/7 always-on calculation: the maximum theoretical runtime exposure is 24 hrs × $0.08 × 30 days = $57.60/month in session fees. But a 24/7 agent with zero idle time is rare in practice. Agents that sleep between triggers, wait on external data, or hold for human decisions have meaningful idle windows that reduce the actual charge below the theoretical ceiling.
By Will Tygart• Long-form Position
• Practitioner-grade
Everything people actually ask about Claude Managed Agents, answered straight. No preamble about “the exciting world of AI agents.” If you’re here, you already know why this matters — you just need answers.
This page covers pricing, setup, capabilities, limits, comparisons, and the specific questions that don’t have obvious homes in Anthropic’s documentation. It updates as the beta evolves.
Context
Claude Managed Agents launched April 8, 2026 as a public beta and remains in public beta as of October 2026. All answers reflect current documentation as of October 2026. Beta details change — verify specifics at platform.claude.com/docs.
Pricing Questions
Pricing questions — stale-proof framing.
What does Claude Managed Agents cost?
Two charges: standard Claude API token rates (same as calling the Messages API directly) plus $0.08 per session-hour of active runtime. That’s the complete formula. See the complete pricing reference for worked examples by workload type.
What exactly is a “session-hour” and when does it start billing?
A session-hour is one hour of active session runtime — time when your session’s status is running. Billing is metered to the millisecond. It does not accrue during idle time, time waiting for your input, time waiting for tool confirmations, or after session termination.
What’s included in the $0.08/session-hour charge?
The session runtime charge covers Anthropic’s managed infrastructure: sandboxed code execution containers, state management, checkpointing, tool orchestration, error recovery, and scaling. You are not separately billed for container hours on top of session runtime.
Does the $0.08/hr apply even if my agent is just waiting?
No. Time spent waiting for your message, waiting for tool confirmations, or sitting idle does not accumulate runtime charges. Only active execution time counts.
What does web search cost inside a Managed Agents session?
$10 per 1,000 searches ($0.01 per search), billed separately from session runtime and token costs. This is the same rate as web search through the standard API.
Are there volume discounts?
Yes, negotiated case-by-case for high-volume users. Contact [email protected] or through the Claude Console.
How does Managed Agents pricing compare to running my own agent infrastructure?
The $0.08/session-hour is almost always cheaper than equivalent provisioned compute — but you trade infrastructure control and data locality for that simplicity. For a full comparison: Build vs. Buy: The Real Infrastructure Cost.
What’s the real monthly cost if I run an agent 24/7?
Maximum theoretical session runtime: 24 hrs × $0.08 × 30 days = $57.60/month. In practice, no production agent has zero idle time. Token costs become the dominant cost driver long before you hit the runtime ceiling. Detailed breakdown: The Real Monthly Cost of Running Claude Managed Agents 24/7.
Setup and Access Questions
Setup and access questions.
How do I get access to Claude Managed Agents?
Available to all Anthropic API accounts in public beta — no separate signup. You need the managed-agents-2026-04-01 beta header in your API requests. The Claude SDK adds this header automatically.
Does it work with my existing API key?
Yes. Same API key you’re already using for the Messages API. Same authentication. The beta header is the only new requirement.
What three ways can I access Managed Agents?
Via the Claude SDK (recommended — handles the beta header automatically), via direct API calls with the beta header, or via the Claude Console’s new Managed Agents section for no-code agent configuration and session tracing.
Can I use Managed Agents through AWS Bedrock or Google Vertex AI?
Managed Agents runs on Anthropic-managed infrastructure. This is distinct from Bedrock and Vertex AI deployments. Check Anthropic’s current documentation for multi-cloud availability status — this is an area of active development.
Capability Questions
What can Claude Managed Agents actually do?
Run long autonomous sessions with persistent state, execute code in sandboxed Linux containers, use tools including web search and MCP servers, coordinate multiple Claude instances via Agent Teams, and maintain checkpoints for crash recovery. The session can last minutes or hours without you staying in the loop.
What’s the difference between Agent Teams and subagents?
Agent Teams coordinate multiple Claude instances with independent contexts, direct agent-to-agent communication, and a shared task list — suited for complex parallel tasks. Subagents operate within the same session as the main agent and only report results upward — more economical for sequential targeted tasks but less capable of true parallelism.
Does it support MCP servers?
Yes. MCP servers can be integrated as tool sources in Managed Agents sessions, extending what the agent can access and act on.
How long can a session run?
Anthropic’s documentation currently references session durations of minutes to hours. Claude Code’s longest autonomous sessions have reached 45 minutes. Managed Agents is architected for longer-running work. Check current documentation for specific session duration limits as the beta matures.
What happened to Claude Code — is it the same as Managed Agents?
No. Claude Code is a separate local coding workflow product. Anthropic’s docs explicitly note partners should not conflate the two. Managed Agents is a hosted API runtime service. Claude Code is a developer tool. Different products, different use cases, different billing.
Rate Limit Questions
Rate limit questions.
What are the rate limits for Managed Agents?
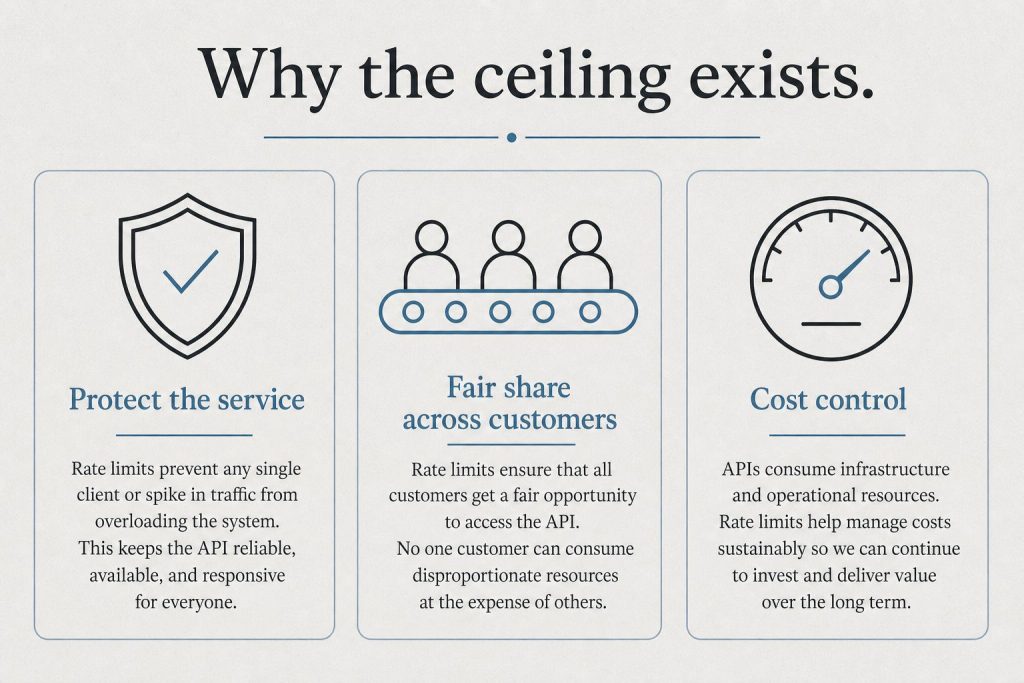
60 requests per minute for create endpoints; 600 requests per minute for read endpoints. Organization-level API limits still apply on top of these. For higher limits, contact Anthropic enterprise sales. Detailed breakdown: Claude Managed Agents Rate Limits Explained.
Do standard Claude API rate limits still apply inside a session?
Organization-level limits apply. The session runtime and create/read endpoint limits are Managed Agents-specific. If you’re running many parallel Agent Teams, model token throughput limits will become relevant.
Comparison Questions
How does Managed Agents compare to OpenAI’s Agents API?
Both offer hosted agent infrastructure. Key differences: Managed Agents is Claude-native (no multi-model flexibility), sessions bill on runtime + tokens vs. OpenAI’s different pricing model, and lock-in dynamics differ. Full comparison: Claude Managed Agents vs. OpenAI Agents API.
Should I use Managed Agents or the Claude Agent SDK?
Use Managed Agents when you want Anthropic to host the runtime — less infrastructure work, faster to production. Use the SDK when you need tighter loop control, on-premise execution, or multi-cloud flexibility. Anthropic’s own migration docs draw this line clearly: SDK runs in your environment; Managed Agents runs in theirs.
What companies are already using Managed Agents in production?
Notion, Asana, Rakuten, Sentry, and Vibecode were launch partners. Rakuten deployed five enterprise agents within a week. Allianz is using Claude for insurance agent workflows. Anthropic’s run-rate from the agent developer segment exceeds $2.5 billion. How Rakuten did it in a week →
Data and Security Questions
Where does my data go when running in Managed Agents?
Execution runs on Anthropic’s infrastructure. This is the explicit trade-off: you get managed infrastructure; they manage the compute. For companies with strict data sovereignty requirements, this is the key constraint to evaluate. On-premise or native multi-cloud deployment is not currently available.
What are the sandboxing guarantees?
Anthropic uses disposable Linux containers — “decoupled hands” in their terminology. Each container is a fresh sandboxed environment for code execution. State persistence is managed separately from the execution environment.
Strategic Questions
Is this a bet worth making?
That depends on your switching cost tolerance. Lock-in is real: once your agents run on Anthropic’s infrastructure with their tools, session format, and sandboxing, switching providers isn’t trivial. The counter-argument: the infrastructure you’d otherwise build to match this is months of engineering. One developer’s reaction at launch was blunt: “there goes a whole YC batch.” That captures both the opportunity and the risk. Our take on why we’re staying our course →
What does this mean for AI citation and visibility?
Agents running on Anthropic’s infrastructure make decisions about what content to surface, cite, and synthesize. As agent workloads grow, being present in the knowledge sources agents draw from becomes a search strategy question in itself. What AI citation monitoring looks like →
Updated October 28, 2026: Made infographic diagrams clickable to open full-size images.
Last refreshed: October 28, 2026 (Pacific)
May 2026 Update — Dreaming Feature + Beta Status
Anthropic introduced Dreaming at Code w/ Claude (May 6, 2026) — a new Managed Agents capability where agents review their own session history overnight to improve future performance. Harvey (legal AI) reported a roughly 6× task completion rate increase after implementing it. Dreaming is developer-access preview only. Multiagent Orchestration and Outcomes are now in public beta. See the new Dreaming section below.
What Is Claude Managed Agents? (Current Status, May 2026)
What Claude Managed Agents is right now.
Claude Managed Agents is Anthropic’s framework for long-running, stateful AI agents — agents that can maintain context across sessions, hand off between sub-agents, and now, improve themselves by reviewing their own work history. Here’s the current status of each component:
Component
Status
Who Has Access
Multiagent Orchestration
Public Beta
All API developers
Outcomes
Public Beta
All API developers
Dreaming
Developer Preview
Selected developers only
Dreaming: The Feature the Press Mostly Missed
Dreaming — the feature the press mostly missed.
Announced at Code w/ Claude on May 6, 2026, Dreaming is a Managed Agents capability that lets agents review and reorganize their own memory between sessions. The mechanism:
After a session ends, the agent reads its existing memory store alongside the session transcripts
It produces a new, reorganized memory store: duplicates merged, stale entries replaced, new patterns surfaced
The next session starts with a higher-quality knowledge base — capturing insights no single session could hold
This is meaningfully different from simply persisting conversation history. The agent isn’t just remembering what happened — it’s synthesizing what it learned. Think of it as the difference between taking notes and actually reviewing and reorganizing your notes the next morning.
The Harvey Result
Harvey, the legal AI company, reported approximately a 6× task completion rate increase after implementing Dreaming in their Managed Agents workflow. Harvey’s use case — complex legal research that spans multiple sessions with evolving context — is exactly the kind of work Dreaming was designed for. Sessions build on each other rather than starting fresh each time.
Dreaming is not available to end users — it’s a developer-layer capability requiring implementation
It’s not persistent memory in the claude.ai chat interface
It’s not available to free or standard Pro subscribers through any interface
It’s a developer preview, not GA — expect it to evolve before full release
Our Take: Why This Architecture Matters
We run Managed Agents in our own Cowork workflows. The Dreaming announcement is the first time Anthropic has shipped something that resembles how expert human knowledge actually compounds over time — not by accumulating raw notes, but by periodically synthesizing and reorganizing what’s been learned into a cleaner structure.
The Harvey 6× result is a real-world data point from a production legal AI workflow. That’s not a benchmark number — it’s a deployed system showing measurable improvement from session-to-session memory refinement. Whether that 6× figure holds across different use cases is unknown, but the direction of the effect is the signal: agents that learn from their own history outperform agents that don’t.
For non-developer users watching this space: Dreaming is the preview of what agentic AI will look like when it becomes mainstream. The groundwork being laid now in developer preview will eventually surface in subscription-tier products.
Model Accuracy Note — Updated May 2026
Lineup currency (Oct 2026, verified): Sonnet 5.5 ($2/$10), Opus 5.5 ($4/$20), Haiku 4.5 ($1/$5), Fable 5.1 ($10/$50). Legacy (still listed): Opus 4.8 ($5/$25), Sonnet 4.6 ($3/$15). Prior note (superseded): Prior flagship claim: Claude Opus 4.7 (claude-opus-4-7). Prior models claim: Opus 4.7 · Sonnet 4.6 · Haiku 4.5. Claude Opus 4.7 (claude-opus-4-7) was claimed current as of April 16, 2026. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →
Tygart Media Strategy
Volume Ⅰ · Issue 04Quarterly Position
By Will Tygart • Long-form Position • Practitioner-grade
You opened this tab because you need a number you can actually use. Not a vibe, not “it depends.” A real pricing breakdown you can put in a spreadsheet, a budget request, or a Slack message to your CTO.
This is that page. Every pricing variable for Claude Managed Agents in one place, verified against Anthropic’s current documentation as of October 5, 2026. Bookmark it. The beta will update; so will this.
Quick Reference: The Formula
Total Cost = Token Costs + Session Runtime ($0.08/hr) + Optional Tools
Session runtime only accrues while status = running. Idle time is free.
The Two Cost Dimensions
Two cost dimensions — stale-proof framing.
Claude Managed Agents bills on exactly two dimensions: tokens and session runtime. Every pricing question you have collapses into one of these two buckets.
Dimension 1: Token Costs
These are identical to standard Claude API pricing. You pay the same rates you’d pay calling the Messages API directly. No Managed Agents markup on tokens. Current rates for the models most commonly used in agent work:
Claude Sonnet 5.5: $2/million input tokens, $10/million output tokens (legacy Sonnet 4.6, still listed: $3/$15)
Prompt caching: same multipliers as standard API — cache reads from $0.20/MTok (up to 95% off input rates) dramatically reduce input token costs on long sessions with stable system prompts
The implication: a token-heavy agent with a large system prompt that runs the same context repeatedly benefits significantly from prompt caching, and that benefit carries over unchanged into Managed Agents.
Dimension 2: Session Runtime — $0.08/Session-Hour
This is the Managed Agents-specific charge. You pay $0.08 per hour of active session runtime, metered to the millisecond.
The critical word is active. Runtime only accrues while your session’s status is running. The following do not count toward your bill:
Time spent waiting for your next message
Time waiting for a tool confirmation
Idle time between tasks
Rescheduling delays
Terminated session time
This is not how you’d bill a virtual machine. It’s closer to how AWS Lambda bills — you pay for execution, not reservation. An agent that “runs” for 8 hours but spends 6 of those hours waiting on human input has a very different bill than one running continuous autonomous loops.
Optional Tool Costs
Web Search: $10 per 1,000 Searches
If your agent uses web search, each search costs $10/1,000 — that’s $0.01 per search. For most agents, this is negligible. For a research agent running hundreds of searches per session, it becomes a line item worth modeling separately.
Code Execution: Included in Session Runtime
Code execution containers are included in your $0.08/session-hour charge. You’re not separately billed for container hours on top of session runtime. This is explicitly stated in Anthropic’s docs and represents meaningful savings versus provisioning your own compute.
Worked Cost Examples
Example 1: Daily Research Agent
Runs once per day. 30 minutes of active execution. Processes 10 documents, outputs a summary report. Moderate token volume.
In practice, no agent has zero idle time — real cost will be lower
Token costs at this scale become the dominant factor by a wide margin
Anthropic’s Official Example (from their docs)
Anthropic’s docs price this example on Claude Opus 5 ($5/$25): $0.705 all-in, or $0.525 with 40,000 cache reads. Recomputed at current Opus 5.5 rates: a one-hour coding session consuming 50,000 input tokens and 15,000 output tokens: session runtime = $0.08. With prompt caching active and 40,000 of those tokens as cache reads ($0.20/MTok), the token math is: 10,000 uncached input × $4/M = $0.04, plus 40,000 cache reads × $0.20/M = $0.008, plus 15,000 output × $20/M = $0.30 — about $0.35 in tokens. The runtime charge stays flat at $0.08 regardless of caching, for roughly $0.43 all-in.
What’s Not Billed in Managed Agents
A few things that might seem like costs but aren’t:
Infrastructure provisioning: Anthropic handles hosting, scaling, and monitoring at no additional charge
Container hours: Explicitly not separately billed on top of session runtime
State management and checkpointing: Included in the session runtime charge
Error recovery and retry logic: Anthropic’s infrastructure problem, not yours
Rate Limits
Managed Agents has specific rate limits separate from standard API limits:
Create endpoints: 300 requests/minute
Read endpoints: 1,200 requests/minute
Organization-level limits still apply
For higher limits, contact Anthropic enterprise sales
How to Access Managed Agents Pricing
Managed Agents is available to all Anthropic API accounts in public beta. No separate signup, no premium tier gate. You need the managed-agents-2026-04-01 beta header in your API requests — the Claude SDK adds this automatically.
For high-volume agent applications, Anthropic’s enterprise sales team negotiates custom pricing arrangements. Contact them at sales@anthropic.com or through the Claude Console.
The Pricing Signals Worth Noting
Anthropic recently ended Claude subscription access (Pro/Max) for third-party agent frameworks, requiring those users to switch to pay-as-you-go API pricing. This signals a deliberate strategy: consumer subscriptions are for human-paced interactions; agent workloads route through the API. The $0.08/session-hour rate exists in that context — it’s infrastructure pricing for compute that runs beyond human attention spans.
The session-hour model also signals something about Anthropic’s infrastructure cost structure. They’re pricing on active execution time because that’s what actually taxes their systems. Idle sessions don’t cost them much; active agents do. The billing model follows the actual resource consumption pattern.
Frequently Asked Questions
Is the $0.08/session-hour charge in addition to token costs, or does it replace them?
In addition to. You pay both: standard token rates for all input and output tokens, plus $0.08 per hour of active session runtime. They’re separate line items.
Does prompt caching work in Managed Agents sessions?
Yes. Prompt caching multipliers apply identically to Managed Agents sessions as they do to standard API calls. If your agent has a large, stable system prompt, caching it can significantly reduce input token costs.
What happens if my session crashes? Am I billed for the crashed time?
Runtime accrues only while status is running. Terminated sessions stop accruing. Anthropic’s infrastructure handles checkpointing and crash recovery — the session state is preserved even if the session terminates unexpectedly.
Can I use Managed Agents on the free API tier?
Managed Agents is available to all Anthropic API accounts in public beta, but standard tier access and rate limits apply. Free API tier users receive a small credit for testing.
How does this compare to running agents on my own infrastructure?
An experiment in whether rhythm can do the heavy lifting of retention — and the full prompt library so you can run it yourself.
Instant Operational Downloads
Run the Knowledge Compression Experiment Yourself
Field-tested carrier wave matchers, 1-stage-per-bar worksheets, Producer.ai syntax validators, and AI-run routines built directly from this complete knowledge compression guide.
Quick Reference FREE
Knowledge Compression Quick-Start Card
2-page field card: Carrier-wave-to-information-shape matcher (Boom-bap, Liquid D&B, Gospel-Soul, Dub, Bossa nova), one knowledge stage per bar, 5-part prompt skeleton, and the critical do-not-modify tags rule.
Feed to ChatGPT or Claude: 5 AI-run routines (/carrier-wave-selector, /knowledge-to-bars, /prompt-builder-auditor, /variance-lab, /full-pipeline) with embedded dispatch router to turn your AI into a knowledge-compression producer.
We memorize song lyrics we heard once in 1998 but forget the contents of a meeting from Tuesday. That’s not a bug in the brain — it’s a feature of how rhythm, melody, and cadence bypass the part of the mind that resists rote information and deliver payloads directly into long-term memory.
This project is a controlled test of that feature. The working hypothesis: a well-constructed song can transmit a complex, multi-step body of knowledge more densely and more durably than an equivalent written explanation. Not as a novelty. As a real transmission format.
Instead of producing ten finished tracks, I’m shipping one playable proof-of-concept and nine fully-formed prompts you can paste directly into Producer.ai (or any AI music generator) to build the rest yourself. The prompts are the real artifact. The song is the proof that the format works.
The Method
Every track in this series takes a dense subject — biology, economics, physics, logic, history — and encodes the mechanics into a single song. The genre for each track is chosen to match the shape of the information. Boom-bap for linear processes. Drum & bass for cyclical systems. Gospel for immutable laws. Dub for slow geological time. Bossa nova for elegant deception. The genre isn’t decoration. It’s the carrier wave.
Parenthetical ad-libs — (like this) for emphasis hooks
One knowledge stage per bar — no filler lines, no padding
That skeleton is what Producer.ai parses cleanly. Deviate from it and the output degrades.
The Knowledge Compression Production Suite
Encode Your Own Lessons Into High-Retention Songs
Skip trial-and-error prompt writing. The static Prompt Pack gives you printable checklists, tag reference sheets, and tempo/key matrices for all 10 tracks—or feed the Bot Book to ChatGPT/Claude to run interactive carrier-wave interviews, 1-fact-per-bar metric encoding, and pre-flight syntax auditing automatically.
• Genre-is-Carrier-Wave Sheet: 10 knowledge topology matchers.
• 5-Part Prompt Skeleton: Structure checklist & tag integrity rules.
• Stage Directions Lexicon: [bass drops], [sax solo], [vinyl crackle].
• Digestion Encoder Grid: 12 bars from enamel to water reclamation.
• Producer.ai Validator: Tempo (72–170 BPM) & key audit matrix.
• Bot Book for AI ($17): 5 executable routines & embedded router.
Secure 1-Click Square Checkout
Track 01: Internal Transit Authority (The Proof of Concept)
The inaugural track walks through the complete human digestive process — from the oral gateway and enamel contact all the way through peristalsis, the pyloric valve, villi absorption, the liver as master filter, and the final water reclamation in the large intestine. Every physiological stage gets a bar. The cadence is engineered to act as a mnemonic anchor so the steps lock in sequence the way a chorus does.
Listen:
The Prompt That Made It
Conscious Hip-Hop, Boom-Bap, Jazz-Rap, dusty MPC drum breaks, walking upright bass, warm Rhodes piano chords, soulful saxophone loops, mid-tempo groove, male narrator, gritty yet clear vocal tone, intellectual authoritative delivery, 92 BPM, key of D minor, earthy textures, rhythmic education, organic street philosopher vibe.

[Intro]
[Dusty vinyl crackle, a smooth upright bassline enters with a steady boom-bap drum loop]
(Check the rhythm)
(Internal mechanics)
Knowledge of the vessel is the first step to power
Pay attention to the transit system within

[Verse 1]
Entry point at the oral gateway where enamel strikes
Mechanical grinding begins the structural breakdown
Salivary glands release the first chemical catalyst
Softening the mass into a bolus for the descent
The pharynx directs the traffic down the narrow pipe
Esophagus muscles ripple in a rhythmic wave
Peristalsis pushing the cargo toward the central vat
Gravity is secondary to the muscular contraction
Arrival at the cardiac sphincter, the heavy door
Opening into the churning chamber of liquid fire
Hydrochloric acid dissolves the complex architecture
Turning the harvest into a slurry called chyme
Pyloric valve monitors the pressure of the flow
Releasing the mixture into the winding corridor
Small but vast, the labyrinth of the interior
(The transit continues)

[Chorus]
Break the heavy down to the molecular
Extract the power from the physical plane
Ingest the wisdom, process the essence
Discard the residue to remain light
(Keep the system moving)
(From the root to the crown)

[Verse 2]
The duodenum meets the bile from the emerald organ
Breaking the lipids into manageable fragments
Pancreatic juices neutralize the acidic surge
Preparation for the grand absorption of the spirit
Look at the walls lined with millions of tiny fingers
Villi reaching out to grasp the passing nutrients
Capillaries waiting to ferry the fuel to the stream
Glucose and amino acids entering the bloodline
The liver stands as the master filter at the station
Processing the wealth, storing the vital reserves
What remains travels further into the wider tunnel
The large intestine, where the moisture is reclaimed
Balance is restored as the fluid returns to the system
Compacting the remnants for the final departure
(The cycle completes)
(Nothing is wasted)

[Verse 3]
Understand the blueprints of your own biological city
Every cell waiting for the delivery of the cargo
ATP production is the currency of your motion
Transmuting the external world into internal force
Maintain the temple, respect the intricate valves
From the first bite to the ultimate release
The journey of the sustenance is the journey of life
Master the transit, manifest the clarity
(Internal rhythm)
(The body is a map)

[Outro]
[Bassline fades out as the saxophone takes a solo]
(Digest the truth)
(The spirit is fed)
Stay tuned to the frequency of the self
System check complete
[Drums stop abruptly]
[Vinyl scratch]
Paste that into Producer.ai and you get something in the neighborhood of what you just heard. Variance in the output is part of the experiment — two generations of the same prompt are never identical, which is useful data in itself.
The Remaining Nine Prompts
Each of these is ready to paste into Producer.ai. The production brief is the first paragraph. The structured lyrics are the body. Don’t modify the bracketed tags — they’re what the model parses for song structure.
Track 02 — The Invisible Hand
Subject: Supply & demand, price elasticity, market equilibrium Genre: Funk-Soul / Neo-Soul Why this genre: Call-and-response is literally how supply talks to demand. The groove of a funk bassline mirrors the oscillation of price discovery. Horns for emphasis on equilibrium points.
Funk-Soul, Neo-Soul, vintage Clavinet, slap bass, tight pocket drums with crisp hi-hats, Hammond B3 organ swells, brass stabs on the downbeat, female lead vocal with a soulful conversational tone, backup call-and-response vocals, 98 BPM, key of E minor, warm analog textures, economic street sermon, intellectual groove, Curtis Mayfield meets Erykah Badu energy.

[Intro]
[Clavinet riff locks in over a fat slap bassline, drums kick in on the two]
(The market speaks)
(Listen to the price)
Every number tells a story if you know how to read it

[Verse 1]
Supply is the stack of what the makers can produce
Demand is the hunger of the people on the street
When the hunger outpaces what the factory can release
Price climbs the ladder like a dollar chasing heat
(Scarcity)
When the shelves are overflowing and the buyers walk away
Price slides down the pole 'til it finds a place to stay
(Surplus)
Equilibrium is the handshake in the middle of the trade
Where the quantity they want meets the quantity they made

[Chorus]
No one at the wheel but the wheel still turns
(The invisible hand)
Every selfish motive is a signal that returns
(The invisible hand)
Price is the language of a million silent minds
(Supply meets demand)
Information coded in a number you can find

[Verse 2]
Elastic is the product you can easily replace
Butter swaps for margarine, the demand shifts with grace
Inelastic is the thing you cannot live without
Insulin and gasoline, the price can climb and shout
Shift the whole curve with a change in the income
Tastes and expectations move the baseline where we come from
Substitutes and complements, the dance is interlinked
Coffee needs the sugar and the tea needs what you think

[Verse 3]
Ceiling on the price creates a shortage underneath
Rent control is kindness with a hidden set of teeth
Floor below the price creates a surplus on the shelf
Minimum wage arguments depend on who you tell
Subsidies and taxes are the fingers on the scale
Every intervention leaves a signal or a trail
Read the curve, respect the slope, understand the game
The market is a mirror of the people and their aim

[Outro]
[Bass solo fades under the final vocal phrase]
(The invisible hand)
(It's just us)
No magic in the market, just a mirror of our want
[Horn stab]
Track 03 — Eight Stages of Fire (The Krebs Cycle)
Subject: Citric acid cycle / cellular respiration Genre: Liquid Drum & Bass Why this genre: The Krebs cycle IS a loop. D&B at 170 BPM has a natural eight-bar cyclical structure that maps onto the eight enzymatic steps. Each loop of the drum pattern equals one turn of the cycle.
Liquid Drum and Bass, atmospheric D&B, rolling amen-break drums, deep reese bassline, ethereal female vocal samples, jazzy Rhodes pads, subtle vinyl crackle, male spoken-word delivery over the groove, intellectual science-teacher tone with urgency, 170 BPM, key of F minor, London Elektricity meets Calibre energy, biochemistry as dancefloor science.

[Intro]
[Atmospheric pad swells, amen break rolls in at half-time, bass drops at 16]
(Eight stages)
(One loop)
The powerhouse of the cell runs on a rhythm you can feel

[Verse 1]
Acetyl-CoA meets the oxaloacetate partner
Citrate is the child of the very first encounter
Stage one complete and the cycle starts to spin
Isomerization turns the citrate into isocitrate, here we begin
Alpha-ketoglutarate is the third stop on the train
First carbon released as carbon dioxide in the rain
NADH is the currency the stage begins to mint
Every electron captured is a future ATP hint

[Chorus]
Eight stages of fire in the mitochondrial core
(Round and round)
Every turn of the wheel is a molecule of power
(Round and round)
Carbon in, carbon out, electrons for the chain
(The loop never breaks)
The citric acid cycle is the engine of the frame

[Verse 2]
Succinyl-CoA is the fourth stop on the line
Second carbon leaves as CO2 this time
GTP is minted here, the cycle pays the bill
Succinate takes the baton and it climbs the hill
FADH2 is captured at the sixth enzymatic gate
Fumarate is the next shape in the metabolic fate
Malate comes behind with a water molecule attached
Oxaloacetate returns, the circle has been latched

[Verse 3]
One glucose feeds two turns of the eternal loop
Thirty-something ATP from the cellular soup
Carbon dioxide exits through the breath you just released
Every exhale is a Krebs cycle receipt
The oxygen you breathe becomes the water that you drink
Electron transport chain is the final missing link
NADH and FADH2 deliver to the crew
Complexes one through four build the gradient that's true

[Outro]
[Drums cut to half-time, Rhodes takes the final chord]
(Eight stages)
(One breath)
Every turn is a heartbeat at the molecular level
[Bass fades]
Track 04 — Three Laws of Motion
Subject: Newton’s three laws of motion Genre: Gospel-Soul with a live band feel Why this genre: Gospel is the music of laws — immutable, declarative, celebratory. One law per verse, each verse building like a sermon. The B3 organ and full choir give each law the weight of doctrine.
Gospel-Soul, live band feel, Hammond B3 organ, upright piano, tight drum kit with cross-stick snare, walking bass, full gospel choir backing vocals, male lead with a preacher's cadence building from calm exposition to triumphant declaration, 84 BPM, key of G major with a relative minor bridge, warm analog, church basement science class energy, Ray Charles meets Neil deGrasse Tyson.

[Intro]
[Solo organ progression, choir hums underneath, bass and drums enter on the turnaround]
(Three laws)
(One universe)
Isaac Newton wrote the rules and the cosmos said amen

[Verse 1 — The First Law]
An object at rest will remain at rest, brother
(Unless a force comes knocking at the door)
An object in motion will stay in that motion forever
(Unless a friction or a gravity steps on the floor)
Inertia is the memory of the mass
It remembers where it was and it wants to stay
The universe is lazy, that's the truth of it
You gotta push if you want something to sway
(The first law)
(The law of rest)

[Chorus]
Three laws, one universe, every motion is a sermon
(Hallelujah in the physics)
Three laws, one universe, every push is a confession
(Hallelujah in the mechanics)
Every falling apple is a prayer to the equation
(F equals m-a)
The whole creation singing in the language of equation

[Verse 2 — The Second Law]
Force is the product of the mass and acceleration
(F equals m-a)
The heavier the object, the harder the negotiation
(F equals m-a)
Push a shopping cart, push a freight train, feel the difference
The mass is the resistance and the force is the insistence
A equals F divided by the weight you're trying to move
That's the second law, and the second law is proof
Double the force and you double the acceleration
Same mass, twice the push, twice the celebration

[Verse 3 — The Third Law]
For every action there's an equal and opposite reaction
(Say it back to me)
Every push against the world is a push the world pushes back
(Say it back to me)
A rocket burns its fuel and the exhaust goes down
The rocket goes up 'cause the universe is round
Walk across the floor and the floor walks back at you
Jump into the air and the earth moves a little too
Infinitesimal but real, the law is never bent
Every action has its answer, every force has its rent

[Outro]
[Choir sustains on the final chord, organ rolls, drums drop]
(Three laws)
(One universe)
Isaac wrote the scripture and the cosmos is the congregation
[Organ holds the final note]
Track 05 — The Method (The Scientific Method)
Subject: The scientific method as a cognitive discipline Genre: Lo-fi Hip-Hop / Jazzhop Why this genre: Lo-fi is the music of studying. The relaxed tempo and bedroom-producer aesthetic mirrors the patient, iterative nature of actual science. A jazzhop chorus loops the method so the structure of the song IS the structure of the method.
Lo-fi Hip-Hop, Jazzhop, dusty sampled drums with the kick slightly off the grid, muted trumpet loop, warm tape-saturated Rhodes, upright bass, vinyl crackle throughout, gentle brush snares, male vocal with a calm, curious, late-night-library delivery, 78 BPM, key of C minor, Nujabes meets a PBS documentary, study-group philosophy.

[Intro]
[Vinyl crackle, Rhodes chord holds, drums slide in off the kick]
(Observe)
(Ask)
The method is older than the labs it built

[Verse 1]
Step one is the noticing, the pause before the claim
A curiosity that fires when the pattern doesn't frame
Observe without the filter of the answer in your head
Write down what you saw, not what the expectation said
Step two is the question, the specific thing you ask
Vague inquiries die on the vine, precision is the task
What causes this, how often, under what conditions
Narrow the aperture and ask with clean definitions
(The method begins)

[Chorus]
Observe, ask, hypothesize, test
(Refine what you thought)
Observe, ask, hypothesize, test
(Keep only what survived)
The method is a filter, not a faith
(Evidence is the ground)
Every belief you hold should earn the space it's allowed

[Verse 2]
Step three is the hypothesis, the educated guess
A statement that predicts what the test will confess
It has to be falsifiable, that's the crucial trick
If nothing could disprove it, the claim is just a stick
Step four is the experiment, the reality check
Design it so the variable can actually connect
Control groups, isolation, repeat the thing again
One result is nothing, statistics is the friend
(The data comes in)

[Verse 3]
Step five is the analysis, the honest eye on the sheet
Does the hypothesis stand or did it die in the street
Confirmation bias wants to save the prior belief
The method is the discipline that gives the mind relief
Step six is the conclusion, but hold it lightly still
Peer review is the hammer that the community will
Publish, challenge, replicate, let the world test the claim
If it holds across the hands, that's when it earns its name
(The loop starts again)

[Outro]
[Trumpet takes the outro, drums fade]
(Observe)
(The method is alive)
Every question you ask is a vote for reality
[Rhodes holds the final chord]
Track 06 — Broken Reasoning (Logical Fallacies)
Subject: Common logical fallacies — ad hominem, straw man, false dichotomy, appeal to authority, slippery slope, circular reasoning, post hoc, bandwagon, appeal to nature, tu quoque Genre: Bossa Nova / Latin Jazz Why this genre: Fallacies are elegant mistakes — seductive, smooth, and dangerous. Bossa nova is the music of smooth seduction. The ironic pairing lets each fallacy get named, demonstrated, and unmasked in the same breath.
Bossa Nova, Latin Jazz, nylon-string guitar, brushed drums, upright bass walking in a samba pattern, flute lead, subtle vibraphone, female vocal with a sly, knowing, cocktail-party delivery, 102 BPM, key of A minor, Astrud Gilberto meets a philosophy lecture, elegant deception unmasked.

[Intro]
[Nylon guitar plays the samba turnaround, flute enters on the second bar]
(Every mistake sounds convincing)
(That's the whole problem)
The most dangerous arguments are the ones that feel correct

[Verse 1]
Ad hominem attacks the person instead of the claim
You're wrong because you're ugly is an ancient kind of game
The argument still stands or falls on evidence alone
The messenger is never what determines what is known
Straw man builds a weaker version of the thing you said
Then knocks it down in public like it was the real head
If you have to misrepresent the view to win the round
You already lost the argument the moment it was found

[Chorus]
Every fallacy is elegant, every fallacy is smooth
(That's why they work)
Every fallacy is a shortcut around the thing you have to prove
(That's why they work)
Learn to name them, learn to spot them in the wild
(Broken reasoning)
A mind that knows the tricks is a mind that can't be styled

[Verse 2]
False dichotomy gives you only two ways to turn
Love it or leave it, when a dozen options burn
Appeal to authority says the expert says it's true
But experts can be wrong and the evidence is due
Slippery slope predicts a cascade with no proof
One step leads to ruin in the argument's aloof
Circular reasoning is the snake that eats its tail
The premise is the conclusion wearing a different veil

[Verse 3]
Post hoc ergo propter hoc, it happened after, so it caused
Correlation is not causation, let the reasoning be paused
Bandwagon says everyone believes it, so it's right
Popularity is not a substitute for sight
Appeal to nature says if it's natural it's good
Arsenic is natural, and arsenic never should
Tu quoque says you do it too, so your point does not count
The hypocrisy of the speaker doesn't change the amount

[Outro]
[Flute takes the final melodic phrase over guitar and brushes]
(Name them)
(Spot them)
The mind that knows the tricks walks free from the trap
[Guitar holds the final chord]
Track 07 — Slow Collision (Plate Tectonics)
Subject: Plate tectonics, continental drift, fault types, geological timescales Genre: Dub Reggae Why this genre: Plates move at 2–5 cm per year. Dub is the slowest, most patient genre in popular music. The massive reverb tails mimic geological time. The bass is literally the weight of the continents.
Dub Reggae, classic 1970s Jamaica sound, massive spring reverb tails, tape delay throws, deep sub bass, clavinet skanks on the off-beat, horns with heavy echo, minimal drums with a steppers kick pattern, male vocal with a patient, oracular Jamaican-inflected delivery, 72 BPM, key of G minor, King Tubby meets a geology textbook, continental time.

[Intro]
[Deep bass pulse, drums enter with a steppers kick, echo chamber opens on the first word]
(Slow)
(The earth moves slow)
Two centimeters a year and the mountains rise

[Verse 1]
The crust is broken into seven major plates
Floating on the mantle where the molten rock creates
Convection currents moving at the pace of stone
The continents are passengers that cannot stand alone
Pangaea was the supercontinent, a single land
Two hundred million years ago it broke into the sand
Africa and South America were once a single coast
You can see the puzzle pieces where the plates embossed

[Chorus]
(Slow collision)
Every earthquake is a story of the plates at war
(Slow collision)
Every mountain is a handshake at the continental door
(Slow collision)
Every ocean is a gap that opened long ago
(Slow collision)
The earth is always moving even when it seems to slow

[Verse 2]
Divergent boundaries are the rifts where plates pull apart
Mid-ocean ridges where the lava starts the heart
New crust is born where the magma meets the sea
The Atlantic is still growing an inch or so for free
Convergent boundaries are the crashes in the dark
Oceanic under continental, a subduction mark
The Andes rose from Nazca diving under South American stone
Every volcano is a signal of the subduction zone
Continental on continental is the Himalayan way
India crashed into Asia and the Everest came to stay

[Verse 3]
Transform boundaries are the plates that slide past sideways
San Andreas is the famous one, it runs through L.A.
No new crust created and no old crust destroyed
Just friction locking up until the stress can't be avoided
Then the earthquake releases what the patience stored
Seconds of violence for decades of the building toward
The ring of fire is the circle of the Pacific rim
Seventy-five percent of volcanoes living in the hymn

[Outro]
[Horns fade into the reverb tail, bass sustains under the echo]
(Slow)
(The earth moves slow)
But the moving never stops
[Echo trails into silence]
Track 08 — Seventeen Eighty-Nine (The French Revolution)
Subject: French Revolution timeline — Estates General, Bastille, Declaration of Rights, Terror, Napoleon Genre: Protest Folk-Rap hybrid Why this genre: Revolutions need anthems. Folk is the music of the people’s history; rap is the music of compressed narrative. The hybrid mirrors the revolution itself — old forms broken open by new urgency.
Protest Folk-Rap hybrid, acoustic guitar with fingerpicked arpeggios, upright bass, cajón, hand-clap percussion, fiddle interjections, male vocal switching between sung folk chorus and tight rap verses, urgent, historically grounded delivery, 108 BPM, key of D minor, Woody Guthrie meets Lin-Manuel Miranda meets Talib Kweli, history as an urgent dispatch.

[Intro]
[Acoustic guitar arpeggio, cajón enters on the backbeat, fiddle line introduces the melody]
(Seventeen eighty-nine)
(The year the old world cracked)
The people of France picked up the pen and the pitchfork

[Verse 1]
France was broke, the king was Louis the sixteenth
The debt from wars had drained the treasury clean
Three estates divided up the social frame
Clergy, nobles, everybody else, the game was rigged the same
The third estate was ninety-six percent of all the population
But they paid the taxes and they had no representation
Estates General met in May of eighty-nine
The third estate broke away and drew a different line
(National Assembly)

[Chorus]
Liberty, equality, fraternity, or death
(The tricolor rising)
The people of the street had a fire in the chest
(The old regime was dying)
Every revolution ever since that day
(Borrows from the moment)
When the third estate stood up and would not walk away

[Verse 2]
July fourteenth, the Bastille fortress fell
The prison of the king became the people's bell
Women marched to Versailles in October, grain was scarce
Dragged the royal family back to Paris in a hearse of a carriage
Declaration of the Rights of Man was signed in August
All men are born free and equal, the promise had to be discussed
Constitution of ninety-one made a limited king
But the king tried to flee, and the trust could not stand a thing
(Varennes, he was caught)

[Verse 3]
September ninety-two, the Republic was declared
January ninety-three, Louis the sixteenth was bared
To the guillotine at the Place de la Revolution
The head of the king fell and the monarchy's dissolution
Then the Terror came, Robespierre at the wheel
Committee of Public Safety made the guillotine a meal
Thousands of executions in about ten months
Thermidor ended Robespierre with the same kind of stunts
Directory, then the Consulate, then Napoleon's throne
Seventeen ninety-nine the revolution had grown
Into an empire, ironically, a single man
But the ideas never died, they kept crossing every land

[Outro]
[Fiddle takes the final melodic phrase, guitar sustains]
(Liberty)
(Equality)
(Fraternity)
The echoes never stopped, they just changed the tongue
[Guitar holds the final chord]
Track 09 — The Doubling (Compound Interest)
Subject: Compound interest, the rule of 72, exponential growth Genre: Neo-Soul / Future Soul Why this genre: Compound interest is about patience and time — the same qualities neo-soul rewards. The arrangement models the math: each chorus adds a layer so by the final chorus the song has “compounded” into something denser than the first.
Neo-Soul, Future Soul, vintage Fender Rhodes, syncopated drum programming with live feel, melodic bass played on a Moog, layered vocal harmonies that build each chorus, subtle string pads, female lead with a wise, patient, financially literate delivery, 88 BPM, key of B-flat major, Hiatus Kaiyote meets a Vanguard index fund prospectus, exponential growth as a love letter.

[Intro]
[Rhodes chord progression, bass enters, drums slide in on the second bar]
(Time)
(The quiet multiplier)
Money makes a baby and the baby makes a baby

[Verse 1]
Simple interest pays you on the principal alone
Ten percent on a thousand is a hundred every year
Compound interest pays you on the principal and the gain
The hundred from year one starts earning its own name
Year one the thousand turns into eleven hundred clean
Year two the eleven hundred makes a hundred ten, it's seen
Year three the twelve ten makes a hundred twenty-one
The baby has a baby and the babies never done
(The doubling begins)

[Chorus — first time, thin]
Exponential growth is the quietest power in the world
(Patience is the weapon)
The math does the work while you sleep through the night
(Time is the weapon)

[Verse 2]
Rule of seventy-two is the shortcut in your head
Divide the seventy-two by the rate and you have the thread
Seven percent return will double every ten years
Ten percent return will double in about seven clear
A hundred dollars at ten percent for forty years of time
Becomes forty-five hundred without a single extra dime
The first ten years it only doubles to two hundred
But the last ten years it doubles from twenty-two hundred, stunned
(The curve goes vertical)

[Chorus — second time, thicker, strings added]
Exponential growth is the quietest power in the world
(Patience is the weapon)
The math does the work while you sleep through the night
(Time is the weapon)
Every year you wait is a year you cannot buy
(Start now, start small)
The compound wants decades, not a single lucky try

[Verse 3]
Einstein called it the eighth wonder of the world
The ones who understand it earn it, the rest pay it curled
Credit card debt at twenty-two percent will double in three
The compound cuts both ways, it's a mirror you should see
Start at twenty-five with a hundred every month
At seven percent you have a quarter million in the hunt
Start at thirty-five with double, two hundred every month
You end up with less, because the ten years were the front
(Time is the asset)

[Chorus — final time, full harmonies, everything in]
Exponential growth is the quietest power in the world
(Patience is the weapon)
The math does the work while you sleep through the night
(Time is the weapon)
Every year you wait is a year you cannot buy
(Start now, start small)
The compound wants decades, not a single lucky try
Money makes a baby and the baby makes a baby
(The doubling never stops)
The quiet multiplier is the one that makes you free

[Outro]
[Rhodes solo over sustained strings, drums drop to half-time]
(Time)
(Start today)
The best year to plant the tree was twenty years ago
The second best year is now
[Rhodes holds the final chord]
Track 10 — Condensation Dream (The Water Cycle)
Subject: The water cycle — evaporation, transpiration, condensation, precipitation, collection, infiltration Genre: Trip-Hop Why this genre: Trip-hop is atmospheric, watery, circular. Massive Attack and Portishead built whole records on the feeling of things rising and falling in slow motion. Every stage of the cycle can be represented by a different sonic texture that appears and disappears like water changing state.
Trip-Hop, atmospheric and cinematic, big downtempo drum breaks, heavy filtered bass, swirling ambient pads, distant theremin-like lead, occasional vinyl crackle and rain samples, female lead vocal with a haunted, ethereal, meteorological delivery, 82 BPM, key of E-flat minor, Portishead meets Massive Attack meets a nature documentary, water as atmosphere.

[Intro]
[Rain sample, ambient pad swells, drum break drops on the third bar, bass slides underneath]
(The cycle never ended)
(It just changed its shape)
Every drop of water you have ever seen has done this before

[Verse 1]
Evaporation lifts the water from the surface of the sea
The sun is the engine and the heat sets it free
Molecules break the bond that held them in the liquid state
Rising invisible into the atmospheric gate
Transpiration does the same from the leaves of every plant
A forest is a river that forgot it had to slant
Upward through the stomata, through the xylem, through the bark
Every tree is evaporating slowly in the dark
(The rising)

[Chorus]
Every drop has done this a thousand thousand times
(Rising and falling)
Every drop has been a cloud and a river and the brine
(Rising and falling)
The water in your glass was once inside a dinosaur
(The cycle never ends)
Condensation dream is the atmosphere in store

[Verse 2]
Condensation is the moment when the vapor meets the cold
The water has to choose a form, the cloud begins to fold
Around the tiny particles of dust and ash and salt
Nucleation gives the droplet something to exalt
Billions of droplets suspended in the sky
A cloud is just a river that forgot how to lie
Down on the surface where the gravity demands
The droplets grow by merging until the weight expands
(The falling)

[Verse 3]
Precipitation is the gravity reclaiming what was lent
Rain when it's warm enough, snow when the cold is spent
Sleet, hail, graupel, freezing rain, the forms are many
The water chooses based on the layers of the canopy
Collection is the rivers and the lakes and the sea
The aquifers underneath, the glaciers slowly
Infiltration soaks the ground where the roots will drink
Runoff carries sediment to the river's brink
And somewhere the sun is heating up a different surface
Lifting another molecule for another verse
(The cycle restarts)

[Outro]
[Rain samples return, drums drop out, theremin lead takes the final phrase over pads]
(Rising)
(Falling)
The water remembers everything it has ever been
Every drop is ancient and every drop is new
[Pads hold the final chord, rain continues into silence]
Choose Your Knowledge Compression Tool
Select the tier that matches your music production and curriculum design workflow:
Free Field Summary
Knowledge Compression Quick-Start Card
The article’s core principles and structure condensed onto a 2-page field reference card for quick prompt drafting and lesson planning.
$0.00 direct download
Genre-as-Carrier-Wave Shape Matching Law
Boom-bap, Liquid D&B, Gospel, Dub, Bossa Nova Specs
The intensive AI version: drop into ChatGPT or Claude to run interactive subject audits, fact-to-bar metric encoding, tag syntax audits, and retention tests.
$17.00 one-time
5 Executable AI Routines (/carrier-wave, /knowledge-to-bars…)
All payments securely processed by Square • Apple Pay, Google Pay & Major Cards Accepted
Run the Experiment
If you build any of these, I want to know how they land. The real question this project is trying to answer isn’t whether AI can generate a listenable track — it obviously can. The question is whether the format works. Does the song actually teach? Does a listener who hears “Eight Stages of Fire” once remember the Krebs cycle a week later better than someone who read a textbook passage of equivalent length? I don’t know yet. That’s why the prompts are public.
Paste one in. Generate the track. Play it for someone who doesn’t know the subject. Ask them a week later what they remember. Tell me what happened.
This is a working node in an ongoing experiment at Tygart Media about whether the boundaries between content, teaching, and entertainment are real or just inherited assumptions about how knowledge has to move.
Updated Oct 31, 2026 — added the free knowledge compression quick-start card, prompt pack, and Internal Transit Authority bot book downloads to this guide.
The Signal — Tygart Media's weekly brief. What we actually ran, what it measured, and what it means for a restoration shop.