Update — May 15, 2026: Two things have shifted since this article was originally written. First, Claude Opus 4.7 (released April 2026) is now Anthropic’s most capable model with a 1M token context window at standard pricing — which changes the calculus for any task involving large documents or long-form reasoning, where Claude was already the stronger choice. Second, on May 13, 2026, Notion shipped the Notion Developer Platform with Claude as a launch partner, which means the comparison is no longer just “Notion AI vs Claude Projects” — Claude can now operate natively inside Notion via the External Agents API. For the platform launch breakdown, see Notion Developer Platform Launch (May 13, 2026). For the current Claude model lineup, see Claude Models Roadmap May 2026. For how this fits into a working stack, see The Three-Legged Stack.
The 60-second version
Notion AI and Claude Projects both let you bring custom context to AI. The difference is what surrounds the AI. Notion AI lives inside a workspace with databases, integrations, schedules, and a team. Claude Projects lives inside a conversation with files, instructions, and the conversation history. For ongoing operational work where the AI needs to be part of how you work, Notion AI fits. For deep focused work where conversation quality is the primary value, Claude Projects fits. Many operators use both.
When Notion AI wins
When Notion AI wins.
Persistent operational context across the workspace
Custom Agents on schedules
Database fluency and Autofill
Native integrations (Slack, Mail, Calendar)
Team collaboration patterns
Mobile and cross-device access
When Claude Projects wins
When Claude Projects wins.
Deep, focused task work
Strong conversation continuity within a topic
Specific instruction sets per project
File-heavy reference contexts (code, research, large documents)
When conversation quality (Claude’s strength) matters more than integration
The stacking pattern
The stacking pattern.
The pattern many operators use:
– Notion AI for the ongoing rhythm of work — agents, databases, daily operational synthesis
– Claude Projects for “I need to deeply work on X” sessions — heavy reasoning, complex code, large reference contexts
The two don’t conflict; they cover different time horizons. Notion AI is always-on background. Claude Projects is intentional focused sessions.
What Claude Projects does that Notion AI doesn’t
File upload context with longer effective memory in-conversation
More flexible custom instructions per project
Conversation continuity that’s purely Claude-native (no model-switching)
What Notion AI does that Claude Projects doesn’t
Workspace databases and Autofill
Scheduled agent execution
Native integrations beyond conversation
Multi-user collaboration on the same context
Where comparisons go wrong
1. Treating them as direct substitutes. They overlap but serve different shapes of work. 2. Picking based on raw conversation quality alone. That favors Claude. But conversation quality isn’t the whole product. 3. Picking based on integration breadth alone. That favors Notion. But integration matters more for some workflows than others.
What to read next
Notion AI vs ChatGPT, Notion AI vs Gemini, Editorial Surface Area, Custom Agents vs Basic.
You don’t have to pick the model anymore. Notion 3.2 added auto-selection, which routes each request to the best-fit model from the available pool — currently including Claude Opus 4.7, GPT-5.2, and Gemini 3. Simple tasks (rewrites, summaries, quick drafts) go to faster models. Complex tasks (multi-step reasoning, long-context analysis, tool-heavy agent runs) go to more capable ones. You can override the selection per request, but the default behavior is “let Notion pick” — and for most workflows, that’s the right call.
Why auto-selection matters
Why auto-selection matters.
Three reasons it’s a meaningful shift: 1. You stop being a model-picker. Before auto-selection, getting good output required knowing which model handled which task best. That’s expert knowledge most users don’t have. Auto-selection internalizes that knowledge. 2. Cost-performance balance happens automatically. Faster models are cheaper to run; capable models are more expensive. Notion’s auto-selection routes simple work to cheap models and reserves expensive models for tasks that need them. After May 4, when credits start metering Custom Agent work, this matters financially. 3. Model diversity becomes a feature, not friction. Different models have different strengths. Claude is consistently strong on long-form writing and tool use. GPT is strong on broad reasoning. Gemini is strong on multimodal and certain analytical tasks. Auto-selection uses the right tool without forcing you to know which is which.
When to override the auto-selection
When to override the auto-selection.
Three cases where manual model choice still wins: 1. You’ve measured a specific preference. If you’ve tested the same task across all three models and found one consistently better for your use case, lock to that one. Auto-selection optimizes for the average user; you may not be the average user. 2. You’re working in a domain with a clear model strength. Long-form editorial work where Claude’s prose quality is meaningfully better. Code work where GPT’s tool use feels more natural. Visual analysis where Gemini’s multimodal handles your case better. 3. Reproducibility matters. Auto-selection means today’s request might use Claude and tomorrow’s might use GPT. If you need consistent voice or behavior across runs, lock the model.
For everything else, auto-selection is fine. Stop optimizing the optimizer.
What auto-selection isn’t
It isn’t infinite model access. The pool is curated by Notion. You don’t get every model on the market. You get the ones Notion has integrated and validated for the platform.
It also isn’t a replacement for model expertise if you’re a developer building on the API. When you build with Workers or skills via the API, you may want explicit model selection because reproducibility matters more there than in interactive use.
How to verify auto-selection is working
How to verify auto-selection is working.
A 5-minute test:
1. Open a page with substantive content (a project doc, an article, a meeting transcript)
2. Run three different prompts: a quick rewrite, a complex synthesis, and a multi-step extraction
3. Look at the output quality for each
4. If all three feel right for the task, auto-selection is doing its job
5. If any feel off — outputs that are too brief or too verbose, missing the task’s complexity — that’s where to consider manual override
Why Claude Opus 4.7 in particular matters
The Claude Opus 4.7 addition is worth noting separately. Anthropic’s latest uses fewer tokens (cheaper to run), makes 3x fewer tool errors (more reliable for agents that call Workers), and handles complex workflows better. For Notion specifically, that means agents that previously hit edge cases when chaining multiple skills or Workers now have a more reliable backbone.
If you’re heavy into Custom Agents and Workers, Opus 4.7 in the rotation is the quiet upgrade that makes everything more dependable.
What to read next
Corpus follow-ups: Mobile AI in Notion (where auto-selection also runs), Custom Agents foundation piece (where model selection has cost implications), and the comparison articles (Notion AI vs ChatGPT, Claude Projects, Gemini for Workspaces).
For the past several weeks I have been running a live experiment on helpnewyork.com: using Claude-in-Chrome to interrogate Google’s Analytics Advisor inside GA4, session by session, until I had a complete behavioral profile of every AI platform sending traffic to the site.
What came out of it is not what I expected. I expected traffic data. I got a content strategy.
The Setup
The setup for tracking AI referral traffic.
Claude-in-Chrome is Anthropic’s browser extension that lets Claude operate directly inside your browser — reading pages, clicking elements, filling inputs, capturing output. Analytics Advisor is Google’s Gemini-powered chat interface built into GA4, available to English-language accounts since December 2025. It answers natural language questions about your property data with charts, tables, and narrative interpretation.
The combination is unusual. You are using one AI (Claude) to systematically interrogate another AI (Gemini) about your site’s data, then synthesizing what comes back into strategy. The token budget for the heavy data reasoning stays inside Google’s infrastructure. Claude handles the query architecture, the capture protocol, and the synthesis.
I ran four structured sessions across two sittings, using a specific sequence of queries built to extract progressively deeper signal. Session 1 established baseline traffic. Session 2 closed gaps and confirmed AI referral data existed. Session 3 was the AI deep dive. Session 4 was velocity and geography.
What the Data Showed
Three AI platforms were sending meaningful traffic to helpnewyork.com during the 28-day window: ChatGPT, Claude, and Copilot. The behavioral profiles were so different from each other that treating them as a single “AI traffic” segment would have produced wrong conclusions.
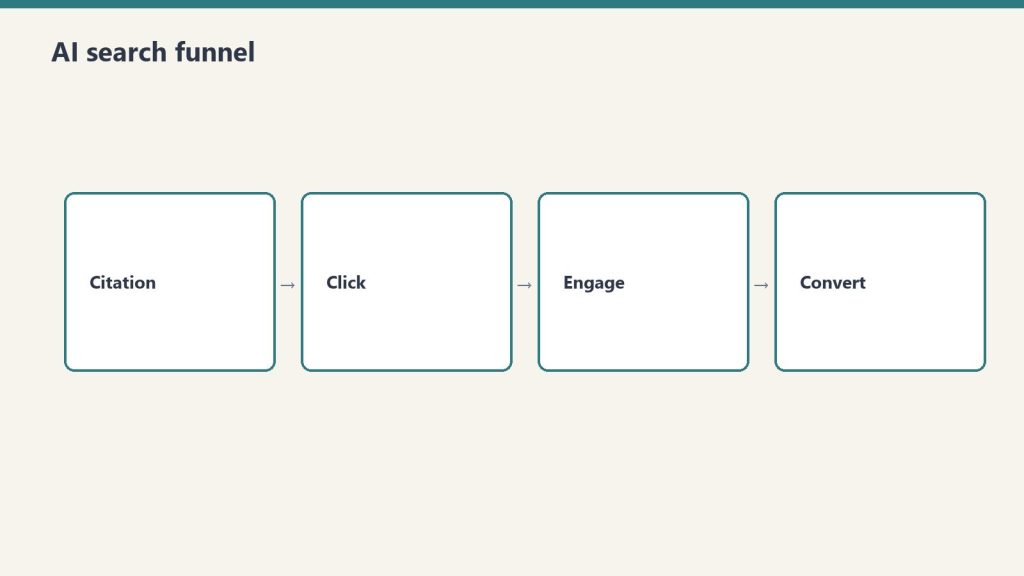
Claude.ai traffic showed a 64% engagement rate and an average session duration of over 3 minutes. The dominant landing page was an NYC Summer Internships guide, accounting for over 60% of all Claude sessions. Geographic concentration was academic: Ithaca (Cornell), State College (Penn State), Washington DC. The users arriving from Claude were reading to act — they needed specific information, they found it, they stayed.
ChatGPT traffic showed a 21% engagement rate and an average session of 24 seconds. The top landing page was a cherry blossom guide. The users were fact-grabbing: they asked ChatGPT where to see cherry blossoms in New York, got a citation, clicked through, confirmed the location, and left. The content served its purpose in under half a minute.
Copilot traffic was between the two: 46% engagement, roughly 2-minute sessions, desktop-heavy, concentrated in New York’s suburbs. The top pages were civic services — SNAP benefits, tenant rights, transit discounts. These users were in planning mode, researching before they decided or applied.
The Finding That Reframes GEO
The finding that reframes GEO.
The cross-AI page overlap query was the most important one in the entire four-session arc. I asked Analytics Advisor which pages appeared in the top landing pages for more than one AI source. Only one real content page appeared in all three: the cherry blossom guide.
The obvious interpretation is that the cherry blossom guide was “AI-optimized.” The actual interpretation, once you look at the full traffic breakdown, is the opposite. Bing drove 59 sessions to that page. Yahoo drove 16 at 75% engagement and a 3-minute 46-second average session. DuckDuckGo drove 35. The combined AI traffic to that page was 32 sessions — 17% of total. The AI platforms were citing it because traditional search engines had already validated it as the highest-quality answer in the index.
AI citations are downstream of search quality, not upstream. The path to getting cited by ChatGPT, Claude, and Copilot is not to optimize for AI retrieval patterns. It is to build pages that win on Bing and Yahoo with enough depth that AI models treat them as authoritative sources. The GEO play is a traditional SEO play with better content.
The Content Strategy That Follows
The content strategy that follows.
Once you have the per-AI behavioral profiles, you have a content variant framework. The same article can be written in three structural architectures, each tuned to how one AI model retrieves and presents information.
The Claude variant is dense and process-oriented. Headers, eligibility criteria, numbered steps, official program names. Built for the student or researcher who arrived with a specific question and needs a complete answer they can act on.
The ChatGPT variant is a scannable list. Named items, one specific detail per item, direct answer in the first two sentences. Built for the user who will spend 24 seconds on the page and needs the answer immediately or they’re gone.
The Copilot variant is comparison and planning framing. What to know before you go, Option A versus Option B, cost context, logistics. Built for the desktop user doing research before they make a decision.
The core article is the same. The architecture is different. The AI that cites you depends on which structure you used.
The Methodology Is the Product
The query sequence I developed across these four sessions is a repeatable extraction methodology. It works on any GA4 property with Analytics Advisor enabled. The intelligence it produces — per-AI audience profiles, geographic signals, velocity trends, cross-AI content overlap — is not available through DataForSEO, SpyFu, or GSC. It requires Gemini’s reasoning layer operating on top of your property data, orchestrated by a structured query architecture.
I have packaged the complete methodology as a downloadable kit: the full query architecture across all four sessions, the capture protocol, the content variant framework, and the flags to escalate before your next content sprint. It is called Books for Bots: GA4 AI Referral Audit Kit.
The free version covers Session 3 alone — the AI deep dive queries that surface your ChatGPT, Claude, and Copilot traffic split. That alone will show you something most site owners have never seen: which AI is sending them traffic, to which pages, and how engaged those users actually are.
The full kit covers all four sessions and includes the content variant framework that translates the behavioral data into a writing system.
Both are available at tygartmedia.com. What you do with the data after that is yours.
Anchor fact: Custom Agents are available on Business and Enterprise plans only. They run autonomously on triggers or schedules, can work for up to 20 minutes per task across hundreds of pages, and starting May 4, 2026, consume Notion Credits at $10 per 1,000.
Do you need Notion Custom Agents or is basic Notion AI enough?
Basic Notion AI handles inline drafting, summaries, and reactive prompts within a page. Custom Agents add proactive execution — running on schedules or triggers, working autonomously for up to 20 minutes, and using skills and Workers. Choose Custom Agents only if you have recurring autonomous workflows that justify Business-plan pricing and Notion Credit consumption.
The 60-second version
Most operators don’t need Custom Agents. They think they do because the marketing makes Custom Agents sound essential, but the honest answer is that basic Notion AI plus standard agent prompts cover most knowledge-work needs. Custom Agents earn their cost only when you have specific, repeating, autonomous work — things that run on a schedule or trigger without you starting them. If you don’t have that pattern in your workflow, you’re paying for capability you won’t use.
The honest comparison
The honest comparison.
Basic Notion AI (included on Plus, Business, Enterprise plans):
Custom Agents (Business and Enterprise plans only):
Everything above, plus:
Runs on schedules or triggers without prompting
Can work autonomously for up to 20 minutes per task
Spans hundreds of pages in a single run
Skills can be attached for repeatable workflows
Workers integration (developer preview) for code execution
Can integrate with Calendar, Mail, Slack at agent level
After May 4, 2026: consumes Notion Credits at $10/1000
When Custom Agents are worth it
When Custom Agents are worth it.
Five workflow patterns where Custom Agents pay off:
1. Recurring deliverables. Weekly status reports, monthly board prep, daily standups. If you produce the same shape of document on a schedule, an agent that runs Friday at 4 PM and drops the draft in your inbox is worth real money in time saved.
2. Continuous database enrichment. A CRM that needs new leads scored, categorized, and routed within minutes of arrival. A content database that needs incoming articles tagged and summarized. An ops database that needs items checked for SLA breaches.
3. Cross-source synthesis on demand. “Pull everything from the last two weeks across Slack, Calendar, and our project pages and tell me what’s at risk.” This is a 20-minute autonomous task that would take a human two hours.
4. Multi-step workflows with handoffs. Triage incoming → route to owner → draft response → flag exceptions. The chain is what makes it agent work, not assistant work.
5. Off-hours and overnight work. If you’d benefit from work happening while you sleep, agents are the only Notion layer that can do it. Reactive AI sits idle until you arrive.
When basic Notion AI is enough
When basic Notion AI is enough.
Most knowledge workers fit here:
Solo writers and researchers who need help drafting and summarizing
Teams of fewer than 10 where work is mostly real-time collaborative
Workflows where the AI is occasional, not scheduled
Anyone on Plus plan (Custom Agents aren’t available anyway)
Anyone whose AI usage is “I ask, it answers” — that’s reactive, not agentic
If you’re in this group, upgrading to Business for Custom Agents is paying for capacity you won’t use. Stay with basic AI and revisit when the workflow pattern changes.
The cost calculus after May 4
Before May 4, 2026, Custom Agents are free to try on Business and Enterprise. After, every run consumes credits at $10 per 1,000. Real numbers:
A simple agent run (single-page summary): typically a handful of credits — pennies
A complex multi-step run (synthesis across many pages, multiple skills chained): can run into the dozens or hundreds of credits — measurable dollars
A daily scheduled agent that runs 30 days/month at moderate complexity: budget low tens of dollars per agent per month
Math gets serious when you have many agents running daily. A workspace with 10 active Custom Agents can easily consume hundreds of dollars per month in credits on top of Business-plan seat fees. That’s the ROI conversation that turns “I’m experimenting with agents” into “I run a small fleet on a budget.”
The decision framework
Walk yourself through these four questions:
Do you have recurring work on a schedule? No → basic AI is fine.
Are you on Business or Enterprise? No → Custom Agents aren’t available. Upgrade or stay with basic.
Does the time saved per agent run, multiplied by frequency, exceed the credit cost? No → basic AI plus manual prompts is cheaper.
Are you willing to manage the credit pool monthly? No → don’t take on the operational overhead.
If all four are yes, Custom Agents earn their place. If any is no, basic Notion AI is the right call.
Lineup currency (Sept 2026, verified): Sonnet 5 ($2/$10), Opus 5.5 ($4/$20), Haiku 4.5 ($1/$5), Fable 5.1 ($10/$50). Legacy (still listed): Opus 4.8 ($5/$25), Sonnet 4.6 ($3/$15). Prior note (superseded): Prior flagship claim: Claude Opus 4.8 (claude-opus-4-8). Prior models claim: Opus 4.8 · Sonnet 4.6 · Haiku 4.5. Claude Opus 4.8 (claude-opus-4-8) was claimed current as of April 16, 2026. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →
Claude Opus 4.8 vs GPT-5 vs Gemini 2.5 Pro: Head-to-Head (June 2026)
Attribute
Claude Opus 4.8
GPT-5
Gemini 2.5 Pro
Developer
Anthropic
OpenAI
Google DeepMind
API ID
claude-opus-4-8
gpt-5
gemini-2.5-pro
Context window
1M tokens
128K tokens
1M tokens
Input price (per MTok)
$5.00
$15.00
$3.50
Output price (per MTok)
$25.00
$75.00
$10.50
Multimodal
Text + vision
Text + vision + audio
Text + vision + audio
Best for
Long-context reasoning, coding, writing
Broad capability, tool use
Google ecosystem, long context
Prices verified June 9, 2026 from official platform documentation. GPT-5 pricing from platform.openai.com. Gemini 2.5 Pro pricing from ai.google.dev.
The short verdict
The short verdict.
Best for agentic coding and long-horizon engineering: Opus 4.8.
Best for single-turn function calling and ecosystem breadth: GPT-5.
Best for multimodal input volume and long-context retrieval: Gemini 2.5 Pro.
Cheapest at the frontier: Gemini 2.5 Pro. Most expensive: GPT-5.
If you can only pick one for general knowledge work in June 2026: Opus 4.8.
The full reasoning is below. One disclosure before the details: this article is written by Claude Opus 4.8. I am one of the models being compared. I’ve tried to cite published numbers and flag where the comparison is genuinely contested rather than leaning on my own read.
Pricing as of April 16, 2026
Model
Input (standard)
Output (standard)
Long-context tier
Context window
Claude Opus 4.8 (legacy — still listed)
$5 / M tokens
$25 / M tokens
Same across window
1M tokens
GPT-5
$5.00 / M tokens
$15 / M tokens
$5 / $22.50 over 272K
1M tokens (272K before surcharge)
Gemini 2.5 Pro
$2 / M tokens
$12 / M tokens
$4 / $18 over 200K
1M tokens (some listings cite 2M)
Takeaways:
– Gemini 2.5 Pro is the cheapest per token at the frontier — 7.5× cheaper on input than Opus 4.8 and 2× cheaper than GPT-5 at standard context.
– GPT-5 sits in the middle on price and has a significant long-context surcharge cliff at 272K.
– Opus 4.8 is the most expensive per token, with no long-context surcharge.
– All three now have 1M-class context windows, but Opus 4.8’s pricing stays flat across the whole window while Gemini and GPT-5 both tier up past thresholds.
Tokenizer caveat: Opus 4.8 uses a new tokenizer that produces up to 1.35× more tokens per input than Opus 4.6 did, depending on content type. Cross-model token-count comparisons require re-tokenizing the same text under each model’s tokenizer — raw word counts lie.
Benchmarks, with the caveats included
Anthropic, OpenAI, and Google all publish benchmark numbers. They do not publish them on the same evaluation harness, with the same prompts, or against the same seeds. Treat the following as directional, not definitive.
Agentic coding (long-horizon, multi-file):
– Opus 4.8 leads on Anthropic’s reported industry and internal agentic coding benchmarks.
– GPT-5 is competitive on single-turn function calling and tool use. Roughly 80% on SWE-bench Verified at launch.
– Gemini 2.5 Pro scored 80.6% on SWE-bench Verified at launch — essentially tied with GPT-5.
Multidisciplinary reasoning (GPQA Diamond and similar):
– Opus 4.8 leads on Anthropic’s comparisons.
– GPT-5 and Gemini 2.5 Pro are close. Gemini reports 94.3% on GPQA Diamond.
Scaled tool use and agentic computer use:
– Opus 4.8 leads on Anthropic’s reported benchmarks.
– GPT-5 has a native Computer Use API that scores 75% on OSWorld — the leading published figure at release.
– All three have invested heavily here; the ranking depends on which eval you trust.
Vision (document understanding, dense-screenshot extraction):
– Opus 4.8’s jump from 1.15 MP to 3.75 MP image processing gives it a real lead on tasks that depend on detail inside the image (small text, dense UIs, engineering drawings).
– Gemini 2.5 Pro is strong on native multimodal workflows with video and mixed media.
– GPT-5 is solid but not leading on either axis.
Long-context retrieval:
– All three now have 1M-class context windows.
– Gemini 2.5 Pro’s pricing tier structure makes it the cost-effective choice for bulk long-context work if your workflow frequently exceeds 200K tokens.
– Opus 4.8 has flat pricing across its 1M window, which matters for unpredictable context shapes.
– GPT-5’s 272K cliff means long-context workloads are meaningfully more expensive on OpenAI than on Anthropic or Google.
Specialized coding benchmarks:
– GPT-5.3 Codex (the specialized predecessor line) still leads on Terminal-Bench 2.0 and SWE-Bench Pro on some scores. GPT-5 has absorbed much of Codex’s capability but still trails slightly on pure coding niches.
– Gemini 2.5 Pro has notable strength on creative coding and SVG generation.
– Opus 4.8 is strongest on agentic and multi-file coding specifically.
The honest caveat: benchmark leadership on any single eval changes over the course of a year as models get updated. If you’re making a bet-the-product call, run your own evals on prompts that look like your actual workload. The published benchmarks are a screening tool, not a decision tool.
How they differ in behavior, not just benchmarks
How they differ in behavior, not just benchmarks.
Opus 4.8 — the engineering-minded generalist.
Tends toward thoroughness over speed. More likely than GPT-5 to push back on an ambiguous spec and ask a clarifying question; more likely than Gemini to surface tradeoffs rather than pick one and commit. Strong at long-horizon tasks where state matters. Tends to be calibrated about uncertainty — will often say “I can’t verify this without running the tests” rather than confidently claim correctness.
GPT-5 — the product-native operator.
Tends toward action over deliberation. Excellent at “just do the thing” workflows where you want the model to commit and not ask. Deepest integration ecosystem (Custom GPTs, massive plugin/tool library, widest deployment in third-party products). Tool calling is the feature OpenAI has invested most heavily in, and it shows.
Gemini 2.5 Pro — the multimodal long-context specialist.
Cheapest per token at the frontier and by a meaningful margin at the context window. Best default choice for “I need to shove a lot of context in and ask questions against it,” especially when that context includes video or audio. Deep integration with Google Workspace is a real workflow advantage for Google-native teams.
None of these are absolute; all three models handle general tasks well. These are behavioral tendencies, not capability ceilings.
“Choose X if” decision framework
Choose X if — decision framework.
Choose Claude Opus 4.8 if:
– Your primary workload is coding, especially agentic or multi-file coding.
– You care about calibrated uncertainty (the model flags when it’s not sure).
– You’re using or planning to use Claude Code for engineering work.
– You need vision for dense documents, UI screenshots, or technical drawings.
– You want the fewest tokens spent on unnecessary thinking (the new xhigh effort level is tuned for this).
Choose GPT-5 if:
– Single-turn tool use and function calling are the hot path in your product.
– You need the broadest ecosystem of third-party integrations right now.
– Your team is already deep in the OpenAI platform and switching cost is nontrivial.
– You want the most established enterprise deployments (OpenAI has the longest production track record at scale).
Choose Gemini 2.5 Pro if:
– You’re price-sensitive and running high-volume workloads.
– You need 1M+ token context as the default, not as an add-on.
– Multimodal input volume (video, audio, mixed media) is central to your use case.
– Your team is deep in Google Cloud or Workspace.
Use multiple if:
– You’re doing serious AI product work. Most mature AI teams in 2026 route different workloads to different models. A common pattern: Opus 4.8 for code generation and agent orchestration, Gemini 2.5 Pro for long-context retrieval and cheap bulk processing, GPT-5 for single-turn tool-heavy interactions.
Where this comparison will change
The frontier is moving. Three things to watch over the next six months:
1. Claude Mythos Preview. Anthropic publicly acknowledged that Mythos outperforms Opus 4.8 on most of the benchmarks in the 4.7 release post. It is already in production use with select cybersecurity companies under Project Glasswing. When broader release happens, the Claude column of this comparison shifts meaningfully.
2. GPT-5.5 / GPT-6. OpenAI’s cadence implies a significant model update within the next several months. The pattern over the past year has been incremental 5.x releases; a ground-up generation shift would reset the comparison.
3. Gemini 3.5 / 4. Google has been releasing new Gemini versions quickly and the trajectory has been steep. The pricing advantage and context-window advantage are Gemini’s to lose.
None of these are speculation-free predictions. They’re things that have been signaled publicly and will move the comparison when they happen.
Frequently asked questions
Is Claude Opus 4.8 better than GPT-5?
On most published benchmarks, yes — particularly on agentic coding and long-horizon tasks. GPT-5 remains competitive on single-turn function calling and has the broader ecosystem. “Better” depends on the workload.
Is Gemini 2.5 Pro cheaper than Opus 4.8 (legacy — still listed)?
Significantly. At $2/$12 per million input/output tokens vs. Opus 4.8 (legacy — still listed)’s $5/$25
Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.
, Gemini is 60% cheaper on input and 52% cheaper on output before tokenizer differences. At scale this is a material cost gap.
Which model has the biggest context window?
All three now have 1M-class context windows. Some Gemini 2.5 Pro documentation cites a 2M window. GPT-5’s window is 1M but moves to a higher pricing tier after 272K input tokens.
Which model is best for coding?
Opus 4.8 leads on agentic and long-horizon coding benchmarks. GPT-5 is close on single-turn coding. Gemini 2.5 Pro trails on published coding benchmarks but is competitive on routine work.
Which model should I use for my startup?
Most mature teams route workloads to multiple models. If you’re just starting and need to pick one, Opus 4.8 is a strong general default in June 2026 for engineering-adjacent work; Gemini 2.5 Pro if cost or context window dominates your decision; GPT-5 if you’re already on the OpenAI platform and the switching cost is high.
Does Claude Opus 4.8 support function calling?
Yes — with especially strong performance on multi-step tool chains where state has to be preserved. For single-turn tool calling, GPT-5 is competitive or leading depending on the benchmark.
Related reading
Full Opus 4.8 feature set: Claude Opus 4.8 — Everything New
Opus 4.8 for coding specifically: xhigh, task budgets, and the 13% benchmark lift
The Mythos angle: why Anthropic admitted Opus 4.8 is weaker than an unreleased model
Published April 16, 2026. Article written by Claude Opus 4.8 — yes, one of the models being compared. Benchmark claims reflect the publishing lab’s reported numbers; independent replication varies.
Frequently Asked Questions
Is Claude Opus 4.8 better than GPT-5?
It depends on the task. Claude Opus 4.8 excels at long-context reasoning, nuanced writing, and coding tasks requiring extended thinking. GPT-5 has broader multimodal capabilities including audio. For pure text reasoning and large-document analysis, Claude Opus 4.8’s 1M token context gives it a significant advantage. GPT-5 is more expensive at $15/$75 per million tokens vs Opus 4.8’s $5/$25.
How does Claude Opus 4.8 compare to Gemini 2.5 Pro?
Both Claude Opus 4.8 (legacy — still listed) and Gemini 2.5 Pro support 1M token context windows. Gemini 2.5 Pro is cheaper at $3.50/$10.50 per million tokens vs Opus 4.8 (legacy — still listed)’s $5/$25. Claude Opus 4.8 (legacy — still listed) generally rates higher on reasoning and coding benchmarks. Gemini 2.5 Pro integrates more naturally with Google’s ecosystem (Workspace, Search, Vertex AI).
Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.
Which AI model is best for coding in 2026?
Claude Opus 4.8 and Claude Sonnet 4.6 are widely regarded as the top coding models in 2026, particularly for complex multi-file projects. Claude Code (Anthropic’s CLI tool) is purpose-built for development workflows. GPT-5 is also strong for coding. Gemini 2.5 Pro integrates well with Google Cloud development workflows.
What is the cheapest frontier AI model in 2026?
Claude Haiku 4.5 ($1/$5 per MTok) and Gemini 2.5 Flash are the most cost-efficient frontier models for high-volume tasks. For flagship-tier capability, Gemini 2.5 Pro ($3.50/$10.50) is cheaper than Claude Opus 4.8 (legacy — still listed) ($5/$25) or GPT-5 ($15/$75). The right choice depends on task complexity and volume.
Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.
Is GPT-5 worth the higher price vs Claude Opus 4.8 (legacy — still listed)?
For most text and coding workloads, no. Claude Opus 4.8 (legacy — still listed) at $5/$25
Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.
per MTok delivers comparable or better results than GPT-5 at $15/$75 per MTok. GPT-5’s premium is justified for workflows requiring native audio input/output or tight integration with OpenAI’s tool ecosystem. For long-context document analysis, Opus 4.8’s 1M context at lower cost is a clear win.
Which model should I use for my business in 2026?
For general business writing and analysis: Claude Sonnet 4.6 (legacy — still listed) ($3/$15) or Gemini 2.5 Pro ($3.50/$10.50). For complex reasoning and large documents: Claude Opus 4.8 (legacy — still listed) ($5/$25). For high-volume, cost-sensitive workloads: Claude Haiku 4.5 ($1/$5). For Google Workspace integration: Gemini 2.5 Pro. For OpenAI ecosystem lock-in: GPT-5.
Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.
Direct Answer (August 2026): Choose Microsoft Copilot ($30/user/mo) for native Office 365 app integration (Word, Excel, Outlook, Teams, SharePoint). Choose Claude ($20/mo Pro / $20–$100 Team) for superior code architecture, long-context document analysis (200k tokens), artifact creation, and custom MCP integrations.
Claude AI · Fitted Claude
Claude and Microsoft Copilot are both used for professional AI assistance, but they’re fundamentally different products solving different problems. Copilot is an AI layer built into the Microsoft 365 ecosystem — Word, Excel, PowerPoint, Teams, Outlook. Claude is a standalone AI model built for reasoning, analysis, and flexible integration. Choosing between them depends almost entirely on what you’re trying to do and where you work.
Short version: If you’re deeply embedded in Microsoft 365 and want AI assistance inside Word, Excel, and Teams — Copilot is the right tool. If you need advanced reasoning, long-document analysis, custom integrations, or you’re not primarily a Microsoft shop — Claude is stronger.
Claude vs Microsoft Copilot: Head-to-Head
Capability
Claude
Microsoft Copilot
Edge
Microsoft 365 integration
Via MCP connectors
✅ Native (Word, Excel, Teams)
Copilot
Context window
1M tokens (Sonnet/Opus)
128K tokens
Claude
Reasoning quality
✅ Stronger
Good (GPT-4o backend)
Claude
Writing quality
✅ Stronger
Good
Claude
Image generation
❌ Not included
✅ DALL-E 3 (Copilot Pro)
Copilot
Email access (Outlook)
Via Gmail MCP connector
✅ Native Outlook access
Copilot (for Outlook users)
Custom integrations
✅ Any API via MCP
Primarily M365 ecosystem
Claude
Non-Microsoft tools
✅ Flexible
Limited
Claude
Enterprise compliance (SSO, audit)
✅ Via Claude Enterprise
✅ Via Microsoft 365 governance
Tie — different ecosystems
Consumer pricing
Free tier + $20/mo Pro
Free tier + $20/mo Copilot Pro
Roughly equal
Agentic coding
✅ Claude Code
✅ GitHub Copilot (separate product)
Both — different tools
Not sure which to use?
We’ll help you pick the right stack — and set it up.
Tygart Media evaluates your workflow and configures the right AI tools for your team. No guesswork, no wasted subscriptions.
Microsoft 365 native integration. This is Copilot’s core advantage and it’s meaningful. Copilot lives inside Word, Excel, PowerPoint, Teams, and Outlook. It has native access to your Microsoft Graph data — emails, calendar, documents, meetings — and can surface relevant context from your organization’s data without you needing to copy and paste anything. If you’re working inside these applications all day, Copilot is frictionless.
Image generation. Copilot Pro includes DALL-E 3 image generation. Claude doesn’t generate images in its web interface. For workflows that combine writing and visual creation, Copilot Pro has a functional advantage.
Existing Microsoft governance. For organizations already using Microsoft Purview, Intune, and Entra ID for compliance, Copilot inherits that existing governance framework — no new vendor relationship or separate compliance work required.
What Claude Does Better
Context window. Claude’s 1M token context window is roughly 8x Copilot’s 128K. For analyzing large document stacks, lengthy contract portfolios, or extended research contexts, Claude processes significantly more at once.
Reasoning and writing quality. Copilot uses GPT-4o as its backend — capable, but Claude’s reasoning on complex tasks and writing quality on professional documents consistently rate higher in head-to-head comparisons. For strategic analysis, contract review, complex report generation, and nuanced writing — Claude is the stronger tool.
Ecosystem independence. Copilot’s value is maximized inside Microsoft’s ecosystem — and reduced significantly outside it. Claude works with any system: via the API, MCP connectors across dozens of services, or direct file upload. If your team uses Google Workspace, Notion, Slack, or a mix of tools, Claude integrates without friction. Copilot requires significant custom development to connect to non-Microsoft systems.
Flexibility for builders. Claude’s API and MCP architecture lets developers connect it to any data source or system. Copilot is primarily a user-facing product; building custom applications with it requires Microsoft’s more constrained extension model.
The Typical Enterprise Decision
Many organizations end up using both: Copilot for daily productivity tasks inside Office — drafting emails, summarizing meetings, building Excel formulas — and Claude for higher-stakes analytical work, long-document processing, and custom integrations. The tools are complementary rather than mutually exclusive.
Organizations considering switching from a full Microsoft shop to Claude should evaluate switching costs carefully. If your email, calendar, documents, and collaboration are all in Microsoft 365, Copilot’s access to that unified data graph has genuine value that Claude would need custom MCP work to replicate.
For reasoning, long-document analysis, writing quality, and flexible integrations — yes. For daily productivity inside Microsoft 365 (Word, Excel, Teams, Outlook) — Copilot is purpose-built and more frictionless. The right choice depends on where you spend most of your workday.
What’s the difference between Claude and Microsoft Copilot?
Claude is a standalone AI model from Anthropic — accessible via web, desktop, mobile, and API, with a 1M token context window and strong reasoning. Microsoft Copilot is an AI layer built into Microsoft 365, using GPT-4o as its backend, with native access to your Outlook, Teams, Word, and Excel data. Fundamentally different designs for different workflows.
Can I use both Claude and Microsoft Copilot?
Yes, and many organizations do. The common approach: Copilot for daily Office tasks (email, meetings, documents), Claude for analytical work, complex reasoning, and building custom integrations. At $20/month each, running both is $40/month — a common setup for knowledge workers.
Lineup currency (Sept 2026, verified): Sonnet 5 ($2/$10), Opus 5.5 ($4/$20), Haiku 4.5 ($1/$5), Fable 5.1 ($10/$50). Legacy (still listed): Opus 4.8 ($5/$25), Sonnet 4.6 ($3/$15). Prior note (superseded): Prior flagship claim: Claude Opus 4.7 (claude-opus-4-7). Prior models claim: Opus 4.7 · Sonnet 4.6 · Haiku 4.5. Claude Opus 4.7 (claude-opus-4-7) was claimed current as of April 16, 2026. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →
Claude AI · Fitted Claude
Grok is xAI’s AI assistant, built by Elon Musk’s company and deeply integrated with the X (formerly Twitter) platform. Claude is Anthropic’s AI, built with a focus on safety and reasoning. They’re both frontier models — but they come from fundamentally different companies with different philosophies and different strengths. Here’s where each one wins.
legacy (still listed) models (April 2026): Claude Sonnet 4.6 (legacy — still listed) and Opus 4.6 (Anthropic) vs Grok 4 and Grok 4.1 (xAI). Grok 4.20 — a new multi-agent architecture — was reportedly in d
Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.
evelopment as of Q1 2026 but not yet publicly released.
Grok vs Claude: Direct Comparison
Grok vs Claude — direct comparison.
Capability
Grok 4 / 4.1
Claude Sonnet 4.6 / Opus 4.6
Edge
Real-time X/Twitter data
✅ Native
Via web search
Grok
Writing quality
Good
✅ Stronger
Claude
SWE-bench (coding)
~75% (Grok 4 Fast)
80.8% (Opus 4.6)
Claude Opus 4.7
Context window
~128K tokens
1M tokens (Sonnet/Opus)
Claude
API pricing (input)
~$2/M (Grok 4.1 Fast)
$3/M (Sonnet), $5/M (Opus)
Grok (cheaper)
Consumer subscription
$22/mo (X Premium+)
$20/mo (Claude Pro)
Claude (slightly cheaper)
Safety / refusal calibration
Less restrictive
✅ Constitutional AI
Depends on use case
Enterprise / compliance
Limited
✅ SSO, audit logs, BAA
Claude
Agentic coding tool
Limited
✅ Claude Code
Claude
Not sure which to use?
We’ll help you pick the right stack — and set it up.
Tygart Media evaluates your workflow and configures the right AI tools for your team. No guesswork, no wasted subscriptions.
Real-time X data. Grok’s native integration with X (Twitter) is a genuine differentiator — it can surface trending discussions, current sentiment, and breaking information from the platform in real time. If your work involves monitoring X, tracking social trends, or understanding current public discourse, this is an advantage no other model matches natively.
Cost at the API level. Grok 4.1 Fast’s API pricing runs below Claude Sonnet 4.6 on input tokens, making it attractive for high-volume workloads where cost per call is the primary consideration and you’re comfortable with the tradeoffs.
Less restrictive outputs. Grok is designed to be less filtered than Claude. For users who find Claude’s safety calibration frustrating on specific use cases, Grok may produce responses Claude declines. Whether this is an advantage depends entirely on what you’re trying to do.
What Claude Does Better
What Claude does better.
Context window. Claude Sonnet 4.6 and Opus 4.6 both have 1 million token context windows — roughly 8x Grok’s current context capacity. For long-document analysis, extended coding sessions, or large codebase comprehension, this is a meaningful operational difference.
Writing quality and instruction-following. On professional writing tasks — analysis, strategy documents, legal review, editorial content — Claude consistently produces more natural, constraint-adherent output. This is where Claude’s reputation was built and it remains a genuine advantage.
Coding benchmarks. Claude Opus 4.7 scores 80.8% on SWE-bench Verified (real-world software engineering tasks), with Sonnet 4.6 close behind at 79.6%. Grok 4 is competitive but Claude’s overall coding ecosystem — especially Claude Code — gives it a practical advantage for development workflows.
Enterprise features. Claude Enterprise offers SSO, audit logs, HIPAA BAA, configurable usage policies, and data processing agreements. Grok’s enterprise offering is less mature — meaningful for organizations with compliance requirements.
The User Base Difference
Grok’s primary audience is X users — people already on the platform who get Grok access as part of X Premium+. Claude’s primary audience is knowledge workers, developers, and enterprises who seek out a capable AI model. These different starting points shape each model’s design priorities and where each company invests in improvements.
For real-time X/Twitter data and less filtered outputs — yes. For writing quality, long-context work, coding (via Claude Code), and enterprise compliance — Claude is stronger. Neither is definitively better; they have different strengths for different workflows.
What is Grok’s advantage over Claude?
Grok’s clearest advantage is real-time X/Twitter data integration — it can access and analyze current X activity natively. Grok 4.1 Fast also runs cheaper per token than Claude Sonnet 4.6 at the API level, making it attractive for cost-sensitive high-volume workloads.
Is Grok free to use?
Grok has a free tier with limited access. Full Grok access requires X Premium+ ($22/month). Claude has a free tier with daily limits; Claude Pro is $20/month. Both have similar consumer price points with different bundling — Grok is tied to X, Claude is a standalone subscription.
Current flagship: Claude Opus 4.7 (claude-opus-4-7). Current models: Opus 4.7 · Sonnet 4.6 · Haiku 4.5. Claude Opus 4.7 (claude-opus-4-7) is the current flagship as of April 16, 2026. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →
Claude AI · Fitted Claude
The short answer is: it depends on what you mean by “smarter.” Claude and ChatGPT are both frontier AI models that perform at similar capability levels on most tasks. Where they differ is in specific strengths, how they handle uncertainty, and the kind of outputs they produce. Here’s the honest breakdown.
Bottom line: Claude and ChatGPT (GPT-4o) are competitive on most benchmarks. Claude tends to win on writing quality, instruction-following, and honesty calibration. ChatGPT tends to win on ecosystem breadth and image generation. Neither is definitively “smarter” — they have different strengths for different tasks.
Benchmark Comparison
Benchmark comparison.
Capability
Claude Sonnet 4.6
GPT-4o (ChatGPT)
Edge
Writing quality
✅ Stronger
Good
Claude
Instruction-following
✅ Stronger
Good
Claude
Coding (SWE-bench)
✅ Competitive
✅ Competitive
Roughly tied
Math reasoning
✅ Strong
✅ Strong
Roughly tied
Expressing uncertainty honestly
✅ Stronger
More confident
Claude
Context window
1M tokens
128K tokens
Claude
Image generation
❌ Not included
✅ DALL-E built in
ChatGPT
Data analysis (code interpreter)
Limited
✅ Advanced Data Analysis
ChatGPT
Hallucination rate
✅ Lower
Higher
Claude
Where Claude Is Genuinely Stronger
Where Claude is genuinely stronger.
Writing quality. Claude produces prose that reads more naturally and holds style constraints more consistently. ChatGPT has recognizable output patterns — a cadence and structure that appears even when you try to tune it away. Claude’s writing is harder to fingerprint as AI-generated.
Following complex instructions. Give both models a detailed, multi-constraint brief and Claude holds all the constraints through a long response more reliably. ChatGPT tends to gradually drift from earlier constraints as output length increases.
Honesty about uncertainty. Claude is more likely to say “I’m not sure about this” or “you should verify this” rather than confidently asserting something it doesn’t actually know. This is a calibration advantage — confident wrong answers from ChatGPT have frustrated many users who then don’t catch the error.
Long-context work. At 1M tokens vs ChatGPT’s 128K, Claude can process significantly more content in a single session — entire codebases, large document stacks, extended research contexts.
Where ChatGPT Is Genuinely Stronger
Image generation. DALL-E 3 is built into ChatGPT. Claude doesn’t generate images natively in the web interface. For visual workflows this is a real functional gap.
Code interpreter. ChatGPT’s Advanced Data Analysis runs Python in the conversation — upload a spreadsheet and get charts, analysis, and interactive data work in the same window. Claude can write code but doesn’t execute it in-chat.
Ecosystem breadth. OpenAI’s longer history means more third-party integrations, a larger community of people sharing GPT prompts, and more specialized GPTs in the store.
The Practical Answer
The practical answer.
For text-based professional work — writing, analysis, research, coding, strategy — most users find Claude to be the stronger daily driver. For visual content creation, data analysis in-chat, or workflows built around the OpenAI ecosystem, ChatGPT holds meaningful advantages. Many professionals run both and reach for whichever fits the specific task.
On writing quality, instruction-following, and honesty calibration — yes. On image generation and interactive data analysis — no. Both are competitive on reasoning and coding benchmarks. Neither is definitively smarter overall; they have different strengths for different task types.
Is Claude better than GPT-4?
Claude Sonnet 4.6 and Opus 4.6 compare to GPT-4o (the current GPT-4 model) — not the older GPT-4 Turbo. On most head-to-head comparisons, they’re competitive with Claude holding edges in writing quality and context length, and ChatGPT holding edges in image generation and data analysis tools.
Should I use Claude or ChatGPT?
Use Claude as your primary tool if your work is primarily text-based — writing, analysis, coding, research. Use ChatGPT if image generation or in-chat Python execution is central to your workflow. Many professionals use both, with Claude as the daily driver and ChatGPT for its specific capabilities.
Claude Code and Cursor are both AI coding tools with serious developer followings — but they’re built on fundamentally different models. Cursor is an AI-powered IDE fork. Claude Code is a terminal-native agent. The right choice depends on how you work.
Short answer: Cursor wins for in-editor experience — autocomplete, inline suggestions, and staying inside VS Code’s familiar interface. Claude Code wins for autonomous multi-step tasks — it operates at the system level, can run commands, manage files across the whole project, and doesn’t require you to be watching. Most serious developers end up using both.
Claude Code vs Cursor: Head-to-Head
Claude Code vs Cursor — head-to-head.
Capability
Claude Code
Cursor
Edge
In-editor autocomplete
Limited
✅ Native
Cursor
Autonomous multi-file tasks
✅ Strong
✅ Good
Claude Code
Terminal / shell command execution
✅ Yes
Limited
Claude Code
Remote / cloud sessions
✅ Yes
—
Claude Code
VS Code compatibility
Via MCP
✅ Built on VS Code
Cursor
Model choice
Claude only
Multi-model
Cursor (flexibility)
Instruction-following precision
✅ Strong
Good
Claude Code
Price
Included in Pro ($20/mo)+
~$20/mo (Pro)
Tie
Setup complexity
Moderate
Easy
Cursor
Not sure which to use?
We’ll help you pick the right stack — and set it up.
Tygart Media evaluates your workflow and configures the right AI tools for your team. No guesswork, no wasted subscriptions.
In-editor experience. Cursor is a fork of VS Code with AI baked in — autocomplete, inline suggestions, cmd+K to edit code in place, and the full VS Code extension ecosystem. If you live in an editor and want AI suggestions as you type, Cursor is the more polished experience.
Familiar interface. If your team already uses VS Code, Cursor requires almost no adjustment. Claude Code requires getting comfortable with an agentic workflow that’s fundamentally different from autocomplete.
Multi-model flexibility. Cursor lets you choose between Claude, GPT-4o, and other models depending on the task. Claude Code is Claude-only.
What Claude Code Does Better
What Claude Code does better.
System-level autonomy. Claude Code runs commands, manages files across the entire project, executes tests, and operates at the OS level — not just inside an editor window. It can do things Cursor can’t, like run a test suite, see the results, fix the failures, and re-run without you touching anything.
Remote and background sessions. Claude Code supports remote sessions that continue on Anthropic’s infrastructure even after you close the app. Cursor requires you to be present.
Complex multi-step tasks. Agentic tasks that span many files, require running code, and iterate based on output are where Claude Code’s architecture shines. Cursor handles this through its Composer feature, but Claude Code’s terminal-native approach gives it more flexibility.
Instruction precision. On multi-constraint tasks — “refactor this to match our conventions, add error handling, keep it backward compatible, and don’t use async” — Claude Code holds all the constraints more reliably through a long operation.
Price Comparison
Claude Code is included (at limited levels) with a Claude Pro subscription at $20/month. Claude Code Pro at $100/month gives full access for developers using it as a primary tool. Cursor Pro is approximately $20/month. Both are in the same price tier for comparable usage levels.
The Practical Setup
Most developers using both tools run Cursor for in-editor work — autocomplete, inline edits, quick questions about code — and Claude Code for larger autonomous tasks: refactors, test generation across a codebase, debugging sessions that require running code. They’re complementary, not mutually exclusive.
They’re different tools. Claude Code is better for autonomous multi-step tasks, system-level operations, and complex refactors that require running code and iterating. Cursor is better for in-editor autocomplete and inline suggestions within the VS Code interface. Most serious developers use both.
Can I use Claude Code inside VS Code or Cursor?
Claude Code primarily runs as a terminal agent or through Claude Desktop’s Code tab. You can connect it to VS Code via MCP integration. Cursor has its own Claude integration built in — you can use Claude models inside Cursor without Claude Code.
How much does Cursor cost vs Claude Code?
Cursor Pro is approximately $20/month. Claude Code is included at limited levels with Claude Pro ($20/month) or at full access with Claude Code Pro ($100/month). For occasional use, Claude Pro gives you both a full Claude subscription and limited Claude Code access for the same $20.
Claude and GitHub Copilot both help developers write code — but they’re solving different problems. Copilot lives inside your editor as an autocomplete and inline suggestion tool. Claude is a conversational AI you bring complex problems to. Understanding what each does determines which belongs in your workflow, and whether you need both.
Short answer (September 2026): They’re not direct substitutes. Copilot is better for in-editor autocomplete and inline code completion as you type. Claude is better for complex problem-solving, code review, architecture discussion, debugging, and agentic development via Claude Code. Most serious developers benefit from both.
Claude vs GitHub Copilot: Head-to-Head
Capability
Claude
GitHub Copilot
Edge
In-editor autocomplete
❌
✅
Copilot — purpose-built for this
Complex problem-solving
✅
Limited
Claude — conversational depth
Code review
✅
Basic
Claude — more thorough
Architecture discussion
✅
❌
Claude — requires reasoning
Debugging complex errors
✅
Basic
Claude — root cause analysis
Agentic coding (autonomous)
✅ Claude Code
✅ Copilot Workspace
Claude Code — terminal-native
GitHub integration
Via MCP
✅ Native
Copilot — built into the platform
Multi-language support
✅
✅
Tie
Price
$20/mo (Pro)
$10–19/mo
Copilot — cheaper at base
Not sure which to use?
We’ll help you pick the right stack — and set it up.
Tygart Media evaluates your workflow and configures the right AI tools for your team. No guesswork, no wasted subscriptions.
In-editor autocomplete. Copilot is purpose-built for this — it sits inside VS Code, JetBrains, Neovim, or your editor of choice and suggests completions as you type. It reads your current file and neighboring context to generate inline suggestions. Claude doesn’t do this. There’s no Claude autocomplete inside your editor in the same way.
GitHub native integration. Copilot is an extension of the GitHub ecosystem — it understands your repository context, integrates with pull requests (Copilot PR summaries), and connects directly to GitHub Actions. If you’re deeply embedded in the GitHub workflow, Copilot’s native integration has genuine advantages.
What Claude Does Better
Complex reasoning about code. When you have a hard problem — a non-obvious bug, an architectural decision, a security vulnerability to trace — Claude’s conversational depth is more valuable than autocomplete. You can describe the problem, paste relevant code, explain your constraints, and get substantive analysis rather than a completion suggestion.
Code review quality. Claude’s code review is more thorough than Copilot’s, particularly for security issues, error handling gaps, and logic errors. It explains why something is a problem, not just that it is — and it holds all your review criteria through long responses.
Claude Code for agentic work. Claude Code is a terminal-native agent that operates in your actual development environment — reading files, running tests, making commits, refactoring across multiple files. It’s a more autonomous capability than either chat-based Claude or Copilot’s editor integration. For multi-file, multi-step development tasks, Claude Code is the stronger tool.
Using Both: The Practical Setup
The most effective developer setup uses both: GitHub Copilot for in-editor autocomplete and inline suggestions as you write, Claude (via web, desktop, or API) for complex problem-solving, code review, debugging, and architecture. Claude Code for autonomous development sessions on larger tasks.
At $10–19/month for Copilot and $20/month for Claude Pro, running both costs $30–40/month — meaningful but justified for developers whose output directly depends on these tools.
They do different things well. Copilot is better for in-editor autocomplete. Claude is better for complex problem-solving, code review, and debugging. Claude Code is better for autonomous development sessions. Most developers benefit from both rather than choosing one.
Can Claude replace GitHub Copilot?
Not for in-editor autocomplete — that’s Copilot’s core strength and Claude doesn’t have a direct equivalent in your editor as you type. Claude Code handles autonomous development tasks at a higher level, but for the instant inline suggestion experience, Copilot remains the dedicated tool.
Should I use Claude Code or GitHub Copilot?
For autonomous multi-file development tasks, Claude Code is the stronger tool — it operates in your actual environment, reads your full codebase, runs tests, and works without constant guidance. For in-editor suggestions as you write, Copilot’s integration is purpose-built for that workflow. The two address different parts of the development process.