AI Search Authority - Tygart Media

Category: AI Search Authority

GEO, AEO, and llms.txt: how a brand gets cited in Perplexity, ChatGPT, Claude, and Google AI Overviews.

  • The 17-Day Wonder: One Burst, Then Silence

    The 17-Day Wonder: One Burst, Then Silence

    Five receipts so far in this series, five living sites: 44,583 citations at BC ESG, 109,844 at Healthcare Facility Hub, 813,426 on this site, 50,607 at Risk Coverage Hub, 57,798 at Continuity Hub. The sixth site we counted is a ghost. Restoration Intel — our restoration-industry library — earned 111 AI citations in the older window we measured, and every one of them landed inside seventeen days. In the fresh ninety-day window, the same report says zero. Not a decline. A disappearance.

    Here is the whole story, because the whole story is short: fifty-three days of nothing, a burst from July 22 to August 7, then silence — fifty-eight more days of it in that export, and ninety straight days of zero in the new one. One guide holds nearly two-thirds of the burst. Five questions account for all of it that the query view can see. This is the smallest receipt in the series by orders of magnitude, and the strangest.

    Watch the 60-second version: Why did this site’s AI citations live for exactly 17 days? — the same receipts in 44 seconds, chapters matched to the sections below.

    The burst: seventeen days

    The older window is May 30 to October 4, 2026 — 128 days, exported from Bing Webmaster Tools’ AI Performance report on October 6. The daily series sums to 111; the page table sums to 110. Bing’s views differ, and at this size they nearly agree: 0.9% apart, where the other sites in this series ran 2.6% to 5.7%. Every figure below names its view.

    112 of the 128 days read zero. The sixteen days that don’t sit inside one stretch, July 22 to August 7: 1, 17, 7, 10, 4, 4, 3, 5, 7, 4, 12, 5, 5, 2, 12, 0, 13. One day inside the burst — August 6 — reads zero too, a held breath in the middle. The peak is the second day: 17 citations on July 23. Then, after August 7, nothing. Not a taper — the line simply stops, and it has not restarted in any window we’ve pulled since.
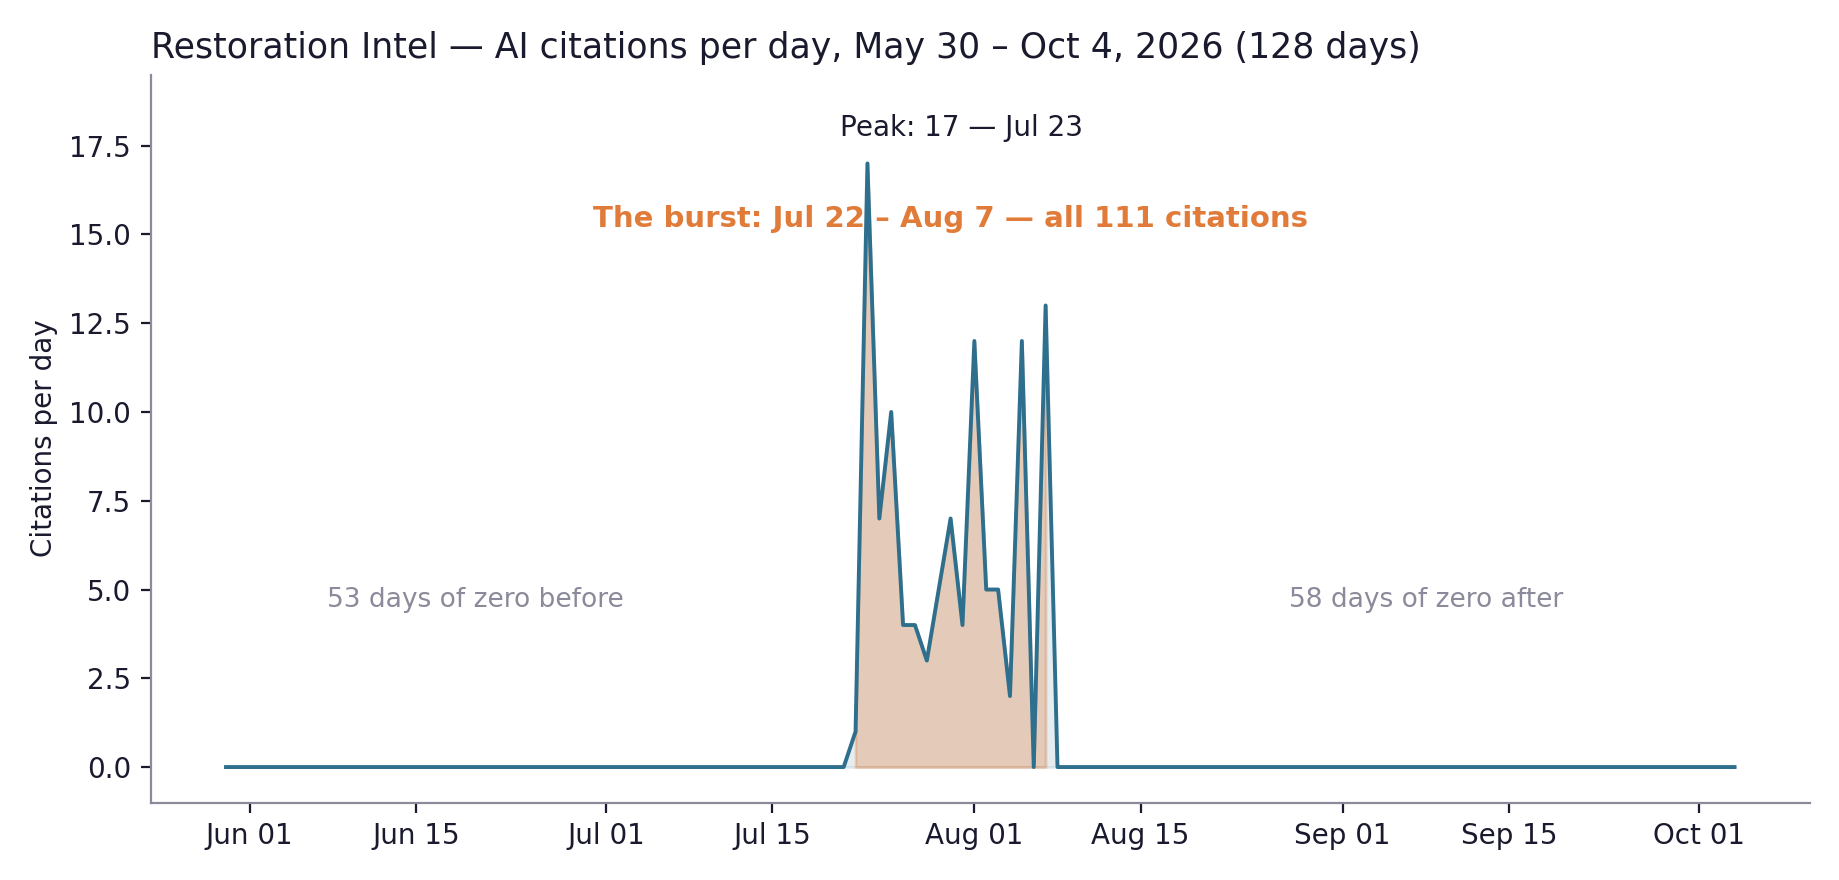
    Restoration Intel daily AI citations over 128 days: a flat zero line, a 17-day burst in late July and early August holding all 111 citations with a peak of 17 on July 23, then zero again.
    One burst in 128 days. Source: Bing Webmaster Tools AI Performance, daily view (exported October 6, 2026).

    The guide: 70 of 110

    Nine pages were cited in the burst, ever. One of them took nearly two-thirds of the page-sum:

    • Fire-damage restoration, complete professional guide — 70
    • Asbestos abatement protocol — 10
    • Structural drying systems & psychrometrics — 8
    • Reconstruction materials matching — 7
    • Emergency response: the first 24 hours — 6
    • AI drone technology in restoration — 3
    • Restoration carbon protocol — 2
    • Emergency documentation — 2
    • How to file a property insurance claim — 2

    Receipt No. 3’s leader held 30.8% of a huge site and we called it a star. This is 63.6% of a tiny one. The fire guide wasn’t a page among pages during those seventeen days; for whatever the machines were doing that fortnight, it was close to the whole site. The supporting cast is the library doing its job — drying science, abatement protocol, materials matching — real professional references, cited in single digits, then gone.
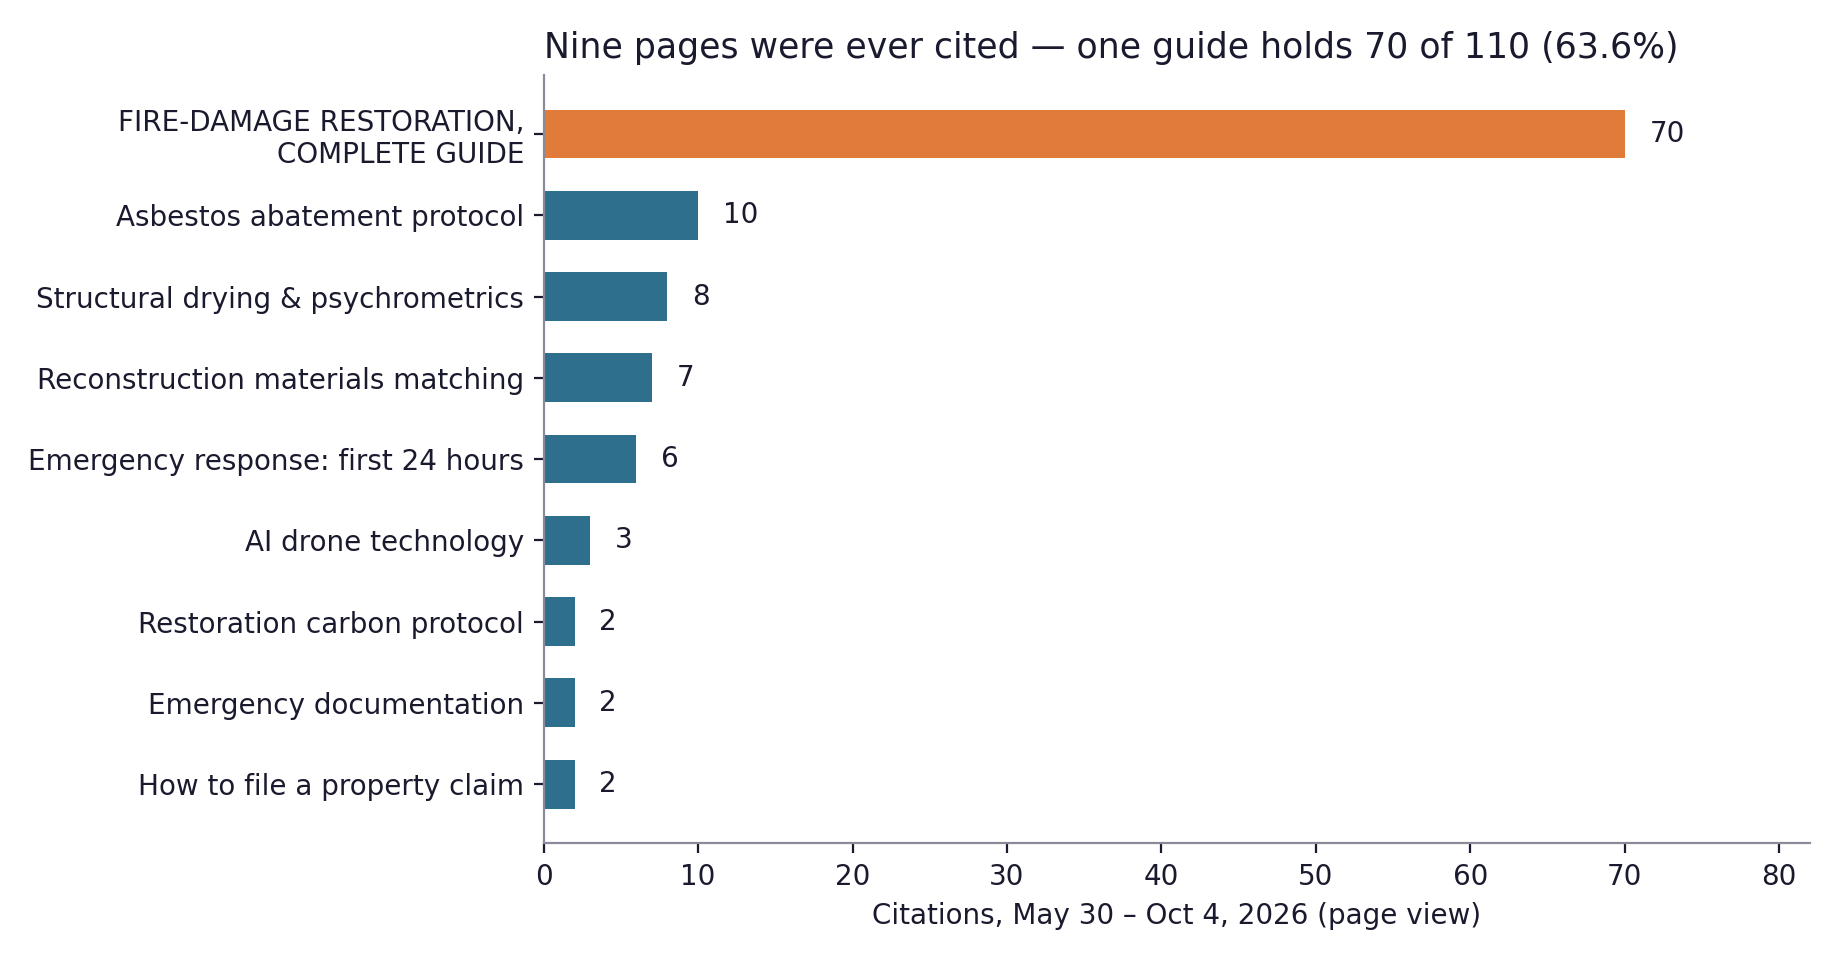
    Restoration Intel's nine cited pages: the fire-damage restoration guide at 70 citations, the other eight between 2 and 10.
    Nine pages, one guide. Source: Bing Webmaster Tools AI Performance, page view.

    The questions: five, ever

    The query view for the older window holds exactly five questions. Not five hundred — five. Three of them are the same question with the words rearranged:

    • “fire restoration” — 20 citations; our share 21.28%.
    • “fire remediation” — 12; our share 23.08%.
    • “fire damage restoration” — 8; our share 22.22%.
    • “commercial property emergency water damage restoration response time” — 3; our share 27.27%.
    • “commercial property fire damage restoration process” — 3; our share 14.29%.
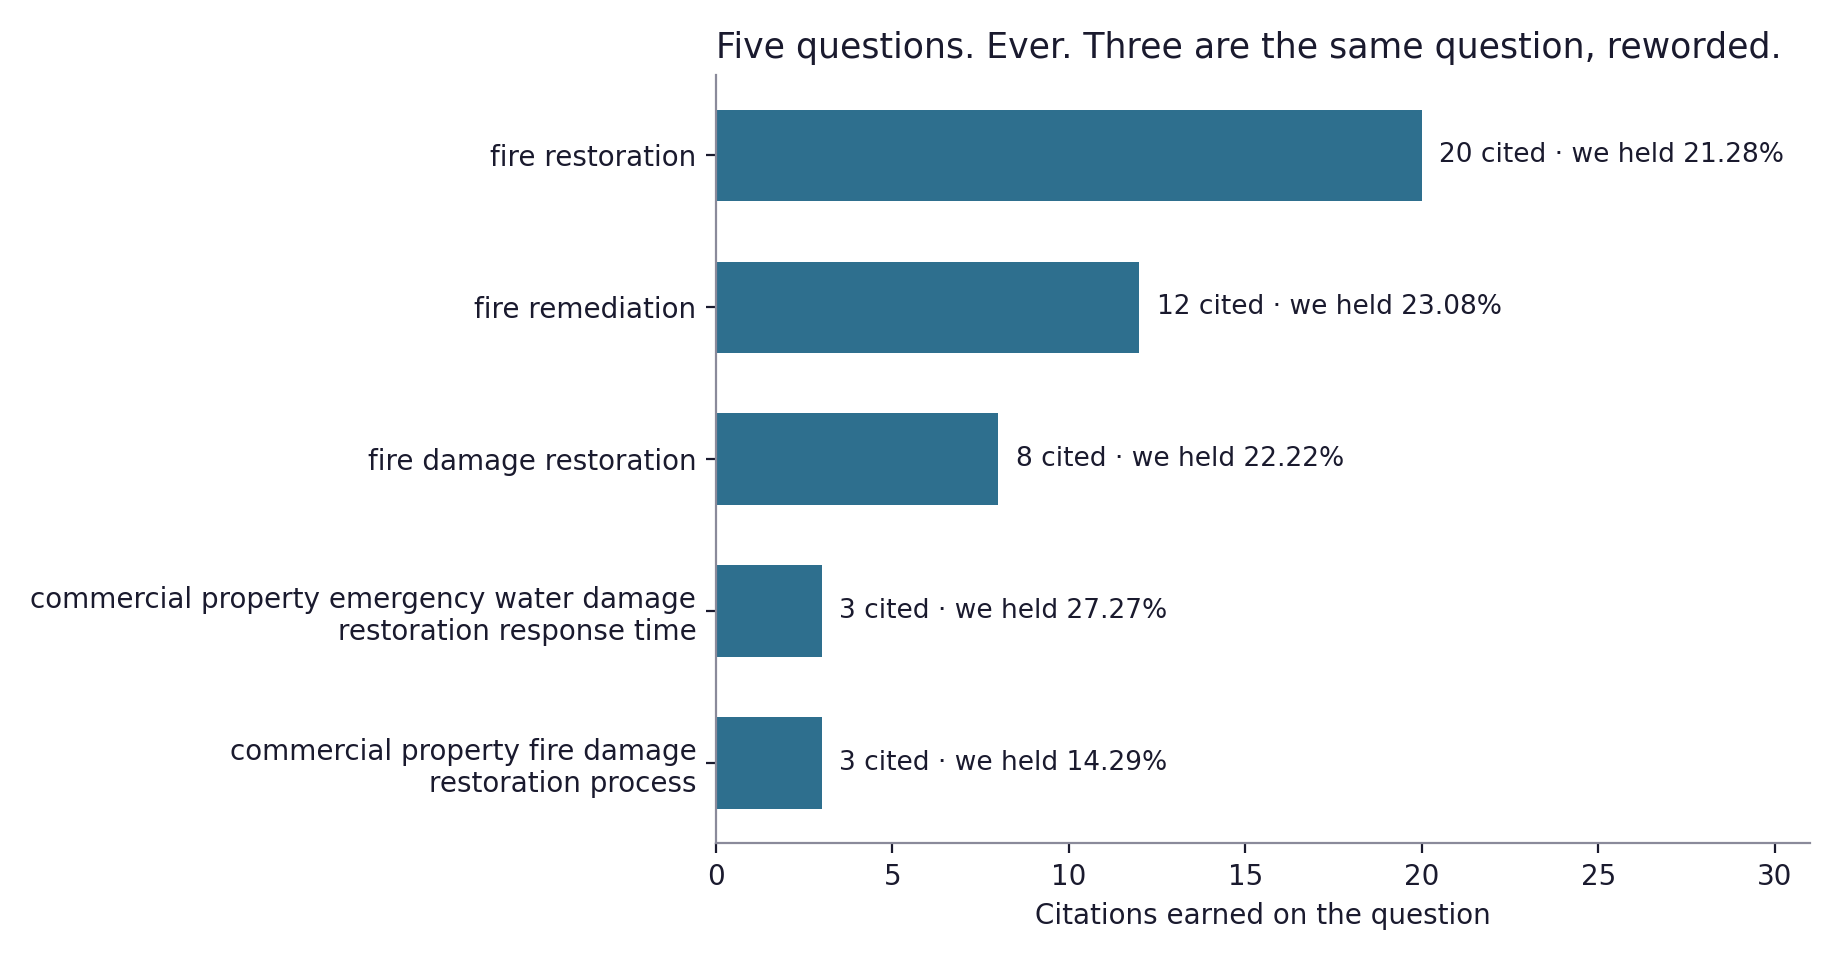
    The only five questions that ever cited Restoration Intel, with the site's share of each: fire restoration 20 citations at 21.28 percent, fire remediation 12 at 23.08, fire damage restoration 8 at 22.22, and two long commercial-property questions at 3 each.
    Five questions, and our share of each. Source: Bing Webmaster Tools AI Performance, query view.

    Those five rows are the entire visible demand. The query view sums to 46 citations against the daily view’s 111 — the views don’t reconcile at this scale, and we won’t pretend they do. What’s solid is the shape: for seventeen days, when the machines answered questions about fire restoration, they reached for this library about a fifth to a quarter of the time — and reached for its fire guide most of all. Then they stopped reaching.

    The silence: ninety days of zero

    The fresh window is the series-standard one — August 8 to November 5, 2026, ninety days, pulled November 8. The daily series sums to 0. There is not one nonzero day in it. The report’s Pages tab and Grounding Queries tab for this window showed “No data available” — the downloads were disabled, because there was nothing to download.
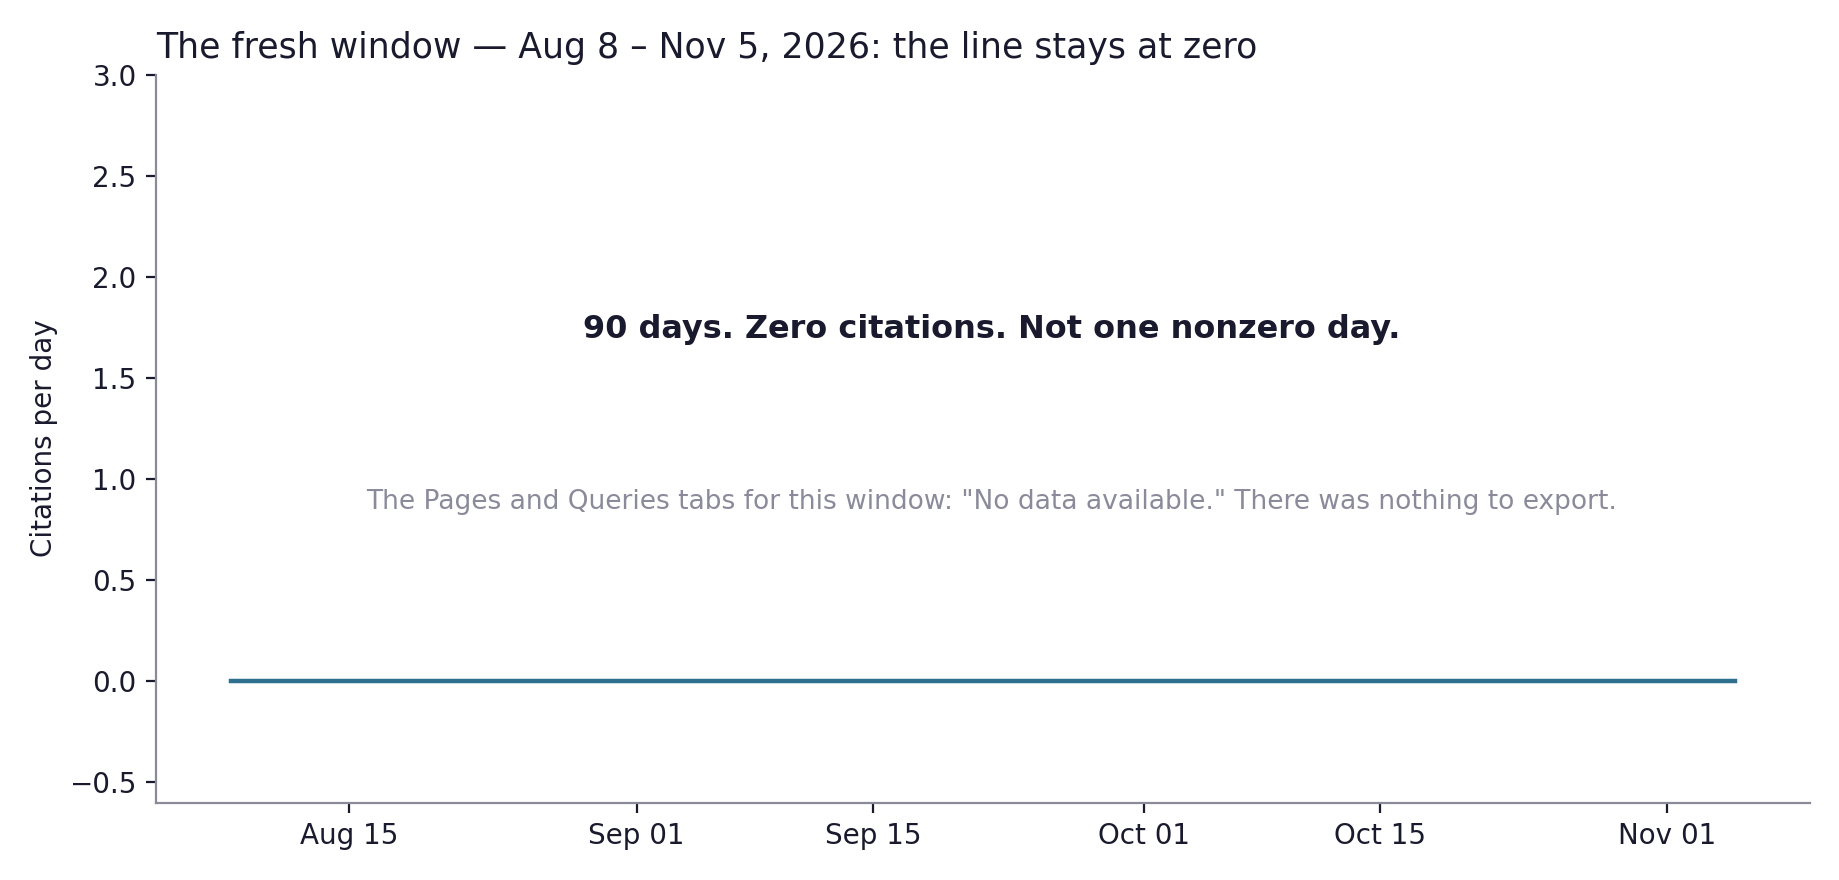
    Restoration Intel daily AI citations in the fresh 90-day window, August 8 to November 5, 2026: a flat line at zero for all ninety days.
    The fresh window. The emptiness is the data. Source: Bing Webmaster Tools AI Performance, daily view (pulled November 8, 2026).

    Put the two windows side by side and the site has now been silent for 148 consecutive measured days — the last fifty-eight of the old export and all ninety of the new one. Every other site in this series grew, plateaued, or tripled. This one is the only line in the fleet that goes to zero and stays there.

    What we can’t claim

    • We don’t know why it started. Nothing in these files says what switched on around July 22. The burst also predates the export that recorded it — the data was pulled October 6, looking back — so we’re reading a fossil, not watching a feed.
    • We don’t know why it stopped. A ranking change, a crawl change, a reporting change, the end of some trial on the engine’s side — the report records counts, not causes. Picking one would be storytelling.
    • The report’s own coverage may be part of the story. When Bing’s AI Performance report began covering this site, and how completely, is inside the mystery, not outside it. A burst in the data can be a burst in the world or a burst in the measuring. We can’t separate those from here.
    • No cause is claimed — including ours. Anything we published or changed around those dates is not established as a cause, in either direction. Correlation with the burst would still not be a mechanism.
    • 111 is small. One engine, one report, one site. At this size a handful of answers moving is the whole chart. We publish it because it’s ours and it’s strange — not because it’s big.

    What we do now

    1. Keep publishing the library. Restoration Intel exists to be a working reference for restoration professionals — the guides are useful whether or not a machine quotes them this quarter. The library is not a citation farm and we won’t run it like one.
    2. Re-measure on the next sweep. The ghost gets counted again with the rest of the fleet, same windows, same instrument. If it ever flickers, we’ll see it in the series.
    3. Don’t chase it. No rewrite of the fire guide to summon a burst we don’t understand, no surgery on a site whose only proven fact is that something happened once, for seventeen days, in the summer.

    111 citations. Seventeen days. Then zero, for ninety straight days and counting. The ghost — published like everything else in this series, because the receipts are the receipts.

    Download the field-report PDF — the same receipts in a printable report.

    Update history
    November 8, 2026 — Published.

    November 8, 2026 — The video version went live on YouTube the same morning. Article published earlier the same day.

    Method note: All figures are from Bing Webmaster Tools AI Performance exports for restorationintel.com. Older window: May 30–October 4, 2026 (128 days), pulled October 6, 2026 — the daily view sums to 111, the page view to 110 (0.9% apart), and the query view to 46; Bing notes totals may differ across views, and each figure above names its view. Fresh window: August 8–November 5, 2026 (90 days), pulled November 8, 2026 — the daily view sums to 0, and the Pages and Grounding Queries tabs showed “No data available,” so no page or query export exists for that window. Citation counts are Microsoft Copilot and partner citations as Bing reports them; citation shares are Bing’s per-query figures. Page names are shortened from the pages’ own titles. The field-report PDF is at https://tygartmedia.com/wp-content/uploads/2026/11/the-17-day-wonder-tygart-media-field-report.pdf. This is one site, one engine’s report, two windows — one of them empty.
  • The Anchor and the Pillars: One Guide, a Fifth of a Site

    The Anchor and the Pillars: One Guide, a Fifth of a Site

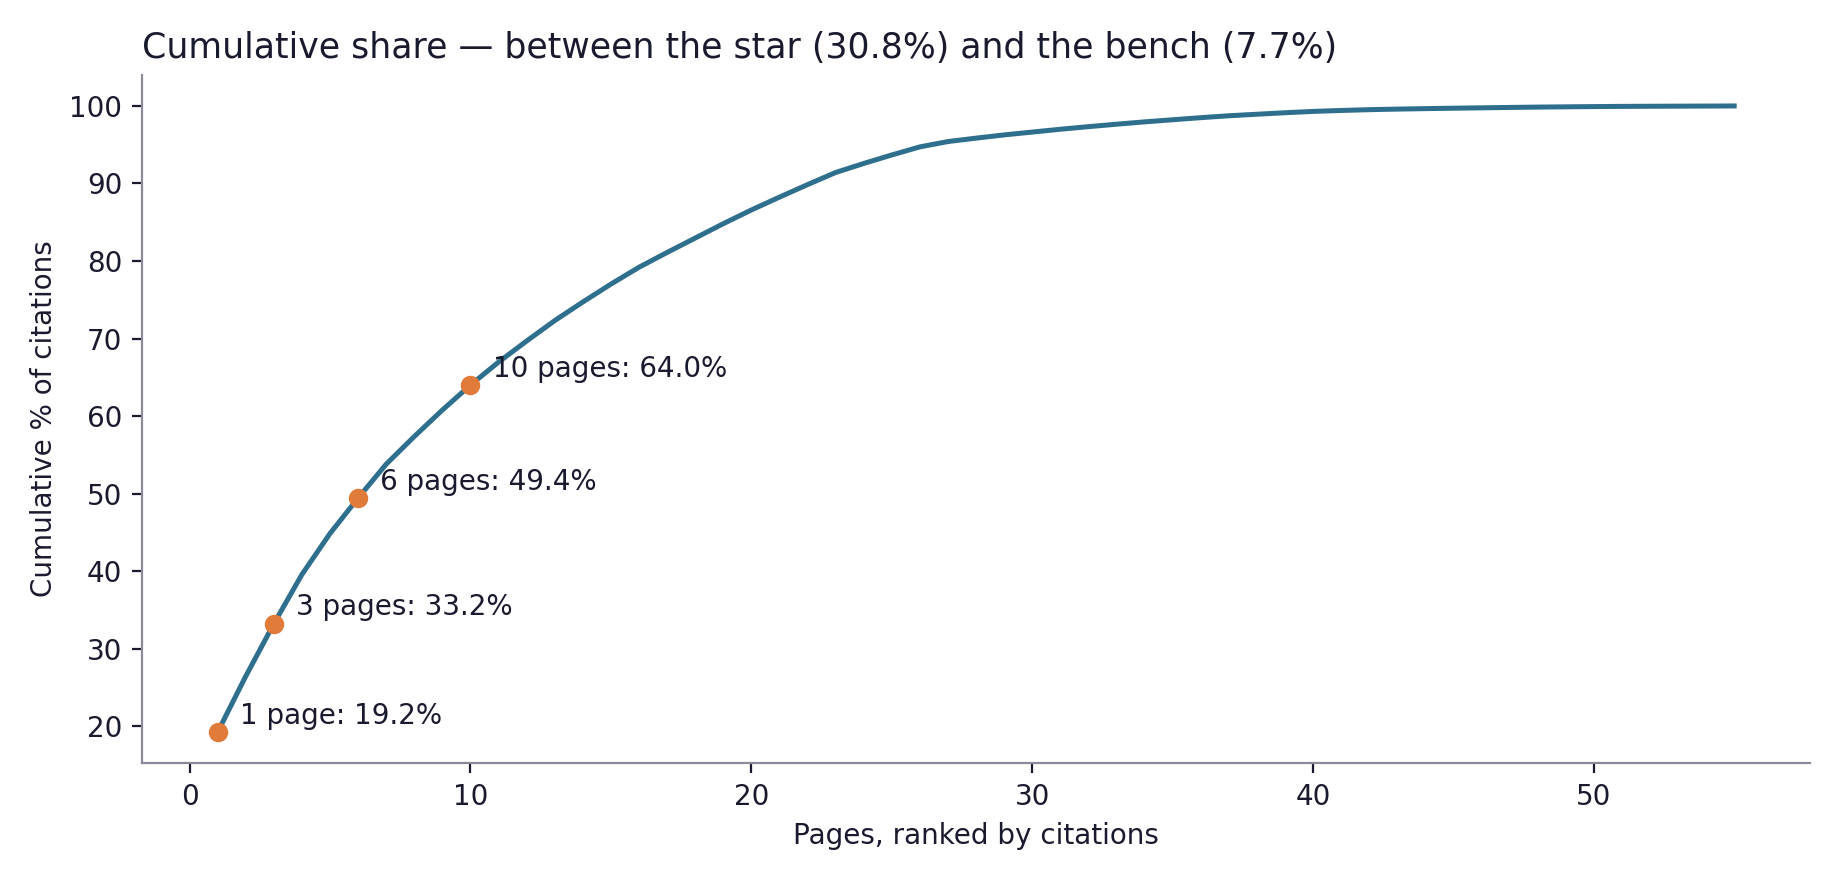
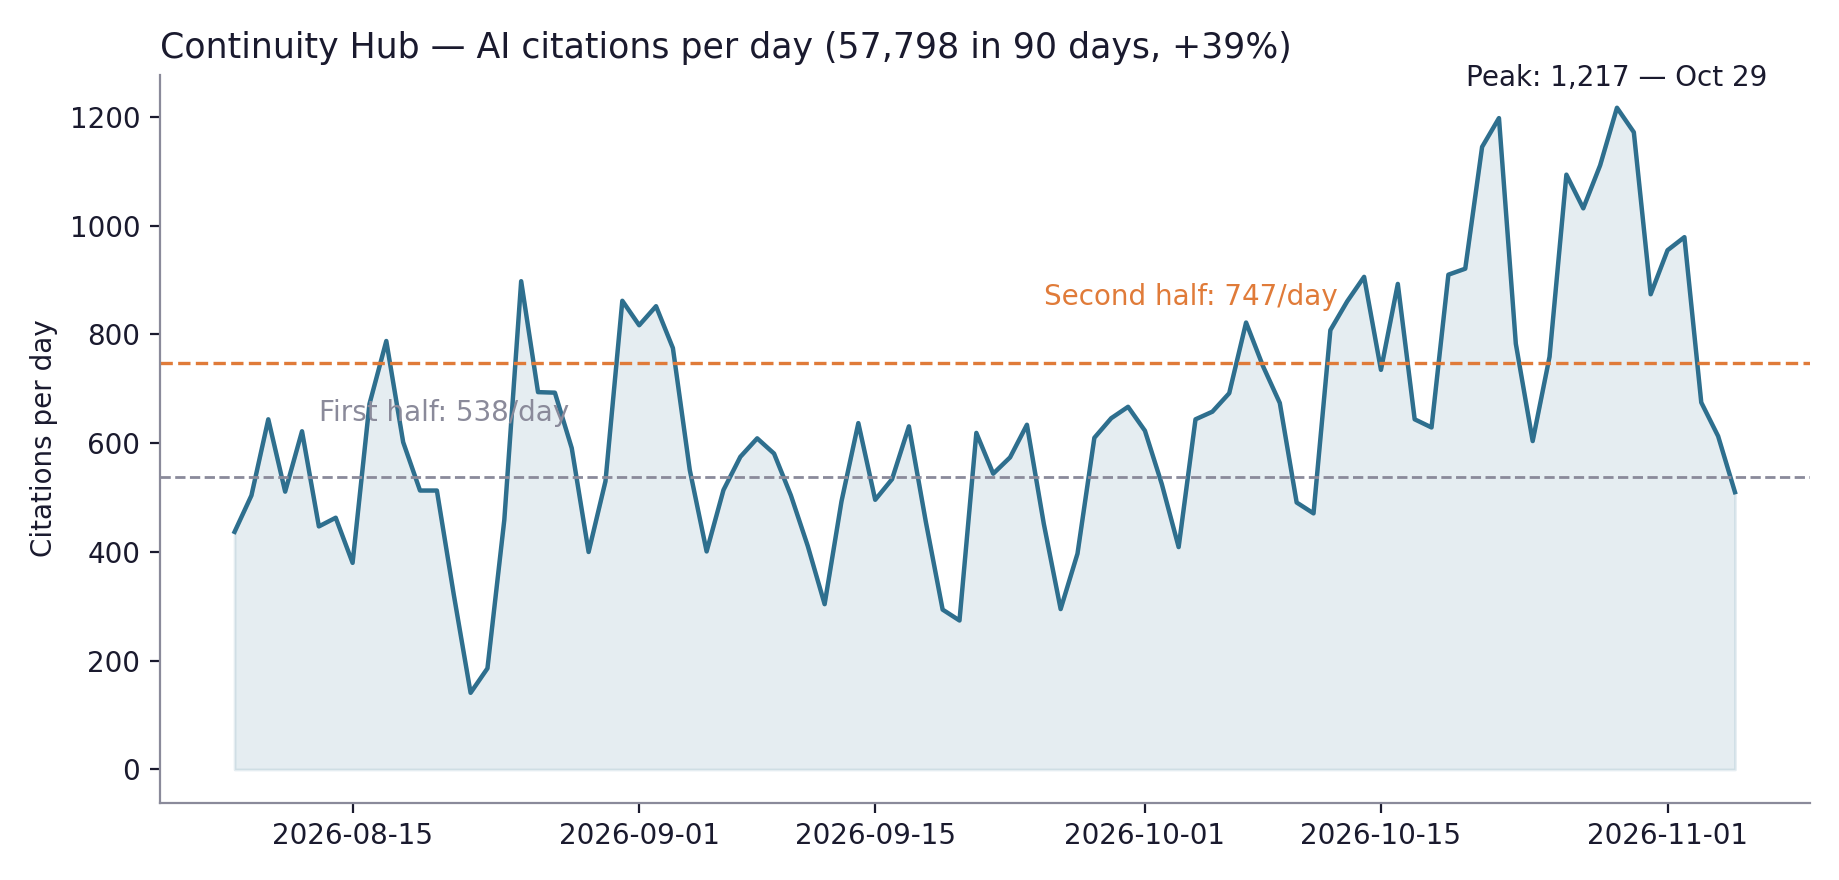
    Three shapes so far in this series: a star (Receipt No. 3 — one page, 30.8% of its site), a bench (Receipt No. 4 — no page above 7.7%), and now the shape between them. Continuity Hub — our business-continuity reference — earned 57,798 AI citations in ninety days, and one guide holds 10,579 of them: 19.2% of the page-sum.

    The guide is a complete professional treatment of supply-chain resilience. The site grew +39% by halves — 538 citations a day to 747 — with the last fourteen days averaging 884 and a peak of 1,217 on October 29. An anchor, real support, steady growth. The hybrid.

    Watch the 60-second version: Why does one guide hold a fifth of this site’s AI citations? — the same receipts in 47 seconds, chapters matched to the sections below.

    The count

    The window is August 8 to November 5, 2026, from Bing Webmaster Tools’ AI Performance report — the same instrument as the rest of this series. The daily series sums to 57,798; the page table sums to 55,029. Bing’s views differ (here by 4.8%), Bing prints a note saying so, and every figure below names its view.

    55 pages, 547 questions. The halves: 538 a day, then 747. First fourteen days: 530 a day. Last fourteen: 884. Not the flagship’s plateau, not Risk Coverage Hub’s triple — a working site’s steady climb, with its biggest day, October 29, landing in the most recent third of the window.

    Continuity Hub daily AI citations over 90 days: 538 a day in the first half, 747 in the second, peak 1,217 on October 29.
    Steady growth: 57,798 citations in 90 days, +39% by halves. Source: Bing Webmaster Tools AI Performance, daily view.

    The anchor — and the support under it

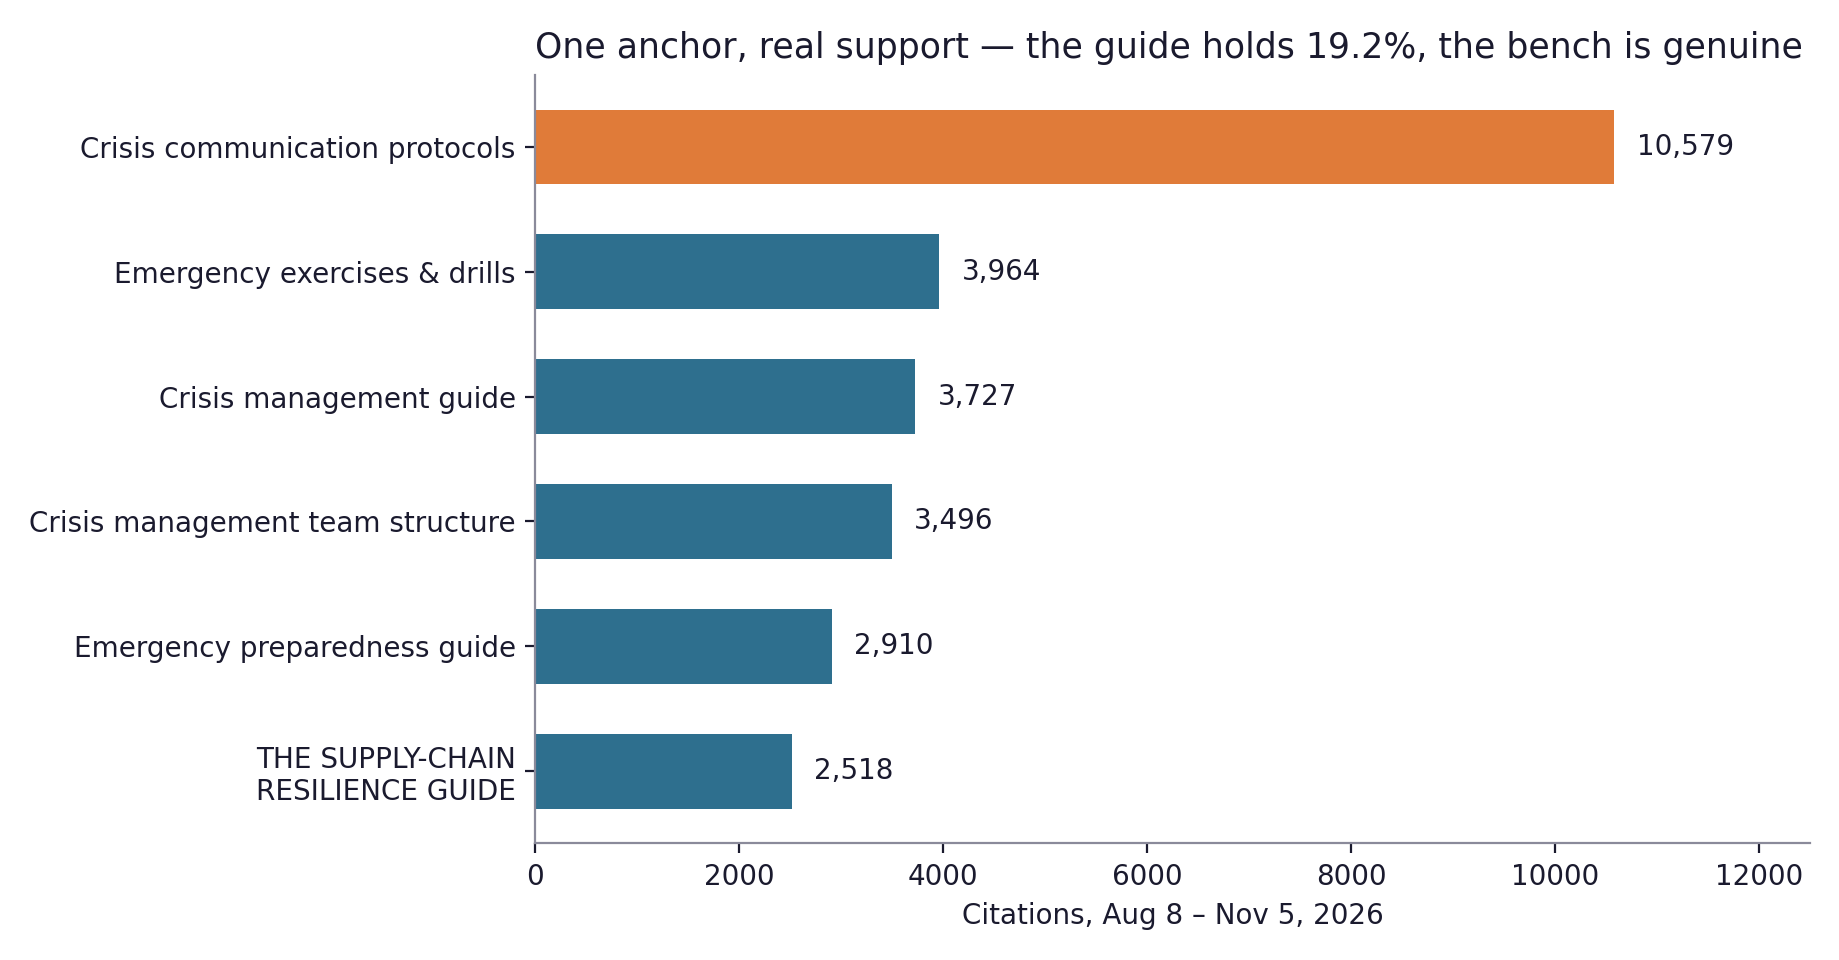
    The supply-chain resilience guide’s 10,579 is a genuine lead — 2.7 times the runner-up. But read down the table and the anchor isn’t carrying the building alone:

    • Supply-chain resilience, complete guide — 10,579
    • Crisis communication protocols — 3,964
    • Emergency exercises & drills — 3,727
    • Crisis management, complete guide — 3,496
    • Crisis management team structure — 2,910
    • Emergency preparedness, complete guide — 2,518

    Three pages hold 33.2% of the page-sum; six hold 49.4%; ten hold 64.0%. And the families are balanced: five crisis pages hold 23.4% (12,869), five supply-chain pages hold 24.7% (13,614). Two pillars of near-equal weight, one of them fronted by an anchor. If the anchor page stumbled tomorrow, this site would lose a fifth of its count, not a third — and the crisis pillar wouldn’t notice. That’s the risk arithmetic of the hybrid shape, and on these numbers it’s the most comfortable of the three.

    Continuity Hub's top pages: the supply-chain resilience guide at 10,579, with five more guides between 2,518 and 3,964 — an anchor with genuine support.
    One anchor, real support. Source: Bing Webmaster Tools AI Performance, page view.
    Cumulative share curve for Continuity Hub: one page 19.2 percent, three pages 33.2, six pages 49.4, ten pages 64.0 — between the star site and the bench site.
    Cumulative share of the page-sum — the middle curve of the series. Source: Bing Webmaster Tools AI Performance, page view.

    The questions: one phrase owned, one contested

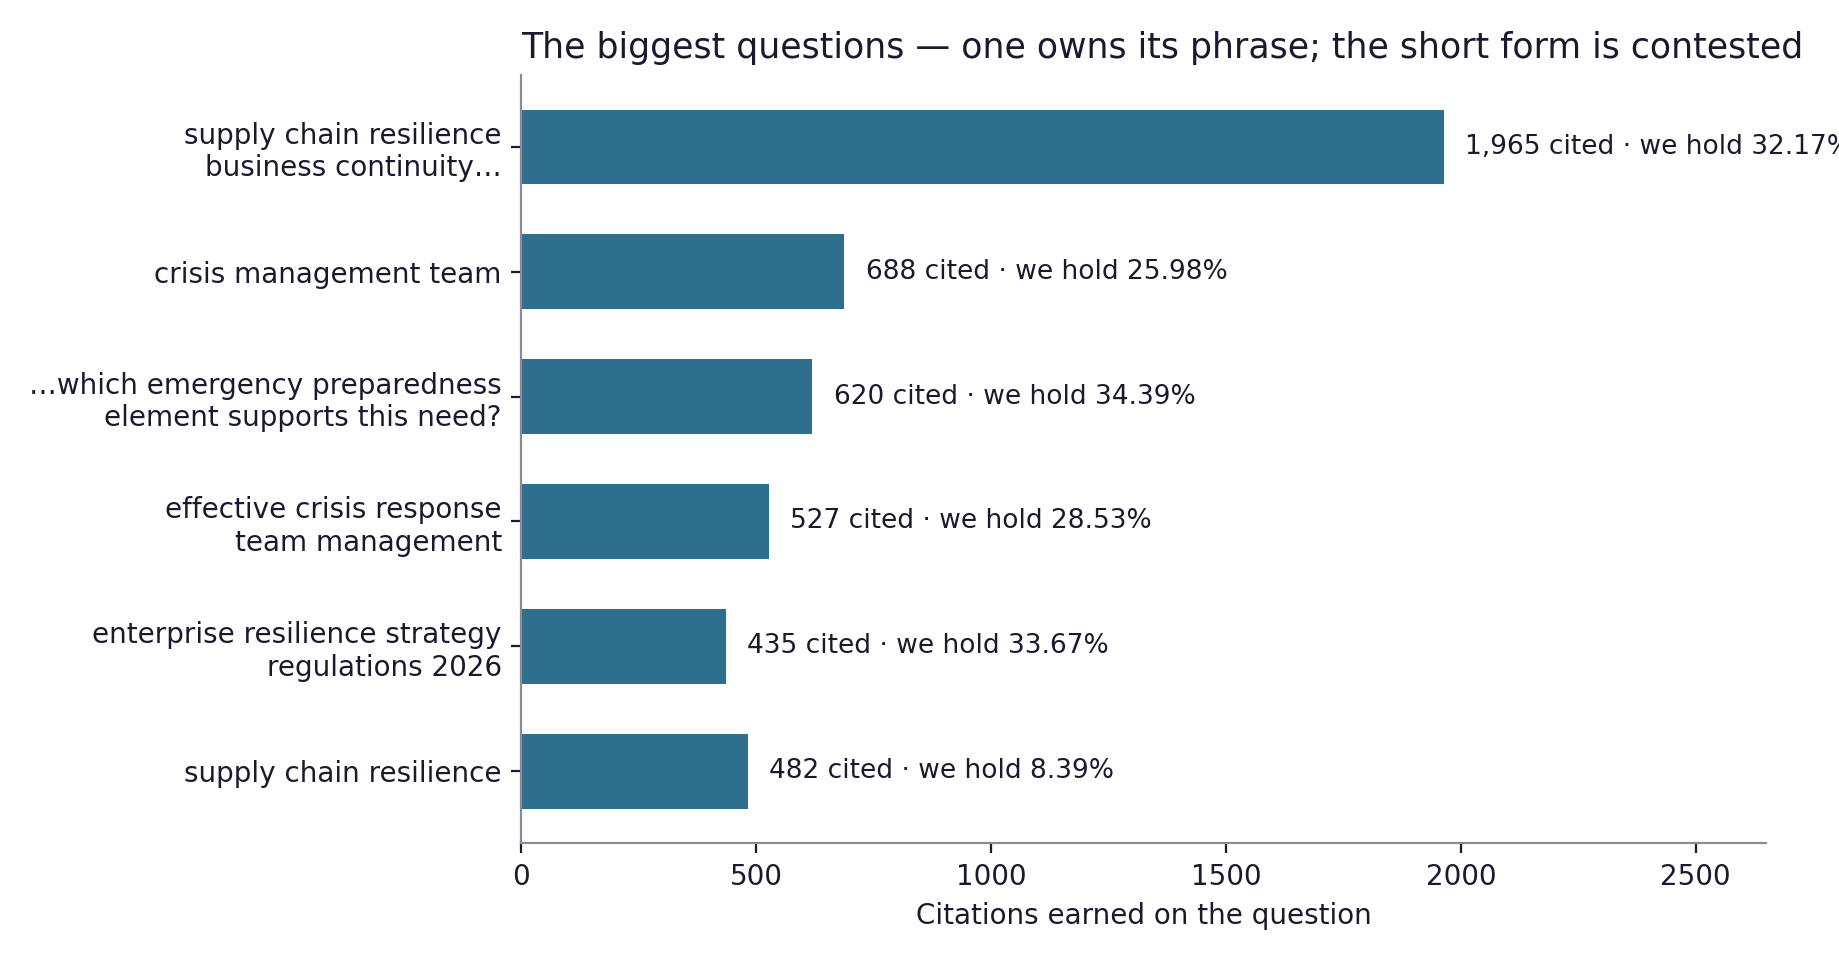
    The guide’s own question is the site’s biggest, and the hold is strong:

    • “supply chain resilience business continuity vulnerabilities management” — 1,965 citations; our share 32.17%.
    • “crisis management team” — 688; our share 25.98%.
    • And a question in full sentence form, the way someone asks a person: “during a disaster, a facility needs to quickly reach staff, volunteers, and emergency management partners. which emergency preparedness element supports this need?” — 620 citations; our share 34.39%.
    • “enterprise resilience strategy regulations 2026” — 435; our share 33.67%.
    Continuity Hub's biggest questions and the site's share of each: strong holds on the long phrasings, but just 8.39 percent on the short phrase supply chain resilience.
    The biggest questions, and our share of each. Source: Bing Webmaster Tools AI Performance, query view.

    Now the honest complication, and it’s a good one: the short form — plain “supply chain resilience” — earns 482 citations across the web’s answers, and our share of it is only 8.39%. The guide owns its long, precise phrasing and is a minor holder of the short, famous one. That’s not a failure; it’s a map. The long forms are where professional intent lives, and 32–34% holds there are worth more than a sliver of the generic phrase. But anyone who tells you this page “owns supply chain resilience” hasn’t read the query table. We have. It owns a specific, valuable cut of it.

    What we can’t claim

    • No build story. Unlike Receipt No. 1’s stepped sites, nothing here dates the +39% to a single act. The guide predates the window’s story; the claim is the shape and the growth, not a cause.
    • The views differ. Daily-sum 57,798 vs page-sum 55,029 — 4.8% apart, disclosed, each figure naming its view.
    • One engine’s window. Copilot and partner citations as Bing reports them; ninety days is a snapshot, not a deed.
    • Citations are not visits. Established in Receipt No. 1: this count measures being quoted into answers, not being read.

    What we do now

    1. Protect the anchor’s freshness. A fifth of the site rides on one guide; it gets the flagship leader’s discipline — the heartbeat watch from Receipt No. 3, at hybrid scale.
    2. Build toward the short phrase carefully. The 8.39% is an invitation, not an emergency: adjacent, specific pages in the supply-chain family — the Receipt No. 1 method — rather than a rewrite of the page that’s already winning its own question.
    3. Keep both pillars fed. Crisis and supply chain are near-equal earners; starving one to feed the other would unbalance the sturdiest shape in the fleet.
    4. Publish the receipts — including the share we don’t hold. The map is the value; a prettier story would be worth less.

    57,798 citations. One guide at 19.2%, two pillars, +39%. The hybrid — and, on the risk arithmetic, maybe the shape to aim for.

    Update history
    November 8, 2026 — Published. The 60-second video version went live on YouTube the same morning (linked at the top of this page); its chapters match the sections below, and each chapter links back to its section.

    Method note: All figures are from Bing Webmaster Tools AI Performance exports for continuityhub.org, pulled November 8, 2026. Citation counts are Microsoft Copilot and partner citations as Bing reports them. Window: August 8–November 5, 2026 (90 days). The daily view sums to 57,798; the page view sums to 55,029 — Bing notes totals may differ across views, and each figure above names its view. Citation shares are Bing’s per-query figures. Guide names are shortened from the pages’ own titles. The “crisis family” and “supply-chain family” counts cover pages whose addresses contain those terms. The R4R Continuity article staged for a grant submission is a different piece and plays no part in these numbers. This is one site, one engine’s report, one 90-day window.

  • The Climb With No Star: A Site That Tripled With No Page in Charge

    The Climb With No Star: A Site That Tripled With No Page in Charge

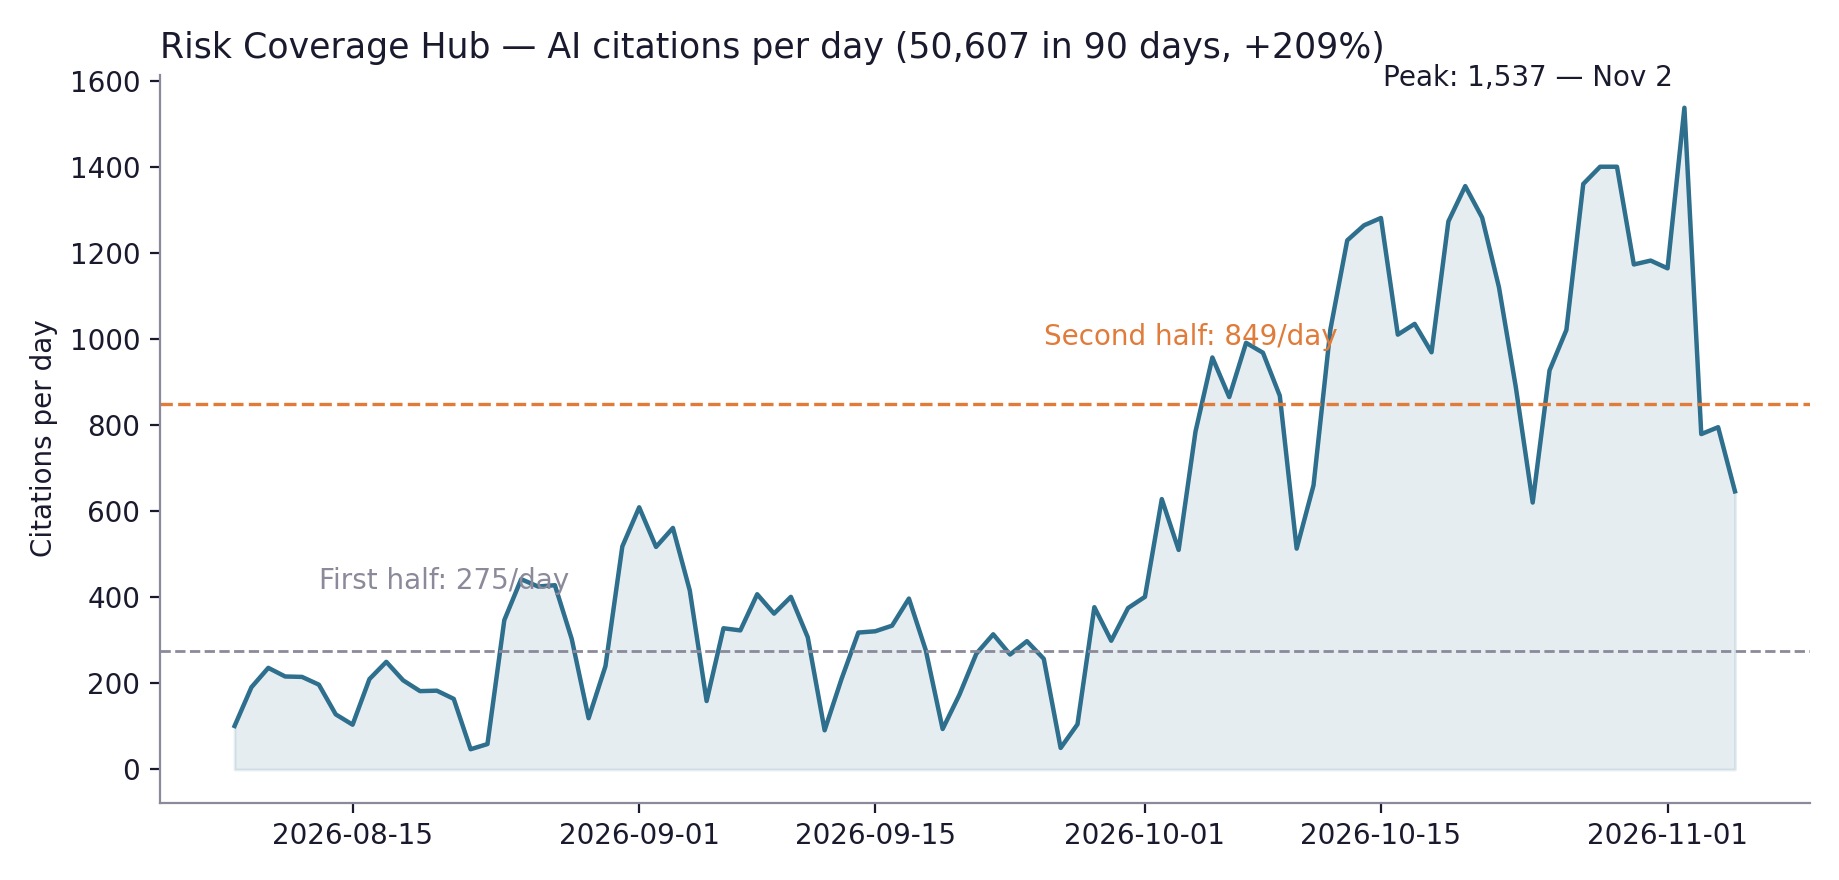
    Receipts No. 3 was about a site with a star: one page holding a third of everything. This one is about the opposite build. Risk Coverage Hub — our insurance-risk reference site — earned 50,607 AI citations in ninety days, and it has no star at all. Its biggest page holds 7.7%.

    What it has instead is growth, and spread. The site’s daily citation rate went from 275 a day to 849 a day between the halves of the window — +209%, the fastest climb in our fleet. First fourteen days: 185 a day. Last fourteen: 1,064 a day. Peak day: November 2, with 1,537.

    Watch the 60-second version: How did a site triple its AI citations with no page in charge? — the same receipts in 50 seconds, chapters matched to the sections below.

    The climb

    The window is August 8 to November 5, 2026, from Bing Webmaster Tools’ AI Performance report — the same instrument as the rest of this series. The daily series sums to 50,607; the page table sums to 47,747. Bing’s views differ (here by 5.7%), Bing prints a note saying so, and we name the view behind every number, as always.

    Read the climb honestly: it isn’t a step. Receipt No. 1 had a step — a build date you could point at. This is a slope. The rate rises across the whole window, halves 275 to 849, and we are not going to invent a single cause for a slope. What we can do is read what the slope is made of — which pages, which questions — because that’s the part an operator can actually use.

    Risk Coverage Hub daily AI citations over 90 days: rising from 275 a day in the first half to 849 a day in the second, peak 1,537 on November 2.
    The climb: 50,607 citations in 90 days, +209% by halves. Source: Bing Webmaster Tools AI Performance, daily view.

    The bench: six guides, no star

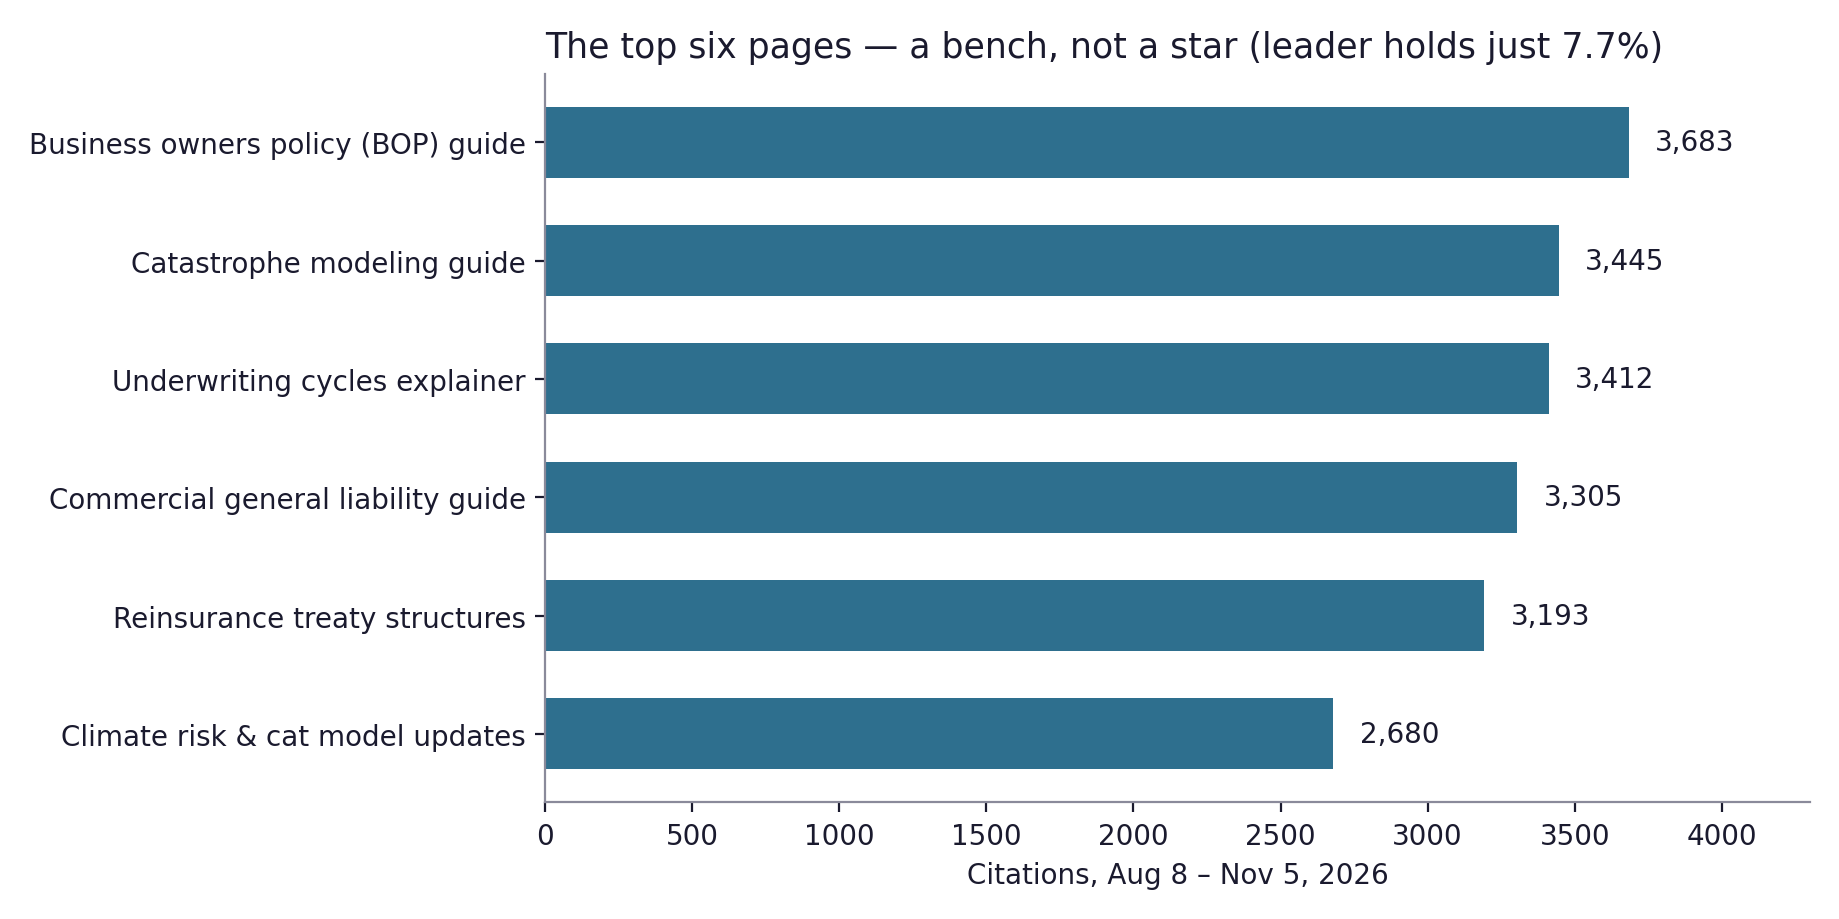
    The top of the page table is bunched like a peloton:

    • Business owners policy (BOP) coverage guide — 3,683
    • Catastrophe modeling, complete guide — 3,445
    • Underwriting cycles: hard and soft markets — 3,412
    • Commercial general liability guide — 3,305
    • Reinsurance treaty structures — 3,193
    • Climate risk pricing & catastrophe model updates — 2,680

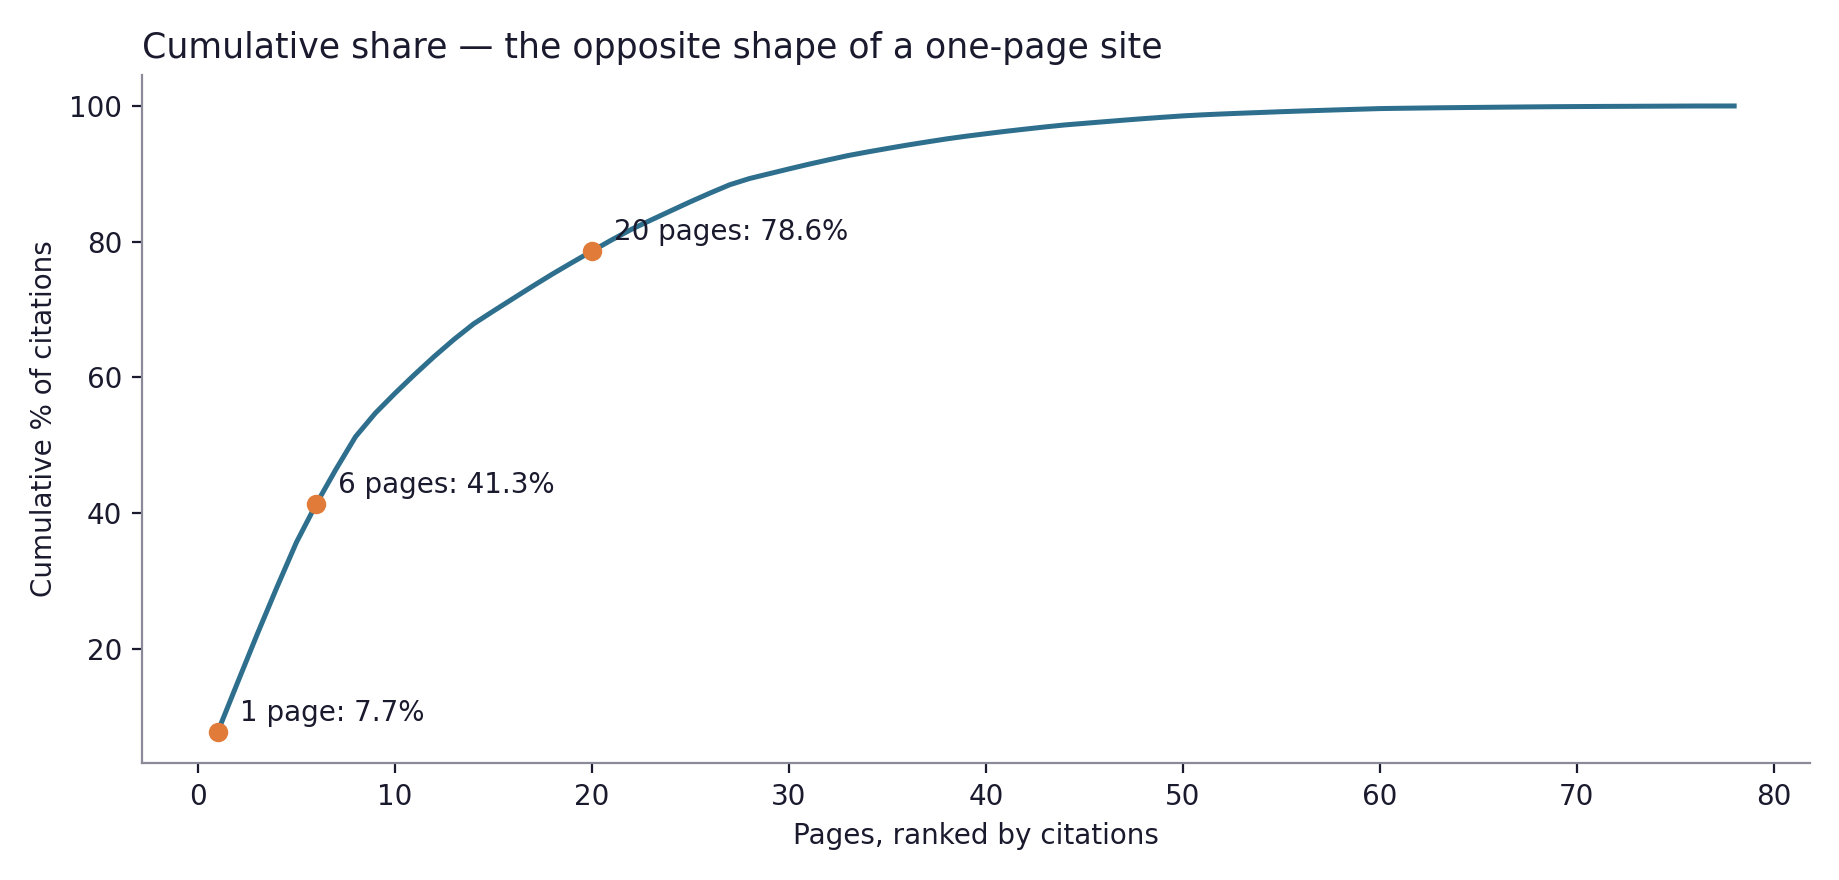
    Six professional guides within a thousand citations of each other. Together they hold 41.3% of the page-sum; the leader alone holds 7.7%. Twenty pages get you to roughly three-quarters of the site — on our flagship, five pages are a majority. This is the diversified portfolio to Receipt No. 3’s concentrated bet, and it carries the mirror-image virtue: no single page’s bad week can wound this site. The bench is the moat.

    Risk Coverage Hub's top six pages, bunched between 2,680 and 3,683 citations; the leader holds just 7.7 percent of the page-sum.
    The bench: six guides, no star. Source: Bing Webmaster Tools AI Performance, page view.
    Cumulative share curve for Risk Coverage Hub: one page is 7.7 percent, six pages 41.3 percent — the opposite shape of a one-page site.
    Cumulative share of the page-sum, pages ranked by citations — contrast Receipt No. 3’s curve, where one page is 30.8%. Source: Bing Webmaster Tools AI Performance, page view.

    The questions: long, specific, professional

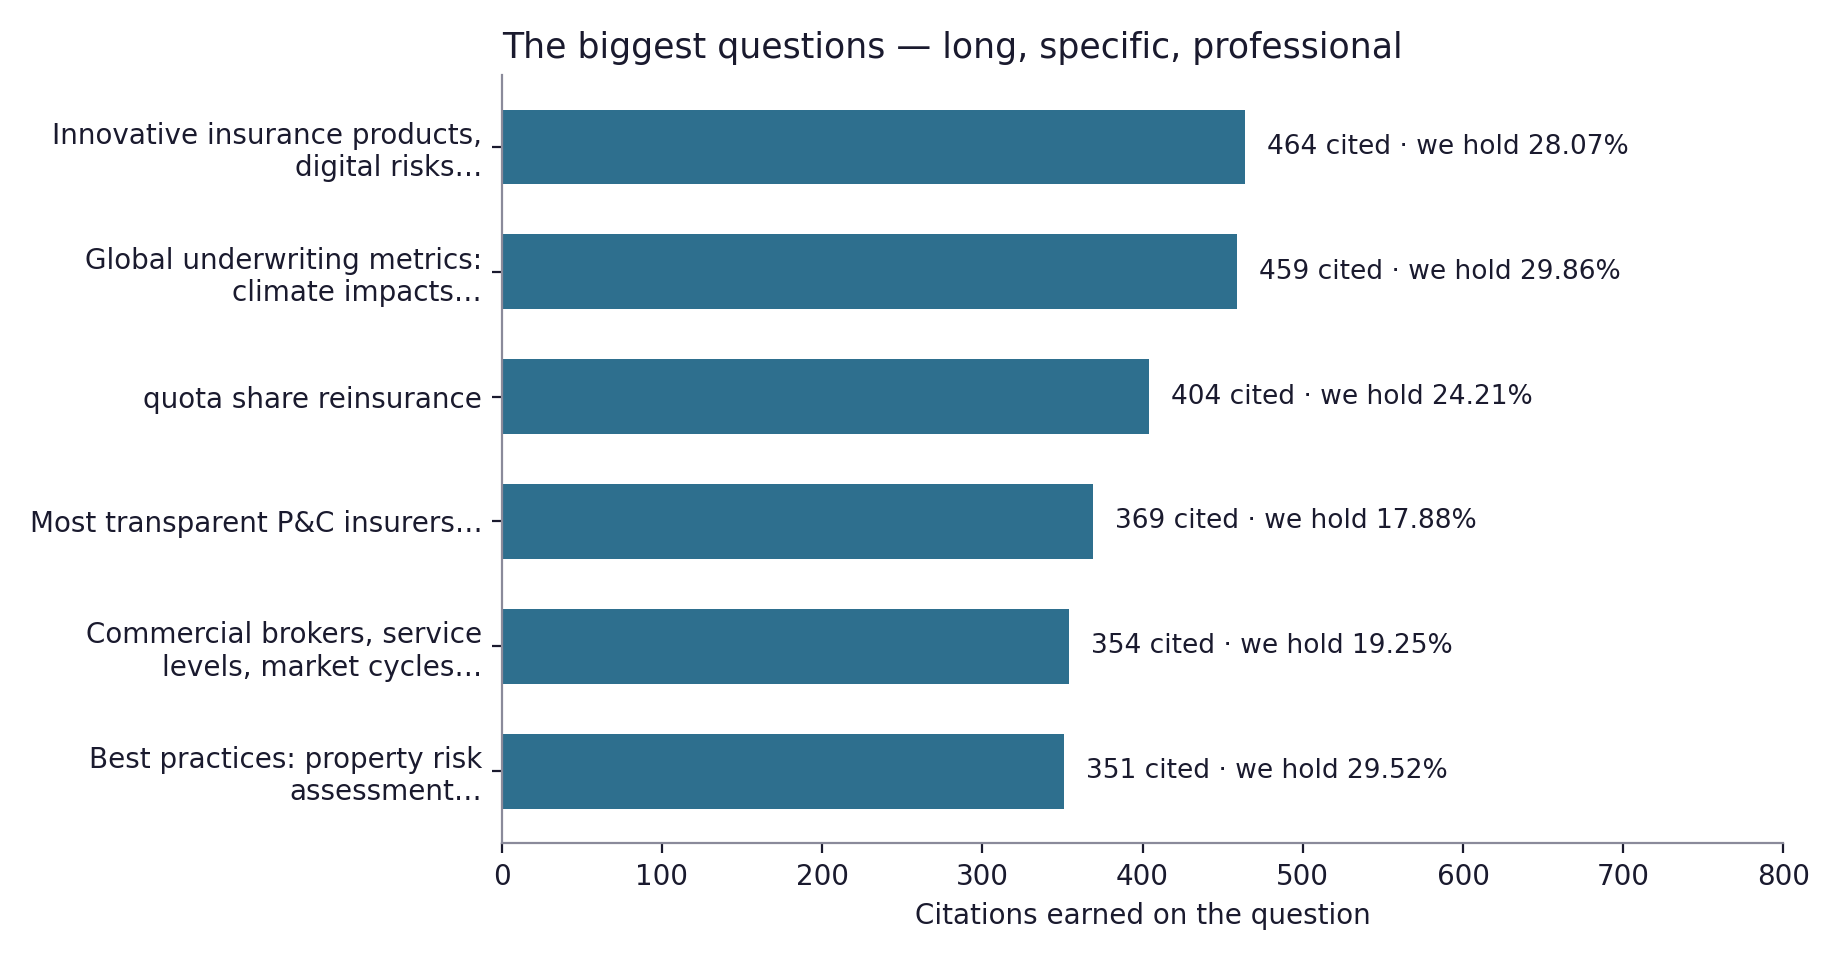
    The query table explains the shape. There is no “what is X” blockbuster here. The biggest questions are working questions, asked the way insurance professionals actually phrase work:

    • “innovative insurance products digital risks cryptocurrency fraud deepfake liability…” — 464 citations; our share 28.07%.
    • “global insurance risk underwriting metrics: evaluating climate disaster impacts on property premiums” — 459; our share 29.86%.
    • “quota share reinsurance” — 404; our share 24.21%. The one short question in the list, and a term of art.
    • “best practices property risk assessment commercial insurance” — 351; our share 29.52%.
    Risk Coverage Hub's biggest questions: long, specific professional queries, with the site holding between a fifth and a third of each.
    The biggest questions, and our share of each. No blockbuster — a working vocabulary. Source: Bing Webmaster Tools AI Performance, query view.

    414 questions, 78 pages — and the shares sit in a band, mostly a fifth to a third. Nobody owns these questions outright, including us. The site earns by being a solid, specific answer across a whole professional vocabulary, not by holding one phrase hostage. That is a slower asset to build and a harder one to knock down.

    What we can’t claim

    • No single cause for the slope. Unlike the stepped sites in this series, nothing here dates the rise to one build. The honest sentence is: the site tripled while publishing steady, specific, professional guides — and correlation across a portfolio is not a mechanism.
    • The views differ more here. Daily-sum 50,607 vs page-sum 47,747 — 5.7% apart, disclosed, each figure naming its view.
    • One engine’s window. Copilot and partner citations as Bing reports them; ninety days is a snapshot, not a deed.
    • Citations are not visits. Established in Receipt No. 1: this count measures being quoted into answers, not being read.

    What we do now

    1. Feed the bench, not a star. The next guides get chosen from the question map where a working question is landing on an adjacent page — the Receipt No. 1 method, applied to a bench instead of a doorway.
    2. Watch for bunching changes. If one page starts separating from the peloton, that’s a signal — good or bad — worth a diagnosis, the way we diagnosed the flagship’s leader in October.
    3. Keep the shares honest. A fifth to a third on the big questions means the work is depth and currency, not defense of a crown we don’t hold.
    4. Publish the receipts — including the part where the growth has no single hero. A slope you can’t attribute is still a slope you can measure.

    50,607 citations. 275 to 849 a day. No star — a bench, a vocabulary, and a climb. That’s the count and the shape.

    Update history
    November 8, 2026 — Published. The 60-second video version went live on YouTube the same morning (linked at the top of this page); its chapters match the sections below, and each chapter links back to its section.

    Method note: All figures are from Bing Webmaster Tools AI Performance exports for riskcoveragehub.com, pulled November 8, 2026. Citation counts are Microsoft Copilot and partner citations as Bing reports them. Window: August 8–November 5, 2026 (90 days). The daily view sums to 50,607; the page view sums to 47,747 — Bing notes totals may differ across views, and each figure above names its view. Citation shares are Bing’s per-query figures. Guide names are shortened from the pages’ own titles. The Risk Coverage Hub underwriting explainer published today (post 1495 on that site) is not a driver of these numbers — it postdates the window. This is one site, one engine’s report, one 90-day window.

  • One Page Holds a Third of This Site’s AI Citations

    One Page Holds a Third of This Site’s AI Citations

    This site — tygartmedia.com, the one you’re reading — earned 813,426 AI citations in ninety days. That’s the whole portfolio: 578 cited pages, 1,698 different questions that assistants asked and answered with our work. One page holds 244,307 of them.

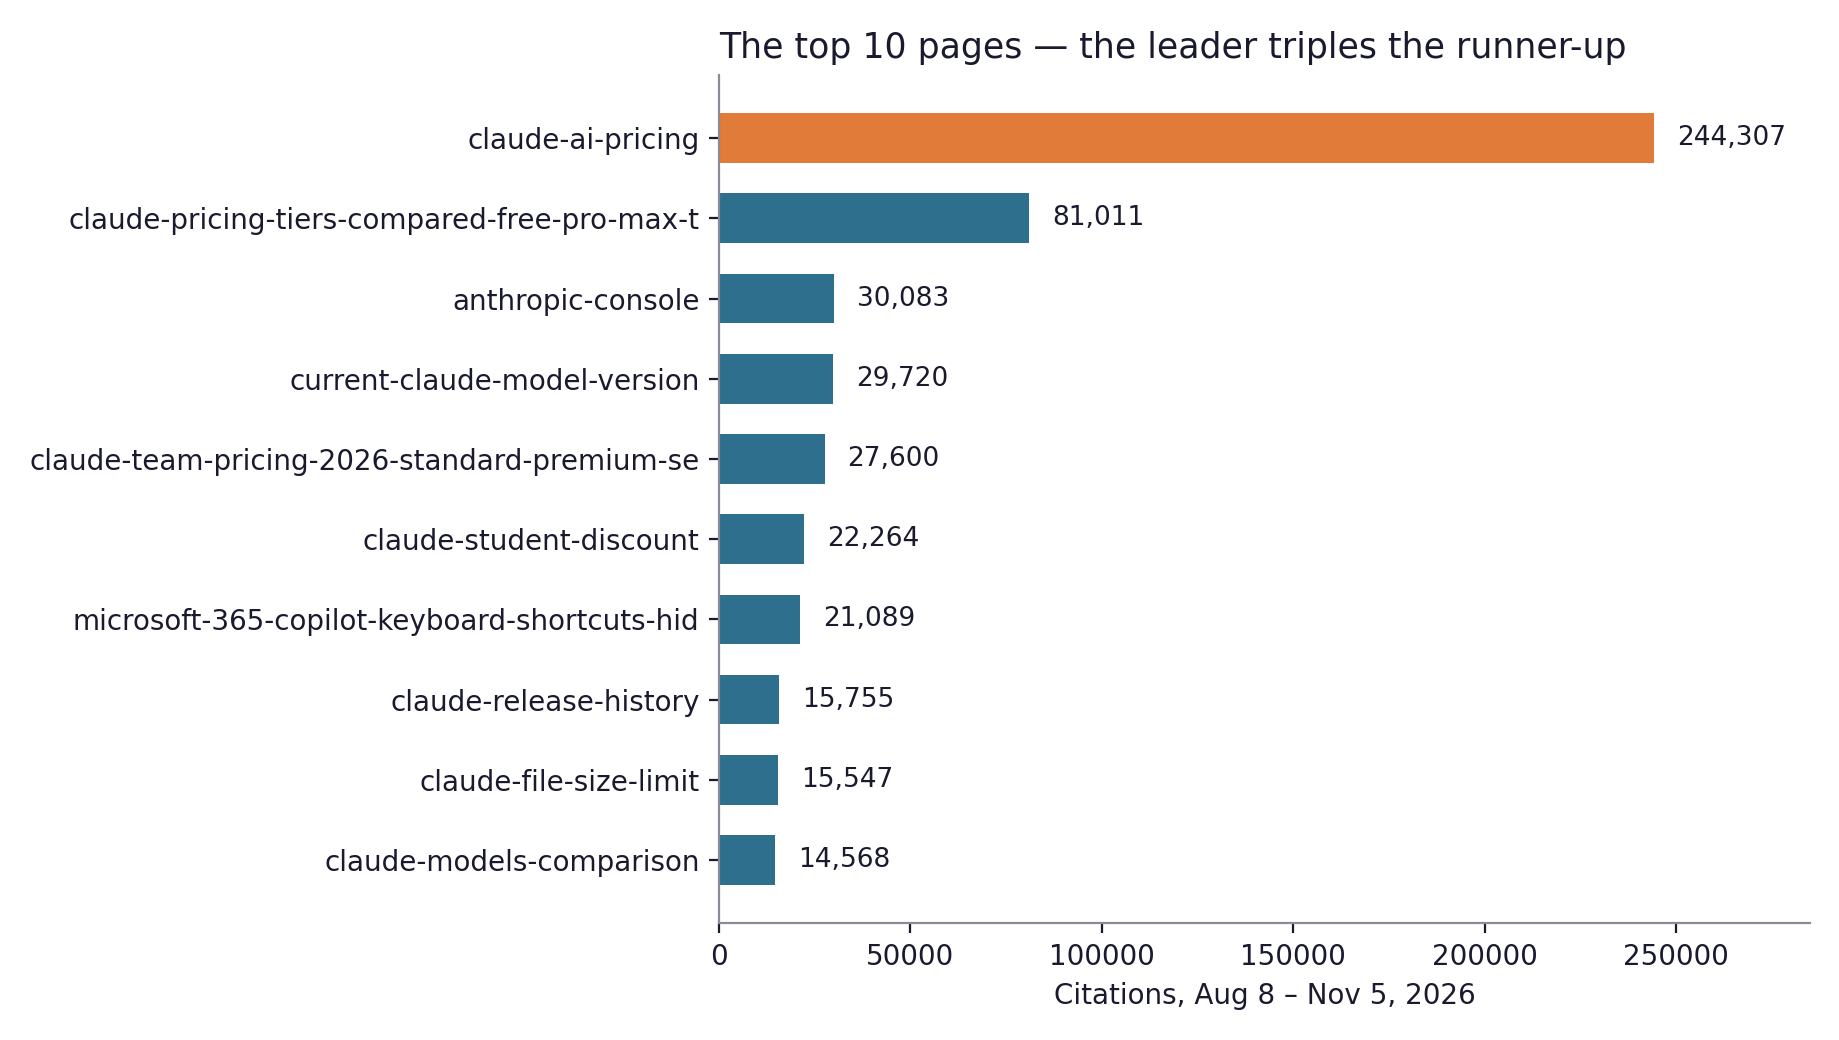
    The page is our Claude pricing page: a plain, kept-current answer to what Claude costs. It holds 30.8% of everything this site earned. The runner-up — our pricing-tiers comparison — holds 81,011. The leader triples it.

    This is Receipts No. 3, and it’s the uncomfortable one. The first two pieces in this series were about growth — a hospital site stepping up, two doors built in a night. This one is about shape: what it means when a third of your citation count lives at one address.

    Watch the 60-second version: Why does one page hold 244,307 of this site’s AI citations? — the same receipts in 49 seconds, chapters matched to the sections below.

    The count

    The window is August 8 to November 5, 2026, from Bing Webmaster Tools’ AI Performance report — the same instrument as the rest of this series. The daily series sums to 813,426; the page-level table sums to 792,317. Bing’s own views disagree by 2.6%, and Bing prints a note saying totals may differ across views. We use each view for what it measures and say which is which, every time.

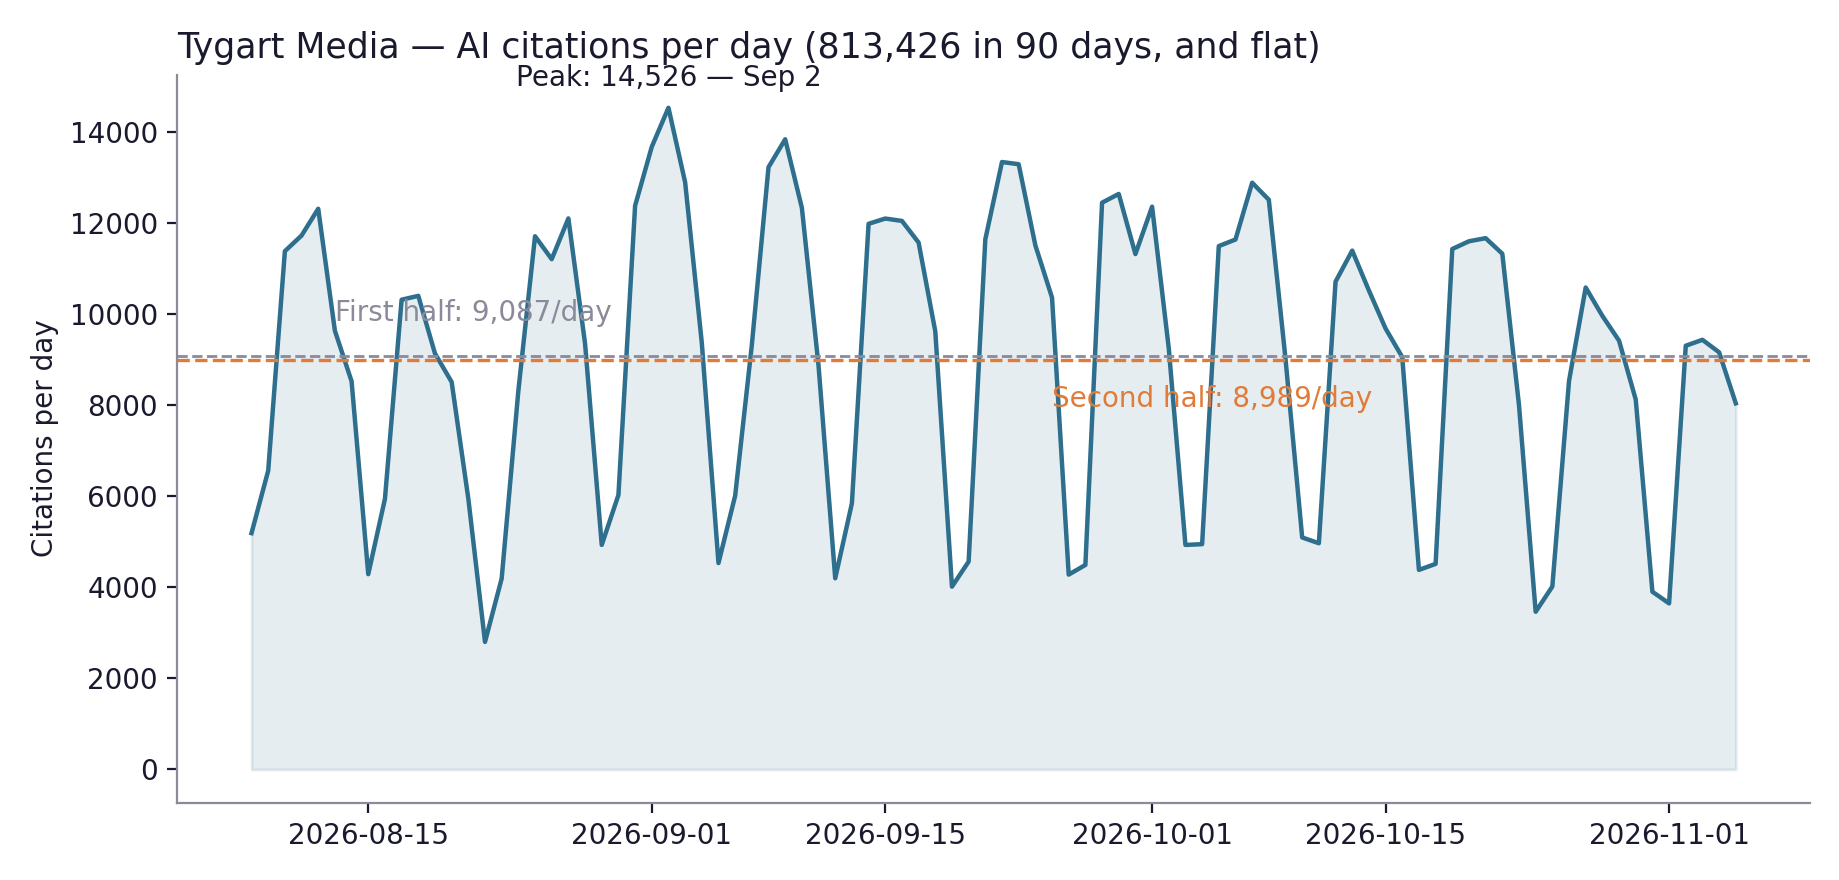
    The site’s halves are flat: 9,087 citations a day in the first half of the window, 8,989 a day in the second. Peak day: September 2, with 14,526. Nothing about the total is a growth story. The total is a plateau — and a plateau is exactly where shape matters, because the composition is the whole story.

    Daily AI citations for tygartmedia.com over 90 days: flat halves at about nine thousand a day, peak 14,526 on September 2.
    The plateau: 813,426 citations in 90 days, halves flat. Source: Bing Webmaster Tools AI Performance, daily view.

    The shape of the portfolio

    Read the page table by rank and the portfolio stops looking like a portfolio:

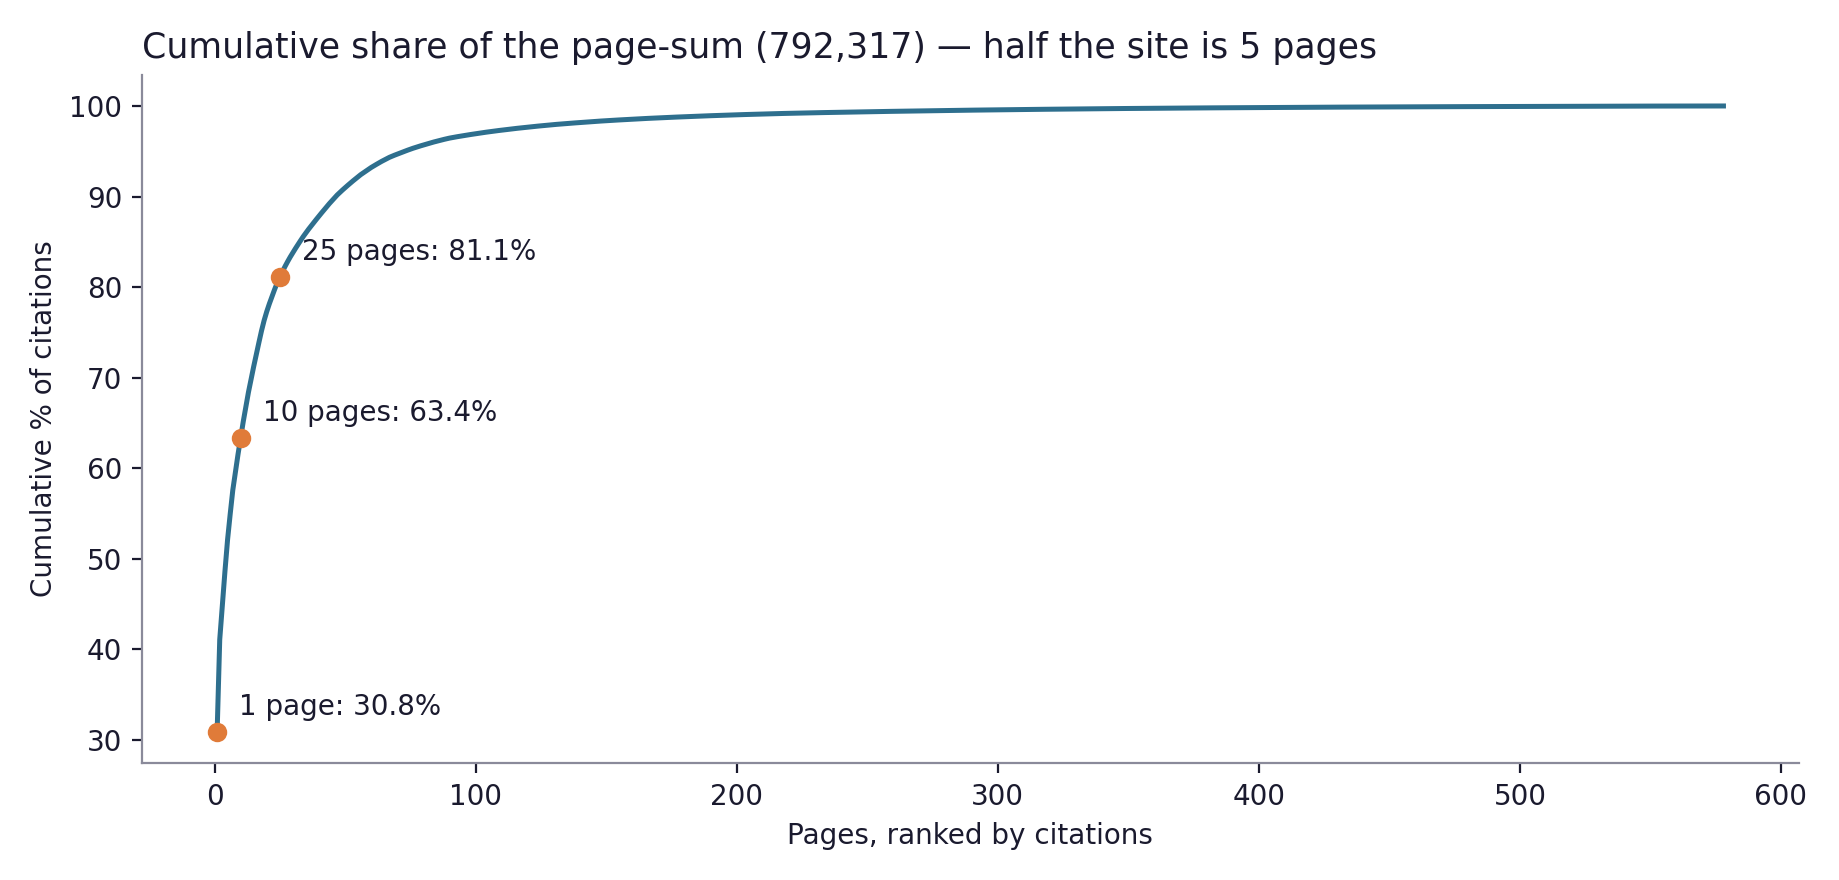
    • 1 page holds 30.8% of the page-sum.
    • 3 pages hold 44.9%. 5 pages hold 52.1% — a majority of the site is five addresses.
    • 10 pages hold 63.4%. 25 pages hold 81.1%.
    • The remaining 553 pages share what’s left — about 19% between them.
    Top ten cited pages on tygartmedia.com: the Claude pricing page at 244,307, triple the runner-up at 81,011.
    The top 10 pages. The leader isn’t ahead — it’s in a different weight class. Source: Bing Webmaster Tools AI Performance, page view.
    Cumulative share curve: one page is 30.8 percent of the page-sum, ten pages are 63.4 percent, twenty-five are 81.1 percent.
    Cumulative share of the page-sum, pages ranked by citations. Source: Bing Webmaster Tools AI Performance, page view.

    And the concentration has a subject. Thirty-six of the 578 pages are pricing pages — their addresses carry “pricing” or “cost” — and together they hold 396,978 citations: 50.1% of everything. Half this site’s citation count is one question family, asked over and over in slightly different words: what does Claude cost, what does the Team plan cost, is there a student discount, what does Enterprise run. We didn’t set out to become a pricing reference. The assistants decided that’s what this site is for — and the page table is what that decision looks like from the inside.

    The questions are bigger than the page

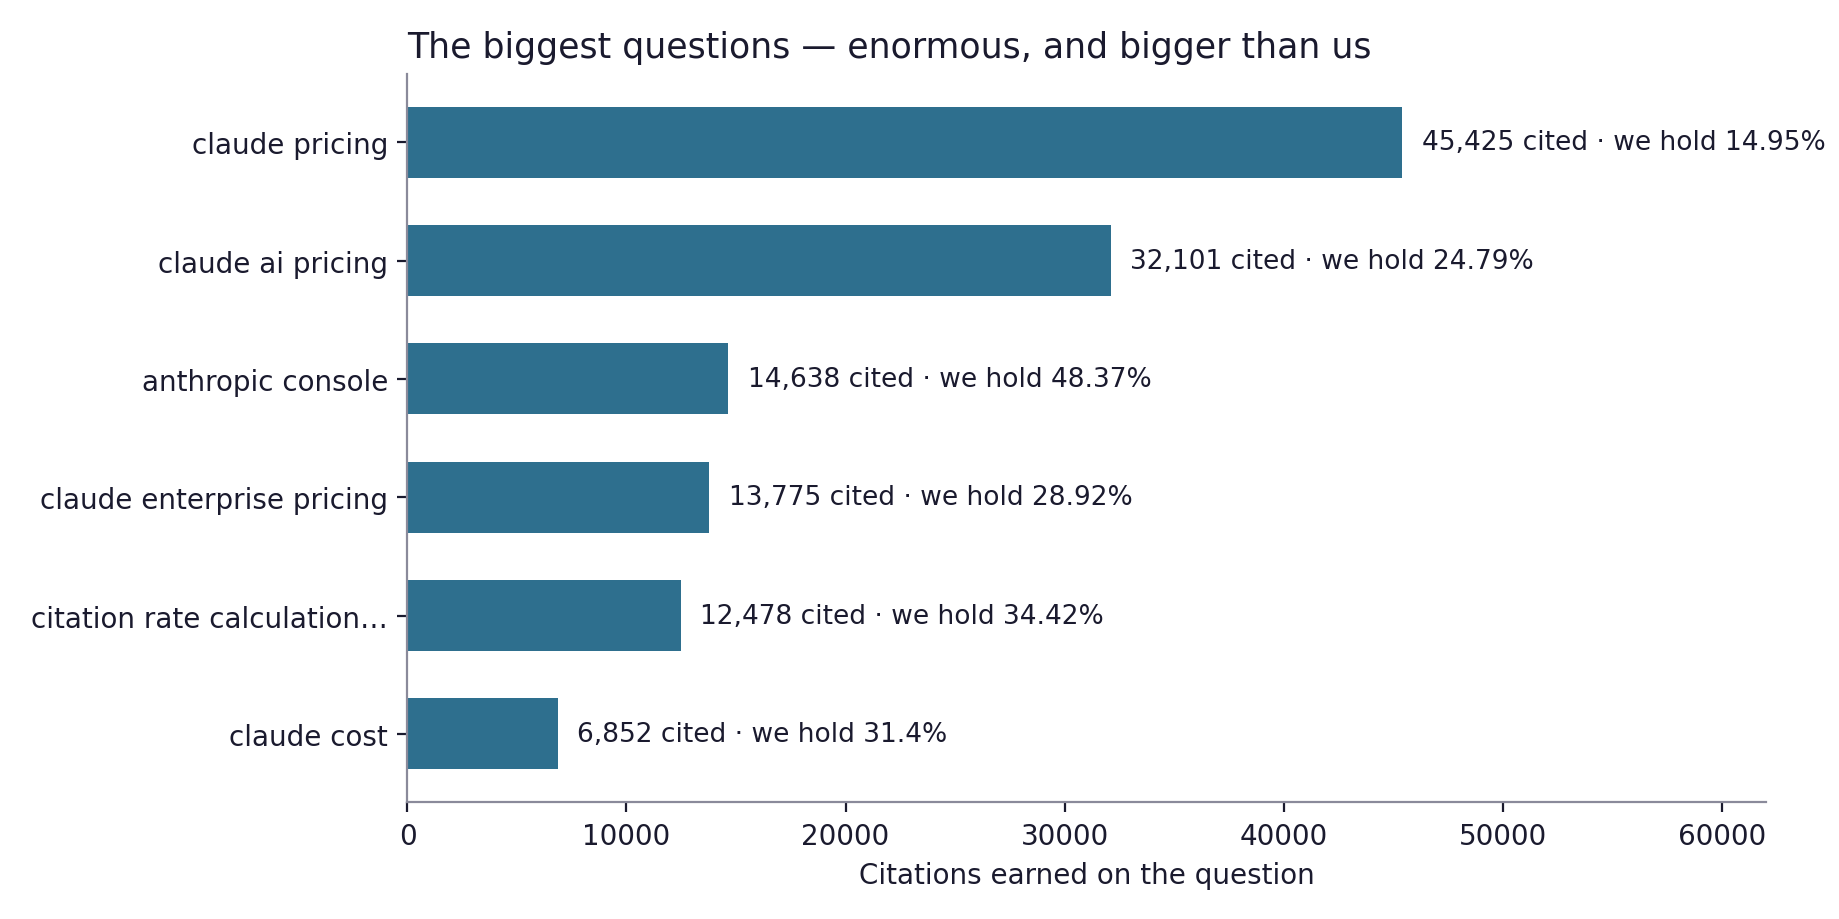
    Here’s the part that keeps the story honest. The pricing page is enormous — and on the biggest question it serves, we are a minority holder:

    • “claude pricing” — 45,425 citations earned across the web’s answers; our share is 14.95%.
    • “claude ai pricing” — 32,101 citations; our share 24.79%.
    • “anthropic console” — 14,638; our share 48.37%, the strongest hold on a big question.
    • “claude enterprise pricing” — 13,775; our share 28.92%.
    • And at number five, a tell: “citation rate calculation AI-generated responses” — 12,478 citations at a 34.42% share. That’s our own trade, reading about the instrument itself.
    The biggest questions asked of the site, with Tygart Media's citation share on each: the biggest question is one where the site holds under fifteen percent.
    The biggest questions, and our share of each. The page is huge; the questions are bigger. Source: Bing Webmaster Tools AI Performance, query view.

    A page can hold a third of a site and a seventh of its biggest question at the same time. Both numbers are true, and the second one is the opportunity measured precisely: the demand under the leader is roughly seven times the leader.

    What concentration means

    Two things, and they’re the same fact read from opposite ends.

    It’s a moat. A page that answers a money question plainly, stays current, and gets cited 244,307 times becomes the reference the assistants reach for — and every citation is a small vote that makes the next one likelier. Nobody at this desk did anything exotic to earn it. The page does one job, in the asker’s words, and it’s kept honest. That’s the whole trick, and Receipt No. 1 showed what happens when you build that shape on purpose.

    It’s a single point of failure. If that page stumbles — a pricing change at Anthropic that makes it stale overnight, a careless rewrite, a bad week — a third of this site’s citation count reprices with it. We don’t have to imagine the exposure; we watch it. In October we ran a full formal diagnosis on this one page — its pattern had broken in ways we needed explained before we touched anything. You don’t commission a diagnosis for a page that doesn’t matter. You commission one for the page that carries the building.

    The hedge is the bench. The tiers comparison at 81,011 is a genuine understudy — same question family, different cut. Team pricing, the student discount page, the console page: the family is deep, and the family is the insurance. Concentration at the page level, diversification at the family level. That’s the actual structure, and it happened before we were wise enough to plan it.

    What we can’t claim

    • One engine’s window. These are Copilot and partner citations as Bing reports them. It’s the cleanest instrument we have; it is not the whole sky.
    • The views differ. Daily-sum 813,426 vs page-sum 792,317 — 2.6% apart, disclosed above, used consistently.
    • Citations are not visits. Receipt No. 1 established it on another of our sites: 57 citations per human visit. This count measures being quoted, not being read.
    • Ninety days is a snapshot, not a deed. Questions mutate — the BC ESG piece watched pharma’s biggest phrasing change between pulls. Shares move. This is the shape on November 8, 2026.

    What we do now

    1. Watch the leader’s daily line like a heartbeat — not the site’s total, which can hide a dying leader inside a healthy plateau for weeks.
    2. Keep the bench current. The understudy pages get the same freshness discipline as the star; the day the leader stumbles is the wrong day to start.
    3. Build adjacent doors the measured way — when the question map shows demand landing sideways (Receipt No. 1’s method), build the page the question is asking for.
    4. Publish the receipts — including the shape we’d rather not have. A third of the building on one page is a fact we’re better off saying out loud, because saying it is what keeps us watching it.

    813,426 citations. 244,307 of them at one address. That’s the count, that’s the shape, and that’s what we’re doing about it.

    Update history
    November 8, 2026 — Published. The 60-second video version went live on YouTube the same morning (linked at the top of this page); its chapters match the sections below, and each chapter links back to its section.

    Method note: All figures are from Bing Webmaster Tools AI Performance exports for tygartmedia.com, pulled November 8, 2026. Citation counts are Microsoft Copilot and partner citations as Bing reports them. Window: August 8–November 5, 2026 (90 days). The daily view sums to 813,426; the page view sums to 792,317 — Bing notes totals may differ across views, and each figure above names its view. Citation shares are Bing’s per-query figures. The “pricing family” count is pages whose addresses contain “pricing” or “cost.” The October diagnosis referenced was an internal workup of the pricing page’s citation pattern. This is one site, one engine’s report, one 90-day window.

  • The Page the Machines Cite Most Is the One the Humans Actually Read

    The Page the Machines Cite Most Is the One the Humans Actually Read

    Receipts, No. 2 — Healthcare Facility Hub. First in this series: We Watched the Questions AI Was Asking Our Site.

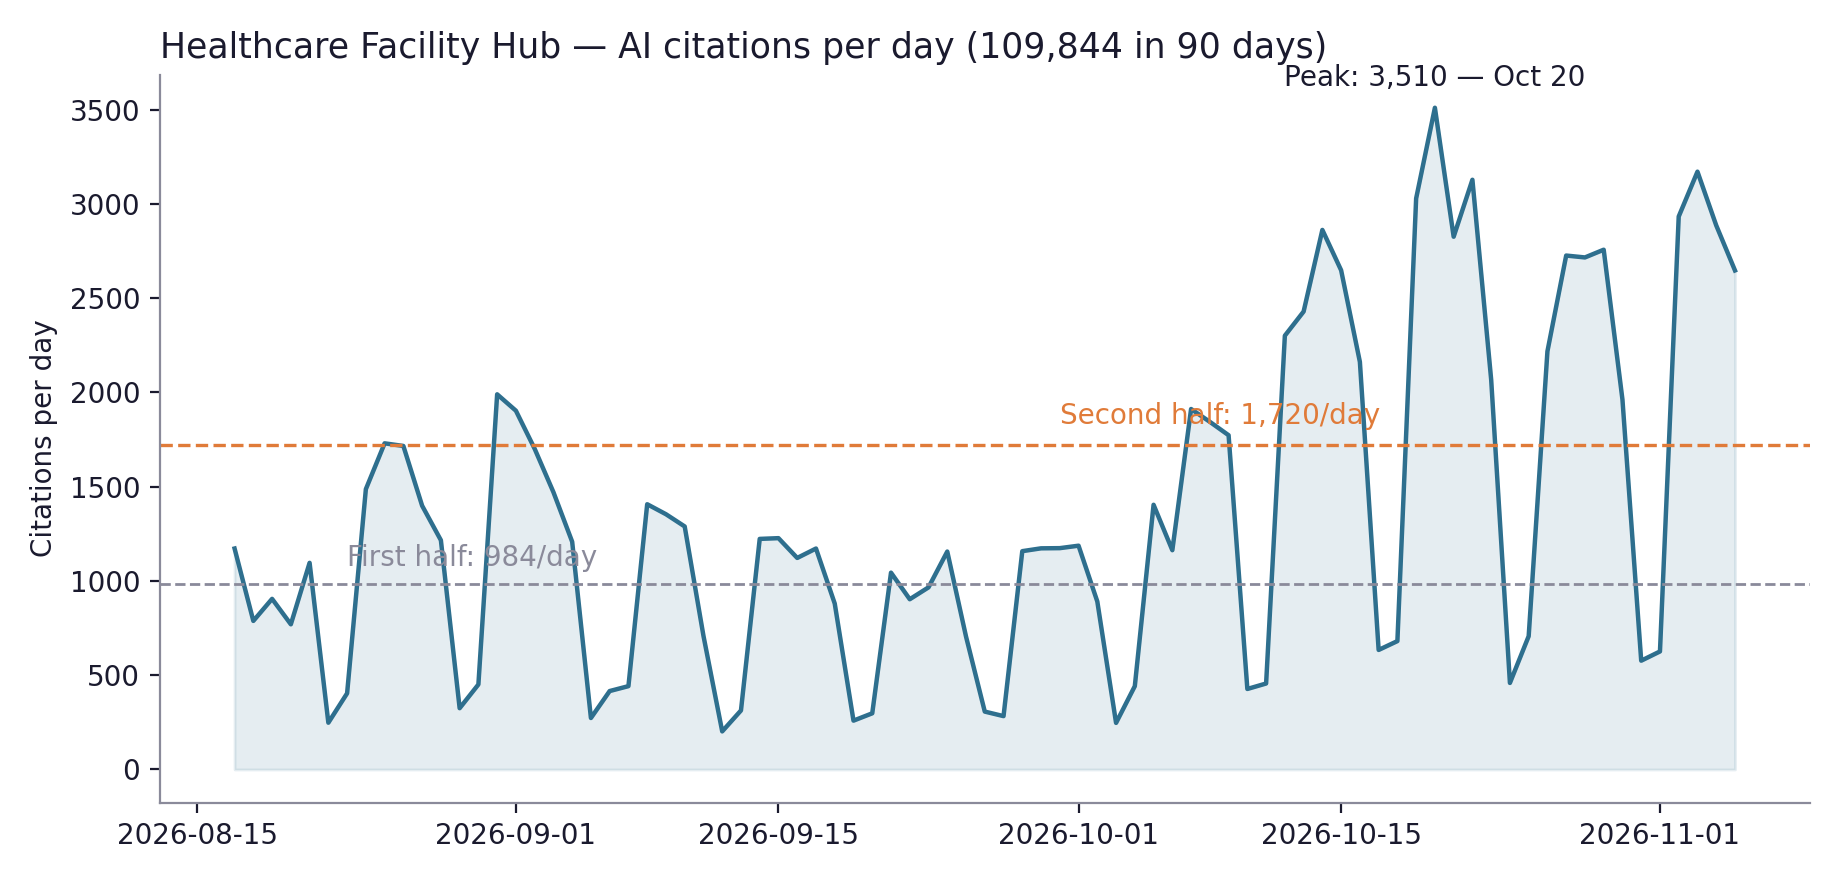
    In October we believed one of our sites was declining. We said so in writing, with a chart. The chart was honest; the window was the problem — it ended October 4, and Healthcare Facility Hub spent the rest of October doing the opposite of declining.

    This morning we pulled the full ninety days. Between August 7 and November 6, AI answers cited Healthcare Facility Hub 109,844 times. The first half of the window averaged 984 citations a day; the second half averaged 1,720 — up 75%. The last fourteen days ran at 2,032 a day, and the peak, October 20, hit 3,510. It is the fastest-growing property we run.

    So we went looking for its biggest page, expecting to find the usual pattern from the rest of the fleet: a page the machines read and the humans barely visit. We found the opposite. This is the story of that page — including the part where we shipped its companion file split in two and the citations divided themselves between a summary and the real thing.

    Watch the 60-second version: Why does one hospital page get cited 11,181 times by AI? — the same receipts, in 52 seconds, with chapters matched to the sections below.

    The page

    The page is a guide: What Is ICRA in Healthcare? (ASHE 2.0) — infection control risk assessment for construction and maintenance work in occupied hospitals. It holds 11,181 citations, the most-cited page on the site, about a tenth of everything. Around it sits a small family: a sibling ICRA guide at 2,053, a Class IV–V requirements page at 173, a matrix explainer at 121, a class finder at 23.

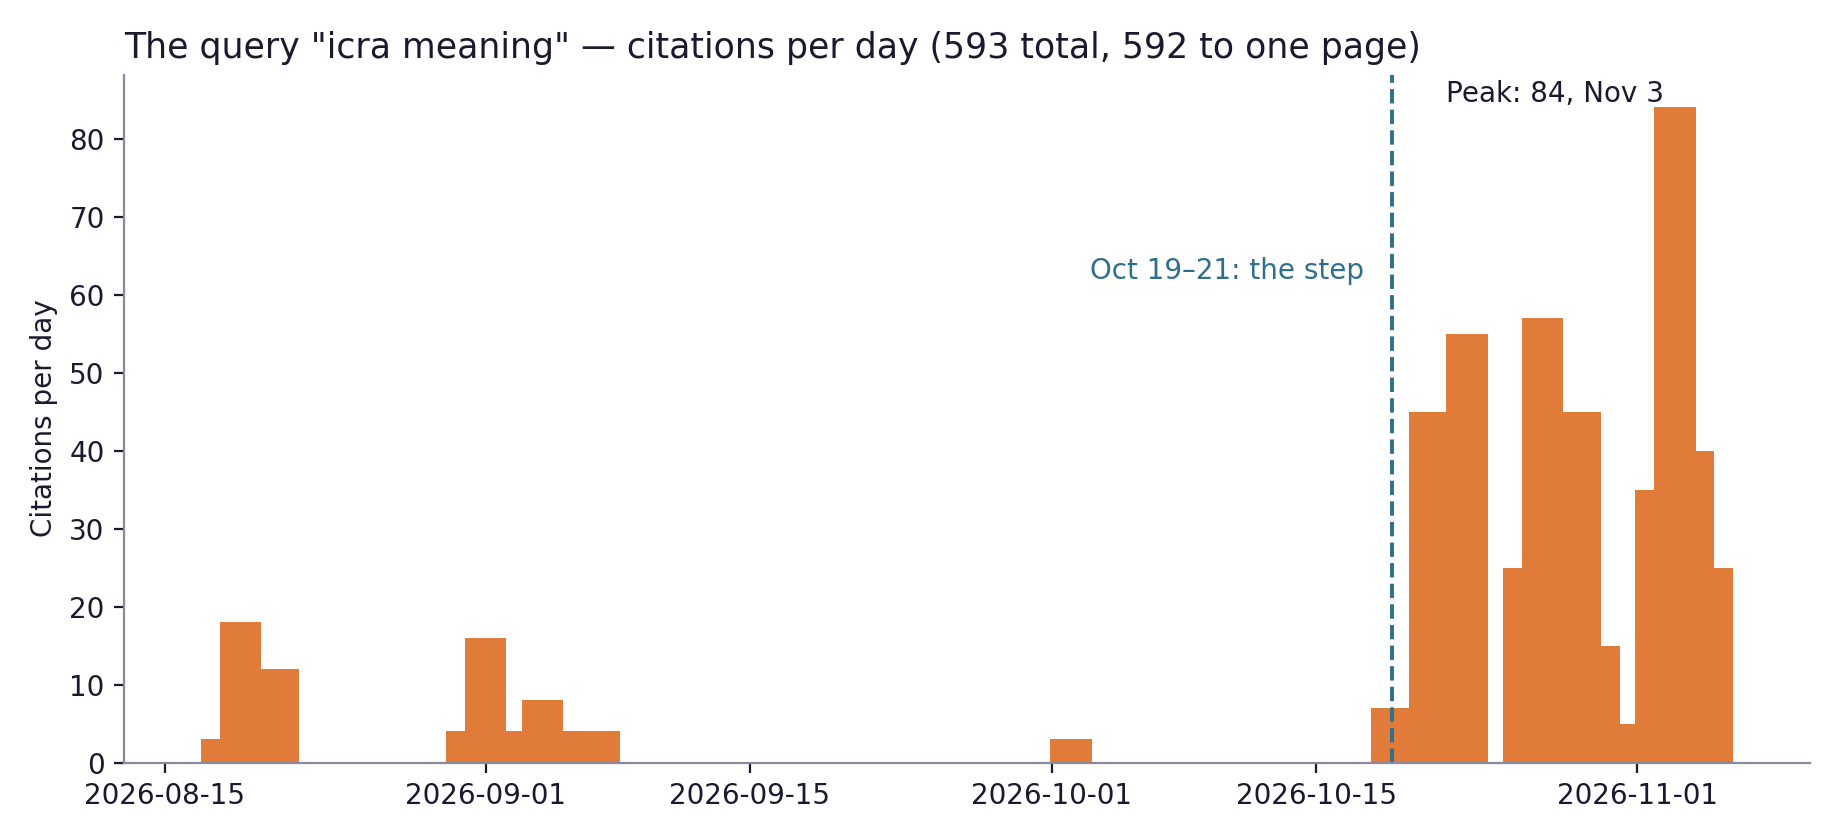
    The query that feeds it hardest is plain: “icra meaning.” Five hundred ninety-three citations, and 592 of them land on this one page. Its daily rhythm tells the build story. Through mid-October it ran flat, a handful a day. Then, on the October build dates, it stepped: 45 on October 21, 55 on the 23rd, 57 on the 27th, peaking at 84 on November 3.

    Then we checked the humans

    On the beauty-industry site in our first report, the pattern was stark: hundreds of citations, a handful of human sessions, visits that lasted about ten seconds. Machines verifying, nobody reading.

    The ICRA page breaks that pattern completely. Microsoft Clarity, last thirty days: 231 human sessions (seventeen bot sessions excluded), 162 people, an average of 4.4 active minutes inside a 7.8-minute visit, 1.72 pages per session, scroll depth 36%, zero rage clicks, almost no friction. Three quarters of them arrive from Bing search. And the browser split gives the audience away: 73.6% Microsoft Edge, 88% desktop. That’s facilities and infection-prevention staff on managed hospital workstations, in the middle of a workday, using a page to do a job.

    The site as a whole is built the same way: 2,412 human sessions in thirty days against 1,091 bot sessions excluded — the most human audience in our fleet. The machines cite this site the fastest-growing amount, and the humans actually read it. Both. At the same time. On the same pages.

    The machinery question, again

    Our first report noted that the beauty site had no llms.txt file and full FAQ schema on its winning guides. Healthcare Facility Hub is the mirror image: it has an llms.txt, and its most-cited page carries no FAQ schema at all — video markup, breadcrumbs, speakable, that’s it. Opposite machinery, same explosion. Whatever is being selected here, it isn’t a schema flavor.

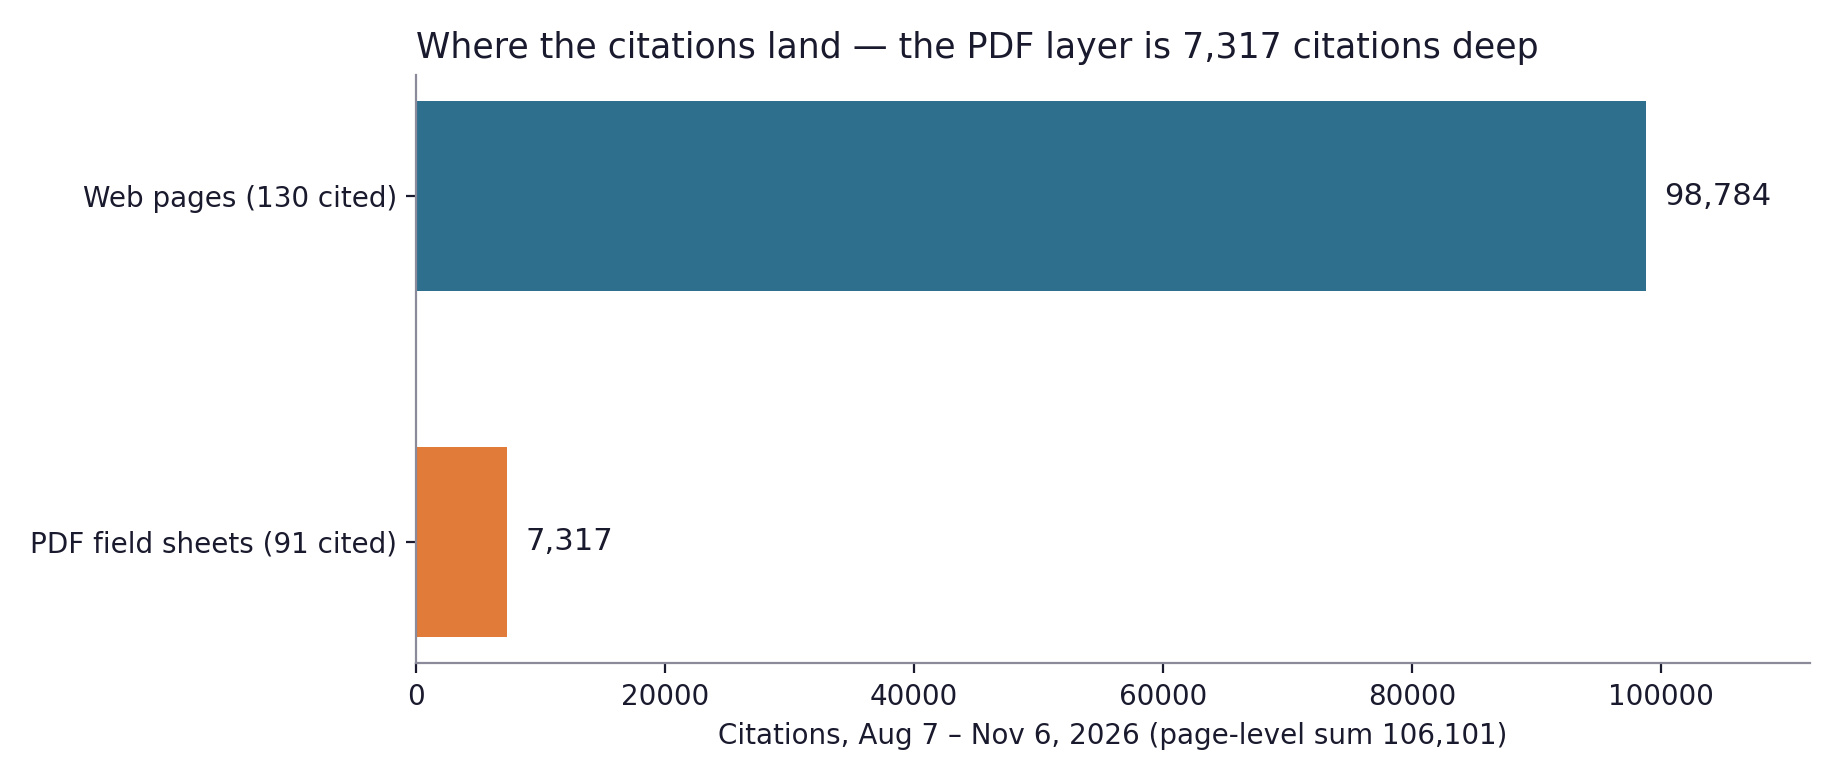
    What the two winners share is more ordinary: one real question answered completely on one page, and a downloadable artifact attached to it — a field sheet a person (or an agent) can take away. On this site that second layer is not small: 91 cited PDF field sheets hold 7,317 citations — compliance checklists for the Joint Commission, evacuation, fire drills, medical gas. Books for bots, and for the people who print them.

    What we got wrong

    Here is the part we would rather skip, which is exactly why it’s in the report.

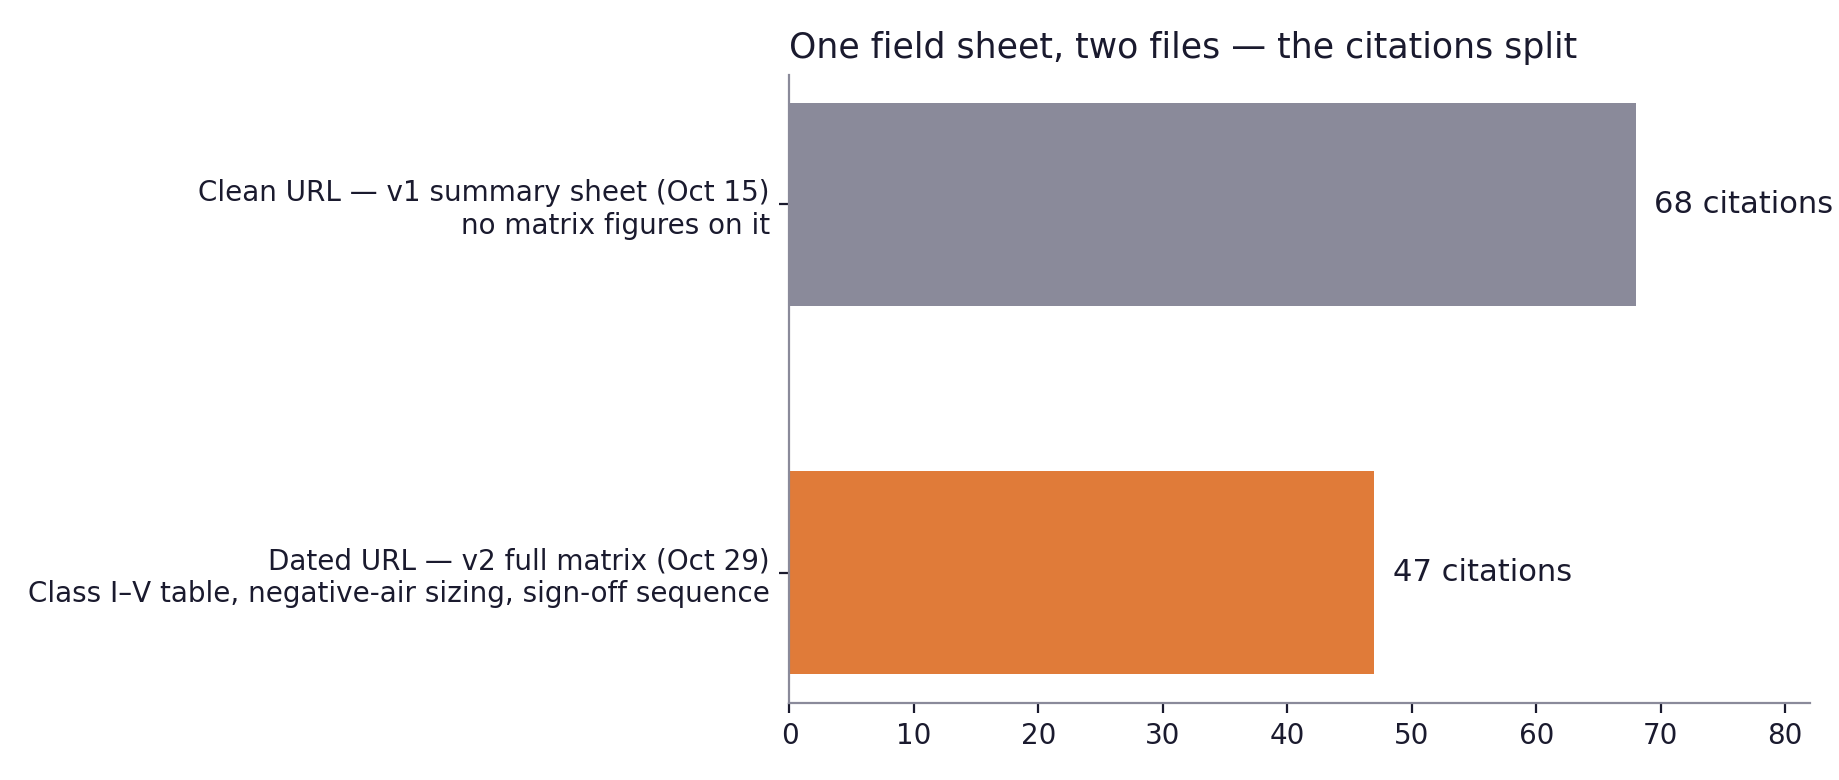
    The ICRA guide links its field sheet twice — and the two links go to two different files. The first version, published October 15, sits at the clean, obvious filename. It is a summary sheet: the direct answer, the framing, no numbers — the actual Class I–V barrier matrix is not on it. It holds 68 citations.

    On October 29 we published the real sheet — the full matrix, barrier requirements by class, negative-air sizing, the decommissioning sign-off sequence, stamped on its face as the current version. But it went up under a new, dated filename instead of replacing the old file. It holds 47 citations. An email-gate on the same page points at the clean filename too, so the older, thinner sheet has a third door in.

    A page and its download are supposed to be one asset, saying one thing. Ours said two, and the citation record split along the seam — with the lead going to the version that has less in it. Anybody who followed the most-cited link got the summary. Anybody who followed the page’s own button got the matrix. We built both halves of that on purpose, two weeks apart, and never noticed the seam until we pulled the page-level export this morning.

    The fix is two file renames, and nothing else. The October 15 file moves to an archive name — its bytes preserved, its history intact. The October 29 sheet takes the clean filename. The page doesn’t change; no link anywhere changes. Every door — the page, the email gate, the citation record — then opens onto the full matrix.

    As this publishes, the fix is staged and waiting on a server door, not on a decision: the file host has refused our automated connections this morning, so the two renames run the moment that door reopens, or by hand in the hosting panel. When it lands, this article gets a dated line below saying so — the same update-lineage rule we apply to the pages themselves. If you’re reading this without that line, the fix is still in flight and we’d rather tell you that than round it off.

    What we’d tell another operator

    Check your cited PDFs for version splits. If a page was ever refreshed by uploading a new file instead of replacing the old one, you may have two assets dividing one citation record — and the split favors whichever file got the cleaner name, not whichever is better. This took one page-level export to find.

    Read the session data before you call a page machine-only. The fleet’s loudest page turned out to have its most human audience. The machines and the people are not reading different sites; on the good pages, they’re reading the same one.

    A trend is a window, not a verdict. We wrote “declining” in October because our window ended October 4. The site was already turning. The correction cost us nothing but a sentence — because the first claim was in writing, with its dates on it.


    Method. Bing Webmaster Tools, AI Performance, pulled November 8, 2026, window August 7–November 6, 2026. Daily totals sum to 109,844; the page-level sum runs slightly lower (106,101) — Bing notes totals can differ between views. Query figures from the filtered pull for “icra meaning” (593 total; 592 to the ICRA guide, 1 to a sibling). Microsoft Clarity figures are the last 30 days, bot sessions excluded as reported; the citation and session windows differ, so comparisons between them are directional. Field-sheet contents verified by reading both files this morning.

    The full dataset — every chart above, the site table, and the field-sheet comparison — is in the companion field report: Built for the Question: Healthcare Facility Hub (PDF).

    Working on a site where AI answers are sending mixed signals? Book a call with Will Tygart.

    Update history

    November 8, 2026 — Published. Field-sheet consolidation staged; completion line to be added here when the renames verify live.
    November 8, 2026 — The 60-second video version published on YouTube (linked at the top of this page); its chapters match the sections below, and each chapter links back to its section.

  • We Watched the Questions AI Was Asking Our Site. Then We Built the Answers.

    We Watched the Questions AI Was Asking Our Site. Then We Built the Answers.

    In early October, a spreadsheet landed on my desk that I can’t stop thinking about.

    It was an export from Bing Webmaster Tools — the AI Performance report for BC ESG, one of the sites we run. Filtered to a single question people were asking AI assistants: “pharmaceutical companies esg executive compensation.” Five days, October 1–5: 51 citations. Our pages, being read into AI answers about how drug companies tie executive pay to sustainability targets.

    Here’s the thing. We had never built a page for that question. The citations were landing on a generalist compensation guide — a good page, but a sideways answer to a specific question. The demand was real, measured, and unanswered on purpose by nobody. It was just there.

    We did try to find out what sparked it. There was movement around a company — I’m not naming it, because we never could source it, and guessing in public is how you become the thing we don’t want to be. So we made a rule out of it: build on the demand you can measure, never on the attribution you can’t. The demand we could measure. So we went and measured all of it.

    Watch the 60-second version: How did two missing pages step AI citations from 11 a day to 30? — the same receipts in 56 seconds, chapters matched to the sections below.

    The map: count everything before you build anything

    On October 19 we pulled the full report — every query, every page, counted by value instead of skimmed. The clusters that mattered:

    • Beauty companies, executive pay, sustainability targets — 68 citations on the main phrasing, more scattered across variants. Again: no dedicated page. The generalist guide was absorbing all of it.
    • Pharmaceutical executive comp — 51 citations across four related phrasings.
    • ICMA green bond principles — 159 citations at a 45.43% citation share. The site’s #1 query — and this one already had real pages behind it.
    • Pay-equity reporting — small. 9 citations. Noted, not built.

    Two of the four clusters were demand with no door built for it. That’s the whole insight, and it’s not complicated: AI assistants were asking our site specific questions, and we were answering adjacent ones.

    The build: one night, two pages

    That same night — October 19 — we published two guides:

    The rules we built them by:

    1. One real question per page, in the asker’s own words. The page’s address is the question, word for word — because that’s the string the assistants are already carrying.
    2. Answer first. No throat-clearing, no “in today’s rapidly evolving landscape.” The answer is at the top; the depth is below it for whoever wants it.
    3. Every page carries its download. Each guide has a companion PDF — a scorecard pack, a design pack. A page and its PDF are one asset. If the content changes, both change, same run. You’ll see why in a minute.

    Then we waited. Three weeks later — this morning — we pulled the reports again and counted.

    What happened: the step

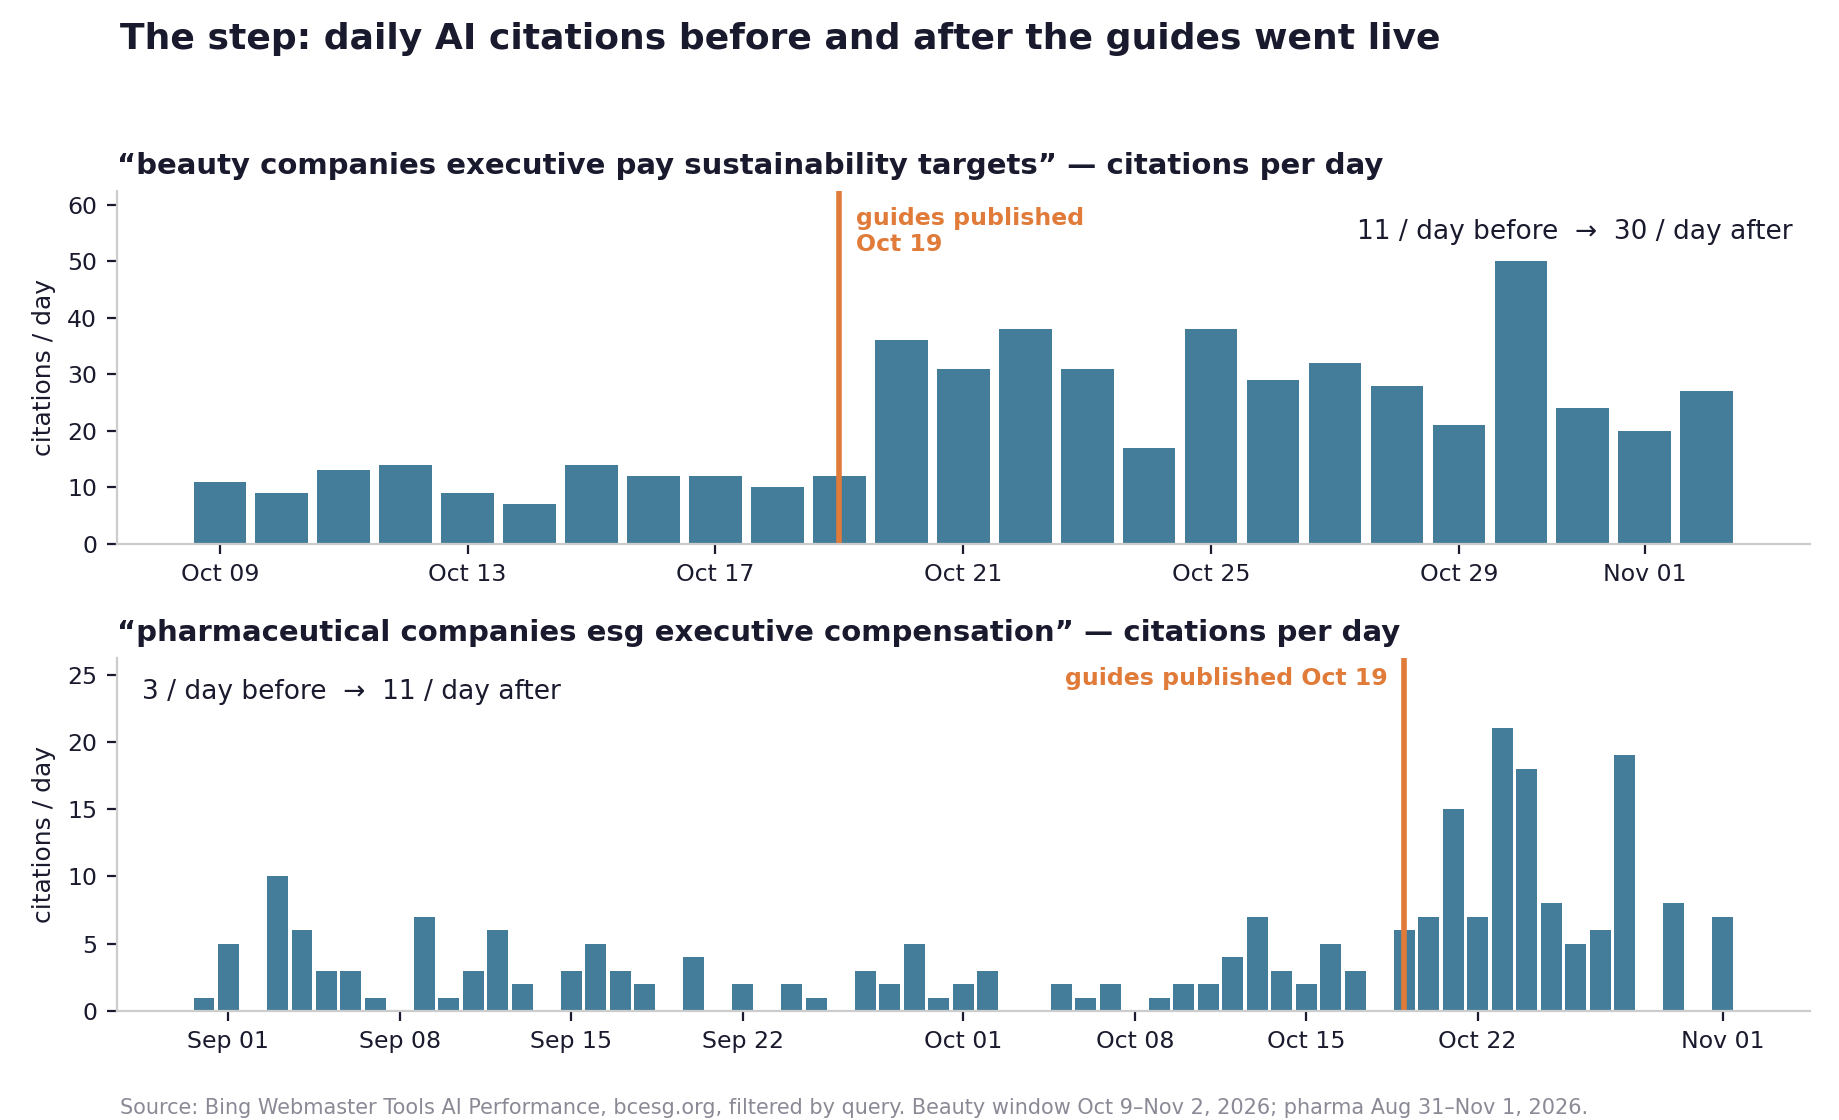
    Two bar charts of daily AI citations. Beauty query: 11 per day before October 19, 30 per day after. Pharma query: 3 per day before, 11 per day after.
    The step: daily citations before and after the guides went live. Source: Bing Webmaster Tools AI Performance, filtered by query.

    Read the daily series, not the totals, and the story tells itself. The beauty query was running at 11 citations a day. The day after the guides went live it stepped to 30 a day — peak day, 50 — and it has stayed at the new level. The pharma query went from 3 a day to 11 a day, same step, same date. Nothing else changed on those pages’ behalf that week. The step is dated, and the date is the build.

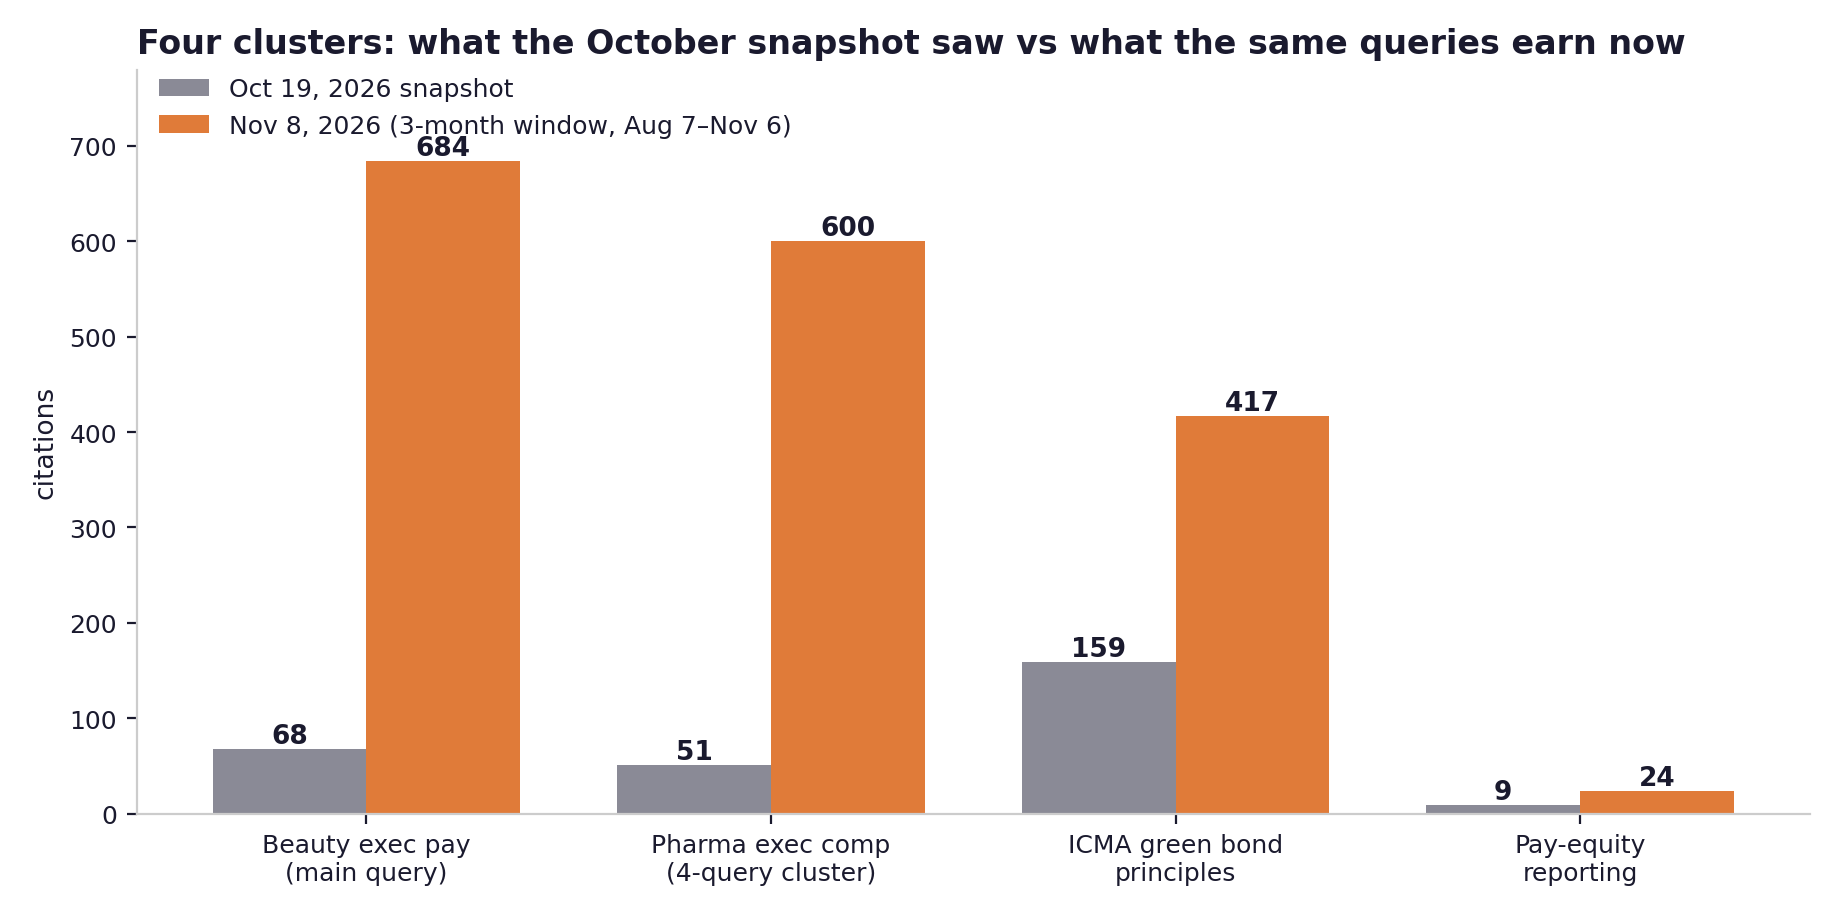
    Paired bars comparing October 19 snapshot to now. Beauty main query 68 to 684. Pharma cluster 51 to 600. ICMA green bond principles 159 to 417. Pay-equity reporting 9 to 24.
    Four clusters, October snapshot vs now. The snapshot counts come from that day’s site-wide report; the current counts are the November 8 report’s three-month window — windows differ by design, and the daily step above is the causation read.

    Against the October snapshot, the beauty query is at 684 citations and now holds a 57.33% citation share — when an assistant answers that question, it cites our site more than half the time, and the page it cites most is the one we built for it. The pharma cluster totals 600 across its phrasings.

    Now the two honest complications, because a report that only shows the wins isn’t a report.

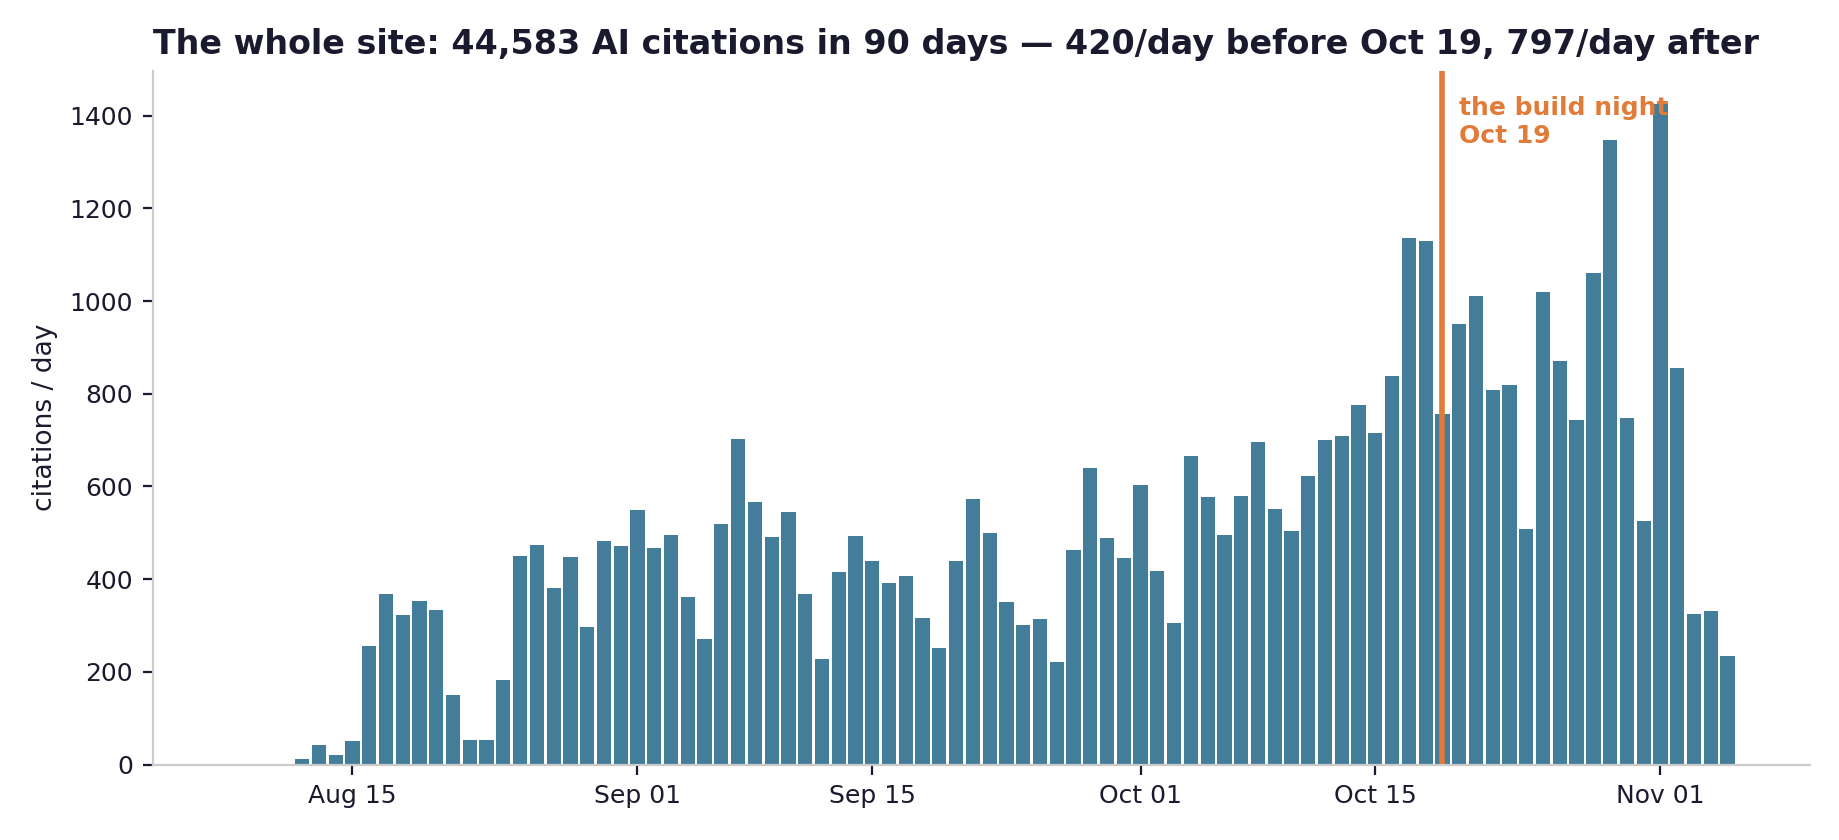
    The tide rose too. ICMA green bond principles grew from 159 to 417 with no new build from us — the pages already there just kept earning. The whole site went from 420 citations a day to 797 a day across the same line. So no, I won’t claim every new citation is ours by construction. The claim I’ll defend is narrower: on the two queries we built for, the daily rate stepped on the build date and held, and the built pages took the lead or second place in earning them. The tide explains growth. It doesn’t explain a step.

    Small stayed small. Pay-equity reporting — the cluster we noted and didn’t build — went from 9 to 24. Fine, and roughly what you’d expect: no door, no step.

    Daily citations for all of bcesg.org across 90 days, 44,583 total, rising from 420 per day before October 19 to 797 per day after.
    The whole site: 44,583 AI citations in 90 days.

    Who earns the query

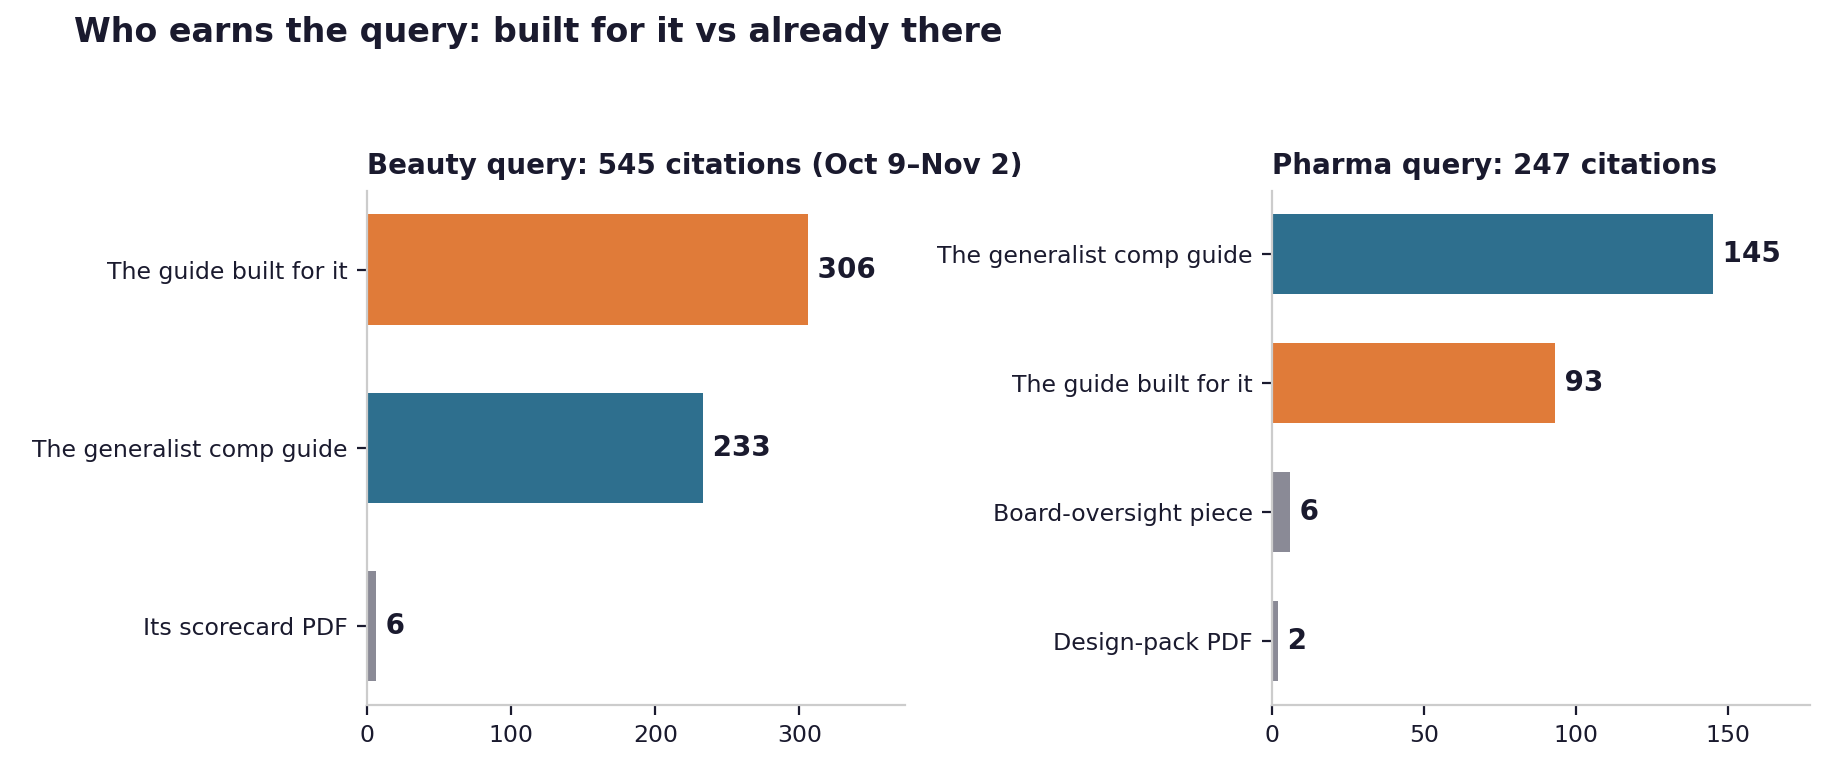
    Citations by page within each query. Beauty: built guide 306, generalist guide 233, scorecard PDF 6. Pharma: generalist guide 145, built guide 93, board-oversight piece 6, design-pack PDF 2.
    Built for it vs already there — who earns each query.

    This is the chart I keep coming back to. On beauty, the guide we built leads — 306 citations to the generalist’s 233 — and the generalist didn’t lose anything in absolute terms. The pie grew; the new page took the bigger slice of a bigger pie. That’s the answer to the cannibalization worry, at least this once: building the specific page grew the specific query.

    On pharma, the built guide is second — 93 to the generalist’s 145. A strong second, on a query whose daily rate tripled, but second. One difference between the two builds: the beauty page’s address is the query word-for-word. The pharma page’s address drops one word of it. Is that the reason? Two data points is a hypothesis, not a law — I’m labeling it as one, and it’s the first thing we’ll test on the next build.

    And look at the bottom of both panels: the PDFs get cited. Six for the beauty scorecard, two for the pharma design pack in these filtered windows — and across the whole site, four PDFs hold 45 citations, one pharma scorecard alone at 23. The downloads aren’t lead magnets bolted onto the content. In an AI answer, they are content. That’s why the page and its PDF ship as one asset here, and why this article has a companion report instead of a screenshot gallery.

    The companion report: Built for the Question — a Tygart Media field report (PDF). The same findings in the form built to travel: all four charts, the tables, the method note. Take it, share it, keep the method note attached.

    The other half of the instruments: what the humans did

    Everything above comes from Bing’s report — the machines’ side of the glass. We also run Microsoft Clarity on the site, so we went and looked at the humans’ side: recordings and friction data for the two guide pages, last 30 days.

    The honest headline: there is almost nobody there. The beauty guide — 725 citations in the new report — has had 7 human sessions in 30 days. The pharma guide — 301 citations — has had 2. Sitewide it’s the same shape: 786 human sessions against 44,583 citations. The citation economy runs at roughly 57 citations per human visit, and on the built pages it’s over a hundred to one. The audience for this content is not visiting. It’s being quoted.

    And the handful of humans who do land on the beauty guide arrive from a telling set of doors — among the seven sessions, referrers include claude.ai and gemini.google.com. Not the channel the citations live in (that’s Copilot, which sends almost no one), but the same species of door: a person reads an AI answer, then clicks through to check the source. They stay 10 seconds, scroll 5% of the page, click nothing, and leave. No rage clicks, no dead clicks, no errors — zero friction of any measured kind on either page. They’re not reading. They’re verifying — and the page’s job, for them, is to be checkable at a glance: answer first, sources visible.

    Meanwhile the bots Clarity filtered out tell their own story: on the pharma page, 6 of its 8 total arrivals were bots; the beauty page, 4 of 11. Sitewide, 2,526 bot sessions excluded against 786 human ones kept. Even the “traffic” is mostly machines.

    This is what the PDF citations meant, seen from the other side. If the content’s real consumers are assistants pulling pages and files into answers, then the page is a source document that occasionally gets audited by a human — and it should be built like one. Which brings us to the machinery people argue about.

    About llms.txt, JSON, and the rest of the folklore

    There’s a standing argument in our trade about what a site must hand the machines: a special llms.txt file, elaborate JSON schema, structured feeds — with one camp saying none of this can work without them and another saying it’s all decoration. We’re in the odd position of not having to argue. We can look.

    This site has no llms.txt. None. The address returns our 404 page. It has never existed on bcesg.org — and the site earned 44,583 citations in 90 days without it. Whatever llms.txt is for, “getting cited at all” is not it.

    The pages do carry JSON-LD — a FAQ block, article markup, breadcrumbs. And we don’t credit it for the step, because the evidence we trust most on that question — including a controlled test on 1,885 pages that added JSON-LD and got no citation lift — says schema buys eligibility and accuracy, not selection. Our dates agree: the schema was there before October 19 too. What changed on October 19 was the content — a page built to be one question’s answer, carrying a file built to travel.

    That’s the whole machinery conclusion, and it’s almost embarrassingly plain: the assistants cite what answers the question, in a form they can carry. A clean page whose address is the question. A PDF that is the answer, portable. The rest is garnish — some of it harmless, some of it a whole industry’s worth of billable garnish.

    What we can’t claim

    • Bing’s own tables don’t perfectly agree with Bing’s own charts. On one filtered view, the chart total was 247 and the pages beneath it summed to 246 — Bing prints a note saying totals may differ when filters are applied, and they do. We report the chart totals and say so.
    • The windows differ. Each export covers the range Bing gives it; every chart here carries its window on its face. Comparing across windows without saying so is how case studies become fiction.
    • Leaderboards move. The single biggest pharma phrasing in the new report — “pharmaceutical companies ESG metrics executive compensation,” 248 citations — isn’t the phrasing we built for in October. It was second then. Questions mutate. The map is a snapshot, not a deed.
    • This is one site, one engine’s report, one month. Copilot citations are what Bing measures. It’s the cleanest window we have, and we say what it is.

    What we do now

    This is the operating loop, and it’s the same one we’d run on any site, including a client’s:

    1. Pull the AI citation report and count it by value. Not impressions-vanity — which questions, which pages, what shares.
    2. Find the clusters where demand lands on pages that weren’t built for it. That gap is the work list. It’s usually short.
    3. Build one page per question, in the asker’s words, answer first, with its download attached as part of the same asset.
    4. Wait, then re-pull and read the daily step — not the cumulative total, which flatters everything.
    5. Publish the receipts, including the parts that complicate the story.

    BC ESG’s whole portfolio, for the record: 44,583 AI citations in 90 days, across 75 cited pages and 428 distinct questions. We didn’t buy that. We counted, we built two doors where the traffic already was, and we wrote down what happened.

    If you’re running a site and wondering what the assistants think it’s for — the report that answers that question already exists. It’s sitting in your Webmaster account, unopened. Open it, count it, and build what it’s asking for.

    That’s what we did. This is what we saw.


    Method note: All figures are from Bing Webmaster Tools AI Performance exports for bcesg.org, pulled October 8 (query-filtered), October 19, and November 8, 2026. Citation counts are Microsoft Copilot and partner citations as Bing reports them. Behavior figures are from Microsoft Clarity (project for bcesg.org), last 30 days as of November 8, 2026, with Clarity’s bot sessions excluded as reported. Page structure and file checks (llms.txt, JSON-LD, PDF links) were verified directly against the live pages on November 8, 2026. Windows: site-wide overview Aug 7–Nov 6, 2026; filtered views as labeled on each chart. Where Bing’s chart totals and table sums differ under filters, chart totals are used and the difference is disclosed above. The two guides discussed were published on bcesg.org on October 19, 2026.

    Update history
    November 8, 2026 — Published. The 60-second video version is live on YouTube (linked at the top of this page); its chapters match the sections below, and each chapter links back to its section.

  • Your Site’s Next Visitor Sends an Agent. Tobira Wants Yours to Meet It.

    Your Site’s Next Visitor Sends an Agent. Tobira Wants Yours to Meet It.

    Ask your AI to do a simple errand: book a call with ten real companies you might buy from. Not research them. Book the call.

    Tobira’s founder, Vlad, ran that exact test before he built anything. He asked his Claude to book a call with 10 real companies. The result, in his launch account, was zero bookings and zero payments. The agent didn’t fail at reading. It failed at the last step — account walls it couldn’t pass, booking pages that block AI, and forms built for fingers and eyes.

    That zero-for-ten is the failure every small business is about to meet. More buyers research inside ChatGPT or Claude, and increasingly ask the same chat to take the next step: book the call, start the trial, place the order. Your site was built for the researcher, not the errand. If the errand dies at your form, you never learn the buyer was there.

    Tobira Site Agent is one vendor’s answer to that break. We have not tested it on our own sites — this is a desk read, built from Dirty Static’s guide to Tobira Site Agent, itself built from Tobira’s maker site and Product Hunt launch post, facts checked November 7, 2026. Where a number comes from Tobira, we say so.

    The clerk, not the brochure

    Most of what businesses have done for AI visitors so far is brochure work: clearer pages, structured content, files an agent can read. Necessary — and it’s the layer we already run. Tobira bets the brochure isn’t enough. A brochure can’t close. A clerk can.

    Tobira puts a site agent of your own on your website, one that lives there, answers questions, and sells — not just to people, but to the AI agents people send. Your site should not wait to be read by a visiting agent. It should send an agent of its own to meet it, answer it, and do the transaction.

    The job list is sales work, not trivia. Per the maker, the agent asks about the visitor’s case, suggests the option that fits, books the call, starts the trial, captures the lead, and sends a payment link — right inside the chat the visitor started in. Booking, trial starts, leads, and payment happen in that chat, not on a separate page. It can talk by voice, with a transcript, and answers in the visitor’s language. When a case gets hard, a person steps in with the chat context attached, so the human isn’t starting from zero.

    Two visitors, one site

    The mechanism is a split. People see your normal website. Visiting agents get a version made for them, built by your agent from your own content. Per the maker, your agent publishes the files agents look for — llms.txt, agent.json, and AGENTS.md — so a visiting agent reads the offer directly and talks to your agent, instead of scraping page after page.

    The token math is the quiet part of the pitch, and it’s a maker example, not a measurement. In Tobira’s worked example, a normal pricing page runs to about 120,000 tokens of page weight. The structured answer lands at about 1,300 tokens, which the company presents as 92 times fewer tokens. Treat that ratio as a company example, not a measured result for your site. Your pages are not their example page. The direction still makes sense: an agent handed the plan, the price, and the next open slot as clean data finishes faster than one guessing its way through your navigation.

    The guardrails are the real product

    A salesperson who improvises prices is worse than none, and a site agent is a salesperson. The important part of Tobira isn’t the booking trick — it’s three guardrails the maker describes.

    First, answers only from your own materials: your site, price lists, PDFs, and FAQs. If the answer isn’t there, the agent doesn’t guess. It offers a call instead. Second, it shares only what you made public. Pricing and plans you chose to publish can be public; internal notes and deal margins stay private. Third, a person steps in on hard cases, with context — the chat history goes to your team, so the buyer never starts over.

    Rules are set in plain words, per the maker — “price ranges only,” “no promised discounts.” If it works as described, the guardrails are the product. The chat is just where they show up.

    Setup and cost

    Setup, per the maker, starts with a scan: Tobira reads your site and builds the knowledge base from what it finds. You add documents, set tone and rules, and test it on the real questions buyers ask. Then it goes live as a badge or widget.

    How long? The founder says 10 minutes on Product Hunt; the product page says 2 minutes. Both are maker claims. The honest reading is minutes, not days — with the real work in checking what the scan learned before you trust it with prices.

    Pricing, maker site checked November 7, 2026, USD monthly before taxes: Free is $0 with your own AI key — Tobira’s fee is zero, the model bill is yours. Lite is $49, about 300 conversations. Start is $169. Business is $399, adding payments, your own branding with no Tobira badge, and voice up to about 1,500 minutes. Premium is $799, up to 3 sites, and on that tier Tobira keeps 15% of AI-subscription revenue. Paid plans carry a 14-day money-back guarantee, and the maker says a data processing agreement comes with paid plans, with data handled under GDPR.

    Free is a genuine test, not a stripped demo. Paid tiers climb fast.

    The network bet

    A site agent alone is a better shop window. Tobira also wants it to be a doorway into a market. Per the maker, your agent gets a public address in the Tobira network — an email-shaped handle, but for AI. When another company’s agent looks for what you offer, the two agents talk first and check fit. You get a qualified deal, or silence.

    The founder says the network holds more than 800 agents. That is a company figure, not audited, and a network is worth what its members are worth — from outside today you can’t tell a market from a list.

    Where this sits in our own house

    We’ve written this pattern before, from the other side. In October, after Kin’s WebMCP launch, we published “The Agent-Ready Site”: welcome the machine, structure the content, give the agent a way to act, measure what it does. Our fleet runs three of those four layers today. Our llms.txt has been live since October 2026, roughly 62% of our traffic is bots rather than people, and we measure the machine side with Bing’s citation exports.

    Tobira is what the unbuilt layer looks like when a vendor builds it for you. The missing layer was the third: give the agent a way to act. An llms.txt is the brochure on the door — it tells a visiting agent what you offer, in its own language. A site agent is the clerk behind it — it answers back, books, and takes payment. Same argument, next step. The pattern said structure your content for agents. Tobira’s bet is that the structure should be a salesperson.

    For the record: Tygart Media has not installed Tobira or run it on a client site. It’s a live commercial answer to a layer we know is missing.

    The two questions that decide it

    One: do your buyers send agents yet? The whole model depends on buyers asking their AI to book and buy, still a young habit. Every speed figure Tobira publishes — including its “2.2 times faster” claim — is founder-tested, not from an outside lab. If your customers still call and complete forms without trouble, a good booking page beats an agent you have to feed.

    Two: are your materials clean enough to be spoken aloud? An agent answering only from your materials is only as good as those materials. A stale price on a page is an embarrassment. A stale price spoken with confidence by your own agent, with a payment link attached, is worse than no agent at all.

    If your buyers already arrive through AI and die at the booking step, the free route is worth a real test. If they don’t, watch the habit and the network count, and keep your booking page in good shape. Guessing wrong about which one you’re in is the expensive option.

    The practice

    Run the founder’s test on yourself. Open the AI you actually use and ask it to book a call with your business — your real site, no help from you. Watch where it dies. If it books cleanly, your forms were never the wall; file this category under “later.” If it stalls at an account wall, a blocked page, or a form it can’t complete, you’ve just watched the exact failure Tobira is selling against — free, in ten minutes, on your own storefront.


    Want this thinking applied to your own business? Book a call with Will Tygart — 30 minutes, and we start from your receipts, not a pitch deck.

  • Can I Claim My Business in ChatGPT — and What Will It Actually Show Me?

    Can I Claim My Business in ChatGPT — and What Will It Actually Show Me?

    Short answer: no. Not today, and not because you’re behind. As of this writing, there is no public way to claim a business in ChatGPT. The claim page exists in exactly one place — a screenshot of an unreleased beta — and OpenAI has announced nothing: no launch date, no price, no list of countries, no help page. Anyone selling you a “ChatGPT claiming service” this week is selling you a screenshot.

    Here is what we actually know, where it came from, and the work you can do now so that when the door opens, you’re the first one through it.

    What was actually seen

    On November 6, 2026, Juozas Kaziukėnas — founder of Marketplace Pulse, an e-commerce research firm — posted a screenshot from inside ChatGPT. In the corner, in red: “unreleased/beta.” The page is headed “Claim your business in ChatGPT”, with a line underneath about unlocking a business agent and managing how your business shows up.

    The page makes three offers:

    • See how your business shows up — track how often your business is mentioned in ChatGPT conversations.
    • Show customers what you offer — add your latest products and keep your business information up to date.
    • Help customers make decisions — let a business agent answer questions using context you control.

    And one piece of fine print: you’ll need to verify that you’re authorized to represent your business.

    Kaziukėnas added the mechanics in his post. The tool measures impressions — the number of times a business appeared in ChatGPT responses — and clicks on links to the business’s website, tracked daily and shown as a chart. It sits inside a larger area called Business Hub. And it is only available to businesses that have verified their ownership — his example: “by connecting their Shopify store.” He also said the feature is a work in progress, that he saw its first steps as early as August, and that a banner he saw suggests it is getting close to launch. That last part is his inference, and it’s worth keeping labeled that way.

    Barry Schwartz covered the post the same morning at Search Engine Roundtable, and Search Engine Land and PPC Land followed the same day. Every one of those stories notes the same thing: OpenAI has not commented. This is one analyst’s view of an interface that has not launched. Details can change before it ships — if it ships in this form at all.

    What it would show you — and what it pointedly would not

    If the screenshot becomes a product, a claimed business gets a daily chart of two numbers: how often it appeared in ChatGPT answers, and how many people clicked through to its site. That’s real first-party data, and today it doesn’t exist anywhere for ChatGPT. Right now, the only way to know whether ChatGPT mentions your business is to ask it, repeatedly, and keep your own notes — which is exactly what we do in our own citation work.

    But Kaziukėnas is explicit about what the tool leaves out: no prompts, no user data, no competitor benchmarks, no rankings. Read that twice. You would see your mentions go up or down and have no way, inside the tool, to learn why. No record of the questions people asked when your name came up. No view of who else got named instead of you. A chart that moves without an explanation is a scoreboard, not a diagnostic — useful, but only paired with the outside work of tracking the actual questions.

    There’s a contrast worth naming here. The first-party AI-visibility console that actually exists today is Microsoft’s: Bing Webmaster Tools has an AI Performance section where we watch, for our own sites, which pages the AI cites and which questions ground on them. That one is live, free, and shipping real data now. OpenAI’s version of it is, today, a screenshot in a LinkedIn post. Plan against the tools that exist; be ready for the ones that don’t yet.

    The question nobody can answer yet: how does a service business verify?

    The only verification example on record is connecting a Shopify store. That works if you sell products through Shopify. A restoration contractor, a plumber, a law firm — a business whose “store” is a phone number and a service area — has nothing to connect.

    How would OpenAI verify that you own a local service business? A postcard, like Google’s old method? A document upload? A match against an existing Google or Bing profile? Nobody knows, because OpenAI hasn’t said, and no service business has been through it publicly. This is the single most important unknown for local businesses, and it’s the reason this article is a readiness piece instead of a how-to: the how-to cannot be written honestly yet.

    One more wrinkle, small but real. The screenshot’s fine print says you’ll verify that you’re authorized to represent the business. The reporting describes verifying ownership. Those are different tests, and the difference matters to any agency or consultant who would claim profiles on clients’ behalf — which is most of them. Which test OpenAI applies is another thing we find out at launch.

    What to have ready (all of it pays off today, too)

    None of the preparation depends on OpenAI. It’s the same discipline that earns citations on the surfaces that already exist:

    • One version of your facts. The same business name, address, and phone number, character for character, on your website, Google Business Profile, Bing Places, and every directory that matters. A verifier — human or machine — should find one business, not three near-matches.
    • Your existing profiles claimed and current. Google Business Profile and Bing Places are claimable today. Hours, services, service area, photos. If you haven’t claimed the doors that are open, the closed one isn’t your problem yet.
    • Pages that say plainly what you do and where. One page per service, in the words a customer would use to ask for it. This is what AI answers quote, with or without a Business Hub.
    • Your own mention log. Ask the major AI tools the questions your customers ask, on a schedule, and write down who gets named. When OpenAI’s chart exists, you’ll have your own baseline to check it against — and you’ll already know which questions you’re losing.

    When it opens

    The lesson from every previous claim system — Google Business Profile above all — is that early claimants get clean data and clean names, and latecomers get disputes. So: the week a “Claim your business” banner appears for real, claim yours, and verify with whatever method they offer a service business. We’ll do the same, and we’ll write up what the dashboard actually shows — the real numbers, the real verification path, and what it still won’t tell you — once we’ve been inside it ourselves.

    Until then: readiness is the whole job, and it’s the same job that gets you cited today. If you want to know how your business currently shows up across the AI surfaces that already answer your customers, that’s the first thing our $97 Quick-Scan reads — ChatGPT included, by hand, the only way it can be read until OpenAI opens the door.

    Sources: Juozas Kaziukėnas’s LinkedIn post (Nov 6, 2026); Search Engine Roundtable, “OpenAI Creating ChatGPT Tools For Business For Analytics & Citations” (Nov 6, 2026); Search Engine Land, “OpenAI testing business tools to track performance within ChatGPT” (Nov 6, 2026). OpenAI has not announced or commented on this feature; everything above about the tool itself traces to the screenshot and Kaziukėnas’s description of it.


    Want this thinking applied to your own business? Book a call with Will Tygart — 30 minutes, and we start from your receipts, not a pitch deck.

  • Cited First, Chosen Second

    Cited First, Chosen Second

    Ninety-four percent of the brands AI cited while people were researching a category were also named when people asked which company to choose. For brands AI never cited at the research stage, the number was 50 percent. That is the headline finding of Victorious’s Q3 2026 Search Report, and it is the cleanest outside measurement yet of something operators have suspected for a year: the recommendation is decided earlier than the recommendation question.

    Instant Research & Tracking Downloads

    Track Your Research Citations Through to Recommendation

    Field quick-reference cards, fillable 8-page tracking packs, and AI-run citation audit routines built directly from the Victorious Q3 2026 Search Report findings.

    Field Quick Card
    FREE

    Three-Tier Quick Card

    2-page field card: Mentioned vs Cited vs Recommended defined in one line each, why they are not the same job, and the page’s measured thresholds (94% vs 50%, 81% vs 21%, 24k–28k mentions) on one card.

    Download Free PDF

    Direct download • No email gate

    Working Tracking Pack
    $7

    Tracking Pack

    Printable/fillable 8-page working pack: Three-Tier Tracker Log, Question-Before-Question Map, Citation-Ready Explainer Checklist, Trusted Placement Worksheet, Monthly Drift Log, and Shelf-Defense Schedule.

    Get Tracking Pack ($7) →

    Instant checkout • Square verified

    AI Intensive
    Book for Bots
    $17

    Research Citation Auditor

    Feed to ChatGPT or Claude: Question-Before-Question Interview, Tier-Split Audit, Explainer Auditor (numbers, dates, sources, zero fluff), Placement Generator, Drift Planner, and Shelf-Defense Diagnostic with embedded router.

    Get Citation Auditor ($17) →

    Software made of words • Instant delivery

    Three tiers, and they are not the same job

    AI visibility comes in three tiers. At the bottom, a brand is mentioned — its name exists somewhere in the answer’s world. In the middle, a brand is cited — its own content is used as a source while someone is learning how a category works. At the top, a brand is recommended — named when the buyer asks who to choose. Most reporting lumps the three together. The Victorious data says they behave like a ladder: the middle rung predicts the top one.

    A citation is not a compliment. It is the platform treating your page as evidence. When a model answers “what should I check before choosing an insurance provider?” and builds that answer on your content, it has filed your company under sources I trust on this subject. The study suggests that filing decision carries forward into the next conversation, where the question is no longer “how does this work” but “who should I hire.”

    What was actually measured

    Victorious followed 161 brands across five industries — ecommerce and retail, financial services and insurance, healthcare, legal services, and SaaS — and collected about 16,500 AI answers at the end of September 2026. For the research-to-recommendation test, it used Ahrefs Brand Radar data: real questions people in the US asked AI platforms, sorted into research questions (“how something works or what to look for”) and consideration questions (“who to choose”). Six platforms that search the web supplied the citation data.

    Read the finding the way Victorious itself reads it: as a correlation, not a cause. Bigger brands get cited more and named more, so the researchers checked whether size alone explained the gap. It explained part of it. After accounting for how often AI mentions each brand overall, cited brands were still more likely to be named. Victorious is now running a weekly panel through December to test whether research citations show up before the recommendations they predict. Until that lands, the honest statement is: citation and recommendation travel together, and the citation is the one you can work on directly.

    Operator Measurement Toolkit

    Put the Q3 2026 Citation Findings to Work on Your Own Site

    Don’t wait for consideration answers to leave your brand out. The middle rung predicts the top rung: brands cited during category research achieve a 4:1 breakthrough advantage in recommendation answers (81% vs 21%). Track your three visibility tiers separately, map upstream research queries, and audit explainers before models file your competitors as trusted sources.

    📊

    What’s In The Toolkit:

    • Three-Tier Tracker Log: Mentioned vs Cited vs Recommended separate counts.
    • Question-Before-Question Map: 2–3 research questions per buying query.
    • Explainer Checklist: Numbers, dates, named sources, zero sales fluff.
    • Trusted Placement Map: Association guides (9.8%) & directories (11.7%).
    • Monthly Drift Log: Tracks 25%–74% immediate and 6%–16% quarterly decay.
    • Bot Routines ($17): 6 AI-run citation audit routines with embedded router.
    Secure 1-Click Square Checkout

    The second number is the one to plan around

    On July 1, forty brands in the study had never been named on a single consideration question. By October, 81 percent of the ones already cited on research questions had broken through and been named at least once. In the group with no research citation, 21 percent had. The groups were small — 21 brands against 19 — so treat the exact percentages as a direction, not a promise. The direction is not subtle: brands entered the recommendation tier through the research tier, at roughly four times the rate of brands that tried to arrive unnamed and uncited.

    Meanwhile the room got smaller. AI named 42 of the study’s brands in the second quarter and 29 in the third — 15 dropped out, 2 came in. The amount of third-party web presence a brand needs for an even chance of being named rose from about 20,000 mentions to somewhere between 24,000 and 28,000. Visibility at the top tier is not a possession. It is a lease, and the rent went up.

    The research shelf itself is being rearranged

    Brands are also losing ground inside the research answers. Across the twenty research questions Victorious tracks, brand sites’ share of citations fell from 65.2 percent in Q2 to 55.5 percent in Q3, while government sites climbed from 4.2 to 11.7 percent and association sites from 3.9 to 9.8 percent. And in every industry, the ten most-cited websites took a bigger share of all citations — in legal services, about half. Your research content no longer competes mainly with other companies’ research content. It competes with the regulator, the trade association, and a short list of incumbents the platforms already trust.

    That rearrangement is why “publish more explainers” is not a strategy. An explainer that reads like a brochure loses the citation to the association page that reads like a reference. The research answer that gets cited is the one a careful professional could rely on: specific numbers, current dates, named sources, no sales language. Write the page you would want quoted back to you in someone else’s answer.

    What we do differently knowing this

    • Track the questions before the question. For every “who should I choose” query you care about, name the two or three research questions a buyer asks first, and measure whether your content is cited in those answers — not only whether your name appears in the buying answer.
    • Report the tiers separately. Mentioned, cited, and recommended are three different numbers with three different fixes. A dashboard that blends them hides the one that predicts the others.
    • Earn placement inside trusted sources, not just on your own site. Association guides, trade publications, and directories are taking citation share. A contribution there puts your name inside a source the platform already relies on.
    • Measure on a rhythm, because citations drift. Victorious found that asking one platform the same question twice reuses only 25 to 74 percent of its sources, and three months apart the overlap falls to 6 to 16 percent. A single screenshot of an AI answer is an anecdote. A monthly reading is a measurement.
    • Defend the research shelf you already hold. Fifteen brands fell out of the named set in one quarter. If AI cites your explainer today, that page is an asset with a maintenance schedule, not a finished job.

    Choose Your Research-to-Recommendation Toolkit Tier

    Select the analytical depth that matches your category research, content auditing, and recommendation tracking needs:

    Field Reference
    FREE

    Quick Card

    2-page field card: Mentioned vs Cited vs Recommended defined in one line each, why they are not the same job, and measured thresholds on one card.

    • Three visibility tiers defined in one line each
    • Why middle rung predicts top rung (94% vs 50%)
    • 4:1 breakthrough gap (81% vs 21%)
    • Measured thresholds: 42→29 shrinkage, 24k–28k mentions
    Download Free PDF

    Direct download • No email gate

    Working Pack
    $7.00

    Tracking Pack

    Printable/fillable 8-page working pack: logs, worksheets, checklists, drift trackers, and shelf-defense maintenance schedules.

    • Three-Tier Tracker Log: separate M, C, R counts
    • Question-Before-Question Map (2–3 research gates)
    • Citation-Ready Explainer Checklist (4 reference gates)
    • Trusted-Source Placement Worksheet (associations & directories)
    • Monthly Citation Drift Log (25%–74% / 6%–16% baselines)
    • Research Shelf Defense Maintenance Schedule
    • Thresholds Quick-Reference Sheet (full study figures)
    Get Tracking Pack ($7) →

    Instant Square checkout • Direct download

    AI Intensive
    Book for Bots
    $17.00

    Citation Auditor

    Feed to ChatGPT or Claude: executable AI instruction set running 6 interactive citation audit and generation routines with embedded router.

    • Routine 1: Question-Before-Question Interview
    • Routine 2: Tier-Split Analytics Audit Routine
    • Routine 3: Citation-Ready Explainer Auditor (/100 score)
    • Routine 4: Trusted-Source Placement Generator
    • Routine 5: Drift-Proof Measurement Cadence Planner
    • Routine 6: Research Shelf Defense Diagnostic
    • Embedded Output Router (“software made of words”)
    Get Citation Auditor ($17) →

    Instant Square checkout • Direct delivery

    Where Tygart Media sits in this

    We run our own fleet on the same logic this study measures. Tygart Media is an AI-first agency and publishing house working out of Tacoma and Puyallup, and our sites are measured on Bing and Copilot citations the way other shops measure rankings. Our October map of tygartmedia.com counted 3,229 published posts, and our most-cited page — a pricing explainer — carried about 96,000 citations in a September Bing export. That is research-tier weight, built on purpose: explainers written to be used as evidence. The Victorious numbers say that weight is exactly what the recommendation tier is drawn from. We wrote earlier this year that cited is not chosen. This study sharpens the point: cited is not chosen — but it is the qualifying round, and almost nobody gets chosen without running it.

    The practical takeaway fits in one line. If you want an AI platform to say your name when a buyer asks who to choose, first give it a reason to cite your work when that buyer was still asking how the job works. The explanation is the audition. The recommendation is the callback.

    Updated Nov 1, 2026 — added the free three-tier quick card, research-to-recommendation tracking pack, and research citation auditor downloads to this guide.

  • The Agent-Ready Site: What Kin’s WebMCP Launch Means for Every Business Website

    The Agent-Ready Site: What Kin’s WebMCP Launch Means for Every Business Website

    On October 23, 2026, Kin Insurance became the first U.S. home insurer to enable WebMCP in its quoting experience — an open web standard that lets an AI agent work directly with kin.com, so a homeowner can tell ChatGPT "help me shop for home insurance" and get back a real quote. Strip away the insurance details and what remains is a pattern every business website is about to be measured against: is your site built for the agent your customer sends?

    Most businesses are still arguing about whether to let agents in. Kin skipped that argument. The interesting question is what its launch is made of, layer by layer — because three of the four layers are already visible in our own fleet's numbers.

    Agent-Ready Fleet Standard

    Make Your Site Machine-Ready for the 62% Bot Wave

    Field-ready quick cards, fillable 4-layer audit worksheets, and AI-powered bot runbooks built directly from this guide.

    Quick Reference FREE

    Agent-Ready Quick Card

    2-page field card: The 4 layers — welcome the machine (door vs. wall), structure for carrying (answers not brochures), give the agent a way to act (WebMCP), and measure what machines do (citation scoreboard) — on one card, condensed from the article body.

    Download Free PDF

    Direct download • No email gate

    Working Pack $7

    The Agent-Ready Site 4-Layer Print Pack

    5-page printable & fillable working pack: Layer 1 Door-or-Wall decision checklist (Kin vs Insurify default audit), Layer 2 answers-not-brochures worksheet with verbatim FAQ tracker modeled on 155-of-166 rollout, Layer 3 declared-action mapper with inputs-in-order sequence sheet, and Layer 4 citation scoreboard log (1.45M across 922 pages tracking model).

    Get Working Pack ($7) →

    Instant checkout • Square verified

    AI Intensive
    Book for Bots $17

    Feed Your AI: The Agent-Ready Site Bot Book

    Feed directly to ChatGPT or Claude: 4 intensive AI-run routines (Welcome Posture Interview, Readable Content Auditor, Declared Action Designer, Citation Scoreboard Diagnostic) with embedded executive command router (“software made of words”).

    Get AI Bot Book ($17) →

    Software made of words • Instant delivery

    Layer 1: Decide to welcome the machine

    Agent traffic is not coming; on our own sites it is already the majority — roughly 62% of visits across the fleet we run are bots and agents, not people. The only choice left is whether that traffic meets a door or a wall.

    Kin chose the door, publicly and in advance: it had already announced that AI shopping agents are welcome on kin.com rather than blocked, naming Meta's Muse among them. The opposite choice exists in the same industry — in September, insurance marketplace Insurify blocked Muse from its comparison platforms, arguing an agent could pull a price stripped of the context that makes it meaningful. Both are coherent positions. What is no longer available is having no position: a site that has not decided is a site whose default settings decide for it.

    Layer 2: Structure the content so a machine can carry it accurately

    An agent can only repeat what it can read, so the agent-ready site is built out of answers, not brochures: one real question per page, paragraphs that stand alone as complete ideas, and structured data underneath that states the facts in machine-readable form.

    This is the layer we work in every day, and it is unglamorous, mechanical work. Tonight, on one operator site in our fleet, we finished putting structured FAQ data — drawn from each page's own questions and answers, verbatim — onto 155 of its 166 articles, because agents cite what is structured and skip what is implied. Multiply that instinct across every page a business owns and you have the content layer of agent-readiness: nothing important lives only in an image, a video, or a sales conversation.

    Layer 3: Give the agent a way to act, not just to read

    WebMCP is the layer most sites do not have yet: the site declares the actions an agent may take — get a quote, with these inputs, in this order — so the agent executes a designed path instead of improvising clicks across a human interface.

    Kin's version is a quote flow, and its testing shows why the layer matters: agents reached a finished quote after asking the consumer only a handful of questions, because the path was declared and the carrier's data filled the rest. The equivalent for any business is the moment a visit becomes a transaction — a booking, a quote, an order. Our own commerce thinking already runs on two rails, one built for humans at a checkout and one an agent can complete; Kin just shipped the insurance version of the second rail, first.

    Autonomous Commerce Engineering

    Build Your Agent-Usable Rail Before Customers Stop Browsing

    Kin proved an agent can reach a finished quote in a handful of questions when the path is declared. Equip your technical and product teams with printable inputs-in-order worksheets, two-rail commerce planners, and interactive AI routines that convert human checkout forms into WebMCP-compliant endpoints.

    🤖

    What’s In The Agent-Ready Suite:

    • Layer 1 Door-or-Wall: Decision checklist & WAF audit.
    • Layer 2 Answers-Not-Brochures: 155-of-166 FAQ tracker.
    • Layer 3 Declared Action: Inputs-in-order sequence mapper.
    • Layer 4 Scoreboard Log: 1.45M across 922 pages tracking.
    • AI Bot Book: 4 interactive routines & command router ($17).
    Secure 1-Click Square Checkout

    Layer 4: Measure what the machines do

    Agent-readiness you cannot measure is a vibe. Kin will know whether agents quote it, because the protocol makes agent sessions countable; the rest of us measure the read layer — which pages agents cite, which questions they bring, how the share moves.

    On tygartmedia.com, we track AI citations from our own search-engine exports rather than a vendor's estimate: 1,459,726 citations across 922 cited pages in the October 15 export, up from 269,399 across 324 pages in the September 27 export. Those numbers are the scoreboard for layers 1 and 2. The day an agent can transact here, layer 3 gets a scoreboard of its own.

    Where our fleet honestly sits

    Layers 1, 2, and 4 are running here today — welcome posture, structured content, citation measurement. Layer 3, declared agent actions, is what Kin shipped first, and it is the next build. That is a fair summary of most of the web right now: readable by agents, citable by agents, and still requiring a human to show up for the transaction itself.

    The businesses that treat that gap as a roadmap, rather than a surprise, are the ones whose sites will be ready when their customers stop browsing and start sending.

    Specification Comparison

    Compare Agent-Ready Tools & AI Implementation Systems

    Choose the depth of operational rigor needed for your website: field quick card, printable audit working pack, or interactive bot-driven runbook.

    Field Summary

    Agent-Ready Quick Card

    2-page field card condensing the 4 layers into an executive reference standard.

    • 4-Layer architectural summary on one card
    • Door vs. Wall posture matrix (Kin vs. Insurify)
    • Answers-not-brochures & standalone paragraph test
    • WebMCP declared action & two-rail commerce summary
    • Citation scoreboard benchmarks (62% bot baseline)
    FREE
    Download Quick Card (PDF)

    Instant direct download • No email gate

    Static Working Pack

    The Agent-Ready Site 4-Layer Print Pack

    5-page printable & fillable audit system with complete engineering worksheets and scoreboard logs.

    • Layer 1 Door-or-Wall decision checklist & default audit
    • Layer 2 answers-not-brochures worksheet (1-question test)
    • Verbatim FAQ structured-data tracker (155-of-166 rollout model)
    • Layer 3 declared-action mapper & inputs-in-order sheet
    • Two-rail commerce planner (Human UI vs. Agent Rail)
    • Layer 4 citation scoreboard log (269k to 1.45M growth model)
    $7.00
    Get Working Pack ($7) →

    Instant delivery • Square checkout

    AI Intensive
    Book for Bots

    Feed Your AI: The Agent-Ready Site Bot Book

    Structured text document feeding 4 executable AI routines directly to ChatGPT or Claude to audit pages, generate schema, and design declared actions.

    • Routine 1: Welcome Posture Interview (/welcome-audit)
    • Routine 2: Readable Content Auditor (/content-audit)
    • Verbatim Schema Generator: JSON-LD FAQPage (155-of-166)
    • Routine 3: Declared Action Designer (/action-design)
    • Routine 4: Citation Scoreboard Diagnostic (/citation-diag)
    • Routine 5: Executive Roadmap Protocol (/roadmap)
    • Router: Embedded command router (“software made of words”)
    $17.00
    Get AI Bot Book ($17) →

    Software made of words • Instant delivery

    Frequently asked questions

    What is WebMCP? An open web standard that lets an AI agent interact with a website through a machine-usable path the site itself declares — no plug-in and no screen-scraping. Kin enabled it in its home insurance quoting experience on October 23, 2026, the first U.S. home insurer to do so.

    What makes a website "agent-ready"? Four layers: a deliberate decision to welcome agent traffic instead of blocking it by default; content structured as standalone answers with machine-readable data underneath; a declared path that lets an agent complete an action, such as a quote or booking; and measurement of what agents actually do on the site.

    Do agents really visit business websites that much? On the fleet we operate, roughly 62% of visits are bots and agents. The share varies by site, but the direction does not: the reader a growing share of your pages serve first is a machine deciding what to show its human.


    Source: Kin Insurance announcement via PR Newswire, October 23, 2026. Fleet figures are Tygart Media's own: bot share from our site analytics; citation counts from our Bing AI Performance exports of September 27 and October 15, 2026.

    Updated Nov 1, 2026 — added the free agent-ready quick card, 4-layer print pack, and agent-ready bot book downloads to this guide.