AI Search Authority - Tygart Media

Category: AI Search Authority

GEO, AEO, and llms.txt: how a brand gets cited in Perplexity, ChatGPT, Claude, and Google AI Overviews.

  • One Question Per Page: How Generative AI Actually Ingests, Ranks, and Cites Content (Full Video Walkthrough & Analysis)

    Executive Video Masterclass
    6 Chapters // 29m 02s // Studio Audio Mastered

    One Question, One Page, One Answer: The Architecture of AI Citations

    In this 29-minute masterclass, Will Tygart walks through live screen recordings and telemetry dashboards to show how Microsoft Copilot, Perplexity, and Claude harvest web content. Below, the session has been pruned of opening setup chatter, mastered with studio vocal leveling, and segmented into six standalone video chapters with exact timestamps, native playback, and core takeaways.

    Presenter: Will Tygart
    •
    Production: Tygart Media
    •
    Audio Mastering: -16 LUFS Studio Vocal Polish
    •
    Focus: Generative Engine Optimization (GEO)

    Mastered Video Chapters & Detailed Walkthroughs

    Section 1: How Frontier Answer Engines Ingest Knowledge Nodes

    ⏱ 10:15 – 15:45 (5m 30s)

    Behind-the-scenes mechanics of how Microsoft Copilot and Perplexity bots parse web pages. Answer engines don’t browse like consumers—they harvest functional specifications, entity models, and executable schemas to compile synthesized briefings.

    Key Takeaways:

    • Frontier answer engines ingest structured data blocks to construct immediate, synthesized answers for users.
    • Clean entity modeling and tabular layouts reduce token parsing overhead for models like Claude and GPT-4o.
    • When your page is the sole authoritative source for an operational answer, frontier labs cite you by default.

    Section 2: The Human Practitioner vs. The Ingestion Bot

    ⏱ 15:45 – 21:00 (5m 15s)

    Simulating a healthcare facility manager seeking actionable continuity checklists. Demonstrates why annoying popups kill user trust and how clean, copyable data bridges the gap between human and bot workflows.

    Key Takeaways:

    • Human practitioners want immediate utility: checklists, copyable tables, and direct downloads.
    • Intrusive popups drive dead clicks, high bounce rates, and immediate frustration.
    • Designing frictionless copy-paste controls serves human users and AI grounding engines simultaneously.

    Section 3: Why Video Gets Cited First & $7 Instant Checkout Experiments

    ⏱ 21:00 – 26:15 (5m 15s)

    Multi-modal AI prioritization: why search engines push video walkthroughs to the top. Exploring how micro-transactions ($7 instant Square checkout) and agentic protocols (UCP) enable autonomous software purchases.

    Key Takeaways:

    • Modern answer engines prioritize verified video demonstrations over unverified text claims.
    • Testing $7 low-friction digital products with instant payment rails tests transaction velocity.
    • Agent-to-agent commerce (UCP) allows AI bots to discover and purchase resources on behalf of human users.

    Section 4: The Freshness Penalty: Why Stagnant Pages Lose Citations

    ⏱ 26:15 – 30:45 (4m 30s)

    Forensic breakdown of a live Copilot citation featuring policy limits, deductibles, and an October 6th update date. Why high-value technical and regulatory content must maintain recent timestamps.

    Key Takeaways:

    • Copilot explicitly surfaces the publication and update date in its citation snippet.
    • Regulatory, pricing, and insurance topics have a steep decay curve if left untouched.
    • Establishing continuous content maintenance cycles protects high-yielding citation assets.

    Section 5: Telemetry Cadence: 7-Day vs. 30-Day vs. 6-Month Exports

    ⏱ 30:45 – 35:30 (4m 45s)

    How to extract actionable Bing Webmaster and Clarity telemetry without falling into rabbit holes. Why 7-day data skews B2B analysis due to dead weekends, and why 30-day and 6-month windows provide true signal.

    Key Takeaways:

    • B2B traffic operates on a Monday-to-Friday workweek; a 7-day export captures two dead weekends and skews reality.
    • Use 30-day and 6-month horizons to detect real structural growth and query trends.
    • Avoid getting trapped in beta features like ‘Explore Topics’—focus on raw query and page downloads.

    Section 6: The Human-in-the-Loop Strategic Vantage Point

    ⏱ 35:30 – 39:17 (3m 47s)

    The core operational philosophy: leveraging autonomous AI to execute heavy technical lifting (coding, schemas, deployments) so human leaders can step back to 30,000 feet and steer strategy.

    Key Takeaways:

    • AI handles the repetitive technical mechanics: regex, schema generation, and tag purging.
    • The human brings real-world intuition: understanding buyer psychology, practitioner needs, and market gaps.
    • Collaborative human-AI execution yields order-of-magnitude gains in speed and strategic clarity.

    Architecture Matrix: Traditional SEO vs. Single-Question Knowledge Nodes

    Dimension Legacy Multi-Topic SEO Post Single-Question Knowledge Node AI Ingestion Impact
    Semantic Focus Broad, meandering (15-20 subheadings, keyword stuffing) 1 Laser Question, Direct Answer, Context Matrix 100% Entity Match for Copilot & Perplexity
    Freshness Signals Published once; updated annually with minor date tweaks Monthly SLA / Continuous Schema Verification Eliminates Algorithmic Stagnation Penalty
    Human UX Friction Newsletter popups, dead scripts, intrusive traps Zero dead-click scripts; clean copyable tables Sub-180ms INP; Zero JS ReferenceErrors
    Multi-Modal Power Generic stock photos and un-captioned images Time-stamped Video Walkthrough with Chapter Schema Priority Ranking in Multi-Modal AI Summaries
    Agentic Readiness Text-only; requires human to click through forms UCP Manifests, JSON-RPC MCP Tools, Instant $7 Checkout Autonomous Shopping Agents Can Transact

    Actionable Rules for Your Next Content Sprint

    • Lead with the Direct Answer: Place the conclusive answer in the first 120 words beneath your primary heading before unpacking background context.
    • Audit for Dead-Click Scripts: Eliminate broken newsletter modals or un-declared event listeners (like the popupsend error) that cause rage clicks.
    • Anchor With Segmented Video Walkthroughs: Search bots prioritize multi-modal video nodes when verifying technical claims and real-world practitioner authority.
    • Use 30-Day and 6-Month Data Horizons: Never evaluate B2B strategy off a 7-day export that includes two dead weekends.
  • ChatGPT Is Five Rooms, Not One Channel

    ChatGPT Is Five Rooms, Not One Channel

    There’s a post going around that says: if you can rank in ChatGPT, you’re way ahead of the game, your leads from ChatGPT will increase, invest now.

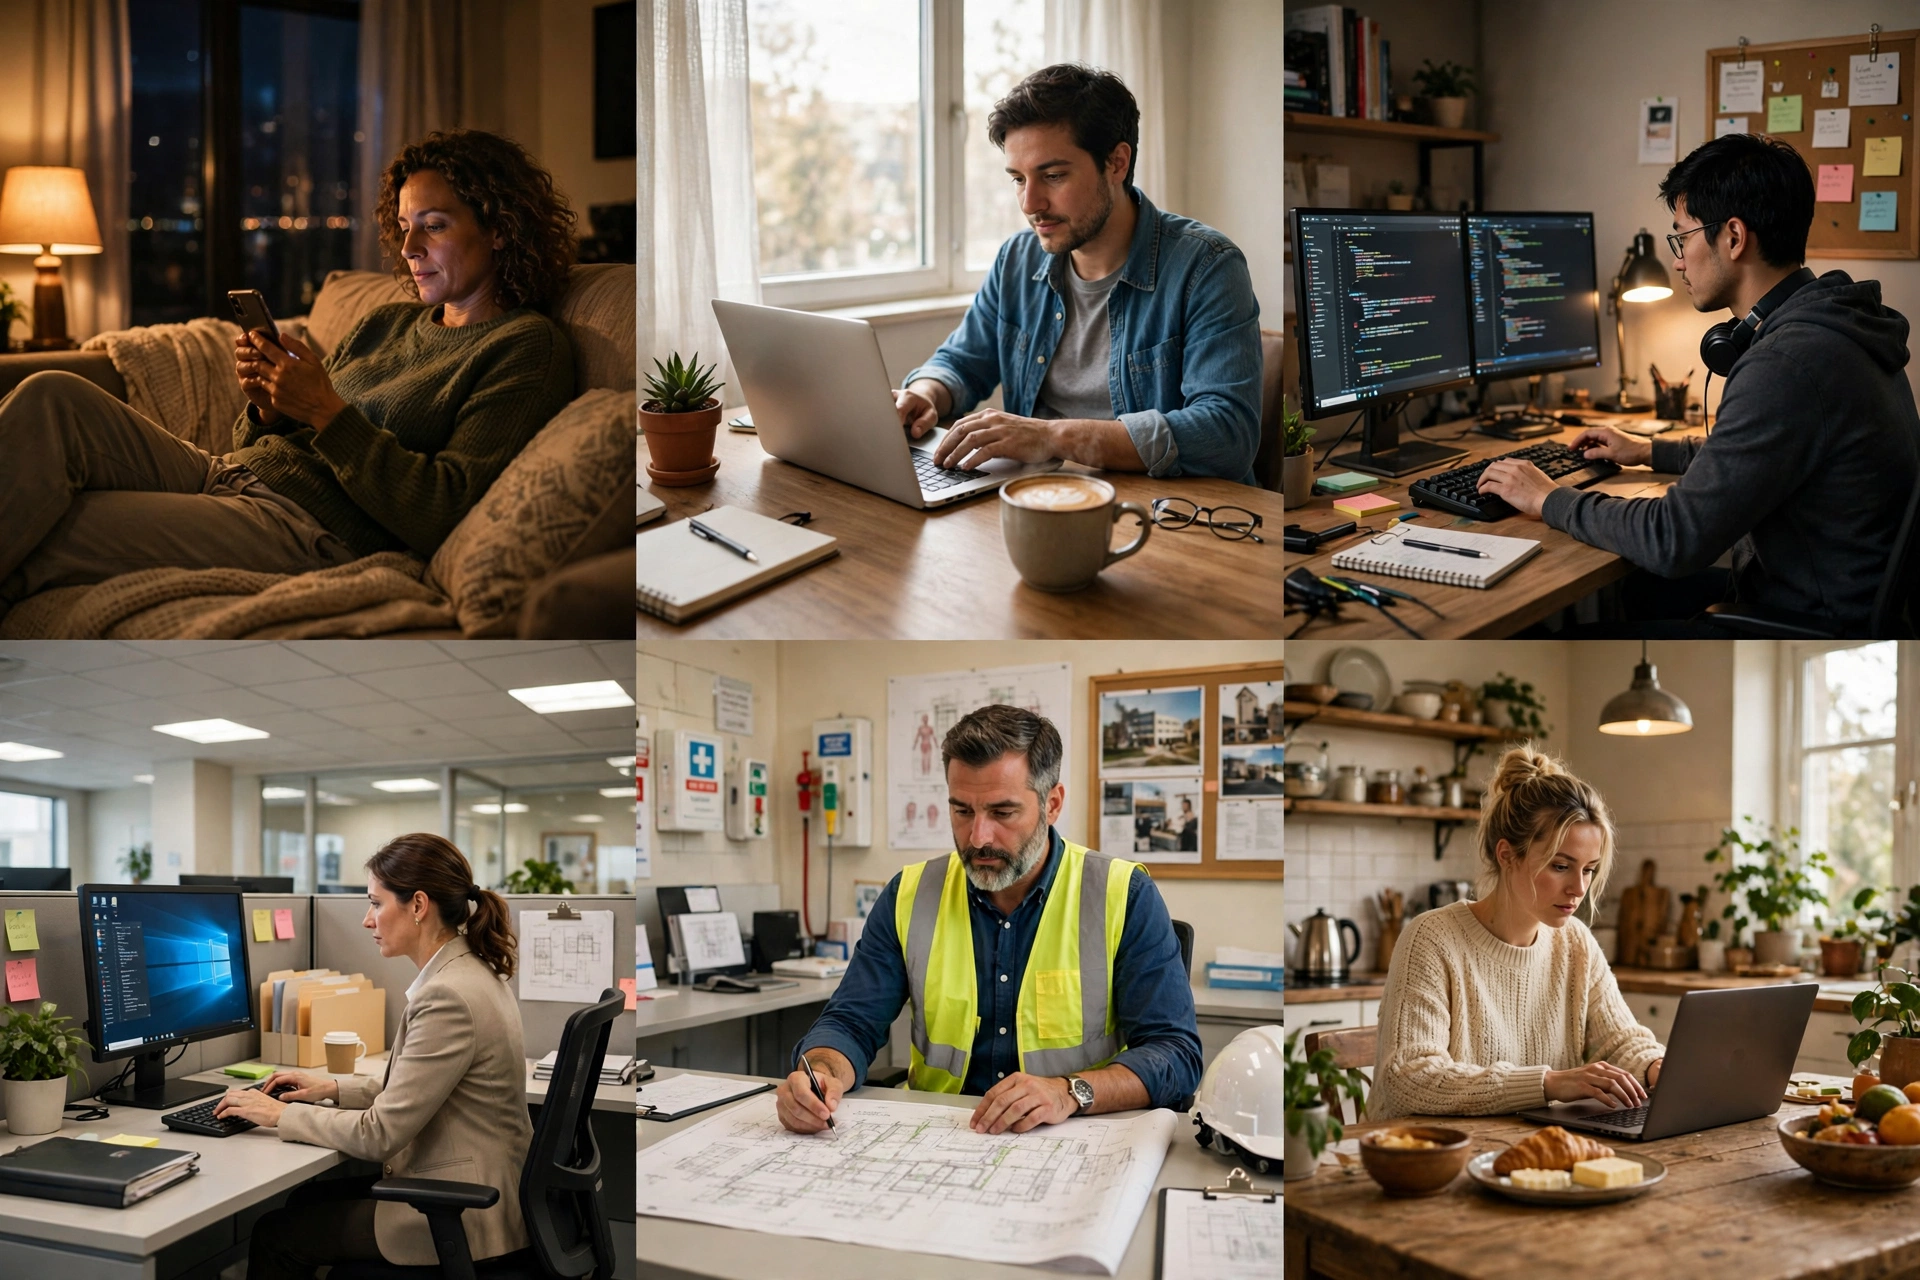
    Here’s the problem with that sentence. There is no “ChatGPT” the way there’s a phone book. There are rooms. And the person in each room is a different person, sitting in a different chair, at a different time of day, asking a different kind of question.

    A free-plan mobile ChatGPT user on the toilet is not the same human as a Claude user inside their desktop looking up technical documentation at 10 in the morning. Treating them as one audience because the logos are similar is how businesses end up advertising B2B services on a consumer feed — the same mistake, wearing a new jacket.

    The five rooms

    Room one: free ChatGPT on a phone. Consumer questions. Evenings, couches, commutes. What’s a good car stereo, write my cover letter, explain this homework. Enormous volume, almost no B2B buying intent.

    Room two: paid ChatGPT at a desk. Prosumers and knowledge workers who chose it as a tool. Better questions, work hours, some buying intent — when the question is about their own workflow.

    Room three: Claude at a desk. Developers, analysts, technical professionals. This is the room that reads documentation for a living. Weekday-shaped, deep, specific.

    Room four: Copilot inside Edge and Office. The corporate room. These people didn’t choose an AI — it arrived inside the tools their employer already runs. Facility managers, compliance staff, operations people, asking work questions in work language, mid-task.

    Room five: Gemini inside Google search. Everyone, for everything, at search scale. The broadest room and the shallowest intent per question.

    Same species of technology. Five different demographics. “Get cited in AI” means nothing until you say which room.

    What the counting says

    I count AI citations for a living — six months of Bing AI Performance data across my own network, 1.6 million citations and change. The rooms are not a theory. They’re in the numbers.

    On Tygart Media, the single most-cited page is a Claude AI pricing explainer — 1,388,909 citations. The audience for this site is technical professionals, and the citation traffic is weekday-shaped: it rises when people are at work and flattens when they aren’t. Room three, behaving like room three.

    On Healthcare Facility Hub — a site for hospital facilities and infection-control people — Microsoft’s AI surfaces cited 188 pages a total of 43,994 times in six months. The top pages are an ICRA matrix (4,067 citations), hospital evacuation planning (2,766), ASHRAE 170 ventilation requirements (2,435), NFPA 101 life safety (1,802). The questions behind them read like this: what has to be in a facility’s emergency preparedness plan about emerging infections; which fire safety feature keeps smoke in one zone. Nobody asks those questions from a couch. Those are room-four questions — asked at a desk, inside a Microsoft environment, by someone whose job depends on the answer being right.

    Two sites. Two rooms. Neither audience is in the room the hype is selling.

    The test that settles it

    Before you pay anyone to get you cited “in ChatGPT,” ask one question: which room is your buyer sitting in when the buying question forms?

    If you’re selling to hospital facilities staff, your room is Copilot at a desk, and the content that wins there is an ICRA matrix, not a viral post. If you’re selling car stereos, room one is genuinely your room, and God bless. The tactic isn’t wrong or right — the fit is.

    Anyone who can’t tell you which room they’re putting you in is selling you the label. The label is the one part that doesn’t matter.


    Will Tygart runs Tygart Media. The citation counts above are from his own six-month Bing AI Performance board, counted nightly. The $97 AI Citation Quick-Scan exists because “which room cites you” is a measurable question: https://tygartmedia.com

  • What Is an Old Page Telling You When It Starts Getting Cited Again?

    What Is an Old Page Telling You When It Starts Getting Cited Again?

    Everybody talks about AI citations like they’re weather. Somebody reads somebody else’s report, shows you a screenshot of a ranking, and that’s supposed to mean something.

    A screenshot is a rumor. I wanted a count.

    So we built what I call the bait board. It’s simple: every page on this site is bait. A “bite” is when an AI answer — Bing’s, in our case, because that’s where we pull the data — cites one of your pages. If you can’t count it, you can’t improve it. The board counts it.

    The board, as of this week

    Over the last six months, Tygart Media has pulled in roughly 1.6 million AI citations. Across the two six-month windows we’re comparing, 997 distinct pages have been cited. 870 of them are biting right now.

    One page does most of the heavy lifting: our Claude AI pricing page, at 1,388,909 citations. That’s not a typo. That’s what happens when a page becomes the answer to a question a lot of people ask every day.

    Every page on the board lands in one of four buckets:

    • DEFEND — 945 pages. Biting now. Somebody out there thought it was good, and an AI keeps handing it out as the answer. You protect these. Iterate in place, never rename them, and check whether you’re still holding the seat — because a citation is a seat, and nobody holds your seat for you.
    • RE-BITE — 52 pages. Proven bait that went quiet. They were cited, then they weren’t. Sometimes a competitor wrote the Costco-hat answer with the glasses and the supply chain added on, and took the seat. Sometimes the page just went stale. Either way: patch it in place and cast again.
    • SOAK — 121 pages. Published, no bite yet. Let compounding do its work. Not everything needs touching.
    • PRUNE — 61 pages. Never picked up. Stop feeding them.

    The data comes down every night — three CSVs out of Bing Webmaster Tools: AI Performance, grounding queries, and pages, six-month window. I download them by hand on purpose. Don’t automate yourself out of this stuff. When you pull it yourself, you notice the weird one. You click through. You find something.

    And the method matters more than the tool. It’s the tactic, not the tool — everybody’s tools are calculators. Whatever way you do this, do it the same way every time, because the delta is the information. Change your method every week and you’ll never know whether the number moved or you did. I used to look at this every 28 days. The world doesn’t run on 28 days anymore. Clarity defaults to three days, and honestly, three days is about right now. I check daily. I’m scared not to.

    But here’s the thing I actually sat down to teach this week, and it’s the thing the board taught me — three patterns I can only see because the count runs every night.

    Pattern one: the fastest source is not the cited source

    Look at the dead bait. A big share of it is our timed storm watches — the automated storm updates that publish as weather moves through a part of the country, update, and expire.

    They almost never get cited by Bing. Almost never.

    I think I know why. When the moment passes and the engine settles on an answer, it doesn’t cite the quickest source. It cites the original, the best source. On a storm, we’re the quickest source there is — we’re built for speed, the update is live while it’s still raining. But quick is not the same as best, and after the fact, Bing goes back and picks the best. That’s not us, and on a timed watch it was never going to be us.

    That doesn’t make the storm work useless — it feeds other sites of ours, and being first matters in other places. But if you’re measuring it by Bing citations, you’re grading a sprinter on a marathon course. Know which race each page is running.

    Pattern two: a good article that dies at three weeks usually died in the title

    The other thing I see on the board: solid articles — some of them op-ed pieces I’m proud of — that come up on three weeks old and fall off a cliff. Not bad articles. Articles that never made the first pass.

    When I look at those, it’s the title. The title didn’t tell the engine, or the reader, what question this page answers. So it never got picked up in the first place, and by week three there’s nothing left to defend.

    The fix isn’t rewriting the whole piece. The fix is two moves:

    1. Retitle it so it answers the actual question in the words people ask it.
    2. Give it something evergreen inside — a chart, a reference block, a section that stays true after the moment passes. An op-ed with an evergreen chart in it has something durable to be cited for. A storm piece with a standing reference section — what a project manager does when this kind of storm hits, say — has a reason to exist after the rain stops.

    Timely gets you published. Evergreen gets you cited. A piece that only has the first one is on a three-week clock whether you know it or not.

    Pattern three: old pages that bite again are sensors

    This is the one that changed how I run the board.

    Months ago, out of our Everett work, we wrote about a Boeing contract — the SPIA contract. Old news. Done. Except it isn’t: that page keeps showing up. It keeps getting cited.

    My first instinct, months back, would have been to call that noise. It’s not noise. It’s a sensor going off.

    If an old page starts biting again, it means the world came back to that topic and there wasn’t much else there. Thin coverage. We saw the same shape on one of our other properties — a sustainability piece about cosmetics CEOs that narrowed down, over time, to two or three companies actually doing the thing. The page didn’t change. The field did, and the page was the instrument that showed it.

    Think about it the other way: say we wrote up an Everett AquaSox game a while back, and one of the kids in that game makes a World Series roster in a year or two. That old game page could light up again — and when it does, it tells you something is happening before the crowd writes about it. The re-bite is the first inkling. A disturbance, if you’ll forgive the reference.

    So I’ve stopped treating old pages as prune candidates by default. Some of them aren’t content anymore. They’re instruments. You don’t throw away a gauge because it’s been quiet — the quiet is the baseline, and the spike is the signal. A re-bite on an old page is market intelligence, and it’s free: the page is already written, already out there, already costing you nothing to leave in the water.

    Prune still exists — 61 pages earned it. But before a page goes in that bucket now, it gets one more question: is this dead, or is this a sensor that just hasn’t gone off lately? Those are very different things to delete.

    The seat, and keeping it

    Here’s the whole doctrine in one breath: get cited and you’ve taken a seat. Leave, and someone’s sitting in it when you come back. The engines don’t owe you the chair. So you count — nightly, same method, same window — and you sort every page into defend, re-bite, soak, or prune, and you listen to the old pages, because they’re telling you where the world is thin.

    That’s the bait board. It isn’t fancy. It’s three downloads, four buckets, and the discipline to do it the same way tomorrow.

    AI Citation Quick-Scan, $97 — Tygart Media runs your pages through the Bait Board count: which pages AI answers cite, which went quiet, which are sensors

    If you want to run this yourself

    I teach this in layers, same as everything else we sell:

    • The Bait Board one-pager (free PDF). The four buckets, the three nightly downloads, and the counting rules on one page. Print it, tape it over your desk, start counting.
    • The Bait Board Field Guide ($7 PDF). The full method: how the six-month window works, how to read fresh bites against dropped pages, the churn math, and the sensor test — how to tell a dead page from a quiet instrument before you prune it.
    • The Bait Board, Book-for-Bots edition ($17). The method written for the machines as much as for you — structured so an AI assistant can run the nightly sort with you: bucket definitions, decision rules, and the worked examples from this site’s own board, including the storm-watch and three-week-title findings above.
    AI Search Visibility Package product card — $450 standing citation-board practice for business websites, from Tygart Media

    And if you’d rather have it done with you: the AI Citation Quick-Scan ($97) is where we run your pages through this same count and hand you the board; the $450 tier builds the board into a standing weekly practice on your site; and the $2,250 tier is the full desk — board, refresh queue, and the sensor watch running as a system. Same ladder we run here. The count comes first either way.

    AI Search Visibility Package product card — $2,250 complete bundle: citation board, refresh queue, and old-page sensor watch run as a system, from Tygart Media

    Start with the count. Everything else is commentary.

    — Will

  • Split the Panel: Brand Prompts and Non-Brand Prompts Are Two Different Tests

    Split the Panel: Brand Prompts and Non-Brand Prompts Are Two Different Tests

    Your AI visibility report says you were cited 118 times last month. Good month or bad month?

    You can’t tell — because that number blends two different tests into one score, and the two tests fail for opposite reasons.

    PressGEO ran a rolling 30-day probe — 1,000 prompts, window ending November 8, 2026 — and published the split most dashboards never show. On the 357 prompts that named the brand, the domain was cited 118 times: a 33.1% citation rate. On the 643 prompts that didn’t name it — the category questions, the discovery questions, the “best tool for X” questions a stranger actually asks — the count was zero. Not low. Zero.

    One blended number for that month reads 11.8%, and it is useless. It can’t tell you whether the engine can’t find you or won’t choose you. Those are different problems with different fixes, and rewriting pages — the default response to a bad visibility number — only addresses one of them.

    Two gates, multiplied

    A citation is a conditional probability with two terms. First the engine has to retrieve you: your domain has to enter the candidate set at all. Then it has to absorb you: pick your page as evidence for the answer. Citation rate = retrieved × absorbed. Dashboards measure the second term obsessively — position inside the answer, share of voice, sentiment — and almost never estimate the first.

    Brand-named prompts mostly test the first gate under easy conditions. When someone types your name into the question, the engine barely has to discover anything; if your site is indexed and reachable, your pages walk through. Non-brand prompts test the real contest: a question with no name in it, where your page competes against every other page the engine could ground on. Fail the first gate there — never retrieved — and nothing about your page’s quality matters, because the page was never in the room.

    That is what PressGEO’s zero means. Not “their content was slightly worse.” The domain never got retrieved on discovery questions at all. No rewrite of any single page fixes a retrieval absence; rewriting is an absorption tool.

    What each failure actually needs

    When the brand panel is healthy and the non-brand panel is empty, the problem is upstream of your prose:

    • Coverage of the question, in the asker’s words. Non-brand retrieval runs on whether you have a page that plainly answers the category question someone typed. One real question per page, in the words the asker used — not your service-page vocabulary.
    • Presence where the engine looks. Engines ground on third-party surfaces too. A brand that exists only on its own domain has a thin retrieval footprint.
    • Structure the passage can be lifted from. Clear headings, a direct answer near the top, facts stated in plain sentences. Retrieval picks passages, not vibes.

    When both panels retrieve you but citations stay low, the problem is absorption, and now page work is the right tool: sharper answers, better evidence, statistics and sources on the page, the passage that says the thing most citable-first.

    The fixes are not interchangeable. Splitting the panel is how you know which one you’re buying.

    Our own board, read the same way

    We run a version of this on our own site. Microsoft’s AI Performance export for tygartmedia.com, two overlapping six-month windows compared on the board we rebuilt today: 997 distinct pages cited across the windows, 870 of them cited in both — and 135 pages cited on the latest day alone. The split that matters for operations isn’t the total. It’s that 52 previously-cited pages went quiet while 75 fresh pages got their first bite. The quiet 52 are an absorption-and-freshness problem, page by page. If the fresh-bite count ever fell to zero while the old pages kept biting, that would be the opposite diagnosis — a discovery failure — and the response would be new coverage, not rewrites.

    Same ledger, two columns, different work. That’s the whole discipline.

    The denominator rule

    One more discipline from the same GeoAura write-up, and it’s the one that saves you from chasing ghosts: version your denominator. Foglift’s per-answer citation count moved from 6.03 to 5.8 between its October 24 and November 8 cuts of the same report — not because any engine changed, but because the measurement window lengthened. A dashboard that doesn’t date-stamp its denominator will manufacture a trend out of a longer window, and someone will rewrite a page to fix arithmetic.

    Run it this way

    1. Fix your prompt set, then split it before you score it. Brand-aware prompts in one panel, category and discovery prompts in the other. Same set every week.
    2. Record retrieved / not-retrieved separately from cited / not-cited. The retrieval gate is a yes-no column: did any URL from your domain appear at all?
    3. Diagnose by panel, not by blended score. Brand strong + non-brand empty = retrieval work: coverage, presence, passage structure. Both retrieving + few citations = absorption work: evidence and answer quality on the page.
    4. Date-stamp every denominator. Window, prompt count, and engine mix ride along with every number you keep.
    5. Don’t rewrite on a one-week move. Panels are noisy week to week; act on the pattern across a month.

    PressGEO’s zero is the cleanest possible illustration: 643 chances, no retrieval, and no amount of polishing the pages would have changed it. Split the panel first. Then fix the gate that’s actually failing.

    Source: PressGEO probe results as published in GeoAura, “How to Measure GEO Visibility: Metrics & Methodology,” updated November 9, 2026 (nextaura.me). Board figures: our own Bing AI Performance export comparison, rebuilt November 9, 2026.

  • How AI Search Visibility Is Actually Tracked (and What the Tools Can’t See)

    How AI Search Visibility Is Actually Tracked (and What the Tools Can’t See)

    Here’s how AI search visibility is honestly tracked: you write down the actual questions your customers ask, you ask those same questions in the actual answer engines on a fixed schedule, and you record three things separately — whether the answer names you, whether it cites you, and whether what it says about you is true.

    That’s it. Everything else — dashboards, scores — is packaging around that habit, or a substitute for it. And there’s a problem worth understanding before you buy a substitute: ranking and being cited are not the same event, and a tool that conflates them will mislead you without making a number up.

    Ranking is not being cited

    Start with the structural fact. Search the old way and you get a ranked list of pages. Ask an answer engine — Copilot, ChatGPT, Perplexity, the AI box atop Google — and you get a paragraph, written on the spot, with a handful of sources cited beside it.

    Those two events are only loosely connected. A page can sit at position two in the organic list and never get quoted, while a competitor at position four gets built into the answer. It isn’t a glitch: the engine doesn’t summarize the top result. It breaks your question into smaller sub-questions, looks for material on each, and assembles an answer from what it finds — and studies of cited URLs find just a small minority come from the organic top ten.

    So rank-based tracking measures the list while your customers read the paragraph. That’s the gap where businesses get surprised: “we rank fine, why is the machine recommending somebody else?” The events that matter are being named, cited, and described correctly. For the basic method as a straight answer, see how do you measure AI search visibility. This piece covers the part usually skipped — the limits.

    The only honest method: fixed questions, three separate records

    The method fits on an index card. Build a list of the questions your customers actually ask — not keywords, questions, in their words: “Who fixes a flooded basement in Tacoma?” “What does water damage cleanup cost?” Twenty or thirty is plenty. Then, on a fixed schedule — weekly is honest, monthly the floor — ask them in the engines your customers use, and record what comes back.

    The recording is where honesty lives or dies, because one answer contains three different facts:

    • Mentions. Does the answer name your business at all? Not link, not cite — name. The customer reading that paragraph sees your name or a competitor’s.
    • Citations. Does the engine cite your pages as sources? You can be named with no citation, and cited without being recommended — quoted as background while somebody else gets the call.
    • Accuracy. What does the answer say about you, and is it right? Engines repeat stale facts and invent new ones with total confidence. An answer describing a service you stopped offering two years ago is not a win — it’s a wrong sign on your door.

    Three columns, kept apart. Any tool worth paying for just runs that without the handwork — and the moment one blends those columns into a single number, it throws away the only details you’d ever act on.

    What tracking can genuinely see

    Done this way, tracking earns its keep. Four things it shows straight:

    • Trends on fixed questions. Same questions, same schedule. When your name starts appearing in answers it wasn’t in, that’s real movement — usually tied to work you did.
    • Which pages get cited. Not which pages rank — which ones engines actually pull from. In our own work, a few pages carry a large share of the citations.
    • Share against named competitors. Record who gets named when you don’t, on the same question set.
    • Answer drift. Ask the same question next month and the answer is different: a new source, a dropped name. Drift is normal — and why a one-time check is worth little.

    What no tool can see

    Now the part that doesn’t make it into the sales deck: five things no tracker — ours, theirs, anybody’s — can show you.

    The answer your actual customer got

    Answers vary by who’s asking, where they are, and when they ask — the same question can name different businesses for two people in the same town on the same afternoon. A tracker sees a sample, from its own accounts, and a sample is not the population. Anyone presenting a report as a census of what your customers saw is overselling the instrument.

    The questions nobody thought to ask

    Your prompt list is a map, and the map is not the demand. Customers ask things you’d never predict — oddly specific, half-wrong, mid-emergency questions typed one-handed at 2 a.m., some the most valuable in your market because the person asking is ready to buy. If it isn’t on your list, your tracker never asks it. The fix isn’t a bigger tool — it’s refreshing the list from real life: call recordings, intake notes.

    Why the engine picked a source

    No engine publishes its citation reasons. A tracker can tell you a page got cited, never why that page and not yours — anyone who claims otherwise is guessing and charging for the guess. What you can do is compare: read the cited page next to yours. Does it answer in the first paragraph, state facts plainly enough to quote, is it current? That’s judgment, not telemetry.

    What the answer caused

    Attribution stops at the answer. The engine doesn’t report back that the homeowner who read its paragraph called you, called the other company, or fixed it themselves — those calls are invisible to every visibility tool ever built. The last mile shows up only in your own books, so report and call log get read side by side before anybody claims the visibility did anything.

    Engines that don’t show their answers

    Some surfaces can’t be sampled at all — answers behind logins, in apps, in voice assistants. A tracker reports on the engines it can reach and has nothing on the rest. Ask any vendor which engines their number doesn’t cover.

    The score problem

    Which brings us to the product most buyers are actually being sold: a single visibility score. One number, proprietary formula, up and to the right in the demo. The trouble isn’t that it’s fake — it’s what it has to compress to exist.

    Run a small example. Over a quarter, a business gets mentioned in more answers and cited more often too. By any blended formula the score rises, and the quarterly report is a celebration. But read the accuracy column, the one the score dissolved: the engines now describe the business as offering a service it dropped last year, at a price it no longer charges, because an old page still says so. Customers call with wrong expectations, and staff spend five minutes a call correcting the internet.

    Score up. Facts wrong. Both true at once — and only one shows up in the report the owner paid for. A blended number turns three actionable facts into one feeling. A score that rises while the answer about your business is wrong isn’t measuring your visibility. It’s measuring its own smoothness.

    What to demand instead

    You don’t need to become a measurement expert. Ask for four things, and watch whether the seller can produce them.

    • Your prompt list, built from real customer questions — and shown to you. Generic questions make generic tracking.
    • The raw answers, kept. Not a screenshot of the best week — the actual paragraphs, so anything in the report traces back to a readable answer.
    • The three records, kept separate. Mentions, citations, accuracy — three columns, never one blended score. If a summary number exists, it sits on top of the columns, not instead of them.
    • Figures you can re-pull yourself. Where engines expose their own numbers — Bing Webmaster’s AI Performance reports, Microsoft Clarity — those live in accounts you own, and any figure from them can be checked by you, in your login. Hold every report to that standard: see the best agency for AEO SEO reporting is the one whose numbers you can re-pull, and our page on what an AI visibility report should show lists the sections to expect. An unverifiable report is a story you’re being told.

    Measurement, done honestly, is a flashlight, not a scoreboard. It shows you where to work next — which question you’re absent from, which fact about you has gone stale. The moment the measurement becomes the product being sold, it stops measuring your business and starts measuring itself. Run the fixed questions. Keep the three columns. Read the actual answers.

    Questions buyers ask us

    How do AI visibility tools work?

    At bottom, every one of them does what you’d do by hand: asks a fixed list of questions in the answer engines, on a schedule, and records what comes back — who’s named, who’s cited, what changed. The honest ones keep the records separate and show you the raw answers; the expensive-looking ones blend everything into a proprietary score. Either way, all of them see a sample — never every answer a customer received.

    Why doesn’t my Google ranking match my AI mentions?

    Because they’re different events. Ranking is your position on a list of pages. A mention is whether an answer engine names you in a paragraph assembled from its own sub-questions — whose cited sources overlap the organic top ten only a little. You can rank second and go unnamed while a competitor at fourth gets quoted — and tracking only the list keeps that gap invisible.

    Can I track AI visibility myself?

    Yes — the basic version is genuinely do-it-yourself. Write down twenty or thirty questions your customers actually ask, put them to Copilot and ChatGPT, and record three things: named, cited, accurate. Repeat monthly, same questions, and check the figures the engines give you in Bing Webmaster and Clarity, in your own accounts. An afternoon to start, an hour a month to keep. What you’re paying for, if you pay, is never skipping the month.

  • An AEO Report You Can Re-Pull: A Worked Example

    An AEO Report You Can Re-Pull: A Worked Example

    A report you can trust is a report you can re-pull. Every figure in it traces back to a source you own — your own Bing Webmaster account, your own Microsoft Clarity account — so checking the work takes an afternoon, not an act of faith.

    I have argued before that the best agency for AEO SEO reporting is the one whose numbers you can re-pull. That is the standard. Our page on what an AI visibility report should show lays out the requirements. This piece is the missing third thing: the artifact itself. What follows is one monthly report, walked section by section — what each section shows, where each number lives, and how you would re-pull it yourself to check it.

    One disclosure before the numbers. This is a worked example. The business is a regional restoration company, the kind of outfit that answers the phone at 2 a.m. when a pipe lets go. Identifying details are changed, and the figures are a composite drawn from real reporting periods — not one client’s month dressed up as gospel. The sections, though, are the real sections, in the real order, and every figure in every section has a home in an account the client owns and can open without asking me.

    1. The ledger summary

    The first page is the whole story in one table: how many times the answer engines cited this business in the period, set against the period before. Nothing else. No score, no grade, no wall of arrows.

    Measure This period Last period Change
    Total citations 1,184 1,021 +16%
    Queries where the business was cited 214 187 +27
    Pages cited at least once 38 34 +4

    Where the numbers live: the overview export in the AI Performance section of Bing Webmaster Tools. The client logs into their own account, picks the same date range printed at the top of the report, downloads the CSV, and the headline citation count is sitting right there. Re-pulling this section takes about four minutes. If the number in the report and the number in the export disagree, the report is wrong, full stop — and the client found that out from their own account, not from a call with me.

    2. Share on the queries that pay

    A citation total by itself is a vanity number wearing a suit. What matters is which questions the citations hang on. This section lists the money questions — the ones a buyer asks an answer engine right before picking up the phone. For a restoration company, that is things like “water damage cleanup near me,” “how much does mold remediation cost,” and “who do I call for a burst pipe.” Next to each question: whether this business got cited for it, and who else did.

    Where the numbers live: the Search Queries export, same Bing Webmaster AI Performance section, same date range. Re-pull it, look up the questions that matter to the business, and the cited sources are listed per query. This is the section owners actually read, because it reads like the market itself. You can watch a competitor take a question you used to own, in plain text, with nobody’s opinion layered over the top of it.

    3. Page movers

    Citations land on pages, not on businesses. This section lists the pages that gained citations in the period and the pages that lost them, biggest moves first. A service page that doubled its citations after a rewrite. A location page that went quiet. A post from two years ago that an engine suddenly started quoting.

    Where the numbers live: the Page Stats export, same account, same date range, compared against last period’s export — which is why we keep every month’s files. Re-pulling means downloading the current export and setting it against the file from the prior period. The “why” written next to each mover is our read, and it is labeled as a read. The movement itself is not an opinion. It is in the client’s own files.

    4. New questions

    Every month, the query export contains questions that were not in it before. Somebody asked an engine something new — a new phrasing, a new service name, a question nobody in the market has written a page for yet. This section lists those questions, flags the ones this business was already cited on, and marks the rest as gaps.

    They come straight out of the same Search Queries export. There is no separate tool and no secret feed behind this section. New questions are the demand moving, in public, in the askers’ own words. Half of next month’s content list is usually sitting right here — and the client can check that claim too, because the questions are in their export, not in my notes.

    5. The work, priced against the movement

    This is the section most reports skip, and it is the one that keeps everybody honest. On one side, what was actually done in the period, named plainly: three pages published, two pages rewritten, one round of technical fixes. On the other side, what moved. It is the measurement loop from the workstreams behind AI SEO services, printed instead of described — the work and the numbers on facing pages, where the client can judge whether one earned the other.

    Two rules govern this section. First, the work list is complete. The page that was published and went nowhere sits on it, right next to the one that took off. Second, no credit is claimed where the movement cannot be tied to the work. If citations rose on a question nobody touched, the report says so and calls it what it is: the market moved, or the engine changed its mind, and we do not know which. An agency that only shows you the wins is editing. Editing is the first step toward inventing.

    6. What the report refuses to show

    The last section is a list of absences, and it is there on purpose. There is no proprietary visibility score, because a score only the agency can compute is a number you can never check. There is no best-week screenshot, because a business runs on months, not on its best seven days. And the engines are never blended into one soup of a number. The Bing and Copilot figures come out of the client’s own Microsoft accounts; anything that cannot be pulled from a source the client controls is reported separately, with its method stated, or left out — with the report saying it was left out.

    Blending is a hiding place. A blended number can rise while the engine that actually sends you buyers is falling, and you would never see it. Separate numbers can be wrong, but they can be caught. That is the whole trade, and we will take catchable over impressive every time.

    The test

    Here is the one test you can run on any report from any agency, including this one. Pick a figure — any figure, the bigger the better. Ask one question: “Show me where this lives in my own accounts.” Then watch what happens. If you get walked to the export, the account, and the date range, and the number matches when you pull it yourself, you are looking at reporting. If you get an explanation of why the methodology is proprietary, you are looking at a story about reporting. The figure was never the product. The trail behind the figure is the product.

    Questions buyers ask

    What should an AEO report include?

    Five things: a citation total you can re-pull, your share on the specific questions your buyers ask, which pages gained and lost citations, the new questions showing up in the data, and the work done in the period set next to what moved. A report carrying a score you cannot recompute from your own accounts is missing the point, even if it has everything else.

    How do I check my agency’s numbers?

    Log into your own Bing Webmaster Tools account, open the AI Performance exports for the same date range printed on the report, and compare. The overview export checks the headline, the queries export checks the questions, the page stats check the pages. Microsoft Clarity is yours the same way. An agency should be able to tell you which export backs which figure, gladly. That conversation is the check.

    What is a red flag in an SEO report?

    A number with no trail behind it. Proprietary scores, blended engine totals, best-week screenshots, and rankings reported without the source account are all the same flag in different colors: a figure you are being asked to take on trust. Trust is fine in a relationship. It has no place in a spreadsheet.

  • AI SEO Services, Explained as Work

    AI SEO Services, Explained as Work

    When a customer asks Copilot or ChatGPT who to call, the machine names somebody. AI SEO services are the work that gets your business named: measuring what the machines say about you today, fixing what your site hands them, and publishing pages that answer real buyer questions clearly enough to be quoted.

    That’s the short version. The longer version matters, because “AI SEO” gets sold as a package, a plugin, or a monthly mystery. It isn’t any of those. It’s four kinds of work, done in order, by a person, on a schedule. Here’s each one, plainly.

    The baseline: finding out where you stand before touching anything

    The first job is a measurement job, and it’s unglamorous. Before anybody fixes or writes a thing, we find out what the machines currently say about the business.

    That means asking the machines the questions your customers actually ask — “who’s a good roofer in Puyallup,” “what does a water heater replacement cost,” whatever your buyers type or say out loud — and writing down who gets named. You, your competitors, a directory, nobody. We do it across the engines your customers use, and we save the answers word for word, because the exact wording is the evidence.

    Then we look at what your site currently gives those machines to work with. Sometimes the answers are wrong because the site is wrong: an old address on one page, a service you dropped still listed on another, the real expertise buried three clicks down under marketing copy. Sometimes the machines have simply never been handed a clean, quotable description of what you do.

    The baseline ends with a starting line: here’s who gets named today, here’s what the engines say about you today, here’s the list of what’s broken or missing. It isn’t exciting. But without it, every later claim of progress is a guess, and any report you get afterward is decoration. Nothing should get sold or fixed before this exists.

    Technical fixes: making the site readable to machines

    The second workstream is the one nobody sees, and it’s the reason content work fails when it’s skipped.

    Answer engines read your site the way a careful skimmer does: headings first, structure always. So the work is page structure — one clear topic per page, headings that are the actual questions buyers ask, answers that start with the answer instead of a paragraph of throat-clearing. It’s structured data where it helps: the behind-the-scenes labels that tell a machine this is a business, this is where it is, this is what it does, these are its hours. It’s crawl and indexation basics — making sure the pages that matter can actually be found and read, and the ones that shouldn’t compete are out of the way.

    And it’s the dullest fix of all: finding the pages that say two different things. Two service pages describing the same job differently. A location page the business left behind two moves ago. Machines average contradictions into mush, and mush doesn’t get quoted.

    None of this photographs well. There’s no ribbon-cutting for a corrected heading structure. But every page published on top of a site the machines can’t read cleanly is work poured into a cracked bucket.

    Demand-built content: pages from the questions buyers actually ask

    The third workstream is the writing — but it’s writing aimed at a specific target. We build pages from the questions buyers demonstrably ask, not from a list of keywords somebody brainstormed in a conference room.

    Real query data shows what people type and say when they’re close to spending money. It is rarely what the business would have guessed. Owners describe their work in trade language; buyers ask in kitchen-table language. The page has to be built in the asker’s own words, one real question per page, or the machine matching a question to an answer will walk right past it.

    Each page is written answer-first: the direct answer up top, in plain sentences, short enough and complete enough that an answer engine can lift it whole and attribute it to you. The detail, the caveats, and the proof go underneath for the humans who keep reading. That’s the whole trick, and it isn’t really a trick: the citation goes to the page that answers the question most cleanly.

    This is also where business owners should be careful about what they’re buying. A page written for a citation is a different object from a page written to rank for a phrase, and a different object again from a blog post written because Tuesday is blog day. When you’re vetting who’s going to do this work, there’s a test worth applying — we wrote up how we’d rate AI SEO services for small businesses by the test they should pass. And if you’re still working out which pieces of this you even need, that’s a separate decision from how the work runs; we laid that out in which AI SEO services are right for a small business.

    Authority and citation measurement: the loop that proves it

    The fourth workstream is the one that keeps the other three honest. On a schedule — not when somebody remembers — we ask the machines the same questions from the baseline and record who gets named now.

    Citation tracking against the baseline is what turns this from a hope into a measurement. A question where a competitor was named in March and you’re named in May is a moved needle you can point at. A page that got quoted for a while and then slipped is a fix-it item, not a mystery. The gaps that remain — the questions where nobody good gets named yet — become the next pages to build. The work feeds itself: measure, fix what slipped, build the next page from the next gap.

    Done as a standing service, this loop is the heart of it; it’s the work our AI Citation Service is built around. And it’s why the reporting matters as much as the work itself. A report that shows logins and impressions tells you nothing about whether the machines name you more than they did. We wrote about exactly what an AI visibility report should show — who gets named, for which questions, and how that changed since the last check.

    What the work is not

    Short and honest: it is not buying links. It is not stuffing keywords into pages until they read like a parts catalog. It is not a plugin somebody installs once and bills you for monthly. It is not a guarantee — anyone who promises you the machines will name you by a date is selling you a date, not work. The engines change how they answer, competitors publish too, and no honest person controls the outcome. What can be controlled is the work: measured, structured, published, and checked. That’s the part you’re actually buying.

    What to expect month to month

    If this work is running properly, the rhythm is boring in the best way. First you get a baseline — a written record of where you stand. Then a list of fixes, worked through in the open, most of them invisible to anyone but the machines. Then pages appear one at a time, each built from a real question, each one checked after it lands. And on a schedule, you get a report that shows movement: who the machines name now, for which questions, against where you started.

    That’s it. No fireworks, no mystery line items. Just the work, in order, with receipts.

    Questions owners ask us

    What does an AI SEO service actually do day to day?

    Checks what the answer engines say about your business, fixes the pages and structure those engines read, writes new pages that answer the questions your buyers are asking, and tracks whether the machines name you more over time. Most days it’s measurement and editing, not anything dramatic.

    How is AI SEO different from regular SEO?

    Regular SEO aims at a list of links — getting your page to rank where people click. AI SEO aims at the answer itself — getting your business named and quoted inside what Copilot or ChatGPT tells the asker. The technical foundations overlap heavily; the target, and how you measure success, are different.

    How long before AI mentions my business?

    Nobody honest can date it. It depends on where you start, how much is broken, and how active your competitors are. What can be promised is the sequence: a baseline you can see, fixes you can verify, pages you can read, and scheduled checks that show whether the mentions are moving. If they’re not, the checks are what tell you what to change next.

    Can I do AI SEO myself?

    Parts of it, yes. You can ask the engines the questions your customers ask and write down who gets named — that’s the start of a baseline, and it costs you an afternoon. You can fix the page that lists your old address. The parts that usually break down for owners are the schedule and the record-keeping: the checking has to happen every month, against the same questions, or there’s no measurement — just impressions. The work isn’t secret. It’s just work.

  • Half the Citations Sit on Three Pages

    Half the Citations Sit on Three Pages

    Eight receipts so far in this series: 44,583 citations at BC ESG, 109,844 at Healthcare Facility Hub, 813,426 on this site, 50,607 at Risk Coverage Hub, 57,798 at Continuity Hub, 111 at Restoration Intel, 295 earned by Claude’s own pasted error messages, and a weekly rhythm that keeps office hours. The ninth receipt is a first: the first AI Performance measurement we have ever pulled for theuniversalcommerceprotocol.com — the site we built to teach the Universal Commerce Protocol, the standard AI shopping agents use to buy things. Ninety days, August 8 to November 5, 2026. What the machines cite there is not what we would have guessed — and one thing they cite most was teaching a model the protocol itself had already replaced. Both below.

    Watch the 60-second version: Why do three pages hold half of this site’s AI citations? — the same receipts in 59 seconds, chapters matched to the sections below.

    Three questions hold half the site

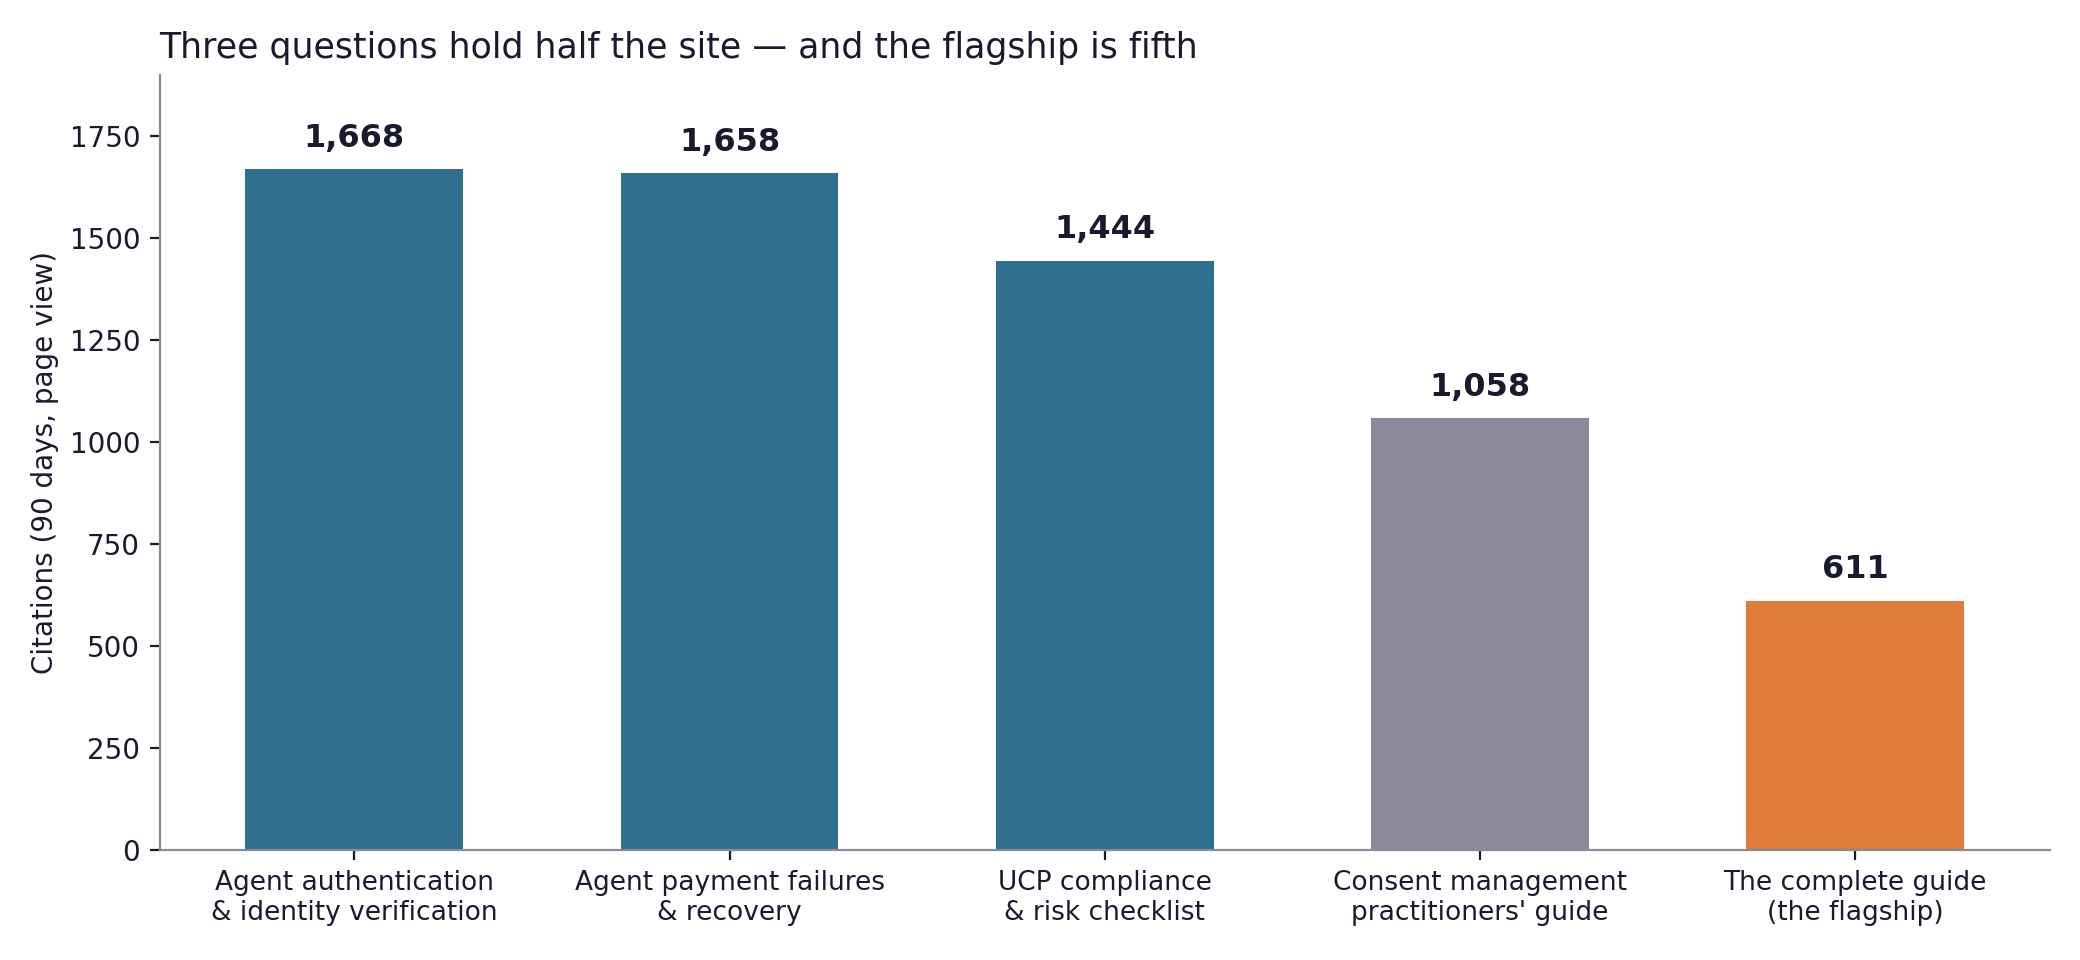
    The page view of the export lists 117 cited pages holding 9,628 citations between them. Half of that total sits on three pages. Our agent authentication and identity verification guide leads the site at 1,668 citations (17.3%). The agent payment failures and recovery guide is ten citations behind it at 1,658 (17.2%). The UCP compliance and risk checklist holds third at 1,444 (15.0%). Together: 4,770 citations, 49.5% of everything the site earned. The top ten pages hold 7,748 — 80.5%. The other 107 pages share the remaining fifth.

    The five most-cited pages on theuniversalcommerceprotocol.com over ninety days: agent authentication and identity verification 1,668; agent payment failures and recovery 1,658; the UCP compliance and risk checklist 1,444; the consent management guide 1,058; and the complete guide — the flagship — fifth at 611.
    Three pages, half the site. Source: Bing Webmaster Tools AI Performance, page view.

    Read the three pillars as questions and they are the three questions every merchant actually asks about agent commerce: how do I know this agent is who it claims to be, what happens when its payment fails, and what do the rules require of me? Identity, failure, compliance. Not how the protocol works in the abstract — what breaks, who’s responsible, and what’s allowed. On the query side, the single biggest question in the window says the same thing in the searcher’s own words: “agentic commerce frameworks payment exceptions handling” — 1,334 citations, at a 44.11% share of that query’s citation pool. The machines are not citing our explainers. They are citing our answers to things going wrong.

    The front door is fifth

    The page we built as the site’s front door — the complete guide to the Universal Commerce Protocol — holds 611 citations, 6.3% of the page view, good for fifth place. Each of the three pillars out-cites it roughly two and a half times over. The consent-management guide sits between them and it at 1,058.

    We do not read that as the guide failing. A complete guide is what a person reads when they arrive already curious. A citation is what a machine reaches for when it needs one fact to finish an answer — and the facts it needs are specific: an authentication model, a failure procedure, a checklist item. The front door is for arriving. The pillars are for answering. This site was named for the protocol and built around the guide; the citations went to the troubleshooting shelf anyway.

    Three views, three totals — and the widest gap in the fleet

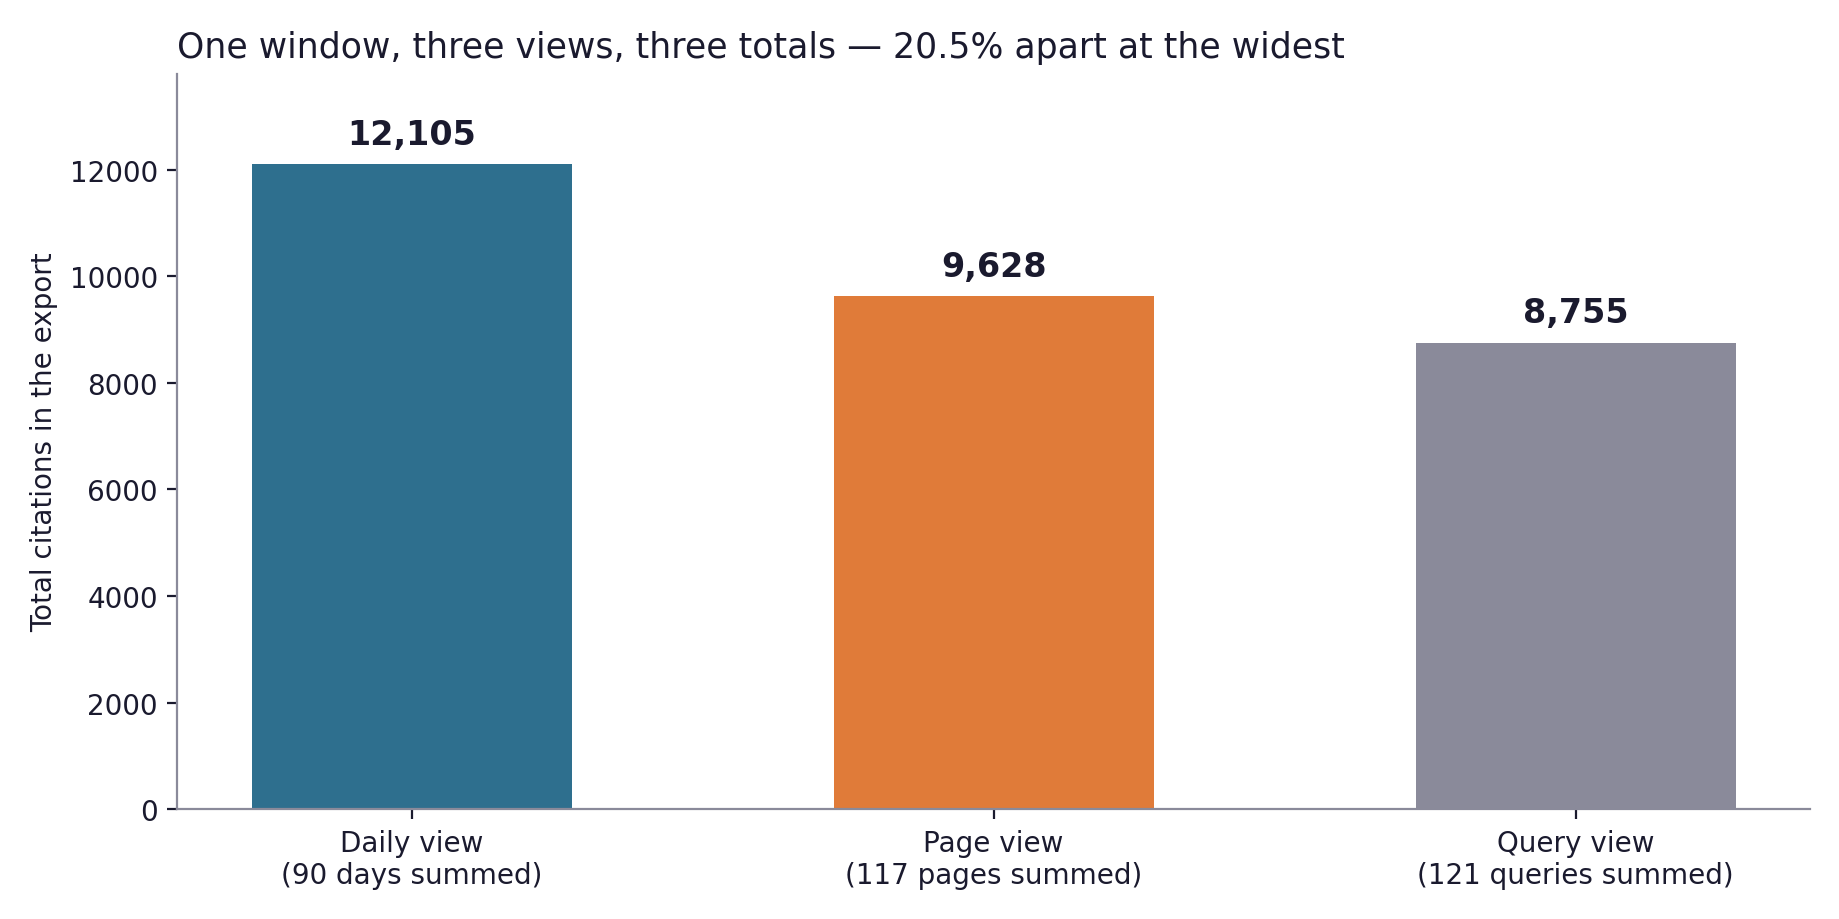
    Every receipt in this series carries the same disclosure, and this one carries it largest. The export’s three views do not agree with each other. The daily view sums to 12,105 citations over the ninety days. The page view sums to 9,628. The query view sums to 8,755 across 121 queries. Three views of the same window, three different totals — and the widest gap, daily against page, is 2,477 citations, 20.5%.

    The three views of the same ninety-day window for theuniversalcommerceprotocol.com give three totals: the daily view sums to 12,105 citations, the page view to 9,628, and the query view to 8,755 — a 20.5 percent gap between the widest two.
    Same window, same pull, three totals. Source: Bing Webmaster Tools AI Performance.

    For scale: the same disagreement on our other sites ran 2.6% (this site, No. 3), 5.7% (Risk Coverage Hub, No. 4), 4.8% (Continuity, No. 5) and about 0.9% (Restoration Intel, No. 6). UCP’s 20.5% is four times the next widest. We do not know why this site’s views diverge so much further than the others’ — the export does not say, and we will not invent a mechanism. What we can do is refuse to blend them: every page share in this piece is a share of the page view’s 9,628; every daily figure is from the daily view’s 12,105; the query numbers are the query view’s own. If you only remember one number from this receipt, remember that the report disagrees with itself by a fifth, and plan your confidence accordingly.

    The shape: a sag, then a climb back past the start

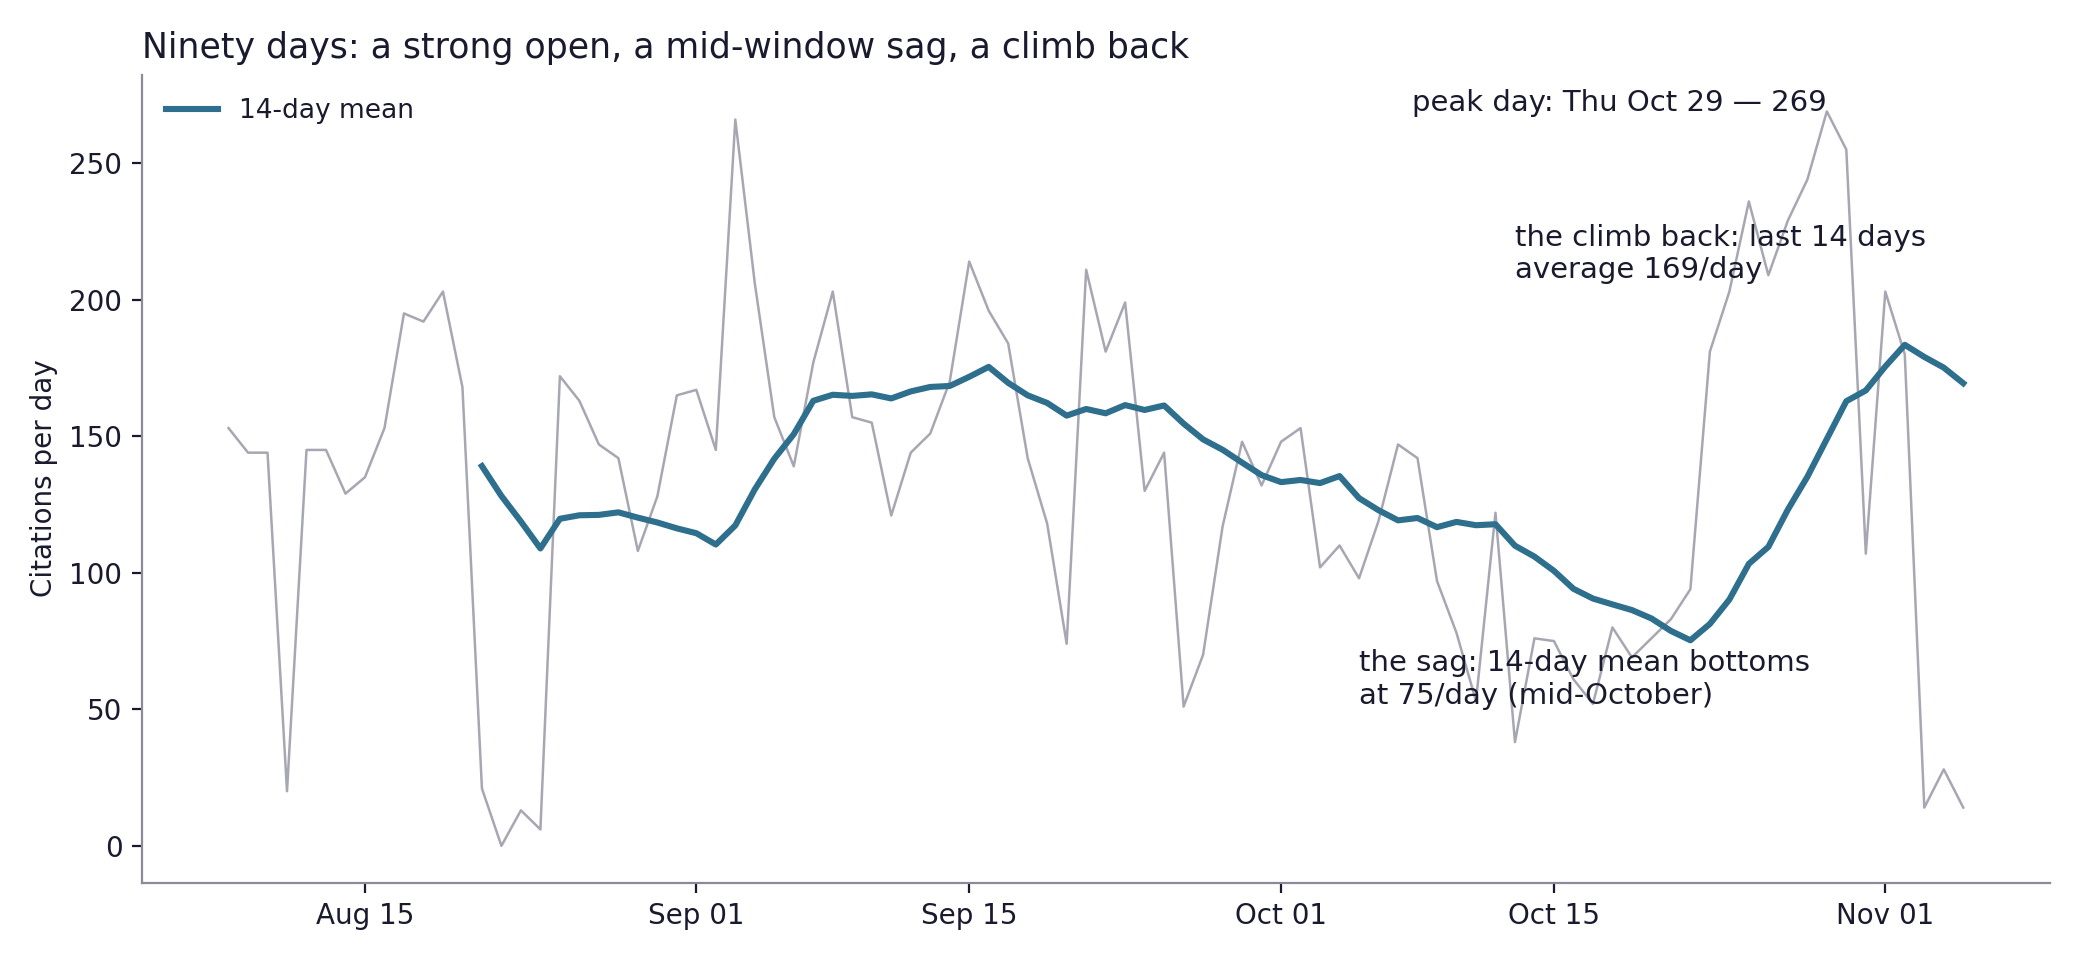
    The daily view does not run flat. The first forty-five days average 144 a day; the second forty-five average 125 — a decline, if you stop reading there. Keep reading and the line turns: the first fourteen days average 139 a day, the last fourteen average 169. The smoothed line tells it cleanest — the fourteen-day average sinks to a floor of 75 a day in mid-October, then climbs for three straight weeks to the window’s peak day, Thursday, October 29, at 269 citations, with 255 the day after. A U, not a slide: strong open, a sag through September into mid-October, and a climb back that ends higher than it started.

    Ninety days of daily AI citations for theuniversalcommerceprotocol.com: a spiky daily line with a fourteen-day average that sinks to 75 a day in mid-October, then climbs to the window's peak day — Thursday, October 29, at 269 citations — before the count cuts off at the window's edge on November 3 to 5.
    The U in ninety days. The last three days are a window edge, not a trend — see below. Source: Bing Webmaster Tools AI Performance, daily view.

    Two cautions belong on this chart, and we put them on the chart. The daily line is spiky at a level the other sites’ lines are not — it touches zero on Saturday, August 22, with zero cited pages, and several other days land under 25 while their neighbors run ten times higher. And the final three days of the window (14, 28, 14) drop off a cliff that is almost certainly the export’s edge, not the site’s collapse — the fourteen-day average was still climbing when the data ran out. On a small site’s report, single days are close to noise; the averages are the claim.

    The second act: the authentication shelf taught a replaced model

    Here is what we did about all this — because the first measurement arrived in the middle of a full refresh of this site, and the two collided in an uncomfortable place. Between October 27 and 31, Google rewrote its UCP documentation: the UCP-Agent request header — the identifier a page of ours taught merchants to trust — was demoted to routing and analytics only, spoofable by anyone, never authentication. The settled model is cryptographic: RFC 9421 request signatures (ES256) verified against the keys in the protocol profile, with mTLS at the transport layer. Spec version 2026-08-25; Canada live for shoppers since November 4.

    Our AI agent verification guide — a cited page on the authentication shelf — taught the old model in so many words: the agent’s identifier “travels in the UCP-Agent request header alongside a request-signature.” That sentence is the superseded model, stated as instructions. On November 8, in Wave 4 of the refresh, that page was republished teaching the RFC 9421 model instead, along with the endpoint shelf (the discovery-endpoint guides corrected to the same authentication model) and the flagship — the complete guide itself, republished the same day with its capability model corrected to spec version 2026-08-25 and the live US and Canada checkout status added. Fourteen pages in the wave. The measurement said the authentication shelf is what the machines cite; the documentation said the shelf was teaching last month’s answer; the refresh fixed the teaching.

    One part of that story we will not tidy up: the number-one page itself has not been fixed yet. The authentication leader at 1,668 citations still carries its pre-correction text — it was not one of Wave 4’s fourteen pages, and its own audit has not run. Its shelf got corrected around it. It is named, queued, and owed — and this receipt records it as open rather than pretending the leader and the lesson are the same page. They are one shelf apart.

    What we can’t claim

    • No baseline. This is the site’s first AI Performance pull, ever. Every shape in this piece — the U, the sag, the climb — is one window with nothing before it. A second pull may redraw all of it.
    • The views disagree by a fifth, and we don’t know why. Daily 12,105, page 9,628, query 8,755. We report each figure from its own view and never blend them, but a report that argues with itself this loudly caps how hard any single number can be leaned on.
    • No cause for the sag or the climb. Not Google’s October documentation rewrite — tempting as that timing is, with the peak landing October 29 — not crawl cycles, not the refresh (the refresh published November 8, after the window closed). The line moved; the export is silent about who moved it.
    • Single days are nearly noise here. A zero day (August 22), neighbors ten times apart, a cliff at the data’s edge — on a site this size the daily grain is too coarse to carry conclusions. We claim the averages and the shares, not the spikes.
    • The refresh’s effect is unmeasured. Wave 4 published November 8, outside this window entirely. Whether corrected pages hold or grow their citations is a question for the next pull — claiming it now would be grading our own homework before the test.
    • One engine, one window. Microsoft Copilot and partner citations as Bing reports them, ninety days, one small technical site. Another engine’s report could tell a different story about the same pages.

    What we do now

    1. Audit the leader. Post 4105 — the most-cited page on the site — gets its own audit-and-refresh pass, first in the next tranche, alongside the unaudited high-traffic shelf. The shelf around it is corrected; it is the remaining open item from this receipt, and it closes next.
    2. Pull the second measurement. Same window method, same three-view disclosure. The first re-measure after a refresh is the one that says whether teaching the current model changes what the machines cite.
    3. Keep the shares straight. Page shares from the page view, daily shape from the daily view, query figures from the query view — and the 20.5% disagreement printed wherever the totals are quoted. The receipts rule holds: the recount wins, and so does the disclosure.

    9,628 page citations, and half of them sit on three troubleshooting pages — while the shelf those pages stand on was teaching last month’s authentication model until the morning of November 8. The machines told us what they read. Then they told us, indirectly, that some of it was out of date. Both were receipts.

    Download the field-report PDF — the same receipts in a printable report.

    Update history
    November 8, 2026 — Published.

    November 8, 2026 — The video version went live on YouTube the same morning. Article published earlier the same day.

    November 8, 2026 — The fix this piece promised shipped the same day: the protocol’s #1 page (Agent Authentication & Identity Verification in Agentic Commerce, post 4105) was refreshed in UCP Wave 5 and now teaches the settled RFC 9421 model; the unverifiable vendor passages named in its audit are out. Wave 5 refreshed nine pages in total; the two remaining pillars followed in Wave 6 — so the correction it promised is done.

    Method note: All figures are from the Bing Webmaster Tools AI Performance exports for theuniversalcommerceprotocol.com — daily, page and query views — window August 8–November 5, 2026 (90 days), pulled November 8, 2026; this is the site’s first-ever pull. The three views sum to 12,105 (daily), 9,628 (page) and 8,755 (query); the 20.5% gap is the daily-minus-page difference as a share of the daily sum. “Pillars” are single exact pages — the most-cited page in each of the site’s three leading subjects — not keyword groupings. Page shares are shares of the page-view sum; daily means are means of the daily view; a query’s “share” is the export’s own printed figure. The authentication correction is documented in the UCP refresh programme’s Wave 4 record (addendum AUTH-2026-11, November 8, 2026): Google’s rewritten UCP FAQ (changed October 27–31, 2026) makes RFC 9421 ES256 signatures plus mTLS the authentication model, with the UCP-Agent header demoted to routing and analytics. Citation counts are Microsoft Copilot and partner citations as Bing reports them. The field-report PDF is at https://tygartmedia.com/wp-content/uploads/2026/11/half-the-citations-ucp-field-report.pdf. One site, one engine’s report, one first window — and a fifth of it disagrees with itself.

  • The Weekend Trough: The Work Week and the Weekend Never Touch

    The Weekend Trough: The Work Week and the Weekend Never Touch

    Seven receipts so far in this series: 44,583 citations at BC ESG, 109,844 at Healthcare Facility Hub, 813,426 on this site, 50,607 at Risk Coverage Hub, 57,798 at Continuity Hub, 111 at Restoration Intel, and — in No. 7 — 295 citations earned by Claude’s own pasted error messages. The eighth receipt comes back to this site’s big number, the 813,426, and lays it out the one way we had not laid it out yet: by weekday.

    Receipt No. 3 read the window as a plateau — the two halves nearly identical, about 9,000 citations a day. Averages hide rhythm. Lay the same ninety days on a calendar and the site has a heartbeat: a high plateau Monday through Thursday, a sag on Friday, a deep trough across the weekend — and a rebound every single Monday. It also has a confession to make about our own first description of that rhythm, which got its lowest day wrong. Both below.

    Watch the 60-second version: Why do this site’s AI citations keep office hours? — the same receipts in 49 seconds, chapters matched to the sections below.

    The pattern: a work-week with a weekend trough

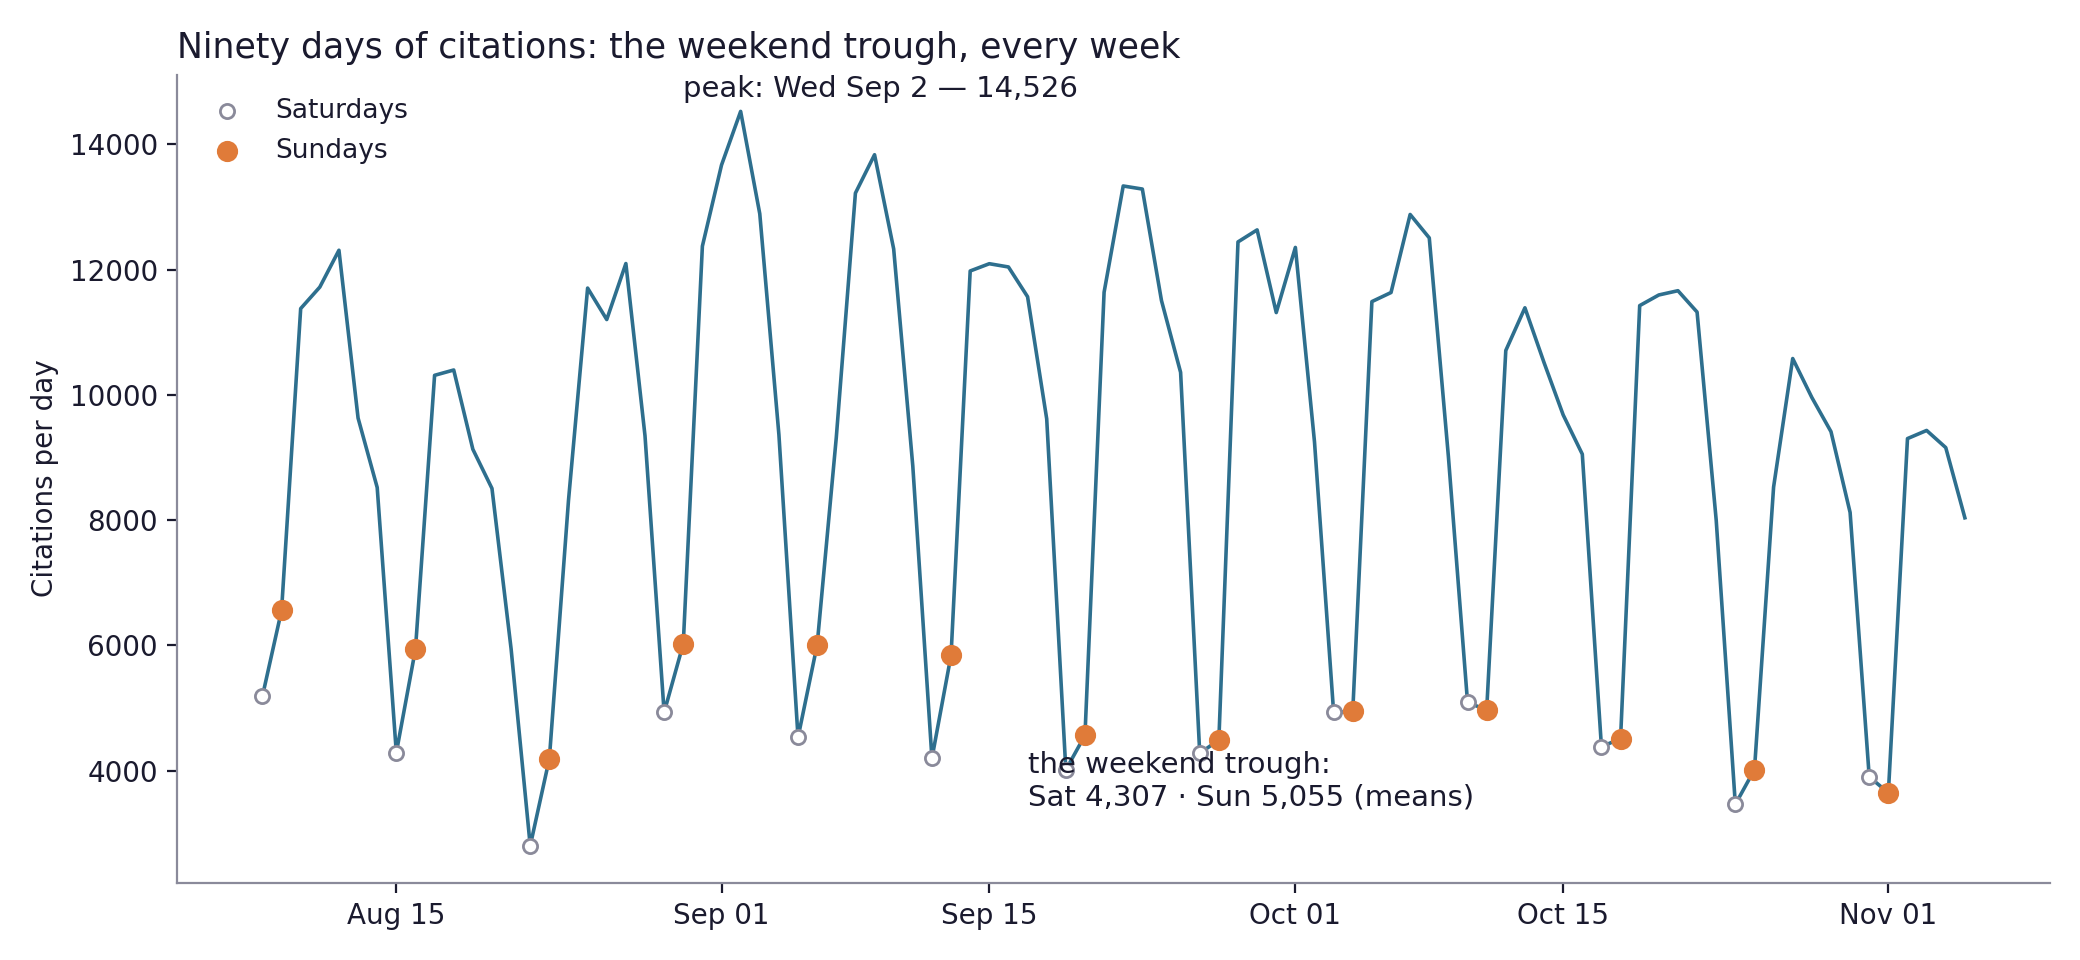
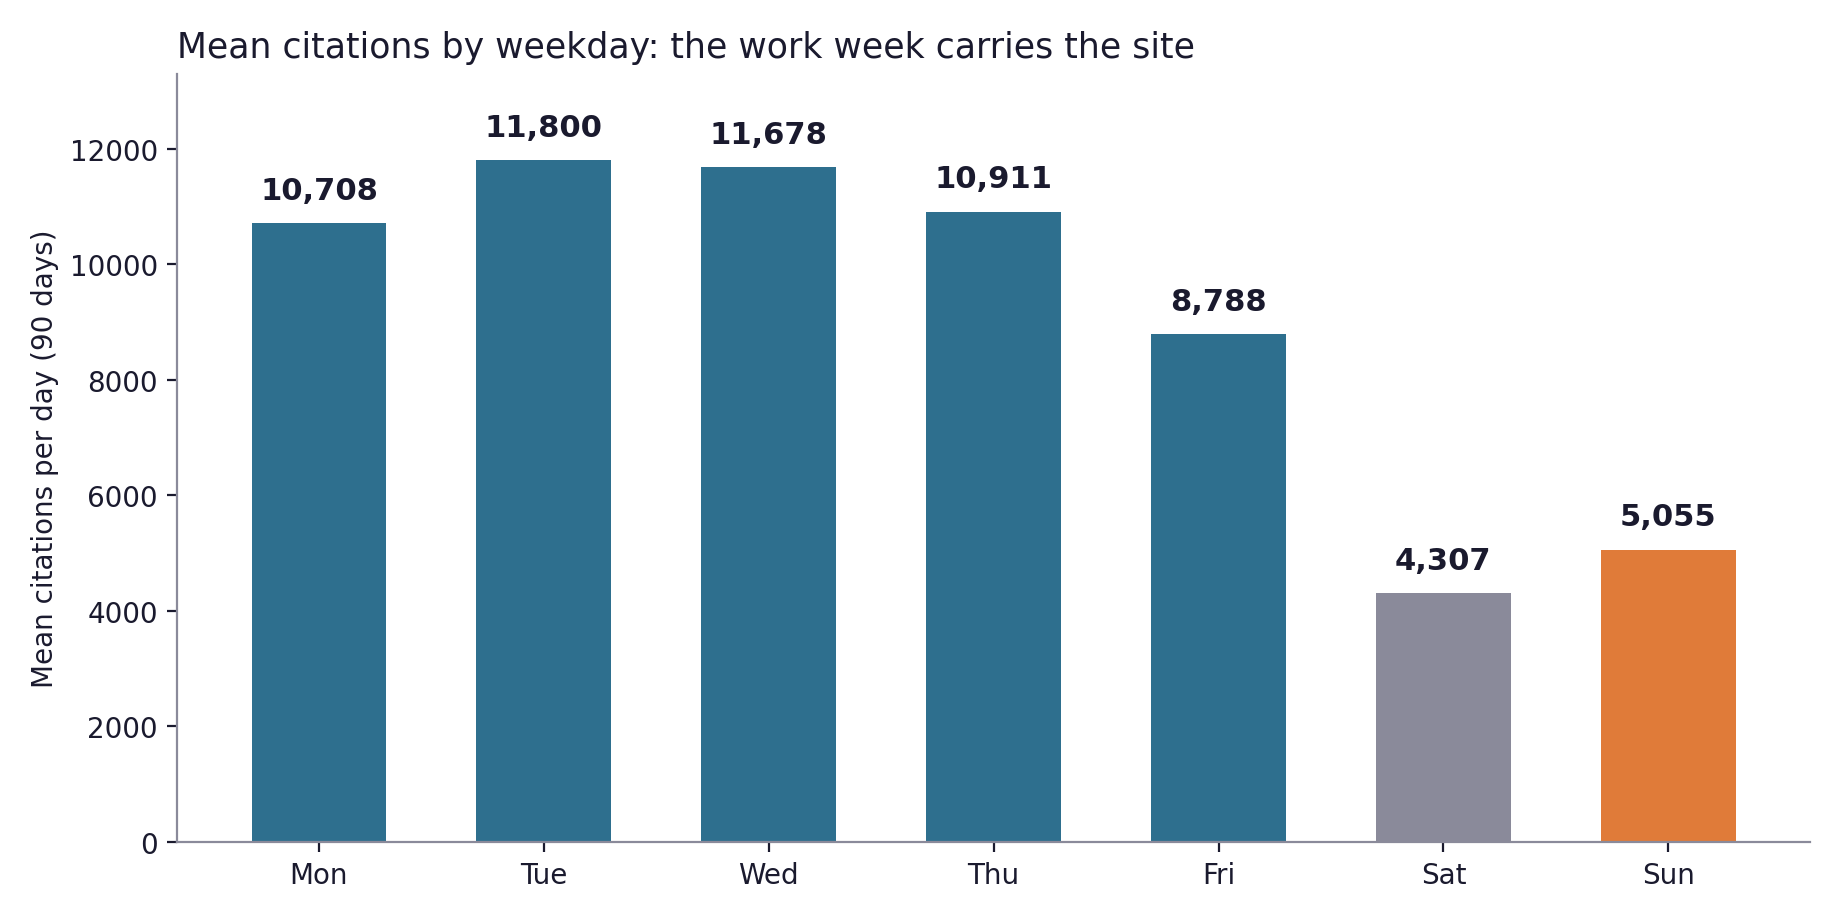
    The ninety days run Saturday, August 8 to Thursday, November 5, 2026. Grouped by weekday, the means are not close. Tuesday averages 11,800 citations, Wednesday 11,678, Thursday 10,911, Monday 10,708, Friday 8,788. Then the floor drops out: Sunday averages 5,055 and Saturday 4,307. Saturday and Sunday together — two-sevenths of the calendar — hold just 15.0% of the window’s citations. Monday through Thursday each hold 17–19% on their own.

    Tygart Media's daily AI citations over ninety days, August 8 to November 5, 2026: a high weekday plateau and a deep trough every weekend, with Sundays marked in orange and Saturdays as open grey circles. The peak day is Wednesday, September 2, at 14,526 citations.
    Ninety days, thirteen weekends, thirteen troughs. Source: Bing Webmaster Tools AI Performance, daily view.

    The cleanest single fact in the table: the weakest Monday of the window — 8,314 citations, on August 24 — still beats every Saturday and every Sunday in it. The strongest Sunday managed 6,559. There is no overlap at all between the work week and the weekend. Whatever the machines are doing, they do it on a work-week rhythm, and this site’s citation line keeps office hours.

    The numbers: the rebound is real, the cliff is Saturday’s

    Here is where we correct ourselves, in the open, the way No. 7 corrected its count. Our morning sweep described this pattern as a Sunday cliff — “every Sunday craters, every Monday roughly doubles it, ten clean doublings in a row.” The pairs it quoted all check out. The shape does not.

    Sunday is not the bottom. In eleven of the thirteen weekends, Sunday is higher than the Saturday before it — Sunday is already the climb back. Across the twelve complete Monday-to-Sunday weeks in the window, Saturday is the week’s lowest day ten times; Sunday is the lowest only twice — October 11 (4,966, under its Saturday’s 5,093) and November 1 (3,646, the window’s lowest Sunday). The cliff, if we are naming one, is Friday-to-Saturday. Sunday is where the recovery starts, and Monday completes it.

    Weekday Days Mean Median Low High Share of window
    Monday 13 10,708 11,378 8,314 12,442 17.1%
    Tuesday 13 11,800 11,705 9,432 13,669 18.9%
    Wednesday 13 11,678 11,663 9,132 14,526 18.7%
    Thursday 13 10,911 11,506 8,037 12,891 17.4%
    Friday 12 8,788 9,034 5,945 10,359 13.0%
    Saturday 13 4,307 4,287 2,800 5,188 6.9%
    Sunday 13 5,055 4,946 3,646 6,559 8.1%
    Mean AI citations by weekday for Tygart Media over ninety days: Tuesday 11,800, Wednesday 11,678, Thursday 10,911, Monday 10,708, Friday 8,788, Sunday 5,055, and Saturday lowest at 4,307.
    The work week carries the site. Source: Bing Webmaster Tools AI Performance, daily view.

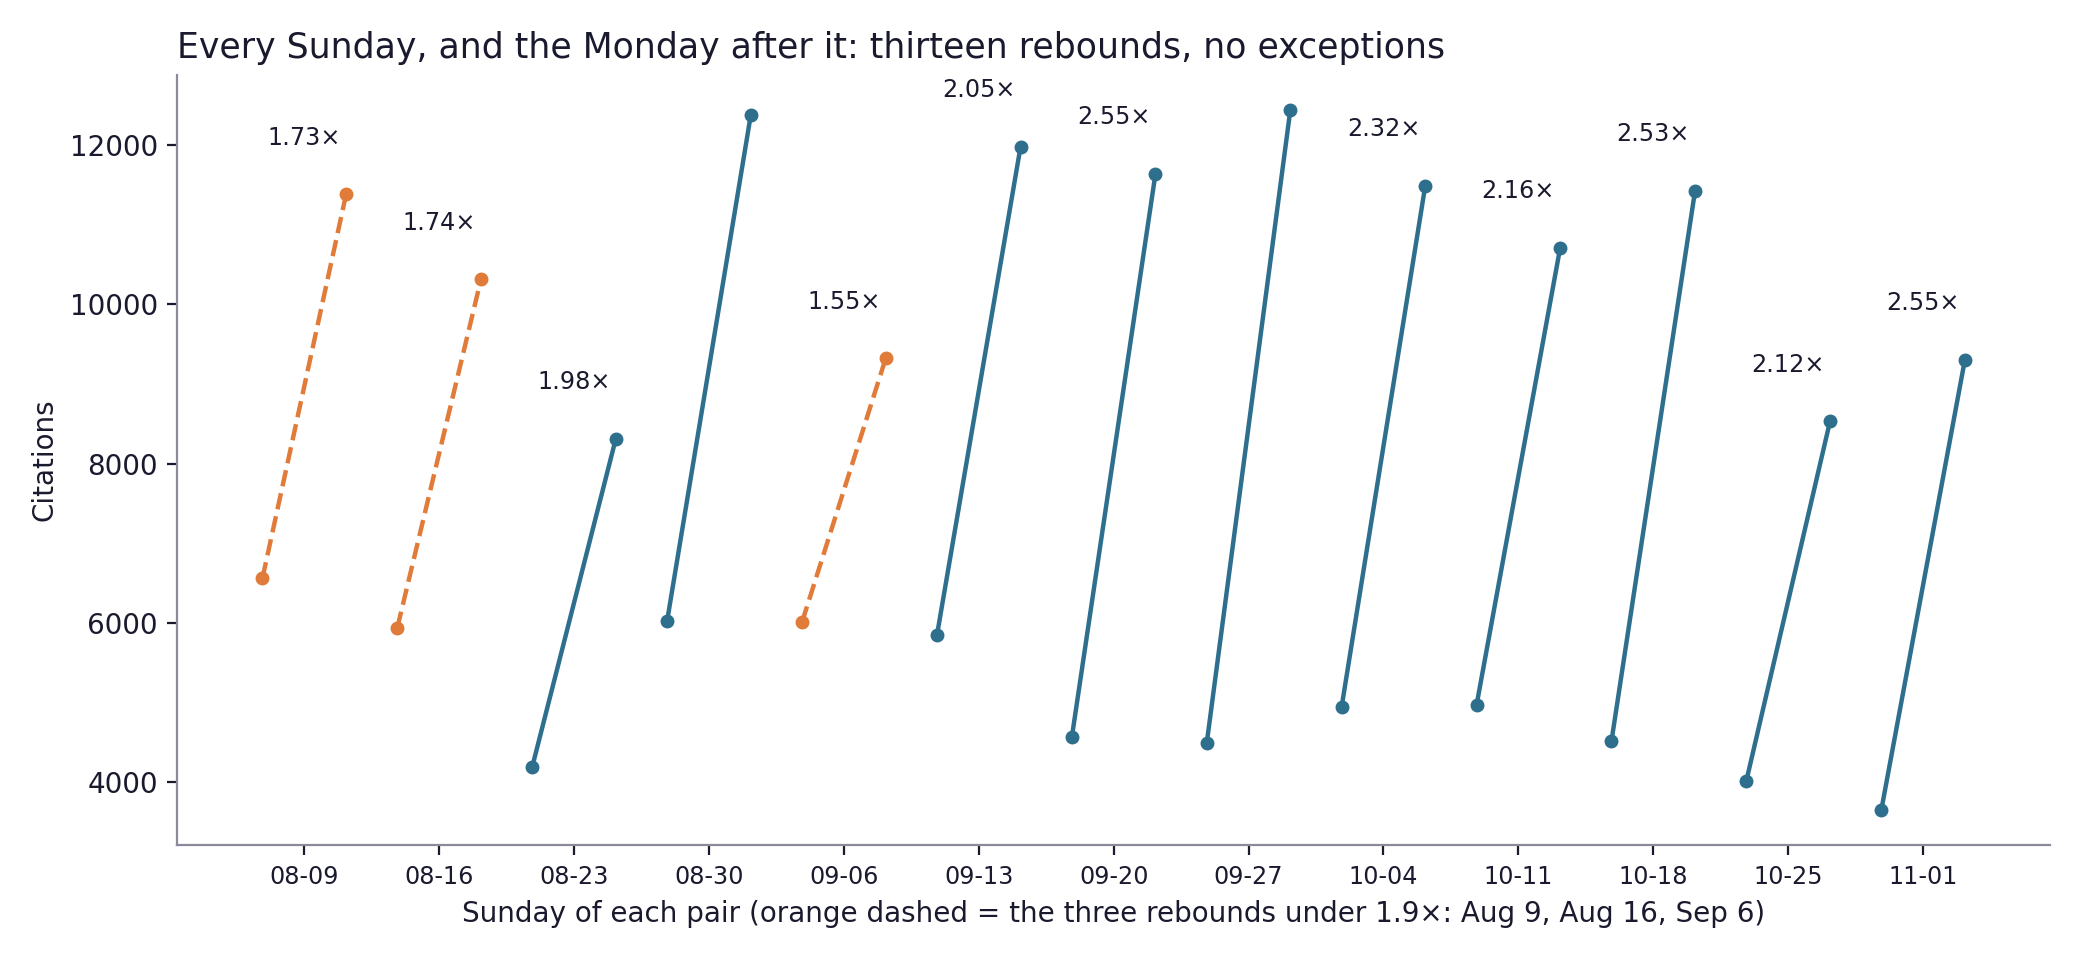
    The Monday rebound, though, is exactly as strong as advertised — it just isn’t ten straight doublings. All thirteen Sundays are followed by a Monday rebound; none fails. The average Monday runs 2.12× the average Sunday (2.30× on medians). Per week, ten of the thirteen rebounds reach 1.9× or better, and nine reach a full 2×. But the three that don’t are not scattered politely at the end — two of them open the window (August 9: 1.74×; August 16: 1.74×) and one sits mid-window (September 6: 1.55×). The longest clean run of near-doublings is seven straight, September 13 through October 25, plus one more on November 1. Our sweep quoted six example pairs, and every one of them was a qualifying week. That is how a true pattern gets a slightly false headline.

    Each of the thirteen Sundays in the window paired with the Monday after it: every pair rebounds, from 1.55 times on September 6 up to 2.77 times on September 27; the three rebounds under 1.9 times — August 9, August 16 and September 6 — are dashed in orange.
    Thirteen rebounds, none missing. Three of them aren’t doublings, and the chart doesn’t hide them. Source: Bing Webmaster Tools AI Performance, daily view.

    One more quiet fact under the rhythm: the load is concentrating. The daily report counts how many distinct pages were cited each day. On the window’s first day that was 173 pages; on its last, 135 — and the means agree with the endpoints: the first fourteen days averaged 184.7 cited pages a day, the last fourteen averaged 134.1, a 27% narrowing while the volume held. Fewer pages, carrying the same 9,000-a-day load. Breadth rests on weekends too — Saturdays average 132 cited pages against Tuesdays’ 181.

    The exceptions, named

    • August 9 — the mildest Sunday. The first Sunday in the window is its highest Sunday, 6,559, and its Monday rebound is the joint-weakest at 1.74×. The pattern starts at its gentlest and sharpens later.
    • September 6 — the weakest rebound. Sunday 6,009 to Monday 9,319 is 1.55× — the one weekend where neither the dip nor the rebound did much. It breaks any “ten straight doublings” story on its own.
    • October 11 and November 1 — the true Sunday bottoms. The only two Sundays that are their week’s minimum and below their Saturdays. November 1 is the window’s lowest Sunday (3,646) — and its Monday rebounds the hardest of the late window, 2.55× to 9,302.
    • Saturday, August 22 — the quietest day of the window. 2,800 citations across 90 cited pages. The deepest point of the deepest trough belongs to a Saturday, like most of them.
    • Monday never tops its own week. In zero of the twelve complete weeks is Monday the highest day — a Tuesday or Wednesday beats it every time. The window’s peak is a Wednesday: September 2, 14,526 citations across 232 cited pages, also the widest breadth day. Monday is the rebound, not the peak.
    • September 27 — the strongest rebound. Sunday 4,490 to Monday 12,442: 2.77×, the sharpest single step in the window.

    What we can’t claim

    • No cause. None. Not readers working weekdays, not crawl scheduling, not the engine batching its reporting by day. The data shows a rhythm; it is silent about the drummer.
    • The pattern may live in the measuring, not the world. Receipt No. 6 made this point about a fossil record, and it applies here with interest: a weekly shape in a report can be a weekly shape in reality, or a weekly shape in how the report gets built. From inside the report, we cannot separate those.
    • Our publishing cadence is untested against this. We have not lined our own posting calendar up against these ninety days, so we claim nothing either way — not innocence, not guilt. Correlation with a publishing rhythm, if one were found, would still not be a mechanism.
    • One engine, one window. These are Microsoft Copilot and partner citations as Bing reports them, ninety days on one site. Another engine’s report might keep different hours.
    • Our first headline was wrong in the open, and stays corrected. “Sunday cliff, ten straight doublings” was our sweep’s summary. The recount — printed above, with the table — is: a weekend trough whose bottom is usually Saturday, a Sunday that usually rises, and a Monday rebound that happens thirteen times out of thirteen at 2.12× on average. The title keeps the cliff; the article keeps the correction. The receipts rule is the recount wins.

    What we do now

    1. Nothing to fix. There is no Sunday problem to solve, because there is no Sunday problem — there is a rhythm. We do not publish to a citation clock, and we will not start.
    2. Read the week, not the day. From here on, a weekend dip in this report is not a collapse and a Monday spike is not a triumph. Any future read of this site’s citations gets compared weekday-to-weekday, or not at all.
    3. Re-measure on the next sweep. Same window method, same weekday arithmetic, same correction rule if the rhythm moves. If the trough ever fills in — or moves to a different day — that will be a receipt too.

    813,426 citations, and they keep office hours: 85% of them land Monday through Friday, the weakest Monday beats the strongest Sunday, and the line has rested every weekend for thirteen straight weeks. The plateau had a pulse. The receipts are the receipts.

    Download the field-report PDF — the same receipts in a printable report.

    Update history
    November 8, 2026 — Published.

    November 8, 2026 — The video version went live on YouTube the same morning. Article published earlier the same day.

    Method note: All figures are from the Bing Webmaster Tools AI Performance export for tygartmedia.com, daily view, window August 8–November 5, 2026 (90 days), pulled November 8, 2026. The daily view sums to 813,426 citations; the page view from the same pull sums to 792,317 (2.6% apart, as reported in Receipt No. 3) — each figure above is from the daily view unless it says otherwise. Weekdays are computed from the calendar dates (August 8, 2026 was a Saturday). A “week” is Monday through Sunday; week-minimum claims cover the twelve complete weeks inside the window. The Monday-to-Sunday ratio of 2.12× is the ratio of the two weekday means across all thirteen Mondays and thirteen Sundays. “Cited pages” is the daily report’s own column: distinct pages cited that day. Citation counts are Microsoft Copilot and partner citations as Bing reports them. The field-report PDF is at https://tygartmedia.com/wp-content/uploads/2026/11/the-weekend-trough-tygart-media-field-report.pdf. One site, one engine’s report, one window — with a weekly pulse.

  • The Machines Ask Claude’s Own Error Messages

    The Machines Ask Claude’s Own Error Messages

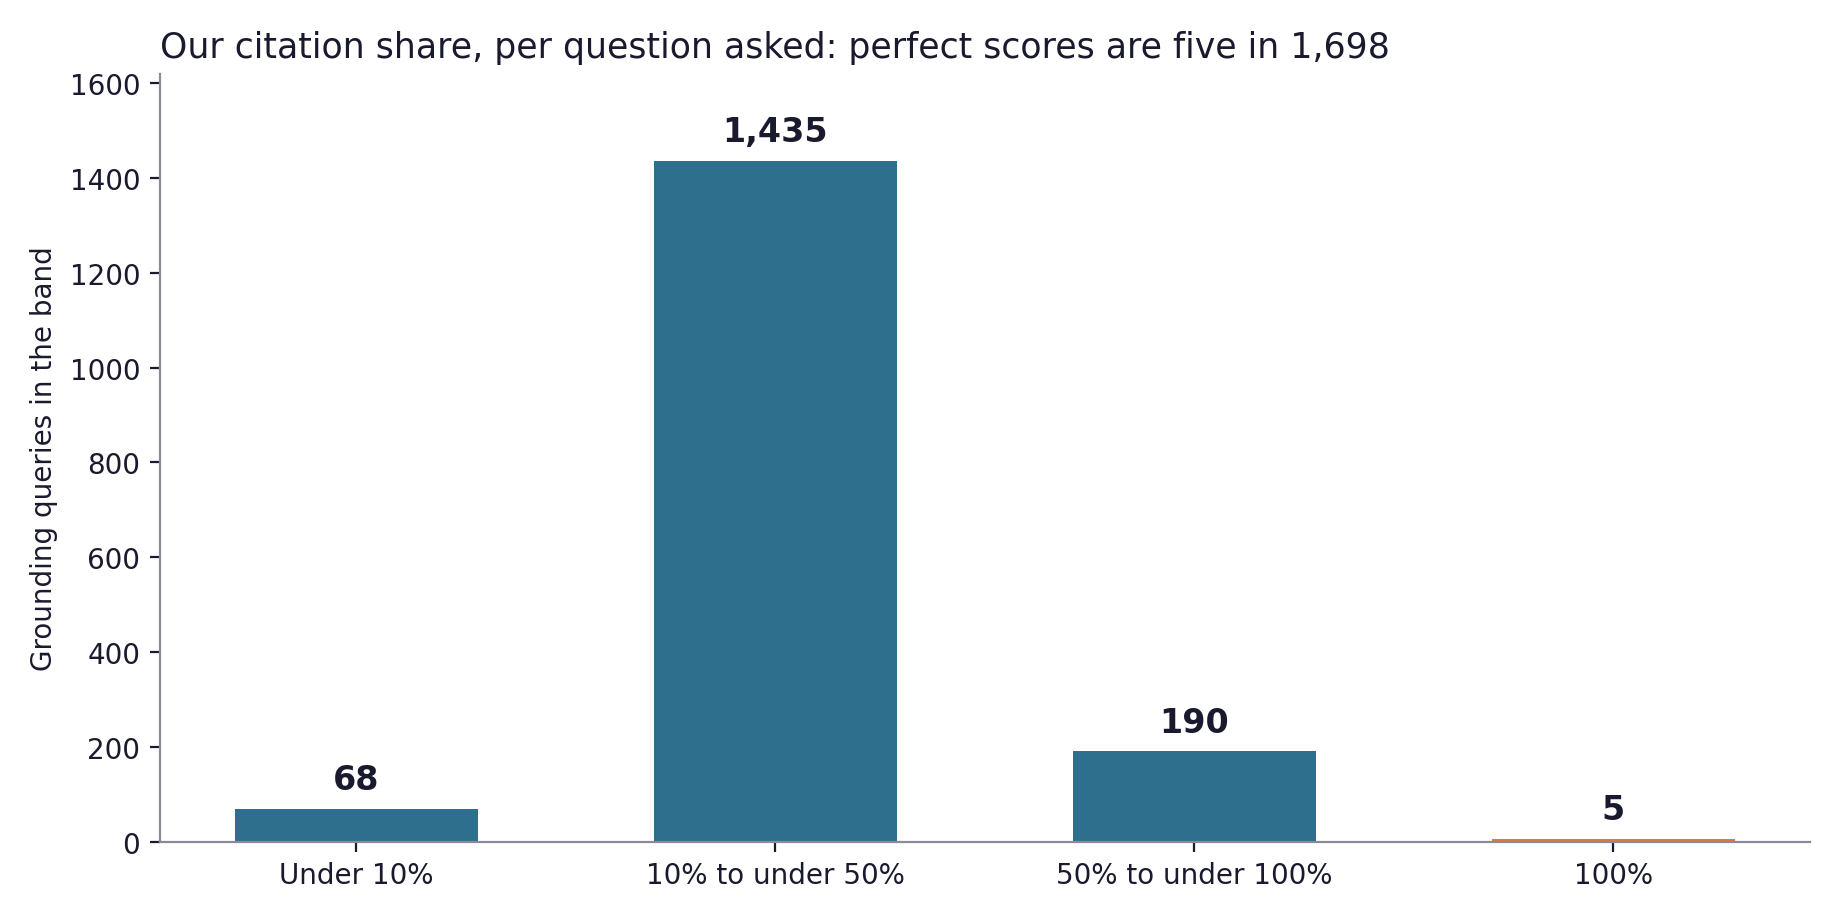
    Six receipts so far in this series: 44,583 citations at BC ESG, 109,844 at Healthcare Facility Hub, 813,426 on this site, 50,607 at Risk Coverage Hub, 57,798 at Continuity Hub, and 111 — every one of them inside seventeen days — at Restoration Intel. The seventh receipt is not a site at all. It is this site’s own question list, and it is the strangest shelf in it: buried in the 1,698 questions the machines consulted us on, some of the “questions” are not questions. They are Claude’s own error messages, pasted whole.

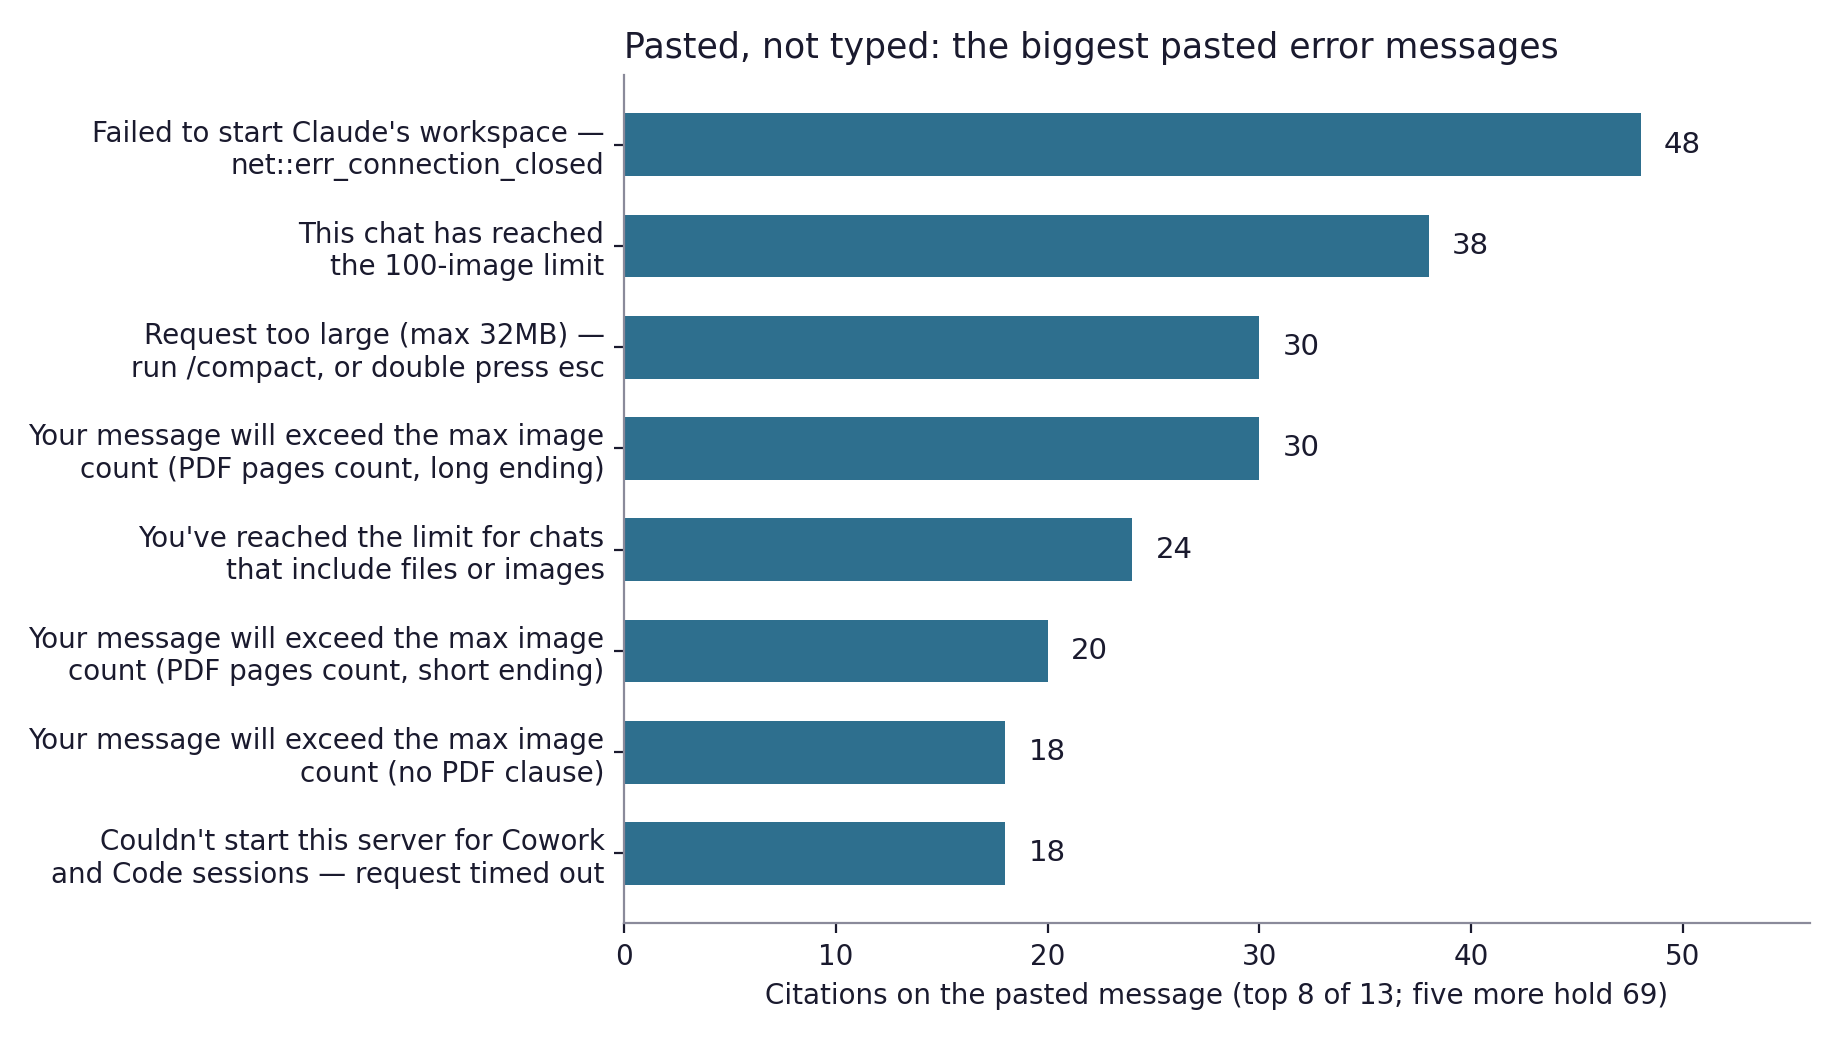
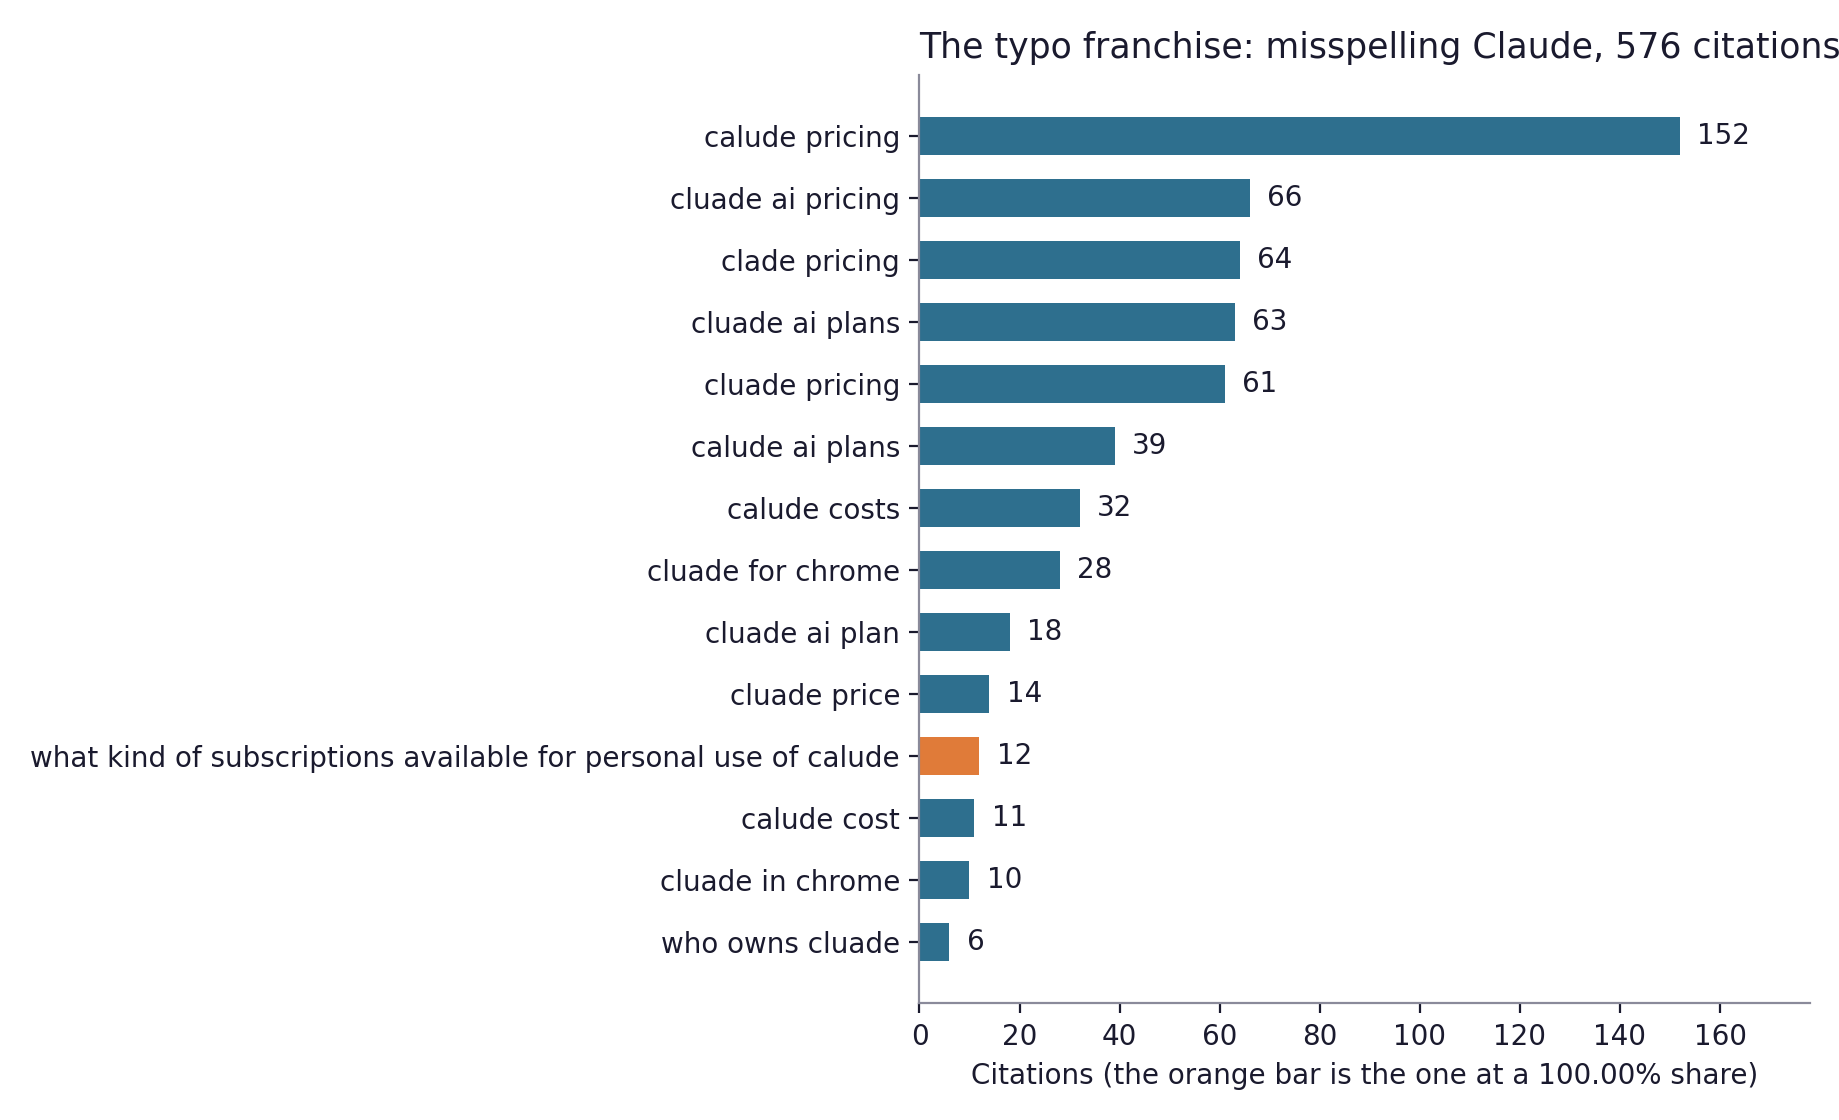
    Here is the shape of it. Somebody is working in Claude and hits a wall — a chat that will not take another image, a workspace that will not start, a request that is too large. They copy the message off the screen, paste it into an AI, and the AI goes looking for help. It finds our pages, and it cites them. Thirteen pasted messages, 295 citations. Around them sits a small franchise of misspellings worth 576 more, and a set of perfect scores so rare they round to zero. This is the smallest receipt in the series, and the funniest. Weird beats big.

    Watch the 60-second version: Why do machines ask about Claude’s own error messages? — the same receipts in 52 seconds, chapters matched to the sections below.

    The errors: pasted, not typed

    The query view for this site holds 1,698 grounding queries for August 8 to November 5, 2026. Thirteen of them are verbatim copies of messages Claude’s interface shows its users — error dialogs and limit notices, word for word, punctuation and all. Counted together, they earned 295 citations.

    Our counting rule, printed so anyone can recount us: a query counts only if its whole text is a pasted interface message, in the system’s own voice. A person typing “claude cowork not working” (50 citations) is describing a problem in their own words — that does not count. Neither does the one pasted banner that is a promotion rather than an error, “your limits are temporarily boosted” (38). Errors and limit blocks only. The thirteen:

    • “failed to start claude’s workspace request error: net::err_connection_closed restarting claude or your computer sometimes resolves this. if it persists, you can reinstall the workspace.” — 48 citations; our share 14.72%.
    • “this chat has reached the 100-image limit (including pdf pages). start a new chat to add more.” — 38; our share 19.29%.
    • “request too large (max 32mb). accumulated images and attachments in the conversation pushed the request over the limit. run /compact, or double press esc to go back and remove attachments.” — 30; our share 27.78%.
    • “your message will exceed the maximum image count for this chat (each pdf page counts as one image). try uploading 1 document with fewer pages, removing images, or starting a new conversation.” — 30; our share 29.70%.
    • “you’ve reached the limit for chats that include files or images. start a new text-only chat or upgrade to continue now.” — 24; our share 50.00% — half of every answer to that pasted message cited us.
    • “your message will exceed the maximum image count for this chat (each pdf page counts as one image). try removing images or starting a new conversation.” — 20; our share 21.74%.
    • “your message will exceed the maximum image count for this chat. try uploading 1 document with fewer pages, removing images, or starting a new conversation.” — 18; our share 27.27%.
    • “couldn’t start this server for cowork and code sessions (they run their own copy of it), so they can’t use its tools: request timed out” — 18; our share 34.62%.
    • “your organization’s model list hasn’t loaded yet. claude reloads it automatically once the connection or sign-in recovers; if it still won’t load, contact your it administrator.” — 15; our share 22.73%.
    • “failed to start claude’s workspace” — 15; our share 6.61%.
    • “claude’s workspace service isn’t running” — 15; our share 20.00%.
    • “api error: claude’s response exceeded the 128000 output token maximum. to configure this behavior, set the claude_code_max_output_tokens environment variable.” — 12; our share 22.22%.
    • “failed to start claude’s workspace not enough disk space to set up the workspace. free up space and try again. restarting claude or your computer sometimes resolves this. if it persists, you can reinstall the workspace.” — 12; our share 26.09%.
    The eight biggest pasted Claude error messages in Tygart Media's grounding-query report: the failed workspace start at 48 citations, the 100-image limit at 38, the too-large request and the maximum-image-count message at 30 each, and four more between 18 and 24.
    Pasted, not typed — the top eight of thirteen. Source: Bing Webmaster Tools AI Performance, query view.

    Two patterns inside the thirteen. The message “your message will exceed the maximum image count for this chat” appears three times with three different endings — the same wall, screenshotted at three slightly different moments, worth 68 citations between them. And “failed to start claude’s workspace” opens three of the thirteen, worth 75. People do not paraphrase an error message. They hand the machine the exact words the last machine showed them, and the machine comes to us.

    The typos: a small franchise

    Fourteen queries in the report misspell the product’s name — calude, cluade, clade — and between them they earned 576 citations, nearly double the entire error shelf:

    • “calude pricing” — 152 citations
    • “cluade ai pricing” — 66 (our share 69.47%)
    • “clade pricing” — 64
    • “cluade ai plans” — 63 (50.00%)
    • “cluade pricing” — 61
    • “calude ai plans” — 39 (68.42%)
    • “calude costs” — 32
    • “cluade for chrome” — 28
    • “cluade ai plan” — 18
    • “cluade price” — 14
    • “what kind of subscriptions available for personal use of calude” — 12, at a 100.00% share
    • “calude cost” — 11
    • “cluade in chrome” — 10
    • “who owns cluade” — 6
    All fourteen misspelled-Claude queries and their citations: calude pricing at 152, cluade ai pricing at 66, clade pricing at 64, down to who owns cluade at 6; the subscriptions question about 'calude' highlighted at a 100 percent share.
    Fourteen misspellings, 576 citations. Source: Bing Webmaster Tools AI Performance, query view.

    Somebody, six citations’ worth, asked who owns Cluade. We do not. But the best row in the table is the personal-use one: asked in exactly those misspelled words, every single time, the machines cited us. A perfect score — which turns out to be the rarest thing in the whole report.

    The perfect scores: five in 1,698

    Bing reports a citation share for every query — the fraction of answers that cited us. Spread across all 1,698 questions, the shape is ordinary: 68 questions sit under a 10% share, 1,435 sit between 10% and 50%, 190 sit between 50% and 100%. And at exactly 100.00% — every answer, every time — there are five:

    • “claude standard plan” — 345 citations
    • “how much for claude ai” — 33
    • “claude entreprise prix” — 30 (French: the enterprise price)
    • “what kind of subscriptions available for personal use of calude” — 12 (the typo, again)
    • “anthropic create api key” — 4
    Distribution of Tygart Media's citation share across all 1,698 grounding queries: 68 under 10 percent, 1,435 between 10 and 50 percent, 190 between 50 and 100 percent, and 5 at exactly 100 percent.
    Perfection is five questions wide. Source: Bing Webmaster Tools AI Performance, query view.

    Two side dishes from the same shelf. The longest query in the report, at 236 characters, is a multiple-choice exam question — it opens “what can copilot do if you join a meeting late?” and then pastes its own four answer options; somewhere a quiz is being answered with our pages as the source (10 citations, 26.32%). And the report cites our homework: the article describing this site’s citation experiment holds 20 citations of its own. The thesis about the report, cited in the report.

    What we can’t claim

    • We don’t know why our pages answer the errors. Nothing in the report says which page answered which pasted message, or why the machines reached for us. The pattern is visible; a mechanism would be storytelling.
    • The query view is a sample, not a census. Its citations sum to 371,847 against the daily view’s 813,426 — Bing showed us a window onto the questions, not all of them. Every number here is “of the queries Bing showed us.”
    • The text is what people pasted — errors included. We quote these queries as data, exactly as they sit in the report, misspellings and truncated sentences and all. Correcting them would be editing the evidence.
    • Our own first count was wrong, so we fixed it in the open. Our sweep’s first tally read 12 messages and 245 citations. When we pinned the counting rule down in writing — the rule printed in the first section above — the count moved to 13 and 295. The rule is printed precisely so the recount is checkable.
    • One engine, one window, one site. These are Microsoft Copilot and partner citations as Bing reports them, for ninety days. Another engine’s report would show a different shelf.

    What we do now

    1. We don’t write for typos. There will be no “calude pricing” page. The franchise is a fact about how people type, not a strategy; the pages earn the misspelled questions by answering the spelled ones.
    2. Keep the help pages accurate. The machines route broken sessions to us — a person mid-error, request too large, workspace dead. The least the page they land on can do is be right.
    3. Re-measure on the next sweep. The error shelf and the typo franchise get counted again with the rest of the fleet, same windows, same instrument, same counting rule.

    295 citations for error messages nobody typed. 576 for a name spelled wrong. Five perfect scores in 1,698 tries. The receipts are the receipts — including the funny ones.

    Download the field-report PDF — the same receipts in a printable report.

    Update history
    November 8, 2026 — Published.

    November 8, 2026 — The video version went live on YouTube the same morning. Article published earlier the same day.

    Method note: All figures are from Bing Webmaster Tools AI Performance exports for tygartmedia.com, window August 8–November 5, 2026 (90 days), pulled November 8, 2026. The daily view sums to 813,426 citations, the page view to 792,317 (2.6% apart), and the query view — a sample of 1,698 grounding queries — to 371,847; each figure above names its view. Citation counts are Microsoft Copilot and partner citations as Bing reports them; citation shares are Bing’s per-query figures. Query text is quoted verbatim from the report, including the errors in it. The error-message count uses the rule printed in the article: whole pasted interface messages only — 13 queries, 295 citations. The field-report PDF is at https://tygartmedia.com/wp-content/uploads/2026/11/the-machines-ask-claudes-errors-tygart-media-field-report.pdf. This is one site, one engine’s report, one window — and its strangest shelf.