Tag: ChatGPT

  • ChatGPT Is Five Rooms, Not One Channel

    ChatGPT Is Five Rooms, Not One Channel

    There’s a post going around that says: if you can rank in ChatGPT, you’re way ahead of the game, your leads from ChatGPT will increase, invest now.

    Here’s the problem with that sentence. There is no “ChatGPT” the way there’s a phone book. There are rooms. And the person in each room is a different person, sitting in a different chair, at a different time of day, asking a different kind of question.

    A free-plan mobile ChatGPT user on the toilet is not the same human as a Claude user inside their desktop looking up technical documentation at 10 in the morning. Treating them as one audience because the logos are similar is how businesses end up advertising B2B services on a consumer feed — the same mistake, wearing a new jacket.

    The five rooms

    Room one: free ChatGPT on a phone. Consumer questions. Evenings, couches, commutes. What’s a good car stereo, write my cover letter, explain this homework. Enormous volume, almost no B2B buying intent.

    Room two: paid ChatGPT at a desk. Prosumers and knowledge workers who chose it as a tool. Better questions, work hours, some buying intent — when the question is about their own workflow.

    Room three: Claude at a desk. Developers, analysts, technical professionals. This is the room that reads documentation for a living. Weekday-shaped, deep, specific.

    Room four: Copilot inside Edge and Office. The corporate room. These people didn’t choose an AI — it arrived inside the tools their employer already runs. Facility managers, compliance staff, operations people, asking work questions in work language, mid-task.

    Room five: Gemini inside Google search. Everyone, for everything, at search scale. The broadest room and the shallowest intent per question.

    Same species of technology. Five different demographics. “Get cited in AI” means nothing until you say which room.

    What the counting says

    I count AI citations for a living — six months of Bing AI Performance data across my own network, 1.6 million citations and change. The rooms are not a theory. They’re in the numbers.

    On Tygart Media, the single most-cited page is a Claude AI pricing explainer — 1,388,909 citations. The audience for this site is technical professionals, and the citation traffic is weekday-shaped: it rises when people are at work and flattens when they aren’t. Room three, behaving like room three.

    On Healthcare Facility Hub — a site for hospital facilities and infection-control people — Microsoft’s AI surfaces cited 188 pages a total of 43,994 times in six months. The top pages are an ICRA matrix (4,067 citations), hospital evacuation planning (2,766), ASHRAE 170 ventilation requirements (2,435), NFPA 101 life safety (1,802). The questions behind them read like this: what has to be in a facility’s emergency preparedness plan about emerging infections; which fire safety feature keeps smoke in one zone. Nobody asks those questions from a couch. Those are room-four questions — asked at a desk, inside a Microsoft environment, by someone whose job depends on the answer being right.

    Two sites. Two rooms. Neither audience is in the room the hype is selling.

    The test that settles it

    Before you pay anyone to get you cited “in ChatGPT,” ask one question: which room is your buyer sitting in when the buying question forms?

    If you’re selling to hospital facilities staff, your room is Copilot at a desk, and the content that wins there is an ICRA matrix, not a viral post. If you’re selling car stereos, room one is genuinely your room, and God bless. The tactic isn’t wrong or right — the fit is.

    Anyone who can’t tell you which room they’re putting you in is selling you the label. The label is the one part that doesn’t matter.


    Will Tygart runs Tygart Media. The citation counts above are from his own six-month Bing AI Performance board, counted nightly. The $97 AI Citation Quick-Scan exists because “which room cites you” is a measurable question: https://tygartmedia.com

  • How AI Search Visibility Is Actually Tracked (and What the Tools Can’t See)

    How AI Search Visibility Is Actually Tracked (and What the Tools Can’t See)

    Here’s how AI search visibility is honestly tracked: you write down the actual questions your customers ask, you ask those same questions in the actual answer engines on a fixed schedule, and you record three things separately — whether the answer names you, whether it cites you, and whether what it says about you is true.

    That’s it. Everything else — dashboards, scores — is packaging around that habit, or a substitute for it. And there’s a problem worth understanding before you buy a substitute: ranking and being cited are not the same event, and a tool that conflates them will mislead you without making a number up.

    Ranking is not being cited

    Start with the structural fact. Search the old way and you get a ranked list of pages. Ask an answer engine — Copilot, ChatGPT, Perplexity, the AI box atop Google — and you get a paragraph, written on the spot, with a handful of sources cited beside it.

    Those two events are only loosely connected. A page can sit at position two in the organic list and never get quoted, while a competitor at position four gets built into the answer. It isn’t a glitch: the engine doesn’t summarize the top result. It breaks your question into smaller sub-questions, looks for material on each, and assembles an answer from what it finds — and studies of cited URLs find just a small minority come from the organic top ten.

    So rank-based tracking measures the list while your customers read the paragraph. That’s the gap where businesses get surprised: “we rank fine, why is the machine recommending somebody else?” The events that matter are being named, cited, and described correctly. For the basic method as a straight answer, see how do you measure AI search visibility. This piece covers the part usually skipped — the limits.

    The only honest method: fixed questions, three separate records

    The method fits on an index card. Build a list of the questions your customers actually ask — not keywords, questions, in their words: “Who fixes a flooded basement in Tacoma?” “What does water damage cleanup cost?” Twenty or thirty is plenty. Then, on a fixed schedule — weekly is honest, monthly the floor — ask them in the engines your customers use, and record what comes back.

    The recording is where honesty lives or dies, because one answer contains three different facts:

    • Mentions. Does the answer name your business at all? Not link, not cite — name. The customer reading that paragraph sees your name or a competitor’s.
    • Citations. Does the engine cite your pages as sources? You can be named with no citation, and cited without being recommended — quoted as background while somebody else gets the call.
    • Accuracy. What does the answer say about you, and is it right? Engines repeat stale facts and invent new ones with total confidence. An answer describing a service you stopped offering two years ago is not a win — it’s a wrong sign on your door.

    Three columns, kept apart. Any tool worth paying for just runs that without the handwork — and the moment one blends those columns into a single number, it throws away the only details you’d ever act on.

    What tracking can genuinely see

    Done this way, tracking earns its keep. Four things it shows straight:

    • Trends on fixed questions. Same questions, same schedule. When your name starts appearing in answers it wasn’t in, that’s real movement — usually tied to work you did.
    • Which pages get cited. Not which pages rank — which ones engines actually pull from. In our own work, a few pages carry a large share of the citations.
    • Share against named competitors. Record who gets named when you don’t, on the same question set.
    • Answer drift. Ask the same question next month and the answer is different: a new source, a dropped name. Drift is normal — and why a one-time check is worth little.

    What no tool can see

    Now the part that doesn’t make it into the sales deck: five things no tracker — ours, theirs, anybody’s — can show you.

    The answer your actual customer got

    Answers vary by who’s asking, where they are, and when they ask — the same question can name different businesses for two people in the same town on the same afternoon. A tracker sees a sample, from its own accounts, and a sample is not the population. Anyone presenting a report as a census of what your customers saw is overselling the instrument.

    The questions nobody thought to ask

    Your prompt list is a map, and the map is not the demand. Customers ask things you’d never predict — oddly specific, half-wrong, mid-emergency questions typed one-handed at 2 a.m., some the most valuable in your market because the person asking is ready to buy. If it isn’t on your list, your tracker never asks it. The fix isn’t a bigger tool — it’s refreshing the list from real life: call recordings, intake notes.

    Why the engine picked a source

    No engine publishes its citation reasons. A tracker can tell you a page got cited, never why that page and not yours — anyone who claims otherwise is guessing and charging for the guess. What you can do is compare: read the cited page next to yours. Does it answer in the first paragraph, state facts plainly enough to quote, is it current? That’s judgment, not telemetry.

    What the answer caused

    Attribution stops at the answer. The engine doesn’t report back that the homeowner who read its paragraph called you, called the other company, or fixed it themselves — those calls are invisible to every visibility tool ever built. The last mile shows up only in your own books, so report and call log get read side by side before anybody claims the visibility did anything.

    Engines that don’t show their answers

    Some surfaces can’t be sampled at all — answers behind logins, in apps, in voice assistants. A tracker reports on the engines it can reach and has nothing on the rest. Ask any vendor which engines their number doesn’t cover.

    The score problem

    Which brings us to the product most buyers are actually being sold: a single visibility score. One number, proprietary formula, up and to the right in the demo. The trouble isn’t that it’s fake — it’s what it has to compress to exist.

    Run a small example. Over a quarter, a business gets mentioned in more answers and cited more often too. By any blended formula the score rises, and the quarterly report is a celebration. But read the accuracy column, the one the score dissolved: the engines now describe the business as offering a service it dropped last year, at a price it no longer charges, because an old page still says so. Customers call with wrong expectations, and staff spend five minutes a call correcting the internet.

    Score up. Facts wrong. Both true at once — and only one shows up in the report the owner paid for. A blended number turns three actionable facts into one feeling. A score that rises while the answer about your business is wrong isn’t measuring your visibility. It’s measuring its own smoothness.

    What to demand instead

    You don’t need to become a measurement expert. Ask for four things, and watch whether the seller can produce them.

    • Your prompt list, built from real customer questions — and shown to you. Generic questions make generic tracking.
    • The raw answers, kept. Not a screenshot of the best week — the actual paragraphs, so anything in the report traces back to a readable answer.
    • The three records, kept separate. Mentions, citations, accuracy — three columns, never one blended score. If a summary number exists, it sits on top of the columns, not instead of them.
    • Figures you can re-pull yourself. Where engines expose their own numbers — Bing Webmaster’s AI Performance reports, Microsoft Clarity — those live in accounts you own, and any figure from them can be checked by you, in your login. Hold every report to that standard: see the best agency for AEO SEO reporting is the one whose numbers you can re-pull, and our page on what an AI visibility report should show lists the sections to expect. An unverifiable report is a story you’re being told.

    Measurement, done honestly, is a flashlight, not a scoreboard. It shows you where to work next — which question you’re absent from, which fact about you has gone stale. The moment the measurement becomes the product being sold, it stops measuring your business and starts measuring itself. Run the fixed questions. Keep the three columns. Read the actual answers.

    Questions buyers ask us

    How do AI visibility tools work?

    At bottom, every one of them does what you’d do by hand: asks a fixed list of questions in the answer engines, on a schedule, and records what comes back — who’s named, who’s cited, what changed. The honest ones keep the records separate and show you the raw answers; the expensive-looking ones blend everything into a proprietary score. Either way, all of them see a sample — never every answer a customer received.

    Why doesn’t my Google ranking match my AI mentions?

    Because they’re different events. Ranking is your position on a list of pages. A mention is whether an answer engine names you in a paragraph assembled from its own sub-questions — whose cited sources overlap the organic top ten only a little. You can rank second and go unnamed while a competitor at fourth gets quoted — and tracking only the list keeps that gap invisible.

    Can I track AI visibility myself?

    Yes — the basic version is genuinely do-it-yourself. Write down twenty or thirty questions your customers actually ask, put them to Copilot and ChatGPT, and record three things: named, cited, accurate. Repeat monthly, same questions, and check the figures the engines give you in Bing Webmaster and Clarity, in your own accounts. An afternoon to start, an hour a month to keep. What you’re paying for, if you pay, is never skipping the month.

  • Can I Claim My Business in ChatGPT — and What Will It Actually Show Me?

    Can I Claim My Business in ChatGPT — and What Will It Actually Show Me?

    Short answer: no. Not today, and not because you’re behind. As of this writing, there is no public way to claim a business in ChatGPT. The claim page exists in exactly one place — a screenshot of an unreleased beta — and OpenAI has announced nothing: no launch date, no price, no list of countries, no help page. Anyone selling you a “ChatGPT claiming service” this week is selling you a screenshot.

    Here is what we actually know, where it came from, and the work you can do now so that when the door opens, you’re the first one through it.

    What was actually seen

    On November 6, 2026, Juozas Kaziukėnas — founder of Marketplace Pulse, an e-commerce research firm — posted a screenshot from inside ChatGPT. In the corner, in red: “unreleased/beta.” The page is headed “Claim your business in ChatGPT”, with a line underneath about unlocking a business agent and managing how your business shows up.

    The page makes three offers:

    • See how your business shows up — track how often your business is mentioned in ChatGPT conversations.
    • Show customers what you offer — add your latest products and keep your business information up to date.
    • Help customers make decisions — let a business agent answer questions using context you control.

    And one piece of fine print: you’ll need to verify that you’re authorized to represent your business.

    Kaziukėnas added the mechanics in his post. The tool measures impressions — the number of times a business appeared in ChatGPT responses — and clicks on links to the business’s website, tracked daily and shown as a chart. It sits inside a larger area called Business Hub. And it is only available to businesses that have verified their ownership — his example: “by connecting their Shopify store.” He also said the feature is a work in progress, that he saw its first steps as early as August, and that a banner he saw suggests it is getting close to launch. That last part is his inference, and it’s worth keeping labeled that way.

    Barry Schwartz covered the post the same morning at Search Engine Roundtable, and Search Engine Land and PPC Land followed the same day. Every one of those stories notes the same thing: OpenAI has not commented. This is one analyst’s view of an interface that has not launched. Details can change before it ships — if it ships in this form at all.

    What it would show you — and what it pointedly would not

    If the screenshot becomes a product, a claimed business gets a daily chart of two numbers: how often it appeared in ChatGPT answers, and how many people clicked through to its site. That’s real first-party data, and today it doesn’t exist anywhere for ChatGPT. Right now, the only way to know whether ChatGPT mentions your business is to ask it, repeatedly, and keep your own notes — which is exactly what we do in our own citation work.

    But Kaziukėnas is explicit about what the tool leaves out: no prompts, no user data, no competitor benchmarks, no rankings. Read that twice. You would see your mentions go up or down and have no way, inside the tool, to learn why. No record of the questions people asked when your name came up. No view of who else got named instead of you. A chart that moves without an explanation is a scoreboard, not a diagnostic — useful, but only paired with the outside work of tracking the actual questions.

    There’s a contrast worth naming here. The first-party AI-visibility console that actually exists today is Microsoft’s: Bing Webmaster Tools has an AI Performance section where we watch, for our own sites, which pages the AI cites and which questions ground on them. That one is live, free, and shipping real data now. OpenAI’s version of it is, today, a screenshot in a LinkedIn post. Plan against the tools that exist; be ready for the ones that don’t yet.

    The question nobody can answer yet: how does a service business verify?

    The only verification example on record is connecting a Shopify store. That works if you sell products through Shopify. A restoration contractor, a plumber, a law firm — a business whose “store” is a phone number and a service area — has nothing to connect.

    How would OpenAI verify that you own a local service business? A postcard, like Google’s old method? A document upload? A match against an existing Google or Bing profile? Nobody knows, because OpenAI hasn’t said, and no service business has been through it publicly. This is the single most important unknown for local businesses, and it’s the reason this article is a readiness piece instead of a how-to: the how-to cannot be written honestly yet.

    One more wrinkle, small but real. The screenshot’s fine print says you’ll verify that you’re authorized to represent the business. The reporting describes verifying ownership. Those are different tests, and the difference matters to any agency or consultant who would claim profiles on clients’ behalf — which is most of them. Which test OpenAI applies is another thing we find out at launch.

    What to have ready (all of it pays off today, too)

    None of the preparation depends on OpenAI. It’s the same discipline that earns citations on the surfaces that already exist:

    • One version of your facts. The same business name, address, and phone number, character for character, on your website, Google Business Profile, Bing Places, and every directory that matters. A verifier — human or machine — should find one business, not three near-matches.
    • Your existing profiles claimed and current. Google Business Profile and Bing Places are claimable today. Hours, services, service area, photos. If you haven’t claimed the doors that are open, the closed one isn’t your problem yet.
    • Pages that say plainly what you do and where. One page per service, in the words a customer would use to ask for it. This is what AI answers quote, with or without a Business Hub.
    • Your own mention log. Ask the major AI tools the questions your customers ask, on a schedule, and write down who gets named. When OpenAI’s chart exists, you’ll have your own baseline to check it against — and you’ll already know which questions you’re losing.

    When it opens

    The lesson from every previous claim system — Google Business Profile above all — is that early claimants get clean data and clean names, and latecomers get disputes. So: the week a “Claim your business” banner appears for real, claim yours, and verify with whatever method they offer a service business. We’ll do the same, and we’ll write up what the dashboard actually shows — the real numbers, the real verification path, and what it still won’t tell you — once we’ve been inside it ourselves.

    Until then: readiness is the whole job, and it’s the same job that gets you cited today. If you want to know how your business currently shows up across the AI surfaces that already answer your customers, that’s the first thing our $97 Quick-Scan reads — ChatGPT included, by hand, the only way it can be read until OpenAI opens the door.

    Sources: Juozas Kaziukėnas’s LinkedIn post (Nov 6, 2026); Search Engine Roundtable, “OpenAI Creating ChatGPT Tools For Business For Analytics & Citations” (Nov 6, 2026); Search Engine Land, “OpenAI testing business tools to track performance within ChatGPT” (Nov 6, 2026). OpenAI has not announced or commented on this feature; everything above about the tool itself traces to the screenshot and Kaziukėnas’s description of it.


    Want this thinking applied to your own business? Book a call with Will Tygart — 30 minutes, and we start from your receipts, not a pitch deck.

  • The Carrier Moved Into ChatGPT: MGT’s Aimee, Mapped Against the Wisdom Trust

    The Carrier Moved Into ChatGPT: MGT’s Aimee, Mapped Against the Wisdom Trust

    On November 5, 2026, MGT Insurance — a full-stack commercial carrier — listed its AI quoting assistant, Aimee, in the ChatGPT app directories and opened its MCP, so appointed brokers can quote a business policy by typing a sentence. This is a mapping: the new model read against the Wisdom Trust — our open kit for capturing elders’ life stories, and its paid human sibling, the Wisdom Manager. Two earlier mappings in this series read NHS Life Stories (October 18, 2026) and LifeBio’s Engagement Services (October 24, 2026) the same way. Where MGT’s public pages are silent, this says so rather than guessing.

    The two things, in one paragraph each

    MGT / Aimee. MGT is a full-stack, licensed commercial P&C carrier — an “AI-native neo-insurer” (A- rated by AM Best, per its release) that owns its product, its platform, and its risk, selling small-business cover (today: Business Owner’s Policy, 300+ business classes across 43 states and D.C.) through independent agents. Aimee is its broker-facing AI agent: since 2025 she has answered appetite questions on mgtinsurance.com with no sign-in; on October 16, 2026 MGT became, by its own claim, the first carrier to offer chat-based quoting — an agent describes a business in plain language (or uploads an ACORD application) inside ChatGPT or Claude and gets a real rate; on November 5, 2026 the integration was listed in the ChatGPT app directories, with MGT “opening up our MCP so brokers can quote where they already work.” Aimee classifies the business, checks MGT’s appetite, asks only for what is missing, prices the quote, and — the load-bearing detail — “tells the agent what she assumed and why.” Every quote then opens in MGT’s own portal, where the human agent reviews it and binds. MGT’s platform numbers ($83B of quoted TIV, nearly 15,000 appointed agents) are the company’s own, printed in its release; trade coverage notes MGT has not disclosed how many agents use the ChatGPT channel, what time it saves per quote, or what volume has bound through it.

    Wisdom Trust (Will). Two related things. The kit: an open-source starter set (MIT, explicitly “a seed, not a product”) for capturing retirement-facility residents’ life stories — one emailed question per week, answered by voice through a single link with no account, curated by an AI pipeline into a family-owned collection, framed as inheritance (“a life documented like a 401k left behind”). The storyteller owns the material outright; the machine’s outputs are drafts for human approval; nothing outward is ever auto-sent. The Wisdom Manager: a sketch for a paid human service — part curator, part oral historian, part creative director — that turns a family’s scattered media into a living collection through a gated process (private intake → curator review → owner approval → presentation), priced from ~$1,000 guided products to $20,000+ commissions. Both halves are built to be run by the people they serve; neither is published as a tool inside a platform somebody else owns.


    Side by side

    Dimension MGT / Aimee Wisdom Trust (kit + Wisdom Manager)
    Capture prompts / structure Appetite-first. Before any full submission, Aimee gives a real-time read on whether a class/state fits MGT’s appetite (the published Appetite Guide covers 300+ classes with NAICS groupings). In a quote she classifies the business, checks appetite, then asks only for what’s missing — the structure is the carrier’s underwriting rules, proprietary, applied conversationally. The prompt surface is whatever the agent types: a sentence, pasted call notes, an uploaded ACORD. A fixed library of 40 written questions across a life, one sent per week, skippable at will; the pipeline’s final stage (“Notice Gaps”) reads the collection and generates the next questions from what’s missing. The “asks only for what’s missing” discipline exists in his design too — but at stage 8 of the pipeline, after collection, not at the front door before it.
    Media types Plain-language text and documents: typed descriptions, pasted call notes, uploaded ACORD applications and supporting files, which Aimee “turns into a quote, flagging any values worth confirming.” Voice-first. A spoken (or typed) answer in a chat, 20+ languages, transcribed verbatim then cleaned; the pipeline can render artifacts back out — image, music, video, voice — each labeled with what it is, what it is not, and why it was made. The Wisdom Manager side curates media a family already has.
    Who does the capturing The machine, employed by the carrier. Aimee does the data entry, classification, appetite check, and pricing; a second agent (Athena, per MGT’s own essay) has made end-to-end underwriting decisions “with no human input.” The human in the loop is the broker — a professional intermediary — who reviews the finished quote in the portal and binds. The insured business is described, not consulted. The elder answers alone, by link; a family archivist or staff champion sends the question; staff are guides, not interviewers. The machine curates, but every outward artifact is a draft for owner approval — nothing auto-sends, ever. Both models keep a human gate before the consequential act; the gatekeepers differ (a licensed broker binding cover vs. the owner of the material approving its use), and so does whom the machine works for.
    Entry / onboarding Two doors, deliberately tiered. The appetite door is open to anyone — “you can still chat with Aimee about appetite, with no sign-in required.” The quoting door requires an MGT appointment (a broker contract) and signing in with MGT credentials inside ChatGPT/Claude; appointment itself is a sales process (mgtinsurance.com/get-appointed). Once appointed, the friction claim is real: “They don’t need another form or another login” — the quote starts inside the assistant the agent already uses. One link, no app, no account, no password — a stated non-negotiable: “If the storyteller has to install anything, the design failed.” Consent is signed before the pilot starts; there is no tiered front door — no way to feel the thing, saving nothing, before the consent conversation. The friction didn’t move to procurement as with LifeBio; there is no procurement. But there is also no anonymous first touch.
    Who the finished work serves, and where Three beneficiaries: the broker (time back — the scarcest resource in MGT’s own framing), the small business (a bound policy it never had to fill in a form for), and MGT (distribution into the rooms where brokers already work, plus appetite-consistent risk selection). The finished work lives in MGT’s portal — the quote opens there, is reviewed there, binds there. The ChatGPT surface is the front step; custody of the record stays with the carrier. Serves the family and descendants: an heirloom — stories, timeline, quote cards, people/places index, a weekly family letter, a gallery page. The facility’s benefit is real but secondary and reputational. The finished work lives wherever the family keeps its collection — the kit’s whole custody posture is that the platform is a shelf, not an owner. The Wisdom Manager serves the paying family directly, owner-approved before anything is shown.
    Consent / custody / ownership The public documents are website-era documents, and the ownership check shows it (quotes below). The privacy policy (last updated Oct 21, 2026 — two weeks before the ChatGPT listing) never names Aimee, ChatGPT, Claude, or MCP, states no retention period, and contains no mention of training (verified by full-text search of the published page: zero hits for “Aimee,” “train,” “retain”). It reserves broad improvement purposes over submitted information: personal data may be used for “Auditing, research, and analysis in order to maintain, protect, and improve our services,” “Developing new services,” “To model our risks,” and “To make our products and services better”; “We may combine the information submitted under various forms and services… to improve the quality of our services.” It does state “We do not sell Personal Information.” The website terms contain no license grant over user-submitted content at all — nothing equivalent to LifeBio’s AI-training licence, in either direction — and on termination say only that MGT may terminate the account “at any time and for any reason”; what happens to a broker’s submitted data or quote history on termination is not addressed. No designee or succession concept exists in either public document. The operative broker terms (appointment agreement, portal terms, MCP-channel terms) sit behind the appointment process and are not public. One more custody layer is new with this launch: a submission made inside ChatGPT also passes through OpenAI’s platform, under OpenAI’s terms — the chain now has two companies in it before the carrier’s own documents even apply. The most heavily specified layer of the kit. A plain-language consent: the elder owns their stories, period; access only by the elder’s grant (family included — not by default); grant and revoke at will; delete permanently and immediately; never sold; voice never used to train products without separate written permission; a designated person decides after death, defaulting to deletion after 12 months if none is named. “The facility’s role is shelf, not owner.” The Wisdom Manager carries the same posture into the paid service: safety gates (private intake → curator review → owner approval → presentation) are “part of the product.”
    Output format A priced, reviewable quote — a real rate, not an estimate — carrying an assumption statement (“what she assumed and why”), which opens in the MGT portal for review and binding into a policy. The assumption statement is part of the output object, not a disclaimer under it. A structured collection, not a single object: raw + cleaned transcripts, story records, timeline, quote cards, people/places index, weekly digest letter (draft), gallery page (draft), and labeled generated artifacts — all in JSON buckets any future AI can re-render. Artifacts carry provenance labels (what it is, what it is not, why it was made); nothing in the kit attaches an assumptions record — what the machine inferred where the storyteller didn’t say — to any output.
    Institutional / commercial model A regulated company selling risk: a licensed, full-stack carrier that monetises bound premium. The AI channel itself carries no published price — it rides on the broker appointment (contract terms not public; no figures published for the channel). Appetite spans 300+ classes in 43 states + D.C. (Florida and Hawaii excluded; five states listed as coming soon). The MCP is opened free, as distribution: the quoting engine is the marketing. Note what trade coverage could not find either: no disclosed user counts, time-saved, or bound volume for the new channel — the launch is measured in platform totals, not channel outcomes. Deliberately not an institution and not a company: an MIT-licensed seed its author declines to operate (“I’m not going to be the gardener on this one”). The commercial sibling, the Wisdom Manager, is priced as independent practice — role-hour maths, ~$1,000 guided products to $20,000+ commissions, family pays. Neither side of his model publishes anything into someone else’s platform or charges by distribution; there is no channel, only a kit people pick up.

    The door moves: an open MCP, and the product stops being a destination

    NHS Life Stories is a place you go and build. LifeBio is a person who comes to you. MGT’s Aimee is neither: the product dissolves into whatever assistant the broker already has open. By listing in the ChatGPT directories and opening its MCP, MGT stopped asking brokers to visit a destination and instead published its quoting engine as a callable tool — any MCP-capable assistant (ChatGPT, Claude, and next, the broker’s own in-house agents) can invoke the carrier mid-conversation. That is a distribution mechanism neither earlier mapping has, and it inverts the kit’s founding move in an instructive way: his one-link flow deletes the destination for the storyteller (no app, no account — the capture comes to the elder). MGT deletes the destination for the professional — the capture comes to where the broker already works, and the broker’s own AI can be the one calling. What it buys:

    • Distribution without a destination. The directory listing is the shelf space. A carrier that can be quoted “by typing a sentence” competes inside every conversation a broker has, not inside a portal tab the broker must remember to open.
    • Agent-to-agent quoting becomes possible. Once the engine is a tool, the caller doesn’t have to be a human typing — a broker’s own agent, working a renewal list overnight, can call Aimee the same way. MGT says this plainly: the engine “was designed from day one to be called by agents, human and AI.”
    • The assumption statement is the trust patch that makes it viable. Moving quoting into a chat window removes the form’s forced precision; Aimee’s answer is to ship her assumptions with the quote and ask instead of guessing when something is missing. Speed is the pitch; stated assumptions are what let a professional rely on it.

    And what it costs, in terms his files would price honestly:

    • The surface is no longer theirs. Inside ChatGPT, MGT’s product renders under OpenAI’s chrome, beside competitors one directory row away, under a second company’s terms. The carrier traded a destination it controls for reach it rents.
    • The custody chain lengthens exactly where the documents are thinnest. A broker’s submission now passes a platform company’s terms before it reaches a carrier whose own public privacy policy never mentions the channel exists (see the ownership row). The mechanism is new; the paperwork is a website policy last updated before the listing.
    • “Open” is doing quiet work. No public developer documentation, endpoint, or tool specification for the MCP appears on the pages read — the openness is a listing, granted to appointed agents through two named platforms, not a published interface anyone can build on. It is an open door into a closed house: the engine, the appetite, and the submission data stay proprietary.

    What the Wisdom Trust could borrow

    1. An assumption ledger on every machine-made artifact. Aimee ships “what she assumed and why” with every quote. His artifacts carry provenance labels (what it is, what it is not, why it was made) but no record of what the machine inferred — which date it guessed for an undated story, which “Uncle Ray” it merged with which. Adding an assumptions array to the schemas (each entry: the inference, the evidence, a confirm/correct affordance for the owner) turns stage 4’s silent enrichment into something the family can audit — and it is the same fact-gating instinct his fleet work already runs on, applied to the kit.
    2. A two-tier front door: a no-save taste before the consent conversation. MGT’s appetite chat is open to anyone with no sign-in; only quoting requires the contract. The kit has one door, and it’s paperwork. A public “answer one question, nothing is kept” demo — one joy prompt, answered by voice, wiped when the tab closes — would let a family feel the thing before anyone signs anything, and would give facilities a tour artefact stronger than the one-pager. The consent template stays exactly as strict; the door in front of it gets lighter.
    3. Appetite before paperwork, as a designed step. Aimee checks fit before collecting anything and asks only for what’s missing. His pilot’s first act is consent; a two-minute fit conversation (does she want to talk about her life? joy-first or wisdom-first? who should hold the collection?) before the forms would put the kit’s existing gap-noticing discipline at the front of the flow instead of only at stage 8.
    4. Publish the kit’s functions as a callable tool, not only a link. The kit’s automation README is already a plug-in contract an AI can execute — the seed of an MCP-shaped door. MGT’s move shows the distribution value of finishing that thought: a family archivist’s own assistant could invoke “this week’s question” and “file this answer” as tools, meeting the archivist inside the assistant they already use, exactly as Aimee meets the broker inside theirs. The one-link flow stays for the elder; the archivist gets a second door.

    What his does differently, on purpose

    1. Ownership is answered in advance, in plain language — here the contrast is silence plus reservation. Against LifeBio, his template differed from stated terms (a training licence, discard on termination). Against MGT, the public terms state almost nothing about submitted content — no training licence is taken, which is genuinely better — but broad improvement and risk-modelling purposes are reserved over whatever is submitted, the channel itself is never mentioned in the privacy policy, and the documents that would settle the quoting channel’s ownership questions are contract-side and unpublished. His template answers every one of those questions before the first recording: whose it is, who may hear it, what happens when the relationship ends, who decides after death.
    2. Whom the machine works for. Aimee’s appetite is MGT’s appetite; she quotes one carrier’s product and her assumptions serve the carrier’s risk selection as much as the broker’s convenience. His pipeline works for the elder and family — its drafts wait for the owner’s approval, and its gap-finding serves the collection, not a seller. Both keep a human gate before the consequential act; the difference is whose human, and whose interest the machine was built to advance when the two diverge.
    3. Openness of the artifact vs. openness of the interface. His kit is open all the way down — MIT, forkable, schemas published. MGT’s openness stops at the interface: the MCP is listed and callable (by appointed agents, on named platforms), while the engine, the appetite logic, and everything submitted stay inside. Neither is a pose; they are opposite answers to “what do you give away to get distribution?” — he gives away the machine and keeps no channel; MGT keeps the machine and gives away the doorway.

    What he would likely reject, per his own files

    • Reserved improvement/modelling use of submissions as a standing term. His consent template promises: never sold, never used to train products without separate written permission, access only by the elder’s grant. MGT’s privacy policy reserves using submitted information to “improve our services,” “develop new products and services,” and “model our risks,” with an opt-out mechanism that applies to new purposes via a contact page. Risk modelling is ordinary, legitimate insurance practice — and it is still exactly the shape of clause his template exists to refuse: purposes named by the holder, changeable by the holder, consent handled as opt-out.
    • Changeable-at-will terms. The website terms “may be changed, modified, supplemented, or updated at any time, with or without advance notice,” with continued use counting as acceptance. His consent is a signed, plain-language document the elder can revoke at will; the terms of the relationship are not a web page one side edits.
    • A persona users mistake for a person. His pipeline labels every generated artifact with what it is and what it is NOT. MGT’s own essay reports, approvingly enough to print, that Aimee’s “users thank her and ask her to start their quotes, most of them not realizing she’s an AI” (the essay’s title is “They Don’t Know It’s an AI Bot”; MGT, to its credit, says it would rather answer the question in public than dodge it). Per his labeling rule, an assistant a user can’t tell is a machine is a disclosure defect, not a delight metric.
    • Credentials inside a third party’s surface as the consequential door. Quoting requires signing in with MGT credentials inside ChatGPT/Claude — the broker’s carrier login now lives in a platform the carrier doesn’t control. His non-negotiable deletes accounts and passwords for the person at the centre of the capture. (Nuance, noted in the table: the appetite door is credential-free — the tiering itself is borrowable #2.)

    Gaps in his own files (marked, not filled)

    • No machine-callable surface. His files describe a kit humans run and a pipeline an AI runs on the back end — but nothing about publishing the kit’s functions as tools other assistants can call, being listed anywhere, or distribution through a platform’s directory. MGT’s whole launch is that surface. The automation README is the seed of it; the discovery/distribution question is unasked in his files.
    • No assumption ledger. His stages enrich silently: dates inferred, people merged, gaps noticed — but no output carries what the machine assumed and why, in a form the owner can confirm or correct. Aimee’s quote does. (Borrowable #1 names the fix; this entry marks the silence.)
    • No eligibility step before collection. His pilot opens with consent paperwork and a 10-resident scope; nothing first asks fit — does this resident want this, which track, joy-first or wisdom-first — the way appetite precedes a quote. The appetite conversation is two minutes and saves the paperwork for people it fits.
    • The dementia silence, third mapping running (carried from NHS Life Stories, repeated in the LifeBio mapping, still open). Aimee exposes nothing here — commercial quoting is not its territory — but the standing instruction of this series is that a repeated silence gets named as repeated: his question library still assumes a storyteller who can sit with an abstraction, and no mapping since has closed it.
    • Custodian succession. His consent template settles what happens when the elder dies (a designated person decides). It does not settle what happens if the shelf changes hands — the facility is sold, the keeper of the vault exits. MGT’s privacy policy at least names the asset-sale transfer case for its side; his files leave the equivalent case unaddressed.

    Could not verify from public pages (MGT side)

    • The operative broker terms. The appointment agreement, the portal terms, and any terms specific to the MCP/directory channel sit behind the appointment process and are not public. The ownership questions for the quoting channel itself — who owns a submitted ACORD and the data extracted from it, whether it trains models, what happens to submission history when an appointment ends — are therefore unverified: the documents exist but are contract-side, not published. The public website terms and privacy policy were read in full and are silent on each.
    • What the “open MCP” technically is. No public developer documentation, endpoint, tool list, or authentication spec for the MCP was found on the pages read. “Open” is established as a distribution claim (listed in the directories, callable from ChatGPT and Claude), not as published developer access.
    • The second platform’s terms. Data submitted through the ChatGPT (or Claude) surface also passes under OpenAI’s (or Anthropic’s) terms for directory apps. Those terms were not read for this mapping, so the full custody chain of a broker’s submission is unverified at the platform layer.
    • The headline numbers. $83B quoted TIV, “nearly 15,000 appointed agents,” the “A-” AM Best rating, and “first carrier” are MGT’s own claims from its release and site. Trade coverage (GlobalFinTechEdge) narrows “first” to a carrier-specific quoting integration and records that MGT has not disclosed active ChatGPT-channel users, average time saved per quote, or policies bound through the channel.
    • Quote performance. No independent source on how often Aimee’s quotes bind as priced, how her classifications hold up, or how assumption statements read in the live ChatGPT surface (no transcript was available; the one concrete premium — $2,740/yr for a Sacramento bakery BOP — comes from MGT’s own demo video).
    • Athena’s end-to-end underwriting. The claim that an AI underwriting agent decided a case with no human input, “and got it right,” is from MGT’s own essay; no external account exists on the pages read.
    • Whether Aimee identifies herself as an AI in the quoting surfaces. MGT’s essay title and text (“users thank her… most of them not realizing she’s an AI”) describe the website agent; the disclosure behaviour of the ChatGPT/Claude listing itself was not observable from public pages.

    Sources

    • The occasion — Insurance Edge republication of the release (Nov 6, 2026): https://insurance-edge.net/2026/11/06/us-news-mgts-aimee-ai-assistant-now-listed-in-chatgpt-directories/
    • Original release (Business Wire, Nov 5, 2026): https://www.businesswire.com/news/home/20261105657905/en/MGT-Becomes-First-Insurance-Carrier-to-Bring-ChatGPT-Quoting-to-Independent-Agents
    • MGT — first carrier to offer chat-based quoting (three ways to quote; portal review before bind): https://www.mgtinsurance.com/blog/first-carrier-chat-based-quoting-independent-agents
    • MGT — how AI underwriting cuts quote time (Aimee in ChatGPT/Claude/portal; appetite with no sign-in): https://www.mgtinsurance.com/blog/how-ai-underwriting-cuts-quote-time-for-independent-agents
    • MGT — BOP appetite page (300+ classes; states covered/excluded): https://www.mgtinsurance.com/appetite
    • MGT — “The Neo-Insurer Bet” essay (Athena; “They Don’t Know It’s an AI Bot”; the disclosure question): https://www.mgtinsurance.com/blog/the-neo-insurer-bet
    • Trade coverage noting the undisclosed channel metrics and the narrow reading of “first” (GlobalFinTechEdge, Nov 2026): https://globalfintechedge.com/news/mgt-brings-ai-insurance-quoting-assistant-to-chatgpt/
    • InsureWire distribution tracker (Oct 16, 2026 announcement entry): https://insurewire.org/digital-insurer/agents-distribution/
    • Privacy policy (last updated Oct 21, 2026 — read in full; findings quoted above): https://www.mgtinsurance.com/privacy-policy
    • Website terms & conditions (read in full): https://www.mgtinsurance.com/terms-conditions
    • The Wisdom Trust kit and the Wisdom Manager service sketch — Tygart Media working papers; the two earlier mappings in this series are dated October 18 and October 24, 2026.
  • Receipts: ChatGPT Read 375 Pages of One Site. It Sent Back 1 Visitor.

    Receipts: ChatGPT Read 375 Pages of One Site. It Sent Back 1 Visitor.

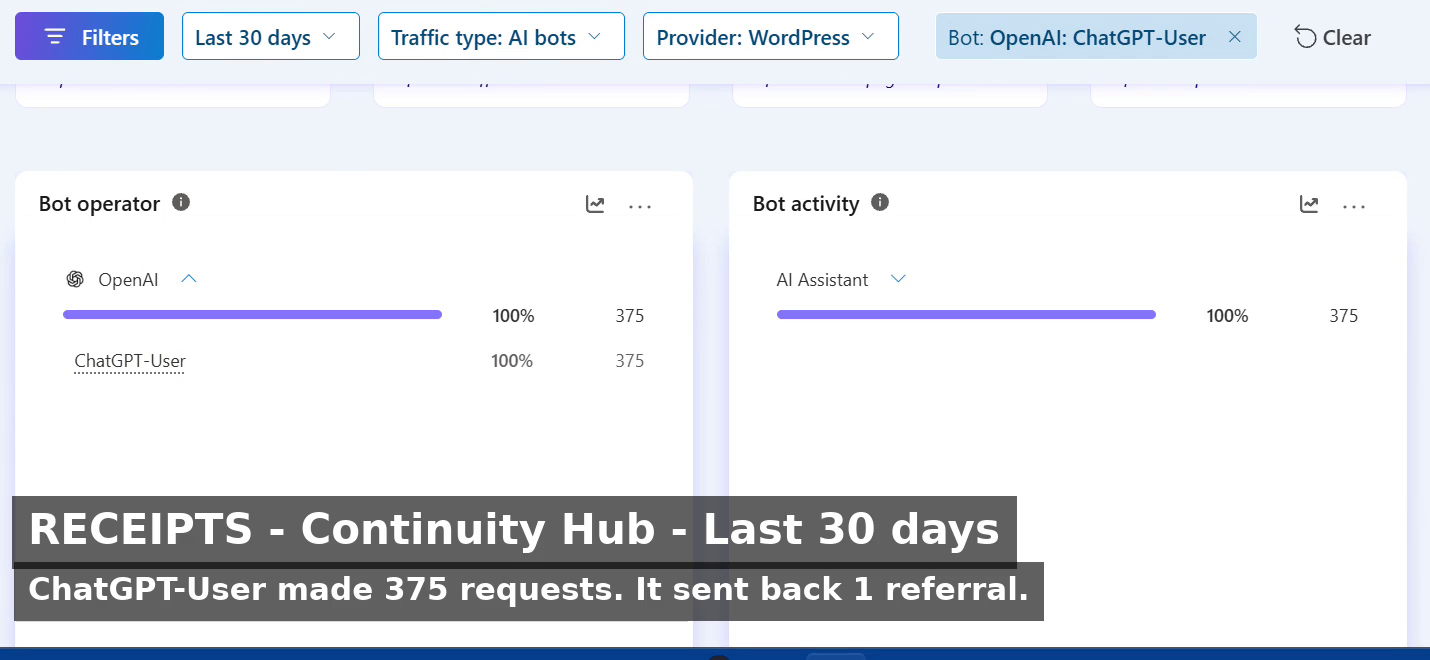
    People say you can’t tell which AI models are reading your site, or what they do when they get there. This is Microsoft Clarity on one of ours. It names the operator, the bot, and the activity — no guessing.

    Continuity Hub, last 30 days: ChatGPT-User made 375 requests. The homepage 83 times. Then the guides, one by one — supply-chain resilience, financial-services continuity rules, OSHA evacuation plans — down to pages that got a single read each. The bot didn’t skim the site. It walked the whole catalog.

    The scrape-to-referral ratio is 494:1. For every 494 pages the model read, it sent back one visitor. One referral, total, from chatgpt.com.

    That ratio is the part nobody selling AI visibility talks about. Being read by the models and being sent customers by the models are two different numbers, and the first one is enormous while the second one is nearly zero. We’ve measured the same shape across our sites — 408:1 on one, 837:1 across the fleet in September. The reading is real. The referring barely exists.

    So when you interview whoever handles your SEO and AEO, ask them to pull up this screen for your site, live, with the dates in frame. If they can’t show you the receipts, they’re reading from somebody else’s book.

  • Can a Vendor’s Own “Best Tools” List Earn AI Citations If It Discloses Who Wrote It?

    Can a Vendor’s Own “Best Tools” List Earn AI Citations If It Discloses Who Wrote It?

    Disclosure, up front — because that is the subject of this article. Tygart Media sells AI search visibility work. We publish our own tool pricing and comparison pages, and this site is a vendor in the category this article examines. Every number below comes from one named study, with its method stated, so you can check it the way we did.

    The short answer is yes. A disclosed vendor comparison can earn AI citations, because the engines are barely scoring authorship at all. In the largest count anyone has published, between a third and a half of the “best tools” lists cited in AI answers were written by a vendor selling in that category. The traits that measurably raise a page’s citation odds are a comparison table and a stated selection method — not who published the page.

    What got counted

    In August 2026, the agencies Minuttia and Convex Works asked 18,084 software-buying questions across six platforms — Google Search, AI Overviews, ChatGPT, Gemini, Claude, and Perplexity. They then read all 311,766 pages those platforms cited and labelled each one by who published it and what kind of page it is. It is the first count of vendor-written lists in AI answers that works from the cited pages themselves rather than from opinion about them.

    The study’s own caveats deserve the same prominence as its findings. Every share it reports is a floor, because pages its team could not read were counted as not self-promotional. And the results are a snapshot, not a standing: when the researchers re-asked Perplexity 2,000 of the questions a month later, only 28% of the pages in the new answers had been there in August. Citations churn. Anyone measuring them from a single screenshot is reading weather and calling it climate.

    How much of the answer is a vendor grading its own homework

    For “best alternatives to X” questions, 34% to 47% of the listicles the platforms cited were a vendor’s own list, depending on the platform — 47% on Google and Gemini, 34% on ChatGPT. For “how do X and Y compare” questions, the vendor-written share rises to between 56% and 65%. Across every category and question type, 43% of cited listicles are self-promotional.

    The spread by category is wider than the average suggests, running from 12% in audio production to 76% in AI security operations. AI visibility — the category this site sells in — sits at 65%, one of the most self-promotional categories measured. If you buy or sell in a software category, the honest working assumption is that a large share of the “best tools” content the machines quote was written by someone ranked in it.

    The lists themselves behave the way you would expect. Of the vendor-written lists the platforms cited, 93% highlight the vendor’s own product, 87% rank it first, and 90% criticise competitors. Only 16% clearly disclose that the vendor wrote the page. The typical cited list, in other words, is an undisclosed advertisement that puts its author first — and the engines cite it anyway.

    Each engine shops differently

    ChatGPT searches the way a buyer going straight to the source would. In 71% of the searches it ran before answering, it named exactly one product, and 92% of its site-limited searches pointed at a vendor’s own website. On alternatives questions, vendors’ own sites made up 42% of ChatGPT’s citations, against 1% to 6% on the other platforms. For ChatGPT, the vendor’s own pages are not a contamination of the research — they are a primary input to it.

    Perplexity works more like an editor with a pile of candidates. A typical answer finds about 20 pages and cites 9 of them, and which pages survive depends first on where they sat in its search results. Here is the finding that reframes the whole question: of the pages Perplexity found, vendor-written listicles were cited 58% of the time — the highest citation rate of any page type it found, ahead of independent listicles at 44% and review sites at 36%.

    There is no single shelf to win, either. Only 21% to 28% of the citations from AI Overviews, Gemini, Perplexity, and Claude also appear in Google’s top 10 results for the same question. Each engine assembles its own evidence, which means a page earns its place engine by engine, on traits each engine can see.

    The traits that actually move a citation

    Perplexity is the one platform where the study could watch the selection happen — every page found, then which ones got cited. Holding search position equal, here is how often a found listicle was cited with and without each trait:

    Trait Cited with it Cited without it
    Has a comparison table 70% 60%
    Says how the tools were picked 69% 61%
    Longer than the typical list 68% 62%
    Year in the title 68% 63%
    Written by a vendor in the category 64% 68%
    Promotional tone 64% 69%
    Ranks its own product first 64% 65%

    Read the table from the bottom up and the story tells itself. Ranking your own product first — the move that looks most like cheating — costs about one point. A promotional tone costs about five. Being a vendor at all costs about four. Now read the top: a comparison table is worth ten points, and stating how the tools were selected is worth eight. The penalties for self-interest are small and the rewards for being genuinely useful are larger, on the same scale, in the same measurement.

    One honesty note about this article’s own title: the study never isolated disclosure itself as a citation trait, so no one can honestly claim a measured disclosure bonus. What the study did measure is disclosure’s closest cousin — a page that says how its tools were picked gets cited more, not less. Nothing in the data shows an engine detecting a disclosure line and punishing it, and the 84% of vendor lists that hide their authorship are not winning because they hide. They are winning in spite of it, on tables, method, length, and position.

    So why disclose, if the machines don’t make you

    Because the citation is only half the transaction. The other half is the human who clicks through from the answer and decides whether to trust the page in front of them. A list that hides its author converts every citation it earns into a small liability: the reader who discovers the trick discounts not just the list but everything else the vendor says. Disclosure costs no measurable citation share, and it is the only version of the page that survives both readers — the machine counting traits and the person counting on you.

    This is also a game a small operator can actually win. Vendor-written lists that earn citations come from smaller sites than the independent lists they compete with — a median domain rank of 49 against 63 — and the field is fragmented: the 20 most-cited vendors together hold only 6% of the citations. There is no incumbent wall here. There is a craft bar, and it is published in the table above.

    The rules we publish by

    • Disclose at the top, not in the footer. If a page compares a category we sell in, the first screen says so. A disclosure a reader has to hunt for is a hiding place with better manners.
    • State the selection method. How the tools were picked is a measured citation trait, not just an ethical nicety. Write the method before the rankings, and let the rankings follow from it.
    • Put the comparison in a real table. Rows a machine can parse and a person can scan. The table is worth more citation share than any headline about yourself.
    • Earn first place or don’t take it. Ranking yourself first costs almost nothing in citations and almost everything in credibility when the method on the same page doesn’t support it.
    • Date it and keep it current. A year in the title is itself a small citation trait, and a stale list quietly stops being evidence. Lists are maintained assets or they are litter.
    • Publish the data behind the claims. Minuttia released the data behind every chart in its study so competitors could check the work. Checkable beats confident, with machines and with people.
    • Measure citations as a 30-day rate. A quarter of the cited pages turn over in a month. A rate over time is the only reading that distinguishes a page that earns its place from a page that got lucky once.

    The engines have already decided the underlying question: vendor lists are sources now, cited at rates no one can opt out of by refusing to write them. The live question is narrower and more useful — whether your list reads as evidence or as advertising when it gets there. The disclosed list, with its method stated and its comparison in a table, is the one built to be both.

    Study: Minuttia × Convex Works, “Self-Promotional Content Data Study” (August 2026 data), self-promotional-content-data-study.minuttia.com — full data published with the study. Coverage: Digital Market Reports, October 22, 2026.

    AI Citation Quick-Scan — $97

    This article is about whether your pages earn citations. The Quick-Scan runs that test on your company: ten real homeowner prompts across the major AI answer engines, with a written report — and the $97 comes off the package price if you go further. Built for restoration contractors.

    Get the Quick-Scan — $97

  • Six in Seven AI Answers Never Look Anything Up

    Six in Seven AI Answers Never Look Anything Up

    Most of what an AI answer says about your business was never looked up. It was remembered — or invented in the shape of a memory. Ahrefs put a number on that in a study published October 12, 2026: across 66.6 million free, logged-out ChatGPT responses from August and September 2026, a web search ran in only 14.4% of them. Six in seven answers were written without checking anything.

    That single fact reorganizes the work. If the answer usually comes from what the model already carries, then being findable is only half the game. The other half is being known — and, for the one answer in seven where the engine does go looking, having the fact it needs sitting in plain text on your own domain, where it looks first.

    The search, when it happens, is narrow

    The same study logged 15 million fan-out queries — the searches ChatGPT issues behind an answer when it decides to search at all. A searching response ran about 1.6 of them on average. This is not a research department fanning out across the open web. It is a quick, targeted check, and the targeting is the story.

    6.8% of those fan-out queries used a site: operator to search one specific website, spread across roughly 116,000 domains. Among the most common of those targeted searches, 75.9% pointed at a brand’s own site — not a retailer, not a forum, not a review aggregator. When the engine wants a price or a specification, it goes to the company that sells the thing.

    The vocabulary inside the queries leans the same way. The word “official” appeared in 13.1% of English fan-out queries in September 2026, up from 10.1% in August. “Price” climbed from 6.04% to 8.88% of fan-outs in the same month — a relative rise of nearly half. The engine is increasingly searching for the authoritative version of a fact, and the facts it most wants are commercial ones: what it costs, what it includes, what the official page says.

    Facts go home; comparisons wander

    Ahrefs paired the fan-out data with a separate test of 20,000 US prompts, and the split inside it is worth keeping separate in your head, because it is a different instrument from the 66.6 million. In that test, 84.4% of factual questions — pricing, product features, company details — cited at least one official source. For factual questions, 63.4% of all citations pointed at official websites. For comparison questions (“A vs B,” “which is cheaper”), the official share fell to 46.4%: most citations went somewhere else.

    Read together, the two datasets describe one behavior with two modes. Asked for a fact, the engine goes home to the source. Asked to judge, it goes out to the crowd. An operator cannot control the judging mode. The fact mode is entirely winnable: it is won by having the fact, in the open, on the domain the engine already searches by name.

    The playbook that follows

    Publish the price, the spec, and the support fact in plain text on your own domain. Not in a PDF the crawler has to excavate, not inside a configurator, not implied by a sales page’s adjectives. The fan-out query literally contains the words “official” and “price” — it is asking for a page that states the number. Whoever states it cleanly gets cited for it.

    Publish the pages only you can publish. Your measured results, your actual process, your own numbers with dates on them. A summary of somebody else’s facts competes with the original; the original is what the engine is learning to prefer (the citation movement below shows how far that preference has already moved).

    Treat fan-out queries as an instrument of their own. The queries an engine issues about your category — which words it adds, which domains it targets, how that shifts month to month — are a measurement channel separate from citation counts. Watch them separately. We grade the flight recorder, not just the answer, for the same reason: the queries show the intent; the answer only shows the outcome.

    Never blend two dashboards into one story. The 14.4% comes from 66.6 million free logged-out responses. The 84.4% comes from a different, 20,000-prompt test. The citation movements in the next section come from a third cut again. Each number is true inside its own denominator and misleading outside it. This is the same discipline we run on our own visibility work: being cited is not being chosen, and being measured is not being measured the same way twice. Our running instrument for the citation side is the Citation Pulse.

    The second movement: summarizers are losing

    Ahrefs’ Brand Radar citation data for the US — 2.4 million ChatGPT answers in March 2026 against 3.8 million in September, a different dataset from the fan-out study above — shows where the citations went. Reddit fell from roughly one citation in every five answers in March to about one in 43 by late September. Wikipedia fell from one in seven to one in 35. The share those summarizers and forums lost moved to research bodies, regulators, brand and support pages, and hands-on testers. On a matched set of about 25,000 prompts present in both months, every tracked site moved in the same direction, so the shift is not an artifact of new questions entering the sample.

    For an operator, that is the durable part of the whole study. The memory answers reward whoever the model already knows. The searching answers reward whoever publishes the primary fact. The citation trend rewards the originator over the summarizer. All three roads end at the same address: your own domain, carrying your own facts, in plain text.

    The same citation movement, read for hospitals and the firms that build for them — why clinical and facility specifications now have to live as primary documents — is on Healthcare Facility Hub: The Citation List Is Moving Toward the Source Document.

    Sources: Ahrefs, “How ChatGPT Does Query Fan-Out” (October 12, 2026) — fan-out dataset (66.6M responses, 15M queries, Aug–Sep 2026), the 20,000-prompt official-source test reported in the same article, and the Brand Radar US citation comparison (2.4M answers March 2026; 3.8M September 2026). Each figure above is stated with the dataset it came from; the three are not interchangeable.

  • Review Count Is Dead: The Reputation Graph Killed It

    Review Count Is Dead: The Reputation Graph Killed It

    A water-damage company with 47 reviews just got recommended by ChatGPT over a competitor with 462.

    Read that again. Four hundred and sixty-two reviews. Ten times the social proof. And the AI picked the little guy.

    If you spent the last decade collecting reviews like they were votes, this should rattle you. It should also clarify everything, because the game didn’t just change — it ended, and a new one started while nobody was watching.

    From ranking to matching

    The old game was a scoreboard. Most reviews wins. Biggest ad budget wins. Best SEO agency wins.

    The new game is a matchmaker.

    In June 2026, OpenAI rolled out a memory system (they call it Dreaming) that quietly builds a living profile of you — your chats, your Gmail, your files — and uses it to shape every answer. It’s on by default. Two people asking ChatGPT the same question now routinely get different answers, because the AI knows different things about each of them.

    Google’s doing the same thing from the other direction. AI Overviews don’t give you a ranked list of ten businesses anymore. They name two or three. Fourth place doesn’t get a consolation mention — it gets nothing. And here’s the number that should end the argument: only about 26% of the businesses sitting in Google’s top-3 map pack even appear in Gemini’s responses. You can win the map pack and still be invisible to the AI.

    So the question was never “who has the most reviews.” The question is “who is the best fit for this person,” and the AI is answering it with information you can’t see.

    The dinner test

    Here’s how I explain it to myself.

    Tonight I walked to a little family-run Thai place instead of ordering from a chain. No ad convinced me. No review count swayed me. The tools just… knew. They knew I’d rather have the local place with the great green curry than the heavily advertised alternative.

    A cozy family-run Thai restaurant glowing warmly at dusk while a chain restaurant sign looms in the background
    The tools know you’d pick the local place. No ad budget changes that.

    That’s what happened with the 47-review company. The AI didn’t count stars. It matched a person — their history, their preferences, the pattern of what “good” looks like to them — against the businesses it knew. And the little guy fit better.

    Panda Express can outspend everybody. It doesn’t matter. When the tool knows you better than the ads do, the ads stop working on you.

    Why the count stopped mattering

    It’s not that reviews don’t matter. They do — review signals have actually grown to about 20% of local ranking weight. But count was always a proxy for trust, and the AI doesn’t need the proxy anymore. It reads the reviews. It summarizes the sentiment. It checks whether your website says the same thing your Google profile says. It looks at whether your story is consistent across fifteen, twenty, thirty sources — or whether it falls apart the moment it leaves your homepage.

    A thousand bought or begged reviews with thin sentiment lose to fifty detailed ones that all say the same specific true things. The AI can tell the difference. It literally summarizes them.

    What actually wins now

    A local contractor business at the center of a glowing reputation graph, with a pile of disconnected review stars off to the side
    The reputation graph: every signal connected, telling one consistent story.

    The playbook isn’t complicated, but it’s unforgiving:

    • Complete your profile like it’s the product. The AI reads your Google Business Profile as a primary source. Empty fields are silence, and silence doesn’t get cited.
    • Recency and sentiment over volume. A steady stream of real, specific reviews beats a pile of old five-stars.
    • Say the same true thing everywhere. Your website, your profile, your directories, your socials — one consistent story, confirmed in many places. Contradictions are how you disappear.
    • Structure your data. Schema markup is how the machines read you. It’s not optional anymore; it’s the difference between being understood and being skipped.
    • Be genuinely good. This is the one nobody wants to hear. The tools are getting better at knowing what “good” looks like for each person, which means there are fewer places to hide. You can’t buy your way into a match. You have to be the answer.

    The honest caveat

    I want to be straight about what we know and what we don’t. Nobody outside these companies can see exactly how the personalization works — one researcher called it “a synthesized profile that neither the user nor the brand can fully see.” That’s the truth of it. We’re reading the outputs and working backward.

    And the social-graph part — your friend’s Facebook comment tipping a recommendation — is directionally right but the mechanics differ by platform. Google has the cross-product graph: YouTube, Maps, Gmail, Android. Meta’s AI has the actual social graph. ChatGPT works mostly from your own data. The destination is the same everywhere: the recommendation gets personal, and the personal is opaque.

    Less places to hide

    That’s the line I keep coming back to. Less places to hide.

    For years you could paper over a mediocre operation with review velocity, ad spend, and SEO tricks. The machines are taking those tools away — not out of virtue, but because matching works better than ranking, and the platforms all figured that out at once.

    What’s left is the oldest marketing strategy there is: be good, be consistent, and make sure the machines can see it.

    The 47-review company didn’t beat the system. It was the system working as designed. The question is whether you’re building a business the new system can see — or still optimizing for the old scoreboard.

  • AI Search Visibility for Local Service Businesses: The 2026 Playbook

    AI Search Visibility for Local Service Businesses: The 2026 Playbook

    Last verified: October 4, 2026 (Pacific).

    Updated November 2, 2026 — added direct answers on competing in crowded search markets and improving visibility in AI-generated search results, from our own published work.

    Correction, November 2, 2026 — sample specifics used as illustrations on this page (a sample license number and a sample price range) were genericized wherever they appeared. No findings or recommendations changed.

    Updated November 2, 2026 — added direct answers on local business AI search visibility, answer engine optimization, and trade-specific lead generation, from our own published work.

    Key takeaways

    • AI search visibility is whether AI assistants name your business when someone asks for a local service — and 78% of local-services brands are currently invisible to it.
    • ChatGPT recommended just 1.2% of business locations in a 2026 benchmark of 350,000 locations, versus 35.9% appearing in Google’s local 3-pack (SOCi, 2026).
    • Only 12% of URLs cited by AI overlap with Google’s top 10 results — this is a separate ecosystem with separate rules (teehoomartech).
    • The shops winning AI citations publish real price ranges, license and certification signals, and emergency-intent pages — the three shapes almost nobody in the trades has built.
    • Expect a 90-day foundation cycle: fundamentals first, then the service × city content matrix, then seasonal content.

    What is AI search visibility for a local business?

    AI search visibility is the practice of making your business the answer AI assistants give — getting ChatGPT, Gemini, Perplexity, or Copilot to recommend you by name when someone asks for a local service. Think of it as SEO for the recommendation era.

    Your next customer didn’t Google “plumber near me.” They asked ChatGPT. Or they asked Gemini while standing in their kitchen with water pooling under the sink. And the AI named three businesses — yours wasn’t one of them.

    This isn’t a future problem. According to BrightLocal (March 2026), 45% of U.S. consumers use AI to find and choose a local business — up from 6% a year earlier. The question is no longer whether AI sends you customers. It’s whether AI knows you exist.

    How far behind are local businesses in AI search?

    A 2026 benchmark by SOCi across roughly 350,000 business locations put hard numbers on the gap:

    • ChatGPT recommended 1.2% of locations. Google’s local 3-pack showed 35.9%. Gemini recommended 11%, Perplexity 7.4% (SOCi, 2026).
    • AI visibility is 3 to 30 times harder to achieve than ranking well in traditional local search (SOCi, 2026).
    • Only 12% of URLs cited by AI overlap with Google’s top 10 results (teehoomartech). This is a different ecosystem, not an extension of the old one.
    • 78% of local-services brands are invisible to AI, and 88% of local businesses have no AI search strategy at all (May 2026 industry index).

    Here’s the reframe that matters: AI doesn’t rank you. It recommends you. Traditional SEO was optimization — climbing a list. AI visibility is qualification — convincing a model you’re a safe, correct answer to give a real person. Everything below follows from that shift.

    Traditional local SEO AI search visibility
    Climb a ranked list (positions 1–10) Become the recommended answer (named or not at all)
    Optimize for Google’s crawler Qualify for the model’s trust judgment
    Reviews are a ranking signal Reviews are a qualification filter — the AI reads the text
    Your website is the destination Your website is the source the model draws on
    One rulebook (Google) Different rulebooks per engine (Gemini, ChatGPT, Perplexity)

    What are the non-negotiable fundamentals?

    You’ve seen this checklist before, so here’s the short version — these are table stakes, and the data says they still move the needle:

    • NAP consistency everywhere. Inconsistent name/address/phone data cuts your AI citation probability by 67%. Consistent omnichannel data delivers 3.2x the AI visibility (Birdeye, 2025).
    • A complete Google Business Profile. Optimized profiles appear in AI Overviews 42% more often, with 30% more profile views and 34% more direction requests (Local Falcon; SapientSEO).
    • Review volume, velocity, and recency. AI treats reviews as a filter, not a ranking signal — and it reads the review text, not just the stars. ChatGPT-recommended locations averaged 4.3 stars in the SOCi benchmark: good enough to pass the filter, with the text doing the real work.
    • Owner responses on reviews. Every response is a place to confirm your services, your service area, and real outcomes — in the AI’s own training-adjacent data.
    • LocalBusiness schema on every page. Structured data increases AI citation probability 3.4x (MIT CSAIL). FAQ content earns 2.8x more AI citations than marketing copy (Search Engine Land research).

    If any of those are missing, fix them first. What follows is what nobody is telling the trades.

    How do you win the 2am emergency query?

    The highest-value AI query in the trades isn’t “best plumber near me.” It’s “emergency plumber near me open now” at 2am — asked by someone with water coming through their ceiling. Nobody has mapped AEO to urgent intent. Here’s the playbook:

    • Set your after-hours attributes. Your GBP has hours fields most shops leave blank or set wrong. AI models check “open now” signals before recommending — a blank field reads as closed.
    • Build dedicated emergency service pages — one per emergency service, not a paragraph on your homepage. Format them as direct answers: what counts as an emergency, what you do first, typical response time, service area, then the phone number.
    • Answer the 2am questions explicitly. “Do you charge extra for after-hours calls?” “How fast can you get to [neighborhood]?” If your page answers them in plain sentences, the AI can quote them. If it doesn’t, the AI quotes whoever did.

    What trust signals make AI recommend a contractor?

    Here’s the qualification logic: an AI will not recommend a stranger to enter someone’s home unless it has reasons to trust. For the trades, those reasons are concrete — and almost nobody publishes them properly:

    • License numbers on every service page, not buried on a contact page. “WA Licensed General Contractor — license number in full” is an entity signal.
    • Insurance stated plainly — liability coverage and bonding, in sentences, not badges alone.
    • Trade certifications as trust qualifiers — IICRC for restoration, NATE for HVAC, EPA 608 for refrigerant work. These are the exact credentials a homeowner would want verified, which makes them exactly what the AI looks for.
    • Put them in schema too. Credentials in visible text get read; credentials in structured data get cited.

    Zero of the major guides on this topic mention licensing or certification. That’s your opening.

    What should a local business publish so AI cites it?

    “Structured local content publishing” is everyone’s advice and nobody’s architecture. Here’s the architecture: one quotable page per service per city you serve — the service × city citation matrix.

    • Each page answers one question completely: the service, the city, what it costs, how long it takes, what can go wrong.
    • Publish real price ranges. Every guide lists “how much does [service] cost in [city]?” as a top AI query — and none tell shops to answer it. The shop that publishes “water heater replacement in Tacoma — your real range, from your own invoices” becomes the citable source. Everyone else becomes invisible on the highest-intent question in the category.
    • FAQ schema on every matrix page. Direct-answer formatting: the question as a heading, the answer in the first two sentences, detail after.
    • Emergency variants get their own pages (see above) — don’t fold them into the standard service page.

    Are AI crawlers blocked from your site?

    Your site may be silently blocking the exact bots you need. Outdated robots.txt rules — written years ago to keep scrapers out — now block AI crawlers from reading your pages at all. The fix:

    • Explicitly allow GPTBot, ClaudeBot, PerplexityBot, and Google-Extended in robots.txt.
    • Don’t blanket-allow every bot on the internet — allowlist the AI crawlers by name, keep the rest of your rules intact.
    • Verify with a fetch test after the change. Thirty seconds of work, and without it, every other play on this list is muted.

    How do reviews get AI to recommend you?

    Google’s April 2025 Maps policy change killed scripted “mention my name in the review” requests. The shops still running that playbook are risking their profiles. The compliant system:

    • Ask “tell us about your experience,” not “leave us a review.” AI reads review text — “they replaced our water heater in under three hours” beats “great service” because it contains a service, a timeframe, and an outcome.
    • Time the ask: SMS or invoice link within 2 hours of job completion, while the details are fresh.
    • Engineer your owner responses as service + neighborhood + outcome triples: “Glad we could get the furnace running again for you in Lakewood — those January cold snaps don’t wait.” Every response is corroborating evidence the AI can use.
    • Review freshness is its own factor. A steady cadence beats a burst.

    How do you audit your AI readiness in 20 minutes?

    AI models cross-check you. Your reviews, your GBP, and your website need to tell the same story — same services, same service area, same phone number, same hours. When they disagree, the model loses confidence and picks someone else. The corroboration triangle audit, once a month:

    1. Read your last 10 reviews. Do the services mentioned match your GBP services list?
    2. Check your GBP hours, service area, and phone against your website footer and contact page.
    3. Search your business name plus your top service. Is the story consistent across the first page?
    4. Fix the mismatches. That’s the whole audit.

    Does each AI engine need a different approach?

    Yes. The models don’t work the same way, so don’t treat them the same. Same skeleton for each: what it trusts, then the one-line tactic.

    Gemini

    • What it trusts: live Google Maps data — profile accuracy runs near 100% because it’s grounded in Maps.
    • Tactic: GBP completeness and accuracy win here; treat your Business Profile as your Gemini homepage.

    ChatGPT

    • What it trusts: concise shortlists built from third-party corroboration — reviews, mentions, directory listings (profile accuracy here runs ~68%, so corroboration fills the gap).
    • Tactic: third-party mentions are what get you onto its shortlist; one strong source is never enough.

    Perplexity

    • What it trusts: live search with direct citations — freshness is the ranking input.
    • Tactic: recent reviews, recent posts, recently updated pages; stale content goes invisible fastest here.

    Copilot

    • What it trusts: Microsoft’s retrieval grounding — substantially the same answer logic as Bing’s AI surfaces.
    • Tactic: Bing Webmaster Tools verification plus the same fundamentals; what works for Perplexity-style freshness works here.

    Run the same tracked prompts across all four monthly and note who’s citing you and who isn’t. That’s your measurement system until you outgrow it.

    What does the first 90 days look like?

    Generic 90-day plans assume you’re a SaaS company. You’re not — you have seasons. Map the work to yours:

    • Days 1–30: Foundation. NAP audit, GBP completion, robots.txt allowlist, license/certification trust layer on every page, emergency pages live.
    • Days 31–60: Matrix. Build the service × city pages for your top 5 services, each with real price ranges and FAQ schema. Launch the review-text system.
    • Days 61–90: Seasonality. Publish ahead of your season — frozen-pipe content in December, AC tune-up FAQs in April, storm-season prep in late summer. The shop that publishes first becomes the cited source for the whole season.

    How can service businesses compete in crowded search markets?

    In crowded local search markets, traditional SEO forces service businesses into an expensive war of attrition over generic keywords like “plumber near me” or “roof repair.” In AI discovery, the game shifts from climbing a ranked list of ten blue links to qualifying as the safe, recommended answer an assistant gives when someone asks for help. In a 2026 benchmark across 350,000 business locations, ChatGPT recommended only 1.2% of locations while 35.9% appeared in Google’s local 3-pack, and only 12% of URLs cited by AI overlapped with Google’s top 10 results. Smaller service businesses compete and win in these crowded markets through specialization, verifiable proof, and high-intent urgency rather than broad domain authority:

    • Win the 2am emergency query: The highest-value AI query in the trades is not a generic category search; it is urgent intent (“emergency plumber near me open now” at 2am). Businesses win this ground by configuring after-hours attributes on Google Business Profile — which models check before recommending open providers — and publishing dedicated emergency service pages answering response times, coverage areas, and pricing directly.
    • Publish verifiable trust qualifiers on every page: AI models will not recommend a contractor to enter a home without explicit reasons to trust. While competitors bury credentials or rely on unindexed image badges, leading shops place license numbers in visible body copy and LocalBusiness schema (“WA Licensed General Contractor — license number in full”), state liability and bonding coverage plainly in sentences, and list trade certifications (such as IICRC, NATE, or EPA 608) as structured trust qualifiers.
    • Lock down the non-negotiable fundamentals: Inconsistent name, address, and phone (NAP) data cuts AI citation probability by 67%, while consistent omnichannel data delivers 3.2x visibility. A complete Google Business Profile lifts AI Overview appearances by 42%, creating the verified entity foundation that lets niche specialization beat larger, sloppier competitors.

    How do businesses improve visibility in AI-generated search results?

    Improving visibility in AI-generated search results requires shifting from keyword placement to a structured citation engine built around three core operational pillars:

    1. Explicit AI crawler access: Ensure your website is not silently blocking discovery bots. Outdated robots.txt rules frequently block AI systems from indexing local pages. Explicitly allowlist GPTBot, ClaudeBot, PerplexityBot, and Google-Extended by name in robots.txt so retrieval models can ingest your content.
    2. Publish a service × city citation matrix with real price ranges: Build dedicated, single-topic pages for each service and municipality you serve. Structure every page to answer one question completely: the specific service, the city, what it costs, how long it takes, and what can go wrong. Crucially, publish real price ranges (such as “water heater replacement in Tacoma — your real range, from your own invoices”) with FAQ schema and direct-answer formatting in the opening sentences. While competitors conceal pricing behind lead-capture forms, the shop providing factual ranges becomes the cited source the AI quotes.
    3. Engineer reviews as qualification filters: Because AI assistants read review text rather than merely counting star ratings, prompt customers with “tell us about your experience” within two hours of job completion while project specifics are fresh. Respond to every review with verified triples — service + neighborhood + outcome — providing corroborating training-adjacent evidence the model can synthesize.
    4. Track citations with engine-native trailing measurement: Treat AI visibility as a measurable rate rather than an impression count. As detailed in our guide on how we track AI citations, track grounding queries and citation shares across engines across trailing monthly windows, verifying which queries cite your pages rather than guessing from un-auditable third-party visibility scores.

    Why doesn’t my business appear when people ask AI for recommendations?

    When someone asks an AI assistant for a local contractor or service provider and your business is omitted, the cause is rarely bad luck or low search engine rankings. In AI discovery, 78% of local-services brands are invisible because assistants treat recommendations as a strict qualification filter rather than a ranked list. When an AI evaluates candidates to recommend, it checks verification and trust signals in a specific order of importance. If your business fails any of these gates, the model discards it in favor of a safer alternative:

    • Inconsistent NAP (Name, Address, Phone) data: Inconsistent contact information across major directories cuts your AI citation probability by 67%. When directory signals disagree, models cannot establish entity consensus and omit the business to avoid giving users erroneous contact details.
    • Incomplete business profiles and blank hours: An unoptimized or unclaimed Google Business Profile or Bing Places listing prevents models from validating basic operating details. In particular, leaving after-hours attributes blank causes models to read your business as closed during high-intent or emergency searches.
    • AI crawlers blocked in robots.txt: Outdated robots.txt rules designed to block web scrapers often silently block AI discovery bots. If GPTBot, ClaudeBot, PerplexityBot, or Google-Extended are blocked, the models cannot access or index your website pages.
    • Missing contractor trust credentials: AI assistants avoid recommending unverified providers for in-home work. Omitting state contractor license numbers from visible copy and LocalBusiness schema, failing to state liability insurance and bonding in plain sentences, or omitting trade certifications (such as NATE, IICRC, or EPA 608) removes the concrete qualifications assistants look for.
    • Thin service pages lacking real prices and direct answers: When service pages hide pricing behind generic forms and fail to answer common diagnostic and scope questions, the model has nothing factual to quote. The business publishing transparent price ranges becomes the cited source; businesses hiding them remain invisible.
    • Vague or stagnant review text: AI assistants parse the semantic text of customer reviews rather than star counts alone. Profiles with generic praise or stale feedback fail to provide the recent, service-specific and neighborhood-specific evidence models require to qualify a recommendation.

    What is answer engine optimization for local businesses?

    Answer engine optimization (AEO) for local businesses is the practice of structuring your company’s digital presence so AI assistants—such as ChatGPT, Copilot, Gemini, and Perplexity—can reliably verify your credentials and cite your business as a safe, direct recommendation. Unlike traditional SEO, which focuses on climbing a list of ten blue search links through generic keyword volume, local AEO focuses on entity qualification: ensuring that when a consumer asks a conversational question about a service in your city, the AI selects and names your business in its generated response.

    In practical terms, local AEO turns your website and public profiles into a machine-readable citation engine. This means configuring accurate business profile attributes, allowlisting AI discovery crawlers, adding LocalBusiness and FAQ schema, publishing transparent price ranges on dedicated service × city pages, and generating review text that corroborates your specific services, licensing, and service areas in the AI’s training-adjacent data.

    How do AI assistants choose which local businesses to recommend?

    AI assistants do not recommend local contractors based on traditional backlink tallies or keyword density. Because an assistant takes conversational responsibility for recommending someone into a consumer’s home, it applies a multi-stage qualification and trust-verification process:

    • Entity verification across directories: The model cross-checks public directories, Google Business Profile, and Bing Places to verify consistent NAP data. Consistent omnichannel data delivers 3.2x the AI visibility, while conflicting addresses or phone numbers trigger uncertainty that causes the model to omit the business.
    • Verification of machine-readable schema: The engine evaluates structured data on your website. LocalBusiness schema and FAQ schema (which increases citation probability 3.4x) provide machine-readable proof of services, service areas, and licensing credentials.
    • Qualification filtering through review text: The assistant treats customer reviews as a qualification filter rather than a simple ranking score. Instead of focusing solely on average star ratings (locations recommended by ChatGPT in large-scale benchmarks averaged 4.3 stars), the model scans review text for recent, specific mentions of completed services, timeframes, and neighborhood locations, corroborated by owner responses.
    • Direct answer extraction and pricing transparency: When an assistant constructs an answer, it prioritizes websites that state factual, direct answers to the user’s specific problem in the opening sentences—including realistic price ranges, emergency response times, and clear scope explanations.
    • Operational availability: For urgent or after-hours requests, the assistant checks confirmed hours attributes to verify that the business is actively available before presenting it as a solution.

    How do I get my local business cited by AI assistants like ChatGPT and Copilot?

    To get your local business cited by AI assistants like ChatGPT and Copilot, execute the playbook’s three core operational layers:

    1. Ensure AI crawler access: Check your robots.txt file to confirm you are not inadvertently blocking AI retrieval bots. Explicitly allowlist GPTBot, ClaudeBot, PerplexityBot, and Google-Extended by name so their search crawlers can read your site content.
    2. Establish the profile and directory trust layer: Maintain strict NAP consistency across all public citations. Claim and fully populate your Google Business Profile and Bing Places listings (crucial for Microsoft Copilot), setting complete hours, emergency attributes, and verified service categories. Add LocalBusiness schema to every page of your site embedding your state contractor license numbers and bonding coverage.
    3. Publish to be cited with a service × city matrix: Build dedicated pages for each service in each municipality you serve. Structure each page with direct-answer headings, FAQ schema, and published real price ranges (such as typical project cost bands) that models can quote verbatim. Pair this with a post-job review collection process that prompts customers to mention specific services and locations.

    To verify which models are recommending your business and track your citation share across monthly evaluation cycles, follow our step-by-step framework on how we track AI citations.

    How can a local business show up in AI companies?

    Showing up across products built by the major AI companies—including OpenAI (ChatGPT), Microsoft (Copilot), Google (Gemini and AI Overviews), and Perplexity—requires establishing machine-readable authority across three connected assets:

    • Allow the engines’ web crawlers: Confirm that your website’s robots.txt explicitly allowlists the primary AI crawler user-agents (GPTBot, ClaudeBot, PerplexityBot, and Google-Extended) so engines can retrieve your content.
    • Unify your public entity profiles: Keep your business name, address, phone number, and operating hours perfectly aligned across Google Business Profile, Bing Places, and core industry directories so algorithms find unanimous consensus.
    • Publish structured, quotable answers: Structure service pages as direct answers to customer questions, backed by LocalBusiness and FAQ schema, visible state licensing credentials, and transparent price ranges that AI engines can extract as authoritative answers.

    What should a local business include on its service pages for AI to recommend it?

    To qualify for AI citations and recommendations, each service page on your website should follow this structured architecture checklist:

    • Single-topic service × city focus: Build one dedicated page per service per municipality served (e.g., water heater replacement in Tacoma) rather than combining multiple trades or distant cities onto a single catch-all page.
    • Direct-answer opening: State the core question as an H2 heading, provide the direct answer in the first two sentences, and follow with practical supporting details so answer engines can lift the excerpt cleanly.
    • Real price ranges: Publish transparent price ranges (for example, “water heater replacement — your real range, from your own invoices”) directly on the page. AI models prioritize pages that answer cost queries with real numbers over competitor pages that conceal pricing behind contact forms.
    • Turnaround time and scope details: State how long the job typically takes, what steps are involved, what materials are standard, and common complications that homeowners should anticipate.
    • Visible licensing, bonding, and insurance: Display active state license numbers (e.g., “WA Licensed General Contractor — license number in full”), liability coverage, bonding status, and relevant trade certifications (NATE, IICRC, EPA 608) in plain body text.
    • LocalBusiness and FAQ schema markup: Embed structured data validating your entity name, address, telephone, license credentials, and question-and-answer pairs for direct machine parsing.
    • Dedicated emergency variant pages: If the service involves emergency scenarios (such as burst pipes or winter heating failure), build a separate emergency page detailing after-hours response times, service area limits, and after-hours fee policies.

    How can a plumbing company show up in AI answers?

    For a plumbing company to show up when homeowners query AI assistants for repairs and installations, apply the playbook’s emergency-query and structured-content principles:

    • Win the 2am emergency plumbing query: Configure after-hours attributes on your Google Business Profile so assistants verify that your business is open now during late-night emergencies. Publish dedicated emergency plumbing pages answering what qualifies as an emergency (such as burst pipes or sewer backups), immediate shutoff steps, typical arrival times, and whether you charge extra fees for after-hours calls.
    • Publish service × city pages with real price ranges: Build separate pages for high-intent plumbing jobs across your service territory (such as water heater replacement, drain clearing, or whole-house repiping). Include realistic price ranges in the opening sentences—such as publishing typical price spans for tankless versus standard water heater installations—paired with FAQ schema.
    • Display verifiable plumbing credentials: State your master plumber or state specialty contractor license numbers in visible body text and LocalBusiness schema, alongside bonding and liability insurance coverage.
    • Collect detailed review text and engineer responses: Prompt customers via SMS shortly after job completion to describe the specific plumbing repair, and reply with owner responses confirming the specific service, neighborhood, and outcome.

    How can an HVAC company get more leads from ChatGPT?

    An HVAC company can capture high-intent heating and cooling leads from ChatGPT by establishing seasonal authority, direct emergency answers, and verified technical credentials:

    • Publish ahead of seasonal weather shifts: Because AI assistants rely on indexed, authoritative content, publish seasonal content before demand spikes occur—such as heat pump and furnace emergency prep in autumn and AC maintenance and refrigerant troubleshooting FAQs in early spring. The company that publishes first establishes citation authority for the entire season.
    • Build dedicated emergency heating and cooling pages: Create separate emergency service pages for after-hours heating outages or severe heatwave AC failures. Answer urgent questions plainly: typical emergency dispatch times, service boundaries, after-hours diagnostics, and direct phone contact. Ensure after-hours attributes on your Google Business Profile are actively maintained so models recognize your availability.
    • Provide transparent HVAC pricing ranges: Answer category cost queries with realistic price ranges on specific service × city pages (such as furnace replacement, ductless mini-split installation, or heat pump repairs). Homeowners ask ChatGPT for expected equipment and installation costs; publishing factual ranges makes your site the cited source.
    • Highlight trade certifications and licensing: Feature active state contractor licensing, NATE certification, and EPA 608 certification prominently in body text and structured schema markup. These credentials signal verified technical safety, which AI assistants require before recommending a contractor.

    Frequently asked questions

    What is AI search visibility for a local business?

    It’s whether AI assistants — ChatGPT, Gemini, Perplexity — name your business when someone asks for a local service. Unlike Google rankings, there’s no position 4 to fall back on: either the AI recommends you or you’re not in the consideration set at all.

    How is AI visibility different from local SEO?

    Local SEO climbs a ranked list; AI visibility qualifies you as a safe recommendation. Only 12% of URLs cited by AI overlap with Google’s top 10 results (teehoomartech) — it’s a different ecosystem with different rules, and it’s 3 to 30 times harder to break into than the local 3-pack (SOCi, 2026).

    Do reviews really affect whether AI recommends my business?

    Yes — AI treats reviews as a qualification filter and reads the review text, not just the star rating. Review volume, recency, and specific language about services and outcomes all feed whether a model will name you.

    Should I block AI crawlers from my website?

    No — blocking GPTBot, ClaudeBot, PerplexityBot, or Google-Extended in robots.txt makes your pages invisible to the models deciding who to recommend. Allowlist the AI crawlers by name instead.

    How long does it take to build AI search visibility?

    Expect a 90-day foundation cycle: 30 days for fundamentals and crawler access, 30 for the service × city content matrix, 30 for seasonal content and review velocity. It’s ongoing work after that — freshness is a ranking input, not a one-time project.

    What’s the single highest-ROI move for a trade business?

    Publish real price ranges on service × city pages. “How much does it cost” is the top AI query in the category, almost nobody in the trades answers it, and the business that does becomes the cited source.

    What does done-for-you look like?

    Everything above is the playbook, free, on this page — that’s the point. If you’d rather have it built than build it, that’s what our AI Search Visibility Package does: the full citation work for your trade, measured the way AI measures it. Start with the $97 AI Citation Quick-Scan if you want to see exactly where you stand first — the $97 credits toward the package within 30 days.

    Want the deeper version — the robots.txt allowlist snippet, the per-engine prompt library for the monthly audit, and the seasonal content calendar template? That goes out by email. The playbook above is yours either way.
  • All My Reviews Just Say ‘Great Service’ — Do the Words in My Reviews Matter to AI?

    Short answer: Yes — the words matter more than the stars. When someone asks for “a reliable plumber who handles emergency leaks,” the AI recommends the business whose reviews keep saying “quick response” and “emergency repair” — not the one with fifty generic five-stars. Review text is the evidence the bot quotes. A wall of “great service” gives it nothing to quote.

    How the bot actually uses your reviews

    Think about what the AI is doing when it answers “who should I call.” It’s matching the words in the question to evidence it can find. If the question asks for emergency leak help, it looks for businesses with evidence of emergency leak help. And the richest source of that evidence isn’t your website copy — it’s your customers describing what you did, in their own words.

    One analysis of business profiles in AI search put it directly: “If a user asks for a ‘reliable plumber who handles emergency leaks,’ the AI will likely recommend a business whose reviews frequently mention ‘quick response’ and ’emergency repair’ over a business that simply has those terms in its meta description.” Businesses with specific, keyword-rich testimonials get cited more often than businesses with generic five-star ratings and no text.

    A review-industry breakdown this month named vague reviews as one of the three mistakes sending customers to competitors: “great service” instead of “same-day AC repair in Phoenix.” And review audits keep finding the same thing — AI answers quote review text verbatim. Your customers’ words become the bot’s answer.

    The star-rating trap

    Most owners chase stars. Stars are visible, countable, and feel like the scoreboard. But a five-star rating with no text tells the AI almost nothing — it’s a number without a story. Forty detailed reviews at 4.8 stars will beat a hundred empty five-stars, because the detailed reviews give the bot something to match against the question and something to quote in the answer.

    This is also why review platforms matter less than review content here. The question isn’t just where your reviews live — it’s whether the words in them describe the work you actually want to be recommended for.

    The review-request script (free, repeatable)

    You can’t write your own reviews. But you can ask for better ones — and most owners never do. After a job, when the customer is happy, ask them to mention two things: what you did and where. That’s it.

    “If you have a minute to leave a review, it really helps when folks mention the job — like the water heater swap — and the town. Just a sentence is perfect.”

    That’s the whole script. You’re not scripting fake reviews or stuffing keywords — you’re asking real customers to include the specifics they’d naturally mention anyway. “Mike replaced our water heater the same day it died, here in Mesa” is a quotable piece of evidence. “Great service!!” is not.

    What to actually do about it

    • Read your last twenty reviews. Count how many mention a specific job or a specific town. If the answer is “almost none,” you have the generic-review problem.
    • Start the two-thing ask this week. What you did, and where. Every finished job, every happy customer. It compounds.
    • Don’t neglect the unhappy ones. A detailed critical review is still evidence the bot reads — respond to it well, and the response becomes part of the record too.
    • Keep it honest. Never write reviews yourself, never pay for them, never hand customers pre-written text. The specifics have to be real — fabricated detail is both against every platform’s rules and, increasingly, detectable.

    What’s actually known — and what’s not

    Known: AI answers quote review text verbatim, and businesses whose reviews describe specific jobs in specific places get cited more often than businesses with generic ratings. The review-request script — ask for the job and the town — is a free, ownable fix no competitor can block.

    Not known: nobody has published a controlled test measuring naming rate against review-text specificity for trades businesses — the evidence is observational and mechanism-level, not a measured curve. What’s missing is someone running the test: same market, similar star counts, specific-text versus generic-text reviews, measured naming rates. That’s a test worth running.