Google shipped one of the most consequential AI Overviews updates of the year on May 6, 2026 — and most SEO teams still have not adjusted their content templates to match. The update changed what gets cited, where citations are drawn from, and how users decide which links to actually click. This is the practitioner walkthrough: what shifted, the data behind it, and the on-page changes that move the needle in the new system.
Forum and social perspective blocks — Overviews now embed direct quotes from Reddit, WordPress blogs, and public forums in a dedicated “perspectives” section.
Subscription-aware citation highlights — links from news outlets the searcher is logged in to are visually flagged. Google’s internal test data showed those flagged links were “significantly more likely” to be clicked.
Suggested exploration topics — bulleted follow-up queries now render at the end of many AI responses, which means downstream traffic flows depend on whether your domain ranks for the fan-out queries, not just the head term.
Further Exploration section — a bulleted-link cluster plus an “Expert Advice” snippet pulling from articles, reviews, and forum threads.
Hover-to-preview link cards — hovering a citation now triggers a card showing site name, page summary, and metadata before the click.
Two of those five — perspectives blocks and Further Exploration — are net-new citation slots. The other three change which citations users actually convert on.
The Citation Math Has Shifted
The citation math has shifted.
The most important measurement from the last 60 days: in March 2026, the share of AI Overview citations pulled from pages ranking in Google’s organic top 10 dropped to 38%, down from 76% in July 2025 (500M-keyword analysis). 31% of cited sources now rank in positions 11–100, and another 31% rank outside the top 100 entirely for the query they get cited on.
Translation for practitioners: Overviews are no longer a rank-amplifier. They are an independent retrieval layer. A page that ranks #47 with the right passage structure can outcompete a page that ranks #3 with the wrong structure. Domain Authority correlation with citation selection is now r=0.18 — effectively noise. Semantic completeness correlation is 0.87.
The Passage That Gets Cited
AI Overview extracts cluster tightly around 134–167 words per passage, with 62% of featured content falling in the 100–300 word range. Position inside the article matters: 44.2% of citations are pulled from the first 30% of the body, 31.1% from the middle, 24.7% from the conclusion (Wellows ranking factor study). Lead-heavy structure is no longer a copywriting preference — it is the extraction surface.
The structural pattern that wins, repeatable across H2 sections:
<h2>[Specific question phrased as a noun phrase]</h2>
<p><strong>[One-sentence direct answer with a named entity or number.]</strong></p>
<p>[Supporting detail with verifiable source attribution.]</p>
<p>[Nuance, caveat, or contrast — kept under the 167-word ceiling.]</p>
Each H2 block becomes a standalone extractable unit. If your article only answers the headline question, you compete for one citation. If five H2 blocks each answer a distinct fan-out question, you compete for five.
Schema That Earns Citations Now
Properly marked-up pages show 73% higher selection rates in AI Overviews versus unmarked content. The three schema types doing the most work in the May 2026 surface:
FAQPage — feeds the Further Exploration section directly. Each Question/Answer pair is treated as a passage candidate.
Article with author and datePublished — freshness is now a citation factor. Content under three months old is 3× more likely to be cited.
HowTo with step-level markup — extracted into the Expert Advice snippet when the query is procedural.
A minimal Article block that hits the freshness and authorship signals Google’s extractor now reads for:
The forum-quote section is the biggest opportunity nobody is optimizing for yet. Reporting from TechCrunch’s coverage of the rollout confirmed Google is pulling from Reddit, public forums, and WordPress blogs explicitly tagged as personal perspective.
Three practitioner moves:
Author bylines with first-person framing on at least one article per topic cluster. Personal-perspective phrasing (“In our deployment of …”, “What surprised us was …”) signals firsthand experience to the extractor.
Engage in the relevant subreddit with substantive comments under your real handle, then link your bylined article from your profile. Reddit threads are now a primary retrieval source for perspectives blocks.
Tag personal-perspective posts with Person schema alongside Article schema. The Person entity is what Google ties to the firsthand-experience signal.
What to Measure Starting This Week
What to measure starting this week.
Citation share by query is the only metric that matters in this surface, and traditional analytics will not give it to you. Two practitioner approaches:
Manual citation logging — pull your 20 highest-value head terms and 50 fan-out queries, query them weekly in an incognito session, log whether your domain appears in the Overview, the perspectives block, or the Further Exploration list. Track citation share, not just rank.
Server-log analysis — Google’s Overview generator hits your pages with a distinct user agent and crawl signature. Filtering for those signatures gives you a leading indicator: pages getting hit by the extractor are pages being evaluated for citation.
Cited pages earn 35% more organic clicks and 91% more paid clicks than uncited peers (Averi.ai citation study). Uncited pages on triggering queries lose 61% of their normal CTR. The gap between cited and uncited is now wider than the gap between position #1 and position #5 in classical SEO. Treat citation as the primary KPI.
The Update in One Sentence
Google has decoupled AI Overview citation from organic rank, opened two new citation slots (perspectives and Further Exploration), and is now rewarding firsthand-experience signals at the page and author level — the practitioners who restructure for passage-level extraction and earn citation in the new slots will pick up the traffic that used to flow to position-#1 pages.
If you publish an llms.txt file this week, no major model is going to fetch it tonight. That is the honest 2026 read on the spec — and yet the file is still worth shipping for narrow, specific reasons. This guide covers the 4-element specification published at llmstxt.org, the robots.txt pairing that actually controls AI crawler behavior right now, and a server-log filter you can run to verify whether anyone is reading the file you just shipped.
What llms.txt actually is (and what it isn’t)
What llms.txt actually is — and isn’t.
llms.txt is a Markdown file served at the site root — /llms.txt — proposed by Jeremy Howard of Answer.AI on September 3, 2024. The spec at llmstxt.org defines four elements: a required H1 with the project or site name; a blockquote summary; zero or more Markdown content sections (no headings); and zero or more H2-delimited file-list sections containing annotated Markdown links to deeper content. That is the entire specification. There is no header convention, no schema requirement, no robots-style allow/deny syntax.
What llms.txt is not: it is not a substitute for robots.txt, it is not an access-control mechanism, and as of May 2026 it is not consumed at inference time by ChatGPT, Claude, Gemini, Perplexity, or Copilot in any documented production system. Server-log audits across multiple independent practitioners show GPTBot, ClaudeBot, and Google-Extended do not request /llms.txt in meaningful volume during routine crawls.
The realistic 2026 use case is developer tooling. AI coding assistants and IDE agents — Cursor, GitHub Copilot, Claude Code, and similar tools — retrieve docs in real time, and a curated llms.txt cuts token waste by pointing them at canonical Markdown sources instead of HTML-rendered pages bloated with nav and tracking. Companies like Anthropic, Stripe, Cursor, Cloudflare, Vercel, Mintlify, Supabase, and LangGraph ship llms.txt for that reason.
The 4-element template — a working example
Here is a real, valid llms.txt for a hypothetical SaaS docs site. Copy this structure, change the project name, and you have a shippable file in under 30 minutes:
# Acme Analytics

> Acme Analytics is a self-hosted product analytics platform for SaaS teams. This file points AI assistants and IDE agents at canonical Markdown documentation, not the rendered HTML.

Authoritative Markdown sources for product, API, and SDK documentation. Use the `.md` variant of any docs page (append `.md` to the URL) for a clean, agent-friendly version.

## Getting Started

- [Quickstart](https://acme.example/docs/quickstart.md): 10-minute setup, install through first event.
- [Concepts](https://acme.example/docs/concepts.md): events, properties, identities, sessions — definitions and examples.

## API Reference

- [REST API Reference](https://acme.example/docs/api/rest.md): every endpoint, request/response schema, rate limits.
- [Webhook Reference](https://acme.example/docs/api/webhooks.md): payload contracts and retry behavior.

## SDKs

- [JavaScript SDK](https://acme.example/docs/sdk/js.md): browser and Node, including server-side rendering notes.
- [Python SDK](https://acme.example/docs/sdk/python.md): server-side ingestion patterns.

## Optional

- [Changelog](https://acme.example/docs/changelog.md): version history, breaking changes flagged inline.
Two practitioner notes. First, the spec uses an “Optional” H2 as a soft signal — links under that heading can be skipped by aggressive token budgets. Second, the file is most useful when every linked URL has a parallel .md Markdown version. If your site is pure HTML, llms.txt without paired Markdown does little.
The robots.txt pairing — this is what actually controls AI bots today
robots.txt pairing — what controls AI bots today.
The lever that meaningfully controls AI crawler behavior in 2026 is robots.txt with user-agent–specific rules. Anthropic publishes official documentation for three bots — ClaudeBot for training, Claude-User for user-initiated fetches, and Claude-SearchBot for search indexing — and confirms all three honor robots.txt. OpenAI runs GPTBot (training) and OAI-SearchBot (live ChatGPT search). Google’s AI training opt-out is the Google-Extended user-agent. Perplexity uses PerplexityBot.
The two-bucket pattern most practitioner sites should ship: block training-only crawlers, allow search and user-initiated retrieval so your content can still be cited in answers.
One operational caveat: robots.txt is policy, not enforcement. Anthropic, OpenAI, and Google have all publicly committed their named bots to compliance, but unnamed scrapers and residential-IP harvesters routinely ignore it. For sites with sensitive content, pair robots.txt with WAF or Cloudflare bot-management rules at the edge.
Structured data still does more heavy lifting than llms.txt
If your goal is AI citation rather than IDE-agent retrieval, structured data on the page itself moves the needle more than llms.txt. The minimum stack for any article you want cited: Article schema with named author and publisher, FAQPage schema on any post that answers a discrete question, and speakable markup on the answer paragraphs. These get parsed during normal HTML fetches by every major AI crawler — no separate file required.
How to verify your llms.txt is actually being read
How to verify llms.txt is being read.
Ship the file, then run this server-log filter weekly for 30 days. On any standard access-log format (nginx, Apache, or a Cloudflare log push), grep for requests to /llms.txt and break them down by user-agent:
What you will almost certainly see in May 2026: a steady trickle of human curl requests, the occasional IDE agent fetch tagged with a Cursor or VS Code user-agent, and effectively zero hits from GPTBot, ClaudeBot, or Google-Extended. That null result is itself the measurement — it tells you llms.txt is a developer-experience asset right now, not an AI-citation asset, and your investment should match that reality.
The recommended 2026 rollout
For most sites, the right sequence is: ship the robots.txt user-agent rules above first, because those are enforceable today and shape every AI crawler interaction. Add structured data to every article that competes for AI citation. Then publish llms.txt — under 30 minutes of work — for the IDE-agent and dev-tooling upside, with no expectation of immediate search lift. When OpenAI, Anthropic, or Google publicly confirm production llms.txt consumption, you are already in position.
Most GEO and AEO case studies you can find online are vendor-published and short on implementation detail. So instead of stacking another “look at this 300% lift” headline, this piece walks through five publicly documented results from 2026 — and pulls out the structural change that actually drove the win in each one. If you want to copy what works, copy the structure, not the percentage.
1) HubSpot: 3x lead conversion from AEO traffic
Case patterns: what actually worked in GEO/AEO.
HubSpot’s own 2026 State of Marketing reporting found 58% of marketers saying AI-referred visitors convert at higher rates than traditional organic, with HubSpot itself reporting roughly 3x better lead conversion from AEO sources versus other channels. The implementation pattern across HubSpot’s blog: question-led H2s, a 40–60 word direct answer in the first paragraph below the heading, then expanded context, then a structured FAQ block with FAQPage schema.
The before/after isn’t “more content.” It’s “the same content, restructured so the answer arrives in the first 60 words.” That single edit is what featured snippets and AI Overviews both reward.
Zero-click visibility lifts without chasing vanity traffic.
Hashmeta documented a 50% increase in zero-click visibility for an e-commerce client after a targeted AEO sprint. The lever: rebuilding product and category pages around explicit question intent (“what is the difference between X and Y,” “is X worth it for Z use case”) and adding HowTo and FAQPage schema. The page didn’t get more traffic from the same query — it started winning the answer position on related queries it wasn’t competing for before.
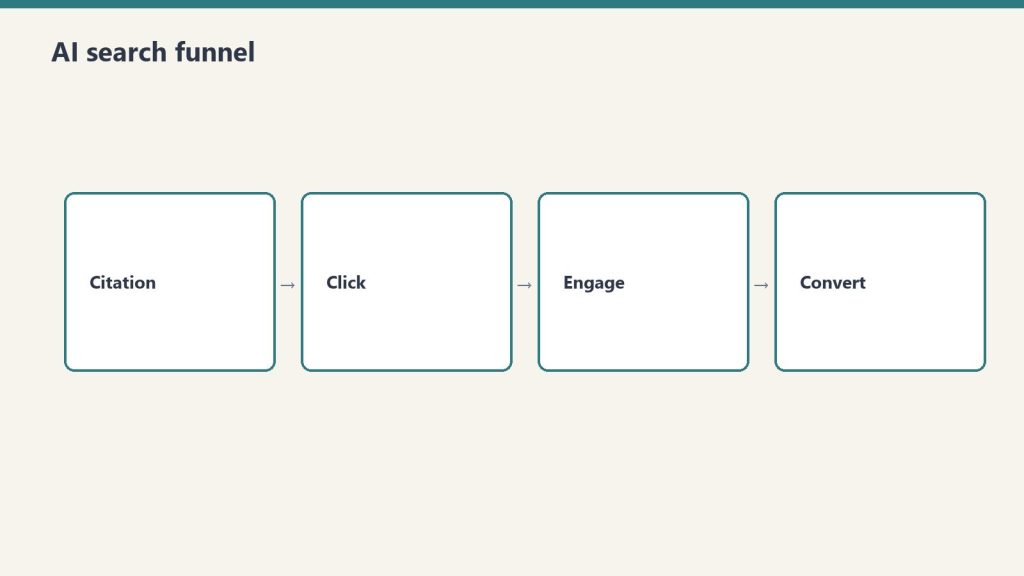
The takeaway for practitioners: zero-click visibility is its own funnel. Track it separately from sessions, because the value shows up in branded search lift two to four weeks later, not in same-day clicks.
3) SaaS brand: 20+ free-trial signups per month from ChatGPT citations
ChatGPT citations can create free-trial demand.
One SaaS case study circulating in the GEO community in early 2026 reported 20+ free-trial signups per month attributed directly to ChatGPT citations, identified via a unique UTM and a referral-source filter in their analytics. The structural pattern: a single canonical comparison page per top competitor, written as a third-person reference rather than first-person marketing, with a clear definition block, a structured comparison table, and a “when to choose X” section.
This is the format ChatGPT cites because it’s the format ChatGPT was trained to produce. Match the output shape and you become the source.
4) Generic brand study: 140% lift in AI-driven search traffic
A widely cited 2026 GEO case study reported a 140% increase in LLM and AI-driven search traffic alongside a 62% rise in AI mentions after a strategy that prioritized entity saturation, internal-link clustering, and structured data over keyword density. The implementation detail worth copying: a single hub page per entity with at least 15 distinct factual data points, then 8–12 supporting articles linking back to it with descriptive anchor text.
The 15-data-point threshold matches what GEO researchers have flagged repeatedly: articles with 15+ verifiable data points receive substantially more AI citations than articles with fewer than five.
5) Mangools: featured-snippet capture from a single edit
Mangools published a walkthrough showing how rewriting one blog post to lead with a 50-word direct answer captured a featured snippet for a head-term query, with the resulting traffic and brand exposure outpacing the rest of the content cluster. No new backlinks, no new content — just a structural rewrite of the first 100 words.
The pattern across all five
Every win has the same shape: question-led H2, 40–60 word direct answer, structured supporting content, schema markup. Here is the minimum viable AEO block, drop-in ready:
<h2>What is generative engine optimization?</h2>
<p><strong>Generative engine optimization (GEO) is the practice of structuring web content so AI systems like ChatGPT, Claude, Gemini, and Perplexity cite it as a source.</strong> Unlike SEO, which optimizes for ranking in a list of links, GEO optimizes for being included in a generated answer. The core levers are entity clarity, factual density, structured data, and crawlability via LLMs.txt and robots.txt.</p>

<script type="application/ld+json">
{
  "@context": "https://schema.org",
  "@type": "FAQPage",
  "mainEntity": [{
    "@type": "Question",
    "name": "What is generative engine optimization?",
    "acceptedAnswer": {
      "@type": "Answer",
      "text": "Generative engine optimization (GEO) is the practice of structuring web content so AI systems cite it as a source in generated answers."
    }
  }]
}
</script>
The measurement layer
None of these case studies mean anything without isolation. The minimum tracking stack: a referrer filter for chatgpt.com, perplexity.ai, claude.ai, gemini.google.com, and copilot.microsoft.com in GA4; a separate event for zero-click impressions from Google Search Console; and a manual citation log — query a representative model with your top 25 prompts weekly and record whether your domain is cited. The third one is what most teams skip, and it’s the only one that tells you whether GEO is working before traffic shows up.
What to copy this week
Pick your top five highest-intent pages. For each one, rewrite the first 100 words as a direct-answer block, add a single FAQPage schema with three questions, and add the page to your LLMs.txt manifest. That is the entire implementation. Every case study above is a variation on those three moves.
Updated November 2, 2026 — added direct answers on competitor benchmarking, audit cadence, and citation drop diagnosis, from our own published measurement.
Direct Answer: Measure LLM visibility with five metrics—citation frequency, prompt coverage, share of voice, AI referral sessions, and conversion quality from that traffic. Pair a monthly 20-prompt audit with GA4: use Google’s May 2026 “AI Assistant” channel where it applies, plus a custom channel group (regex on session source, ordered above Referral) so Perplexity and historical sessions don’t stay buried in Referral or Direct.
Most SEO teams know they need to care about AI search. Almost none of them have a measurement system in place for it. That’s the gap this article closes.
Ranking in ChatGPT, Perplexity, Google AI Overviews, or Claude isn’t a vanity metric anymore — it’s a traffic channel. But unlike Google, AI systems don’t serve a results page you can screenshot. They weave citations into prose. Your brand either shows up in that prose or it doesn’t, and if you’re only watching default GA4 channel reports, you’re flying mostly blind.
This is a practitioner’s setup guide: the exact metrics, GA4 configuration, and tool stack needed to track LLM visibility systematically — including how to define AI citation rate before you buy software.
The Five Metrics That Define LLM Visibility
Five metrics that define LLM visibility.
Traditional SEO tracks ranking position, impressions, and clicks. None of those exist in AI search. You need a new metric set:
Citation frequency — How often your domain or brand is mentioned in AI-generated answers for your target query set. LLMs typically cite a handful of sources per response. Capturing one of those slots consistently is the entire game.
Prompt coverage — Out of your tracked prompt library, what percentage of prompts return your brand at all? Calculate it as: (prompts where you appear ÷ total tracked prompts) × 100. A brand actively optimizing for AI search should be above 40% coverage on tier-1 prompts within 90 days of focused content work.
Share of voice — For a given topic cluster, how often do AI answers cite you versus competitors? If you appear in 12 of 30 tested prompts and a competitor appears in 20, they hold 67% share of voice on that topic. That ratio is more strategically meaningful than any single citation count.
AI referral sessions — The sessions in GA4 that arrived from an AI platform with a usable referrer header (or GA4’s native AI Assistant classification). This is the metric that ties visibility to business outcomes. Setup is covered in the next section.
Conversion quality from AI traffic — AI-referred visitors often arrive with higher intent: they asked a specific question and your site was the answer. Track engagement rate, pages per session, and goal completions for AI referral sessions separately. If this cohort converts at 2–3× the rate of your organic traffic — which early practitioner data suggests — it changes how you think about GEO investment.
Setting Up GA4 to Capture AI Traffic
GA4 regex to capture AI traffic.
Native AI Assistant channel (May 2026)
Since May 13, 2026, GA4’s default channel group includes an AI Assistant channel. When Google recognizes an assistant referrer, it sets medium ai-assistant. You will see it under Reports → Acquisition → Traffic acquisition. That is progress, but it is not a complete LLM visibility stack: Perplexity commonly still lands in Referral, assistant coverage in Google’s list changes, and clicks from Google AI Overviews or AI Mode still arrive as google.com — they stay in Organic Search, not AI Assistant.
Custom channel group and regex
For Perplexity, legacy referrers, and retroactive reporting, build your own group. In GA4: Admin → Data Display → Channel Groups → Create New Channel Group. Name it “AI Search” and add a rule:
Critical step: Place “AI Search” above “Referral” (and treat order as first-match-wins). If Referral appears first, Perplexity and other assistant referrers never reach your AI rule. Custom channel groups can be applied retroactively in reports; the native AI Assistant channel does not backfill history the same way.
Scope caveat: Many assistant-driven visits still arrive without a referrer — mobile apps, in-app browsers, and privacy modes send them to Direct or (not set). Your AI channel captures the visible minority. Don’t benchmark on absolute volume alone. Benchmark on growth rate, and watch Direct only when other signals line up.
To supplement GA4, add a self-reported source question on high-intent forms: “How did you find us?” Include “ChatGPT / AI assistant” as an option. That gives ground truth session data cannot.
The Tool Tier: Free to Enterprise
The LLM visibility tool market matured through 2025 and 2026. Three tiers cover most teams. Start manual before you pay — the same discipline described in our AI citation monitoring guide applies whether you use a spreadsheet or a dashboard.
Free / DIY — start here
Run 20 representative prompts manually across ChatGPT, Perplexity, Claude, and Google AI Overviews each month. Record mentions in a spreadsheet: cited (yes/no), cited with link (yes/no), competitor named instead. That gives you baseline prompt coverage and share of voice with zero budget. Do it for at least one month before buying software — you’ll know which gaps actually hurt.
Mid-market tools (roughly $30–$500/month)
OtterlyAI runs scheduled prompt sets and tracks brand mentions, cited URLs, and share of voice. Published USD pricing starts at $29/month (Lite, 15 prompts); Standard is $189/month (100 prompts); Premium is $489/month (400 prompts). ChatGPT, Google AI Overviews, Perplexity, and Copilot are included; Google AI Mode, Gemini, and Claude are add-ons. Enterprise starts around $1,000/month.
LLMrefs takes a keyword-first approach: import SEO keywords, and the platform generates prompt fan-outs and refreshes visibility on a schedule — closer to a rank tracker than a blank prompt spreadsheet. Useful when your team already thinks in keyword lists rather than conversational prompts.
Enterprise layer ($1,000+/month)
Profound centers on Prompt Volumes — modeled demand from real answer-engine conversations (ChatGPT, Gemini, Claude, Perplexity). It helps you prioritize which questions deserve content before you commit headcount. Valuable at scale; overkill for a single-location operator on the 20-prompt audit. Pair it with playbooks such as the GEO case studies series when you need proof the numbers moved.
The 20-Prompt Audit: Your Monthly Baseline Protocol
Whether you use a paid tool or not, run this protocol monthly:
Build a prompt library of 20 questions your target buyer would ask an AI system. These should be questions your content is designed to answer — not keyword-stuffed phrases, but real conversational queries.
Run each prompt across ChatGPT, Perplexity, and Google AI Overviews (3 platforms × 20 prompts = 60 data points per month).
For each result, record: was your brand cited in text, was your domain linked, and which competitor was cited if you were not.
Calculate prompt coverage per platform and total share of voice versus your top three competitors.
Log results in a spreadsheet with a date column. Three months of data reveals directional trends — whether your GEO and AEO work is moving the needle. Longitudinal baselines also make experiments legible; structured publishing tests (for example, the 40-article Bing citation experiment) only pay off when you can compare citation rates month over month.
How do I benchmark my AI visibility against competitors?
To benchmark your AI visibility against competitors, measure your citation rate against named rivals across a fixed, controlled prompt set rather than chasing broad keyword rankings. Run your core buyer prompts across the major AI search surfaces (ChatGPT, Perplexity, and Google AI Overviews). For each response, log whether your domain was cited in the text or footnotes, and record which competitors took the remaining citation slots. Your competitive benchmark is your share of authority—also called share of voice—which is the percentage of total citations on that prompt set awarded to your domain versus competing sources. Tracking this metric across monthly evaluation runs reveals whether your content is displacing rivals in finite answer slots or losing ground.
How often should I check my AI visibility?
Check your AI visibility monthly. A monthly cadence using a consistent prompt library of 20 conversational buyer queries across three major engines (generating 60 data points per cycle) provides the minimum sample size needed to detect genuine shifts in prompt coverage and share of voice. Weekly spot checks are useful only for immediate post-deployment verification or crisis audits; monthly logging over a trailing 90-day window filters out algorithmic noise, accounts for crawler refresh latency, and reveals true directional trends.
Diagnosing a Citation Drop
Diagnosing a citation drop.
If your monthly audit shows prompt coverage declining, run through this checklist before blaming a black-box algorithm change:
Did you remove or restructure a previously cited page? AI systems build representations of your content over time. Pages that disappear or get heavily rewritten lose citation weight. Check your changelog against the prompts that declined.
Did a competitor publish stronger content on the topic? Citation slots in a single answer are finite. If a competitor shipped a more authoritative page, it may have displaced yours. Review their recent publishing calendar.
Check LLMs.txt and robots.txt. A crawlability block in LLMs.txt or a misconfigured Disallow directive cuts AI access at the source. Verify both files allow the URLs you expect to be cited.
Check for a platform or model update. Major chatbot and search-model releases in 2025–2026 shifted which sources each engine trusted. Read the platform’s public changelog for the period in question.
If none of these apply, audit structured data on the pages that lost citations — schema, FAQ blocks, heading hierarchy, and factual density all affect extraction. A redesign that removed an FAQ block can remove your citation utility in the same deploy.
Why does AI cite my competitor but not me?
Citation slots in an AI-generated answer are finite. When an AI assistant cites a competitor instead of your domain on a query your business is qualified to answer, evaluate the cause using this diagnostic checklist in order:
Competitor content density: A rival published a more comprehensive, factually dense, or directly structured answer that displaced your page in limited citation real estate.
URL removals or restructuring: A previously cited page on your domain was renamed, relocated, or substantially rewritten, disrupting accumulated citation authority.
Crawlability directives: Check your robots.txt and LLMs.txt files to ensure crawler access has not been restricted by unintended Disallow rules.
Assistant and model releases: Major platform and underlying model updates frequently alter source-weighting criteria across AI engines.
Extraction utility: Review structured data, schema markup, FAQ blocks, and heading hierarchy on the target URL; removing an FAQ section or answer block during a redesign can strip away machine extractability.
The Bottom Line
LLM visibility measurement is not solved, but the primitives exist: GA4’s AI Assistant channel plus a custom regex group for traffic, manual prompt audits for citation coverage, and mid-market tools when labor becomes the bottleneck. Operators who need a packaged starting point can map the same metrics to a vertical playbook such as the AI search visibility package for water damage — the measurement layer stays identical even when the prompts change.
Build the 20-prompt library this week. Configure GA4 today. Everything else stacks on those two streams.
FAQ
What is LLM visibility? LLM visibility is how often your brand or domain appears in AI-generated answers — in the prose, in linked citations, or both — for the questions your buyers ask. It is the AI-search equivalent of showing up on page one, except there is no single rank number to screenshot.
Does GA4 automatically track ChatGPT and Perplexity traffic? Partially. Since May 2026, GA4’s AI Assistant channel classifies some assistant referrers with medium “ai-assistant.” Perplexity often remains Referral, AI Overview clicks stay Organic, and no-referrer visits stay Direct. A custom “AI Search” channel group with a source regex — placed above Referral — is still required for complete trending.
How often should I run a prompt audit? Monthly is the minimum useful cadence. Run the same 20 core prompts each cycle so prompt coverage and share of voice are comparable. Weekly spot checks are fine for crisis monitoring, but monthly logging is what builds a baseline.
What is the difference between prompt coverage and share of voice? Prompt coverage is the share of your tracked prompts where you appear at all. Share of voice compares how often you appear versus named competitors across that same prompt set. High coverage with low share of voice means you show up, but rivals dominate the answers.
Do I need a paid tool to measure AI citations? No. A spreadsheet and 60 manual checks per month (20 prompts × three platforms) are enough to start. Paid tools mainly automate scheduling, add engines, and export reports once you know which prompts and competitors matter.
Why would AI citations drop suddenly? Common causes are URL removals or restructures, stronger competitor pages, crawl blocks via robots.txt or LLMs.txt, or model updates on the assistant platform. Rule those out before you assume your entire GEO strategy failed.
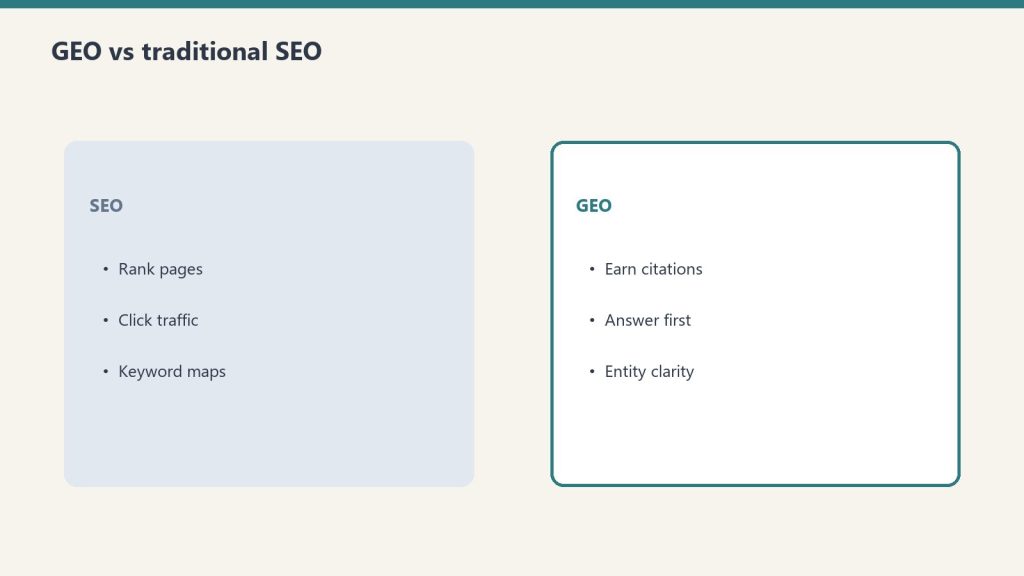
If you’ve optimized content for Google and still can’t get AI systems to cite you, you’re running the wrong playbook. GEO — Generative Engine Optimization — is the discipline of making your content visible, credible, and citable to AI engines like ChatGPT, Claude, Perplexity, Gemini, and Google’s AI Overviews. It is not SEO with a new name. It is a different game with different rules.
Definition: Generative Engine Optimization (GEO) is the practice of structuring content so that large language models and AI search engines select it as a source when generating responses to user queries. Where SEO earns rankings, GEO earns citations.
Why GEO Is Not SEO
Why GEO is not SEO.
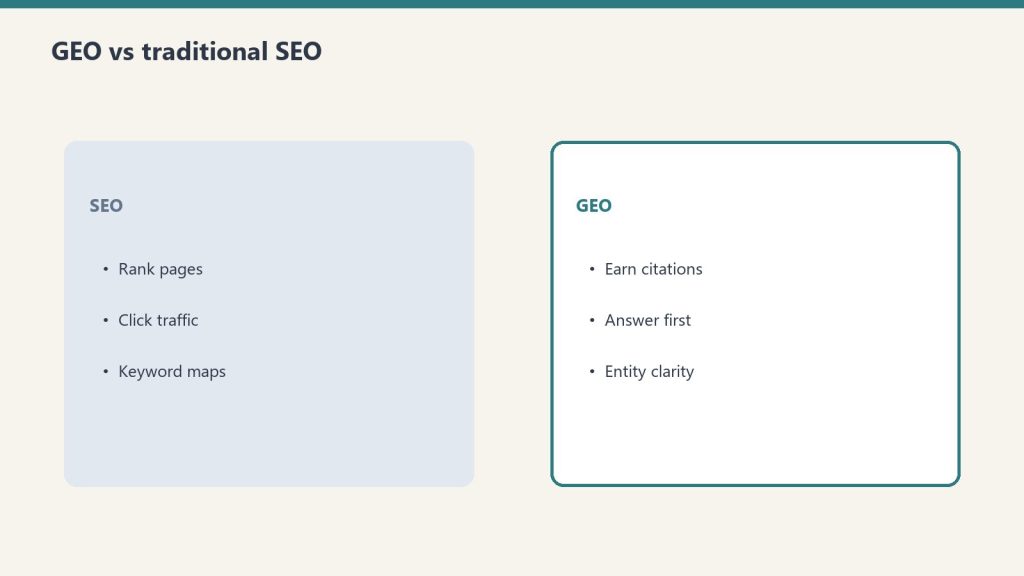
SEO is about ranking. You optimize a page so Google’s algorithm surfaces it when someone searches. The goal is a click. GEO is about being quoted. You structure content so an AI system trusts it enough to pull a fact, a definition, or an explanation from it when synthesizing a response. The user may never click your URL — but your content shaped what they read.
The mechanisms are fundamentally different. Google’s ranking algorithm weighs hundreds of signals — backlinks, page speed, user behavior, authority. AI citation selection weights entity density, factual specificity, source credibility signals, and structural clarity. A page that ranks #1 on Google may get zero AI citations. A page that ranks #8 may be the one Perplexity quotes every time someone asks about that topic.
How AI Engines Select Content to Cite
How AI engines select content to cite.
Large language models used in AI search (GPT-4, Claude, Gemini) were trained on large corpora of text, but the retrieval-augmented generation (RAG) layer that powers tools like Perplexity, ChatGPT search, and Google AI Overviews works differently. It pulls live content at query time, scores it for relevance and credibility, and synthesizes a response. The signals it uses to score your content include:
Entity clarity — Are the people, places, companies, and concepts in your content clearly named and linked to known entities?
Factual density — Does your content contain specific, verifiable claims rather than vague generalities?
Structural legibility — Can the AI parse your content’s structure — headings, definitions, lists — without ambiguity?
Source signals — Does your content cite primary sources, studies, or named experts?
Speakable schema — Have you marked up key paragraphs as machine-readable answer candidates?
The Three Layers of GEO
Three layers of GEO — structure, entity, proof.
Layer 1: Content Architecture
GEO-optimized content is built for extraction, not just reading. That means every major claim is in a standalone sentence. Definitions appear near the top. Section headers are declarative, not clever. The structure tells an AI where the answer is before it has to read the full article.
Layer 2: Entity Saturation
AI systems understand content through entities — named people, organizations, places, products, and concepts that exist in their training data. A GEO-optimized article saturates relevant entities: it doesn’t say “a major AI company” when it means Anthropic. It doesn’t say “a popular search tool” when it means Perplexity. Every entity is named, spelled correctly, and used in the right context.
Layer 3: Schema and Structured Data
JSON-LD schema markup is a signal to both traditional search engines and AI crawlers. FAQPage schema makes your Q&A content directly extractable. Speakable schema flags the paragraphs most useful for voice and AI synthesis. Article schema establishes authorship and publication date. These are not optional extras — they are the machine-readable layer that gets your content selected.
GEO vs AEO: What’s the Difference?
Answer Engine Optimization (AEO) focuses on winning featured snippets, People Also Ask boxes, and zero-click search results in traditional search engines. GEO focuses on being cited by generative AI systems. The tactics overlap — both require clear structure, direct answers, and FAQ sections — but the targets are different. AEO wins position zero on Google. GEO wins the paragraph that Perplexity writes for the next million queries on your topic.
At Tygart Media, we run both in parallel. The content pipeline produces articles that pass the AEO gate (featured snippet structure, FAQ schema) and the GEO gate (entity density, speakable markup, citation-worthy claims) before publishing.
What GEO Looks Like in Practice
Here is the difference between a standard paragraph and a GEO-optimized version of the same content:
Standard: “Water damage restoration is an important service for homeowners who have experienced flooding or leaks.”
GEO-optimized: “Water damage restoration — the professional remediation of structural damage caused by flooding, pipe failure, or storm intrusion — is performed by IICRC-certified contractors following the S500 Standard for Professional Water Damage Restoration. The process includes water extraction, structural drying, moisture monitoring, and antimicrobial treatment.”
The second version names the certifying body (IICRC), the standard (S500), and the process steps. An AI system can extract that paragraph as a factual, citable answer. The first version has nothing to extract.
How to Start with GEO
If you’re running an existing content operation and want to layer in GEO, the priority order is:
Audit your top 20 pages for entity gaps — everywhere you use vague references, replace with specific named entities
Add speakable schema to your three strongest definitional paragraphs per page
Run a factual density check — every statistic should have a source, every claim should be specific
Add FAQPage schema to any page with question-format headings
Submit your top pages to Google’s Rich Results Test and verify structured data is reading cleanly
GEO Is Compounding Infrastructure
The reason GEO matters for content operations is compounding. Once an AI system has indexed and trusted your content as a reliable source on a topic, subsequent queries on that topic draw from your content repeatedly — without you publishing anything new. A single GEO-optimized pillar article can generate thousands of AI citations over 12 months. That is a different kind of ROI than a ranked page that gets clicked and forgotten.
We built the Tygart Media content stack around this principle. Every article that leaves our pipeline passes a GEO gate before it publishes. That gate checks entity saturation, factual specificity, schema completeness, and structural legibility. It is the same gate we build for clients.
Frequently Asked Questions About GEO
What does GEO stand for?
GEO stands for Generative Engine Optimization — the practice of optimizing content to be cited by AI-powered search systems and large language models.
Is GEO the same as SEO?
No. SEO (Search Engine Optimization) targets traditional search rankings. GEO targets AI citation in tools like ChatGPT, Perplexity, Claude, and Google AI Overviews. The tactics overlap but the mechanisms and goals are different.
How do I know if my content is being cited by AI?
Run queries related to your topic in Perplexity, ChatGPT (with search enabled), and Google AI Overviews. Check whether your domain appears as a cited source. Tools like Profound and Otterly.ai can automate this monitoring.
Does GEO replace AEO?
No. AEO and GEO are complementary. AEO wins traditional search features like featured snippets. GEO wins AI citations. A mature content strategy runs both in parallel.
How long does GEO take to show results?
Unlike SEO, GEO results can appear quickly — sometimes within days of a page being indexed by AI crawlers. The compounding effect builds over 60–180 days as AI systems repeatedly select your content for related queries.
Si has optimizado contenido para Google y aun así no logras que los sistemas de inteligencia artificial te citen, es porque estás usando el manual equivocado. GEO —Generative Engine Optimization u Optimización para Motores Generativos— es la disciplina de hacer que tu contenido sea visible, creíble y citable para motores de IA como ChatGPT, Claude, Perplexity, Gemini y los AI Overviews de Google. No es SEO con un nombre nuevo. Es un juego distinto con reglas distintas.
Definición: La Optimización para Motores Generativos (GEO) es la práctica de estructurar el contenido para que los modelos de lenguaje de gran escala (LLM) y los motores de búsqueda con IA lo seleccionen como fuente al generar respuestas a las consultas de los usuarios. Donde el SEO obtiene posiciones, el GEO obtiene citas.
Por qué GEO no es SEO
Por qué GEO no es SEO.
El SEO trata de posicionarse. Optimizas una página para que el algoritmo de Google la muestre cuando alguien busca algo. El objetivo es un clic. El GEO trata de ser citado. Estructuras el contenido para que un sistema de IA confíe en él lo suficiente como para extraer un dato, una definición o una explicación cuando sintetiza una respuesta. El usuario puede no hacer clic en tu URL, pero tu contenido moldeó lo que leyó.
Los mecanismos son fundamentalmente diferentes. El algoritmo de posicionamiento de Google pondera cientos de señales: backlinks, velocidad de página, comportamiento del usuario, autoridad. La selección de citas por IA pondera la densidad de entidades, la especificidad factual, las señales de credibilidad de la fuente y la claridad estructural. Una página que ocupa el puesto #1 en Google puede recibir cero citas de IA. Una página que ocupa el puesto #8 puede ser la que Perplexity cita cada vez que alguien pregunta sobre ese tema.
Cómo los motores de IA seleccionan el contenido que citan
Los modelos de lenguaje de gran escala utilizados en la búsqueda con IA (GPT-4, Claude, Gemini) fueron entrenados en grandes corpus de texto, pero la capa de generación aumentada por recuperación (RAG) que impulsa herramientas como Perplexity, la búsqueda de ChatGPT y los AI Overviews de Google funciona de manera diferente. Extrae contenido en tiempo real en el momento de la consulta, lo puntúa por relevancia y credibilidad, y sintetiza una respuesta. Las señales que utiliza para puntuar tu contenido incluyen:
Claridad de entidades — ¿Las personas, lugares, empresas y conceptos en tu contenido están claramente nombrados y vinculados a entidades conocidas?
Densidad factual — ¿Tu contenido contiene afirmaciones específicas y verificables en lugar de generalidades vagas?
Legibilidad estructural — ¿Puede la IA analizar la estructura de tu contenido —encabezados, definiciones, listas— sin ambigüedad?
Señales de fuente — ¿Tu contenido cita fuentes primarias, estudios o expertos nombrados?
Esquema speakable — ¿Has marcado párrafos clave como candidatos de respuesta legibles por máquinas?
Las tres capas del GEO
Las tres capas del GEO.
Capa 1: Arquitectura de contenido
El contenido optimizado para GEO está diseñado para la extracción, no solo para la lectura. Eso significa que cada afirmación importante está en una oración independiente. Las definiciones aparecen cerca de la parte superior. Los encabezados de sección son declarativos, no creativos. La estructura le dice a la IA dónde está la respuesta antes de que tenga que leer el artículo completo.
Capa 2: Saturación de entidades
Los sistemas de IA entienden el contenido a través de entidades: personas, organizaciones, lugares, productos y conceptos nombrados que existen en sus datos de entrenamiento. Un artículo optimizado para GEO satura las entidades relevantes: no dice “una importante empresa de IA” cuando se refiere a Anthropic. No dice “una popular herramienta de búsqueda” cuando se refiere a Perplexity. Cada entidad está nombrada, escrita correctamente y usada en el contexto correcto.
Capa 3: Esquema y datos estructurados
El marcado de esquema JSON-LD es una señal tanto para los motores de búsqueda tradicionales como para los rastreadores de IA. El esquema FAQPage hace que tu contenido de preguntas y respuestas sea directamente extraíble. El esquema speakable marca los párrafos más útiles para la síntesis de voz e IA. El esquema de artículo establece la autoría y la fecha de publicación. No son extras opcionales: son la capa legible por máquinas que hace que tu contenido sea seleccionado.
GEO vs AEO: ¿Cuál es la diferencia?
GEO vs AEO: cuál es la diferencia.
La Optimización para Motores de Respuesta (AEO) se centra en ganar fragmentos destacados, cuadros de Preguntas relacionadas y resultados de búsqueda de cero clics en los motores de búsqueda tradicionales. El GEO se centra en ser citado por los sistemas de IA generativa. Las tácticas se superponen, pero los objetivos son diferentes. El AEO gana la posición cero en Google. El GEO gana el párrafo que Perplexity escribe para el próximo millón de consultas sobre tu tema.
Cómo empezar con GEO
Si estás gestionando una operación de contenido existente y quieres incorporar GEO, el orden de prioridad es:
Audita tus 20 páginas principales en busca de lagunas de entidades — donde uses referencias vagas, reemplázalas con entidades nombradas específicas
Añade esquema speakable a tus tres párrafos definitorios más sólidos por página
Ejecuta una verificación de densidad factual — cada estadística debe tener una fuente, cada afirmación debe ser específica
Añade esquema FAQPage a cualquier página con encabezados en formato de pregunta
Envía tus páginas principales a la Prueba de resultados enriquecidos de Google y verifica que los datos estructurados se lean correctamente
GEO es infraestructura que se acumula
La razón por la que GEO importa para las operaciones de contenido es el efecto acumulativo. Una vez que un sistema de IA ha indexado y confiado en tu contenido como fuente confiable sobre un tema, las consultas posteriores sobre ese tema extraen de tu contenido repetidamente, sin que publiques nada nuevo. Un solo artículo pilar optimizado para GEO puede generar miles de citas de IA durante 12 meses. Eso es un tipo diferente de ROI al de una página posicionada que recibe clics y se olvida.
Preguntas frecuentes sobre GEO
¿Qué significa GEO?
GEO significa Generative Engine Optimization —Optimización para Motores Generativos— la práctica de optimizar contenido para ser citado por sistemas de búsqueda impulsados por IA y modelos de lenguaje de gran escala.
¿Es GEO lo mismo que SEO?
No. El SEO apunta a posiciones en la búsqueda tradicional. El GEO apunta a citas de IA en herramientas como ChatGPT, Perplexity, Claude y los AI Overviews de Google. Las tácticas se superponen pero los mecanismos y objetivos son diferentes.
¿Cómo sé si mi contenido está siendo citado por la IA?
Ejecuta consultas relacionadas con tu tema en Perplexity, ChatGPT (con búsqueda activada) y los AI Overviews de Google. Verifica si tu dominio aparece como fuente citada. Herramientas como Profound y Otterly.ai pueden automatizar este monitoreo.
¿GEO reemplaza al AEO?
No. AEO y GEO son complementarios. El AEO gana características de búsqueda tradicional como fragmentos destacados. El GEO gana citas de IA. Una estrategia de contenido madura ejecuta ambos en paralelo.
¿Cuánto tiempo tarda el GEO en mostrar resultados?
A diferencia del SEO, los resultados de GEO pueden aparecer rápidamente, a veces en días después de que una página sea indexada por los rastreadores de IA. El efecto acumulativo se construye durante 60 a 180 días a medida que los sistemas de IA seleccionan repetidamente tu contenido para consultas relacionadas.
Content About Your Business Is Being Created Without You
Right now, somewhere on the internet, a system is writing content that mentions your business. It might be an AI answering a question about your industry. It might be a local publication compiling a roundup of businesses in your area. It might be a travel app generating a recommendation list for visitors to your town. It might be a voice assistant responding to “find me a [your service] near me.”
This is the secondary content market — the ecosystem of publications, platforms, AI systems, and apps that create derivative content about businesses using whatever structured data they can find. It’s not new, but it’s accelerating. And the quality of what gets created about your business depends entirely on the quality of the data you make available.
What Gets Pulled and What Gets Missed
When we build local content for publications like Belfair Bugle and Mason County Minute, we pull from every structured data source available: Google Business Profiles, chamber of commerce directories, official business websites, social media pages, and public records. The businesses that load up their profiles — full menus, current photos, detailed descriptions, accurate hours, complete service lists — make it easy for us to write about them accurately and compellingly.
The businesses that have a bare GBP listing, no menu, a stock photo, and hours from 2023? We either skip them or qualify everything with hedging language because we can’t verify the details. The same thing happens at scale when AI systems generate content. Rich data gets cited confidently. Sparse data gets ignored or, worse, hallucinated.
Menus, Photos, and the Data That Feeds the Machine
Think about what a well-stocked business profile actually provides to the secondary content market. Your menu gives food publications and AI systems specific dishes to recommend. Your photos give travel guides and social platforms visual content to feature. Your service list gives industry roundups specifics to cite. Your business description gives AI systems entities and context to work with.
Every piece of data you add to your Google Business Profile, your website’s structured data, your social media profiles — all of it feeds into the content supply chain. Publications pull your menu to write about your restaurant. AI systems pull your service list to answer questions about your industry. Travel apps pull your photos to recommend your hotel. The richer your data, the more surface area you have in the secondary content market.
The Local Angle: Why This Hits Small Businesses Hardest
Large chains have marketing teams that maintain consistent data across every platform. Local businesses usually don’t. That means the secondary content market disproportionately favors chains over independents — unless the independent makes a deliberate effort to load up their structured data.
This is particularly true in areas like Mason County and the Olympic Peninsula, where local businesses are the backbone of the community but often have the thinnest digital presence. A family-owned restaurant with an incredible menu but no Google Business Profile menu entry is invisible to every AI system and publication that relies on structured data. A boutique hotel with stunning views but no photos on their GBP is a ghost to travel recommendation engines.
What To Do About It
The secondary content market isn’t going away — it’s growing. The actionable response is straightforward: make your business data machine-readable, complete, and current. Start with your Google Business Profile. Fill every field. Upload quality photos. Add your full menu or service catalog. Update your hours. Write a description that includes the terms and entities relevant to your business.
Then do the same for your website — add structured data (schema markup) so AI systems can parse your content programmatically. Make sure your social media profiles are consistent and current. The goal isn’t to game any one platform. It’s to ensure that when any system anywhere creates content about your business, it has accurate, rich data to work with.
Your business data is already on the secondary content market. The only question is whether you’ve given it good material to work with.
Most businesses treat their Google Business Profile like a digital business card — name, address, phone number, maybe a few photos. Update it once, forget about it. That approach made sense when GBP was primarily a search listing. It doesn’t make sense anymore.
Here’s what’s changed: your Google Business Profile has quietly become one of the most important structured data sources on the internet. Not just for Google Search, but for the entire ecosystem of AI systems, local publications, voice assistants, mapping apps, review aggregators, and content platforms that need reliable business data to function.
What’s Actually Pulling From Your GBP
When an AI system like ChatGPT, Claude, or Perplexity answers a question about “best restaurants in Shelton, WA,” it needs ground truth data. Where does that data come from? Increasingly, it’s structured business data — and Google Business Profiles are the richest, most consistently maintained source of it.
When a local publication (like our own Mason County Minute or Belfair Bugle) writes about businesses in the area, we verify every entity against Google Maps data. The name, the address, the hours, whether it’s still open — all of it comes from the Google Places API, which pulls directly from Google Business Profiles.
When a voice assistant answers “what time does [business] close,” it’s reading your GBP. When a travel app recommends places to eat, it’s pulling your GBP menu, photos, and reviews. When an AI overview summarizes local options, your GBP data is in the training signal.
The Knowledge Node Mental Model
Stop thinking of your GBP as a listing. Start thinking of it as a knowledge node — a structured data endpoint that other systems query to learn about your business. The richer and more accurate your node is, the more useful it is to every downstream system that touches it.
What does a well-maintained knowledge node look like? It has complete, current hours (including holiday hours). It has a full menu or service list with prices. It has high-quality photos of the exterior, interior, products, and team. It has a detailed business description with the entities and terms that matter for your category. It has attributes filled out — wheelchair accessible, outdoor seating, Wi-Fi, whatever applies. It has regular posts showing activity and relevance.
Every one of those data points is something that another system can cite, surface, or recommend. A missing menu means a food app can’t include you. Missing photos mean an AI-generated travel guide has nothing to show. Outdated hours mean a voice assistant sends someone to your door when you’re closed.
Why This Matters Now More Than Before
We’re entering a period where AI-generated content and AI-powered search are growing rapidly. Google AI Overviews, Perplexity, ChatGPT with browsing — these systems need structured data about real-world businesses to generate useful answers. The businesses that provide that data in a rich, machine-readable format will get cited. The ones that don’t will get skipped.
This isn’t theoretical. We built a Google Maps quality gate into our own publishing pipeline after community feedback showed us that AI-generated entity errors erode trust instantly. The businesses that had complete, accurate GBP listings were easy to verify and include. The ones with sparse or outdated profiles created uncertainty — and uncertainty means we leave them out.
The Action Step
Open your Google Business Profile today. Look at it not as a customer would, but as a machine would. Is every field filled? Are your photos recent and high-quality? Is your menu or service list complete? Are your hours accurate, including holidays? Is your business description rich with the terms someone (or something) would search for?
If the answer is no, you’re leaving distribution on the table. Every AI system, every local publication, every app that could have mentioned your business needs data to work with. Your GBP is where that data lives. Treat it like the API it’s becoming.
📎 Book for Bots — Free
Take this article on steroids.
The Claude Implementation Playbook is a dense 9-section PDF you can attach directly to any AI conversation — pricing tables, model API strings, routing logic, context engineering rules. Verified October 2026.
Usage limits are the first thing you hit when Claude starts working. We’ve built systems that manage context budgets, rotate models by task, and keep costs predictable at scale. If that’s the problem you’re solving, let’s talk.
By Will Tygart • Long-form Position • Practitioner-grade
Most SaaS pricing pages are designed to justify a price. The best ones are designed to eliminate a reason not to buy. That sounds like the same thing. It isn’t. Justifying a price assumes the customer already wants what you’re selling and just needs to feel okay about the number. Eliminating friction assumes the customer wants it but has found a reason to wait — and your job is to remove that reason before they close the tab.
Node pricing is the second kind of pricing. It’s not a discount strategy. It’s not a freemium ladder. It’s a structural acknowledgment that your product contains more than one thing of value, and not every customer needs all of it. The $9/node model — where a customer pays $9 per knowledge sub-vertical per month, with a minimum of three nodes — does something that flat subscription tiers almost never do: it makes the product accessible at the exact scope the customer actually wants, rather than at the scope you’ve decided they should want.
This matters more than it sounds. The gap between what a customer wants to pay for and what your pricing page forces them to pay for is where most SaaS revenue quietly dies.
The Friction Taxonomy
Before you can eliminate friction, you have to know which kind you’re dealing with. There are three distinct friction types that kill knowledge product conversions, and they require different solutions.
Price friction is the most obvious and the least interesting. The customer looks at the number and thinks it’s too high relative to what they’re getting. The standard response is discounts, trials, and annual pricing incentives. These work, but they’re universally available to competitors and therefore not a strategic advantage.
Scope friction is more interesting and more solvable. The customer looks at what’s included and thinks: I need the mold section. I don’t need water damage, fire, or insurance. But the only way to get mold is to buy the whole restoration corpus at $149/month. That’s not a price objection — they might genuinely be willing to pay $40 for mold-only access. The friction is architectural. The pricing structure forces them to buy more than they want, so they buy nothing.
Identity friction is the least discussed and often the most decisive. The customer looks at your Growth tier at $149/month and thinks: that’s a serious software subscription. It implies a level of commitment and organizational buy-in that I’m not ready to make. Even if $149 is financially trivial to them, the psychological weight of a $149 line item on a budget is different from three $9 charges that collectively total $27. The first feels like a decision. The second feels like a purchase. That distinction is not rational. It is real.
Node pricing at $9/node addresses all three friction types simultaneously — and that’s why it’s a more interesting pricing philosophy than it appears to be on first read.
Why $9 Is Not Arbitrary
The $9 price point is doing several things at once. It’s below the threshold where most individuals and small business operators feel they need approval from anyone else to make a purchase. It’s above the threshold that signals “this is a real product with real value” rather than a free tier with artificial limits. And it creates an obvious natural upsell path: the customer who starts with one node at $9 and finds it useful adds a second, then a third. At three nodes they’re at $27/month. At five they’re at $45. Somewhere between five and ten nodes, the Growth tier at $149 starts looking like a better deal than individual nodes — and the customer has already been educated on why they want more coverage, by their own experience of adding nodes one at a time.
This is not an accident. It’s a funnel architecture disguised as a pricing structure. The customer who would never have clicked “Start Trial” on a $149 product clicked “Add mold node” at $9, found out the corpus is actually good, added two more nodes, and is now a much warmer prospect for the Growth tier than any free trial would have produced — because they’ve already been paying, which means they’ve already decided the product is worth money.
Paying, even a small amount, is a qualitatively different commitment than trialing for free. The psychology of sunk cost works in your favor when the cost is real. Free trial users can walk away feeling nothing. A customer who has paid three months of $27/month has a relationship with the product that is fundamentally stickier, even before the node count justifies an upgrade.
The Scope Signal
There is a second thing node pricing does that is easy to overlook: it collects enormously useful intelligence about what customers actually value.
A flat subscription tier tells you how many people bought. It tells you almost nothing about why, or which part of the product they’re using. Node pricing tells you exactly which knowledge sub-verticals customers are willing to pay for, in what combinations, at what rate of adoption. That is product market fit data at a granularity that flat pricing can never produce.
If 70% of customers add the mold node first, that tells you something about where to invest in corpus depth. If almost nobody adds the insurance and claims node despite it being objectively one of the most technically complex verticals in the corpus, that tells you something about either the quality of that content or the demand signal for it among your current customer base. If customers consistently add three nodes and stop, that tells you something about the natural scope of what most buyers want — and it should inform where you set the minimum bundle threshold for the Growth tier conversion.
This is market research that runs continuously and costs nothing beyond what you were already building. It requires only that you look at the data.
The Minimum Bundle Logic
Node pricing works best with a thoughtfully designed minimum. Three nodes at $9/month means $27 minimum — low enough to feel like a purchase, high enough to produce real revenue and signal real intent. But the choice of three is not purely arbitrary.
Below a certain node count, the knowledge base isn’t useful enough to demonstrate value. A single mold node in isolation tells a contractor something. Three nodes — mold, water damage, and drying science — tells them enough to use the product meaningfully in a real job situation. The minimum bundle is designed to get the customer past the “is this actually good?” threshold before they’ve made a large enough commitment to feel burned if the answer is no.
The minimum also creates a natural comparison point with the next tier up. Three nodes at $27 versus the Growth tier at $149 is a stark difference. But eight nodes at $72 versus $149 starts to narrow. The minimum bundle pushes customers to a price point where the comparison becomes interesting — and interesting comparisons produce upgrades.
What This Has to Do With Content Strategy
Node pricing is a product architecture decision. But the philosophy behind it — that friction is the real barrier, not price — applies directly to how content products should be built and sequenced.
The content equivalent of scope friction is the pillar article problem. You write a comprehensive 3,000-word guide on a topic and wonder why the conversion rate is lower than expected. The reason is often that the reader wanted one specific section — the part about how to document moisture readings for an insurance claim — and had to work through 2,000 words of context they already knew to get there. The scope of the article exceeded the scope of their need. They left.
The content equivalent of node pricing is granular entry points. Instead of one comprehensive guide, you publish the moisture documentation section as a standalone piece, linked from the comprehensive guide but findable independently. The reader who needs exactly that finds it, gets the answer, and converts at a higher rate than the reader who had to excavate it from a wall of text. The comprehensive guide still exists for the reader who wants full coverage. Both types of readers are served at their own scope.
The underlying insight is the same in both cases: matching the scope of what you offer to the scope of what each specific customer wants is more powerful than optimizing within a fixed scope. The customer who wants mold-only is not a lesser customer than the one who wants the full corpus. They’re a customer at the beginning of a different path that, if you’ve designed correctly, leads to the same destination.
The $1 First Month Isn’t a Trick
One pricing mechanic worth calling out specifically is the $1 first month offer — available on any single corpus, unlimited queries, 30 days, one dollar. No catch.
This is not a trick and should not be presented as one. It is a philosophical statement about where conversion friction lives. If the product is good, the barrier isn’t price — it’s the activation energy required to start. Most people don’t try things because they haven’t gotten around to it, not because the price is wrong. A dollar removes the “is it worth the money to find out?” calculation entirely and replaces it with: the only reason not to try this is inertia.
The customers who try it and stay are the ones who found value. The ones who don’t renew weren’t going to stay at any price, and the dollar was a better use of that lead than a free trial that never converts because free things feel optional.
Priced at $1, the first month is a commitment. Priced at $0, it’s a maybe. That difference in psychological framing shows up in activation rates, usage depth during the trial period, and ultimately in renewal rates. Free is not always better than cheap. Sometimes cheap is better than free because cheap requires a decision, and a decision creates an owner.
Frequently Asked Questions
What is node pricing in a knowledge API product?
Node pricing is a model where customers pay per knowledge sub-vertical — called a node — rather than for access to the entire corpus at a flat tier price. At $9/node with a three-node minimum, customers pay only for the specific knowledge domains they need, reducing scope friction and creating a natural upgrade path to higher tiers as they add more nodes.
Why is friction the real barrier rather than price in knowledge products?
Most knowledge product prospects aren’t declining because the price is objectively too high — they’re declining because the pricing structure forces them to commit to more scope than they currently need. Node pricing addresses scope friction (buying only what you want) and identity friction (avoiding the psychological weight of a large monthly commitment) in ways that discounting alone cannot.
How does node pricing create an upgrade path to higher tiers?
Customers who start with three nodes at $27/month add nodes as they discover value. As the node count climbs toward eight or ten, the per-node cost of the Growth tier at $149 becomes more attractive than continuing to add individual nodes. The customer has also been paying throughout this process — establishing a payment relationship and demonstrating intent that makes the tier upgrade a natural next step rather than a new decision.
What intelligence does node pricing generate about customer demand?
Node-level purchase data reveals which knowledge sub-verticals customers value enough to pay for, in what order, and in what combinations. This is granular product-market fit data that flat subscription tiers can’t produce. It informs corpus investment priorities, identifies underperforming verticals, and reveals natural scope limits in the customer base — all without additional research spending.
Why is a $1 first month more effective than a free trial?
Free trials feel optional because they require no commitment. A $1 first month requires a purchasing decision — the customer has decided this is worth trying rather than just started a free account. This small financial commitment increases activation rates, usage depth, and renewal conversion because customers who pay, even minimally, have already decided the product is worth their attention.
By Will Tygart• Long-form Position
• Practitioner-grade
The most interesting business models don’t just sell to customers. They turn customers into the product’s engine. There’s a version of this in every category — the marketplace that gets better as more buyers and sellers join, the review platform that gets more useful as more people leave reviews, the map that gets more accurate as more drivers report conditions. Network effects are well understood. But there’s a quieter version of this dynamic that almost nobody is building yet, and it may be more valuable than the classic network effect in the AI era.
Call it the corpus contributor model. The customer who pays for access to your knowledge base also happens to be a practitioner in the exact domain your knowledge base covers. They use the product. They notice what it gets wrong. They have opinions about what’s missing. And if you build the right mechanic, they can feed those observations back into the corpus — making it more accurate, more complete, and more current than you could ever make it by yourself.
This is not a theoretical model. It’s a specific architectural decision with specific business implications. And most AI knowledge product builders are missing it entirely.
Last refreshed: November 6, 2026 (Pacific)
What the Corpus Contributor Flip Actually Is
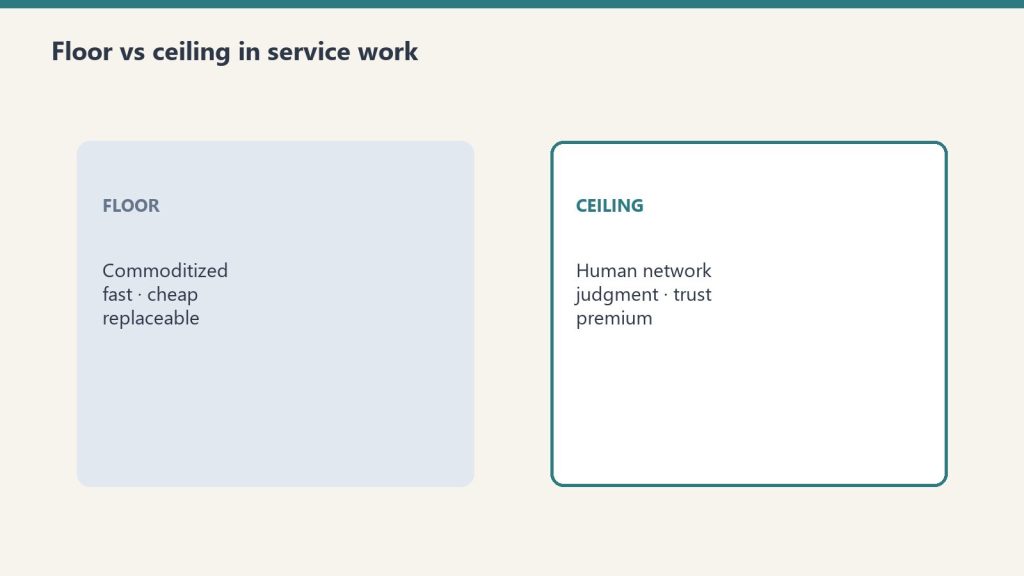
Floor versus ceiling cards: commoditized work sits at the floor, human-network premium work at the ceiling — the flip moves a knowledge product toward the ceiling.
The standard model for a knowledge API product looks like this: you extract knowledge from practitioners, structure it, and sell access to it. The customer is a buyer. The knowledge flows one direction — from your corpus into their AI system. You maintain the corpus. They consume it. Revenue comes from subscriptions.
The corpus contributor model adds a second flow. The customer — who is themselves a practitioner — also has the option to contribute validated knowledge back into the corpus. Their contribution improves the product for every other customer. In exchange, they get something: a lower subscription rate, a named credit in the corpus, early access to new verticals, or simply a better product faster than the passive subscriber would get it.
The word “flip” matters here. You are not just adding a feature. You are reframing who the customer is. They are not only a consumer of knowledge. They are simultaneously a source of it. The relationship is bilateral. That changes the economics, the product roadmap, the sales conversation, and the defensibility of the whole business in ways that compound over time.
Why This Is Different From Crowdsourcing
The immediate objection is that this sounds like crowdsourcing, which has a complicated track record. Wikipedia works. Most other crowdsourced knowledge projects don’t. The reason Wikipedia works at scale and most others don’t comes down to one thing: intrinsic motivation. Wikipedia contributors edit because they care about the topic. There’s no transaction.
The corpus contributor model is not crowdsourcing and should not be designed like it. The distinction is selection and validation.
Selection: You are not asking the general public to contribute. You are asking paying subscribers who have already demonstrated that they operate in this domain by the fact of their subscription. A restoration contractor who pays $149 a month for access to a restoration knowledge API has self-selected into a group with genuine domain expertise and a financial stake in the quality of the product. That is a fundamentally different contributor pool than an open wiki.
Validation: Contributor submissions don’t go directly into the corpus. They go into a validation queue. Every submission is reviewed against existing knowledge, cross-referenced against standards where they exist, and flagged for expert review when there’s conflict. The contributor model doesn’t replace the extraction and validation process — it feeds it. Contributors surface what’s missing or wrong. The validation layer decides what actually enters the corpus.
This is closer to the model used by high-quality technical reference databases than to Wikipedia. The contributors are domain insiders with a stake in accuracy. The editorial layer maintains quality. The corpus improves faster than it could with internal extraction alone.
The Flywheel
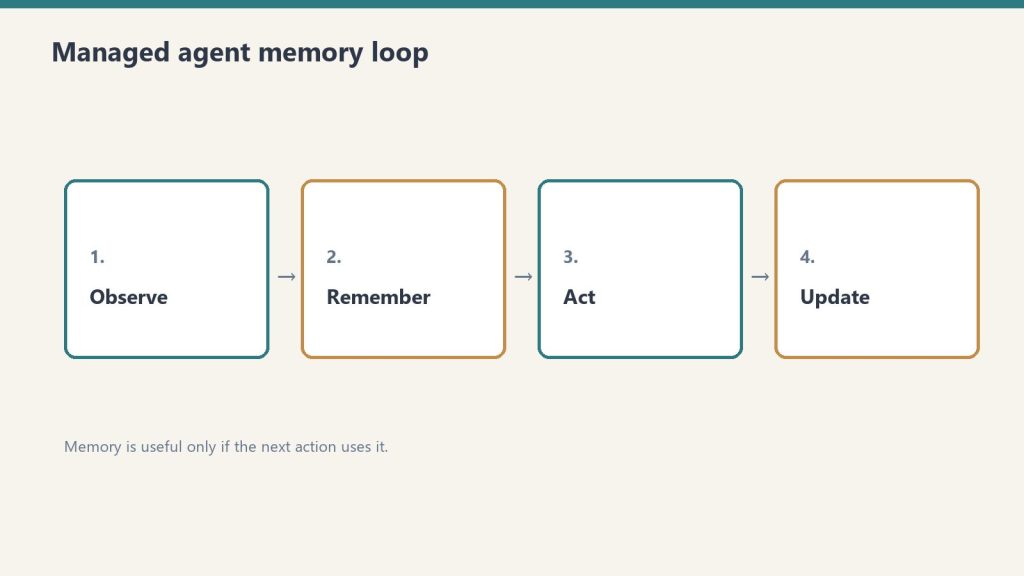
The managed agent memory loop: Observe, Remember, Act, Update — memory is useful only if the next action uses it; the contributor flywheel compounds the same way.
Here is where the model gets genuinely interesting. Every traditional subscription business has a churn problem. The customer pays monthly. They evaluate monthly whether the product is worth it. If nothing changes, their willingness to pay is roughly static. The product has to justify itself again and again against a customer whose needs are evolving.
The corpus contributor model changes this dynamic in two ways that reinforce each other.
First, contributors have a personal stake in the corpus that passive subscribers don’t. If you submitted three validated knowledge chunks about LGR dehumidification performance in high-humidity climates, and those chunks are now in the corpus being used by other contractors and by AI systems that serve your industry, you have a relationship with that corpus that is qualitatively different from someone who just queries it. You built part of it. Your churn rate is lower because leaving the product means leaving something you helped create.
Second, the corpus gets better as contributors engage. A better corpus is worth more to new subscribers, which brings in more potential contributors, which improves the corpus further. This is a flywheel, not just a retention mechanic. The passive subscriber benefits from the contributor’s work. The contributor gets a better product to work with. New subscribers join a product that is measurably more accurate and complete than it was six months ago. The value proposition strengthens over time without requiring proportional increases in internal extraction cost.
Compare this to a standard knowledge API where the corpus is maintained entirely internally. The corpus improves at the rate of your internal extraction capacity. If you can run four extraction sessions a month, you add roughly four sessions’ worth of new knowledge per month. With contributors, that rate is multiplied by however many qualified practitioners are actively engaged. The internal team still controls quality through the validation layer. But the input volume grows with the customer base rather than with internal headcount.
The Enterprise Version
Individual contributors are valuable. Enterprise contributors are transformative.
Consider a restoration software company that builds job management tools for contractors. They have access to millions of completed job records — real-world data on what drying protocols were used on what loss categories in what climate conditions, with what outcomes. That data, properly structured and validated, is worth dramatically more to a restoration knowledge corpus than anything extractable from individual interviews.
The standard sales conversation with that company is: “Pay us $499 a month for API access.” That’s fine. It’s a transaction.
The corpus contributor conversation is different: “We want to build the knowledge infrastructure that makes your product’s AI features better. You have data we need. We have a structured corpus and a validation layer you’d spend years building. Let’s make the corpus jointly better and share the value.” That’s a partnership conversation. It changes the deal size, the relationship depth, and the defensibility of the resulting product — because the enterprise contributor’s data is now embedded in a corpus they can’t easily replicate by going to a competitor.
Enterprise corpus contributors also create a named knowledge layer opportunity. The restoration software company’s contributed data doesn’t disappear into an anonymous corpus — it’s credited, tracked, and potentially sold as a named vertical: “Job outcome data layer, contributed by [Partner].” That attribution has marketing value for the contributor and validation signal for the subscribers who use it. Everyone’s incentives align.
What the Sales Conversation Becomes
The corpus contributor model changes the initial sales conversation in a way that most knowledge product builders miss because they’re too focused on the subscription tier.
The standard pitch leads with access: “Here’s what you can query. Here’s the price.” That’s a cost-benefit conversation. The prospect weighs whether the knowledge is worth the fee.
The contributor pitch leads with participation: “You know things we need. We have infrastructure you’d spend years building. Join as a contributor and help shape the corpus your AI stack runs on.” That’s a different conversation entirely. It’s not about whether the existing product justifies its price — it’s about whether the prospect wants to have a role in what the product becomes.
For practitioners who care about their industry’s AI infrastructure — and in most verticals, there are a meaningful number of these people — the contributor framing is more compelling than the subscriber framing. It gives them agency. It makes them a participant in something larger than a software subscription. That is a qualitatively different reason to write a check, and it is stickier than feature value alone.
The Validation Layer Is the Business
Five security domains — identity, data, code governance, audit, and agents — the governance surface a validation layer has to cover before a contribution enters the corpus.
Everything described above depends on one thing working correctly: the validation layer. If contributors can inject bad knowledge into the corpus, the product becomes unreliable. If the validation layer is so restrictive that nothing gets through, the contributor mechanic produces no value. The design of the validation layer is where the real intellectual work of the corpus contributor model lives.
A well-designed validation layer has three properties. It is domain-aware — it knows enough about the field to evaluate whether a contribution is plausible, consistent with existing knowledge, and meaningfully different from what’s already there. It is conflict-surfacing — when a contribution contradicts existing corpus entries, it flags the conflict for expert review rather than silently accepting or rejecting either. And it is contributor-transparent — contributors can see the status of their submissions, understand why something was accepted or rejected, and engage in a dialogue about contested points.
The validation layer is also the moat that a competitor can’t easily replicate. Building a corpus takes time. Building relationships with contributors takes time. But building the domain expertise required to run a validation layer that practitioners trust — that takes the longest. It’s the part of the business that scales slowest and defends best.
Who Should Build This First
The corpus contributor model is available to any knowledge product company that has, or can develop, three things: a practitioner customer base with genuine domain expertise, an extraction and validation infrastructure that can process contributions at volume, and the product design capability to build a contribution mechanic that practitioners actually use.
In the restoration industry, the conditions are nearly ideal. The customer base — contractors, adjusters, estimators, project managers — has deep domain knowledge and a direct financial interest in AI tools that work correctly. The knowledge gaps are enormous and well-understood. And the trust infrastructure, built through trade associations, peer networks, and industry events, already exists as a substrate for the kind of relationship-based contributor model that works at scale.
The first knowledge product company in any vertical to implement the corpus contributor model well will have an advantage that is very difficult to replicate. Not because their technology is better. Because they turned their customers into co-authors of the most defensible asset in vertical AI.
What is the corpus contributor model in AI knowledge products?
The corpus contributor model is a product architecture where paying customers — who are domain practitioners — also have the option to contribute validated knowledge back into the product’s knowledge base. This creates a bilateral relationship where the customer is both a consumer and a source of knowledge, improving the corpus faster than internal extraction alone could achieve.
How is this different from crowdsourcing?
The corpus contributor model differs from crowdsourcing in two critical ways: selection and validation. Contributors are self-selected domain practitioners who pay for access, not anonymous volunteers. And contributions pass through a structured validation layer before entering the corpus — they don’t go in automatically. This makes it closer to a high-quality technical reference database model than an open wiki.
Why does the corpus contributor model reduce churn?
Contributors develop a personal stake in the corpus that passive subscribers don’t have. Having built part of the product, contributors are less likely to cancel because leaving means leaving something they helped create. Additionally, active contributors see the corpus improving in response to their input, which reinforces the value they’re receiving beyond passive access.
What makes enterprise corpus contributors particularly valuable?
Enterprise contributors — such as software companies with large volumes of structured job outcome data — can contribute knowledge at a scale and quality that individual extraction sessions can’t match. Their data also creates a named knowledge layer opportunity: credited, tracked contributions that signal validation quality to other subscribers and create a partnership relationship that is significantly stickier than a standard subscription.
What is the validation layer and why does it matter?
The validation layer is the quality control system that evaluates contributor submissions before they enter the corpus. It must be domain-aware enough to assess plausibility, conflict-surfacing when contributions contradict existing knowledge, and transparent enough that contributors understand how their submissions are evaluated. The validation layer is also the hardest component to replicate, making it the deepest competitive moat in the model.
The Signal — Tygart Media's weekly brief. What we actually ran, what it measured, and what it means for a restoration shop.