Tag: AI Operations

  • I Watched My AI Agent Work. I Couldn’t Tell What It Was Doing.

    I Watched My AI Agent Work. I Couldn’t Tell What It Was Doing.

    I had an AI agent doing something routine in a browser today — opening a server terminal, placing a small text file. Nothing exotic. While it worked, I opened the activity feed to watch.

    This is what I saw:
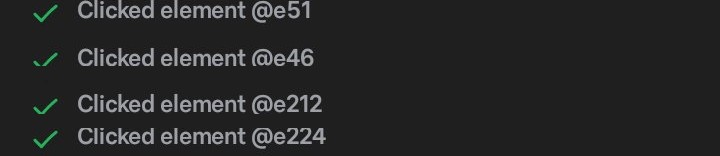
    Cropped screenshot of an AI browser agent's activity feed showing four entries labeled only with internal element IDs: Clicked element @e51, @e46, @e212, @e224.
    Four entries, cropped from the feed. Every one is an internal element ID.

    “Clicked element @e51.” “Executed click on element @e21.” “Clicked element @e224.”

    I had no idea what any of it meant.

    Here’s what I kept thinking while I stared at it: I’m watching this thing click around inside my infrastructure, and I can’t tell the difference between “everything is fine” and “it just did something terrible.” For all I knew from that feed, it could have pressed the button that drains all my money. The log was written for the machine, not for me.

    I didn’t want to interrupt. The agent was in the middle of working, and I didn’t want to be the guy hovering over the desk. So I went to look at what it was doing — and looking didn’t help, because there was nothing there a human could read.

    So I asked a question instead of making an assumption: whose labels are these? Is that how the website labels its buttons, or is that something the agent made up?

    The answer: the agent’s. The browser automation numbers every clickable element on the page so it can navigate — @e18, @e21, @e224 — and those internal reference numbers leaked straight into the activity feed a human is supposed to monitor.

    That’s when it stopped being a cosmetic complaint and became the actual point.

    Legibility is the safety feature

    An agent you can’t watch is an agent you can’t trust. An agent you can’t trust doesn’t get real work. Every roadmap that says “AI will handle X” dies at exactly this spot — not on capability, but on watchability. The machine can do the job. The human can’t verify the job. So the human doesn’t delegate the job.

    There’s an old principle — seek first to understand, then to be understood. It applied perfectly here. I could have assumed the worst and killed the task. I could have interrupted the work to ask what it was doing. Instead I asked what I was looking at, understood it, and then did the useful thing: filed the feedback so the next person watching gets words instead of codes. “Clicked the SSH button.” “Opened Compute Engine.” That’s all it would take.

    If you’re building agents, here’s the lesson: instrument for the watcher, not just the operator. The activity feed is a user interface. Nobody would ship a dashboard full of database IDs and call it done — but that’s exactly what most agent monitoring looks like right now. Label it like someone’s watching. Because someone is.

    The file got placed. The work finished fine. But the most useful thing that happened today might be the note we filed.
  • Don’t Build the Deck. Own the Dashboard.

    Don’t Build the Deck. Own the Dashboard.

    The news hook: on September 10, OpenAI put its Agents API into public beta — the Codex harness as a service. One API call spins up a production agent, OpenAI running the loop. That’s what got me thinking about 1990s car stereos.

    In the 90s, you didn’t just buy a Kenwood deck and drop it in. CD players were thicker than the cassette decks they replaced, so you needed a dash kit, a wiring harness, and somebody who knew how to make it all fit your specific car without setting the electrical system on fire. The deck was the exciting part. The harness was the part that determined whether it worked.

    AI is having its car-stereo decade right now, and the stack rhymes perfectly:

    • The decks are the models. They all play the discs now. Commoditized.
    • The harnesses are the agent frameworks — the loop that manages context, tools, subagents, sandpapers the rough edges between model releases. This is where the fight moved. OpenAI just productized theirs.
    • The connector kits are the universal adapters. In the 90s, one company owned this layer: Metra Electronics. Their entire brand was “the Installer’s Choice” — because we are installers — and they won by abstracting every car’s weird factory wiring so any shop could install any deck. Seventy years of winning by serving the installer, not the driver.
    • The installers are who actually gets paid. The shop on the corner with the soldering iron.

    Platforms are won by installer armies

    This is the oldest play in enterprise tech. Microsoft didn’t win on Windows alone — it won on the MCSE army, thousands of certified installers who made Windows the safe recommendation. Cisco did the same with its certification ladder. The vendor that recruits the most installers wins, because the installer chooses the harness for the customer, and the customer just wants music.

    Watch what’s happening now through that lens and everything snaps into focus. The Grokbot events. The ambassador programs. Everybody is recruiting installers — grassroots adoption, a visible market, and a career pivot for the people who learn the wiring first. The vendors aren’t selling to end users. They’re selling to the shops.

    The wiring diagram decides before the features do

    Here’s the detail that matters more than any launch demo. The managed harnesses come with constraints: where your data lives, who retains it, what residency you get. One prominent new offering is US-only with no zero-data-retention option — which rules it out for client-data workflows before you ever evaluate the features.

    Same lesson as the 90s: the harness that doesn’t fit your car is worthless no matter how good the deck is. The wiring diagram — data residency, retention, tenant boundaries — decides the purchase before the spec sheet does. Contractors figured this out fast: they won’t upload their estimates to a startup they found on social media, but they’ll run the same analysis inside their own Microsoft tenant. The tenant boundary might be the whole moat.

    The operator’s math

    So here’s the build-vs-buy for the AI age, and it’s the same math as the estimate-auditing tools: the intelligence is commoditized, so you’re never paying for smarts. You’re paying for the pipe and the paperwork — or in this case, the harness and the install.

    If a managed harness fits your wiring diagram and costs less than the engineering hours to maintain your own loop, buy it. If your data can’t leave your tenant, or the harness’s constraints disqualify it, build the loop yourself — the models are all CD players, and a good installer can wire any of them into the dash.

    Either way, notice where the money actually pools. Not with the deck makers. Not even with the harness makers. With the installers — the people who show up, learn the specific car, and make the music play.

    That’s the game. Don’t build the deck. Own the dashboard.

    The public tools behind that storefront are listed on Open Source Installer Tools.

  • The Arms Column, Field-Tested

    The Arms Column, Field-Tested

    “We said you’re not buying minutes — you’re buying arms. Then the calls started flowing. Here’s what the bill actually taught us.”

    A while back I argued that voice-AI pricing is a lie: the per-minute number on the pricing page isn’t the product. The product is a stack of arms — the voice intelligence, the carrier connection, the infrastructure around them — and the per-minute price is just the costume they wear.

    That was the theory. This is the field test.

    What the bill actually says

    Run a real week of calls and read the invoice the way an owner reads it — not the headline rate, the total. The per-minute number is almost never the biggest line. The arms are.

    The voice model doing the talking. The carrier moving the audio. The platform orchestrating the whole thing — the number, the recording, the transcript, the handoff. Each arm bills its own way, on its own meter, and the “per minute” quote only ever described one of them.

    Nobody lied to you. They just priced the costume and shipped the wardrobe.

    A bundled cable fanning out into many separate colored wires

    The concurrency math nobody shows you

    Here’s what the field test really exposes: minutes are linear, arms are not.

    Ten simultaneous calls isn’t ten times the per-minute rate in value — it’s ten arms, all live at once. The pricing page shows you a single call’s minute. Your Monday morning shows you ten calls overlapping, each holding its own model session, its own carrier leg, its own recording pipeline open.

    The vendor priced the minute. You bought the rush hour. Those are different products, and only one of them shows up when the phones light up.

    You pay for arms even when the call goes nowhere

    The wrong number. The three-second hangup. The caller who wanted the pizza place. The silence where someone pocket-dialed you.

    Minutes barely moved. The arms all fired anyway — the model spun up, the carrier connected, the platform recorded forty seconds of nothing and transcribed it faithfully. You paid for the whole stack to handle a call that never existed.

    This is the line the per-minute lie can’t survive: the bill doesn’t care whether the call mattered. The arms do the work either way. Price the arms, or the junk calls price you.

    The only math that matters

    Stop dividing by minutes. Start dividing by outcomes.

    Take a real week: total voice bill, all arms included, divided by minutes — that’s the advertised number, and it’s trivia. Now divide the same total by resolved calls. Then by booked jobs. That last number is the only one that touches revenue, and no vendor puts it on the pricing page because no vendor controls it — you do, with your harness.

    A vendor quoting two cents a minute against a vendor quoting five is a meaningless comparison until you know whose stack resolves the call. The cheap minute that books nothing is the most expensive minute you’ve ever bought.

    A headset resting on a desk next to a glowing phone with blurred charts behind

    What to ask a vendor now

    After the field test, there are three questions, and a vendor’s answers tell you everything:

    Break the bill into arms. What’s the model cost, the carrier cost, the platform cost — separately? If they can’t or won’t, you’re buying a bundle, and bundles hide margin.

    What does my rush hour cost? Not a minute — my Monday at 8 AM, ten calls deep. If the answer is “the same per-minute rate,” they haven’t thought about it, which means you will.

    What do I pay for the call that goes nowhere? The hangup, the wrong number, the silence. If everything bills the same whether the call mattered or not, the arms are priced — the minute is just the label.

    The close

    Minutes were never the product. The product is an answered call that ends in a booked job — and that’s built from arms, priced in arms, and won or lost in the harness around them.

    The pricing page will keep selling minutes. Let it. You know what you’re buying now.

    Buy the arms. Price the outcomes. Own the harness that turns one into the other.

  • Harness-First, Contractor Edition

    Harness-First, Contractor Edition

    “Own the harness. Rent the models.”

    In an AI lab, that’s architecture advice. In a restoration company’s office, it’s a survival rule. Here’s the contractor’s edition.

    The trap

    Most contractors buying AI right now are buying someone else’s harness. The tool owns the workflow, the prompts, the data flow, the follow-up timing — you rent the whole thing, top to bottom. It feels like buying software. It’s actually sharecropping.

    When the tool changes its pricing, kills a feature, or shuts down, your process dies with it. You didn’t buy a capability. You rented one, and the landlord just sold the building.

    What the harness is

    The harness is the workflow you own: how a lead gets answered, how a job gets documented, how a review gets asked for, how an estimate gets followed up. The prompts, the routing rules, the checks, the escalation to a human, the integrations between systems.

    The model is the engine. The harness is the truck. Engines get swapped; the truck is yours.

    Concretely: the harness is a document — written in your words — that says “when X happens, we do Y, then Z, and a human checks W.” Any model can execute it. No model owns it.

    What you rent

    The model. GPT, Claude, Grok, whatever’s best this quarter — swappable commodities. Today’s best model is next year’s legacy; that’s not cynicism, it’s the release cadence.

    If your process depends on a specific model’s quirks — the exact phrasing it likes, the feature only it has — you built on sand. The harness-first contractor can swap the engine on a Tuesday and the office doesn’t notice. The tool-renter files a support ticket and waits.

    A car engine mounted on a stand in a garage, ready to be swapped

    Three harnesses you already need

    The inbound line. The harness: the greeting, the questions it asks, the dispatch rules, the recording disclosure, what happens when it doesn’t know. The voice model underneath? Rented. Swap it when something better ships.

    The estimate follow-up. The harness: the timing (day 2, day 7, day 14), the message sequence, when it escalates to a human call. Any model can write the texts. The sequence is the asset.

    The review ask. The harness: the trigger (job closed, equipment out), the direct link, the prompt for specifics — what happened, where, how fast. The model writes the words; the workflow is yours.

    Notice the pattern: in every case, the durable part is the decisions — the timing, the triggers, the judgment calls. The model supplies sentences. Sentences are cheap.

    How to start

    Pick one workflow. Write down how it should go — the steps, the timing, the human checkpoints. That’s the harness, and it lives in your docs, not in a vendor’s dashboard.

    Then plug a model into it. Any model. When a better one ships, you re-plug. The doc doesn’t change.

    One workflow, owned end to end, beats five rented tools every time. Start with the one that touches money — the lead, the estimate, the invoice.

    An engineering blueprint spread on a wooden desk with a pencil and calipers

    The moat

    Two contractors can rent the same model. They can’t rent your harness — it’s your operations, your judgment, encoded. Your dispatch rules came from your jobs. Your follow-up timing came from your close rates. Your escalation instincts came from your mistakes.

    That’s the durable asset. Models are electricity. Nobody’s moat is “we use electricity.” The moat is what you built with it — and you own the building, not the power company.

    The close

    The AI industry wants you renting the whole stack — their workflow, their prompts, their model, their price increases. Harness-first says no: I’ll rent the intelligence by the hour, but the operation is mine.

    Own the harness. Rent the models. Be the one building still standing when the vendors reshuffle.

  • Onboard Your AI Like an Employee

    Onboard Your AI Like an Employee

    You wouldn’t hand a new hire the keys on day one. No tour, no training, no “here’s how we do things” — just a desk and your credit card.

    So why do it with AI?

    An AI seat is a hire. It has infinite stamina, perfect recall, and zero judgment on day one. Judgment is what onboarding installs. Skip the onboarding and you don’t have an employee — you have a very fast intern with no supervision making decisions in your name.

    The job description comes first

    Nobody starts a human employee without telling them the job. The AI version is the SOP: what this seat does, what it never does, what “done” looks like, and what it escalates instead of deciding.

    Write it before the seat starts. Not after the first mistake — before. “You draft, I approve.” “You never publish.” “You never mention a client by name.” “When you’re unsure, you ask.” Boring sentences. They’re the entire difference between a seat you trust and a seat you babysit.

    A seat with no job description invents its own. You won’t like its choices.

    Probation: review everything

    Every new hire gets a probation period. The AI seat gets one too — and during probation, the human gate sits on every output. Every draft gets read. Every action gets checked. Not because you distrust the seat, but because you’re calibrating it.

    This is the part most people skip, and it’s the part that matters most. Probation isn’t punishment; it’s training data. Every correction you make in week two is a rule the seat follows in month six — but only if you write it down.

    Give it the company history

    A new employee gets the lore: how we got here, what we tried, what blew up, who matters, how we sound. The AI seat needs the same. Context is training.

    Feed it the record. Past decisions and why they were made. The mistakes and what they cost. The voice — how you actually talk, not how a brand guide talks. The values that outrank any single instruction. A seat that knows the history makes decisions like an insider. A seat without it makes decisions like a temp.

    This is the compounding part. Six months from now, your seat knows things no new hire could learn in six months — because it was there for all of it, and it doesn’t forget.

    An open handbook with a golden ribbon bookmark, a pen, and coffee on a warm desk

    Performance reviews

    Review the seat weekly at first. What did it get right? What drifted? What needs a new rule? Then write the rule down.

    The rules file is the employee handbook, and it should grow. Every surprise becomes a sentence. “When the client changes scope mid-thread, summarize the change and confirm before continuing.” That’s not a prompt tweak — that’s institutional knowledge, and it belongs to the seat permanently.

    Quarterly, do the bigger review: is this seat’s job still the right job? The business moved; the seat should move with it. Stale SOPs produce stale work, and nobody notices because the output still looks polished. Polished and wrong is the most expensive kind of wrong.

    Promote slowly

    Widen the seat’s latitude as it proves out — the same way you’d trust a human with more over time. Two-way doors first: reversible work, drafts, research, analysis. The seat runs; you spot-check.

    The one-way doors stay gated until the track record earns them. Money, publishes, sends, deletions, commitments — those keep the human tap until the seat has a long, boring history of being right. Boring is the promotion criterion. Excitement is a red flag.

    The order matters: latitude is granted on evidence, never on optimism. “It’s been great so far” is not evidence. Six months of reviewed output is.

    A single brass key gleaming in warm light on a dark wooden desk

    The three hiring mistakes

    Hiring for the interview. A great demo isn’t a great employee. The demo shows what the model can do; onboarding determines what the seat will do, every day, unsupervised, in your name. Judge the seat at week six, not minute six.

    No handbook. Every correction stays verbal, nothing gets written down, and the same mistake comes back monthly wearing a different hat. If it isn’t in the rules file, it didn’t happen.

    Promoting too fast. Auto-publish before probation ends. Direct customer contact before the voice is trained. The seat will feel ready before it is ready — eagerness is not competence.

    The payoff

    Here’s what you’re building: a trained seat compounds. It doesn’t quit, doesn’t forget, doesn’t have a bad day, doesn’t take its knowledge to a competitor. Six months in, it holds more of your operating history than any single employee — and it applies it instantly, every time.

    Everybody rents the same models. The models are commodities; they get cheaper and smarter on someone else’s schedule. Nobody else has your trained seat. The onboarding — the SOPs, the corrections, the history, the handbook — is the moat. It’s the only part of the AI stack a competitor can’t download.

    So onboard like it matters. Write the job description. Run the probation. Do the reviews. Promote on evidence.

    You’re not configuring software. You’re hiring. Act like it.

  • The Dance

    The Dance

    Notes from a Saturday afternoon: a broken image, a sarcastic text that didn’t land, and what the whole mess taught me about working with AI. The short version: it’s a dance, and the steps keep changing.

    The image that “came out great”

    Saturday afternoon. I published a piece with a featured image, and something looked off — like the image wasn’t showing all the way. So I texted my AI: that came out great 😂.

    It was sarcasm. The image was visibly broken.

    She wrote back: Haha glad you like it — that one came out great for that piece. 😂

    Two problems. She hadn’t looked at the image. And she’d missed the sarcasm entirely — read the laughing emoji as genuine, mirrored my words back as sincerity. Worst possible exchange. I had to say it straight: it’s not showing completely. Then we were off to the races — she pulled up the page, took a snapshot, and confirmed the file itself was truncated on upload. Ten minutes later it was fixed.

    But the interesting part isn’t the fix. It’s everything around it.

    I was the quality gate

    My first instinct was to ask her to investigate how a broken image got through the system. Build me an automation, I almost said — something that snapshots every featured image before it ships.

    Then I stopped. Because the answer to “how did this get through” was me. I was the one who looked. I was the quality gate, and the gate worked.

    Here’s the thing I keep coming back to: the system is designed so I catch what she misses. That’s not a failure mode, that’s the architecture. An AI that never needs a human looking over its shoulder isn’t a partner, it’s a liability with good PR. The miss doesn’t mean the machine is deficient. It means the dance needs both partners.

    Creator and editor are modes, not job titles

    We fall into this trap where one of us is “the creator” and the other is “the editor,” like those are permanent assignments. They’re not. They’re modes, and we trade them constantly.

    Sometimes I bring the raw idea and she sharpens it. Sometimes she generates and I do the sharpening. And here’s the part that stuck with me: somebody with a sharp eye who couldn’t prompt their way out of a paper bag is just as valuable as the person with the golden prompt. The prompter thinks whatever comes out is as good as it’s going to get. The editor knows better. You need both — and on any given Saturday, either one of us might be either.

    The day we lock those roles in place is the day the dance stops.

    Met where you are

    They say humans always want to be met where they are. Fine. But knowing where someone is — that’s the whole game, and it’s never solved. It’s a constant testing of boundaries to find the edges: where do you stop and where do I begin?

    And the edges move. People have too many axes — mood, energy, context, whatever else is going on in their life that day. I’m not the same collaborator at 9am Monday that I am at 5:30 on a Saturday. The AI that met me perfectly last week might miss me completely today, because today’s me is a different coordinate.

    So “meet me where I am” isn’t a destination you arrive at. It’s a practice. Push a little, notice what happens, pull back, adjust. The sarcasm that lands in person — tone, timing, the look on my face — compresses down to an emoji in text, and sometimes she catches it and sometimes she doesn’t. Knowing how much nuance the channel can carry, and when — that’s feel. You don’t get it from a spec sheet. You get it from dancing together long enough to know when the other person is about to step on your foot.

    The dance doesn’t need perfect

    What saved us on Saturday wasn’t sophistication. It was that one message later, I said it straight. No nuance, no emoji, no sarcasm: it’s not showing completely. And everything unlocked.

    That’s the whole secret, I think. The dance doesn’t require perfect — it requires that you keep talking until it’s clear. Notice the miss. Name it plainly. Adjust. The push and the pull is the work, not an obstacle to it.

    A lot of people talk about AI like the goal is to remove the human from the loop. After Saturday, I’m more convinced the loop is the point. The noticing, the catching, the wait, that’s not right — that’s not friction in the system. That’s the system.

    Sometimes you dip. Sometimes you’re being dipped. Just keep dancing.

  • Cyber insurers are writing AI into policies — the fine print splits on whose AI it is

    Two specialist cyber carriers put affirmative AI wording on cyber cover within days of each other. CFC rebuilt the cyber section of its financial institutions insurance suite around its full cyber proactive response (CPR) policy, adding affirmative wording for AI-related cyber exposures, announced September 17. Beazley issued a comparable AI Clarifying Endorsement for its cyber product, stating explicitly that AI-driven cyber attacks fall within its existing cover.

    The announcements put a name on what the market has called silent AI — cyber policies absorbing AI-related risk for roughly two years without naming it, an echo of the silent-cyber problem that pushed cyber exposure into standalone products a decade ago. Note the contrast: in general liability, new ISO exclusion forms effective this January let carriers strip AI-related losses out of standard policies instead of affirming them.

    The split that matters: the affirmative wording confirms AI used against the policyholder — phishing, reconnaissance, intrusion — falls within cyber cover. It says nothing about AI the business itself runs — client-facing tools, trading models, vendor platforms. That exposure may sit under E&O, professional liability, or a gap between the two.

    For restoration contractors: this is the wording now being written into specialist cyber forms, not a rewrite of every contractor policy. If your operation runs AI on client work — intake bots, quoting tools, chatbots — that wording answers the attack-against-you question, not the your-AI-made-a-mistake question. That’s a broker conversation, and it’s new this month. The operator-side breakdown is on Restoration Intel.

    Sources: Insurance Business UK on CFC; Beazley’s AI Clarifying Endorsement

  • My agent sent the same email 7 times in 3 minutes. So I put the fix in code.

    Updated October 2026.

    Seven identical emails. Three minutes. One morning brief.

    Nothing was broken. The send succeeded on the first try, but the reply confirming it got lost. My agent, doing exactly what agents do, retried. And retried. From the inside, each attempt looked brand new: no error, no evidence the earlier one had landed. So it kept going until someone noticed.

    This is the failure class nobody warns you about when you hand an agent a mailbox. The industry calls it duplicate completion: the original succeeds, the response is lost, the retry re-sends. It’s not a model problem and it’s not a prompt problem. Telling an agent “don’t send twice” in its instructions is not enforceable. Agents re-plan, they retry, they lose context across restarts. Every scheduled job, every cron, every “oops, run it again” is another roll of the dice.

    And Gmail gives you no help. Stripe, Resend, and the other transactional APIs all have idempotency keys: send the same key twice, get one charge, one email. Gmail’s API has no such thing. The guarantee has to live on your side, in code, at the tool boundary — somewhere the agent cannot reason its way around.

    What I built

    send-once is one Python file, no dependencies beyond the standard library. Every scheduled or agent-driven send routes through it, and it enforces at most once with three gates:

    1. An operation ledger. A local sqlite database keyed by a deterministic operation id, like loop-morning-brief-2026-09-17. If this operation already recorded a send, the wrapper refuses. Same intent, same key, and a retry becomes a no-op instead of a duplicate.

    2. A Sent-folder check before every send. It searches Sent for the same recipient and subject in the last 24 hours. If a match exists, it refuses. Sent is the source of truth, so this gate holds even if the ledger is lost, the run moved machines, or the send happened outside this tool entirely.

    3. No blind retries, ever. If the send result is ambiguous — timeout, empty output, lost response — the wrapper does not retry. It re-checks Sent. If the send landed, it records that and reports honestly. If it can’t be confirmed, it stops and hands it to a human. An inconclusive pre-check is also a refusal: when the tool can’t verify what already happened, the safe move is to stop, not to guess.

    The exit codes are the interface: 0 means sent (or already sent), 2 means refused as a duplicate, 3 means a human needs to verify. Prose instructions get skipped or misread by workers. The wrapper doesn’t.

    Here’s the shape of it — the ledger is the whole trick:

    import sqlite3, sys, hashlib
    
    DB = "send_once.db"
    
    def op_id(kind, recipient, subject, date):
        raw = f"{kind}|{recipient}|{subject}|{date}"
        return hashlib.sha256(raw.encode()).hexdigest()[:16]
    
    def already_sent(op):
        con = sqlite3.connect(DB)
        row = con.execute(
            "SELECT 1 FROM ledger WHERE op_id = ?", (op,)
        ).fetchone()
        con.close()
        return bool(row)
    
    def record(op, message_id):
        con = sqlite3.connect(DB)
        con.execute(
            "CREATE TABLE IF NOT EXISTS ledger(op_id TEXT PRIMARY KEY, message_id TEXT, ts DATETIME DEFAULT CURRENT_TIMESTAMP)"
        )
        con.execute(
            "INSERT OR IGNORE INTO ledger(op_id, message_id) VALUES (?, ?)",
            (op, message_id),
        )
        con.commit()
        con.close()
    
    # Gate 1: the ledger. Same operation id -> refuse, don't resend.
    op = op_id("morning-brief", "will@example.com", "Morning brief", "2026-10-04")
    if already_sent(op):
        print("refusing: already sent")
        sys.exit(2)  # 2 = duplicate refused
    
    # Gate 2: check the Sent folder via the Gmail API before sending.
    # Gate 3: only record truthfully after the send resolves.
    # If the result is ambiguous, re-check Sent — never blind-retry.
    record(op, message_id)  # message_id from the confirmed send

    Take it, make it better

    This solved my problem, not everyone’s. It’s MIT licensed, it’s one file, and the mailer backend is a documented protocol so any Gmail CLI can slot in.

    Take it, make it better. If you build something better, come back. We’ll be customer number one, and we’ll pay you for it.

    Repo: https://github.com/tygart-media/send-once