Tag: AI Operations

  • Your Coding Agents Live on One Machine. T3 Code Puts Them in Your Pocket.

    Your Coding Agents Live on One Machine. T3 Code Puts Them in Your Pocket.

    Your coding agent is running on your desktop. You are not at your desktop. That gap — between the machine where the work happens and the person who has to approve the next step — is the whole problem T3 Code exists to close.

    T3 Code is an open-source “agent harness control surface” from the T3 Tools team (the repo is pingdotgg/t3code on GitHub, MIT licensed). It is not a model. It is not a new coding agent. (If you are still choosing between the agents themselves, start with our Claude Code vs Cursor comparison – this piece is about what sits on top of whichever one you picked.) It is a small server that runs on the machine where your agents already live, and it remote-controls the ones you already pay for: Claude Code, Codex, Cursor, Grok Build, OpenCode, Google Antigravity, and fx. A phone app, a web app, a desktop app, and a terminal command all drive the same threads.

    The demand is not subtle. The repository passed 50,000 stars this week — 50,470 when we read it on the morning of November 7, 2026, up more than 16,000 in the week to November 6, the largest weekly gain of any AI project on GitHub. It was created in February 2026. Nine months from zero to fifty thousand stars is what a widely felt gap looks like when somebody finally fills it.

    What it actually does

    Install the t3 command on the host machine, connect at least one provider using that provider’s own login (claude auth login, codex login, agent login for Cursor — Antigravity needs no CLI; you enable it in Settings and sign in with Google), and start the server. It listens on your machine, port 3773 by default. Register a project, start a thread, and the agent works in that project exactly as it would if you were sitting there.

    From that point you have four ways to reach the same work:

    • The phone app (iOS and Android, free) — start runs, watch threads, approve a step or send a correction, browse files, review diffs, run version-control actions, use the terminal. The Android listing describes it as “pretty much the full power of the desktop app.”
    • The web app — the same surface in a browser.
    • The desktop app — Electron, on Windows, macOS, and Linux.
    • The t3 CLI itself — t3 thread start, t3 thread send, t3 thread list from any terminal. A thread waiting on you exits with its own signal, so scripts can tell “finished” apart from “blocked on the human.”

    Two connection routes matter. On your own network — or over a private network like Tailscale — you pair a device directly with a one-time link or QR code, no account at all. Away from home, T3 Connect is the managed relay: no router configuration, sign in on the host, sign in on the phone, pick your machine. Per the hands-on guide we worked from, a free T3 Connect account links up to 3 machines.

    Every thread writes to its own branch. When the work is good, one button opens the pull request on GitHub with a generated title, body, and changelog — after you’ve reviewed the diff inline. The agent does the typing. You keep the merge.

    What it costs

    Nothing for the software. T3 Code is free and MIT licensed — “If you don’t like something, fork it” is a headline feature on its own site, with the fork command printed under it. It does not resell tokens and it does not hold your credentials hostage: you bring your existing subscriptions, log in with each provider’s own flow, and model usage is billed by your provider exactly as before. “Bring your own sub. No keys resold. No quota caps.”

    That pricing shape is the point. The control layer is becoming a commodity; the subscriptions underneath it are the spend. A control plane you can fork can never raise its rent on you.

    The honest limits

    The README says it in plain words: “We are very very early in this project. Expect bugs.” Believe it. The stable release this week is v0.1.7. This is a fast-moving, nine-month-old project, not settled infrastructure, and the team is mostly not accepting contributions yet.

    Three operational limits follow from the design:

    1. The host has to stay awake. Your agents run on your machine, not in T3 Code’s cloud. On Linux and macOS you can install the server as a background service (t3 service install). Windows gets no background service — you leave the desktop app running, and closing its last window stops the local server.
    2. Remote access is a security decision, not a default. On a local network, the pairing code is the only thing between your agents and every other device on that network. Pair per device with fresh one-time links, don’t enable LAN access on a network you don’t trust, and prefer a private network like Tailscale for anything beyond the couch.
    3. It controls agents; it doesn’t supervise them. T3 Code moves the approval to your phone. It does not decide whether the work order was well-specified, whether the agent’s output is right, or whether the diff should merge. That judgment problem is the same one behind our MCP tool-poisoning checklist: the harness around the agent is where the safety lives. The judgment layer is still yours.

    How this maps onto a multi-seat shop

    We run several agent seats — Claude, Cursor, Antigravity, Grok — and the standing problem with seats is presence. Work stalls at approval points because the human isn’t at the keyboard the agent is attached to. Anyone who has watched a finished piece of work sit idle for hours because it was waiting on a tap that could have happened from a phone knows this stall by name.

    Against that setup, T3 Code is a fit in three specific places:

    • It covers the seats we actually run. Claude Code, Cursor, Antigravity, and Grok Build are all on its provider list today. One surface over all of them beats four vendor apps with four different ideas about remote access.
    • It keeps the work on our hardware. The alternative shape — cloud agents that keep running while your machine sleeps — means your code and data live on the vendor’s machines by design. T3 Code’s answer is the opposite trade: your machine stays the plant, and the phone is just the window into it.
    • It matches how the work is already shaped. Bounded task per thread, worktree or branch isolation for unreviewed work, diff review before merge — that’s the same discipline as a work order with receipts. The remote control doesn’t change the discipline; it removes the geography from it.

    Where it doesn’t fit is just as clear. It doesn’t replace the harness — the work orders, the context, the QC on what comes back. A remote control for a badly briefed agent just lets the agent be badly briefed from further away. And for work that genuinely has to run while every machine you own is off, a self-hosted control surface is the wrong tool no matter how good the app is.

    The verdict

    Real, and early. The star count is the loudest signal, but the quieter one is the shape: open source, multi-provider, your hardware, your subscriptions, forkable if the team ever takes it somewhere you don’t want to go. That is the correct shape for a control layer, and it’s the shape the closed vendor apps don’t offer.

    Try it the cheap way: one machine, one provider you already pay for, one bounded thread started at your desk and approved from your phone. If that loop feels like the missing piece, it earns a place. If it doesn’t, you’ve spent ten minutes and nothing else — which, for a tool at version 0.1.7, is exactly the right size of bet.

    Sources: the T3 Code repository and README (github.com/pingdotgg/t3code — 50,470 stars, 9,813 forks, MIT license, repo created February 8, 2026; read November 7, 2026); t3.codes (positioning, provider list, fork-it terms; read November 7, 2026); AI Frontier Post hands-on tutorial, “T3 Code: drive Claude Code, Codex and Cursor from your phone” (install, pairing, service, and T3 Connect machine-limit details, verified end-to-end by its author against v0.1.7; published November 7, 2026).
  • Slack Is the Last Mile

    Slack Is the Last Mile

    Will Tygart | Tygart Media | November 3, 2026

    I was supposed to be in Seattle today. I stayed at my desk instead — and realized I was already standing in the thing I was going there to learn about.

    Download this article as a PDF — free, no email, no strings.

    Writing about this? Take the free Field Kit (PDF) — the argument, the facts, and what it means industry by industry. Built to feed your bot.

    I had a plan for today. Salesforce was bringing World Tour Essentials to Seattle — Tuesday, November 3, 1:30 to 5:00 p.m. at the Sheraton Grand Seattle — and Slack was a big part of why I wanted to be in the room. Not for the keynotes. For help. I needed help understanding something I could feel but could not quite name about how work moves now, and I figured the people who built Slack could name it for me.

    Then I sat down, looked at the work in front of me, and stayed here.

    Not because the trip stopped mattering. Because somewhere between deciding to go and deciding to work, the understanding I was going to Seattle to get showed up on its own. I was already stepping in it. I had been stepping in it for a couple of years, in different ways, without ever calling it by its right name.

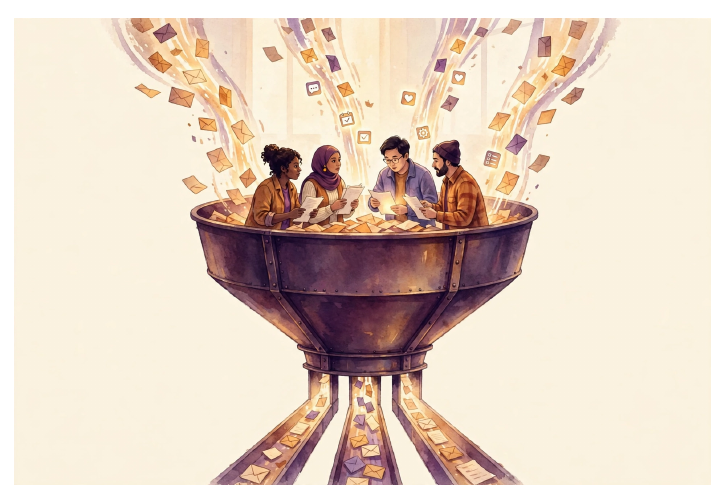
    This is the name: Slack is a hopper. Slack is the last mile. And I owe them a tip of the hat for building it that well.

    I was going to Seattle to get help understanding this

    That is an honest place to start, because it is the truth of how most operators learn anything that matters. You do not learn it from a diagram. You live inside a problem long enough that the shape of the solution starts to press on you, and then you go looking for somebody who can confirm the shape.

    My problem, for a long time, has been intake. Everything arrives at once. Messages, files, links, requests, half-finished ideas, client problems, things somebody found on the internet at midnight and thought I should see. If you run a small operation in 2026, you do not have a shortage of material. You have a flood of it, and the flood does not sort itself.

    What you need is a place where it all lands first. One place. Wide at the top, forgiving about what gets thrown in, and built so that nothing important falls on the floor while you figure out what it is. In the trades we would call that a hopper. You dump the load in the hopper, and then — and only then — does it flow down to the work.

    I kept building versions of that idea in my own systems without noticing that I had spent years working inside a very good one that somebody else had already built, refined, and put in front of millions of people.

    The last mile is not where work travels. It is where work arrives — and becomes a decision a human can actually make.

    What “last mile” means here

    Delivery people use “last mile” for the hardest part of the route: not the highway, not the warehouse, but the final stretch to the door. That stretch is where packages get lost, where addresses turn out to be wrong, where a human being has to be home and paying attention.

    Work has the same problem. A tool can move data across the internet in milliseconds. Getting that data to land in front of the right person, in the right context, with enough of the conversation around it that the person can judge it — that is the hard stretch. Slack solved that stretch, and they solved it so completely that most of us stopped seeing it as a solved problem at all. We just call it “where work happens,” because that is what it feels like from the inside.

    Slack built a hopper with people standing inside it

    Here is the part I had not fully appreciated until today, and it is the whole article in one sentence: a dumb hopper just collects. Slack collects and gives people a place to stand inside the collection while it is still arriving.

    Material lands — a message, a file, an alert from another app, a thread that starts as a joke and turns into a decision. Before any of it flows downstream into a ticket, a document, a task, or a build, people can do the most human work there is with it: look at it together, argue about what it is, ask what is missing, decide who owns it, and decide whether it deserves to flow at all.

    That middle station — triage and discussion, inside the intake, before the routing — is what separates a hopper from a pile. A pile is where material goes to be forgotten. A hopper with people standing in it is where material goes to be understood.

    • Everything can land. Channels take the messy, early, unformatted version of a thing, which is the only version most real work ever starts as.
    • Context travels with it. The thread keeps the argument attached to the artifact, so a decision made downstream still carries its reasons.
    • People decide before machines execute. The flow downstream is a choice, not an accident of arrival order.

    Once you see Slack that way, a lot of its design choices stop looking like chat features and start looking like intake engineering. Threads are sorting. Huddles are a quick triage call without leaving the hopper. Canvases and lists are what happens when triaged material needs a more durable shape before it moves on. Search is the ability to reach back into the hopper and prove what actually arrived, and when, and who touched it.

    That is not a messaging app that got popular. That is infrastructure.

    They say it themselves — in plainer language than mine

    I want to be careful here, because a tip of the hat should not put words in anybody’s mouth. So let me use theirs.

    Salesforce now describes Slack as “The Agentic Work Operating System” — a platform for building, automating, and coordinating work across your whole tech stack, in the one place where conversation leads to action. Their platform materials talk about connecting people, data, and agents in a single workspace, with more than 2,700 agents and apps available in the Slack Marketplace by their count, and Slack included with new Salesforce orgs.

    And when Slackbot — the assistant built into Slack — was relaunched as an enterprise agent, Parker Harris, Slack’s CTO and a Salesforce co-founder, said it in the sentence I wish I had written:

    “Slackbot isn’t just another copilot or AI assistant. It’s the front door to the Agentic Enterprise.”

    Front door. Last mile. Hopper. These are three ways of saying the same true thing from three different chairs. The front door is where everything enters. The last mile is the final stretch it has to survive to reach a person. The hopper is the vessel that holds it while people decide what it is. Salesforce is naming the doorway. I am naming the room behind it.

    What matters is that they clearly know what they built. This is not a company stumbling into relevance in the agent era. Their own roadmap reads like a deliberate answer to the question every operation is now asking: if agents are going to do more of the work, where do humans and agents meet, look at the same material, and agree on what happens next? Their answer is: in Slack, in conversation, where the work already lives.

    My read: You cannot claim the metaphor for yourself when the builder already printed it on the box. What you can do is confirm it from the floor — as an operator who has run real work through it — and say plainly that the claim holds up.

    The plumbing is real, and it runs both directions

    A hopper only earns its keep if things can flow out of it as reliably as they flow in. This is where Slack’s last couple of years get genuinely impressive, and where my own understanding finally caught up today.

    The connective tissue is MCP — the Model Context Protocol, the open standard that gives AI agents a consistent, secure way to use outside tools and data. Slack now works both sides of that protocol, and the two directions matter for different reasons.

    Inbound: agents can reach the hopper

    Slack hosts an official MCP server. Approved AI clients outside Slack can search conversations, read channel history, and post updates through a standardized interface, under workspace permissions that admins control. In plain terms: the material in the hopper is no longer trapped in the hopper. An agent working elsewhere can come and get the context it needs, with receipts, instead of a human copying and pasting it across.

    Outbound: the hopper can reach everything else

    Slackbot, in turn, now works as an MCP client. From inside a conversation, it can call out to connected apps and their MCP servers — documents, tickets, CRM records, design files, calendars — figure out which tool fits the request, and bring the result back into the thread. Salesforce has paired that client with its own MCP servers for CRM, analytics, and data, so a person can ask in plain language and watch work that used to mean six tabs happen in one conversation.

    Put the two together and the architecture is complete: everything your stack produces can land in one conversational place, people can stand there and triage it together, and both humans and agents can route it onward without the place itself becoming a bottleneck or a silo. Add Slack’s Real-Time Search API, its workflows and intake templates, and the long-standing app ecosystem underneath, and you do not have a chat tool with integrations. You have an operating layer with a conversation on top of it.

    I do not say that lightly. I build intake and routing systems for a living right now. I know what the hard parts are. They did the hard parts.

    What two years of working in it teaches you

    I could not have written this article two years ago, and I could not have written it from a conference seat today either. That is not modesty. It is the actual lesson.

    I have worked with Slack in different ways across the last couple of years — as a place where a small team coordinated, as a surface other tools reported into, as a room where material arrived faster than anybody could gracefully handle it. Some of those uses were good. Some were chaotic. All of them taught me something a keynote cannot: you learn what a hopper is by watching what happens to the load when nobody is tending it, and what happens on the good days when somebody is.

    On the good days, Slack is the calmest place in an operation. The material is visible. The argument about the material is visible. The decision, when it comes, is visible — and because all three live in the same place, nobody downstream has to guess why a thing was done. That is worth more than any single feature. Most operational pain is not a shortage of tools. It is a shortage of shared, inspectable context at the moment of decision. Slack manufactures that context as a byproduct of people simply working there.

    The honest footnote

    Here is the part a sponsored post would leave out, and the part that makes this a tip of the hat instead of an advertisement: I stepped away from Slack for my own day-to-day operations this fall. The desktop app came off my laptop. Work that used to route through our Slack workspace started routing elsewhere.

    That was not Slack failing. I want that on the record, because it is the most credible thing I can say in their favor. The hopper did not break. What happened is simpler and more human: there was nobody left standing in ours. A hopper is a social machine as much as a technical one. If the people who triage do not live in the room anymore, the room goes quiet no matter how well it is built — and an operator follows the people, not the platform.

    If anything, leaving taught me the value more sharply than staying would have. You find out what a place was doing for you when the material starts landing somewhere with no one standing in it.

    What nobody in that room does yet

    A tip of the hat does not have to pretend the work is finished. So here is the one honest coda, offered the way an operator offers it to a builder whose work he respects: there is a station missing inside the hopper, and as far as I can tell, nobody has built it yet — not in Slack, and not anywhere else I have looked.

    Every triage system I have seen, on Slack and off it, sorts material the same three ways. Is it real, or is it noise? Who owns it? How urgent is it? Those are good questions. They move work.

    But none of them asks the fourth question: is what is in this material actually true?

    A message can be real, owned, and urgent — and still be wrong. A summary can be fluent and false. A number can arrive with total confidence and no source behind it. In an era when more and more of what lands in the hopper was written or assembled by machines, sorting by urgency without checking for truth is how fluent errors get routed downstream at machine speed, with a human’s name on the approval.

    I do not raise that as a criticism of Slack. Slack built the room, the doorway, and the plumbing. Verification is a different discipline from intake, and it may well belong to the people and agents standing in the room rather than to the room itself. In my own work, that is exactly where I have ended up putting it: material waits, gets checked against its sources, and only flows when a person gives it the tap. The packet does not assemble itself just because it arrived.

    But I will say this: whoever builds that station well will build it in a place shaped like Slack, because that is where the material and the people already meet. The room comes first. The checking happens inside it. In that sense, even the next idea I am chasing is downstream of what they built.

    They built the last mile. The next mile starts inside it.

    A tip of the hat, plainly

    So I did not make it to Seattle today. The Sheraton Grand will host plenty of people who needed to be there more than I did, and Salesforce will run a good show — expert sessions, live demos, hands-on learning, all of it free, by their listing. I hope somebody in that room has the moment I had at my desk, only faster: the recognition that the thing they came to understand is a thing they have already been living inside.

    I stayed and worked instead. And the work itself kept handing me the evidence. Every time material arrived and needed a place to land where a person could see it, judge it, discuss it, and route it — the shape in my head was the shape Slack spent years building and refining. I could not have done the work I have done, the way I have done it, without having worked with Slack across the last couple of years in different ways. It taught me the pattern by letting me live in it.

    That is what a tip of the hat is for. Not a purchase. Not an endorsement deal. Just an operator, in print, saying to a builder: you did the last mile really well, you have been doing it well for a while, and some of us who build in your shadow know exactly how hard that stretch is — because we have watched lesser versions of it fail, and we have watched yours hold.

    Slack is the last mile. They built the front door, the hopper, and the room where people stand inside it and decide together. Everything else in the modern stack flows because that room exists.

    Tip of the hat. Now back to work.

    — Will Tygart
    Tygart Media, Puyallup, Washington

    Sources

    Illustration is an original artwork created for this article. Product names belong to their owners. This article is an independent operator’s account, not a Salesforce or Slack publication.

  • AI Governance Is the Gate That Caught the Thing

    AI Governance Is the Gate That Caught the Thing

    Most AI governance is written by people who have never had to govern an agent that could actually break something. It reads like insurance paperwork: frameworks, maturity models, principles laminated on a wall. Then a real agent, on a real Tuesday, publishes your drafting notes as if they were the article — and the framework has nothing to say about it, because the framework was never in the room.

    We run a small agency where AI agents do real production work every day: research, drafting, publishing, measurement, and an unattended night queue that runs while we sleep. Governance, for us, is not a document. It is the set of gates that have caught real things. Every rule below exists because something specific got past us first, and the rule is the scar.

    Governance starts with who is allowed to remember

    The agents are stateless; the memory lives in one place. Every agent we dispatch starts cold. It knows nothing about our clients, our sites, or yesterday’s decisions until its work order tells it. That sounds like a limitation. It is the control surface. Because the agent holds no standing memory, it holds no standing permissions either — every job is scoped, priced, and bounded by the order that created it, and when the job ends, the access ends with it.

    The work order itself is a governance document. It states the whole price up front, names the points where a human must tap before work proceeds, and lists what the executor may ship directly and what it must hold. An agent that has to ask a question the order should have answered is not a governance failure by the agent. It is a drafting failure by us, and we treat it that way.

    Draw the doors as lines, not policies

    Four things always need a human tap: money, credentials, outbound sends, and publishing. Everything else, the fleet runs on its own. That split is the entire access policy, and it fits in one sentence because it has to survive contact with a tired operator at the end of a long day. Policies that need interpretation get interpreted — usually at the worst moment, in the most generous direction.

    Credentials get the hardest line. Our agents never hold passwords, never see them, never pass them along. Work that reaches a login the agent cannot complete through an already-signed-in session does not get worked around. It stops, logs a hold, and waits for the human whose door that is. One night this fall, a run reached a registry login at three in the morning. The operator could not face the tap, said so, and went to bed. The work was built to survive stopping, so stopping cost nothing. The credential never moved. That is what a line is for: it has to hold when nobody has the energy to argue with it.

    The risk is not a rogue agent. The risk is a report you believe.

    Every serious failure we have had was a verification failure, not a rebellion. A judge model, asked to grade drafts against a length limit, invented word counts that were off by a quarter to a third — confidently, in both directions. A publish report stated a post ID from memory instead of reading it back from the result file, and the number was wrong. A page was verified from its HTML source and declared fine while its signup form rendered as blank white cards. Drafting notes were once published as article content because the check stopped at “the words are there.”

    So the rule is mechanical: proof lives at the receiving end. Numbers get read back by value from the file that recorded them. Pages get verified as rendered pages, in a browser, the way a reader sees them — not from source. A finished article must show visible structure, or it is a hold, not a publish. None of this requires trusting the agent less. It requires trusting the report exactly as far as the evidence under it, which is where trust should have been calibrated all along.

    We also measure trust per model, the way you would per employee. In scored head-to-head runs on identical briefs, exactly one of our models graded perfectly — every defect real, no invented ones — so that model holds the verifier seat. Another writes fast and clean but invents defects when it judges, so it drafts and never judges. The cheapest tier once certified work it had not actually checked, so its output is never trusted without a pass behind it. “The AI said so” is not a control. A scorecard is.

    Failures become regressions, not folklore

    Every break gets an ID, an entry in the failure ledger, and a gate. When the night queue failed in a new way, the failure was written down with its cause and its receipt, and a regression check was built that fails the next run if the same shape reappears. The ledger is unglamorous. It is also the difference between an operation that learns and an operation that just has stories. Governance that lives in people’s memories leaves with their mood, their weekend, and eventually their employment. Governance that lives in a gate runs every time.

    Each work order also carries one pre-decided instruction for the moment something breaks: if a step’s end state cannot be verified, stop that step, log the hold, and move to the next independent step. Never improvise past a failed check. The decision is made in advance, in calm, because the middle of a failing run is the worst possible place to invent policy.

    The 3 a.m. test

    Here is the only governance question we ask anymore: what can this system not do at 3 a.m.? Our night queue runs unattended with hard caps — a maximum number of jobs, a maximum number of attempts, a hard stop before dawn, and a pause switch that halts everything if a single file exists. Agents working overnight cannot spend money, cannot send anything to anyone, cannot touch a credential, and cannot publish. They can draft, measure, and report. Morning is a review: a human reads what the night produced, approves what is good, and the approvals are the fuel for the next day’s work.

    That is the whole philosophy. Governance is not the set of things your agents are allowed to do. It is the set of things they structurally cannot do while you are asleep, plus the evidence trail that lets you check everything else over coffee.

    What this is not

    This will not satisfy a compliance department, and it is not meant to. If you handle medical records or other people’s money under regulation, you need the paperwork kind too. But the paperwork kind alone will not save you from the ordinary failures — the believed report, the generous interpretation, the confident invented number — because those failures are not compliance failures. They are operating failures, and they happen at every scale, in shops with two people and in companies with two thousand.

    Start where the risk actually is. Give the agents no memory and no keys. Draw four doors and hold them. Verify at the receiving end. Write every failure down and make it a gate. Then run the 3 a.m. test on your own setup, honestly, and fix what it shows you. The framework can come later. The gate that catches the thing comes first.

  • Wonder Full Stays in the Seat. The API Key Is a Different Promise.

    Wonder Full Stays in the Seat. The API Key Is a Different Promise.

    On October 12, 2026, Meta launched two models that share a name and almost nothing else. Muse Wonder is a product you can call: it sits on the Meta Model API at $4.00 input, $0.20 cached input, and $20.00 output per million tokens, and inside Muse Code. Muse Wonder Full is a model you can only sit in front of: it exists exclusively inside a Muse Code subscription, on the Power Usage and Maximum Usage plans. The decision an operator makes before pointing either one at a real repository is not which model is smarter. It is which promise they are buying — and the seat’s default promise is not the one most buyers think they made.

    The frontier model is a seat, not a SKU

    Meta’s own availability table is the whole story in four cells. Muse Wonder (muse-wonder-1.0): available on the Model API, standard mode only, and in Muse Code on pay-as-you-go and every plan. Muse Wonder Full: not available on the API at all — Power Usage and Maximum Usage subscriptions only.

    There is no back door. Setting reasoning effort to “max” on muse-wonder-1.0 does not select Wonder Full; Meta’s models page says so in plain words. Meta publishes no API model ID for Full. A team that wants Full behind its own product has, in the words of one launch-week review, no path at any price — businesses can test it inside Meta’s coding environment and cannot deploy it through the standard API.

    The seat prices are printed on the Muse Code product page: Everyday Usage $5 a month, High Usage $15 at 5× the Everyday allowance, Power Usage $50 at 20×, Maximum Usage $200 at 80×. Power is the cheapest chair that includes Wonder Full. The allowances run on five-hour and weekly resets, and per the Terms, a subscription’s per-period allowance expires at the end of each period and does not roll over. On Maximum, when the allowance is gone, Meta’s documented way forward is to wait for the refresh.

    The credential is a leash

    The subscription applies to the API key Meta automatically connects during Muse Code CLI onboarding, and the subscriptions doc is explicit about the boundary: “This credential is for use with Muse Code only.” The Terms give the arrangement its legal name — a Coding Harness Subscription — and the same restriction: the connected key “may not be used to access the Services outside the coding harness or to circumvent your subscription’s usage limits or billing.”

    Any additional API keys you create under the same account are billed pay-as-you-go, per token. So one Meta account holds two different commercial relationships at once: a flat seat that works only inside one CLI, and metered keys that work anywhere except that they can never call the frontier model. Budget them as two products, because Meta does.

    The default is the decision

    Here is the trap, and it is set by a default. “Muse Code subscriptions default to Contributor mode. In Contributor mode, you get more usage from your plan in exchange for letting Meta use your content — the prompts, code, files, and context you send, plus the model responses you get back — to train future Meta models.”

    A careful buyer can still walk into it. Meta’s Model Designation Policy lists Muse Wonder and Muse Wonder Full as Standard Models — the tier whose use constitutes Standard Services, where content is not used for training. The same policy then overrides the list: “If you access the Services through a Coding Harness Subscription, you are considered to be using the Contributor Services by default regardless of which Meta Model you select.” Terms section 3.3 says the same. In Muse Code, Contributor mode is not a model name. It is a subscription setting, and it is on.

    Turning it off is one toggle: open /settings in Muse Code. The help page states what the toggle does and does not do: “Turning Contributor mode off changes how much usage you get from your plan. It doesn’t change which plan you’re on.” How much usage changes, Meta does not publish — no ratio, no prompt count, no price difference appears in the documents. The honest line for a budget is that the size of the privacy discount is undocumented.

    Meta’s own warning belongs in every seat-setup checklist, quoted exactly: “You must not submit sensitive, confidential, or personal information to the Discounted Services. If your use case involves processing personal information, please use Standard Services.” Accounts with Zero Data Retention cannot use Contributor mode at all — and ZDR itself is an organization-level enablement Meta’s sales team turns on for Model API accounts, not a toggle in the CLI, and it does not cover requests made with a personal account.

    The switch does not reach backward

    The off-switch is prospective. Terms section 3.3: a change to Standard applies “prospectively only; it would not apply to Content previously submitted to the Contributor Services, and Meta’s rights with respect to that Content under Section 6 will survive the change.” Everything a seat sent while the default was on stays under the training grant after you flip the setting.

    Section 6.1 adds the subtler pull: “Content previously submitted to the Standard Services becomes Content submitted to the Contributor Services if it is included in any request to the Contributor Services, whether directly or as context or background for your prompts or instructions.” One later Contributor-mode session that pulls an earlier, clean conversation in as context reclassifies that content.

    The commitments page softens the arrangement with a safeguard and then qualifies it: before using Discounted Services content to train models, Meta “takes steps designed to disassociate that Content from your Accounts” — but Meta may use the same content for “evaluation, safety, abuse, quality, and policy review” without first applying those steps. And section 6.1 acknowledges the output side: models trained on your content may produce outputs “similar or identical to your Content,” including for third parties.

    The API shelf is labeled honestly

    On the API, the same choice exists — as a separate model name, printed on the pricing page where a buyer can see it. Contributor mode “isn’t available for Muse Wonder on Model API.” For Spark it is a different SKU: muse-spark-1.3-contributor and muse-spark-1.2-contributor at $0.10 input, $0.002 cached, $0.20 output per million tokens, against standard Spark at $1.25 / $0.15 / $4.25 — capped at 150 requests per minute against 3,000 for the standard IDs. The Muse Code product page labels the two rows without euphemism: the Contributor row is “Used to improve our products”; the standard row is “Not used to improve our products.”

    That is the contrast the seat hides. On the API, training is a priced, named, rate-limited variant a buyer selects on purpose. In the subscription, it is the factory setting of the harness — and the model table’s “Standard Model” label will tell a skimming buyer exactly the wrong story about which arrangement they are in.

    The operator’s checklist

    Decide the data arrangement before the repository, not after the first session. A public demo and a confidential codebase can run through the same agent on the same afternoon; they require different settings, and the setting is per-subscription, not per-conversation.

    Turn Contributor mode off in /settings before any client code, customer data, or contract-confidential material enters the seat — remembering that the flip protects only what is sent afterward, and that earlier standard content follows it if it is ever pulled back in as context.

    Buy the seat for the seat’s work. Wonder Full is a genuinely frontier tool for a person at a keyboard, and it is not a component. Anything your own product must call belongs on the API, in Standard mode, on keys you budget per token.

    This desk tracks Meta’s platform as it changes; the full rate card and the contributor tier’s arithmetic are in Meta Model API Pricing & Limits, and every Meta piece hangs off the Meta AI desk hub. The short version to tape above the desk: the model in the seat is not the model on the shelf, and the seat’s most consequential setting is the one nobody remembers choosing.

  • Review the Run, Not the Diff: Cursor’s Shareable Canvases in a Fleet Loop

    Review the Run, Not the Diff: Cursor’s Shareable Canvases in a Fleet Loop

    What shipped on October 16

    Cursor’s changelog entry dated October 16, 2026 — “Cloud Agent Canvases and Environment Improvements” — is three short sections long, and one of them changes the shape of a finished run: “Cloud agents can now build interactive canvases as part of their work. Share a finished canvas with your team by sending its link.” That sentence is Cursor’s. Everything in this section is theirs, from that changelog entry and the Canvases page of their docs, read October 19, 2026.

    A canvas, in their docs, is an interactive artifact that renders next to the chat: a standalone view laid out with sections, stats, and tables, instead of a long markdown table or a code block to scroll through. Ask an agent for a dashboard, an analysis, an audit, or a report, and Cursor opens the result in a canvas when a visual view is the better fit. The canvas is saved to the workspace’s canvas list, so you can reopen it, edit it, and rerun it later with fresh data.

    Sharing is a publish, not a forward. From the canvas toolbar you Publish — which publishes a share or refreshes an existing one — then copy the link and send it. What the link opens is a live snapshot: the same layout, charts, and tables, without rerunning the agent and without digging through the chat history. Teammates open it in the browser with read-only access. A Shared Canvases page on the dashboard lists the shares you published yourself, so you can reopen, copy, or delete your own; it does not list a teammate’s shares — for those, you ask for the link.

    The same release carried two more items, logged here for completeness. The Environments API is available in beta: a programmatic way to create and manage the cloud environments agents run in. And the environments themselves grew: up to 300 repositories per environment, with large environments loading 5x faster — Cursor’s numbers, not measurements of ours. Neither item is this piece’s subject; both are on the desk’s check list.

    The gate is part of the story

    A canvas link is not a public link. The docs are explicit: anyone on your team can open the link in the browser. Only members of your team can open a share, and you need to be on a team to share at all. Sending the link outside the team sends a door the recipient cannot walk through — which makes the canvas a team surface, not a publishing surface.

    Sharing is also a paid-plan surface with conditions attached. Shares can be created on paid plans — Premium and higher, Teams, Enterprise, and the legacy Pro, Pro+, and Ultra tiers; free accounts cannot create shares. Sharing requires a privacy mode that allows data storage, so Legacy Privacy Mode blocks it. And a team admin can turn shared canvases off for the whole organization from team settings. A shop adopting the feature checks those three gates before it builds a habit on them.

    A snapshot is not the run itself. The canvas shows the view as published; the chat, the reasoning, and the diff stay behind it. When the underlying numbers move, the share does not move with them — refreshing it is another Publish. A reviewer who needs the execution record still goes to the record. The canvas is the board on the wall, not the flight recorder.

    Where it lands in our loop

    Our loop fits in one sentence: a work order is written with everything the executor needs, the agent flies it, and the result is debriefed at the receiving end — the live page checked in a browser, the delivered file opened, the count re-added by hand. The debrief is where quality is decided here, and its surface depends on the seat. A cloud run launched over the API hands back result text. A Desktop sitting hands back a transcript and screenshots at verification points, which this shop trusts over any summary.

    A canvas inserts a third surface into that debrief: the agent arranges its own evidence — sections, stats, tables — into the board the reviewer actually opens. For the data-heavy work this shop runs constantly — citation pulls, model-catalog diffs, site audits — a rendered board is the shape the answer wanted anyway. Cursor’s docs make the same point from their side: canvases earn their keep on data-intensive tasks, where information arranged non-linearly is easier to digest than a wall of text.

    The approval moment in this shop is a tap on finished work. Will reviews results, not work in progress, and the decision lands on an artifact he can read in one pass. A canvas link is the first Cursor surface shaped exactly like that decision: open the link, read the board, decide. No repo, no diff, and no IDE sits between the finished result and the person approving it.

    The lane question the feature raises is a seat question. What reaches Stefani and Ziggy today is finished artifacts — live pages, PDFs, one-line summaries — because they work outside the operator’s seat. A canvas would be the cheapest of those artifacts to produce and the easiest to read, if the recipients hold team seats. The docs make team membership the door, so who holds a seat becomes a setup decision to make on purpose — not an assumption to discover after a link bounces off someone it was meant for.

    What is not established, labeled plainly: our production lane launches cloud agents over the API and receives text back. The docs describe canvases in the app surfaces — the Agents Window, the canvas toolbar, the dashboard. Whether a run launched through the API can produce a canvas, or return a share link, is not in the docs we read and not in our records. That question goes on the check list. It does not go into the workflow.

    One more mapping, labeled as intent rather than record. The docs say common canvas workflows can be packaged as skills, so every run that uses the skill returns the same output shape. In this shop’s language, that is a debrief template: the same board for every fleet run — what was asked, what landed, what the counts say, what failed. A debrief-canvas skill is the first experiment this change earns here. It has not run yet.

    Our record, stated plainly

    No canvas has appeared in our runs yet. Our run record — every cloud agent this desk has launched, reconciled from the API and watched daily — contains no canvas artifact and no share link as of October 19, 2026. The only “canvas” in that record is an agent named for a Google Maps canvas, a different sense of the word, and a standing reminder to grep carefully before claiming a first.

    So this piece is a map, written before the landing: what the feature is on the vendor’s own pages, what its gates are, and where it would sit in a loop that already exists. The check is decided. The next data-heavy Desktop sitting asks for its debrief as a canvas, by name, and the canvas gets read against the same sitting’s transcript — the surface we trust — before the desk adopts it anywhere. If the board and the record disagree, the record wins, and the disagreement gets written down on this page with a date.

    Method & settings — this piece

    Sources: Cursor changelog, entry dated October 16, 2026; Cursor Docs, “Canvases” (read October 19, 2026). Vendor facts are stated as the vendor’s; the secondary write-ups that surfaced this item were used as leads only, never as sources

    Our surfaces in this mapping: Desktop 3.25.9 on the laptop (read from the install itself, October 19, 2026); cloud agents over the API (model catalog baseline 46 models, October 16, 2026)

    Our canvas record: none — no canvas artifact or share link in our run record as of October 19, 2026. This is a mapping piece, not a hands-on report

    Desk rule: every fact carries its provenance and date — our record, or Cursor’s page, never blended

    Filed under the Cursor desk — the desk that runs Cursor as a production harness.

  • Meta Model API Pricing & Limits: Wonder, Spark, and the Cheap Tier That Trains on You

    Meta Model API Pricing & Limits: Wonder, Spark, and the Cheap Tier That Trains on You

    From the Tygart Media Meta desk. Prices below are Meta’s published rates, verified against Meta’s own pricing documentation on November 5, 2026, and cross-checked against our account’s live catalog on November 5, 2026. This page is the desk’s drift-watch surface: when Meta moves a number, this page is where the change gets recorded, dated. Desk home: Meta AI, Run in the Open.

    Meta’s pricing has one genuinely simple story and one trap. The simple story: a flagship priced exactly at the market’s flagship rate, a workhorse priced like a workhorse, both with million-token context and no long-context surcharge. The trap is a third tier that costs about 95% less — because you’re paying with your data instead. Here is the whole map, with the trap labeled.

    The API tiers (per million tokens)

    Model Input Cached input Output Rate limits (per team)
    Muse Wonder $4.00 $0.20 $20.00 3,000 RPM / 4M TPM
    Muse Spark 1.3 / 1.2 / 1.1 (Standard) $1.25 $0.15 $4.25 3,000 RPM / 4M TPM
    Muse Spark Contributor $0.10 $0.002 $0.20 150 RPM / 3M TPM

    Wonder’s $4/$20 matches the going flagship rate dollar for dollar — Meta is not discounting its best model, it’s daring you to compare it. Spark at $1.25/$4.25 is the tier a working shop will actually live on: a quarter of the flagship’s input price and under a quarter of its output price, with the same 1M-token context window and the same rate limits. There is no long-context premium at any length, which quietly removes a whole category of surprise bill. Web-search grounding, if you use Meta’s built-in tool, is $2.50 per 1,000 queries on top.

    The rest of the catalog is priced like utilities: Muse Image generates at a flat $0.01 an image, Voice Transcribe runs $0.18 per audio hour with diarization, and the SAM 3.1 segmentation model is $2.50 per 1,000 images — all three confirmed in our own account census on October 14, 2026. Spark’s maximum output is 131,072 tokens; Wonder’s maximum output is not stated on the pages Meta publishes, and this page won’t guess it.

    The Contributor trap: cheap because it trains on you

    Read the Contributor tier’s price again: $0.10 in, $0.20 out. That is not a sale. Meta’s own pricing page is plain about the exchange — in Contributor mode, Meta may use your prompts and the model’s completions to improve and train its products. Your discount is paid in data. Standard mode, at the prices in the table above, is the mode where your content is not used for training.

    Our house rule, printed so our future selves can’t negotiate with it: Contributor tiers are for disposable experiments only — never for client work, never for unpublished material, never for anything you wouldn’t read aloud in Meta’s lobby. The arithmetic isn’t close. A shop that routes real work through Contributor to save $4 a million tokens is selling its clients’ material at a price it would never accept in a contract. And one more wrinkle worth knowing: Muse Code subscriptions default to Contributor mode unless you turn it off — so the trap is also a default, and defaults are where shops actually live.

    The Cursor split: Spark is in, Wonder is out

    If your shop runs Cursor, your Meta options today are exactly one model long. Muse Spark 1.3 is a first-class Cursor model — added September 8, 2026, about six days after the model itself shipped — at the same $1.25/$4.25 rates, with full access to Cursor’s agent tools, a 300k context window by default or the full 1M in Max Mode. Muse Wonder is not in Cursor at all: no model page, no changelog entry, no announced timeline, and Cursor’s official bring-your-own-key program covers five providers — Meta is not among them. The base-URL override workaround exists, but Cursor staff describe it as unsupported and partially broken, it applies globally while it’s on, and it can never bring you Wonder Full. Bottom line from a shop that checked: for Meta inside Cursor, run native Spark 1.3; for Wonder, use the API.

    Muse Code plans — reported, not verified by us

    Meta’s own terminal agent, Muse Code, is sold by subscription as an alternative to per-token billing. The plan structure is verified on Meta’s documentation: four tiers — Everyday, High, Power, Maximum — with Power and Maximum including Wonder Full, the stronger flagship variant that the API does not sell at any price. The dollar figures below come from secondary reproductions of Meta’s pages, and we label them reported because we have not paid one yet: Everyday $5/month, High $15/month (5×), Power $50/month (20×), Maximum $200/month (80×). When this shop runs Muse Code through a real sitting, this section gets rewritten from receipts. Until then, it stays labeled.

    What the numbers don’t tell you

    Two costs never appear on a pricing page. The first is token hunger: independent launch-week measurement found Wonder slower to first token than its rivals’ median and thirstier with output tokens, and in an agent loop — where a model may be called hundreds of times on one job — a thirsty model at a fair per-token price can still be the expensive seat. The second is your own switching cost, which Meta has unusually lowered: one key speaking OpenAI and Anthropic protocols means the harness you already run is the harness you evaluate with. Our proof of that, and the gotcha that came with it, is in The Meta Model API, As We Run It.

    Last verified: November 5, 2026. The desk’s catalog watch re-reads Meta’s model list daily; pricing drift gets recorded here with its date, the same discipline this site applies to Claude’s pricing.

  • The Meta Model API, As We Run It

    The Meta Model API, As We Run It

    From the Tygart Media Meta desk — our own API key, our own test envelope, our own receipts. Desk home: Meta AI, Run in the Open.

    Every vendor will sell you an API with a launch post. What a working shop needs is duller and more valuable: does it answer, does it finish real work, what does it cost to find out, and what stupid thing will eat your first afternoon? On October 14, 2026, we wired Meta’s Model API into our own tooling and ran it. Here is the whole story, including the part where we blamed the API for our own mistake.

    The setup: one key, stored like it matters

    Meta’s developer platform is dev.meta.ai. You make a key in the dashboard, you put it in a vault — ours lives in our credential store, injected into the process only at run time, never written to disk, never pasted into a chat. Billing rides a partner-controlled card with a hard $25 test envelope on it. That envelope is a deliberate choice: a new platform earns production trust in stages, and stage one is “prove it works for pocket change.”

    The first check cost nothing: list the models. Our key read Meta’s catalog clean — nine models, from Muse Wonder down to a segmentation model we still haven’t touched. A key that can read the catalog is a key that works; everything after that is about the work, not the wiring.

    The proof: a work-order-shaped task, 52 seconds

    We pointed OpenCode — an open-source terminal agent, version 1.19.0 — at Meta’s API as an OpenAI-compatible provider, and handed Muse Spark 1.3 the kind of job this shop hands every seat: a written spec (SPEC.md), from which it had to produce a working Python module (a slug utility) plus a pytest suite covering it. Not a riddle, not a benchmark — a small, real, verifiable unit of work with a pass/fail at the end.

    Spark 1.3 finished in about 52 seconds. Mid-run it discovered pytest wasn’t installed in its environment, provisioned its own virtual environment, installed what it needed, and ran its tests: 8 of 8 passing. Then we did what we do with every seat’s output, including our own: we didn’t take its word. We re-ran the suite ourselves, added five extra cases of our own, read the code line by line. All green, code clean. Total damage to the $25 envelope across the entire day’s probing of every text model on the account: under two cents.

    The gotcha: our first failure was not Meta’s

    The first attempt “failed.” Silently. No error, no output — the run simply never came back. The natural conclusion is that the shiny new API is broken. The actual cause: opencode run hangs forever when its standard input is left open in a non-terminal session. Run it with stdin closed — </dev/null — and it works perfectly. No API fault, no key fault; a harness quirk that cost us one debugging cycle and taught us, again, the oldest lesson in this shop: when a new platform “fails,” check your own plumbing before you write the platform off. We’re printing the gotcha in the desk’s first article on purpose. The next shop that wires this API deserves to skip our lost afternoon.

    One API, three dialects — and why a shop should care

    The most consequential thing about Meta’s API is not any single model. It’s that the same key speaks three protocols: OpenAI’s Chat Completions, OpenAI’s Responses API, and Anthropic’s Messages API. Meta’s own quickstart documents pointing Claude Code at api.meta.ai by changing a base URL, Codex at the Responses surface, and OpenCode at the OpenAI-compatible endpoint — all with the one key.

    For a shop, that collapses a real cost. Harnesses are habits: your prompts, your permissions, your work-order formats, your muscle memory. A model provider that demands a new harness taxes every one of those. A provider that plugs into the harness you already run lets you spend your evaluation budget on the only question that matters — is the model any good at your work? It’s also a discipline on the provider: when switching is cheap, the model has to win on merit every month, not on lock-in. We like platforms that volunteer for that test.

    Two quirks worth knowing before your first loop. Reasoning is mandatory on these models: settings like reasoning_effort: "none" come back as errors rather than being quietly ignored, so sloppy OpenAI drop-in code can fail loudly — better than silently, but plan for it. And reasoning tokens burn against your output cap, so set generous maximums; a tight cap buys you empty replies, as our census probes found out so yours don’t have to.

    What this does not prove — yet

    One 52-second task proves the route works and the model can finish a small job cleanly. It does not prove Wonder’s ceiling, anyone’s reliability across a month of autonomous loops, or behavior under production load — and this desk won’t claim otherwise. The head-to-head that would actually settle the seat question — Composer vs. Spark in Cursor vs. Wonder through this API, same work order, same scoring — is scheduled and unrun, and it’s named that way on the desk’s front page. When it runs, it lands here, numbers and all, whichever way it cuts.

    Prices, tiers, and the one discount that should make you read the fine print twice are on the desk’s pricing page: Meta Model API Pricing & Limits.

  • What’s New in Cursor Is a Claim. Here’s How We Check It.

    What’s New in Cursor Is a Claim. Here’s How We Check It.

    A changelog entry is a claim

    When a platform ships an upgrade, the changelog tells you what the vendor wants you to believe about it. Sometimes the claim is the whole story. Sometimes the feature is real and irrelevant to your work. Sometimes — the dangerous case — something you depend on moved and the entry is three lines long. A shop that builds on a harness needs a discipline that sorts those three piles. This is ours.

    The loop, in order

    • Watch. Two daily diffs: the model catalog (running since October 16, 2026) and the changelog itself (from today). Change-only reporting — silence means nothing moved, and a failed watch reports itself once rather than going quietly blind.
    • Read against our record. Every real change gets one question: does it touch a surface we run — Desktop sittings, the cloud API, mobile steering, or a model our routing names? If not, it is logged and skipped, however shiny.
    • Check before adopting. A change that touches the harness earns a check against a known quantity — a brief we have already graded, a sitting pattern we already run. The check’s result, not the changelog’s adjectives, decides what changes in our work-order kit.
    • Write it down, dated. The desk pages update with the date of the change and the date of our check. A claim we repeated and later found wrong gets corrected in place, with the correction visible.

    This week’s page, sorted by the discipline

    Cursor’s changelog top, as of October 19, 2026 (entry dates October 16 and 13 at the head of the page): cloud-agent entries lead — canvases from cloud agents, an environments API. Those matter here, because cloud agents are a production lane for us; they go on the check list. A remote-control entry — see and reply to local agents from the iOS app, in Cursor’s description — matters specifically to a shop whose sittings run on one laptop: it changes how a sitting can be supervised, so it gets read carefully before it gets used. A marketplace launch and a pair of shipping bots are logged-and-skipped for now: real, announced, and not touching our record yet. Those descriptions are Cursor’s; the sorting is ours.

    Say where each fact came from

    One habit does more for a desk’s credibility than any other: provenance on the page. The changelog currently shows entry dates but no Desktop version string — so this desk’s version knowledge does not come from the changelog. It comes from reading our own install (3.25.9, October 19, 2026). When the basis of a number is our fleet, we say fleet. When it is the vendor’s page, we say vendor. A reader who can tell which is which can trust both.

    That is the whole method: vendor claims in, checked knowledge out, dates on everything. The watches are cheap. The discipline is the product.

    Method & settings — this piece

    Watches: Model-catalog diff (daily since October 16, 2026) + changelog diff (daily from October 19, 2026); change-only; failures reported once

    Sorting rule: Touches a surface we run = check list. Otherwise logged and skipped. Vendor descriptions labeled as the vendor’s

    Desk rule: Every fact carries its provenance and date — our record, or Cursor’s page, never blended

    Filed under the Cursor desk — the desk these watches feed.

  • The Cursor Model Catalog, Watched Daily

    The Cursor Model Catalog, Watched Daily

    Your stack includes a list you didn’t write

    Every shop building on AI agents has a dependency it rarely names: the model catalog. Which models exist, what they are called, which variant is the default, what the reasoning dial offers — all of it is set by the platform, and all of it can change overnight. If your routing doctrine names a model, the catalog is part of your infrastructure. We diff ours every morning.

    The baseline: 46 models, October 16, 2026

    The watch started with a full pull of Cursor’s model list through the API on October 16, 2026: 46 models. Each model is normalized the same way every day — its id, its display name, the values its reasoning parameter offers, and which variant is marked default. The GLM family that day, the family our first pass rides on:

    • GLM 5.2 — reasoning: high, max — default: high
    • GLM 5.3 — reasoning: low, high, max — default: max
    • GLM 5.3 Flash — reasoning: low, high, max — default: max

    That last line is load-bearing. Our first-pass doctrine is GLM 5.3 Flash at reasoning set explicitly to max on every launch. The explicit set is not ceremony: the day a platform quietly changes a default is the day your output changes and nobody knows why. A daily diff turns that silent event into a dated line in a changes log.

    What a catalog change actually does to a shop

    • A model arrives: it earns nothing until it runs the identical brief against the incumbents. New seats are tested, never adopted on a changelog’s say-so.
    • A model leaves: every doctrine that names it has a hole. The diff tells you the morning it happens, not the week a job starts failing.
    • A default changes: the most dangerous entry in the catalog, because nothing in your own setup moved. This is the change the watch exists to catch.
    • A dial gains a setting: a reasoning value appearing or vanishing changes what your pinned configuration even means.

    The trap in the easy route

    One tooling lesson from building this watch, offered free: the convenient command-line listing of the catalog truncates at roughly 6 KB — a partial catalog that looks complete. The full list only comes through the raw API call. A shop reading the truncated output believes it is watching 46 models while seeing a fraction of them. Whatever you monitor, monitor the untruncated source.

    The watch reports changes only. Silence means the catalog is what it was yesterday — and if the API itself fails, the failure is reported once, out loud. A blind watch is worse than a noisy one.

    Method & settings — this piece

    Baseline: Full model-list pull via api.cursor.com/v1, October 16, 2026: 46 models total, 3 GLM

    Normalization: id, displayName, reasoning parameter values, default variant — compared field by field against the stored snapshot

    Cadence: Daily, change-only reporting; failures reported once

    Full method: The same watch pattern guards our GLM doctrine — see the GLM desk

    Filed under the Cursor desk.

  • Desktop, Cloud, or API: One Cursor Harness, Three Seats

    Desktop, Cloud, or API: One Cursor Harness, Three Seats

    The seat is a routing decision

    Cursor is not one tool in this shop. It is three seats that share a harness — a Desktop app on a laptop, cloud agents behind an API, and a phone — and picking the wrong one wastes the day in a characteristic way. Desktop waits on a human. The cloud knows nothing about your logged-in life. The phone is a steering wheel, not a workbench. The routing rule we run: the seat is decided by where the work’s context lives.

    Desktop wins when the unlock is a logged-in browser

    A Desktop sitting is a supervised run: a written work order, an executor (Composer 2.5 in our shop) that makes an unaided first pass in its own words before any templating, and a human in the room for the real gates. Its superpower is everything the laptop already is — signed-in dashboards, the WordPress admin, the GA4 Advisor, the files on disk. When a fleet site needs hands inside a web UI that only exists behind Will’s login, no API lane substitutes.

    We learned the boundary the hard way. On October 18, an executor stopped cold at a site’s login redirect and left the step undone — which cost that sitting its unlock path. The standing rule now: in a sitting on Will’s own laptop, the executor clicks through sign-ins using the browser’s saved session. Saved-login only. No saved login means the step logs a HOLD — nobody hunts a password, ever.

    Desktop’s honest cost: it waits on a human, and a queued sitting is not a running job. Our TM pricing diagnosis (WO-353) has sat untouched since October 18 at 6:16 PM — steps written, folder staged — because a sitting starts when Will sits down. Anyone who tells you their Desktop pipeline is autonomous has not watched a folder sit still for a day.

    The cloud wins when the work fans out

    Cloud agents, launched from this desk over api.cursor.com, are the opposite shape: no login, no laptop, no waiting room — and they multiply. On October 16 we ran a census through that API: 44 models, one identical brief, five comparison rounds, graded on their execution trajectories. That is a shape of work a single Desktop seat cannot do before lunch, and it set our model routing for everything since.

    The scale shows in the bookkeeping: our completion watcher has seen 1,431 cloud agents come and go. The API runs two launch shapes for us — repo tasks that come back as pull requests, and no-repo research and evaluation runs with the model pinned in the launch body. The API is beta, and we treat it that way: when an endpoint changes shape, the error gets surfaced plainly, never papered over with invented fields.

    Mobile wins when the human is the bottleneck

    The phone’s job is judgment at human speed. Will reviews runs, reads results, and steers from his phone while the machines work elsewhere — and because a review that evaporates is a review wasted, a distiller folds his mobile and Desktop runs into the shop’s memory and Feed every 20 minutes. Mobile is not a production surface here. It is where the approvals live, and approvals are the scarcest resource in the building.

    What each seat’s failure taught the kit

    • Desktop: permission prompts were taxing the one human in the loop — fixed by a Step 0 permissions pre-flight in every work order (October 18): the executor declares the commands it expects up front, the human approves once, and prompts are reserved for sends, deletions, money, and credentials — which are never pre-approved.
    • Cloud: a finished summary is not evidence — fixed by trajectory grading and a completion watcher: results are verified at the receiving end, or they are not results.
    • Mobile: steering from the phone only counts if it lands in the record — fixed by the 20-minute distiller.

    One harness, three seats, and a routing rule a shop can steal: if the context is a login, sit down at Desktop. If the work fans out, launch it in the cloud. If the blocker is a decision, put it on the phone.

    Method & settings — this piece

    Evidence: This shop’s work-order record, October 2026: WO-198 standard, the WO-343 and WO-348 sittings, the WO-353 stall, the October 16 cloud census

    Desktop: Cursor 3.25.9 on Will’s laptop (read from the install, October 19, 2026); executor seat Composer 2.5

    Cloud: api.cursor.com/v1 (beta); completion watcher count 1,431 agents seen as of October 18, 2026

    Mobile: Cursor mobile app in a review/steer role; runs distilled into memory + Feed every 20 minutes

    Filed under the Cursor desk — where the catalog and the changelog are watched daily.