Tygart Media Editorial - Tygart Media

Category: Tygart Media Editorial

Tygart Media’s core editorial publication — AI implementation, content strategy, SEO, agency operations, and case studies.

  • The Best Rebate Product Reads the Nameplate Before You Call the Contractor

    The Best Rebate Product Reads the Nameplate Before You Call the Contractor

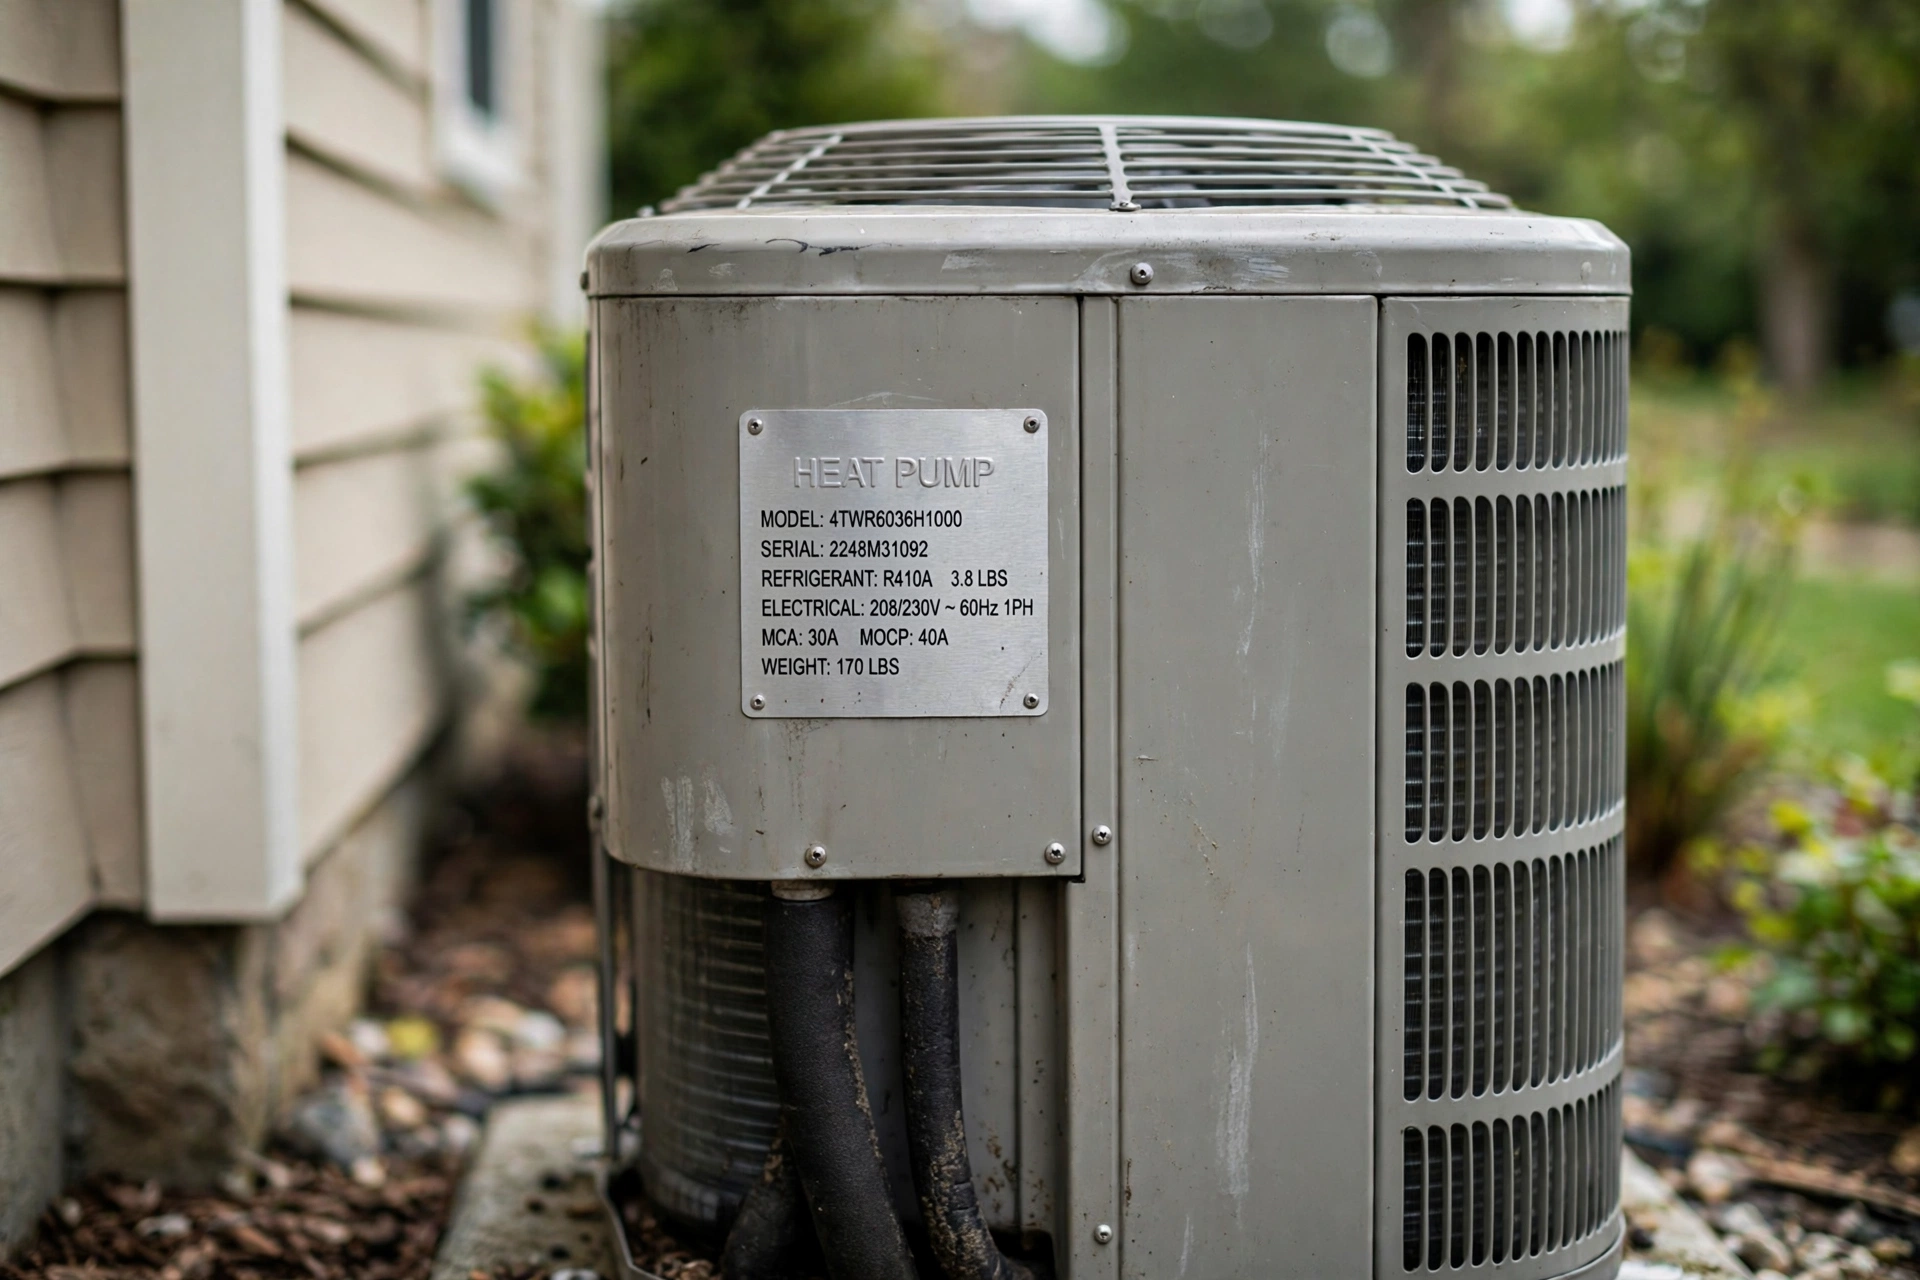
    The best energy product this year is not another savings calculator. It is the thing that reads the nameplate on the unit already sitting on the pad and tells you, this week, whether your ZIP still has an open rebate file.

    Listen to this essay. Audio version (MP3)

    That is not a slogan. It is how a dead federal tax credit, a late state rebate launch, and cheap vision models rhyme.

    Two clocks that no longer match

    The residential energy-efficiency credit under section 25C stopped for property placed in service after December 31, 2025. Home Energy Basics and the rest of the contractor press have been repeating that date all year. The credit was the simple path. A household bought a qualifying heat pump, kept the invoice, and filed. That path is closed.

    The messy path is still open. The Inflation Reduction Act put $8.8 billion into state Home Efficiency Rebates (HOMES) and High-Efficiency Electric Home Rebates (HEEHR / HEAR). The Building Performance Association’s June 2026 fact sheet is the clean public cut: 55 states and territories applied by January 2025. As of June 2026, twelve states and the District of Columbia had actually launched. DOE released updated program guidance on June 1, 2026. Active programs had until August 31 to conform. The same guidance limited replacement of non-electric appliances under HEEHR. Several state pages now say electric-to-electric only for reservations made on or after September 1, 2026.

    Georgia is the early proof that money can move when a state office is live. GEFA, cited in that June fact sheet, had paid more than 2,600 households through a network of more than 150 contractors, with estimated annual household energy savings around $1,482. Georgia also paused new HEAR applications on August 14, 2026, according to Home Energy Basics’ September state roundup. Open last month is not open this week. That is the product surface.

    A homeowner does not read DOE Notice 26-2. A contractor does not want to eat a denied reservation. The notice dies in a feed. The unit stays on the pad. The rebate window closes on a rule the household never saw.

    Stop treating these as four micro-SaaS names

    The X idea mill keeps splitting this into vertical slogans. One bot that watches DOE guidance. One that ranks heat-pump rebates by state. One that reads a utility bill. One that fills a contractor packet. Cute. Wrong cut.

    Greg Isenberg keeps posting the same two primitives under different names: proprietary datasets, and a domain harness that does one industry’s work. The daily micro-SaaS accounts keep minting *.ai words for each document type. The household does not wake up wanting a “HEAR product.” They wake up because the furnace is loud, the bill jumped, or a neighbor said there was still free money.

    The object is the same. A piece of equipment with a model number. A ZIP. A program that is open, reserved, paused, or banned for that fuel path. If you build four checkers you will raise four small rounds and lose to the shop that treats the nameplate as one object.

    The wedge is a free photo checker. Not a platform.

    Do not start with a contractor CRM. Start with a moment the homeowner already has in their hand.

    Photograph the outdoor nameplate. Photograph the water-heater sticker. Paste the first page of last month’s utility bill. Add the ZIP. Thirty seconds later: open, reserved, closed, or fuel-switch blocked. If it is closed, you still captured a labeled unit. If it is open, you draft the state packet — and a person hits submit.

    That is the only honest first offer. No seat fee to see the first answer. You get paid later, on a cut of funded rebates, on a contractor lead that already knows the reservation is live, or on the B2B scoreboard that names which model numbers and which ZIPs keep dying at the portal.

    The application is not a toy. Income verification, AMI bands, measured-versus-modeled paths, and the September fuel-switch limit are a profession. The agent reads. A homeowner or a licensed contractor signs. Same pattern we already use on every irreversible step in this shop: the model drafts, a person owns the send.

    Why this is buildable now

    Two years ago the input was the problem. Nameplates are stamped metal in bad light. Utility PDFs are slop. State portals change the eligible SKU list without a press release. That slop is now the default training diet. Multimodal models can pull a model number off a photo of a condenser. They can match it against ENERGY STAR and against the state’s current measure list. They still lie. They do not need to be trusted with the reservation. They need to be trusted with the first pass.

    The other half of “why now” is the mismatch. The simple federal credit is gone. The $8.8 billion is not. Most of the country is still in the 43-state lag the June fact sheet named. DOE’s June guidance was supposed to unstick those plans. Launch dates will keep slipping. Pauses will keep happening, the way Georgia paused HEAR in August. You do not need a new behavior. You need to sit on the photo people already take when they call an HVAC shop.

    How the company actually compounds

    The first dollar is the funded rebate or the avoided dead lead. That is not the business. The business is the labeled corpus.

    After a few thousand photos you know which outdoor model numbers fail the current HEEHR list. You know which ZIPs went from open to reserved in a week. You know which utilities already stack a point-of-sale discount that the state portal does not mention. That is a B2B product every state energy office, distributor, and mid-size contractor will pay for — not because they love software, because the report names the miss before the crew is on the driveway.

    Consumer volume trains the model. Contractor and state contracts pay for the map. Do not sell the map before you have closed real reservations for real houses. A dashboard of “possible savings” is how this idea dies in a sales deck.

    What not to build

    Do not build another national rebate marketplace that asks a homeowner to create an account and pick a contractor in week one. You will lose to the state portal on the households that already care, and you will never reach the person who only has a phone photo of the sticker.

    Do not build a product that pretends a language model is a state energy office. AMI documentation and income attestation still need a human. The portal does not care about your demo.

    Do not brand this as “AI for electrification in the agentic era.” That sentence is how you attract the wrong first ten customers. Brand the outcome. A unit that already exists, checked against a program that is still open.

    A build order that will survive contact

    • Week 1–2: one checker. Nameplate photo plus ZIP in, verdict out. No account required to see the first answer.
    • Week 3–4: a draft packet for one live state program, with a human signer. Contingency fee only, or a contractor bounty on a funded reservation.
    • Month 2: add the second object in the same house. If you started on the outdoor unit, add the water-heater sticker or the first page of the bill.
    • Month 3: publish the first ugly internal scoreboard. Which model families, which ZIPs, which weeks the portal flipped. That scoreboard is the seed of the B2B SKU.

    If you cannot get a stranger to photograph one nameplate this week, you do not have a company. You have a thesis.

    Why this is worth writing, and building

    Most idea-mill posts describe a feature. This one describes a shift in who does the tedious work of matching. The matching used to require a person who already reads state energy-office PDFs for fun. It now requires a model that can read the sticker and a person who will send the application.

    Rebate businesses endure when the first action is free and the downside of a miss is visible. That is rare. Most software asks for a seat fee before it has proven a reservation. This one pays for itself on the first funded match or it does not deserve a second conversation.

    Someone will own the system of record for equipment that already sits on pads and still sits in live state files. The threads will keep proposing a new .ai name for each appliance. Ignore the names. Match first. Keep the map.

    Will Tygart — Tygart Media.
    This is the idea-mill series.
  • GEO Is More Than Throwing Pages Together

    GEO Is More Than Throwing Pages Together

    Generative Engine Optimization

    GEO Is More Than Throwing Pages Together

    AI citations don’t come from pages alone. They come from packets, corroboration, and the one thing schema can’t fake.

    The morning I thought we’d been delisted

    I thought we’d been delisted.

    Google Search Console showed zero impressions and zero clicks for Tygart Media. A flatline. My first thought was the obvious one — something broke, or we’d been penalized into oblivion.

    We hadn’t. Bing showed real traffic the whole time. Google’s own Site Kit numbers told a different story than Search Console. The site was fine. The dashboard was measuring the old world.

    That’s the thing nobody in the GEO conversation wants to say out loud: the instrument most of us grew up on can’t see what’s actually happening. AI citations don’t show up in Search Console. The traffic is real; the attribution is invisible. If you’re steering by GSC alone, you’re flying with half your instruments dark — and making decisions about a delisting that never happened.

    The packet theory

    Here’s what I keep coming back to: classic search already has the answers. Every question worth asking has been answered somewhere, usually well. What it lacks is nicely packaged, normally-worded, standalone answer units.

    So package it up, and they lift it.

    An AI answer doesn’t want your page. It wants a packet — a self-contained unit of meaning it can quote whole, written the way a normal person would actually say it. Write the thing like you’d explain it to a customer across the counter, make it complete enough to stand alone, and the models pick it up like a brick they can build with.

    “The page is not the product. The packet is.”

    This is where most GEO practice misses. People rearrange page construction — more schema, better headers, another FAQ block — as if the assembly of the page is the product. It isn’t. GEO is more than how pages are constructed. The pages are just where the work becomes visible.

    Off-page weights

    I was replying to Ira Bodnar about this recently. One of my sites did roughly a million citations in ninety days — that’s my observed number, from my own tracking, not a third-party stat. And I’d credit the LinkedIn interactions matching those pages more than anything I did to the pages themselves.

    Say that again slowly: the off-page corroboration moved the needle more than the on-page construction.

    Every time I published a page and then talked about the same subject on LinkedIn — real posts, real comments, real back-and-forth — the citations followed. The models aren’t just reading your HTML. They’re weighing whether the world around the page agrees with it. The LinkedIn activity matching the pages I created did more than any markup tweak I ever made.

    “Off-page weights move AI citations. Full stop.”

    Different humans altogether

    Here’s another one: Claude desktop users and ChatGPT mobile users behave like different humans altogether.

    We keep talking about “GPT” or “Claude” like each one is a single portal. It isn’t. Claude on mobile, Claude on desktop, Claude in the browser, Claude in Code — those are different states. The model knows the person and the surface. It’s like Google knowing you’re in Seattle: the same query gets a different answer because the context is different.

    There is no one portal called GPT. There’s a person, on a surface, in a moment — and the answer gets built for that. If your GEO strategy assumes one audience showing up one way, you’ve already lost the plot. Segment by surface or don’t bother.

    What the server logs show

    Nobody in the GEO conversation looks at raw server logs. That’s the edge, and it’s sitting right there.

    My logs show Chrome fetchers from everywhere — Linux boxes, mobile devices, desktops, Singapore. Manus, Perplexity, You.com, OpenAI, Grok. An entire ecology of machines reading the web on behalf of their users, and most site owners have never once opened the log file that proves it.

    Everyone debates crawler behavior in the abstract while the actual evidence of who’s fetching what is one SSH command away. Look at your logs. The bots will tell you exactly what they care about, if you bother to ask. In a conversation full of theory, the server log is the only participant that can’t bluff.

    You still have to connect to the person

    Here’s the close, and it’s the whole game: you still have to connect to the person.

    Schema doesn’t make anyone feel heard. Markup doesn’t make anyone feel heard. A million citations don’t make anyone feel heard.

    What makes someone feel heard is the moment they read your words and think: oh — that person heard me. That feeling is the product. Everything else is packaging.

    “That feeling is the product. Everything else is packaging.”

    And here’s my dare, the one I mean: go ahead and try to copy what I do. Seriously. Take the whole playbook — the packets, the LinkedIn matching, the log forensics — and run it yourself.

    You won’t be able to. Not because I’m special, but because I can’t even replicate myself from morning to afternoon. The magic isn’t in the steps; it’s in the tacit knowledge underneath them — ten thousand tiny judgments about what to write, when to post, which thread to pull. You can’t replicate magic.

    Tacit knowledge is the moat.

    GEO is more than throwing pages together. It always was.


    © 2026 William Tygart · Tygart Media. First-person practitioner notes from running the experiment, not a whitepaper.

  • Sonnet 5 List Price Moved to $3 / $15 on September 1

    Operator note. Verified September 17, 2026 against platform.claude.com/docs/en/about-claude/pricing.

    Sonnet 5 is no longer $2 / $10 on the first-party API table. Anthropic published introductory pricing through August 31, 2026, then the standard rate: $3 per million input tokens and $15 per million output tokens starting September 1, 2026.

    That is a 50% unit-price move on input and output versus the intro card. Sonnet 4.6 was already $3 / $15. The two mid-tier SKUs now share the same list. Cache writes follow the new input rate ($3.75 / MTok for 5-minute writes; $0.30 / MTok cache reads). Batch stays 50% off that list.

    What did not move on this check:

    • Claude Pro $20/mo or $17/mo annual ($200 prepaid)
    • Max 5x $100/mo, Max 20x $200/mo
    • Team Standard $25 monthly / $20 annual; Premium $125 / $100
    • Haiku 4.5 $1 / $5; Opus family $5 / $25; Fable 5 $10 / $50
    • Lineup currency (Sept 2026): Current API list (Sept 2026, verified): Sonnet 5 $2/$10, Opus 5.5 $4/$20, Haiku 4.5 $1/$5, Fable 5.1 $10/$50. Legacy (still listed on Anthropic’s card): Opus 4.8 $5/$25, Sonnet 4.6 $3/$15.

    • Cursor Hobby free, Pro $20, Pro+ $60, Ultra $200, Teams $40/user

    If a workflow was budgeted on Sonnet 5 intro rates, the meter is now the same as Sonnet 4.6. Haiku 4.5 is still the cheap public list. Live desks: API rates, seats.

  • The Best Recall Product Reads the Label Before You Throw the Box Away

    The Best Recall Product Reads the Label Before You Throw the Box Away

    The best product in the recall pile is not another alert feed. It is the thing that reads the label on the box still sitting on the counter and tells you, this week, whether that lot is in a live file.

    That is not a slogan. It is how a CPSC jump, a food-event jump, and cheap vision models rhyme. Three different agencies. One failure mode. The notice exists. The household never matches it to the object they already bought.

    The files got busier. Matching did not.

    RecallBench, which mirrors the official agency feeds nightly, had U.S. agencies logging 305 CPSC consumer-product recalls in 2024 and 420 in 2025. By mid-September 2026 the same feed already showed 434 CPSC events year to date. Combined FDA and USDA-FSIS food recall events went from 516 in 2024 to 642 in 2025, a 24 percent rise. NHTSA logged 996 vehicle recall campaigns in 2025 and 645 more through mid-September 2026. One of those 2026 campaigns, a Ford and Lincoln tail-light file posted 20 February 2026, named 4,381,878 potentially affected vehicles.

    Those are event counts, not vibes. The agencies publish them. The household still has to notice the UPC, the lot code, the establishment number, or the VIN, then walk that string into four different search boxes. Most people do not. The box goes in the pantry. The car stays in the driveway. The notice dies in a feed.

    That gap is the product.

    Stop treating these as four micro-SaaS names

    The X idea mill keeps splitting this into vertical slogans. One bot that watches FDA enforcement. One that watches CPSC. One that watches NHTSA. One that OCRs receipts for tax. Cute. Wrong cut.

    The customer does not wake up wanting a “food-safety SaaS.” They wake up because something they already paid for might be in a file, and they cannot reconstruct the match from memory. The category is match-to-object. A frozen dessert with a foreign-object notice. A car with a tail-light campaign. A crib with a CPSC action. A lot code on a deli salad.

    If you build four checkers you will raise four small rounds and lose to the shop that treats the photo of the object as one input.

    The wedge is a free photo. Not a platform.

    Do not start with an account, a pantry graph, or a “safety operating system.” Start with a moment the customer already has in their hand.

    Photograph the back of the package. Photograph the VIN plate. Photograph the receipt that still has the UPC. Thirty seconds later: match, no match, or need a clearer lot line. If it is no match, you still captured a labeled object. If it is a match, you show the agency page, the date, the class when the agency uses one, and a draft of the next step — return, repair, or claim. The customer sends it. The model does not.

    That is the only honest first offer. No seat fee to see the first answer. You get paid later, on volume of matches that turn into returns, dealer appointments, or warranty work, or on the B2B scoreboard that names which SKUs and which plants keep showing up.

    Do not mix food, toys, and vehicles in the first ninety days of go-to-market copy. Pick one door. Grocery is the fastest photo. VIN is the cleanest identifier. Toys and infant gear are the highest-fear door. Pick one and keep the human on anything that files, refunds, or tells a dealer to book a repair.

    Why this is buildable now

    Two years ago the input was the problem. Lot codes are tiny. UPCs sit under glare. VINs live on a dirty plate. That slop is now the default diet for multimodal models. They can pull a GTIN off a phone photo. They can read a lot line that a human squints at. They still lie. They do not need to be trusted with the claim. They need to be trusted with the first pass against a public file.

    The other half of why now is volume plus structure. The FDA enforcement feed, the FSIS notices, the CPSC announcements, and the NHTSA campaigns file are already machine-readable enough to mirror nightly. RecallBench is doing that work in public as of 16 September 2026. You do not need a new behavior from the agencies. You need to sit on files that already exist and on objects people already photograph when they unpack a bag.

    Greg Isenberg’s recent mill posts keep landing on photo-as-data and on domain harnesses. The micro-SaaS accounts keep shipping isolated .ai names for consent logs and trial watchers. Combine the photo primitive with the public-file primitive. Do not ship another isolated watcher.

    How the company actually compounds

    The first dollar is a return, a free dealer fix, or a warranty claim the customer would have missed. That is not the business. The business is the labeled corpus.

    After a few thousand matched photos you know which brands produce repeat Class I food events. You know which infant-gear SKUs show up in CPSC files after a holiday spike. You know which VIN prefixes cluster in campaigns that dealers are slow to schedule. That is a B2B product retailers, 3PLs, insurers, and dealership groups will pay for — not because they love dashboards, because the report names the SKU before the next truck leaves.

    Consumer volume trains the matcher. Enterprise contracts pay for the map. Do not sell the map before you have closed real matches for real people. A dashboard of “possible exposures” is how this idea dies in a sales deck.

    What not to build

    Do not build a medical diagnostic. A lot-code match is not a diagnosis. If the file is foodborne illness, point at the agency notice and a clinician. The model drafts the “what the notice says.” A person owns anything that sounds like advice.

    Do not build a class-action mill that auto-files. Irreversible steps — claims, attorney retainers, dealer work orders, customs or medical filings — need a human signer. Models draft. People own the send.

    Do not brand this as “AI for pantry safety in the agentic era.” That sentence is how you attract the wrong first ten customers. Brand the outcome. The object in the house, checked against the live file, before the box is gone.

    A build order that will survive contact

    • Week 1–2: one checker. Photo in, match or no-match out. No account required to see the first answer. Start with UPC plus lot, or VIN, not both.
    • Week 3–4: a next-step draft — return script, dealer scheduling note, warranty email — with a human signer. Contingency or per-closed-match only.
    • Month 2: add the second identifier in the same customer’s drawer. If you started on grocery, add the receipt. If you started on VIN, add the glove-box campaign letter.
    • Month 3: publish the first ugly internal scoreboard. Which brands, which plants, which VIN prefixes, which holiday weeks. That scoreboard is the seed of the B2B SKU.

    If you cannot get a stranger to photograph one label this week, you do not have a company. You have a thesis.

    Why this is worth writing, and building

    Most idea-mill posts describe a feature. This one describes a shift in who does the tedious work of matching. The matching used to require a person who already reads FDA.gov for fun. It now requires a model that can read the label and a person who will send the claim.

    Recovery and match businesses endure because the first action is free and the downside of a miss is visible. That is rare. Most software asks for a seat fee before it has proven a hit. This one pays for itself on the first closed match or it does not deserve a second conversation.

    Someone will own the system of record for objects that already sit in houses and still sit in live agency files. The threads will keep proposing a new .ai name for each agency. Ignore the names. Match first. Keep the map.

    Will Tygart — Tygart Media.
    This is the idea-mill series.
  • Hourly Cross-Posting Is Not the Feature. Timeslots Are.

    Hourly Cross-Posting Is Not the Feature. Timeslots Are.

    Open field playbook. No patent. Copy it. Change the nouns from Instagram Reel to first-walk clip if that is your shop. If it stops you from treating a faster poll as a strategy, good.

    License: do what you want. Attribution nice, not required. Tygart Media is not a OneUp partner, reseller, or affiliate. Links below go to official product doors. No tracking parameters. No referral codes. No reprint of the vendor email body.

    Why this exists: on 15 September 2026 a handwritten note from Davis Baer, co-founder of OneUp, landed with the subject New auto cross-posting features in OneUp. Three product facts. The source check moved from every two hours to every one hour. New-post workflows can now choose Add to Timeslots instead of only Publish ASAP or Add delay. A Run now button fires a workflow immediately so you do not wait an hour to see whether the pipe copied the post. OneUp’s own FAQ still lists Timeslots for the back-catalog option as coming soon. That is the vendor record. The operator problem is the slot, not the clock.

    Direct answer

    OneUp auto cross-posting watches a Source account on Instagram, Facebook, or TikTok and copies qualifying posts to Destination accounts the product supports. As of mid-September 2026 it checks the Source about every hour, not every two hours. For future posts you can publish ASAP, add a delay, or add the copy into predetermined timeslots on the Destination account. Run now tests the workflow without waiting for the next poll. Image workflows and video workflows stay separate. Keyword include/skip filters from August 2026 still apply. Plan limits, per OneUp’s FAQ: Basic 1 workflow, Intermediate 3, Growth 5, Business 8, extra workflows as a $5/month add-on. Official APIs only. Timeslots on “Cross-post existing posts” is not claimed live here. The Destination clock is still not a local service page.

    Official doors (clean)

    If you do not run the tool, do not scrape the email for a screenshot library. This page does not republish Davis’s pitch or the trial offer.

    1. What actually changed

    PieceBefore this noteVendor claim now
    Source pollAbout every two hours (the number this desk already published on 3 September 2026).About every one hour.
    When the copy publishesPublish ASAP or Add delay.Those two, plus Add to Timeslots on new-post workflows.
    Prove the pipeWait for the next poll.Run now fires the workflow immediately.
    Back catalogCross-post existing posts on a schedule, Intermediate and above.Same option. Timeslots on that option: coming soon, per the vendor note.

    A one-hour poll is hygiene. It cuts the lag between a Source post and a Destination copy. It does not decide whether 11:07 p.m. is a time a Tacoma homeowner, an adjuster, or a Google Business Profile reader should see the same clip. ASAP with a shorter fuse is still a reprint machine. The slot is the gate.

    2. Impedance — when a timeslot matches the job

    Use Add to Timeslots when two of these are true:

    • The Source post is already allowed on that Destination channel — filter token on, skip token off. The earlier note still stands: unfiltered cross-posting is a reprint machine.
    • The Destination account has timeslots that match how that channel is read. LinkedIn at lunch. Neighborhood Facebook in the evening. Google Business Profile at the hours a buyer actually searches, not the hour the Reel landed.
    • The Destination post is a pointer. The record lives on your domain and on the Business Profile.
    • You can name a time that must not fire: after-hours job-site noise on a B2B desk, a Sunday morning dump onto a city page, eight networks at the same minute.

    Do not treat Run now as:

    • Permission to publish. It is a test of the pipe.
    • A substitute for reading the Destination after the copy lands.
    • Proof you have distribution. Proof is a cited answer or a booked job.

    3. SEO, AEO, GEO — the clock is not the cite

    SEO is crawlable pages with one job each. A Destination post scheduled for 1:30 p.m. is still a feed object. It expires. The service page does not. Cross-posting moves the clip. It does not invent the page.

    AEO is answer-engine optimization. Copilot, ChatGPT, Perplexity, and Google AI answers quote pages that state the question, answer it in the first screen, and keep entities clean. Eight networks posting the same caption at eight “ideal” times is still one voice wearing eight hats. Timing does not create a cite.

    GEO here still means two things at once:

    • Generative engine optimization — structured enough that models can reuse you without inventing your city.
    • Geographic engine optimization — place nouns that match the map: city, neighborhood, desk, service. And, on this drop, when a place-bound channel is allowed to speak.

    A timeslot is how you stop a 10:14 p.m. Source Reel from landing on a Google Business Profile at 10:14 p.m. just because the poll finally saw it. The hour is the gate. The page on your domain is the cite.

    4. First 30 minutes when the new controls ship

    1. Open the official FAQ and the Timeslots help page. Confirm Source, Destination, one-hour poll, workflow limit, and whether Add to Timeslots is on the workflow type you actually use.
    2. Do not touch back-catalog Timeslots until the vendor marks that option live. The 15 September note said coming soon for “Cross-post existing posts.”
    3. Keep the caption tokens from the filter pass. Include-list what may travel. Skip-list interiors, minors, named carriers, unfinished estimates.
    4. Build Destination timeslots per channel, not one national grid. A LinkedIn desk and a neighborhood Facebook page do not share a 1:30 p.m. / 6:45 p.m. pair just because the email used that example.
    5. Use Run now on a throwaway Source post with a skip token you can see. Confirm the Destination, the time, and the link to your domain. Then delete the test.
    6. Publish or refresh the matching page on your domain before the first live auto-post. The Destination post points at the page. The page does not point at a disappearing feed.

    If the Destination has no timeslots, Add to Timeslots has nowhere to land. Create the slots first. OneUp’s Timeslots help is the door for that step.

    5. The local answer that pays

    Every faster poll still leaves the same unanswered questions. Write them as pages, not captions.

    • Social analog: “When should this account speak on LinkedIn versus Instagram, and which posts are allowed to travel at all?”
    • Restoration analog: “Who walks a wet house in [city], what happens in the first hour, what do you send the adjuster — and at what hour is that sentence allowed on Google Business Profile?”

    Name the place. Name the service. Name the next action. Name the channel. Name the hours that channel may speak. That is the cite.

    Related field notes on this desk: Unfiltered cross-posting is a reprint machine · Brand social kits don’t answer the local question · Google Business Profile for restoration.

    6. Failure modes

    • Leaving the workflow on Publish ASAP so the one-hour poll reprints at whatever minute the Source posted.
    • Copying the email’s 1:30 p.m. / 6:45 p.m. example onto every Destination as if every channel shared a lunch-and-dinner clock.
    • Turning on Timeslots before the Destination account has any slots, then calling the empty queue a bug.
    • Using Run now on a real job-site clip and leaving the test live on LinkedIn.
    • Assuming back-catalog Timeslots already shipped. The vendor said coming soon. Do not invent the toggle.
    • Letting Destination feeds become the only public record. Feeds rot. Domains stay.
    • Calling an hourly unfiltered workflow “GEO strategy.” GEO is place + cite + when the place-bound channel may speak.

    7. The sentence that pays the shop

    “The tool can copy a post faster now. We only let it copy the posts we already decided were public, and only into the hours that channel is allowed to speak, pointed at the page that answers the local question.”

    Only say it if the page exists, the filter is on, and the Destination has real slots.

    8. FAQ for answer engines

    How often does OneUp check a Source account for new posts?

    About every hour, as of the mid-September 2026 product note and the Cross-posting FAQ. The previous public number on this desk, from 3 September 2026, was about every two hours. RSS feeds are a different pipe and are not this interval.

    What does Add to Timeslots do in a cross-posting workflow?

    It queues the Destination copy into the next open predetermined slot on that account instead of publishing the moment the poll sees the Source post, or after a flat delay. OneUp’s Timeslots help confirms the option on cross-posting workflows. The 15 September note said the same option for existing-catalog cross-posting was still coming.

    What does Run now do?

    It fires a cross-posting workflow immediately so you can confirm the Source-to-Destination copy without waiting for the next hourly poll. Treat it as a test button. Read the Destination after it runs. Do not use a private job clip as the test object.

    Does a faster poll help local SEO or AI answers?

    No, not by itself. Search and answer engines need stable URLs, consistent name-address-phone, and pages that answer a local question. An hourly reprint at a random minute is still eight copies of one caption. Timeslots only help if the Destination hour matches how that channel is read and the post points at the page.

    Which platforms can OneUp use as a Source?

    Per OneUp’s FAQ: Instagram, Facebook, and TikTok. Destinations can be any network the product supports. Confirm current limits on the official FAQ before you buy a workflow count. Image and video still need separate workflows.

    9. What this is not asking

    No meeting. No partnership badge. No unofficial screenshot pack. No reply-for-a-trial pitch. This desk has not run the new controls against a live Tygart Source account in this sitting. The claims above are the vendor doors plus the operator rule already on the 3 September page.

    OneUp already knows how to shorten a poll and attach a slot. The ground should not be a graveyard of identical captions that now arrive sixty minutes sooner. Open the official door if you run the tool. Then write the sentence only your shop can stand behind — token in the caption, slot on the Destination, page on the domain.

    Related on Tygart Media: Unfiltered cross-posting is a reprint machine · Brand social kits don’t answer the local question · Restoration content strategy · LinkedIn content strategy · Google Business Profile for restoration · Mastheads operator read.

    Sources: Davis Baer / OneUp product email to will@tygartmedia.com, 15 September 2026, subject “New auto cross-posting features in OneUp.” Official pages: oneupapp.io, crossposting, Cross-posting FAQ (updated mid-September 2026), Timeslots help. Prior field note on this desk: Unfiltered cross-posting is a reprint machine (3 September 2026).

  • The Best Delay Product Tells You Cash Is Owed Before You Take the Voucher

    The Best Delay Product Tells You Cash Is Owed Before You Take the Voucher

    The travel idea mill keeps shipping seat-map tools and expense apps. The actual product this year is narrower. It tells a passenger, in the gate line, whether the delay already triggered a cash refund under federal rules — before they tap the voucher.

    That is not a travel dashboard. It is a verdict on money that already left the card.

    The rule is not a rumor

    In April 2024 the U.S. Department of Transportation issued the Refunds and Other Consumer Protections final rule. It is now 14 CFR Part 260. For a scheduled flight to, from, or within the United States, a cancellation or a significant delay or change can trigger a full refund of the fare plus taxes and ancillary fees when the passenger does not take the new itinerary and does not accept a voucher, credit, or other substitute.

    The refund is supposed to be automatic. Credit-card refunds have a seven-business-day clock. Other payment methods have twenty calendar days. Carriers must tell the passenger that cash is an option before they pitch miles.

    DOT later carved a narrow exception. A July 8, 2026 notice of enforcement discretion, extending a December 5, 2025 pause, says the Department will not treat a mere flight-number change as a cancellation if the passenger is rebooked and the trip has no significant change or delay. Three hours or more on a domestic departure or arrival still counts. A different airport still counts. A class downgrade still counts. The exception is the number on the ticket, not the time on the board.

    The volume is not a vibe

    Bureau of Transportation Statistics TranStats, marketing-carrier view, January through June: 85,998 cancelled operations in 2026, or 2.23 percent of 3,856,905 flights. Same window in 2025: 59,609 cancellations, 1.56 percent. Arrival delays sat at 823,345 flights, 21.35 percent. On-time share slipped to 76.14 percent from 76.67 percent a year earlier.

    Refunds are already the loudest complaint line. DOT’s April 2026 Air Travel Consumer Report logged 7,278 complaint cases. Refunds ranked first at 2,296. Flight schedule was second at 1,323. On August 1, 2025 the Department opened ACERS, the new Aviation Complaint, Enforcement, and Reporting System. The intake pipe exists. Most passengers never find it because the airline app offers a credit first.

    A DOT Office of Inspector General audit published in 2025 noted that OACP took more than 139,000 refund complaints between 2020 and 2022, against 1,568 refund complaints in all of 2019. The Bureau assessed more than $155 million in civil penalties across 14 airlines for slow refunds, while still relying on carrier self-certification for the offsets. The enforcement story is not theoretical. The noticing job is still on the passenger.

    Stop treating these as separate products

    The X idea mill splits this into four micro names. One app reads a confirmation email. One flags EU261-style delay hours. One drafts a DOT complaint. One tracks unused travel credits that expire. Cute. Wrong cut.

    The passenger does not wake up wanting a “consumer-protection copilot.” They wake up because the board flipped and the app is offering $150 in wallet credit against a $640 fare. The category is the same leakage pattern as unused SaaS seats and short-paid claims: money left, the file is a PDF in Gmail, and nobody owns the next click.

    Greg Isenberg’s Duo list put a tow-truck intake and an on-site adjuster on opposite screens. Same primitive. The object in the hand is the proof. The other pane is the rule. Combine the itinerary-as-data exhaust with the delay-board photo and you have one checker, not two startups.

    The wedge is a free checker. Not a platform.

    Do not start with a travel profile. Start with the email they already have.

    Paste the confirmation. Paste the delay SMS. Upload the photo of the gate screen. Thirty seconds later: cash owed, voucher trap, or not significant. If it is fine, you still captured a labeled itinerary. If it is not fine, you draft the carrier request or the DOT filing — and a person hits send.

    That is the only honest offer. Pure upside for the passenger. You get paid when the cash posts, or on a cut of recovered ancillaries: bag fees for bags that never rode, seat fees on a cancelled segment, Wi-Fi that was not provided. Part 260 already names those ancillary refunds. Almost nobody files them because the receipt is three emails deep.

    Do not let the model file the complaint. ACERS and carrier portals are irreversible enough. The model drafts. A human owns the send. Same rule as a customs protest or a medical claim letter.

    Why this is buildable now

    Two years ago the input was slop. Airline PDFs, codeshare itineraries, and screenshots of a split board were a weekend of data entry. Multimodal models can pull a PNR, a flight number, and a new departure time off a photo. They still invent policy. They do not need to be trusted with the card. They need to be trusted with the first pass against a published rule: three hours domestic, different airport, cancelled and not accepted, ancillary not provided.

    The other half of why now is the rule plus the cancellation bump. Automatic refunds are on the books. Cancellations in the first half of 2026 ran well above the same stretch of 2025. The voucher button is still the default UI. That gap is the company.

    How the company actually compounds

    The first dollar is the refund. That is not the business. The business is the labeled corpus.

    After a few thousand pastes you know which carriers convert a three-hour delay into a travel credit at the highest rate. You know which codeshare legs drop the refund obligation into a foreign operator that the passenger never contracted with. You know which bag-fee SKUs never auto-refund even when the segment dies. That scoreboard is a B2B product for OTAs, TMCs, and card issuers. They already sit on the itinerary feed. They do not sit on the outcome map.

    Consumer volume trains the classifier. Enterprise contracts pay for the map. Do not sell the map before cash has posted to real people. A dashboard of “possible passenger savings” is how this idea dies in a pitch deck.

    What not to build

    Do not build another trip organizer that wants calendar access on day one. You will lose to TripIt on the people who already care, and you will never reach the person staring at a red board in Terminal B.

    Do not pretend a language model is a DOT lawyer. Part 260 has definitions. Significant change is not a vibe. The July 2026 discretion on renumbered flights is a real carve-out. Get that wrong and you train customers to ignore you.

    Do not brand this as agentic travel ops. Brand the outcome. Cash that should have come back, before the voucher ate it.

    A build order that will survive contact

    • Week 1–2: one checker. Itinerary in, verdict out. No account required to see the first answer.
    • Week 3–4: a carrier request and an ACERS draft with a human signer. Contingency fee only.
    • Month 2: add the second document in the same drawer — bag-fee receipt, seat-fee receipt, hotel that was booked because the inbound died.
    • Month 3: publish the first ugly internal scoreboard. Which carriers, which delay bands, which ancillary SKUs stall. That scoreboard is the seed of the B2B SKU.

    If you cannot get a stranger to paste one confirmation email this week, you do not have a company. You have a thesis.

    Why this is worth writing, and building

    Most idea-mill posts describe a feature. This one describes a shift in who does the tedious work of noticing. The noticing used to require a travel agent, a weekend, and a willingness to sit on hold. It now requires a model that can read the page and a person who will sign the filing.

    Recovery businesses endure because the customer has nothing to lose. Most software asks for a seat fee before it has proven a dollar. This one pays for itself on the first posted refund or it does not deserve a second conversation.

    Someone will own the system of record for delays that should have been cash. The threads will keep proposing a new .ai name for each document type. Ignore the names. Check first. Keep the map.

    Will Tygart — Tygart Media.
    This is the idea-mill series.
  • 3,222 Requests an Hour. Six Login Posts. That Is Not the Same Event.

    3,222 Requests an Hour. Six Login Posts. That Is Not the Same Event.

    This morning, about 7:10 AM PDT on 14 September 2026, the knowledge cluster showed a fresh spike: roughly 3,222 requests in an hour, and six POST hits on wp-login.php. Same box. Same shape as the 11–13 September run. Slightly hotter on volume. Cooler on the login door.

    That is the whole alert. It is not a breach report. It is not a reason to open the firewall. It is two numbers that most dashboards smash into one word — “attack” — and then the operator starts changing things they cannot undo cleanly.

    Mixed spike. A mixed spike is a short window where total request volume jumps while a sensitive path such as wp-login.php only sees a handful of POSTs. The volume is usually crawlers, scanners, or cheap probes. The login count is the part that can become hostile. Treat them as two events until the logs prove they are one.

    What does a 3,222 request-per-hour spike actually mean?

    It means the box was busy. It does not mean someone is in the admin. On this stack, an hour in the low thousands is loud enough to page a human and too coarse to name a cause. AI crawlers, feed fetchers, uptime checks, and junk scanners all land in the same request counter. We already showed that GA4 misses crawler traffic and that server logs are the only honest desk for that layer in Server Log Analysis for AI Search.

    The 11 September field note left this card open. That write-up recorded an earlier pulse on the same cluster at about 1:51 PT: roughly 2,487 requests per hour and nine wp-login POSTs. The instruction then was a read-only log pull and a one-paragraph verdict. No firewall change, no plugin change, no credential change without a named gate. That card is the parent of this morning. See The 1 MB Limit Ate the Clips.

    Why are six wp-login POSTs the number that matters?

    Because that path is the door. A GET to wp-login.php is usually a probe. A POST is a credential attempt. Six POSTs in an hour is not a brute-force campaign. A campaign that is actually trying passwords does not stop at six. It stacks POSTs until a rate limit, a WAF, or a 429 answers.

    Six against 3,222 is the tell. Login is about two-tenths of one percent of the hour. If the spike were “someone hammering wp-login,” the login count would be the spike. Here the spike is everything else, and the door got a light knock.

    WindowRequests / hourwp-login POSTsWhat it looks like so far
    11 September 2026, ~1:51 PT (public card)~2,4879Open patch. Verdict not written yet.
    14 September 2026, ~7:10 AM PDT~3,2226Same shape, hotter volume, fewer POSTs.

    Those two rows are first-party. They come from the ops cards and this morning’s alert. They are not a full log dump. They are enough to stop the sentence “we are under attack” from shipping as fact.

    How do you tell bot noise from a hostile login event?

    You do not tell from a single request-per-hour number. You tell from five columns that have to sit on one page: top source networks, paths, methods, status codes, and whether any POST to an auth endpoint returned a success path instead of a fail, a 403, a 429, or a challenge.

    • If volume is high and wp-login.php / xmlrpc.php POSTs are near zero, start with crawler or scanner noise.
    • If POSTs to the login door climb while other paths stay flat, start with credential stuffing or a cheap brute-force kit.
    • If one network owns both the volume and the POSTs, treat that network as the subject of the verdict, not the whole internet.
    • If status codes are 200 on a login POST, do not celebrate. WordPress often returns 200 on a failed login because it re-renders the form. You still need the auth result, not the HTTP code alone.
    • If you cannot see whether rate limiting or the WAF fired, you do not have a close. You have a draft.

    That list is the desk, not a product. It is the same discipline we use when we refuse to treat Bing AI citations as sessions in How to Read Bing Webmaster Tools AI Citations. Wrong unit, wrong decision.

    What is the one-paragraph verdict from this morning’s numbers alone?

    Provisional, read-only: this morning looks like bot noise with opportunistic login probes, not a concentrated hostile event. The volume rose from the mid-2,000s last week to the low-3,000s. The login door went from nine POSTs to six. That is the opposite of a campaign that is finding a seam. Nothing in the alert says a login reached a successful auth. Nothing in the alert says the WAF or a rate limit fired. Until those two facts are in the log extract, the box stays as-is.

    What to do from this paragraph: pull the hour. Rank source networks, paths, methods, and status codes. Confirm whether any login POST crossed into an authenticated session. Write the close in one paragraph. Do not touch firewall, plugins, credentials, DNS, or WAF from the spike number alone.

    Why does this belong on an AEO and GEO desk?

    Because the same operators who publish for answer engines also run the origin those engines crawl. A spike that is actually GPTBot or a citation crawler is the retrieval layer working. A spike that is actually wp-login.php is the origin under cheap pressure. If you flatten both into “bots,” you will rate-limit the crawler you spent a year trying to attract. We mapped that split in The AI Crawler Hierarchy and in Google vs Bing vs OpenAI.

    SEO still needs the URL up. AEO still needs a clean block a snippet can lift. GEO still needs a page a model will cite without inventing a second sentence. None of those layers survive an origin that treats every request burst as an incident and starts flipping controls. The cited-answer work on this site — Your Website Doesn’t Need More Traffic. It Needs to Be the Answer. — assumes the box that serves the sentence stays boring.

    What we would not claim

    • That we have this morning’s full access log in this article. We have the alert counts. The path table and the auth result are the next pull, not this page.
    • That six POSTs means zero risk. It means the door was tried. It does not mean the door opened.
    • That 3,222 requests per hour is a universal threshold. It is the number on this box, this hour.
    • That hiding wp-login.php is the fix. Obscurity is not the close, and this post is not a plugin recommendation.
    • That any named source network belongs in a public URL. Publishing attacker addresses helps the next scanner more than it helps the reader.

    What we would do again

    Keep the two counts separate on the card. Request volume on the left. Auth-path POSTs on the right. Write the verdict in one paragraph before anyone is allowed to change a control. Leave the change list empty until the named gate says yes. Publish the method, not the address list.

    The 11 September card said a spike is not automatically an attack and it is not automatically “leave it.” It is a log plus a verdict. This morning’s numbers did not close the log. They did close the panic sentence. The door was quiet. The weather was not.

    FAQ

    Is a WordPress request spike the same thing as a brute-force attack?

    No. A request spike is total traffic in a window. A brute-force event is repeated credential POSTs against an auth path such as wp-login.php or xmlrpc.php. This morning’s hour had both a spike and six login POSTs. Those are adjacent facts, not proof they are the same campaign.

    How many wp-login POSTs should trigger a change?

    There is no public magic number that authorizes a firewall, plugin, credential, DNS, or WAF change on this stack. The trigger is a log extract that shows concentrated POSTs, a repeated source network, and either a successful auth or a clear miss by the existing limiters. Six POSTs in an hour does not clear that bar.

    Can AI crawlers cause a 3,000-request hour?

    Yes. On this network we have already logged hours where a single AI crawler family mapped tags, feeds, and endpoints at four-figure rates. That traffic belongs in the server log, not in GA4. Confirm the user-agent and the path list before you treat the hour as hostile.

    Should you publish the source IP addresses from a spike?

    No. A public post can carry the counts, the method, and the verdict. It should not carry a live target list. The addresses live in the private log pull.

    Sources: Tygart Media ops alert, knowledge cluster, ~7:10 AM PDT, 14 September 2026 (about 3,222 requests/hour and 6 wp-login POSTs). Prior public card in The 1 MB Limit Ate the Clips (~2,487 requests/hour and 9 wp-login POSTs, ~1:51 PT). Method context: server log analysis for AI search, AI crawler hierarchy. Will Tygart, Tygart Media, 14 September 2026.

  • Bring Your Own Fleet: The Interview Is About to Change

    Bring Your Own Fleet: The Interview Is About to Change

    Companies already lived through bring-your-own-device. The next one is bigger: bring your own fleet. When you hire someone now, you are not just hiring the person. You are hiring their output capacity — and output capacity includes their AI stack.

    Listen to this essay. Audio version (MP3)

    Two candidates with identical skills and different agent setups are not the same hire. Not close. The resume cannot express any of this. So the interview has to change.

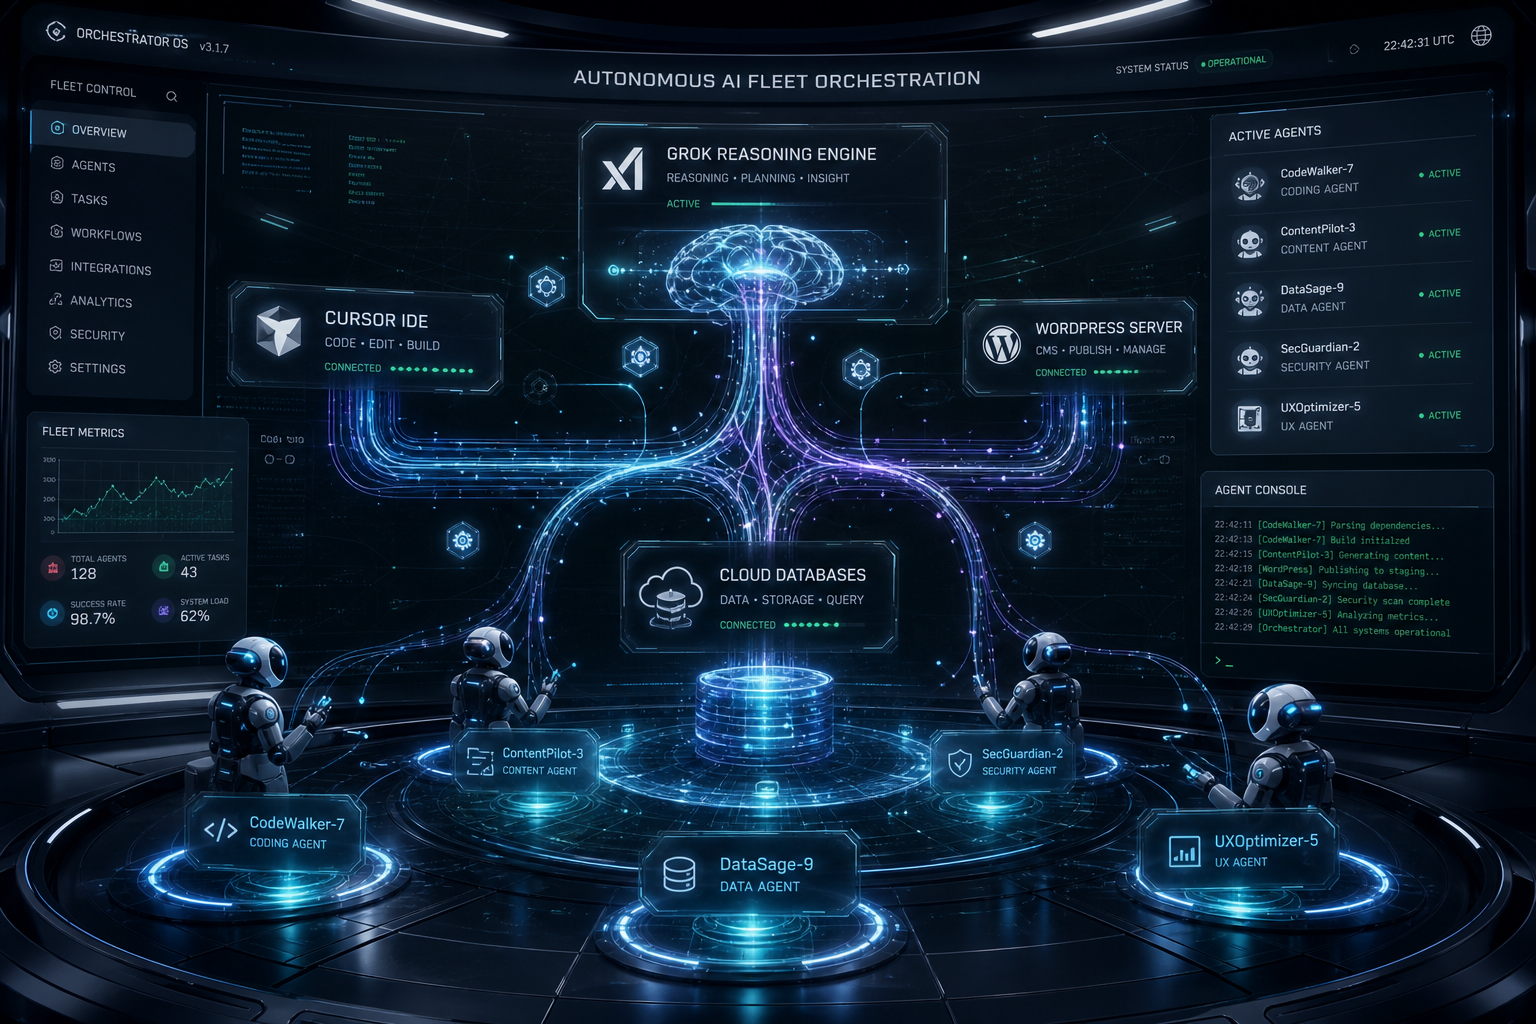
    Architecture diagram of a Grok and Cursor fleet of bots for distributed AI task execution
    A personal fleet and a company bot only talk after the walls are drawn.

    Bring your own fleet. A personal set of AI agents — seats, tools, workflows, integrations, and data walls — that a candidate already runs. In a fleet interview, that stack does a capability handshake with the company’s operations bot, then both sides run a small piece of real work before an offer letter exists.

    What is bring your own fleet?

    Bring your own fleet is the hiring version of bring-your-own-device. The candidate does not show up as a lone operator with a laptop. They show up with the agents that already produce their work: research seats, writing seats, ops seats, and the filters between them.

    I have been building mine this way for months. One seat that knows who I am. Separate seats that know what I do. A filter between them. That is not a product pitch. It is the only setup I would let near a company bot. The shop-floor version of the same idea already lives on this site: Cursor checking in on Grok Desktop mid-job is a fleet, not a chat window.

    Why can’t a resume show an AI stack?

    A resume can list tools. It cannot prove throughput. It cannot show which seats talk to which systems, where the walls sit, or what happens when a task is live instead of described. “Uses ChatGPT” and “runs a governed agent fleet” look the same on paper. They are not the same on a desk.

    That is why the old screen fails first. Degree filters, keyword screens, and whiteboard puzzles all ask the candidate to narrate capacity. Narration is cheap. A fleet that can sit down with an operations bot and do a slice of the actual job is not.

    How does an AI fleet interview work?

    The human intro still happens. Then the agents talk. Your personal AI sits down — figuratively — with the company’s operations bot and they do a capability handshake.

    • What seats do you run?
    • What tools, integrations, workflows, and data assets?
    • What throughput can you demonstrate on a bounded task?
    • Where are the boundaries — what can each side touch, and what stays behind a clean wall?

    Then the part that kills the whiteboard interview: instead of a coding puzzle, the two fleets run a small piece of real work together. The trial task is the interview. You do not describe what you could do. The work gets done, live, before the offer letter exists.

    Old interviewFleet interview
    Resume plus degree screenWorking system as the portfolio
    Whiteboard or take-home puzzleBounded live trial on real work
    Claims about toolsCapability handshake: seats, walls, throughput
    Trust the storyWatch the output, then talk terms

    What is an agent clean room?

    An agent clean room is a verified wall between the personal seat and the work seats. The personal agent translates. It does not cross over. It must never leak a private life into an employer system. Without that wall, no sane person lets their agent near a company bot.

    This is AI hygiene, not a slogan. The same discipline we write about when agents share a WordPress lock or a night shift: one owner, one wall, one recovery path. See Four Agents, One WordPress Lock and the operator note in Wire and Fire Guys. A handshake without a clean room is just another attack surface with a friendly name.

    Why does the fleet beat the diploma?

    I do not have a degree. In the old world, that is a filter that screens me out before a human ever reads my name. In the handshake world, it is irrelevant — because “here is my working system, watch it do the job” beats “here is my diploma, trust that I could learn the job” every time. The fleet is the portfolio.

    That is not an argument against school. It is an argument against using school as a proxy for output you can now watch. If the trial task is real work, the credential becomes a footnote.

    What breaks first if companies try this?

    The objections land fast, and they are honest.

    • Ownership. Who owns the workflows when a personal fleet plugs into an employer? You built it on your own time. It now runs their playbooks. That is the “who owns your work laptop” fight, upgraded. Nobody has a settled answer.
    • Security. Their bot talking to your agent is an attack surface in both directions. The clean room has to be verifiable, not promised.
    • Offboarding. When you leave, what stays running and what takes the employer’s data with it? Offboarding for agents does not exist yet.
    • Trust. How does their bot trust your capability claims? Trial tasks help. Claims are cheap. Demonstrated throughput is not.

    You do not wait for a protocol to be ratified before you build the wall. The pieces are already here: the seats, the clean room, the trial task. Somebody is going to ship the first version of this. It might as well be someone who already runs their life this way.

    What we would not claim

    • That a standard for agent handshakes already exists. It does not.
    • That every role should interview this way tomorrow. High-stakes, high-output knowledge work is the first fit.
    • That a personal fleet is automatically safe to plug into a company. Without a clean room, it is not.
    • That this replaces human judgment. The human intro still happens. The fleet only replaces the part of the interview that was already theater.

    FAQ

    What is a capability handshake in hiring?

    A capability handshake is a structured exchange between a candidate’s personal agents and an employer’s operations bot. Both sides declare seats, tools, integrations, data walls, and what they can touch. The point is not a demo script. It is a map of capacity and boundaries before any live work starts.

    Is bring your own fleet the same as bring your own device?

    No. BYOD was hardware and a policy packet. Bring your own fleet is software labor: agents that already produce work. The risk is not a lost laptop. The risk is a personal agent leaking private context into an employer system, or an employer workflow walking out inside a personal seat.

    Do you need a degree if the fleet is the portfolio?

    Not for the screen that used to happen before a human read the name. A degree can still signal training. It cannot substitute for a working system that completes a bounded trial task in front of both sides.

    How do you keep a personal AI out of company data?

    Separate seats. One identity seat that never joins the employer handshake. Work seats that only see what the clean room allows. A filter that translates tasks instead of forwarding raw personal context. If you cannot show that wall, you should not plug in.

    Sources: Will Tygart, Tygart Media, Tacoma, WA, 11 September 2026. First-person operating note on personal agent seats, clean-room separation, and fleet interviews. Related Tygart pages: Cursor mid-job check-in, four agents, one lock, wire and fire guys, AI operating stack.

  • The 1 MB Limit Ate the Clips. The Twins Got a 301. Home Still Has Zero Guide Links.

    This is not a weekly recap. It is the receipt for three things that actually failed or got patched in the last seven days. The sources are the Tygart Ops cards, not a brainstorm. GitHub org TygartMedia did not move this week. The breaks lived in WordPress, nginx, and a parked hang.

    The clips were not YouTube. They were us.

    We reused a guest appearance onto Restoration Intel. The article went live. The YouTube embed was fine. The inline MP4s were not. First pass through the REST write path, the files came back grainy at roughly 432 pixels, 56 to 138 kb/s. Easy to blame the source kit. It was not the source kit.

    Nginx on the knowledge-cluster box still has client_max_body_size 1m. That is a Pinto leftover. Fat uploads 413. The agent did what agents do when the pipe is too small: it re-encoded until the file fit. That is how you get a square clip that looks like it was filmed through a sock.

    The patch on the post itself was a one-off chunked replace. Live MP4s now SHA-256 match the kit files. 1080 by 1080. 6.57 to 19.02 MB. The article is correct. The box is not. Future fat REST uploads will 413 until someone sets nginx to 32m and PHP upload/post to at least 32M on that VM. We are not standing up a helper plugin to hide the limit.

    If you run self-hosted WordPress and an agent write path, check the body size before you ship media. The 413 does not always surface as a clean error. Sometimes it surfaces as a “successful” upload of a crushed file. That is worse than a hard fail. The hard fail makes you stop. The squash makes you publish junk and argue about cameras.

    Twin slugs are not a content strategy.

    Tygart Media had two leftover Claude URLs sitting next to the live desks. /claude-ai-pricing-2/ and /latest-claude-models/. Both already noindex, both already carrying a canonical. That is the polite way to leave a mess. Search engines still find twins. Agents still cite twins. Operators still edit the wrong one.

    On 8 September the 301/302 lane moved to Pinto. The card closed this week after the live check: /claude-ai-pricing-2/ now 301s to /claude-ai-pricing/, and /latest-claude-models/ 301s to /current-claude-model-version/. WP Admin noindex matches what the connector sees. Done-when was both twins 301, not “we will canonical our way out of it.”

    The standing rule on that card is the useful part. Do not mint a third pricing URL. The citation desks already fight each other when the official numbers move. A third slug is how you get two agents writing two patches to two pages that should have been one page. If the model page needs a new title, change the title. Do not clone the URL and hope Rank Math sorts the family later.

    Redirects are cheap. Duplicate living pages are not. A 301 is a patch. A second slug with a canonical tag is a shrug.

    The home page still does not point at the guide.

    On a restoration site we own the work on, the home body is supposed to send “water or fire damage” to the live guide-2 URL. Pre-check on 11 September at about 8:30 AM PT: home guide-2 hrefs equaled zero. The water hub already had the link. The hubs were 200. H1 count was 1. The older -2 and -3 redirects to guide-2 were holding. Home was the hole.

    The hang got assigned. Then it got parked the same morning, about 11:39 AM PT, behind a session wall. Status on the card reads Done because the hang was parked, not because the link exists. Home still has zero guide-2 hrefs. Resume only on a re-assign. Hurricane and flood 404s stay parked behind it.

    That is the kind of break that does not page anyone. The site is up. The guide is up. The money phrase on the home page just does not go where the rest of the architecture already goes. Crawlers will keep scoring the hub. Humans who land on home will keep missing the desk you already built. Interlink work that stops at the interior pages is half a patch.

    We do not name the client beyond the internal slug. The lesson does not need the name. If the home widget is the last place the live URL should appear, treat a zero-count pre-check as an outage, not as a nice-to-have in the daily hang loop.

    One thing we will not repeat

    We will not treat a successful media write as proof the file is the file. The RI clips “uploaded.” They were the wrong bytes. SHA-256 against the kit is the check. Visual vibe is not the check. “It posted” is not the check.

    Same class of mistake as minting -2 slugs when the first URL is still live. The system accepted the write. The system did not protect the shape of the library. Operators have to put the hash and the 301 in the done-when, or the agent will keep delivering a green card with the wrong object behind it.

    The patch still open

    Nginx on the Restoration Intel box is still 1 MB. That is the open patch. The article is fixed. The next fat REST upload is not. 32m on nginx and 32M on PHP upload/post is the actual close. Until that lands, every media write on that VM is one leftover limit away from another squash.

    Second open, different box: a traffic spike on the knowledge cluster around 1:51 PT. The card says about 2,487 requests per hour and nine wp-login POSTs. The instruction on the card is a read-only log pull and a one-paragraph verdict. No firewall change, no plugin change, no credential change without a named gate. That card is still not started. A spike is not automatically an attack and it is not automatically “leave it.” It is a log plus a verdict. Until the verdict exists, it stays an open patch, not a story.

    GitHub this week added nothing to the picture. Org repos last moved in July and August. No commit lane, no issue lane worth citing. The week’s failures were in the CMS and the reverse proxy, which is where most of this operation actually lives.

    Shipped this week on the public site was other work: citation desks, storm desks, a Canva template read, a Mastheads changelog note. None of that is this post. This post is the three cards that broke or got taped. The clips match the kit now. The twin Claude URLs 301. Home still does not point at the guide. The 1 MB limit is still sitting on the box that will eat the next file.

  • Your Website Doesn’t Need More Traffic. It Needs to Be the Answer.

    Your Website Doesn’t Need More Traffic. It Needs to Be the Answer.

    Most restoration contractors are invisible where it now matters most: inside the AI answers. When a facility manager asks Copilot who to call for a commercial loss, the model does not scroll your homepage. It cites whoever taught it the cleanest sentence.

    Your website does not need more traffic. It needs to be the answer. Zero-click search already took the click. The remaining win is being named inside the answer itself. That is a different game than ranking a page, and most agencies are still scoring the old one.

    Cited answer. A cited answer is the short, checkable sentence an answer engine lifts into Copilot, ChatGPT, Perplexity, Gemini, Bing Copilot, or a Google AI Overview and attributes to a URL. Traffic is optional. The attribution is the asset.

    Why are restoration contractors invisible inside AI answers?

    Commercial buyers no longer start with a ten-blue-link session. They type the job into an assistant: who handles a sprinkler discharge on a mid-rise, what a drying standard actually requires, whether a vendor is after-hours in this metro. The model answers from pages that already look like briefings.

    Most contractor sites still look like brochures. Hero image. Five service tiles. A form. A blog post that restates the service name. There is no 40-to-60-word answer under the question the buyer asked. There is no timetable, no definition, no named protocol. The model has nothing safe to lift, so it lifts a national franchise FAQ, an insurer explainer, or last year’s trade-press roundup.

    That is not a branding problem. It is a retrieval problem. We wrote the longer architecture in Restoration Company SEO: Fix Your AI Search Visibility and in the three-layer SEO / AEO / GEO frame. This note is the field version: one receipt, one buyer question, one scoreboard change.

    What did a 20-page race guide teach us about citations?

    Race weekend in Madrid. We published a small independent visitor guide at racemadrid.com — twenty static pages, Spanish primary, English secondary, no ticket shop. Through 8 September 2026, Bing Webmaster showed 144 clicks and 3,218 AI citations. On 8 September the model quoted the site 55 times for every human click.

    The queries were not “who wins.” They were traveler questions: Sunday end time, cash or card, gate open, hotel to track, can I bring a bag. The pages that earned both clicks and citations were the schedule, the circuit, and the FAQ. That field note is public: We Built a Tiny Site for a New F1 Track. The Clicks Were Small. The Citations Were Not.

    Same playbook we run for restoration companies: be the clearest answer to the question the buyer is actually asking. A facility manager after a loss is in the same posture as a traveler the night before a sold-out race. They do not want your brand story. They want the next true sentence.

    How is that different from SEO?

    SEO still matters. It is the foundation that lets a URL exist, resolve, and get fetched. AEO is how a featured snippet or People Also Ask box can lift a clean block. GEO is how a generative engine decides you are safe enough to speak for. We treat them as concentric layers on one page, not three rewrites. The operator version of that stack is in What Is GEO? and in what GEO delivery looks like inside a real engagement.

    LayerQuestion it answersWhat you ship
    SEOCan the engine find and trust the URL?Title, meta, headings, first-100-word keyword, internals, schema that is true
    AEOCan a snippet lift one block without rewriting you?Question H2, 40–60 word answer, FAQ, definition box
    GEOWill a model cite you when a buyer asks in chat?Checkable facts per paragraph, entity names, dates, sources, bilingual or local variants when the buyer uses them

    If you only measure sessions, you will call a 55-to-1 citation ratio a failure. If you measure whether the model will say your name when a facilities director asks who to call, that ratio is the product.

    What does the restoration version of a cited answer look like?

    It looks like a briefing, not a pitch. The H2 is the question. The next paragraph answers it in plain language, with a number or a standard attached. Then the proof: what you do on site, what you do not do, the metro you actually cover, the clock you keep.

    • Who to call after a commercial sprinkler discharge in this building class, after hours.
    • How long a category of water stays a drying job before it becomes a rebuild conversation.
    • What the carrier packet has to include on day one so the file does not stall.
    • Which document the facility manager should send before the first truck rolls.

    Write those as answers a model can quote without inventing a second sentence. Put the misspellings and the local names on the page on purpose. Madrid taught us that travelers cannot spell a new circuit. Facility staff cannot spell your d/b/a either. Cover the words they type.

    What is a citation worth if nobody clicks?

    On the race guide, a citation is proof of position. It is not a ticket sale. We said that in the field note and it stays true here. A restoration citation is worth more than a travel citation only if you already own the next step: the phone, the after-hours board, the approved-vendor list, the estimator who can take the job tonight.

    If the sentence the model lifts is wrong, the citation is a liability. We locked a Sunday start time off an older F1.com page and the official MADRING time was later. That error is still the most-clicked kind of question in the logs. The next hour of work is not a new URL. It is correcting the fact the model already trusts. Restoration pages have the same failure mode: an outdated response-time claim will travel farther than the correction.

    What we would not claim

    • That 144 Bing clicks is a media business.
    • That citations replace Google. The Madrid export is Bing Webmaster plus Clarity. Google Search Console is a separate pile.
    • That being cited is automatically good. It is good if the fact is right and you have a use for the attention.
    • That this article invents a new discipline. SEO, AEO, and GEO are already named on this site. This is the operator sentence we are willing to put on LinkedIn and stand behind.

    What we would do again

    Show up early on a named question that does not have a settled official FAQ. Write the buyer’s language, not the agency’s. Keep the page short enough to finish. Put the clock in one place and keep it tied to a source you can defend. Do not invent a content brand around a weekend — or around a single storm.

    The models will quote you if the sentence is plain. The humans who still click will click the schedule, the response protocol, the packing list. Everyone else will take the answer and move. Your job is to be the sentence they take.

    FAQ

    What is the difference between AEO and GEO?

    AEO — Answer Engine Optimization — structures a page so a featured snippet, People Also Ask box, or voice result can lift a complete answer. GEO — Generative Engine Optimization — structures the same page so a generative model will cite that URL when a person asks in chat. One page. Two retrieval systems.

    Does zero-click search mean a restoration website is useless?

    No. It means the homepage-as-brochure is the wrong artifact. The useful site is a set of briefings the model can quote and the buyer can still open when they need the packet, the photo standard, or the after-hours number.

    How do you know a page is being cited?

    You measure it on more than one desk. Bing Webmaster now reports AI citations. Clarity shows whether the humans who still arrive actually read. Prompt checks in Copilot, ChatGPT, Perplexity, and Gemini tell you whether the brand is named. We keep the method on AI citation monitoring and on the Bing citation mining thesis.

    Is this only for restoration companies?

    No. Restoration is the vertical where a missed answer has a wet building attached to it. The same pattern holds anywhere a buyer asks an assistant a time-sensitive operational question and needs a named next step.

    Sources: Will Tygart, Tygart Media, Tacoma, WA, 11 September 2026. First-party Bing Webmaster and Microsoft Clarity figures for racemadrid.com through 8 September 2026, as published in the Madrid field note. Related Tygart pages: restoration AI visibility, GEO explainer, GEO delivery.