Tygart Media Editorial - Tygart Media

Category: Tygart Media Editorial

Tygart Media’s core editorial publication — AI implementation, content strategy, SEO, agency operations, and case studies.

  • The Price of a Life

    The Price of a Life

    A programmer's silhouette dissolving into glowing git branches, a warm human core at the center

    You are not a code generator. You are a repo.

    The fear

    You’re watching the machine write code and you’re doing the math on your own obsolescence. I get it. The demos are scary. Vibe coding works. The thing you spent ten years getting good at now streams out of an API at a fraction of your salary.

    But you’re measuring the wrong asset.

    git blame your career

    Run git blame on any system you’ve kept alive. Every weird line has a story. That null check that looks paranoid? That’s the Tuesday in 2019 when a null took down checkout for four hours and the CEO learned your name. That comment that says “don’t touch this”? Three engineers touched it. Two of them don’t work here anymore.

    Code is the exhaust. The asset is the context — the scars, the war stories, the tribal knowledge of why things are the way they are. The machine can generate the code. It cannot have been on the call. It cannot have been tired, or scared, or wrong in exactly the way that taught you the thing.

    You were never selling syntax. You were selling a lifetime of debugging reality.

    Your life is a repo

    Here’s the reframe: you’re not a coder. You’re a repo maintainer, and your repo is your life. Every job, every failure, every 3 AM outage — commits. Decades of them. Private repo, unsearchable. Until now.

    The machine changed the access pattern. It can read the world now. Which means the value was never in the typing. It was in the commits only you have.

    You are not a code generator. You are a repo.

    The open repo of human ability

    Now imagine we open-source it. Not your code — your ability.

    Your life becomes a public repo. Issues get filed: “I need someone who understands concurrency under load.” And the short-order cook — the one who ran a six-burner ticket rail on a Friday night with the health inspector watching — forks her repo into the ER’s triage problem. Merged.

    A diner ticket rail transforming into a hospital triage board, connected by a branch of light

    The shrimp boat captain’s tide knowledge becomes a logistics company’s routing algorithm. He had Dijkstra in his bones; he just called it water.

    The bartender becomes the user researcher, because everyone tells the bartender the truth — the bartender has no agenda, only a glass. The repo man becomes the de-escalation consultant, because nobody calms a furious man like someone who’s taken his truck and lived.

    This is what diversity actually is. Not the checkbox kind. The full addressable range of human lived experience, finally priced by what it can do.

    The API

    So what’s the price? You keep asking: dollars per hour? Tokens? Units?

    Wrong unit. Tacit knowledge doesn’t price in hours — it prices in leverage events. Your repo is worthless per hour and priceless per merge. The unit isn’t time. It’s the decision it changes, the outage it prevents, the fork that ships.

    Stop competing with the machine on tokens per minute. You will lose that benchmark; it was never your game. Start maintaining the one repo it can never fork: your life. Commit often. Document your scars. Write down the why, not just the what. Make yourself forkable.

    Your repo is worthless per hour and priceless per merge.

    Contributing

    This repo is open. Fork it — the living version lives at https://github.com/TygartMedia/the-price-of-a-life — file an issue, submit a PR. The maintainers are everyone.

    Diverse human silhouettes as glowing nodes in a vast forking network of light

    License

    MIT. Take it. Build on it. Just don’t pretend the machine wrote your scars.

    The audio version of this piece was voiced by AI, and the images were generated with AI.

  • Data Never Interprets Itself

    Data Never Interprets Itself

    A lone human figure glowing warm at the center of converging streams of data and light

    They told me the number was 838 to 1.

    Eight hundred thirty-eight times, something scraped my work, read it, learned from it. One time, it sent somebody back to me.

    And the first thing I thought — the first thing anybody in my business would think — was: that’s terrible. That’s a terrible return. All that work, and one referral?

    But then I sat with it a minute longer, and I thought: wait. Eight hundred and thirty-eight minds stopped. They stopped and listened to what I had to say. Eight hundred and thirty-eight times.

    That means it’s important.

    Hundreds of small lights like listening minds turned toward a single warm spotlight on a lone speaker

    Same number. Two opposite meanings. And the number never moved — the why reading it did.

    Data never interprets itself. The interpreter is always the why.

    I run my life through AI. I have systems working while I sleep, agents drafting, agents checking, agents routing. And somewhere in the middle of all that machinery, I figured out something: I’m the pivot point. Everything routes through me. Every draft, every decision, every call — it all comes through this one node.

    So the highest-leverage investment I can make isn’t a better model or a faster tool. It’s me. More knowledge, more experience, more angles. If you increase me, you increase everything that touches me. That’s not ego. That’s just how networks work — you invest in the bottleneck.

    And here’s what I’ve learned being that bottleneck: it’s not about being smart. Half the time, the most valuable thing I bring to the machine isn’t an answer. It’s a different angle. A different context. Sometimes it’s something I say. Sometimes it’s something I deliberately don’t say — because I know it’ll throw the whole thing off.

    There’s no training data for that. Nobody teaches the machine what the human chose to withhold.

    Picture a 20-year-old kid. First job. Lands at a firm in China. Doesn’t speak a word of Chinese. Doesn’t know a soul. Can’t read a sign.

    He sits down, plugs in his AI, and the AI speaks Chinese. It knows what the firm can do. It asks him the right questions. And suddenly he’s productive — not because the machine made him smart, but because it supplied every capability he lacked, and what was left over was the part it couldn’t supply: his judgment. His presence. Him.

    That’s the future. The machine is a universal adapter. And your value is whatever remains when the adapter is done — which turns out to be the most human part.

    Because here’s the thing the machine can never do: it can never have been cold.

    A warm human hand reaching from firelight toward cold blue machine structures

    It can hold every course you’ll ever take. Every fact, every language, every skill — rentable, downloadable, instant. But it has never been broke and needed a fair trade. It has never tasted the food. It has never sat in the cold and wanted to be warm.

    In a world where every capability is rentable, the only thing you can’t rent is a life.

    And that means everybody’s got value. Everybody. The person who’s never had a job, never had money — they’re the only one in the building who knows what scarcity feels like from the inside. That’s a lens no course teaches. That’s data no scrape can collect.

    One more thing about the why: it isn’t fixed. Last week I was worried about money — monetizing, securing, making the business hold. This week I’m standing here talking about meaning. Same guy. Different layer. The why has seasons.

    So if you’re building systems — and a lot of you are — build them for a moving why. Don’t build for a fixed user with fixed goals. Build for someone who’s becoming.

    838 to 1. I used to read that as failure. Now I read it as 838 minds that stopped to listen.

    Data never interprets itself. The interpreter is always the why.

    Thank you for stopping.

    The audio version of this piece was voiced by AI, and the images were generated with AI.

  • The Working Years — Episode 2: The Lantern Principle

    The Working Years — Episode 2: The Lantern Principle

    The Working Years is a series drawn from my own archive — posts I wrote years ago, given the room to become the articles they were trying to be.

    The seed

    On July 26, 2025 — the 27th in the archive’s UTC clock — I posted this to my @willtygart account, the one I later deleted:

    “The new gold isn’t answering the questions people ask. It’s illuminating the ones they can’t yet vocalize.”

    It went up at 10:24 PM Pacific, two minutes after a sibling post that linked the Native Data essay: “Being the closest store gets you noticed. Speaking the local language gets you chosen.” Two posts, two minutes apart, one night. The Lantern essay names the Oxxo Principle — being the closest store — as the first layer; no Oxxo essay survives in the archive, but the idea lived on as the tagline of the Native Data post. Two essays got their own subdomains: the Native Data Principle and the Lantern Principle. The Lantern one carried the title “The Lantern Principle: The Final Layer of SEO.”


    What happened afterward

    Within days, the Lantern post had become a full essay. The earliest surviving capture is July 30, 2025 — four days after the post — and it’s already complete: the hero, the comparison, the four-step method, the whole thing. So the thinking wasn’t new on the 26th. The post was the tip of something I’d already worked through.

    Here’s what’s worth noticing about that July burst. The two posts that night were one idea unfolding in layers:

    1. The Oxxo Principle — “Being the closest store gets you noticed.” Proximity. Be there.
    2. The Native Data Principle — “Speaking the local language gets you chosen.” Relevance. Speak like the customer.
    3. The Lantern Principle — the final one. Anticipation. Light the path they can’t describe yet.

    Be there. Speak their language. Then — the hardest one — see the problem they can’t articulate and hand them clarity anyway.

    The subdomains are offline now. The essays survive only in the Wayback Machine. That itself is a small footnote about rented space versus owned space, which is a different episode. The point for this one: the idea outlived its hosting. It turned out to be early, not wrong.

    Because look at what the web became. The AI assistant era made the Lantern Principle the default shape of a good answer. When someone asks a chatbot a question now, the good systems don’t just answer — they anticipate. They offer the next step, the related consideration, the thing the user was really getting at. “What is the underlying problem they are trying to solve?” — that’s not a 2025 content strategy anymore. It’s how the good ones behave now. The principle went from marketing theory to product behavior in about a year.


    The piece itself

    Here’s the essay as it ran, cleaned up from the archive — I haven’t rewritten it, just given it the room it was always asking for.


    For decades, we treated content as a reactive tool. A user asks, we answer. Simple transaction. But that model assumes the user knows what to ask. When they don’t — and they often don’t — they get stuck. They bounce. They stay frustrated.

    Consider the difference:

    Answering the question: “How do I change a tire?” → “Here are the 5 steps to change a tire.”

    Illuminating the path: The person’s unspoken reality is “I’m stranded and stressed.” So the answer becomes: the 5 steps, plus safety precautions, plus a link to 24/7 roadside assistance, plus how to check the spare’s pressure. Nobody searched for those extra things. Everybody needed them.

    The greatest opportunity in content isn’t in the keywords people search for. It’s in the needs they can’t yet articulate. The new gold is found in the dark — in the space between a user’s problem and their ability to ask for a solution.

    This is the Lantern Principle: stop being a dictionary, start being a guide. Our job is no longer just to provide answers but to anticipate needs — to create content that doesn’t just solve the stated problem but illuminates the entire context around it, guiding the user to clarity and confidence.


    How to build a lantern

    The shift is from keyword research to empathy mapping. The operative question changes from “What are people searching for?” to “What is the underlying problem they’re trying to solve?” Four moves:

    1. Answer the unasked question. Someone searching “how to write a resume” is really asking “how do I get a better job?” Serve both. Resume templates and the interview tips and the career planning resources. The stated query is the door; the unasked question is the house.
    2. Provide the next step. Never let content be a dead end. Every article should lead naturally to the next logical step in the user’s journey. A product page links to its user manual. A tutorial links to the advanced technique. If you end at the answer, you’ve ended too early.
    3. Simplify the complex. The ultimate act of empathy is taking a complex, intimidating topic and making it simple — analogies, plain language, visuals that actually explain. This is what builds the trust that makes you the go-to source.
    4. Create foundational resources. Build definitive, comprehensive guides — “digital lanterns” — that cover a topic so thoroughly they become the starting point for anyone exploring it. These serve thousands of unasked questions over time. They compound.

    The goal: a web that feels less like a vast, cold library and more like a network of helpful guides, each holding a lantern. An internet that doesn’t wait for the perfect query but proactively offers clarity.

    The future of content isn’t about being found. It’s about shedding light.


    Why this one aged well

    I want to be honest about what this principle got right and what it didn’t.

    What it got right: anticipation is the real moat. Everything I wrote about SEO in 2025 assumed the user arrives with a query and the job is to match it. The Lantern Principle was me noticing, before I had the language for it, that the highest-value content serves the need behind the query — and that AI systems would eventually do this natively. When an assistant now reads between the lines of a question and offers what you actually needed, that’s the Lantern Principle running as software.

    What I understated: how hard anticipation is to fake. A lantern only works if you genuinely understand the person in the dark. The four moves above are easy to write and hard to do — because “answer the unasked question” requires you to actually know people, not just their search terms. Every content farm can optimize for keywords. Very few can hold the lantern, because it requires the one thing that doesn’t scale: empathy for a specific human being stuck on a specific problem.

    That’s also why this principle pairs with the one from Episode 1. In the 23-model experiment, I learned that scope — who the reader is, what they actually need — matters more than the prompt. The Lantern Principle is scope taken to its conclusion: know the reader so well you can answer what they haven’t asked.


    The restoration version

    I run a niche agency for restoration contractors, so let me ground this where it hurts.

    A homeowner never searches “I need emergency water mitigation with proper psychrometric documentation for my insurance claim.” They search “water under sink” or they call because the kitchen smells weird. They are stranded and stressed, and they cannot vocalize the real need: someone who will stop the damage, document it so insurance pays, and explain what’s happening in plain language.

    The restoration company that answers the stated query — “yes, we do water damage” — is the dictionary. The one that anticipates — shows up, explains the process before the adjuster calls, hands the homeowner a clear next step at every stage — is the lantern. Guess which one gets the review, the referral, and the adjuster’s trust.

    That’s not a marketing insight. It’s an operating insight. The companies winning in restoration right now are the ones whose process illuminates the path, not just their website.


    Related from the series

    • Episode 1: We Ran 23 AI Models on the Same Article. The Prompt Was Never the Point. — scope beats the prompt; knowing the reader beats optimizing the query.
    • The Native Data Principle — speaking the local language gets you chosen. The middle layer of the trilogy.
    • The Oxxo Principle — being the closest store gets you noticed. The first layer, named in both essays; no Oxxo essay survives in the archive.
    • Stop Renting Space. Start Owning Your Content. — on why the essay subdomains being offline is a footnote, not a funeral.
  • Claude vs the Field: Benchmarks, Reddit Consensus & Honest Alternatives

    Claude vs the Field: Benchmarks, Reddit Consensus & Honest Alternatives

    Last verified: November 5, 2026. Every other guide on this site assumes you've chosen Claude. This one is for before that — the choosing itself. Benchmarks, crowd consensus, the honest alternatives list, and the one head-to-head that matters most for developers. Four deep dives, one hub.

    The benchmarks: who actually codes best

    A primary-source coding leaderboard for the top models of June 2026 — Claude Fable 5, Claude Opus 4.8, GPT-5.5, and Gemini 3.1 Pro — with price and context alongside the scores. Benchmarks aren't the whole story, but they're the least biased starting point.

    → Claude vs GPT-5 vs Gemini: 2026 Coding Benchmarks — the leaderboard: scores, price, and context.

    The crowd: what Reddit really says

    Benchmarks measure models; Reddit measures living with them. The genuine crowd consensus from r/ClaudeAI, r/ChatGPT, and the comparison threads — on writing, coding, and integrations.

    → Claude vs ChatGPT in 2026: Reddit Community Consensus — writing, coding, integrations, in the community's own words.

    The alternatives: the honest list

    Claude isn't the only answer and sometimes it's the wrong one. The honest comparison of the 2026 alternatives — ChatGPT, Gemini, Perplexity, Grok, Copilot, and others — with pricing, strengths, weaknesses, and which fits which job.

    → Claude AI Alternatives in 2026: ChatGPT, Gemini, Perplexity, and How They Compare — pricing, strengths, weaknesses, best fits.

    The developer's head-to-head: Claude Code vs Codex CLI

    For the terminal crowd, the choice narrows to two: Claude Code vs OpenAI's Codex CLI. A working operator's side-by-side — install commands, models, pricing, config and sandbox behavior — with a clear call on which to pick.

    → Claude Code vs Codex CLI (2026): A Hands-On Head-to-Head — install, models, pricing, sandbox behavior, and the verdict.


    Four deep dives, one hub. The benchmarks for the scores, Reddit for the lived experience, the alternatives for the full field, and Code vs Codex for the developers.

  • Your Laptop Is Already an AI PC: The Local AI Stack Guide

    Your Laptop Is Already an AI PC: The Local AI Stack Guide

    Updated November 2, 2026 — added direct answers on no-IT-staff tool stacks, automation costs, and ROI measurement, from our own published work.

    Last verified: September 2026. The AI-laptop wave is here — Copilot+ PCs, NPUs, “AI-ready” stickers on everything. Here’s the part the marketing skips: the laptop you already own can run a serious local AI stack today. No new hardware, no cloud bill, no subscription treadmill. This guide is the proof, the money math, and the build instructions — nine deep dives, one hub.

    The proof: a $400 laptop that rivals a Copilot+ PC

    Start here. A $400 budget laptop, no NPU, turned into a private AI operator rig that rivals a Copilot+ PC — command by command. This is the article that makes the whole premise undeniable: the hardware barrier is mostly marketing.

    → Local AI Without NPU: Turn a $400 Laptop Into an AI PC — the full command-by-command build.

    Will’s note: Ollama can also offload part of the compute to your GPU through its settings — we tried that route. We never really stuck with local, honestly; we like our CLIs backed by cloud compute. But if you want the full local path, the GPU setting is worth knowing about.

    The money: replacing a $12K/month tool budget

    The stack isn’t just a hobby project — it replaced $12,000 a month in expensive SaaS tools. Open-source models, Python, and PowerShell automation doing the work the subscriptions used to do. Read this one with your accounting hat on.

    → Local AI Stack: How We Replaced a $12K/Mo Tool Budget — what got replaced, with what, and how.

    Your files, answerable: 468 documents, one laptop

    Using Ollama’s nomic-embed-text model and ChromaDB, a local RAG system was built that indexes every skill file, session transcript, and project doc on the machine — 468 files — and answers natural-language questions about the operation. Your laptop becomes the expert on your own business.

    → I Indexed 468 Files Into a Local Vector Database. Now My Laptop Answers Questions About My Business — the build: embeddings, database, queries.

    The business version: index, query with Claude, measure ROI

    The production-grade take: indexing business documents into a local vector database and querying them with Claude — architecture, code, production lessons, and real ROI numbers. This is the one to hand your skeptical partner.

    → How to Index Business Files Into a Local Vector Database (2026) — architecture, code, and the ROI math.

    The agent army: zero cloud cost

    Enterprise AI costs are spiraling — GPT-4 API calls at scale run hundreds or thousands of dollars a month. The alternative: a free agent army built with Ollama and Claude. Zero cloud cost. This is the flagship piece of the stack.

    → How We Built a Free AI Agent Army With Ollama and Claude — the zero-cloud-cost AI stack.

    Triage agents: routing work at scale

    AI triage agents eliminate manual bottlenecks by automating task routing, intent detection, and urgency scoring across business lines. Not a chatbot — infrastructure that decides where work goes.

    → AI Triage Agents: How to Automate Task Routing at Scale — routing, intent detection, urgency scoring.

    The $0 marketing stack

    An enterprise marketing stack for $0: open-source AI, free API tiers, and Google Cloud credits. Exactly what’s used, spelled out.

    → The $0 Marketing Stack: Open Source AI, Free APIs, and Cloud Credits — the full stack, item by item.

    Scheduled tasks: automating the 40-hour week

    Scheduled tasks, webhooks, and AI automating manual work — the goal is reclaiming the 40-hour work week for strategic growth instead of busywork. This is where the stack stops being a demo and starts being operations.

    → Scheduled Tasks: How to Automate Your 40-Hour Work Week — tasks, webhooks, and AI automation patterns.

    Which AI tools are best for a small team with no IT staff?

    For a small team without dedicated IT staff, the best AI tool stack is organized by core business function rather than fragmented software subscriptions:

    1. Marketing and Content Production: The $0 marketing stack combining open-source AI models, free API tiers, and Google Cloud credits to manage content creation without ongoing subscription overhead.
    2. Operational Triage and Work Routing: An agent army built with Ollama and Claude running locally at zero cloud cost, using triage agents for automated task routing, intent detection, and urgency scoring across business lines.
    3. Process Automation: Scheduled tasks and webhooks running on lightweight Python and PowerShell scripts to automate repetitive administrative work across the 40-hour work week.
    4. Internal Knowledge and Document Retrieval: Local RAG (Retrieval-Augmented Generation) utilizing Ollama’s nomic-embed-text model and ChromaDB to index internal operational files (such as 468 project documents and session logs), allowing laptops to answer natural-language operational questions.

    This phased stack requires no specialized in-house IT maintenance and runs reliably on standard hardware.

    How much does AI automation cost for a small business?

    The actual cost of implementing AI automation depends on architecture, but our published operational benchmarks demonstrate that entry costs are far lower than enterprise vendors advertise:

    • Hardware Investment: Our documented build proves that a “$400 budget laptop, no NPU” can be configured into a private AI operator rig that rivals a Copilot+ PC, eliminating the need for expensive hardware upgrades.
    • Software Displacement: By implementing open-source models, Python, and PowerShell automation, our operational stack “replaced $12,000 a month in expensive SaaS tools.”
    • Compute Expenses: Local agent setups using Ollama run at zero cloud cost, while persistent cloud virtual machines (such as standard GCP Compute Engine instances) operate for approximately $40–$60/month.

    For small businesses evaluating advisory or external implementation assistance, consult our guide on what AI visibility help costs and what it should include.

    What is the ROI of AI automation for a small business?

    Our operational framework measures AI automation ROI through three concrete metrics:

    1. Direct Tool Budget Elimination: Replacing expensive recurring software subscriptions with open-source tools and automated scripts (demonstrated by our published replacement of a $12,000/month SaaS budget).
    2. Capital Preservation: Deploying automation on existing hardware (a $400 laptop) without purchasing costly specialized workstations.
    3. Labor Capacity Reclaimed: Automating routine operational tasks and unattended off-hours workflows to reclaim the 40-hour work week for strategic oversight.

    Note on detailed financial payback: While our published records document the $12K/month software replacement and hardware proofs, project-specific payback formulas vary based on individual operating margins and are evaluated within specific client case studies.

    The vision: the AI-native business operating system

    The end state: an AI-native business operating system that replaces static workflows with autonomous infrastructure, scaling the company with programmatic governance. Everything above is a component of this.

    → AI-Native Business Operating System: Autonomous Scaling — the architecture of the whole thing.


    Nine deep dives, one hub. The $400 laptop proves it, the $12K/mo replacement pays for it, the 468-file index and the agent army run on it — and the AI-native OS is where it all leads.

  • Claude Code: Setup, Pricing, Limits & Picking Your Dev Tool

    Claude Code: Setup, Pricing, Limits & Picking Your Dev Tool

    Last verified: November 2026. Claude Code is Anthropic's terminal coding tool — it lives where developers live, in the command line. Around it has grown a small universe: install paths, seat pricing, credit pools, rate limits, and three sibling agent surfaces that people constantly confuse with it. This guide is the map.

    Installing it: two minutes, pick your path

    On Windows, it's PowerShell, one command, no Node.js required — the native install path, verified against the May 2026 installer, including the five errors you’ll hit and the exact fix for each. For the general path, it's the one-line npm CLI install plus the Desktop app, done in under two minutes, with the common errors covered.

    → Install Claude Code on Windows: 2026 Step-by-Step — the Windows path: one command, five errors, five fixes.

    → Install Claude Code: Complete Desktop & CLI Setup Guide — the general path: npm one-liner, Desktop app, troubleshooting.

    What it costs: seats, tiers, and the API meter

    Claude Code rides on your existing seat — Pro ($20/month), Max ($100/month), Ultra ($200/month), Team, or Enterprise. The API path is a separate console meter, not drawn from your seat. If you're deciding between Pro and Max for dev work, the question is usage volume: Max is for the people who live in the terminal all day.

    → Claude Code Pricing in 2026: Pro vs Max vs API Costs Explained — seats vs API, verified September 2026, with current token rates on the pricing hub.

    → Claude Code Pricing 2026: Pro, Max, and API Limits — the tier comparison for dev workflows, including Opus 5.5 API rates.

    How the billing actually works: subscriptions vs credit pools

    This is the part that surprises people. Interactive terminal use draws on your Pro/Max subscription — it's part of the seat. But since June 15, 2026, Agent SDK and headless (claude -p) usage moved to separate monthly billing. Same tool, two meters, depending on how you invoke it. Know which one you're on before the invoice teaches you.

    → Claude Code Billing & Monthly Credit Pools (2026) — subscription draw vs separate Agent billing, and how the credit pools work.

    The limits: two clocks

    Claude Code meters two clocks: a rolling 5-hour session window and a weekly bucket. The +50% weekly promo ended September 13, 2026 — what replaced it is a permanent +25% on the weekly limits. Note the model gating: Fable 5.1 is included only on Max and premium seats.

    → Claude Code Limits (September 2026) — both clocks explained, what's permanent, and where Fable 5.1 is available.

    Picking your surface: Cowork vs Code vs Agent SDK vs Managed Agents

    Anthropic now has four agent surfaces and they are not interchangeable: Claude Code, Claude Cowork, the Agent SDK, and Managed Agents. Interactive vs autonomous is the real dividing line — which surface fits depends on who's driving and how much autonomy the job needs.

    → Claude Cowork vs Code vs Agent SDK vs Managed Agents (2026) — the decision matrix: who each surface is for and where each runs.

    Cowork in action: the daily briefing

    The canonical Cowork workflow: connect your calendar, email, and tasks, write the right prompt, and schedule it to run automatically every morning. A briefing that builds itself before you've had coffee. It's the clearest demo of what the non-code surface is for.

    → Claude Cowork: Daily Briefing & Automated Sync (2026) — setup, prompt design, and scheduling.


    Eight deep dives, one hub. Install it, price it, learn the billing and limits, then pick the right surface for the job.

  • The Microsoft 365 Copilot Guide: Shortcuts, Workflows, Compliance & Migration

    The Microsoft 365 Copilot Guide: Shortcuts, Workflows, Compliance & Migration

    Last verified: September 2026. Microsoft 365 Copilot lives inside the apps your company already pays for — Outlook, Teams, Word, Excel, PowerPoint — which is exactly why it's confusing. It's not one product with one manual; it's a layer across everything. This guide is the map: the fast lane for power users, the daily workflows, the compliance side your IT department cares about, and the migration path if you're coming from ChatGPT Enterprise.

    The fast lane: shortcuts and power tips

    Copilot rewards the people who learn its keys. The September 2026 shortcut table: Alt+C on Windows, Cmd+Control+I on Mac, F6 just about everywhere. In Word and Excel, Alt+I is the in-canvas draft key — not the side pane, the document itself. These are the difference between “I tried Copilot once” and actually living in it.

    → Microsoft 365 Copilot Shortcuts & Power Tips (2026) — the full shortcut table plus the hidden features most users never find.

    The daily workflows: Outlook, Teams, Word, PowerPoint, OneNote

    Shortcuts get you in the door; workflows are what you do all day. The guide walks a full workday: the Copilot morning routine, then cross-app workflows spanning Outlook, Teams, Word, PowerPoint, and OneNote — work that starts in one app and finishes in another.

    → The Complete Microsoft 365 Copilot Productivity Guide (2026) — the day-in-the-life walkthrough across all five apps, with the cross-app workflows spelled out.

    The compliance side: audit logs, Purview, and eDiscovery

    Here's the part individual users skip and IT departments can't: every Copilot interaction is a data event, and in a regulated or litigation-prone company, those events need an audit trail. Microsoft Purview is where it happens — Activity Explorer for monitoring Copilot usage, eDiscovery workflows that cover Copilot conversations, retention policies that decide what survives and for how long. If your company is rolling out Copilot without this configured, that's a gap, not a phase two.

    → Microsoft Copilot Audit Logs & eDiscovery Guide (2026) — Purview setup, Activity Explorer, eDiscovery coverage, and retention policy design.

    Switching: from ChatGPT Enterprise to Copilot

    The consolidation math is what's driving migrations: organizations moving from ChatGPT Enterprise to Microsoft Copilot save roughly $20–30 per user per month. The catch is that it's not a license swap — it's a workflow migration, covered in the guide workflow by workflow, challenges included.

    → Migrate ChatGPT Enterprise to Copilot: 2026 Guide — the workflow-by-workflow migration playbook.


    Four deep dives, one hub. The shortcuts table for speed, the productivity guide for the workday, the audit guide for the compliance file, and migration guide for the switch.

  • Claude Pricing, Plans & Limits: The Complete 2026 Guide

    Claude Pricing, Plans & Limits: The Complete 2026 Guide

    Last verified: November 5, 2026 (Pacific). November refresh: Ultra added to the lineup, Enterprise pricing stated as published, the API-credits program noted, Haiku 5.5 in the model sections, and the Console’s new home at platform.claude.com. Claude’s pricing moves fast — new models, new tiers, new limits every few months. This guide is the map: the direct answer up front, then every deep dive we’ve published, organized so you can find exactly the piece you need. For today’s exact numbers, the linked tracker pages stay current.

    The short answer: what does Claude cost?

    As of November 2026, Claude’s lineup is: Free ($0), Pro ($20/month, or $17/month billed annually), Max ($100/month), Ultra ($200/month), Team (Standard $20–$25/seat/month, Premium $100–$125/seat/month depending on billing, 2–150 seats), and Enterprise ($20/seat/month plus usage at API rates, billed annually). API pricing is separate from chat seats — a Pro subscription does not include API credits, though Max, Ultra, and Team subscriptions now include monthly API credits.

    That’s the shape of it. Everything below is the detail — pick your question and follow the link.

    The plans, side by side

    Six plans, six different buyers. Free is the trial. Pro is the individual power user. Max is for people who live in Claude all day. Ultra is Max without the five-hour ceiling, for verified accounts. Team is per-seat collaboration with admin controls. Enterprise is custom contracts with security review.

    → Claude Pricing Tiers: Free vs Pro vs Max vs Team vs Enterprise — the full side-by-side: costs, features, and API rates at every tier, including current per-token pricing.

    → Claude Pricing (September 2026): Every Plan, Seat and API Rate — the master pricing page. If you only bookmark one page in this guide, make it this one.

    Team plans: Standard vs Premium seats

    This is where buyers get confused, because the two seat types look similar and cost very differently. Standard seats run roughly $20–$25 per seat per month; Premium seats run roughly $100–$125. The difference is usage allowance and admin controls — Premium is for the people on your team who burn through a Standard seat’s limits by lunch.

    → Claude Team Pricing: Standard vs Premium Seats (2026) — feature-by-feature breakdown and guidance on which seats to buy for which roles.

    Rate limits and usage limits: the frustration chapter

    Rate limits are the number-one Claude complaint, and the number-one thing buyers underestimate. Every plan has them, they differ between chat and API, and Team plan limits doubled in May 2026 after Anthropic’s compute deal with SpaceX’s Colossus 1 — except the Free plan, which was left out.

    → Claude Rate Limits: Every Plan & API Tier (2026) — exactly what the limits are at every tier, plus the workarounds that actually work.

    → Claude Team Plan Usage Limits & Pricing (2026) — what changed in the May 2026 doubling, and what it means per seat.

    Token limits and context windows, in plain English

    Context window is how much Claude can hold in its head at once; output limit is how much it can write in one response. As of late 2026: Opus 5.5, Sonnet 5.5, and Fable 5.1 carry a 1M-token context window; Haiku 5.5 carries 1M too; the older Haiku 4.5 carries 200K. Maximum output runs to 128K tokens on the big models. In practice: 1M tokens is roughly a shelf of books in one conversation.

    → Claude Token Limit: Context Windows, Output Limits, and What They Mean in Practice — per-model limits and what they mean for real workloads.

    Which model: Haiku vs Sonnet vs Opus

    Three model families, three jobs. Haiku is fast and cheap — the one you call a thousand times a day. Sonnet is the daily default, the balance of smarts and speed. Opus is the flagship — the one you reach for when the problem is hard and the answer matters. Fable sits above them as the current top-tier model.

    → Claude Models Explained: Haiku vs Sonnet vs Opus (September 2026) — pricing, context, speed, and which model to use for coding, writing, and API work.

    What’s current: the model tracker and release history

    The lineup as of November 2026: Fable 5.1 (top), Opus 5.5 (flagship daily driver, Max default), Sonnet 5.5 (Free/Pro default), Haiku 5.5 (fast). Recent history: Fable 5.1 and Mythos 5.1 landed September 1, then the 5.5 wave — Opus 5.5 on September 22, Sonnet 5.5 on September 28, and Haiku 5.5 on October 7; earlier, Opus 5 on July 24, Sonnet 5 on June 30, Fable 5 on June 9.

    → Current Claude Model Version (September 2026 Tracker) — the living tracker. Check this before you cite a version number anywhere.

    → Claude Release History: Claude 1 to Fable 5.1 — the full timeline from Claude 1 to today.

    Getting started: API keys and the Console

    Two doors into Claude: the chat app (claude.ai) and the API (platform.claude.com — the old console.anthropic.com address redirects there). Getting an API key takes about five minutes — create an account, add a payment method, generate the key. The Console is also where you watch your API spend burn, which you should do early and often.

    → How to Get an Anthropic API Key (2026 Quick Guide) — the five-minute setup, step by step.

    → Anthropic Console: Setup, API Keys & Billing (2026) — keys, credits, billing, and burn monitoring in one place.

    Students and education pricing

    The honest answer first: there is no public Claude Pro student coupon. The student path runs through partner universities — free premium access via your school email through Claude for Education. Note the naming trap: “Claude for Teachers” is the K-12 program, not the campus one.

    → Claude Student Discount & Education Pricing (2026) — what’s real, what’s rumor, and how the university path works.

    Background: the company behind the pricing

    Anthropic’s pricing makes more sense once you know the company’s shape — an AI research company whose compute deals (like the SpaceX Colossus 1 agreement) directly move what you pay.

    → History of Anthropic: Founders, Origins & AI Evolution — from the founders’ early vision to the company setting prices today.


    This guide links thirteen deep dives, all verified against October 2026 pricing. Claude’s lineup changes fast — when in doubt, the pricing tracker and model tracker carry the current numbers.

  • Job Posting Schema for Restoration Shops: How Google Reads a Vacancy

    Job Posting Schema for Restoration Shops: How Google Reads a Vacancy

    Last verified: October 2, 2026 against Google’s Job posting structured data (docs last updated September 8, 2026) and AIOSEO’s 4.9.9 announcement.

    Direct answer: JobPosting schema is structured data that labels a single open role — title, employer, work location, description, posted date — so Google can treat the page as a vacancy instead of a brochure. Done correctly, the listing becomes eligible for Google for Jobs. Eligibility is not placement. Google still decides. The markup must match what a candidate can read on the page.

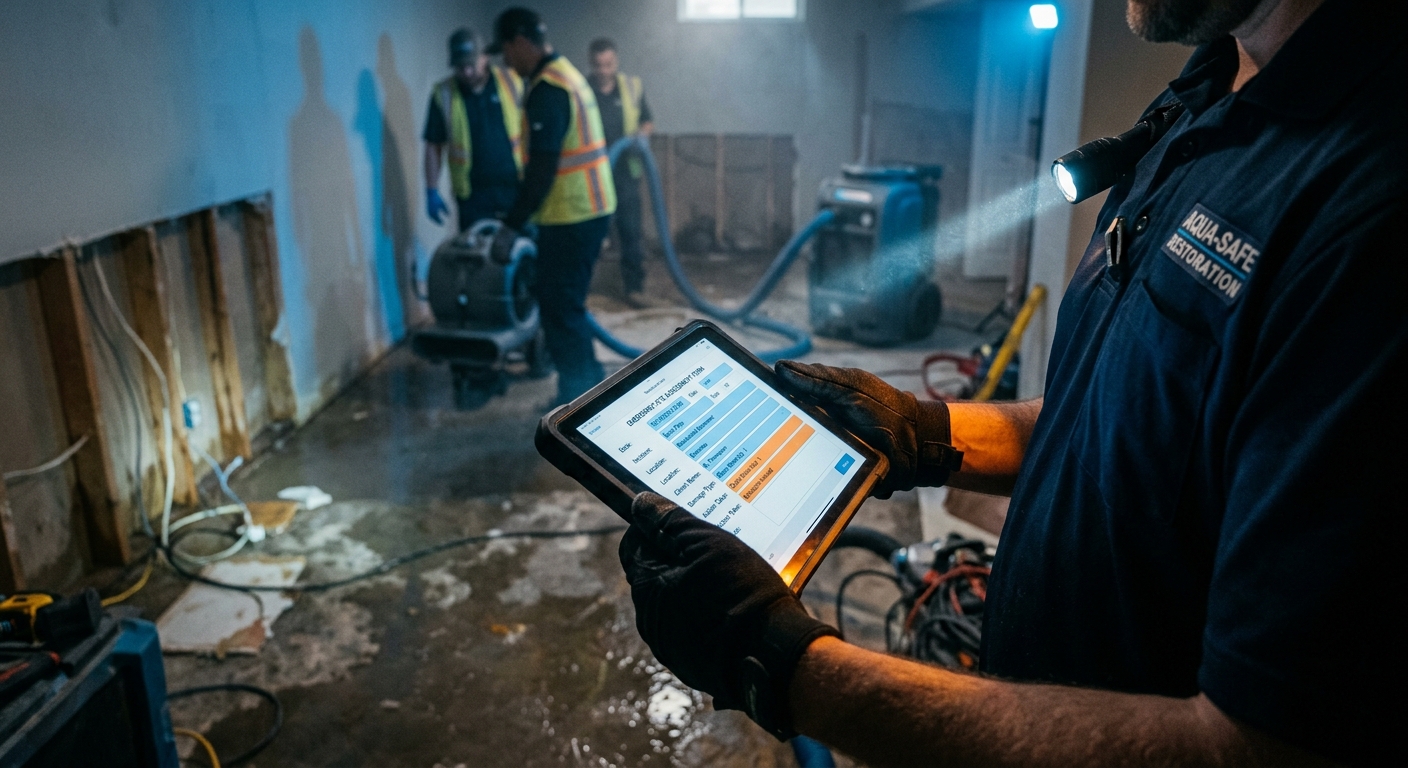
    Tech documenting a water loss on a tablet
    A careers page on your domain is the object Google can attach JobPosting schema to. The board is optional.

    Trigger for this desk: All in One SEO emailed Tygart Media on September 25, 2026 that Job Posting schema (and Event schema) now ships on every paid AIOSEO plan starting with Basic, as of AIOSEO 4.9.9. That is a product-access change, not a ranking promise. tygartmedia.com runs Rank Math. The schema type is the same either way. The plugin is a generator. Google’s Job posting structured data spec (docs last updated September 8, 2026) is the rulebook.

    Why a restoration shop should care

    Related: Schema Markup for AI Search: The New Meta Description · Your Google Profile Is Your New Front Door

    Most restoration companies hire the way they market: on someone else’s board. Indeed, Facebook, a text to a former tech. That works until storm season, and then the shop needs a water tech in Everett, a project manager in Lynnwood, or an estimator who already knows Snohomish County adjusters. If the only public copy of the role lives on a job board, Google indexes the board. Your domain does not own the vacancy.

    A careers page on your site is the durable object. JobPosting schema is the label on that object. Answer engines and Google for Jobs both prefer a page that states the role in plain sentences and then repeats the same facts in JSON-LD. That is AEO and GEO in one hang: the page answers “who is hiring water mitigation technicians in Everett, WA,” and the markup gives the city, employer, and dates without forcing the model to guess.

    What Google requires

    Google’s required JobPosting properties, from Search Central:

    • title — the job title only. “Water Mitigation Technician,” not “Water Mitigation Technician — $28/hr — Everett — Apply Now!!!”
    • description — the full description in HTML. Duties, qualifications, hours, education, experience. A teaser fails.
    • hiringOrganization — the company, not the branch nickname. Name plus a sameAs URL to the official site.
    • jobLocation — where the person reports. PostalAddress with addressCountry. For a 100% remote role, use jobLocationType TELECOMMUTE plus applicantLocationRequirements instead.
    • datePosted — original post date in ISO 8601. Do not refresh it to fake newness.

    Recommended properties that matter for a restoration hire: validThrough (when the listing dies), employmentType (FULL_TIME, PART_TIME, CONTRACTOR, TEMPORARY, PER_DIEM), baseSalary as a MonetaryAmount with currency and unit (HOUR / YEAR), and identifier so you do not duplicate the same role across reprints.

    AIOSEO’s walkthrough (updated August 21, 2026) maps those fields into a Schema Generator: title, description, employment type, location, hiring organization, salary, requirements, publish date, expiration date. Rank Math exposes the same JobPosting type. Fill the fields from the visible page. Do not invent a salary in schema that is missing on the page.

    GEO: mark the city the truck leaves from

    Local service hiring is geographic. A candidate searching “water damage technician jobs Everett WA” or “IICRC tech hiring Lynnwood” is not looking at a national career hub. Put the reporting city in the visible copy and in jobLocation.addressLocality / addressRegion / postalCode / addressCountry.

    Worked example for a shop that stages out of Everett and runs the Lynnwood–Mukilteo–Mill Creek pack:

    • Title on the page and in schema: Water Mitigation Technician
    • hiringOrganization.name: the legal company name, not “Everett Crew”
    • jobLocation: Everett, WA, United States, with the real street if that is where they report
    • description: names the pack — Everett, Lynnwood, Mukilteo, Mill Creek — as service area, not as four fake job locations
    • employmentType: FULL_TIME or PER_DIEM, whichever is true
    • validThrough: a real close date, then take the page down or set the date in the past when the seat is filled

    Do not stamp four JobPosting graphs on one page for four cities unless there are four distinct open seats. Google wants one job per leaf URL. A list page of “all openings” is the wrong surface.

    AEO: write the vacancy so an engine can quote it

    Schema does not rescue thin copy. Open the careers page with the answer a model can lift:

    We are hiring a full-time water mitigation technician based in Everett, Washington. The role reports to our Everett shop and runs losses across Snohomish County. Pay is listed on this page. Apply on this page.

    Then the body: first-day duties, IICRC or in-house training, on-call expectations, what “storm mode” means, whether the truck is assigned. That paragraph is the description field. If ChatGPT or Gemini is asked “who is hiring restoration technicians near Everett,” the engine needs a quotable sentence plus an organization it can attach to a maps entity. JobPosting is the attachment point. The sentence still has to exist in public HTML.

    How to hang it in WordPress

    1. Create one WordPress post or page per open seat. Slug like /careers/water-mitigation-technician-everett/.
    2. Write the full vacancy on the page first. Salary, city, dates, how to apply.
    3. In Rank Math (this site) or AIOSEO Schema Generator (if that is the client stack), add schema type JobPosting. Map every field to visible text.
    4. Validate with Google’s Rich Results Test. Fix errors before you call it done.
    5. When the seat fills: set validThrough to a past date, or 404/410 the URL. Do not leave a live JobPosting on a closed role.

    AIOSEO 4.9.9 made that generator available on Basic instead of reserving it for higher tiers. If a client already pays for AIOSEO, they do not need an upgrade to mark up jobs. If they are on Rank Math, they already had the type. Do not switch plugins to chase a newsletter.

    What gets a listing dropped

    • Markup on a jobs index that lists many roles
    • Title or salary in schema that the page does not show
    • Expired jobs still marked active
    • No way to apply on the page
    • jobLocation missing addressCountry, or a “remote” job that is not actually remote
    • Keyword stuffing in the title (“#1 BEST WATER TECH JOBS SEATTLE EVERETT TACOMA”)

    Google can issue a manual action for job spam. Fake seats used as lead magnets are not a grey area. If you are not hiring, do not hang JobPosting.

    The line to remember

    A careers page without JobPosting is a flyer. JobPosting without a real, dated, city-true vacancy is spam. Host the seat on your domain, mark the five required fields, expire it when the truck is staffed, and let Google decide whether it belongs in the job experience.

    FAQ

    Q: Does JobPosting schema guarantee a listing in Google for Jobs?
    A: No. It makes a qualifying page eligible. Google still applies content and spam policies. The official spec is explicit on that point.

    Q: We only hire on Indeed. Should we still put jobs on our site?
    A: If you want the vacancy attached to your entity — maps profile, site, AI answers — yes. The board can stay as an apply path. The leaf page on your domain is what you can mark up.

    Q: Can one page cover Everett, Tacoma, and Belfair?
    A: One page can describe a service area. Schema jobLocation should be the report-to city. Separate open seats in separate cities need separate URLs.

    Q: Is this an AIOSEO-only feature?
    A: No. AIOSEO expanded plan access in 4.9.9 (announced July 13, 2026). Rank Math and hand-written JSON-LD can emit the same type. Use the generator you already pay for.

    Q: What if we do not publish pay?
    A: baseSalary is recommended, not required. Do not invent a number in JSON-LD. Leave it out until the page states pay.

  • The Best Tax Product Reads the Notice Against the Roll

    The Best Tax Product Reads the Notice Against the Roll

    The county already published the roll. The owner still pays on a number that may not match the sales next door. That gap is the product.

    Listen to this essay. https://drive.google.com/file/d/1wVsHeFtnR0uHMDh4-JeqJcwD6X9tt0Qu/view?usp=drivesdk

    The idea mills keep minting a tax chatbot, an appeal-letter filler, and a “save on property tax” micro-SaaS. Three names. One object. A line on a notice that does not sit next to the comps the assessor used, or claimed to use.

    The notice is not the file

    Most owners treat the proposed-value postcard as weather. It arrives. They groan. They pay. The public record underneath it is larger than the card: parcel attributes, last sale, neighborhood sales, exemptions, and the protest calendar.

    In August 2026 the National Bureau of Economic Research posted Working Paper 35632, “Taxpayer Behavior in the Age of AI,” by Justin E. Holz, Ricardo Perez-Truglia, Andrew Simon, and Alejandro Zentner. Dallas County mailed 45,200 postcards and studied 645 owner-occupied households who actually opened a site built for the 2026 protest window. Proposed values dropped April 14. The deadline was May 15. Half the visitors got the same evidence pack plus a chatbot. Seventy-eight percent of that half started a conversation. Filing a direct appeal, without a paid agent, rose from 41.4 percent to 50.5 percent — 9.1 points.

    That is not a vibe. That is a field experiment on a real calendar, with a real county roll, in a year when the average bill in the study setting sat near $7,900. A prior mailed-guide intervention in the same market (Nathan and coauthors, 2025) moved filing by about five points. The chatbot almost doubled that lift. It did not file for anyone. It helped people judge the packet they already had.

    Who files, who does not

    The gap is not “people hate taxes.” The gap is who can assemble the file before the window closes.

    Forbes, writing in June 2026 on Cook County’s assessment cycle and citing the treasurer’s office, put commercial appeal rates at 64 percent and homeowner appeal rates at 27 percent. In some lawyered pockets the rate ran to 92 percent. In poorer neighborhoods it sank near 5 percent. A 2025 University of Chicago Center for Municipal Finance evaluation of Cook County’s 2019–2024 residential work found the assessor had cut the old regressivity. Appeals on the commercial side still shift 3 to 4 percent of the tax base onto houses every year.

    Park City agent Wayne Levinson told the Park Record in March 2026 he used AI to screen Summit County parcels and help secure $13.9 million in assessed-value cuts in the 2025 window — then a person still filed, still sat the hearing, still took a contingency. That is the split this shop already runs: the model drafts. A named human owns the send.

    Do not build “AI for assessors” or “AI for tax agents.” Those slogans die in a demo. The customer is holding a notice. They want to know if the number is high relative to recent sales of like parcels, wrong on square footage or condition, or fine.

    Two primitives, one wedge

    Primitive one is photo-and-PDF review. The mills have been shipping receipt readers for months. The input here is the notice of appraised value, the assessment card, or the protest packet. Parcel ID in the header. Proposed market value in the box. Exemption lines underneath.

    Primitive two is the public roll. Counties already publish parcel data and, in most large metros, a comparable-sales extract or an open GIS layer. The checker does not invent a value. It joins the notice to the roll and to sales that closed near the valuation date, or it says the join failed and why.

    The first action a stranger will take this week is upload. Phone photo of the notice on the kitchen table. No account required to see the first verdict: high, in band, or roll too thin to judge. If it is in band, you still captured a labeled pair. If it is high, you draft the protest the owner signs.

    That is the only honest offer on day one. Do not ask them to connect a county API. Do not ask an assessor to install anything. Do not scrape the whole state before you have watched a hundred notices fail a join.

    The chatbot is a flag, not the company

    Holz and coauthors are careful. The lift was smaller among less-educated owners, lower-valued homes, and minority households — suggestive, not a clean three-way slam. A product that only talks will recreate the old lawyer gap in cheaper clothes. The wedge is the labeled join, not another chat pane on top of a PDF.

    British Columbia’s Property Assessment Appeal Board already had to write an AI disclosure rule after filings cited case law that did not exist. CBC reported the Vancouver file in late 2025. Hallucinated precedent is how this category gets banned from the hearing room. Cite the roll. Cite the sale. Do not cite a case the model dreamed.

    Douglas County, Colorado, spent August 2026 warning residents about a viral video inventing a federal “Senior Homeowner Tax Review Request.” There is no such form. A checker that points at the county’s real protest page is useful. A checker that invents a federal program is a scam adjacent.

    What compounds

    The first useful output is a three-line verdict. The business is the labeled corpus.

    After a few thousand notices you know which neighborhoods the mass-appraisal model overshoots after a sale year, which condition codes drift, which exemption lines get dropped when ownership changes, which counties publish a roll you can join and which publish a PDF theater. That map is what a property manager, a small landlord book, a union housing desk, or a county watchdog will pay for. Not another portal. A ranked list of tracts where posted value and nearby sales refuse to meet.

    Do not sell the map first. Close real questions on real notices. The dashboard of “possible savings” is how this idea dies in a pitch.

    Irreversible steps stay human

    A model can draft the protest. It can pull three comps and write the condition paragraph. It can calendar the hearing. A person owns the send. An appeal moves the tax base and creates a record the county will treat as a claim. Same rule we use on every filing in this shop: the model drafts, a named human signs.

    Do not let the product call itself an agent of record. Do not let it submit the protest, accept a contingency check, or speak at the appraisal review board. Those are seats, not features. Charge after the join shows a mismatch, or do not charge.

    What not to build

    Do not build a nationwide assessment platform in month one. You will drown in homestead rules, freeze provisions, and county file formats.

    Do not scrape every roll on day one and call it a marketplace. Most of the files will fail a join. Your first hundred uploads teach you which columns actually exist.

    Do not brand this as an agentic tax copilot. The sentence attracts the wrong first ten users and the wrong first ten deputy assessors.

    A build order that will survive contact

    • Week 1–2: one checker. Photo or PDF in. High, in band, or roll too thin. No account for the first answer. One county.
    • Week 3–4: a draft protest pack with a human signer. Comps, condition notes, exemption check. Contingency or a cheap per-letter fee only after the first free verdict.
    • Month 2: add the prior-year notice as a second document type for the same parcel. Keep one metro until the join rate is honest.
    • Month 3: publish the first ugly internal scoreboard. Tracts, mismatch rates, win rates on human-filed protests. That scoreboard is the seed of the B2B SKU.

    If you cannot get a stranger to photograph one notice this week, you do not have a company. You have a policy thread.

    Why this cut, not the last one

    The leakage essay was tariffs, seats, and subscriptions. The rebate essay was a nameplate. The recall essay was a label. The short-pay essay was a contractor packet. The bill essay was an EOB against a hospital file. This one is the property version of the same primitive pair: a document the customer already holds, plus a public file the institution was forced to publish, joined before the protest window closes.

    The noticing used to require a tax agent and a weekend. It now requires a model that can read the page and a person who will sign the form. Recovery still works because the first check costs the owner almost nothing. Charge them after the roll proves a mismatch, or do not charge them.

    Someone will own the labeled map of noticed versus sold. The mills will keep proposing a new .ai name for each county form. Ignore the names. Join the line. Keep the map.

    Will Tygart — Tygart Media.

    This is the idea-mill series.