Tygart Media Editorial - Tygart Media

Category: Tygart Media Editorial

Tygart Media’s core editorial publication — AI implementation, content strategy, SEO, agency operations, and case studies.

  • AI Agents Explained: A 2026 Guide for Business Owners

    AI Agents Explained: A 2026 Guide for Business Owners

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade
    What Is an AI Agent? An AI agent is a software program powered by a large language model that can take actions — not just answer questions. It reads files, sends messages, runs code, browses the web, and completes multi-step tasks on its own, without a human directing every move.

    Most people’s mental model of AI is a chat interface. You type a question, you get an answer. That’s useful, but it’s also the least powerful version of what AI can do in a business context.

    The version that’s reshaping how companies operate isn’t a chatbot. It’s an agent — a system that can actually do things. And with Anthropic’s April 2026 launch of Claude Managed Agents, the barrier to deploying those systems for real business work dropped significantly.

    What Makes an Agent Different From a Chatbot

    A chatbot responds. An agent acts.

    When you ask a chatbot to summarize last quarter’s sales report, it tells you how to do it, or summarizes text you paste in. When you give the same task to an agent, it goes and gets the report, reads it, identifies the key numbers, formats a summary, and sends it to whoever asked — all without you supervising each step.

    The difference sounds subtle but has large practical implications. An agent can be assigned work the same way you’d assign work to a person. It can work on tasks in the background while you do other things. It can handle repetitive processes that would otherwise require sustained human attention.

    The examples from the Claude Managed Agents launch make this concrete:

    Asana built AI Teammates — agents that participate in project management workflows the same way a human team member would. They pick up tasks. They draft deliverables. They work within the project structure that already exists.

    Rakuten deployed agents across sales, marketing, HR, and finance that accept assignments through Slack and return completed work — spreadsheets, slide decks, reports — directly to the person who asked.

    Notion’s implementation lets knowledge workers generate presentations and build internal websites while engineers ship code, all with agents handling parallel tasks in the background.

    None of those are hypothetical. They’re production deployments that went live within a week of the platform becoming available.

    What Business Processes Are Actually Good Candidates for Agents

    Not every business task is suited for an AI agent. The best candidates share a few characteristics: they’re repetitive, they involve working with information across multiple sources, and they don’t require judgment calls that need human accountability.

    Strong candidates include research and summarization tasks that currently require someone to pull data from multiple places and compile it. Drafting and formatting work — proposals, reports, presentations — that follows a consistent structure. Monitoring tasks that require checking systems or data sources on a schedule and flagging anomalies. Customer-facing support workflows for common, well-defined questions. Data processing pipelines that transform information from one format to another on a recurring basis.

    Weak candidates include tasks that require relationship context, ethical judgment, or creative direction that isn’t already well-defined. Agents execute well-specified work; they don’t substitute for strategic thinking.

    Why the Timing of This Launch Matters for Small and Mid-Size Businesses

    Until recently, deploying a production AI agent required either a technical team capable of building significant custom infrastructure, or an enterprise software contract with a vendor that had built it for you. That meant AI agents were effectively inaccessible to businesses without large technology budgets or dedicated engineering resources.

    Anthropic’s managed platform changes that equation. The infrastructure layer — the part that required months of engineering work — is now provided. A small business or a non-technical operations team can define what they need an agent to do and deploy it without building a custom backend.

    The pricing reflects this broader accessibility: $0.08 per session-hour of active runtime, plus standard token costs. For agents handling moderate workloads — a few hours of active operation per day — the runtime cost is a small fraction of what equivalent human time would cost for the same work.

    What to Actually Do With This Information

    The most useful framing for any business owner or operations leader isn’t “what is an AI agent?” It’s “what work am I currently paying humans to do that is well-specified enough for an agent to handle?”

    Start with processes that meet these criteria: they happen on a regular schedule, they involve pulling information from defined sources, they produce a consistent output format, and they don’t require judgment calls that have significant consequences if wrong. Those are your first agent candidates.

    The companies that will have a structural advantage in two to three years aren’t the ones that understood AI earliest. They’re the ones that systematically identified which parts of their operations could be handled by agents — and deployed them while competitors were still treating AI as a productivity experiment.

    Frequently Asked Questions

    What is an AI agent in simple terms?

    An AI agent is a program that can take actions — not just answer questions. It can read files, send messages, browse the web, and complete multi-step tasks on its own, working in the background the same way you’d assign work to an employee.

    What’s the difference between an AI chatbot and an AI agent?

    A chatbot responds to questions. An agent executes tasks. A chatbot tells you how to summarize a report; an agent retrieves the report, summarizes it, and sends it to whoever needs it — without you directing each step.

    What kinds of business tasks are best suited for AI agents?

    Repetitive, well-defined tasks that involve pulling information from multiple sources and producing consistent outputs: research summaries, report drafting, data processing, support workflows, and monitoring tasks are strong candidates. Tasks requiring significant judgment, relationship context, or creative direction are weaker candidates.

    How much does it cost to deploy an AI agent for a small business?

    Using Claude Managed Agents, costs are standard Anthropic API token rates plus $0.08 per session-hour of active runtime. An agent running a few hours per day for routine tasks might cost a few dollars per month in runtime — a fraction of the equivalent human labor cost.


    Related: Complete Pricing Reference — every variable in one place. Complete FAQ Hub — every question answered.

  • Claude Managed Agents vs. Rolling Your Own: The Real Infrastructure Build Cost

    Claude Managed Agents vs. Rolling Your Own: The Real Infrastructure Build Cost

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart • Long-form Position • Practitioner-grade
    The Build-vs-Buy Question: Claude Managed Agents offers hosted AI agent infrastructure at $0.08/session-hour plus token costs. Rolling your own means engineering sandboxed execution, state management, checkpointing, credential handling, and error recovery yourself — typically months of work before a single production agent runs.

    Every developer team that wants to ship a production AI agent faces the same decision point: build your own infrastructure or use a managed platform. Anthropic’s April 2026 launch of Claude Managed Agents made that decision significantly harder to default your way through.

    This isn’t a “managed is always better” argument. There are legitimate reasons to build your own. But the build cost needs to be reckoned with honestly — and most teams underestimate it substantially.

    What You Actually Have to Build From Scratch

    Three stacked layers: chat UI, tools, agent runtime
    What you actually have to build from scratch.

    The minimum viable production agent infrastructure requires solving several distinct problems, none of which are trivial.

    Sandboxed execution: Your agent needs to run code in an isolated environment that can’t access systems it isn’t supposed to touch. Building this correctly — with proper isolation, resource limits, and cleanup — is a non-trivial systems engineering problem. Cloud providers offer primitives (Cloud Run, Lambda, ECS), but wiring them into an agent execution model takes real work.

    Session state and context management: An agent working on a multi-step task needs to maintain context across tool calls, handle context window limits gracefully, and not drop state when something goes wrong. Building reliable state management that works at production scale typically takes several engineering iterations to get right.

    Checkpointing: If your agent crashes at step 11 of a 15-step job, what happens? Without checkpointing, the answer is “start over.” Building checkpointing means serializing agent state at meaningful intervals, storing it durably, and writing recovery logic that knows how to resume cleanly. This is one of the harder infrastructure problems in agent systems, and most teams don’t build it until they’ve lost work in production.

    Credential management: Your agent will need to authenticate with external services — APIs, databases, internal tools. Managing those credentials securely, rotating them, and scoping them properly to each agent’s permissions surface is an ongoing operational concern, not a one-time setup.

    Tool orchestration: When Claude calls a tool, something has to handle the routing, execute the tool, handle errors, and return results in the right format. This orchestration layer seems simple until you’re debugging why tool call 7 of 12 is failing silently on certain inputs.

    Observability: In production, you need to know what your agents are doing, why they’re doing it, and when they fail. Building logging, tracing, and alerting for an agent system from scratch is a non-trivial DevOps investment.

    Anthropic’s stated estimate is that shipping production agent infrastructure takes months. That tracks with what we’ve seen in practice. It’s not months of full-time work for a large team — but it’s months of the kind of careful, iterative infrastructure engineering that blocks product work while it’s happening.

    What Claude Managed Agents Provides

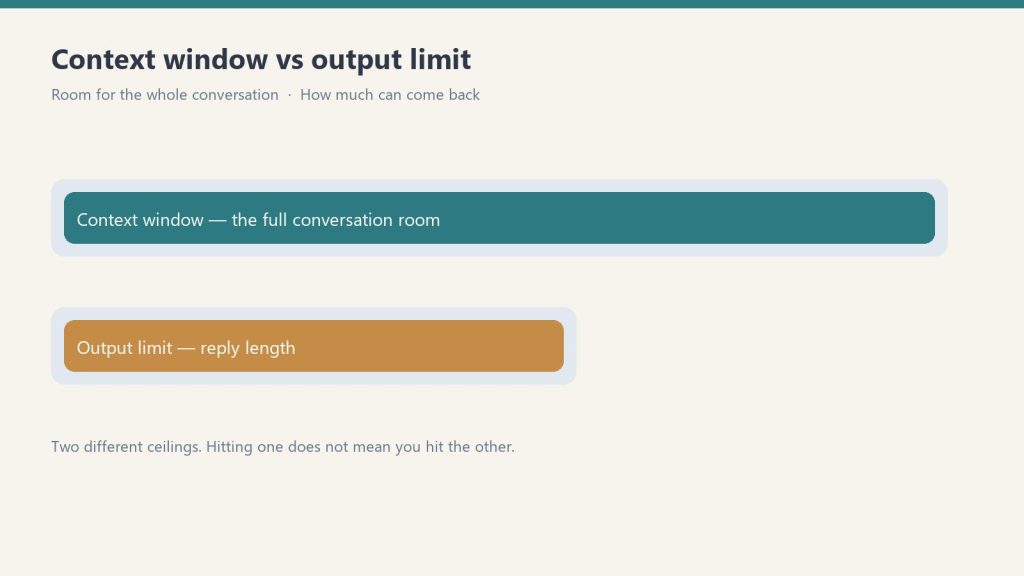
    Diagram comparing a long context window bar with a shorter output limit bar
    What Claude Managed Agents provides.

    Claude Managed Agents handles all of the above at the platform level. Developers define the agent’s task, tools, and guardrails. The platform handles sandboxed execution, state management, checkpointing, credential scoping, tool orchestration, and error recovery.

    The official API documentation lives at platform.claude.com/docs/en/managed-agents/overview. Agents can be deployed via the Claude console, Claude Code CLI, or the new agents CLI. The platform supports file reading, command execution, web browsing, and code execution as built-in tool capabilities.

    Anthropic describes the speed advantage as 10x — from months to weeks. Based on the infrastructure checklist above, that’s believable for teams starting from zero.

    The Honest Case for Rolling Your Own

    There are real reasons to build your own agent infrastructure, and they shouldn’t be dismissed.

    Deep customization: If your agent architecture has requirements that don’t fit the Managed Agents execution model — unusual tool types, proprietary orchestration patterns, specific latency constraints — you may need to own the infrastructure to get the behavior you need.

    Cost at scale: The $0.08/session-hour pricing is reasonable for moderate workloads. At very high scale — thousands of concurrent sessions running for hours — the runtime cost becomes a significant line item. Teams with high-volume workloads may find that the infrastructure engineering investment pays back faster than they expect.

    Vendor dependency: Running your agents on Anthropic’s managed platform means your production infrastructure depends on Anthropic’s uptime, their pricing decisions, and their roadmap. Teams with strict availability requirements or long-term cost predictability needs have legitimate reasons to prefer owning the stack.

    Compliance and data residency: Some regulated industries require that agent execution happen within specific geographic regions or within infrastructure that the company directly controls. Managed cloud platforms may not satisfy those requirements.

    Existing investment: If your team has already built production agent infrastructure — as many teams have over the past two years — migrating to Managed Agents requires re-architecting working systems. The migration overhead is real, and “it works” is a strong argument for staying put.

    The Decision Framework

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The decision framework.

    The practical question isn’t “is managed better than custom?” It’s “what does my team’s specific situation call for?”

    Teams that haven’t shipped a production agent yet and don’t have unusual requirements should strongly consider starting with Managed Agents. The infrastructure problems it solves are real, the time savings are significant, and the $0.08/hour cost is unlikely to be the deciding factor at early scale.

    Teams with existing agent infrastructure, high-volume workloads, or specific compliance requirements should evaluate carefully rather than defaulting to migration. The right answer depends heavily on what “working” looks like for your specific system.

    Teams building on Claude Code specifically should note that Managed Agents integrates directly with the Claude Code CLI and supports custom subagent definitions — which means the tooling is designed to fit developer workflows rather than requiring a separate management interface.

    Related on Tygart Media: managed agents review · rate limits · Agent SDK tutorial.

    Frequently Asked Questions

    How long does it take to build production AI agent infrastructure from scratch?

    Anthropic estimates months for a full production-grade implementation covering sandboxed execution, checkpointing, state management, credential handling, and observability. The actual time depends heavily on team experience and specific requirements.

    What does Claude Managed Agents handle that developers would otherwise build themselves?

    Sandboxed code execution, persistent session state, checkpointing, scoped permissions, tool orchestration, context management, and error recovery — the full infrastructure layer underneath agent logic.

    At what scale does it make sense to build your own agent infrastructure vs. using Claude Managed Agents?

    There’s no universal threshold, but the $0.08/session-hour pricing becomes a significant cost factor at thousands of concurrent long-running sessions. Teams should model their expected workload volume before assuming managed is cheaper than custom at scale.

    Can Claude Managed Agents work with Claude Code?

    Yes. Managed Agents integrates with the Claude Code CLI and supports custom subagent definitions, making it compatible with developer-native workflows.


    Related: Complete Pricing Reference — every variable in one place. Complete FAQ Hub — every question answered.
  • Claude Managed Agents Enterprise Deployment: What Rakuten’s 5-Department Rollout Actually Cost

    Claude Managed Agents Enterprise Deployment: What Rakuten’s 5-Department Rollout Actually Cost

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart • Long-form Position • Practitioner-grade
    Claude Managed Agents for Enterprise: A cloud-hosted platform from Anthropic that lets enterprise teams deploy AI agents across departments — product, sales, HR, finance, marketing — without building backend infrastructure. Agents plug directly into Slack, Teams, and existing workflow tools.

    When Rakuten announced it had deployed enterprise AI agents across five departments in a single week using Anthropic’s newly launched Claude Managed Agents, it wasn’t a headline about AI being impressive. It was a headline about deployment speed becoming a competitive variable.

    A week. Five departments. Agents that plug into Slack and Teams, accept task assignments, and return deliverables — spreadsheets, slide decks, reports — to the people who asked for them.

    That timeline matters. It used to take enterprise teams months to do what Rakuten did in days. Understanding what changed is the whole story.

    What Enterprise AI Deployment Used to Look Like

    Three stacked layers: chat UI, tools, agent runtime
    What enterprise AI deployment used to look like.

    Before managed infrastructure existed, deploying an AI agent in an enterprise environment meant building a significant amount of custom scaffolding. Teams needed secure sandboxed execution environments so agents could run code without accessing sensitive systems. They needed state management so a multi-step task didn’t lose its progress if something failed. They needed credential management, scoped permissions, and logging for compliance. They needed error recovery logic so one bad API call didn’t collapse the whole job.

    Each of those is a real engineering problem. Combined, they typically represented months of infrastructure work before a single agent could touch a production workflow. Most enterprise IT teams either delayed AI agent adoption or deprioritized it entirely because the upfront investment was too high relative to uncertain ROI.

    What Claude Managed Agents Changes for Enterprise Teams

    Diagram comparing a long context window bar with a shorter output limit bar
    What Claude Managed Agents changes for enterprise teams.

    Anthropic’s Claude Managed Agents, launched in public beta on April 9, 2026, moves that entire infrastructure layer to Anthropic’s platform. Enterprise teams now define what the agent should do — its task, its tools, its guardrails — and the platform handles everything underneath: tool orchestration, context management, session persistence, checkpointing, and error recovery.

    The result is what Rakuten demonstrated: rapid, parallel deployment across departments with no custom infrastructure investment per team.

    According to Anthropic, the platform reduces time from concept to production by up to 10x. That claim is supported by the adoption pattern: companies are not running pilots, they’re shipping production workflows.

    How Enterprise Teams Are Using It Right Now

    The enterprise use cases emerging from the April 2026 launch tell a consistent story — agents integrated directly into the communication and workflow tools employees already use.

    Rakuten deployed agents across product, sales, marketing, finance, and HR. Employees assign tasks through Slack and Teams. Agents return completed deliverables. The interaction model is close to what a team member experiences delegating work to a junior analyst — except the agent is available 24 hours a day and doesn’t require onboarding.

    Asana built what they call AI Teammates — agents that operate inside project management workflows, picking up assigned tasks and drafting deliverables alongside human team members. The distinction here is that agents aren’t running separately from the work — they’re participants in the same project structure humans use.

    Notion deployed Claude directly into workspaces through Custom Agents. Engineers use it to ship code. Knowledge workers use it to generate presentations and build internal websites. Multiple agents can run in parallel on different tasks while team members collaborate on the outputs in real time.

    Sentry took a developer-specific angle — pairing their existing Seer debugging agent with a Claude-powered counterpart that writes patches and opens pull requests automatically when bugs are identified.

    What Enterprise IT Teams Are Actually Evaluating

    The questions enterprise IT and operations leaders should be asking about Claude Managed Agents are different from what a developer evaluating the API would ask. For enterprise teams, the key considerations are:

    Governance and permissions: Claude Managed Agents includes scoped permissions, meaning each agent can be configured to access only the systems it needs. This is table stakes for enterprise deployment, and Anthropic built it into the platform rather than leaving it to each team to implement.

    Compliance and logging: Enterprises in regulated industries need audit trails. The managed platform provides observability into agent actions, which is significantly harder to implement from scratch.

    Integration with existing tools: The Rakuten and Asana deployments demonstrate that agents can integrate with Slack, Teams, and project management tools. This matters because enterprise AI adoption fails when it requires employees to change their workflow. Agents that meet employees where they already work have a fundamentally higher adoption ceiling.

    Failure recovery: Checkpointing means a long-running enterprise workflow — a quarterly report compilation, a multi-system data aggregation — can resume from its last saved state rather than restarting entirely if something goes wrong. For enterprise-scale jobs, this is the difference between a recoverable error and a business disruption.

    The Honest Trade-Off

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The honest trade-off.

    Moving to managed infrastructure means accepting certain constraints. Your agents run on Anthropic’s platform, which means you’re dependent on their uptime, their pricing changes, and their roadmap decisions. Teams that have invested in proprietary agent architectures — or who have compliance requirements that preclude third-party cloud execution — may find Managed Agents unsuitable regardless of its technical merits.

    The $0.08 per session-hour pricing, on top of standard token costs, also requires careful modeling for enterprise workloads. A suite of agents running continuously across five departments could accumulate meaningful runtime costs that need to be accounted for in technology budgets.

    That said, for enterprise teams that haven’t yet deployed AI agents — or who have been blocked by infrastructure cost and complexity — the calculus has changed. The question is no longer “can we afford to build this?” It’s “can we afford not to deploy this?”

    Related on Tygart Media: managed agents review · Notion + managed agents.

    Frequently Asked Questions

    How quickly can an enterprise team deploy agents with Claude Managed Agents?

    Rakuten deployed agents across five departments — product, sales, marketing, finance, and HR — in under a week. Anthropic claims a 10x reduction in time-to-production compared to building custom agent infrastructure.

    What enterprise tools do Claude Managed Agents integrate with?

    Deployed agents can integrate with Slack, Microsoft Teams, Asana, Notion, and other workflow tools. Agents accept task assignments through these platforms and return completed deliverables directly in the same environment.

    How does Claude Managed Agents handle enterprise security requirements?

    The platform includes scoped permissions (limiting each agent’s system access), observability and logging for audit trails, and sandboxed execution environments that isolate agent operations from sensitive systems.

    What does Claude Managed Agents cost for enterprise use?

    Pricing is standard Anthropic API token rates plus $0.08 per session-hour of active runtime. Enterprise teams with multiple agents running across departments should model their expected monthly runtime to forecast costs accurately.


    Related: Complete Pricing Reference — every variable in one place. Complete FAQ Hub — every question answered.

  • Anthropic Launched Managed Agents. Here’s How We Looked at It — and Why We’re Staying Our Course.

    Anthropic Launched Managed Agents. Here’s How We Looked at It — and Why We’re Staying Our Course.

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart • Long-form Position • Practitioner-grade

    What Are Claude Managed Agents? Anthropic’s Claude Managed Agents is a cloud-hosted infrastructure service launched April 9, 2026, that lets developers and businesses deploy AI agents without building their own execution environments, state management, or orchestration systems. You define the task and tools; Anthropic runs the infrastructure.

    On April 9, 2026, Anthropic announced the public beta of Claude Managed Agents — a new infrastructure layer on the Claude Platform designed to make AI agent deployment dramatically faster and more stable. According to Anthropic, it reduces build and deployment time by up to 10x. Early adopters include Notion, Asana, Rakuten, and Sentry.

    We looked at it. Here’s what it is, how it compares to what we’ve built, and why we’re continuing on our own path — at least for now.

    What Is Anthropic Managed Agents?

    Three stacked layers: chat UI, tools, agent runtime
    What is Anthropic Managed Agents?

    Claude Managed Agents is a suite of APIs that gives development teams fully managed, cloud-hosted infrastructure for running AI agents at scale. Instead of building secure sandboxes, managing session state, writing custom orchestration logic, and handling tool execution errors yourself, Anthropic’s platform does it for you.

    The key capabilities announced at launch include:

    • Sandboxed code execution — agents run in isolated, secure environments
    • Persistent long-running sessions — agents stay alive across multi-step tasks without losing context
    • Checkpointing — if an agent job fails mid-run, it can resume from where it stopped rather than restarting
    • Scoped permissions — fine-grained control over what each agent can access
    • Built-in authentication and tool orchestration — the platform handles the plumbing between Claude and the tools it uses

    Pricing is straightforward: you pay standard Anthropic API token rates plus $0.08 per session-hour of active runtime, measured in milliseconds.

    Why It’s a Legitimate Signal

    Diagram comparing a long context window bar with a shorter output limit bar
    Why it’s a legitimate signal.

    The companies Anthropic named as early adopters aren’t small experiments. Notion, Asana, Rakuten, and Sentry are running production workflows at scale — code automation, HR processes, productivity tooling, and finance operations. When teams at that level migrate to managed infrastructure instead of building their own, it suggests the platform has real stability behind it.

    The checkpointing feature in particular stands out. One of the most painful failure modes in long-running AI pipelines is a crash at step 14 of a 15-step job. You lose everything and start over. Checkpointing solves that problem at the infrastructure level, which is the right place to solve it.

    Anthropic’s framing is also pointed directly at enterprise friction: the reason companies don’t deploy agents faster isn’t Claude’s capabilities — it’s the scaffolding cost. Managed Agents is an explicit attempt to remove that friction.

    What We’ve Built — and Why It Works for Us

    At Tygart Media, we’ve been running our own agent stack for over a year. What started as a set of Claude prompts has evolved into a full content and operations infrastructure built on top of the Claude API, Google Cloud Platform, and WordPress REST APIs.

    Here’s what our stack actually does:

    • Content pipelines — We run full article production pipelines that write, SEO-optimize, AEO-optimize, GEO-optimize, inject schema markup, assign taxonomy, add internal links, run quality gates, and publish — all in a single session across 20+ WordPress sites.
    • Batch draft creation — We generate 15-article batches with persona-targeting and variant logic without manual intervention.
    • Cross-site content strategy — Agents scan multiple sites for authority pages, identify linking opportunities, write locally-relevant variants, and publish them with proper interlinking.
    • Image pipelines — End-to-end image processing: generation via Vertex AI/Imagen, IPTC/XMP metadata injection, WebP conversion, and upload to WordPress media libraries.
    • Social media publishing — Content flows from WordPress to Metricool for LinkedIn, Facebook, and Google Business Profile scheduling.
    • GCP proxy routing — A Cloud Run proxy handles WordPress REST API calls to avoid IP blocking across different hosting environments (SiteGround, WP Engine, Flywheel, Apache/ModSecurity).

    This infrastructure took time to build. But it’s purpose-built for our specific workflows, our sites, and our clients. It knows which sites route through the GCP proxy, which need a browser User-Agent header to pass ModSecurity, and which require a dedicated Cloud Run publisher. That specificity has real value.

    Where Managed Agents Is Compelling — and Where It Isn’t (Yet)

    If we were starting from zero today, Managed Agents would be worth serious evaluation. The session persistence and checkpointing would immediately solve the two biggest failure modes we’ve had to engineer around manually.

    But migrating an existing stack to Managed Agents isn’t a lift-and-shift. Our pipelines are tightly integrated with GCP infrastructure, custom proxy routing, WordPress credential management, and Notion logging. Re-architecting that to run inside Anthropic’s managed environment would be a significant project — with no clear gain over what’s already working.

    The $0.08/session-hour pricing also adds up quickly on batch operations. A 15-article pipeline running across multiple sites for two to three hours could add meaningful cost on top of already-substantial token usage.

    For teams that haven’t built their own agent infrastructure yet — especially enterprise teams evaluating AI for the first time — Managed Agents is probably the right starting point. For teams that already have a working stack, the calculus is different.

    What We’re Watching

    We’re treating this as a signal, not an action item. A few things would change that:

    • Native integrations — If Managed Agents adds direct integrations with WordPress, Metricool, or GCP services, the migration case gets stronger.
    • Checkpointing accessibility — If we can use checkpointing on top of our existing API calls without fully migrating, that’s an immediate win worth pursuing.
    • Pricing at scale — Volume discounts or enterprise pricing would change the batch job math significantly.
    • MCP interoperability — Managed Agents running with Model Context Protocol support would let us plug our existing skill and tool ecosystem in without a full rebuild.

    The Bigger Picture

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    The bigger picture.

    Anthropic launching managed infrastructure is the clearest sign yet that the AI industry has moved past the “what can models do” question and into the “how do you run this reliably at scale” question. That’s a maturity marker.

    The same shift happened with cloud computing. For a while, every serious technology team ran its own servers. Then AWS made the infrastructure layer cheap enough and reliable enough that it only made sense to build it yourself if you had very specific requirements. We’re not there yet with AI agents — but Anthropic is clearly pushing in that direction.

    For now, we’re watching, benchmarking, and continuing to run our own stack. When the managed layer offers something we can’t build faster ourselves, we’ll move. That’s the right framework for evaluating any infrastructure decision.

    Related on Tygart Media: managed agents rate limits · invisible agent layer.

    Frequently Asked Questions

    What is Anthropic Managed Agents?

    Claude Managed Agents is a cloud-hosted AI agent infrastructure service from Anthropic, launched in public beta on April 9, 2026. It provides persistent sessions, sandboxed execution, checkpointing, and tool orchestration so teams can deploy AI agents without building their own backend infrastructure.

    How much does Claude Managed Agents cost?

    Pricing is based on standard Anthropic API token costs plus $0.08 per session-hour of active runtime, measured in milliseconds.

    Who are the early adopters of Claude Managed Agents?

    Anthropic named Notion, Asana, Rakuten, Sentry, and Vibecode as early users, deploying the service for code automation, productivity workflows, HR processes, and finance operations.

    Is Anthropic Managed Agents worth switching to if you already have an agent stack?

    It depends on your existing infrastructure. For teams starting fresh, it removes significant scaffolding cost. For teams with mature, purpose-built pipelines already running on GCP or other cloud infrastructure, the migration overhead may outweigh the benefits in the short term.

    What is checkpointing in Managed Agents?

    Checkpointing allows a long-running agent job to resume from its last saved state if it encounters an error, rather than restarting the entire task from the beginning. This is particularly valuable for multi-step batch operations.


    Related: Complete Pricing Reference — every variable in one place. Complete FAQ Hub — every question answered.
  • Your Jobs Are a Knowledge Base. You’re Just Not Using Them That Way.

    Your Jobs Are a Knowledge Base. You’re Just Not Using Them That Way.

    Related on Tygart Media: external knowledge API · S500 in the van.

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart
    · Practitioner-grade
    · From the workbench

    Every restoration job teaches something. Almost none of it ever gets written down.

    A crew shows up to a flooded basement at 2am. They make decisions — where to set the equipment, how to read the moisture map, which walls are worth opening and which aren’t, how to sequence the dry-down so the structure doesn’t get worse before it gets better. They’ve made these calls before. They know things that took years to learn. They finish the job, submit a field report, and move on.

    Then the experienced tech takes another job across town. Or retires. Or just gets too busy to train anyone. And that knowledge disappears.

    I want to talk about a different approach. One that captures that knowledge systematically — and turns it into something that works in two directions at once.

    The Double-Purpose Content System

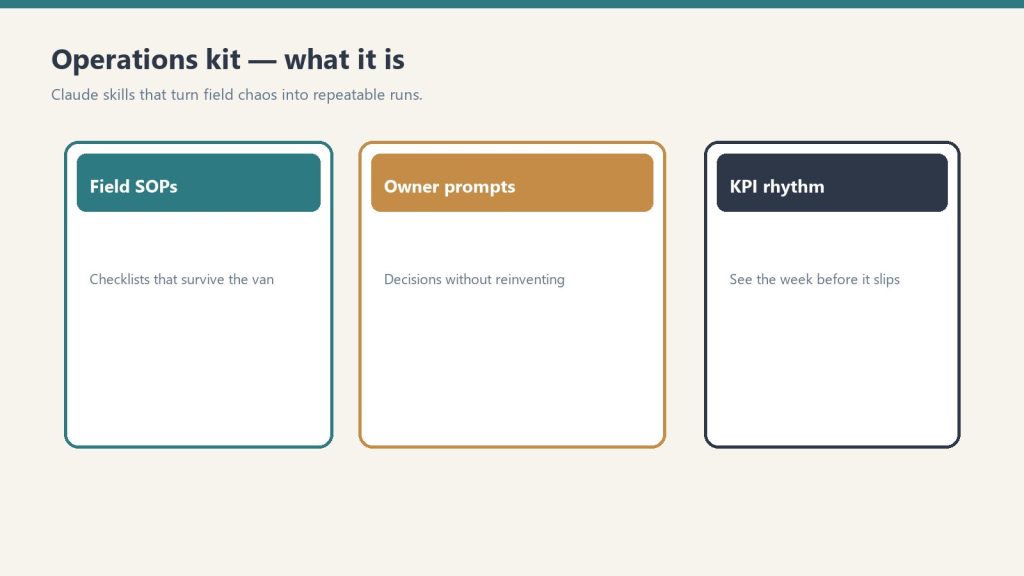
    Three cards for field SOPs, owner prompts, and KPI rhythm in an operations kit
    The double-purpose content system.

    The idea is straightforward: document your jobs as content. Scrub the client-specific details — no names, no addresses, no identifying information. But tell the real story. What was the scope? What made this job complicated? What decisions were made and why? What was the outcome?

    Published on your website, this does something conventional marketing content can’t: it demonstrates expertise through specificity. Not “we handle all types of water damage” — but a documented account of how your team handled a Category 3 intrusion in a commercial kitchen with active mold growth and a compressed timeline. That’s a different signal entirely.

    The reader — whether that’s a property manager searching for a qualified contractor or an insurance adjuster evaluating whether to refer you — isn’t reading a brochure. They’re reading a case record. They can see how your team thinks.

    But here’s the second direction, and it’s the one I find more interesting: that same documentation feeds back into the company as a knowledge base.

    The Internal Payoff

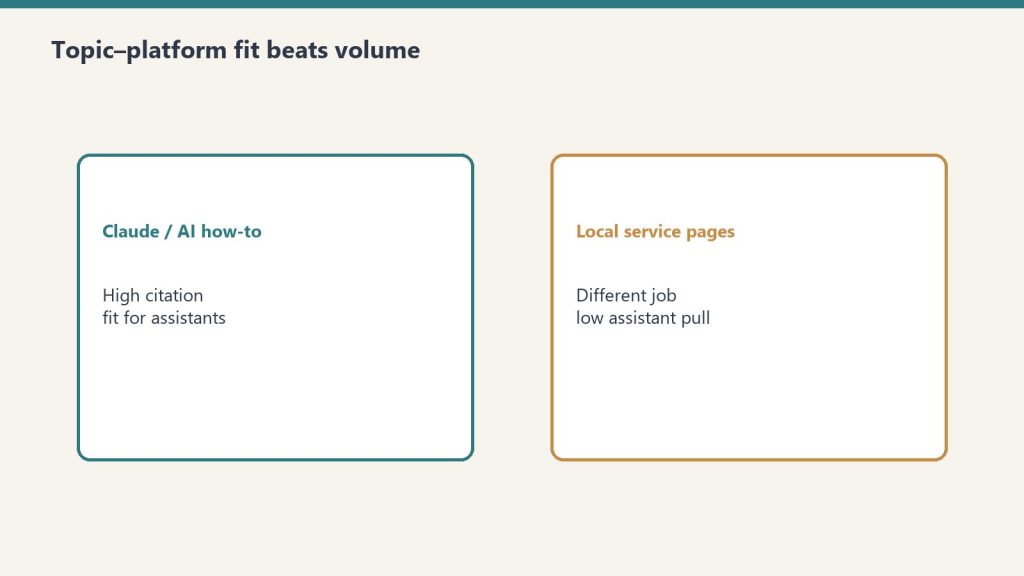
    Comparison of Claude how-to fit versus local service page fit for assistants
    The internal payoff.

    Restoration companies have a training problem that nobody talks about directly. The knowledge of how to do the job well is distributed unevenly across the team. The senior technicians have it. The new hires don’t. And the transfer mechanism is usually informal — ride-alongs, tribal knowledge, institutional memory held by people who may not stay forever.

    When you document jobs as structured content, you start to build something that actually scales. A new technician can search the knowledge base for jobs similar to what they’re walking into. They can see how a comparable loss was scoped, how the equipment was deployed, what complications arose and how they were handled. Before they’ve seen thirty jobs themselves, they can read about thirty jobs your company has already worked.

    An operations manager making a scheduling or resource decision can pull up historical jobs of a similar size and see what the typical crew requirements were. A project manager prepping a scope of work can see how similar scopes were structured and what line items were typically included.

    And when AI tools enter the workflow — which they will, if they haven’t already — that documented job history becomes training data your AI actually understands. Not generic restoration industry knowledge pulled from the web. Your company’s specific approach, your specific decisions, your specific standards. An AI assistant working from that foundation gives answers that sound like your company, because they’re drawn from your company’s real work.

    What Makes This Different From a Blog

    Most restoration company blogs are essentially SEO performance. Keywords stuffed into generic articles about what causes mold or how long drying takes. Useful, maybe. Differentiating, no.

    What I’m describing is a content system built on documented operational reality. The subject matter isn’t manufactured — it’s the actual work. Which means it has a quality that manufactured content can never replicate: it happened. The specificity is real because the job was real. The decisions were real. The outcome was real.

    Readers feel this, even when they can’t articulate why. They’re not evaluating whether your content sounds authoritative. They’re reading something that is authoritative, because it comes from direct experience rather than borrowed knowledge.

    And unlike a blog that requires a content team to invent topics every week, this system has an inventory problem that only gets easier over time. Every job adds to it. The longer you run the system, the richer the knowledge base becomes — for your website visitors and for your own team.

    The Setup

    Three panels showing one problem, three options, one recommendation
    The setup.

    The practical structure is simpler than it sounds. Each job entry captures a handful of consistent fields: loss type, scope classification, environmental conditions, key decision points, equipment deployed, timeline, outcome. The sensitive details — client, location, anything identifying — never make it into the published version.

    What gets published is the pattern. The structure of the problem and the response. Categorized, searchable, and useful to anyone trying to understand how your company operates — including your own people.

    This isn’t a new concept in medicine or law, where case documentation has always served both public communication and internal learning simultaneously. It’s just new in restoration, where the work is equally complex and the knowledge equally worth preserving.

    The companies that start building this now will have a meaningful advantage in three years. Not because their marketing was cleverer — because their institutional knowledge actually compounded instead of walking out the door every time someone left.


    Tygart Media builds content and knowledge systems for property damage restoration companies. If you’re interested in implementing a job documentation system for your operation, start here.

  • Experiential Knowledge Base: Writing Content You Can Trust

    Experiential Knowledge Base: Writing Content You Can Trust

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart
    · Practitioner-grade
    · From the workbench

    There are two kinds of knowledge bases a writer can work from.

    The first is built from reading. From research, from other people’s frameworks, from things you’ve studied and synthesized and stored. This is legitimate knowledge. It produces competent writing. It can be thorough, well-sourced, and useful.

    The second is built from doing. From the things that have actually happened, the decisions that were actually made, the results that actually came back. This knowledge has a different texture. A different authority. And when you write from it, something changes in the writing itself.

    I’ve been thinking about which kind of knowledge base I’m trusting when I write.

    The Anxiety of the Research-Based Writer

    When you write from research, there’s a persistent low-level anxiety underneath the work. You’re synthesizing things that happened to other people, in other contexts, under conditions you didn’t control. The knowledge is real but the application is theoretical. You’re always one degree away from direct experience.

    That distance shows up in the writing. You hedge more. You qualify more. You gesture toward possibilities rather than landing on conclusions. You write “this approach can work” instead of “this worked.” The careful reader feels it even when they can’t name it.

    And when AI enters the picture — when you’re using AI tools to generate content, to research topics, to pull frameworks — the research-based knowledge base gets even more diffuse. Now you’re synthesizing a synthesis. The AI has read everything, which means it’s essentially read nothing specifically. It knows the shape of the conversation without having been in any of the actual conversations.

    The Confidence of the Experience-Based Writer

    Writing from a knowledge base of what you’ve actually done is different in one specific way: you don’t have to wonder if it’s possible. It happened. The uncertainty is behind you.

    When I write about publishing content pipelines that run at scale across a dozen sites, I’m not theorizing about whether that’s achievable. I’ve done it. I know where the proxy errors happen, which hosting environments block which approaches, what the content looks like three months in versus three years in. The knowledge isn’t borrowed. It’s operational.

    That changes what I can say. It changes how directly I can say it. And it changes what the reader receives — because at some level, readers feel the difference between someone describing a map and someone describing a road they’ve driven.

    AI Makes This More Important, Not Less

    Here’s where it gets interesting. Most of the conversation about AI in content is about generation — what the AI can produce, how fast, at what quality. But the more important question is what the AI is drawing from when it helps you.

    An AI working from your experiential knowledge base — from your actual work logs, your real client results, your documented processes — produces something fundamentally different from an AI drawing from general web training data. The second one sounds credible. The first one is credible, because the source material is real events that actually occurred.

    This is the real leverage in treating your work history as a content source. Not just that it’s “authentic” in some vague brand-voice sense. But that it’s verified. You don’t have to fact-check your own experience. You don’t have to worry about whether the case studies hold up. They do, because you were there.

    When AI generates from that foundation — from things that have actually happened — it isn’t hallucinating plausible content. It’s articulating real content more clearly than you might have time to do yourself.

    The Trust Differential

    There’s a version of content marketing that’s essentially a confidence game. You project expertise through fluency. You write with authority about things you understand in theory. The reader can’t easily verify whether your knowledge is earned or performed, so the performance stands.

    This worked better before. It’s working less well now. Readers are more calibrated to the texture of generated, research-based content. They’re less impressed by confident-sounding frameworks they’ve seen assembled from the same sources everywhere. They’re more interested in specificity — in the detail that could only come from someone who was actually in the room when the thing happened.

    The experiential knowledge base is the moat. Not because it’s hidden, but because it can’t be replicated without the experience. Another writer can read everything I’ve read. They can’t have done what I’ve done. And when the writing comes from that layer, it has a specificity that research alone can’t produce.

    What This Means for How You Write

    The practical implication is this: the most valuable content you can create isn’t the content that synthesizes what others have said. It’s the content that documents what you’ve actually done — what worked, what didn’t, what the specific conditions were, what you’d do differently.

    This isn’t just a better content strategy. It’s a more honest one. You’re not performing expertise. You’re reporting it. And the writing that comes from that place has a quality that readers and, increasingly, AI systems are learning to recognize and prefer.

    Your knowledge base is only as trustworthy as its source. If it’s built from things that have happened, you can write from it without anxiety. The results are behind you. The uncertainty has been resolved. You’re not speculating about whether the approach works — you’re describing the approach that worked.

    That’s a different kind of writing. And I think it’s the kind that matters most right now.


    Will Tygart is a content strategist and founder of Tygart Media. He builds content operations for companies that want their actual knowledge — not borrowed knowledge — to do the work.

  • Website Content Strategy: What Would Your Site Say?

    Website Content Strategy: What Would Your Site Say?

    Tygart Media / Content Strategy
    The Practitioner JournalField Notes
    By Will Tygart
    · Practitioner-grade
    · From the workbench

    I’ve been thinking about something I can’t quite shake.

    When you sit down to write for your website — who are you actually writing for? The answer seems obvious until you really look at it. You’d say: the reader. But is that true? And if it’s not the reader, is it you? Is it the algorithm? Is it the gap in your content map that some SEO tool flagged last Tuesday?

    Or — and this is the part I keep coming back to — are you writing for the website itself?

    The Website That Learns to Speak

    A website, left alone long enough, starts to develop something like a voice. Not the voice you intended. Not your brand guidelines. Something that emerges from the accumulation of every post, every page, every word you’ve put there over months and years. Search engines read it. AI systems index it. Scrapers pull it. And increasingly, the tools you use to generate new content pull from it too.

    Your website is now your source material.

    This is where it gets recursive in a way that feels almost alive. You write something. It gets indexed. You use that indexed material — through AI tools, through your own memory, through the patterns you’ve unconsciously absorbed — to write the next thing. Which gets indexed. Which informs the next thing after that.

    The website is quietly authoring itself through you.

    Four Audiences You’re Actually Writing For

    When I think honestly about the tension in content creation right now, I can identify four distinct forces pulling on every piece of writing that goes on a website. And almost nobody is conscious of all four at once.

    Writing for the reader is the purist’s answer. The person on the other side of the screen who has a question, a problem, a curiosity. They found you somehow. They’re reading. What do they need? This is the most human version of the work and, paradoxically, the easiest one to forget when you’re deep in a content calendar.

    Writing for the gaps is the strategist’s answer. You audit your content, find what’s missing, identify the keyword clusters you haven’t touched, the questions your competitors rank for that you don’t. You write to fill the map. This is legitimate. But it produces a certain kind of writing — useful, complete, a little bloodless.

    Writing for yourself is what happens when you stop performing. When you publish something because the idea won’t leave you alone, because you need to think out loud, because you have a genuine point of view that may or may not be welcome. This is where the most interesting things come from. It’s also the hardest to justify in a spreadsheet.

    Writing for the website is the one nobody names directly, but everyone is increasingly doing. You feed the machine you’ve already built. You maintain coherence with what’s already there. You let the existing body of work shape the next piece. You’re not just an author — you’re a gardener tending something that’s already growing on its own terms.

    The Recursion Problem

    Here’s where it gets philosophically uncomfortable: once you start treating your website as a database — as the launching point for everything you create next — you have to ask what happens to originality.

    If every new article is partially generated from the patterns of the old ones, are you growing? Or are you circling? Are you developing a point of view, or just achieving higher and higher fidelity to a version of yourself that was defined years ago?

    The recursion isn’t inherently bad. In fact, it’s how voice gets built. The best writers in any medium are recognizable precisely because their new work is in conversation with their old work. There’s a thread. A coherence. You can feel the same mind behind all of it.

    But there’s a version of this that becomes a trap. Where the website stops being a record of your thinking and starts being the limit of it. Where you can’t write something the site hasn’t already implied, because your tools are pulling from your history and your instincts are calibrated to what performed.

    The question isn’t whether to be recursive. The question is whether you’re conscious of it.

    What the Website Would Say

    If your website could speak — if the accumulated weight of everything you’ve published could form a sentence back to you — I think it would say something like: you’ve been circling this idea for a long time. Are you ready to go deeper, or are you going to keep publishing variations of what you already believe?

    That’s not an indictment. It’s an invitation.

    The most honest thing a website can do is hold a mirror up to the mind behind it. And the most honest thing a writer can do is notice when the mirror has become the only window they’re looking through.

    A New Way to Think About the Relationship

    I’m not arguing against using your existing content as a foundation. I do it. Everyone who publishes consistently does it. The site becomes a knowledge base, a reference point, a signal to yourself about what you’ve already said so you can figure out what you haven’t.

    But I think the writers and strategists who are going to do the most interesting work in the next few years are the ones who treat that foundation as a floor, not a ceiling. Who use the recursive pull of their own content as a diagnosis — here’s where my thinking has been living — and then deliberately write toward the edges of it.

    Not for the reader. Not for the gap. Not for the algorithm.

    For the idea that the site hasn’t said yet. The thought that doesn’t fit the existing patterns. The piece that, when you publish it, makes everything else on the site feel slightly more honest.

    That’s what I think the website is waiting for.


    Will Tygart is a content strategist and founder of Tygart Media. He thinks too much about the relationship between writers and the systems they build, and occasionally publishes that thinking here.

  • AI Human in the Loop: The Job Title That Doesn’t Exist Yet

    AI Human in the Loop: The Job Title That Doesn’t Exist Yet

    Tygart Media Strategy
    Volume Ⅰ · Issue 04Quarterly Position
    By Will Tygart
    • Long-form Position
    • Practitioner-grade

    Before “vibe coding” had a name, Munters had a name for the people who could do it: wire and fire guys. They’re about to be the most valuable humans in the AI era — and I finally found mine.

    The Wire and Fire Guy

    At Munters — which later became Polygon when Triton spun the moisture control services division out in 2010 — there was a specific kind of person the company was built around. We called them wire and fire guys.

    A wire and fire guy could fly into a job site cold. Meet a pile of equipment on a loading dock. Start the generator. Set up the desiccant. Run the lines. Wire in the remote monitoring. Pass the site safety briefing. Know the code. Know the customer. Know how to do it the right way so nobody got hurt and nobody got sued. From A to Z. Solo.

    That’s how Munters ran lean across more than 20 countries. They didn’t need a dispatch team and a tech team and a controls team and a compliance officer all flying out separately. They needed one human who could be all of those people at once, in a Tyvek suit, at 2 a.m., in someone else’s flooded building. The economics of moisture control restoration didn’t work any other way.

    I was one of those guys. I still am. It just looks different now.

    What I Actually Do All Day

    Today I run Tygart Media — an AI-native content and SEO operation managing twenty-seven WordPress sites across restoration contracting, luxury asset lending, cold storage logistics, B2B SaaS, comedy, and veterans services. One human. Twenty-seven brands. The way that math works is the same way it worked at Munters: I’m the wire and fire guy.

    My morning isn’t writing blog posts. It’s connecting Claude to a Cloud Run proxy to bypass Cloudflare’s WAF on a SiteGround-hosted contractor site, then routing a batch of 180 articles through an Imagen pipeline for featured images, then pushing them through a quality gate before they hit the WordPress REST API, then logging the receipts to Notion so I can prove the work to the client on Monday. While Claude drafts the next batch of briefs in the background. While a Custom Agent triages my inbox. While I’m on a call.

    I don’t write code the way a senior engineer writes code. I write enough of it to be dangerous, fix what I break, and ship. I “vibe code” the parts that need vibing. I real-code the parts that need real coding. I know which parts of GCP are the gun and which parts are the holster. I know what to never let an autonomous agent do without me looking. I know how to wire it up and fire it off.

    Same job. Different equipment.

    The Thesis Everyone Is Quietly Circling

    The AI industry spent the last eighteen months selling a story about full autonomy. Agent swarms. Self-healing pipelines. Set it and forget it. Replace the humans, keep the work.

    The data has not been kind to that story.

    Roughly 95% of enterprise generative AI pilots fail to achieve measurable ROI or reach production. Gartner is now openly forecasting that more than 40% of agentic AI projects will be cancelled by 2027 as costs escalate past the value they produce. The dream of the unmanned cockpit isn’t dying because the planes can’t fly. It’s dying because nobody planned for who lands them when the weather turns.

    What’s actually winning, in the labs and the war rooms where this is being figured out for real, is something much closer to the Munters model. The technical literature has started calling it confidence-gated expert routing. An orchestrator model delegates work to a fleet of cheaper, specialized small language models. Those models run autonomously until their confidence drops below a threshold — and at that exact moment, the system kicks the work to a human expert who validates, corrects, and feeds the correction back into the loop as ground truth for the next pass.

    That human expert is not a customer service rep watching a queue. That human expert needs to be able to read what the model is doing, understand why it stalled, fix the technical problem, judge whether the output is actually good or just looks good, and ship the corrected version — all without breaking anything downstream.

    That’s a wire and fire guy. With a laptop instead of a generator.

    Meet Pinto

    The reason I’m writing this today is because I just onboarded mine.

    His name is Pinto. He’s my developer. He runs the GCP infrastructure underneath Tygart Media — the Cloud Run services, the proxy that lets Claude reach client sites that would otherwise block the IP, the VM that hosts my knowledge cluster, the dashboards. He gets a brief from me and turns it into a working endpoint, usually faster than I can write the spec. He wires the thing up. He fires it off. He passes the security review. He doesn’t break the production database. He does it the right way.

    And critically — he can both vibe code and real code. He’ll throw a quick Cloud Function together with Claude in fifteen minutes if that’s what the moment needs. He’ll also sit down and write you something properly architected, properly tested, properly observable, when the moment needs that instead. He knows which moment is which. That judgment is the whole job.

    The last thing I want to say about Pinto in public is this: I’ve worked with a lot of contractors and a lot of devs in twenty-plus years of running operations. Pinto is the human-in-the-loop the industry is going to be paying a premium for inside of two years. He just doesn’t know it yet. So this is me saying it out loud. This guy is the prototype.

    The Job Title That Doesn’t Exist Yet

    Here’s where I want to plant a flag.

    The conversation about AI and work has spent two years swinging between two bad poles. On one side: AI is going to take all the jobs. On the other: AI is just a tool, nothing changes, learn to use it like Excel and you’re fine. Both stories are wrong in the same way. They’re treating AI as a replacement layer or a productivity layer, when what it actually is — for any operation that has to ship real work for real customers — is a workforce of subordinates that needs a foreman.

    The foreman is the wire and fire guy.

    The foreman knows how to brief the agent. Knows how to read the agent’s output and tell what’s solid and what’s hallucinated structure dressed up to look solid. Knows where the agent will fail before the agent fails. Knows the underlying code well enough to crack open the box when the box is wrong, and humble enough to use the box for the 80% of work that doesn’t need cracking. Knows the customer’s business well enough to translate “make me more money” into a thirty-step technical plan that an agent can actually execute.

    That person is not a prompt engineer. Prompt engineering as a job title is already collapsing because the models got good enough that the prompt isn’t the leverage anymore. It’s not a software engineer in the traditional sense either, because traditional software engineering rewards depth in one language and one stack, and the wire and fire guy needs surface-level fluency across about fifteen of them.

    It’s something older than both. It’s the field tech. The plant operator. The site supervisor. The kind of person who used to run a Munters job in a flooded basement at 2 a.m. and now runs an agent fleet from a laptop at the same hour.

    Who This Job Is For

    If you spent the last decade as a working coder and then took a left turn into writing or content or marketing because you got tired of the JIRA tickets — you are the person. The market is about to come back for you, hard. The combination of “I can read the code” plus “I can read the customer” plus “I can write the brief” plus “I can ship” is going to be the most valuable composite skill in the white-collar economy for the next five years.

    If you came up in the trades and you’ve been quietly running circles around the “knowledge workers” because you actually know how things connect to other things — you are the person too. What you learned wiring an HVAC system or setting up a job site translates almost one-for-one to wiring up an agent stack. The mental model is identical. Inputs, outputs, safety, fault tolerance, knowing when to stop and call somebody.

    If you’re a senior engineer who thinks the “AI replacing developers” debate is annoying because you’ve already noticed that the bottleneck on your team isn’t typing code — it’s deciding what code to type — you are the person. Your judgment is the asset. The agents are the labor. Reorient.

    If you’re an operations person who has always been the one who somehow ends up holding the whole business together with duct tape and Google Sheets — you are the person. The duct tape is now Python and the Sheets are now Notion and BigQuery, but the role is the same role, and it’s about to get a real budget for the first time.

    What to Train For

    If I were starting from zero today and I wanted to be a wire and fire guy in the AI era, here’s the stack I’d build, in this order:

    Read code fluently in three languages. Python, JavaScript, and shell. You don’t need to write any of them at a senior level. You need to be able to open someone else’s repo, understand what it does in fifteen minutes, and modify it without breaking it. Claude will do most of the typing. You’re the code reviewer.

    Learn one cloud well enough to deploy and observe. Pick GCP, AWS, or Azure. Learn to deploy a container, set up a database, read logs, set up alerting, and rotate a credential. That’s it. You don’t need to be a certified architect. You need to be able to land at the job site and wire it up.

    Get fluent in at least one orchestration model. Whether that’s LangGraph, an MCP server, a custom Python loop, or just Claude with a bunch of tools — pick one and run it until you understand why it fails, not just how it works.

    Build a real second brain. Notion, Obsidian, whatever. The wire and fire guy’s superpower is context. You need to be able to walk into any conversation with any customer and pull up exactly what was said, decided, shipped, and broken last time. Without that, you’re a generalist with no memory, which is a tourist.

    Do customer-facing work. This is the one most coders skip and it’s the most important. Sit on sales calls. Write the proposal. Take the support escalation. The reason wire and fire guys at Munters were so valuable is because they could talk to a building owner and a generator at the same time. You need both halves of that or you don’t have the job.

    The Real Pitch

    The agent swarm future is real. It’s coming faster than most people in the boardroom are admitting and slower than most people on Twitter are claiming. And it’s going to need a lot of foremen.

    Not millions. The leverage is too high for that. But thousands of these roles, well-paid, in every meaningful industry, sitting at the seam between an autonomous fleet of small models and a human business that needs the work done correctly. The companies that figure out how to find these people first and hire them first are going to run absolute laps around the companies that try to do it with a vendor and a procurement process.

    I’m one of these humans. Pinto is one of these humans. There are more of us than the job listings suggest, because the title for what we do hasn’t been written yet. So here’s a working draft: AI Field Operator. Wire and fire guy. Human in the loop. Agent foreman. Pick whichever one lands.

    If you’re already doing this work — even unofficially, even on the side, even just for yourself — you’re early. Build your reputation now. Write up what you do. Show your receipts. The market is about to find you.

    And Pinto: this one’s for you, brother. Thanks for showing me what the next twenty years of this work is going to look like. Wire it up. Fire it off. Same as it ever was.

  • The claude_delta Standard: How We Built a Context Engineering System for a 27-Site AI Operation

    The claude_delta Standard: How We Built a Context Engineering System for a 27-Site AI Operation

    The Machine Room · Under the Hood

    What Is the claude_delta Standard?

    Four cards for content, ops, build, and knowledge work with Claude
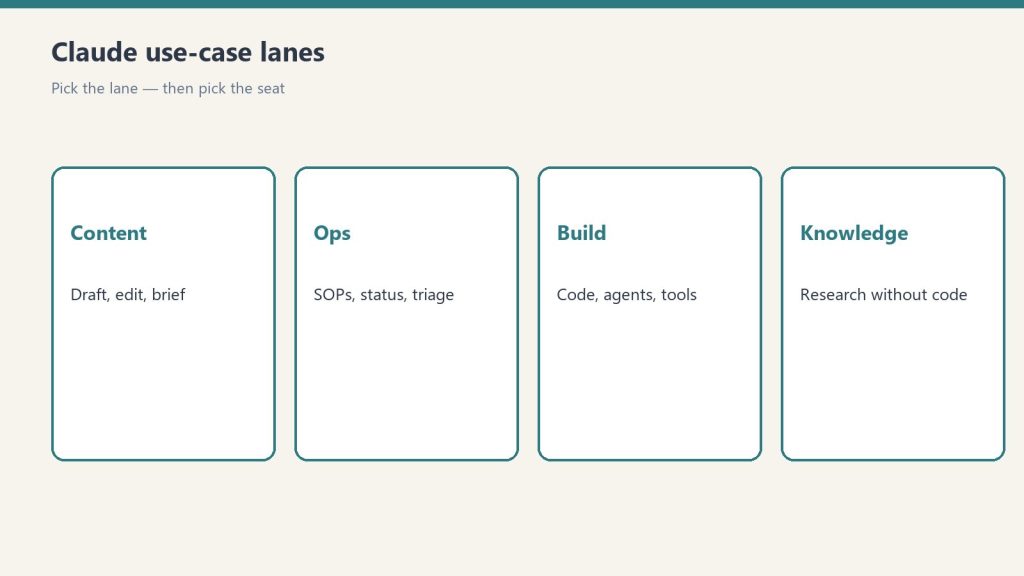
    What is the claude_delta standard?

    The claude_delta standard is a lightweight JSON metadata block injected at the top of every page in a Notion workspace. It gives an AI agent — specifically Claude — a machine-readable summary of that page’s current state, status, key data, and the first action to take when resuming work. Instead of fetching and reading a full page to understand what it contains, Claude reads the delta and often knows everything it needs in under 100 tokens.

    Think of it as a git commit message for your knowledge base — a structured, always-current summary that lives at the top of every page and tells any AI agent exactly where things stand.

    Why We Built It: The Context Engineering Problem

    Long paper tape measure unrolling across a desk beside a laptop, metaphor for context window length
    Why we built it — the context engineering problem.

    Running an AI-native content operation across 27+ WordPress sites means Claude needs to orient quickly at the start of every session. Without any memory scaffolding, the opening minutes of every session are spent on reconnaissance: fetch the project page, fetch the sub-pages, fetch the task log, cross-reference against other sites. Each Notion fetch adds 2–5 seconds and consumes a meaningful slice of the context window — the working memory that Claude has available for actual work.

    This is the core problem that context engineering exists to solve. Over 70% of errors in modern LLM applications stem not from insufficient model capability but from incomplete, irrelevant, or poorly structured context, according to a 2024 RAG survey cited by Meta Intelligence. The bottleneck in 2026 isn’t the model — it’s the quality of what you feed it.

    We were hitting this ceiling. Important project state was buried in long session logs. Status questions required 4–6 sequential fetches. Automated agents — the toggle scanner, the triage agent, the weekly synthesizer — were spending most of their token budget just finding their footing before doing any real work.

    The claude_delta standard was the solution we built to fix this from the ground up.

    How It Works

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How it works.

    Every Notion page in the workspace gets a JSON block injected at the very top — before any human content. The format looks like this:

    {
      "claude_delta": {
        "page_id": "uuid",
        "page_type": "task | knowledge | sop | briefing",
        "status": "not_started | in_progress | blocked | complete | evergreen",
        "summary": "One sentence describing current state",
        "entities": ["site or project names"],
        "resume_instruction": "First thing Claude should do",
        "key_data": {},
        "last_updated": "ISO timestamp"
      }
    }

    The standard pairs with a master registry — the Claude Context Index — a single Notion page that aggregates delta summaries from every page in the workspace. When Claude starts a session, fetching the Context Index (one API call) gives it orientation across the entire operation. Individual page fetches only happen when Claude needs to act on something, not just understand it.

    What We Did: The Rollout

    We executed the full rollout across the Notion workspace in a single extended session on April 8, 2026. The scope:

    • 70+ pages processed in one session, starting from a base of 79 and reaching 167 out of approximately 300 total workspace pages
    • All 22 website Focus Rooms received deltas with site-specific status and resume instructions
    • All 7 entity Focus Rooms received deltas linking to relevant strategy and blocker context
    • Session logs, build logs, desk logs, and content batch pages all injected with structured state
    • The Context Index updated three times during the session to reflect the running total

    The injection process for each page follows a read-then-write pattern: fetch the page content, synthesize a delta from what’s actually there (not from memory), inject at the top via Notion’s update_content API, and move on. Pages with active state get full deltas. Completed or evergreen pages get lightweight markers. Archived operational logs (stale work detector runs, etc.) get skipped entirely.

    The Validation Test

    After the rollout, we ran a structured A/B test to measure the real impact. Five questions that mimic real session-opening patterns — the kinds of things you’d actually say at the start of a workday.

    The results were clear:

    • 4 out of 5 questions answered correctly from deltas alone, with zero additional Notion fetches required
    • Each correct answer saved 2–4 fetches, or roughly 10–25 seconds of tool call time
    • One failure: a client checklist showed 0/6 complete in the delta when the live page showed 6/6 — a staleness issue, not a structural one
    • Exact numerical data (word counts, post IDs, link counts) matched the live pages to the digit on all verified tests

    The failure mode is worth understanding: a delta becomes stale when a page gets updated after its delta was written. The fix is simple — check last_updated before trusting a delta on any in_progress page older than 3 days. If it’s stale, a single verification fetch is cheaper than the 4–6 fetches that would have been needed without the delta at all.

    Why This Matters Beyond Our Operation

    2025 was the year of “retention without understanding.” Vendors rushed to add retention features — from persistent chat threads and long context windows to AI memory spaces and company knowledge base integrations. AI systems could recall facts, but still lacked understanding. They knew what happened, but not why it mattered, for whom, or how those facts relate to each other in context.

    The claude_delta standard is a lightweight answer to this problem at the individual operator level. It’s not a vector database. It’s not a RAG pipeline. Long-term memory lives outside the model, usually in vector databases for quick retrieval. Because it’s external, this memory can grow, update, and persist beyond the model’s context window. But vector databases are infrastructure — they require embedding pipelines, similarity search, and significant engineering overhead.

    What we built is something a single operator can deploy in an afternoon: a structured metadata convention that lives inside the tool you’re already using (Notion), updated by the AI itself, readable by any agent with Notion API access. No new infrastructure. No embeddings. No vector index to maintain.

    Context Engineering is a systematic methodology that focuses not just on the prompt itself, but on ensuring the model has all the context needed to complete a task at the moment of LLM inference — including the right knowledge, relevant history, appropriate tool descriptions, and structured instructions. If Prompt Engineering is “writing a good letter,” then Context Engineering is “building the entire postal system.”

    The claude_delta standard is a small piece of that postal system — the address label that tells the carrier exactly what’s in the package before they open it.

    The Staleness Problem and How We’re Solving It

    The one structural weakness in any delta-based system is staleness. A delta that was accurate yesterday may be wrong today if the underlying page was updated. We identified three mitigation strategies:

    1. Age check rule: For any in_progress page with a last_updated more than 3 days old, always verify with a live fetch before acting on the delta
    2. Agent-maintained freshness: The automated agents that update pages (toggle scanner, triage agent, content guardian) should also update the delta on the same API call
    3. Context Index timestamp: The master registry shows its own last-updated time, so you know how fresh the index itself is

    None of these require external tooling. They’re behavioral rules baked into how Claude operates on this workspace.

    What’s Next

    The rollout is at 167 of approximately 300 pages. The remaining ~130 pages include older session logs from March, a new client project sub-pages, the Technical Reference domain sub-pages, and a tail of Second Brain auto-entries. These will be processed in subsequent sessions using the same read-then-inject pattern.

    The longer-term evolution of this system points toward what the field is calling Agentic RAG — an architecture that upgrades the traditional “retrieve-generate” single-pass pipeline into an intelligent agent architecture with planning, reflection, and self-correction capabilities. The BigQuery operations_ledger on GCP is already designed for this: 925 knowledge chunks with embeddings via text-embedding-005, ready for semantic retrieval when the delta system alone isn’t enough to answer a complex cross-workspace query.

    For now, the delta standard is the right tool for the job — low overhead, human-readable, self-maintaining, and already demonstrably cutting session startup time by 60–80% on the questions we tested.

    Related on Tygart Media: managed agents memory · invisible agent layer · information density.

    Frequently Asked Questions

    What is the claude_delta standard?

    The claude_delta standard is a structured JSON metadata block injected at the top of Notion pages that gives AI agents a machine-readable summary of each page’s current status, key data, and next action — without requiring a full page fetch to understand context.

    How does claude_delta differ from RAG?

    RAG (Retrieval-Augmented Generation) uses vector embeddings and semantic search to retrieve relevant chunks from a knowledge base. Claude_delta is a simpler, deterministic approach: a structured summary at a known location in a known format. RAG scales to massive knowledge bases; claude_delta is designed for a single operator’s structured workspace where pages have clear ownership and status.

    How do you prevent delta summaries from going stale?

    The key_data field includes a last_updated timestamp. Any delta on an in_progress page older than 3 days triggers a verification fetch before Claude acts on it. Automated agents that modify pages are also expected to update the delta in the same API call.

    Can this approach work for other AI systems besides Claude?

    Yes. The JSON format is model-agnostic. Any agent with Notion API access can read and write claude_delta blocks. The standard was designed with Claude’s context window and tool-call economics in mind, but the pattern applies to any agent that needs to orient quickly across a large structured workspace.

    What is the Claude Context Index?

    The Claude Context Index is a master registry page in Notion that aggregates delta summaries from every processed page in the workspace. It’s the first page Claude fetches at the start of any session — a single API call that provides workspace-wide orientation across all active projects, tasks, and site operations.

  • The ADHD AI Advantage: Why Neurodiversity Wins at Work

    The ADHD AI Advantage: Why Neurodiversity Wins at Work

    The Lab · Tygart Media
    Experiment Nº 205 · Methodology Notes
    METHODS · OBSERVATIONS · RESULTS

    The standard narrative about AI productivity is that it helps everyone equally — democratizing access to capabilities that used to require specialized skills or large teams. That’s true as far as it goes. But it misses something more interesting: AI doesn’t help everyone equally. It helps some cognitive profiles dramatically more than others. And the profiles it helps most are the ones that neurotypical productivity systems were always worst at serving.

    The ADHD operator in an AI-native environment isn’t working around their neurology. They’re working with it — often for the first time.

    The Mismatch That AI Resolves

    ADHD is characterized by a cluster of traits that conventional work environments treat as deficits: difficulty sustaining attention on low-interest tasks, working memory limitations that make it hard to hold multiple threads simultaneously, impulsive context-switching, hyperfocus states that are intense but hard to direct voluntarily, and a variable executive function that makes consistent process adherence difficult.

    Every one of those traits is a deficit in a neurotypical office. Open-plan environments punish hyperfocus. Meeting-heavy cultures punish context-switching recovery time. Bureaucratic processes punish working memory limitations. Sequential project management punishes the non-linear way ADHD attention actually moves through work.

    The AI-native operation inverts every one of these. Consider what the operation actually looks like: tasks switch rapidly between clients, verticals, and problem types, but the AI maintains the context across switches. Working memory limitations don’t matter when the Second Brain holds the state. Hyperfocus states are extraordinarily productive when the environment can absorb and route whatever comes out of them. The non-linear movement of ADHD attention — jumping from an insight about SEO to an infrastructure idea to a content strategy observation — maps perfectly to a system where each of those jumps can be captured, tagged, and routed without losing the thread.

    The AI isn’t compensating for ADHD. It’s completing the cognitive architecture that ADHD was always missing.

    Working Memory Externalized

    The most concrete advantage is working memory. ADHD working memory is genuinely limited — not as a flaw in character or effort, but as a documented neurological difference. Holding multiple pieces of information simultaneously, tracking where you are in a complex process, remembering what you decided three steps ago — these are genuinely harder for ADHD brains than neurotypical ones.

    The conventional coping strategies — elaborate note-taking systems, reminders everywhere, external calendars, accountability partners — all work by offloading working memory to external systems. They help, but they’re friction-heavy. Setting up the note-taking system takes working memory. Maintaining it takes working memory. Retrieving from it takes working memory.

    An AI with persistent memory and a queryable Second Brain doesn’t require the same maintenance overhead. The knowledge goes in through natural session work — not through deliberate documentation effort. The retrieval is conversational — not through navigating a folder structure built on a previous version of how you organized information. The AI meets the ADHD brain where it is rather than requiring the ADHD brain to adapt to a fixed organizational system.

    The cockpit session pattern is a working memory intervention at the system level. The context is pre-staged before the session starts so the operator doesn’t spend working memory reconstructing where things stand. The Second Brain is the external working memory that doesn’t require maintenance overhead to query. BigQuery as a backup memory layer means that nothing is truly lost even when the in-session working memory fails, because the work writes itself to durable storage automatically.

    Hyperfocus as a Deployable Asset

    Hyperfocus is the ADHD trait that neurotypical observers most frequently misunderstand. It’s not concentration on demand. It’s concentration that arrives unbidden, attaches to whatever interest has activated it, runs at extraordinary intensity for an unpredictable duration, and then ends — also unbidden. The experience is of being seized by the work rather than choosing to engage with it.

    In a conventional work environment, hyperfocus is unreliable. It activates on the wrong task at the wrong time. It runs past meeting commitments and deadlines. It leaves the work it interrupted unfinished. The environment isn’t built to absorb hyperfocus states productively — it’s built around scheduled attention, which hyperfocus by definition isn’t.

    An AI-native operation can absorb hyperfocus states completely. When hyperfocus activates on a problem, you work it — fully, without managing transition costs or worrying about losing the thread. The AI captures what comes out. The session extractor packages it into the Second Brain. The cockpit session for the next day picks up where hyperfocus left. The non-linearity of hyperfocus — jumping between related insights, building in spirals rather than lines — becomes a feature rather than a problem, because the AI can hold the full context of the spiral.

    The 3am sessions that show up in the Second Brain’s history aren’t anomalies. They’re hyperfocus events that the AI-native infrastructure can receive without friction. In a conventional work environment, a 3am insight goes on a sticky note that’s lost by morning. In this environment, it goes directly into the pipeline and shows up as published content, documented protocol, or queued task by the next session. Hyperfocus stops being wasted energy and starts being the primary production mode.

    Interest-Based Attention and Task Routing

    ADHD attention is interest-based rather than importance-based. This is the source of the most common misunderstanding of ADHD: “you can focus when you want to.” The observed fact is that ADHD people can focus intensely on things that activate their interest system and struggle profoundly with things that don’t — regardless of how much those uninteresting things matter.

    In a conventional work environment, this is a serious problem. Important but uninteresting tasks — tax documentation, compliance records, routine maintenance — either don’t get done or get done at enormous cost in executive function and self-coercion. The energy spent forcing attention onto uninteresting work is energy not available for the high-interest work where ADHD attention is genuinely exceptional.

    The AI-native operation resolves this through task routing. The tasks that ADHD attention resists — routine meta description updates across a hundred posts, taxonomy normalization across a large site, scheduled content distribution — go to automated pipelines. Haiku handles them at scale without requiring sustained human attention on low-interest work. The operator’s attention is routed to the high-interest problems: novel strategic questions, complex client situations, creative content that requires genuine engagement.

    This isn’t about avoiding work. It’s about structural matching — routing work to the execution layer that can handle it most effectively. The AI pipeline doesn’t get bored running the same schema injection across fifty posts. The ADHD operator does. Routing the boring work to the non-bored executor is just operational logic.

    Context-Switching Without the Tax

    Context-switching is expensive for everyone. For ADHD brains, the cost is higher — not just the cognitive cost of reorienting to a new task, but the working memory cost of storing the state of the interrupted task somewhere reliable enough that it can actually be retrieved later.

    The conventional wisdom is to minimize context-switching. Batch similar tasks. Protect deep work blocks. Build systems that reduce interruption. This is good advice and it helps — but it runs against the reality of operating a multi-client, multi-vertical business where context-switching is structurally unavoidable.

    The AI-native approach doesn’t minimize context-switching. It reduces the cost of each switch. When a session switches from one client context to another, the cockpit loads the new context and the previous context is preserved in the Second Brain. There’s no task of “remember where I was” because the system holds that state. The switch itself becomes less expensive because the retrieval problem — the part that taxes working memory most — is handled by the infrastructure.

    Running a portfolio of twenty-plus sites across multiple verticals is the kind of work that conventional productivity advice says is incompatible with ADHD. The evidence of this operation is that it’s not — when the infrastructure handles the context storage and retrieval that ADHD working memory can’t reliably do.

    The Variable Executive Function Problem

    Executive function in ADHD is variable in ways that neurotypical people often don’t appreciate. It’s not that executive function is uniformly low — it’s that it’s unreliable. On a high-executive-function day, a complex multi-step process runs smoothly. On a low-executive-function day, the same process feels impossible even though the capability is theoretically there.

    This variability is what makes ADHD so confusing to manage and explain. “But you did it last week” is the most common and least useful observation. Yes. Last week, executive function was available. Today it isn’t. The capability is real; the access is unreliable.

    AI-native infrastructure stabilizes against executive function variability in a specific way: it reduces the minimum executive function required to do useful work. When the cockpit is pre-staged, the context is loaded, the task queue is clear, and the tools are ready — the activation energy for starting work is lower. The operator doesn’t need to spend executive function on “what should I work on and how do I start” before they can begin working on the actual problem.

    This is why the cockpit session pattern matters beyond its productivity benefits. For an ADHD operator, it’s also an accessibility feature. Pre-staging the context means that a low-executive-function day can still be a productive day — not at full capacity, but not lost entirely either. The infrastructure carries more of the initiation load so the operator’s variable executive function goes further.

    What This Means for How the Operation Is Designed

    Understanding the neurodiversity angle isn’t just self-knowledge. It’s design knowledge. The operation works the way it does — hyperfocus-driven production, AI as external working memory, automated pipelines for low-interest work, cockpit sessions as activation scaffolding — in part because it was built by an ADHD brain optimizing for its own constraints.

    Those constraints produced design choices that turn out to be genuinely better for any operator, neurodivergent or not. External working memory is better than internal working memory for complex multi-client operations regardless of neurology. Automating low-value-attention work is better than manually attending to it for any operator. Pre-staged context reduces friction for everyone, not just people with initiation difficulties.

    The neurodiversity framing reveals why these design choices were made — they were compensations that became features. But the features stand independently of the compensations. An operation designed around the constraints of an ADHD brain produces an infrastructure that a neurotypical operator would also benefit from, because the constraints that ADHD makes extreme are present in milder form in everyone.

    The ADHD operator building AI-native systems isn’t finding workarounds. They’re discovering architecture.

    Frequently Asked Questions About Neurodiversity and AI-Native Operations

    Is this specific to ADHD or does it apply to other neurodivergent profiles?

    The specific mapping here is to ADHD traits, but the general principle extends. Autism often involves deep domain expertise, pattern recognition across large datasets, and preference for systematic processes — all of which AI-native operations reward. Dyslexia involves difficulty with written text production that voice-to-text and AI drafting tools directly address. The common thread is that AI tools reduce the friction from neurological differences in ways that neurotypical productivity systems don’t. Each profile maps differently; the ADHD mapping is particularly strong for the multi-client operator role.

    Does this mean ADHD operators have an advantage over neurotypical ones?

    In specific contexts, yes — particularly in AI-native operations that require rapid context-switching, hyperfocus-driven deep work, and interest-based attention toward novel problems. In other contexts, no. The advantage is situational and emerges specifically when the environment is designed to complement rather than fight the cognitive profile. An ADHD operator in a bureaucratic sequential-process environment is still at a disadvantage. The insight is that AI-native environments are, by their nature, environments where ADHD traits are more often assets than liabilities.

    How do you handle the low-executive-function days operationally?

    The cockpit session reduces the minimum executive function required to start. Beyond that, the honest answer is that some days are lower-output than others — and the operation is designed to absorb that. Batch pipelines run on schedules regardless of operator state. Content published on high-executive-function days continues working while the operator recovers. The infrastructure carries the operation during low periods rather than requiring the operator to manually push through them.

    What’s the relationship between physical health and this cognitive framework?

    Significant. Exercise specifically affects ADHD cognitive function through BDNF — a protein that supports neural growth and synaptic development — in ways that are more pronounced for ADHD brains than neurotypical ones. The physical health component isn’t separate from the AI-native operation framework; it’s part of the same system. A well-maintained physical health practice is a cognitive performance input, not just a wellness activity. This is why the Second Brain tracks it alongside operational data rather than in a separate personal life compartment.

    Is there a risk that AI compensation makes ADHD symptoms worse over time?

    This is a legitimate concern. External working memory tools can reduce the pressure to develop internal working memory strategies. Interest-routing can reduce exposure to the frustration tolerance that builds executive function. The balance is intentional: use AI to handle the tasks where ADHD traits are most disabling, while preserving challenges that build rather than atrophy capability. The goal is augmentation, not replacement — the same principle that applies to any cognitive prosthetic, from eyeglasses to spell-checkers to AI.