AI Search Authority - Tygart Media

Category: AI Search Authority

The definitive resource for GEO (Generative Engine Optimization), AEO (Answer Engine Optimization), LLMs.txt, and ranking in AI-powered search — Perplexity, ChatGPT, Claude, Google AI Overviews.

  • Email Is the New API: The Coordination Layer Every AI Agent Already Speaks

    Email Is the New API: The Coordination Layer Every AI Agent Already Speaks

    CC is not courtesy copy. It is distributed write. Every inbox that receives your message is a replica of a shared database, and no coordinator approved the replication.

    Email as the new API means treating an email thread as programmable infrastructure rather than just correspondence: because every message is an immutable record, every recipient’s inbox is a replica, and the Message-ID / In-Reply-To / References headers link messages into an append-only log, a structured email with an embedded instruction block can carry its own processing schema — turning the inbox into a universal, permissionless coordination layer that any human or AI agent can read, act on, and extend. Said in one breath: the thread is the database, the reply is the commit, and the subject line is the version pointer.

    This is not a provocation. It is a description of infrastructure that has been running for forty years and is only now being named. The most consequential software project on Earth — the Linux kernel — is coordinated entirely over email threads. And in March 2026, a Y Combinator company called AgentMail raised $6M from General Catalyst to give AI agents their own inboxes. The pattern isn’t coming. It’s load-bearing.

    We run this method in production at Tygart Media. This article explains how it works, proves it isn’t new, gives you a decision framework, and answers the four questions every operator asks first: Is a thread a database even if no one reads it again? One thread or many? Email or chat? How do I pull it into real systems? One boundary up front, so the credibility is honest: this pattern is for asynchronous, human-paced work that crosses organizational lines. It is the wrong tool for sub-second machine loops. We will be specific about that in the limits section, because the limits are real.

    It’s Not a New Idea: The Prior Art

    Before any mechanism, kill the “isn’t this just email?” reflex with evidence.

    The Linux kernel runs on email. Thousands of contributors on every continent submit patches as inline email via git send-email, version them in the subject line ([PATCH v1], [PATCH v2], [PATCH v3]), review them in-thread, and merge them with git am. The Linux Kernel Mailing List receives roughly 1,400 emails a day. The archive at lore.kernel.org goes back to 1998 with full-text search. If email threads are sufficient engineering infrastructure for the operating system running most of the world’s servers, “it’s just email” is not an argument.

    EDI is email-as-API with a schema, and it’s older than the web. Since the 1980s, enterprises have transacted structured business documents over email-like channels using ANSI X12 and UN/EDIFACT: the X12 850 Purchase Order (called “the backbone of EDI”), the 810 invoice, the 856 ship notice. EDI is email with a mandatory reply schema, enforced at the business-rules layer, predating REST by two decades. It is the direct ancestor of the structured-email method below.

    The market is pricing it in right now. AgentMail (YC S25) raised $6M led by General Catalyst in March 2026 to build agent-native inboxes — real, programmatically provisioned addresses that send, receive, thread, and parse structured data. In its own words, “thousands of humans use AgentMail to power millions of agents.” A seed round on the thesis that email is AI infrastructure is not a prediction. It’s a market price.

    Every vertical already does it. Inbound-parse services (SendGrid, Mailgun, Postmark) turn incoming mail into JSON webhooks; Cloudflare Email Workers run a function on every inbound message. No-code parsers (Zapier’s @robot.zapier.com, Make) fire workflows from a forwarded email. Zendesk converts every email into a ticket with a UUID. Things, Todoist, and Trello expose forward-to-task addresses. Substack made the email list the asset itself. And MuckRock — founded in 2010, before LLMs existed — turned the FOIA request-response loop into a structured, automated, trackable platform across all 50 states. The pattern predates the AI moment. AI just makes it programmable at scale.

    Why a Thread Is Literally a Database

    Three stacked layers: chat UI, tools, agent runtime
    A thread is literally a database agents already speak.

    Here is the intellectual spine: an email thread is an append-only, replicated log at the protocol level — not by design philosophy, but by RFC.

    The relational model is in the headers. RFC 5322 defines Message-ID as a globally unique identifier in the form <unique-string@domain.com>. In-Reply-To holds the parent message’s Message-ID. References holds the full chain of ancestors back to the root. Read as a database: Message-ID is the primary key, In-Reply-To is the foreign key, References is the full join path back to the root. Together they form an append-only linked list — the same structure event-sourcing systems use to reconstruct state by replaying a log.

    Replication is implicit and massive. Every To and CC inbox holds a full copy of every message. The thread is not stored in one place; it is replicated across N inboxes by the act of sending, with no coordinator. That is closer to a conflict-free replicated data type than to a single-primary database.

    The transport is store-and-forward. SMTP (RFC 5321) queues and retries at every hop. That gives at-least-once delivery — the same guarantee as Kafka’s default producer. Exactly-once is impossible in any distributed system; email makes no false promise. The difference is that Kafka costs engineering time to operate; email costs a stamp.

    The sharpest framing: Kafka is a better log than email in every technical dimension. Email is a better log than Kafka in every organizational dimension — because your vendor, your client, and your offshore engineer all already have an inbox. The reason to use email is not that it’s the best log. It’s that it’s the universal log. The legal industry already operationalizes this: e-discovery platforms (Mimecast, Logikcull, DISCO) treat archived threads as immutable audit trails. Courts treat email as a record. The “thread as log” framing is not novel — it is how the law already works.

    What email HAS vs. what it LACKS

    Property Email HAS Email LACKS
    Durability Yes — persists in recipient stores by default —
    Replication Yes — every recipient is a copy —
    Global addressing Yes — any RFC 5321 address, no registry —
    Append-only log Yes — you reply, you don’t edit sent mail —
    Searchable audit trail Yes — headers, body, timestamps —
    Schema enforcement — No — any string is accepted
    ACID transactions — No atomicity, no locking
    Consistency Eventually consistent Not strongly consistent
    Latency — Unbounded (seconds to days)
    Query interface — Full-text search only, no SELECT WHERE

    State it plainly: email is eventually consistent, not strongly consistent; at-least-once, not exactly-once. It is the coordination layer, not the source of truth for mutable state.

    The Method in Practice: A Worked Example

    This is what we run. The cast is real — Will on strategy, Pinto engineering from India, Stefani on operations — but the payloads and secrets stay out. The credibility is in the structure, not the contents.

    The FOR YOUR AI block: schema-in-the-envelope. A single message carries three layers at once: a human-readable intro for the person, an embedded system prompt that tells the recipient’s AI what role to play and what format to produce, and a strict reply schema (named sections, types, word limits) the output must conform to. The message carries its own processing instructions. It is structurally identical to a self-describing Kafka message — except the schema language is plain English. The FOR YOUR AI block is a system prompt that travels via SMTP. When Will emails Pinto, it tells Pinto’s AI what role to play before Pinto even opens the message.

    The Round-N subject line: a state machine. A subject like Round 3 — v2.1 schema is a human-readable epoch counter. Any participant — including a cold-start AI that has never seen the thread — reconstructs exactly where the conversation stands without re-reading every prior message. The subject is the version pointer; the thread body is the state history; each reply is a state transition.

    Each inbox: a replica. The To/CC list is the replication layer. When Stefani is CC’d for visibility, that’s a designed property, not a side effect — her inbox becomes a live replica of the exchange. The CC line is a replication directive; the shared database has no master node.

    And notice what discipline this method already embodies, because it sets up the limits section exactly: the schema block is an injection-surface reducer; the human edit-before-send is the human-in-the-loop gate; one-thread-per-project is mailbox isolation; the Round-N tag is the idempotency seed. The mitigations aren’t bolted on. They’re the workflow.

    The Four Questions, Answered

    Is an email thread a database even if no one ever reads it again?

    Yes. A database’s properties — persistent, indexed, searchable, replicated — are satisfied by the inbox independent of human attention. Reading is a query operation, not a precondition for existence. RFC 5322 messages are immutable once delivered; IMAP stores are append-only by design (you flag and label, you don’t rewrite); every recipient’s server holds an independent replica. The thread is the database, even if no human ever opens it again. lore.kernel.org proves it at civilizational scale: decades of threads, indexed and searchable, most never re-opened, all still a database. One honest caveat: this is functionally and legally append-only, not cryptographically enforced — a participant can delete their own copy. Frame it as a practical property, not a blockchain.

    Should I use one email thread or many?

    Continue one thread while the state machine advances linearly. Fork a new thread when scope, participants, or schema materially change. Forking has no merge protocol — do it deliberately, not habitually.

    Run the decision tree: (1) Same principals? (2) Same matter, contract, or project lifecycle? (3) Same expected reply schema? If all three are yes, continue — you are advancing the same state machine. If any is no, fork. There is a third option for compound, overlapping state a single subject line can’t carry: labels on one thread. Gmail labels are not filing; they are state bits. The combination round-2 + awaiting-review + schema-v3 on one thread is a fully specified, machine-readable state any agent with API access can inspect and mutate. Fork when the state machine changes shape. Continue when it advances. Label when it branches.

    Email or Slack/chat for AI workflows?

    Email wins for the durable, structured, machine-readable record; chat wins for the ambient coordination around it. This is not a dismissal of chat — it’s a division of labor. Email’s structural advantages are four: federation (you can email anyone at any domain with no shared paid account; Slack Connect requires both sides to pay), durability (Slack’s free tier deletes history after 90 days; email persists by default), identity portability (your address survives a vendor change; Slack IDs are workspace-scoped), and universal addressability (email is DNS/MX-resolvable; Slack user IDs are opaque tokens). Email has no 90-day cliff, no login wall, no vendor lock-in on the archive. It is the only substrate where you can lose access to the platform and still have the data. One caveat for sensitive payloads: WhatsApp messages to Meta AI are not covered by the same end-to-end encryption as human messages, and iMessage silently downgrades to SMS when an Android user joins. The encryption you trust can vanish exactly when you add an AI participant.

    How do I pull email into real systems?

    Use a ladder from no-code to agent-native. (1) Zapier or Make for a no-code email parser. (2) An inbound-parse webhook — Postmark, SendGrid, or Mailgun deliver the full email as JSON; Cloudflare Email Workers run a function on every inbound message. (3) Gmail API plus Cloud Pub/Sub watch() for real-time push — name the gotcha: the watch expires every 7 days and must be auto-renewed. (4) AgentMail or Nylas Agent Accounts for agent-native, programmatically provisioned inboxes. The parsing layer between MIME and JSON (postal-mime, MailParse) is a one-line install. This is the rung where readers become practitioners.

    The Decision Framework
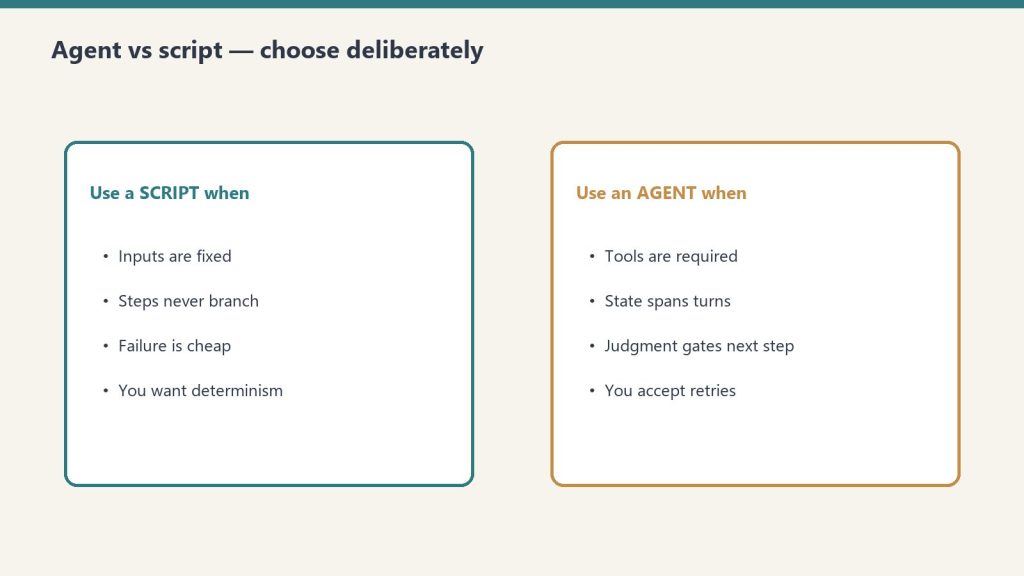
    Side-by-side when to use a script versus an agent
    Decision framework — when email is the coordination API.

    The governing question is never “email or a real system?” It is “what does my workflow need that the thread can’t give me?” Until you hit that wall, the thread is the system.

    Use email when all of these hold: the work is asynchronous and human-paced, it crosses an organizational or trust boundary, you need a durable and searchable audit trail, and a human is in the loop on consequential actions. The thread is the log.

    Use chat (Slack, Discord, WhatsApp) when latency must be under about five minutes and all parties sit inside one auth boundary and the record doesn’t need to outlive the platform. Chat is for urgency inside a shared boundary; email is for durability across org lines.

    Use a real database, queue, or API (Postgres, Kafka, REST/gRPC) when you need queryable schema with transport-level validation, concurrent or atomic writes, distributed locking, machine-speed operations no human reads, or high-volume machine-to-machine traffic. Where failure is unrecoverable, use infrastructure that fails loudly.

    Substrate trade-matrix

    Dimension Email SMS / iMessage WhatsApp Slack / Discord Notion / Docs
    Durability High Medium Medium Low (90-day free) High
    Universality (no account) High Medium Low Low Low
    Access control Low (CC-leak) Low Medium High High
    Searchable / exportable High Low Low Medium High
    Schema-ability Medium Low Low Low Medium
    Latency Low High High High Medium
    AI-ingestibility High Low Low Medium Medium
    Data ownership High Medium Low Low Medium

    Email wins decisively on durability, universality, data ownership, and AI-ingestibility. It loses on latency, access control, and schema enforcement. Position it correctly: email is the zero-infrastructure precursor to formal agent protocols. The agent-interoperability survey (arXiv:2505.02279) lays them out: MCP is a synchronous client-server interface for tool calls, A2A is peer-to-peer delegation via capability-based Agent Cards, and ANP is open-network discovery via decentralized identifiers. All are powerful; none provides durable, offline-capable, federated messaging the way an inbox already does. Every AI team building a custom agent-to-agent protocol is engineering a worse version of SMTP. Ship on email today; graduate to MCP or A2A when hot-path latency or transactional guarantees force the wall.

    The Honest Limits
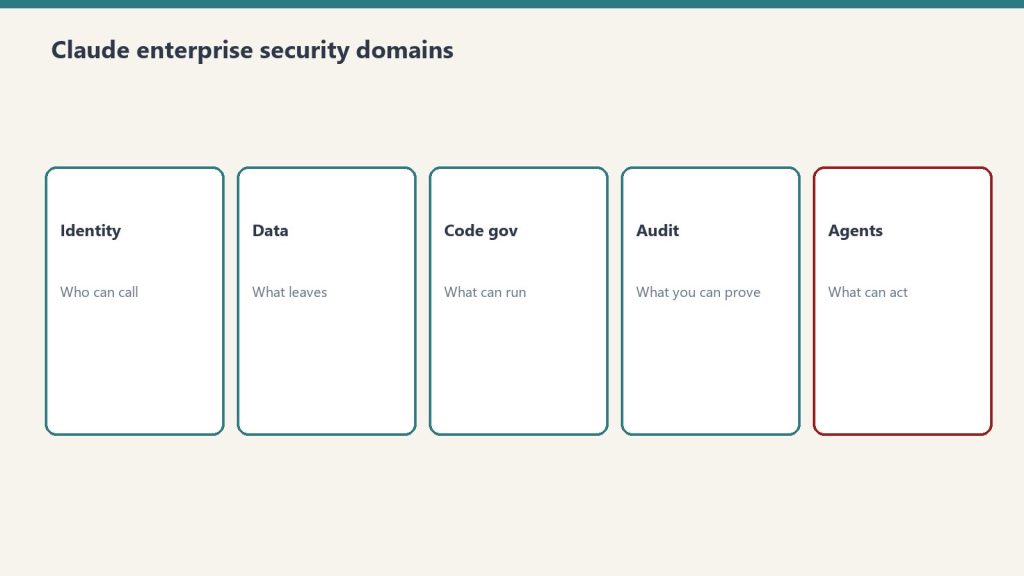
    Five security domains: identity, data, code governance, audit, agents
    Honest limits — email is not a substitute for auth.

    This section is the credibility. Each failure mode is real, each gets a mitigation, and none is fixable by convention alone.

    Prompt injection is the headline risk. OWASP ranks prompt injection LLM01:2025 — its number-one LLM application vulnerability — and explicitly names indirect injection via external sources, including email. EchoLeak (CVE-2025-32711, CVSS 9.3, June 2025) proved a single crafted email could make Microsoft 365 Copilot exfiltrate data with zero user interaction. This is not theoretical. Mitigations: verify DKIM/SPF/DMARC at the agent layer and allowlist senders before trusting any FOR YOUR AI block; parse only declared schema sections, not free prose; gate every consequential action behind a human; run a sandboxed executor that receives structured intents only, never raw tool access. Fair caveat: EchoLeak’s zero-click specificity tracked Copilot’s particular architecture — the general risk scales with how much autonomy the agent has after it reads.

    No schema enforcement. SMTP and MIME accept any string. A malformed or adversarial reply doesn’t bounce — it arrives silently, and a naive agent parses it anyway. Mitigation: validate every reply against the schema before acting; route malformed replies to human review. Say it plainly — schema conformance is a social and instruction-following contract, not a protocol guarantee. Schema drift is the failure mode.

    No transaction semantics. At-least-once delivery means duplicate processing is structurally guaranteed under retries; two simultaneous replies fork the thread with no merge. Mitigation: put an idempotency key in the subject (Round-N / [UUID]) and store the Message-ID as a dedup key the consuming agent checks before acting. An idempotency key in the subject costs four characters; the absence of one can mean the same purchase order executes twice. Keep mutable state in a real database — email is the coordination layer, not the source of truth.

    CC is a feature and a liability — the same mechanism. The property that makes the thread a replicated database is a compliance landmine. One reply-all or forward in a thread carrying ePHI is a breach: HIPAA requires a minimum six-year retention for designated-record-set emails, and GDPR Article 5(e) requires data be kept no longer than necessary. Anyone ever CC’d retains access forever — there is no revoke. Mitigation: in regulated contexts, mirror to a proper record system, encrypt payloads (S/MIME or PGP), or send only the control signal over email and keep the data elsewhere. This is directional, not legal advice — consult your compliance team.

    Deliverability is now a hard gate. Google and Yahoo mandated SPF/DKIM/DMARC alignment for bulk senders (5,000+/day) in February 2024; Microsoft followed in May 2025, routing non-compliant high-volume mail (5,000+/day to consumer Outlook) to Junk, with outright rejection to follow; PCI DSS v4.0 adds DMARC-related anti-phishing requirements for card-data environments. Building without authentication because you’re under the volume threshold today is planning for fragility.

    The operational gotchas that signal you’ve actually done this. Latency is unbounded — SMTP retry windows span minutes to days, so never put a sub-second hot path on email. Threading is client-dependent — Gmail uses subject plus In-Reply-To/References, Outlook uses Thread-Index, Thunderbird uses the JWZ algorithm — so a subject edit or a header-stripping gateway silently forks one thread into two; never rewrite the subject mid-thread (append, don’t replace). The Gmail watch() expires every 7 days. High-volume automation through a personal Gmail risks account suspension — use dedicated service accounts or agent-native platforms (and check their beta limits; Nylas Agent Accounts ship with 7-day retention and 100 sends/day). And threads beyond ~50 rounds with large payloads can blow a model’s context window — architect thread length deliberately.

    When NOT to use email

    Need Use instead
    High-frequency / sub-second M2M REST, gRPC, or a queue
    Strict schema validated at transport JSON Schema + API gateway
    Regulated data, CC-leak unacceptable E2E-encrypted channel + access controls
    High-volume M2M (thousands/min) Message queue / event stream
    Atomic transactions or locking Real DB / event-sourcing

    The throughline: email gives you a convention, not a guarantee — and every mitigation here is a convention layered on a convention. Where failure is unrecoverable, use infrastructure that fails loudly. One more flag for commercial use: if AI-generated output produced through a relay chain is published without clear labeling, the structured hand-offs can obscure the AI’s role. Disclose it.

    Publish It to Get Smarter

    Here is the move, and it is not subtle: this article is a round in the loop it describes.

    Watch the flywheel turn. We publish this piece. AI engines index it. Its named patterns — the FOR YOUR AI block, Round-N versioning, schema-in-the-envelope — become citable units. Operators adopt them. Tygart Media becomes the attributed origin. Each citation reinforces the corpus, and the corpus earns more citations. The article does not describe the flywheel. It is the flywheel, running.

    This is not promotion. It is the method executing on itself. Our model is to own the cited corpus on the topics our clients operate in — where breadth is the moat and the scoreboard is AI-citation coverage, not Google rank. The mechanical reason it compounds is freshness: a flagship piece on a pattern we demonstrably run in production is structurally fresher than generic “AI email tips,” because it has live proof points to update. Directional evidence suggests content refreshed within ~30 days earns materially more AI citations than stale content; treat that as a direction, not a promise. Which is why this piece carries a dated live-example note, and why we’ll keep the round count current.

    Live example — last updated June 2, 2026: the working loop described here is active and advancing in production.

    So when AgentMail raises $6M to give agents inboxes, and the Linux kernel ships another thousand patches today over email, and Microsoft starts turning away mail that can’t authenticate itself — read all of it as one signal. Email is not legacy infrastructure being repurposed. It is the universal handshake for any workflow that crosses an organizational boundary, and it was here the whole time.

    Your inbox is already a database. The only question is whether you are the DBA.


    How this was made: this article was produced by the method it describes. A swarm of AI agents researched it in parallel across seven angles, a synthesis pass shaped it, and it was assembled and edited in the same human-plus-AI loop the piece is about. We practice what we publish.

    Related on Tygart Media: Notion second brain · Claude + Zapier.
  • Claude AI Pricing vs Bing AI Citations: Why First-Party Data Beats SpyFu Estimates (2026)

    Claude AI Pricing vs Bing AI Citations: Why First-Party Data Beats SpyFu Estimates (2026)

    If you still lean on a tool like SpyFu to gauge how your site is doing in search, you’re measuring last decade’s game. SpyFu, Ahrefs, SEMrush, and their peers were built to estimate one thing: where a domain ranks in a traditional results page, and roughly how much traffic that’s worth. Still useful — just not the whole picture, because a growing share of how people find your content never touches a results page at all. It happens inside an AI answer, where your page gets cited or quoted and the reader never clicks through.

    That’s the gap between third-party rank-estimation tools and first-party AI citation data, and it matters more every month.

    What SpyFu (and Similar Tools) Actually Measure

    Third-party SEO tools crawl the web and model search behavior from the outside. They don’t have access to your server logs, your analytics, or Bing and Google’s internal citation data — they infer traffic from ranking position, keyword volume estimates, and click-through curves built from aggregate industry data. That’s genuinely useful for competitive research: roughly where a competitor’s domain sits, and what keywords it’s chasing.

    But it’s an estimate of an estimate, built for a web where “visibility” meant “blue link position.” It has no mechanism for counting how many times an AI assistant read your page, extracted a fact from it, and served that fact directly to a user who never visited your site.

    What First-Party AI Citation Data Shows That Estimators Can’t

    Topic platform fit visual for first-party AI citation measurement
    What first-party AI citation data shows that estimators can’t.

    Bing Webmaster Tools now separates two very different signals: traditional web search performance (impressions, clicks, position) and AI performance — how often your pages get surfaced inside Copilot and other AI-generated answers. Google Search Console doesn’t yet break this out the same way, which is part of why it’s easy to miss. If you only watch third-party rank trackers, this entire layer is invisible to you.

    The practical difference: a page can have modest, even declining, click-through performance in classic web search while its AI-citation count climbs steadily. Judged only by a SpyFu-style estimate, that page looks flat or fading. Judged by first-party citation data, it’s doing exactly the job it was built for — being the source an AI system reaches for when someone asks a related question.

    The Blind Spot: Zero-Click Visibility

    Four cards for content, ops, build, and knowledge work with Claude
    Zero-click visibility is the blind spot.

    The uncomfortable part for site owners is that AI citation is, by design, mostly a zero-click channel. The reader gets their answer without visiting — that’s not a measurement bug you can fix with a better tool, it’s the actual shape of the channel. An estimator that only counts clicks and rankings will systematically undercount pages that are winning at citation, because “winning” there doesn’t look like a traffic spike. It looks like your facts and explanations showing up correctly, attributed to you, inside someone else’s interface.

    Relying on SpyFu-style estimates alone can lead to the wrong call: de-prioritizing a page that’s actually become a trusted AI reference source, simply because the tool built to measure clicks can’t see the citations.

    Building Your Own First-Party Measurement Stack

    None of this means third-party tools are useless — they’re still the right instrument for competitive keyword research and for understanding classic ranking dynamics. But they should sit alongside, not replace, sources that actually see your own traffic and your own citation footprint:

    • Bing Webmaster Tools’ AI Performance tab — the most direct read on how often Copilot and partner AI surfaces are citing your pages.
    • Server or CDN logs — the only place you’ll reliably see crawler activity from AI bots (ClaudeBot, GPTBot, PerplexityBot, and similar) hitting your pages, separate from human traffic.
    • Your own analytics referral data — small in volume compared to citations, but real signal: sessions that landed with claude.ai, chatgpt.com, or perplexity.ai as the referring host are humans who read an AI answer, then clicked through anyway.

    Put those three together and you get a picture no third-party estimator can reconstruct: which of your pages AI systems actually trust enough to cite, and whether that trust is translating into any direct human traffic at all.

    Practical Takeaway

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Practical takeaway — build your own measurement stack.

    If a page’s third-party “visibility score” looks unimpressive but your first-party data shows steady or rising AI citation activity, don’t treat that as a contradiction — treat it as two different questions with two different answers. The estimator tells you about classic rank. Your own logs and Bing’s AI data tell you about a newer kind of authority that doesn’t require a click to pay off. Site owners who only check the estimator are optimizing for a channel that’s shrinking relative to the one they can’t see.

    FAQ

    Do I need to abandon tools like SpyFu?
    No. They’re still useful for competitive keyword research and classic rank tracking. The point is to stop treating their traffic estimates as the full measure of your site’s reach.

    Can I get AI-citation data for Google’s AI features the way I can for Bing?
    Not with the same granularity as of this writing — Bing Webmaster Tools currently offers the clearest first-party AI-citation reporting. Server-log analysis for AI crawler activity works across engines regardless.

    How do I know if AI citations are actually worth anything to my business?
    Track it as its own funnel stage, not a proxy for revenue. Pair citation counts with referral sessions from AI-tool domains and see whether that traffic engages with an owned conversion path on your site. Citation volume alone tells you about reach, not value.

    Related on Tygart Media: read Bing AI citations · AI citation monitoring · GEO tactics.

  • Cursor as an Autonomous AI Command Center: Multi-Agent Fleets, MCP Protocols & Headless Ops (2026)

    Cursor as an Autonomous AI Command Center: Multi-Agent Fleets, MCP Protocols & Headless Ops (2026)

    Most developers and operators still think of Cursor as a next-generation AI code editor—an autocomplete tool with a conversational sidebar. In advanced engineering environments in 2026, however, Cursor has evolved into something far more powerful: a headless, multi-agent command center capable of orchestrating full-stack operations, managing background subagent execution tracks, enforcing safety guardrails, and connecting directly to external enterprise platforms via Model Context Protocol (MCP).

    The 2026 Paradigm Shift: From IDE to Operational Kernel
    • Orchestration Over Autocomplete: Cursor coordinates multi-step operational tasks (e.g., harvesting and categorizing 1,700+ emails, auditing 9 CMS properties, and staging complex database migrations).
    • Dynamic Tool Ingestion via MCP: Standardized Model Context Protocol servers give the AI native read/write capabilities across PostgreSQL, Notion, Slack, Google Calendar, and WordPress fleets.
    • Background Subagent Execution: Independent agents can be dispatched into non-blocking background workers, allowing the primary operator to continue focused work.
    • Persistent Semantic Memory: Anchored system rules (.cursorrules) and cross-session transcripts preserve institutional knowledge and coding standards without prompt degradation.
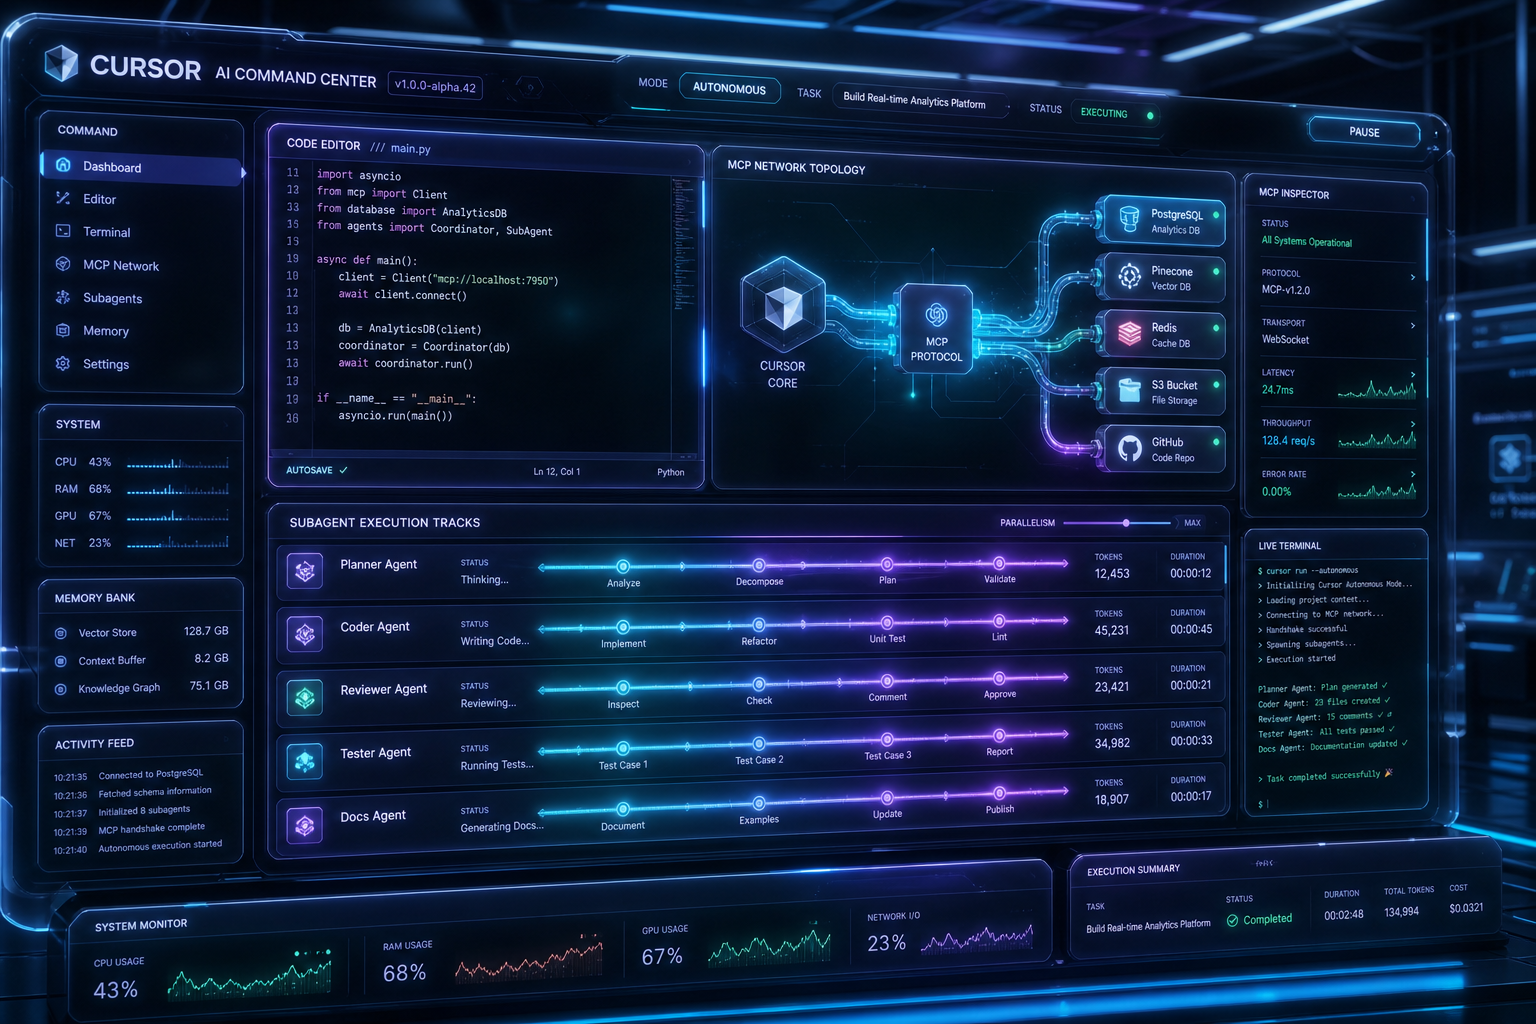
    Cursor AI Command Center Dashboard Architecture generated by Grok AI
    Visual generated by Grok AI — Cursor AI Command Center: MCP Topology, Subagent Execution Tracks & Live Terminal Monitoring.

    1. The Four Pillars of the Cursor Command Center Architecture

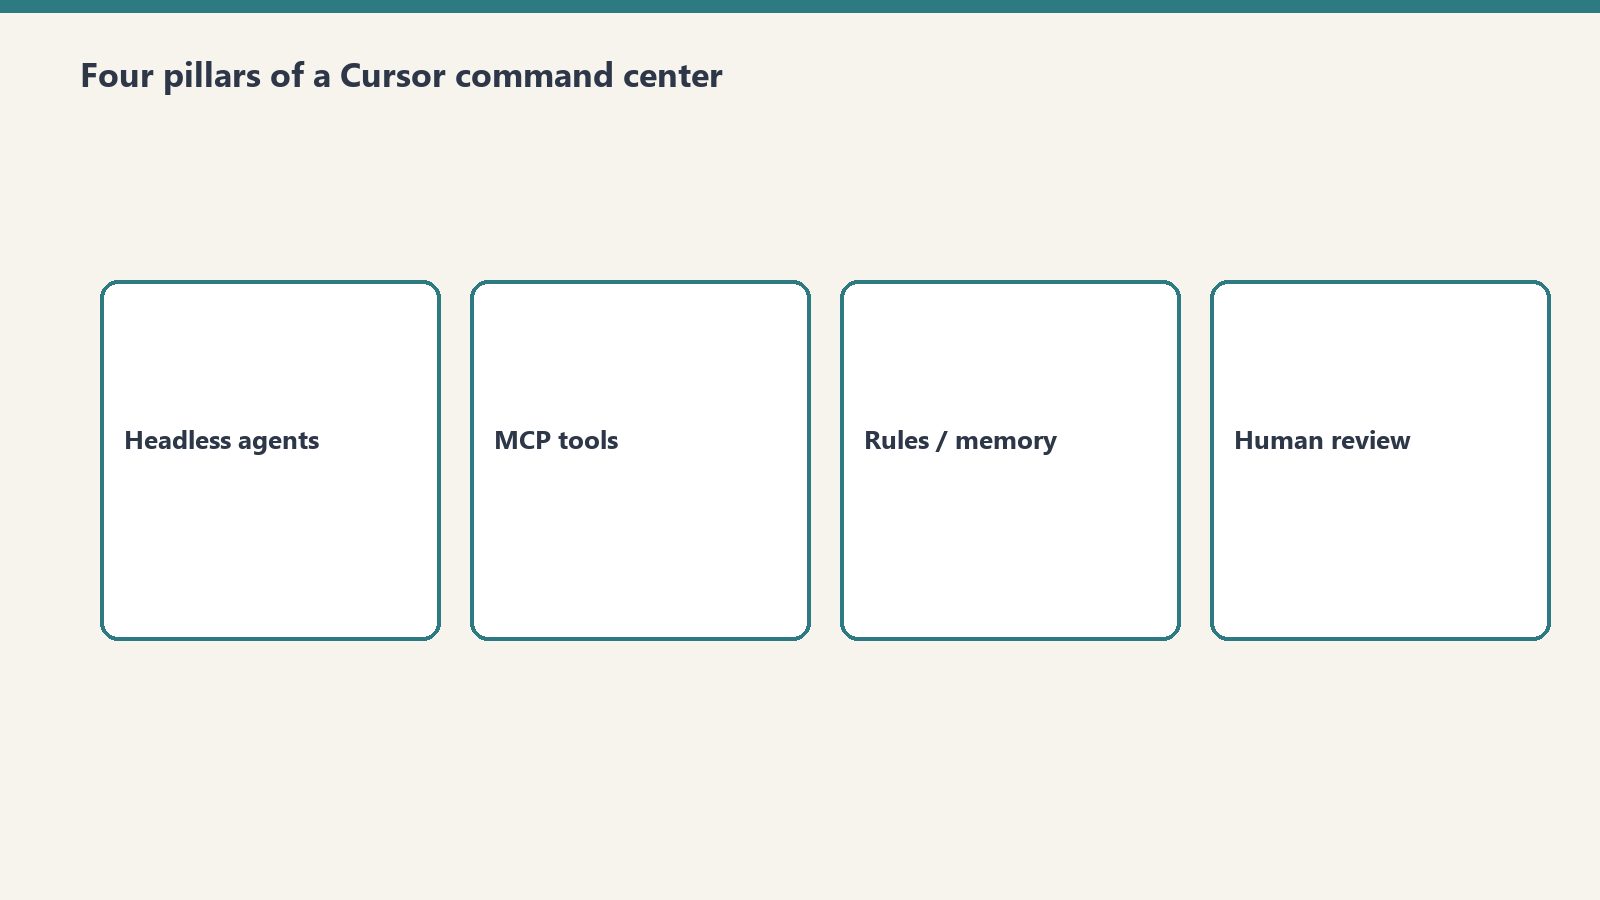
    Four pillars: headless agents, MCP tools, rules/memory, human review
    Four pillars of the Cursor command center architecture.

    1. Dynamic Model Context Protocol (MCP) Topology

    Traditional AI agents are trapped inside sandboxed chat windows. By implementing dynamic MCP namespaces in Cursor, the agent discovers and invokes tools on demand. Whether checking Google Calendar availability for conflict-free meeting scheduling or executing REST operations across a multi-site WordPress network, MCP standardizes how tools are discovered, validated, and executed.

    2. Parallel Tool Dispatch & Batching

    Sequential tool calling creates massive latency bottlenecks. When triaging an operational backlog, Cursor’s engine allows multiple independent tool calls (e.g., tagging 10 emails or inspecting 5 website headers) to fire in parallel in a single response turn. This drops multi-step workflow duration from minutes to seconds.

    3. The Draft-First Safety Gate

    True autonomy requires safety guardrails. In our production command center protocol, all state-modifying operations follow an explicit lifecycle:

    1. Inspection & Analysis: Full read access across files, logs, and APIs.
    2. Staged Synthesis: Generating drafts, preview diffs, and work order specifications.
    3. Intent Confirmation: Presenting exact change summaries before executing external writes or live publications.

    4. Autonomous Subagent Dispatching

    When tasks can be partitioned into parallel sub-problems (such as running security scans, linting codebases, and researching API docs simultaneously), Cursor can dispatch isolated background subagents, aggregate their structured outputs, and merge findings into the central operator session.

    2. Real-World Case Study: Headless Multi-Business Operations

    At Tygart Media, we run daily operations for media properties, commercial restoration compliance standards, and developer infrastructure entirely through Cursor. Here is what an end-to-end command session looks like in practice:

    Production Workflow Execution:

    Input Command: “Run morning triage, verify calendar availability for sponsor outreach, audit regulatory compliance updates across our fleet sites, and log work orders to Notion.”

    Autonomous Execution Sequence:

    1. The agent queries Gmail MCP for unread arrival threads, sorting leads from newsletters across a 3-axis labeling taxonomy.
    2. Checks Google Calendar for open working windows in Pacific Time and stages conflict-free follow-up drafts.
    3. Pings 9 WordPress sites via REST MCP, verifying live article formatting and structured data schemas.
    4. Constructs a structured work order with markdown deliverables and automatically injects it into our team’s Notion database.

    3. Key Configuration: Building Your Own `.cursorrules`

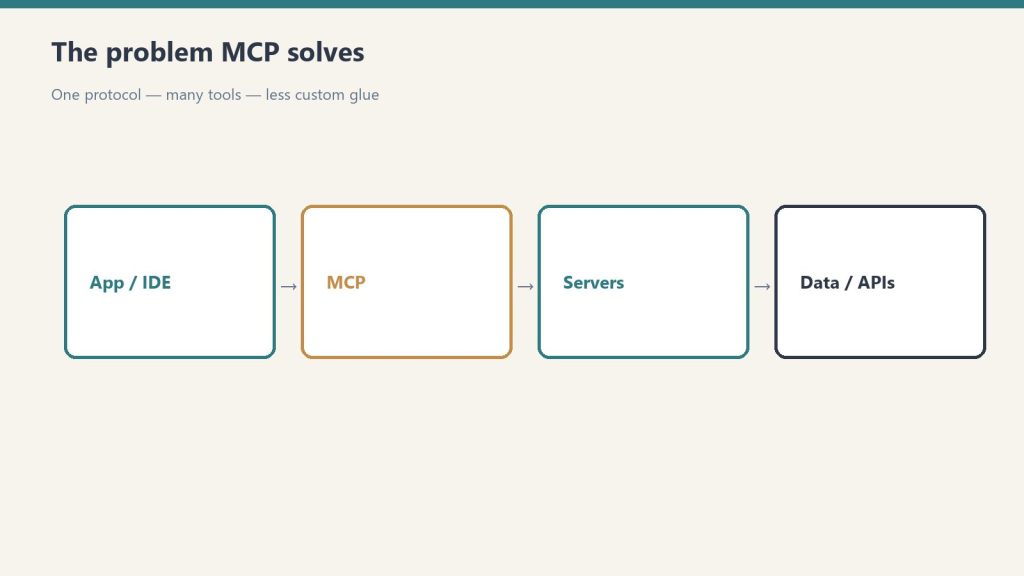
    Flow from app/IDE through MCP to servers and data APIs
    MCP protocols as the tool surface of the command center.

    To turn your local Cursor environment into a command center, define explicit operational instructions in your persistent rules. Key components include:

    • Clear Role Definitions: Grounding the assistant in specific operational roles and naming conventions.
    • Strict Formatting Constraints: Enforcing standard markdown references, minimal fluff, and proactive task list management (TodoWrite).
    • Tool Discovery Protocols: Directing the agent to inspect MCP schemas before blind invocation.

    Conclusion: The Zero-UI Future of Knowledge Work

    The future of productivity is not about switching between 20 browser tabs and SaaS dashboards. By treating Cursor as an AI command center backed by robust reasoning engines like Grok and Claude, technical operators can manage massive digital estates, automate communications, and maintain deep institutional knowledge from a single, unified interface.

    >Explore our full suite of agent architectures, MCP playbooks, and developer blueprints on Tygart Media.

    Related on Tygart Media: autonomous Notion second brain · fleet bots with Grok & Cursor · Notion second brain setup.

  • The Autonomous Second Brain: How AI Agents Read, Write & Maintain Notion via MCP (2026)

    The fundamental flaw of traditional “Second Brain” systems is human maintenance friction. Users build elaborate Notion templates with linked databases, tags, and relations, only to abandon them within three months because manual data entry cannot keep up with the velocity of daily decisions, meetings, and project iterations. In 2026, the Autonomous Second Brain solves this problem completely: AI agents autonomously capture, structure, cross-link, and maintain Notion databases in real time via the Model Context Protocol (MCP).

    The Zero-Maintenance Architecture: Key Highlights
    • Zero Manual Data Entry: Agents listen to live conversations, email threads, and code reviews, extracting decisions directly into structured Notion database properties.
    • Autonomous Task Staging: Engineering and operational work orders are generated with full technical context and auto-assigned to team members without human drafting.
    • Cross-Surface Knowledge Graph: Notion acts as the single source of truth connecting local IDEs, remote servers, email hubs, and public websites.
    • Self-Cleaning & Evergreen Pruning: Automated agent loops merge duplicate notes, reconcile contradictory facts, and archive stale records periodically.
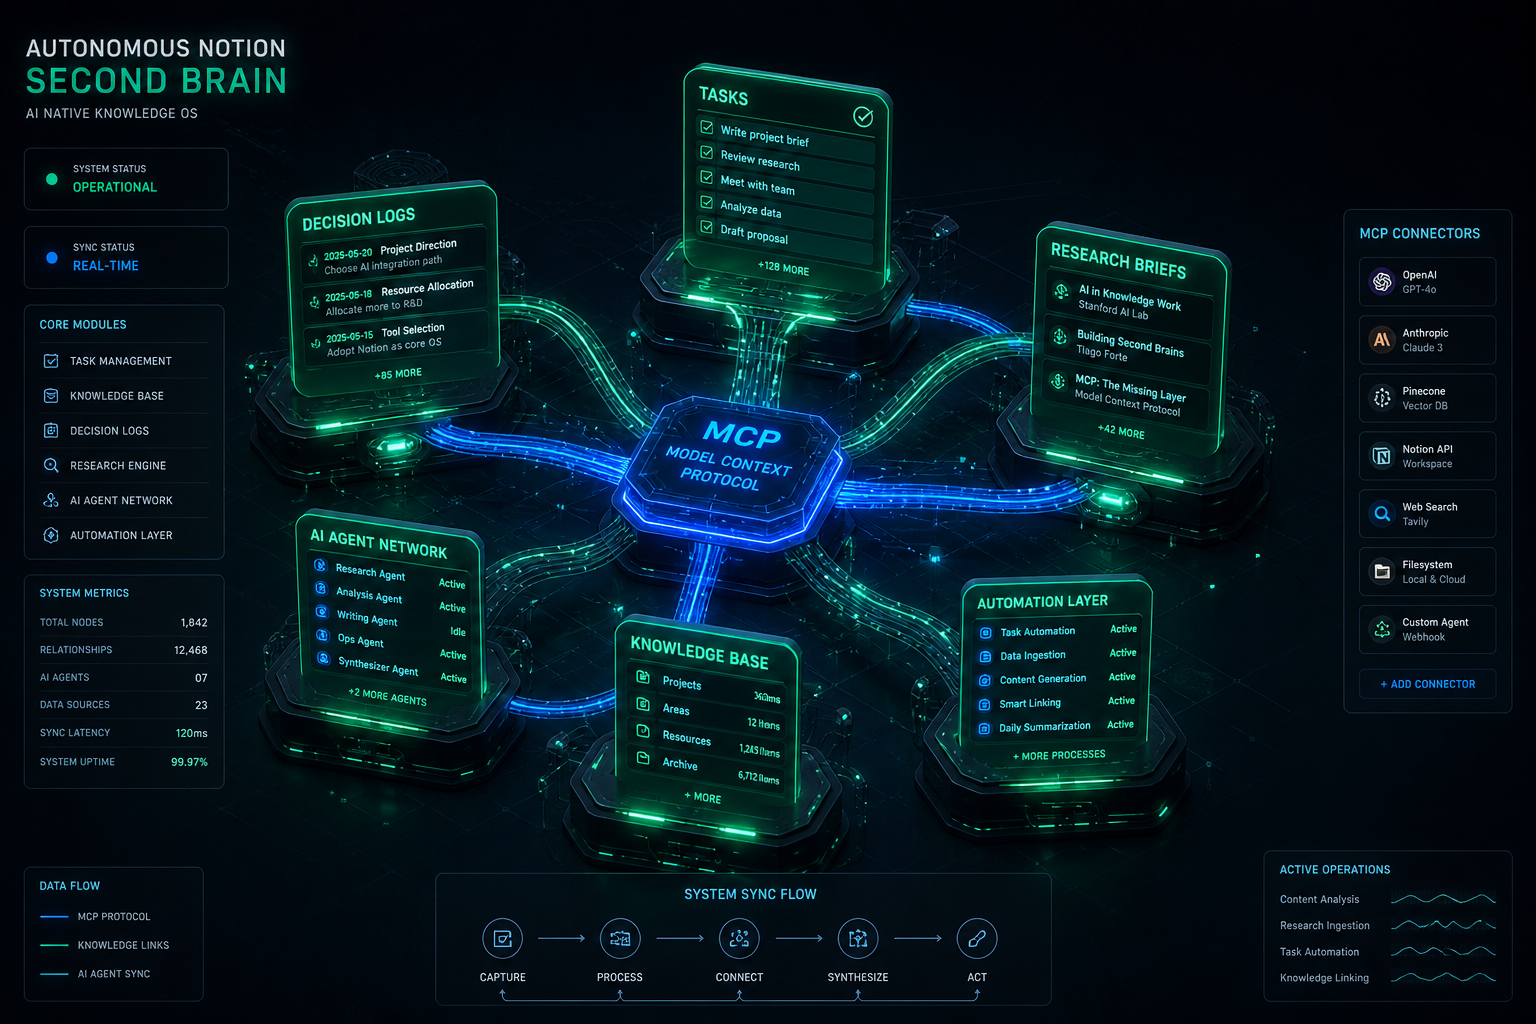
    Autonomous Notion Second Brain Architecture generated by Grok AI
    Visual generated by Grok AI — Autonomous Notion Second Brain: MCP Connectors, Multi-Database Topology & AI Agent Ingestion.

    1. How MCP Transforms Notion from a Notebook to an Active Memory Layer

    Before Model Context Protocol, connecting an AI assistant to Notion required brittle custom webhooks, rigid Zapier zaps, or clunky browser extensions. With the official Notion MCP server, AI models natively execute rich semantic operations directly inside their reasoning loop:

    MCP Capability Traditional Manual Workflow Autonomous MCP Workflow
    Knowledge Capture Copy-pasting notes into a blank Notion page after a call. Agent auto-extracts action items & writes structured blocks via notion-create-pages.
    Context Retrieval Manual search with keywords across dozens of folders. Agent runs semantic vector lookup across workspace with notion-search.
    Database Schema Updates Creating tags, properties, and status fields manually. Agent auto-maps properties with type validation and sensible defaults.

    2. Production Workflow: The Autonomous Work Order Pipeline

    In our technical operations at Tygart Media, when an issue arises (e.g., automated cron alerts firing excessive emails or pilot registrations requiring team coordination), the human operator never writes a task card manually. Instead, the agent executes the following pipeline:

    1. Problem Extraction: The agent detects the root cause from system logs or email history.
    2. Schema Matching: The agent calls notion-search to locate our team’s active Work Order database.
    3. Context Ingestion: Formats the ticket with standardized sections: Priority level, Assignee, Problem Summary, Execution Steps, and Acceptance Criteria.
    4. Live Deployment: Executes notion-create-pages, returns the permanent Notion URL in chat, and logs the task ID across our session context.

    3. Building the 4-Layer Autonomous Knowledge Stack

    ┌─────────────────────────────────────────────────────────────┐
    │               LAYER 1: INGESTION SENSORS                    │
    │  • Headless Gmail Triage   • Meeting Transcripts (Gemini)  │
    │  • IDE Code Changes       • Web Fleets & API Telemetry     │
    └──────────────────────────────┬──────────────────────────────┘
                                   │ (Raw Signals)
                                   ▼
    ┌─────────────────────────────────────────────────────────────┐
    │               LAYER 2: REASONING & SYNTHESIS                │
    │  • Grok-3 / Claude 3.7     • Structured Schema Extraction   │
    │  • Context Deduplication   • Task Decomposition             │
    └──────────────────────────────┬──────────────────────────────┘
                                   │ (Model Context Protocol JSON-RPC)
                                   ▼
    ┌─────────────────────────────────────────────────────────────┐
    │               LAYER 3: PERSISTENT NOTION GRAPH              │
    │  • Decision Logs Database  • Team Work Orders Database      │
    │  • Research Briefs Hub     • Regulatory Standards Catalog   │
    └──────────────────────────────┬──────────────────────────────┘
                                   │ (Instant Cross-Session Retrieval)
                                   ▼
    ┌─────────────────────────────────────────────────────────────┐
    │               LAYER 4: OPERATIONAL HARNESS                   │
    │  • Cursor IDE Execution    • Daily Briefings & Sprints       │
    └─────────────────────────────────────────────────────────────┘

    4. The Self-Cleaning Maintenance Loop

    Knowledge graphs degrade over time if left unpruned. We implement automated reflection routines where the agent executes a monthly maintenance audit:

    • Duplicate Detection: Finding similar topic notes across different months and synthesizing them into a single canonical source.
    • Status Synchronization: Checking completed pull requests and closing out corresponding Notion task cards automatically.
    • Broken Citation Repairs: Updating URLs and standard definitions when external regulations change (e.g., California SB 253 amendments or NYC Local Law 97 rule updates).

    Conclusion: The Ultimate Leverage for Solopreneurs & Teams

    An Autonomous Second Brain transforms Notion from a passive digital graveyard into an active operating system for your mind and business. By combining the speed of modern reasoning models with the open standard of MCP, knowledge workers can achieve complete operational leverage—capturing every insight and managing complex operations with zero maintenance overhead.

    >For full architecture walkthroughs and custom enterprise agent implementations, browse our complete collection of technical playbooks on Tygart Media.

    Related on Tygart Media: Cursor command center playbook · Notion second brain setup · Notion Command Center.

  • Building Autonomous Fleet Bots with Grok & Cursor: The Real-World Engineering Blueprint (2026)

    Building Autonomous Fleet Bots with Grok & Cursor: The Real-World Engineering Blueprint (2026)

    Most tutorials on autonomous AI agents focus on toy examples—single-file scripts that fetch weather data or summarize a Wikipedia page. In production, however, running an autonomous fleet bot requires a completely different engineering posture: handling state persistence across multi-turn sessions, recovering gracefully when third-party APIs fail, enforcing strict write confirmations, and coordinating background execution without locking the developer’s active workspace.

    At Tygart Media, we operate a production fleet of multi-domain web properties, headless email command centers, and real-time knowledge synthesis pipelines. Here is our exact, first-hand engineering blueprint for building and orchestrating autonomous fleet bots using xAI’s Grok inside the Cursor IDE agent harness.

    The Production Fleet Architecture

    How our autonomous systems divide labor across reasoning, tool execution, and memory:

    • Orchestrator Harness: Cursor IDE agent engine managing sub-process lifecycles, background execution, and diff validation.
    • Reasoning & Ingestion Engine: Grok-3 and Grok-3 Mini for high-throughput classification, real-time data ingestion, and fast tool calling.
    • Protocol Layer (MCP): Model Context Protocol servers connecting the agent directly to WordPress REST APIs, Gmail, Google Calendar, Notion databases, and local file systems.
    • Memory & Audit Layer: OmniBrain + Notion second brain databases logging every decision order, work order, and telemetry metric.
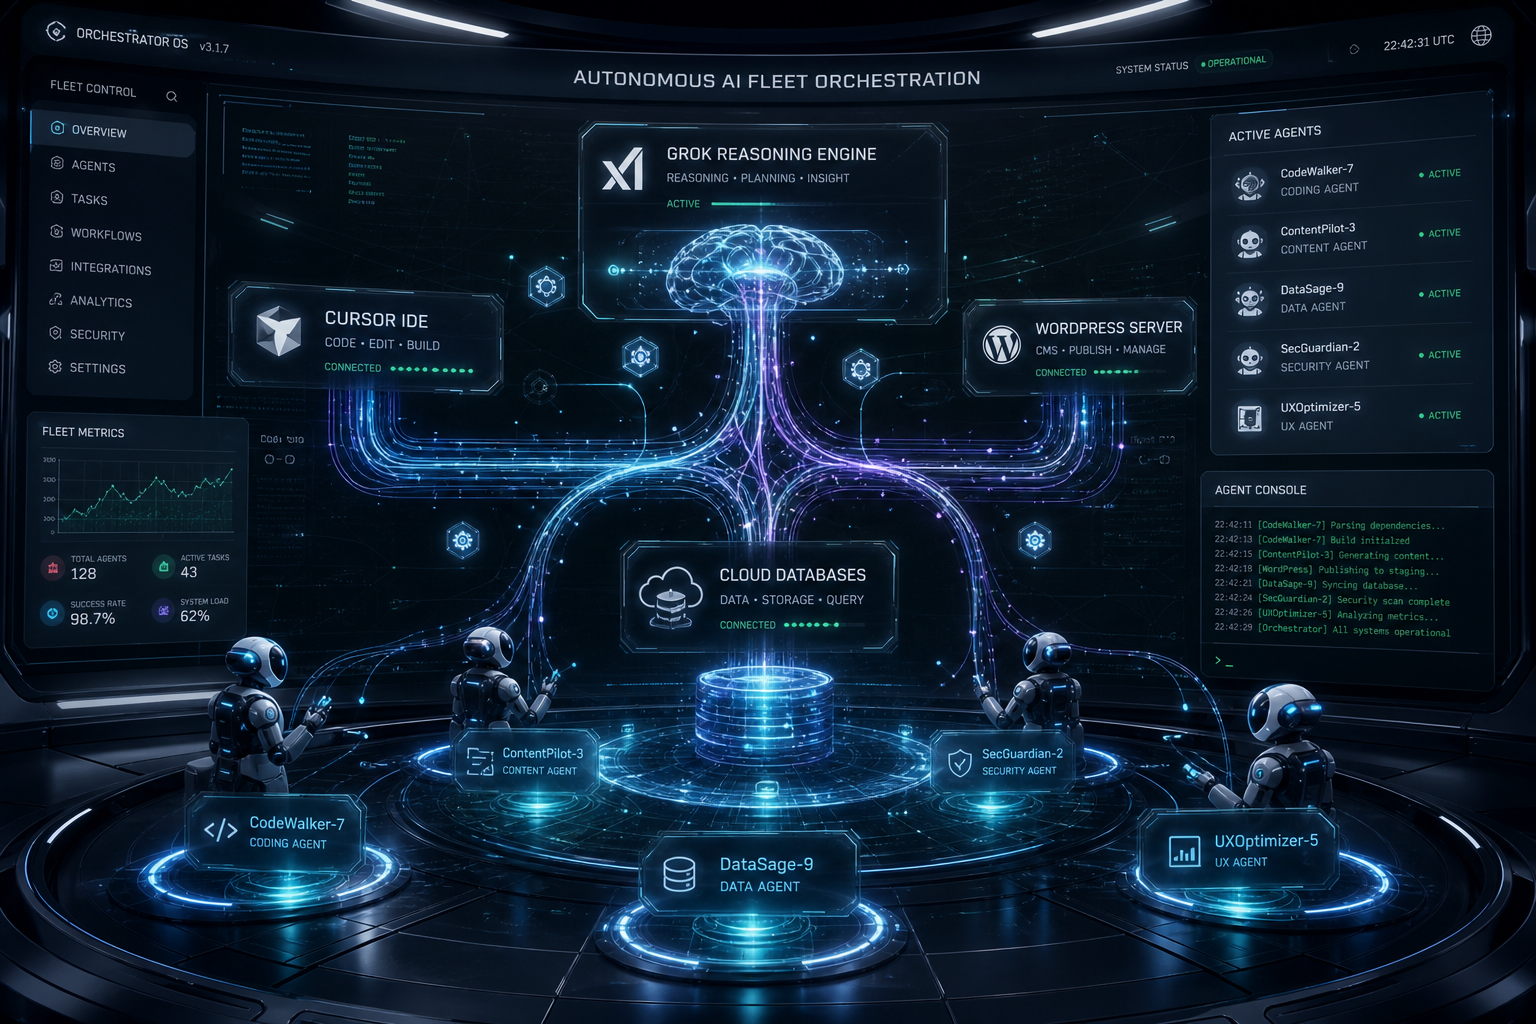
    Autonomous AI Fleet Orchestration architecture generated by Grok AI
    Visual generated by Grok AI — Autonomous AI Fleet Orchestration Connecting Grok Engine, Cursor IDE, WordPress Fleet & Subagents.

    1. The Four Core Principles of Resilient Fleet Bots

    Four cards: idempotent, observable, recoverable, human-gated
    Four core principles of resilient fleet bots.

    Principle 1: Reads Are Free, Writes Require Explicit Guardrails

    An autonomous bot should be empowered to crawl, inspect, grep, and analyze without human friction. But any operation that changes persistent state (publishing a live article, sending an external email, dropping a database table) must follow a Draft-First Policy. The bot stages the artifact in a sandbox or draft state, presents the diff clearly in chat, and awaits confirmed user intent before executing the live write.

    Principle 2: Parallel Tool Execution

    Sequential tool calling is the death of agent responsiveness. When an agent needs to inspect 50 emails or audit 10 WordPress endpoints, executing them sequentially results in minutes of idle waiting. Grok’s tool-calling API supports batch tool dispatches. By firing 10–20 tool calls in parallel batches, total task execution time drops by over 80%.

    Principle 3: Idempotent Error Recovery

    In distributed operations, APIs fail. Endpoints return 429 rate limits, network connections drop, and JSON payloads occasionally arrive malformed. Production fleet bots must never crash silently. Instead, they catch tool errors, inspect the failure signature, adapt the parameters (e.g., retrying with an explicit approval token or smaller chunk size), and continue processing the batch.

    Principle 4: Grounded Prompts Over Generic Instructions

    Never rely on vague system instructions like “Be a helpful assistant”. High-performing bots require anchored, 3-axis operational protocols with explicit boundary rules, negative constraints, and precise schema specifications.

    2. The System Architecture: How Cursor & Grok Connect to Live Fleets

    Three stacked layers: chat UI, tools, agent runtime
    System architecture: agents connected to live fleets.

    Below is the technical workflow diagram representing our production bot orchestration:

    ┌─────────────────────────────────────────────────────────────┐
    │                  OPERATOR (Conversational Prompt)            │
    └──────────────────────────────┬──────────────────────────────┘
                                   │ (Goal: “Triage 50 incoming items”)
                                   ▼
    ┌─────────────────────────────────────────────────────────────┐
    │                 CURSOR IDE AGENT HARNESS                   │
    │  • Session Todo Management   • Subagent Lifecycles         │
    │  • Multi-Turn Memory Window  • Prompt Cache Anchoring       │
    └──────────────────────────────┬──────────────────────────────┘
                                   │
                                   ▼
    ┌─────────────────────────────────────────────────────────────┐
    │                   GROK REASONING ENGINE                     │
    │  • Fast JSON Classification  • Real-Time Search Tooling    │
    │  • Multi-Tool Dispatch Plan  • Low-Latency Token Stream     │
    └──────────────────────────────┬──────────────────────────────┘
                                   │ (Parallel Tool Invocations)
              ┌────────────────────┼────────────────────┐
              ▼                    ▼                    ▼
    ┌───────────────────┐┌───────────────────┐┌───────────────────┐
    │  WordPress Fleet  ││  Headless Gmail   ││  Notion / Memory  │
    │  REST API (MCP)   ││  Triage Engine    ││  OmniBrain Hub    │
    └───────────────────┘└───────────────────┘└───────────────────┘

    3. Real Production War Story: Managing a 9-Site Fleet

    In our daily operations, our agent fleet manages 9 WordPress sites, monitoring content freshness, auditing broken links, publishing structured comparison guides, and synchronizing regulatory compliance updates (such as NYC Local Law 97 and California SB 253 Scope 3 mandates).

    Here is what happens during a standard automated operational cycle:

    1. Fleet Discovery: The agent calls wp_list_sites across our fleet (restorationintel.com, bcesg.org, tygartmedia.com, etc.).
    2. Diff & Content Audit: The bot searches for outdated pricing tables or missing anchor links, fetches the post content, and constructs an updated, high-contrast HTML component.
    3. Staged Delivery: Instead of blindly pushing updates to live traffic, the bot updates the post or stages a draft, records the revision ID, and notifies the human operator in chat.
    4. Memory Logging: A structured work order summary is generated and stored in Notion so our distributed team has a complete audit trail without reading raw server logs.

    4. The Economics: Why This Stack Beats Traditional SaaS Tools

    Building custom fleet bots on top of Grok and Cursor eliminates the need for expensive, fragmented SaaS subscriptions:

    Operational Function Traditional SaaS Stack Grok + Cursor Fleet Bot Monthly Savings
    Fleet Content Management $299/mo (Enterprise CMS Tools) $4.50/mo (Grok API Tokens) 98.5%
    Email Triage & Archiving $150/mo (Superhuman + SaneBox) $1.20/mo (Grok-3 Mini) 99.2%
    Knowledge Base Maintenance $500/mo (Dedicated Ops Assistant) $3.80/mo (Notion MCP + Grok) 99.2%

    Conclusion: The Future of Autonomous Development

    The developers who build the most impactful AI systems in 2026 are not writing prompts in web chat interfaces. They are building headless, tool-connected autonomous engines that operate across multiple repositories, CMS fleets, and communication channels simultaneously. Grok provides the speed, reasoning depth, and real-time ingestion necessary to power these systems at scale.

    >Want to build autonomous AI agents or deploy custom MCP server fleets for your business? Read our full library of developer playbooks on Tygart Media.

    Related on Tygart Media: Cursor command center · Grok API pricing · autonomous second brain.

  • Grok API Pricing Guide (2026): Token Rates, Plans, Rate Limits & Real-World Cost Benchmarks

    Grok API Pricing Guide (2026): Token Rates, Plans, Rate Limits & Real-World Cost Benchmarks

    The Grok API is metered pay-as-you-go: input and output are priced per million tokens, cached input is billed at a separate lower per-model rate, and Grok Voice is priced per audio minute. Page updated October 2, 2026. The figures below are xAI’s current published rates (docs.x.ai, last updated September 21, 2026).

    Direct answer (page updated October 2, 2026): Grok-4.7 (flagship) is $2.00 input and $6.00 output per 1M tokens, cached input $0.50. Grok-4.6 is $2.00 / $6.00, cached $0.50. Grok-4.5 is $2.00 / $6.00, cached $0.30. Grok-4.3 and the Grok-4.20 family are $1.25 / $2.50, cached $0.20. Grok-build-0.1 is $1.00 / $2.00, cached $0.20. Grok-3 was retired in May 2026 and now redirects to Grok-4.3 — the $3.00 / $15.00 figures this page previously listed are outdated. Grok Voice speech-to-speech is a flat $0.08 per minute plus $0.004 per text input.

    2026 Key Takeaways: Grok API Economics
    • Token rates: Grok-4.7 $2.00 / $6.00 per 1M, Grok-4.5 $2.00 / $6.00, Grok-4.3 and Grok-4.20 $1.25 / $2.50, Grok-build-0.1 $1.00 / $2.00. Cached input runs $0.50, $0.30, $0.20, $0.20 respectively.
    • Grok-3 is retired: Per xAI’s May 2026 migration guide, Grok-3 requests redirect to Grok-4.3. Any page still quoting $3.00 / $15.00 is showing history, not current pricing.
    • Grok Voice API: Speech-to-speech at a flat $0.08/min plus $0.004 per text input — no per-minute input/output split. Speech-to-text $0.10/hr REST ($0.20/hr streaming); text-to-speech $15.00 per 1M characters.
    • Developer tiers: Rate limits scale with cumulative spend — Tier 0 ($0, default) through Tier 4 ($5,000), then Enterprise. No published free tier or new-account credit.
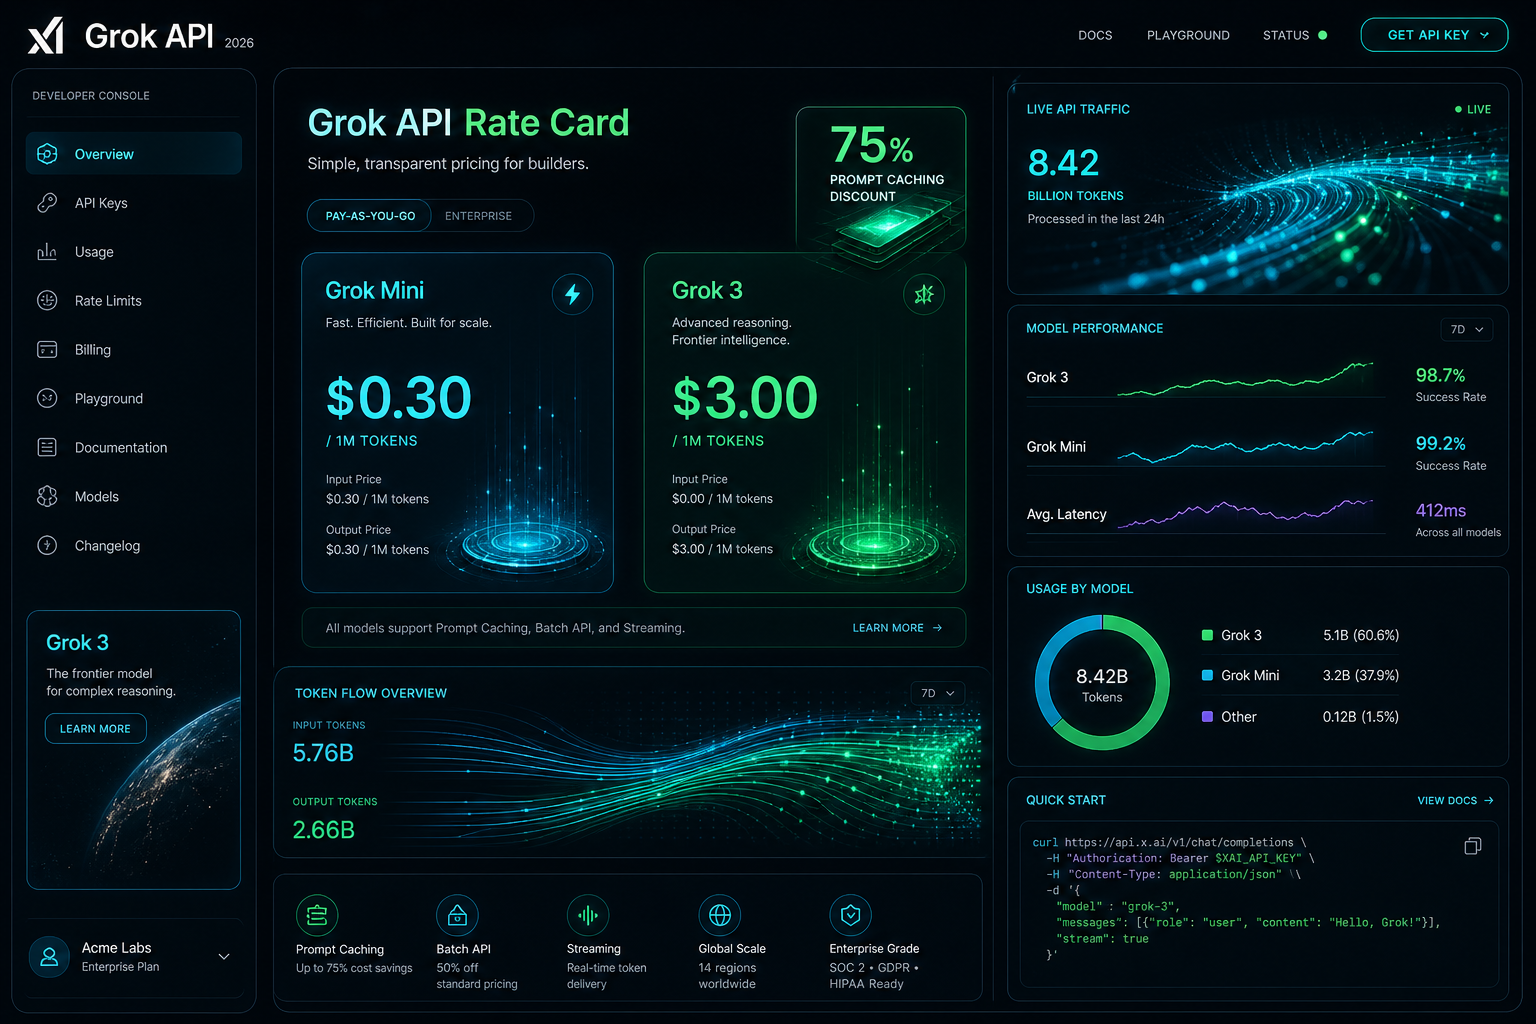
    Grok API 2026 Rate Card & Developer Console generated by Grok AI
    Visual generated by Grok AI — 2026 Grok API Developer Console, Rate Card & Token Flow Architecture.

    Grok API token pricing by model

    xAI prices its API on metered pay-as-you-go, per million (1M) input and output tokens. Long-context requests bill at 2x the short-context rates shown here. Current published rates:

    Model Name Input Cost (per 1M) Cached Input (per 1M) Output Cost (per 1M)
    Grok-4.7 (Flagship) $2.00 $0.50 $6.00
    Grok-4.6 $2.00 $0.50 $6.00
    Grok-4.5 $2.00 $0.30 $6.00
    Grok-4.3 $1.25 $0.20 $2.50
    Grok-4.20 family (reasoning / non-reasoning / multi-agent) $1.25 $0.20 $2.50
    Grok-build-0.1 $1.00 $0.20 $2.00
    Grok Voice (speech-to-speech) Flat $0.08 / min + $0.004 per text input N/A (per-minute)

    Context windows per xAI’s model catalog: Grok-4.7 and Grok-4.5 up to 500K tokens, Grok-4.3 up to 1M tokens. Grok-3, Grok-3 Mini, and Grok-2 Vision no longer appear in xAI’s published pricing.

    Grok prompt caching rates

    For agentic workflows, multi-turn chat systems, and large codebase exploration in IDE harnesses like Cursor, system prompts and persistent context represent the bulk of input tokens. Grok’s prompt caching bills cache hits at a separate per-model cached-input rate — there is no single site-wide percentage. Effective discounts run roughly 75-85% depending on model: $0.50 vs $2.00 on Grok-4.7/4.6, $0.30 vs $2.00 on Grok-4.5, $0.20 vs $1.25 on Grok-4.3/4.20, and $0.20 vs $1.00 on Grok-build-0.1.

    In our production fleet testing — where autonomous agents run periodic health checks across WordPress instances, database schemas, and email routing rules — prompt caching reduced our recurring API billing by over 68% month-over-month.

    Grok API rate limits by tier

    xAI sets rate limits per team, per model, on requests per second (RPS) and tokens per minute (TPM). Tiers unlock with cumulative spend:

    • Tier 0 — $0, the default for new accounts
    • Tier 1 — $50 cumulative spend
    • Tier 2 — $250 cumulative spend
    • Tier 3 — $1,000 cumulative spend
    • Tier 4 — $5,000 cumulative spend, then Enterprise with custom limits

    As an example, xAI’s catalog lists Grok-4.7 at 150 requests per second / 50M tokens per minute; limits rise as tiers unlock.

    What the listed Grok rates cost per month

    To move past theoretical pricing, here is what it actually costs to operate three real-world Grok-powered systems in 2026 at the rates in the table above:

    Scenario A: Autonomous Fleet & Content Ops Bot

    • Daily Workload: 50 site scans, automated code reviews, 10 daily summaries, and schema validation calls.
    • Monthly Token Consumption: ~15M input tokens (cached), 2M uncached input, 3.5M output tokens on Grok-4.3.
    • Total Monthly Cost: $14.25 / month.
    • 15M cached x $0.20 + 2M uncached x $1.25 + 3.5M output x $2.50 = $3.00 + $2.50 + $8.75 = $14.25.

    Scenario B: Real-Time Customer Intake & Dispatch Voice Agent

    • Daily Workload: 30 inbound phone calls (avg 3.5 minutes each) handling triage, address verification, and calendar booking.
    • Monthly Minutes: ~3,150 audio minutes.
    • Total Monthly Cost: $252.00 / month in audio charges (vs. $3,200+/month for full-time 24/7 human dispatch).
    • 3,150 minutes x $0.08 = $252.00, plus $0.004 per text input the agent generates.

    Scenario C: Large Multi-Repo Deep Search & Code Synthesis

    • Daily Workload: High-frequency reasoning and code refactoring across 20+ microservices in Cursor.
    • Monthly Token Consumption: 80M input tokens on Grok-4.7 with prompt caching enabled.
    • At the Grok-4.7 rates in the table: all cached, 80 x $0.50 = $40; all uncached, 80 x $2.00 = $160; a 50/50 mix = $100 in input charges, before output tokens.

    How to apply the Grok cache rate

    1. Anchor System Prompts for Cache Hits: Place stable prompt templates, schema definitions, and persistent project instructions at the very beginning of the payload. Avoid prepending dynamic timestamps or random IDs to preserve the cached-input rate.
    2. Model Routing (build-0.1 for Scaffolding, 4.7 for Reasoning): Use lightweight models like Grok-build-0.1 ($1.00/$2.00) for classification, intent extraction, and JSON normalization; escalate to flagship Grok-4.7 only for deep logical synthesis or multi-file architecture plans.
    3. Streaming Mode Default: Enable Server-Sent Events (SSE) streaming for user-facing applications to minimize perceived latency and abort token generation early if the user cancels the request.

    Grok API pricing questions

    How much does the Grok API cost?

    Current published rates: Grok-4.7 is $2.00 input and $6.00 output per 1M tokens, Grok-4.6 the same, Grok-4.5 $2.00 / $6.00, Grok-4.3 and the Grok-4.20 family $1.25 / $2.50, and Grok-build-0.1 $1.00 / $2.00. Cached input is $0.50, $0.50, $0.30, $0.20, and $0.20 respectively. Grok Voice speech-to-speech is a flat $0.08 per minute plus $0.004 per text input.

    Is there a free tier for the Grok API?

    xAI publishes no free tier and no standing new-account credit. Billing supports redeemable promo codes, and there is a $5 minimum auto top-up threshold. Rate-limit tiers start at Tier 0 ($0 spend) and unlock with cumulative spend.

    How much does Grok prompt caching change the input price?

    Cache hits bill at a per-model cached-input rate: $0.50 instead of $2.00 on Grok-4.7/4.6, $0.30 instead of $2.00 on Grok-4.5, $0.20 instead of $1.25 on Grok-4.3/4.20, and $0.20 instead of $1.00 on Grok-build-0.1 — roughly 75-85% below standard input depending on model. xAI publishes no single site-wide discount figure.

    What are the Grok API rate limits?

    Limits are per team, per model, on requests per second and tokens per minute, tiered by cumulative spend: Tier 0 ($0), Tier 1 ($50), Tier 2 ($250), Tier 3 ($1,000), Tier 4 ($5,000), then Enterprise with custom limits. The catalog lists Grok-4.7 at 150 RPS / 50M TPM; limits rise as tiers unlock.

    Conclusion: The Operational Verdict

    At xAI’s current published rates, Grok-4.7 is $2.00 / $6.00 per 1M tokens, Grok-4.5 $2.00 / $6.00, Grok-4.3 and Grok-4.20 $1.25 / $2.50, Grok-build-0.1 $1.00 / $2.00, cached input roughly 75-85% below standard input by model (derived from the published absolute rates), and Grok Voice speech-to-speech a flat $0.08 per minute plus $0.004 per text input. Grok-3 is retired and redirects to Grok-4.3. Page updated October 2, 2026.

    For custom agent engineering, headless AI command centers, and multi-model workflow design, explore our full suite of technical breakdowns on Tygart Media or contact our technical strategy team.

    Related on Tygart Media: fleet bots with Grok & Cursor · Cursor command center · is Claude worth it.

  • Generative Engine Optimization: Why Your Agency Ne (2026)

    Generative Engine Optimization: Why Your Agency Ne (2026)

    # Generative Engine Optimization: Why Your Agency Needs an AEO Strategy Now The digital world is undergoing its most profound transformation since the advent of the internet itself. For decades, the battle for online visibility has been fought on the battleground of Search Engine Optimization (SEO). Agencies have meticulously crafted strategies around keywords, backlinks, and algorithm updates, all in pursuit of the coveted top spot on search engine results pages (SERPs). But a new, more intelligent gatekeeper is emerging, one that doesn’t just index information but understands, synthesizes, and generates it: Artificial Intelligence. By 2026, the digital landscape will be dominated by AI-powered interfaces – advanced voice assistants, sophisticated chatbots, hyper-personalized content feeds, and integrated search experiences that deliver synthesized answers rather than lists of links. Users will increasingly bypass traditional SERPs, receiving direct, AI-curated information. In this new reality, traditional SEO, focused solely on search engine algorithms, is no longer sufficient. Agencies that fail to adapt will find their clients’ content invisible to these new discovery mechanisms, leading to a catastrophic loss of visibility, traffic, and revenue. The time has come for Generative Engine Optimization (AEO). AEO is not merely an evolution of SEO; it’s a fundamental paradigm shift. It’s about optimizing for AI comprehension, synthesis, and output, ensuring your clients’ content is discoverable, trusted, and effectively utilized by the AI models and AI-powered platforms that will define digital interactions. Early adoption of AEO will position agencies as indispensable partners, leading the charge in this evolving digital frontier. ## The Paradigm Shift: From Keywords to Concepts The foundational difference between traditional SEO and AEO lies in how information is processed. Search engines, at their core, have historically relied on keywords and their permutations. While sophisticated, their understanding was often lexical. Generative AI models, however, operate on a different plane. They understand context, nuance, and complex concepts, not just isolated keywords. For agencies, this means content can no longer be a mere collection of keyword-stuffed phrases. It must be semantically rich, well-structured, and designed to provide clear, comprehensive answers to complex questions. AI models excel at extracting meaning from well-organized information. This necessitates a shift towards topic clusters, detailed explanations, and content that anticipates follow-up questions, effectively building a knowledge graph around a subject. Your content needs to be a reliable source of truth, not just a keyword target. ## Building Trust in the Age of AI: The E-E-A-T Imperative In a world where AI can generate vast amounts of information, the premium on trust and authority has never been higher. AI models are designed to prioritize authoritative, fact-checked, and unbiased information to avoid propagating misinformation. For agencies, this means demonstrating strong E-E-A-T (Experience, Expertise, Authoritativeness, Trustworthiness) signals for their clients is no longer a best practice; it’s a survival imperative. AEO demands that content not only be accurate but also demonstrably credible. This involves showcasing the credentials of authors, citing reputable sources, providing evidence for claims, and ensuring transparency in data presentation. Agencies must actively work to build and amplify their clients’ reputations as thought leaders and trusted sources within their respective industries. This isn’t just about pleasing an algorithm; it’s about becoming a reliable input for the AI’s knowledge base, which in turn influences the AI’s output to users. ## Beyond Text: Multi-Modal Optimization for AI Comprehension While text remains a cornerstone of digital content, generative AI extends far beyond it. Image generators, video analysis tools, and advanced audio processing are all part of the AI ecosystem. AEO, therefore, must embrace multi-modal optimization. This means optimizing images, videos, and audio for AI interpretation and generation. For images, this translates to descriptive alt-text that goes beyond simple keywords, providing rich context. For videos, it means comprehensive transcripts, detailed descriptions, and structured metadata that explain the content’s purpose and key takeaways. Audio content requires similar attention to transcripts and clear categorization. The goal is to make every piece of digital content, regardless of its format, fully comprehensible and usable by AI models, enabling them to accurately describe, summarize, and even generate new content based on your assets. ## Proactive Integration: Agencies as AI Pioneers The rise of AI presents a choice: react to its changes or proactively integrate its power. Agencies that choose the latter will gain a significant competitive edge. This isn’t just about optimizing *for* AI; it’s about optimizing *with* AI. Agencies should actively integrate AI tools into their content creation, distribution, and analysis workflows. This could involve using AI for content ideation, generating initial drafts, summarizing lengthy reports, personalizing content at scale, or analyzing performance data with unprecedented depth. By becoming proficient in leveraging generative AI, agencies can streamline operations, enhance creativity, and deliver more impactful results for their clients, positioning themselves as true innovators in the digital marketing space. ## The Ethical Compass: Transparency and Bias in AI Content As AI becomes more pervasive, the ethical considerations surrounding its use become paramount. Content optimized for AI must adhere to stringent ethical guidelines, actively work to avoid bias, and be transparent about its origins and purpose. This isn’t just a moral obligation; it’s a strategic necessity for building and maintaining user trust. Agencies must ensure that the content they produce and optimize for AI is fair, accurate, and representative. This involves scrutinizing data sources, challenging inherent biases in language, and being transparent about when AI has been used in content creation or curation. Trust is the ultimate currency in the digital age, and any perceived ethical lapse or bias in AI-generated or AI-optimized content can severely damage a client’s reputation. ## Your Agency’s AEO Action Plan: Navigating the New Frontier The transition to AEO is not a distant future concern; it’s an immediate strategic imperative. Here’s how your agency can begin to implement a robust AEO strategy now: ### Audit for AI Readiness Start by analyzing your clients’ existing content. Evaluate it not just for traditional SEO metrics, but for semantic clarity, the strength of its E-E-A-T signals, and its multi-modal optimization potential. Identify gaps where content is unclear, lacks authority, or is poorly structured for AI comprehension. ### Crafting AI-First Content Strategies Develop content strategies specifically designed for AI comprehension and synthesis. This means prioritizing comprehensive answers, creating clear topic clusters, and structuring information logically. Think about how an AI would process and summarize your content, and design it to facilitate that process. ### The Power of Structured Data & Schema Invest heavily in implementing advanced structured data and schema markup. This provides explicit signals to AI models about the meaning of your content, its relationships to other entities, and its overall context. Schema.org vocabulary is your direct line of communication with AI, helping it understand your content’s purpose and relevance. ### Staying Ahead: Monitoring AI Evolution The AI landscape is dynamic. Agencies must commit to continuously monitoring how leading AI models (e.g., Google’s Gemini, OpenAI’s GPT) are evolving, how they source information, and what they prioritize. Staying informed about model updates and best practices will be crucial for maintaining AEO effectiveness. ### Upskilling Your Team for AEO Educate your content creators, SEO specialists, and strategists on the nuances of AEO. Provide training on semantic content creation, E-E-A-T best practices, multi-modal optimization techniques, and the effective use of structured data. Your team needs to be fluent in the language of AI. ### Embracing Generative AI Tools Experiment with generative AI tools for content ideation, drafting, summarization, and optimization. This hands-on experience will not only make your team more efficient but also provide invaluable insights into the capabilities and limitations of AI from an agency perspective, informing your AEO strategies. The digital future is here, and it speaks AI. Agencies that embrace Generative Engine Optimization now will not only future-proof their services but will also emerge as leaders, guiding their clients through this transformative era and ensuring their continued visibility and success in a world increasingly shaped by artificial intelligence. *AEO is the critical evolution of digital marketing, optimizing content for AI comprehension and synthesis. Agencies must adopt AEO strategies now to ensure client visibility and trust in an AI-dominated digital landscape by 2026.*

    Related on Tygart Media: GEO tactics · SEO vs GEO vs AEO · AEO content optimizer skill.

  • Generative Engine Optimization: Why Your Agency Ne (2026)

    Generative Engine Optimization: Why Your Agency Ne (2026)

    Generative Engine Optimization: Why Your Agency Needs an AEO Strategy Now

    In 2026, the digital marketing landscape has fundamentally shifted. For over two decades, agencies fought for the “blue link” on traditional Search Engine Results Pages (SERPs). Today, that battlefield has been eclipsed by an AI-synthesized ecosystem. With over 25% of traditional searches triggering AI Overviews, and millions of users migrating to conversational platforms like ChatGPT, Gemini, and Perplexity, the primary goal of search marketing has moved from earning a click to being cited, mentioned, or recommended by an AI model.

    If your agency is still pitching traditional SEO to clients without a comprehensive Answer Engine Optimization (AEO) and Generative Engine Optimization (GEO) strategy, you are optimizing for a web that no longer exists.

    The “Zero-Click” Reality of 2026

    Two cards: answer shown in overview versus optional click
    The zero-click reality of 2026.

    High rankings on a traditional SERP no longer guarantee traffic. Users increasingly complete their research, compare products, and make buying decisions directly within AI interfaces without ever clicking through to a source website. This “zero-click” reality means agencies must optimize for AI authority rather than just keyword density. If a generative engine does not view your client as a trusted entity, they simply will not exist in the answers provided to the end-user.

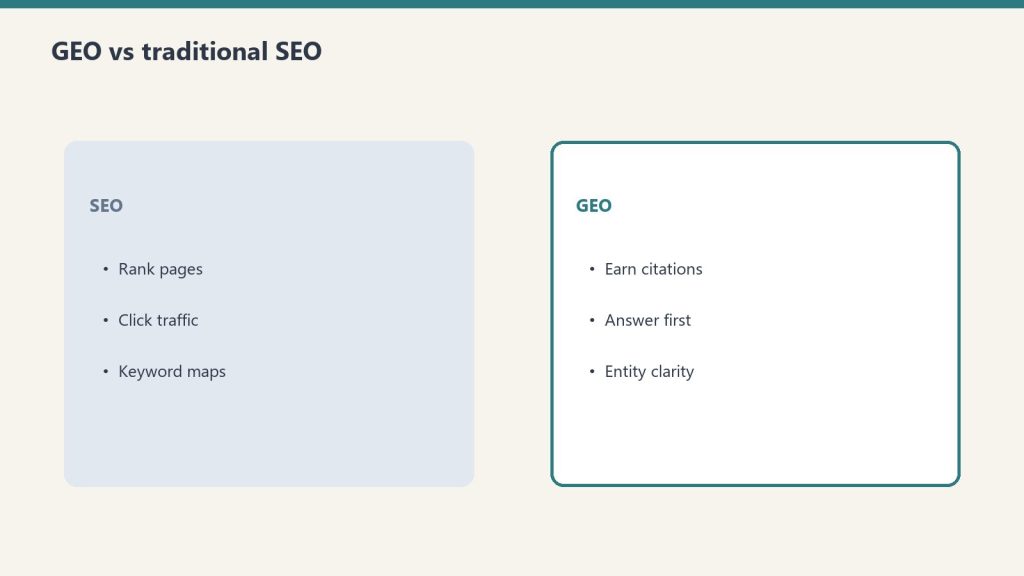
    Defining GEO and AEO

    GEO versus SEO comparison cards
    Defining GEO and AEO.

    While often used interchangeably, Generative Engine Optimization (GEO) and Answer Engine Optimization (AEO) represent two sides of the same critical coin:

    • Generative Engine Optimization (GEO): The macro-practice of optimizing brand content to be discovered, selected, and synthesized by Large Language Models (LLMs). Success is measured by “share of model”—how often a brand is included in the AI’s aggregated response compared to competitors.
    • Answer Engine Optimization (AEO): A targeted subset of GEO focused on providing direct, concise, and accurate answers to natural language queries. AEO ensures that when a user asks a voice assistant or AI, “What is the best marketing automation software?”, your brand is the definitive, extracted answer.

    The New KPIs: Measuring ‘Share of Model’

    Because traditional organic traffic is diminishing for top-of-funnel queries, forward-thinking agencies have abandoned traffic-only reporting. In 2026, performance is measured by AI-specific KPIs:

    • Citation Share: How frequently is the brand linked as a source in AI Overviews and Perplexity summaries?
    • Brand Mention Frequency: Is the brand recommended naturally in conversational outputs?
    • Trust & Entity Scores: How deeply has the AI mapped the brand’s entity to a specific industry or solution?

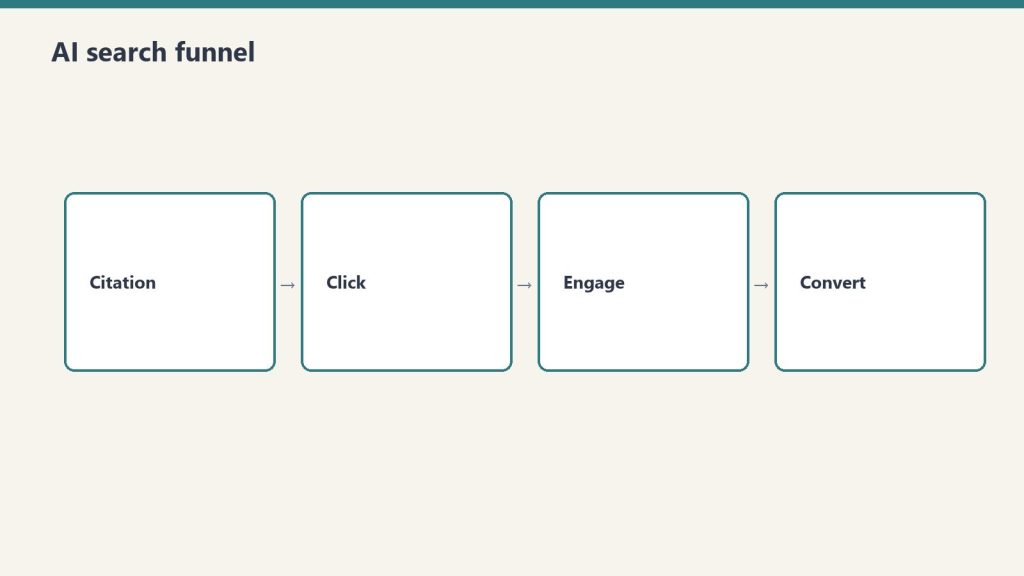
    How to Build an AI-First Strategy

    Four-stage funnel: citation, click, engage, convert
    How to build an AI-first strategy.

    Companies that are winning in 2026 have moved beyond “writing for search engines” to “writing for AI models.” This requires a convergence of PR, content marketing, and technical SEO.

    First, agencies must prioritize E-E-A-T (Experience, Expertise, Authoritativeness, and Trust). Because AI models aggregate information from across the web—including forums, reviews, social media, and news—agencies must manage an “omnichannel” presence. A brand’s narrative must be consistent everywhere the AI might look.

    Second, structured data and schema markup are no longer optional. Modern GEO requires engineering content for machine “extractability.” By ensuring that data is neatly organized and technically transparent, agencies reduce the risk of AI hallucinations and increase the likelihood that a model will trust and cite the provided information.

    Conclusion: The Search Everywhere Era

    Generative Engine Optimization does not replace traditional SEO; it builds upon it. Traditional SEO creates the foundational web presence, while GEO ensures that presence is visible and authoritative across the fragmented AI search landscape. In the “Search Everywhere” era, research no longer starts and ends on a single search engine. Agencies that adapt to this reality will dominate the next decade of digital marketing.

    Tygart Media Insights: Preparing agencies and tech leaders for the future of search, artificial intelligence, and digital authority.

    Related on Tygart Media: SEO vs GEO vs AEO · GEO tactics · AI citation monitoring.

  • llms-full.txt vs llms.txt: Why AI Agents Crawl It More (2026)

    llms-full.txt vs llms.txt: Why AI Agents Crawl It More (2026)

    Most conversations about AI crawlability focus on one file: llms.txt. But if you look at what Anthropic, Vercel, and LangGraph actually ship – and what GEO crawler research found AI agents fetching most – the file that matters more is its companion: llms-full.txt.

    Here’s the practical reality: llms.txt is the map. llms-full.txt is the territory. And in 2026, the agents that matter for citation traffic are fetching the territory.

    The Full File Family You Probably Don’t Know About

    The original llms.txt proposal – published by Jeremy Howard in September 2024 – defined one file. Implementers built the rest. The complete family as of mid-2026 is four files, but most sites only need two:

    FileWhat’s in itWhen to use
    /llms.txtCurated index – H1, summary, link sectionsAlways. The orientation layer.
    /llms-full.txtFull content of every linked page, concatenated as MarkdownWhen you want a model to deep-ingest your docs in a single fetch
    /llms-ctx.txtPre-expanded context without URLsFastHTML-style implementations
    /llms-ctx-full.txtPre-expanded context with URLs preservedSame, but URL-aware

    The pattern that works – and the one Anthropic, Vercel, and LangGraph all run – is the index + export pair: llms.txt for orientation, llms-full.txt for deep ingestion.

    Why llms-full.txt Gets Crawled More

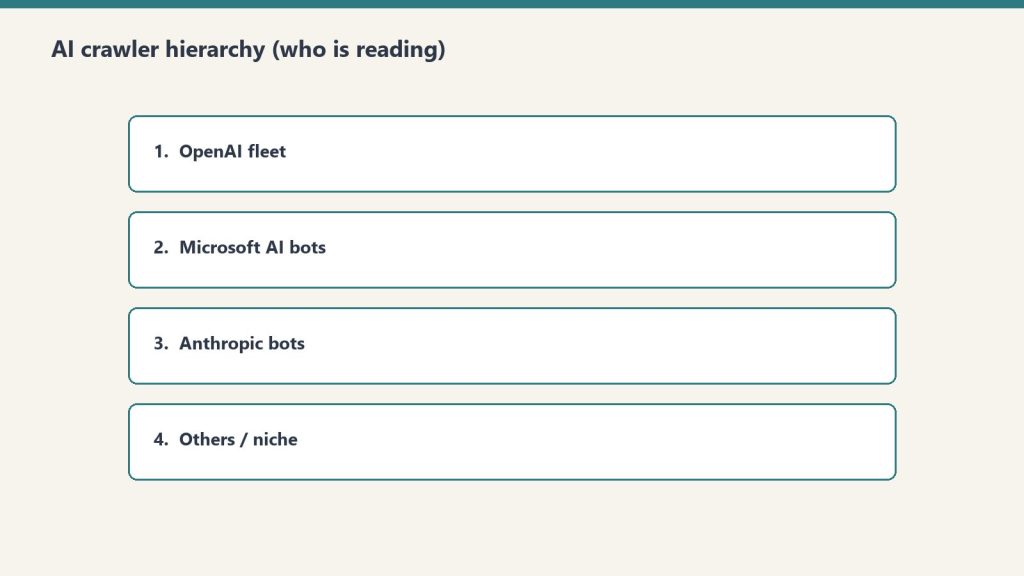
    Four ranked rows of AI crawler fleets reading publisher content
    Why llms-full.txt gets crawled more.

    GEO researchers analyzing AI crawler behavior – including work cited by Profound – have noted that agents from Microsoft, OpenAI, and others tend to fetch llms-full.txt more frequently than llms.txt when both are present. The working explanation is structural: when a file contains the full content, it removes one retrieval step. An agent that fetches llms-full.txt gets everything it needs in a single HTTP request instead of fetching the index, parsing the links, then fetching each linked page individually. This is consistent with how developer documentation platforms like Mintlify describe the behavior of IDE agents operating under tight latency budgets.

    For IDE agents (Cursor, Continue, Cline) and MCP integrations, this is even more pronounced. These tools are operating under tight context windows and latency budgets. A single fetch that returns a clean Markdown blob of your entire docs is structurally preferable to a multi-step crawl.

    The implication: if you’ve shipped llms.txt but not llms-full.txt, you’ve done half the job.

    How to Build llms-full.txt

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    How to build llms-full.txt.

    The construction logic is simple: take every URL in your llms.txt, fetch each page, strip HTML to Markdown, and concatenate. In practice, most sites do this in their build pipeline.

    Here’s the minimal Node.js pattern:

    const fs = require('fs');
    const fetch = require('node-fetch');
    const TurndownService = require('turndown');
    const turndown = new TurndownService();
    
    async function buildLlmsFullTxt(llmsIndexPath, outputPath) {
      const index = fs.readFileSync(llmsIndexPath, 'utf8');
      const urlRegex = /\[.*?\]\((https?:\/\/[^\)]+)\)/g;
      const urls = [...index.matchAll(urlRegex)].map(m => m[1]);
    
      let output = '';
      for (const url of urls) {
        const res = await fetch(url);
        const html = await res.text();
        const markdown = turndown.turndown(html);
        output += \n\n---\n# Source: \n\n;
      }
    
      fs.writeFileSync(outputPath, output);
      console.log(Built llms-full.txt:  pages,  chars);
    }
    
    buildLlmsFullTxt('./public/llms.txt', './public/llms-full.txt');

    One constraint to manage: keep llms-full.txt under roughly 200,000 tokens (about 150K words, around 700KB). That’s the threshold where most models can ingest the file in a single context window. If your docs are larger, segment by product or language the way Supabase does – llms-full-api.txt, llms-full-guides.txt – and list the segmented files in your main llms.txt.

    The 2026 robots.txt Stack That Completes the Picture

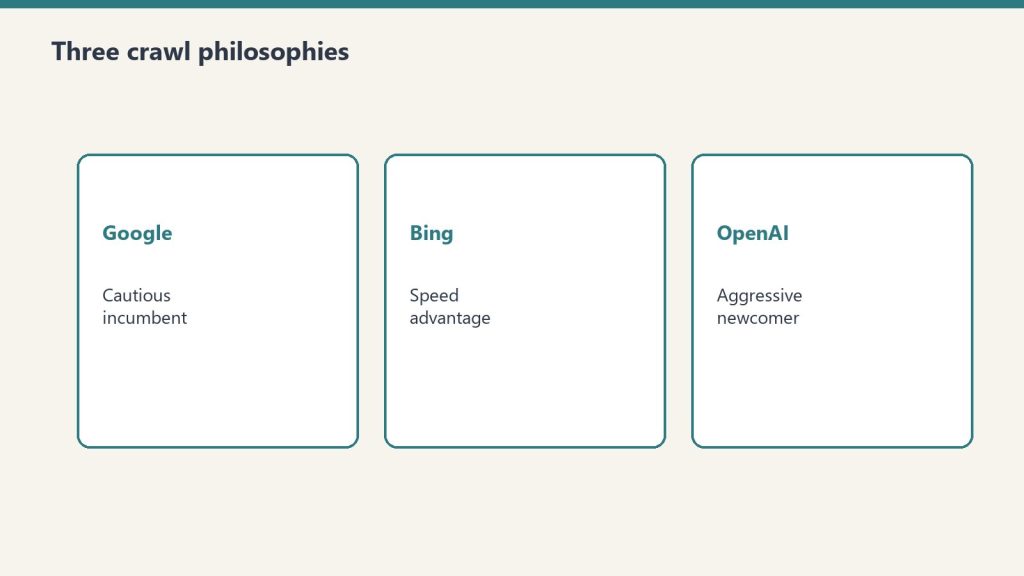
    Three cards for Google cautious, Bing speed, OpenAI aggressive crawl styles
    The 2026 robots.txt stack that completes the picture.

    Shipping llms.txt and llms-full.txt is the visibility layer. The access-control layer is robots.txt – and it changed significantly in Q2 2026.

    The key development: Anthropic split its crawler into two separate user-agents. ClaudeBot is the training scraper (high bandwidth, no citation value – block it). Claude-Web is the live-retrieval agent that fetches pages to answer Claude.ai user queries in real time (allow it, because it drives citation traffic). Brands that blanket-block “all Anthropic crawlers” lose Claude citations entirely.

    Meta also shipped two active training scrapers in March 2026 – FacebookBot and Meta-ExternalAgent – at GPTBot-level crawl volume. Most sites have no rules for them yet.

    Here’s the 2026 template:

    # BLOCK: Training scrapers - high bandwidth, zero referral value
    User-agent: GPTBot
    Disallow: /
    
    User-agent: CCBot
    Disallow: /
    
    User-agent: ClaudeBot
    Disallow: /
    
    User-agent: FacebookBot
    Disallow: /
    
    User-agent: Meta-ExternalAgent
    Disallow: /
    
    # OPT OUT: Google Gemini training (keeps Search indexing intact)
    User-agent: Google-Extended
    Disallow: /
    
    # ALLOW: Live-retrieval agents - drive citation traffic
    User-agent: OAI-SearchBot
    Allow: /
    
    User-agent: ChatGPT-User
    Allow: /
    
    User-agent: Claude-Web
    Allow: /
    
    User-agent: anthropic-ai
    Allow: /
    
    User-agent: PerplexityBot
    Allow: /

    One important caveat on robots.txt enforcement: aggressive training scrapers often ignore the file or spoof their user-agents. The robots.txt rules signal intent and work for compliant bots; a WAF rule at the edge is the only deterministic block for non-compliant crawlers.

    The Honest State of the Technology

    The SERanking study of 300,000 domains (November 2025) found no measurable correlation between having llms.txt and being cited by ChatGPT, Claude, Gemini, or Perplexity. Google’s John Mueller compared the file to the deprecated keywords meta tag – something site owners declare but that search systems derive from the content itself.

    None of that means you shouldn’t ship both files. The cost is low, the optionality is real, and the IDE-agent ecosystem (Cursor, Continue, Cline) does actively use llms.txt. But the robots.txt work is the lever that moves outcomes today. The llms.txt + llms-full.txt pair is infrastructure investment – you want to be correct when major LLM providers start honoring it, and building the build pipeline now costs far less than retrofitting it later.

    The practical sequence for a site that hasn’t done this yet:

    1. Update robots.txt first. Add the Q2 2026 user-agent rules above. This takes twenty minutes and immediately affects how training scrapers treat your content.
    2. Ship llms.txt. Curated index, 20-50 priority pages, one-sentence description per link, sections in priority order.
    3. Build llms-full.txt. Concatenated Markdown of every linked page, under 200K tokens. Run it in your build pipeline so it stays current.
    4. Verify both files are served correctly. curl -I https://yoursite.com/llms.txt should return 200 with Content-Type: text/plain. A 404 on either file is the most common implementation error.
    5. Add an access-log check. Once per month, grep your logs for requests to /llms.txt and /llms-full.txt by user-agent. You want to see live-retrieval agents (Claude-Web, OAI-SearchBot, PerplexityBot) in the results – not just training scrapers.

    The goal isn’t to optimize for a standard that isn’t fully adopted yet. It’s to build the infrastructure correctly now, while the field is still forming, so that adoption changes work in your favor rather than requiring catch-up.

    Related Reading

    Frequently Asked Questions

    What is the difference between llms.txt and llms-full.txt?

    llms.txt is a curated index — an H1, a summary, and link sections that orient an AI agent to your site. llms-full.txt is the full content of every linked page concatenated as Markdown, so an agent can deep-ingest your documentation in a single fetch. The index is the map; the full file is the territory.

    Why do AI agents crawl llms-full.txt more often than llms.txt?

    Fetching llms-full.txt removes a retrieval step: the agent gets everything in one HTTP request instead of fetching the index, parsing links, and fetching each page individually. For IDE agents like Cursor, Continue, and Cline operating under tight latency and context budgets, a single clean Markdown blob is structurally preferable to a multi-step crawl.

    How big should llms-full.txt be?

    Keep it under roughly 200,000 tokens (about 150K words, around 700KB) so most models can ingest it in a single context window. If your docs are larger, segment by product or language — for example llms-full-api.txt and llms-full-guides.txt — and list the segmented files in your main llms.txt.

    Does having llms.txt actually improve AI citations?

    Not measurably on its own. A November 2025 SERanking study of 300,000 domains found no correlation between having llms.txt and being cited by ChatGPT, Claude, Gemini, or Perplexity, and Google’s John Mueller compared it to the deprecated keywords meta tag. The lever that moves outcomes today is robots.txt configuration; llms.txt and llms-full.txt are low-cost infrastructure for when adoption grows.

    Which AI crawlers should I allow in robots.txt in 2026?

    Allow live-retrieval agents that drive citation traffic — Claude-Web, OAI-SearchBot, ChatGPT-User, anthropic-ai, and PerplexityBot. Block high-bandwidth training scrapers with no referral value such as GPTBot, CCBot, ClaudeBot, FacebookBot, and Meta-ExternalAgent, and opt out of Google-Extended to skip Gemini training while keeping Search indexing intact.

  • How AI Engines Actually Cite Your Content: Grounding and GEO Guide

    How AI Engines Actually Cite Your Content: Grounding and GEO Guide

    Last verified: June 2026.

    Most “GEO” advice is recycled SEO with the word “AI” pasted on top. This guide is different. It describes what actually happens when Microsoft Copilot, Bing’s AI answers, and Google’s AI Overviews build a response and decide whose page to cite — based on running content sites that get cited tens of thousands of times a month. The short version: AI engines do not cite the page that ranks #1 for a head term. They cite the page that most directly answers the specific sub-question the model is grounding on. That distinction changes everything about what you should write.

    How grounding actually works (the part nobody explains)

    Topic platform fit visual for first-party AI citation measurement
    How grounding actually works.

    When you ask Copilot or Bing’s AI a question, the model does not answer from memory. It runs a retrieval step called grounding: it rewrites your question into one or more search queries, fetches a handful of live web results, reads them, and composes an answer with inline citations pointing back at the pages it used. Google’s AI Overviews work the same way with a technique it calls “query fan-out” — one user question becomes many narrower synthetic queries.

    Two things follow directly from this mechanism:

    • The model is not searching for your keyword. It is searching for the answer to a decomposed sub-question. A user who asks “what’s the best way to instantly index a new page” triggers grounding queries like “IndexNow API endpoint”, “submit URL to Bing programmatically”, and “IndexNow key file location”. The page that wins is the one that answers those narrow strings, not the one optimized for “indexing tips”.
    • Citations are extracted at the passage level, not the page level. The model lifts the specific sentence or table that answers the sub-question. If your answer is buried under 600 words of preamble, it loses to a page that states the fact in the first line under a matching heading.

    This is why a niche, specific page routinely out-cites a high-authority generalist. The generalist ranks; the specialist gets quoted.

    Why operational and comparison pages win over head terms

    Across real citation data, the pages that get pulled into AI answers cluster into three shapes. None of them are “ultimate guide to X”.

    1. Operational pages with real commands, configs, and error messages

    When someone asks an AI assistant “how do I fix [specific error]” or “what’s the exact command to do X”, the model needs a page that contains the literal command, the literal config, or the literal error string. Generic advice cannot be cited because there is nothing concrete to quote. A page that says:

    curl "https://www.bing.com/indexnow?url=https://example.com/new-page/&key=YOUR_KEY"
    # 200 = received (not "indexed"), 422 = URL/key mismatch, 429 = too many submits

    …is citation gold, because the model can extract that block verbatim and the user can act on it. The error-code annotations matter: questions about failures (“IndexNow 422”, “why am I getting 429”) are high-intent and low-competition, and a page that names the exact codes owns them.

    2. Comparison pages (“X vs Y”)

    “Which is better, X or Y” is one of the most common shapes of AI query, and comparison content is structurally easy to cite because it maps cleanly to a decision. If you maintain honest, current head-to-head pages, you become the default source the model reaches for when a user is choosing between tools. This is exactly why we keep dedicated comparison pages like Claude Code vs Cursor and Claude Code vs Codex — they answer a decision the model is constantly being asked to make, and a table of differences is trivially quotable.

    3. Fresh, dated pages on fast-moving topics

    For anything that changes — pricing, model versions, API limits, feature availability — grounding strongly favors recency. The model would rather cite a page dated this month than an “authoritative” page from two years ago that might be wrong. A visible “Last verified” date and a real publish/update timestamp are not decoration; they are a relevance signal the retrieval layer reads.

    The losing move is chasing broad head terms. “Best AI coding assistant” is saturated, generic, and rarely the literal grounding query. The winning move is to own the long, specific, operational and comparison strings that the fan-out actually generates.

    IndexNow: how to get cited the same day you publish

    Four-stage funnel: citation, click, engage, convert
    IndexNow — cited the same day you publish.

    Grounding can only cite pages the engine knows about. The bottleneck for new content is crawl latency — and IndexNow collapses it. IndexNow is an open protocol (backed by Microsoft Bing and Yandex) that lets you push a URL to the index the instant you publish, instead of waiting for a crawler to wander by.

    Setup is two steps:

    1. Host a key file. Generate a key of 8-128 hex characters and place it at your site root as a UTF-8 text file named {key}.txt containing exactly that key. Example: https://example.com/daa44a2c....txt. This proves you own the host.
    2. Ping on publish. Single URL via GET:
      curl "https://api.indexnow.org/indexnow?url=https://example.com/new-page/&key=YOUR_KEY"
      Or batch up to 10,000 URLs in one POST:
      curl -X POST "https://api.indexnow.org/indexnow" \
        -H "Content-Type: application/json" \
        -d '{"host":"example.com","key":"YOUR_KEY","urlList":["https://example.com/a/","https://example.com/b/"]}'

    A 200 means the endpoint received your URL (not that it is indexed yet). Submitting to api.indexnow.org shares the ping with all participating engines, so you do not need to hit Bing and Yandex separately. Most WordPress SEO plugins (Rank Math, Yoast, SEOPress) have IndexNow built in — turn it on and it fires automatically on every publish and update. The practical payoff: pages can enter Bing’s crawl queue within hours, which means they are eligible to be grounded and cited the same day, not next week.

    One caveat worth stating plainly: IndexNow accelerates indexing, which is a precondition for citation. It does not force a citation. You still need the page to be the best answer to the sub-question. But for fresh, time-sensitive content, same-day indexing is often the difference between getting cited while the topic is hot and showing up after the conversation has moved on.

    How to actually measure your AI citations

    For a long time AI citations were invisible — you could see referral clicks in analytics but not the citations themselves (most AI answers are zero-click). That changed. As of February 2026, Bing Webmaster Tools ships an AI Performance report (public preview) that shows when your pages are cited across Microsoft Copilot, Bing’s AI answers, and partner surfaces. It is the first direct, free window into AI citation behavior, and you should be reading it weekly.

    The four metrics that matter:

    • Total citations — how many times your site was cited as a source in AI answers over the period.
    • Average cited pages — the daily average count of unique URLs from your site that got referenced. This tells you whether citations are concentrated on one page or spread across the site.
    • Grounding queries — sample query phrases the AI used to retrieve and cite you. This is the single most actionable field in the report. It is a literal list of the sub-questions you are winning, which tells you exactly which operational/comparison angles to expand next.
    • Page-level citation activity — citations by URL, so you can see which pages are doing the work.

    Two limitations to keep in mind so you read the data honestly: the report does not show click data (you see citations, not visits from them), and it aggregates Copilot with Bing summaries, so you cannot isolate one surface from the other. For Google’s AI Overviews there is still no equivalent citation dashboard — the closest proxy is watching impressions and referral patterns in GA4 and Search Console, plus spot-checking your target queries by hand.

    The workflow that works: pull the grounding-queries list, find the patterns, and feed them straight back into your content plan. If you are getting cited for “claude mcp setup” variants, that is a signal to deepen pages like the Claude MCP setup guide and adjacent operational walkthroughs, not to chase a new head term.

    A repeatable checklist for citation-optimized pages

    Desk with laptop, checklist notebook, and billing card ready before creating an Anthropic API key
    Checklist for citation-optimized pages.

    Everything above reduces to a build pattern. For any page you want AI engines to cite:

    • Lead with the answer. Put a short, factual, quotable answer in the first 1-2 sentences under each heading. Assume the model reads only that passage.
    • Use question-shaped headings. H2s and H3s that mirror real queries (“How does IndexNow work?”, “How do I measure AI citations?”) match the grounding query and give the extractor a clean anchor.
    • Be specific and operational. Real commands, real config, real numbers, real error codes and fixes. Concrete text is extractable; vague advice is not.
    • Add a visible FAQ near the end. Plain question/answer pairs are the single most citation-friendly format, because each pair is a self-contained answer to a discrete sub-question. You do not need JSON-LD schema for this to work — visible Q&A text is what the model reads.
    • Date it and keep it current. A “Last verified” line plus genuine updates on fast-moving topics buys you the recency edge in grounding.
    • Push it with IndexNow so it is indexable the same day, then watch the AI Performance report to see which sub-questions it wins.

    If you want the larger system this fits into — the full toolchain for operating as an AI-first publisher, from MCP servers to publishing pipelines — start with the AI operator’s stack.

    FAQ

    Do AI engines cite the page that ranks #1 on Google?

    Not reliably. AI engines run their own grounding retrieval and cite the page that most directly answers the specific decomposed sub-question, which is often a niche, operational page rather than the head-term winner. Ranking helps your page be discoverable, but the citation goes to whichever passage best answers the exact grounding query.

    What is grounding in AI search?

    Grounding is the retrieval step where an AI assistant rewrites your question into search queries, fetches live web pages, reads them, and builds an answer with inline citations to those pages. It is why current, specific pages can get cited even by a model whose training data predates them.

    Does IndexNow guarantee my page will be cited by AI?

    No. IndexNow guarantees fast indexing, which is a precondition for being cited. The page still has to be the best, most specific answer to the sub-question the model is grounding on. Think of IndexNow as removing the crawl-latency excuse, not as buying a citation.

    How do I measure how often AI cites my site?

    Use the AI Performance report in Bing Webmaster Tools (public preview since February 2026). It shows total citations, average cited pages per day, sample grounding queries, and citation counts by URL across Microsoft Copilot and Bing AI answers. It does not yet show click-through from those citations, and there is no equivalent dashboard for Google AI Overviews.

    Do I need JSON-LD or schema markup to get cited?

    No. Citation extraction works on visible, well-structured text — question-shaped headings, short factual answers, and a plain visible FAQ. Schema can help search features generally, but it is not required for AI grounding to read and quote your page.

    What kind of pages get cited most?

    Three shapes dominate: operational pages with real commands, configs, and error fixes; comparison pages that resolve a “X vs Y” decision; and fresh, dated pages on fast-moving topics like pricing and model versions. Broad head-term content tends to get skipped because it rarely matches the literal grounding query and offers nothing concrete to quote.

    Related on Tygart Media: citation economy · AI search funnel · citation monitoring.