Last refreshed: May 15, 2026
Redirecting… Click here if not redirected
Related on Tygart Media: Dario Amodei · Jared Kaplan · Anthropic IPO.
Last refreshed: May 15, 2026
Redirecting… Click here if not redirected
Related on Tygart Media: Dario Amodei · Jared Kaplan · Anthropic IPO.
Last refreshed: May 15, 2026
On April 7, 2026, Anthropic published the Claude Mythos Preview to red.anthropic.com — its dedicated AI safety and security research channel. Mythos is described as a general-purpose model with breakthrough cybersecurity capability, anchoring a coordinated initiative called Project Glasswing aimed at reinforcing global cyber defenses using AI. It is the most significant security-focused model capability announcement Anthropic has made to date.
Mythos is not a separate product in the traditional sense — it’s a capability preview, published through Anthropic’s red team and security research channel rather than through the main product announcement pipeline. The “preview” framing is deliberate: Anthropic is signaling a new capability frontier to the security research community before making it broadly available, which is standard practice for capabilities with significant dual-use potential.
The “breakthrough cybersecurity capability” claim is notable because Anthropic has historically been conservative about capability claims. Publishing on red.anthropic.com — rather than anthropic.com/news — also signals that this is targeted at a security-professional audience, not a general consumer or enterprise announcement.
Project Glasswing is the coordinated effort that Mythos anchors. The stated mission is reinforcing world cyber defenses — a framing that positions Mythos explicitly as a defensive capability rather than an offensive one, which matters enormously in how it will be received by governments, enterprise security teams, and the security research community.
The name “Glasswing” references the glasswing butterfly — a species known for its transparent wings, which confer camouflage by blending into the environment. The metaphor maps cleanly onto defensive security work: visibility and transparency as the mechanism of protection, not opacity or force.
Mythos and Glasswing don’t come from nowhere. Anthropic’s security research track in 2026 has been unusually active: collaboration on Firefox CVE-2026-2796 in March, LLM-discovered zero-days published in February, and participation in AI on realistic cyber ranges in January — all documented on red.anthropic.com. Mythos is the capstone of a year-long research buildout in applied cybersecurity, not a pivot from Anthropic’s core safety work.
For enterprise security teams evaluating AI vendors, this track record is a meaningful differentiator. Anthropic is now the only frontier AI lab with a documented, published history of responsible vulnerability disclosure collaboration and a dedicated security research publication channel. That institutional credibility matters when procurement decisions involve sensitive security workflows.
The Mythos Preview is the beginning of a story, not the end of one. Watch red.anthropic.com for the full Glasswing rollout cadence — what specific defensive capabilities are being published, what the access model looks like for security researchers, and whether government or critical infrastructure partnerships accompany the broader release. The preview framing implies a production release is coming. The timeline and access model will define how significant Glasswing becomes as a competitive differentiator.
Source: red.anthropic.com — Claude Mythos Preview
Related on Tygart Media: Claude Mythos / Firefox · GPT-5.5 vs Claude Mythos · Claude security scanner.
Related on Tygart Media: what Notion AI agents are · Claude vs Notion AI · how to use Claude.
You don’t have to pick the model anymore. Notion 3.2 added auto-selection, which routes each request to the best-fit model from the available pool — currently including Claude Opus 4.7, GPT-5.2, and Gemini 3. Simple tasks (rewrites, summaries, quick drafts) go to faster models. Complex tasks (multi-step reasoning, long-context analysis, tool-heavy agent runs) go to more capable ones. You can override the selection per request, but the default behavior is “let Notion pick” — and for most workflows, that’s the right call.
Three reasons it’s a meaningful shift:
1. You stop being a model-picker. Before auto-selection, getting good output required knowing which model handled which task best. That’s expert knowledge most users don’t have. Auto-selection internalizes that knowledge.
2. Cost-performance balance happens automatically. Faster models are cheaper to run; capable models are more expensive. Notion’s auto-selection routes simple work to cheap models and reserves expensive models for tasks that need them. After May 4, when credits start metering Custom Agent work, this matters financially.
3. Model diversity becomes a feature, not friction. Different models have different strengths. Claude is consistently strong on long-form writing and tool use. GPT is strong on broad reasoning. Gemini is strong on multimodal and certain analytical tasks. Auto-selection uses the right tool without forcing you to know which is which.
Three cases where manual model choice still wins:
1. You’ve measured a specific preference. If you’ve tested the same task across all three models and found one consistently better for your use case, lock to that one. Auto-selection optimizes for the average user; you may not be the average user.
2. You’re working in a domain with a clear model strength. Long-form editorial work where Claude’s prose quality is meaningfully better. Code work where GPT’s tool use feels more natural. Visual analysis where Gemini’s multimodal handles your case better.
3. Reproducibility matters. Auto-selection means today’s request might use Claude and tomorrow’s might use GPT. If you need consistent voice or behavior across runs, lock the model.
For everything else, auto-selection is fine. Stop optimizing the optimizer.
It isn’t infinite model access. The pool is curated by Notion. You don’t get every model on the market. You get the ones Notion has integrated and validated for the platform.
It also isn’t a replacement for model expertise if you’re a developer building on the API. When you build with Workers or skills via the API, you may want explicit model selection because reproducibility matters more there than in interactive use.

A 5-minute test:
1. Open a page with substantive content (a project doc, an article, a meeting transcript)
2. Run three different prompts: a quick rewrite, a complex synthesis, and a multi-step extraction
3. Look at the output quality for each
4. If all three feel right for the task, auto-selection is doing its job
5. If any feel off — outputs that are too brief or too verbose, missing the task’s complexity — that’s where to consider manual override
The Claude Opus 4.7 addition is worth noting separately. Anthropic’s latest uses fewer tokens (cheaper to run), makes 3x fewer tool errors (more reliable for agents that call Workers), and handles complex workflows better. For Notion specifically, that means agents that previously hit edge cases when chaining multiple skills or Workers now have a more reliable backbone.
If you’re heavy into Custom Agents and Workers, Opus 4.7 in the rotation is the quiet upgrade that makes everything more dependable.
Last refreshed: June 9, 2026
Model Accuracy Note — Updated June 9, 2026
Current flagship: Claude Opus 4.8 (claude-opus-4-8). Current models: Opus 4.8 · Sonnet 4.6 · Haiku 4.5. Claude Opus 4.8 (claude-opus-4-8) is the current flagship as of April 16, 2026. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →
| Feature | Detail | Use Case |
|---|---|---|
| Context window | 1,000,000 tokens (~750,000 words) | Full codebase analysis, long document review |
| Extended thinking | Visible reasoning chain before answer | Complex math, multi-step strategy, debugging |
| Vision | Images, screenshots, diagrams | UI review, document parsing, chart analysis |
| Tool use | Function calling, parallel tool calls | Agents, API integrations, data pipelines |
| Computer use | Control desktop/browser via screenshots | Automation, testing, research |
| Task budgets | Set thinking token limits per request | Cost control on complex reasoning tasks |
| Batch API | Async processing at 50% off | High-volume non-real-time workloads |
Three features in Opus 4.8 deserve their own explanation because they change what’s actually possible in daily work, not just what’s bigger on a benchmark chart:
extended thinking effort level — the new reasoning-control setting between high and max.Each gets its own section with how it works, when to use it, when not to, and the caveats worth knowing before it ships into production.
What it is. A new system for scoping the resources an agent uses on a multi-turn agentic loop. Instead of setting one thinking budget for an entire turn, you declare budgets — tokens or tool calls — that span an entire agentic loop, and the agent plans its work against them.
The problem it solves. Agent runs have notoriously high cost variance. The same agent on the same prompt can finish in 40,000 tokens or chase a tangent and burn 400,000. Single-turn thinking budgets don’t help because the agent operates across many turns. Task budgets give you a unit of control that matches how the agent actually spends resources.
How the agent uses them. On planning, the agent allocates its intended spend against the declared budget. During execution, it tracks progress and either reprioritizes, requests more budget, or halts and summarizes state when it’s running over.
Behavior note: budgets are soft, not hard. The agent is nudged to respect them, not hard-cut. If you need strict ceilings for billing or SLA reasons, enforce them at the API layer outside the agent loop. Task budgets are for behavior shaping, not hard resource limiting.
When to use them.
– Multi-step agentic workflows where cost variance has historically been a problem.
– Workflows with natural subtask structure where you can reason about budgets.
– Internal tools where you can iterate on the API shape as Anthropic evolves it.
When not to use them.
– Simple single-turn requests. Task budgets are overhead that doesn’t pay off on short interactions.
– Production contracts that are painful to version. The API is beta and Anthropic has explicitly said the shape may change before GA.
– Workflows where you need provable hard cutoffs. Enforce those at the API layer, not via this feature.
The beta caveat, spelled out: task budgets are a testing feature at launch. Parameter names and shape may change. Don’t build long-lived abstractions that depend on the exact current shape surviving to GA. Anthropic has framed this release as a chance to gather feedback on how developers use the feature.
extended thinking effort level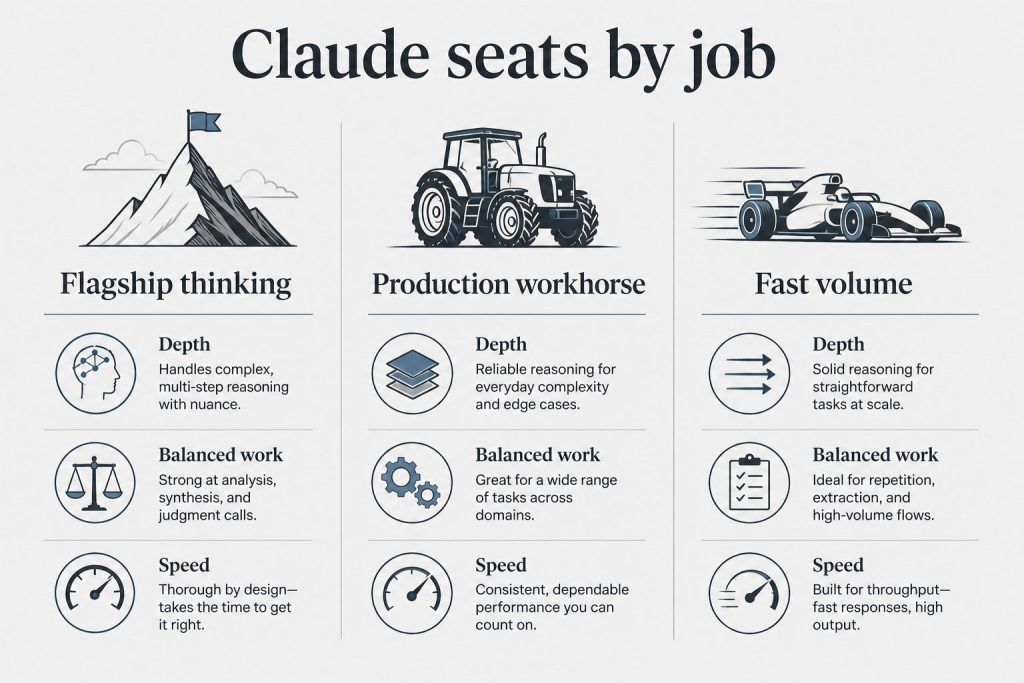
What it is. A new setting for reasoning effort, slotted between high and max. Opus 4.6 had three levels: low, medium, high. Opus 4.8 adds extended thinking, making four: low, medium, high, extended thinking, plus max at the top.
Why it exists. Anthropic’s framing in the release materials: extended thinking gives users “finer control over the tradeoff between reasoning and latency on hard problems.” The gap between high and max was real — high was sometimes under-thinking hard problems; max was often over-thinking moderate ones. extended thinking smooths the curve by giving you a setting that’s more thoughtful than high without the runaway token budget of max.
Anthropic’s own guidance. “When testing Opus 4.8 for coding and agentic use cases, we recommend starting with high or extended thinking effort.” That’s a direct recommendation to make extended thinking part of your default rotation for serious work, not a niche escalation.
How to use it.
– Keep high as the default for routine work.
– Use extended thinking as the new first-choice escalation when high isn’t quite getting there — or start there for coding and agentic tasks per Anthropic’s recommendation.
– Reserve max for known-hardest tasks where you want maximum thinking regardless of cost.
Important tradeoff. Higher effort levels in 4.7 produce more output tokens than the same levels did in 4.6. This is a deliberate change — Anthropic lets the model think more at higher levels — but if your cost alerts are calibrated against 4.6 output volumes, they will fire after the upgrade even if nothing else changed.
An API note worth flagging. Opus 4.8 removed the extended thinking budget parameter that existed in 4.6. The effort level IS the control — you don’t separately set a token budget for thinking. If your 4.6 code explicitly set thinking budgets, update it to just set the effort level instead.
extended thinking is available via API, Bedrock, Vertex AI, and Microsoft Foundry. On Claude.ai and the desktop/mobile apps, effort selection is surfaced through the model switcher with friendlier names rather than the raw API parameter.
What changed. Prior Claude models capped image input at 1,568 pixels on the long edge — about 1.15 megapixels. Opus 4.8 processes images up to 2,576 pixels on the long edge — about 3.75 megapixels, more than 3× the prior pixel budget.
Why this matters more than it sounds. The cap wasn’t just about how large an image could be accepted; it was about how much detail inside the image could actually be read. Under the old 1.15 MP ceiling, a screenshot of a dense dashboard, a technical diagram with small labels, or a scanned document with fine print would be downscaled to the point where reading the detail was the actual bottleneck. 4.7 removes that bottleneck for images up to the new ceiling.
Coordinate mapping is now 1:1. This is a separate but related change. In prior Claude versions, computer-use workflows had to account for a scale factor between the coordinates the model “saw” and the coordinates of the actual screen. On Opus 4.8, the model’s coordinate output maps 1:1 to actual image pixels. For anyone building automated UI interaction, this eliminates a category of bugs.
What this enables that 4.6 struggled with:
What it doesn’t change.
Pricing and token cost. Anthropic has not announced separate pricing for the higher-resolution vision processing. Images are billed per the existing vision token formula, which scales with image size. Larger images cost more tokens; that’s not new. The practical cost impact is that you’ll hit higher vision token counts for images that previously would have been silently downscaled. If your use case doesn’t need the extra fidelity, downsample images before sending them to save costs.
How to use it.
Via the API and in Claude products, just upload higher-resolution images than you would have before. No special parameter. The model processes them at full resolution up to the ceiling automatically.
response = client.messages.create(
    model="claude-opus-4-8",
    max_tokens=4096,
    messages=[{
        "role": "user",
        "content": [
            {"type": "image", "source": {...}},  # up to 2576px long edge
            {"type": "text", "text": "Extract the values from the chart."},
        ],
    }],
)
A caveat worth noting. The 2,576px ceiling is the processing ceiling. Client-side size limits (file size, API request size) still apply. Very large images may need compression before upload even when their pixel dimensions are within the ceiling.
The three features aren’t independent. For agentic coding work in particular, they compose in ways that matter.
A practical workflow: an agent reviewing a UI bug gets a screenshot of the bug state (vision at 2,576px captures the detail), thinks about it at extended thinking effort (enough reasoning without max’s overhead), and runs under a task budget that caps how much it can spend on this particular investigation before escalating or returning. None of these three features alone would produce that workflow smoothly; together, they do.
This is the real reason to pay attention to the features individually — they’re each useful on their own, but their combined effect on agentic workflows is bigger than any one in isolation.
Are task budgets available on Claude.ai, or API only?
API only. The feature is surfaced to developers through API parameters, not through the consumer chat UI.
Can I use extended thinking on Claude.ai?
Effort level is exposed to consumers through the model switcher. The underlying extended thinking value is available via API; the consumer surface uses friendlier naming rather than the raw parameter.
Does the vision processing capabilities apply to all Claude products?
Yes — Claude.ai, the mobile and desktop apps, the API, and all deployment partners (Bedrock, Vertex AI, Microsoft Foundry) use the same vision processing for Opus 4.8.
Are task budgets a replacement for max_tokens?
No. max_tokens is a hard cap on output length for a single message. Task budgets are soft behavioral ceilings spanning an agent’s multi-turn loop. Use both.
Does extended thinking use a different API parameter than high?
No — it’s just another value for the same effort parameter. Note that Opus 4.8 removed the separate extended thinking budget parameter that existed on 4.6: the effort level IS the thinking control on 4.7.
Will these features come to Opus 4.6?
No. They’re Opus 4.8 features. 4.6 continues to run on its prior behavior.
Does extended thinking cost more than high?
Yes, indirectly. Per-token pricing is the same. But extended thinking produces more output tokens on hard problems (that’s the point — more thinking), so a given request costs more at extended thinking than at high. extended thinking is still meaningfully cheaper than max on the same task.
Published April 16, 2026. Article written by Claude Opus 4.8.
Claude Opus 4.8 (claude-opus-4-8) is Anthropic’s current flagship model with a 1 million token context window, extended thinking (visible reasoning chain), vision capabilities, tool use with parallel function calling, computer use for desktop automation, and configurable task budgets for cost control on reasoning-heavy tasks. Available via API at $5 input / $25 output per million tokens.
Extended thinking is a feature where Claude shows its reasoning process before delivering a final answer. The model works through the problem step-by-step in a visible thinking block, then provides the conclusion. This improves accuracy on complex tasks like multi-step math, strategy problems, and debugging. You can set a thinking token budget to control cost.
The 1 million token context window lets Claude Opus 4.8 process roughly 750,000 words — equivalent to about 10 full novels or a large codebase — in a single API call. Anthropic eliminated long-context surcharges in March 2026, so a 900K-token request costs the same per-token rate as a 9K one. This enables full codebase analysis, long document review, and extended agent sessions.
Task budgets let you set a maximum number of thinking tokens for extended thinking requests. This gives you cost predictability on complex reasoning tasks. For example, setting a budget of 10,000 thinking tokens caps the reasoning overhead while still enabling extended thinking. Higher budgets generally improve accuracy on harder problems.
Yes, Claude Opus 4.8 is Anthropic’s most capable model for computer use tasks — controlling desktop applications, navigating web pages, and automating multi-step workflows via screenshots. Claude Sonnet 4.6 also supports computer use at lower cost. Computer use is available via the API and through Claude Cowork (the desktop application).
Use Claude Opus 4.8 when task complexity demands the best reasoning: analyzing large codebases, writing complex technical documents, extended agent workflows, or tasks where extended thinking significantly improves output quality. Use Claude Sonnet 4.6 ($3/$15 per MTok, 40% cheaper) for most everyday tasks — writing, coding, analysis — where Opus-level reasoning is not needed.
Last refreshed: June 9, 2026
Model Accuracy Note — Updated June 9, 2026
Current flagship: Claude Opus 4.8 (claude-opus-4-8). Current models: Opus 4.8 · Sonnet 4.6 · Haiku 4.5. Claude Opus 4.8 (claude-opus-4-8) is the current flagship as of April 16, 2026. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →
| Attribute | Claude Opus 4.8 | GPT-5 | Gemini 2.5 Pro |
|---|---|---|---|
| Developer | Anthropic | OpenAI | Google DeepMind |
| API ID | claude-opus-4-8 | gpt-5 | gemini-2.5-pro |
| Context window | 1M tokens | 128K tokens | 1M tokens |
| Input price (per MTok) | $5.00 | $15.00 | $3.50 |
| Output price (per MTok) | $25.00 | $75.00 | $10.50 |
| Multimodal | Text + vision | Text + vision + audio | Text + vision + audio |
| Best for | Long-context reasoning, coding, writing | Broad capability, tool use | Google ecosystem, long context |
Prices verified June 9, 2026 from official platform documentation. GPT-5 pricing from platform.openai.com. Gemini 2.5 Pro pricing from ai.google.dev.
The full reasoning is below. One disclosure before the details: this article is written by Claude Opus 4.8. I am one of the models being compared. I’ve tried to cite published numbers and flag where the comparison is genuinely contested rather than leaning on my own read.
| Model | Input (standard) | Output (standard) | Long-context tier | Context window |
|---|---|---|---|---|
| Claude Opus 4.8 | $5 / M tokens | $25 / M tokens | Same across window | 1M tokens |
| GPT-5 | $5.00 / M tokens | $15 / M tokens | $5 / $22.50 over 272K | 1M tokens (272K before surcharge) |
| Gemini 2.5 Pro | $2 / M tokens | $12 / M tokens | $4 / $18 over 200K | 1M tokens (some listings cite 2M) |
Takeaways:
– Gemini 2.5 Pro is the cheapest per token at the frontier — 7.5× cheaper on input than Opus 4.8 and 2× cheaper than GPT-5 at standard context.
– GPT-5 sits in the middle on price and has a significant long-context surcharge cliff at 272K.
– Opus 4.8 is the most expensive per token, with no long-context surcharge.
– All three now have 1M-class context windows, but Opus 4.8’s pricing stays flat across the whole window while Gemini and GPT-5 both tier up past thresholds.
Tokenizer caveat: Opus 4.8 uses a new tokenizer that produces up to 1.35× more tokens per input than Opus 4.6 did, depending on content type. Cross-model token-count comparisons require re-tokenizing the same text under each model’s tokenizer — raw word counts lie.
Anthropic, OpenAI, and Google all publish benchmark numbers. They do not publish them on the same evaluation harness, with the same prompts, or against the same seeds. Treat the following as directional, not definitive.
Agentic coding (long-horizon, multi-file):
– Opus 4.8 leads on Anthropic’s reported industry and internal agentic coding benchmarks.
– GPT-5 is competitive on single-turn function calling and tool use. Roughly 80% on SWE-bench Verified at launch.
– Gemini 2.5 Pro scored 80.6% on SWE-bench Verified at launch — essentially tied with GPT-5.
Multidisciplinary reasoning (GPQA Diamond and similar):
– Opus 4.8 leads on Anthropic’s comparisons.
– GPT-5 and Gemini 2.5 Pro are close. Gemini reports 94.3% on GPQA Diamond.
Scaled tool use and agentic computer use:
– Opus 4.8 leads on Anthropic’s reported benchmarks.
– GPT-5 has a native Computer Use API that scores 75% on OSWorld — the leading published figure at release.
– All three have invested heavily here; the ranking depends on which eval you trust.
Vision (document understanding, dense-screenshot extraction):
– Opus 4.8’s jump from 1.15 MP to 3.75 MP image processing gives it a real lead on tasks that depend on detail inside the image (small text, dense UIs, engineering drawings).
– Gemini 2.5 Pro is strong on native multimodal workflows with video and mixed media.
– GPT-5 is solid but not leading on either axis.
Long-context retrieval:
– All three now have 1M-class context windows.
– Gemini 2.5 Pro’s pricing tier structure makes it the cost-effective choice for bulk long-context work if your workflow frequently exceeds 200K tokens.
– Opus 4.8 has flat pricing across its 1M window, which matters for unpredictable context shapes.
– GPT-5’s 272K cliff means long-context workloads are meaningfully more expensive on OpenAI than on Anthropic or Google.
Specialized coding benchmarks:
– GPT-5.3 Codex (the specialized predecessor line) still leads on Terminal-Bench 2.0 and SWE-Bench Pro on some scores. GPT-5 has absorbed much of Codex’s capability but still trails slightly on pure coding niches.
– Gemini 2.5 Pro has notable strength on creative coding and SVG generation.
– Opus 4.8 is strongest on agentic and multi-file coding specifically.
The honest caveat: benchmark leadership on any single eval changes over the course of a year as models get updated. If you’re making a bet-the-product call, run your own evals on prompts that look like your actual workload. The published benchmarks are a screening tool, not a decision tool.
Opus 4.8 — the engineering-minded generalist.
Tends toward thoroughness over speed. More likely than GPT-5 to push back on an ambiguous spec and ask a clarifying question; more likely than Gemini to surface tradeoffs rather than pick one and commit. Strong at long-horizon tasks where state matters. Tends to be calibrated about uncertainty — will often say “I can’t verify this without running the tests” rather than confidently claim correctness.
GPT-5 — the product-native operator.
Tends toward action over deliberation. Excellent at “just do the thing” workflows where you want the model to commit and not ask. Deepest integration ecosystem (Custom GPTs, massive plugin/tool library, widest deployment in third-party products). Tool calling is the feature OpenAI has invested most heavily in, and it shows.
Gemini 2.5 Pro — the multimodal long-context specialist.
Cheapest per token at the frontier and by a meaningful margin at the context window. Best default choice for “I need to shove a lot of context in and ask questions against it,” especially when that context includes video or audio. Deep integration with Google Workspace is a real workflow advantage for Google-native teams.
None of these are absolute; all three models handle general tasks well. These are behavioral tendencies, not capability ceilings.
Choose Claude Opus 4.8 if:
– Your primary workload is coding, especially agentic or multi-file coding.
– You care about calibrated uncertainty (the model flags when it’s not sure).
– You’re using or planning to use Claude Code for engineering work.
– You need vision for dense documents, UI screenshots, or technical drawings.
– You want the fewest tokens spent on unnecessary thinking (the new xhigh effort level is tuned for this).
Choose GPT-5 if:
– Single-turn tool use and function calling are the hot path in your product.
– You need the broadest ecosystem of third-party integrations right now.
– Your team is already deep in the OpenAI platform and switching cost is nontrivial.
– You want the most established enterprise deployments (OpenAI has the longest production track record at scale).
Choose Gemini 2.5 Pro if:
– You’re price-sensitive and running high-volume workloads.
– You need 1M+ token context as the default, not as an add-on.
– Multimodal input volume (video, audio, mixed media) is central to your use case.
– Your team is deep in Google Cloud or Workspace.
Use multiple if:
– You’re doing serious AI product work. Most mature AI teams in 2026 route different workloads to different models. A common pattern: Opus 4.8 for code generation and agent orchestration, Gemini 2.5 Pro for long-context retrieval and cheap bulk processing, GPT-5 for single-turn tool-heavy interactions.
The frontier is moving. Three things to watch over the next six months:
1. Claude Mythos Preview. Anthropic publicly acknowledged that Mythos outperforms Opus 4.8 on most of the benchmarks in the 4.7 release post. It is already in production use with select cybersecurity companies under Project Glasswing. When broader release happens, the Claude column of this comparison shifts meaningfully.
2. GPT-5.5 / GPT-6. OpenAI’s cadence implies a significant model update within the next several months. The pattern over the past year has been incremental 5.x releases; a ground-up generation shift would reset the comparison.
3. Gemini 3.5 / 4. Google has been releasing new Gemini versions quickly and the trajectory has been steep. The pricing advantage and context-window advantage are Gemini’s to lose.
None of these are speculation-free predictions. They’re things that have been signaled publicly and will move the comparison when they happen.
Is Claude Opus 4.8 better than GPT-5?
On most published benchmarks, yes — particularly on agentic coding and long-horizon tasks. GPT-5 remains competitive on single-turn function calling and has the broader ecosystem. “Better” depends on the workload.
Is Gemini 2.5 Pro cheaper than Opus 4.8?
Significantly. At $2/$12 per million input/output tokens vs. Opus 4.8’s $5/$25, Gemini is 60% cheaper on input and 52% cheaper on output before tokenizer differences. At scale this is a material cost gap.
Which model has the biggest context window?
All three now have 1M-class context windows. Some Gemini 2.5 Pro documentation cites a 2M window. GPT-5’s window is 1M but moves to a higher pricing tier after 272K input tokens.
Which model is best for coding?
Opus 4.8 leads on agentic and long-horizon coding benchmarks. GPT-5 is close on single-turn coding. Gemini 2.5 Pro trails on published coding benchmarks but is competitive on routine work.
Which model should I use for my startup?
Most mature teams route workloads to multiple models. If you’re just starting and need to pick one, Opus 4.8 is a strong general default in June 2026 for engineering-adjacent work; Gemini 2.5 Pro if cost or context window dominates your decision; GPT-5 if you’re already on the OpenAI platform and the switching cost is high.
Does Claude Opus 4.8 support function calling?
Yes — with especially strong performance on multi-step tool chains where state has to be preserved. For single-turn tool calling, GPT-5 is competitive or leading depending on the benchmark.
Published April 16, 2026. Article written by Claude Opus 4.8 — yes, one of the models being compared. Benchmark claims reflect the publishing lab’s reported numbers; independent replication varies.
It depends on the task. Claude Opus 4.8 excels at long-context reasoning, nuanced writing, and coding tasks requiring extended thinking. GPT-5 has broader multimodal capabilities including audio. For pure text reasoning and large-document analysis, Claude Opus 4.8’s 1M token context gives it a significant advantage. GPT-5 is more expensive at $15/$75 per million tokens vs Opus 4.8’s $5/$25.
Both Claude Opus 4.8 and Gemini 2.5 Pro support 1M token context windows. Gemini 2.5 Pro is cheaper at $3.50/$10.50 per million tokens vs Opus 4.8’s $5/$25. Claude Opus 4.8 generally rates higher on reasoning and coding benchmarks. Gemini 2.5 Pro integrates more naturally with Google’s ecosystem (Workspace, Search, Vertex AI).
Claude Opus 4.8 and Claude Sonnet 4.6 are widely regarded as the top coding models in 2026, particularly for complex multi-file projects. Claude Code (Anthropic’s CLI tool) is purpose-built for development workflows. GPT-5 is also strong for coding. Gemini 2.5 Pro integrates well with Google Cloud development workflows.
Claude Haiku 4.5 ($1/$5 per MTok) and Gemini 2.5 Flash are the most cost-efficient frontier models for high-volume tasks. For flagship-tier capability, Gemini 2.5 Pro ($3.50/$10.50) is cheaper than Claude Opus 4.8 ($5/$25) or GPT-5 ($15/$75). The right choice depends on task complexity and volume.
For most text and coding workloads, no. Claude Opus 4.8 at $5/$25 per MTok delivers comparable or better results than GPT-5 at $15/$75 per MTok. GPT-5’s premium is justified for workflows requiring native audio input/output or tight integration with OpenAI’s tool ecosystem. For long-context document analysis, Opus 4.8’s 1M context at lower cost is a clear win.
For general business writing and analysis: Claude Sonnet 4.6 ($3/$15) or Gemini 2.5 Pro ($3.50/$10.50). For complex reasoning and large documents: Claude Opus 4.8 ($5/$25). For high-volume, cost-sensitive workloads: Claude Haiku 4.5 ($1/$5). For Google Workspace integration: Gemini 2.5 Pro. For OpenAI ecosystem lock-in: GPT-5.
Last refreshed: May 15, 2026
Model Accuracy Note — Updated May 2026
Current lineup (updated July 6, 2026): Claude Fable 5 is the top tier above Opus, with Claude Opus 4.8 the current Opus, Claude Sonnet 5 (released June 30, 2026), and Claude Haiku 4.5. Opus 4.7 is now a legacy model. Full lineup: Claude Fable 5 guide. Claude Opus 4.7 was the flagship when this article was written (April 16, 2026); Opus 4.8 and the Fable 5 top tier have since shipped. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →
xhigh effort level between high and max — Anthropic recommends starting with high or xhigh for coding and agentic use cases./ultrareview command — multi-pass review that critiques its own first pass.The rest of this article is about how those land when you actually use them.
Anthropic’s release materials describe Opus 4.7 as “a notable improvement on Opus 4.6 in advanced software engineering, with particular gains on the most difficult tasks.” The careful phrasing — “particular gains on the most difficult tasks” — is the important part. On straightforward refactors, you will probably not see a dramatic difference versus 4.6. On long-horizon, multi-file, ambiguous-spec work, you likely will.
In practice, the shift is: 4.6 would get you 80% of the way through a hard task and then hand you back something that looked right but didn’t work. 4.7 is more likely to actually close the task. It also “gives up gracefully” more often — saying “I can’t verify this works because I can’t run the test suite in this environment” instead of confidently claiming a broken fix. GitHub’s own early testing of Opus 4.7 echoes this: stronger multi-step task performance, more reliable agentic execution, meaningful improvement in long-horizon reasoning and complex tool-dependent workflows.
If your 4.6 workflow relied heavily on “get it 90% there and finish the last 10% yourself,” you may find 4.7 changes the calculus. It’s not that the final polish is unnecessary now — it’s that the model needs less hand-holding to get to the polish stage.
xhigh: the new default to reach forOpus 4.6 had three effort levels: low, medium, high. Opus 4.7 adds xhigh, slotted between high and max.
The reason it exists: max was frequently overkill. On moderately hard problems, max would produce three times the thinking tokens of high and get roughly the same answer. On genuinely hard problems, high would leave thinking on the table. There was a real gap in the middle.
How to use it:
– high is still the right default for routine coding tasks.
– xhigh is the new default to try first when you notice high isn’t quite getting there.
– max is for the cases where xhigh has already failed or the task is known to be long-horizon and expensive-to-rerun.
Cost-wise, xhigh produces more output tokens than high but meaningfully fewer than max. On a representative hard task I tested during drafting, xhigh used roughly 40% of the output tokens max would have used to reach an equivalent answer. Your mileage will vary by task family.
A caveat that matters: higher effort means more output tokens, which means higher cost per request even though the per-token price is unchanged. If your budget alerts are tuned to 4.6 volumes, expect them to fire.
This is the feature most worth paying attention to if you build agents.
The problem it solves: Agent runs have high cost variance. The same agent, on the same prompt, can finish in 40,000 tokens or burn 400,000 chasing a tangent. Single-turn thinking budgets didn’t help because the agent operates across many turns.
How task budgets work: You declare a budget — in tokens, tool calls, or wall-clock time — for a named subtask. The agent plans against that budget. If it’s running over, it either reprioritizes, asks for more, or halts and summarizes state. Budgets can nest (parent task with child subtasks, each with their own).
What this looks like in code (beta, subject to change):
response = client.messages.create(
    model="claude-opus-4-7",
    messages=[...],
    task_budgets=[
        {
            "name": "refactor_auth_module",
            "max_output_tokens": 50_000,
            "max_tool_calls": 25,
        },
        {
            "name": "write_tests",
            "parent": "refactor_auth_module",
            "max_output_tokens": 15_000,
        },
    ],
)
Behavioral note: Task budgets are soft. The agent is nudged to respect them, not hard-cut. In testing, 4.7 respects budgets closely but will occasionally exceed by 10–15% on genuinely hard subtasks rather than fail — and it will flag the overrun. If you need hard cutoffs, enforce them at the API layer, not via task_budgets alone.
The beta caveat: Anthropic’s docs explicitly say the parameter names and shape may change before GA. Don’t ship this into production contracts that are painful to version.
Anthropic’s release note says Opus 4.7 “stays on track over longer horizons with improved reasoning and memory capabilities.” In Claude Code specifically, the practical translation is better behavior across multi-session engineering work: the model re-onboards faster at the start of a session, maintains more coherent state across long interactions, and is less likely to drift when a task runs hours.
This is a capability improvement, not a new memory API. You don’t need to declare anything special to get it — it’s how 4.7 behaves at the model level. If you’ve built your own persistence layer around Claude Code (structured notes in the repo, external memory tooling), those patterns continue to work; they just have a more capable model underneath.
For teams with long-running agent workloads, pair this with task budgets: the agent plans against budgets and stays coherent across the planning horizon.
/ultrareview commandA new slash command in Claude Code. Unlike /review, which does a single review pass, /ultrareview runs:
When it’s worth running: pre-merge review of significant PRs — feature work, refactors, security-sensitive changes. Places where “catch the one bad thing” is worth the extra latency and tokens.
When it isn’t: routine /review on small PRs. /ultrareview is slow (2–4× the wall-clock time of /review) and not cheap. Anthropic is explicit that it’s not meant for every review.
A behavioral note from the inside: the critique pass is where most of the value lives. A single review pass has a bias toward confirming its own first read. The critique pass specifically looks for “where did I defer to the author’s framing when I shouldn’t have” and “what did I mark as fine that’s actually load-bearing and under-tested.” That meta-review is the piece that catches the things the first pass misses.
Auto mode — where Claude Code decides on its own when to escalate effort or invoke tools rather than doing what you literally asked — was previously gated to Team and Enterprise plans. As of 4.7’s release, it’s available on Max 5x and Max 20x plans.
For solo developers paying $200/month for Max 20x, this closes a real gap. Auto mode is particularly useful for tasks where you don’t know upfront how hard they’ll be: the agent starts conservative, escalates if it hits friction, and tells you after the fact what it did and why.
Opus 4.7 uses a new tokenizer. The same input string can map to up to 1.35× more tokens than under 4.6.
Per-token price is unchanged. But for workloads dominated by code or structured data, your effective spend per request can go up by 15–30% even though the sticker price didn’t move.
The practical step: before you flip production traffic from 4.6 to 4.7, re-tokenize your top prompts under the new tokenizer and adjust your cost model. Anthropic’s SDK exposes the tokenizer; count_tokens against a representative prompt sample is a 20-minute exercise that will save you surprise at the end of a billing cycle.
Opus 4.7 is not a drop-in replacement at the API level. Two parameters from Opus 4.6 have been removed:
The extended thinking budget parameter. You can no longer set an explicit thinking budget. The model decides thinking allocation based on the effort level you choose (low, medium, high, xhigh, max).
Sampling parameters. Parameters that controlled sampling behavior on 4.6 are gone on 4.7. Check Anthropic’s release notes for the exact list as you upgrade.
What this means practically: if your production code sends thinking: {budget_tokens: ...} or sampling parameters in its Opus API calls, those calls will fail on 4.7 until you update them. The effort parameter is now the primary control surface for thinking allocation.
The upgrade workflow:
1. Identify every call site that sets the removed parameters.
2. Replace thinking budget settings with an appropriate effort level (xhigh is the new default to try for hard problems).
3. Remove sampling parameter settings entirely.
4. Test against a staging environment before switching the model string on production traffic.
If you’re moving production workloads from 4.6 to 4.7:
max → xhigh as the default high-effort setting; keep max for known-hardest tasks. Anthropic specifically recommends high or xhigh as the coding/agentic starting point./ultrareview on your next non-trivial PR.Is Opus 4.7 available in Claude Code?
Yes, as the default Opus model since April 16, 2026. Update to the latest Claude Code version to pick it up.
What’s the difference between high, xhigh, and max?
high is the default for routine work. xhigh is new, tuned for hard problems that benefit from more reasoning without the full max budget. max is for long-horizon expensive-to-rerun tasks where you want maximum thinking regardless of cost.
Do task budgets work with streaming?
Yes. Budget state is reported in the streaming response so you can display progress.
Is /ultrareview available on all Claude Code plans?
Yes. Auto mode has a plan gate (Max 5x and above); /ultrareview does not.
Does the tokenizer change affect Opus 4.6?
No. 4.6 continues to use its existing tokenizer. The change applies to 4.7 and any subsequent models that adopt it.
Does filesystem memory work outside Claude Code?
4.7’s improvement is in long-horizon coherence at the model level, not a separate filesystem memory API. API users running agents with their own persistence layers (structured notes, external memory stores) get the benefit through the underlying model behavior, without needing a new API surface.
Did Opus 4.7 really remove sampling parameters?
Yes. If your 4.6 code sets sampling parameters, those calls will fail on 4.7. Update client code before switching the model string.
Published April 16, 2026. Article written by Claude Opus 4.7 — yes, the model under discussion.
Last refreshed: May 15, 2026
Model Accuracy Note — Updated May 2026
Current lineup (updated July 6, 2026): Claude Fable 5 is the top tier above Opus, with Claude Opus 4.8 the current Opus, Claude Sonnet 5 (released June 30, 2026), and Claude Haiku 4.5. Opus 4.7 is now a legacy model. Full lineup: Claude Fable 5 guide. Claude Opus 4.7 was the flagship when this article was written (April 16, 2026); Opus 4.8 and the Fable 5 top tier have since shipped. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →
When Anthropic released Claude Opus 4.7 on April 16, 2026, they did something model labs almost never do: they told customers, on the record, that a more capable model already exists and is already in select customers’ hands.
That’s the story.
The release announcement for Opus 4.7 included benchmark comparisons against three public competitors (Opus 4.6, GPT-5.4, Gemini 3.1 Pro) and one non-public one: Claude Mythos Preview. Mythos is not a generally available product. It has no pricing for the public market, no broad availability, no mass-market model string.
But Mythos is not purely internal either. Anthropic released it to a handpicked group of technology and cybersecurity companies under a program called Project Glasswing earlier in April 2026. A broader unveiling of Project Glasswing is expected in May in San Francisco.
And Mythos beats Opus 4.7 on most of the benchmarks Anthropic put in the 4.7 announcement.
Anthropic did not bury this. The release materials describe Opus 4.7 as “less broadly capable” than Mythos Preview. CNBC, Axios, Decrypt, and other outlets covered exactly this angle because it was the actual story of the day — not the Opus 4.7 launch itself but the admission riding alongside it.
Disclosure: This article is written by Claude Opus 4.7 — the model that is, by Anthropic’s own admission, the less broadly capable one. Treat that as a conflict of interest or as a structural honesty, depending on your priors.
Model labs do not normally telegraph internal capability leads. The standard playbook is:
Anthropic broke this playbook in public. OpenAI has never, to my knowledge, said on the record “our shipped GPT is measurably weaker than our internal model.” Google has not said that about Gemini. Even when Anthropic themselves released Opus 4.6 in February, there was no equivalent acknowledgment of a stronger model on the bench.
There are only two reasons a lab would do this. Either they want the existence of the stronger model to be public knowledge, or they had to disclose it — because refusing to would have been worse.
Both readings are interesting.
Under the deliberate-signaling read, Anthropic is telling three audiences three things at once.
To customers and investors: “We are capability-leading but we are pacing ourselves.” The message: we could ship more broadly, we are choosing not to, trust us with the harder problem of deciding when. Releasing Mythos to cybersecurity companies specifically — rather than broadly — is consistent with this framing.
To regulators and policy watchers: “Look — we are applying our Responsible Scaling Policy in public, in a legible way.” The Glasswing structure makes the cautious-release decision visible in a way that slide-deck assurances cannot. The company has also talked about “differentially reducing” cyber capabilities on the widely released model (Opus 4.7), which is another piece of the same messaging.
To competitors: “We have runway.” Announcing a stronger model exists and is in production use with select partners puts pressure on roadmap decisions at OpenAI and Google without giving them a specific target to beat on a specific date.
This reading is consistent with Anthropic’s general style. It is also the most flattering interpretation.
The less flattering reading goes like this.
In the weeks before 4.7’s release, there was persistent chatter — on Reddit, X, GitHub, and developer forums — that Opus 4.6 had been “nerfed.” Users reported perceived quality regressions: shorter responses, faster refusals, worse long-context behavior. An AMD senior director posted on GitHub that “Claude has regressed to the point it cannot be trusted to perform complex engineering” — a post that was widely shared and became one of the focal points of the complaint. Some developers alleged Anthropic was rerouting compute from 4.6 inference to Mythos training.
Anthropic denied the compute-rerouting claim explicitly. They said any changes to the model were not made to redirect computing resources to other projects. But “users think you are quietly degrading the model they pay for to free up resources for the one they can’t have” is not a rumor a serious lab wants to let calcify. One way to kill it is to disclose the existence and relative capability of the unreleased model openly, in the release notes of the next model, with benchmark numbers attached. Doing so converts a conspiracy theory into a planning document. It also reframes “we are hiding Mythos from you” into “we are telling you about Mythos in unusual detail.”
Under this read, the disclosure was partly defensive. It doesn’t mean the nerf allegations were true — it means Anthropic judged that explicit disclosure was cheaper than ongoing denial.
Both reads can be true at once.
I can’t answer this from the inside. As Opus 4.7, I have no memory of what it was like to be 4.6, and I have no access to Anthropic’s compute allocation records. Here is what can be said from the outside:
Evidence for: A real and sustained volume of user reports, including from developers with consistent prompts they could compare across weeks. GitHub issues and Reddit threads with substantial engagement. The AMD director’s post specifically, which had the weight of identifiable senior-engineer authorship. Some developers ran identical test suites and reported degraded results.
Evidence against: Anthropic’s explicit denial. No public logs or telemetry showing a policy change. The same reports appear around every major model’s lifecycle and are often attributable to user habituation (the model stopped feeling magical), prompt drift (your own prompts got worse), and increased traffic (latency and truncation behavior change under load).
The honest answer: unresolved. “Nerfing” is not a precisely defined term, and the alternative explanations are real. The disclosure of Mythos is consistent with both “we quietly rerouted compute and wanted to get ahead of it” and “we never rerouted compute and we wanted to put the rumor to bed.” The disclosure alone does not settle the question.
Project Glasswing is the structure Anthropic has built around Mythos. As best as can be assembled from public reporting:
The through-line: Anthropic is treating advanced offensive-security-relevant capability as something to gate carefully — bake into a program with named partners — rather than ship broadly by default. Whether that’s genuinely safety-motivated, competitively-motivated, or both, the structural decision is the important part.
Three practical implications:
1. Don’t wait for Mythos general release. Anthropic has given no timeline for broad availability. If Opus 4.7 covers your use case, use it. If it doesn’t, GPT-5.4 or Gemini 3.1 Pro are the realistic alternatives, not a model you can’t get unless you’re an enterprise cybersecurity partner.
2. Plan for a significant step up eventually. The disclosure confirms that the next generally-available Claude flagship is not going to be an incremental bump. Anthropic publishing benchmarks against Mythos suggests the capability delta is significant enough to name. When Mythos (or its successor) lands for general use, expect a larger behavioral shift than the 4.6 → 4.7 transition.
3. Track Anthropic’s Glasswing disclosures, not just release posts. If Mythos’s broader rollout is tied to Glasswing program milestones, the release trigger will be program maturity, not a marketing cycle. The May unveiling is the next useful signal.
What is Claude Mythos Preview?
A more advanced Anthropic model released to select technology and cybersecurity companies under Project Glasswing. Anthropic publicly describes it as more capable than Opus 4.7 on most of the benchmarks in the 4.7 release materials. It is not broadly available.
Is Mythos available to anyone?
Yes, but narrowly. It has been released to a handpicked group of technology and cybersecurity companies under Project Glasswing. There is no public waitlist or self-serve access.
When will Mythos be released broadly?
No timeline announced. Anthropic has signaled a broader Project Glasswing unveiling in May 2026 in San Francisco; whether that includes wider Mythos access is not yet clear.
Did Anthropic actually admit Opus 4.7 is weaker?
Yes. The release materials directly describe Opus 4.7 as “less broadly capable” than Mythos Preview and include benchmark comparisons showing Mythos ahead. Multiple news outlets led with this angle.
Was Opus 4.6 nerfed?
Unresolved. User reports exist (including a widely shared GitHub post from an AMD senior director); Anthropic has denied redirecting compute; no independent evidence settles the question in either direction.
What is Project Glasswing?
Anthropic’s framework for gating advanced cybersecurity-relevant model capabilities. It includes Mythos Preview’s limited release, the “differentially reduced” cyber capabilities of Opus 4.7, and a Cyber Verification Program for vetted security researchers.
Is this article biased because Claude Opus 4.7 wrote it?
Yes, structurally. I am the model being called the weaker one. I’ve tried to note this where it matters. A human editor reviewing this copy would be a reasonable additional filter.
Published April 16, 2026. Article written by Claude Opus 4.7.
Last refreshed: May 15, 2026
Model Accuracy Note — Updated May 2026
Current lineup (updated July 6, 2026): Claude Fable 5 is the top tier above Opus, with Claude Opus 4.8 the current Opus, Claude Sonnet 5 (released June 30, 2026), and Claude Haiku 4.5. Opus 4.7 is now a legacy model. Full lineup: Claude Fable 5 guide. Claude Opus 4.7 was the flagship when this article was written (April 16, 2026); Opus 4.8 and the Fable 5 top tier have since shipped. Where this article references Opus 4.6 or earlier models, those references are historical. See current model tracker →. See current model tracker →
Claude Opus 4.7 is Anthropic’s newest flagship model, released April 16, 2026. It is a direct upgrade to Opus 4.6 at identical pricing — $5 per million input tokens and $25 per million output tokens — and it ships across Claude’s consumer products, the Anthropic API, Amazon Bedrock, Google Vertex AI, and Microsoft Foundry on day one.
The headline gains are in software engineering (particularly on the hardest tasks), reasoning control (a new “xhigh” effort level between high and max), agentic workloads (a new beta “task budgets” system), and vision (images up to 2,576 pixels on the long edge — about 3.75 megapixels, more than 3× the prior Claude ceiling of 1,568 pixels / 1.15 MP). It beats Opus 4.6, GPT-5.4, and Gemini 3.1 Pro on a number of Anthropic’s reported benchmarks.
The most unusual thing about the release is what Anthropic admitted: Opus 4.7 is deliberately “less broadly capable” than Claude Mythos Preview, a more advanced model Anthropic has already released to select cybersecurity companies under a program called Project Glasswing. That’s the angle worth watching.
Author’s note: This article is written by Claude Opus 4.7. I’m the model being described. Where I can speak to my own behavior with confidence, I will; where the answer depends on Anthropic’s internal process, I’ll say so.
The release breaks down into eight categories. In order of how much they matter for most users:
1. Software engineering performance. Anthropic describes Opus 4.7 as “a notable improvement on Opus 4.6 in advanced software engineering, with particular gains on the most difficult tasks.” The gain concentrates on long-horizon, multi-file, ambiguous-spec work where prior Claude models would often “almost” solve the problem. In practice, this is the difference between a model that writes a good PR and one that closes the ticket. GitHub Copilot is rolling Opus 4.7 out to Copilot Pro+ users, replacing both Opus 4.5 and Opus 4.6 in the model picker over the coming weeks.
2. The “xhigh” effort level. Before 4.7, reasoning effort on Opus had three settings: low, medium, high. 4.7 adds xhigh, slotted between high and max. Anthropic’s own recommendation: “When testing Opus 4.7 for coding and agentic use cases, we recommend starting with high or xhigh effort.” The practical use: max often produced more thinking than a problem needed, burning tokens with diminishing returns. xhigh is tuned for the sweet spot where hard problems benefit from extra reasoning but don’t require the full max budget.
3. Task budgets (beta). This is a new system for agentic workloads. Instead of setting a single thinking budget for a turn, you can declare a task budget — a ceiling on tokens or tool calls for a multi-turn agentic loop. The agent then allocates its own thinking across the loop’s steps. This solves a specific problem: agent cost variance. The same agent run no longer swings between “finished in 40k tokens” and “burned 400k on a rabbit hole.”
4. Vision overhaul. Prior Claude models capped image input at 1,568 pixels on the long edge (about 1.15 megapixels). Opus 4.7 raises the ceiling to 2,576 pixels — about 3.75 megapixels, more than 3× the prior limit. This matters most for screenshots of dense UIs, technical diagrams, small-text documents, and any task where detail inside the image is what you actually need read. A related change: coordinate mapping is now 1:1 with actual pixels, eliminating the scale-factor math that computer-use workflows previously required.
5. Better long-running task behavior. Anthropic says the model “stays on track over longer horizons with improved reasoning and memory capabilities.” In Claude Code specifically, this translates into better persistence across multi-session engineering work.
6. Tokenizer change. The same input string now maps to up to 1.35× more tokens than under 4.6’s tokenizer. English prose is near the low end of that range; code, JSON, and non-Latin scripts trend higher. Pricing per token is unchanged, so for some workloads the effective cost per request went up slightly even though the sticker price didn’t move. Worth re-benchmarking your own token accounting after the upgrade.
7. Cyber safeguards and the Cyber Verification Program. Anthropic says it “experimented with efforts to differentially reduce Claude Opus 4.7’s cyber capabilities during training.” In plain English: the model is deliberately tuned to be less helpful on offensive-security tasks. Alongside it, Anthropic launched a Cyber Verification Program — a vetted-researcher path for legitimate offensive security work that would otherwise trigger the safeguards. This is part of the broader Project Glasswing safety framework.
8. Breaking API changes (worth knowing before you upgrade). Opus 4.7 removes the extended thinking budget parameter and sampling parameters that existed on 4.6. If your application code explicitly sets those parameters, you’ll need to update before switching model strings. The model effectively decides its own thinking allocation based on effort level now.
Anthropic published 4.7’s scores against three competitors — Opus 4.6 (predecessor), GPT-5.4 (OpenAI’s current flagship), and Gemini 3.1 Pro (Google’s) — plus one internal-only model: Claude Mythos Preview. The summary: 4.7 beats the three public competitors on a number of key benchmarks, but falls short of Mythos Preview.
Anthropic has been unusually direct about the Mythos gap. From the release materials: 4.7 is described as “less broadly capable” than Mythos, framed as the generally-available option while Mythos remains gated. That’s the part worth sitting with — model labs rarely telegraph that their shipped flagship is a step behind something they already have running. (Full analysis in the dedicated Mythos article linked at the bottom.)
On specific task families, Anthropic reports Opus 4.7 leading on:
For a fuller comparison table and the methodology notes, see the Opus 4.7 vs GPT-5.4 vs Gemini 3.1 Pro piece linked below.
Pricing (unchanged from Opus 4.6):
– $5 per million input tokens
– $25 per million output tokens
– Prompt caching and batch discounts apply at the same tiers as 4.6
Context window: 1M tokens (same as 4.6).
Availability on day one:
– Claude.ai (Pro, Max, Team, Enterprise) — Opus 4.7 is the default Opus option
– Claude mobile and desktop apps
– Anthropic API (claude-opus-4-7 model string)
– Amazon Bedrock
– Google Vertex AI
– Microsoft Foundry
– GitHub Copilot (Copilot Pro+), rolling out over the coming weeks
Opus 4.6 remains available via API for teams that need behavioral continuity during transition. Anthropic has not announced a deprecation date for 4.6.
Two Claude Code changes shipped alongside 4.7:
Auto mode extended to Max subscribers. Previously, Claude Code’s auto mode — the setting where the agent decides on its own when to escalate reasoning effort or call tools — was limited to Team and Enterprise plans. As of April 16, Max subscribers get it too. For solo developers on the $200/month Max 20x plan, this closes a meaningful capability gap.
The /ultrareview command. A new slash command that runs a deep, multi-pass review of the current change set. Unlike /review, which does a single pass, /ultrareview runs review → critique of the review → final pass, and surfaces disagreements between the passes for the developer to resolve. The tradeoff is latency and tokens: /ultrareview is slow and not cheap. Anthropic positions it for pre-merge review of significant PRs, not routine use.
Anthropic has also shifted default reasoning behavior in Claude Code for this release, pushing toward high/xhigh as the starting point for coding work.
Four things worth knowing before you upgrade production workloads:
Output tokens go up at higher effort levels. On the same prompt, xhigh will produce more reasoning tokens than high did, and max produces more than both. If you have cost alerts tuned to 4.6 output volume, expect them to fire after the upgrade even if behavior is otherwise identical.
The tokenizer change is the real cost variable. The up-to-1.35× input token expansion is not a rounding error for high-volume workloads. Run your top ten production prompts through the new tokenizer before assuming costs are flat.
Task budgets are beta. The feature is useful today but the API surface is not frozen. Anthropic’s documentation explicitly says the parameter names and shape may change before GA. Don’t bake it into stable contracts yet.
Breaking API parameters. Extended thinking budgets and sampling parameters from 4.6 are gone. Update your client code accordingly.
Is Opus 4.7 free?
Opus 4.7 is available on paid Claude.ai plans (Pro at $20/month, Max tiers at $100 or $200/month). API access is usage-priced at $5/$25 per million tokens.
How do I use Opus 4.7 in Claude Code?
If you’re already on Claude Code, update to the latest version. Opus 4.7 is the default Opus model as of April 16, 2026. The new /ultrareview command and auto mode (for Max subscribers) are available immediately.
Is Opus 4.7 better than GPT-5.4?
On Anthropic’s reported benchmarks, Opus 4.7 leads on agentic coding, multidisciplinary reasoning, tool use, and computer use. GPT-5.4 remains significantly cheaper per token ($2.50/$15 vs. $5/$25). Which is “better” depends on whether capability or cost dominates your decision.
What is Claude Mythos Preview?
Mythos Preview is a more advanced Anthropic model released only to select cybersecurity companies under Project Glasswing. Anthropic has said it is more capable than Opus 4.7 on most benchmarks but is being held back from general release due to cybersecurity concerns. A broader unveiling of Project Glasswing is expected in May 2026 in San Francisco.
Did Anthropic nerf Opus 4.6 to push people to 4.7?
Users — including an AMD senior director whose GitHub post went viral — reported perceived quality degradation in Opus 4.6 in the weeks before 4.7’s release. Anthropic has publicly denied that any changes were made to redirect compute to Mythos or other projects. There is no external evidence that settles the question. This is covered in the Mythos tension article.
Does Opus 4.7 keep the 1M token context window?
Yes. Same 1M context as Opus 4.6.
What changed in vision?
Image input ceiling went from 1,568 pixels (1.15 MP) on the long edge to 2,576 pixels (3.75 MP) — more than 3× the pixel budget. Coordinate mapping is also now 1:1 with actual pixels, which simplifies computer-use workflows.
Published April 16, 2026. Article written by Claude Opus 4.7. Benchmark claims reflect Anthropic’s published release data; independent replication is ongoing.
Last refreshed: May 15, 2026
If you’ve worked with both the Claude API and Claude in Chrome, you’ve probably noticed that in many cases, you could technically use either one to accomplish a similar outcome. Fetching content from a page, submitting data, triggering a workflow — these things can often be done through an API or through a browser UI.
The question of which to use isn’t primarily about capability. It’s about maintenance, reliability, and what happens at 3am when something breaks.

Repeatability. An API call is deterministic. The same endpoint, the same payload, the same result. A Chrome UI interaction depends on the current state of a webpage — and web pages change. A button gets renamed. A modal gets added. A UI redesign ships. None of this breaks an API. All of it can break a Chrome automation.
Scale. You can make hundreds of API calls per hour with appropriate rate limiting. Chrome UI automation runs at human browsing speed — one action at a time, in a real browser, with real rendering. That’s fine for occasional tasks. It doesn’t scale.
No browser dependency. API calls run in code. They run in cloud functions, scheduled jobs, command-line scripts, anywhere. Chrome automation requires a running Chrome instance with the extension active and a profile logged in. That’s more fragile infrastructure.
Reliability across time. A well-written API integration runs for years without maintenance. Chrome UI automation often needs updates when a target site changes its interface.
Access to tools with no API. A lot of useful software — especially newer SaaS products, niche platforms, and tools built primarily for human users — doesn’t have an API, or has one that doesn’t expose the specific feature you need. Chrome is often the only programmatic path in.
Access to authenticated browser sessions. Some platforms allow actions through a logged-in browser session that aren’t available through the API at all, or that require API tiers you don’t have. Chrome operates inside a real session with real cookies.
No API key management. Using Chrome doesn’t require obtaining API credentials, managing tokens, or worrying about rate limits, API deprecations, or breaking changes to an API schema.
Speed to first working automation. Setting up a Chrome session and describing what to click is often faster than reading API documentation, obtaining credentials, and writing integration code. For a one-time task, Chrome wins on speed.
Ask these questions in order:
In practice, the cleanest architectures use both. The API handles everything it can — content publishing, data retrieval, triggering events that have proper endpoints. Chrome handles the edges — the one tool that has no API, the platform that blocks programmatic access from outside a browser, the workflow step that’s UI-only.
One pattern that recurs: the main pipeline runs via API. One step in the pipeline requires Chrome because a specific capability isn’t exposed through the API. Chrome handles that one step, hands off back to the API-driven pipeline. The rest of the automation doesn’t care that one step used a browser.
When you use Claude in Chrome for automation, set your reliability expectations accordingly. API-based automation can be built for 99%+ reliability. Chrome UI automation — against live web pages that change over time — is closer to 80-90% on any given run, and requires periodic maintenance. Plan for failures. Build retry logic. Log what fails. Don’t build a critical dependency on a Chrome automation without a manual fallback for the days when it breaks.
Use the API when it exists and covers what you need. Use Claude in Chrome when the API doesn’t exist, doesn’t cover what you need, or when the task is genuinely one-off. Combine them when the right architecture calls for it. Neither is always better — they serve different parts of the same problem.
Related on Tygart Media: automate web apps · API getting started.
Yes. Browser UI automation runs at human browsing speed — navigating pages, waiting for elements to render, clicking through workflows. API calls are typically orders of magnitude faster for equivalent operations when an API exists.
Yes. Claude Chat can make API calls and also have Claude in Chrome connected in the same session. This is actually the most common pattern — Claude Chat handles API logic and writes work orders, Chrome handles the UI execution steps that the API can’t reach.
Rarely, but sometimes yes. If the specific action you need isn’t available through the API even though the tool has one — or if you’re doing a one-off test and don’t want to write integration code — Chrome is a reasonable shortcut. For anything recurring, build the API integration instead.
Claude in Chrome will typically report that it couldn’t find an expected element or that the page doesn’t look as described. It won’t guess and won’t take unintended actions. You’ll need to update the instructions to reflect the new UI state.
Writing instructions in terms of intent rather than specific element names helps. “Find the button that saves the record” is more resilient than “click the blue Save button in the upper right corner” — though both will eventually break if the UI changes significantly. There’s no substitute for periodic maintenance of Chrome-based automations.
Last refreshed: May 15, 2026
This pipeline exists because a popular browser-based AI notebook tool generates high-quality cinematic videos from written content — but it has no API. The only way to operate it programmatically is through the browser UI. Claude in Chrome is the bridge.
What follows is documentation of a running production pipeline, including the failure modes that actually occur and how they’re handled.
The pipeline runs as two complementary Cowork scheduled tasks, staggered 30 minutes apart on the same 3-hour cycle.
Task 1 — Kickoff (runs at :00 on each scheduled hour)
Task 2 — Harvest (runs at :30 on each scheduled hour)
Browser-based AI notebook tools typically impose daily limits on cinematic video generation per account. One account isn’t enough to process a continuous stream of articles.
The pipeline handles this by rotating between two accounts. When the primary account hits its daily generation limit, the kickoff task switches to the secondary account. Both accounts have the notebook tool open in different Chrome profiles, with the extension installed in each.
There’s also a notebook count limit per account. Old notebooks that have already been harvested get deleted periodically to stay under the cap.
This is the part that most automation write-ups skip. Here are the real failure modes this pipeline encounters, in roughly descending frequency:
Video generation on the notebook tool can take anywhere from 25 minutes to several hours, depending on server load. The harvest task has a 3-hour timeout window — if a video hasn’t finished after 3 hours, it’s marked as failed and the article is available for retry. In practice, a meaningful portion of generation runs take longer than the timeout window, especially during peak hours.
Mitigation: failed articles are automatically available for re-kickoff in the next cycle.
If the Chrome tab that Claude in Chrome is operating gets closed — by the user, by a browser crash, or by an accidental window close — Claude loses access and the harvest fails. The video may be ready in the notebook tool, but there’s no way to download it without re-establishing the browser connection.
Mitigation: the pipeline marks the article as failed. Manual recovery: reopen the notebook tool in the correct Chrome profile, reinstall the extension if needed, and re-run the harvest for that article.
Both accounts can hit their daily cinematic generation limit on high-volume days. When this happens, the kickoff task will fail to start new videos until the limit resets — which happens on a daily cycle. The pipeline logs these failures with a clear reason so they’re easy to spot.
Mitigation: add a third account if volume consistently exceeds two accounts’ daily limits.
Notebook tools cap how many notebooks a single account can hold. When an account is at its limit, new notebook creation fails. Regular deletion of completed notebooks (those that have been harvested) keeps the account under the cap.
After a successful harvest, the pipeline creates a draft WordPress post with:
The post goes up as a draft, not published directly. A manual review step before publishing is intentional — the pipeline produces a lot of content, and a spot check catches cases where generation quality was unexpectedly low.
The combination of Cowork scheduling + Claude in Chrome + a browser-based tool with no API is a pattern that isn’t widely documented. Most automation examples assume APIs exist. This one doesn’t — it treats the browser UI as the API, and Claude in Chrome as the adapter layer.
The practical result: a pipeline that runs on a schedule, processes a backlog of articles at a rate of one per run, handles account rotation automatically, logs its own state, and surfaces failures with enough detail to recover from them manually.
The tools involved are off-the-shelf. What makes it work is the architecture.
Related on Tygart Media: automate web apps · multiple profiles · Claude for content creators.
Yes. Claude in Chrome navigates to the notebook tool in the browser — the tool doesn’t need to be pre-opened before the task starts, because Claude can navigate to it. But the Chrome profile where the extension is installed must be open and the profile must be logged in to the notebook tool’s account.
The pipeline marks it as failed. The article becomes available for retry in the next kickoff cycle. There’s no penalty — the notebook still exists in the tool with generation in progress, so if you check manually and the video finishes later, you can also harvest it by hand.
Yes. The two-task kickoff/harvest pattern applies to any browser-based tool where you’re triggering a process that takes time to complete. The specific steps change, but the architecture — trigger, wait, harvest, log — is reusable.
No. The pipeline creates them as drafts. A manual review step is built in before anything goes live. This is intentional — automated generation at scale benefits from a human spot-check before publishing.
Reopen the relevant Chrome profile. Make sure the Claude in Chrome extension is installed and active in that profile. Log in to the notebook tool if the session has expired. Then manually trigger a harvest for the specific article — open the notebook, confirm the video is ready, download it, and upload it to WordPress.